Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Lightning-fast Machine Learning with Spark
Search
Probst Ludwine
November 11, 2014
Programming
1k
6
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Lightning-fast Machine Learning with Spark
Probst Ludwine
November 11, 2014
More Decks by Probst Ludwine
See All by Probst Ludwine
Tech Beyond Borders
nivdul
0
240
Tech Beyond Borders
nivdul
0
110
Analytics in the age of the Internet of Things
nivdul
1
260
Lightning-fast Machine Learning with Spark
nivdul
15
5.4k
Introduction to Spark
nivdul
4
660
Other Decks in Programming
See All in Programming
個人開発者よ、Honoを使え(おじさんver)
tanahiro2010
2
290
flutter_test のその先へ — Flutter アプリの LLM 機能に「評価」という品質保証を
kosukesaigusa
0
140
Domain-Driven Transformation
hschwentner
2
2.4k
クラウドエージェントは、 何がそんなに便利なのか / what makes cloud agents so useful
rkaga
3
620
社内AIエージェント「Askワンバン」における コストチューニングの取り組み
t0yohei
0
110
Performance Optimization With LLMs
xleitix
0
230
複雑なUIコンポーネントとの ⻑い付き合い⽅:波及するバグからテスト戦略を経て、安全な再設計へ
mixplace
0
490
AI主導のプログラミング学習アプリを作ってみた
econanringo
0
200
Coding with AI: How to trust the storyteller (AWS Community Day Adria, Ljubljana 2026)
slobodan
0
130
PyConTW 2026 - AI Coding 不只是工具升級, 區域醫院醫療資訊系統協作開發與資訊團隊轉型實踐
cclai999
0
210
R8 の設定見直しでアプリサイズ削減
andpad
0
240
私なりのハーネスエンジニアリング ~独自の言語処理系の開発を通して~
seosoft
0
140
Featured
See All Featured
How to Think Like a Performance Engineer
csswizardry
28
2.9k
Building Flexible Design Systems
yeseniaperezcruz
330
41k
ピンチをチャンスに:未来をつくるプロダクトロードマップ #pmconf2020
aki_iinuma
128
56k
Visual Storytelling: How to be a Superhuman Communicator
reverentgeek
2
730
The Illustrated Children's Guide to Kubernetes
chrisshort
51
53k
The State of eCommerce SEO: How to Win in Today's Products SERPs - #SEOweek
aleyda
2
12k
Improving Core Web Vitals using Speculation Rules API
sergeychernyshev
21
1.7k
Between Models and Reality
mayunak
4
530
Speed Design
sergeychernyshev
33
2.2k
How GitHub (no longer) Works
holman
316
150k
More Than Pixels: Becoming A User Experience Designer
marktimemedia
3
600
Thoughts on Productivity
jonyablonski
76
5.4k
Transcript
@nivdul #DV14 #MLwithSpark Lightning fast Machine Learning with Spark Ludwine
Probst
@nivdul #Devoxx #MLwithSpark me Data engineer at Leader of Duchess
France
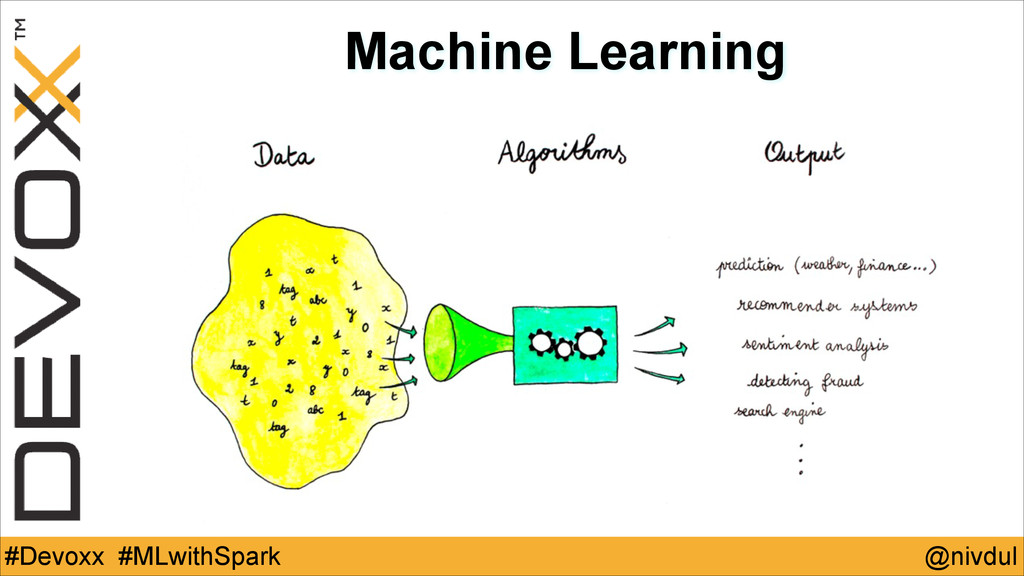
@nivdul #Devoxx #MLwithSpark Machine Learning
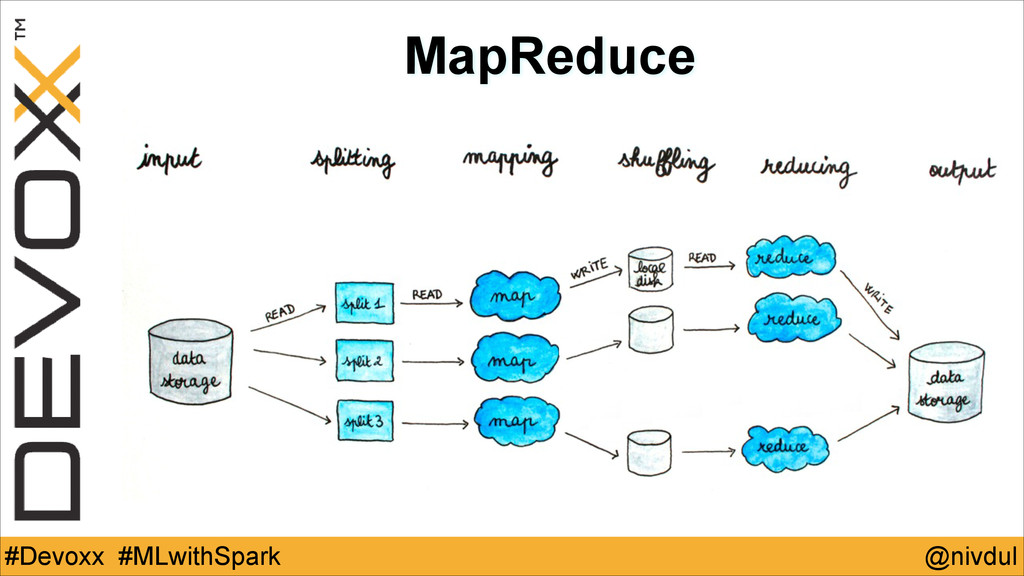
@nivdul #DV14 #MLwithSpark MapReduce Lay of the land
@nivdul #Devoxx #MLwithSpark MapReduce
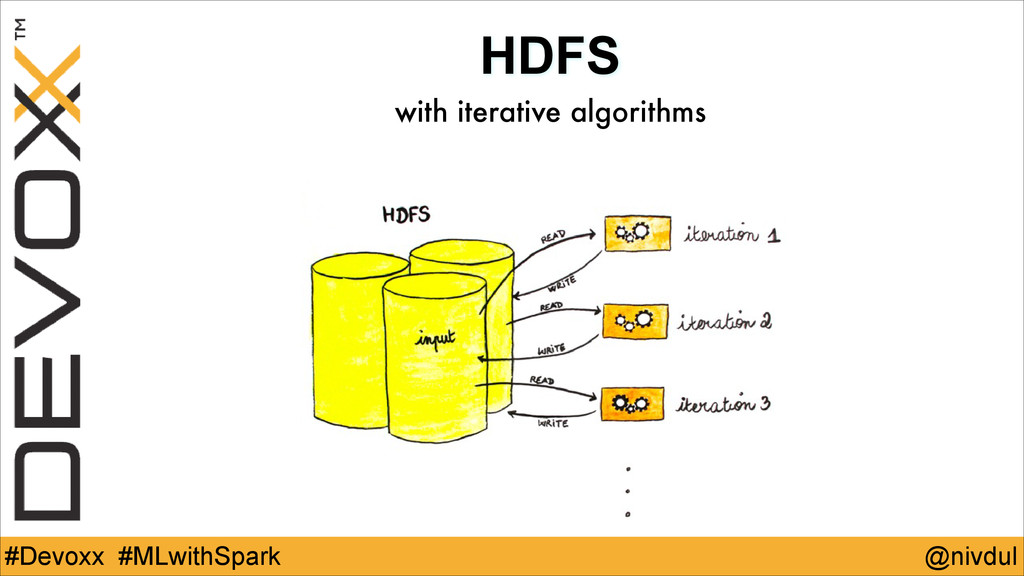
@nivdul #Devoxx #MLwithSpark HDFS with iterative algorithms
@nivdul #Devoxx #MLwithSpark
@nivdul #Devoxx #MLwithSpark is a fast and general engine for
large-scale data processing
@nivdul #DV14 #MLwithSpark •big data analytics in memory/disk •complements Hadoop
•fast and more flexible •Resilient Distributed Datasets (RDD) •shared variables
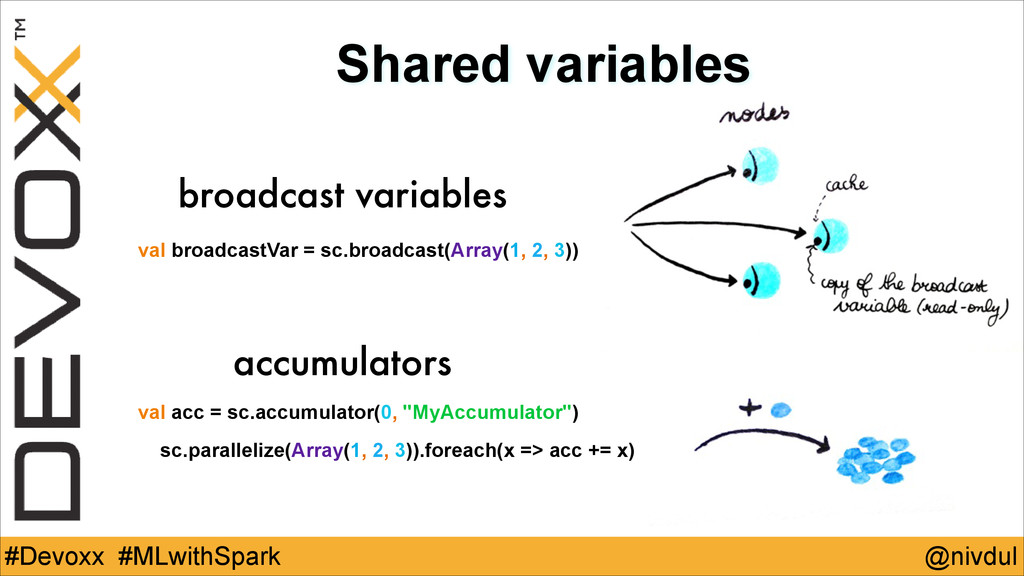
@nivdul #Devoxx #MLwithSpark Shared variables broadcast variables accumulators val broadcastVar
= sc.broadcast(Array(1, 2, 3)) val acc = sc.accumulator(0, "MyAccumulator") sc.parallelize(Array(1, 2, 3)).foreach(x => acc += x)
@nivdul #DV14 #MLwithSpark RDD (Resilient Distributed Datasets) •process in parallel
•controllable persistence (memory, disk…) •higher-level operations (transformation & actions) •rebuilt automatically using lineage
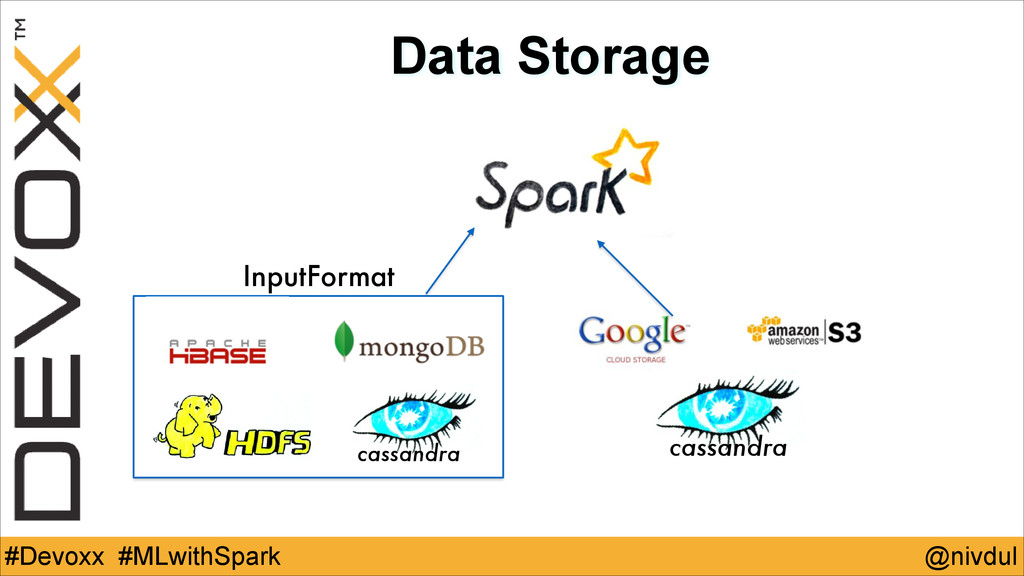
@nivdul #Devoxx #MLwithSpark Data Storage InputFormat cassandra cassandra
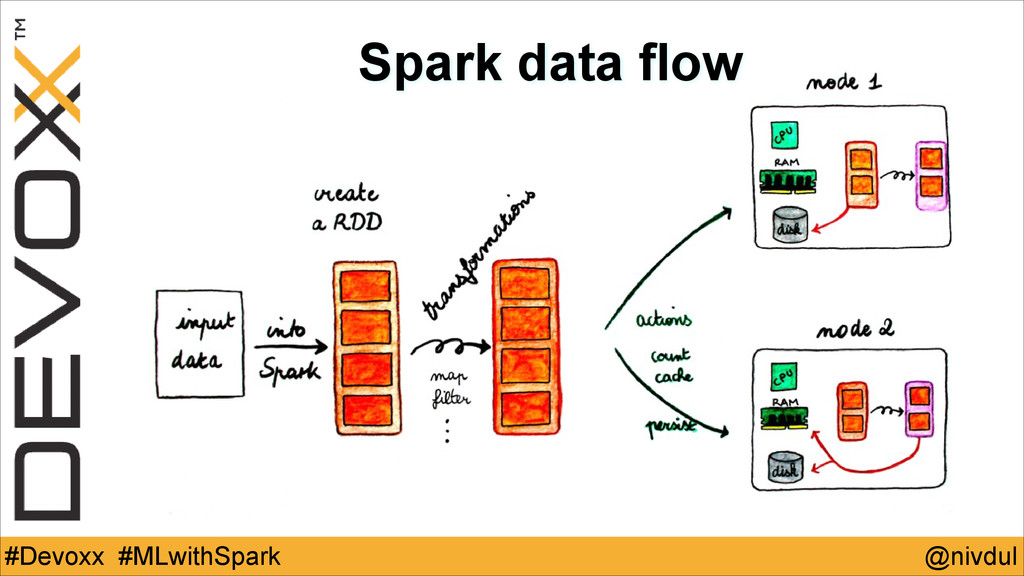
@nivdul #Devoxx #MLwithSpark Spark data flow
@nivdul #Devoxx #MLwithSpark Languages interactive shell (scala & python) Lambda
(Java 8)
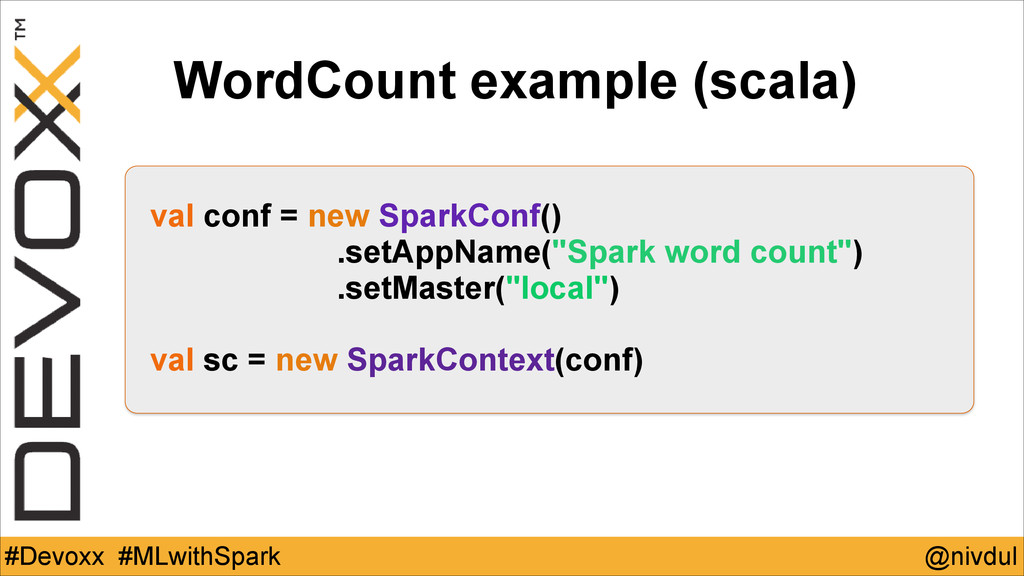
@nivdul #Devoxx #MLwithSpark val conf = new SparkConf() .setAppName("Spark word
count") .setMaster("local") ! val sc = new SparkContext(conf) WordCount example (scala)
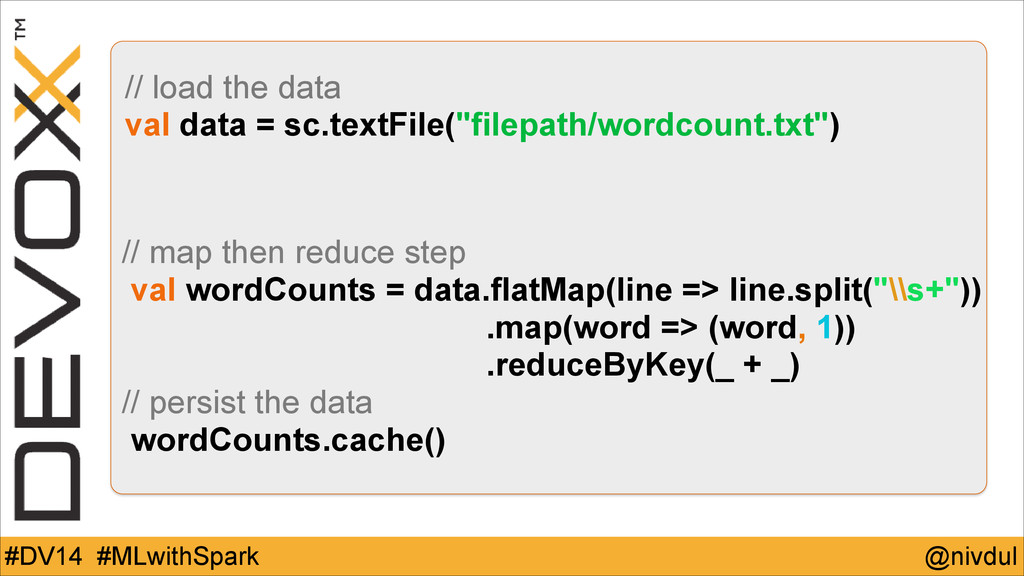
@nivdul #DV14 #MLwithSpark // load the data val data =
sc.textFile("filepath/wordcount.txt") // map then reduce step val wordCounts = data.flatMap(line => line.split("\\s+")) .map(word => (word, 1)) .reduceByKey(_ + _) // persist the data wordCounts.cache()
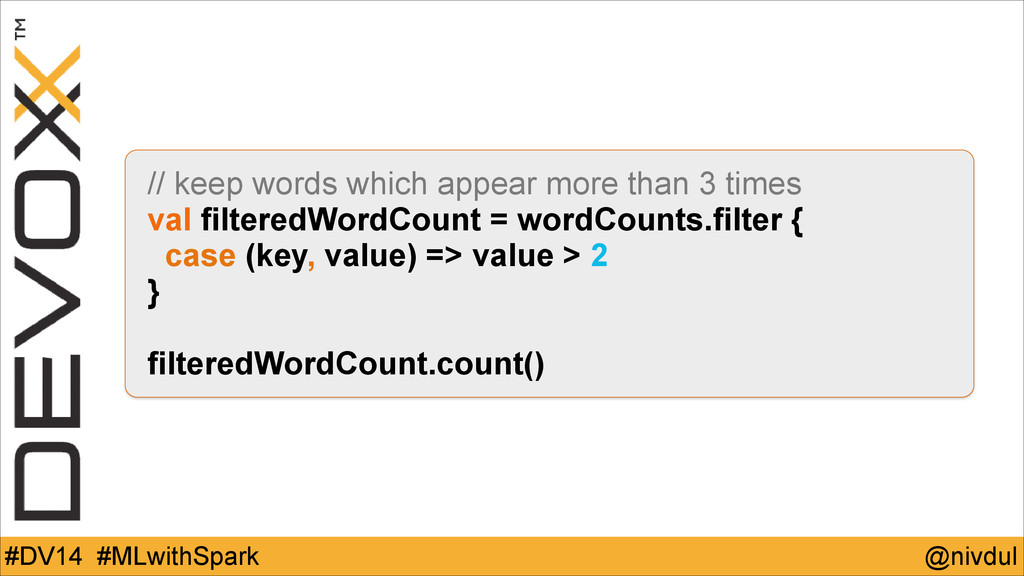
@nivdul #DV14 #MLwithSpark // keep words which appear more than
3 times val filteredWordCount = wordCounts.filter { case (key, value) => value > 2 } ! filteredWordCount.count()
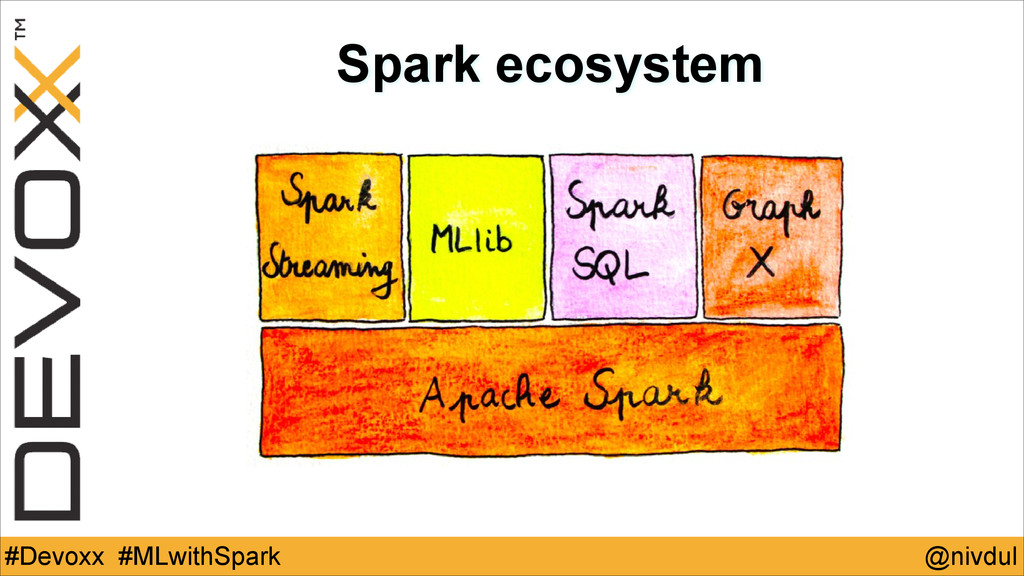
@nivdul #Devoxx #MLwithSpark Spark ecosystem
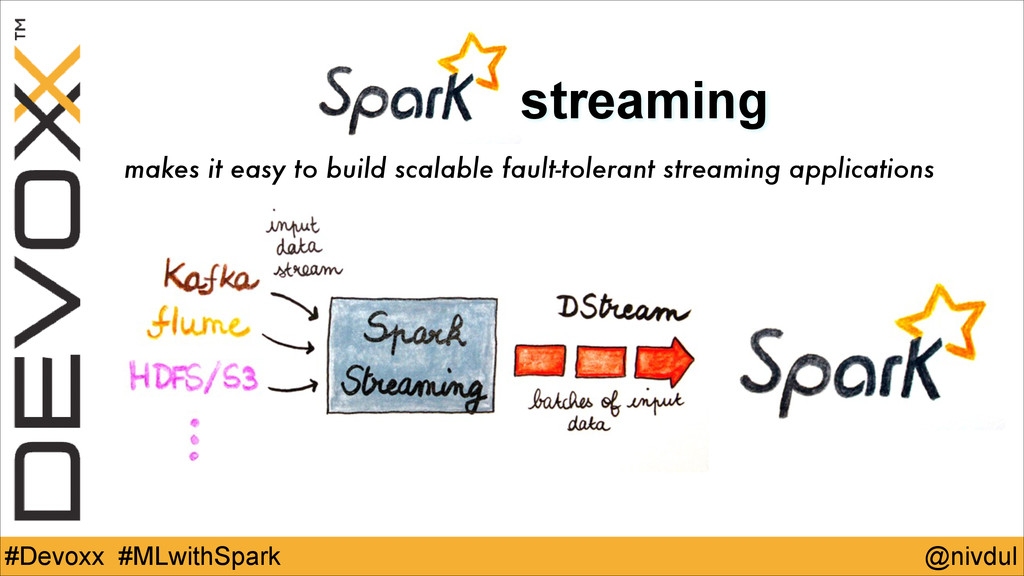
@nivdul #Devoxx #MLwithSpark streaming makes it easy to build scalable
fault-tolerant streaming applications
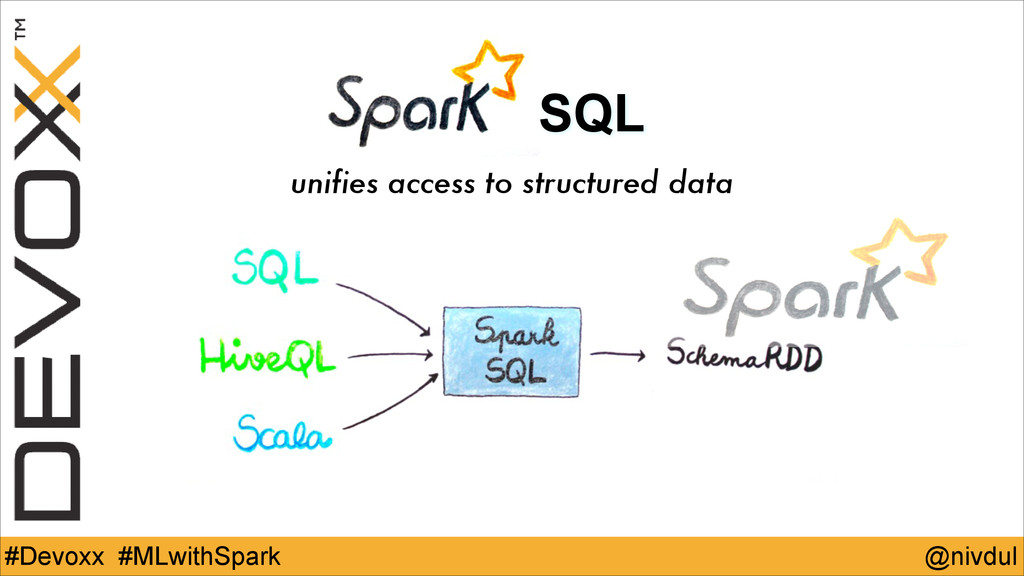
@nivdul #Devoxx #MLwithSpark SQL unifies access to structured data
@nivdul #Devoxx #MLwithSpark is Apache Spark's API for graphs and
graph-parallel computation
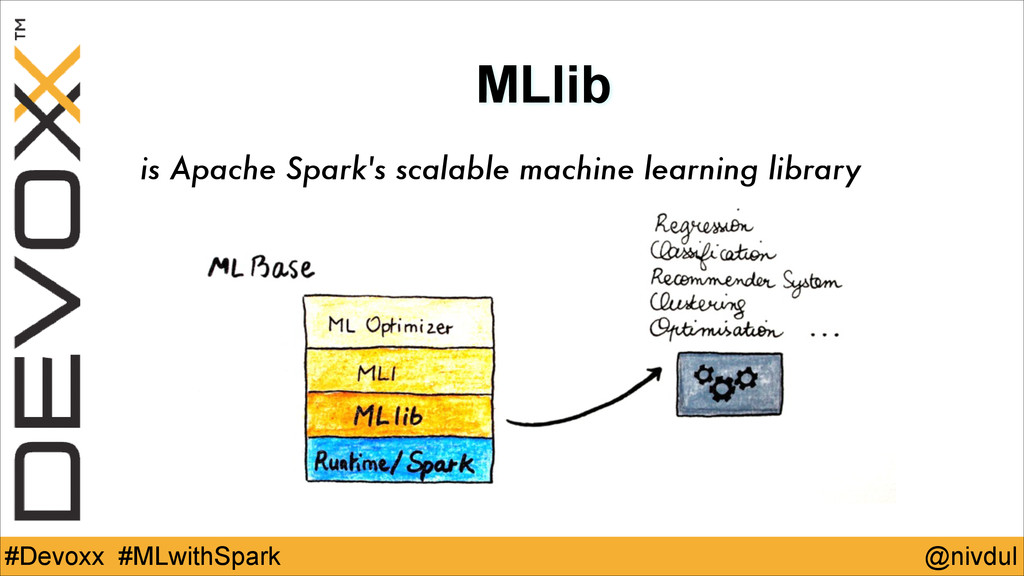
@nivdul #Devoxx #MLwithSpark MLlib is Apache Spark's scalable machine learning
library
@nivdul #Devoxx #MLwithSpark Machine learning with Spark / MLlib
@nivdul #Devoxx #MLwithSpark Machine learning libraries scikit
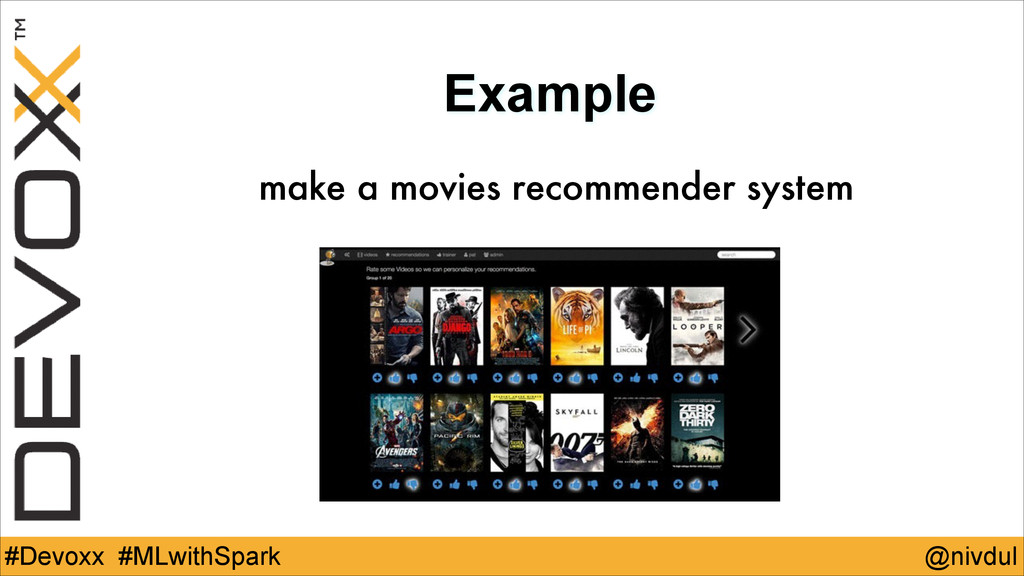
@nivdul #Devoxx #MLwithSpark Example make a movies recommender system
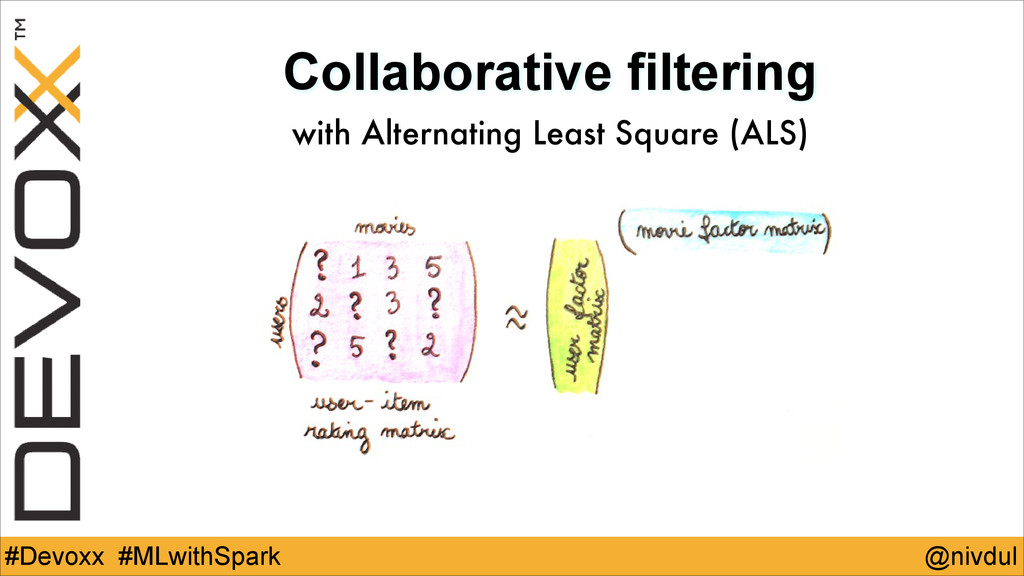
@nivdul #Devoxx #MLwithSpark Collaborative filtering with Alternating Least Square (ALS)
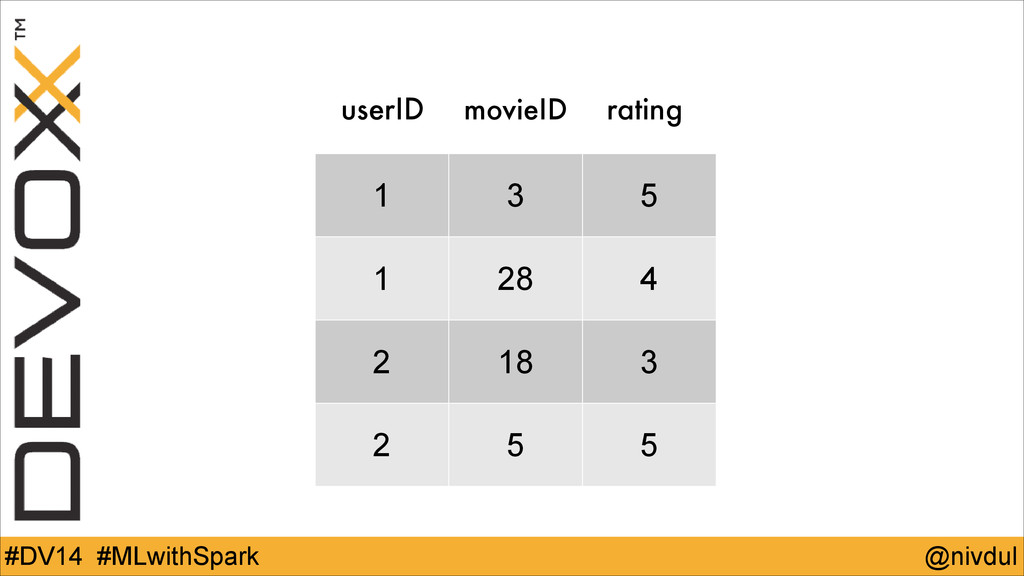
@nivdul #DV14 #MLwithSpark 1 3 5 1 28 4 2
18 3 2 5 5 userID movieID rating
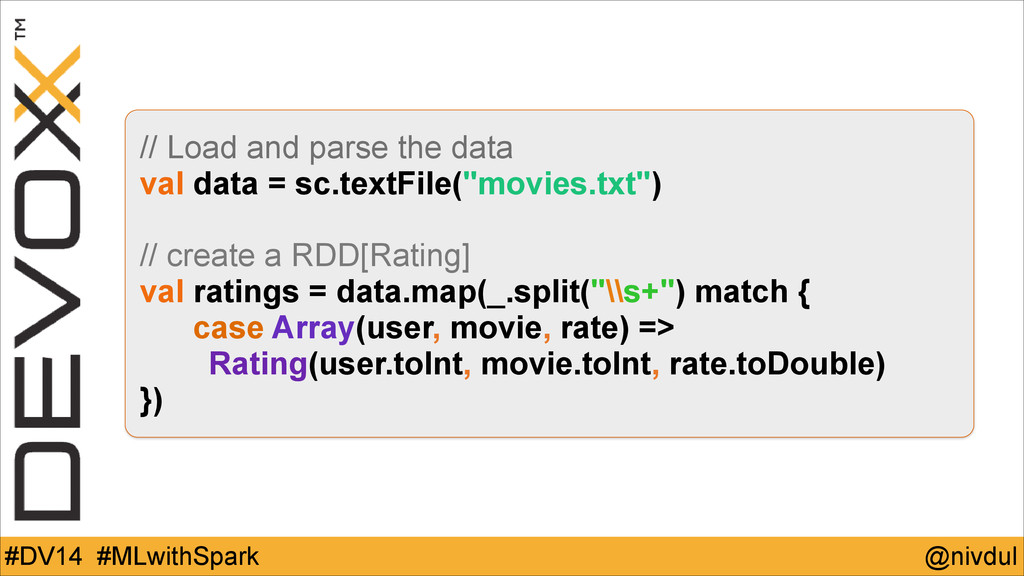
@nivdul #DV14 #MLwithSpark // Load and parse the data val
data = sc.textFile("movies.txt") ! // create a RDD[Rating] val ratings = data.map(_.split("\\s+") match { case Array(user, movie, rate) => Rating(user.toInt, movie.toInt, rate.toDouble) })
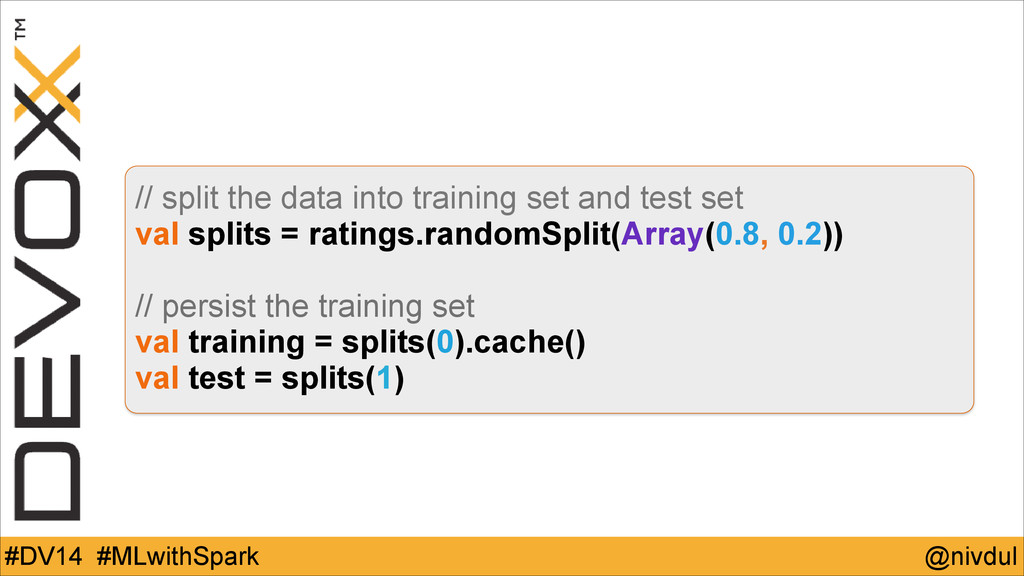
@nivdul #DV14 #MLwithSpark // split the data into training set
and test set val splits = ratings.randomSplit(Array(0.8, 0.2)) ! // persist the training set val training = splits(0).cache() val test = splits(1)
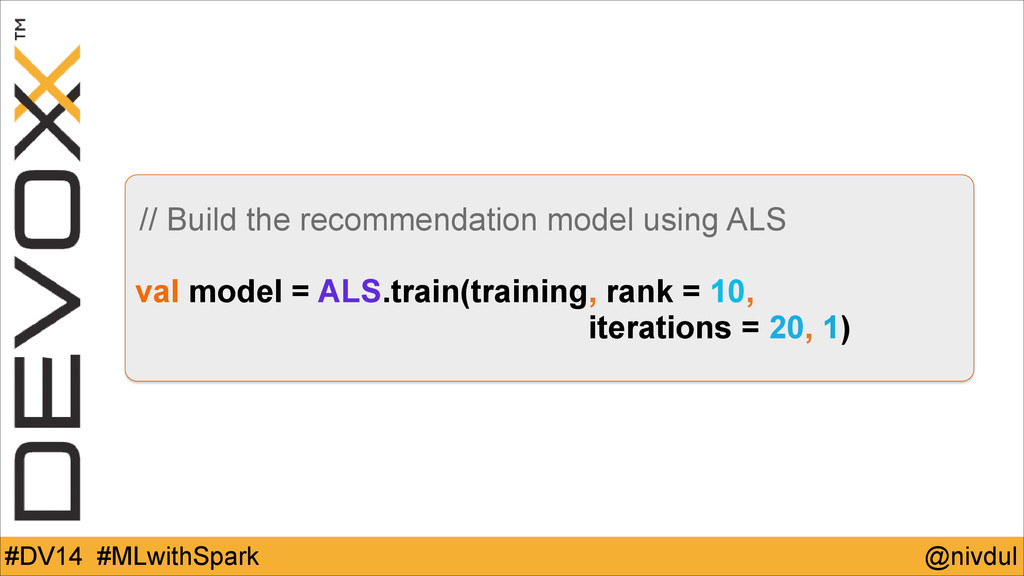
@nivdul #DV14 #MLwithSpark // Build the recommendation model using ALS
! val model = ALS.train(training, rank = 10, iterations = 20, 1)
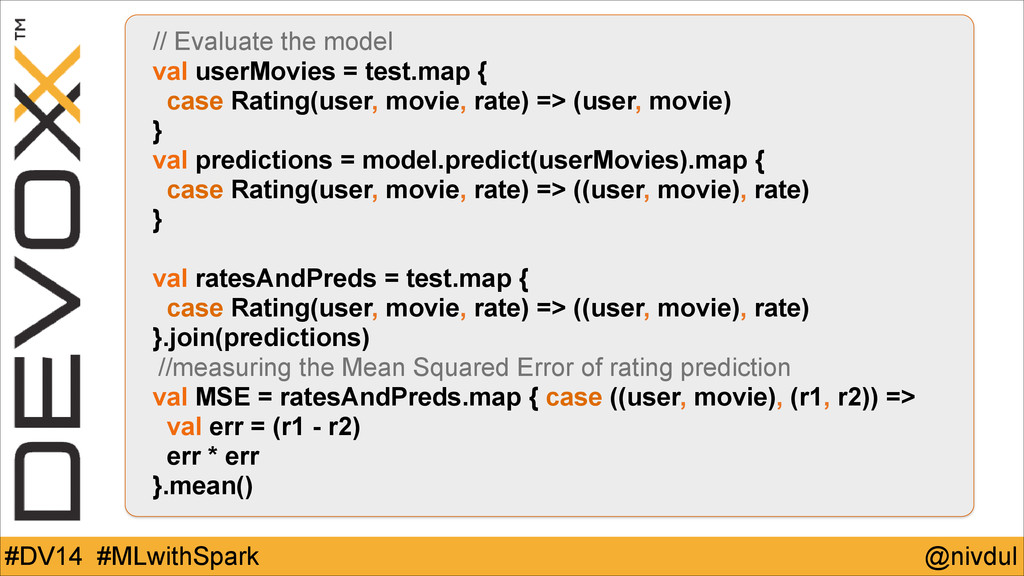
@nivdul #DV14 #MLwithSpark // Evaluate the model val userMovies =
test.map { case Rating(user, movie, rate) => (user, movie) } val predictions = model.predict(userMovies).map { case Rating(user, movie, rate) => ((user, movie), rate) } ! val ratesAndPreds = test.map { case Rating(user, movie, rate) => ((user, movie), rate) }.join(predictions) //measuring the Mean Squared Error of rating prediction val MSE = ratesAndPreds.map { case ((user, movie), (r1, r2)) => val err = (r1 - r2) err * err }.mean()
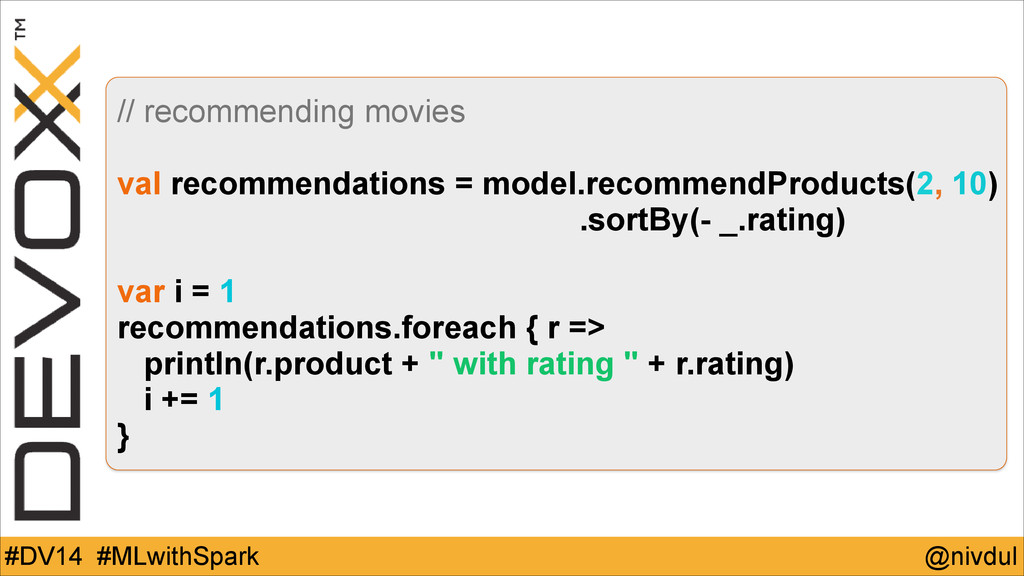
@nivdul #DV14 #MLwithSpark // recommending movies ! val recommendations =
model.recommendProducts(2, 10) .sortBy(- _.rating) ! var i = 1 recommendations.foreach { r => println(r.product + " with rating " + r.rating) i += 1 }
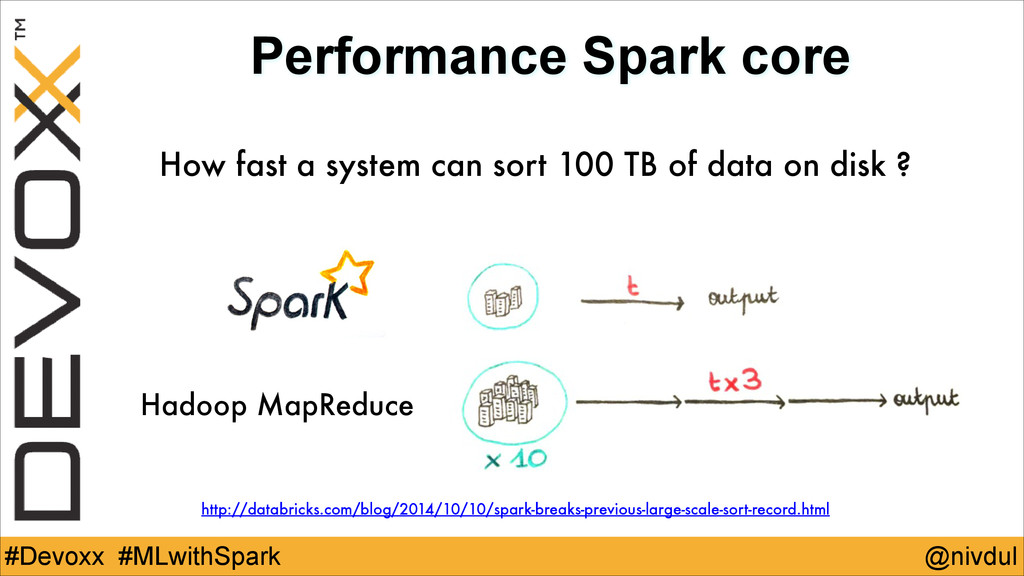
@nivdul #Devoxx #MLwithSpark Performance Spark core Hadoop MapReduce http://databricks.com/blog/2014/10/10/spark-breaks-previous-large-scale-sort-record.html How
fast a system can sort 100 TB of data on disk ?
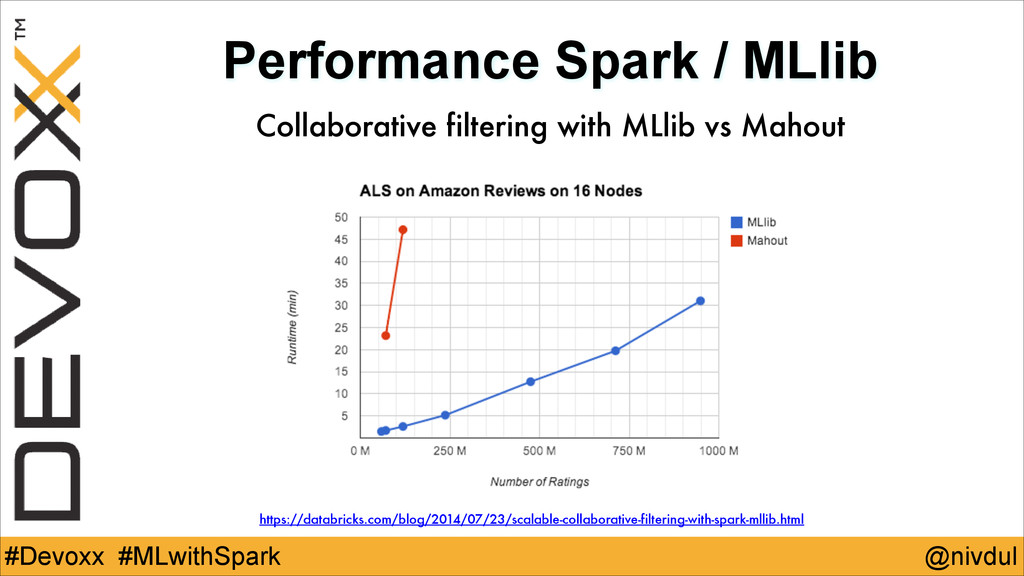
@nivdul #Devoxx #MLwithSpark Performance Spark / MLlib Collaborative filtering with
MLlib vs Mahout https://databricks.com/blog/2014/07/23/scalable-collaborative-filtering-with-spark-mllib.html
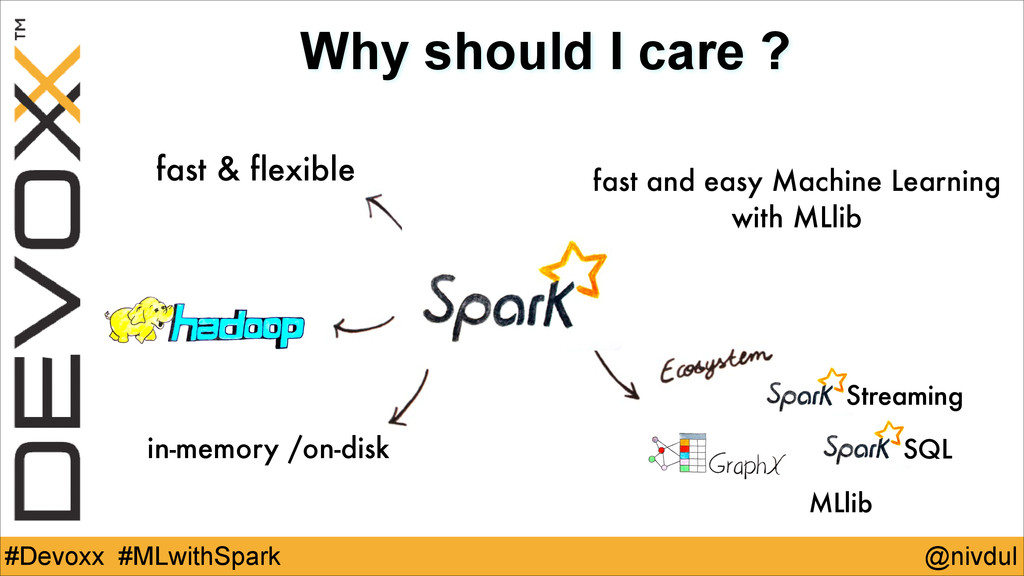
@nivdul #Devoxx #MLwithSpark Why should I care ? fast and
easy Machine Learning with MLlib fast & flexible in-memory /on-disk SQL Streaming MLlib
None


 nivdul
 tanahiro2010
 kosukesaigusa
 hschwentner
 rkaga
 t0yohei
 xleitix
 mixplace
 econanringo
 slobodan
 cclai999
 andpad
 seosoft
 csswizardry
 yeseniaperezcruz
 aki_iinuma
 reverentgeek
 chrisshort
 aleyda
 sergeychernyshev
 mayunak
 holman
 marktimemedia
 jonyablonski