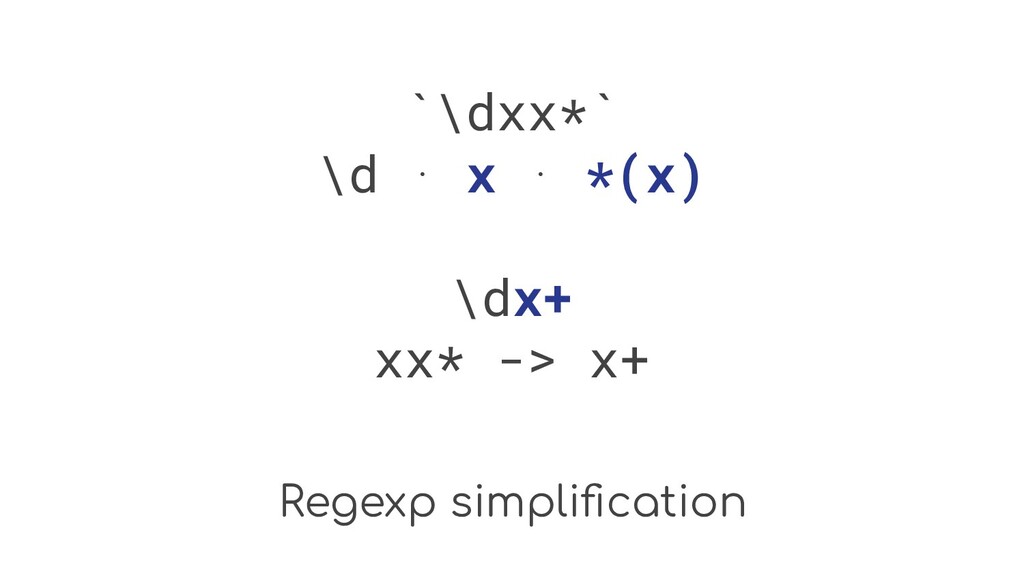Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
How to do regexp analysis
Search
Iskander (Alex) Sharipov
April 25, 2020
Programming
330
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
How to do regexp analysis
Iskander (Alex) Sharipov
April 25, 2020
More Decks by Iskander (Alex) Sharipov
See All by Iskander (Alex) Sharipov
quasigo
quasilyte
0
110
Go gamedev: XM music
quasilyte
0
160
Zero alloc pathfinding
quasilyte
0
800
Mycelium
quasilyte
0
110
Roboden game pitch
quasilyte
0
320
Ebitengine Ecosystem Overview
quasilyte
1
1k
Go gamedev patterns
quasilyte
0
570
profile-guided code analysis
quasilyte
0
400
Go inlining
quasilyte
0
180
Other Decks in Programming
See All in Programming
Go × SIMDで高速化するベクトル検索 ~ルーフラインモデルでSIMDが効く境界を探れ! ~
po3rin
1
2.8k
ハーネス設計入門 〜 基礎知識の整理から実務へのステップアップ 〜
kinopeee
16
13k
技術的負債を組織課題として解く-増えすぎたマイクロサービスとの戦い-
reimaru
1
2.3k
Snowflakeで業務アプリを作ろう。 Snowflakeのアプリ機能解説&実践ガイド
ayumu_yamaguchi
2
300
フロントエンドUIフレームワークのこれまでとこれから
ssssota
5
2.9k
AWS DevOps Agentで インシデント対応をAIに任せたい
honmarkhunt
7
3.1k
App Storeの外へ──日本のiOSサイドローディング入門 for iOSDC Japan 2026
yuukiw00w
0
240
Webの地図
yosuke_furukawa
PRO
6
4.7k
wkhtmltopdfの次どうするか問題2026
willnet
2
1.6k
JPUG勉強会 OSSデータベースの内部構造を理解しよう(第2回)
oga5
0
270
FreeBSDでZabbixを動かす
kenkino
0
320
UnityでSystem.Net.WebSocketsなWebSocketサーバが動かないのでUnity Monoのコードを覗いてみた / about implementing websocket server with unity mono
drumath2237
1
320
Featured
See All Featured
Pawsitive SEO: Lessons from My Dog (and Many Mistakes) on Thriving as a Consultant in the Age of AI
davidcarrasco
0
250
Evolution of real-time – Irina Nazarova, EuRuKo, 2024
irinanazarova
9
1.6k
Let's Do A Bunch of Simple Stuff to Make Websites Faster
chriscoyier
508
140k
Lightning talk: Run Django tests with GitHub Actions
sabderemane
0
260
Between Models and Reality
mayunak
4
460
Helping Users Find Their Own Way: Creating Modern Search Experiences
danielanewman
31
3.4k
Conquering PDFs: document understanding beyond plain text
inesmontani
PRO
4
3.1k
Raft: Consensus for Rubyists
vanstee
142
7.7k
エンジニアに許された特別な時間の終わり
watany
109
250k
State of Search Keynote: SEO is Dead Long Live SEO
ryanjones
0
280
Design and Strategy: How to Deal with People Who Don’t "Get" Design
morganepeng
133
19k
Taking LLMs out of the black box: A practical guide to human-in-the-loop distillation
inesmontani
PRO
3
2.4k
Transcript
How to do regexp analysis @quasilyte / GolangKazan 2020
Not why, but how Implementation advice and potential issues overview.
go-critic NoVerify Open-Source analyzers
Discussion plan • Handling regexp syntax • Analyzing regexp flow
• Finding bugs in regular expressions • Regexp rewriting
Handling regexp syntax
Why making own parser? Most regexp libraries use parsers that
give up on the first error. For analysis, we need rich AST (parse tree even) and error-tolerant parser.
Writing a parser Useful resources: • Regexp syntax docs (BNF,
re2-syntax) • Pratt parsers tutorial (RU, EN) • Regexp corpus for tests (gist) • Dialect-specific documentation
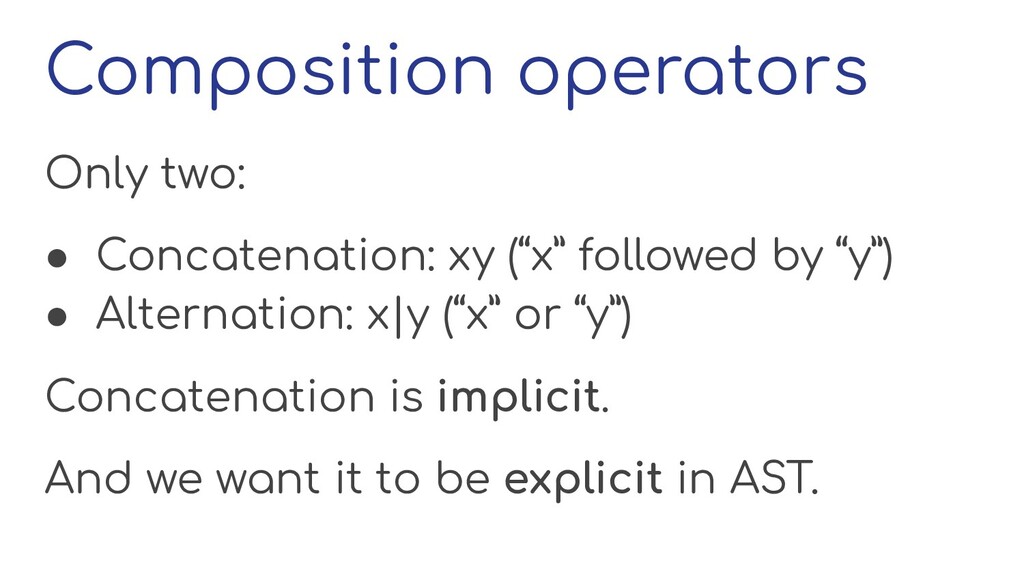
Composition operators Only two: • Concatenation: xy (“x” followed by
“y”) • Alternation: x|y (“x” or “y”) Concatenation is implicit. And we want it to be explicit in AST.
Concat operation `0|xy[a-z]` ⬇ 0 | x ⋅ y ⋅
[a-z]
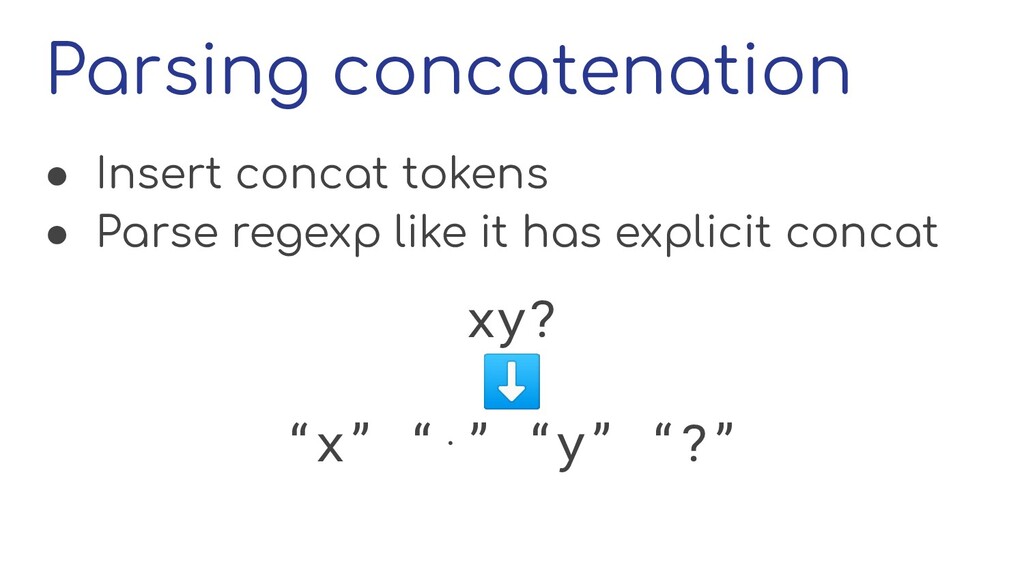
Parsing concatenation • Insert concat tokens • Parse regexp like
it has explicit concat xy? ⬇ “x” “⋅” “y” “?”
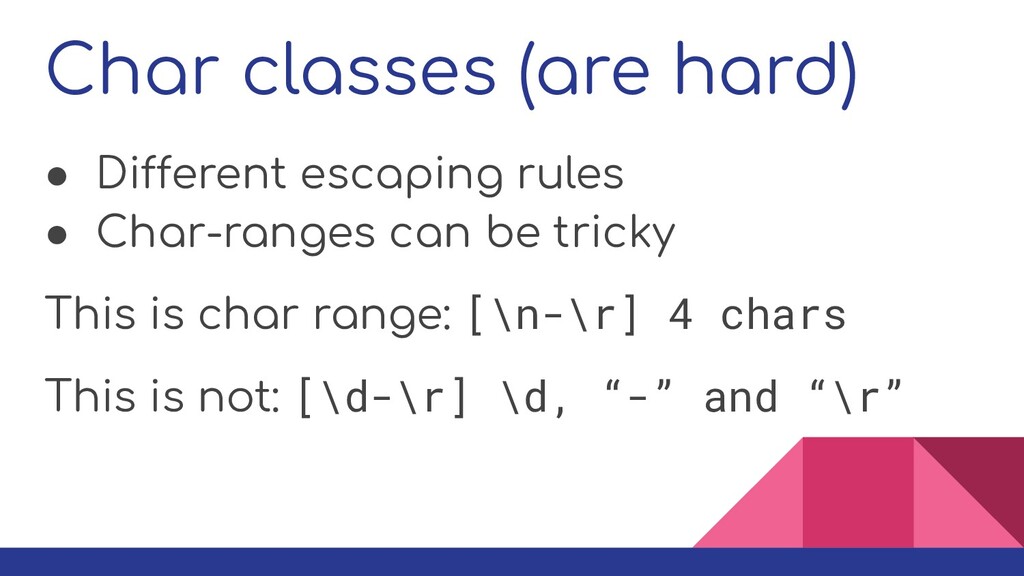
Char classes (are hard) • Different escaping rules • Char-ranges
can be tricky This is char range: [\n-\r] 4 chars This is not: [\d-\r] \d, “-” and “\r”
Char classes syntax `[][]` What is it?
Char classes syntax `[][]` A char class of “]” and
“[“! `[\]\[]`
Char classes syntax `[^]*|\[[^\]]` What is it?
Char classes syntax `[^]*|\[[^\]]` A single char class! `[^\]*|\[\[^\]]`
Char classes syntax `[+=-_]` What will be matched?
Char classes syntax `[+=-_]` “F” matched
Char classes syntax `[+=\-_]` “F” not matched
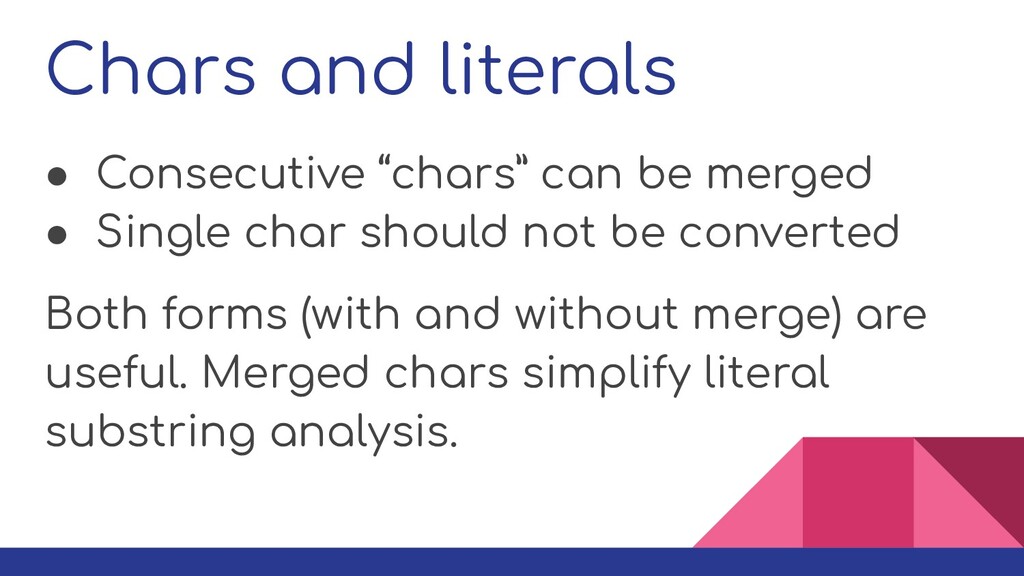
Chars and literals • Consecutive “chars” can be merged •
Single char should not be converted Both forms (with and without merge) are useful. Merged chars simplify literal substring analysis.
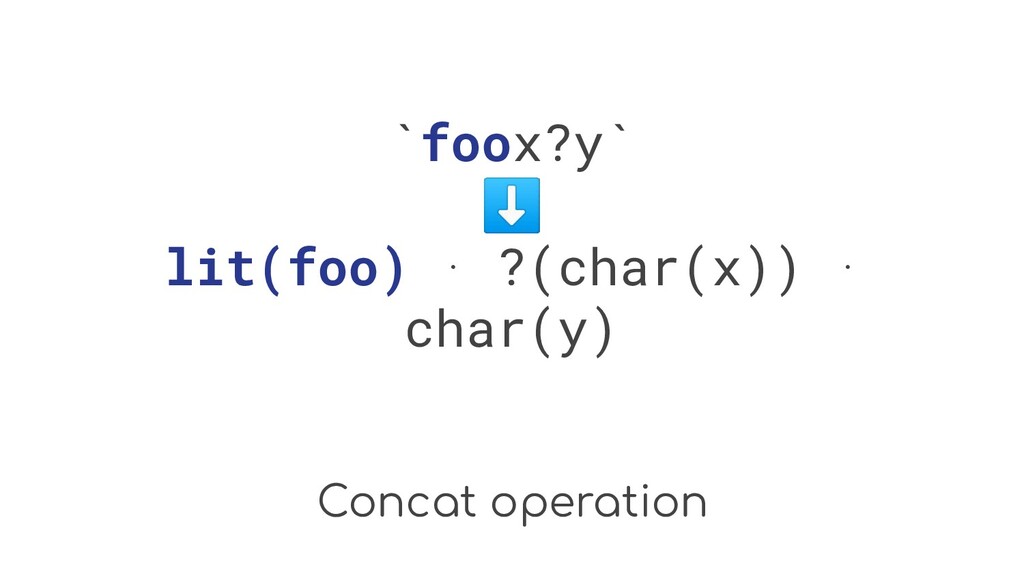
Concat operation `foox?y` ⬇ lit(foo) ⋅ ?(char(x)) ⋅ char(y)
AST types There are at least two approaches: • One
type + enum tags • Many types + shared interface/base Both have pros and cons.
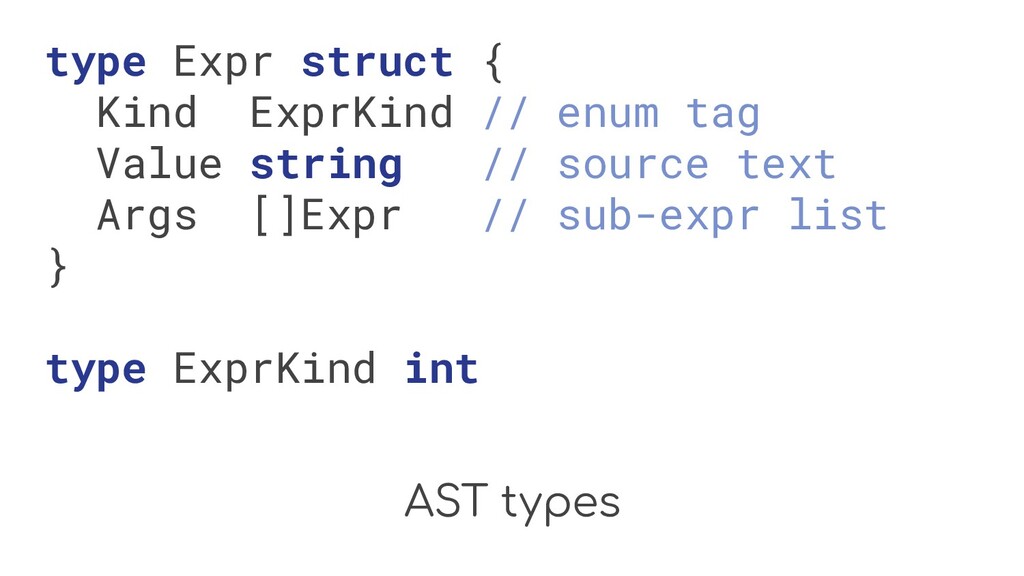
AST types type Expr struct { Kind ExprKind // enum
tag Value string // source text Args []Expr // sub-expr list } type ExprKind int
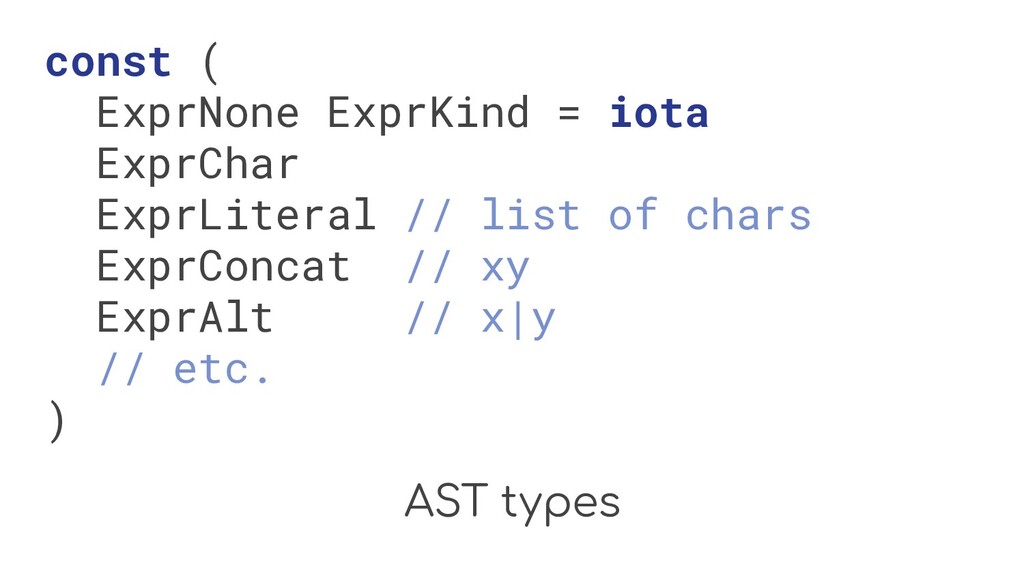
AST types const ( ExprNone ExprKind = iota ExprChar ExprLiteral
// list of chars ExprConcat // xy ExprAlt // x|y // etc. )
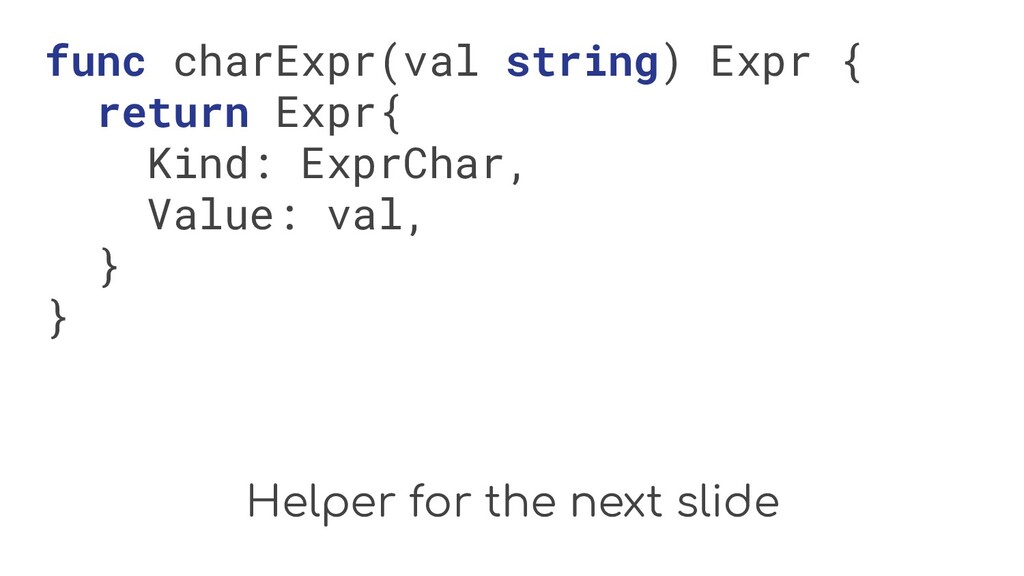
Helper for the next slide func charExpr(val string) Expr {
return Expr{ Kind: ExprChar, Value: val, } }
AST of `x|yz` Expr{ Kind: ExprAlt, Value: "x|yz", Args: []Expr{
charExpr("x"), { Kind: ExprConcat, Value: "yz", Args: []Expr{ charExpr("y"), charExpr("z"), }, }, }, }
Go regexp parsing library https://github.com/quasilyte/regex contains a `regex/syntax` package that
is used in both NoVerify and go-critic. It can parse both re2 and pcre patterns.
Analyzing regexp flow
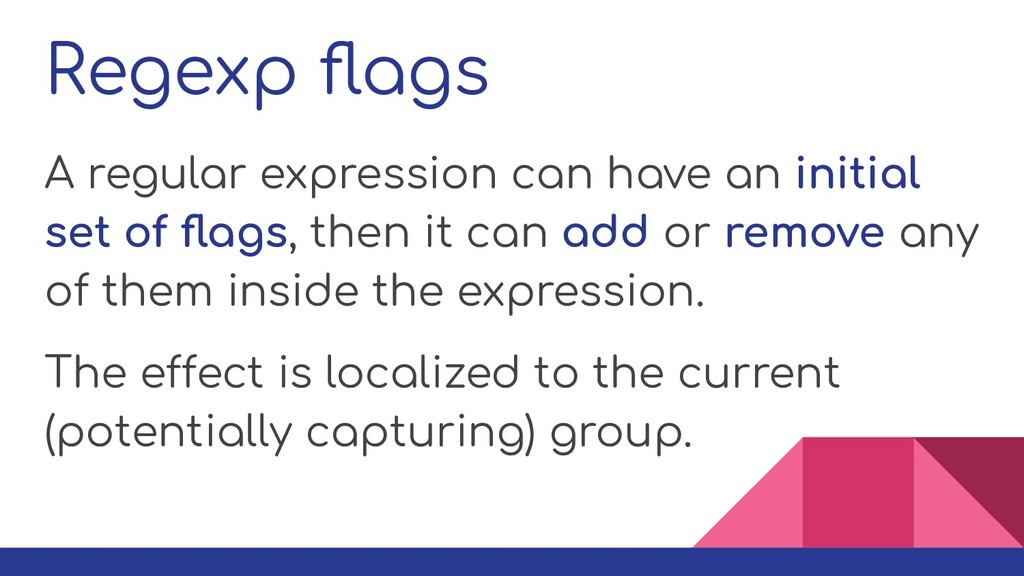
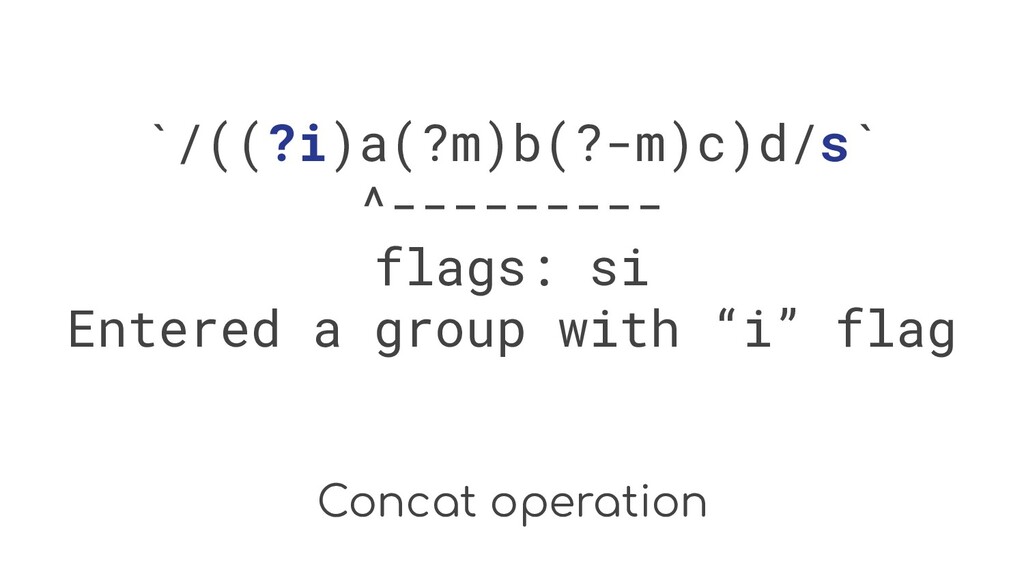
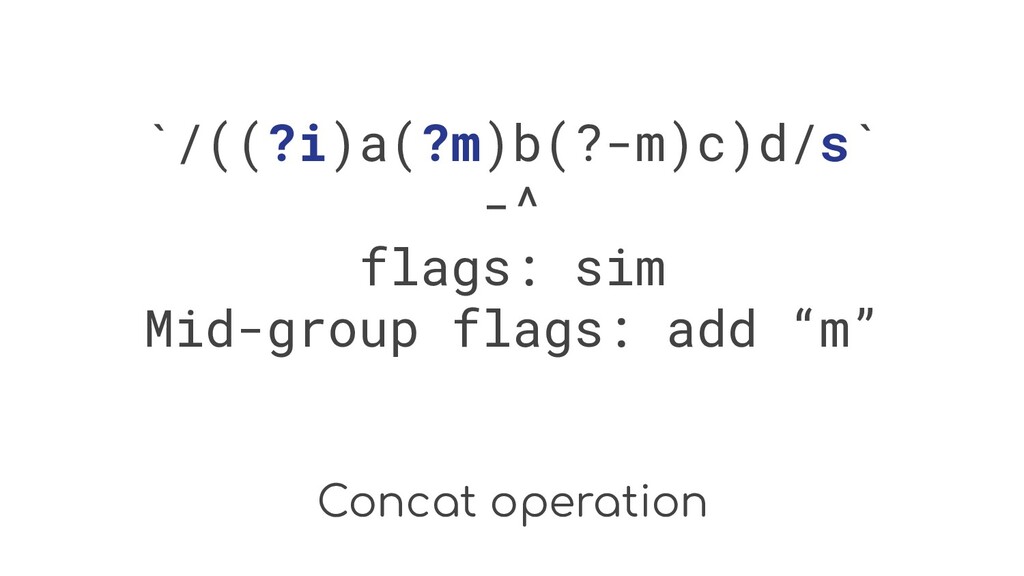
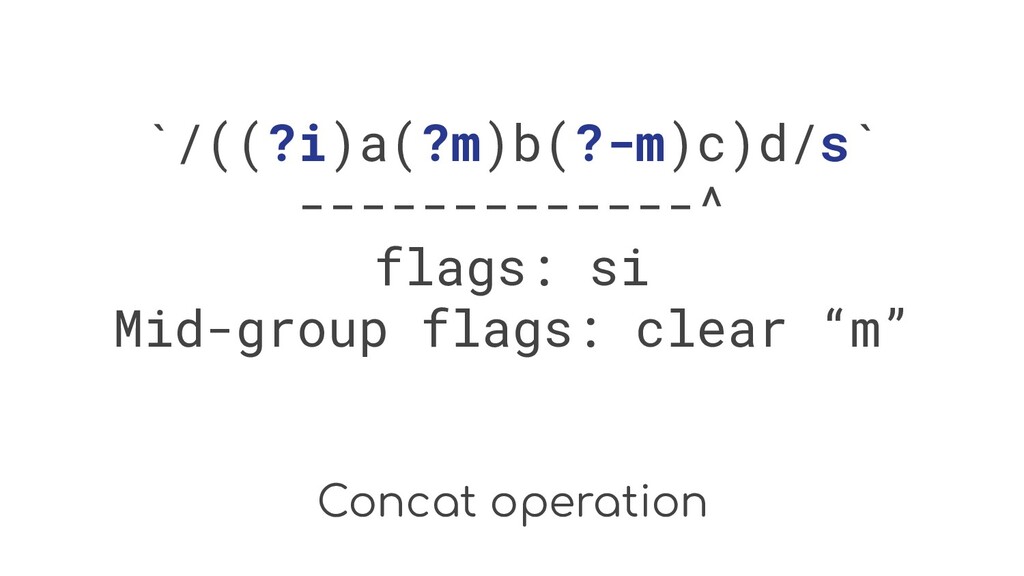
Regexp flags A regular expression can have an initial set
of flags, then it can add or remove any of them inside the expression. The effect is localized to the current (potentially capturing) group.
Concat operation `/((?i)a(?m)b(?-m)c)d/s` ^--------- flags: si Entered a group with
“i” flag
Concat operation `/((?i)a(?m)b(?-m)c)d/s` -^ flags: sim Mid-group flags: add “m”
Concat operation `/((?i)a(?m)b(?-m)c)d/s` -------------^ flags: si Mid-group flags: clear “m”
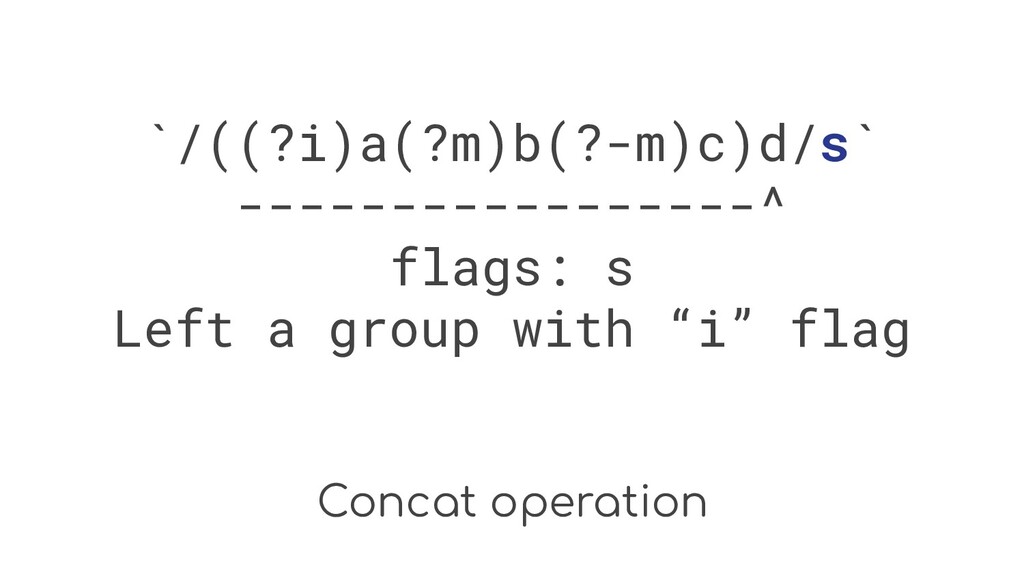
Concat operation `/((?i)a(?m)b(?-m)c)d/s` -----------------^ flags: s Left a group with
“i” flag
Flags flow • Flags are lexically scoped • Groups are
a scoping unit • Leaving a group drops a scope • Entering a group adds a scope
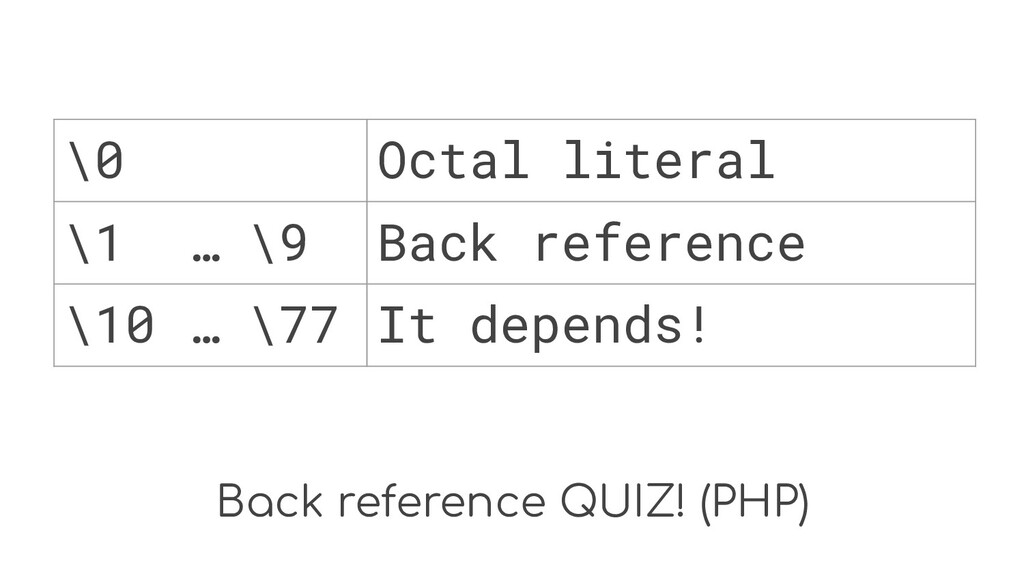
Back references • Rules vary among engines/dialects • Syntax may
clash with octal literals • Can also be relative/named: \g{-1}, etc We’ll use PHP rules as an example.
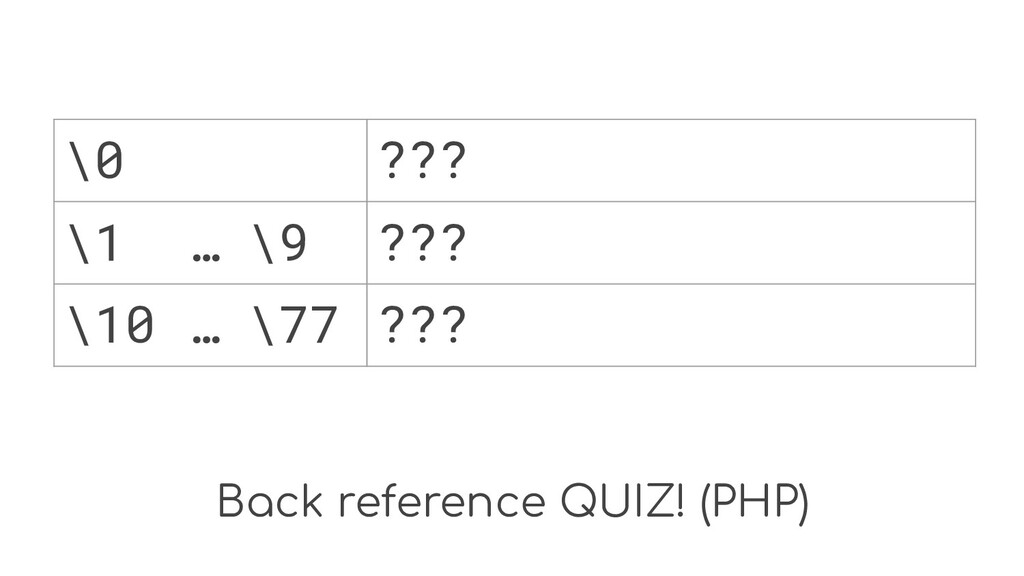
Back reference QUIZ! (PHP) \0 ??? \1 … \9 ???
\10 … \77 ???
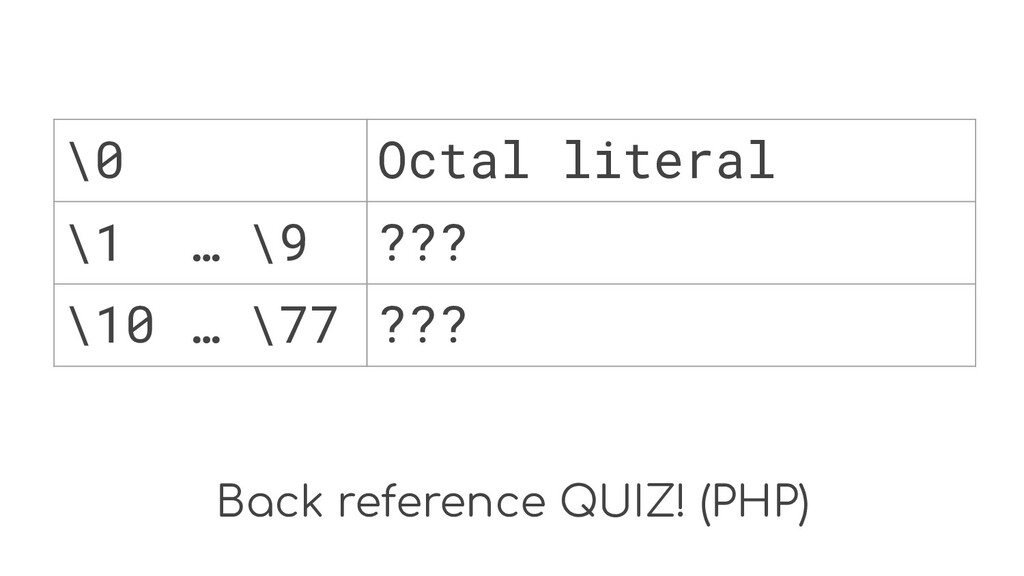
Back reference QUIZ! (PHP) \0 Octal literal \1 … \9
??? \10 … \77 ???
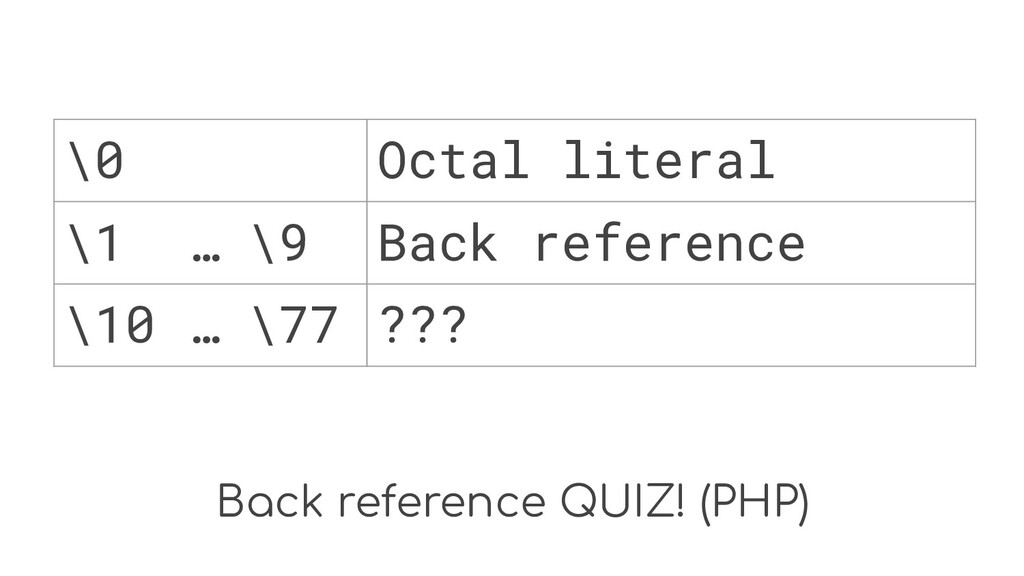
Back reference QUIZ! (PHP) \0 Octal literal \1 … \9
Back reference \10 … \77 ???
Back reference QUIZ! (PHP) \0 Octal literal \1 … \9
Back reference \10 … \77 It depends!
Groups flow • Capturing groups are numbered from left to
right. • Non-capturing groups are ignored. • Groups can have a name.
Finding bugs in regular expressions
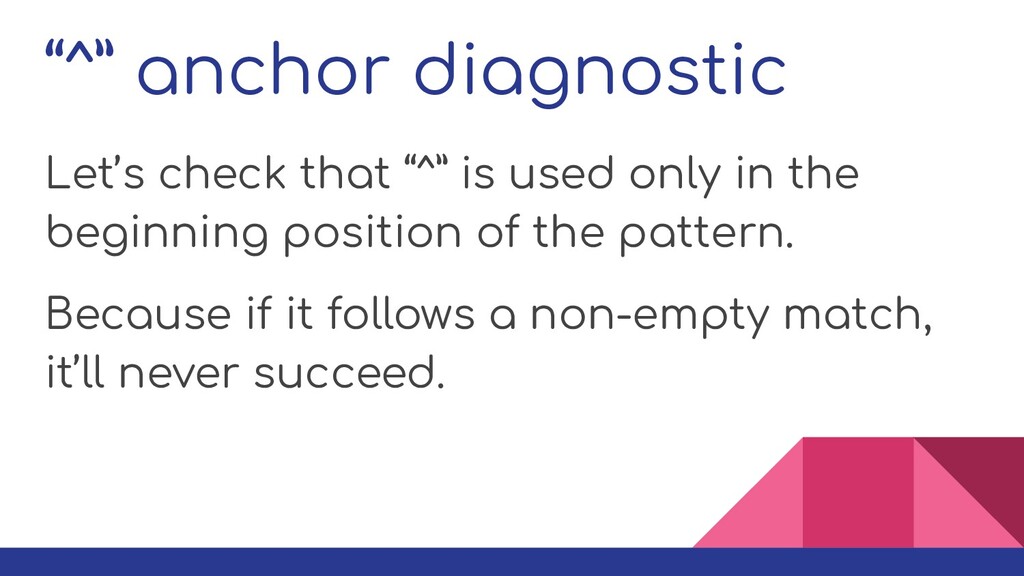
“^” anchor diagnostic Let’s check that “^” is used only
in the beginning position of the pattern. Because if it follows a non-empty match, it’ll never succeed.
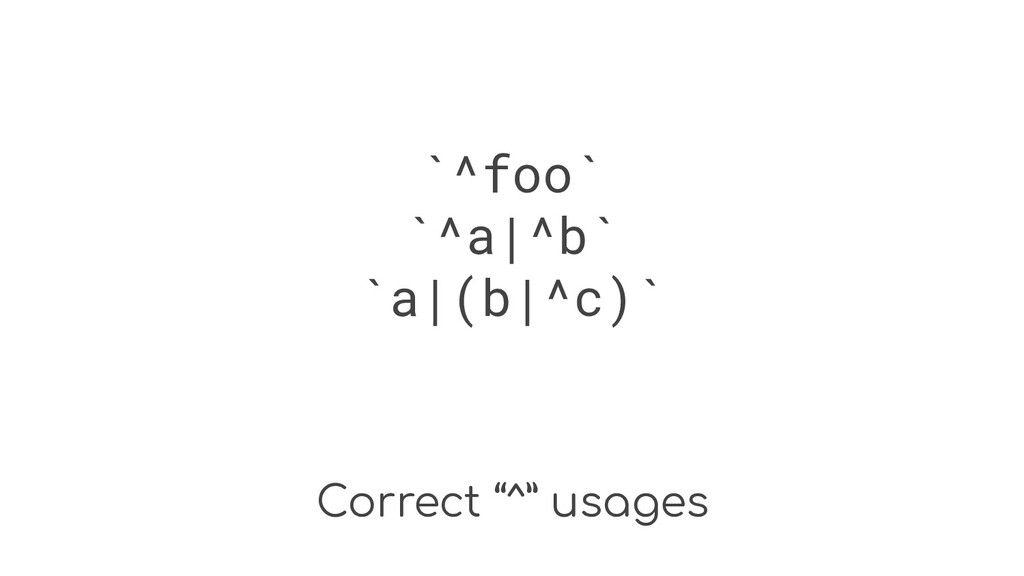
Correct “^” usages `^foo` `^a|^b` `a|(b|^c)`
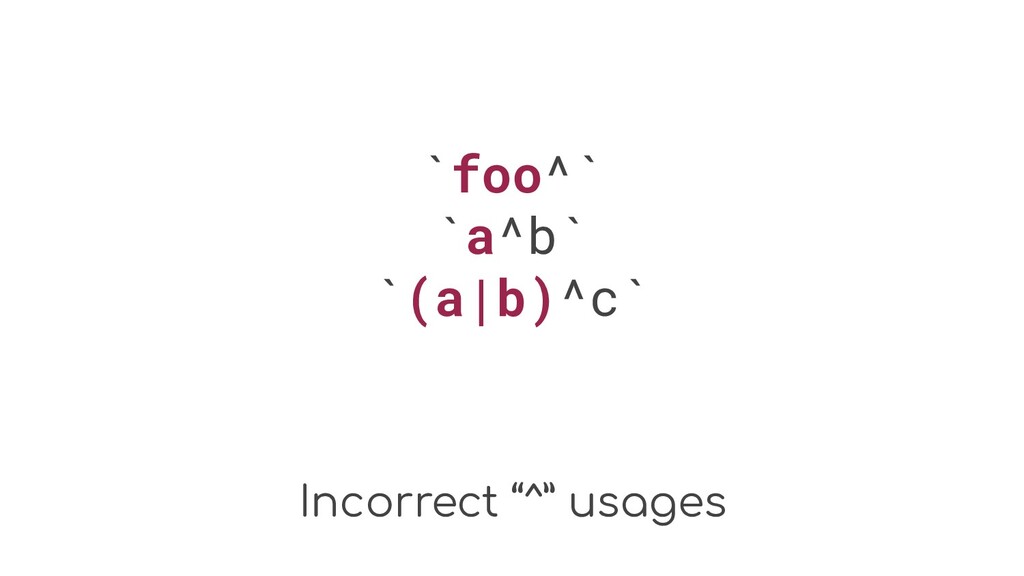
Incorrect “^” usages `foo^` `a^b` `(a|b)^c`
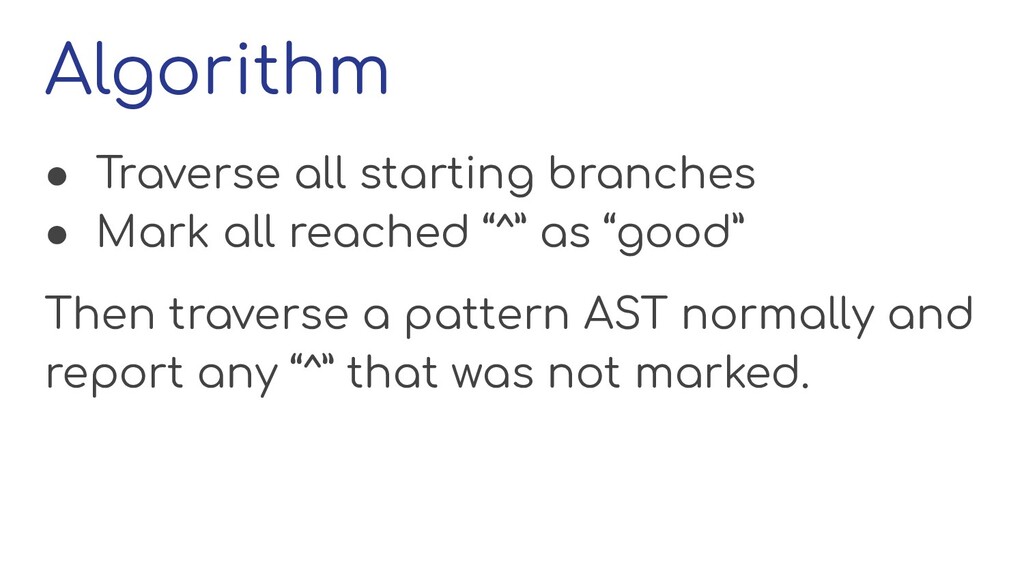
Algorithm • Traverse all starting branches • Mark all reached
“^” as “good” Then traverse a pattern AST normally and report any “^” that was not marked.
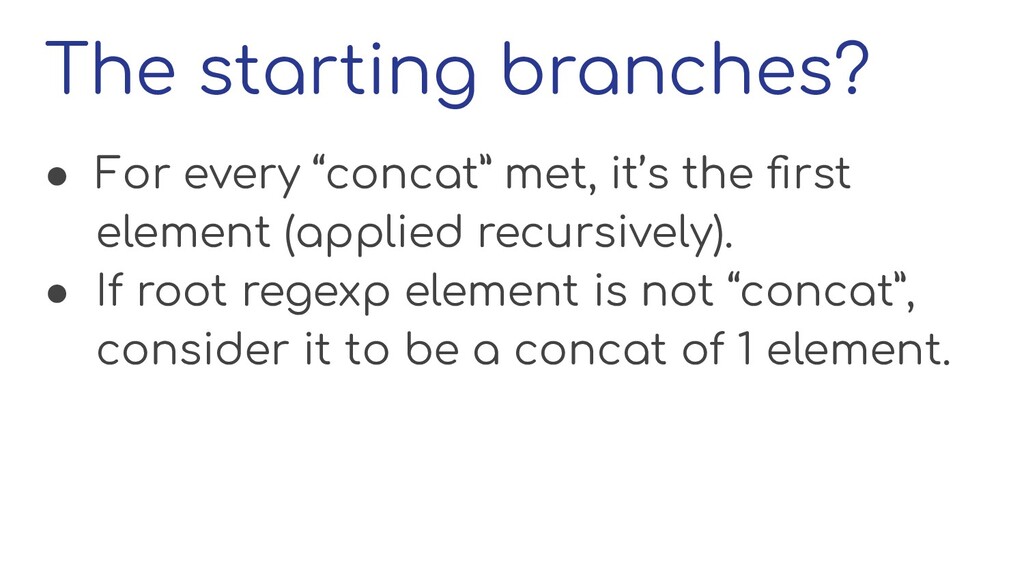
The starting branches? • For every “concat” met, it’s the
first element (applied recursively). • If root regexp element is not “concat”, consider it to be a concat of 1 element.
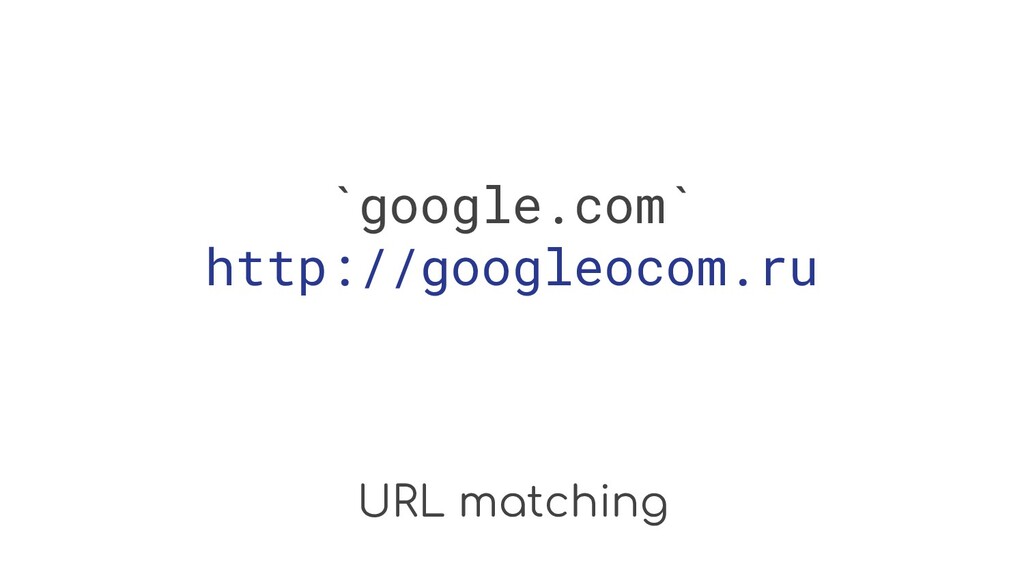
URL matching `google.com`
URL matching `google.com` http://googleocom.ru
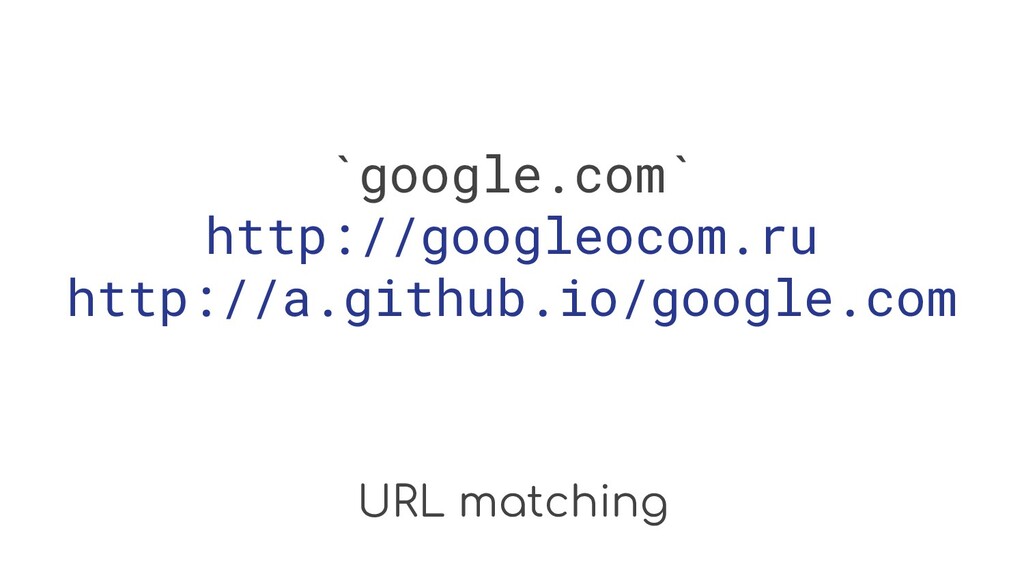
URL matching `google.com` http://googleocom.ru http://a.github.io/google.com
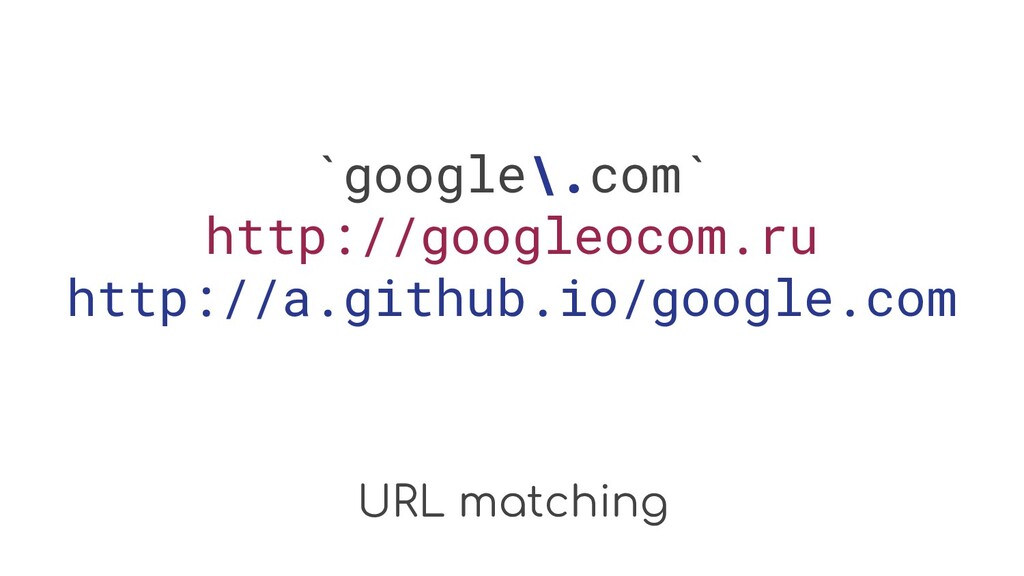
URL matching `google\.com` http://googleocom.ru http://a.github.io/google.com
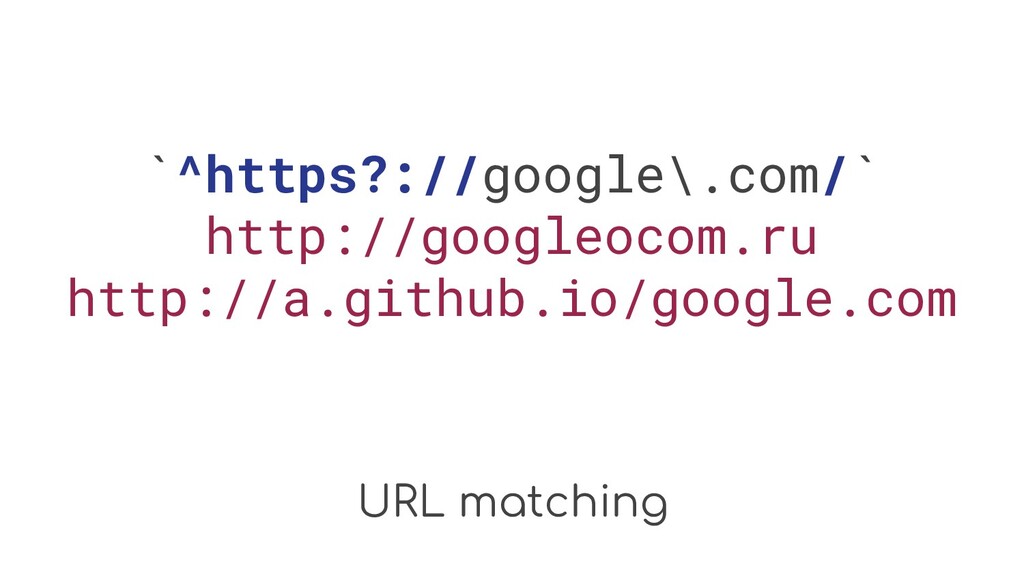
URL matching `^https?://google\.com/` http://googleocom.ru http://a.github.io/google.com
URL matching When “.” is used before common domain name
like “com”, it’s probably a mistake. If we have char sequences represented as a single AST node, this analysis is trivial.
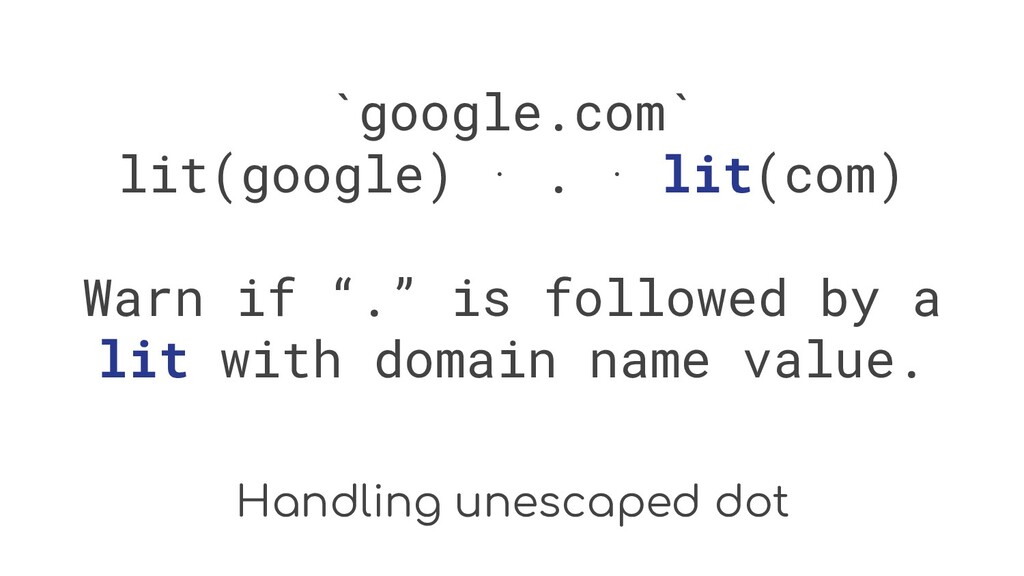
Handling unescaped dot `google.com` lit(google) ⋅ . ⋅ lit(com) Warn
if “.” is followed by a lit with domain name value.
Regexp rewriting
Regexp input generation It’s quite simple to generate a string
that will be matched by a regular expression if you have that regexp AST.
Generating matching string (N=2) `\w*[0-9]?$` *(\w) ⋅ ?([0-9]) ⋅ $
Generating matching string (N=2) `\w*[0-9]?$` *(\w) ⋅ ?([0-9]) ⋅ $
aa N matches of \w
Generating matching string (N=2) `\w*[0-9]?$` *(\w) ⋅ ?([0-9]) ⋅ $
aa7 1 match of [0-9]
Generating matching string (N=2) `\w*[0-9]?$` *(\w) ⋅ ?([0-9]) ⋅ $
aa7 May do nothing for $
Regexp input generation Generating a non-matching strings can be useful
for catastrophic backtracking evaluation.
Regexp simplification Instead of writing a matching characters we can
write the pattern syntax itself. By replacing recognized AST node sequences with something simpler, we can perform a regexp simplification.
Regexp simplification `\dxx*` \d ⋅ x ⋅ *(x)
Regexp simplification `\dxx*` \d ⋅ x ⋅ *(x) \d Can’t
simplify \d, write as is
Regexp simplification `\dxx*` \d ⋅ x ⋅ *(x) \dx+ xx*
-> x+
Oh, the possibilities! x{1,} -> x+ [a-z\d][a-z\d] -> [a-z\d]{2} [^\d]
-> \D a|b|c -> [abc]
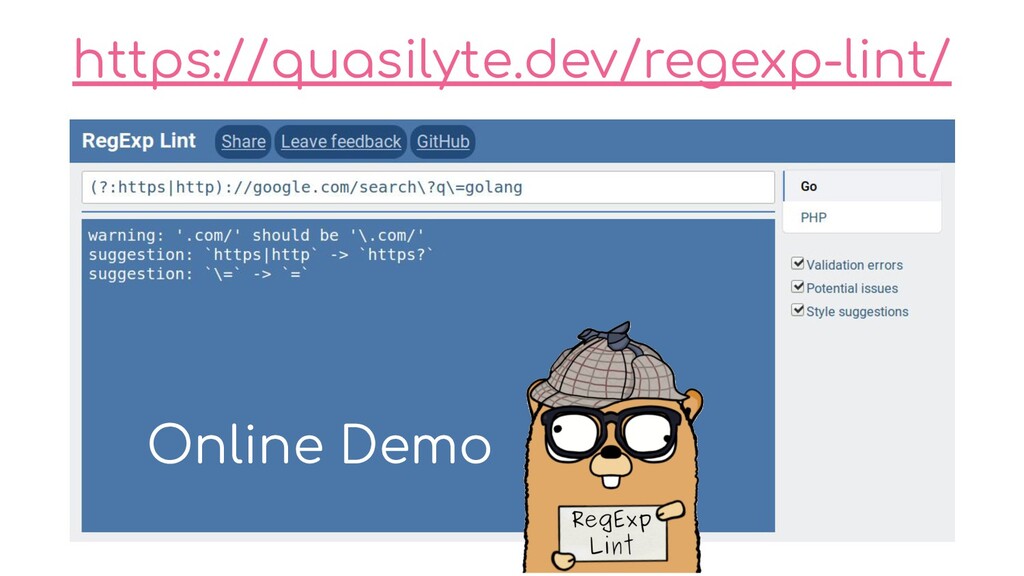
https://quasilyte.dev/regexp-lint/ Online Demo
Submit your ideas! :) If you have a particular regexp
simplification or bug pattern that is not detected by regexp-lint, let me know.
Thank you.


 quasilyte
 po3rin
 kinopeee
 reimaru
 ayumu_yamaguchi
 ssssota
 honmarkhunt
 yuukiw00w
 yosuke_furukawa
 willnet
 oga5
 kenkino
 drumath2237
 davidcarrasco
 irinanazarova
 chriscoyier
 sabderemane
 mayunak
 danielanewman
 inesmontani
 vanstee
 watany
 ryanjones
 morganepeng


![Char classes syntax `[][]` A char class of “]” and](https://files.speakerdeck.com/presentations/80b2d4f016f84985a2e4aff96dbbccbd/slide_12.jpg)