Share
Embed
Legal Document Processing with AI and AWS Project Lakechain
Build Serverless, Modular, and Scalable document processing pipelines on AWS using Infrastructure as Code! 🚀
Aletheia
January 16, 2025
Transcript
22 slides
-
Build Serverless, Modular, and Scalable document processing pipelines on AWS
using Infrastructure as Code! 🚀 Project LakeChain -
Luca Bianchi, PhD Who am I? CTO, AI Expert, proud
d a d, a nd AWS Serverless Hero, p a ssion a te a bout softw a re a rchitectures, serverless, a nd m a chine le a rning. Serverless It a ly, [Gen]AI It a ly, a nd MMUG Meetup co-founder. ServerlessD a ys Mil a no a nd AWS Community D a y co-org a nizer. Big Daddy Little Elisa github.com/aletheia https://it.linkedin.com/in/lucabianchipavia https://speakerdeck.com/aletheia bianchiluca.com @bianchiluca -
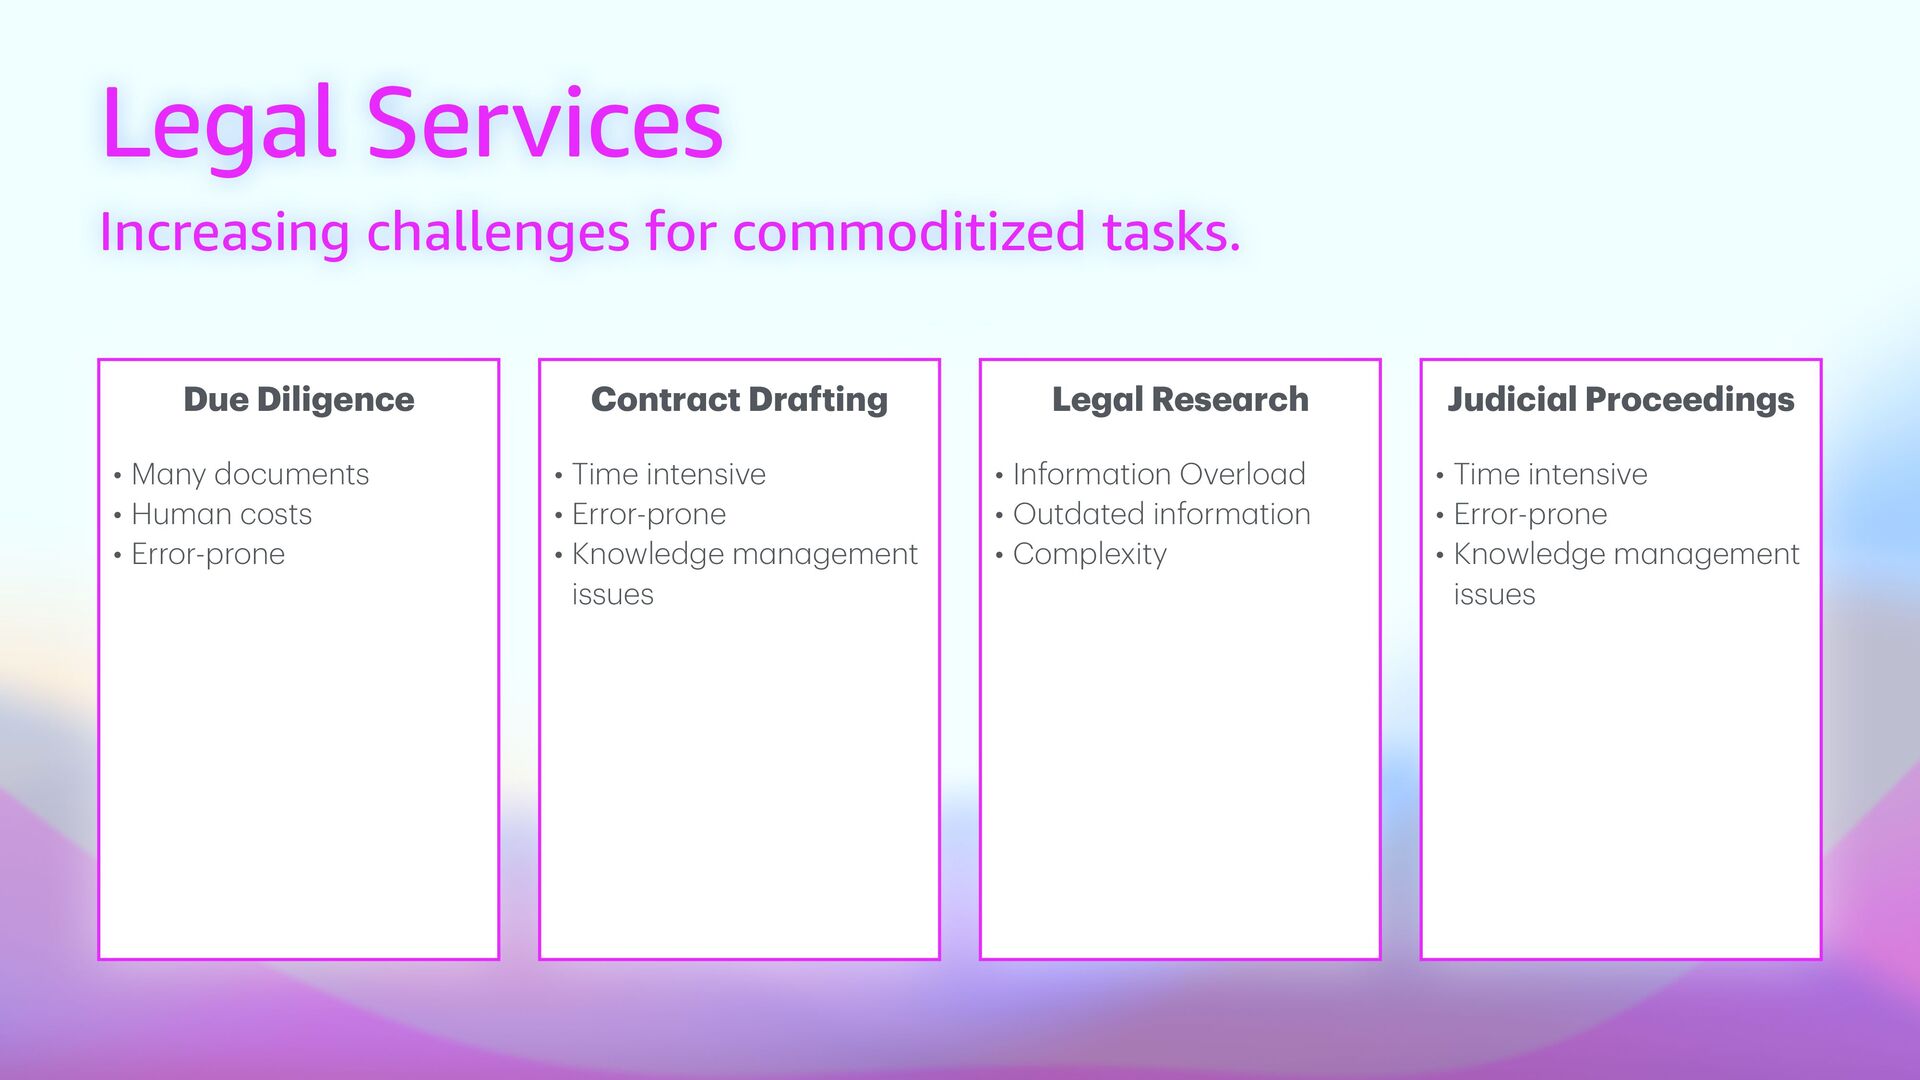
Increasing challenges for commoditized tasks. Legal Services Due Diligence •
M a ny documents • Hum a n costs • Error-prone Contr a ct Dr a fting • Time intensive • Error-prone • Knowledge m a n a gement issues Leg a l Rese a rch • Inform a tion Overlo a d • Outd a ted inform a tion • Complexity Judici a l Proceedings • Time intensive • Error-prone • Knowledge m a n a gement issues -
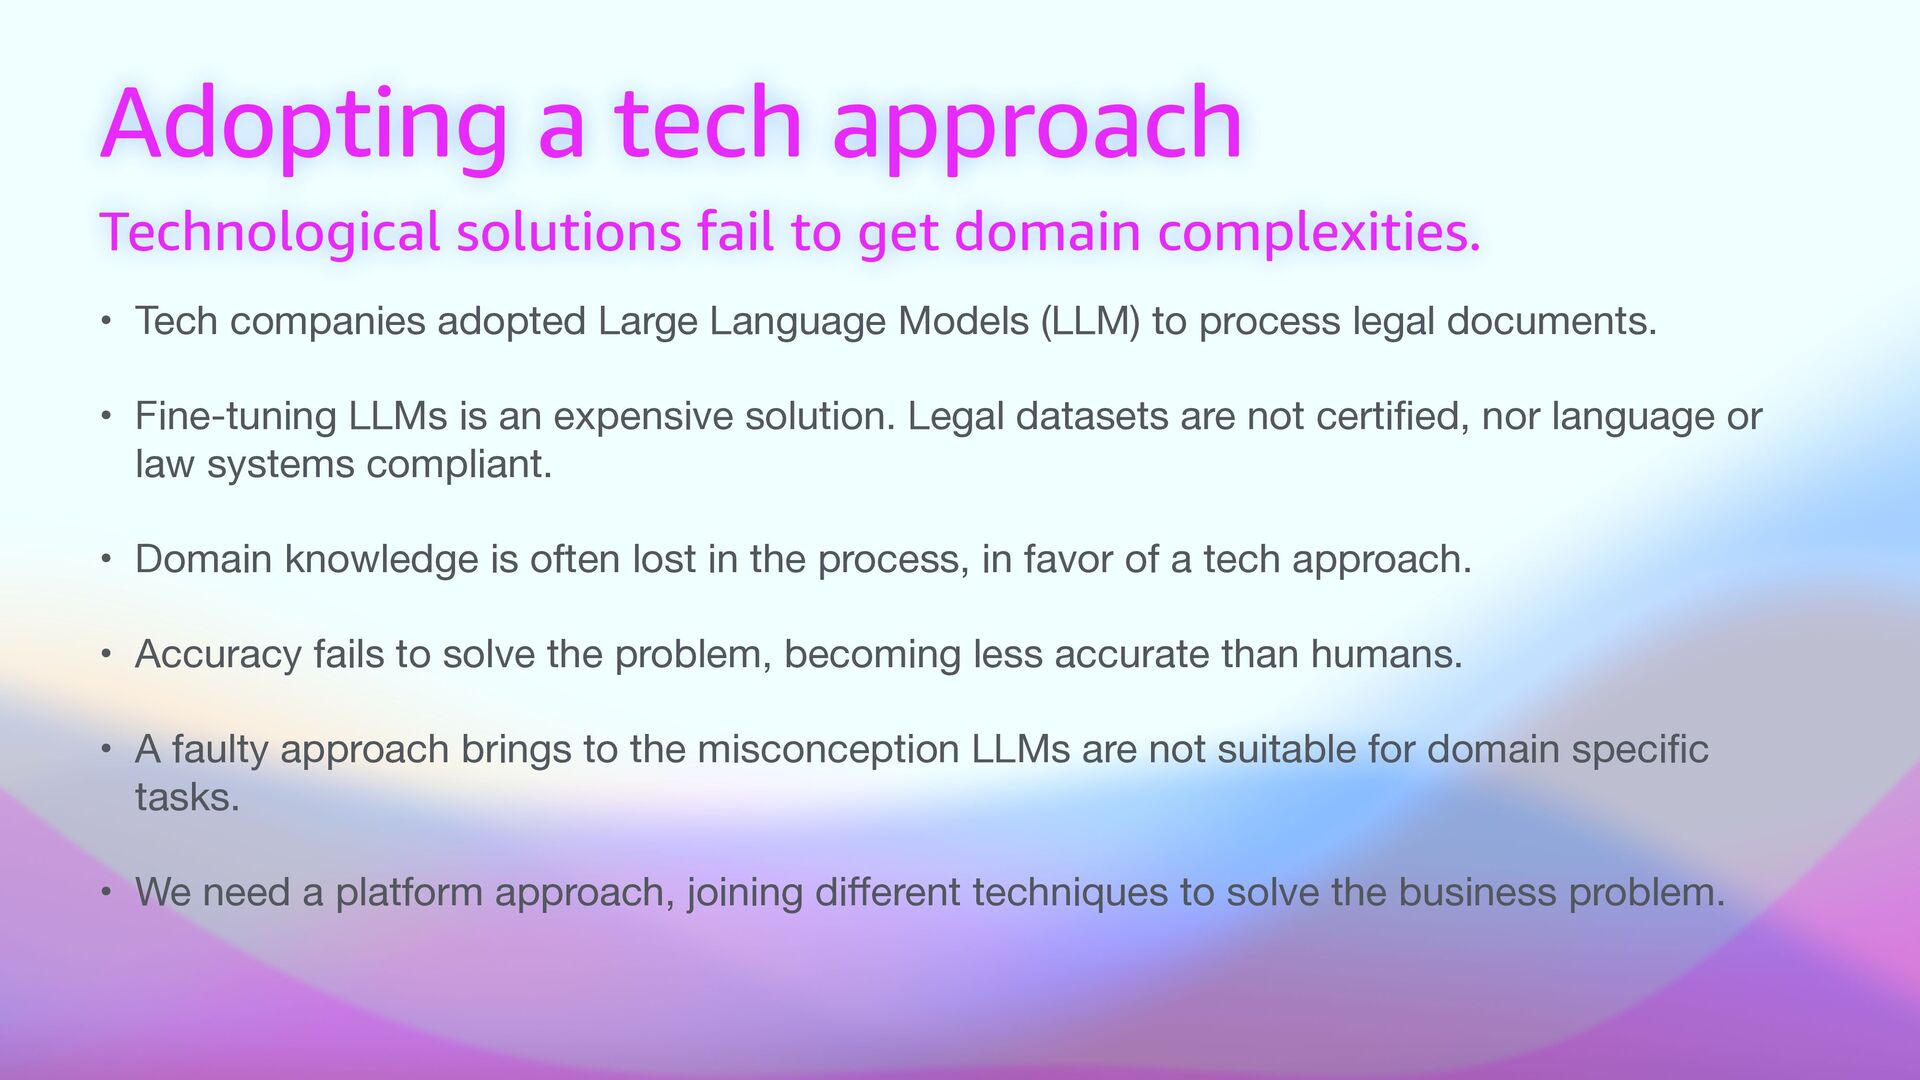
Technological solutions fail to get domain complexities. Adopting a tech
approach • Tech companies adopted Large Language Models (LLM) to process legal documents. • Fine-tuning LLMs is an expensive solution. Legal datasets are not certi fi ed, nor language or law systems compliant. • Domain knowledge is often lost in the process, in favor of a tech approach. • Accuracy fails to solve the problem, becoming less accurate than humans. • A faulty approach brings to the misconception LLMs are not suitable for domain speci fi c tasks. • We need a platform approach, joining di ff erent techniques to solve the business problem. -
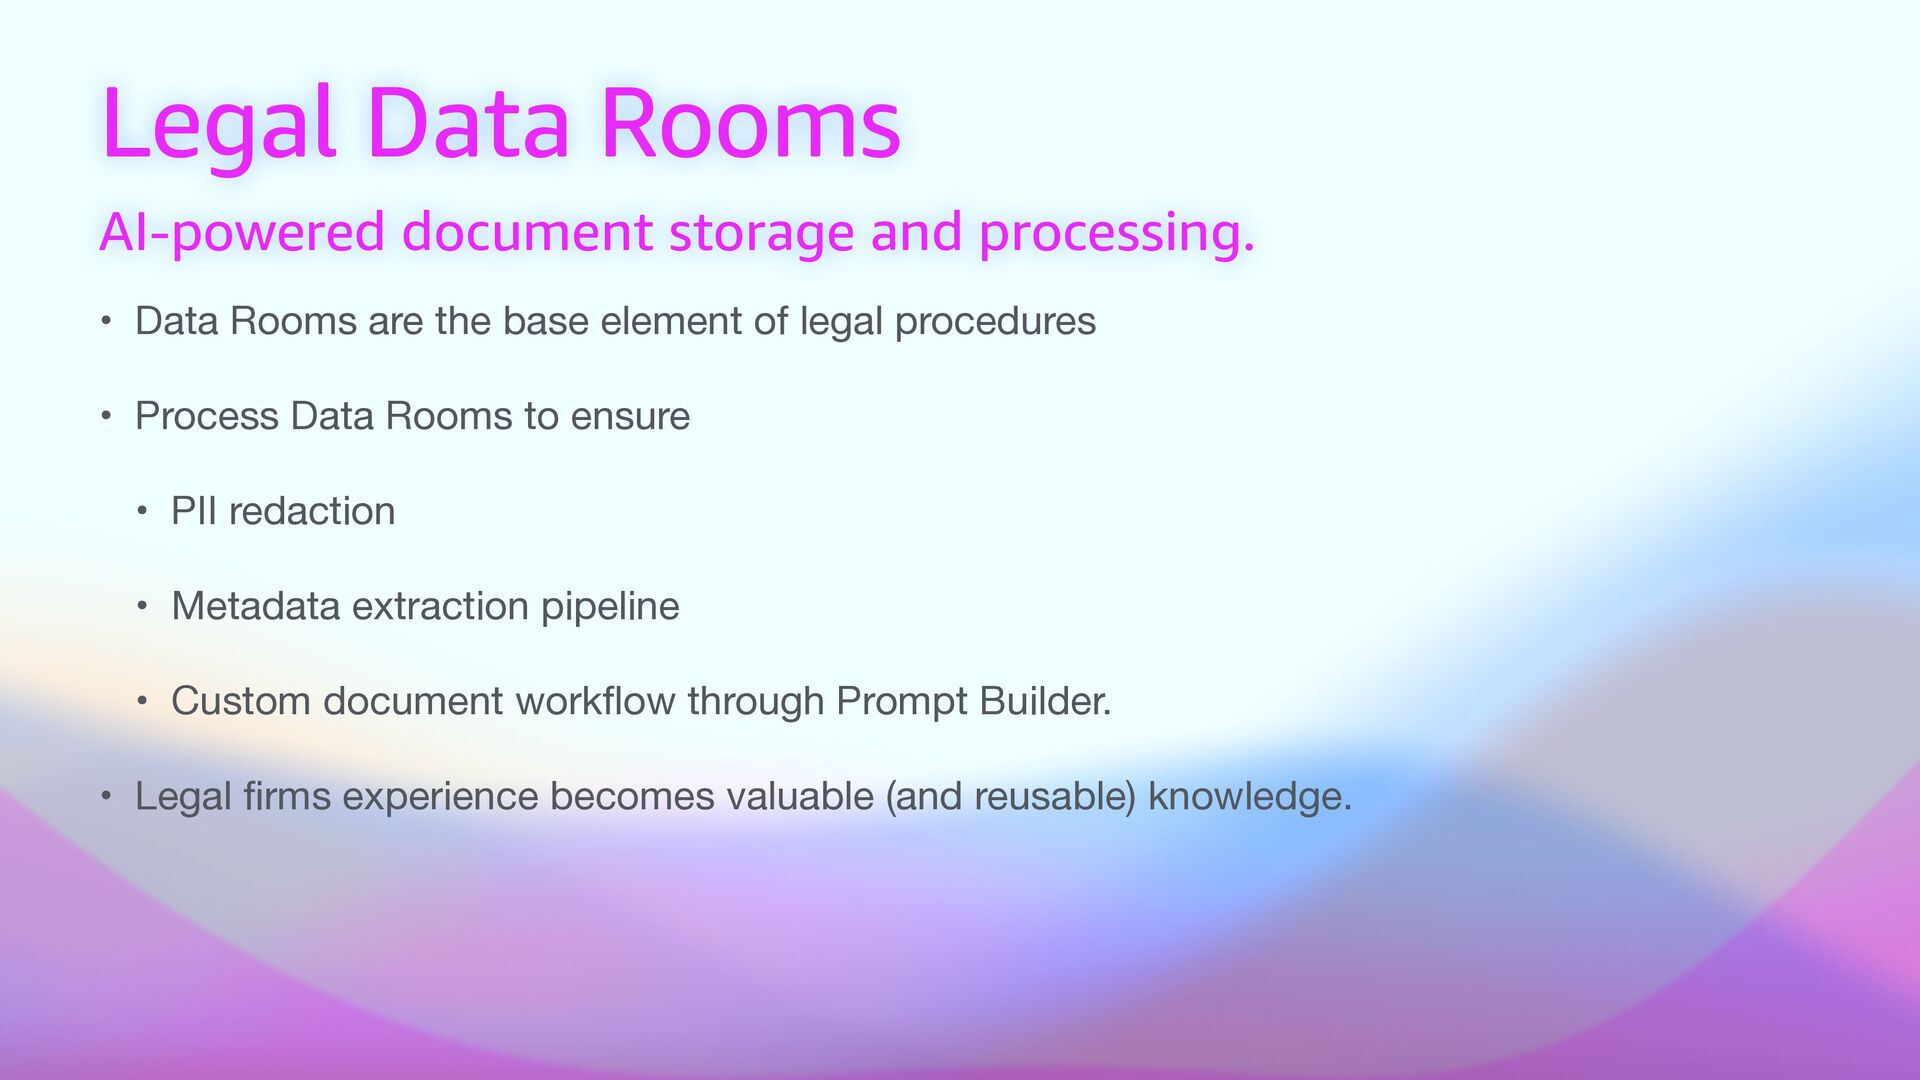
AI-powered document storage and processing. Legal Data Rooms • Data
Rooms are the base element of legal procedures • Process Data Rooms to ensure • PII redaction • Metadata extraction pipeline • Custom document work fl ow through Prompt Builder. • Legal fi rms experience becomes valuable (and reusable) knowledge. -
Pipelines • Straightforward data processing through pre-de fi ned steps
• Can be attached to speci fi c document types • Document-based processing • Reusable data extraction procedures • Easy to operationalize, hard to maintain • Many moving parts • LLM Ops are not easy -
Unlock the Potential of Unstructured Data with AWS AWS LakeChain
• A framework based on the AWS Cloud Development Kit (CDK) • allows the expression and deployment of scalable document processing pipelines on AWS using infrastructure-as-code. • Modularity • Extensibility (through plugins) • Re-usable components • Addressing many use cases • It is not bounded to generative AI use cases -
Features AWS LakeChain • 🤖 Composable — Composable API to
express document processing pipelines using middlewares. • ☁ Scalable — Scales out-of-the box. Process millions of documents and scale to zero automatically when done. • ⚡ Cost E ff i cient — Uses cost-optimized architectures to reduce costs and drive a pay-as-you-go model. • 🚀 Ready to use — 60+ built-in middlewares for document processing tasks, ready to be deployed. • 🦎 GPU and CPU Support — Use the right compute type to balance performance and cost. • 📦 Bring Your Own — Create your transform middlewares to process documents and extend Lakechain. • 📙 Ready Made Examples -
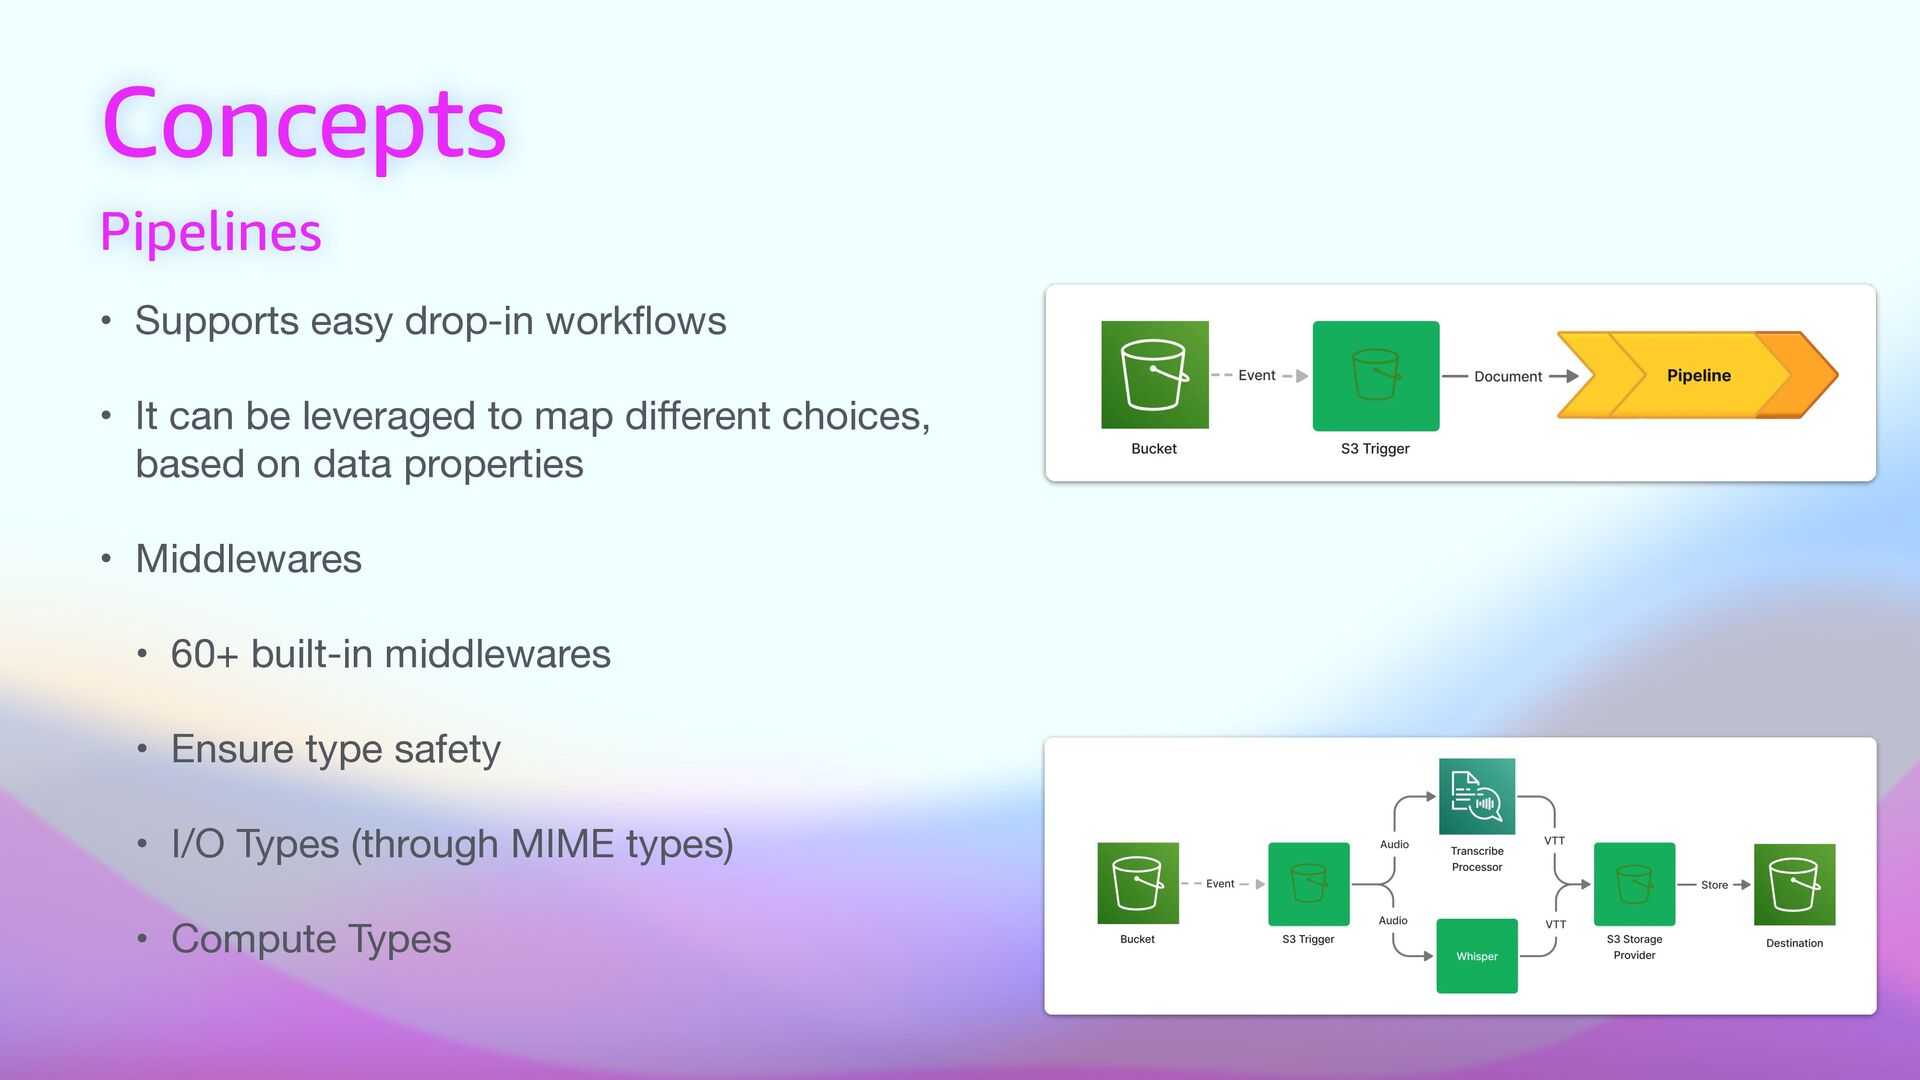
• Supports easy drop-in work fl ows • It can
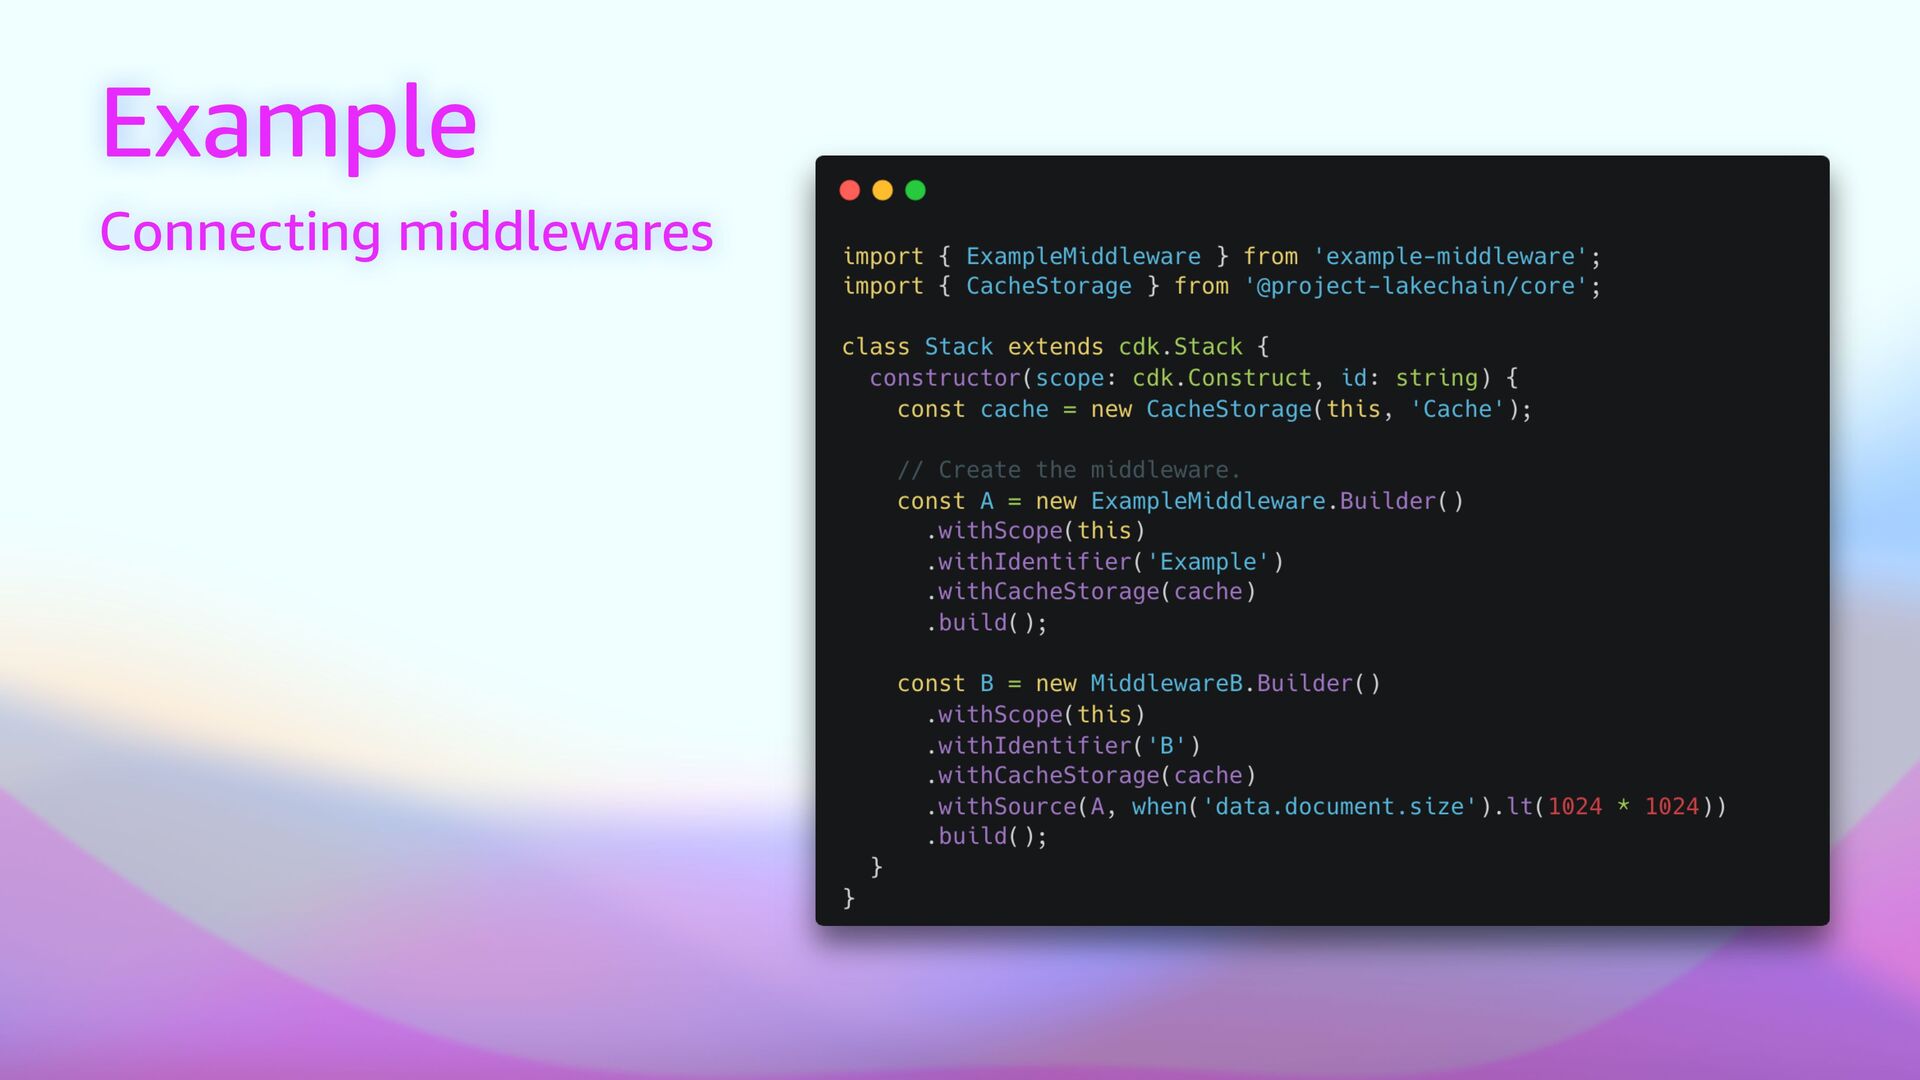
be leveraged to map di ff erent choices, based on data properties • Middlewares • 60+ built-in middlewares • Ensure type safety • I/O Types (through MIME types) • Compute Types Pipelines Concepts -
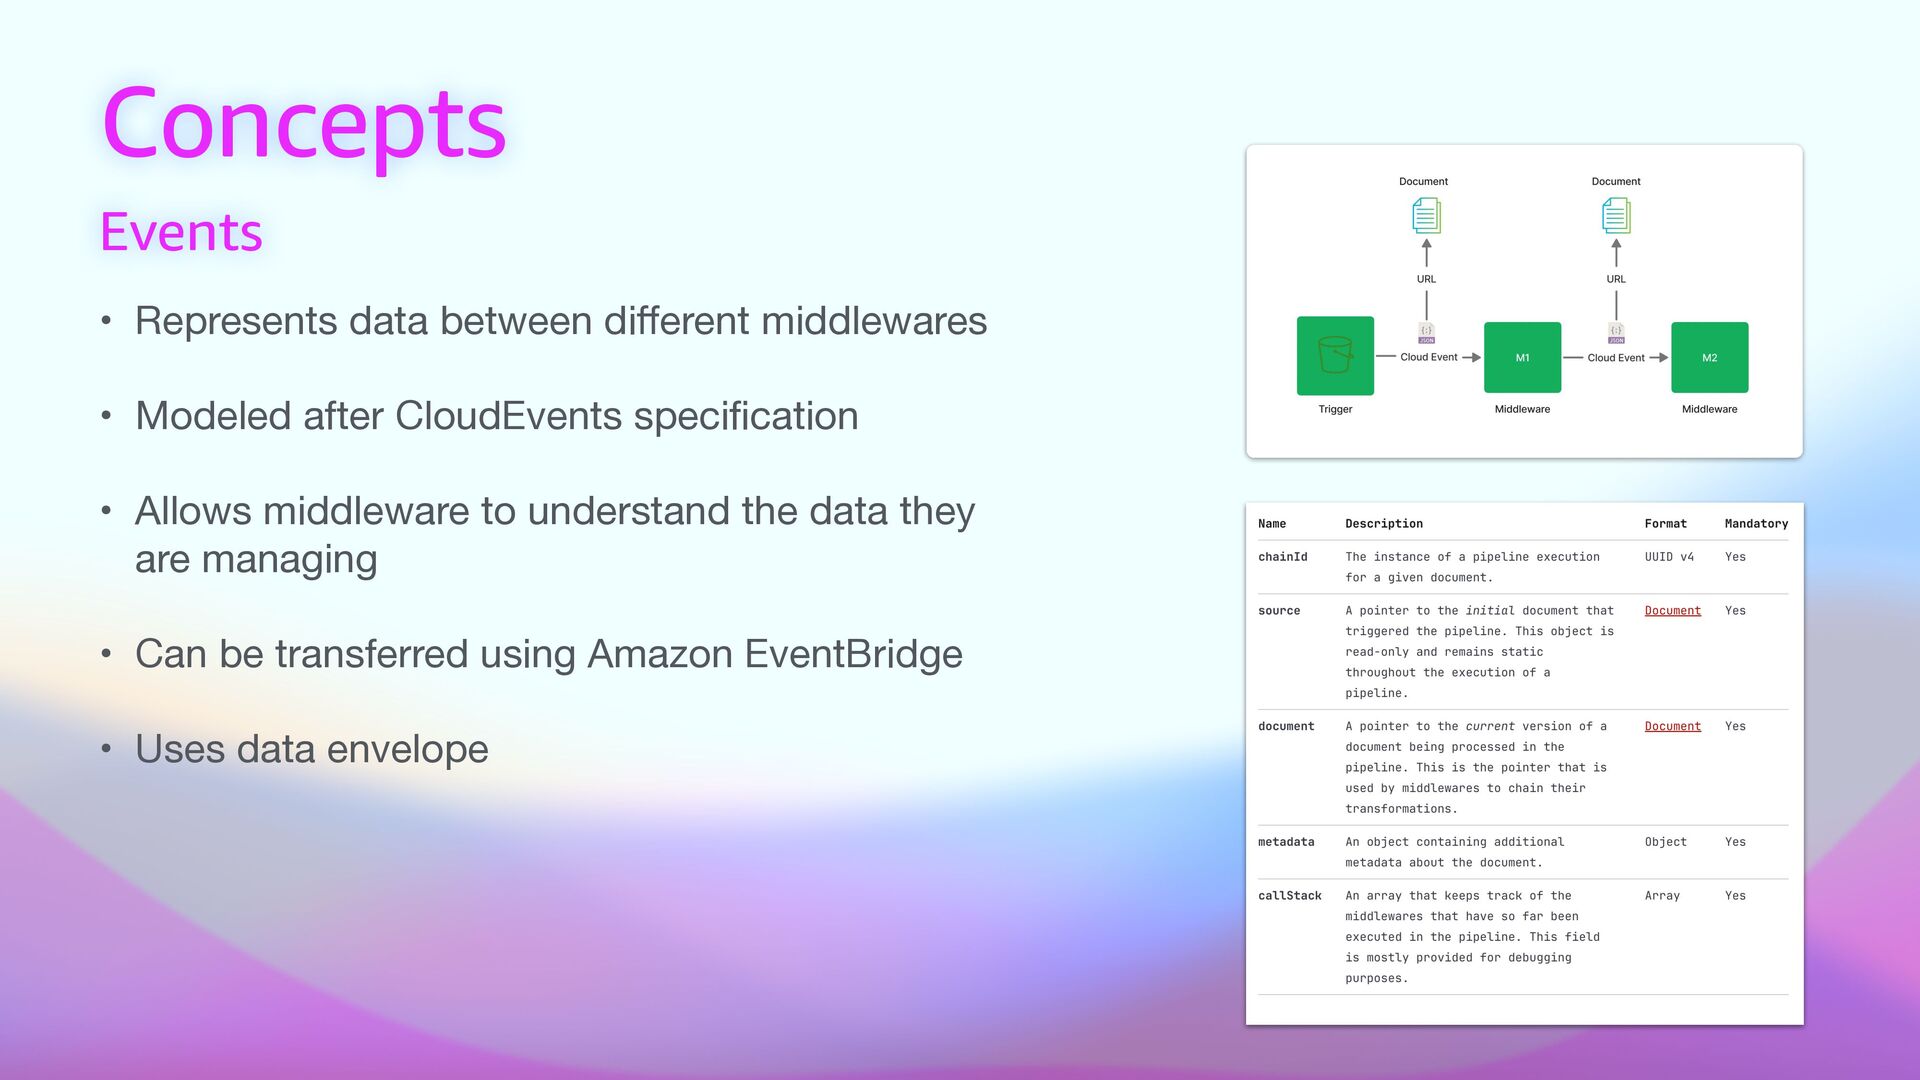
• Represents data between di ff erent middlewares • Modeled
after CloudEvents speci fi cation • Allows middleware to understand the data they are managing • Can be transferred using Amazon EventBridge • Uses data envelope Events Concepts -
Architecture • Messaging (built with AWS SQS and AWS SNS)
• Scalability • Integration (through AWS SDK) • Error Handling (and DLQ) • Patterns • Fan-in/Fan-out • Filtering / throttling • Batch processing -
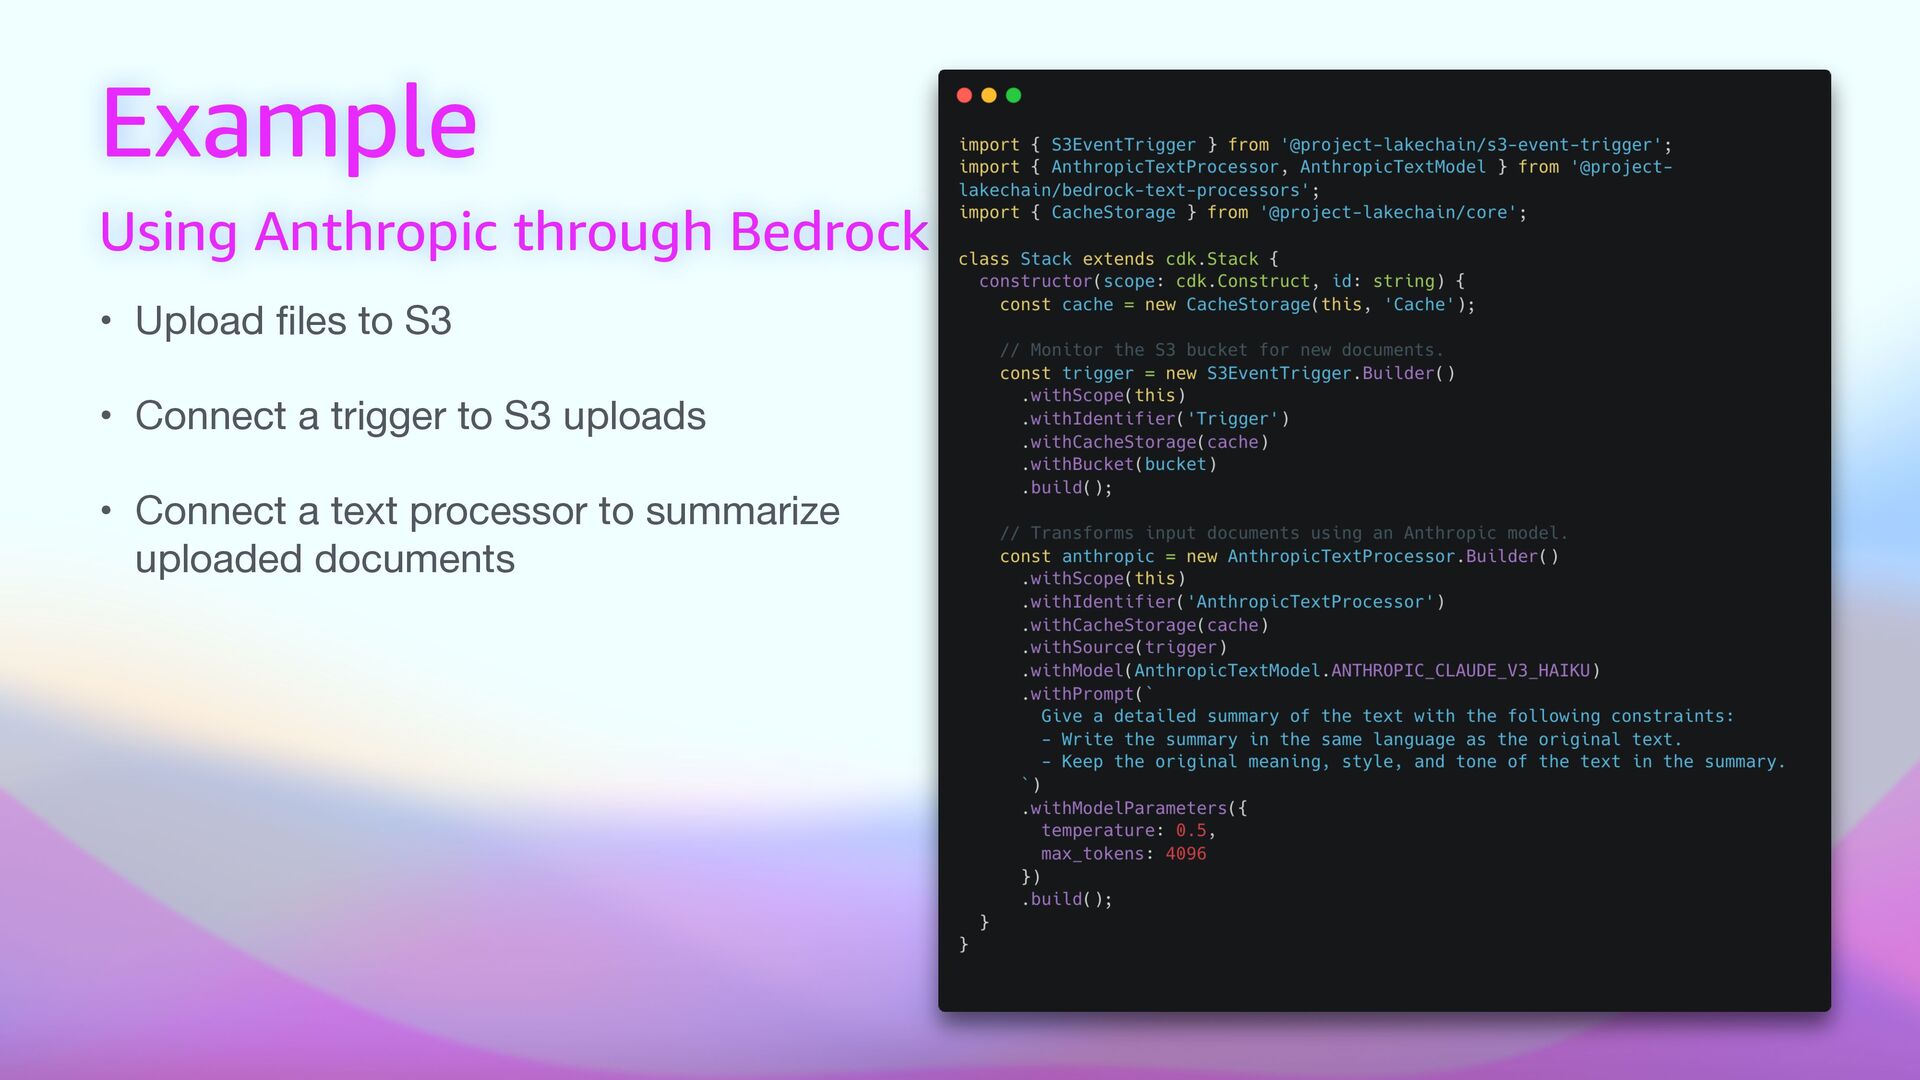
Using Anthropic through Bedrock Example • Upload fi les to
S3 • Connect a trigger to S3 uploads • Connect a text processor to summarize uploaded documents -
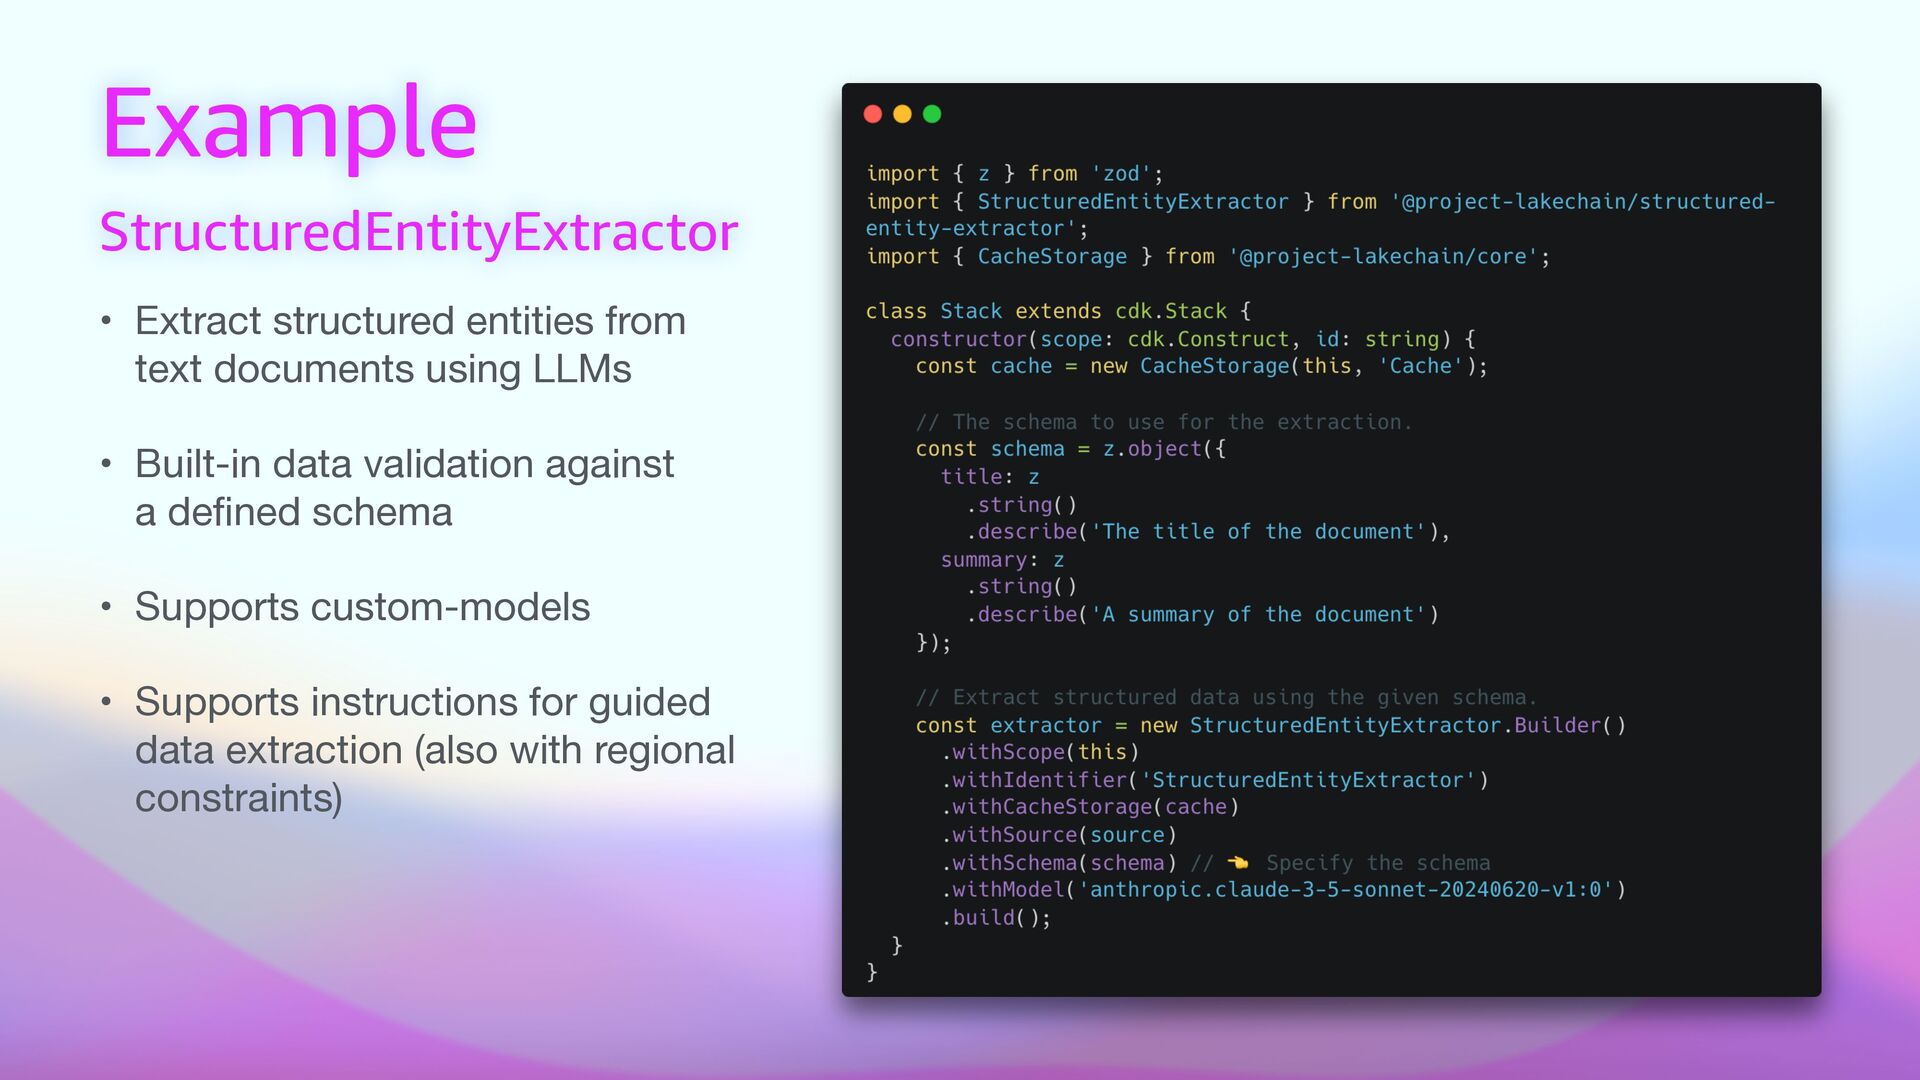
StructuredEntityExtractor Example • Extract structured entities from text documents
using LLMs • Built-in data validation against a de fi ned schema • Supports custom-models • Supports instructions for guided data extraction (also with regional constraints) -
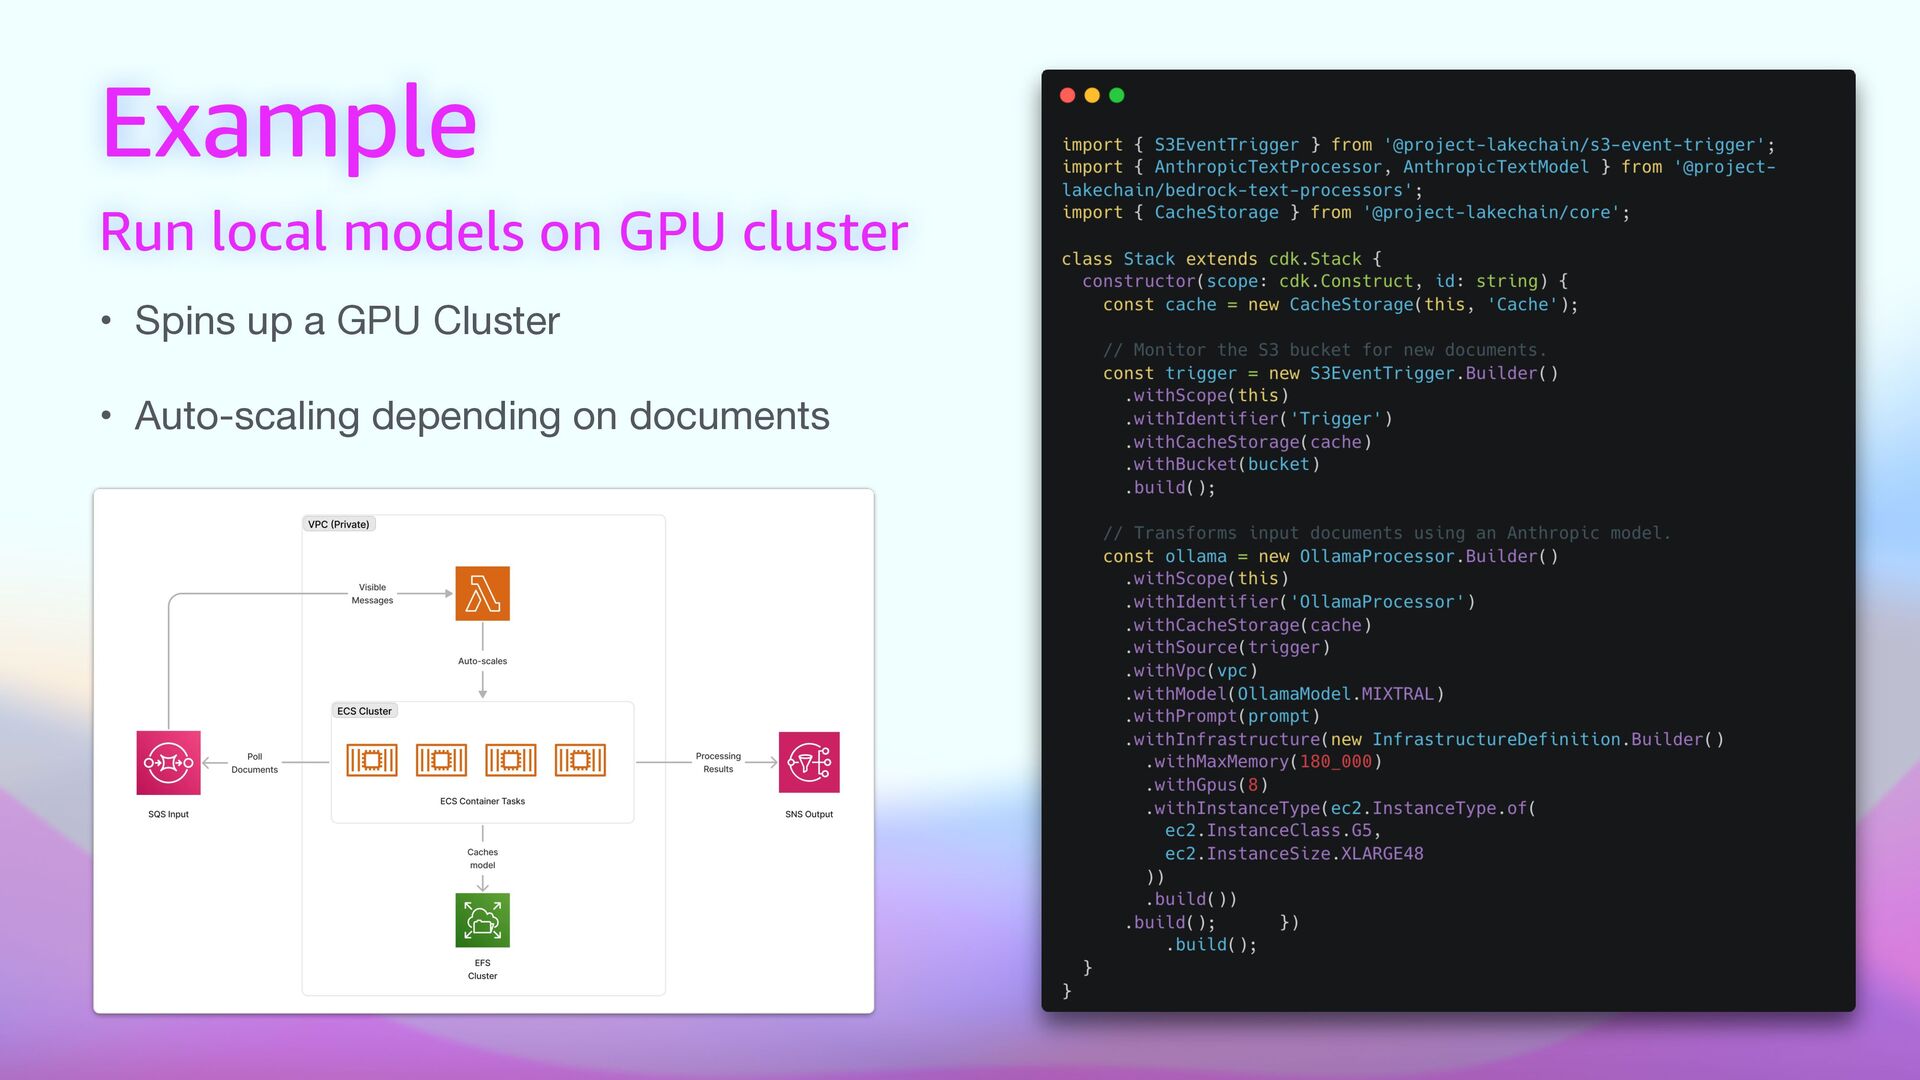
Run local models on GPU cluster Example • Spins up
a GPU Cluster • Auto-scaling depending on documents -
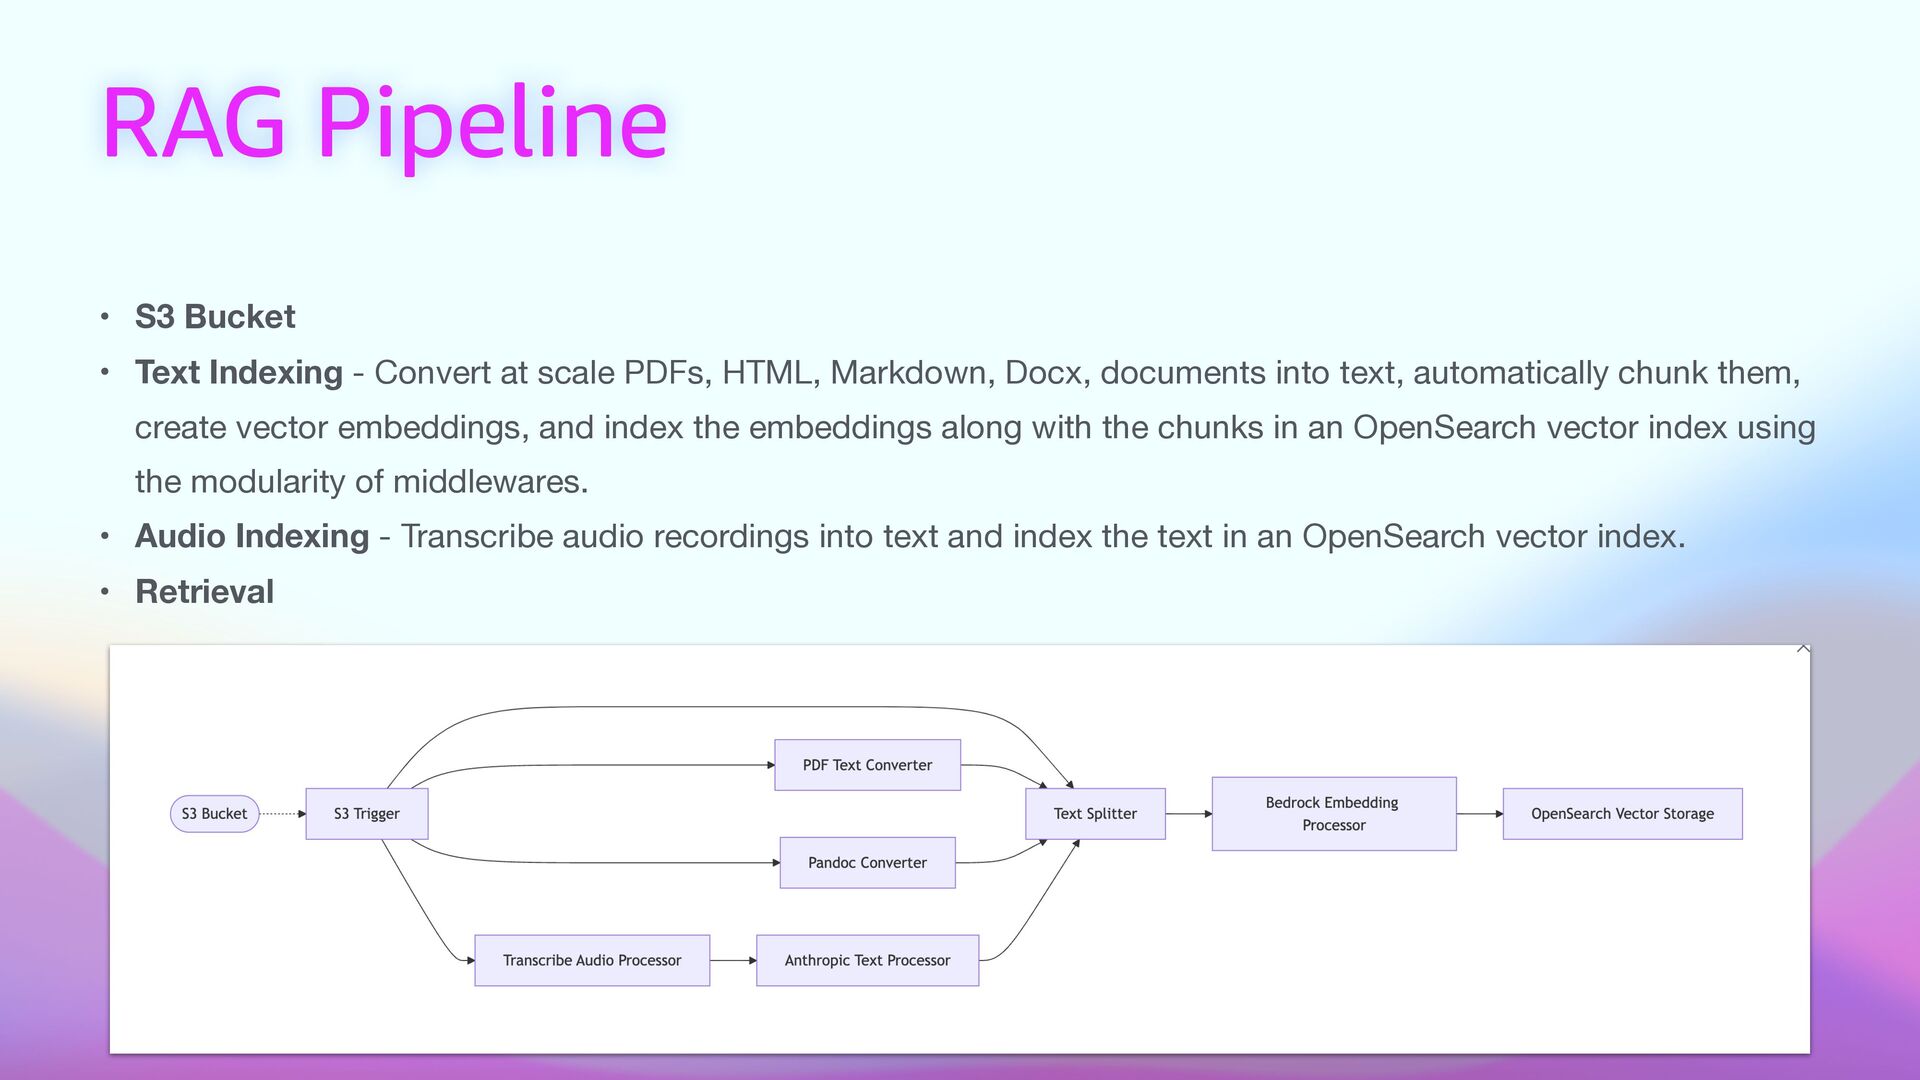
RAG Pipeline • S3 Bucket • Text Indexing - Convert
at scale PDFs, HTML, Markdown, Docx, documents into text, automatically chunk them, create vector embeddings, and index the embeddings along with the chunks in an OpenSearch vector index using the modularity of middlewares. • Audio Indexing - Transcribe audio recordings into text and index the text in an OpenSearch vector index. • Retrieval -
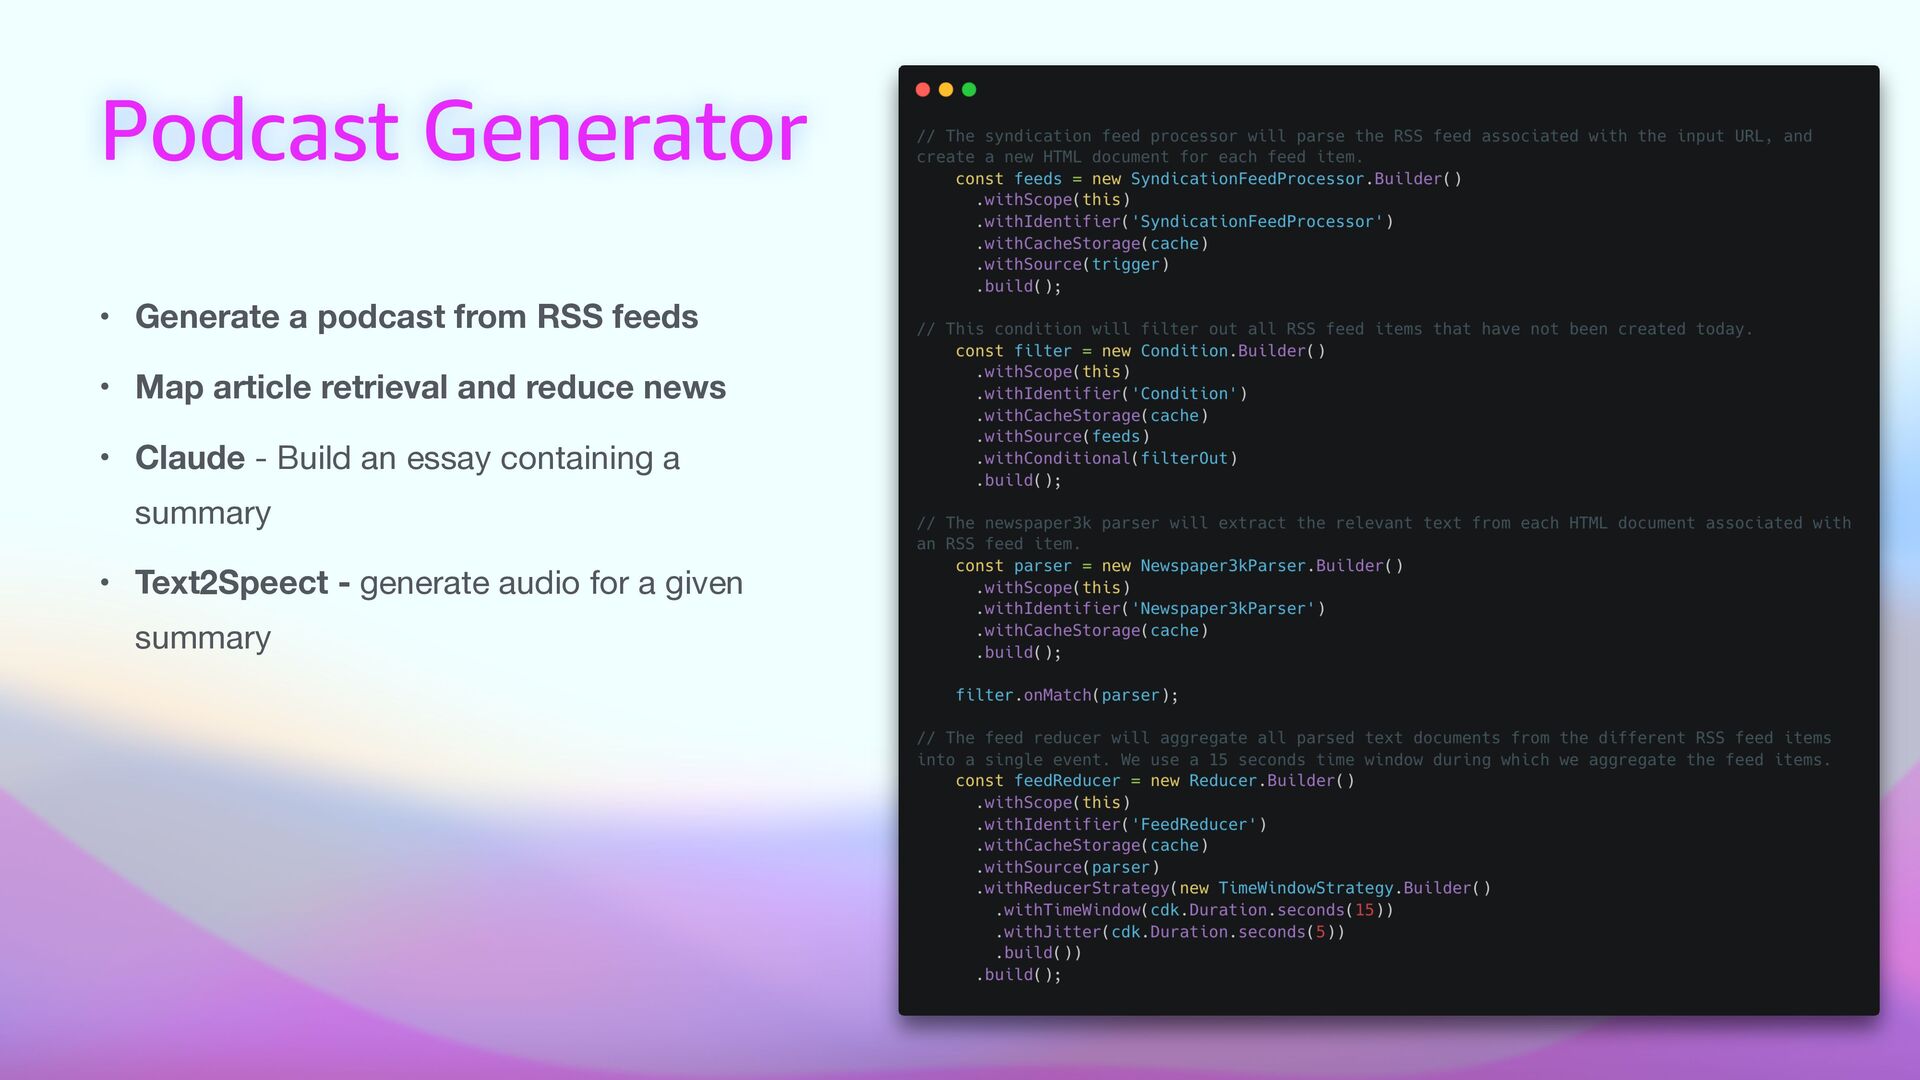
Podcast Generator • Generate a podcast from RSS feeds •
Map article retrieval and reduce news • Claude - Build an essay containing a summary • Text2Speect - generate audio for a given summary -
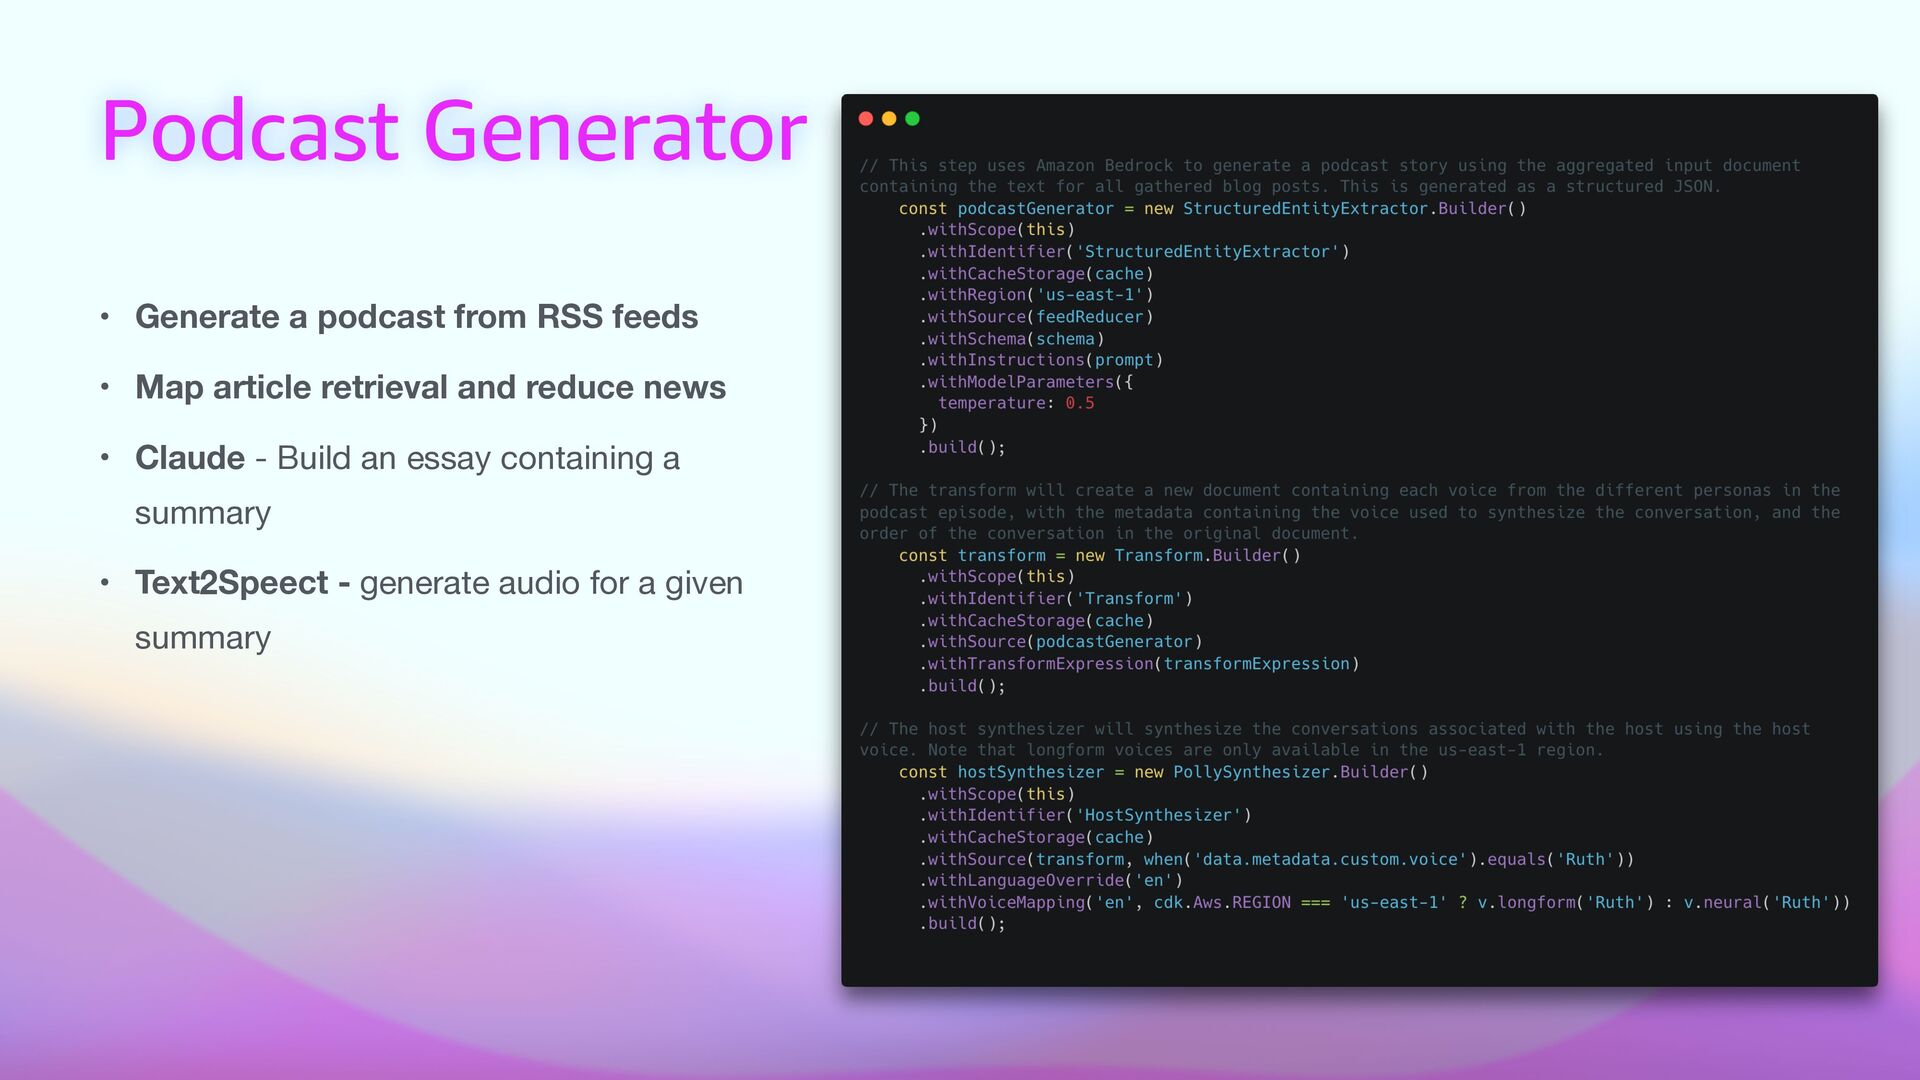
Podcast Generator • Generate a podcast from RSS feeds •
Map article retrieval and reduce news • Claude - Build an essay containing a summary • Text2Speect - generate audio for a given summary -
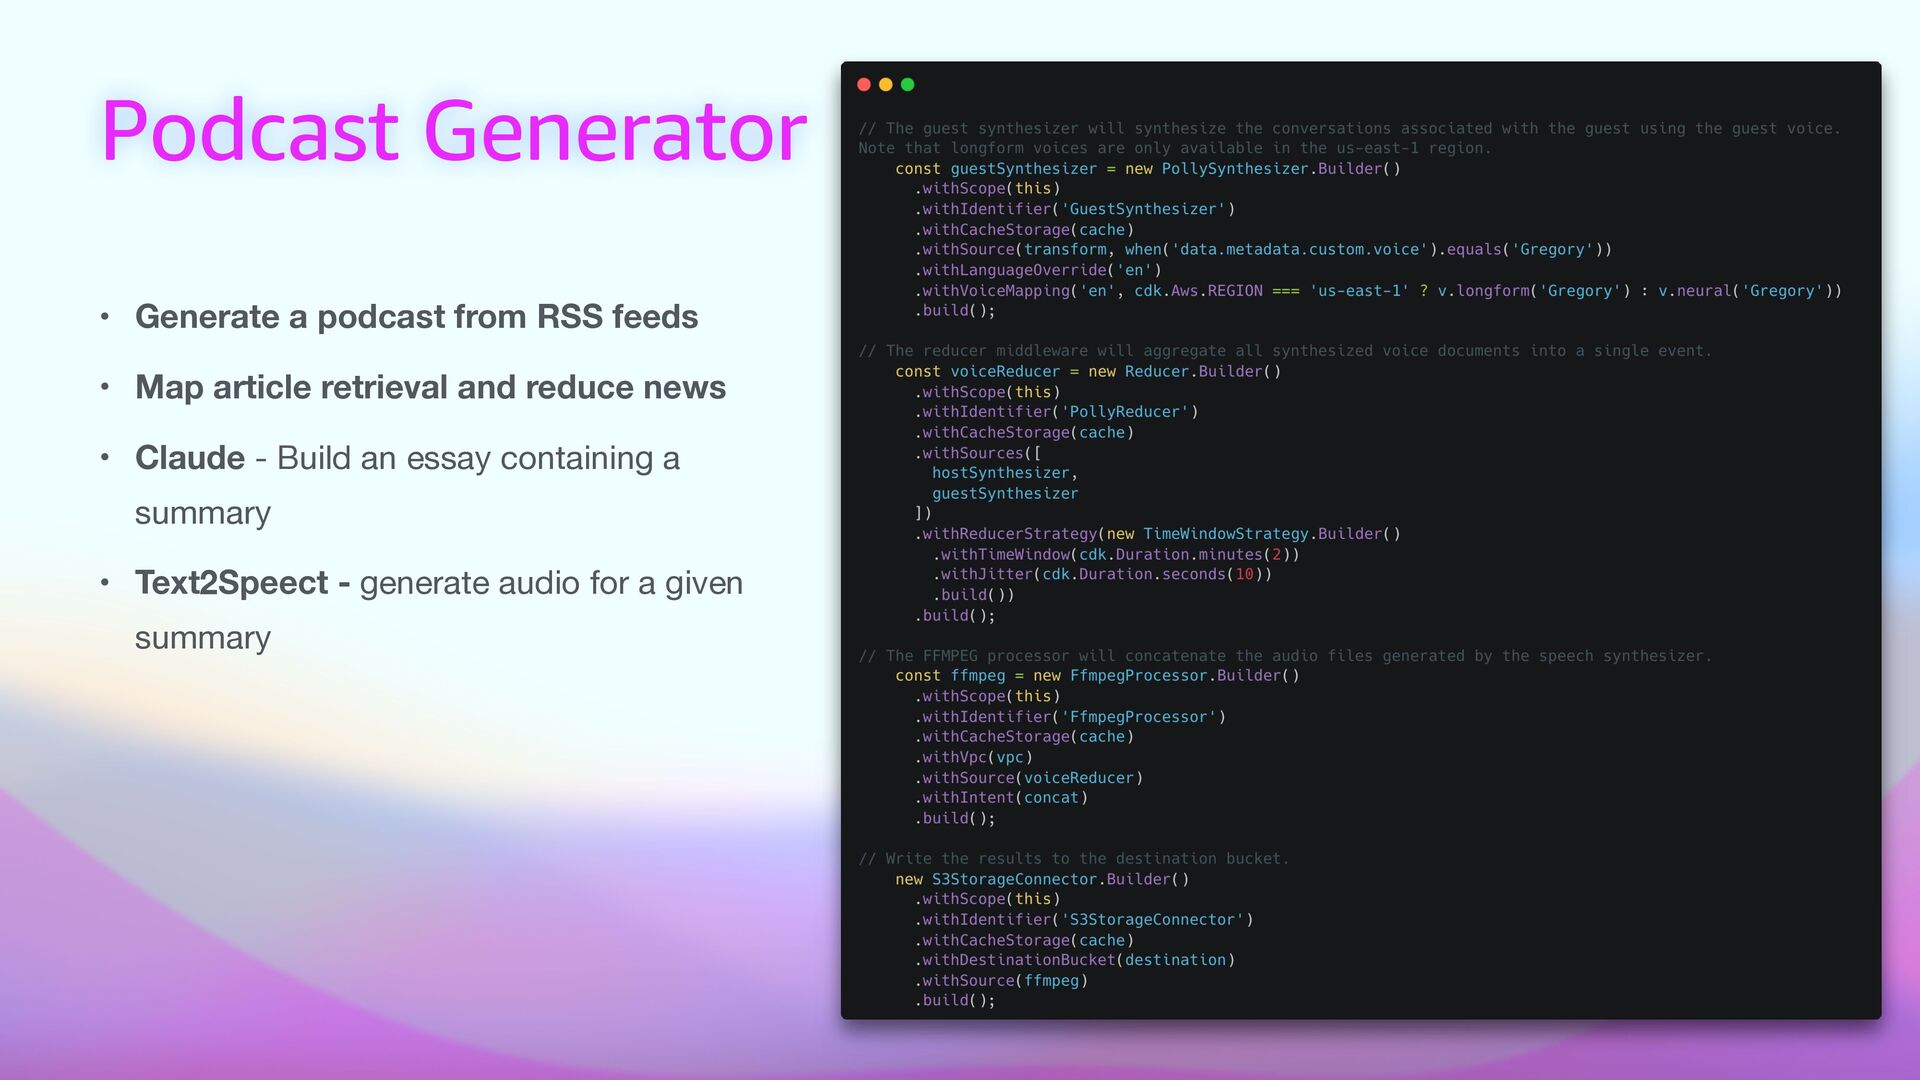
Podcast Generator • Generate a podcast from RSS feeds •
Map article retrieval and reduce news • Claude - Build an essay containing a summary • Text2Speect - generate audio for a given summary -
Podcast Generator • Generate a podcast from RSS feeds •
Map article retrieval and reduce news • Claude - Build an essay containing a summary • Text2Speect - generate audio for a given summary