Share
Embed
The Analytic Platform behind IBM’s Watson Data Platform by Luciano Resende at Big Data Spain 2017
IBM has built a “Data Science Experience” cloud service that exposes Notebook services at web scale.
https://www.bigdataspain.org/2017/talk/the-analytic-platform-behind-ibms-watson-data-platform
Big Data Spain 2017
November 16th - 17th Kinépolis Madrid
Big Data Spain
December 04, 2017
Transcript
24 slides
-
IBMSpark Technology Center Big Data Spain – Nov 2017 The
Analytic Platform behind IBM’s Watson Data Platform Luciano Resende IBM | Spark Technology Center -
2 Data Science Platform Architect – IBM – Spark Technology
Center • Have been contributing to open source at ASF for over 10 years • Currently contributing to : Jupyter Notebook ecosystem, Apache Bahir, Apache Spark, Apache Toree among other projects related to Apache Spark ecosystem [email protected] http://lresende.blogspot.com/ https://www.linkedin.com/in/lrese nde @lresende1975 https://github.com/lresende @ About me - Luciano Resende -
IBMSpark Technology Center IBM Spark Technology Center Founded in 2015.
Location: Physical: 505 Howard St., San Francisco CA Web: http://spark.tc Twitter: @apachespark_tc Mission: Contribute intellectual and technical capital to the Apache Spark community. Make the core technology enterprise- and cloud-ready. Build data science skills to drive intelligence into business applications — http://bigdatauniversity.com Key statistics: About 40 developers, co-located with 25 IBM designers. Major contributions to Apache Spark http://jiras.spark.tc Apache SystemML is now a top level Apache project ! Founding member of UC Berkeley AMPLab and RISE Lab Member of R Consortium and Scala Center 3 -
IBMSpark Technology Center Agenda IBM Data Science Experience IBM Analytics
Engine Challenges faced building Analytic Platform Jupyter Enterprise Gateway 4 -
IBMSpark Technology Center IBM Data Science Experience is an environment
that brings together everything that a Data Scientist needs to be more productive, including tools, data and content Be a better data scientist IBM Data Science Experience (DSX) -
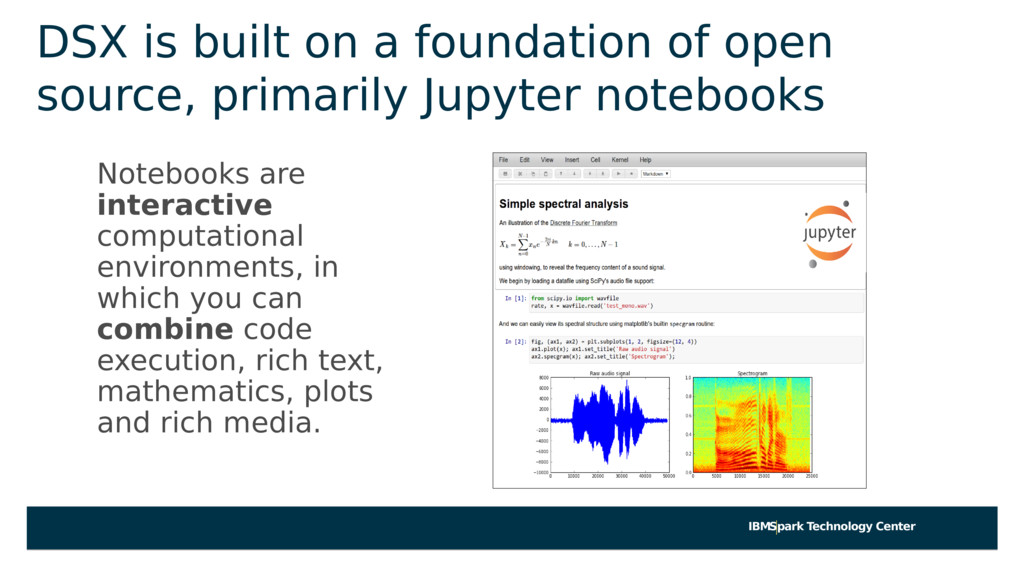
IBMSpark Technology Center DSX is built on a foundation of
open source, primarily Jupyter notebooks Notebooks are interactive computational environments, in which you can combine code execution, rich text, mathematics, plots and rich media. -
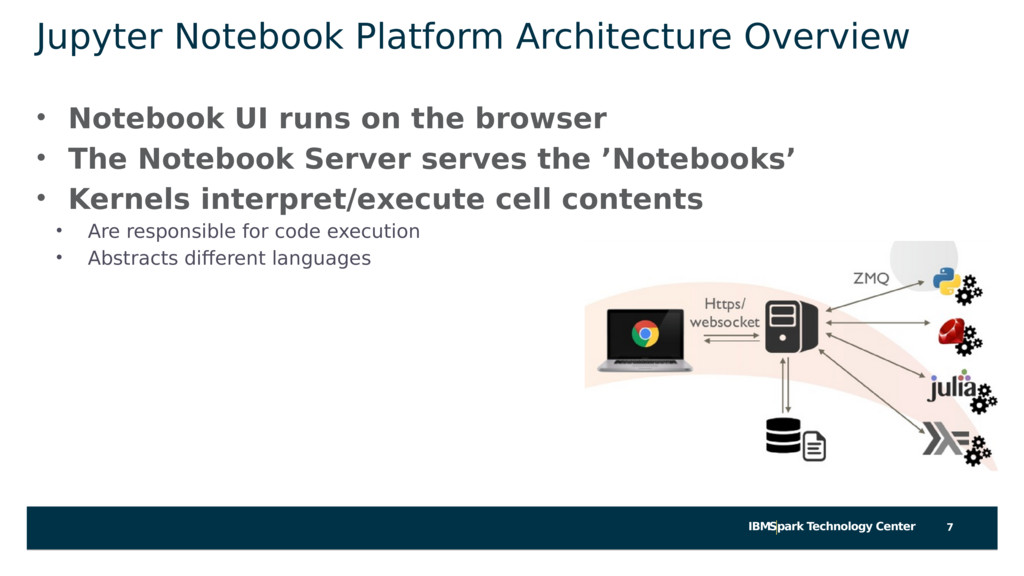
IBMSpark Technology Center Jupyter Notebook Platform Architecture Overview • Notebook
UI runs on the browser • The Notebook Server serves the ’Notebooks’ • Kernels interpret/execute cell contents • Are responsible for code execution • Abstracts different languages 7 -
IBMSpark Technology Center Follow-ups TRY IT: datascience.ibm.com Event registration URL:
https://ibm.biz/BdjJUw -
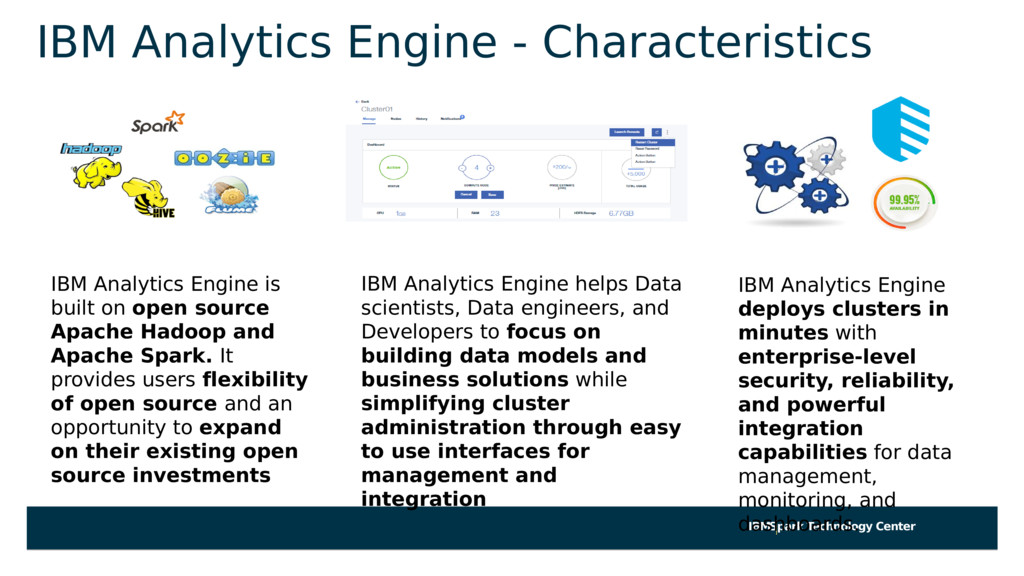
IBMSpark Technology Center IBM Analytics Engine - Characteristics IBM Analytics
Engine is built on open source Apache Hadoop and Apache Spark. It provides users flexibility of open source and an opportunity to expand on their existing open source investments IBM Analytics Engine helps Data scientists, Data engineers, and Developers to focus on building data models and business solutions while simplifying cluster administration through easy to use interfaces for management and integration IBM Analytics Engine deploys clusters in minutes with enterprise-level security, reliability, and powerful integration capabilities for data management, monitoring, and dashboards. -
IBMSpark Technology Center Enterprise/Cloud Analytics Platform Characteristics Large pool of
shared computing resources • Enterprise Cloud, Public Cloud or Hybrid • Data in the cloud (Data Lakes/Object Storage) Distributed Consumers • Notebooks running local (users laptop) or as a service Different Resource Utilization Patterns • High number of idle resources 13 -
IBMSpark Technology Center Analytics Platform – Current state of the
art Open Source Jupyter based Notebook Platform • Single User sharing the same distributed filesystem and privileges • Jupyter Kernels running as local process • Resources are limited by what is available on the one single node that runs all Kernels and associated Spark drivers. • No security, users can see and control each others process using Jupyter’s administration utilities. 14 -
IBMSpark Technology Center Analytics Platform Today – Shared Cluster Allows
Jupyter notebooks running outside of the cluster to run Jupyter kernels inside the cluster sharing it’s resources. • All Jupyter kernels run under a shared, “service” user ID. • Users can see and control each others’ kernels using Jupyter’s administration utilities. • All kernels and their associated Spark drivers run on a single (configurable) node of the cluster. 15 Spark Cluster Bob’s Desktop Multiple Notebooks Jupyter Kernel Gateway (Sandboxed by service user privileges) Jupyter Kernel Gateway Jupyter Kernel Gateway Jupyter Notebook Server (with NB2KG) Executors (as Alice) Executors (as Alice) Spark Executors (as JNBG Service User) Kernel [Spark Driver] (yarn-client mode as JNBG Service User) Kernel [Spark Driver] (yarn-client mode as JNBG Service User) YARN Workers Bob’s Desktop Multiple Notebooks Jupyter Notebook Server (with NB2KG) Security Layer Kernel [Spark Driver] (yarn-client mode as JNBG Service User) Kernel [Spark Driver] (yarn-client mode as JNBG Service User) Executors (as Alice) Executors (as Alice) Spark Executors (as JNBG Service User) -
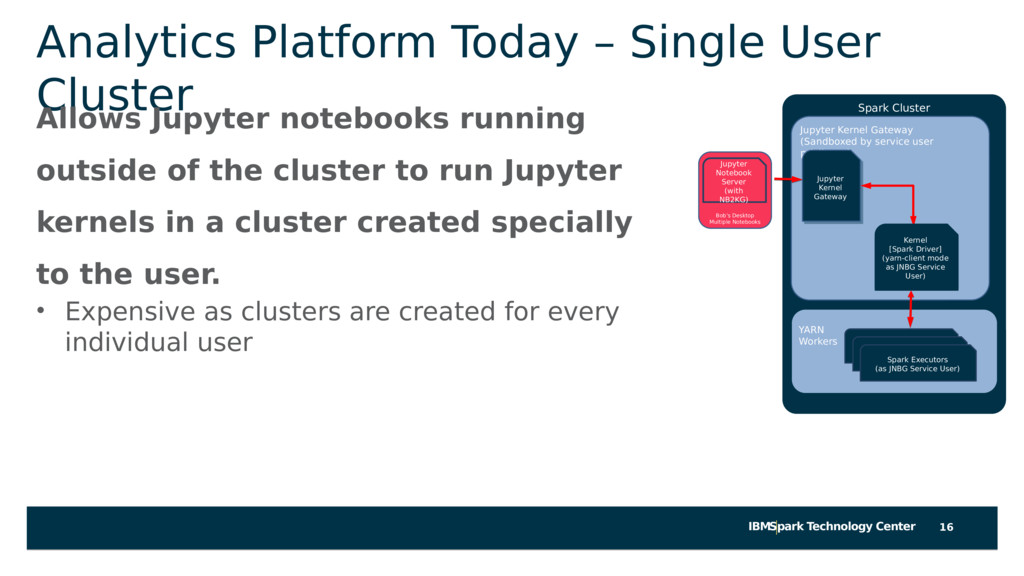
IBMSpark Technology Center Analytics Platform Today – Single User Cluster
Allows Jupyter notebooks running outside of the cluster to run Jupyter kernels in a cluster created specially to the user. • Expensive as clusters are created for every individual user 16 Spark Cluster Bob’s Desktop Multiple Notebooks Jupyter Kernel Gateway (Sandboxed by service user privileges) Jupyter Kernel Gateway Jupyter Kernel Gateway Jupyter Notebook Server (with NB2KG) Executors (as Alice) Executors (as Alice) Spark Executors (as JNBG Service User) Kernel [Spark Driver] (yarn-client mode as JNBG Service User) Kernel [Spark Driver] (yarn-client mode as JNBG Service User) YARN Workers -
IBMSpark Technology Center Jupyter Enterprise Gateway A lightweight, multi-tenant, scalable
and secure gateway that enables Jupyter Notebooks to share resources across an Apache Spark cluster aiming on Enterprise/Cloud requirements and use cases 18 -
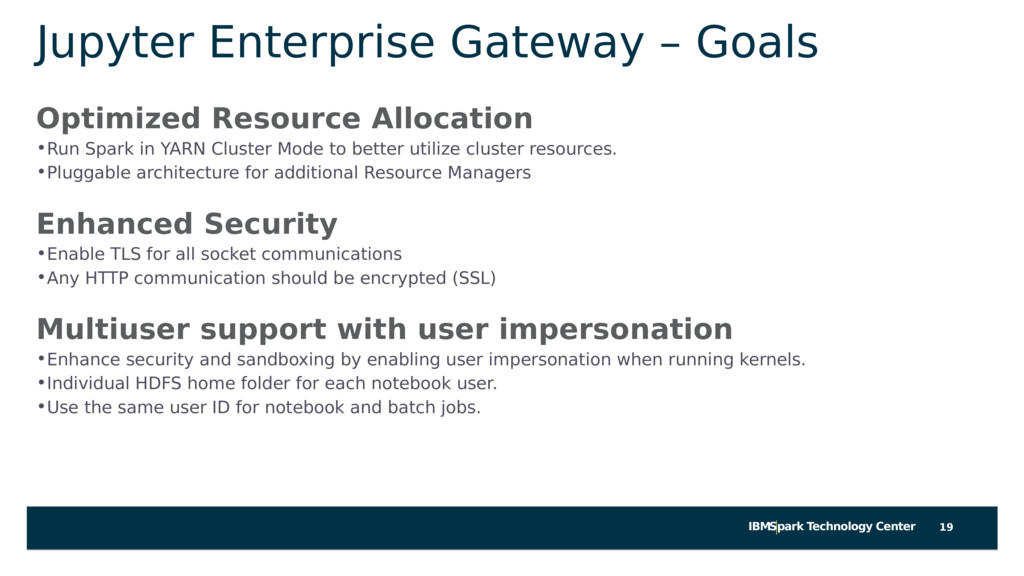
IBMSpark Technology Center Jupyter Enterprise Gateway – Goals Optimized Resource
Allocation •Run Spark in YARN Cluster Mode to better utilize cluster resources. •Pluggable architecture for additional Resource Managers Enhanced Security •Enable TLS for all socket communications •Any HTTP communication should be encrypted (SSL) Multiuser support with user impersonation •Enhance security and sandboxing by enabling user impersonation when running kernels. •Individual HDFS home folder for each notebook user. •Use the same user ID for notebook and batch jobs. 19 -
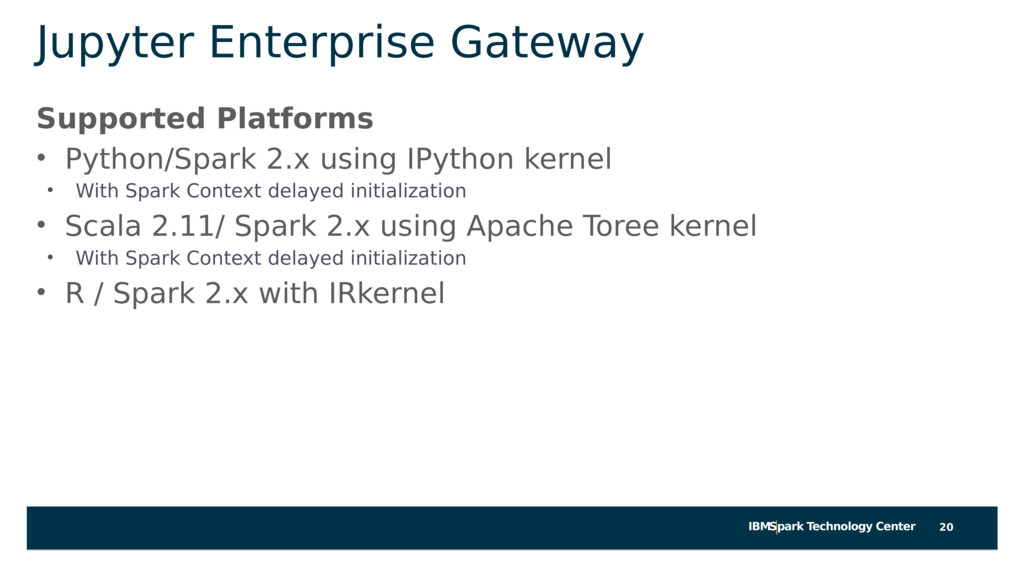
IBMSpark Technology Center Jupyter Enterprise Gateway Supported Platforms • Python/Spark
2.x using IPython kernel • With Spark Context delayed initialization • Scala 2.11/ Spark 2.x using Apache Toree kernel • With Spark Context delayed initialization • R / Spark 2.x with IRkernel 20 -
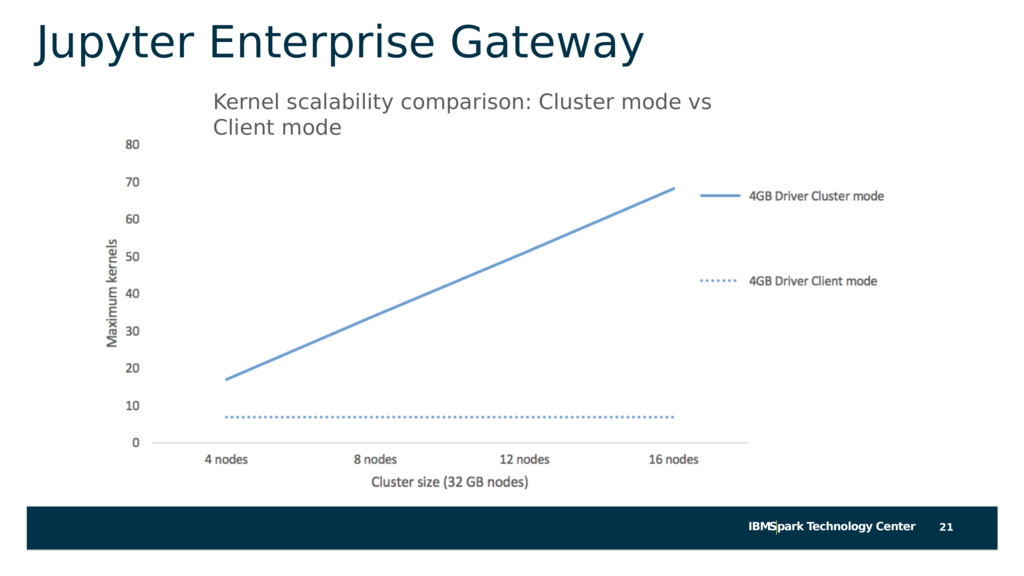
IBMSpark Technology Center Jupyter Enterprise Gateway 21 Kernel scalability comparison:
Cluster mode vs Client mode -
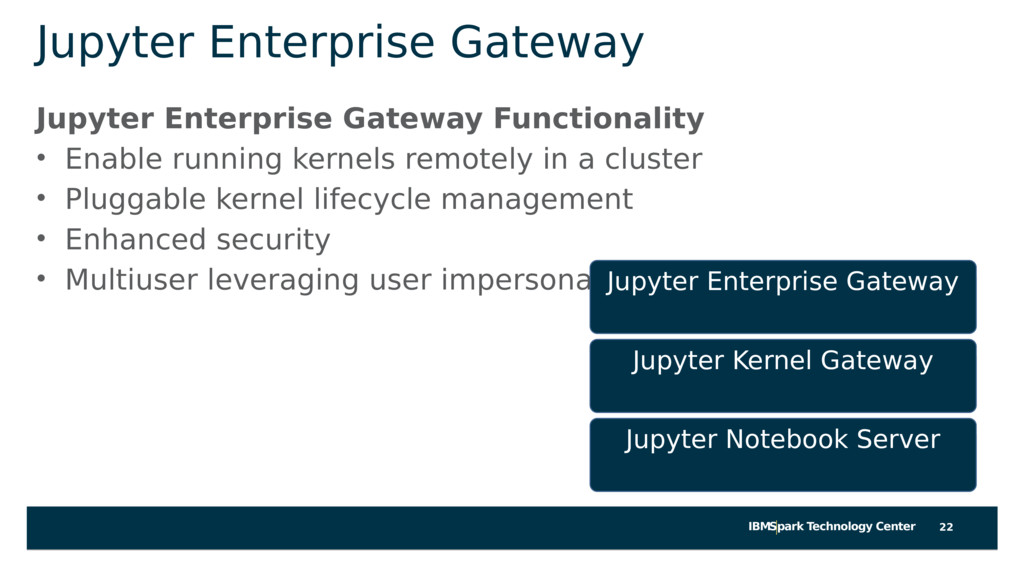
IBMSpark Technology Center Jupyter Enterprise Gateway Jupyter Enterprise Gateway Functionality
• Enable running kernels remotely in a cluster • Pluggable kernel lifecycle management • Enhanced security • Multiuser leveraging user impersonation 22 Jupyter Enterprise Gateway Jupyter Kernel Gateway Jupyter Notebook Server -
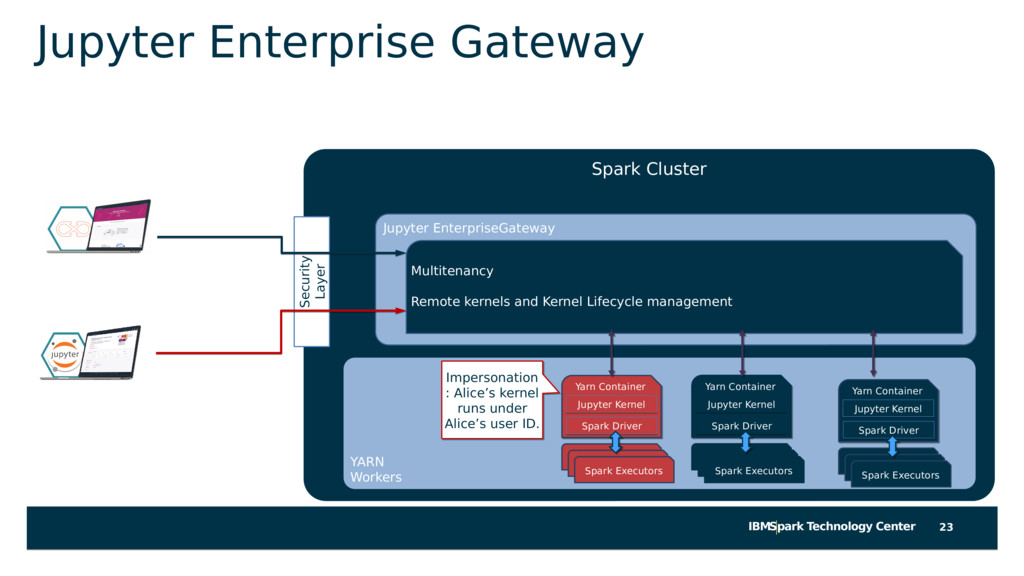
IBMSpark Technology Center Spark Cluster Jupyter Enterprise Gateway 23 Security
Layer YARN Workers Jupyter EnterpriseGateway Multitenancy Remote kernels and Kernel Lifecycle management Spark Executors Spark Executors Spark Executors Yarn Container Yarn Container Jupyter Kernel Jupyter Kernel Spark Driver Spark Driver Spark Executors Spark Executors Spark Executors Yarn Container Yarn Container Jupyter Kernel Jupyter Kernel Spark Driver Spark Driver Spark Executors Spark Executors Spark Executors Yarn Container Yarn Container Jupyter Kernel Jupyter Kernel Spark Driver Spark Driver Impersonation : Alice’s kernel runs under Alice’s user ID. Impersonation : Alice’s kernel runs under Alice’s user ID. -
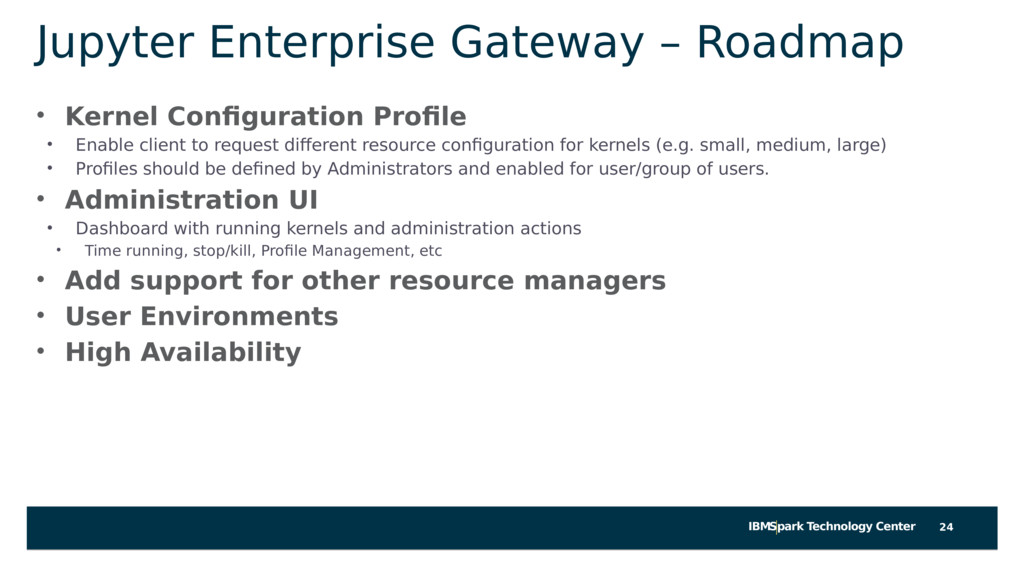
IBMSpark Technology Center Jupyter Enterprise Gateway – Roadmap • Kernel
Configuration Profile • Enable client to request different resource configuration for kernels (e.g. small, medium, large) • Profiles should be defined by Administrators and enabled for user/group of users. • Administration UI • Dashboard with running kernels and administration actions • Time running, stop/kill, Profile Management, etc • Add support for other resource managers • User Environments • High Availability 24 -
IBMSpark Technology Center Jupyter Enterprise Gateway Jupyter Enterprise Gateway at
IBM Code https://developer.ibm.com/code/openprojects/jupyter-enterprise-gateway/ Jupyter Enterprise Gateway no GitHub https://github.com/jupyter-incubator/enterprise_gateway 25