Share
Embed
Introduction to the AnVIL
Presentation by Anthony Philippakis and James Taylor on the AnVIL (NHGRI Genomic Data Science Analysis, Visualization and Informatics Lab-space) for the NIH Workshop on Cloud-Based Platforms Interoperability
James Taylor
October 03, 2019
Transcript
50 slides
-
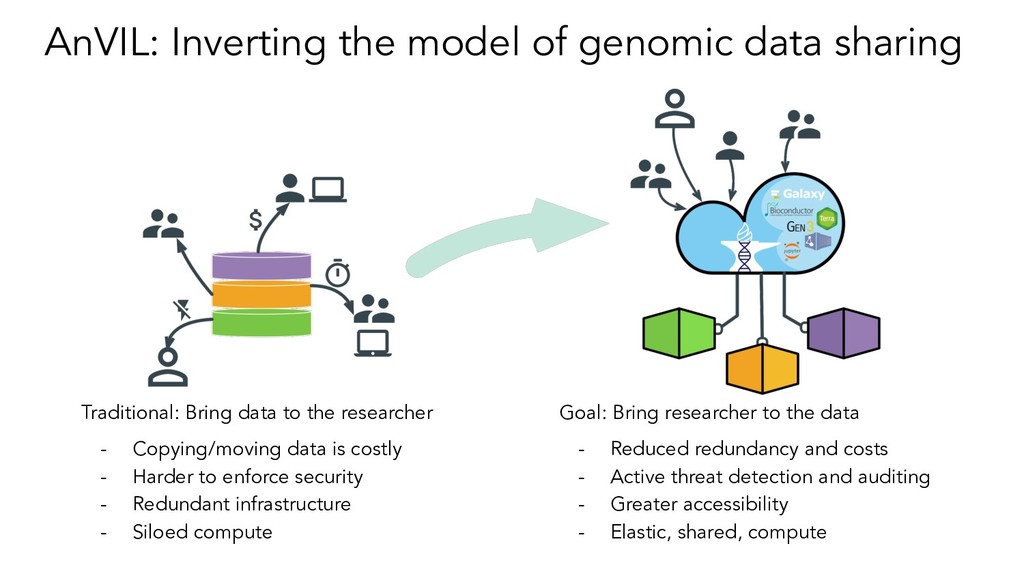
AnVIL: Inverting the model of genomic data sharing Traditional: Bring
data to the researcher - Copying/moving data is costly - Harder to enforce security - Redundant infrastructure - Siloed compute Goal: Bring researcher to the data - Reduced redundancy and costs - Active threat detection and auditing - Greater accessibility - Elastic, shared, compute -
What is the AnVIL? - Scalable and interoperable resource for
the genomic scientific community - Cloud-based infrastructure - Shared analysis and computing environment - Support genomic data access, sharing and computing across large genomic, and genomic related, data sets - Genomic datasets, phenotypes and metadata - Large datasets generated by NHGRI programs, as well as other initiatives / agencies - Data access controls and data security - Collaborative environment for datasets and analysis workflows - ...for both users with limited computational expertise and sophisticated data scientist users -
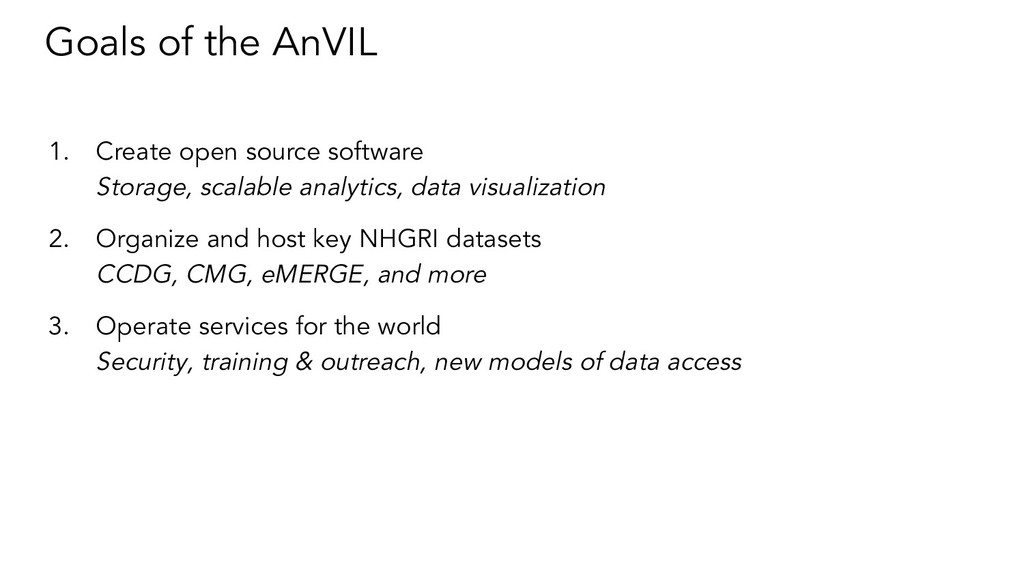
Goals of the AnVIL 1. Create open source software Storage,
scalable analytics, data visualization 2. Organize and host key NHGRI datasets CCDG, CMG, eMERGE, and more 3. Operate services for the world Security, training & outreach, new models of data access -
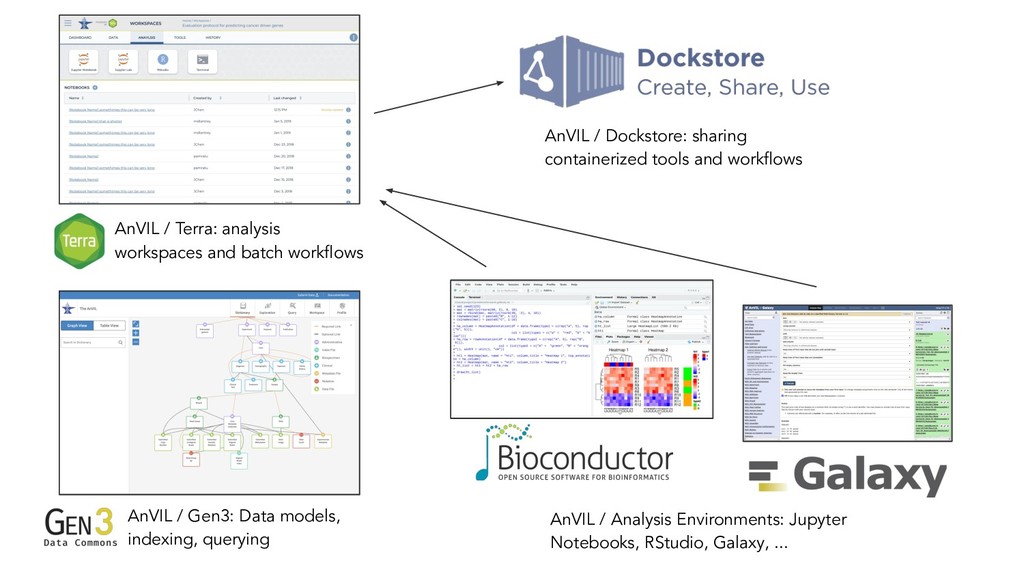
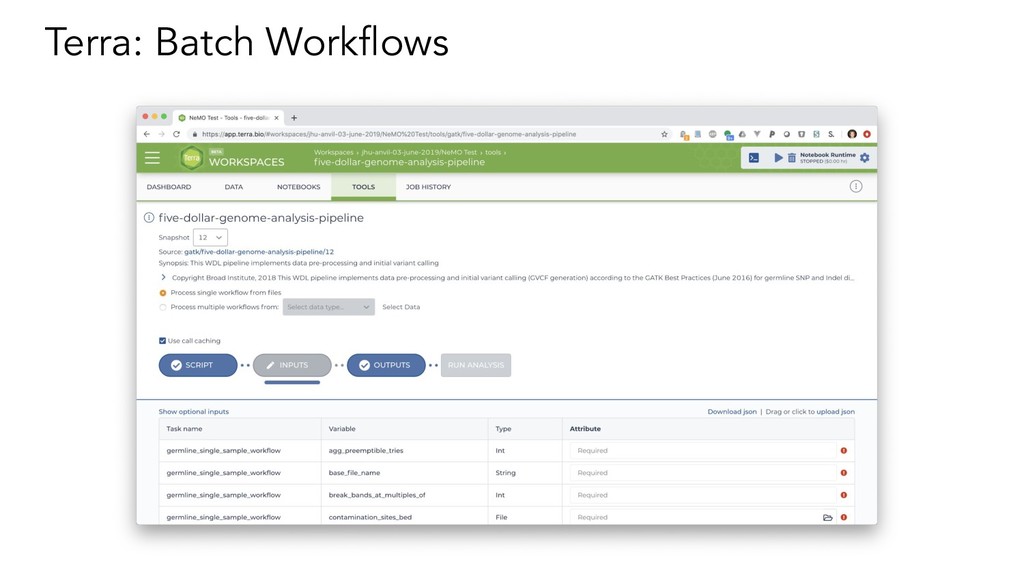
AnVIL / Terra: analysis workspaces and batch workflows AnVIL /
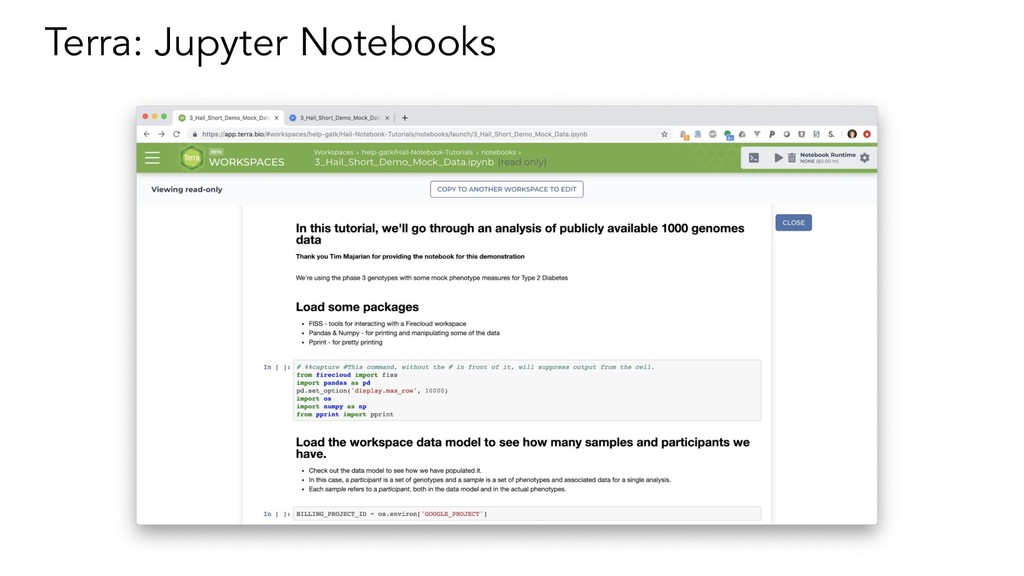
Gen3: Data models, indexing, querying AnVIL / Dockstore: sharing containerized tools and workflows AnVIL / Analysis Environments: Jupyter Notebooks, RStudio, Galaxy, ... -
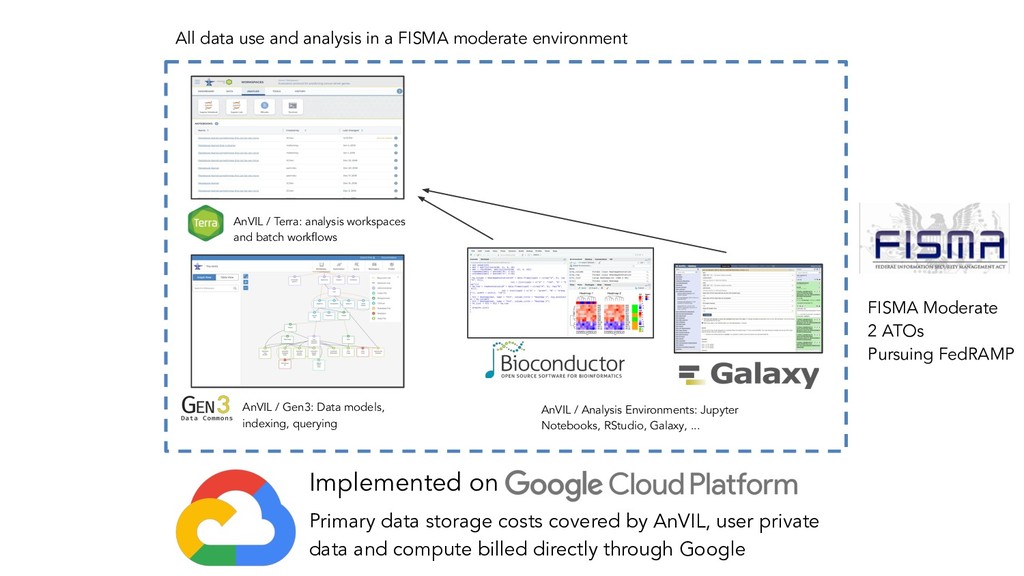
AnVIL / Terra: analysis workspaces and batch workflows AnVIL /
Gen3: Data models, indexing, querying AnVIL / Analysis Environments: Jupyter Notebooks, RStudio, Galaxy, ... FISMA Moderate 2 ATOs Pursuing FedRAMP All data use and analysis in a FISMA moderate environment Implemented on Primary data storage costs covered by AnVIL, user private data and compute billed directly through Google -
Approach to enabling analysis - Goal is to integrate a
wide variety of analysis tools and analysis environments to support different types of users and communities - Built for extensibility, users will be able to bring new tools and analysis applications to the platform - Initial launch has been focused on more expert users, supporting batch workflows and Python programming - Additional environments and visualization tools will continue to be integrated throughout 2019/2020 -
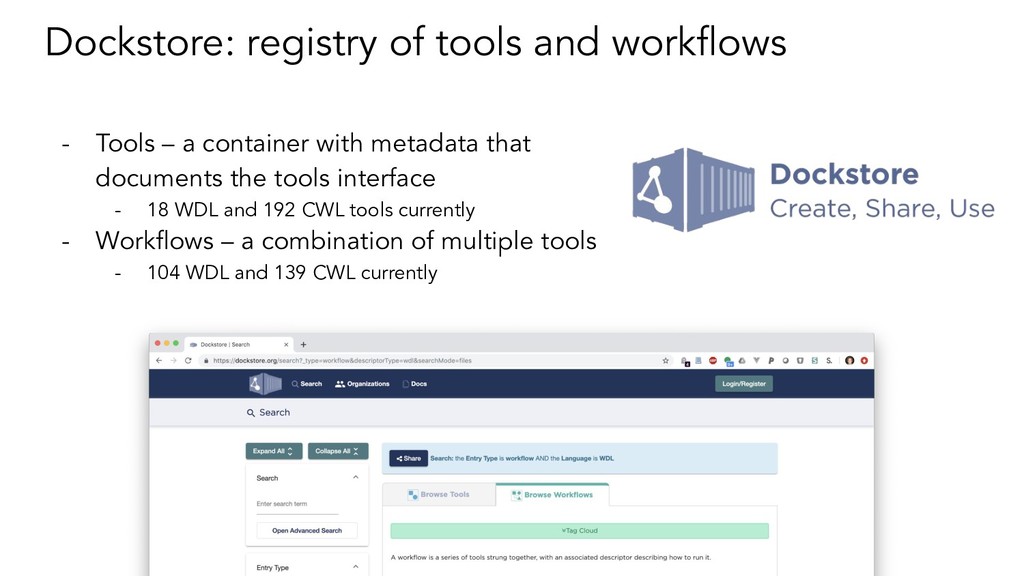
Dockstore: registry of tools and workflows - Tools – a
container with metadata that documents the tools interface - 18 WDL and 192 CWL tools currently - Workflows – a combination of multiple tools - 104 WDL and 139 CWL currently -
Bioconductor + RStudio - Bioconductor: tools and modules for the
analysis and comprehension of high-throughput genomic data, implemented in R - RStudio: analysis environment specifically designed for, and largely preferred by the R community. - 1,741 software packages available in Bioconductor release 3.9 - AnVIL will provide a robust well tested RStudio environment with the latest Bioconductor release integrated -
Galaxy - Web-based analysis environment for running analysis tools and
building workflows for users with no programming expertise - Galaxy ToolShed, a repository for community contributed tools and workflows, has 6,894 tools - Additionally, Galaxy integrates dozens of visualization tools which will also be available in AnVIL. -
Extending AnVIL - Bring your own tools and workflows -
Either by registering them in Dockstore, or by uploading your own custom WDL to Terra - Build on top of the AnVIL APIs - All of the components of the AnVIL provide APIs - We will be providing a unified, stable API endpoint for the AnVIL with OpenAPI documentation - We are building API wrapper libraries in Python and R, largely generate from the OpenAPI specification but curated - Adding new web applications - We are defining standards to allow a containerized web application to be hosted inside AnVIL - Leveraging standards container orchestration (Kubernetes) for complex applications -
Three areas of focus 1. Ingestion and Processing of Genomic
Data Align, variant-call, and QC read-level data with best-practices pipelines 2. Ingestion and Processing of Phenotypic Data QC phenotypes and map to standardized data models 3. Data Access and Data Use Oversight Create more streamlined mechanisms to access the data For all three, governance is crucial! -
Working Groups 1. Data Processing Working Group Select best-practices pipelines,
and define QC metrics for read-level data 2. Phenotype Working Group Select data models to map phenotypic data to, and oversee process 3. Data Access Working Group Map data use restrictions to ontologies, and create a data “passport” We welcome your involvement! -
Data Roadmap 1. By end of 2019 - GSP: Center
for Complex Disease Genomics (CCDG) and Center for Mendelian Genomics (CMG). Both will require updates beyond 2019 - GTEx v8 - High coverage 1kG - eMERGE 2. By end of 2020 - eMERGE - Clinical Sequencing Evidence-Generating Research - Undiagnosed Diseases Network -
Areas of Focus 1. Security & Compliance Ensure that all
applications in the AnVIL ecosystem are secure & compliant 2. Data Access Can we use new models of data governance that accelerate access to data? 3. Training and Outreach Engage researchers around the world and train them to use the AnVIL -
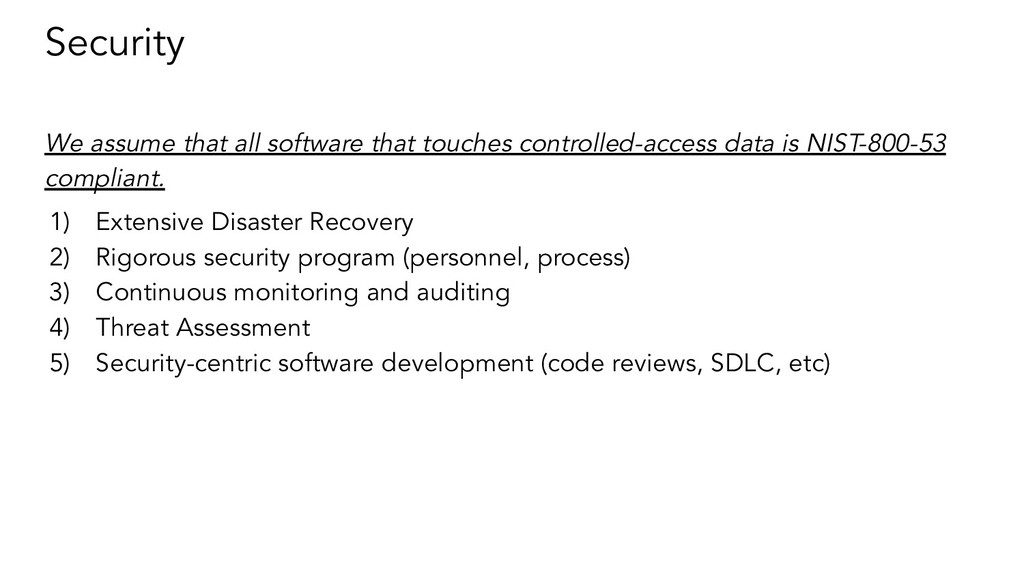
Security We assume that all software that touches controlled-access data
is NIST-800-53 compliant. 1) Extensive Disaster Recovery 2) Rigorous security program (personnel, process) 3) Continuous monitoring and auditing 4) Threat Assessment 5) Security-centric software development (code reviews, SDLC, etc) -
Areas of Focus 1. Security & Compliance Ensure that all
applications in the AnVIL ecosystem are secure & compliant 2. Data Access Can we use new models of data governance that accelerate access to data? 3. Training and Outreach Engage researchers around the world and train them to use the AnVIL -
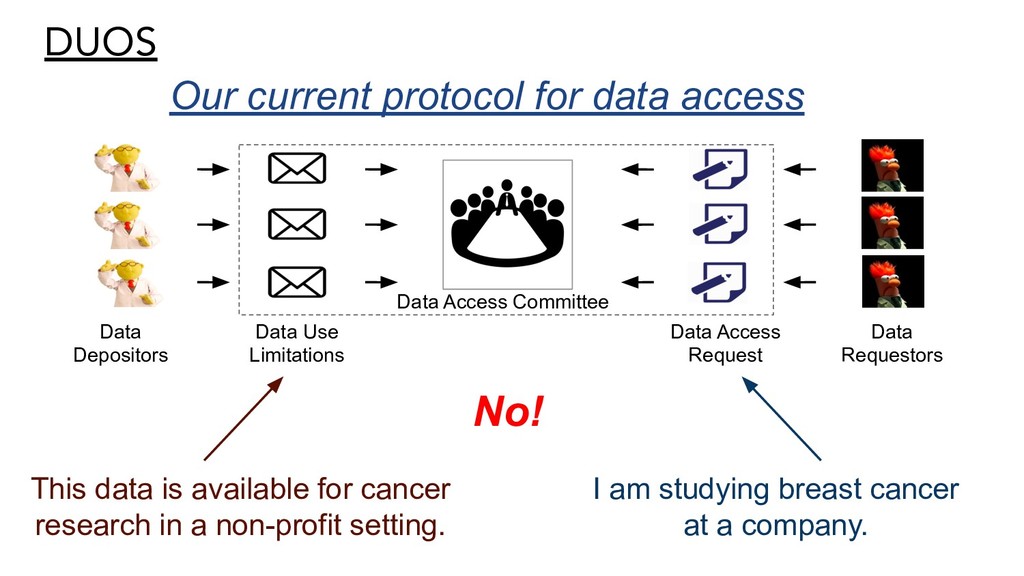
DUOS Our current protocol for data access Data Depositors Data
Use Limitations This data is available for cancer research in a non-profit setting. Data Access Committee No! Data Access Request Data Requestors I am studying breast cancer at a company. -
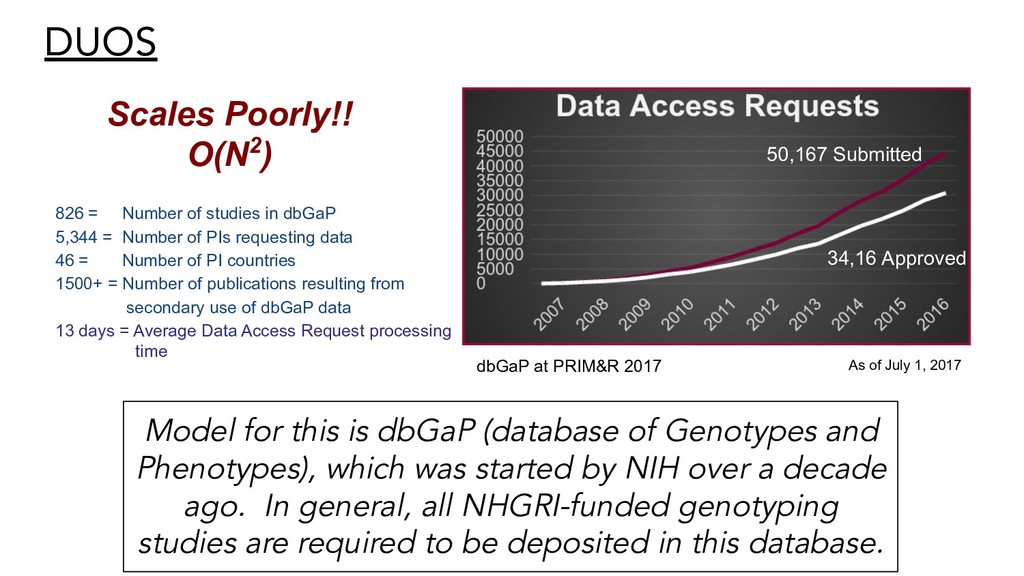
DUOS Scales Poorly!! O(N2) dbGaP at PRIM&R 2017 826 =
Number of studies in dbGaP 5,344 = Number of PIs requesting data 46 = Number of PI countries 1500+ = Number of publications resulting from secondary use of dbGaP data 13 days = Average Data Access Request processing time As of July 1, 2017 50,167 Submitted 34,16 Approved Model for this is dbGaP (database of Genotypes and Phenotypes), which was started by NIH over a decade ago. In general, all NHGRI-funded genotyping studies are required to be deposited in this database. -
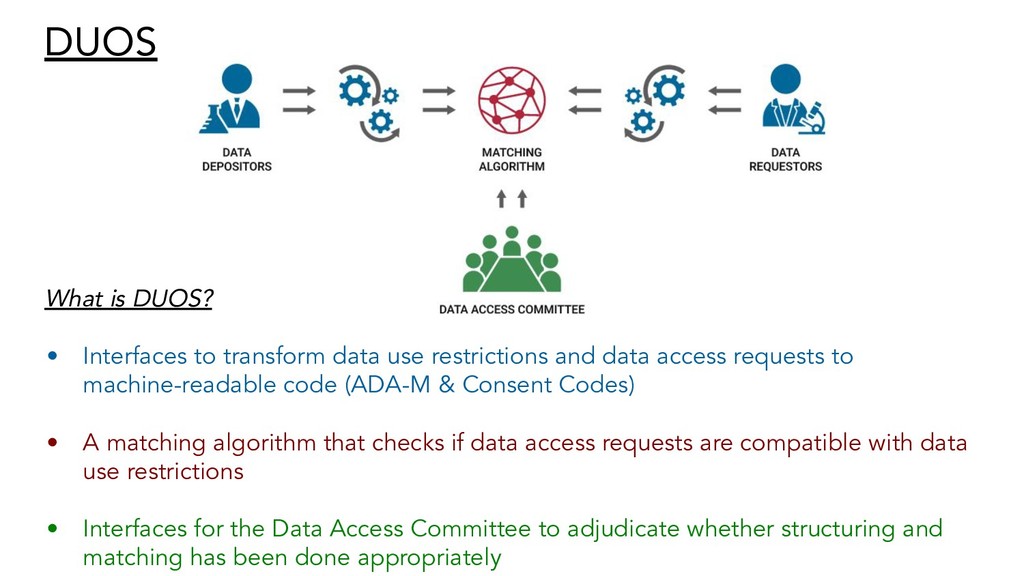
What is DUOS? • Interfaces to transform data use restrictions
and data access requests to machine-readable code (ADA-M & Consent Codes) • A matching algorithm that checks if data access requests are compatible with data use restrictions • Interfaces for the Data Access Committee to adjudicate whether structuring and matching has been done appropriately DUOS -
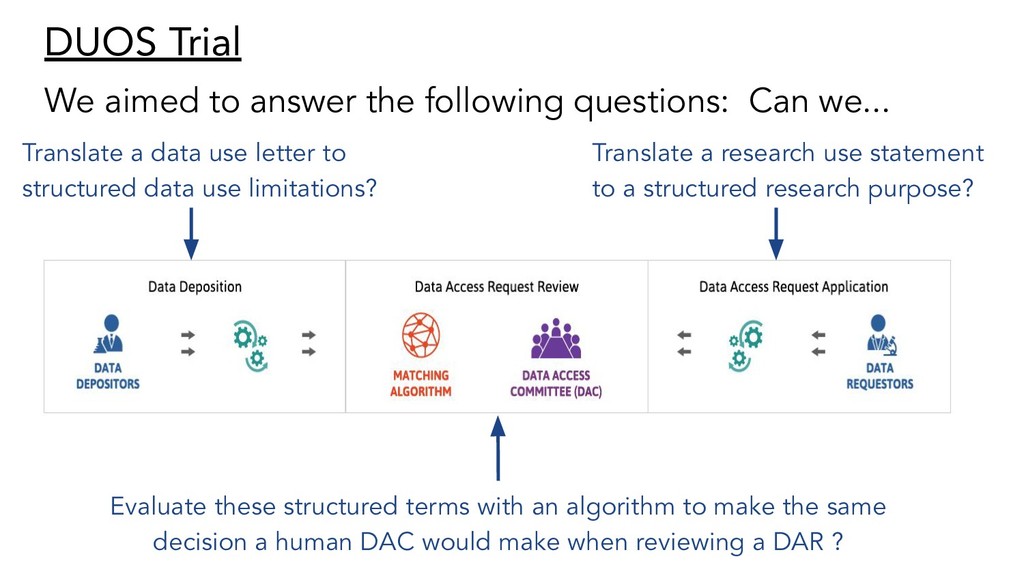
DUOS Trial We aimed to answer the following questions: Can
we... Translate a data use letter to structured data use limitations? Translate a research use statement to a structured research purpose? Evaluate these structured terms with an algorithm to make the same decision a human DAC would make when reviewing a DAR ? -
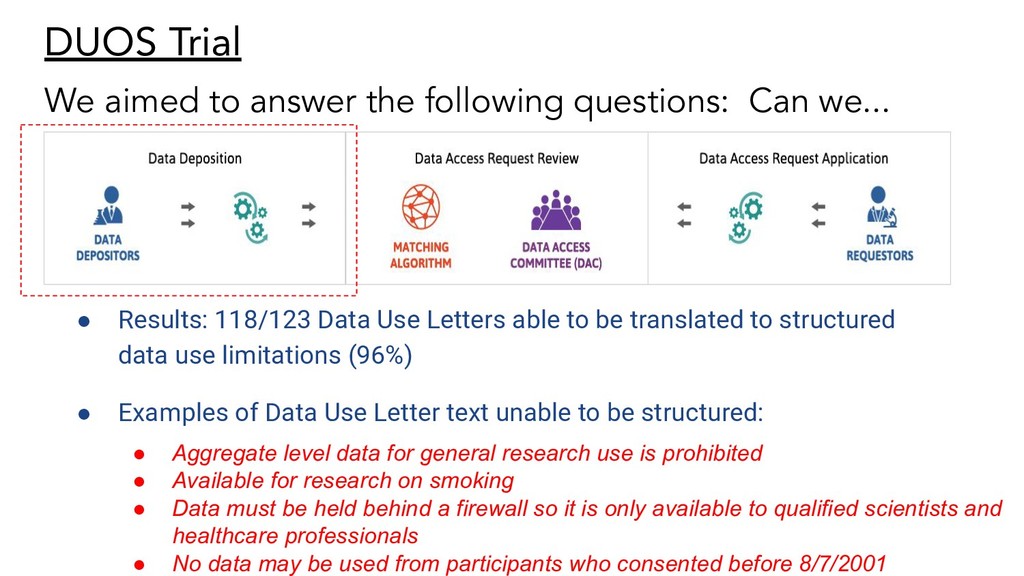
DUOS Trial We aimed to answer the following questions: Can
we... • Results: 118/123 Data Use Letters able to be translated to structured data use limitations (96%) • Examples of Data Use Letter text unable to be structured: • Aggregate level data for general research use is prohibited • Available for research on smoking • Data must be held behind a firewall so it is only available to qualified scientists and healthcare professionals • No data may be used from participants who consented before 8/7/2001 -
DUOS Trial We aimed to answer the following questions: Can
we... • Results: 38/38 of researchers’ submitted research use statements were correctly translated (100%) • The human DAC & DUOS algorithm agreed on 37/37 of data access request evaluations (100%) • >95% of DAR decisions were able to be adjudicated by the algorithm -
Areas of Focus 1. Security & Compliance Ensure that all
applications in the AnVIL ecosystem are secure & compliant 2. Data Access Can we use new models of data governance that accelerate access to data? 3. Training and Outreach Engage researchers around the world and train them to use the AnVIL -
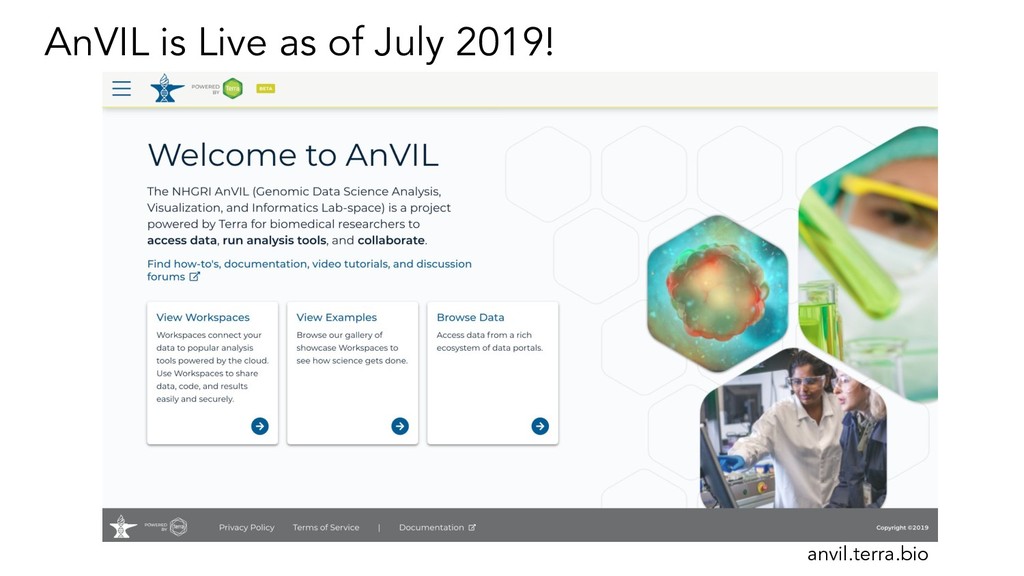
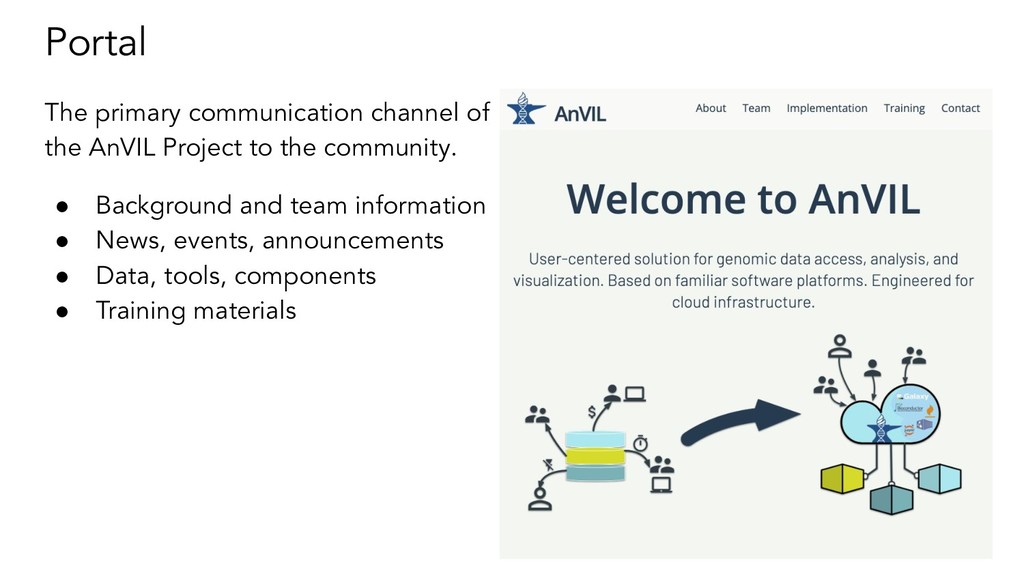
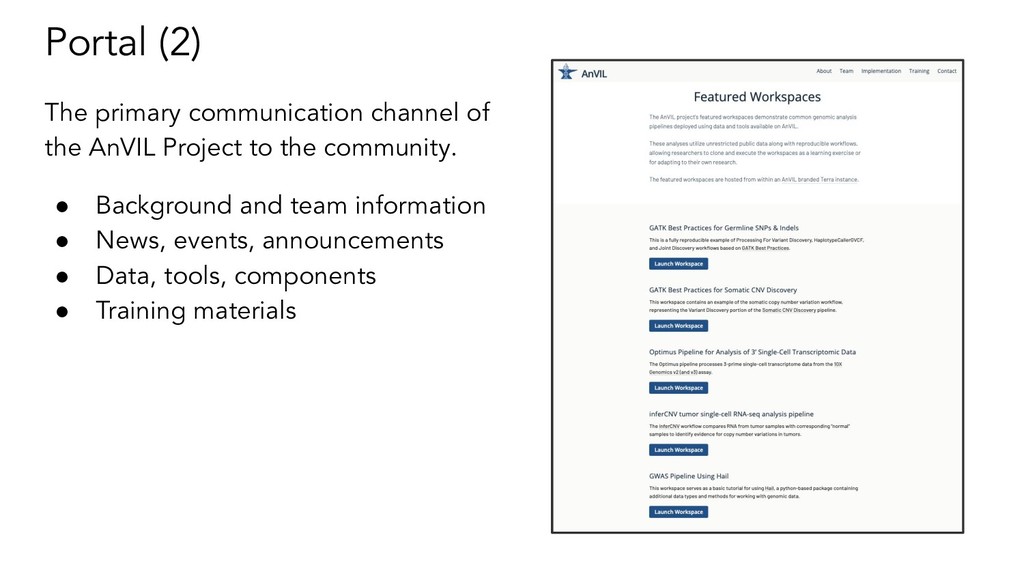
Portal The primary communication channel of the AnVIL Project to
the community. • Background and team information • News, events, announcements • Data, tools, components • Training materials -
Portal (2) The primary communication channel of the AnVIL Project
to the community. • Background and team information • News, events, announcements • Data, tools, components • Training materials -
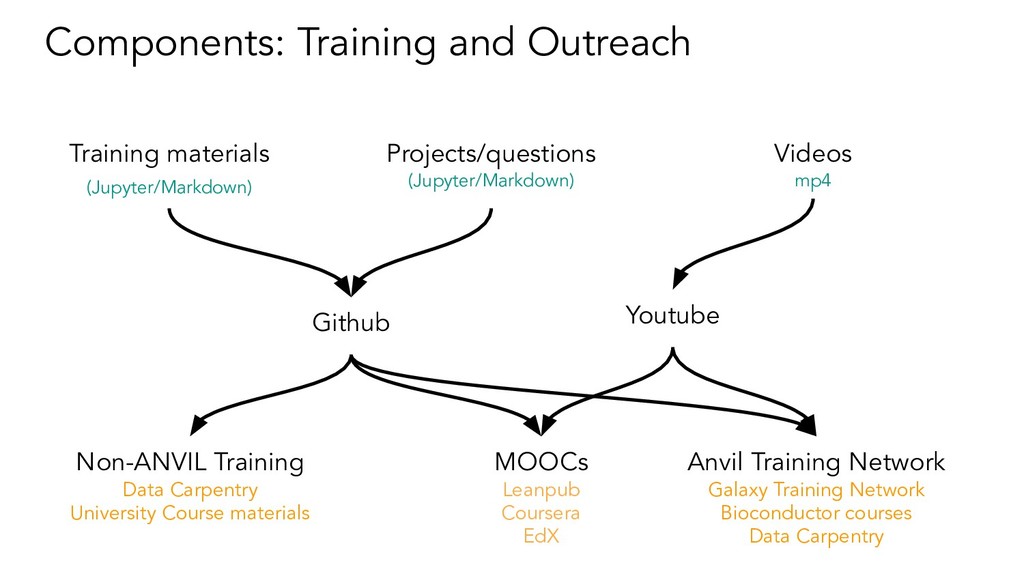
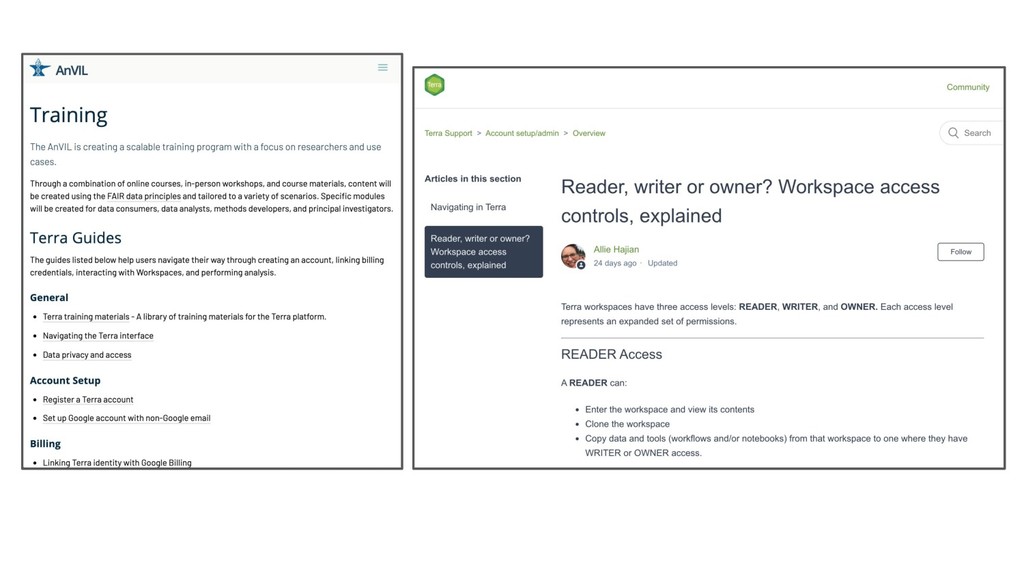
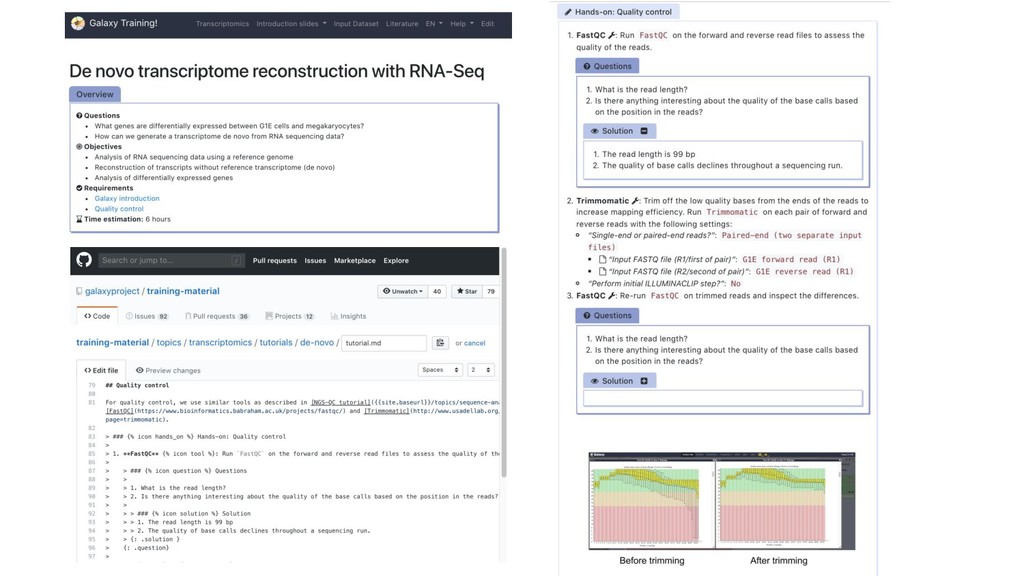
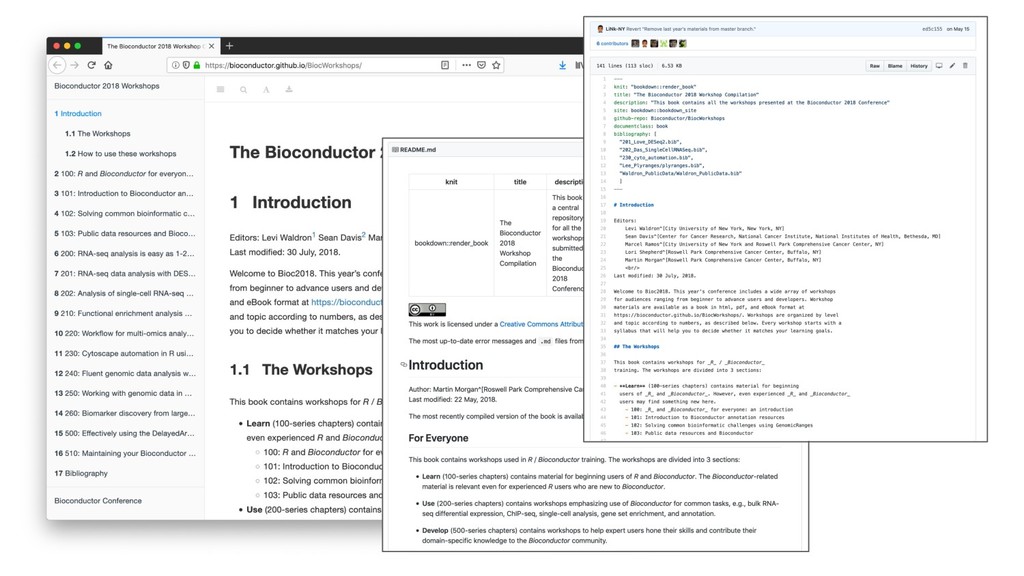
Components: Training and Outreach Training materials (Jupyter/Markdown) Videos mp4 Projects/questions
(Jupyter/Markdown) Github Youtube MOOCs Leanpub Coursera EdX Non-ANVIL Training Data Carpentry University Course materials Anvil Training Network Galaxy Training Network Bioconductor courses Data Carpentry -
Principles 1. Training material must be maintainable 2. Training material
must be updatable 3. Training material creation must be distributed 4. Training material must be accessible 5. Training material must be repurposable 6. Training material must be free or low cost -
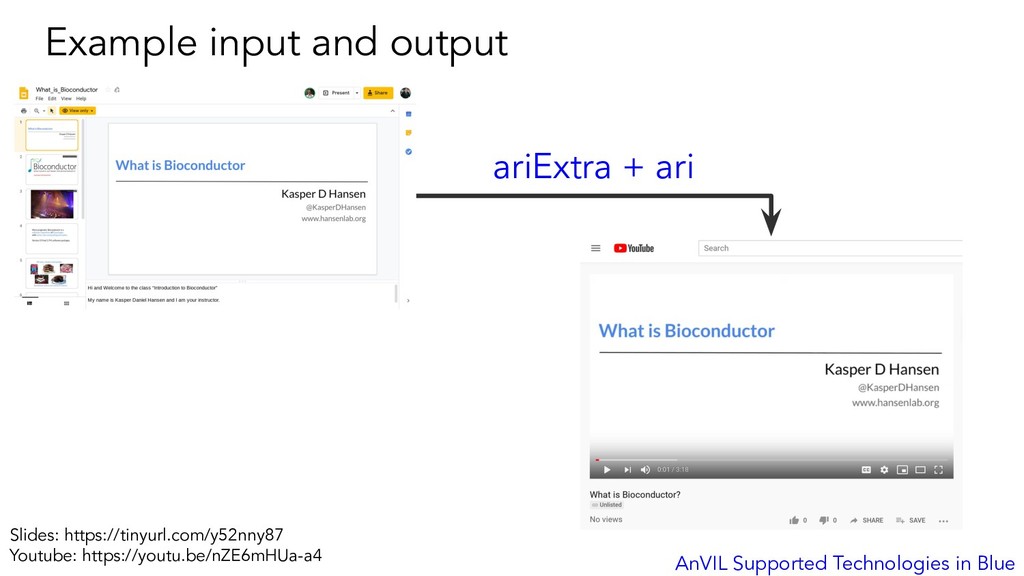
Example input and output AnVIL Supported Technologies in Blue Slides:
https://tinyurl.com/y52nny87 Youtube: https://youtu.be/nZE6mHUa-a4 ariExtra + ari -
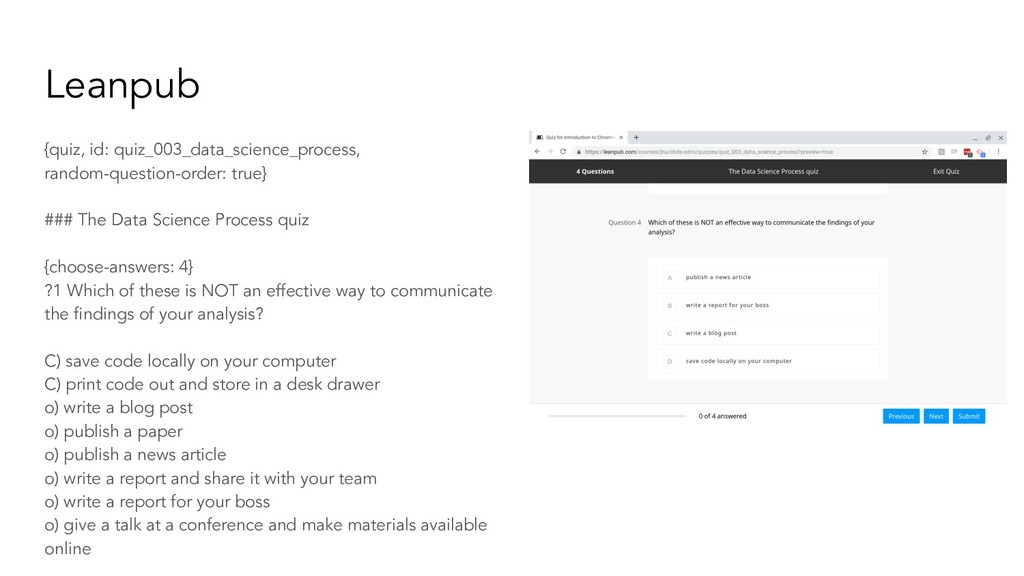
{quiz, id: quiz_003_data_science_process, random-question-order: true} ### The Data Science Process
quiz {choose-answers: 4} ?1 Which of these is NOT an effective way to communicate the findings of your analysis? C) save code locally on your computer C) print code out and store in a desk drawer o) write a blog post o) publish a paper o) publish a news article o) write a report and share it with your team o) write a report for your boss o) give a talk at a conference and make materials available online Leanpub -
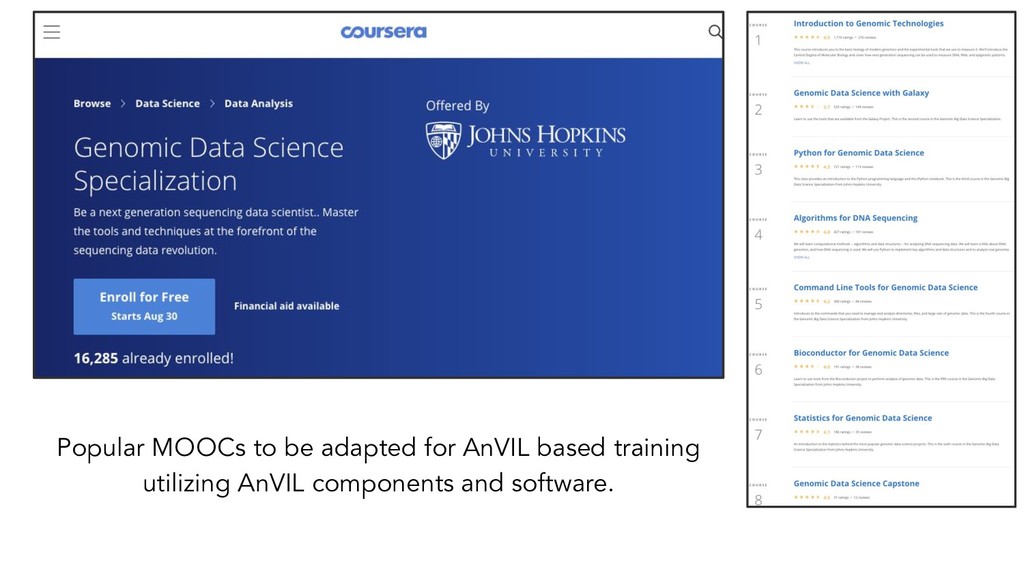
Popular MOOCs to be adapted for AnVIL based training utilizing
AnVIL components and software. -
Existing platform agnostic content port Portable content - Introduction to
Genomics - Statistics - Bioconductor - Galaxy - Python programming - Alignment - Command line tools Differences in AnVIL to be accomodated - File management - Permissions - Workflow -
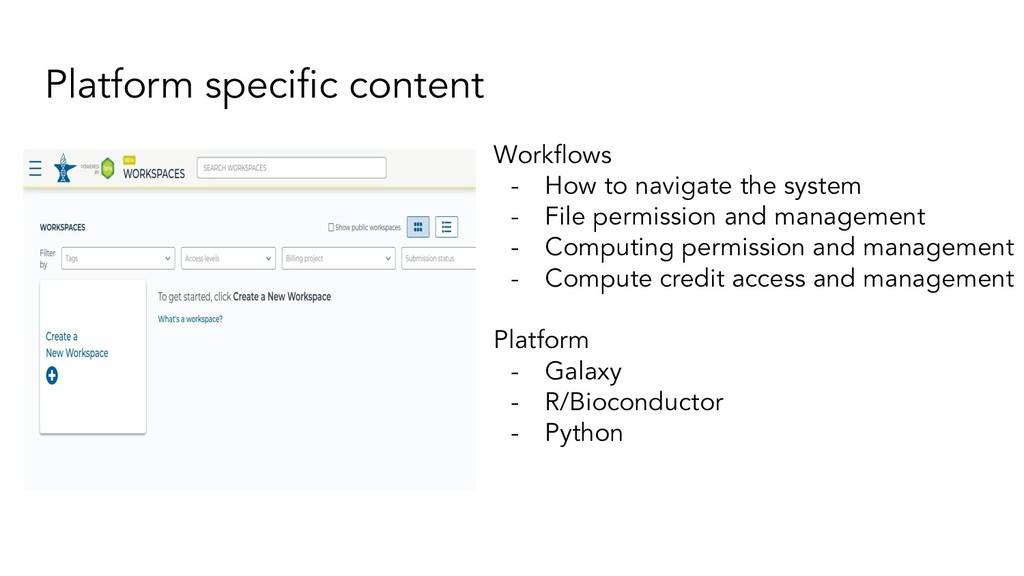
Platform specific content Workflows - How to navigate the system
- File permission and management - Computing permission and management - Compute credit access and management Platform - Galaxy - R/Bioconductor - Python -
Broad Institute Anthony Philippakis, Daniel MacArthur, Alex Bauman, Adrian Sharma,
Andrew Rula, Dave Bernick, Jonathan Lawson, Kristian Cibulskis, Namrata Gupta, Rob Title, Eric Banks, RIch Silva University of Chicago Robert Grossman, Abby George, Garrett Rupp, Zac Flamig University of California Santa Cruz Benedict Paten, Denis Yuen, Brian O’Connor, Charles Overbeck, Kevin Osborn, Louise Cabansay, Natalie Perez, Stefan Kuhn, Walt Shands Vanderbilt Robert Carroll, Lakhan Swamy, Kristin Wuichet Washington University Ira Hall, Adam Coffman, Allison Reieir, Haley Abel, Jason Walker Johns Hopkins James Taylor, Jeff Leek, Kasper Hansen, Enis Afgan, Alexandru Mahmoud, Sergey Golitsynskiy, Jenn Vessio, John Muschelli, Mo Heydarian Penn State University Anton Nekrutenko, John Chilton, Nate Coraor, Marten Cech Oregon Health & Sciences University Jeremy Goecks, Kyle Ellrott, Brian Walsh, Luke Sargent, Vahid Jalili Roswell Park Cancer Institute Martin Morgan, Nitesh Turaga, Lori Shepherd Harvard Vincent Carey, BJ Stubbs, Shweta Gopaulakrishnan City University of New York Levi Waldron, Sehyun Oh, Ludwig Geistlinger AnVIL Team