Share
Embed
elasticsearch, Big Data, Search & Analytics
A talk given at berlin buzzwords 2012
Shay Banon
June 06, 2012
Transcript
44 slides
-
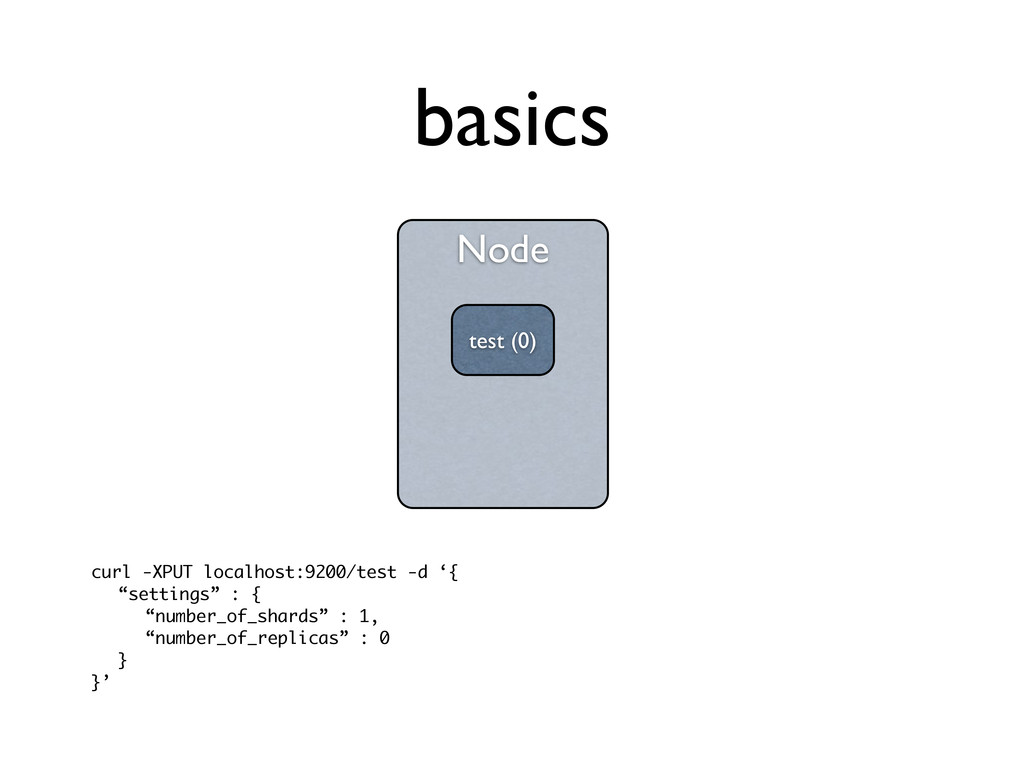
basics Node curl -XPUT localhost:9200/test -d ‘{ “settings” : {
“number_of_shards” : 1, “number_of_replicas” : 0 } }’ test (0) -
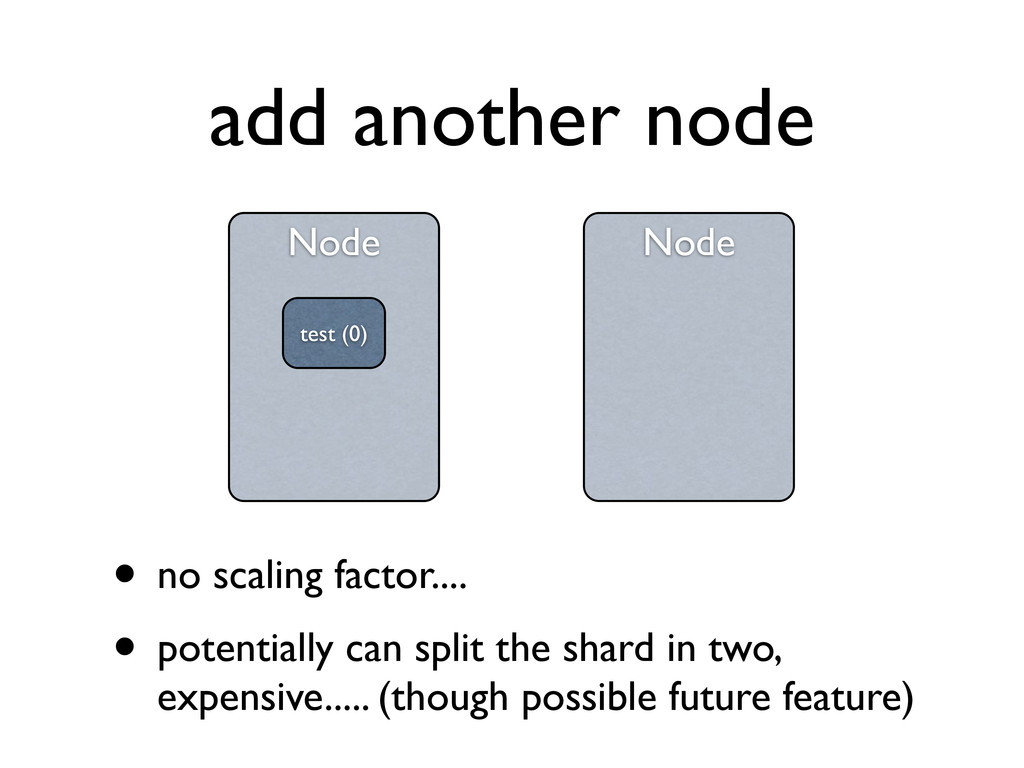
add another node Node test (1) Node Node test (0)
• no scaling factor.... • potentially can split the shard in two, expensive..... (though possible future feature) -
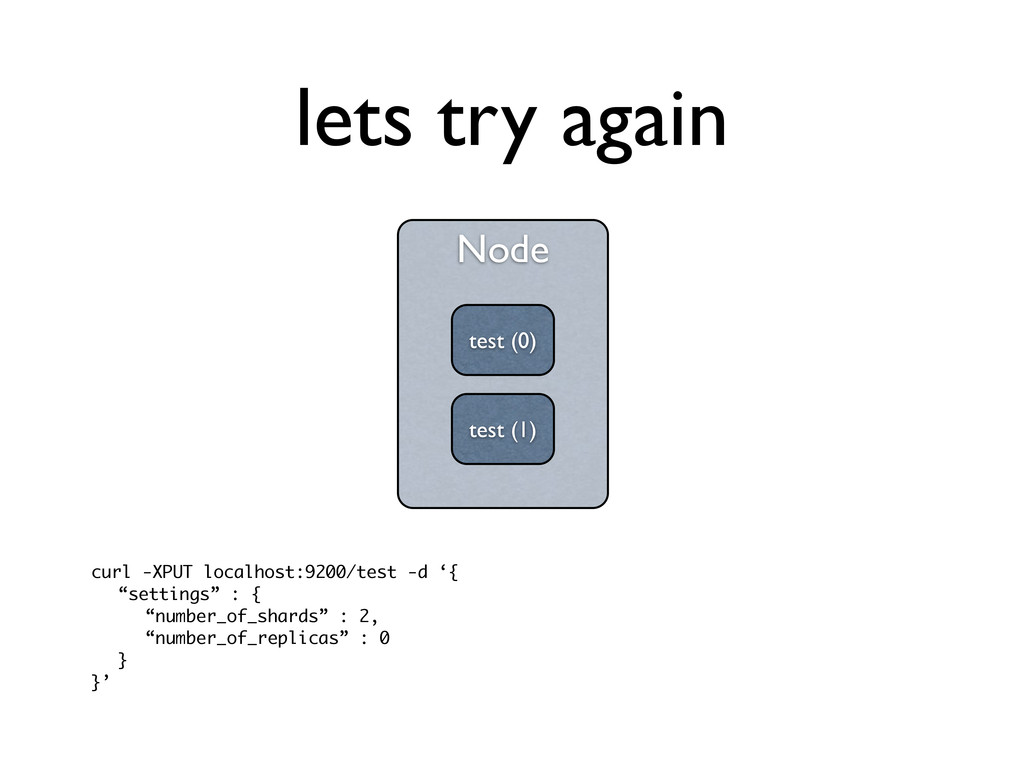
lets try again Node curl -XPUT localhost:9200/test -d ‘{ “settings”
: { “number_of_shards” : 2, “number_of_replicas” : 0 } }’ test (0) test (1) -
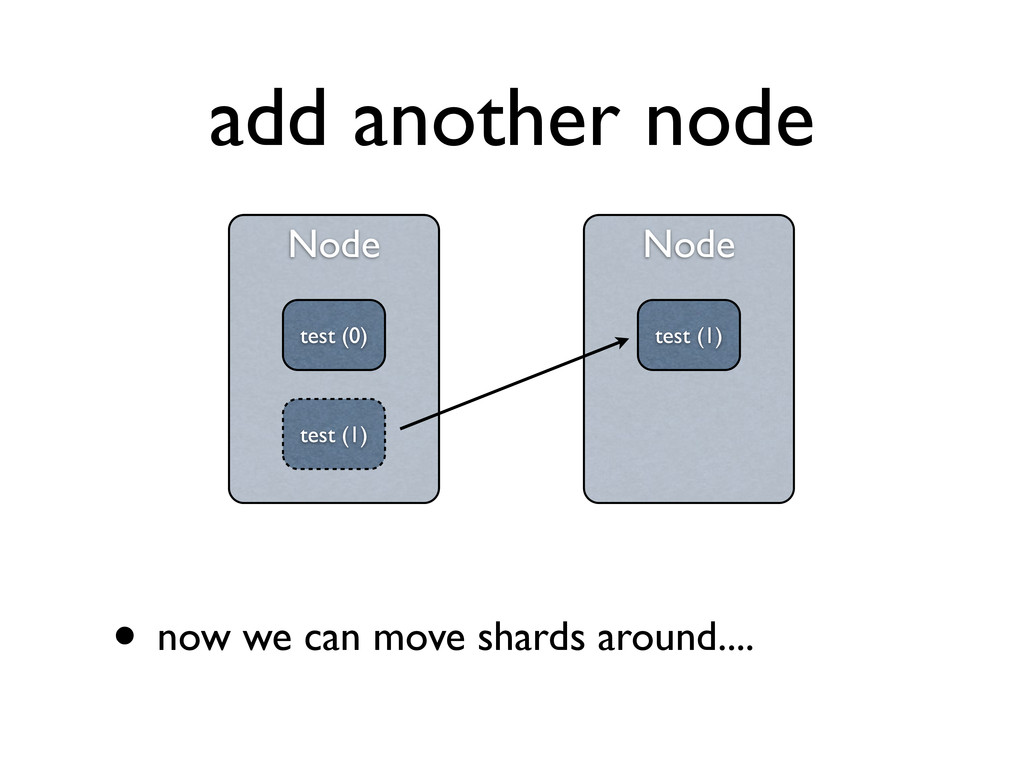
add another node Node test (1) Node Node test (0)
• now we can move shards around.... test (1) test (1) -
#shards > #nodes (overallocation) • number of shards as your
scaling unit • common architecture (others call it virtual nodes) • moving shards around is faster than splitting them (no reindex) -
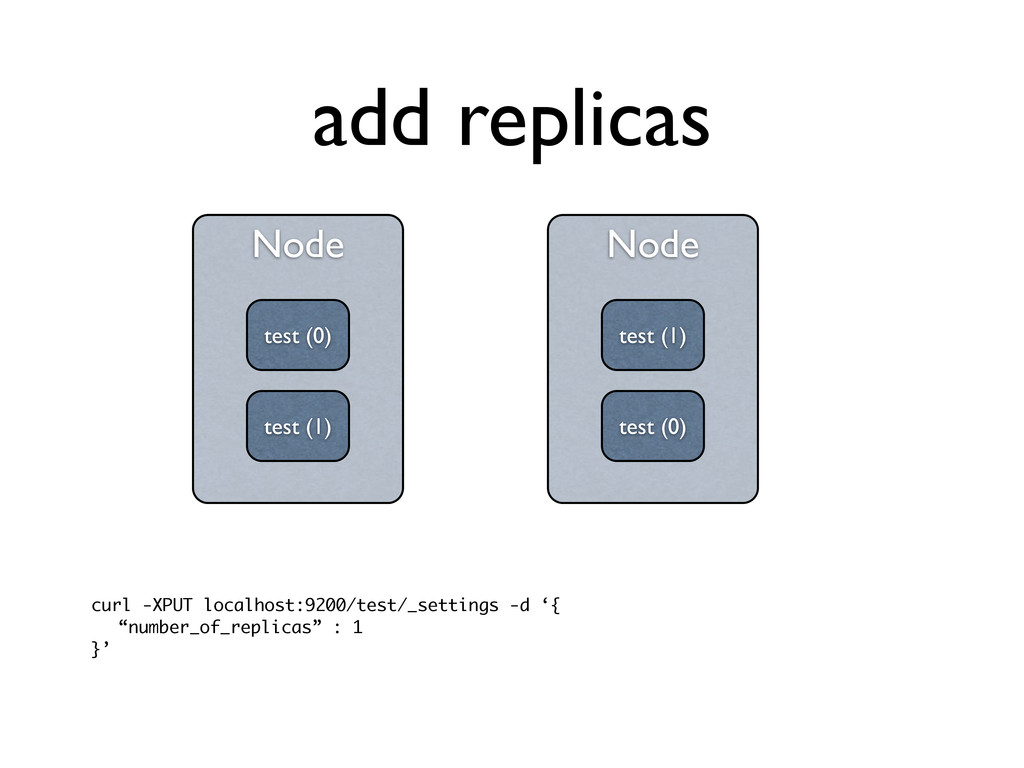
replicas • multiple copies of the data for HA (high
availability) • also serves reads, allowing to scale search -
add replicas Node test (1) Node Node test (0) test
(1) curl -XPUT localhost:9200/test/_settings -d ‘{ “number_of_replicas” : 1 }’ test (0) test (1) -
add another node Node test (1) Node Node test (0)
test (1) test (1) Node test (0) • shards move around to make use of the new nodes -
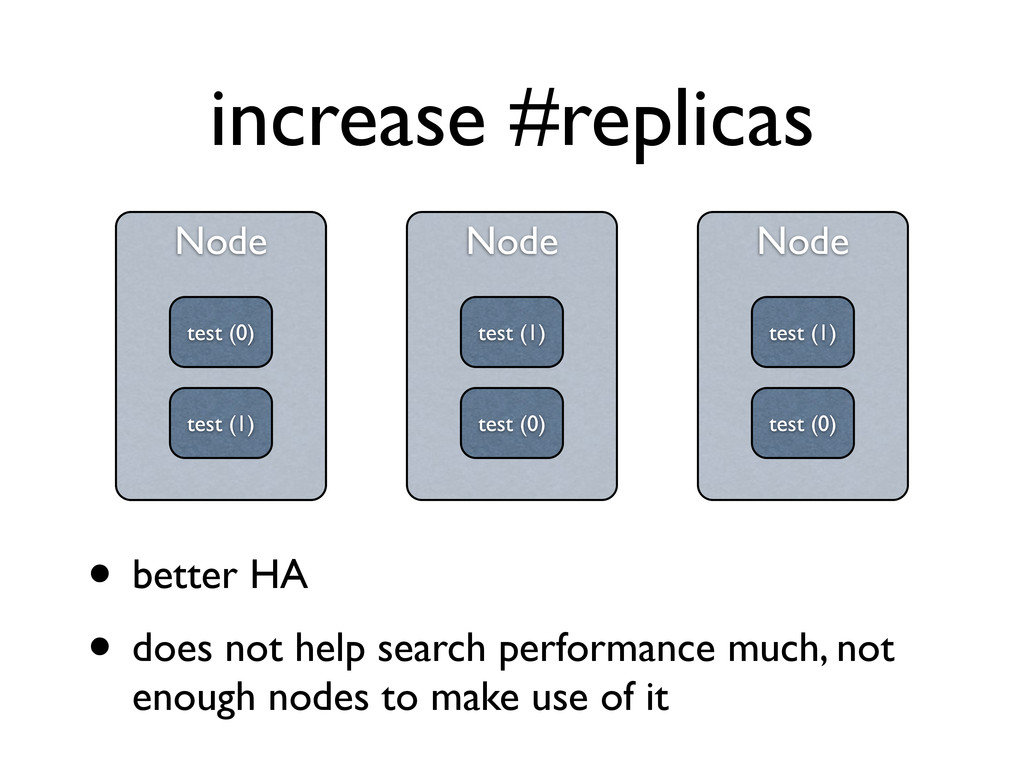
increase #replicas Node test (1) Node Node test (0) test
(1) test (1) Node test (0) • better HA • does not help search performance much, not enough nodes to make use of it test (1) test (0) -
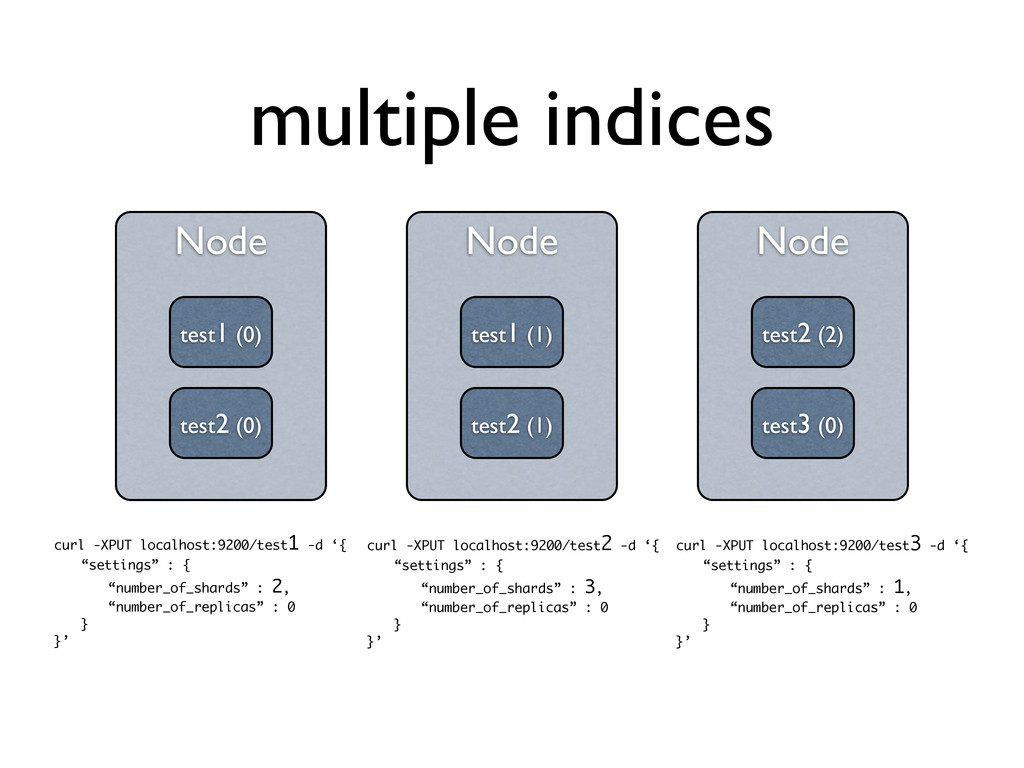
multiple indices Node test (1) Node Node test1 (0) test1
(1) test2 (0) Node test2 (2) test2 (1) test3 (0) curl -XPUT localhost:9200/test1 -d ‘{ “settings” : { “number_of_shards” : 2, “number_of_replicas” : 0 } }’ curl -XPUT localhost:9200/test2 -d ‘{ “settings” : { “number_of_shards” : 3, “number_of_replicas” : 0 } }’ curl -XPUT localhost:9200/test3 -d ‘{ “settings” : { “number_of_shards” : 1, “number_of_replicas” : 0 } }’ -
multiple indices • easily search across indices (/test1,test2,test3/_search ). •
each index can have different distributed characteristics. • searching on 1 index with 50 shards is the same as searching 50 indices with 1 shard. -
sizing • there is a “maximum” shard size • no
simple formula to it, depends on usage • usually a factor of hardware, #docs, #size, and type of searches (sort, faceting) • easy to test, just use one shard and start loading it -
sizing • there is a maximum “index” size (with no
splitting) • #shards * max_shard_size • replicas play no part here, they are only additional copies of data • need to be taken into account with *cluster* sizing -
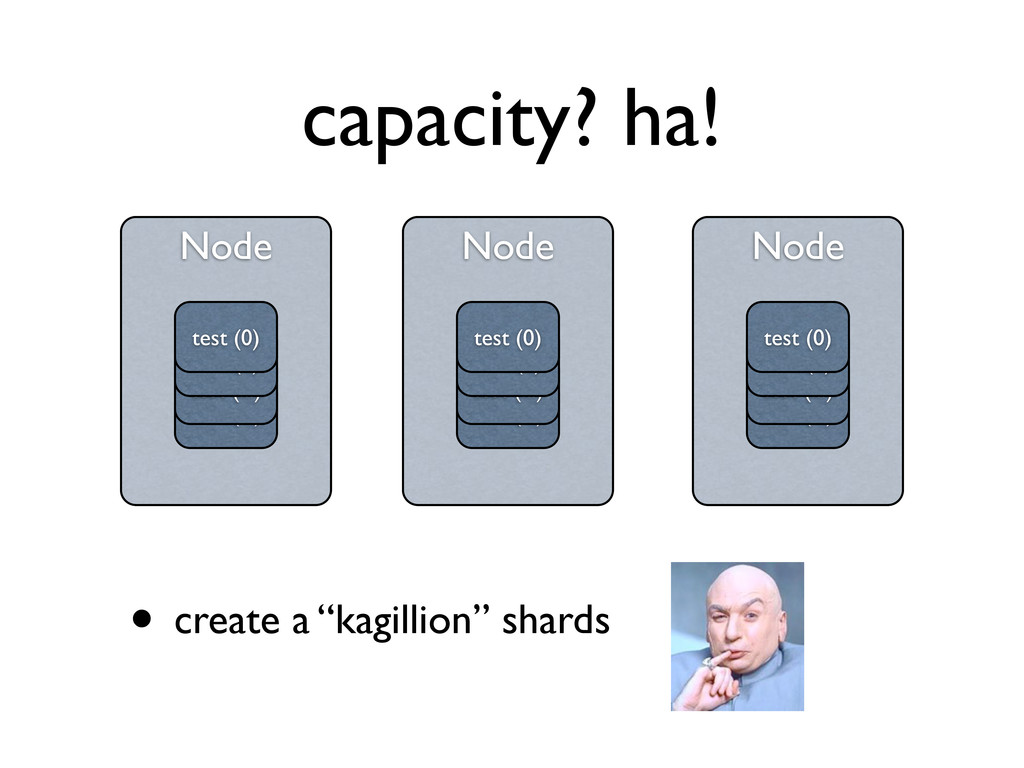
capacity? ha! • create a “kagillion” shards Node test (1)
Node test (...) test (...) test (1) test (0) Node test (1) Node test (...) test (...) test (1) test (0) Node test (1) Node test (...) test (...) test (1) test (0) -
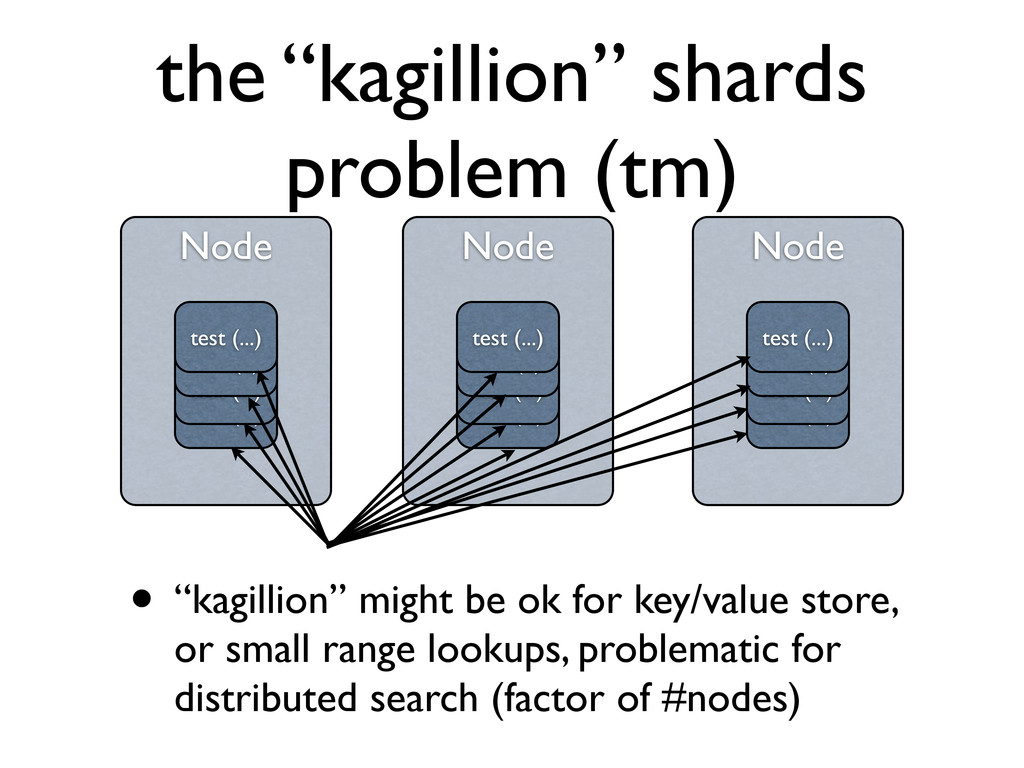
the “kagillion” shards problem (tm) • each shard comes at
a cost • lucene under the covers • file descriptors • extra memory requirements • less compactness of the total index size -
the “kagillion” shards problem (tm) • “kagillion” might be ok
for key/value store, or small range lookups, problematic for distributed search (factor of #nodes) Node test (1) Node test (...) test (...) test (1) test (...) Node test (1) Node test (...) test (...) test (1) test (...) Node test (1) Node test (...) test (...) test (1) test (...) -
sample data flows for “extreme” cases, 5 (default) or N
shards index can take you a looong way (its fast!) -
“users” data flow • each “user” has his own set
of documents • possibly big variance • most users have small number of docs • some have very large number of docs • most searches are “per user” -
“users” data flow an index per user Node test (1)
Node Node user1 (0) user1 (1) user2 (0) Node user2 (2) user2 (1) user3 (0) • each user has his own index • possibly with different sharding • search is simple! (/user1/_search) -
“users” data flow an index per user • a single
shard can hold a substantial amount of data (docs / size) • small users become “resource expensive” as they require at least 1 shard • more nodes to be able to support so many shards (remember, a shard requires system resources) -
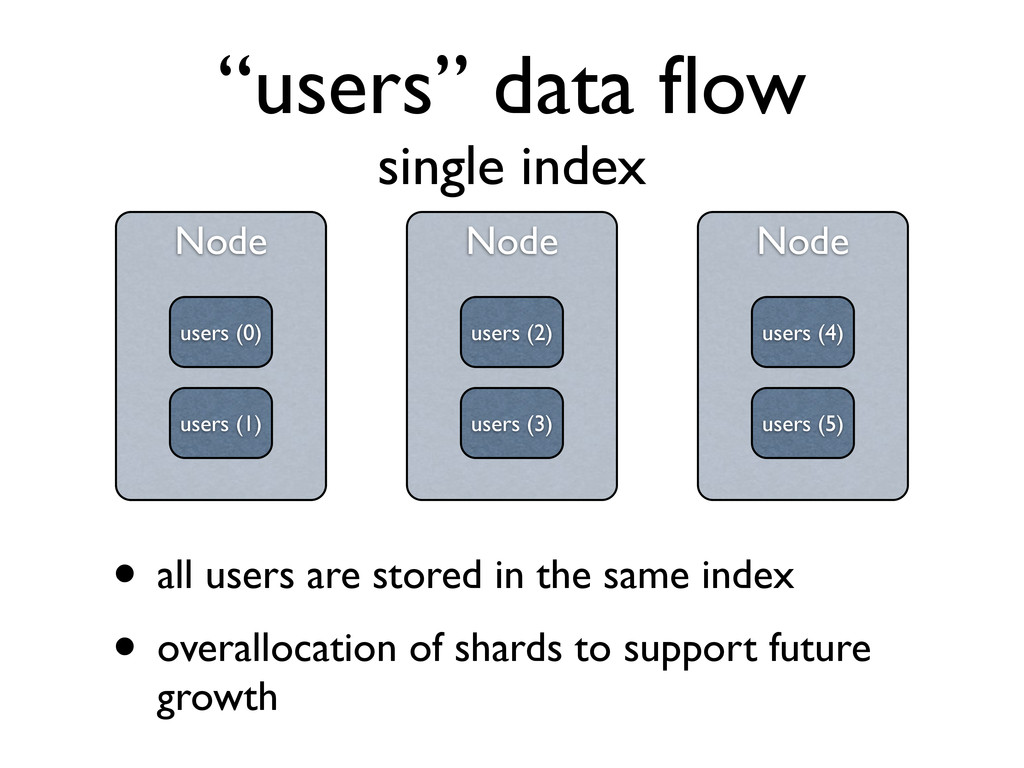
“users” data flow single index Node test (1) Node Node
users (0) users (2) users (1) Node users (4) users (3) users (5) • all users are stored in the same index • overallocation of shards to support future growth -
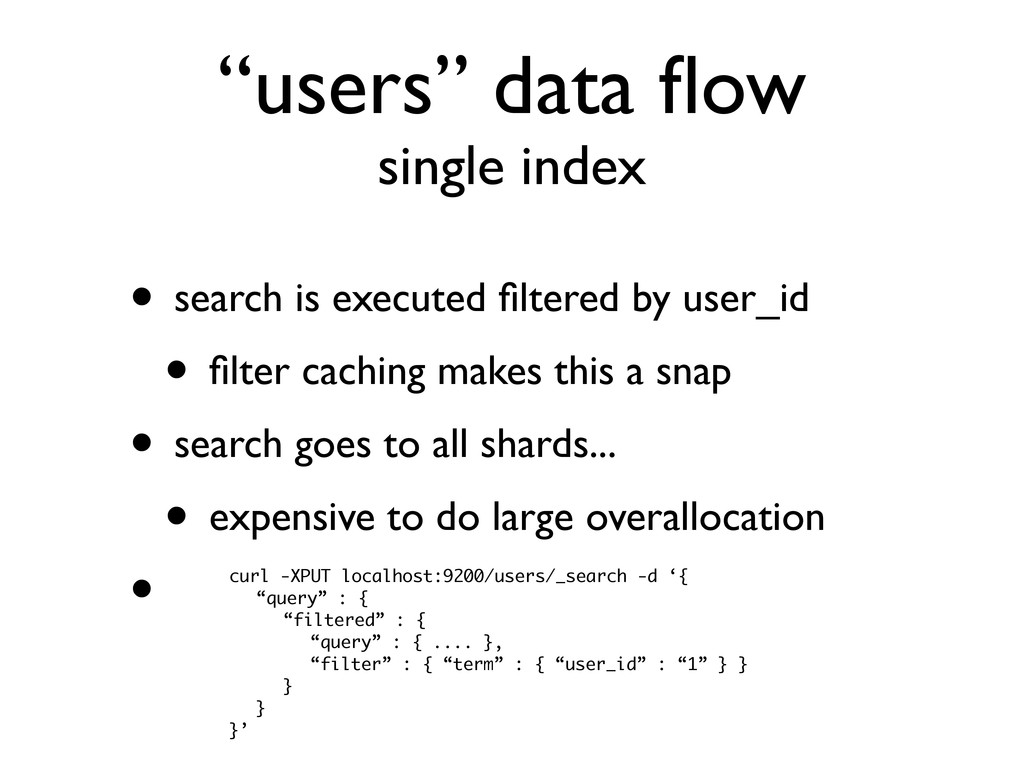
“users” data flow single index • search is executed filtered
by user_id • filter caching makes this a snap • search goes to all shards... • expensive to do large overallocation • curl -XPUT localhost:9200/users/_search -d ‘{ “query” : { “filtered” : { “query” : { .... }, “filter” : { “term” : { “user_id” : “1” } } } } }’ -
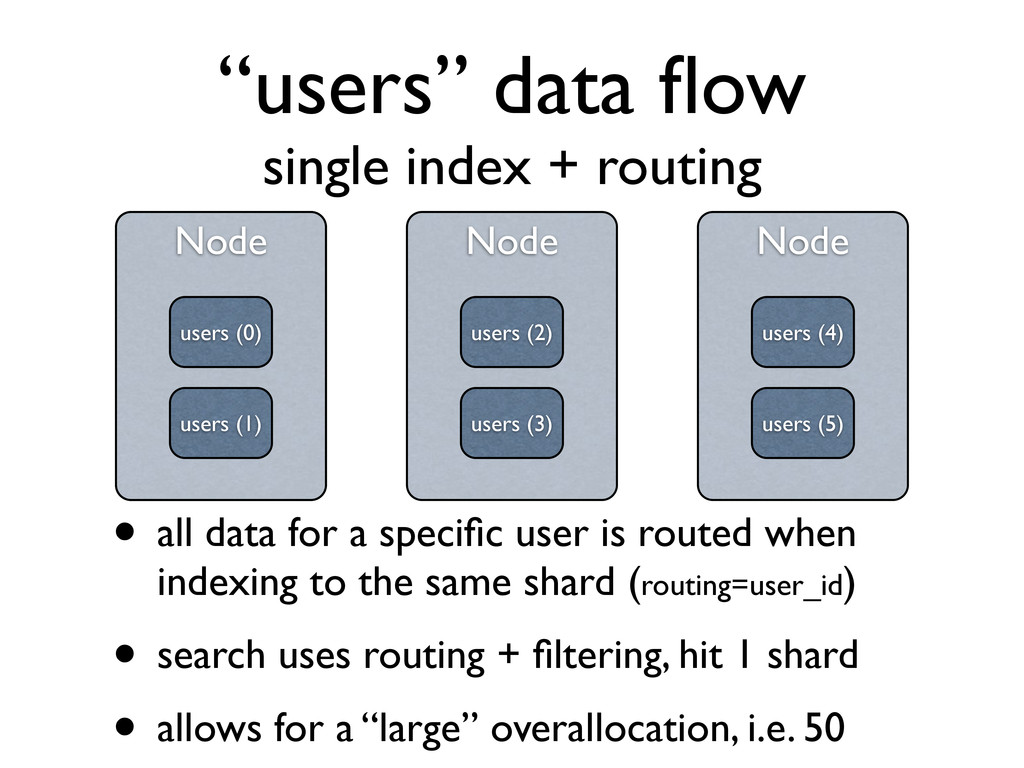
“users” data flow single index + routing Node test (1)
Node Node users (0) users (2) users (1) Node users (4) users (3) users (5) • all data for a specific user is routed when indexing to the same shard (routing=user_id) • search uses routing + filtering, hit 1 shard • allows for a “large” overallocation, i.e. 50 -
“users” data flow single index + routing • aliasing makes
this simple! curl -XPOST localhost:9200/_aliases -d '{ "actions" : [ { "add" : { “index” : “users”, “alias” : “user_1”, “filter” : { “term” : { “user” : “1” } }, “routing” : “1” } } ] }' • indexing and search happens on the “alias”, with automatic use of routing and filtering • multi alias search possible (/user_1,user_2/_search) -
“users” data flow single index + routing • Very large
users can be migrated to their own respective indices • The “alias” of the user now points to its own index (no routing / filtering needed), with its own set of shards -
“time” data flow • time base data (specifically, range enabled)
• logs, social stream, time events • docs have a “timestamp”, don’t change (much) • search usually ranged on the “timestamp” -
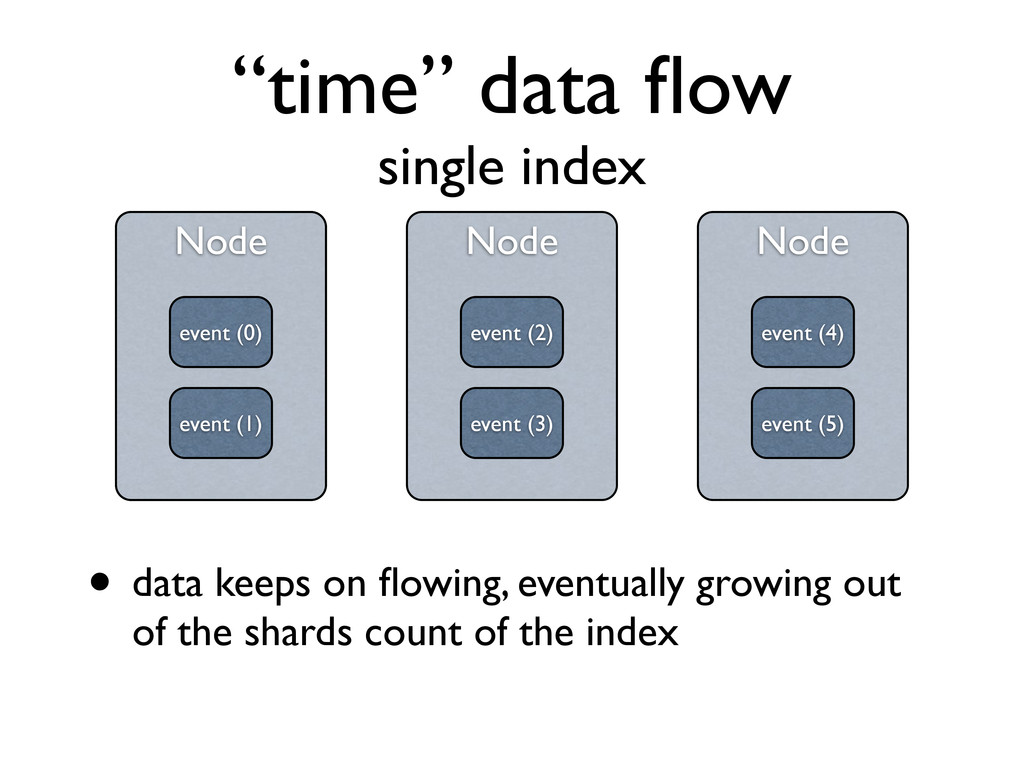
“time” data flow single index Node test (1) Node Node
event (0) event (2) event (1) Node event (4) event (3) event (5) • data keeps on flowing, eventually growing out of the shards count of the index -
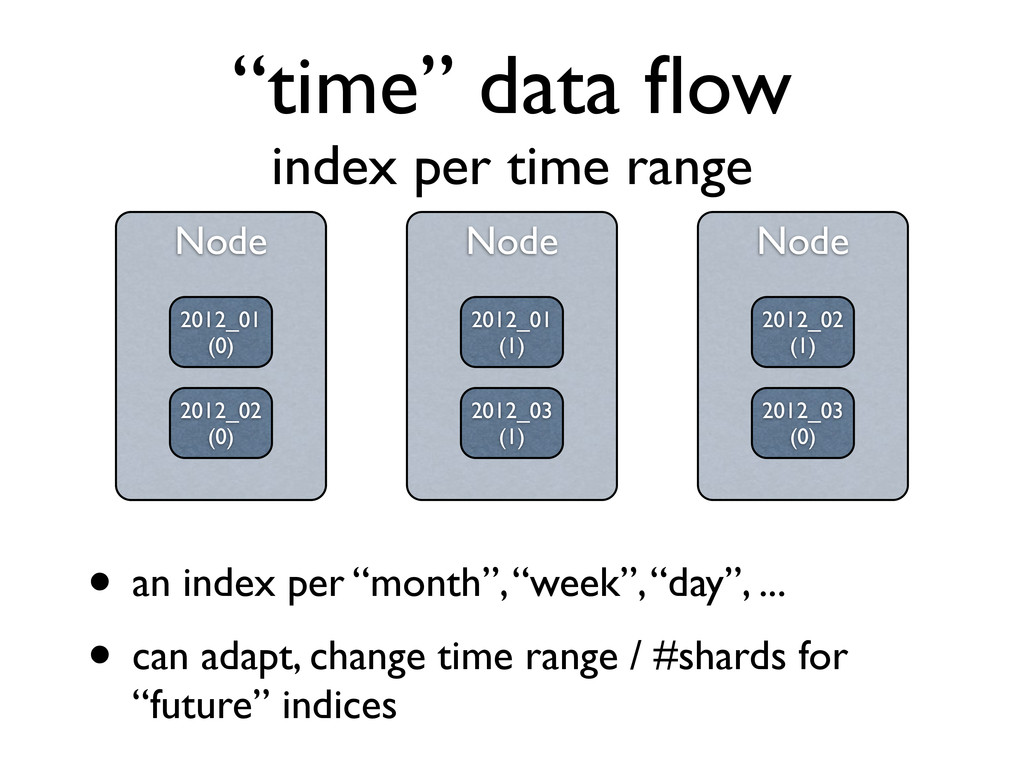
“time” data flow index per time range Node test (1)
Node Node 2012_01 (0) 2012_01 (1) 2012_02 (0) Node 2012_02 (1) 2012_03 (1) 2012_03 (0) • an index per “month”, “week”, “day”, ... • can adapt, change time range / #shards for “future” indices -
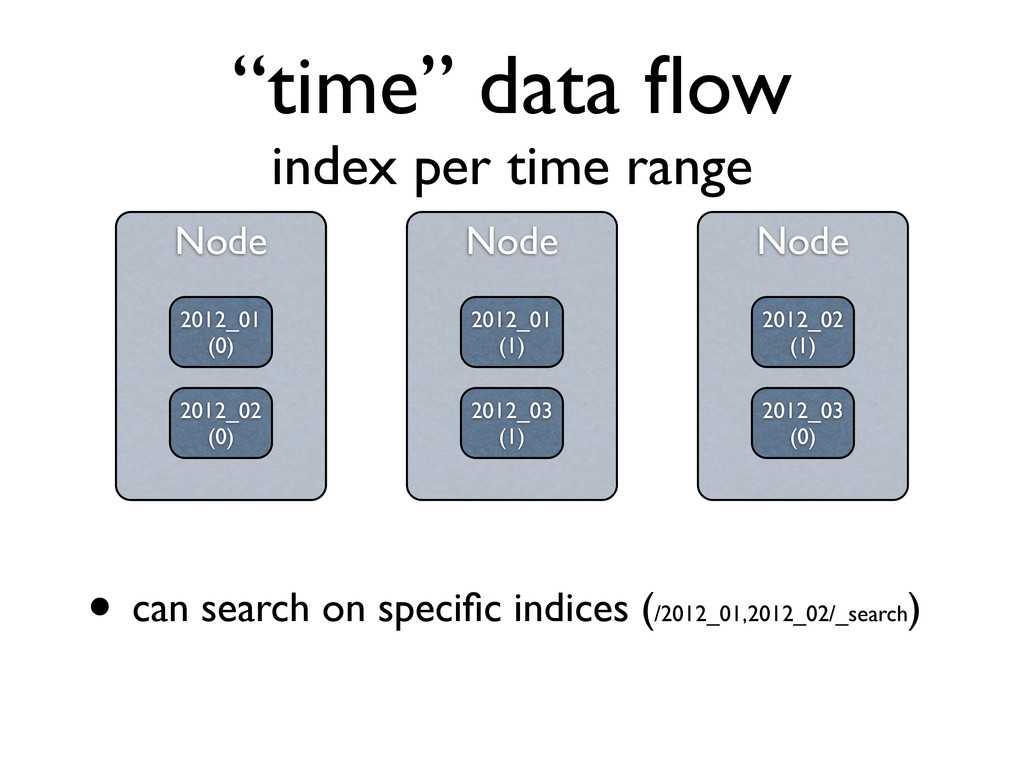
“time” data flow index per time range Node test (1)
Node Node 2012_01 (0) 2012_01 (1) 2012_02 (0) Node 2012_02 (1) 2012_03 (1) 2012_03 (0) • can search on specific indices (/2012_01,2012_02/_search ) -
“time” data flow index per time range • aliases simplifies
it! curl -XPOST localhost:9200/_aliases -d '{ "actions" : [ { "add" : { “index” : “2012_03”, “alias” : “last_2_months”, }, “remove” : { “index” : “2012_01”, “alias” : “last_2_months” } } ] }' -
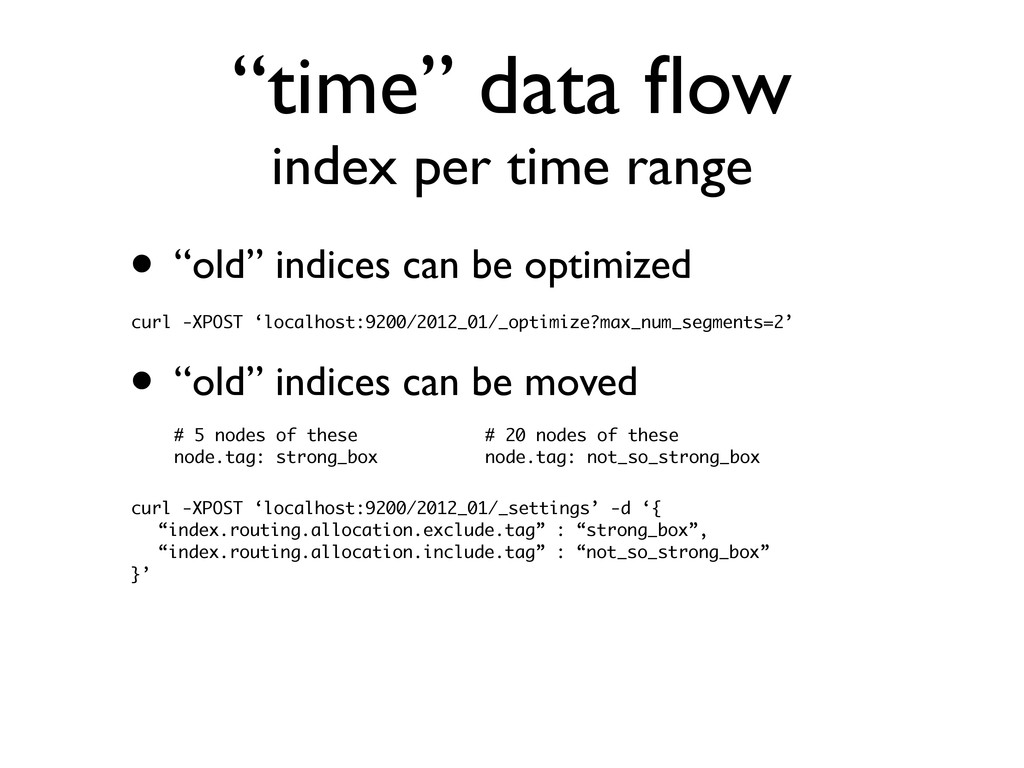
“time” data flow index per time range • “old” indices
can be optimized curl -XPOST ‘localhost:9200/2012_01/_optimize?max_num_segments=2’ • “old” indices can be moved curl -XPOST ‘localhost:9200/2012_01/_settings’ -d ‘{ “index.routing.allocation.exclude.tag” : “strong_box”, “index.routing.allocation.include.tag” : “not_so_strong_box” }’ # 5 nodes of these node.tag: strong_box # 20 nodes of these node.tag: not_so_strong_box -
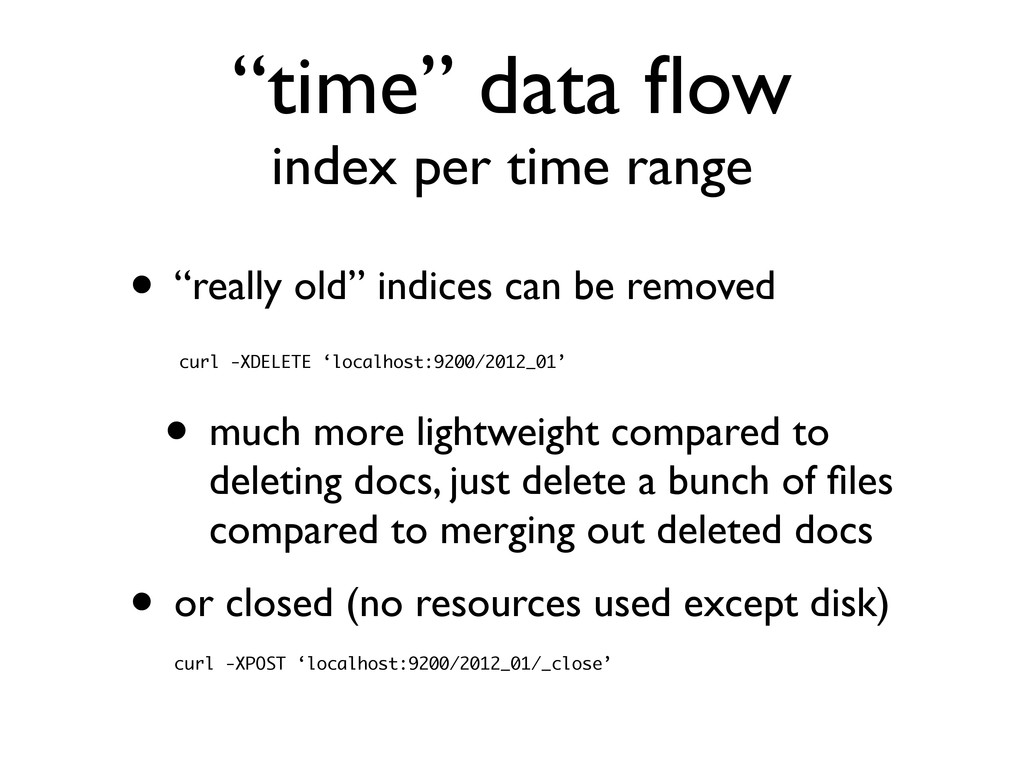
“time” data flow index per time range • “really old”
indices can be removed • much more lightweight compared to deleting docs, just delete a bunch of files compared to merging out deleted docs • or closed (no resources used except disk) curl -XDELETE ‘localhost:9200/2012_01’ curl -XPOST ‘localhost:9200/2012_01/_close’ -
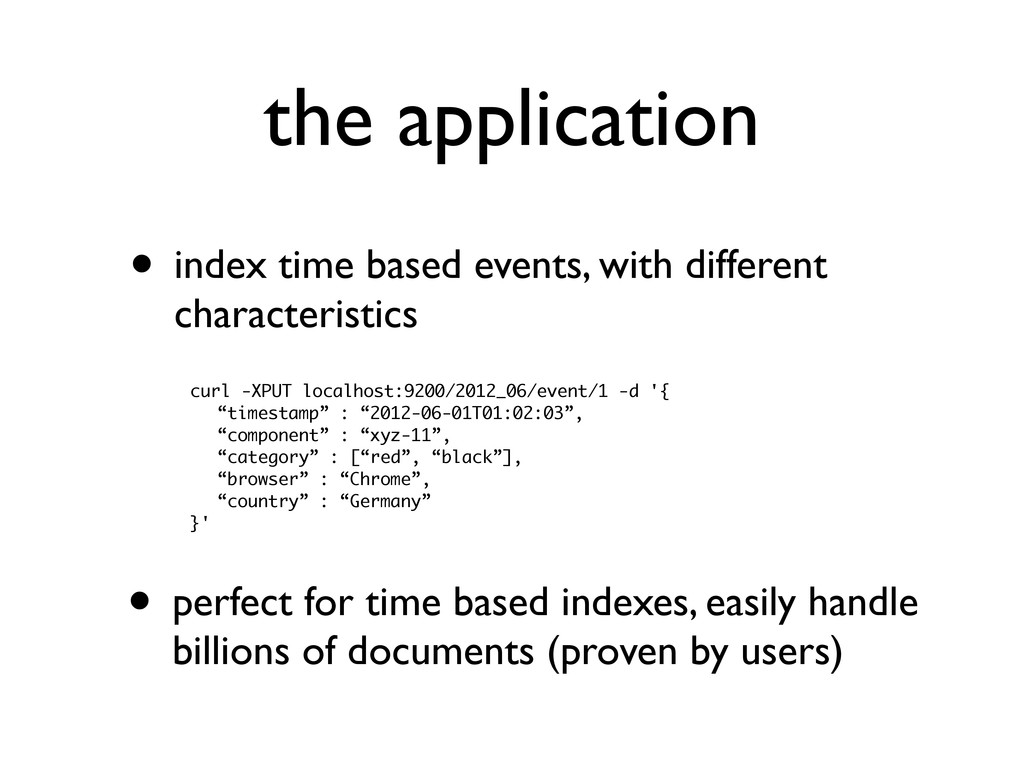
the application • index time based events, with different characteristics
curl -XPUT localhost:9200/2012_06/event/1 -d '{ “timestamp” : “2012-06-01T01:02:03”, “component” : “xyz-11”, “category” : [“red”, “black”], “browser” : “Chrome”, “country” : “Germany” }' • perfect for time based indexes, easily handle billions of documents (proven by users) -
slice & dice • no need to decide in advance
how to slice and dice your data • for example, no need to decide in advance on the “key” structure for different range scans -
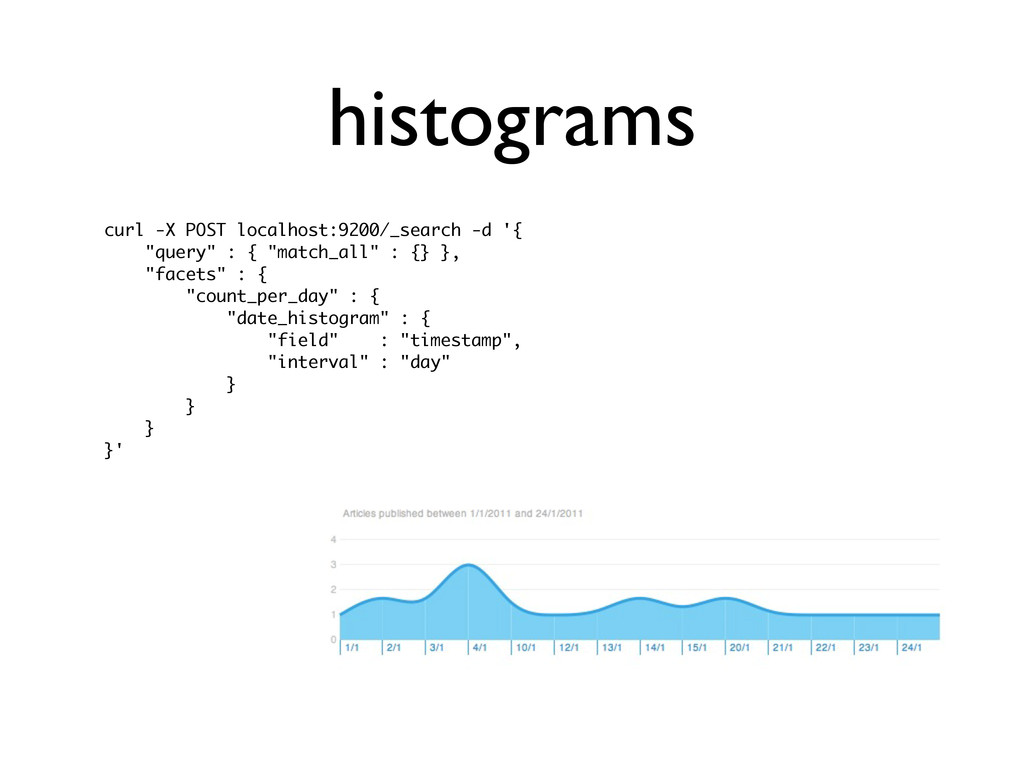
histograms curl -X POST localhost:9200/_search -d '{ "query" : {
"match_all" : {} }, "facets" : { "count_per_day" : { "date_histogram" : { "field" : "timestamp", "interval" : "day" } } } }' -
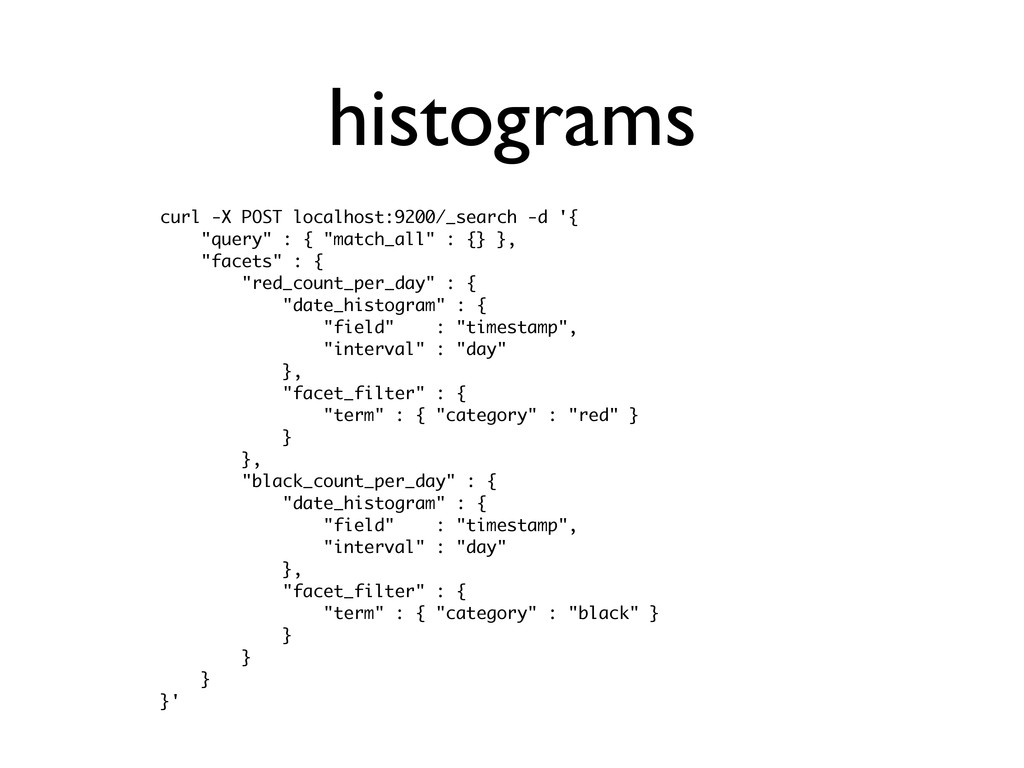
histograms curl -X POST localhost:9200/_search -d '{ "query" : {
"match_all" : {} }, "facets" : { "red_count_per_day" : { "date_histogram" : { "field" : "timestamp", "interval" : "day" }, "facet_filter" : { "term" : { "category" : "red" } } }, "black_count_per_day" : { "date_histogram" : { "field" : "timestamp", "interval" : "day" }, "facet_filter" : { "term" : { "category" : "black" } } } } }' -
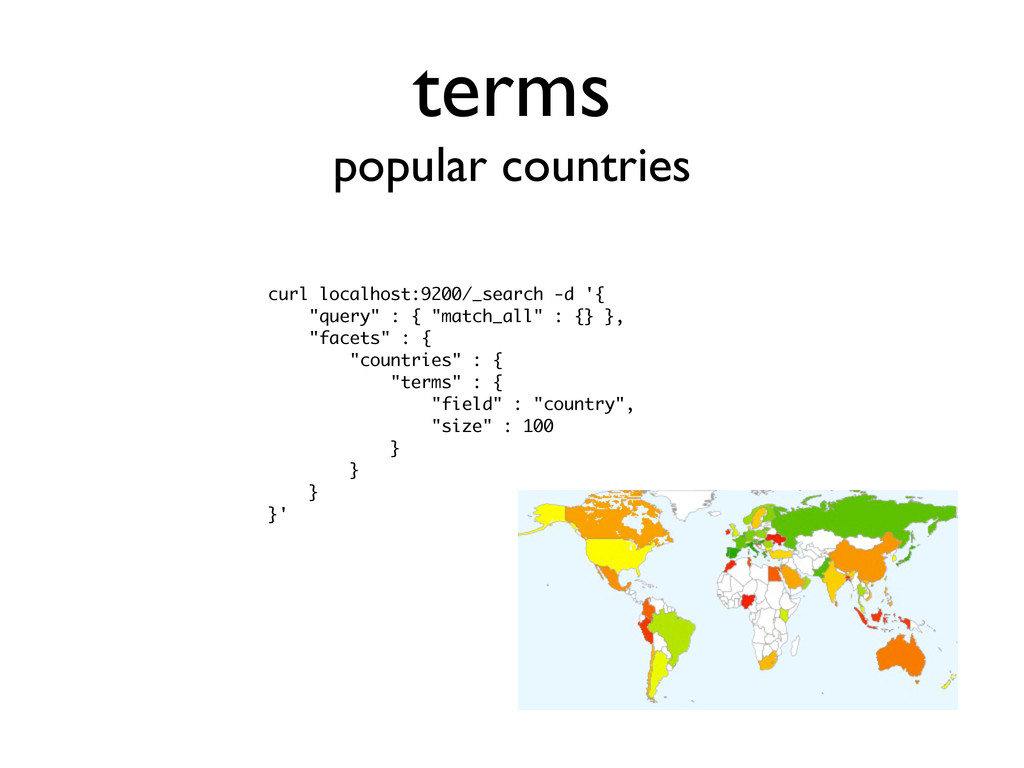
terms popular countries curl localhost:9200/_search -d '{ "query" : {
"match_all" : {} }, "facets" : { "countries" : { "terms" : { "field" : "country", "size" : 100 } } } }' -
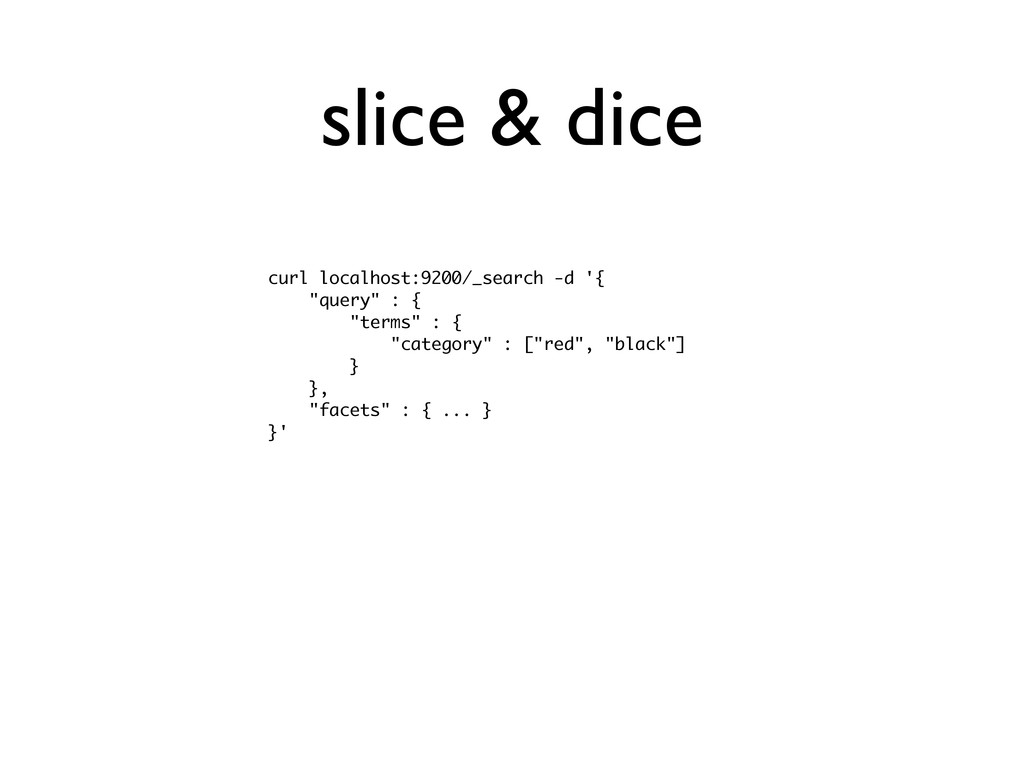
slice & dice curl localhost:9200/_search -d '{ "query" : {
"terms" : { "category" : ["red", "black"] } }, "facets" : { ... } }' -
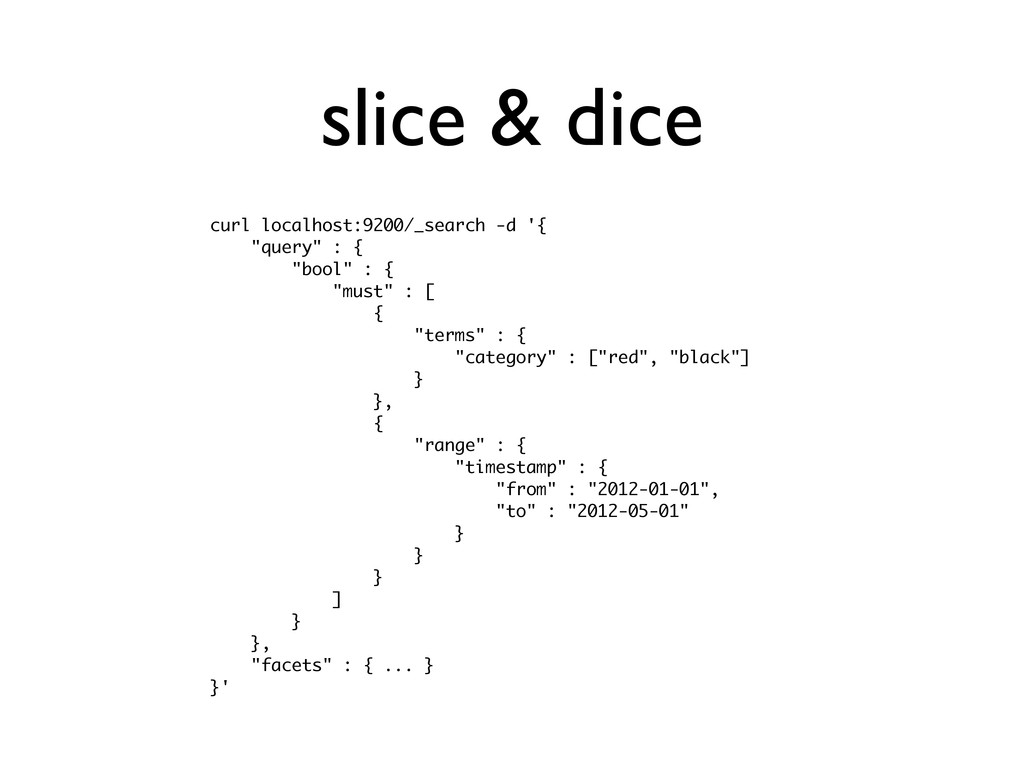
slice & dice curl localhost:9200/_search -d '{ "query" : {
"bool" : { "must" : [ { "terms" : { "category" : ["red", "black"] } }, { "range" : { "timestamp" : { "from" : "2012-01-01", "to" : "2012-05-01" } } } ] } }, "facets" : { ... } }' -
more.... • more facets options (terms stats, scripting, value aggregations...)
• filters play a major part in “slice & dice” (great caching story) • full text search? :)