Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Improving Data Gathering And Research
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Luca Matteis
November 26, 2011
Programming
160
2
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Improving Data Gathering And Research
How to improve data gathering using web scraping methodologies.
Luca Matteis
November 26, 2011
More Decks by Luca Matteis
See All by Luca Matteis
Linked Open Data
lmatteis
1
140
What I do
lmatteis
1
90
Crop Ontology
lmatteis
1
99
Why NPM rocks!
lmatteis
2
310
Informatics Development Tools
lmatteis
0
120
Other Decks in Programming
See All in Programming
mrbgem 三角測量 開発
ogom
0
150
UnityでSystem.Net.WebSocketsなWebSocketサーバが動かないのでUnity Monoのコードを覗いてみた / about implementing websocket server with unity mono
drumath2237
1
510
AHC070解法紹介
eijirou
0
140
Augmenting AI with the Power of Jakarta EE
ivargrimstad
0
360
Go × SIMDで高速化するベクトル検索 ~ルーフラインモデルでSIMDが効く境界を探れ! ~
po3rin
1
5.1k
難しいけど、読めた。- OSSの入口に立った話。
sts11142
0
130
MVNOの申込からeSIM開通までをiOSアプリでつなぐ- 本人確認・MNP・通信事業者基盤をまたぐ実装
satotakeshi
0
510
AgentCore CLI で進化した AWS での AI エージェントの作り方 : 必要な機能を必要な時に
icoxfog417
PRO
4
400
iOS 27でニュースアプリはどう変わる!? 〜日経電子版の新機能対応と、開発事例から〜
lynnswap
7
13k
市販E-Readerを乗っ取れ 〜Embedded Swiftで電子ペーパーガジェットを制御する〜
trickart
0
220
Augmenting AI with the Power of Jakarta EE
ivargrimstad
0
360
【高い買い物LT会】初任給で話題の国産フィジカルAIを買った話
akagami
PRO
0
180
Featured
See All Featured
Lightning Talk: Beautiful Slides for Beginners
inesmontani
PRO
2
710
AI in Enterprises - Java and Open Source to the Rescue
ivargrimstad
0
1.5k
Beyond borders and beyond the search box: How to win the global "messy middle" with AI-driven SEO
davidcarrasco
3
270
Mozcon NYC 2025: Stop Losing SEO Traffic
samtorres
1
560
HTML-Aware ERB: The Path to Reactive Rendering @ RubyCon 2026, Rimini, Italy
marcoroth
5
750
Building Adaptive Systems
keathley
44
3.2k
Connecting the Dots Between Site Speed, User Experience & Your Business [WebExpo 2025]
tammyeverts
11
1k
BBQ
matthewcrist
89
10k
Redefining SEO in the New Era of Traffic Generation
szymonslowik
1
450
Game over? The fight for quality and originality in the time of robots
wayneb77
1
290
Let's Do A Bunch of Simple Stuff to Make Websites Faster
chriscoyier
508
140k
Everyday Curiosity
cassininazir
0
330
Transcript
RESEARCH IMPROVING DATA GATHERING & Luca Matteis
What is Research?
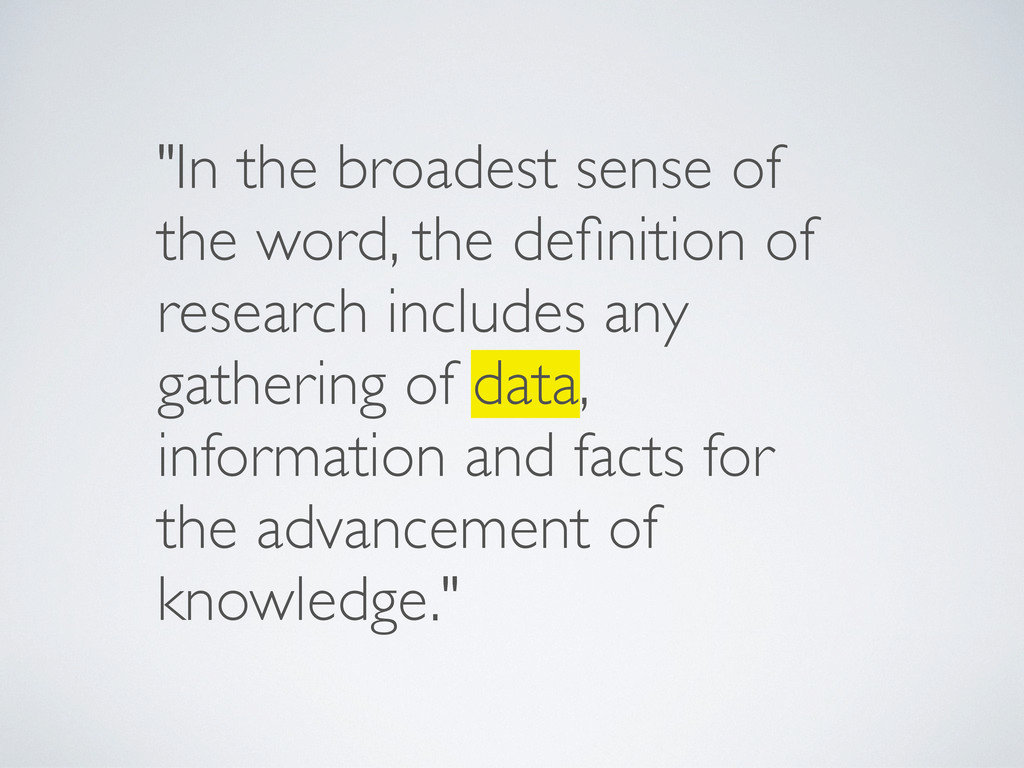
"In the broadest sense of the word, the definition of
research includes any gathering of data, information and facts for the advancement of knowledge."
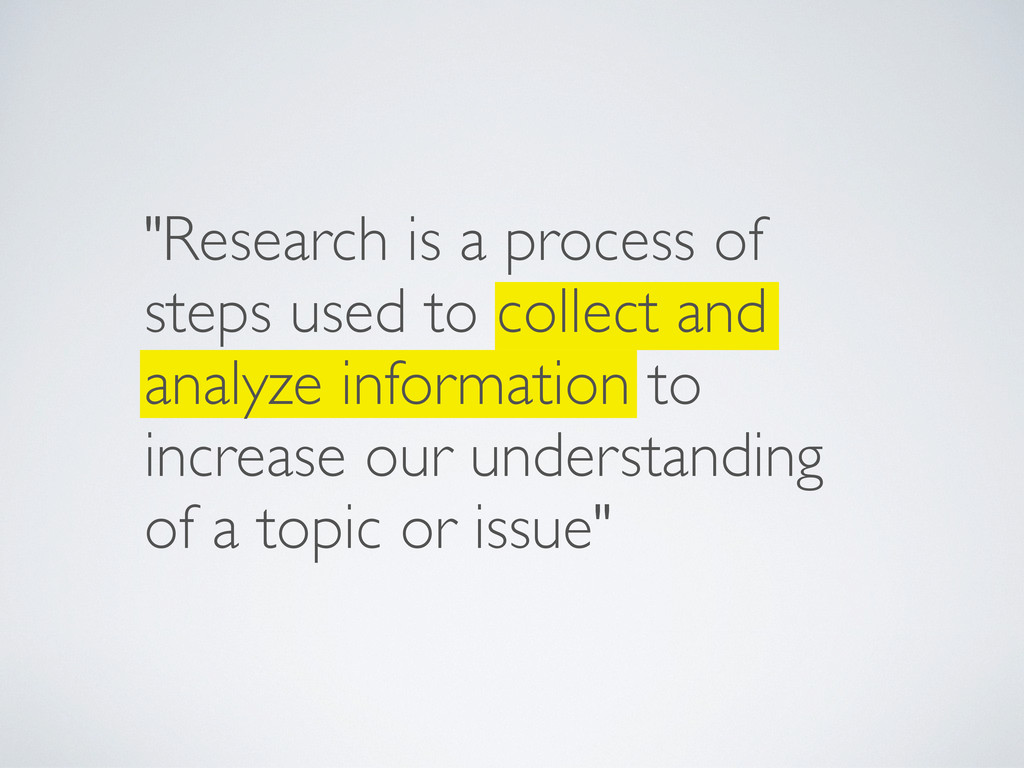
"Research is a process of steps used to collect and
analyze information to increase our understanding of a topic or issue"
Data is essential for research
Where do we get data from? Einstein got his data
from his own experiments and from other peoples experiments Information exchange took weeks if not months
Today we have the internet! Information exchange takes milliseconds Works
much better than anything Einstein had
BUT THERE’S STILL ISSUES
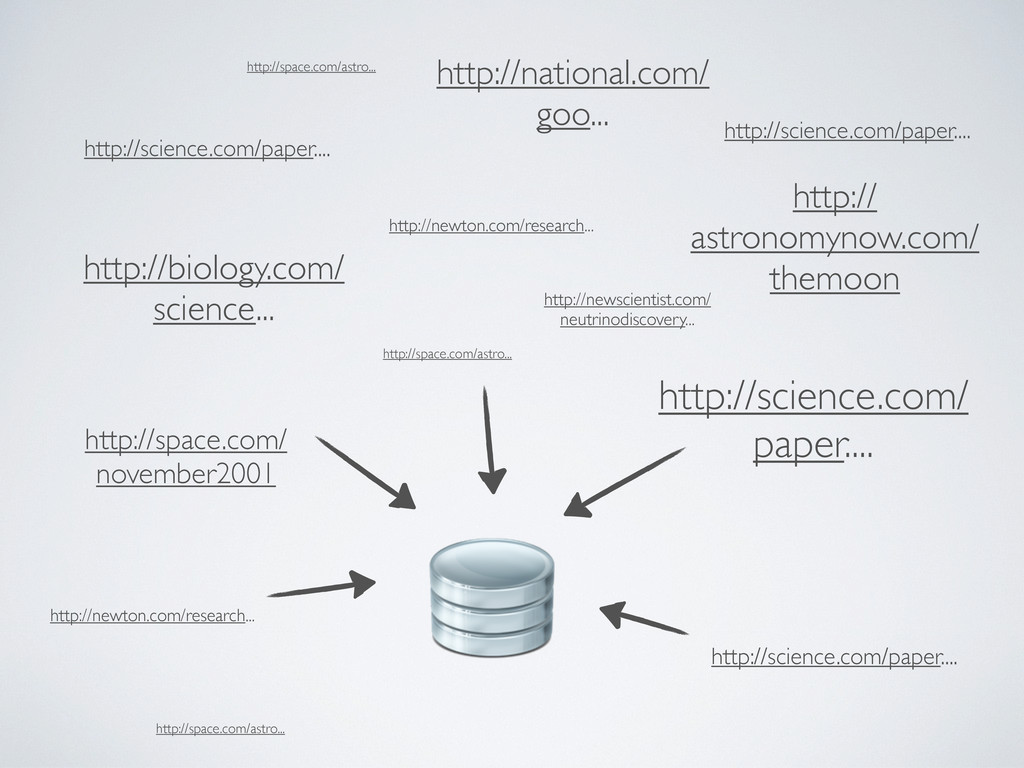
DATA IS SCATTERED ALL OVER THE WEB
http://science.com/paper.... http://newton.com/research... http://national.com/ goo... http://biology.com/ science... http://newscientist.com/ neutrinodiscovery... http:// astronomynow.com/
themoon http://space.com/ november2001 http://science.com/ paper.... http://newton.com/research... http://science.com/paper.... http://space.com/astro... http://space.com/astro... http://space.com/astro... http://science.com/paper....
Information that can be extremely valuable, lives somewhere online and
we don’t know it because we can’t find it
EVEN WITH GOOGLE, IT’S STILL HARD TO FIND WHAT WE
NEED
Scientific data searching is facilitated if there is a central
repository or data bank
http://science.com/paper.... http://newton.com/research... http://national.com/ goo... http://biology.com/ science... http://newscientist.com/ neutrinodiscovery... http:// astronomynow.com/
themoon http://space.com/ november2001 http://science.com/ paper.... http://newton.com/research... http://science.com/paper.... http://space.com/astro... http://space.com/astro... http://space.com/astro... http://science.com/paper....
When our information is centralized by context, we can more
easily find what we’re looking for
We already have websites that centralize this information
And allow us to find data that Google couldn’t
BUT THERE’S ROOM FOR IMPROVEMENT
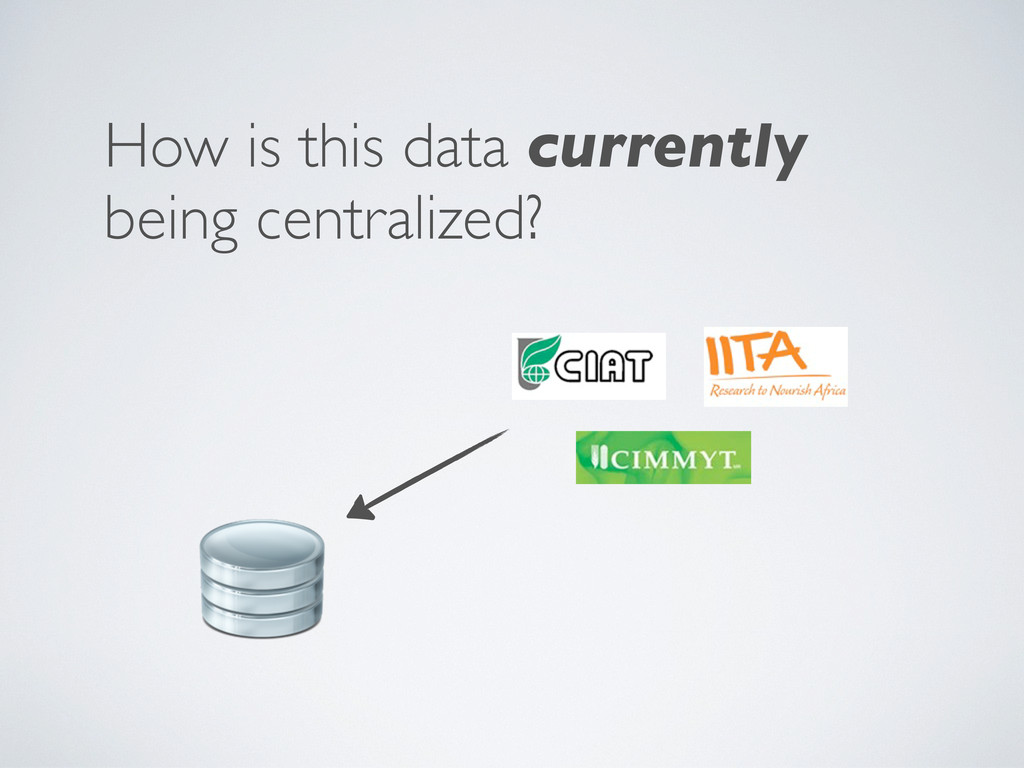
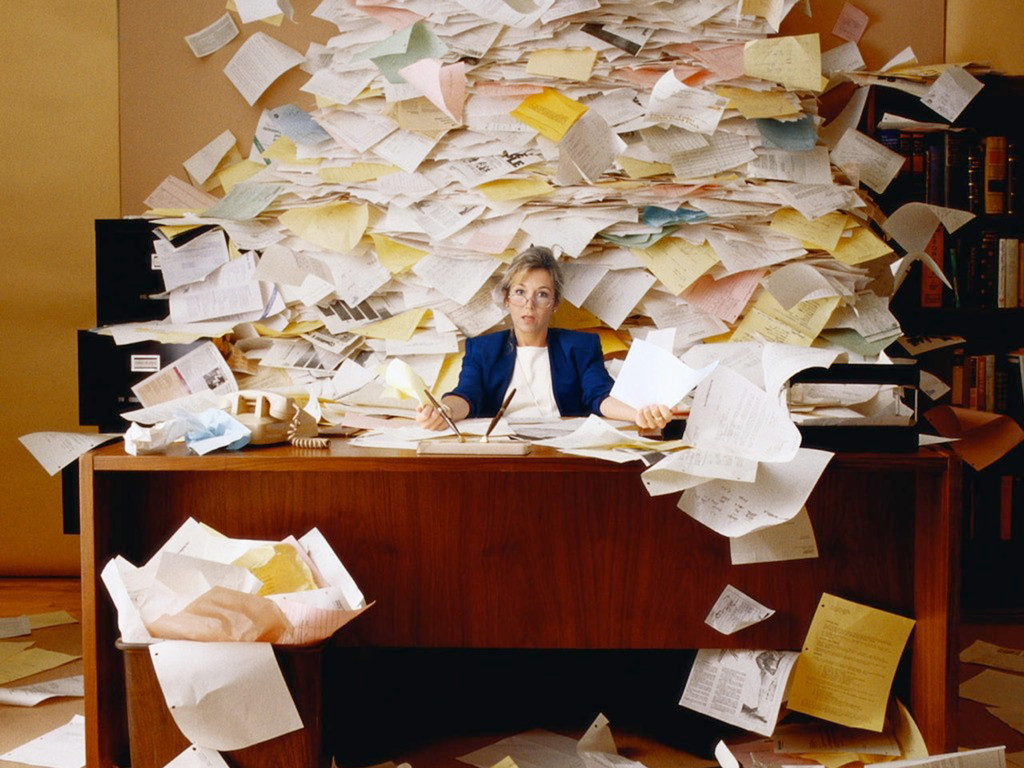
How is this data currently being centralized?
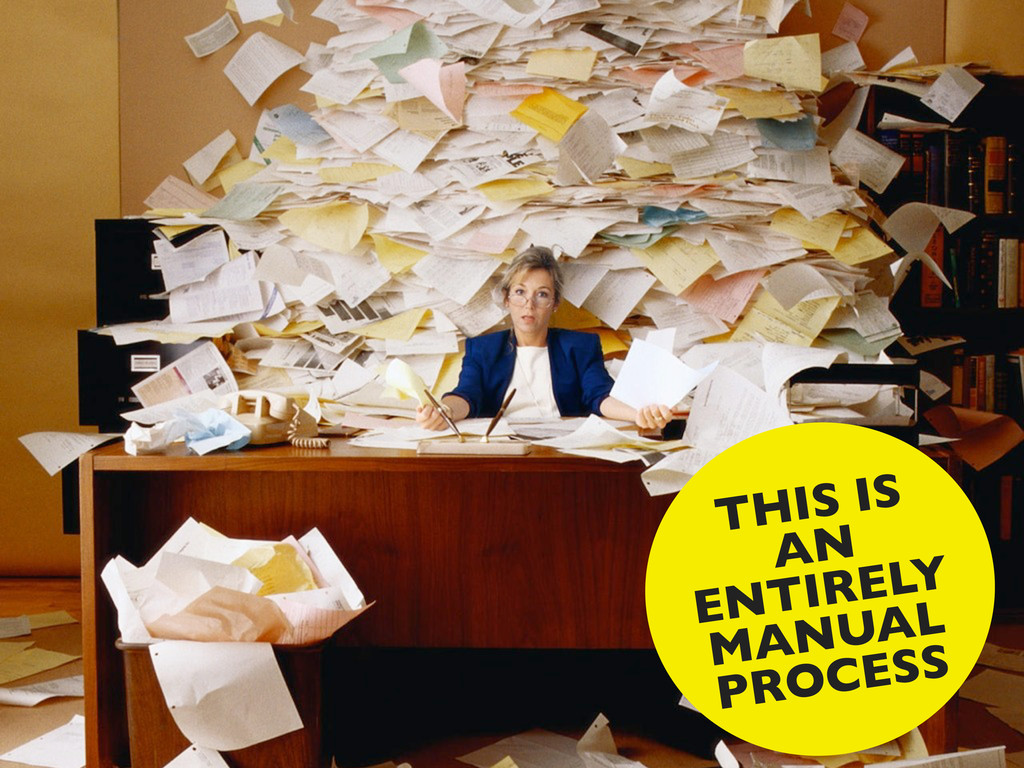
Each center sends us their data in the form of
Excel or Access files, through FTP or Email
None
THIS IS AN ENTIRELY MANUAL PROCESS
Is this sustainable?
Is this sustainable? This process needs to be automated
• no human interference • less communication hassles • less
human errors • more accurate data • more data What are the advantages of automating the data exchange process?
How do we automate? Centers no longer have to send
us anything. We get it directly from their website
There’s no secret. Google, hotel sites, flight search engines and
many others do this It is called web scraping
How does it work
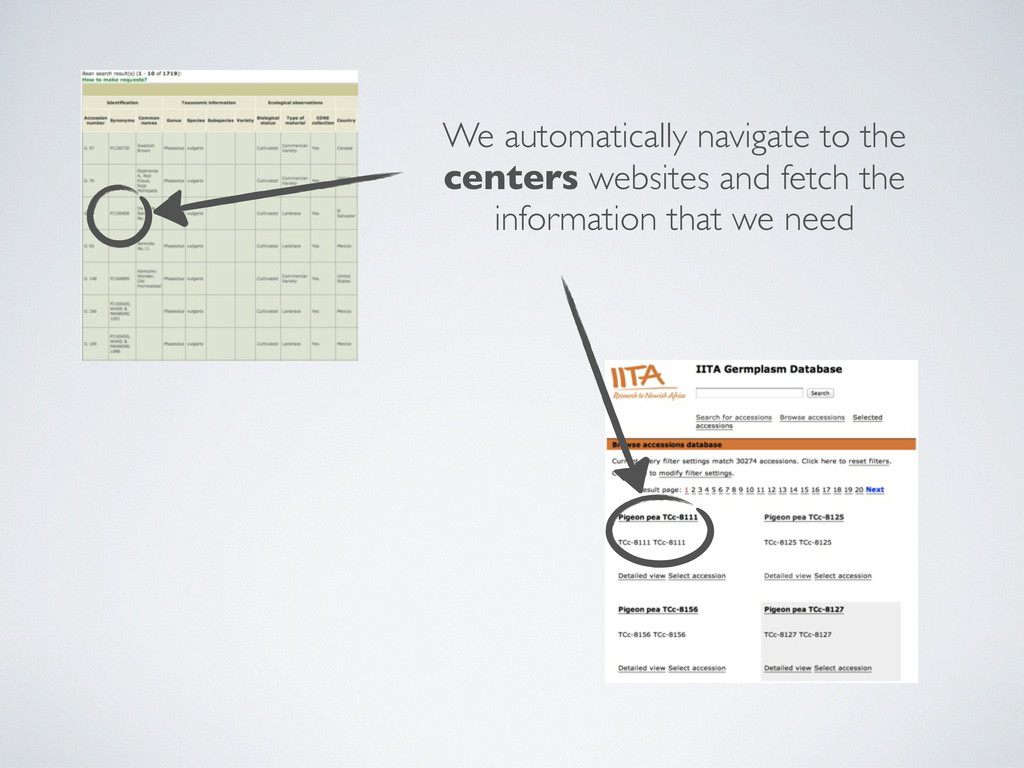
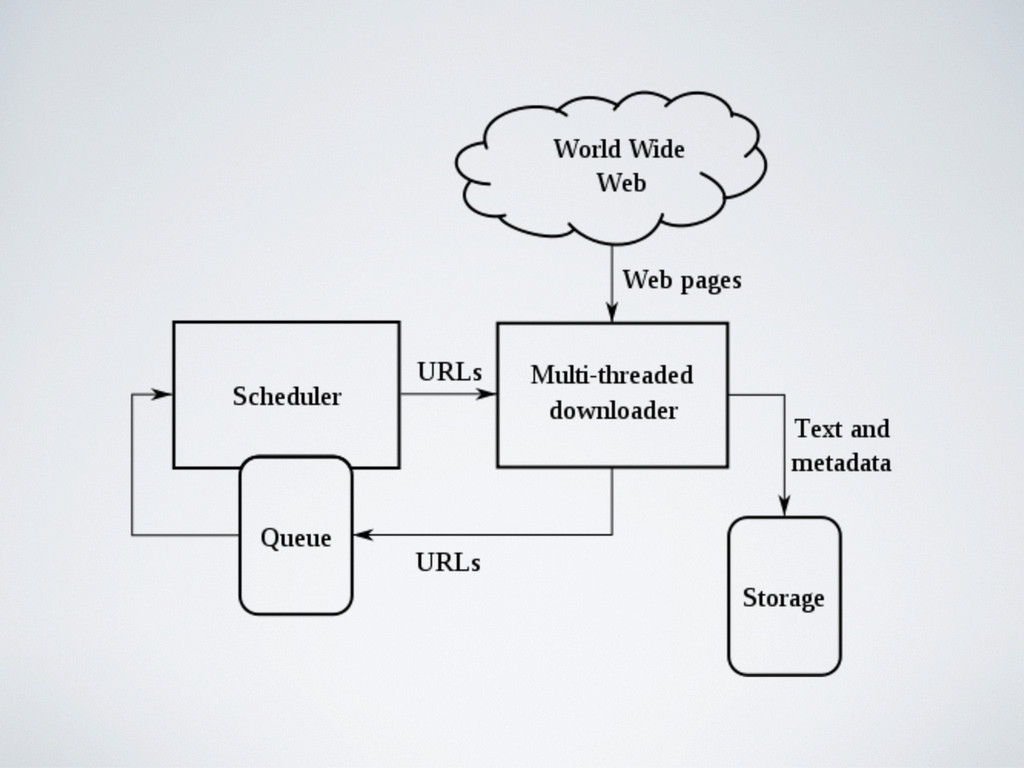
We automatically navigate to the centers websites and fetch the
information that we need
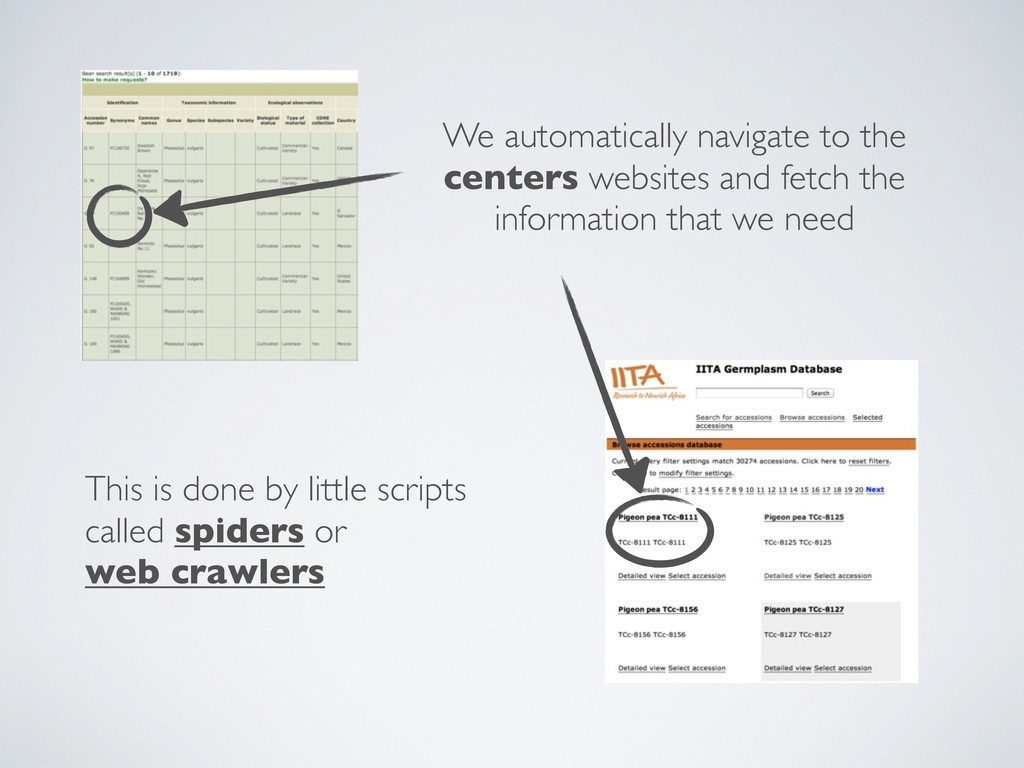
We automatically navigate to the centers websites and fetch the
information that we need This is done by little scripts called spiders or web crawlers
What? Spiders?
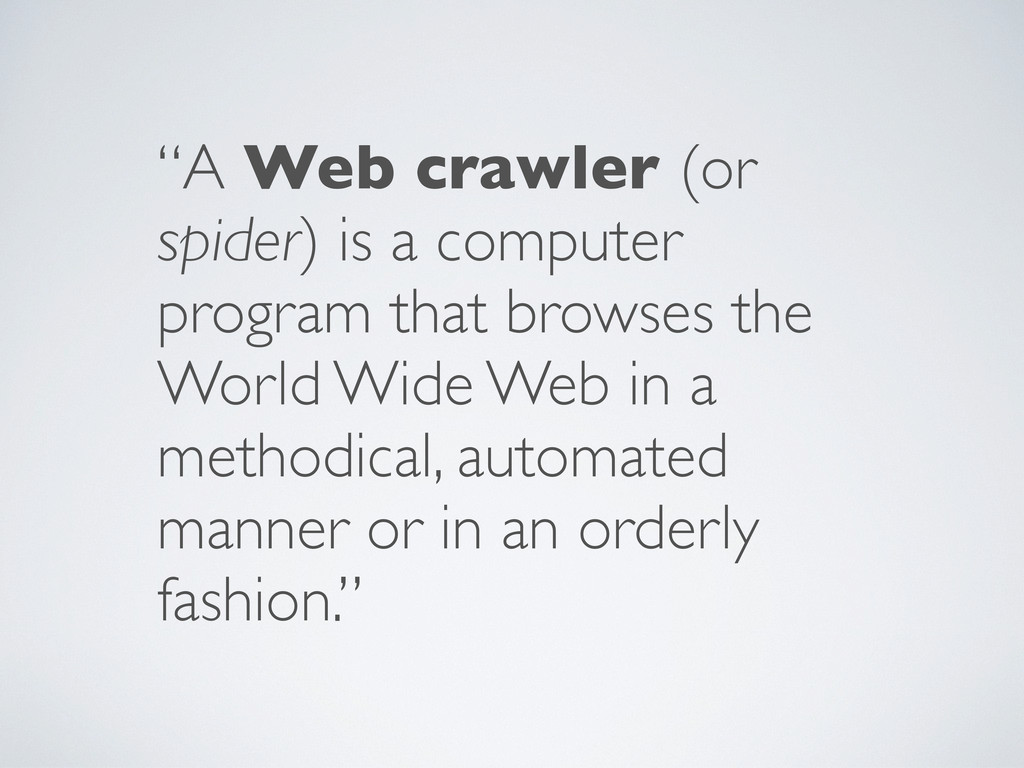
“A Web crawler (or spider) is a computer program that
browses the World Wide Web in a methodical, automated manner or in an orderly fashion.”
None
This process allows us to reach more centers and gather
more data
For each center to have a website that displays their
information The main requirement Without a website we wouldn’t be able to automate this exchange
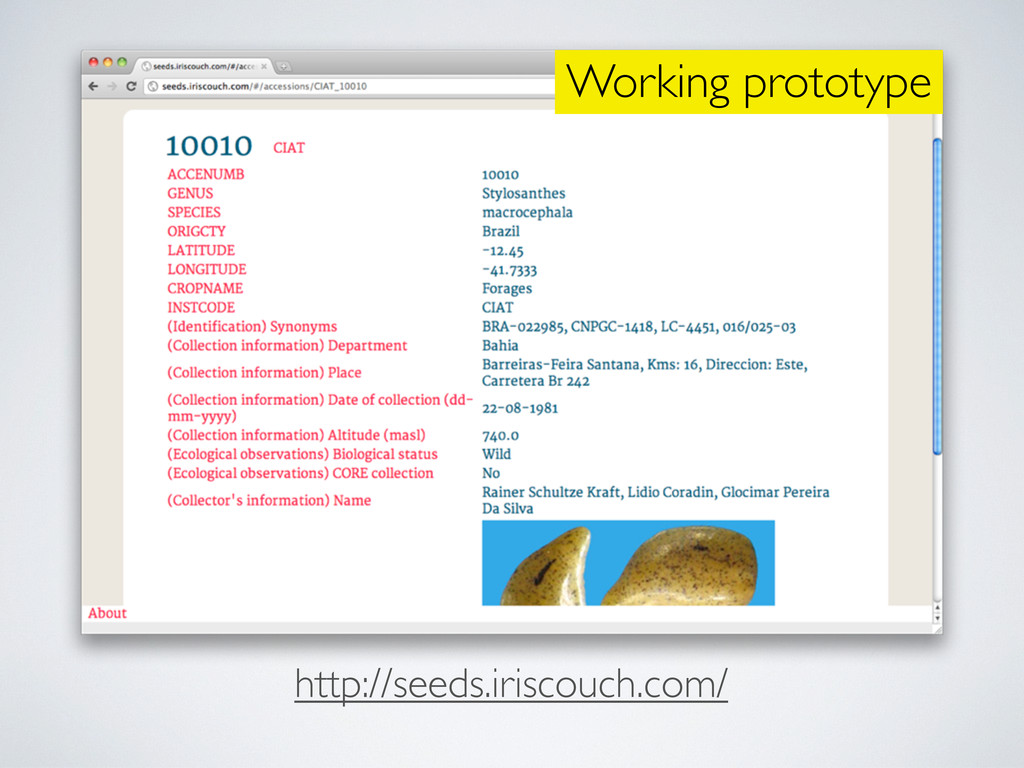
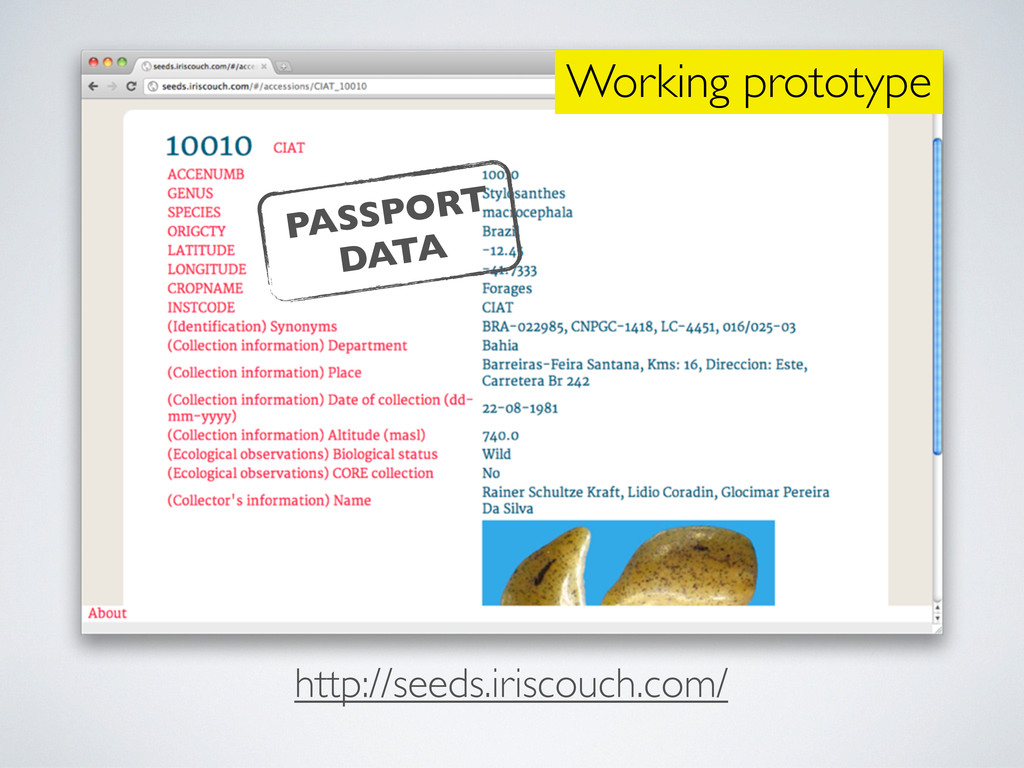
Working prototype http://seeds.iriscouch.com/
Working prototype http://seeds.iriscouch.com/ PASSPORT DATA
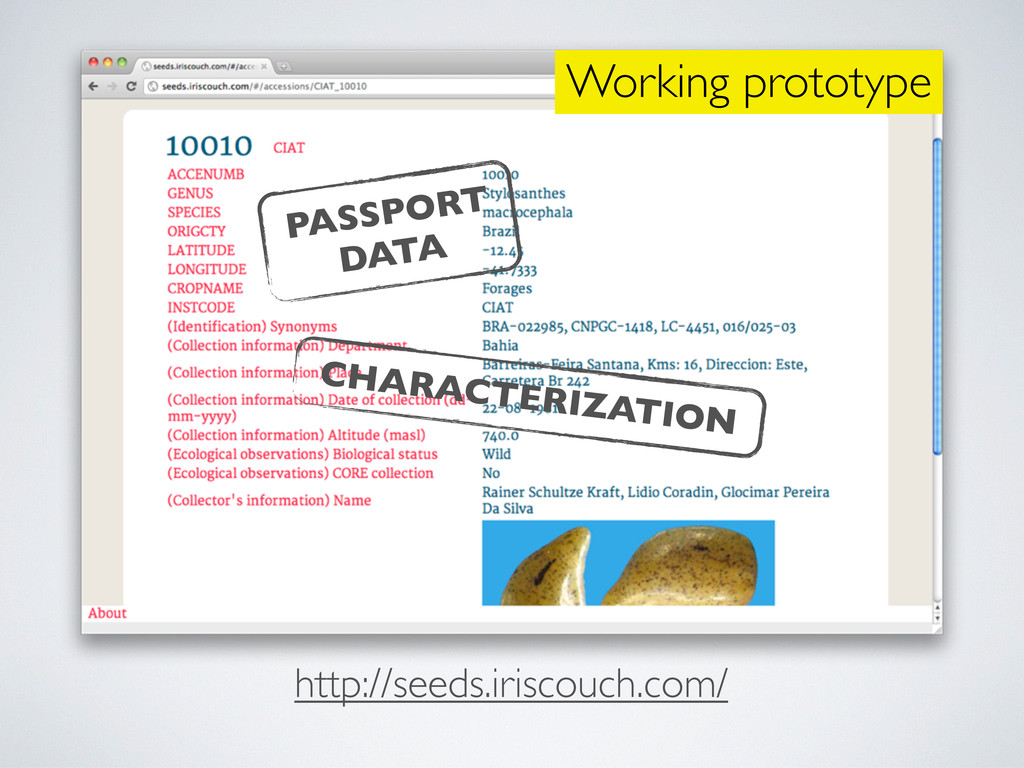
Working prototype http://seeds.iriscouch.com/ PASSPORT DATA CHARACTERIZATION
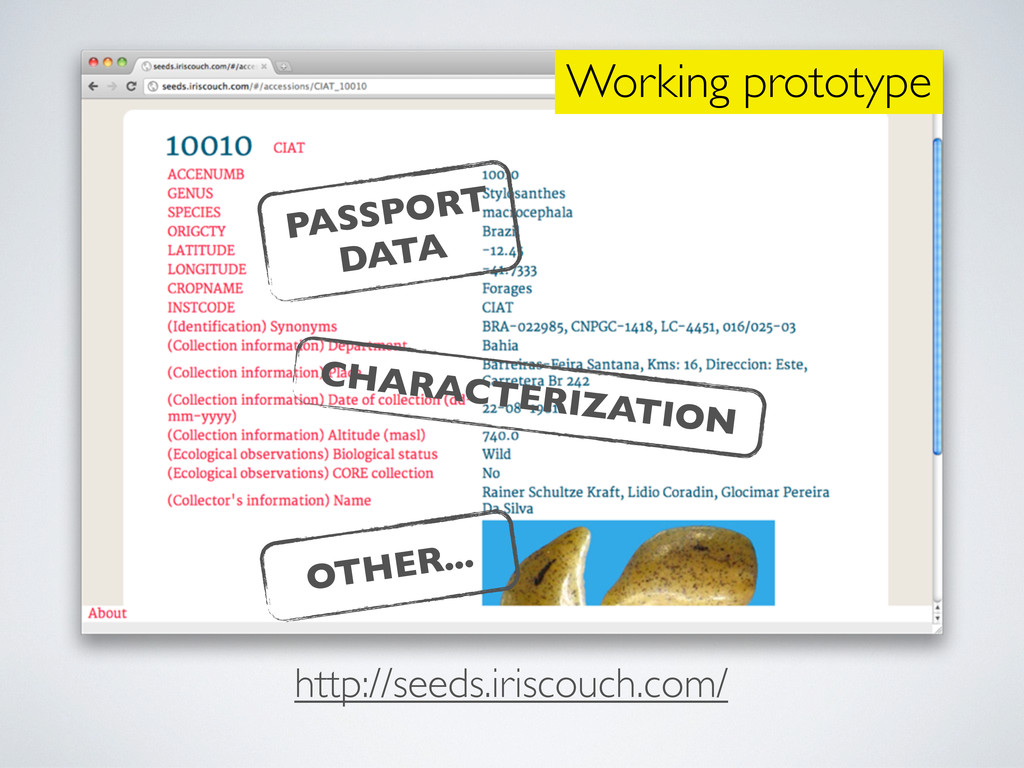
Working prototype http://seeds.iriscouch.com/ PASSPORT DATA CHARACTERIZATION OTHER...
RECAP
RECAP Automation of the data exchange process is the only
sustainable solution
RECAP Automation of the data exchange process is the only
sustainable solution With new technologies, web scraping has become a very reliable system
RECAP Automation of the data exchange process is the only
sustainable solution With new technologies, web scraping has become a very reliable system The process is modular and will allow us to plug-in systems such as GRIN-Global
THANK YOU


 lmatteis
 ogom
 drumath2237
 eijirou
 ivargrimstad
 po3rin
 sts11142
 satotakeshi
 icoxfog417
 lynnswap
 trickart
 akagami
 inesmontani
 davidcarrasco
 samtorres
 marcoroth
 keathley
 tammyeverts
 matthewcrist
 szymonslowik
 wayneb77
 chriscoyier
 cassininazir