Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Leveraging LLMs for student feedback in introdu...

Leveraging LLMs for student feedback in introductory data science courses (IDWSDS)

A considerable recent challenge for learners and teachers of data science courses is the proliferation of the use of LLM
-based tools in generating answers. In this talk, I will introduce an R package that leverages LLMs to produce immediate feedback on student work to motivate them to give it a try themselves first. I will discuss technical details of augmenting models with course materials, backend and user interface decisions, challenges around evaluations that are not done correctly by the LLM, and student feedback from the first set of users. Finally, I will touch on incorporating this tool into low -stakes assessment and ethical considerations for the formal assessment structure of the course relying on LLMs.

Avatar for Mine Cetinkaya-Rundel

Mine Cetinkaya-Rundel

October 05, 2026

More Decks by Mine Cetinkaya-Rundel

Other Decks in Education

Transcript

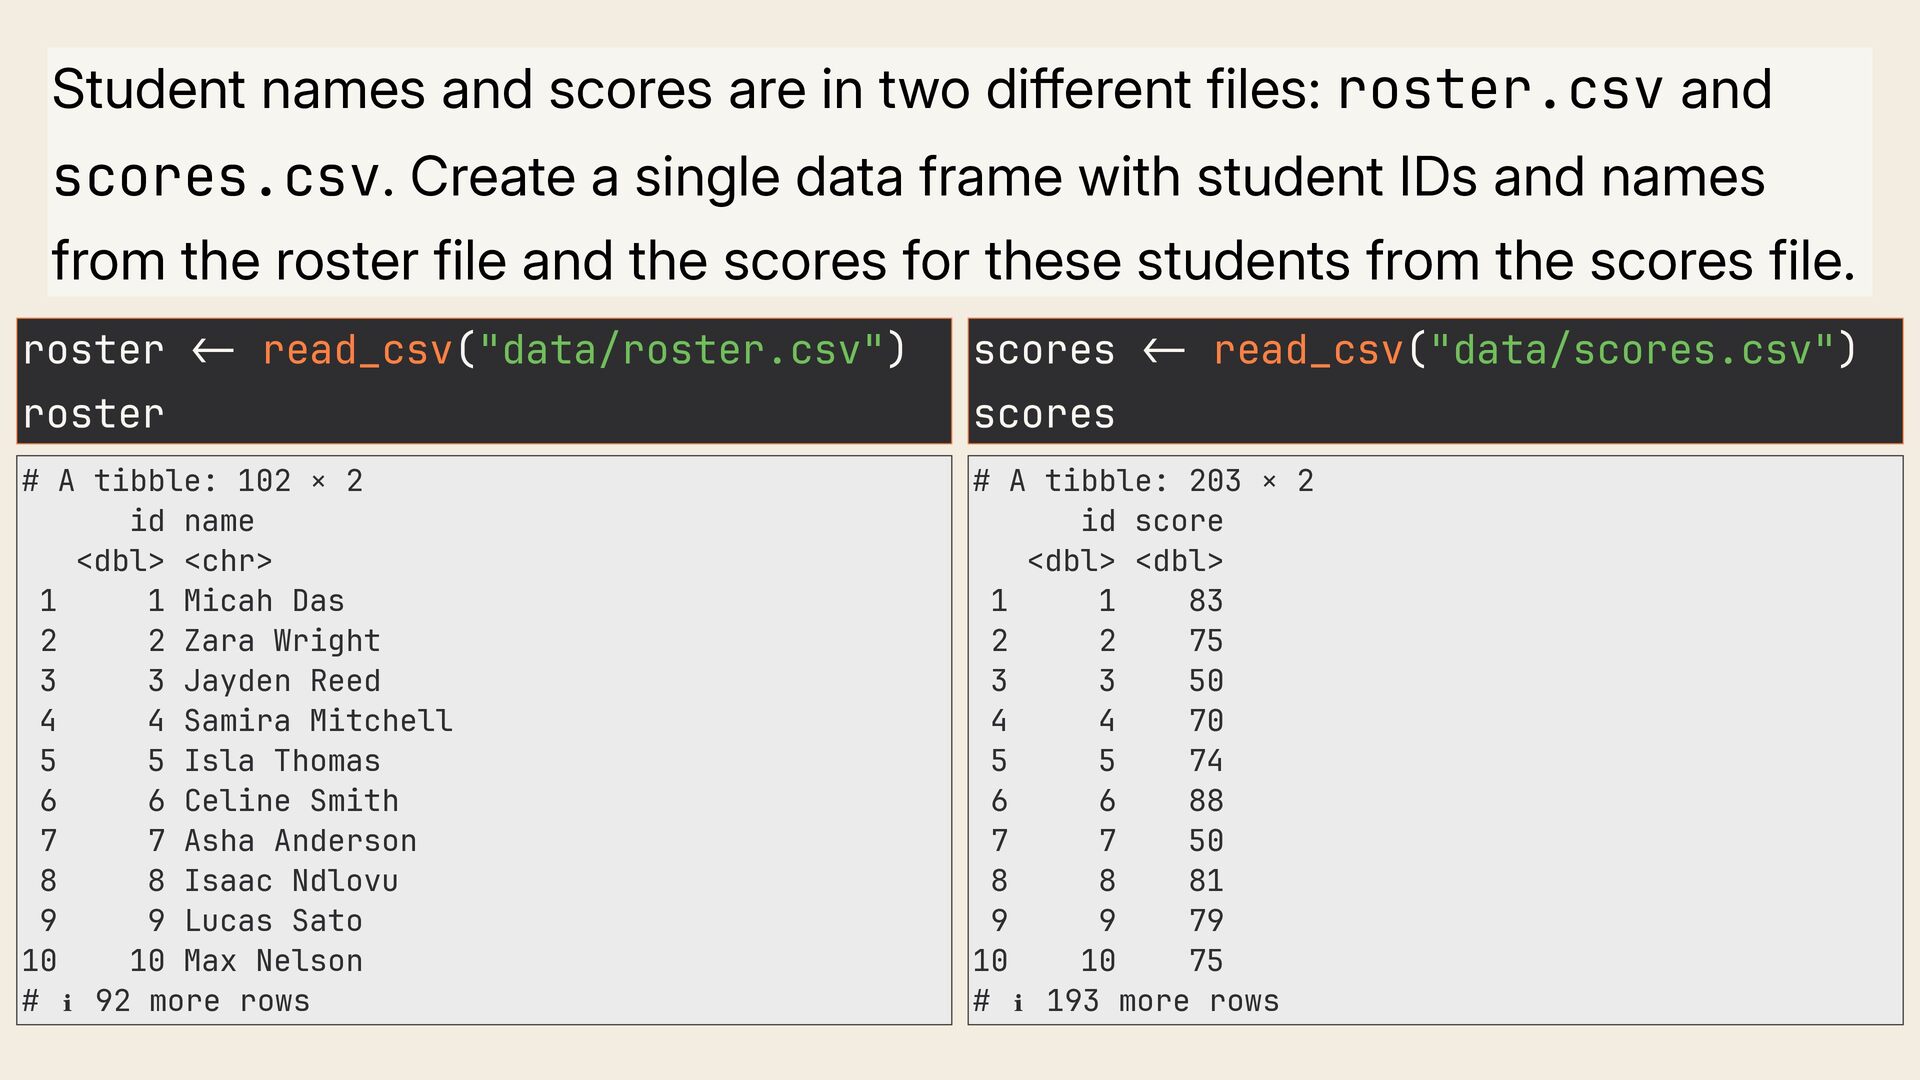
  1. Student names and scores are in two different files: roster.csv

    and scores.csv. Create a single data frame with student IDs and names from the roster file and the scores for these students from the scores file. roster read_csv("data/roster.csv") scores read_csv("data/scores.csv") - # A tibble: 203 × 2 id score <dbl> <dbl> 1 1 83 2 2 75 3 3 50 4 4 70 5 5 74 6 6 88 7 7 50 8 8 81 9 9 79 10 10 75 # ℹ 193 more rows - # A tibble: 102 × 2 id name <dbl> <chr> 1 1 Micah Das 2 2 Zara Wright 3 3 Jayden Reed 4 4 Samira Mitchell 5 5 Isla Thomas 6 6 Celine Smith 7 7 Asha Anderson 8 8 Isaac Ndlovu 9 9 Lucas Sato 10 10 Max Nelson # ℹ 92 more rows < scores < roster
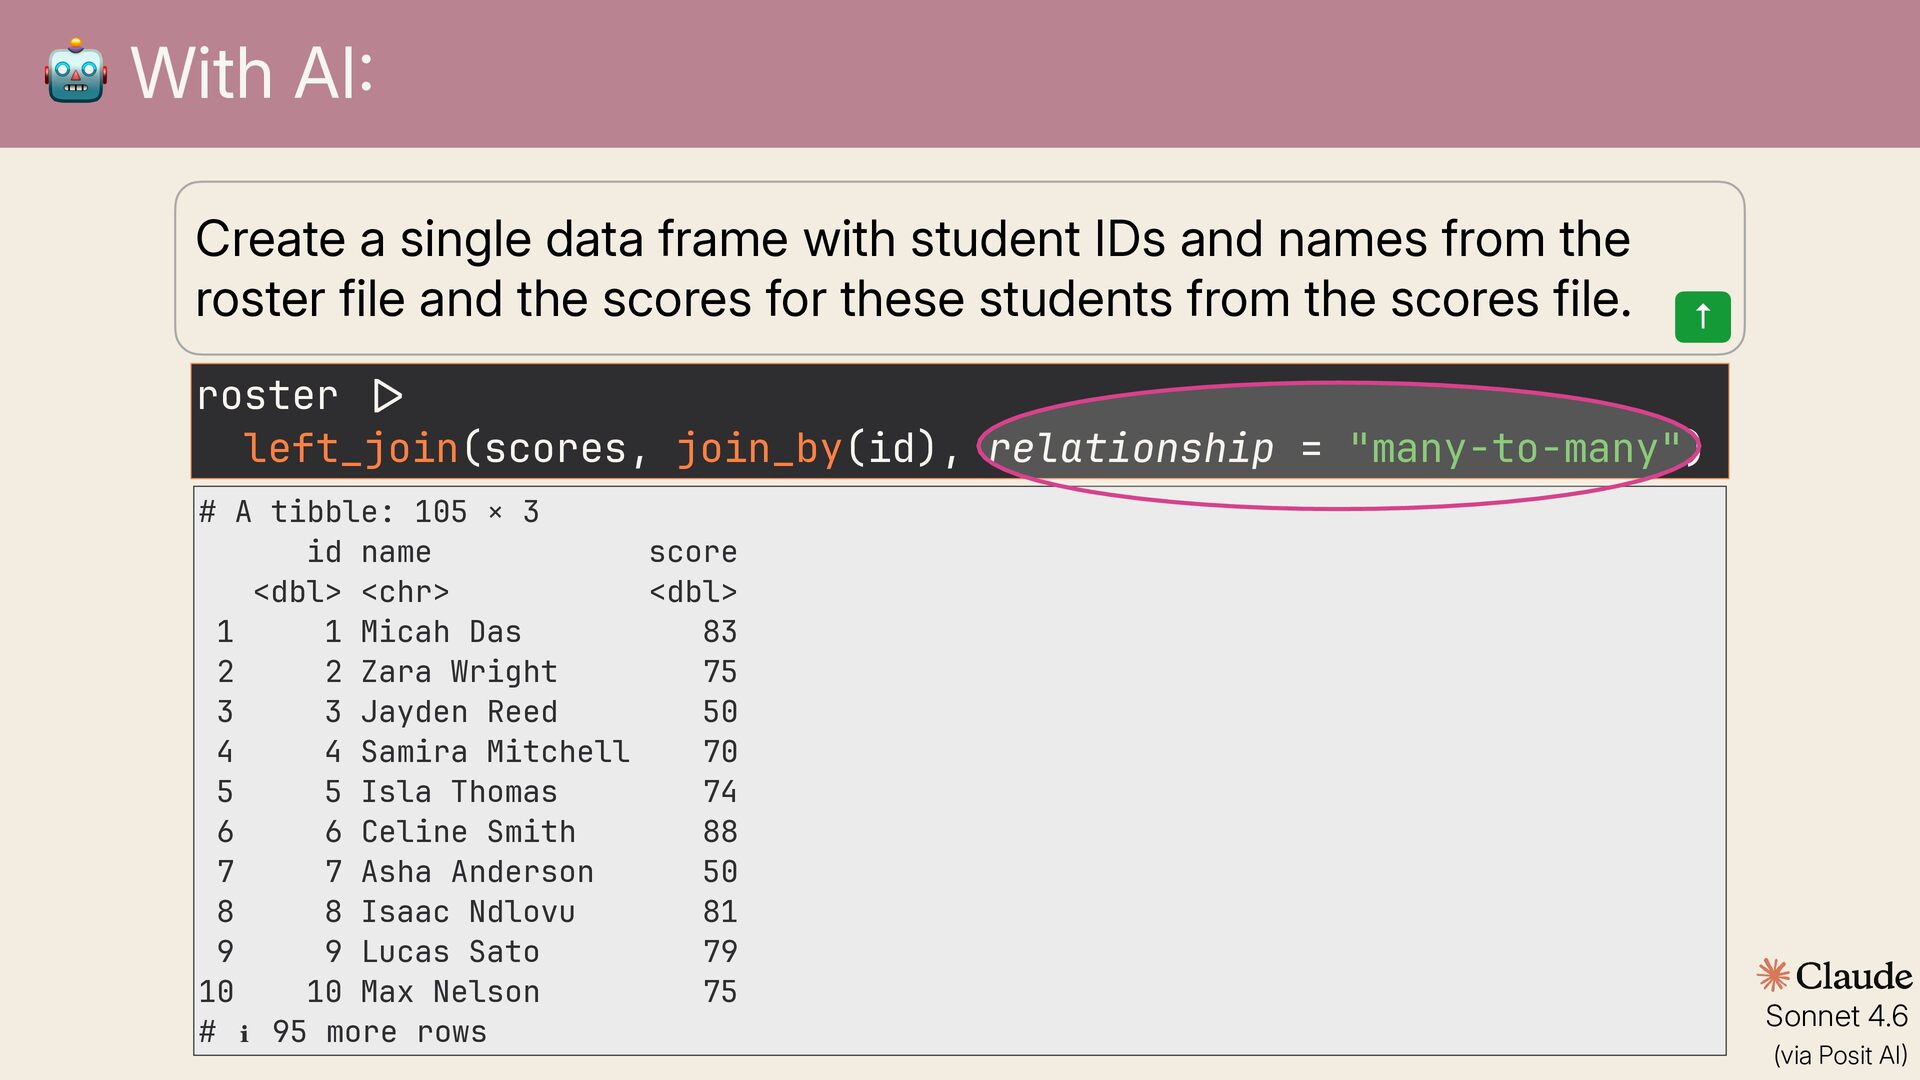
  2. 🤖 With AI Create a single data frame with student

    IDs and names from the roster file and the scores for these students from the scores file. ↑ roster left_join(scores, join_by(id), relationship = "many-to-many") : > | ) # A tibble: 105 × 3 id name score <dbl> <chr> <dbl> 1 1 Micah Das 83 2 2 Zara Wright 75 3 3 Jayden Reed 50 4 4 Samira Mitchell 70 5 5 Isla Thomas 74 6 6 Celine Smith 88 7 7 Asha Anderson 50 8 8 Isaac Ndlovu 81 9 9 Lucas Sato 79 10 10 Max Nelson 75 # ℹ 95 more rows Sonnet 4.6 (via Posit AI
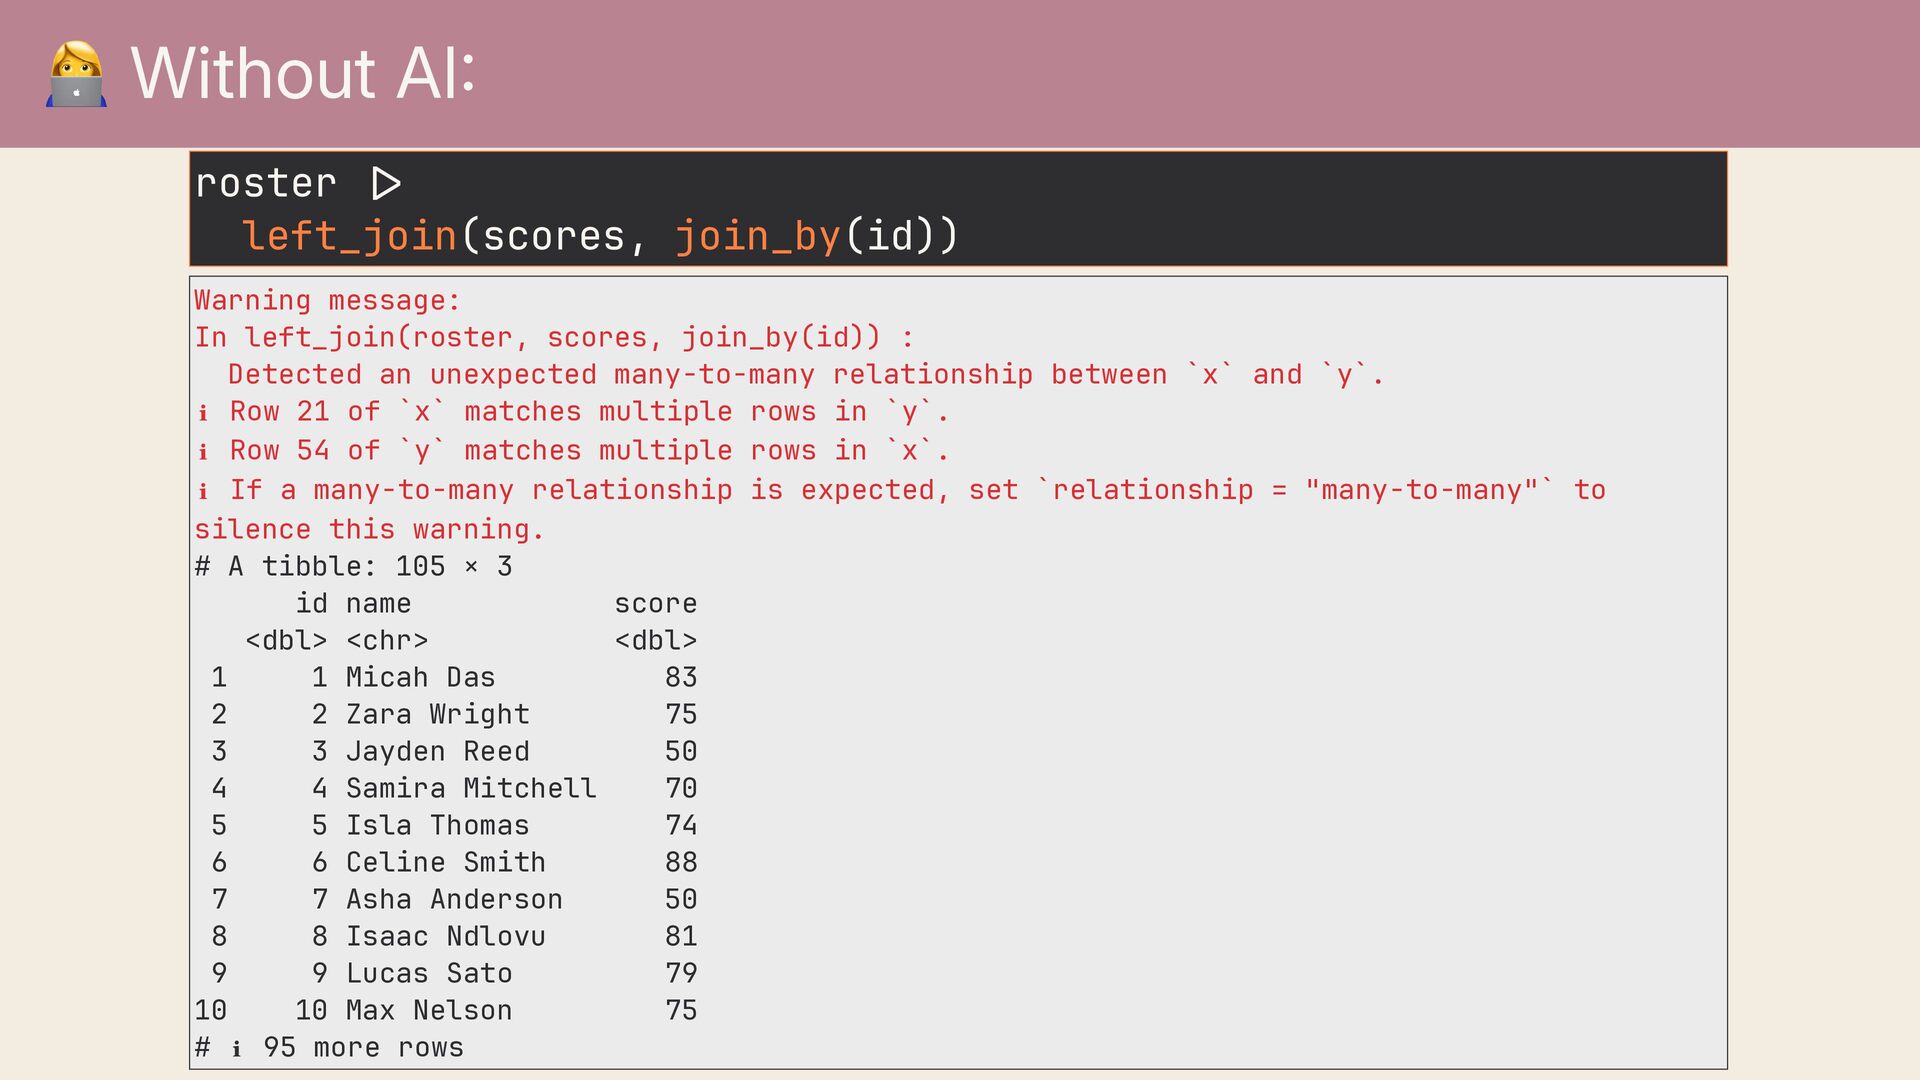
  3. 👩💻 Without AI roster left_join(scores, join_by(id)) : > | Warning

    message: In left_join(roster, scores, join_by(id)) : Detected an unexpected many-to-many relationship between `x` and `y`. ℹ Row 21 of `x` matches multiple rows in `y`. ℹ Row 54 of `y` matches multiple rows in `x`. ℹ If a many-to-many relationship is expected, set `relationship = "many-to-many"` to silence this warning. # A tibble: 105 × 3 id name score <dbl> <chr> <dbl> 1 1 Micah Das 83 2 2 Zara Wright 75 3 3 Jayden Reed 50 4 4 Samira Mitchell 70 5 5 Isla Thomas 74 6 6 Celine Smith 88 7 7 Asha Anderson 50 8 8 Isaac Ndlovu 81 9 9 Lucas Sato 79 10 10 Max Nelson 75 # ℹ 95 more rows
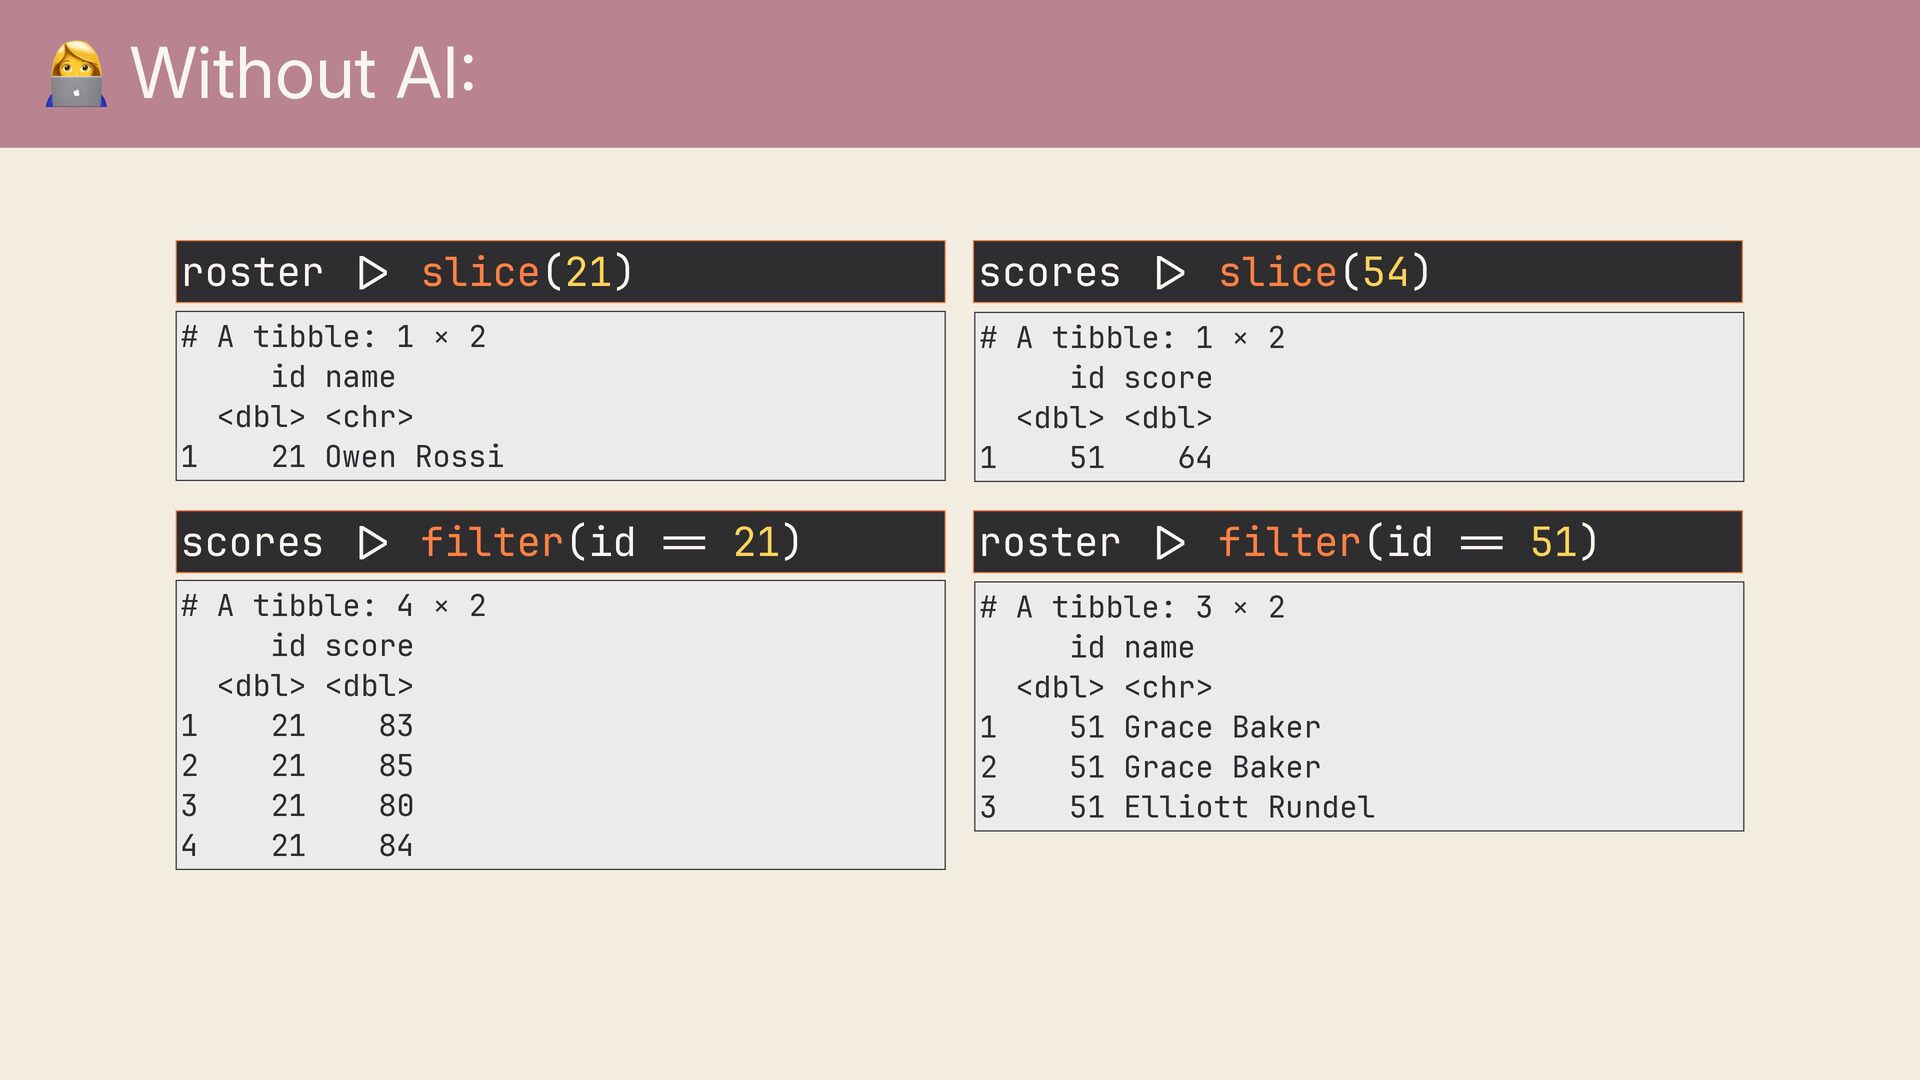
  4. 👩💻 Without AI roster slice(21) scores # A tibble: 1

    × 2 id name <dbl> <chr> 1 21 Owen Rossi scores filter(id # A tibble: 1 × 2 id score <dbl> <dbl> 1 51 64 21) roster filter(id = # A tibble: 3 × 2 id name <dbl> <chr> 1 51 Grace Baker 2 51 Grace Baker 3 51 Elliott Rundel = = = : > > > > | | | | # A tibble: 4 × 2 id score <dbl> <dbl> 1 21 83 2 21 85 3 21 80 4 21 84 slice(54) 51)
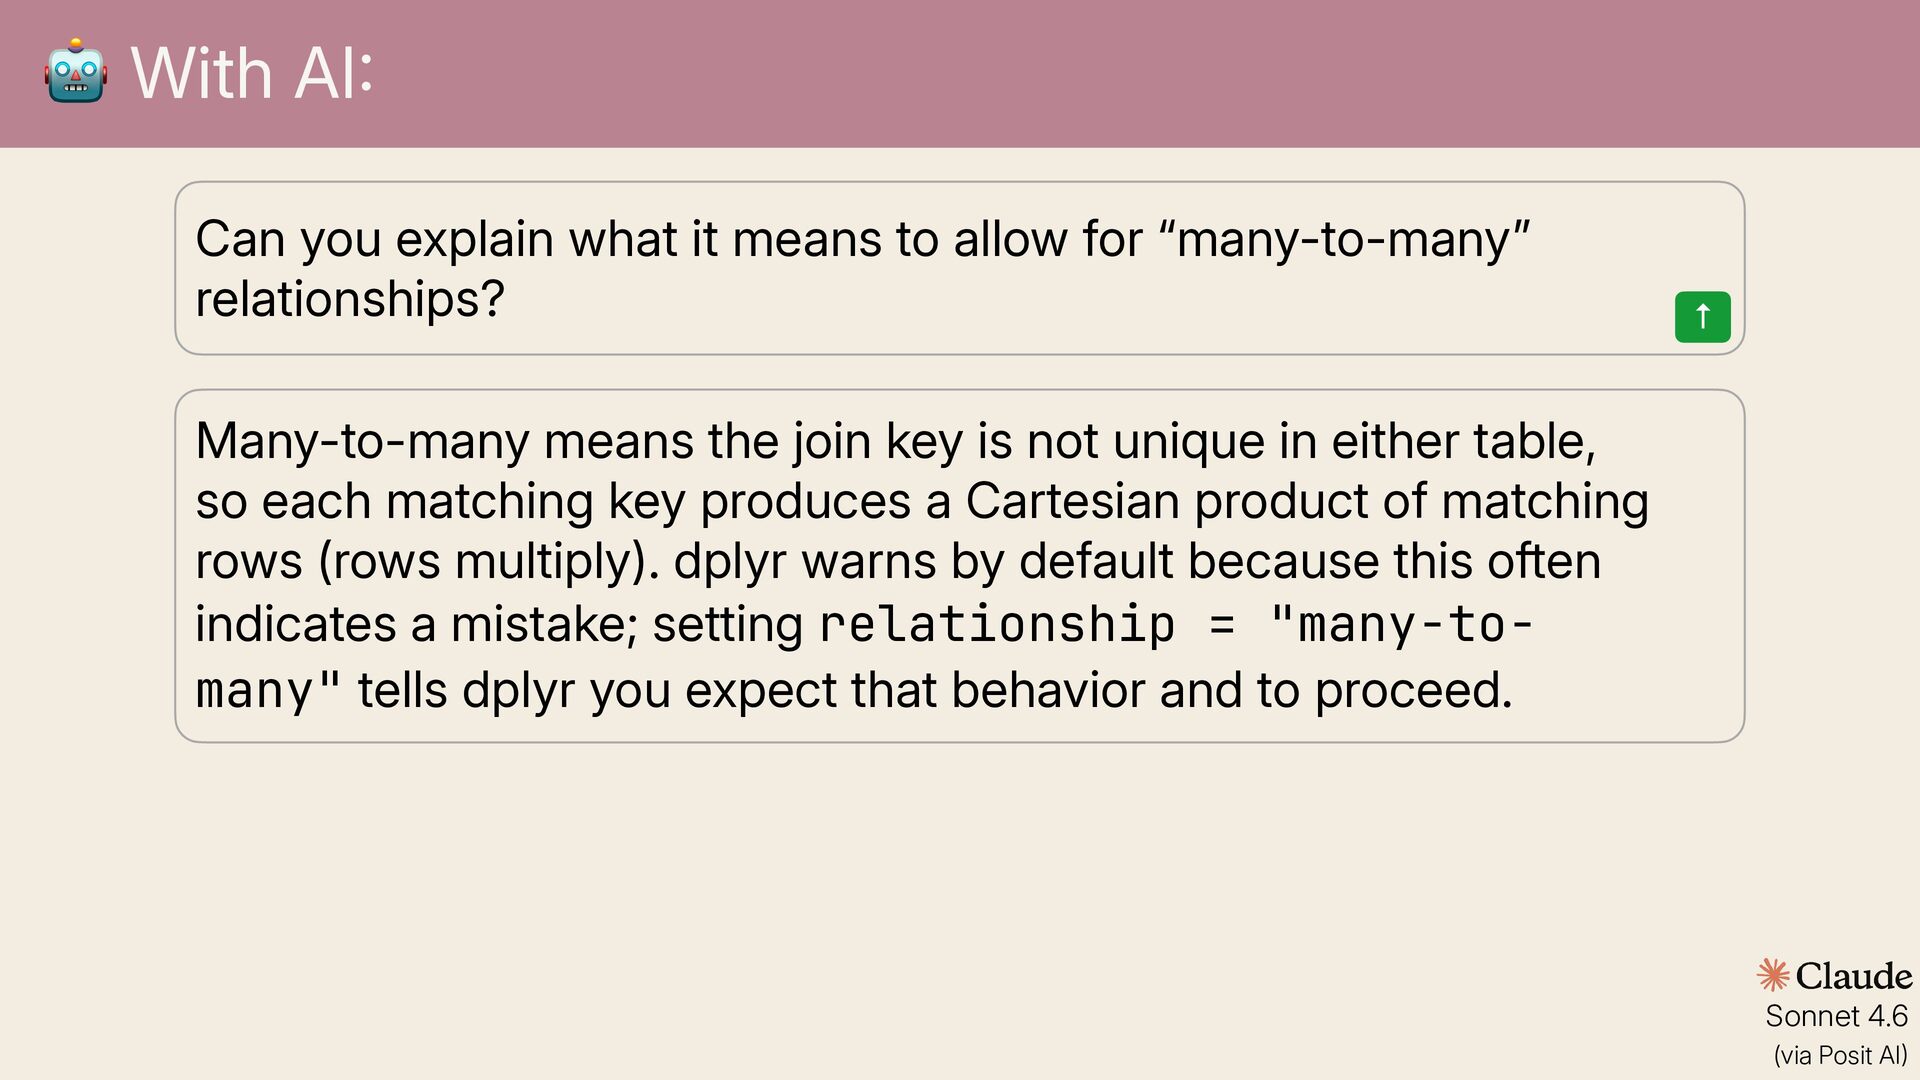
  5. 🤖 With AI Can you explain what it means to

    allow for “many-to-many relationships? ↑ Many-to-many means the join key is not unique in either table, so each matching key produces a Cartesian product of matching rows (rows multiply). dplyr warns by default because this often indicates a mistake; setting relationship = "many-tomany" tells dplyr you expect that behavior and to proceed. Sonnet 4.6 ” : ) (via Posit AI
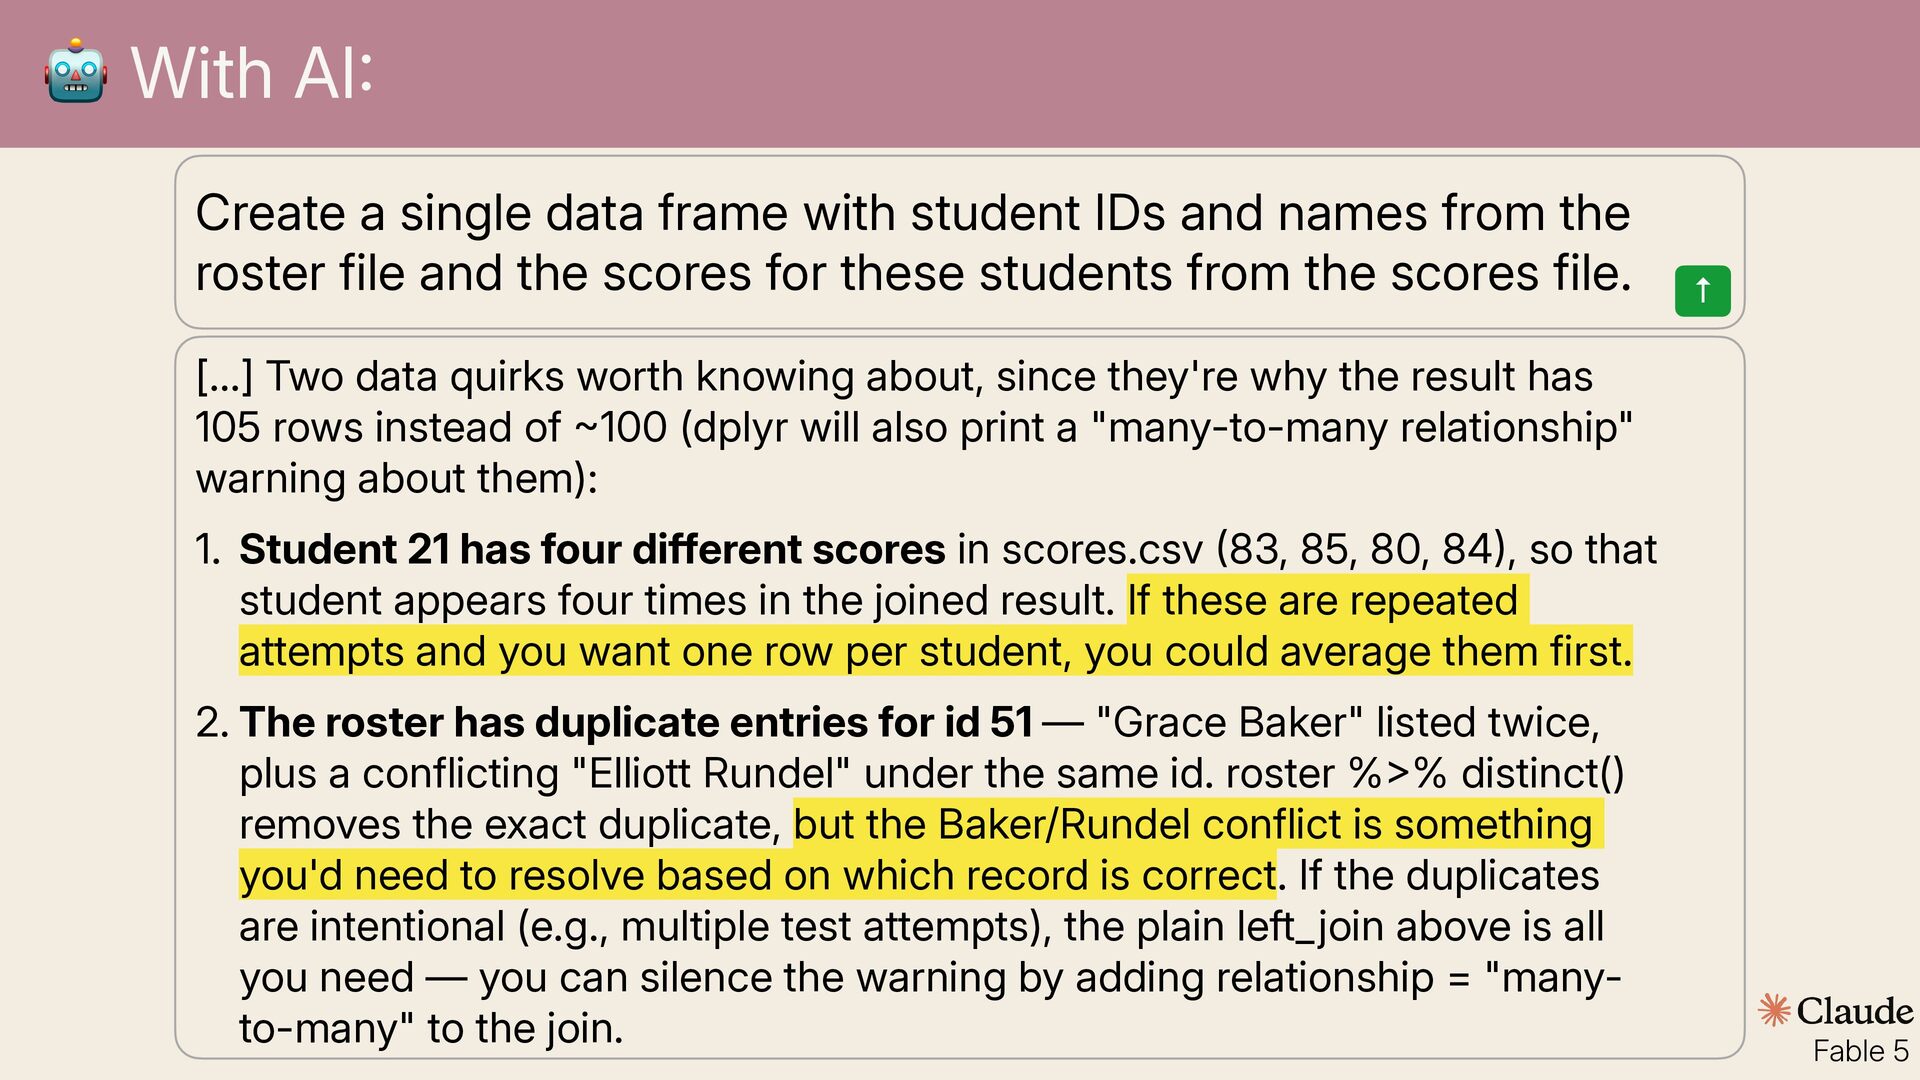
  6. 🤖 With AI Create a single data frame with student

    IDs and names from the roster file and the scores for these students from the scores file. ↑ […] Two data quirks worth knowing about, since they're why the result has 105 rows instead of 100 (dplyr will also print a "many-to-many relationship" warning about them): 1. Student 21 has four different scores in scores.csv 83, 85, 80, 84 , so that student appears four times in the joined result. If these are repeated attempts and you want one row per student, you could average them first. ) > ( ~ : 2. The roster has duplicate entries for id 51 — "Grace Baker" listed twice, plus a conflicting "Elliott Rundel" under the same id. roster % % distinct() removes the exact duplicate, but the Baker/Rundel conflict is something you'd need to resolve based on which record is correct. If the duplicates are intentional (e.g., multiple test attempts), the plain left_join above is all you need — you can silence the warning by adding relationship = "manyto-many" to the join. Fable 5
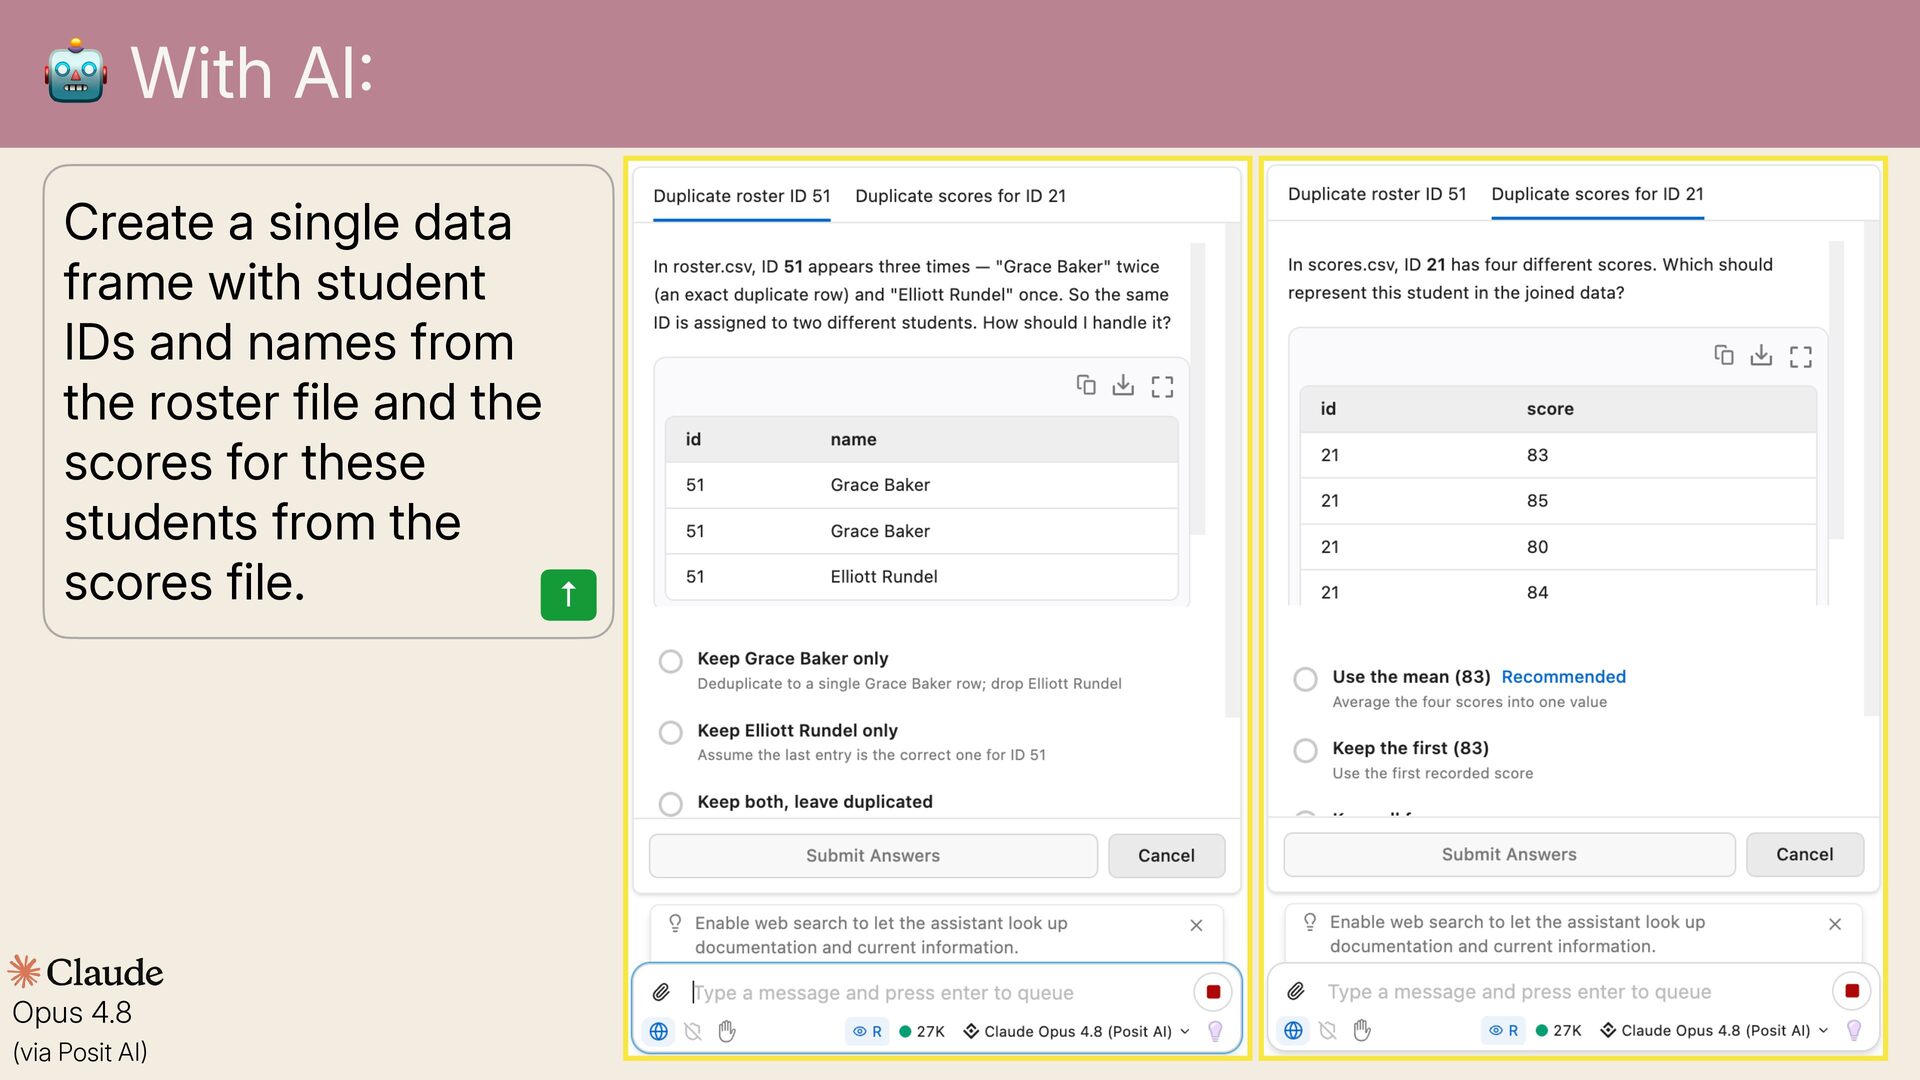
  7. 🤖 With AI Create a single data frame with student

    IDs and names from the roster file and the scores for these students from the scores file. ↑ Opus 4.8 : ) (via Posit AI
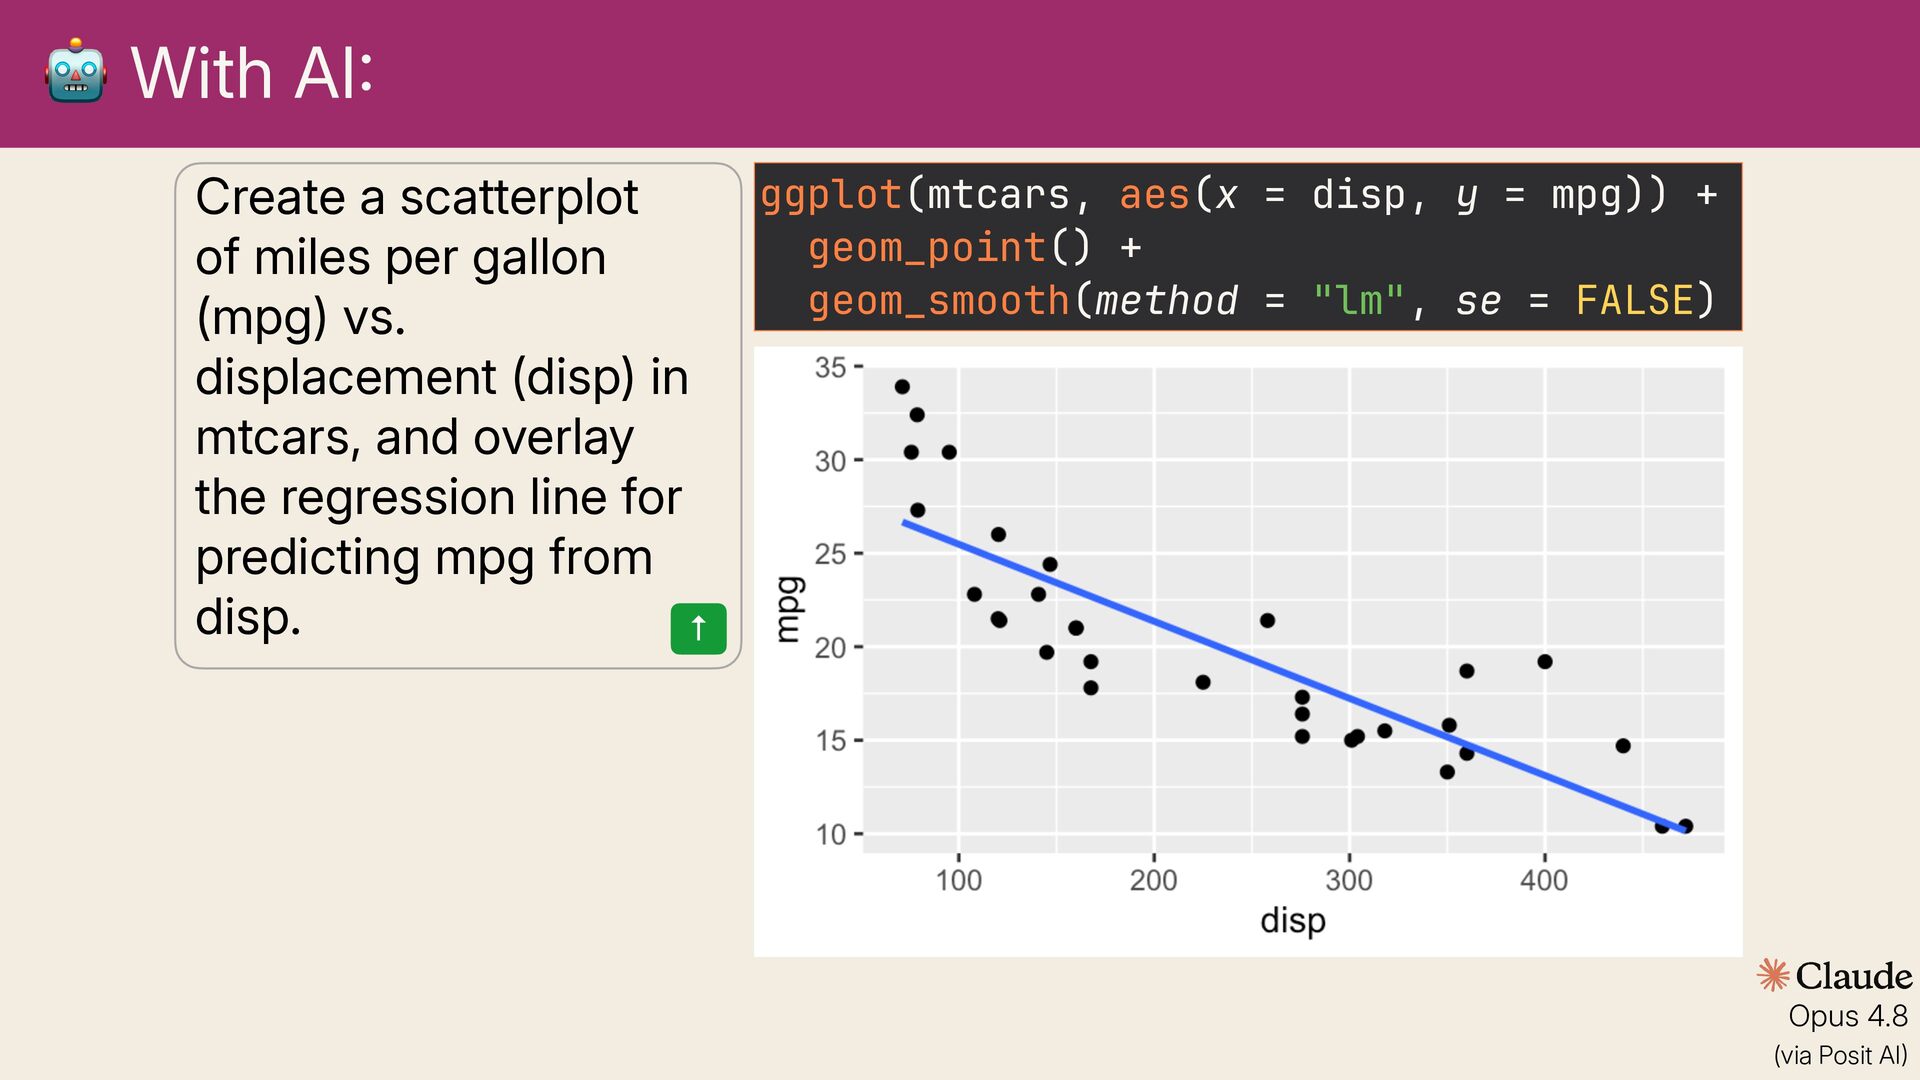
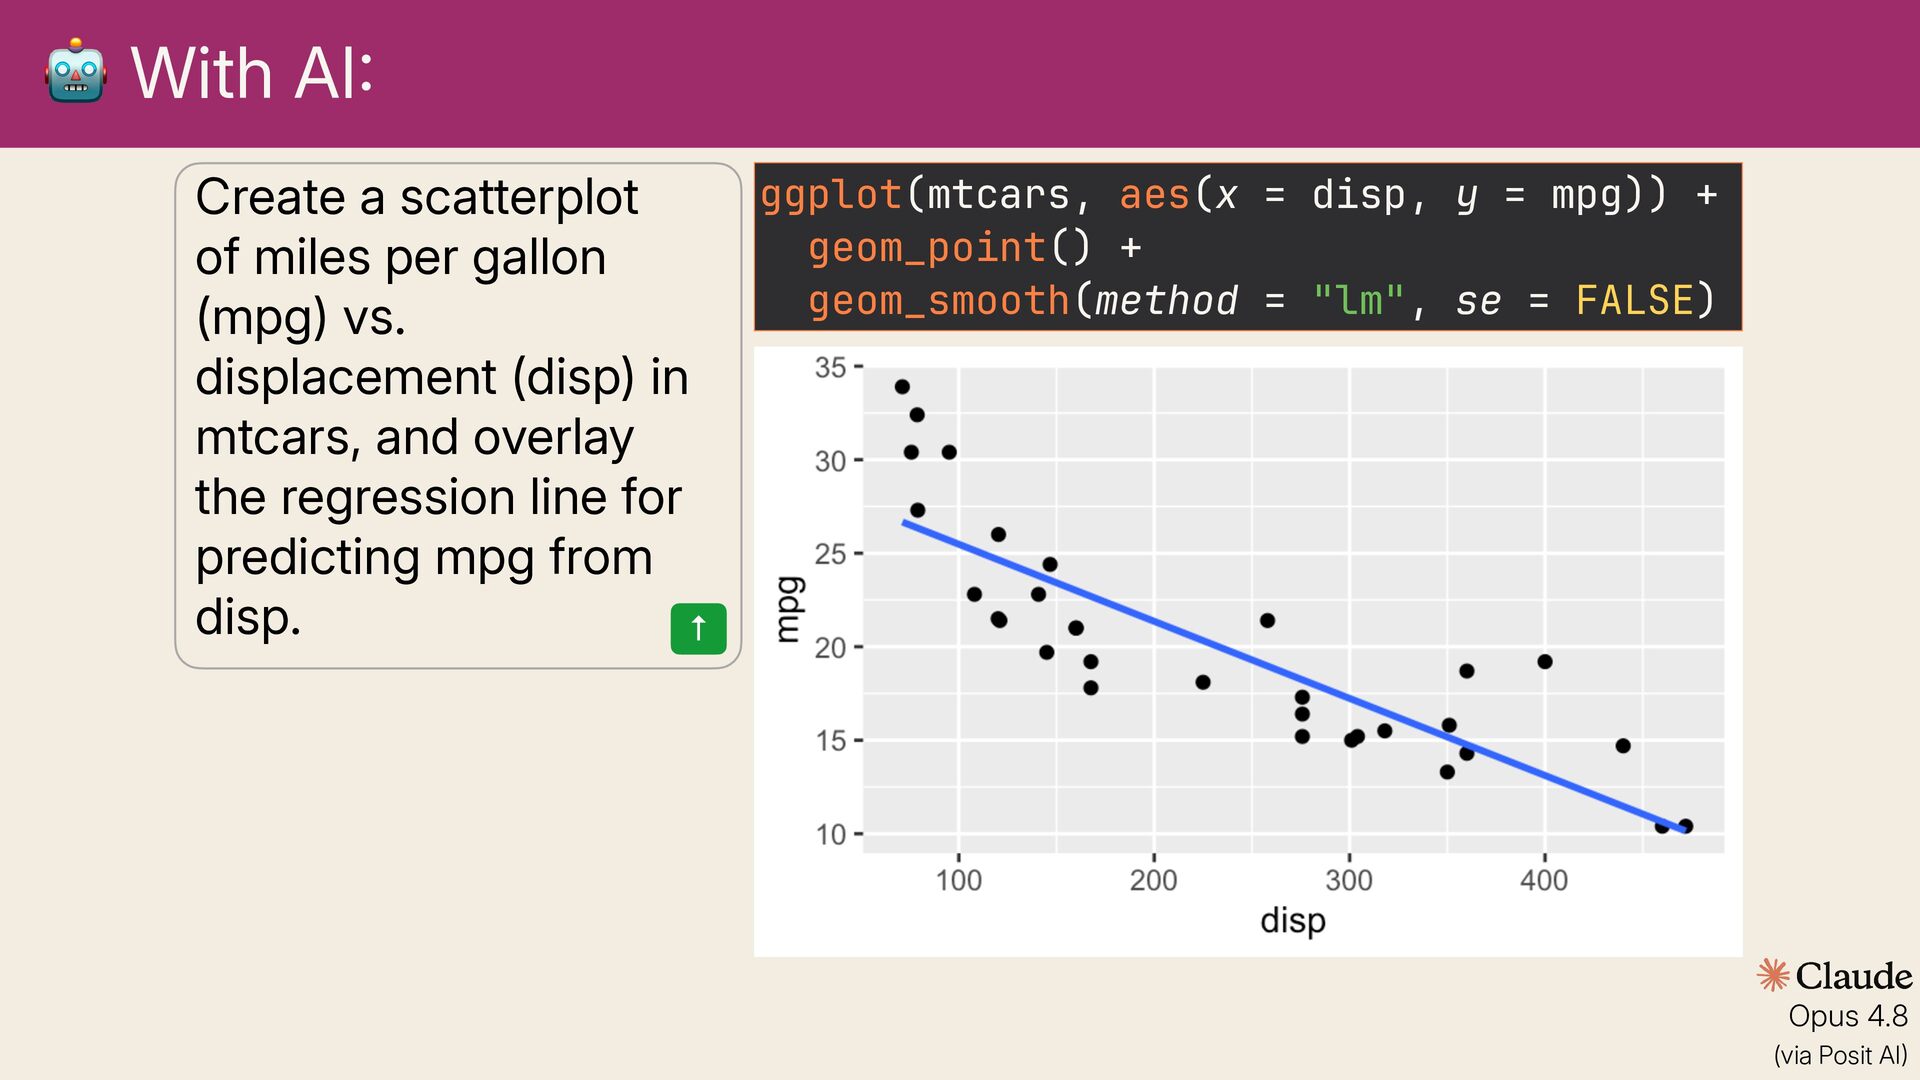
  8. 🤖 With AI Create a scatterplot of miles per gallon

    (mpg) vs. displacement (disp) in mtcars, and overlay the regression line for predicting mpg from disp. ↑ ggplot(mtcars, aes(x = disp, y = mpg)) + geom_point() + geom_smooth(method = "lm", se = FALSE) Opus 4.8 : ) (via Posit AI
  9. 🤖 With AI Create a scatterplot of miles per gallon

    (mpg) vs. displacement (disp) in mtcars, and overlay the regression line for predicting mpg from disp. ↑ ggplot(mtcars, aes(x = disp, y = mpg)) + geom_point() + geom_smooth(method = "lm", se = FALSE) Opus 4.8 : ) (via Posit AI
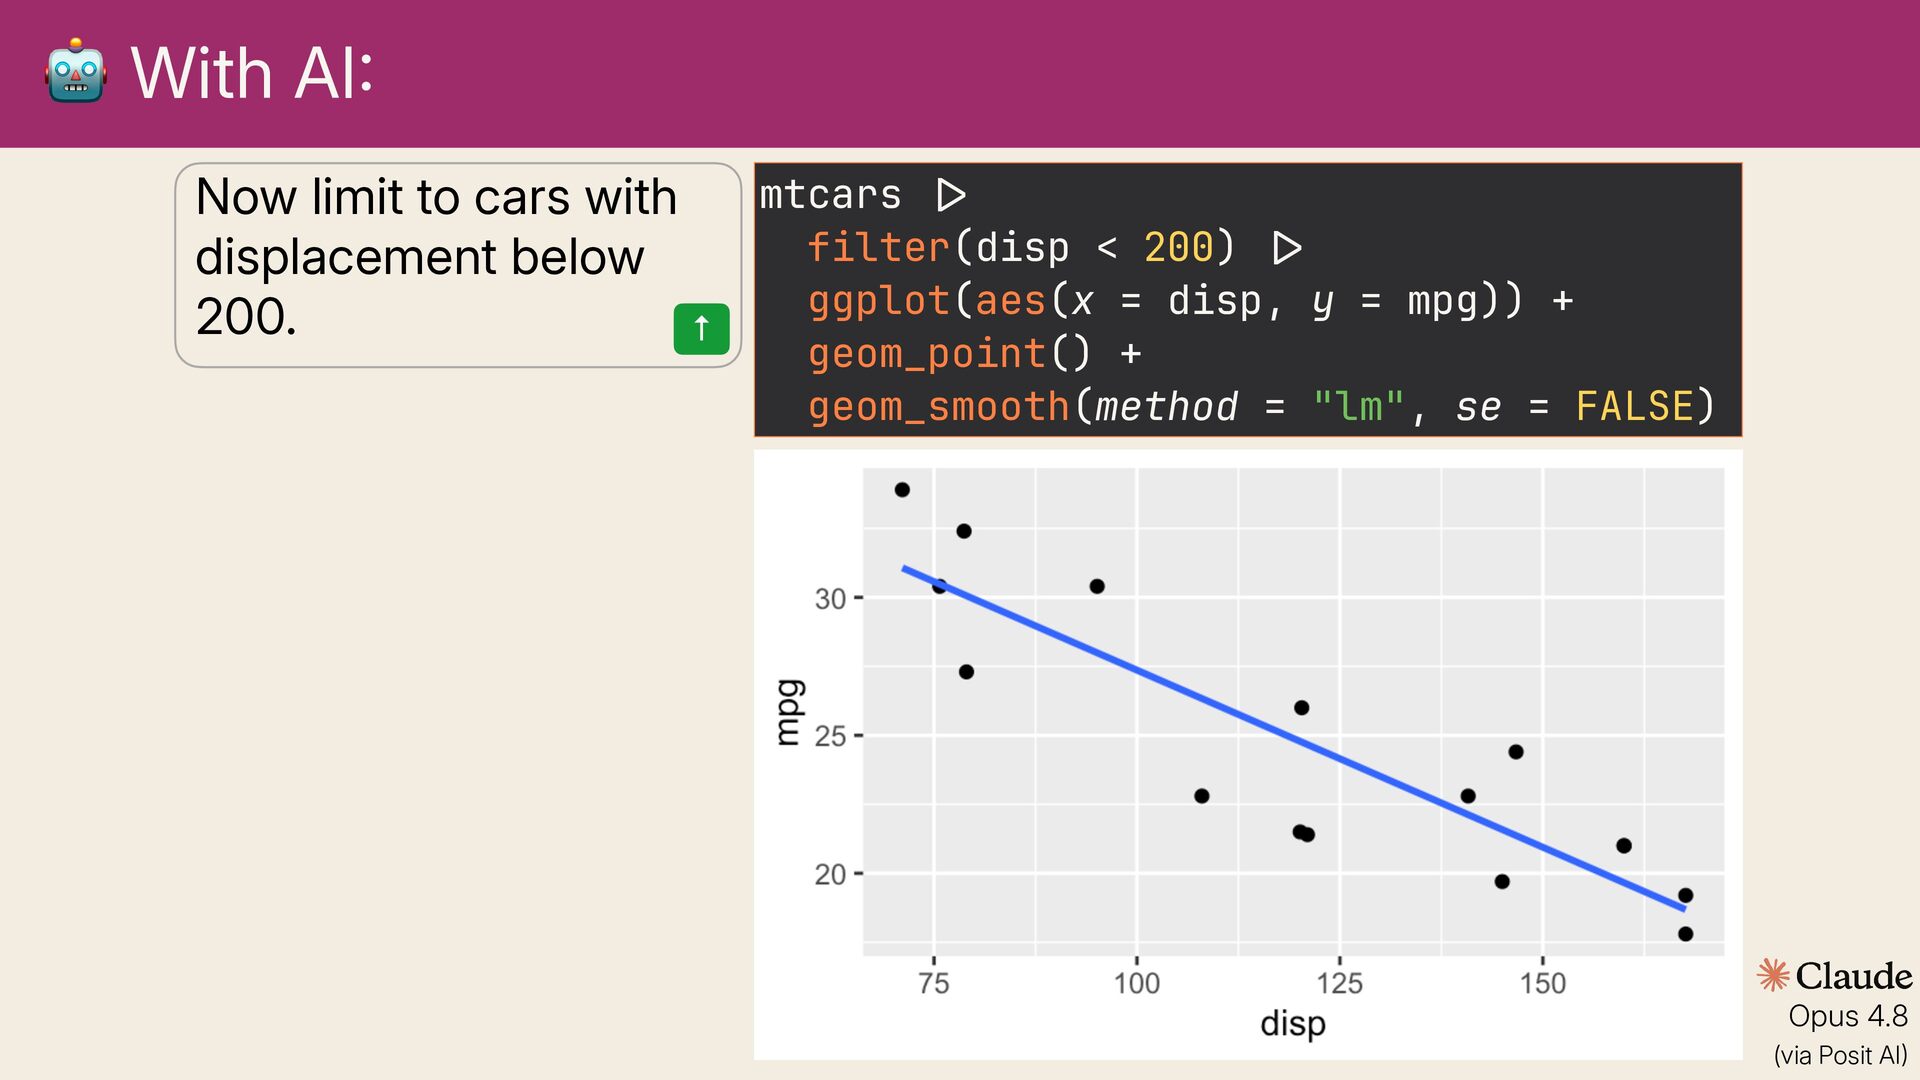
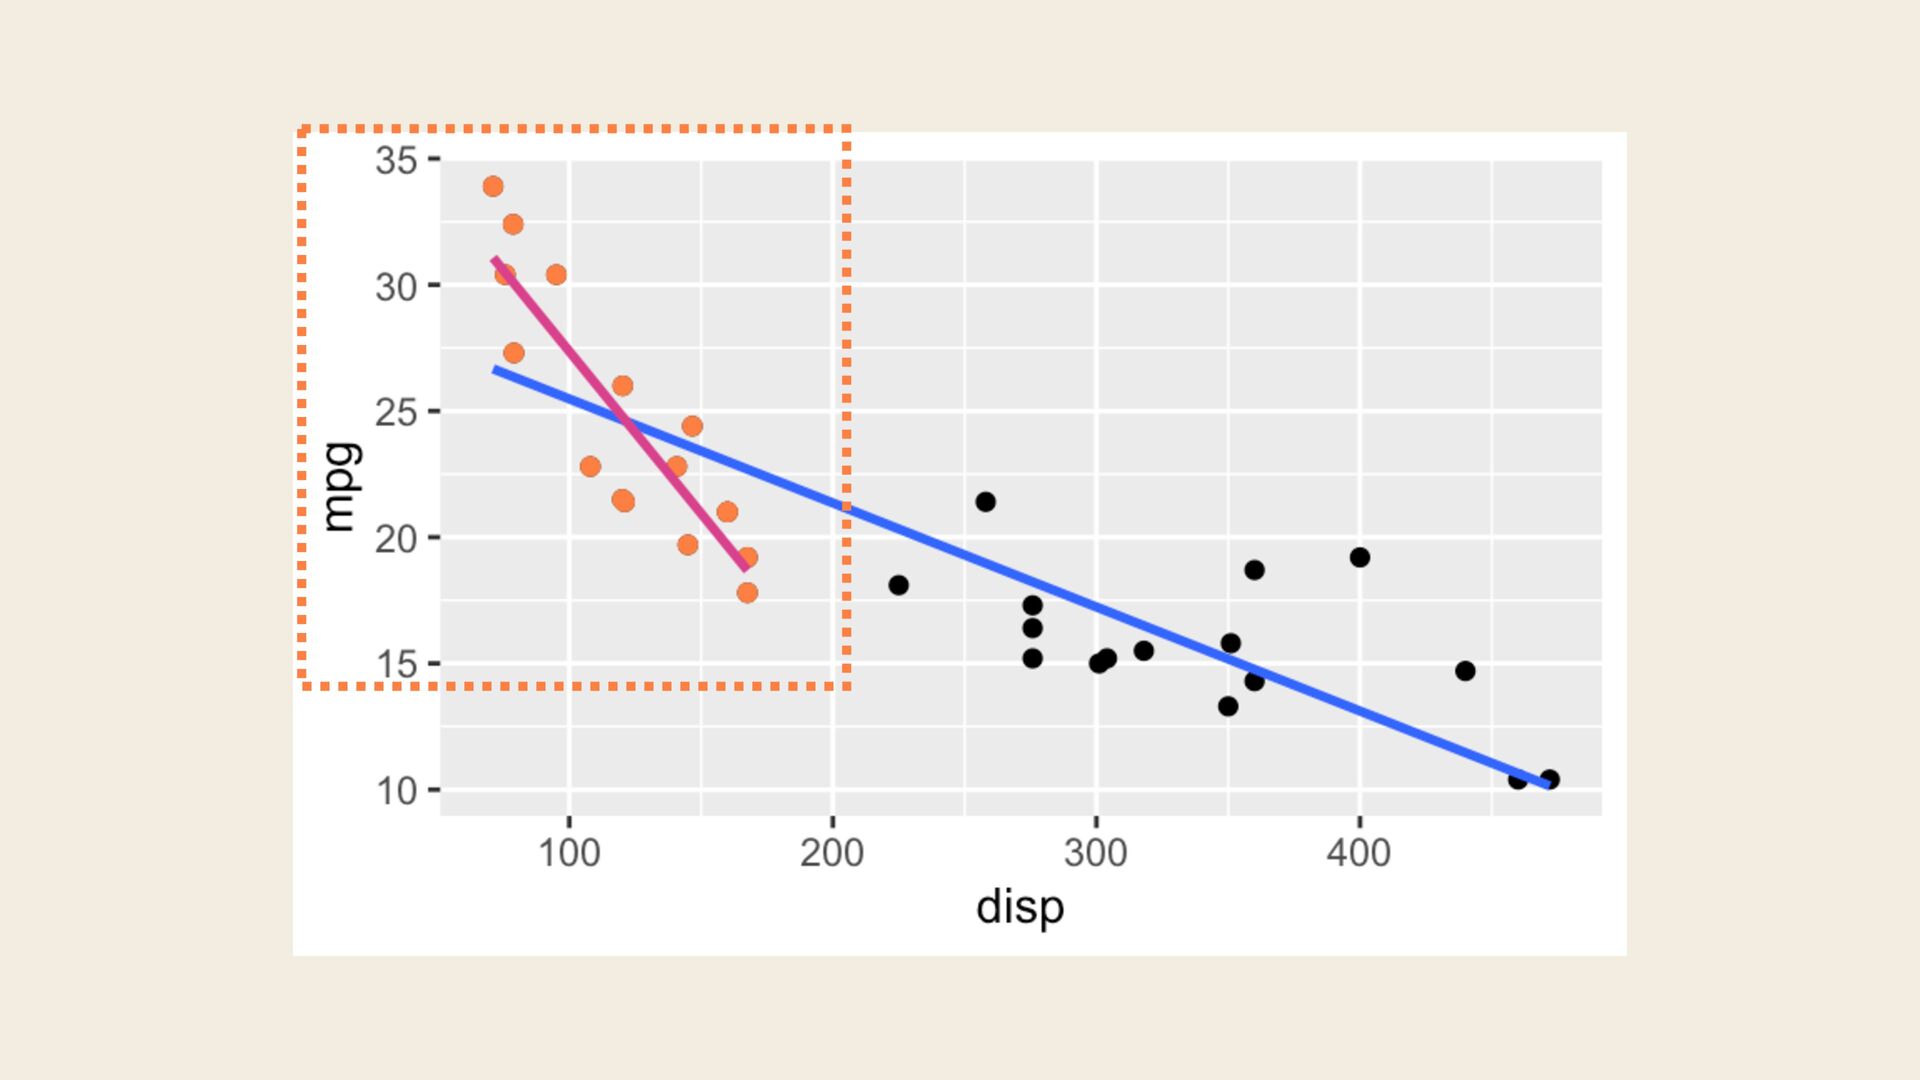
  10. 🤖 With AI Now limit to cars with displacement below

    200. ↑ mtcars filter(disp < 200) ggplot(aes(x = disp, y = mpg)) + geom_point() + geom_smooth(method = "lm", se = FALSE) Opus 4.8 > | : > | ) (via Posit AI
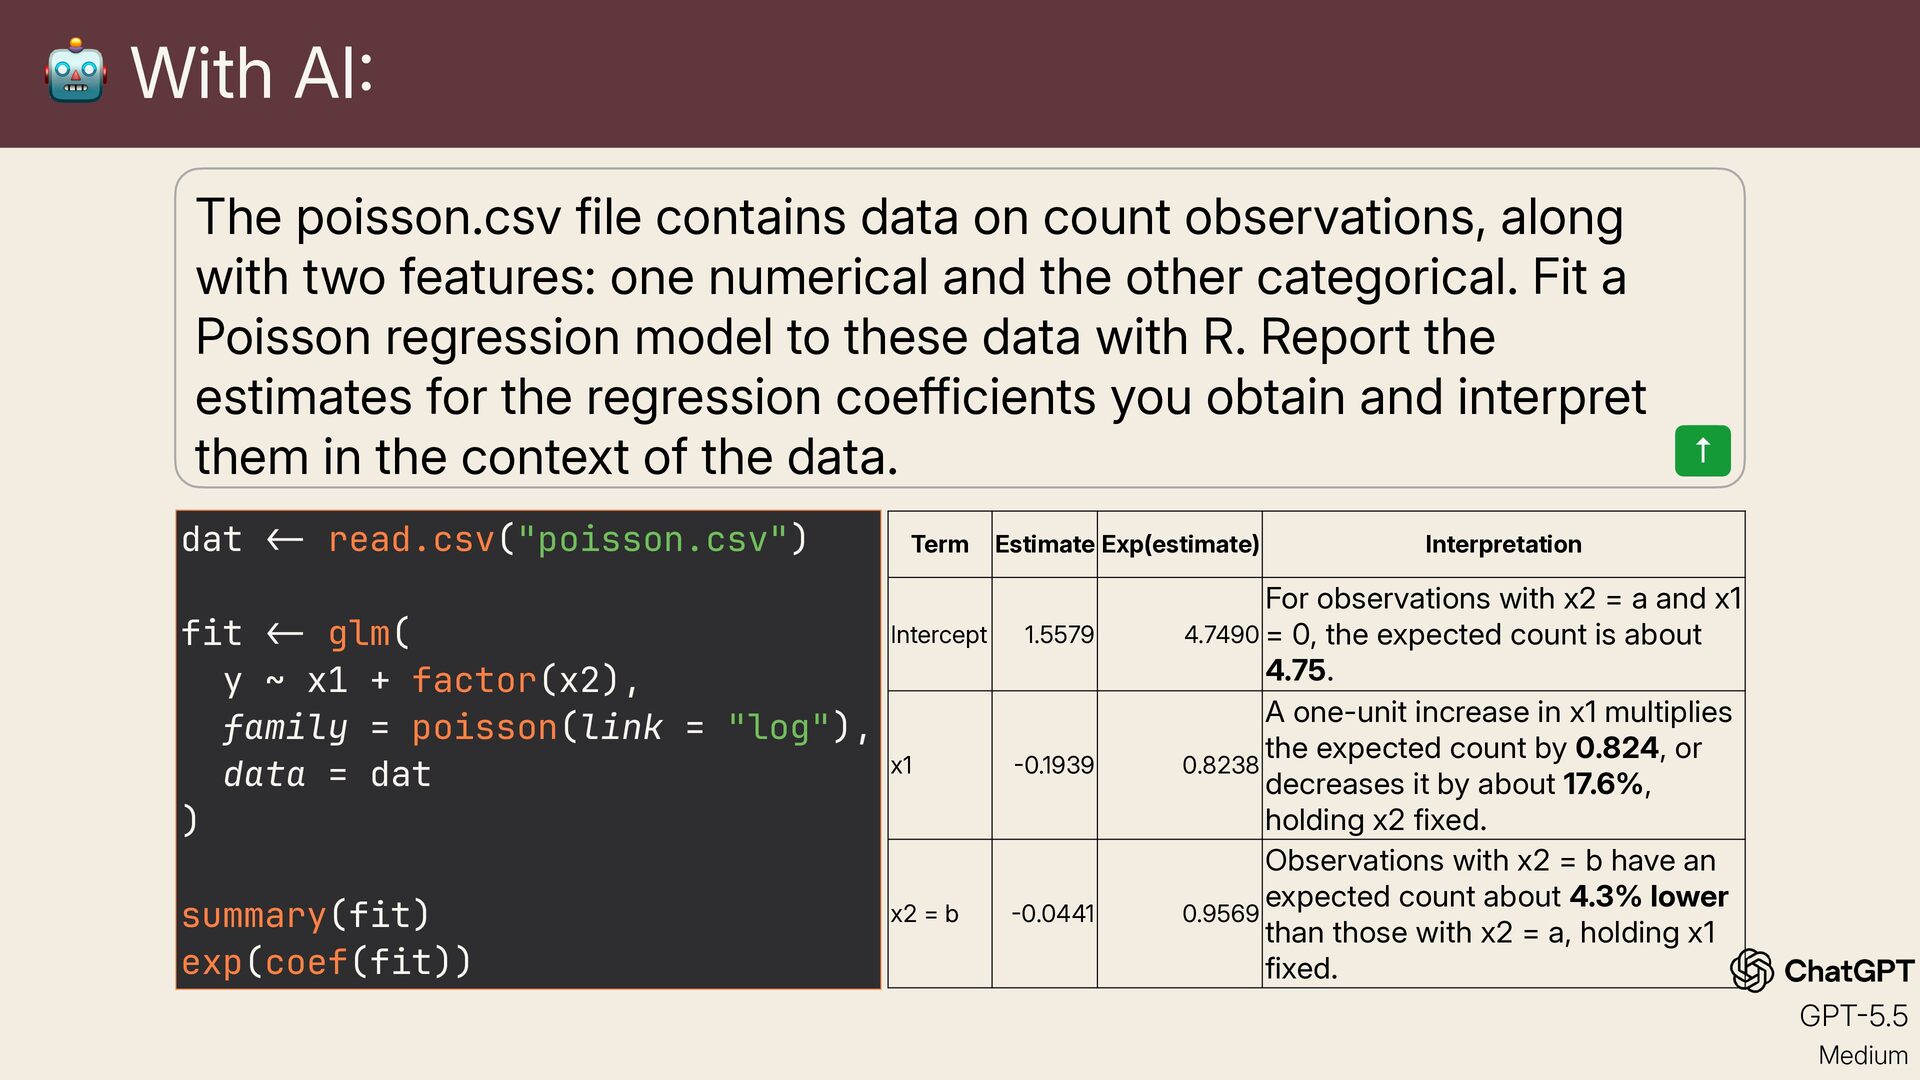
  11. The poisson.csv file contains data on count observations, along with

    two features: one numerical and the other categorical. Fit a Poisson regression model to these data with R. Report the estimates for the regression coefficients you obtain and interpret them in the context of the data. dat read.csv("poisson.csv") Term Intercept fit glm( y ~ x1 + factor(x2), family = poisson(link = "log"), x1 data = dat ) summary(fit) exp(coef(fit)) x2 = b Estimate Exp(estimate) 1.5579 0.1939 0.0441 ↑ Interpretation For observations with x2 = a and x1 4.7490 = 0, the expected count is about 4.75. A one-unit increase in x1 multiplies the expected count by 0.824, or 0.8238 decreases it by about 17.6%, holding x2 fixed. Observations with x2 = b have an expected count about 4.3% lower 0.9569 than those with x2 = a, holding x1 fixed. GPT 5.5 : - - < < Medium - - - 🤖 With AI
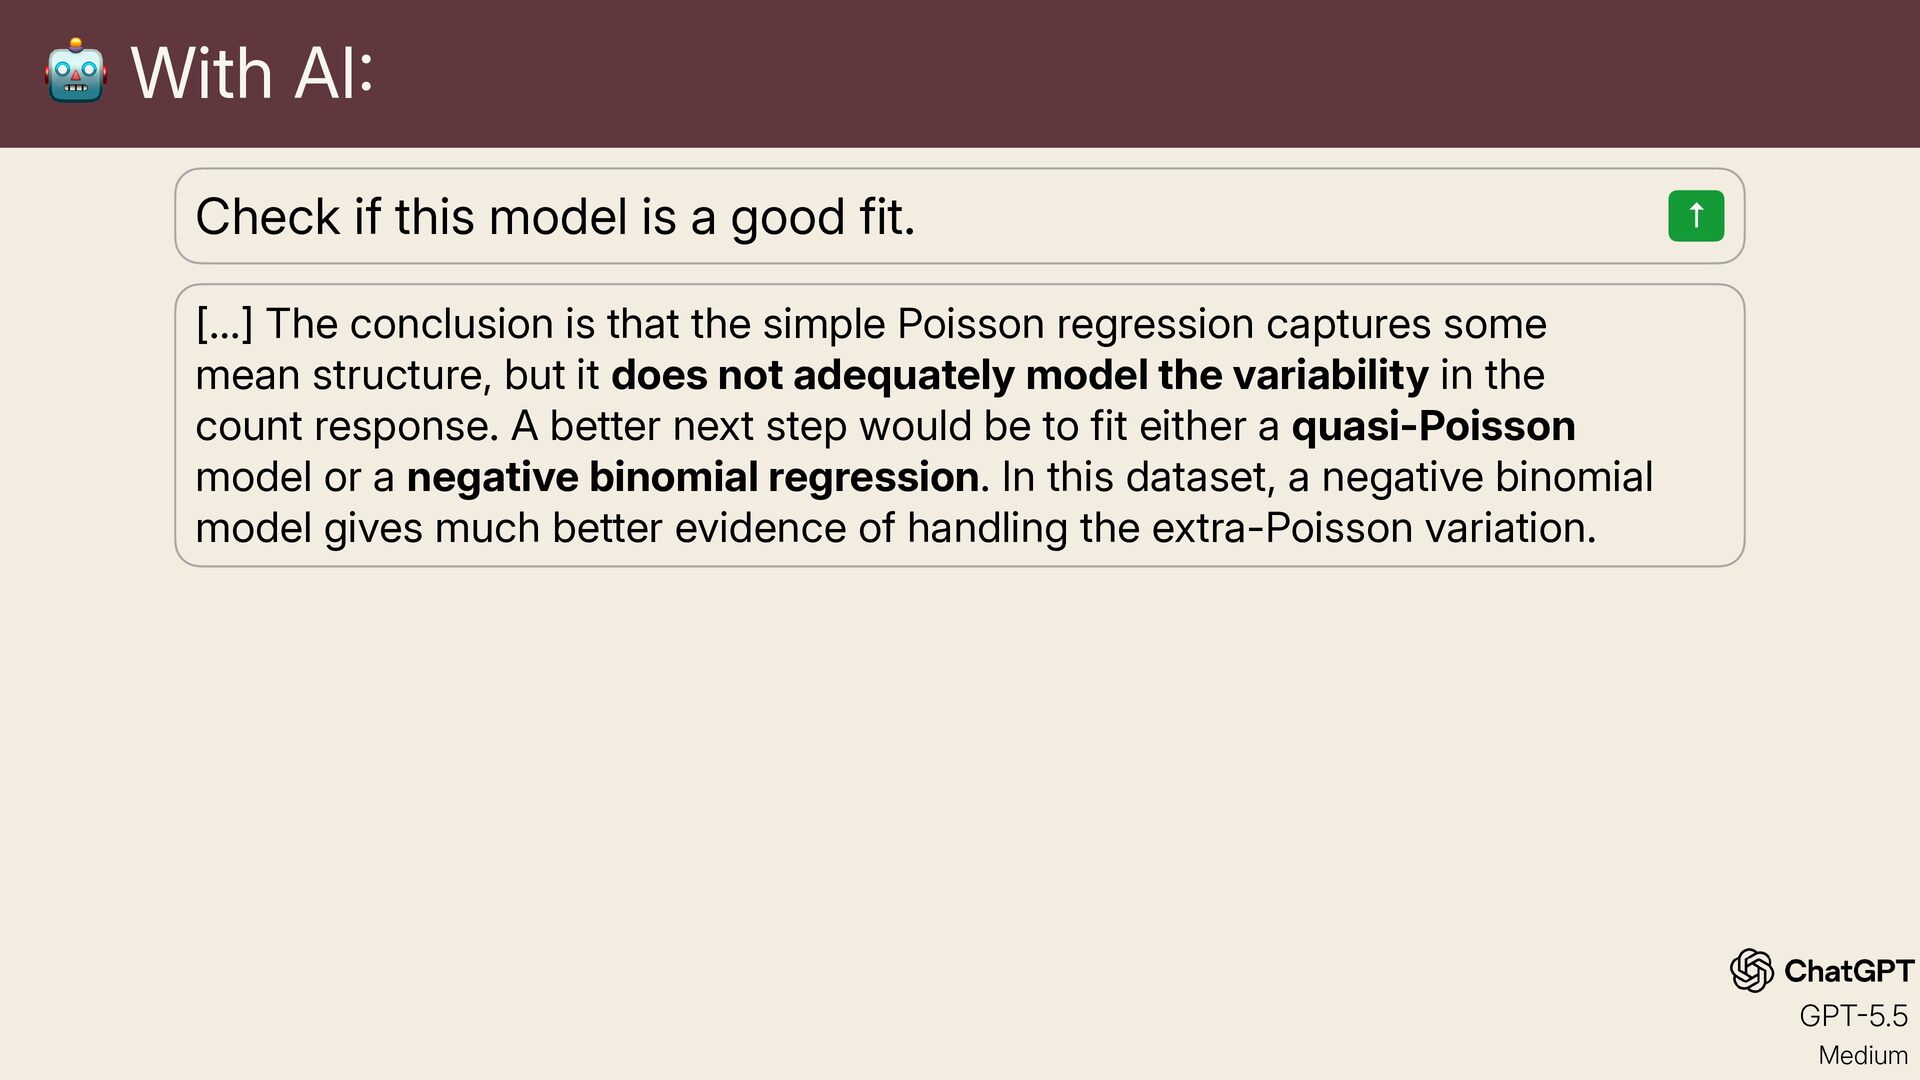
  12. 🤖 With AI Check if this model is a good

    fit. ↑ […] The conclusion is that the simple Poisson regression captures some mean structure, but it does not adequately model the variability in the count response. A better next step would be to fit either a quasi-Poisson model or a negative binomial regression. In this dataset, a negative binomial model gives much better evidence of handling the extra-Poisson variation. GPT 5.5 : - Medium
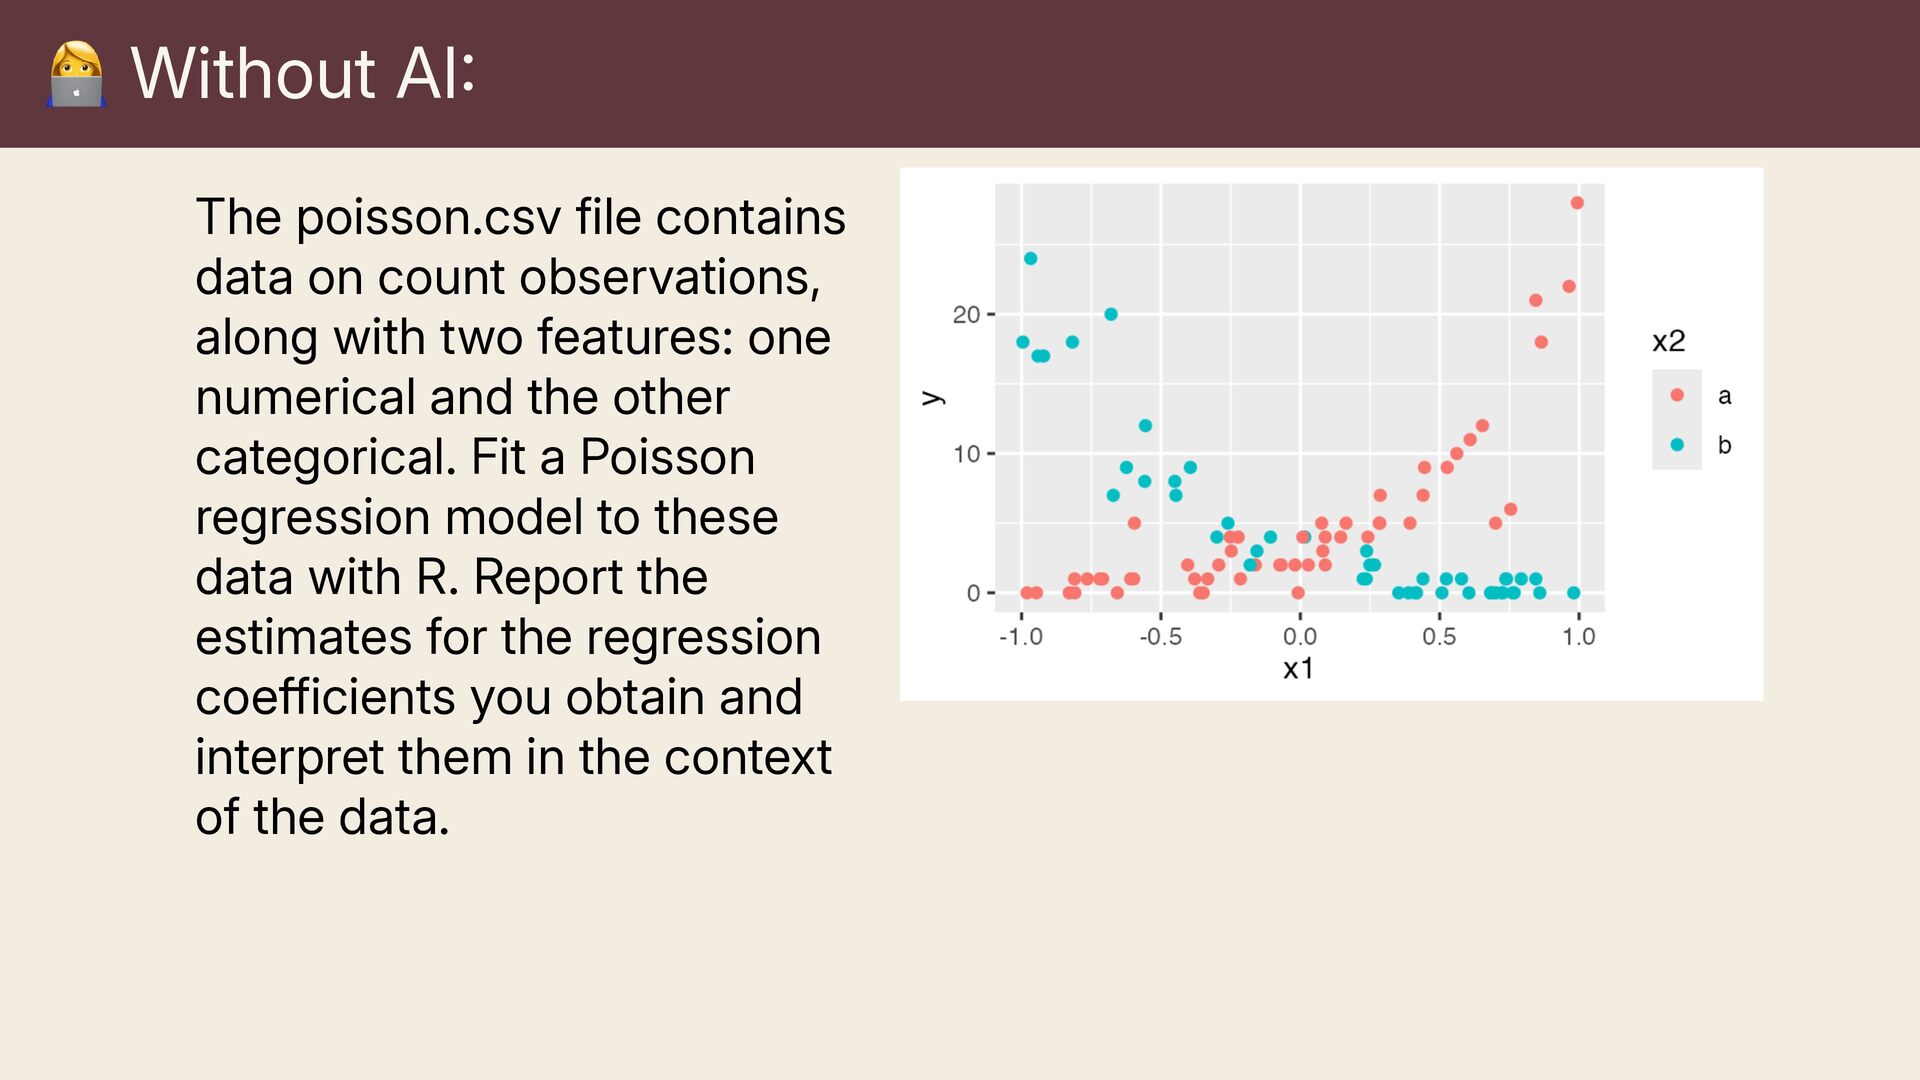
  13. 👩💻 Without AI : The poisson.csv file contains data on

    count observations, along with two features: one numerical and the other categorical. Fit a Poisson regression model to these data with R. Report the estimates for the regression coefficients you obtain and interpret them in the context of the data.
  14. ✅ Small periodic doses, not a single lecture. ✅ Explicit

    examples for proper, sufficient citation, not expecting students get it right. ✅ Expect to update each semester, if not more often. ✅ Also teach the what, the how, and the ethical considerations. ” Level the playing field with explicit “how to best AI instruction
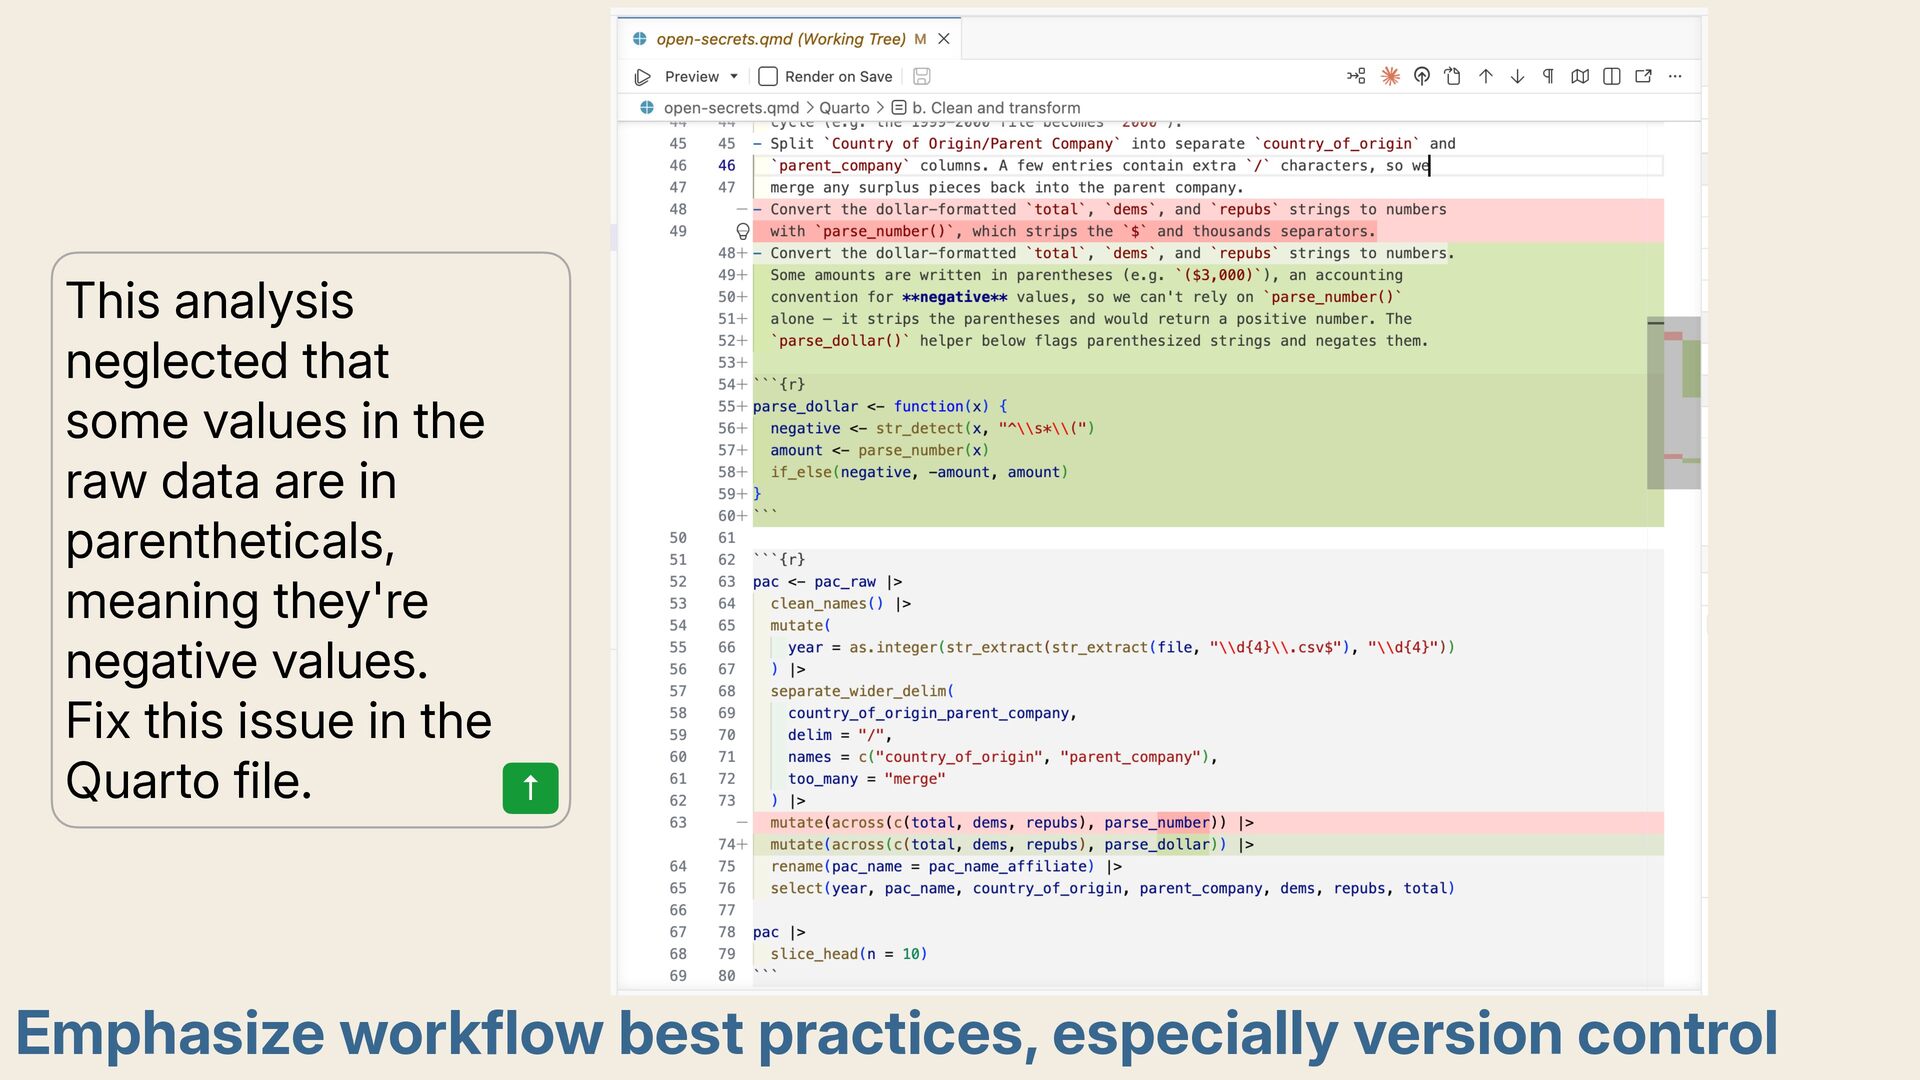
  15. This analysis neglected that some values in the raw data

    are in parentheticals, meaning they're negative values. Fix this issue in the Quarto file. ↑ Emphasize workflow best practices, especially version control
  16. APPROACH 3. Shift AI use from taking shortcuts, towards supporting

    learning ) (+ experiment with building with AI
  17. FROM “THE ART OF STATISTICS “There is no substitute for

    simply looking at data properly.” ” David Spiegelhalter Professor, University of Cambridge