Share
Embed
Kubernetes Node Under the Hood
Kubernetes Node deep dive. This is the presentation I did in CNCF meetup at 3 June 2017, in Netease's main campus.
Lei (Harry) Zhang
June 03, 2017
Transcript
32 slides
-
What is “Node”? Where the container lives Kubernetes cluster is
bootstrapped container centric features are implemented docker/rkt/runV/runC is plugged in networking is implemented volume is enabled sig-node -
Why “Node” Matters? Kubernetes a bottom-up design of container cloud
with special bonus from Google … Node Container Control Panel Pod Replica StatefulSet Deployment DaemonSet Job … How Kubernetes is created? ? Containers -
Borg Borg = engineer oriented deployment scheduling & management system
Google internal is massively using cgroups container, not Container :) Kubernetes = re-innovate Borg with Container -
Kubelet Overview kubelet SyncLoop kubelet SyncLoop proxy proxy 1 Pod
created etcd scheduler api-server -
Kubelet Overview kubelet SyncLoop kubelet SyncLoop proxy proxy 2 Pod
object added etcd scheduler api-server -
Kubelet Overview kubelet SyncLoop kubelet SyncLoop proxy proxy 3.1 New
pod object detected 3.2 Bind pod with node etcd scheduler api-server -
Kubelet Overview kubelet SyncLoop kubelet SyncLoop proxy proxy 4.1 Detected
pod bind with me 4.2 Start containers in pod etcd scheduler api-server -
Pod “Alloc” in Borg The atomic scheduling unit in Kubernetes
Process group in container cloud Implemented in Node But why? -
Are You Using Container Like This? 1.use supervised/systemd to manage
multi-apps in one container 2.ensure container order by tricky scripts 3.add health check for micro-service group 4.copy files from one container to another 5.connect to peer container across whole network stack 6.schedule super affinity containers in cluster -
Multiple containers Multiple Apps in One Container Master Pod kube-apiserver
kube-scheduler controller-manager -
Health Check for Containers Liveness probe Pod will be reported
as Unhealthy Master Pod kube-apiserver kube-scheduler controller-manager -
Copy Files from One to Another Pod volumes is shared
Master Pod kube-apiserver kube-scheduler controller-manager /etc/kubernetes/ssl -
Connect to Peer Container Pod network is shared Master Pod
kube-apiserver kube-scheduler controller-manager network namespace -
Pod is atomic scheduling unit • controller super affinity apiserver
• Request: • controller: 1G, apiserver: 0.5G • Available: • Node_A: 1.25G, Node_B: 2G • What happens if controller is scheduled to Node_A first? Schedule Super Affinity Containers -
So, this is Pod Design pattern in container world decoupling
reuse & refactoring describe more complex workload by container e.g. ML -
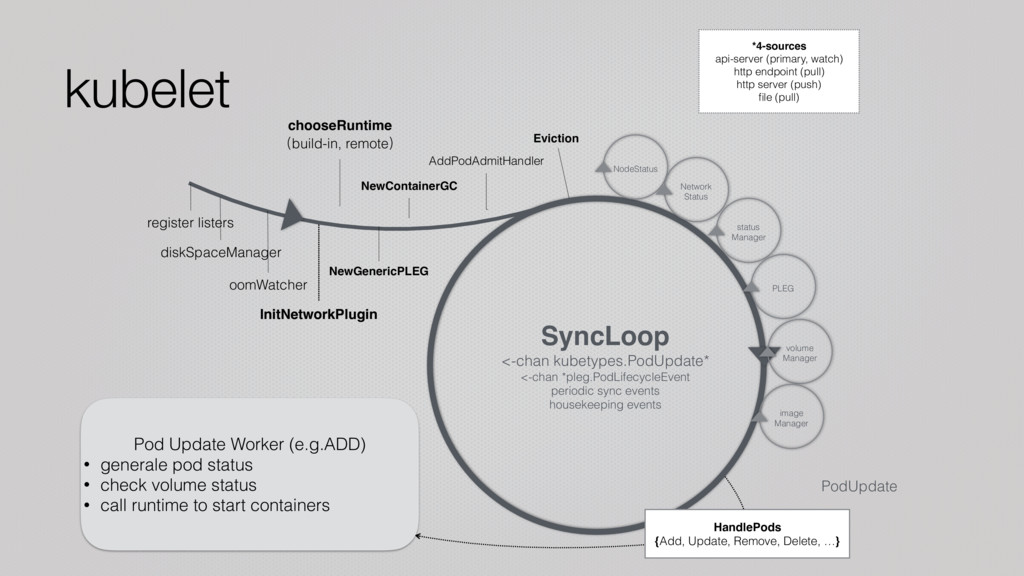
kubelet register listers diskSpaceManager oomWatcher InitNetworkPlugin chooseRuntime (build-in, remote) InitNetworkPlugin
NewGenericPLEG NewContainerGC AddPodAdmitHandler HandlePods {Add, Update, Remove, Delete, …} NodeStatus Network Status status Manager PLEG SyncLoop <-chan kubetypes.PodUpdate* <-chan *pleg.PodLifecycleEvent periodic sync events housekeeping events Pod Update Worker (e.g.ADD) • generale pod status • check volume status • call runtime to start containers volume Manager PodUpdate *4-sources api-server (primary, watch) http endpoint (pull) http server (push) file (pull) image Manager Eviction -
Prepare Volume Volume Manager desired World reconcile Find new pods
createVolumeSpec(newPod) Cache volumes[volName].pods[podName] = pod • Get mountedVolume from actualStateOfWorld • Unmount volumes in mountedVolume but not in desiredStateOfWorld • AttachVolume() if vol in desiredStateOfWorld and not attached • MountVolume() if vol in desiredStateOfWorld and not in mountedVolume • Verify devices that should be detached/unmounted are detached/unmounted • Tips: 1. -v host:path 2. attach VS mount 3. Totally independent from container management -
Eviction Guaranteed Be killed until they exceed their limits or
if the system is under memory pressure and there are no lower priority containers that can be killed. Burstable killed once they exceed their requests and no Best- Effort pods exist when system under memory pressure Best-Effort First to get killed if the system runs out of memory -
Management kubelet CRI Workloads Orchestration kubelet SyncLoop Scheduling api-server Etcd
bind pod, node list pod GenericRuntime SyncPod CRI grpc dockershim remote (no-op) Sandbox Create Delete List Container Create Start Exec Image Pull List shim client api dockerd runtime pod CRI Spec -
CRI Runtime Shim dockershim: docker frakti: hypervisor container (runV) cri-o:
runC rktlet: rkt cri-containerd: containerd -
NODE Container Lifecycle Pod foo container A container B 1.
RunPodSandbox(foo) Created Running Exited null null CreatContainer() StartContainer() StopContainer() RemoveContainer() $ kubectl run foo … A B foo foo (hypervisor) A B 2. CreatContainer(A) 3. StartContainert(A) 4. CreatContainer(B) 5. StartContainer(B) docker runtime hypervisor runtime -
Streaming (old version) kubelet becomes bottleneck runtime shim in critical
path code duplication among runtimes/shims kubectl apiserver kubelet runtime shim 1. kubectl exec -i 2. upgrade connection 3 stream api Design Doc -
Streaming (CRI version) kubectl apiserver kubelet runtime shim 1. kubectl
exec -i 2. upgrade connection 3. stream api serving process 4. launch a http2 server 6. URL: <ip>:<port> 7. redirect responce 8. update connection CRI Design Doc 5. response -
Streaming in Runtime Shim kubelet frakti Streaming Server Runtime apiserver
url of streaming server CRI Exec() url Exec() request $ kubectl exec … "/exec/{token}" stream resp runtime exec api Stream Runtime Exec() Attach() PortForward() -
CNI Network in Runtime Shim Workflow in runtime shim (may
vary from different runtimes): 1. Create a network NS for sandbox 2. plugin.SetUpPod(NS, podID) to configure this NS 3. Also checkpoint the NS path for future usage (TearDown) 4. Infra container join this network namespace 1. or scanning /etc/cni/net.d/xxx.conf to configure sandbox Pod A B eth0 vethXXX -
Physical Server frakti Mixed Runtimes: IaaS-less Kubernetes Hypervisor container +
Docker Handled by: https://github.com/kubernetes/frakti/ 1.Share the same CNI network 2.Fast responsiveness (no VM host needed) 3.High resource efficiency (k8s QoS classes) 4.Mixed run micro-services & legacy application 1. independent kernel + hardware virtualization 2. high I/O performance + host namespace hyper runtime dockershim CRI grpc hypervisor NFV monitor hypervisor NFV logger docker docker docker docker docker -
Node & Kubernetes is Moving Fast GPU isolation libnvidia-container is
proposed CRI enhancement cri-containerd (promising default), cri-tools, hypervisor based secure container CPU pin (and update) and NUMA affinity (CPU sensitive workloads) HugePages support for large memory workloads Local storage management (disk, blkio, quota) “G on G”: run Google internal workloads on Google Kubernetes -
Recently Kubernetes CRI enhancement, equivalence class scheduler (Borg), NodeController, StatefulSet
https://github.com/kubernetes/frakti (Secure container runtime in k8s) Mentoring cri-containerd, cri-tools Unikernels & LinuxKit + k8s (Google Summer of Code 2017) ovn-kubernetes (coming soon) Newly started: Stackube -
Stackube https://github.com/openstack/stackube (Hypernetes v2) 100% upstream Kubernetes + OpenStack plugins
+ Mixed Runtime A IaaS-less, multi-tenant, secure and production ready Kubernetes distro Milestone: 2017.9