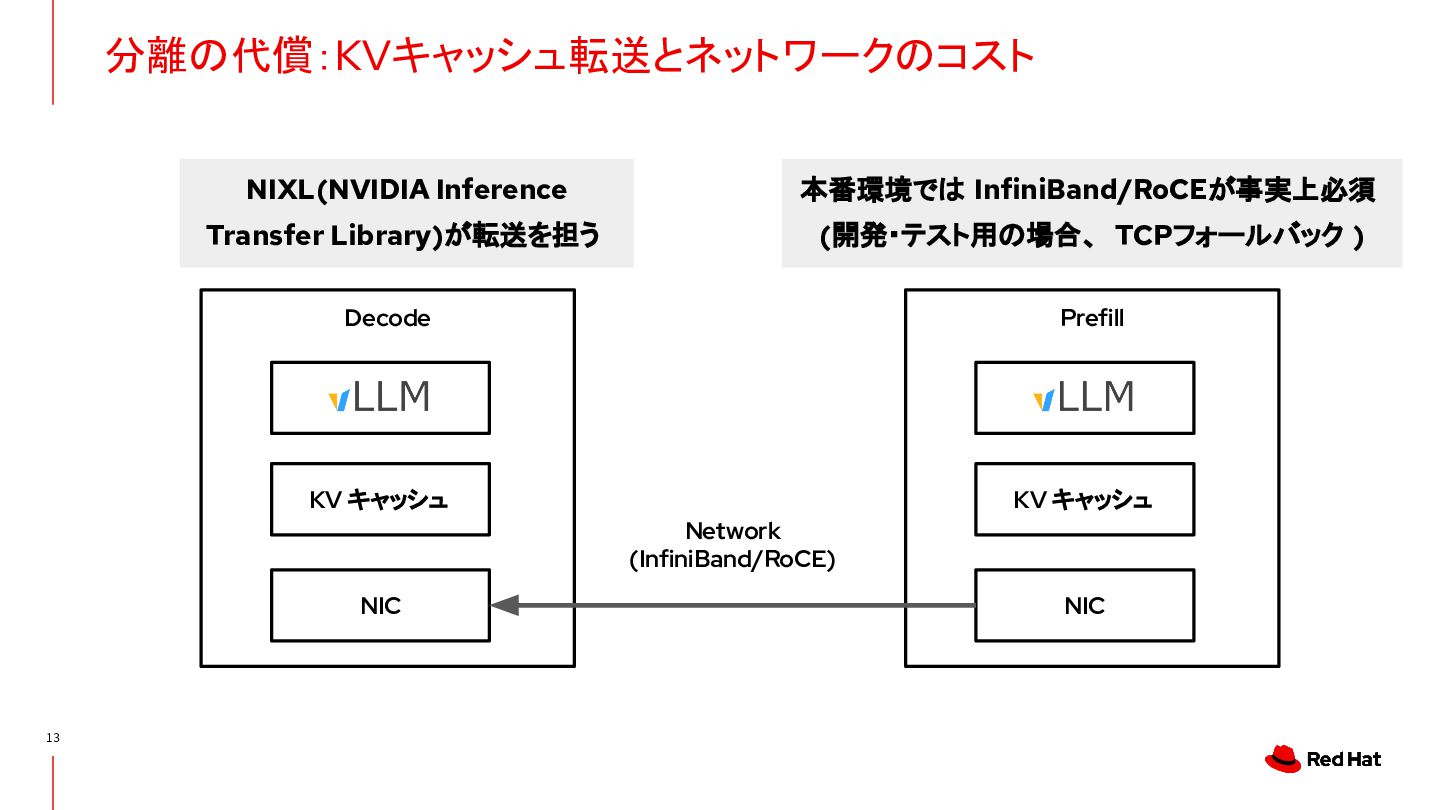
Upgrade to Pro — share decks privately, control downloads, hide ads and more …

1つのリクエストを追って理解する - llm-dのP/D分離

Avatar for akhino akhino
October 14, 2026

1つのリクエストを追って理解する - llm-dのP/D分離

Avatar for akhino

akhino

October 14, 2026

Other Decks in Technology

Transcript

  1. 自己紹介 ▸ 名前 ・ Hino Akihisa ▸ 所属 ・ レッドハット

    - コンサルタント ▸ プロジェクト ・ 主に通信事業者向けOpenShift‧OpenShift AIの導⼊⽀援 ・ AI駆動開発‧プラットフォームエンジニアリングの⽀援 2
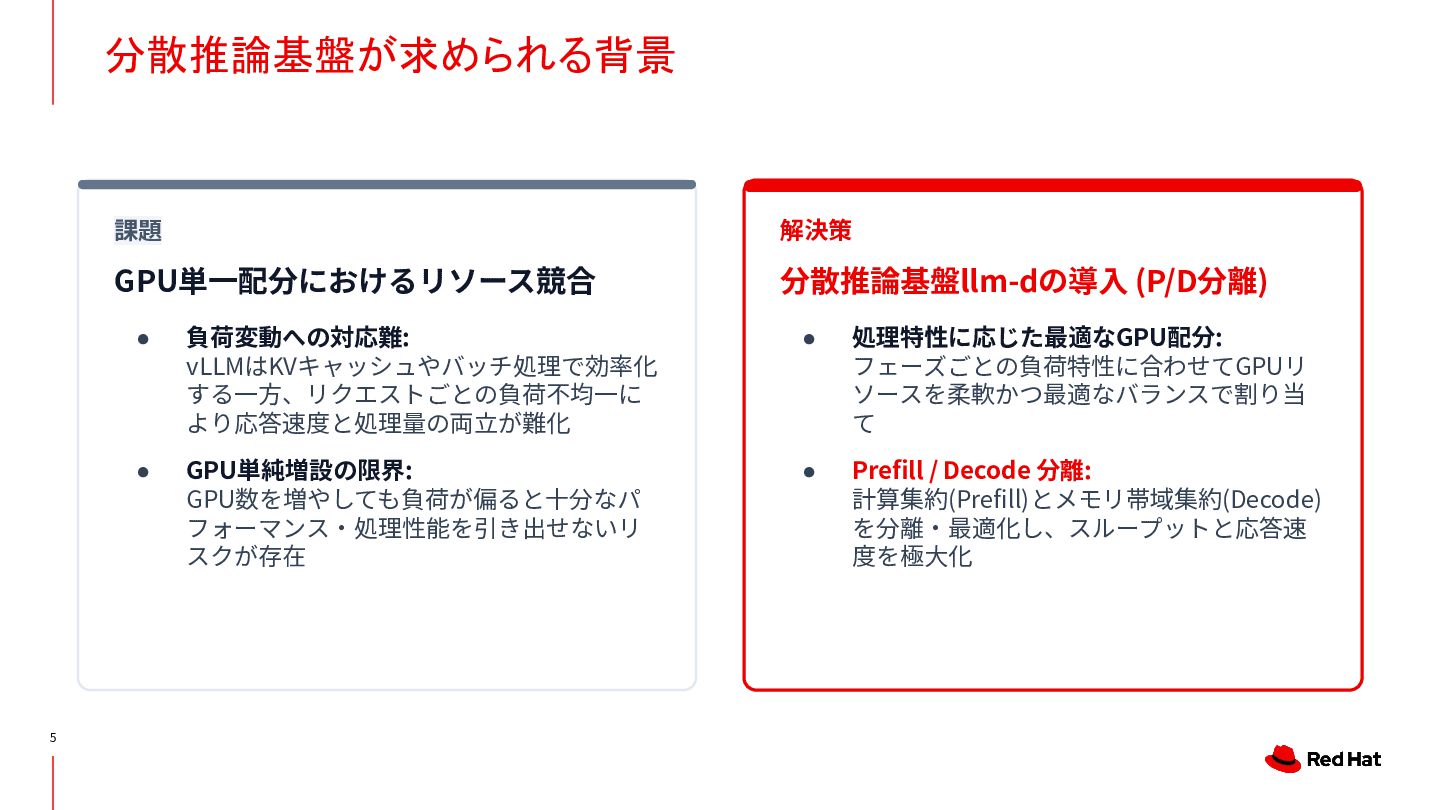
  2. 分散推論基盤が求められる背景 5 課題 解決策 GPU単⼀配分におけるリソース競合 分散推論基盤llm-dの導⼊ (P/D分離) • 負荷変動への対応難: vLLMはKVキャッシュやバッチ処理で効率化

    する⼀⽅、リクエストごとの負荷不均⼀に より応答速度と処理量の両⽴が難化 • 処理特性に応じた最適なGPU配分: フェーズごとの負荷特性に合わせてGPUリ ソースを柔軟かつ最適なバランスで割り当 て • GPU単純増設の限界: GPU数を増やしても負荷が偏ると⼗分なパ フォーマンス‧処理性能を引き出せないリ スクが存在 • Prefill / Decode 分離: 計算集約(Prefill)とメモリ帯域集約(Decode) を分離‧最適化し、スループットと応答速 度を極⼤化
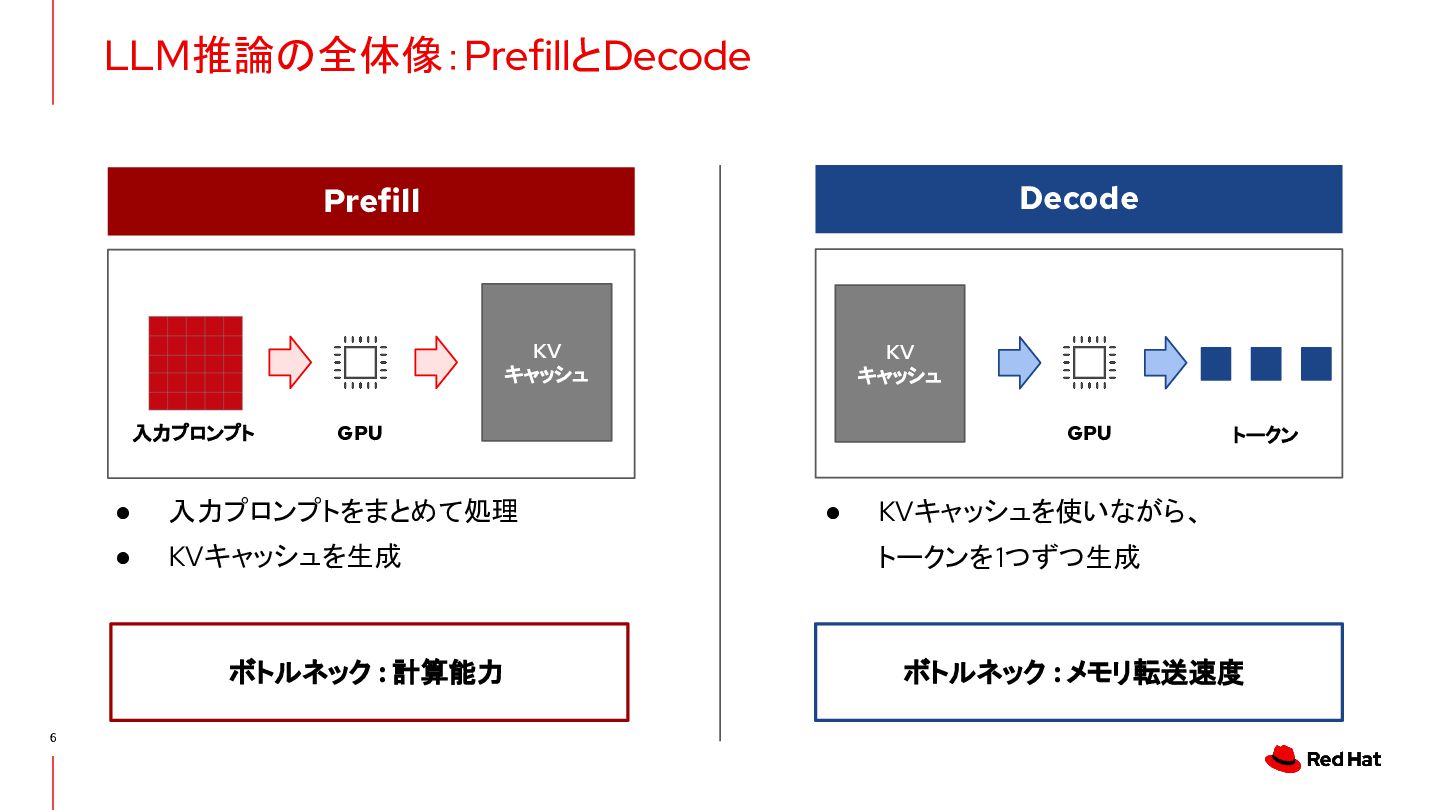
  3. LLM推論の全体像:PrefillとDecode Decode Prefill KV キャッシュ 入力プロンプト GPU GPU • 入力プロンプトをまとめて処理

    • KVキャッシュを生成 ボトルネック : 計算能力 6 KV キャッシュ • トークン KVキャッシュを使いながら、 トークンを1つずつ生成 ボトルネック : メモリ転送速度
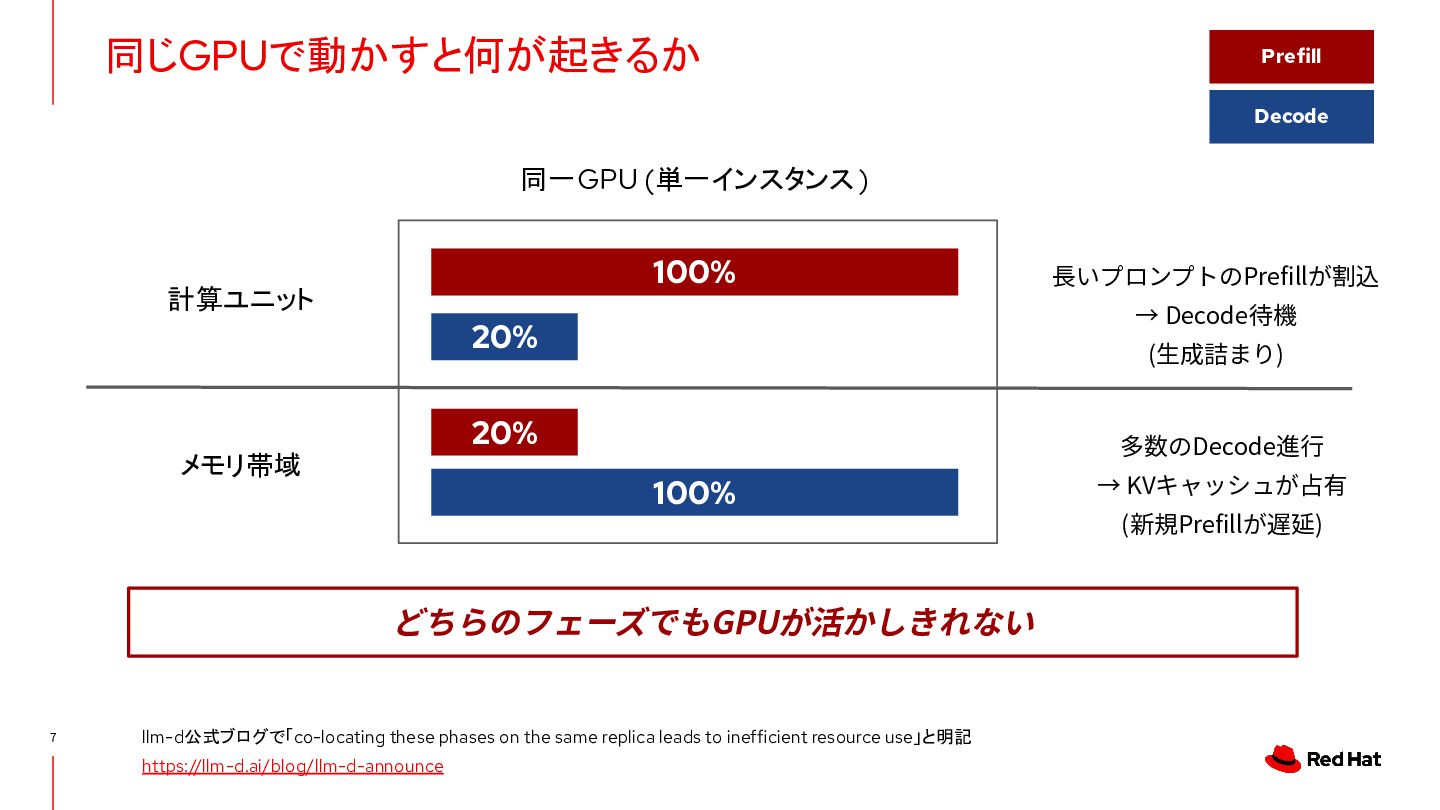
  4. 同じGPUで動かすと何が起きるか Prefill Decode 同一GPU (単一インスタンス ) 100% 計算ユニット → Decode待機

    20% (⽣成詰まり) 20% メモリ帯域 多数のDecode進⾏ 100% どちらのフェーズでもGPUが活かしきれない 7 llm-d公式ブログで「co-locating these phases on the same replica leads to inefficient resource use」と明記 https://llm-d.ai/blog/llm-d-announce ⻑いプロンプトのPrefillが割込 → KVキャッシュが占有 (新規Prefillが遅延)
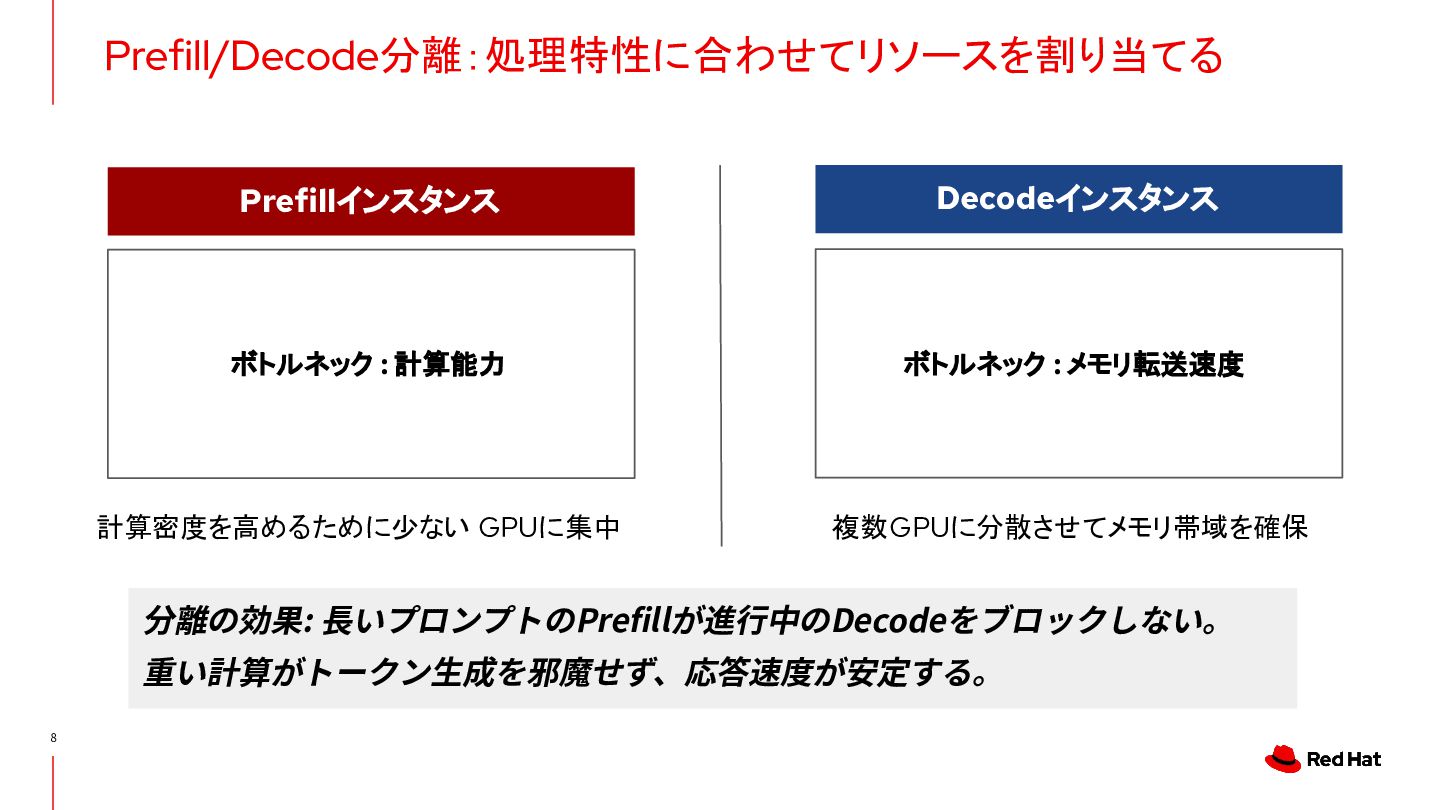
  5. Prefill/Decode分離:処理特性に合わせてリソースを割り当てる Prefillインスタンス Decodeインスタンス ボトルネック : 計算能力 ボトルネック : メモリ転送速度 計算密度を高めるために少ない

    GPUに集中 複数GPUに分散させてメモリ帯域を確保 分離の効果: ⻑いプロンプトのPrefillが進⾏中のDecodeをブロックしない。 重い計算がトークン⽣成を邪魔せず、応答速度が安定する。 8
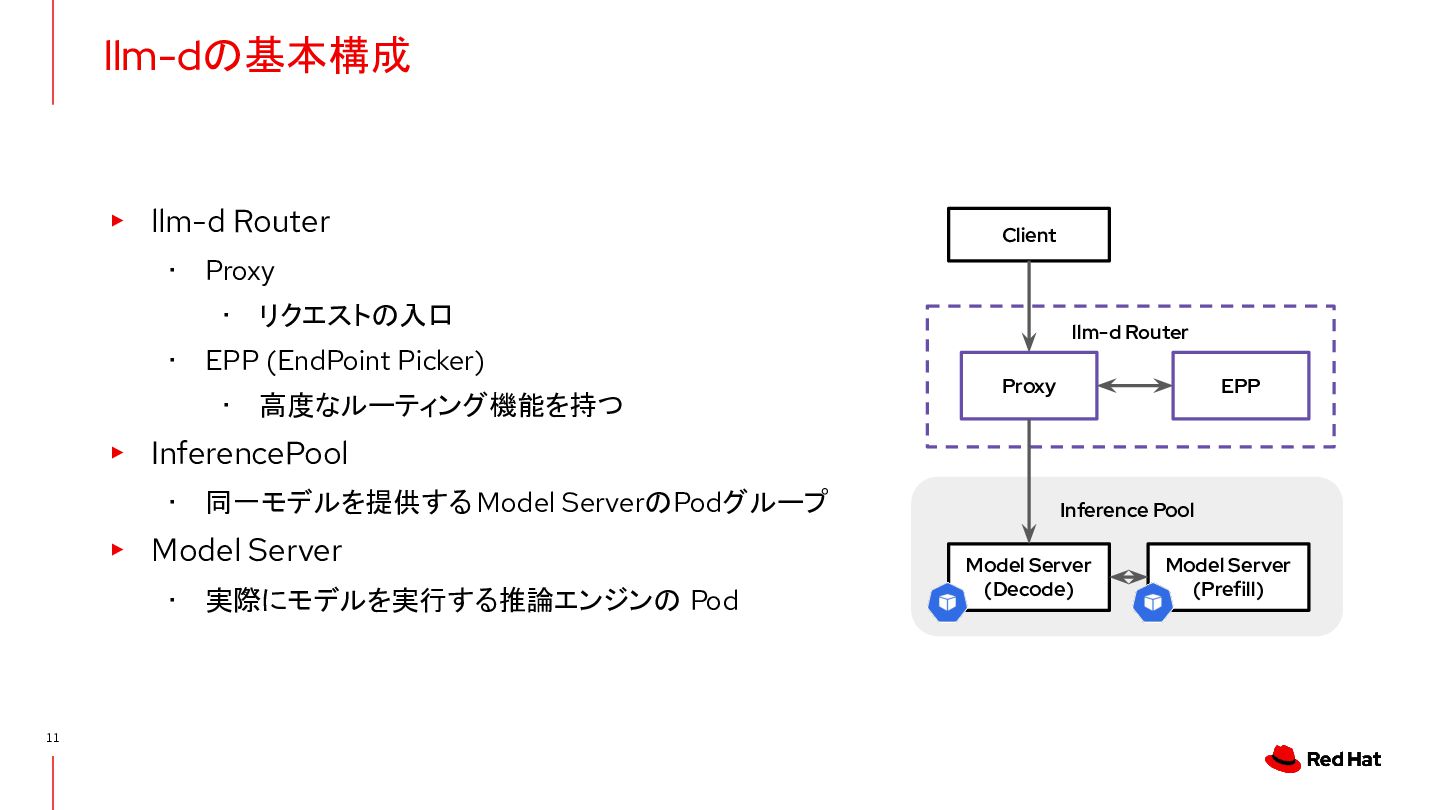
  6. llm-dの基本構成 ▸ llm-d Router Client ・ Proxy ・ リクエストの入口 ・

    EPP (EndPoint Picker) ・ 高度なルーティング機能を持つ llm-d Router Proxy EPP ▸ InferencePool ・ 同一モデルを提供する Model ServerのPodグループ ▸ Model Server ・ 実際にモデルを実行する推論エンジンの Pod 11 Inference Pool Model Server (Decode) Model Server (Prefill)
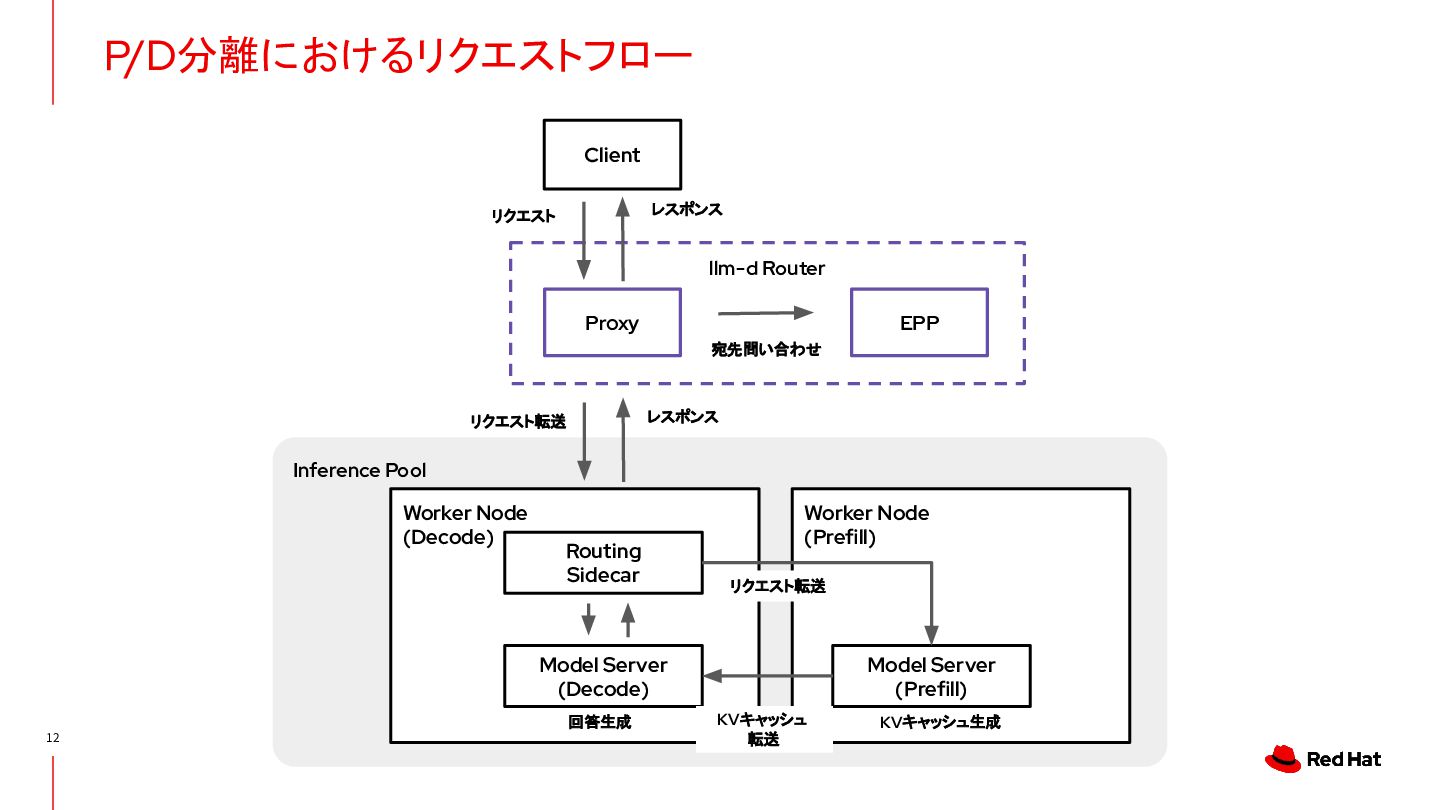
  7. P/D分離におけるリクエストフロー Client レスポンス リクエスト llm-d Router Proxy EPP 宛先問い合わせ レスポンス

    リクエスト転送 Inference Pool Worker Node (Decode) Routing Sidecar Worker Node (Prefill) リクエスト転送 Model Server (Decode) 回答生成 12 Model Server (Prefill) KVキャッシュ 転送 KVキャッシュ生成
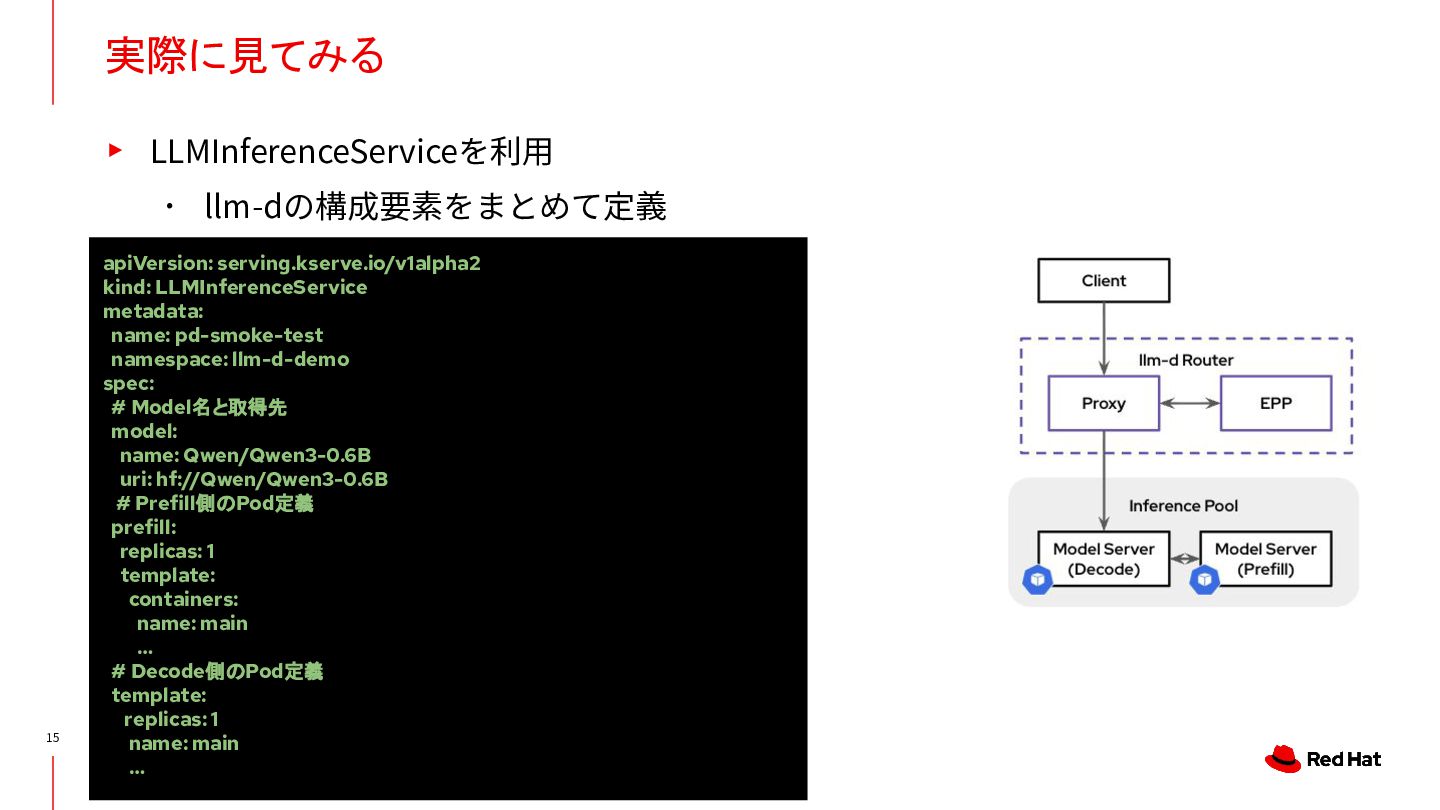
  8. 実際に見てみる ▸ LLMInferenceServiceを利⽤ ・ llm-dの構成要素をまとめて定義 15 apiVersion: serving.kserve.io/v1alpha2 kind: LLMInferenceService

    metadata: name: pd-smoke-test namespace: llm-d-demo spec: # Model名と取得先 model: name: Qwen/Qwen3-0.6B uri: hf://Qwen/Qwen3-0.6B # Prefill側のPod定義 prefill: replicas: 1 template: containers: name: main … # Decode側のPod定義 template: replicas: 1 name: main …
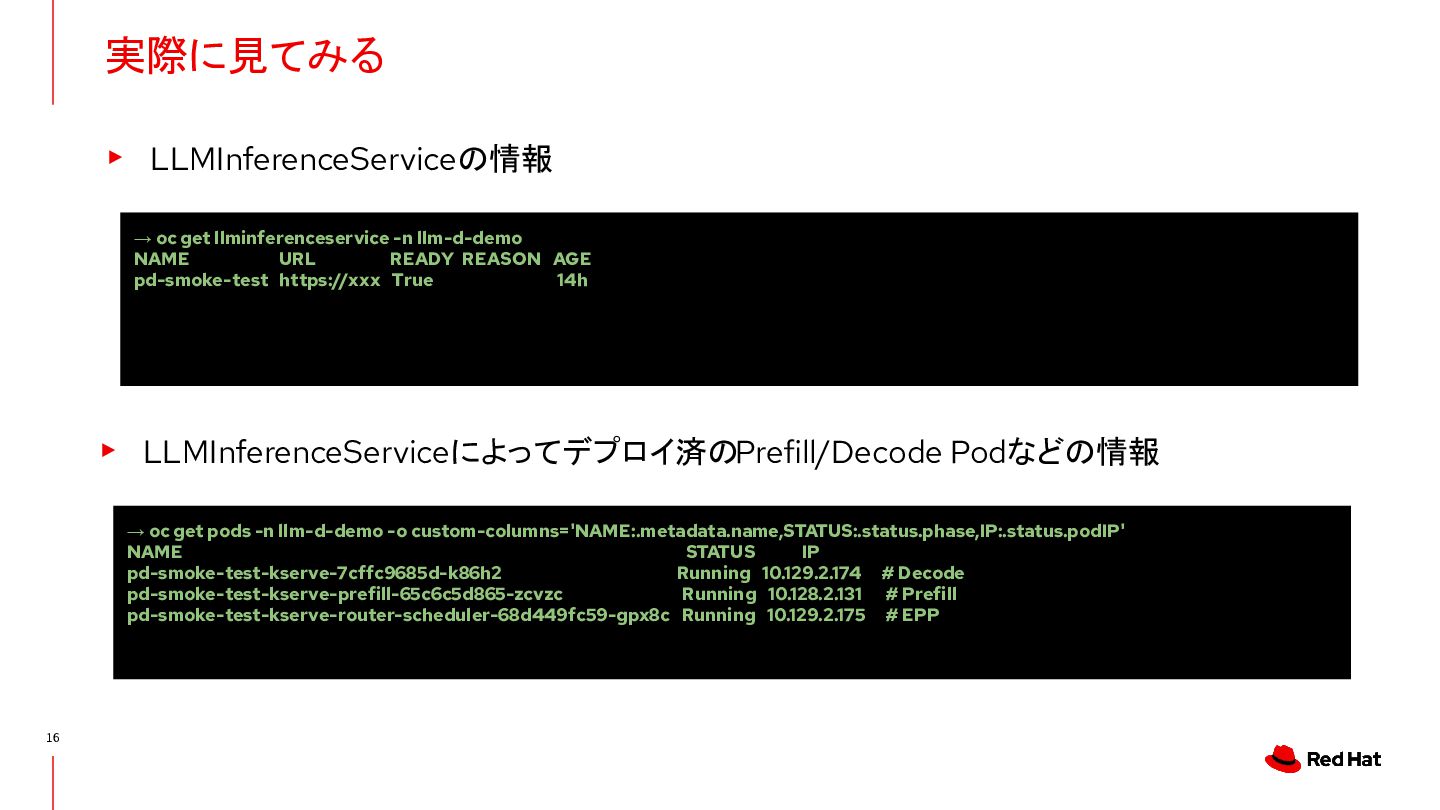
  9. 実際に見てみる ▸ LLMInferenceServiceの情報 → oc get llminferenceservice -n llm-d-demo NAME

    URL READY REASON AGE pd-smoke-test https://xxx True 14h ▸ LLMInferenceServiceによってデプロイ済のPrefill/Decode Podなどの情報 → oc get pods -n llm-d-demo -o custom-columns='NAME:.metadata.name,STATUS:.status.phase,IP:.status.podIP' NAME STATUS IP pd-smoke-test-kserve-7cffc9685d-k86h2 Running 10.129.2.174 # Decode pd-smoke-test-kserve-prefill-65c6c5d865-zcvzc Running 10.128.2.131 # Prefill pd-smoke-test-kserve-router-scheduler-68d449fc59-gpx8c Running 10.129.2.175 # EPP 16
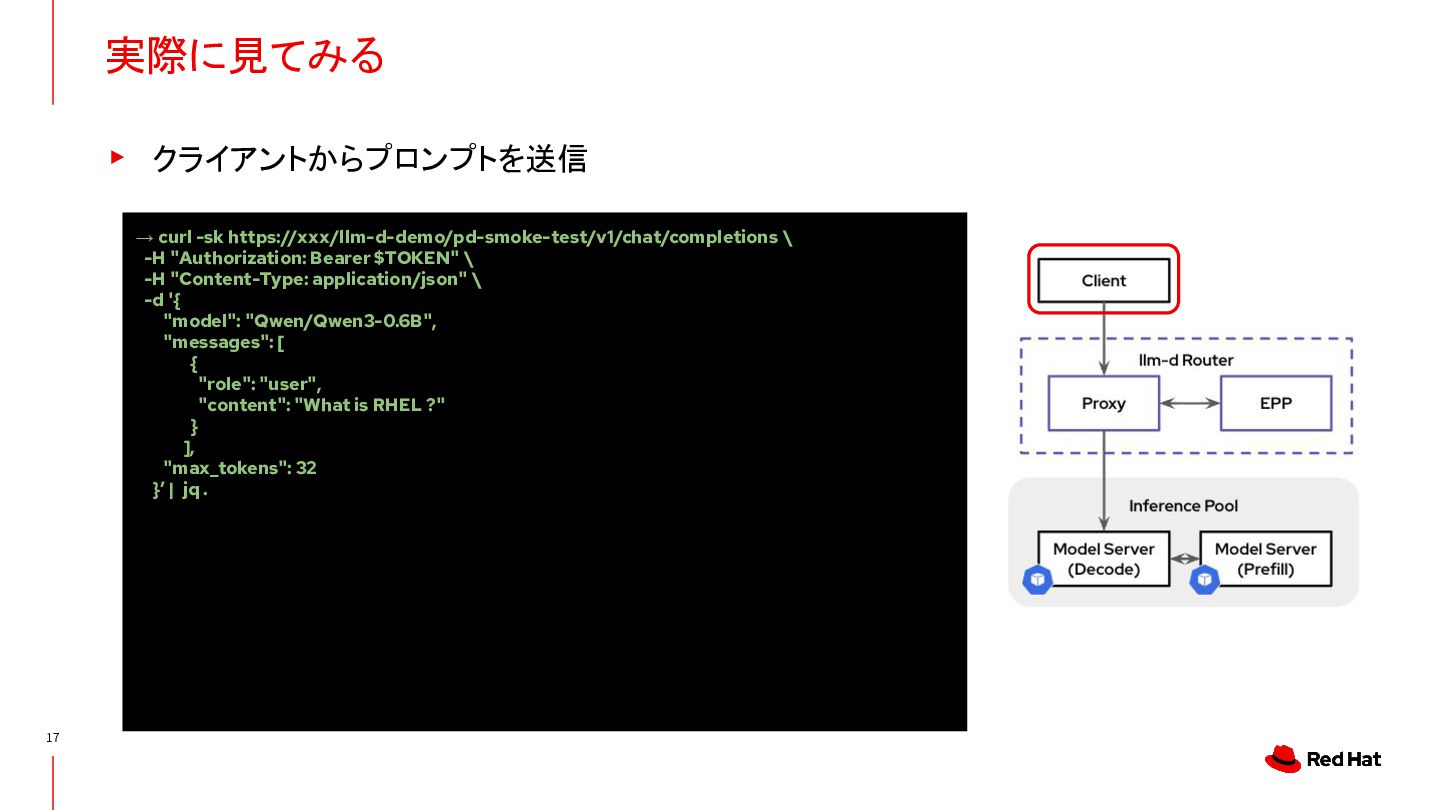
  10. 実際に見てみる ▸ クライアントからプロンプトを送信 → curl -sk https://xxx/llm-d-demo/pd-smoke-test/v1/chat/completions \ -H "Authorization:

    Bearer $TOKEN" \ -H "Content-Type: application/json" \ -d '{ "model": "Qwen/Qwen3-0.6B", "messages": [ { "role": "user", "content": "What is RHEL ?" } ], "max_tokens": 32 }’ | jq . 17
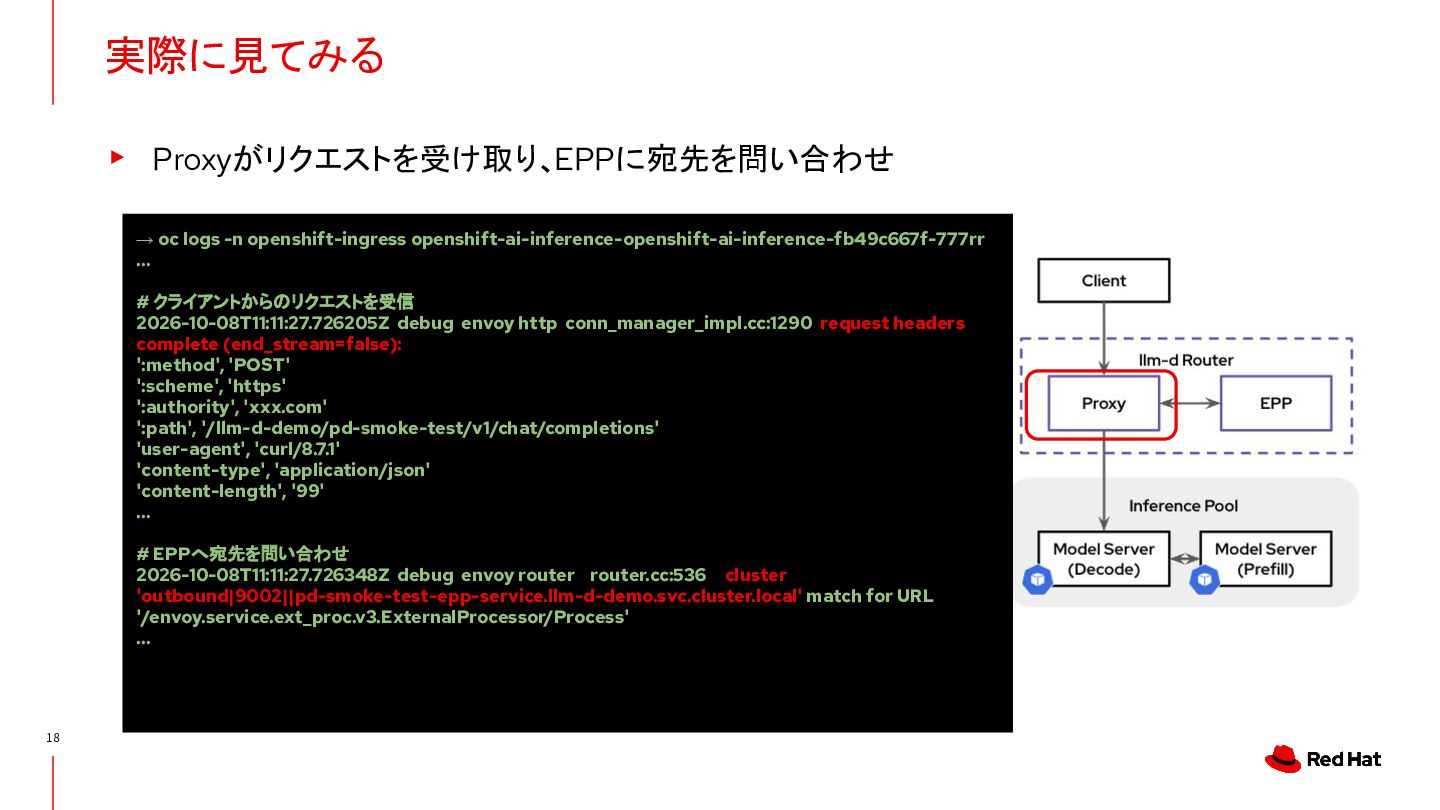
  11. 実際に見てみる ▸ Proxyがリクエストを受け取り、EPPに宛先を問い合わせ → oc logs -n openshift-ingress openshift-ai-inference-openshift-ai-inference-fb49c667f-777rr …

    # クライアントからのリクエストを受信 2026-10-08T11:11:27.726205Z debug envoy http conn_manager_impl.cc:1290 request headers complete (end_stream=false): ':method', 'POST' ':scheme', 'https' ':authority', 'xxx.com' ':path', '/llm-d-demo/pd-smoke-test/v1/chat/completions' 'user-agent', 'curl/8.7.1' 'content-type', 'application/json' 'content-length', '99' … # EPPへ宛先を問い合わせ 2026-10-08T11:11:27.726348Z debug envoy router router.cc:536 cluster 'outbound|9002||pd-smoke-test-epp-service.llm-d-demo.svc.cluster.local' match for URL '/envoy.service.ext_proc.v3.ExternalProcessor/Process' … 18
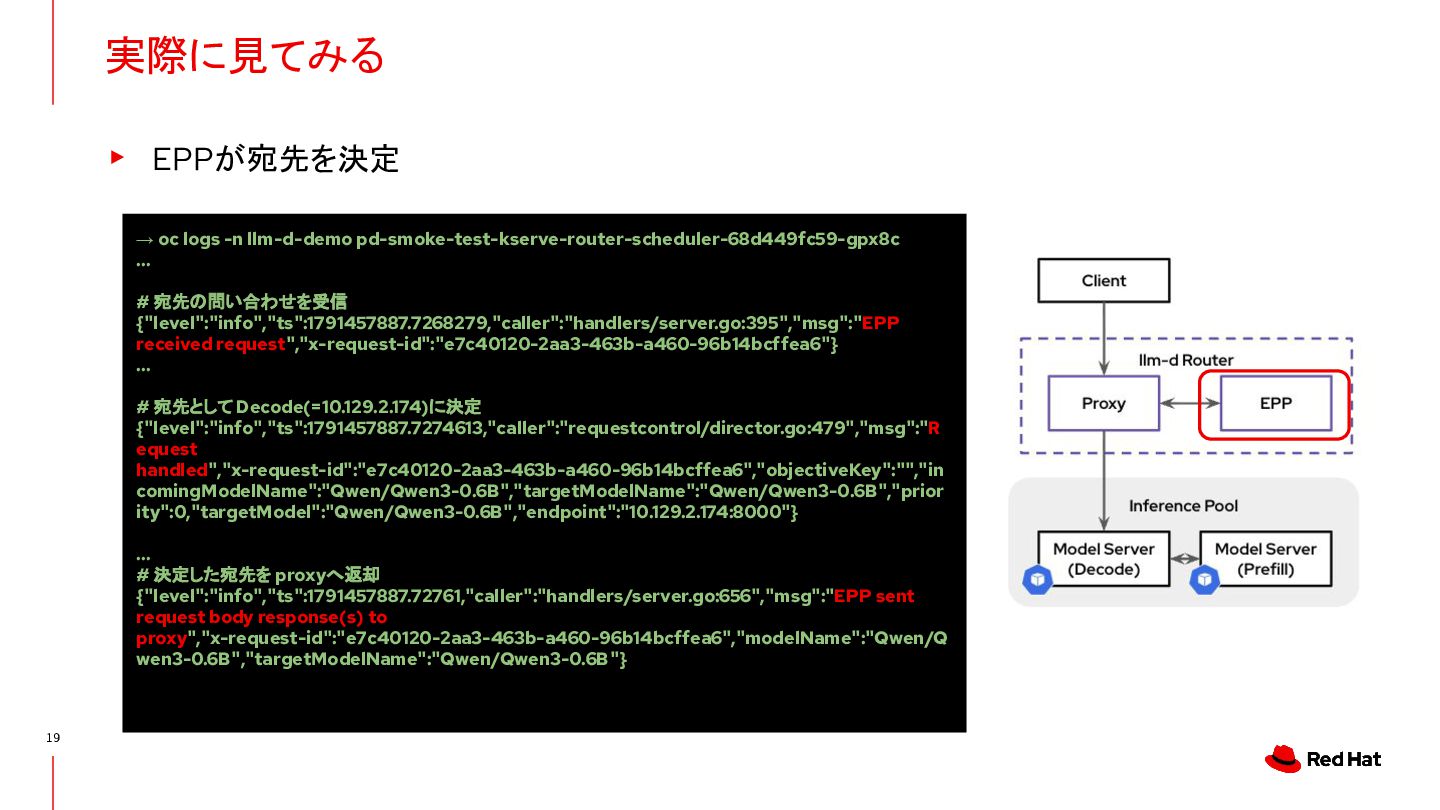
  12. 実際に見てみる ▸ EPPが宛先を決定 → oc logs -n llm-d-demo pd-smoke-test-kserve-router-scheduler-68d449fc59-gpx8c …

    # 宛先の問い合わせを受信 {"level":"info","ts":1791457887.7268279,"caller":"handlers/server.go:395","msg":"EPP received request","x-request-id":"e7c40120-2aa3-463b-a460-96b14bcffea6"} … # 宛先として Decode(=10.129.2.174)に決定 {"level":"info","ts":1791457887.7274613,"caller":"requestcontrol/director.go:479","msg":"R equest handled","x-request-id":"e7c40120-2aa3-463b-a460-96b14bcffea6","objectiveKey":"","in comingModelName":"Qwen/Qwen3-0.6B","targetModelName":"Qwen/Qwen3-0.6B","prior ity":0,"targetModel":"Qwen/Qwen3-0.6B","endpoint":"10.129.2.174:8000"} … # 決定した宛先を proxyへ返却 {"level":"info","ts":1791457887.72761,"caller":"handlers/server.go:656","msg":"EPP sent request body response(s) to proxy","x-request-id":"e7c40120-2aa3-463b-a460-96b14bcffea6","modelName":"Qwen/Q wen3-0.6B","targetModelName":"Qwen/Qwen3-0.6B"} 19
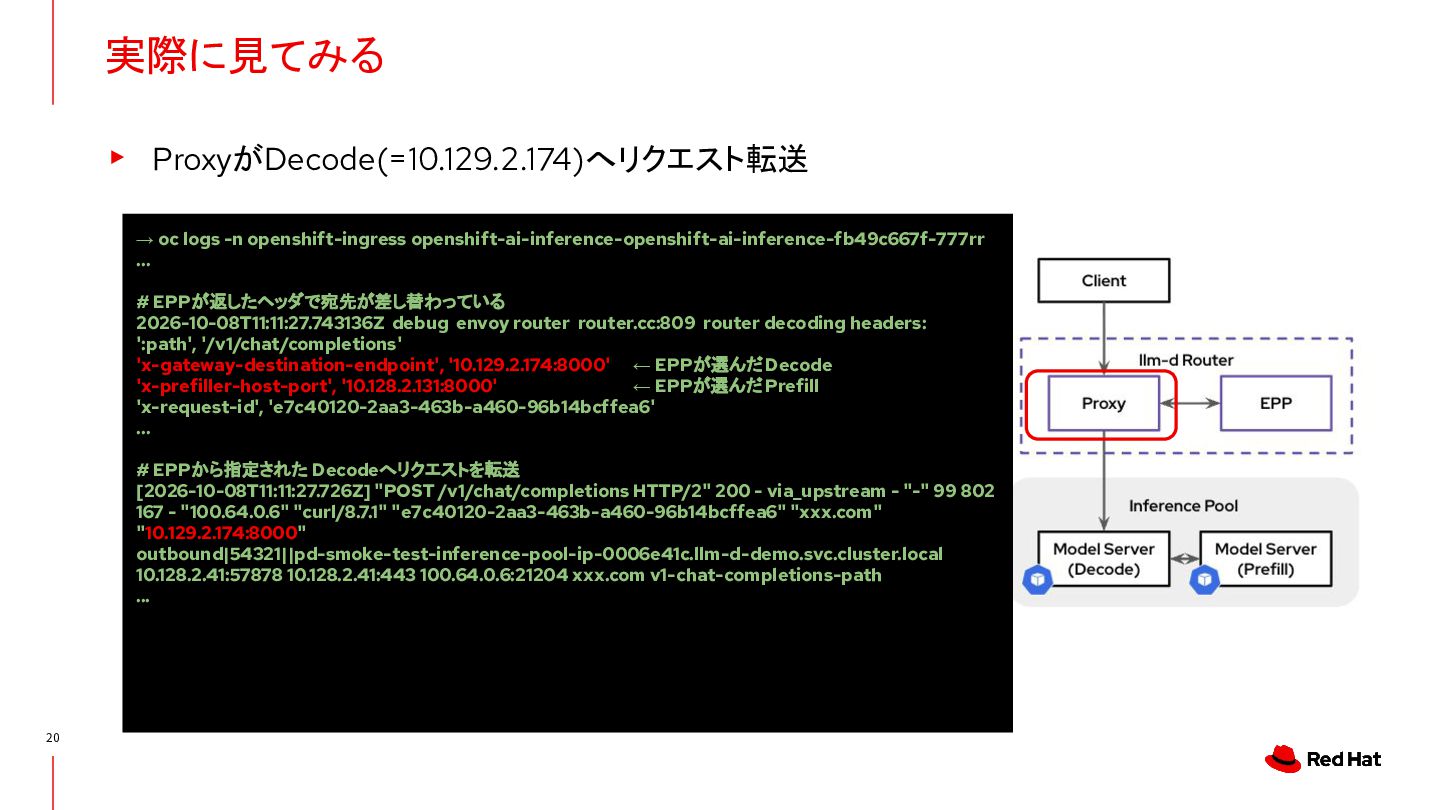
  13. 実際に見てみる ▸ ProxyがDecode(=10.129.2.174)へリクエスト転送 → oc logs -n openshift-ingress openshift-ai-inference-openshift-ai-inference-fb49c667f-777rr …

    # EPPが返したヘッダで宛先が差し替わっている 2026-10-08T11:11:27.743136Z debug envoy router router.cc:809 router decoding headers: ':path', '/v1/chat/completions' 'x-gateway-destination-endpoint', '10.129.2.174:8000' ← EPPが選んだ Decode 'x-prefiller-host-port', '10.128.2.131:8000' ← EPPが選んだ Prefill 'x-request-id', 'e7c40120-2aa3-463b-a460-96b14bcffea6' … # EPPから指定された Decodeへリクエストを転送 [2026-10-08T11:11:27.726Z] "POST /v1/chat/completions HTTP/2" 200 - via_upstream - "-" 99 802 167 - "100.64.0.6" "curl/8.7.1" "e7c40120-2aa3-463b-a460-96b14bcffea6" "xxx.com" "10.129.2.174:8000" outbound|54321||pd-smoke-test-inference-pool-ip-0006e41c.llm-d-demo.svc.cluster.local 10.128.2.41:57878 10.128.2.41:443 100.64.0.6:21204 xxx.com v1-chat-completions-path ... 20
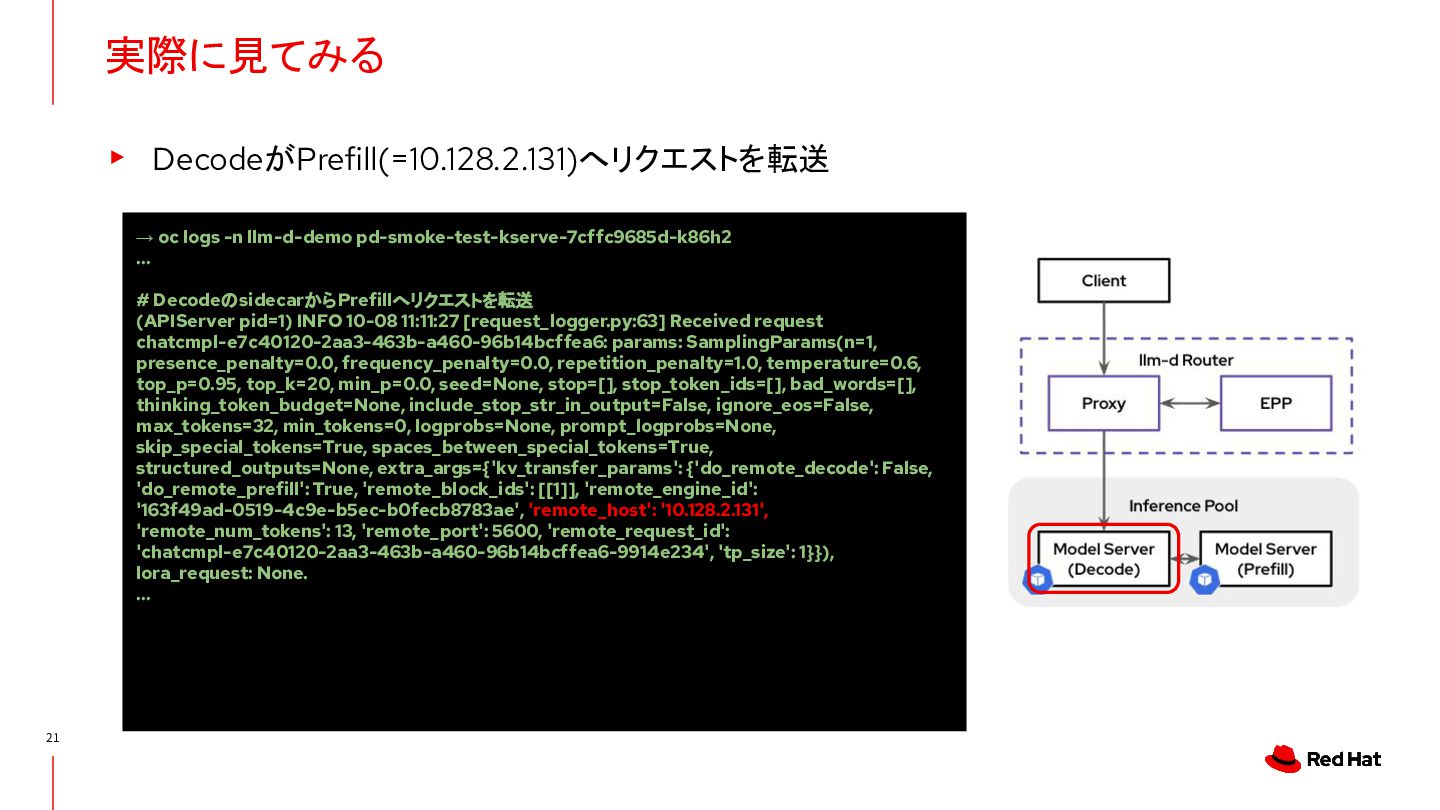
  14. 実際に見てみる ▸ DecodeがPrefill(=10.128.2.131)へリクエストを転送 → oc logs -n llm-d-demo pd-smoke-test-kserve-7cffc9685d-k86h2 …

    # DecodeのsidecarからPrefillへリクエストを転送 (APIServer pid=1) INFO 10-08 11:11:27 [request_logger.py:63] Received request chatcmpl-e7c40120-2aa3-463b-a460-96b14bcffea6: params: SamplingParams(n=1, presence_penalty=0.0, frequency_penalty=0.0, repetition_penalty=1.0, temperature=0.6, top_p=0.95, top_k=20, min_p=0.0, seed=None, stop=[], stop_token_ids=[], bad_words=[], thinking_token_budget=None, include_stop_str_in_output=False, ignore_eos=False, max_tokens=32, min_tokens=0, logprobs=None, prompt_logprobs=None, skip_special_tokens=True, spaces_between_special_tokens=True, structured_outputs=None, extra_args={'kv_transfer_params': {'do_remote_decode': False, 'do_remote_prefill': True, 'remote_block_ids': [[1]], 'remote_engine_id': '163f49ad-0519-4c9e-b5ec-b0fecb8783ae', 'remote_host': '10.128.2.131', 'remote_num_tokens': 13, 'remote_port': 5600, 'remote_request_id': 'chatcmpl-e7c40120-2aa3-463b-a460-96b14bcffea6-9914e234', 'tp_size': 1}}), lora_request: None. … 21
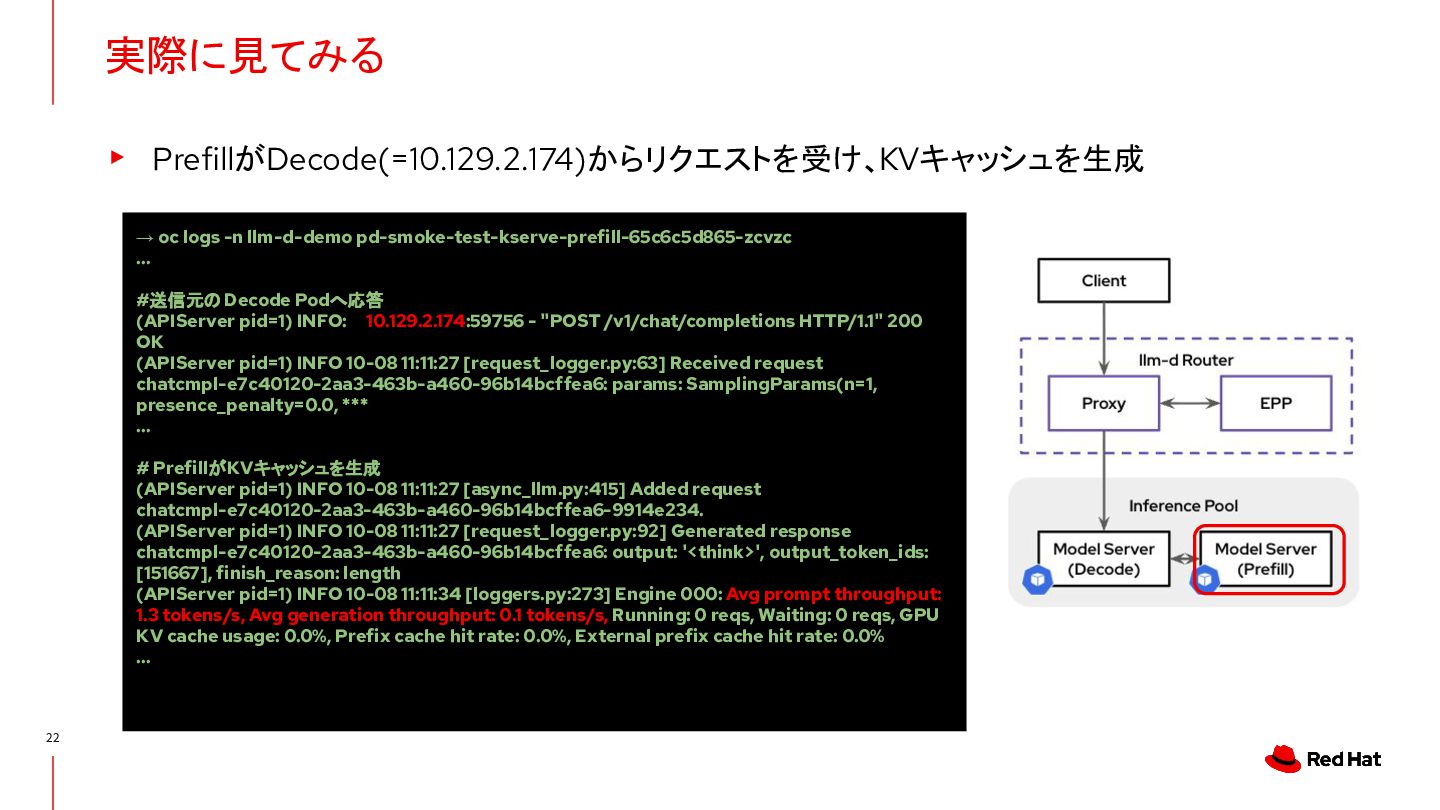
  15. 実際に見てみる ▸ PrefillがDecode(=10.129.2.174)からリクエストを受け、KVキャッシュを生成 → oc logs -n llm-d-demo pd-smoke-test-kserve-prefill-65c6c5d865-zcvzc …

    #送信元の Decode Podへ応答 (APIServer pid=1) INFO: 10.129.2.174:59756 - "POST /v1/chat/completions HTTP/1.1" 200 OK (APIServer pid=1) INFO 10-08 11:11:27 [request_logger.py:63] Received request chatcmpl-e7c40120-2aa3-463b-a460-96b14bcffea6: params: SamplingParams(n=1, presence_penalty=0.0, *** … # PrefillがKVキャッシュを生成 (APIServer pid=1) INFO 10-08 11:11:27 [async_llm.py:415] Added request chatcmpl-e7c40120-2aa3-463b-a460-96b14bcffea6-9914e234. (APIServer pid=1) INFO 10-08 11:11:27 [request_logger.py:92] Generated response chatcmpl-e7c40120-2aa3-463b-a460-96b14bcffea6: output: '<think>', output_token_ids: [151667], finish_reason: length (APIServer pid=1) INFO 10-08 11:11:34 [loggers.py:273] Engine 000: Avg prompt throughput: 1.3 tokens/s, Avg generation throughput: 0.1 tokens/s, Running: 0 reqs, Waiting: 0 reqs, GPU KV cache usage: 0.0%, Prefix cache hit rate: 0.0%, External prefix cache hit rate: 0.0% … 22
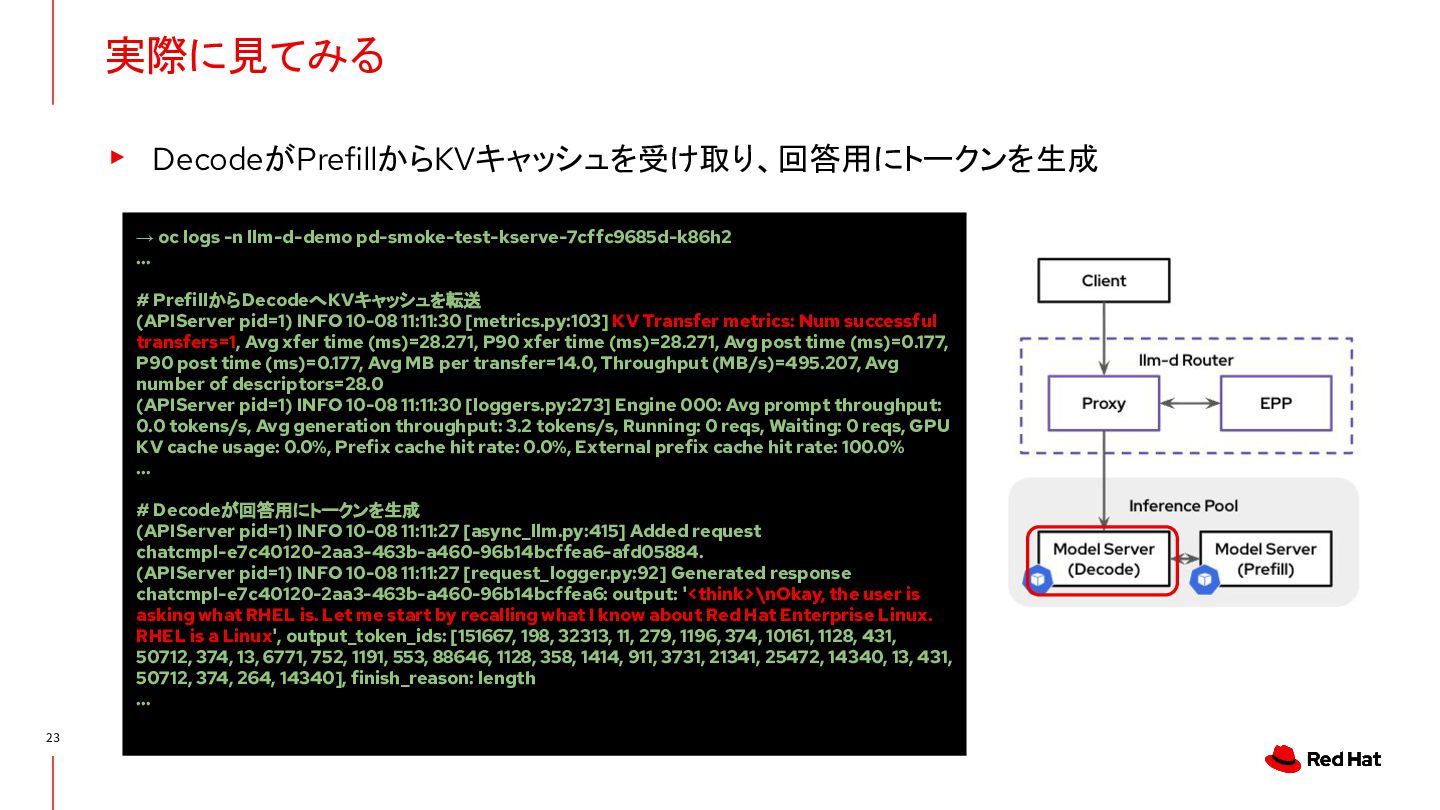
  16. 実際に見てみる ▸ DecodeがPrefillからKVキャッシュを受け取り、回答用にトークンを生成 → oc logs -n llm-d-demo pd-smoke-test-kserve-7cffc9685d-k86h2 …

    # PrefillからDecodeへKVキャッシュを転送 (APIServer pid=1) INFO 10-08 11:11:30 [metrics.py:103] KV Transfer metrics: Num successful transfers=1, Avg xfer time (ms)=28.271, P90 xfer time (ms)=28.271, Avg post time (ms)=0.177, P90 post time (ms)=0.177, Avg MB per transfer=14.0, Throughput (MB/s)=495.207, Avg number of descriptors=28.0 (APIServer pid=1) INFO 10-08 11:11:30 [loggers.py:273] Engine 000: Avg prompt throughput: 0.0 tokens/s, Avg generation throughput: 3.2 tokens/s, Running: 0 reqs, Waiting: 0 reqs, GPU KV cache usage: 0.0%, Prefix cache hit rate: 0.0%, External prefix cache hit rate: 100.0% … # Decodeが回答用にトークンを生成 (APIServer pid=1) INFO 10-08 11:11:27 [async_llm.py:415] Added request chatcmpl-e7c40120-2aa3-463b-a460-96b14bcffea6-afd05884. (APIServer pid=1) INFO 10-08 11:11:27 [request_logger.py:92] Generated response chatcmpl-e7c40120-2aa3-463b-a460-96b14bcffea6: output: '<think>\nOkay, the user is asking what RHEL is. Let me start by recalling what I know about Red Hat Enterprise Linux. RHEL is a Linux', output_token_ids: [151667, 198, 32313, 11, 279, 1196, 374, 10161, 1128, 431, 50712, 374, 13, 6771, 752, 1191, 553, 88646, 1128, 358, 1414, 911, 3731, 21341, 25472, 14340, 13, 431, 50712, 374, 264, 14340], finish_reason: length … 23
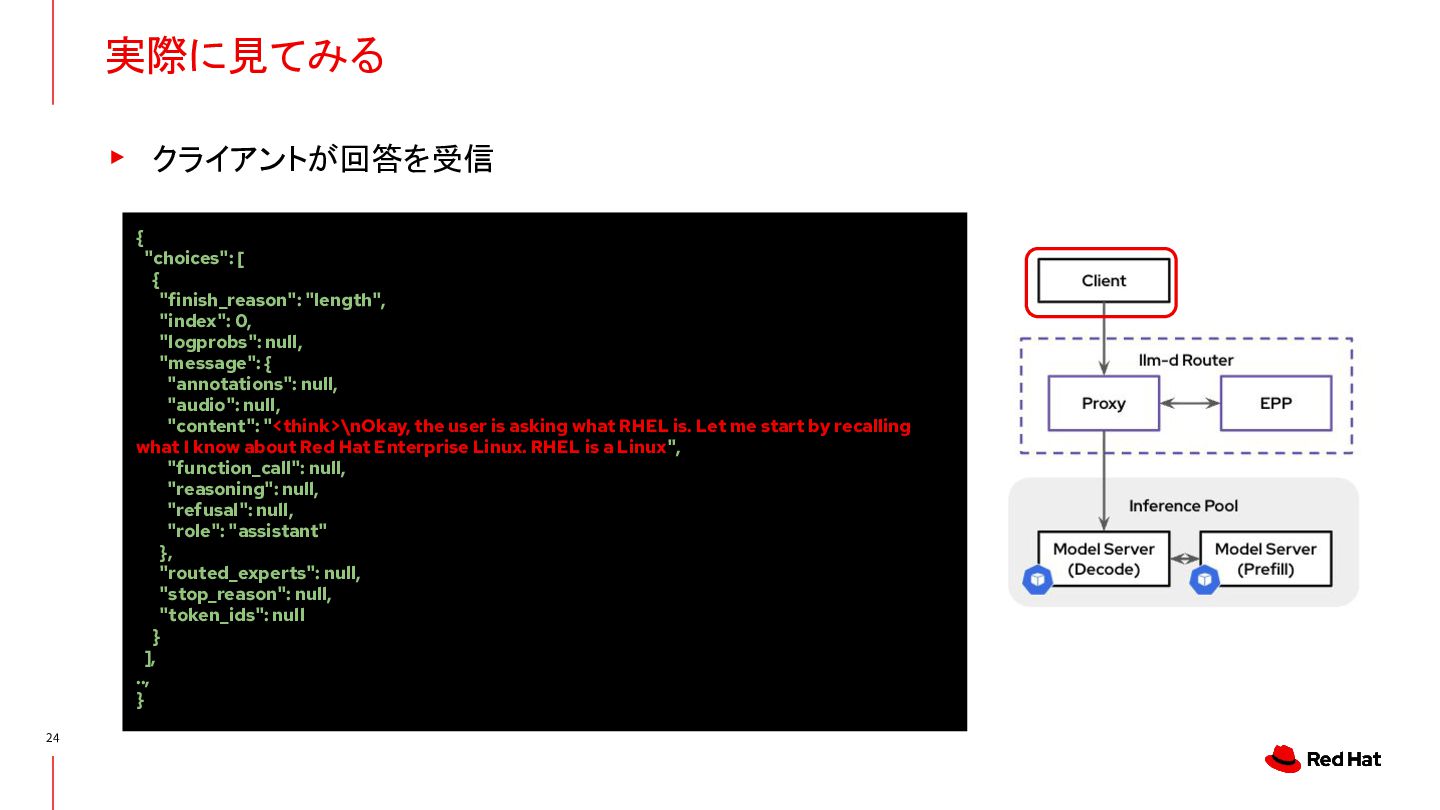
  17. 実際に見てみる ▸ クライアントが回答を受信 { "choices": [ { "finish_reason": "length", "index":

    0, "logprobs": null, "message": { "annotations": null, "audio": null, "content": "<think>\nOkay, the user is asking what RHEL is. Let me start by recalling what I know about Red Hat Enterprise Linux. RHEL is a Linux", "function_call": null, "reasoning": null, "refusal": null, "role": "assistant" }, "routed_experts": null, "stop_reason": null, "token_ids": null } ], .., } 24
  18. まとめ ▸ P/D分離は、処理特性に応じて、リソースを分離し、処理性能を最適化します。 ▸ llm-dにおけるP/D分離では、LLMInferenceServiceから管理できます。 ▸ llm-dにおけるP/D分離のリクエストフロー: ・ Prefill: Client

    -> llm-d Router -> Decode Pod -> Prefill Pod の順でリクエストが渡 り、KVキャッシュが生成される。 ・ Decode: Prefill Podから転送されたKVキャッシュを受け取り、Decode Podが回答を 生成してClientへ返す。 27
  19. Thank you linkedin.com/company/red-hat youtube.com/user/RedHatVideos Red Hat is the world’s leading

    provider of enterprise open source software solutions. facebook.com/redhatinc Award-winning support, training, and consulting services make Red Hat a trusted adviser to the Fortune 500. 30 twitter.com/RedHat