Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Training Deep Learning Models on Multiple GPUs ...

Sponsored · Your Podcast. Everywhere. Effortlessly. Share. Educate. Inspire. Entertain. You do you. We'll handle the rest. →

Training Deep Learning Models on Multiple GPUs in the Cloud by Enrique Otero at Big Data Spain 2017

GPUs on the cloud as Infrastructure as a Service (IaaS) seem a commodity. However to efficiently distribute deep learning tasks on several GPUs is challenging.

https://www.bigdataspain.org/2017/talk/training-deep-learning-models-on-multiple-gpus-in-the-cloud

Big Data Spain 2017
November 16th - 17th Kinépolis Madrid

Avatar for Big Data Spain

Big Data Spain

December 04, 2017

More Decks by Big Data Spain

Other Decks in Technology

Transcript

  1. DEEP LEARNING & MULTI GPUs Training Deep Learning Models on

    Multiple GPUs in the Cloud BEE PART OF THE CHANGE Avenida de Burgos, 16 D, 28036 Madrid [email protected] www.beeva.com
  2. ENRIQUE OTERO [email protected] @beevalabs_eom Data Scientist in BEEVA [email protected] |

    www.beeva.com The intro: deep learning & GPUs The training: challenges & benchmarks on image classification The lessons: science, engineering, infrastructure & business
  3. WWW.BEEVA.COM 3 BIG DATA CLOUD COMPUTI NG MACHINE INTELLIGE NCE

    • INNOVATION LABS • INNOVATION SERVICES 100 % +40 % Annual growth rate in last 4 years +65 0 Employees in Spain +80 0 Employees globally WE MAKE COMPLEX THINGS SIMPLE
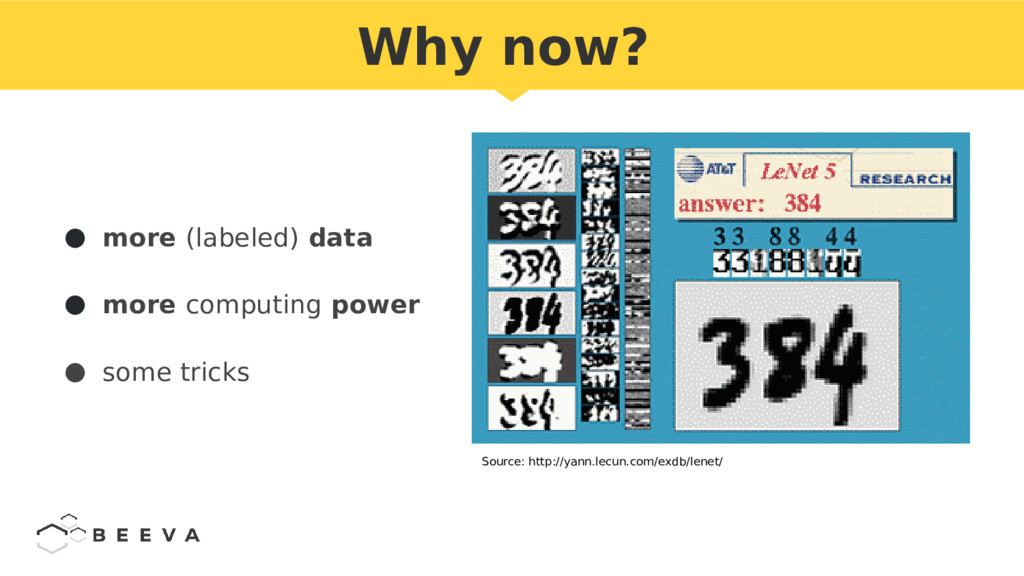
  4. • more (labeled) data • more computing power • some

    tricks Why now? Source: http://yann.lecun.com/exdb/lenet/
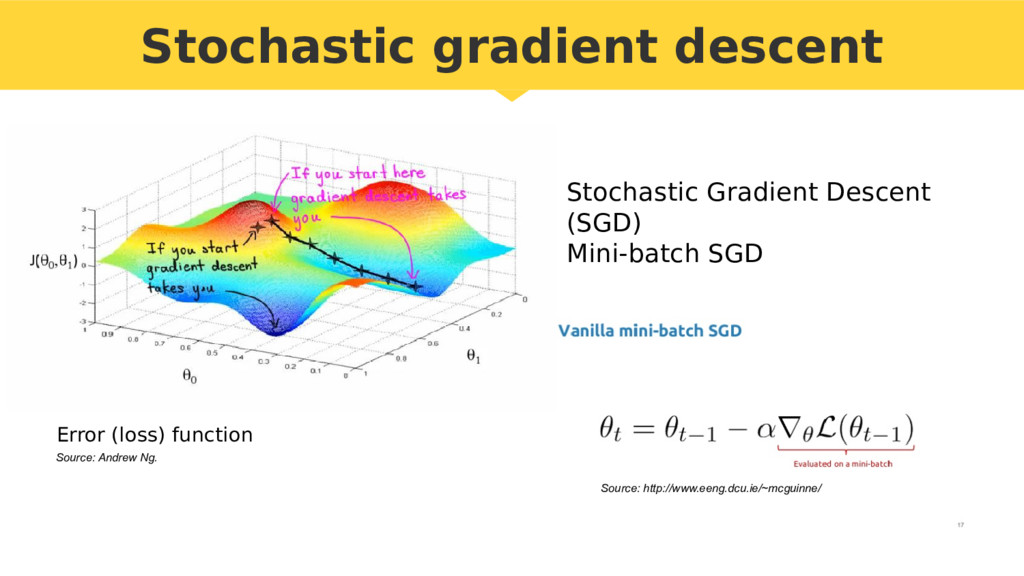
  5. • Stochastic Gradient Descent (SGD) • Mini-batch SGD Source: Andrew

    Ng. Source: http://www.eeng.dcu.ie/~mcguinne/ Error (loss) function Stochastic gradient descent
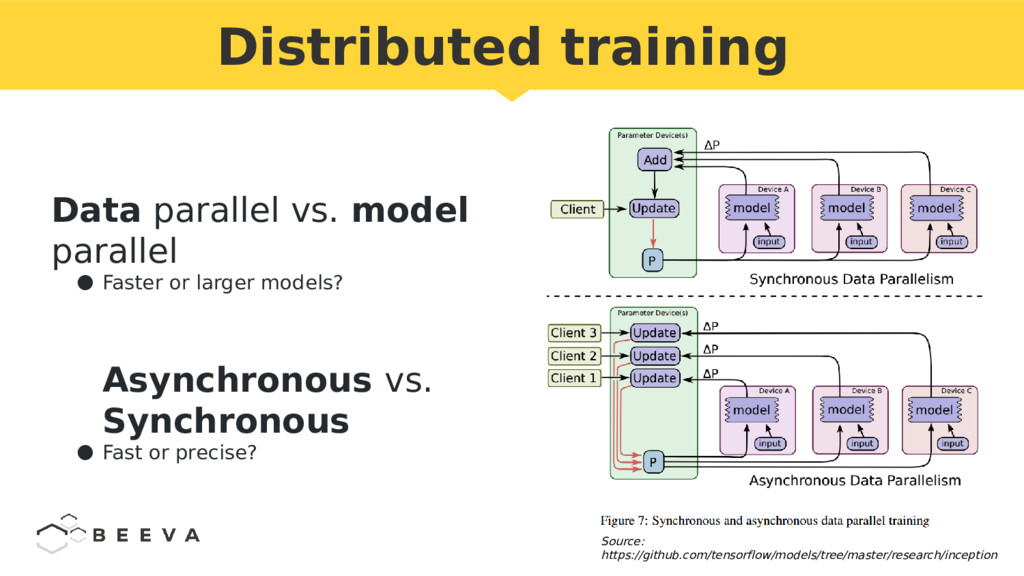
  6. Data parallel vs. model parallel • Faster or larger models?

    Asynchronous vs. Synchronous • Fast or precise? Distributed training Source: https://github.com/tensorflow/models/tree/master/research/inception
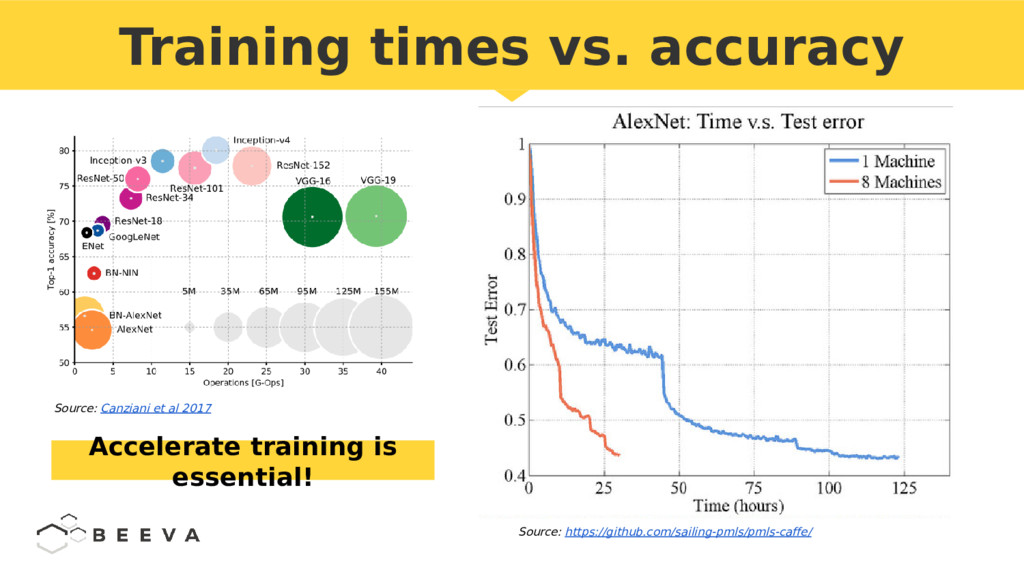
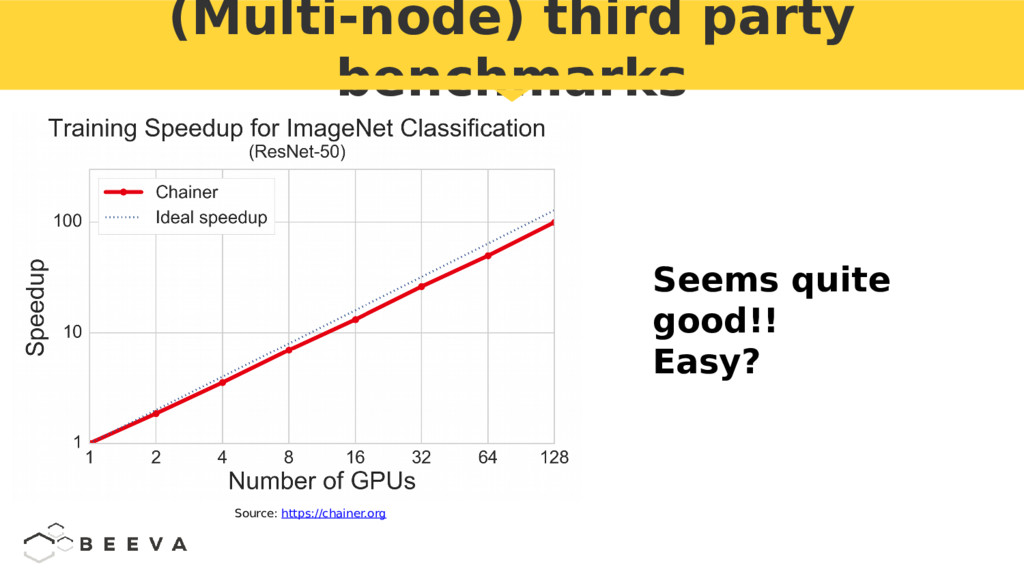
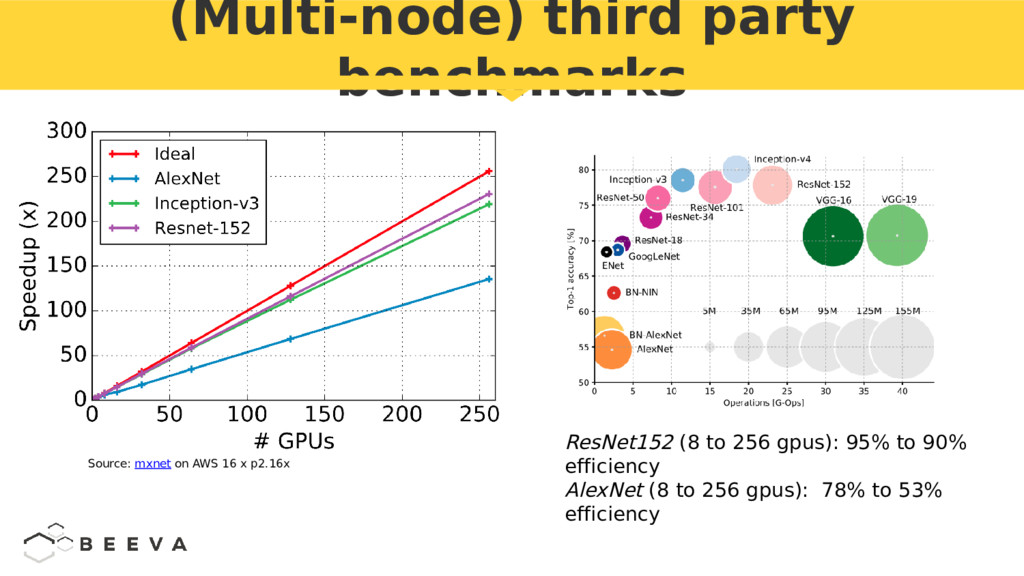
  7. (Multi-node) third party benchmarks ResNet152 (8 to 256 gpus): 95%

    to 90% efficiency AlexNet (8 to 256 gpus): 78% to 53% efficiency Source: mxnet on AWS 16 x p2.16x
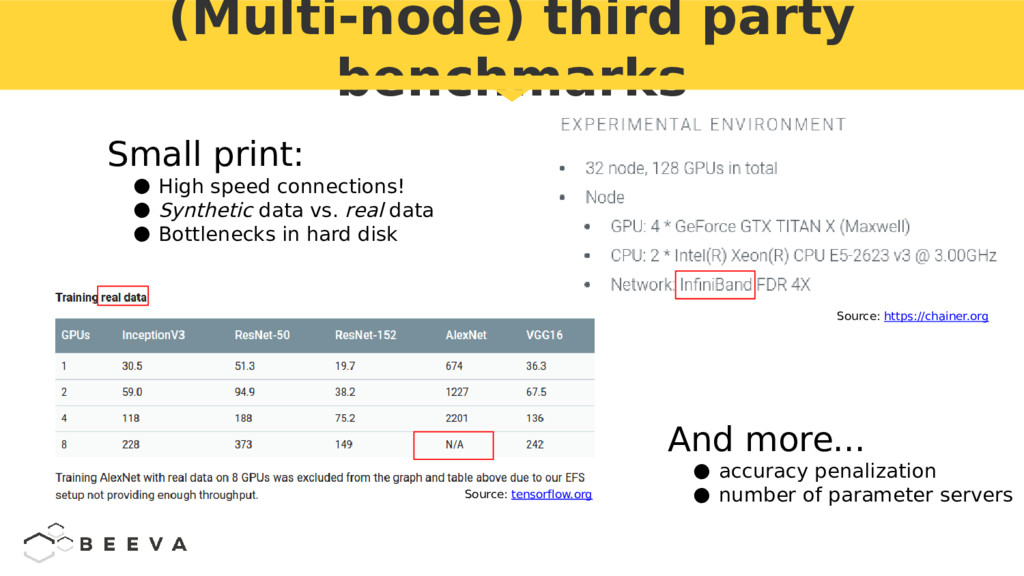
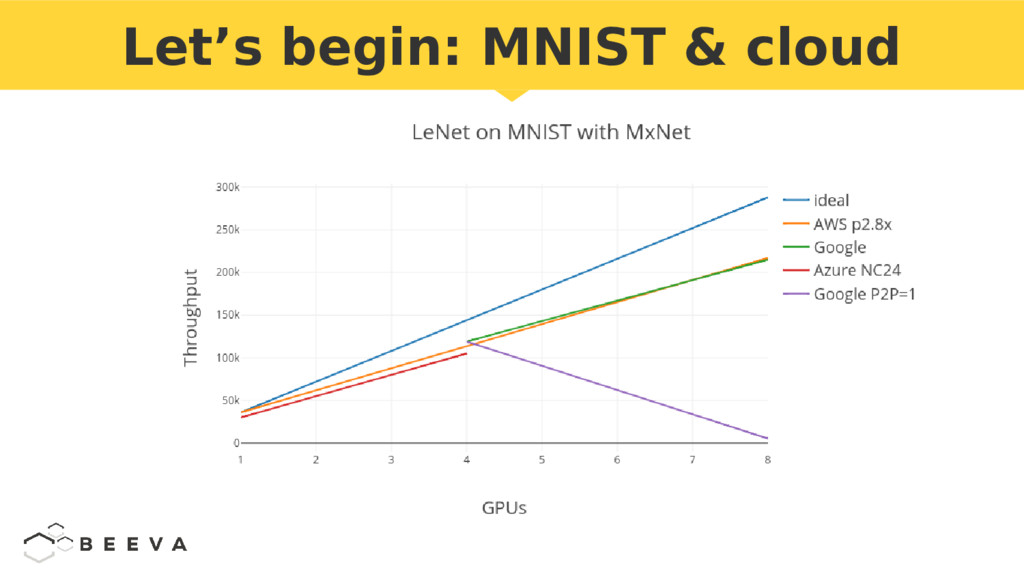
  8. (Multi-node) third party benchmarks Small print: • High speed connections!

    • Synthetic data vs. real data • Bottlenecks in hard disk And more... • accuracy penalization • number of parameter servers Source: tensorflow.org Source: https://chainer.org
  9. Let’s begin: Tesla K80 K80 GPUs on: • AWS p2:

    1, 8 & 16 ◦ ready-to-go AMIs • Azure NC: 1, 2 & 4 • Google Cloud Platform: 1 to 8 ◦ setup scripts
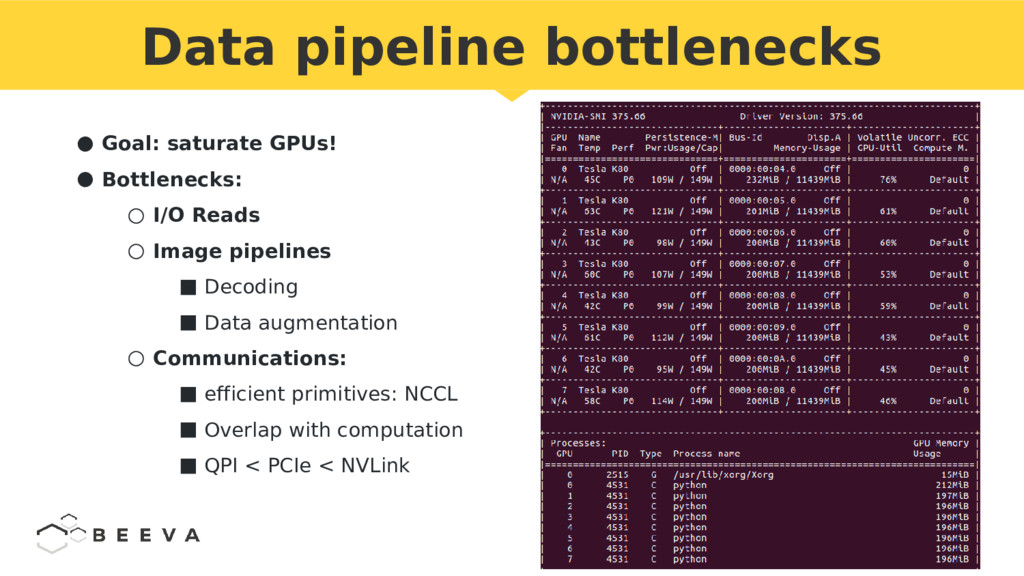
  10. • Goal: saturate GPUs! • Bottlenecks: ◦ I/O Reads ◦

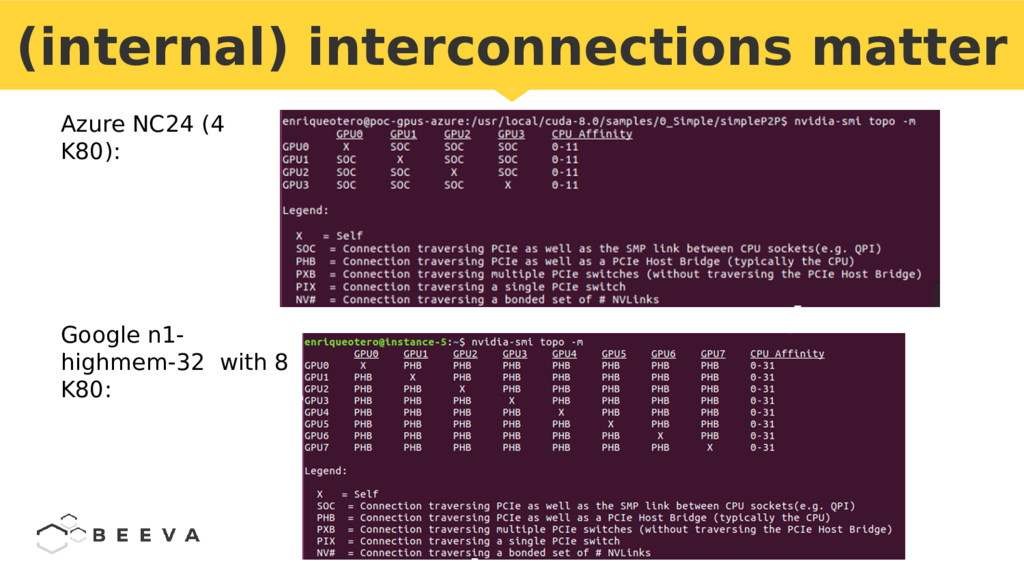
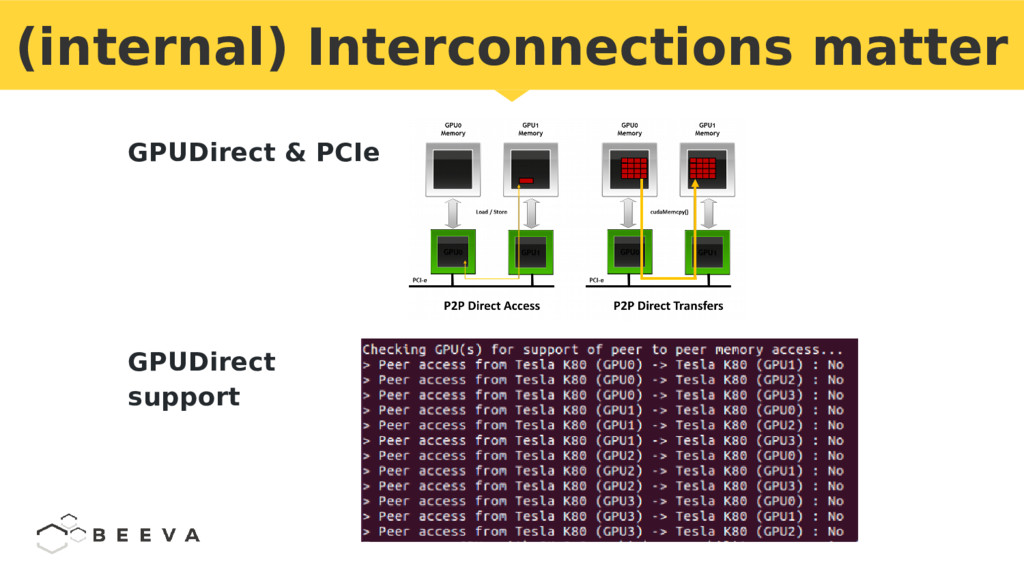
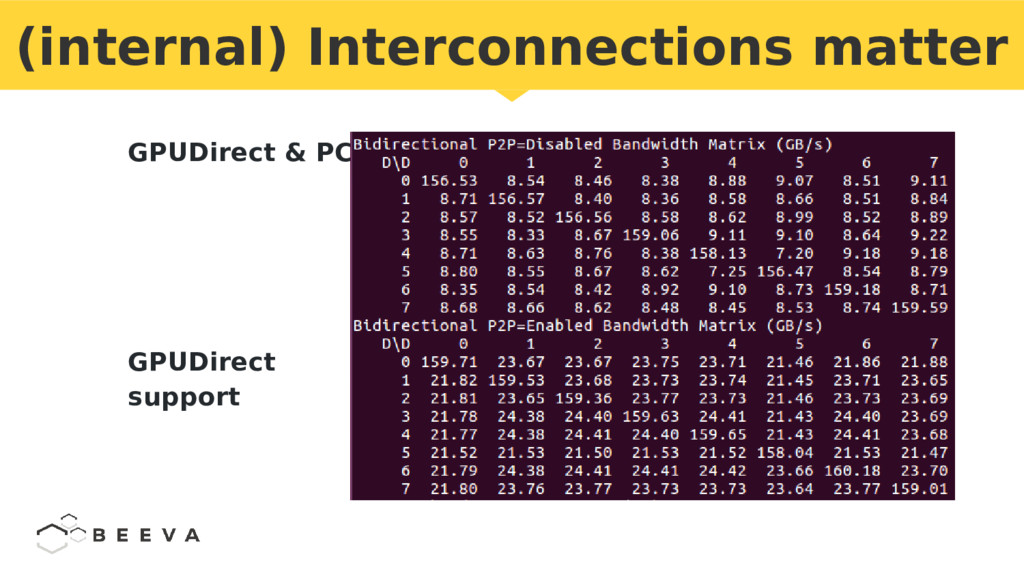
    Image pipelines ▪ Decoding ▪ Data augmentation ◦ Communications: ▪ efficient primitives: NCCL ▪ Overlap with computation ▪ QPI < PCIe < NVLink Data pipeline bottlenecks
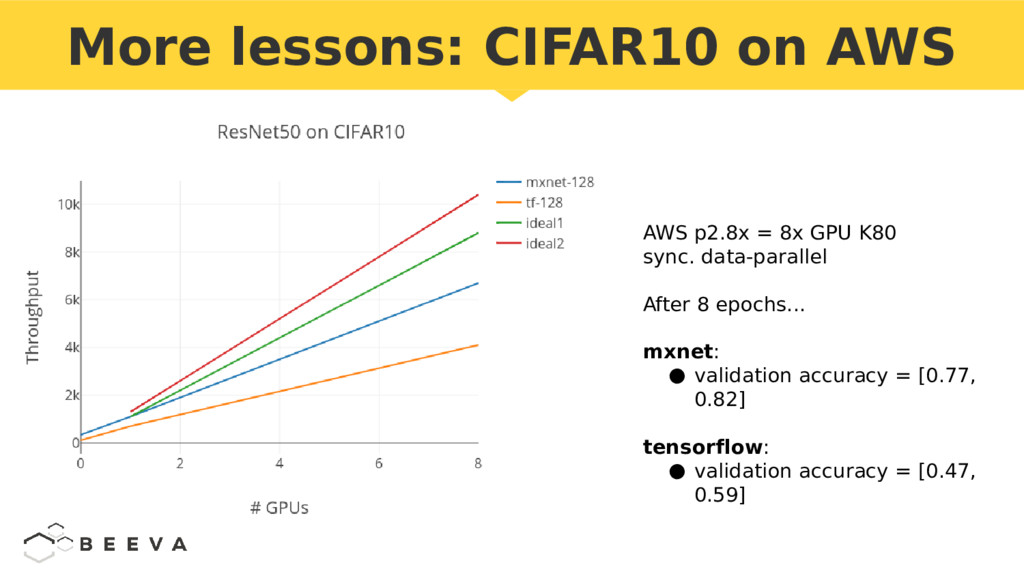
  11. More lessons: CIFAR10 on AWS AWS p2.8x = 8x GPU

    K80 sync. data-parallel After 8 epochs... mxnet: • validation accuracy = [0.77, 0.82] tensorflow: • validation accuracy = [0.47, 0.59]
  12. Batch sizes matter • Larger batches reduce communication overhead ◦

    More throughput • But degrade convergence. ◦ Less accuracy!
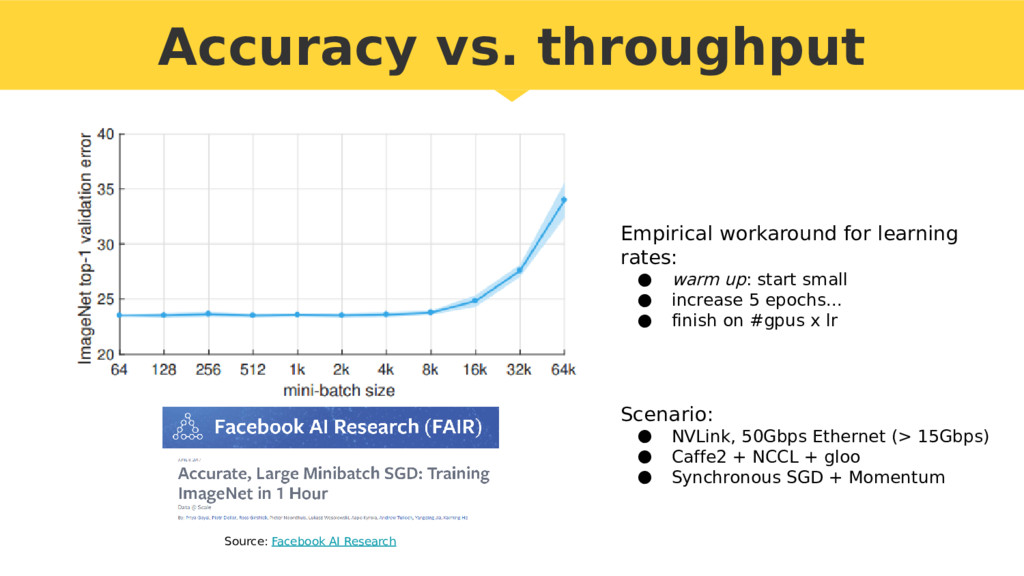
  13. Accuracy vs. throughput Empirical workaround for learning rates: • warm

    up: start small • increase 5 epochs... • finish on #gpus x lr Scenario: • NVLink, 50Gbps Ethernet (> 15Gbps) • Caffe2 + NCCL + gloo • Synchronous SGD + Momentum Source: Facebook AI Research
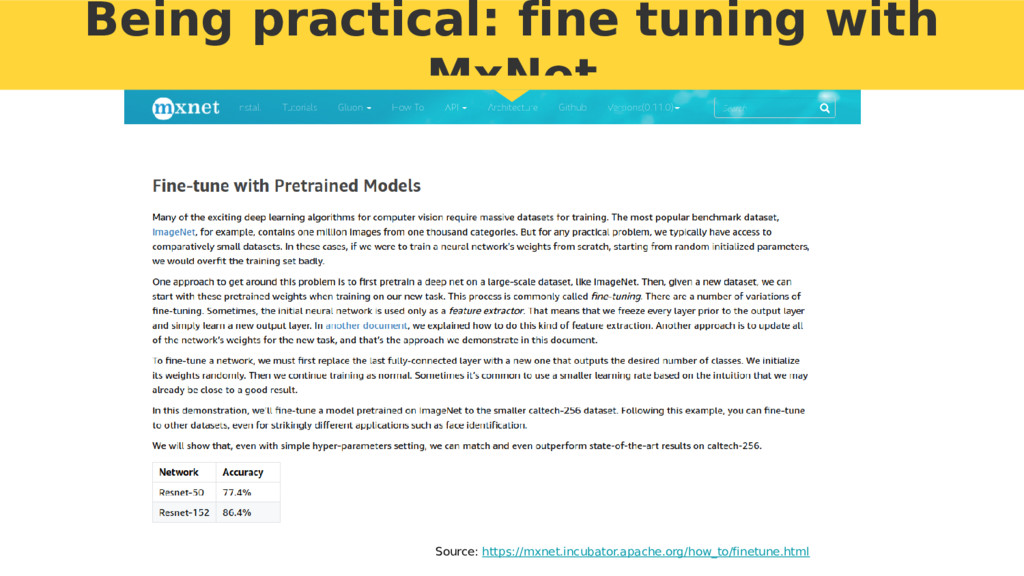
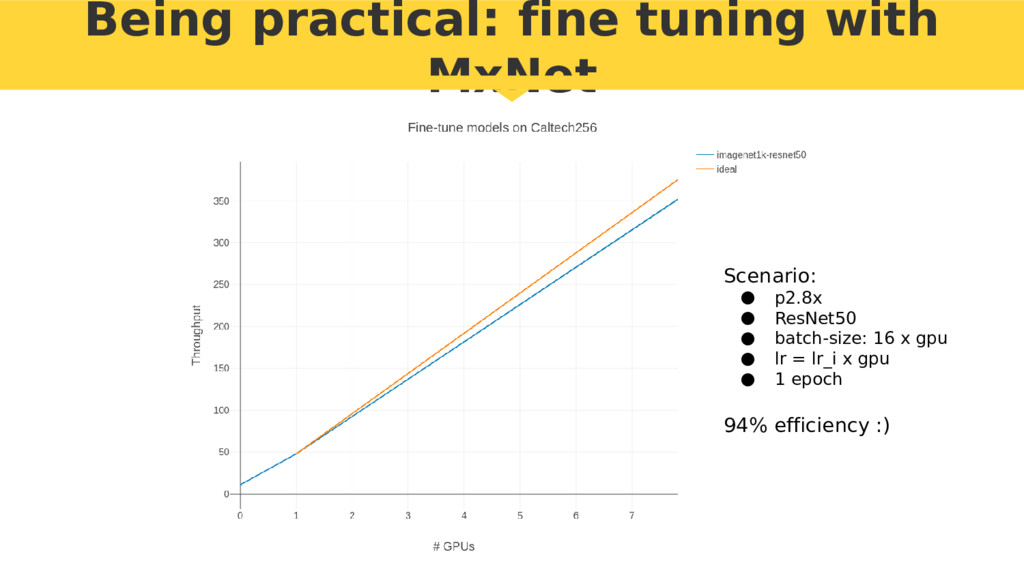
  14. Being practical: fine tuning with MxNet Scenario: • p2.8x •

    ResNet50 • batch-size: 16 x gpu • lr = lr_i x gpu • 1 epoch 94% efficiency :)
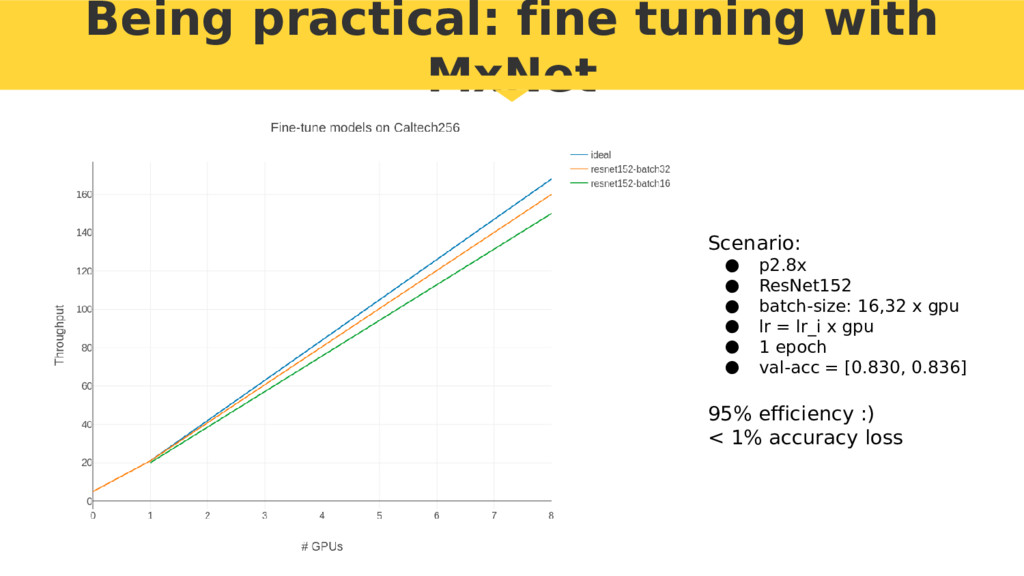
  15. Being practical: fine tuning with MxNet Scenario: • p2.8x •

    ResNet152 • batch-size: 16,32 x gpu • lr = lr_i x gpu • 1 epoch • val-acc = [0.830, 0.836] 95% efficiency :) < 1% accuracy loss
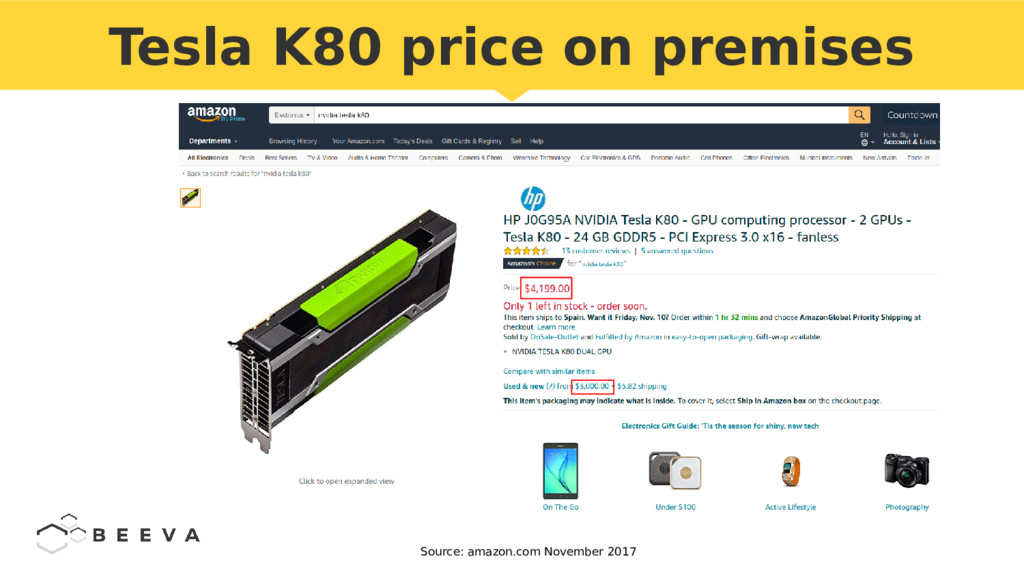
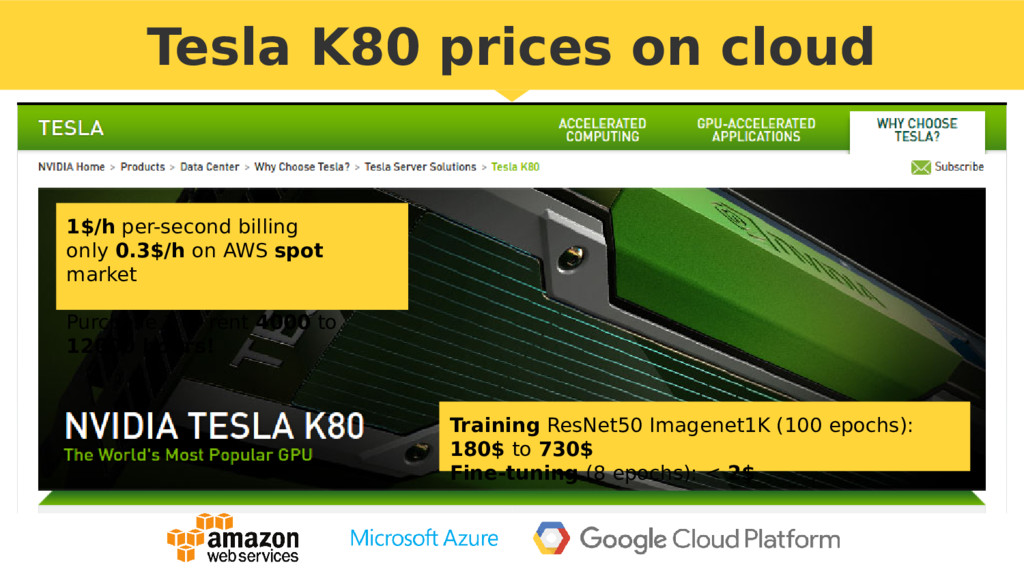
  16. Tesla K80 prices on cloud 1$/h per-second billing only 0.3$/h

    on AWS spot market Purchase 1 or rent 4000 to 12000 hours! Training ResNet50 Imagenet1K (100 epochs): 180$ to 730$ Fine-tuning (8 epochs): < 2$
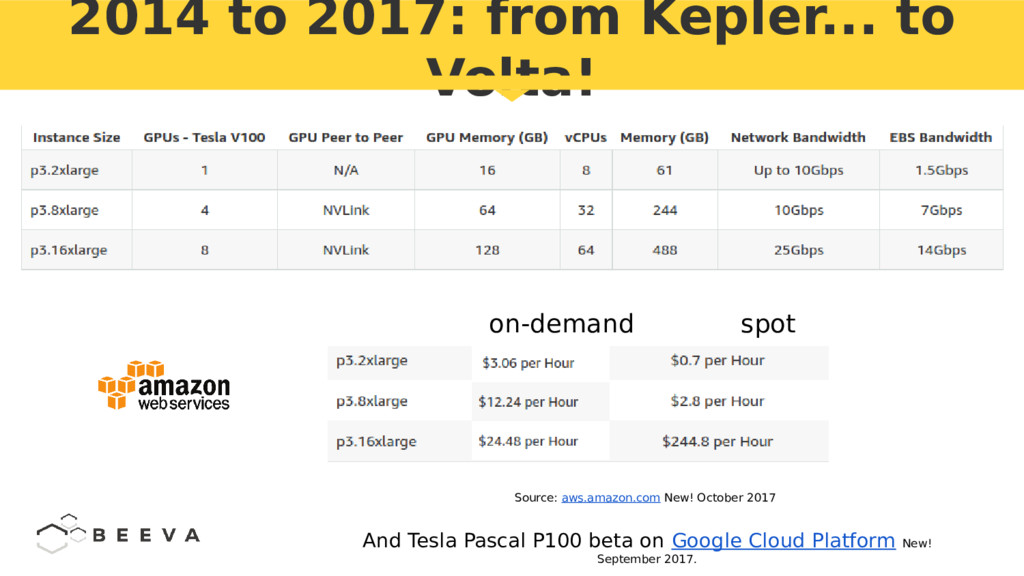
  17. 2014 to 2017: from Kepler... to Volta! Source: aws.amazon.com New!

    October 2017 And Tesla Pascal P100 beta on Google Cloud Platform New! September 2017. on-demand spot
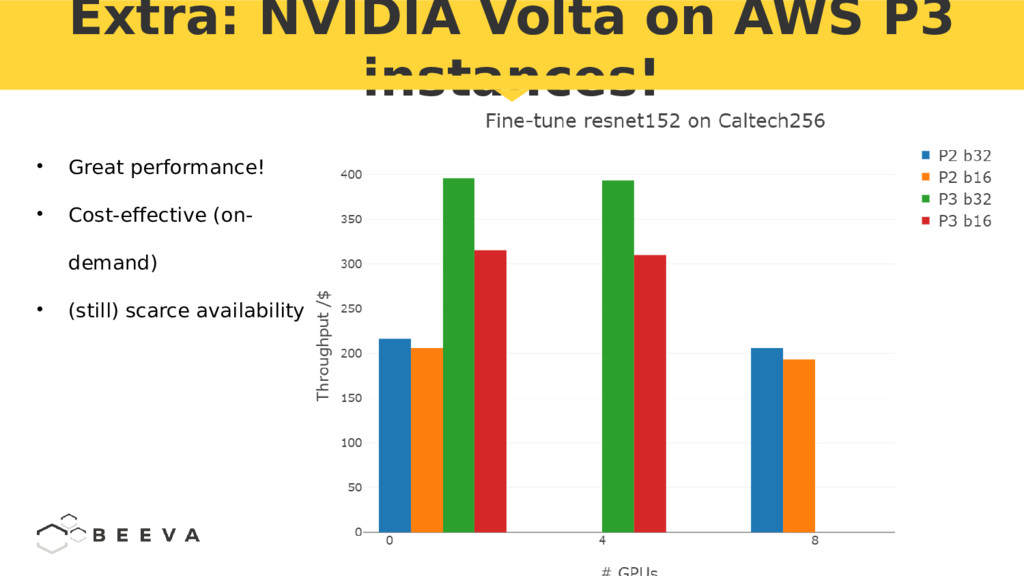
  18. Extra: NVIDIA Volta on AWS P3 instances! • Great performance!

    • Cost-effective (on- demand) • (still) scarce availability
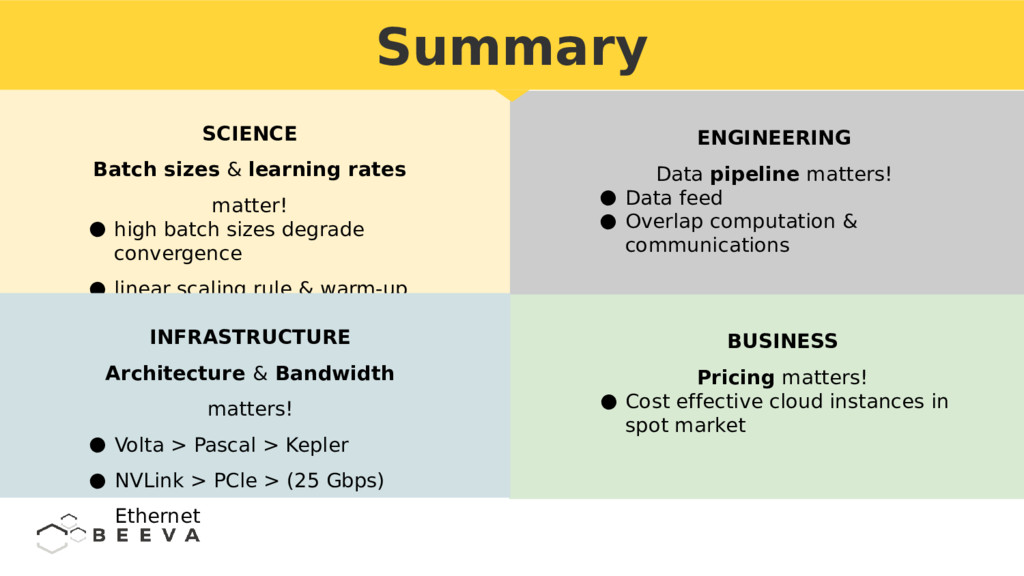
  19. Summary SCIENCE Batch sizes & learning rates matter! • high

    batch sizes degrade convergence • linear scaling rule & warm-up ENGINEERING Data pipeline matters! • Data feed • Overlap computation & communications INFRASTRUCTURE Architecture & Bandwidth matters! • Volta > Pascal > Kepler • NVLink > PCle > (25 Gbps) Ethernet BUSINESS Pricing matters! • Cost effective cloud instances in spot market