Share
Embed
Big Data Analytics with Couchbase, Hadoop, Kafka, Spark and More
By Matt Ingenthron, Sr. Director SDK Engineering and Developer Advocacy, Couchbase
Datageeks Paris
March 25, 2015
Transcript
41 slides
-
Big Data Analytics with Couchbase, Hadoop, Kafka, Spark and More
Matt Ingenthron, Sr. Director SDK Engineering and Developer Advocacy -
About Me Matt Ingenthron Worked on large site scalability problems
at previous company… memcached contributor Joined Couchbase very early and helped define key parts of system @ingenthr 2 -
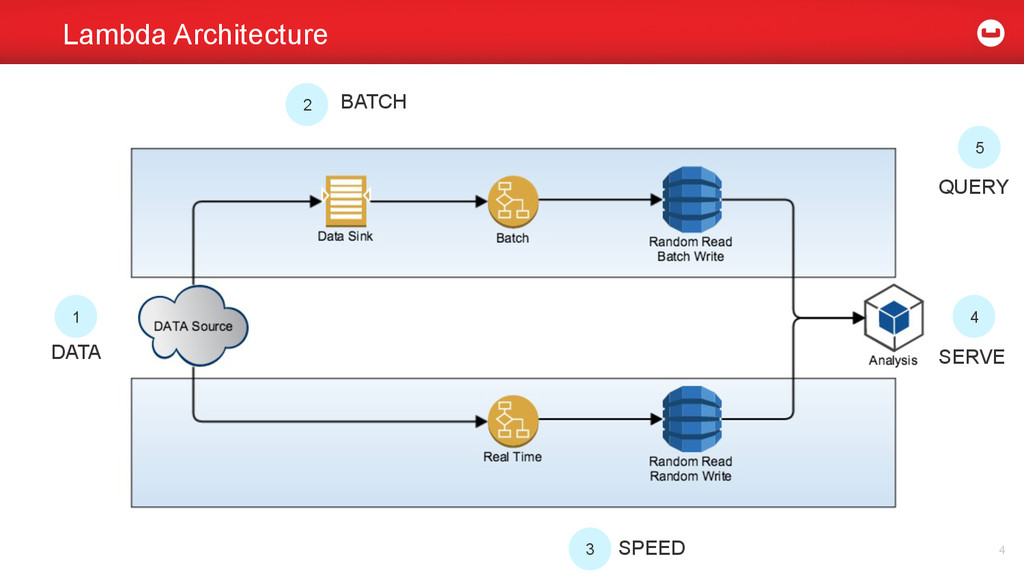
Lambda Architecture 4 1 2 3 4 5 DATA BATCH
SPEED SERVE QUERY -
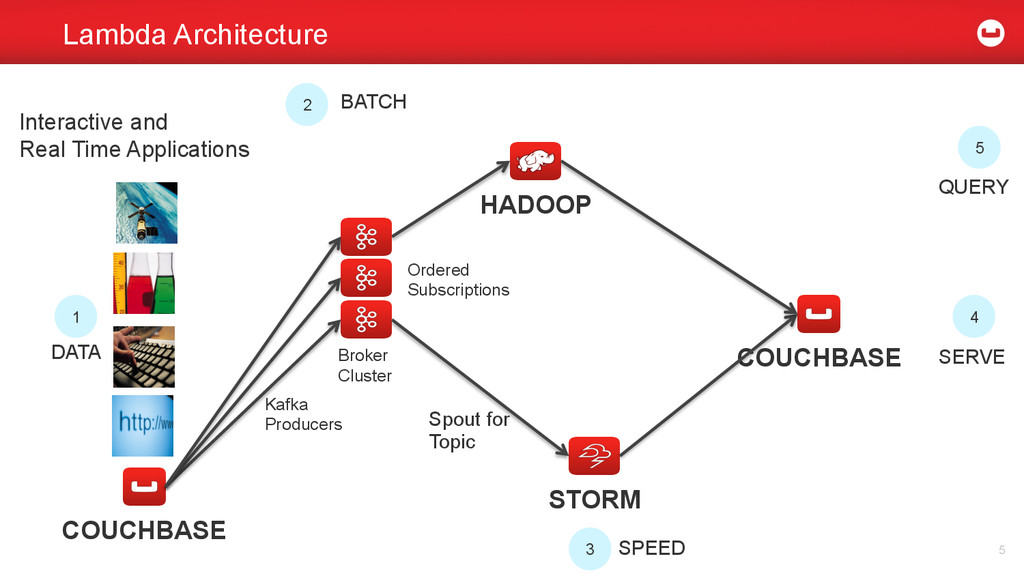
Lambda Architecture 5 Interactive and Real Time Applications 1 2
3 4 5 DATA BATCH SPEED SERVE QUERY HADOOP COUCHBASE STORM COUCHBASE Broker Cluster Spout for Topic Kafka Producers Ordered Subscriptions -
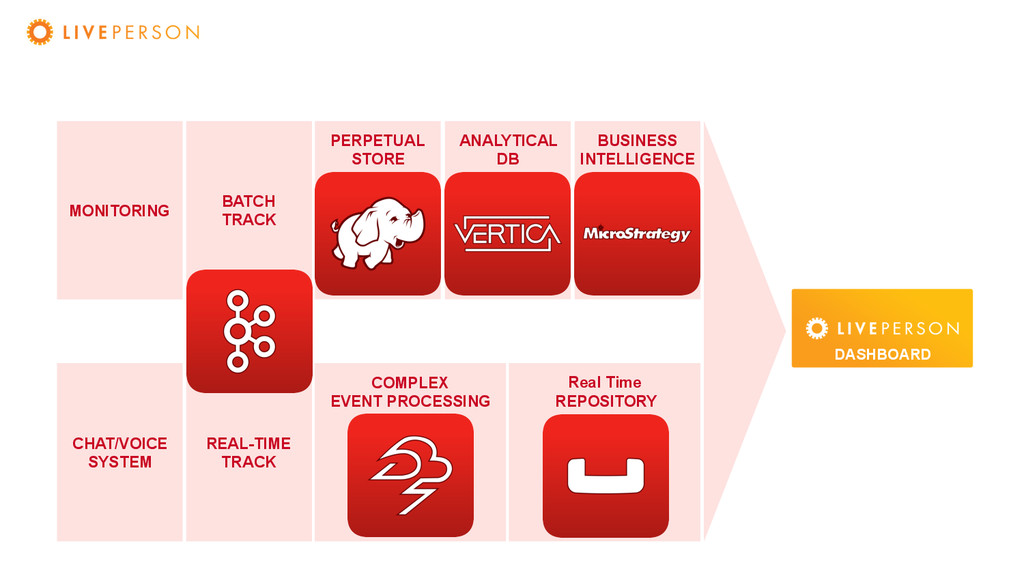
COMPLEX EVENT PROCESSING Real Time REPOSITORY PERPETUAL STORE ANALYTICAL DB
BUSINESS INTELLIGENCE MONITORING CHAT/VOICE SYSTEM BATCH TRACK REAL-TIME TRACK DASHBOARD -
9 Requirements for data streaming in modern systems… • Must
support high throughput and low latency • Need to handle failures • Pick up where you left off • Be efficient about resource usage -
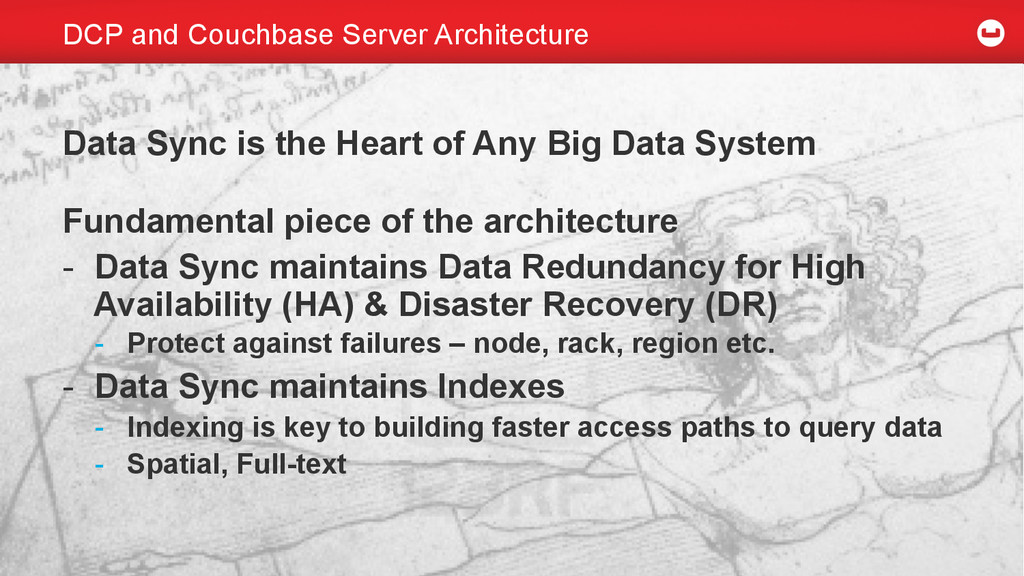
Data Sync is the Heart of Any Big Data System
Fundamental piece of the architecture - Data Sync maintains Data Redundancy for High Availability (HA) & Disaster Recovery (DR) - Protect against failures – node, rack, region etc. - Data Sync maintains Indexes - Indexing is key to building faster access paths to query data - Spatial, Full-text DCP and Couchbase Server Architecture -
What is DCP? DCP is an innovative protocol that drive
data sync for Couchbase Server • Increase data sync efficiency with massive data footprints • Remove slower Disk-IO from the data sync path • Improve latencies – replication for data durability • In future, will provide a programmable data sync protocol for external stores outside Couchbase Server DCP powers many critical components What is DCP? 11 -
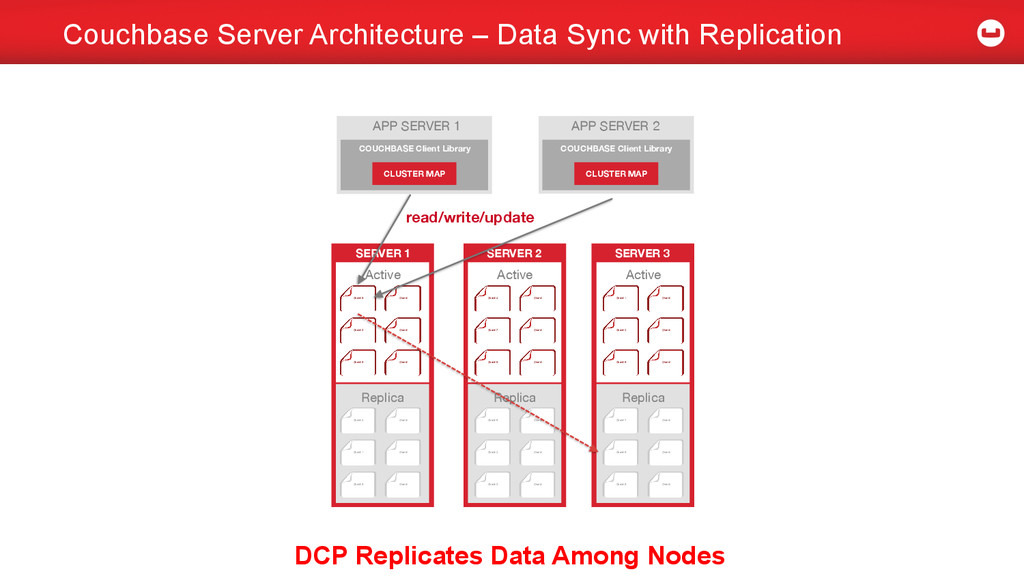
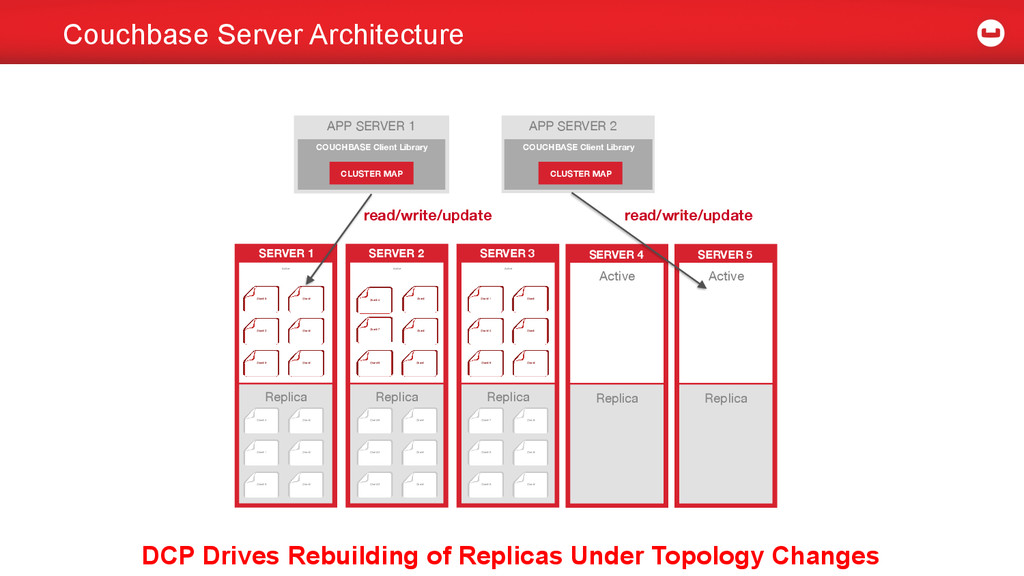
read/write/update Active SERVER 1 Active SERVER 2 Active SERVER 3
APP SERVER 1 COUCHBASE Client Library CLUSTER MAP COUCHBASE Client Library CLUSTER MAP APP SERVER 2 Shard 5 Shard 2 Shard 9 Shard Shard Shard Shard 4 Shard 7 Shard 8 Shard Shard Shard Shard 1 Shard 3 Shard 6 Shard Shard Shard Replica Replica Replica Shard 4 Shard 1 Shard 8 Shard Shard Shard Shard 6 Shard 3 Shard 2 Shard Shard Shard Shard 7 Shard 9 Shard 5 Shard Shard Shard Couchbase Server Architecture – Data Sync with Replication DCP Replicates Data Among Nodes -
SERVER 4 SERVER 5 Replica Active Replica Active read/write/update APP
SERVER 1 COUCHBASE Client Library CLUSTER MAP COUCHBASE Client Library CLUSTER MAP APP SERVER 2 Active SERVER 1 Shard 9 Shard Replica Shard 4 Shard 1 Shard 8 Shard Shard Shard Active SERVER 2 Shard 8 Shard Replica Shard 6 Shard 3 Shard 2 Shard Shard Shard Active SERVER 3 Shard 6 Shard Replica Shard 7 Shard 9 Shard 5 Shard Shard Shard read/write/update Shard 5 Shard 2 Shard Shard Shard 4 Shard 7 Shard Shard Shard 1 Shard 3 Shard Shard Couchbase Server Architecture DCP Drives Rebuilding of Replicas Under Topology Changes -
Ordering To build interesting features a streaming protocol needs to
have a concept of when operations happened. Couchbase operation ordering at the node level: § Each mutation is assigned a sequence number § Sequence numbers increase monotonically § Sequence numbers are assigned on a per VBucket basis Restart-ability Need to handle failures with grace, in particular being efficient about the amount of data being moved around. Consistency points Points in time for incremental backup, query consistency. Performance Recognize that durability on a distributed system may have different definitions. Design Goals 15 -
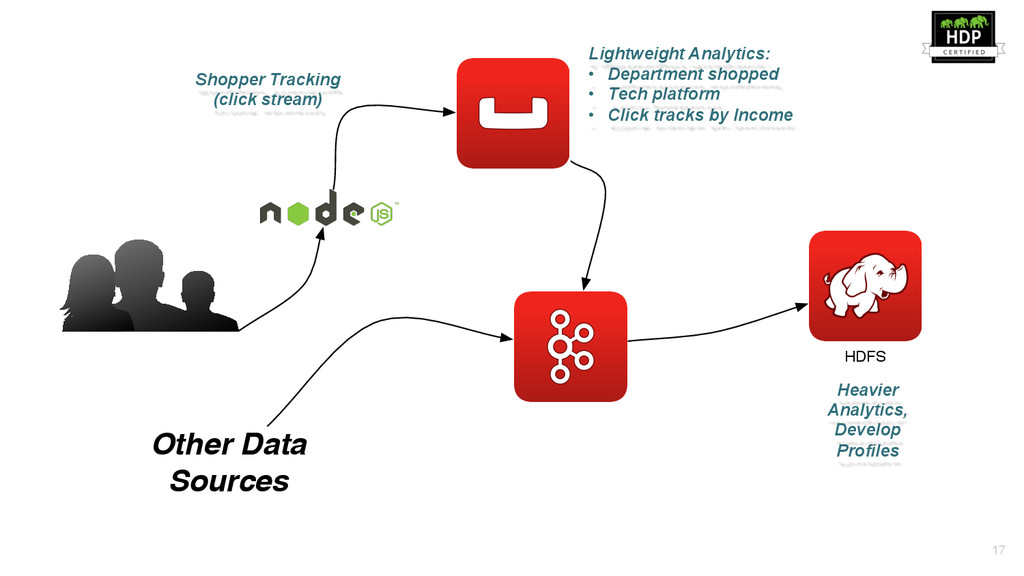
17 Other Data Sources HDFS Shopper Tracking (click stream) Lightweight
Analytics: • Department shopped • Tech platform • Click tracks by Income Heavier Analytics, Develop Profiles -
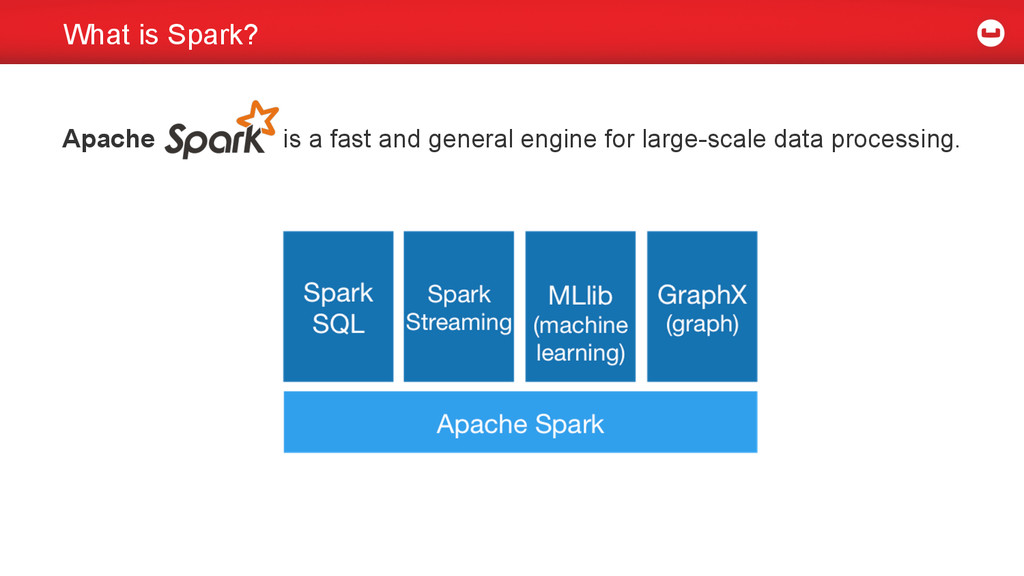
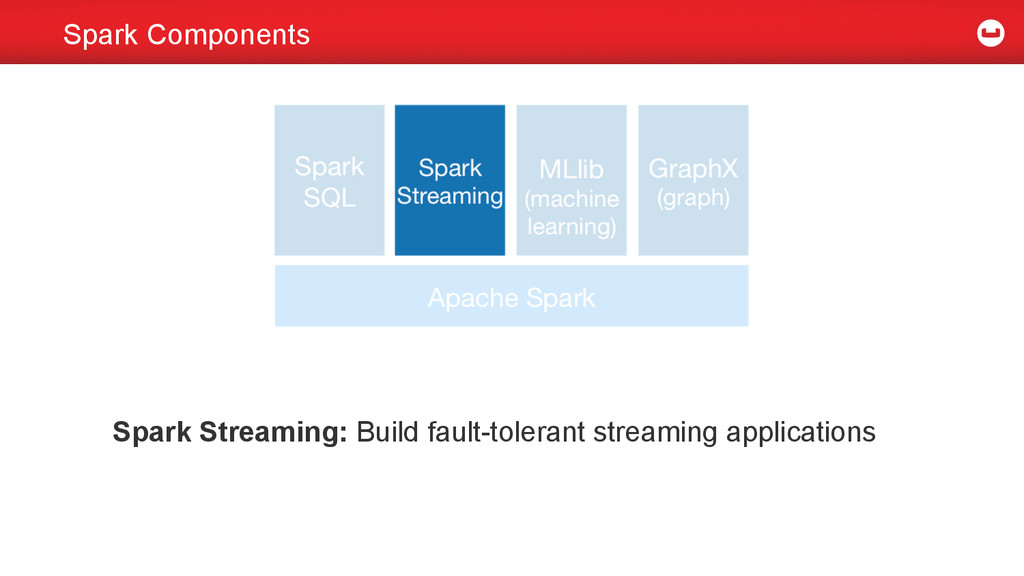
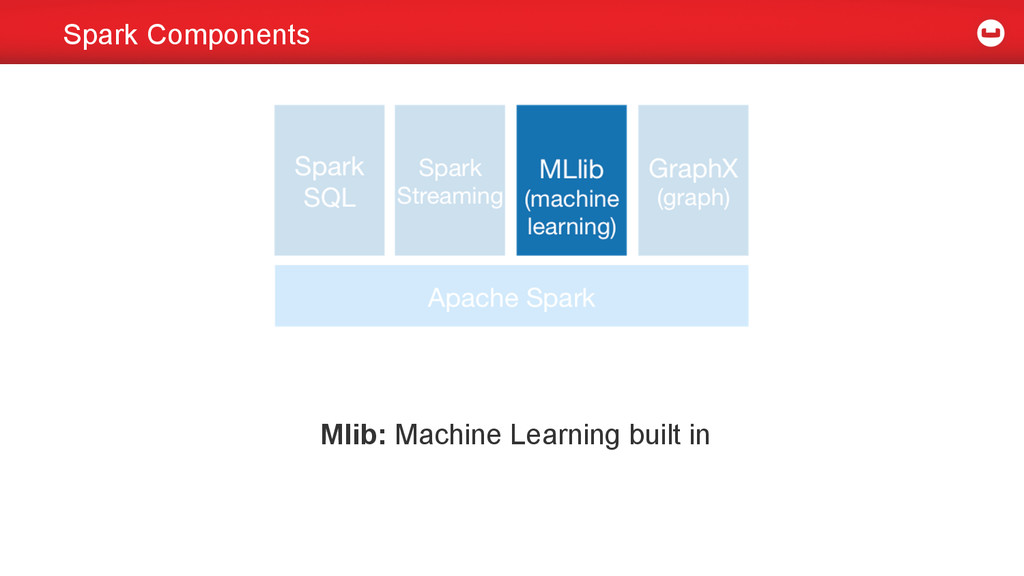
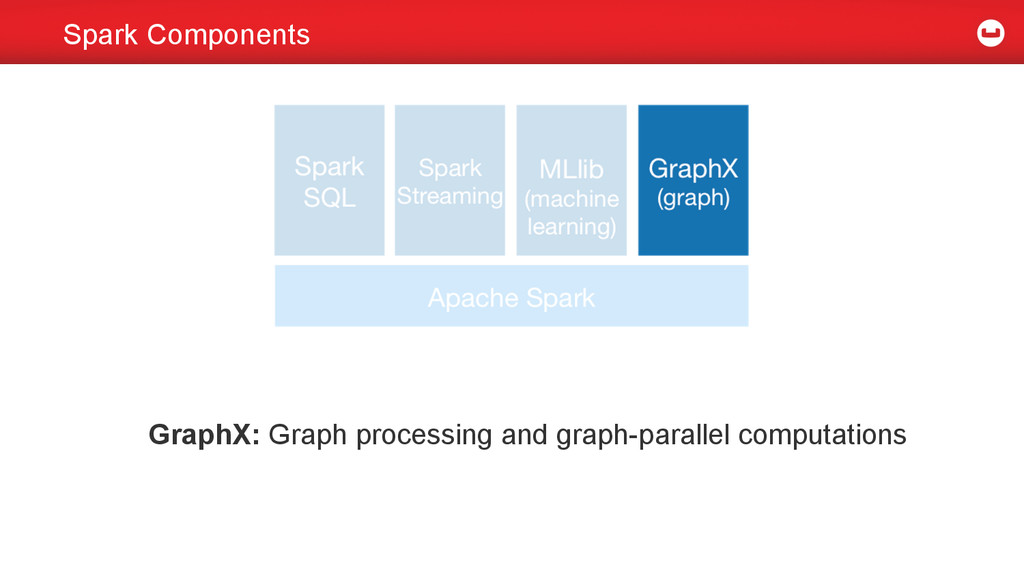
What is Spark? Apache is a fast and general engine
for large-scale data processing. -
Spark Benefits • Linear Scalability • Ease of Use •
Fault Tolerance • For developers and data scientists • Tight but not mandatory Hadoop integration -
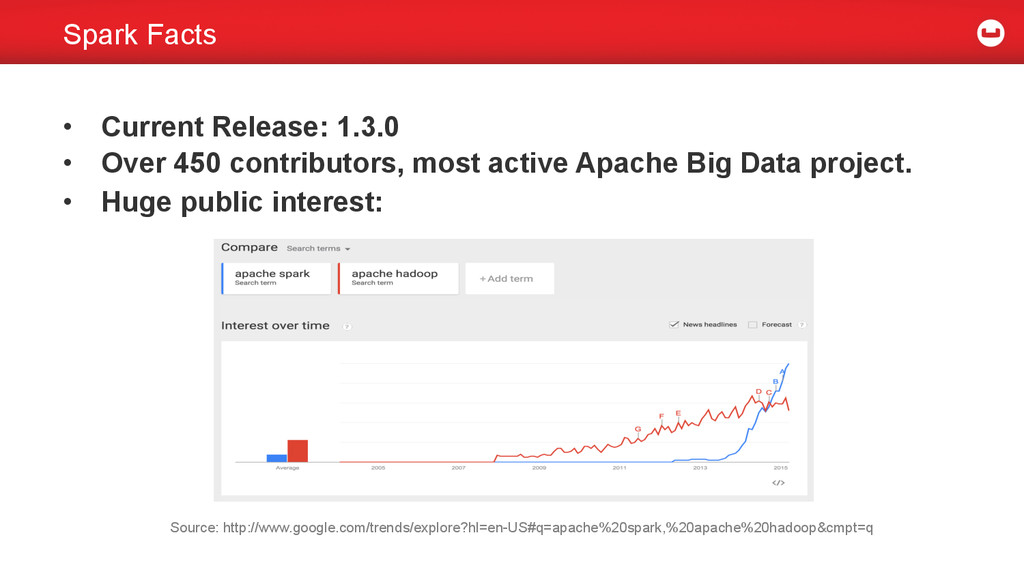
Spark Facts • Current Release: 1.3.0 • Over 450 contributors,
most active Apache Big Data project. • Huge public interest: Source: http://www.google.com/trends/explore?hl=en-US#q=apache%20spark,%20apache%20hadoop&cmpt=q -
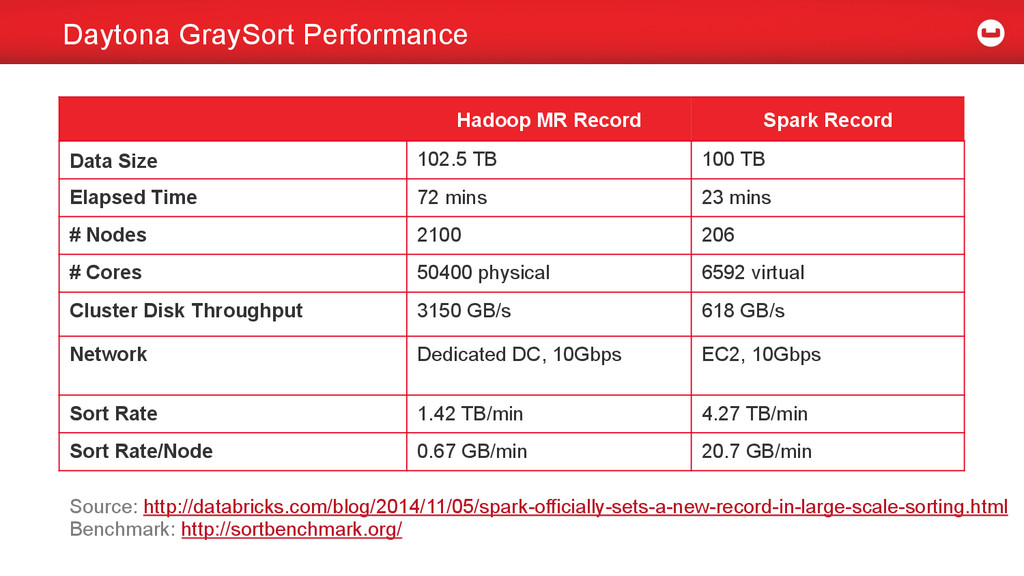
Daytona GraySort Performance Hadoop MR Record Spark Record Data Size
102.5 TB 100 TB Elapsed Time 72 mins 23 mins # Nodes 2100 206 # Cores 50400 physical 6592 virtual Cluster Disk Throughput 3150 GB/s 618 GB/s Network Dedicated DC, 10Gbps EC2, 10Gbps Sort Rate 1.42 TB/min 4.27 TB/min Sort Rate/Node 0.67 GB/min 20.7 GB/min Source: http://databricks.com/blog/2014/11/05/spark-officially-sets-a-new-record-in-large-scale-sorting.html Benchmark: http://sortbenchmark.org/ -
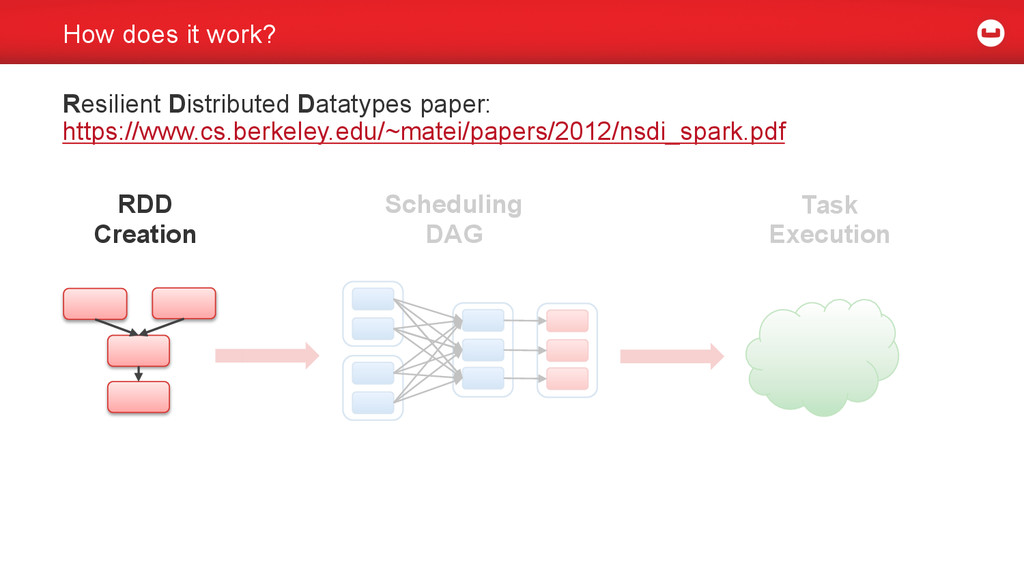
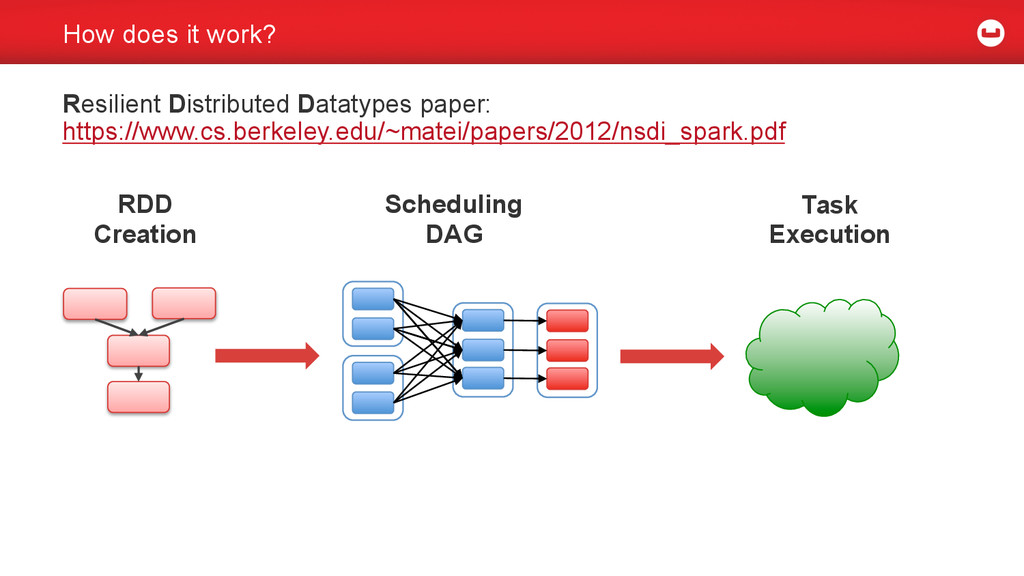
How does it work? Resilient Distributed Datatypes paper: https://www.cs.berkeley.edu/~matei/papers/2012/nsdi_spark.pdf RDD
Creation Scheduling DAG Task Execution -
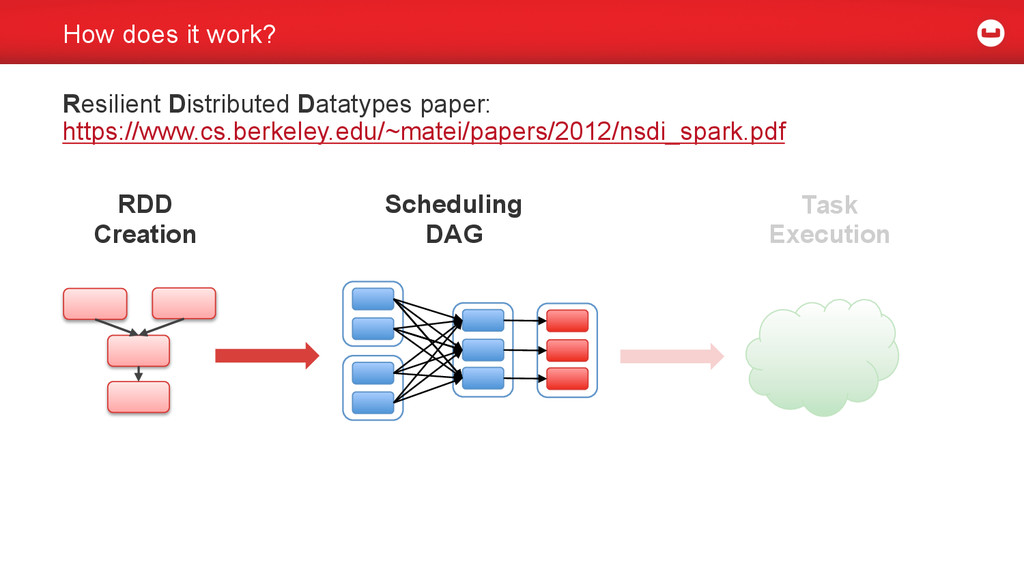
How does it work? Resilient Distributed Datatypes paper: https://www.cs.berkeley.edu/~matei/papers/2012/nsdi_spark.pdf RDD
Creation Scheduling DAG Task Execution -
How does it work? Resilient Distributed Datatypes paper: https://www.cs.berkeley.edu/~matei/papers/2012/nsdi_spark.pdf RDD
Creation Scheduling DAG Task Execution -
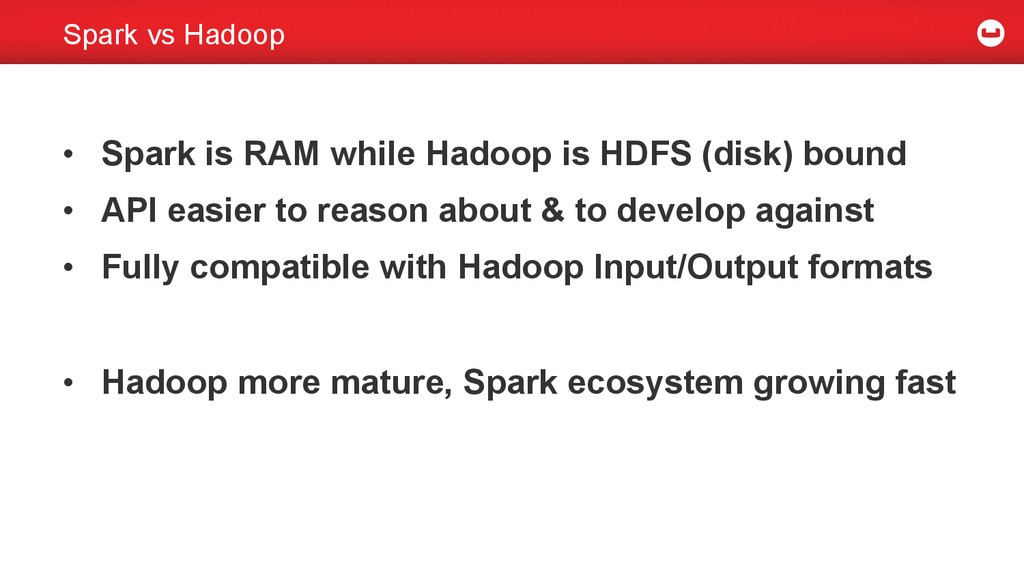
Spark vs Hadoop • Spark is RAM while Hadoop is
HDFS (disk) bound • API easier to reason about & to develop against • Fully compatible with Hadoop Input/Output formats • Hadoop more mature, Spark ecosystem growing fast -
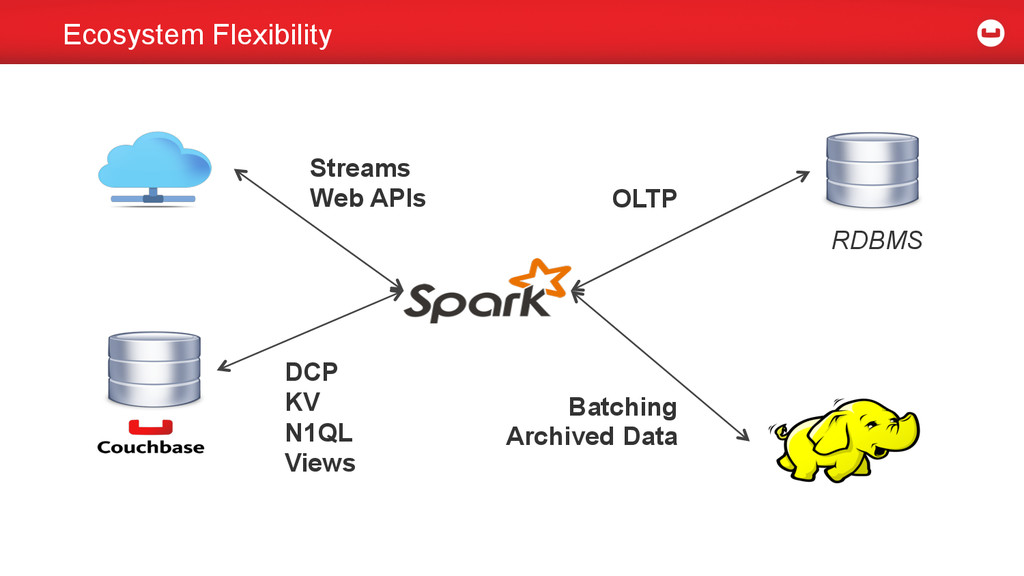
Ecosystem Flexibility RDBMS Streams Web APIs DCP KV N1QL Views
Batching Archived Data OLTP -
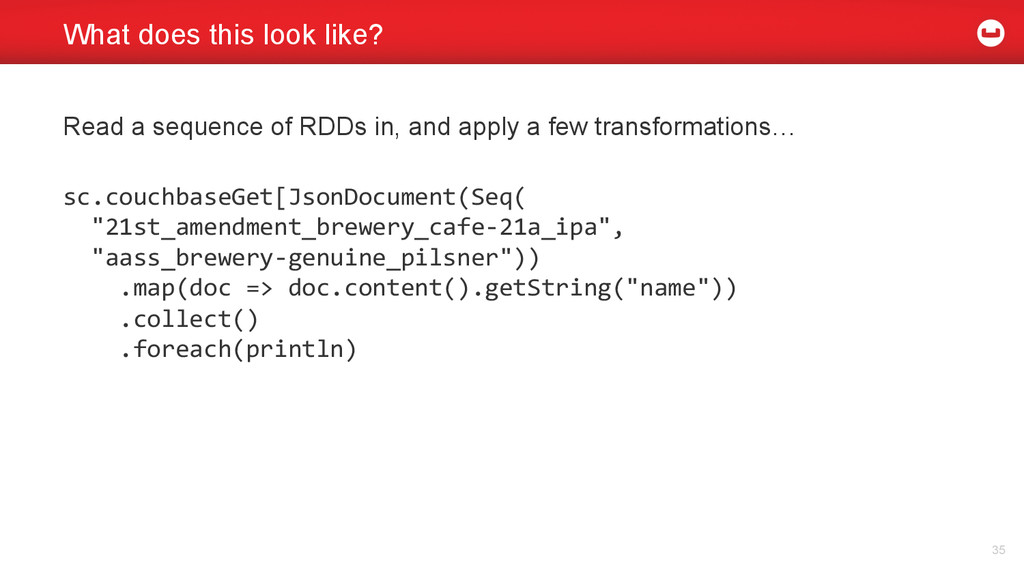
What does this look like? 35 Read a sequence of
RDDs in, and apply a few transformations… sc.couchbaseGet[JsonDocument(Seq( "21st_amendment_brewery_cafe-‐21a_ipa", "aass_brewery-‐genuine_pilsner")) .map(doc => doc.content().getString("name")) .collect() .foreach(println) -
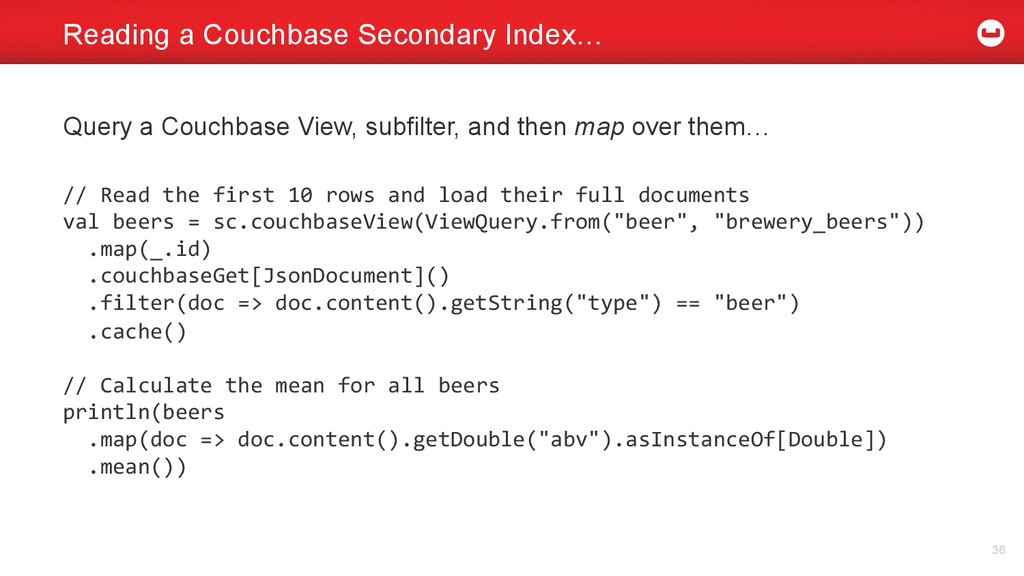
Reading a Couchbase Secondary Index… 36 Query a Couchbase View,
subfilter, and then map over them… // Read the first 10 rows and load their full documents val beers = sc.couchbaseView(ViewQuery.from("beer", "brewery_beers")) .map(_.id) .couchbaseGet[JsonDocument]() .filter(doc => doc.content().getString("type") == "beer") .cache() // Calculate the mean for all beers println(beers .map(doc => doc.content().getDouble("abv").asInstanceOf[Double]) .mean()) -
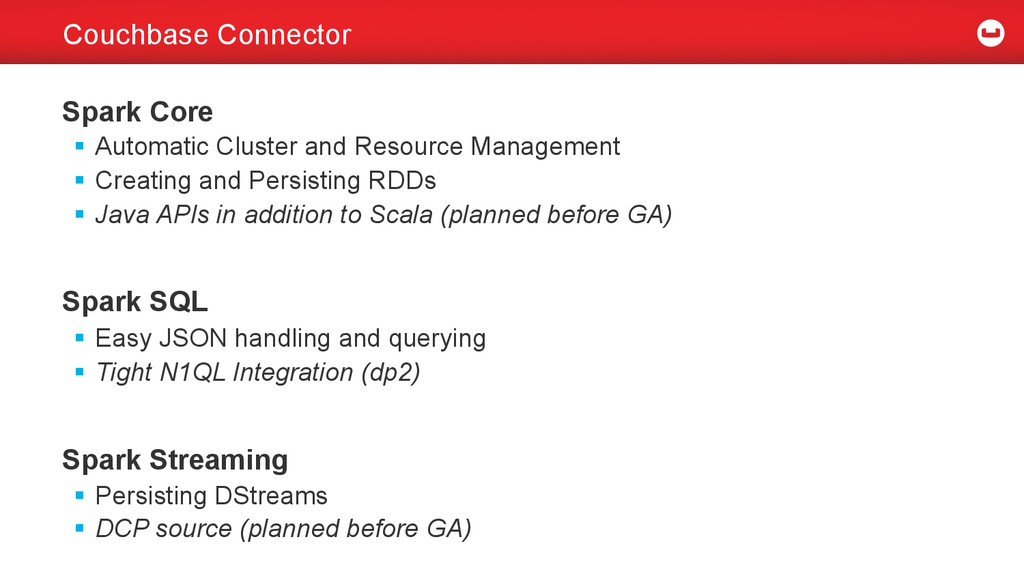
Couchbase Connector Spark Core § Automatic Cluster and Resource Management
§ Creating and Persisting RDDs § Java APIs in addition to Scala (planned before GA) Spark SQL § Easy JSON handling and querying § Tight N1QL Integration (dp2) Spark Streaming § Persisting DStreams § DCP source (planned before GA) -
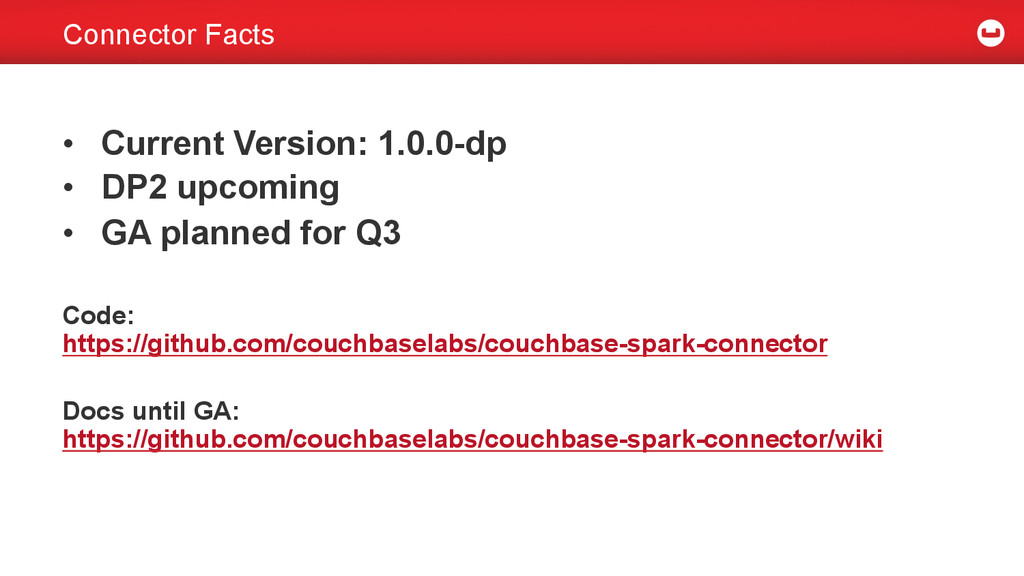
Connector Facts • Current Version: 1.0.0-dp • DP2 upcoming •
GA planned for Q3 Code: https://github.com/couchbaselabs/couchbase-spark-connector Docs until GA: https://github.com/couchbaselabs/couchbase-spark-connector/wiki -
Links • Subscribe to Couchbase newsletter: • http://info.couchbase.com/Community-Newsletter- Signup.html •
Couchbase is hiring a Solution Engineer in Paris • http://www.couchbase.com/careers • Join Paris Couchbase Meetup • http://www.meetup.com/Couchbase-France/