AI-Aware Traffic Management: Scaling Inference ...

AI-Aware Traffic Management: Scaling Inference with Istio Ambient Mesh
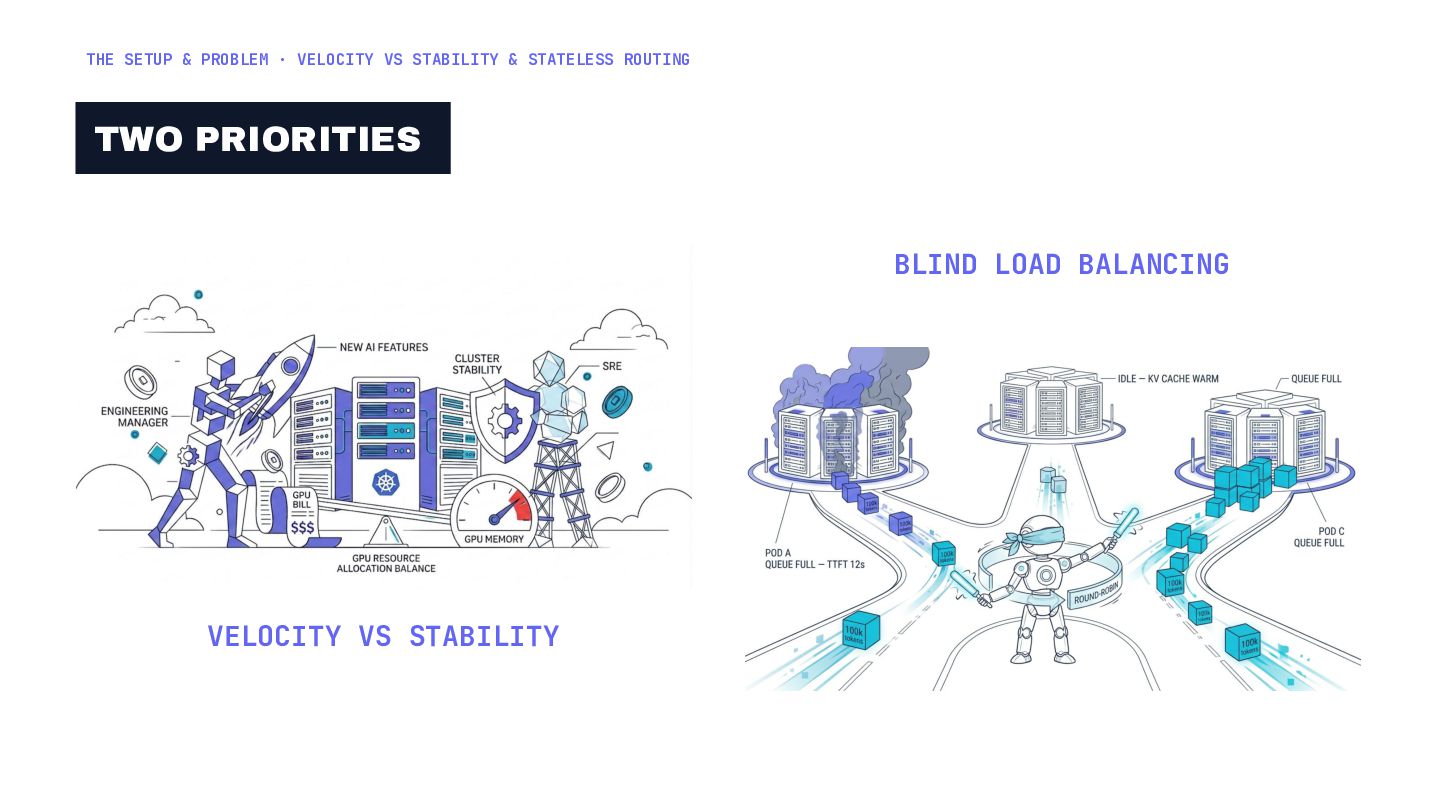
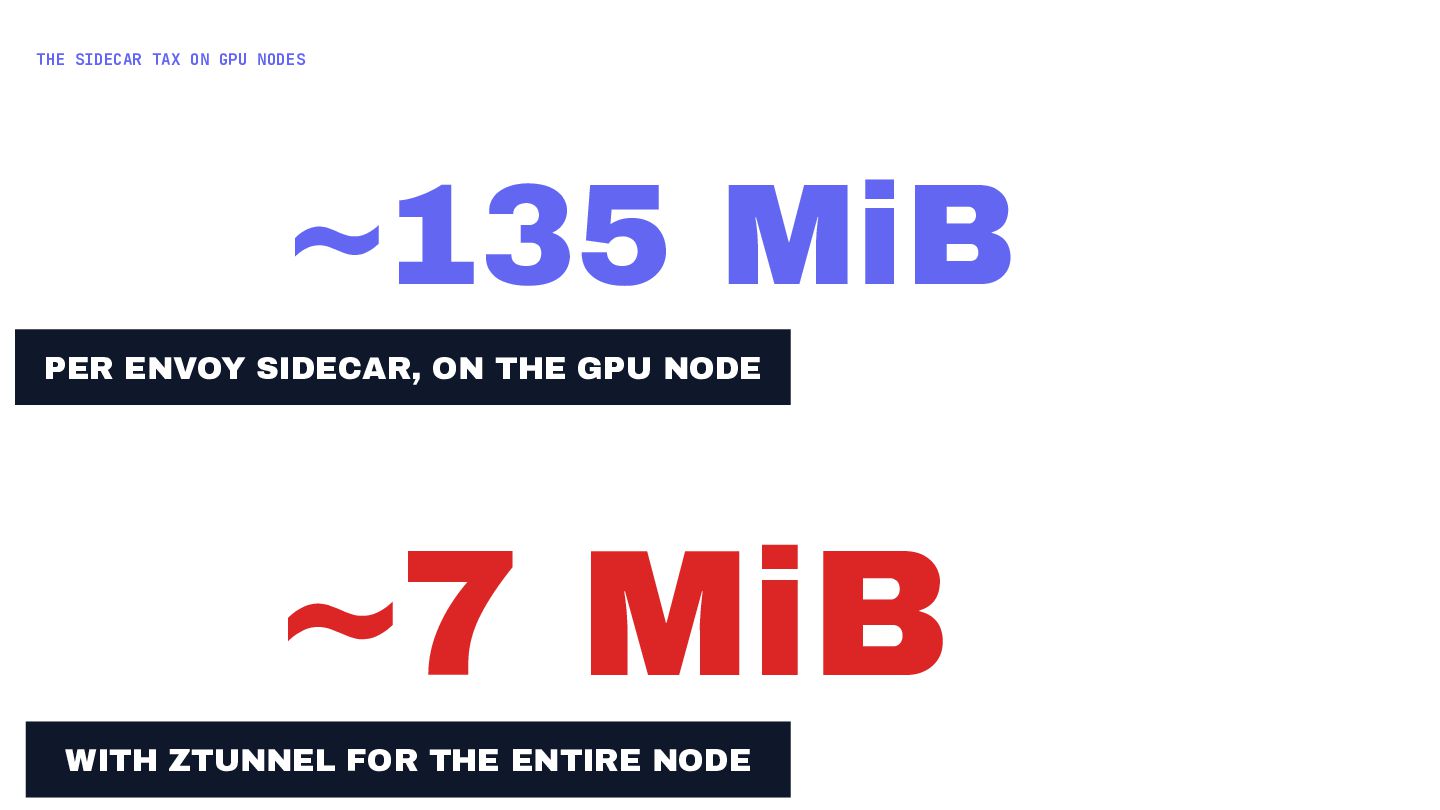
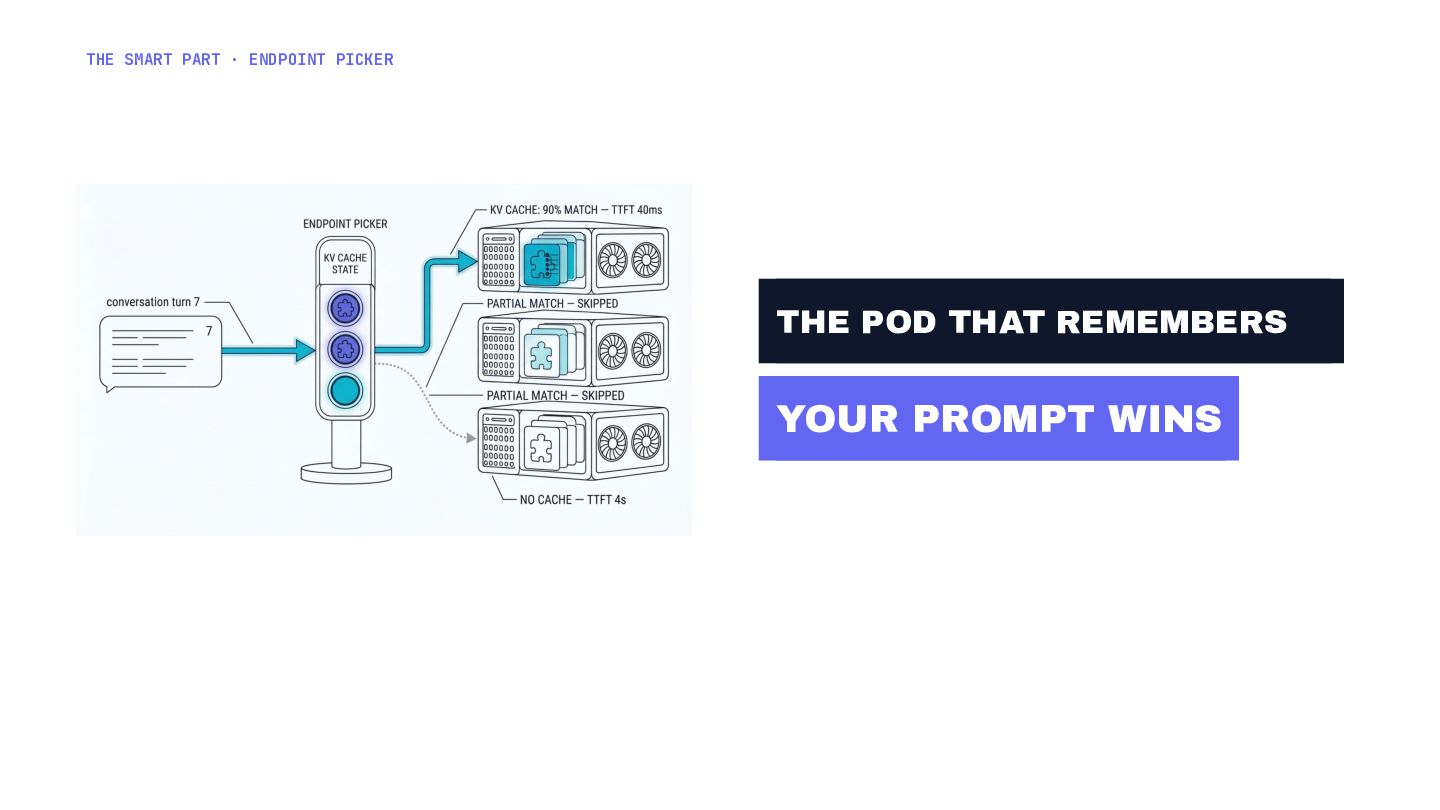
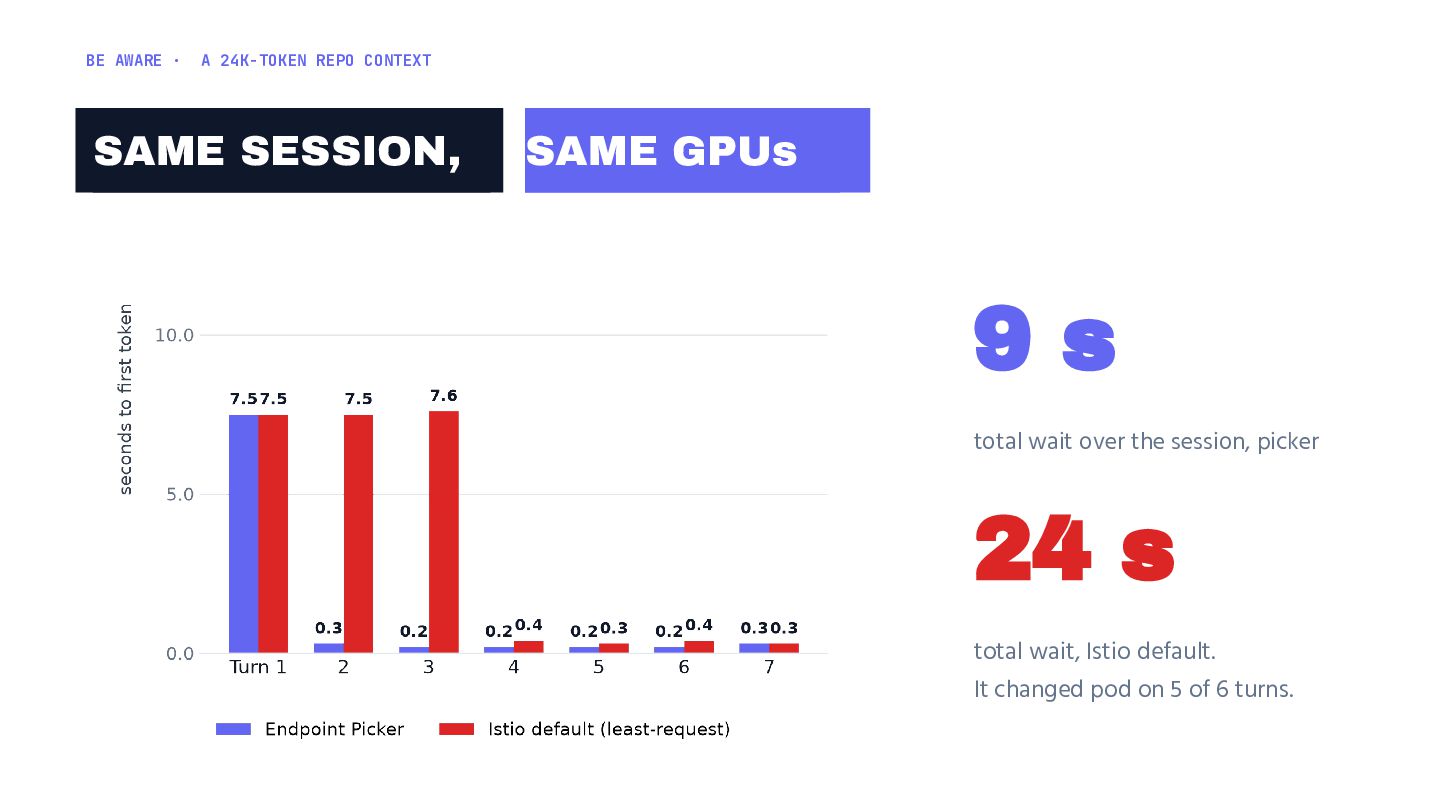
When rolling out AI inference and agentic workflows, a natural tension emerges between product velocity and platform stability. Engineering Managers push to ship LLM features quickly while keeping premium GPU cloud spend under control, while SREs face an operational nightmare. Traditional round-robin load balancers blindly send massive token requests to already choking GPU pods. Securing this traffic typically requires Envoy sidecars, which steal precious memory and CPU from the GPU nodes running the LLMs.
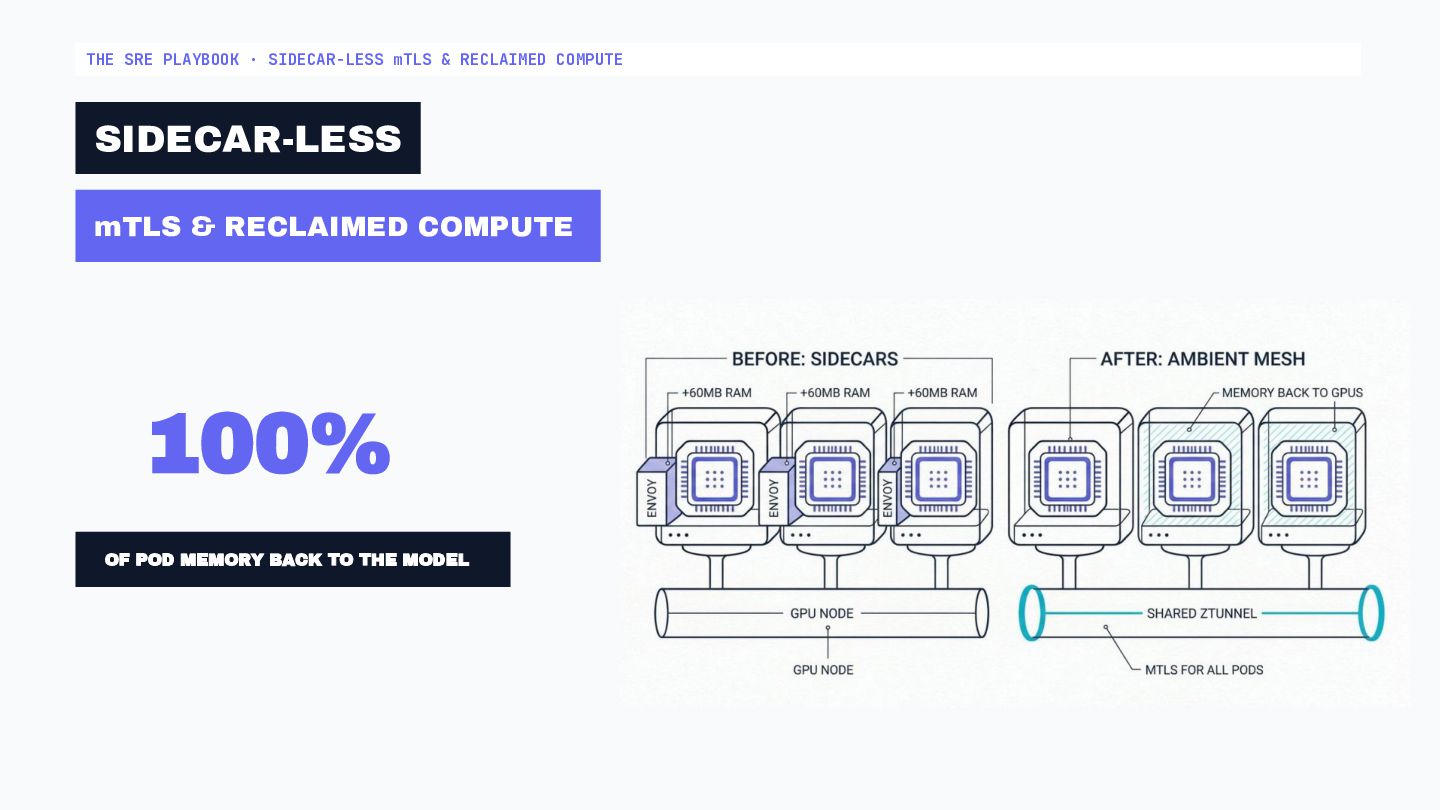
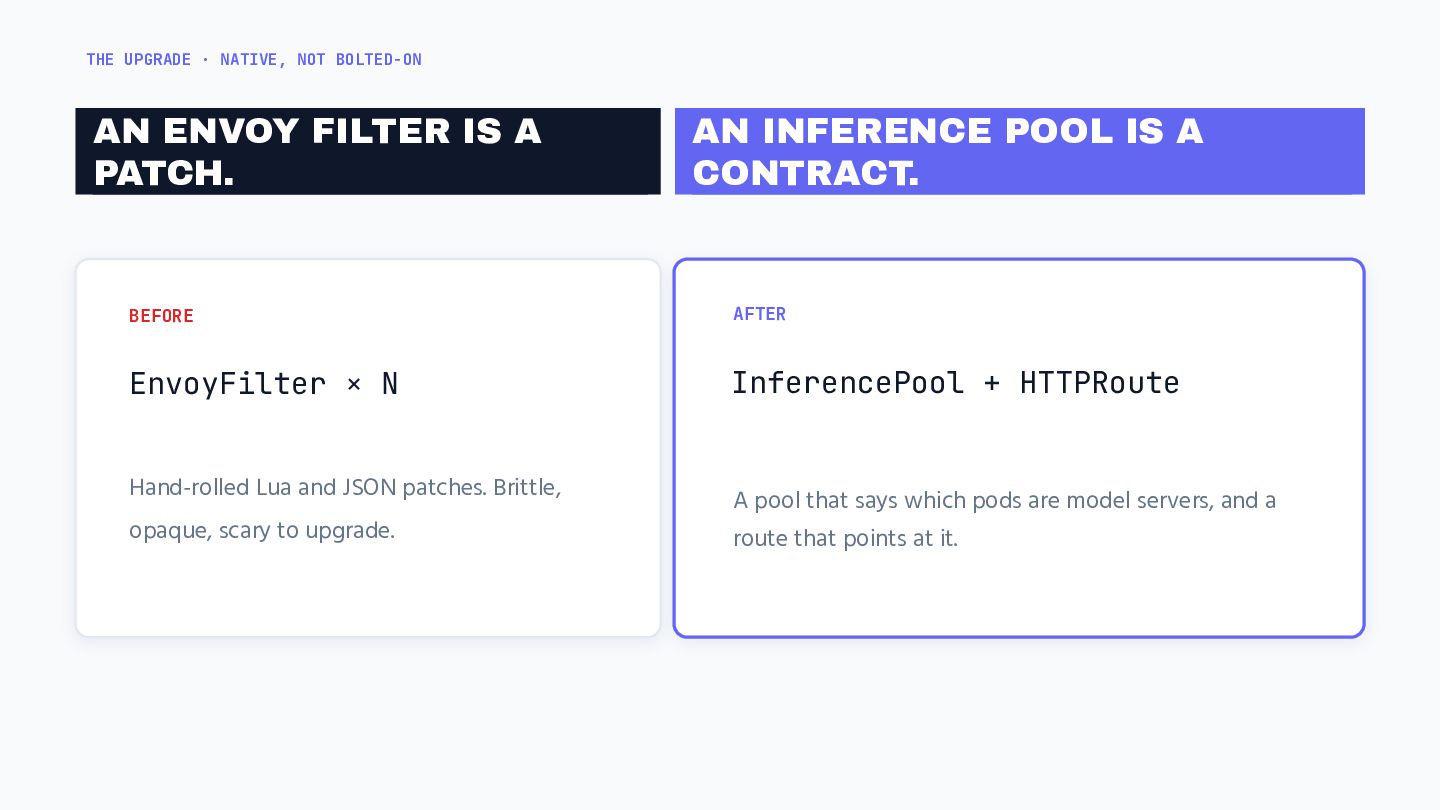
In this dual-perspective session, an Engineering Manager and SRE will debate and dissect the realities of scaling AI infrastructure. We will show how to resolve the velocity versus control paradox by treating AI workloads as first-class citizens in the mesh. We will demonstrate Istio Ambient Mesh ztunnels for sidecar-less mTLS, pushing L7 processing to Waypoint proxies on standard CPU nodes and reclaiming compute for GPUs.

 hannaholukoye
 taiki45
 takuros
 kmotohas
 naltatis
 birgitta410
 orimanabu
 oidfj
 inariku
 raksulrecruiting
 riyaamemiya
 tomoaki25
 dougneiner
 nonsquared
 sarafernandez
 reverentgeek
 helmedeiros
 greggifford
 thekraken
 mfonobong
 3n
 jonoalderson
 sugarenia
 katarinadahlin