AI Infrastructure at Speed: Governance Without ...
Sponsored
·
 Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→

Share
Embed
AI Infrastructure at Speed: Governance Without the Drag
A session at LINE THAILAND DEVELOPER CONFERENCE 2026

LINE Developers Thailand
October 17, 2026
Transcript
85 slides
-
AI Infrastructure at Speed: Governance Without the Drag Enabling governed
AI for engineers and non-engineers Kajornsak Peerapathananont -
The pain: chasing AI • API keys: who owns each
key, and where is it used? -
The pain: chasing AI • API keys: who owns each
key, and where is it used? • Usage: who is using what, across which providers? -
The pain: chasing AI • API keys: who owns each
key, and where is it used? • Usage: who is using what, across which providers? • Billing: separate dashboards, invoices, and surprise costs 💰💰💰. -
The pain: chasing AI • API keys: who owns each
key, and where is it used? • Usage: who is using what, across which providers? • Billing: separate dashboards, invoices, and surprise costs 💰💰💰. • Every new provider adds another thing to chase. -
Agenda • The problem: AI is already everywhere • Design
principle: centralize governance, decentralize UX -
Agenda • The problem: AI is already everywhere • Design
principle: centralize governance, decentralize UX • Architecture & tools: LiteLLM, Langfuse, Onyx, Sourcebot -
Agenda • The problem: AI is already everywhere • Design
principle: centralize governance, decentralize UX • Architecture & tools: LiteLLM, Langfuse, Onyx, Sourcebot • The hard part: usage outside the gateway -
Agenda • The problem: AI is already everywhere • Design
principle: centralize governance, decentralize UX • Architecture & tools: LiteLLM, Langfuse, Onyx, Sourcebot • The hard part: usage outside the gateway • Governance as guardrails, not gates • What we learned -
Everyone wants AI. Everyone wants it differently. Engineers • Non-engineers
• Product teams • Management -
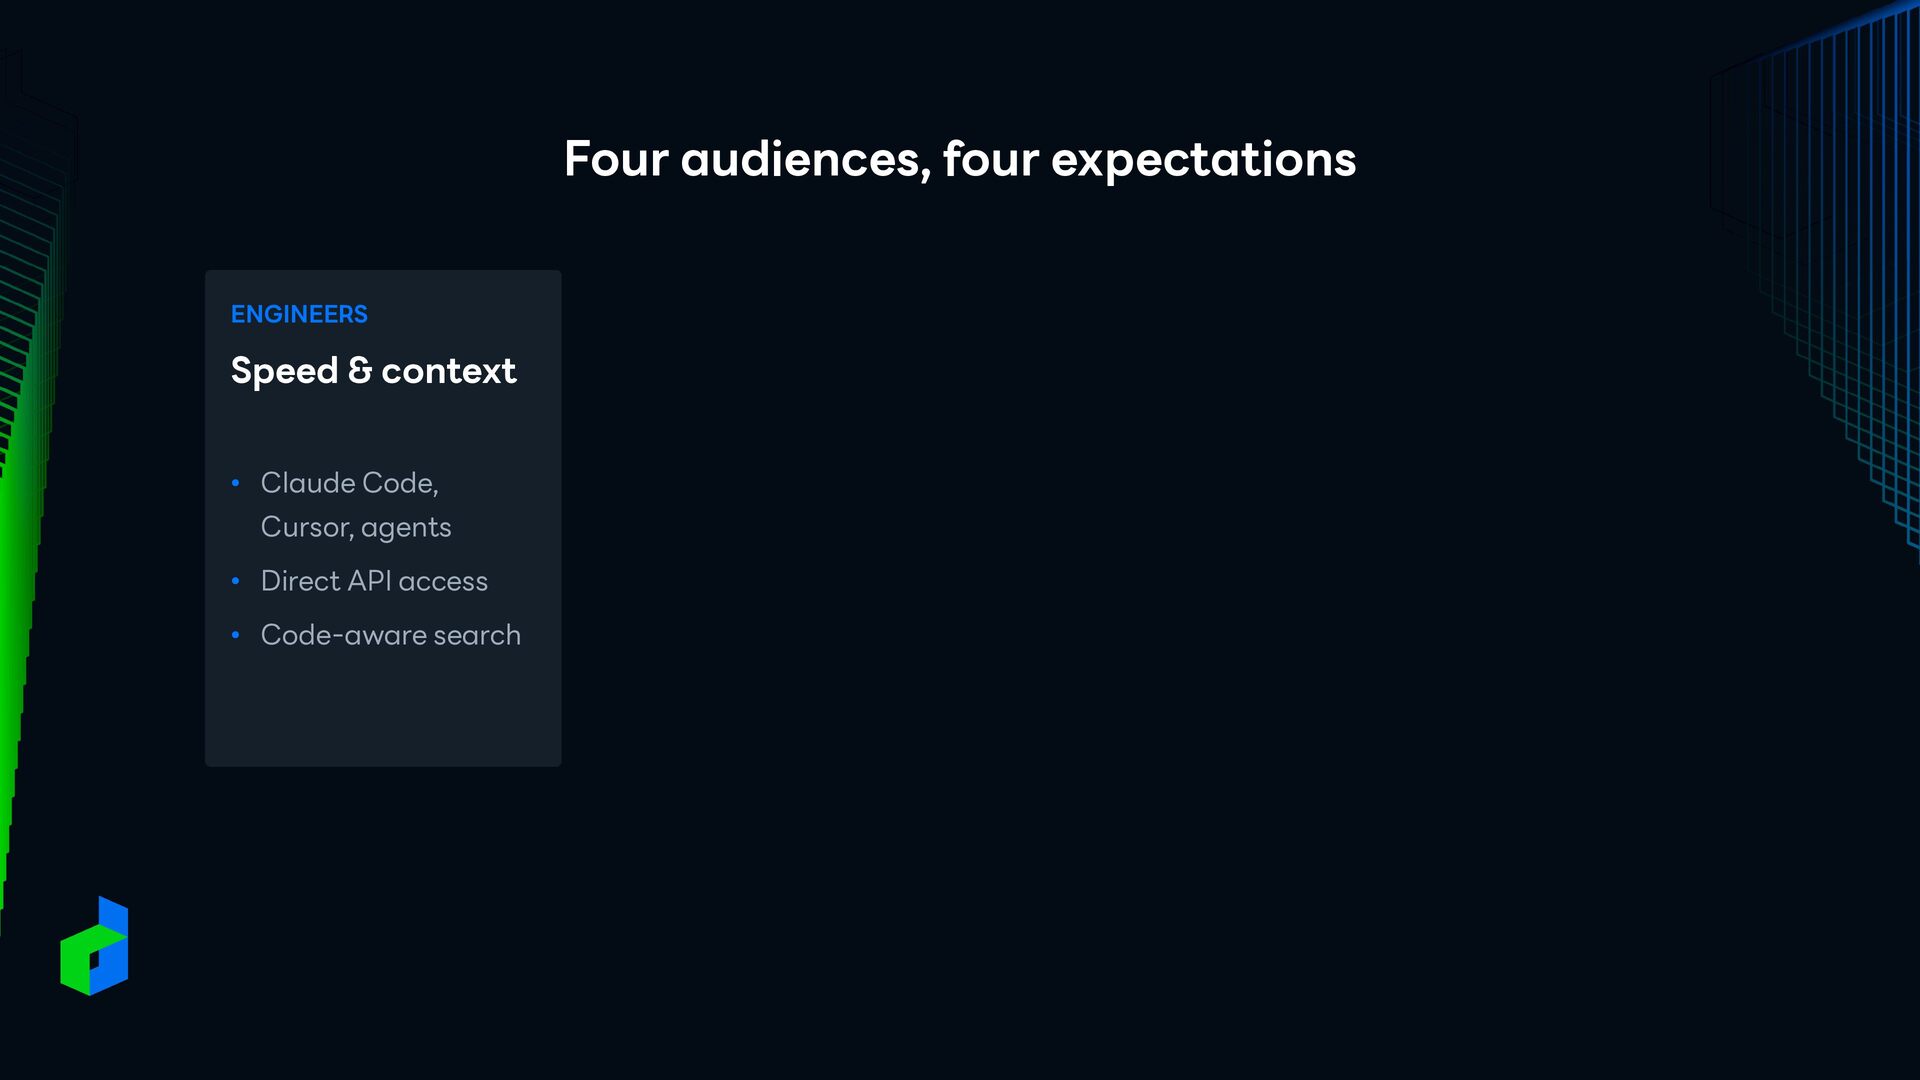
Four audiences, four expectations ENGINEERS Speed & context • Claude
Code, Cursor, agents • Direct API access • Code-aware search -
Four audiences, four expectations ENGINEERS NON-ENGINEERS Speed & context Answers,
not • Claude Code, • Chat in web & Slack Cursor, agents • Direct API access • Code-aware search APIs • Company knowledge • No subscription to manage -
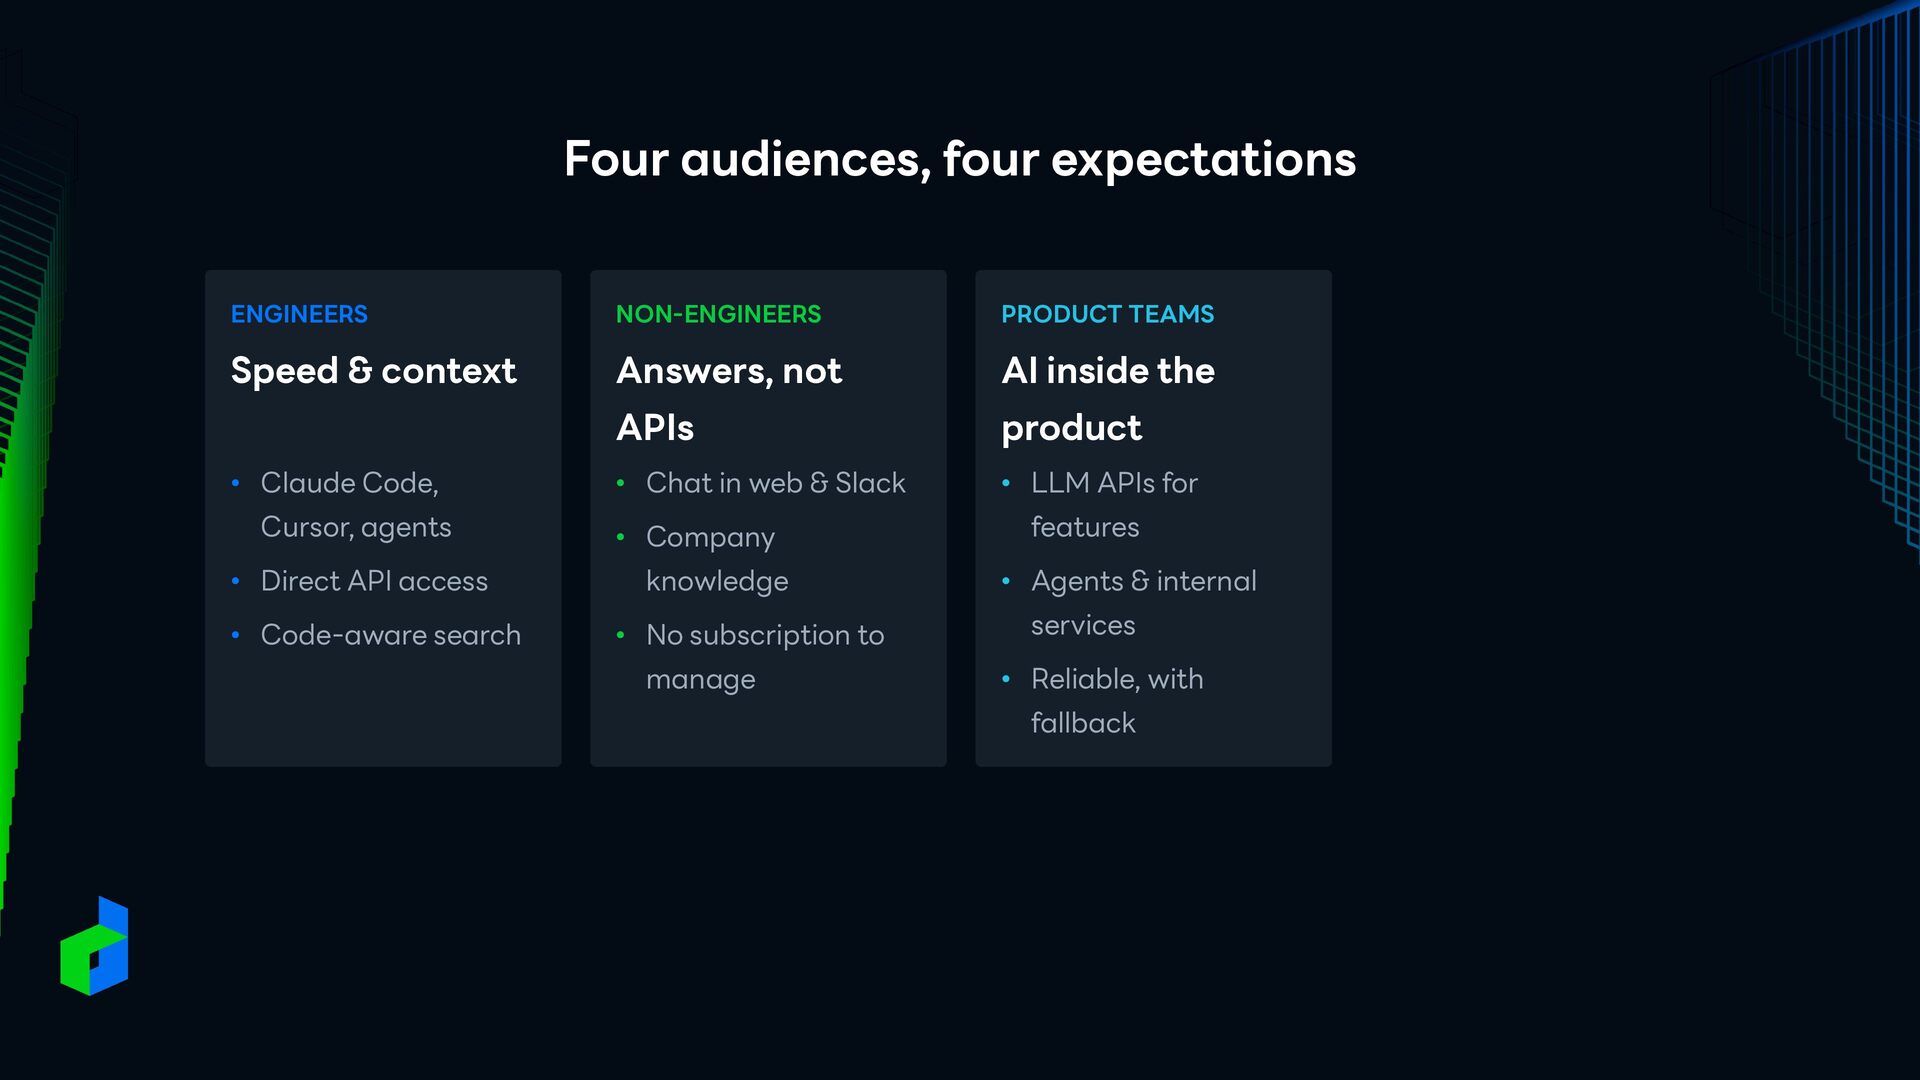
Four audiences, four expectations ENGINEERS NON-ENGINEERS PRODUCT TEAMS Speed &
context Answers, not AI inside the • Claude Code, • Chat in web & Slack • LLM APIs for Cursor, agents • Direct API access • Code-aware search APIs • Company knowledge • No subscription to manage product features • Agents & internal services • Reliable, with fallback -
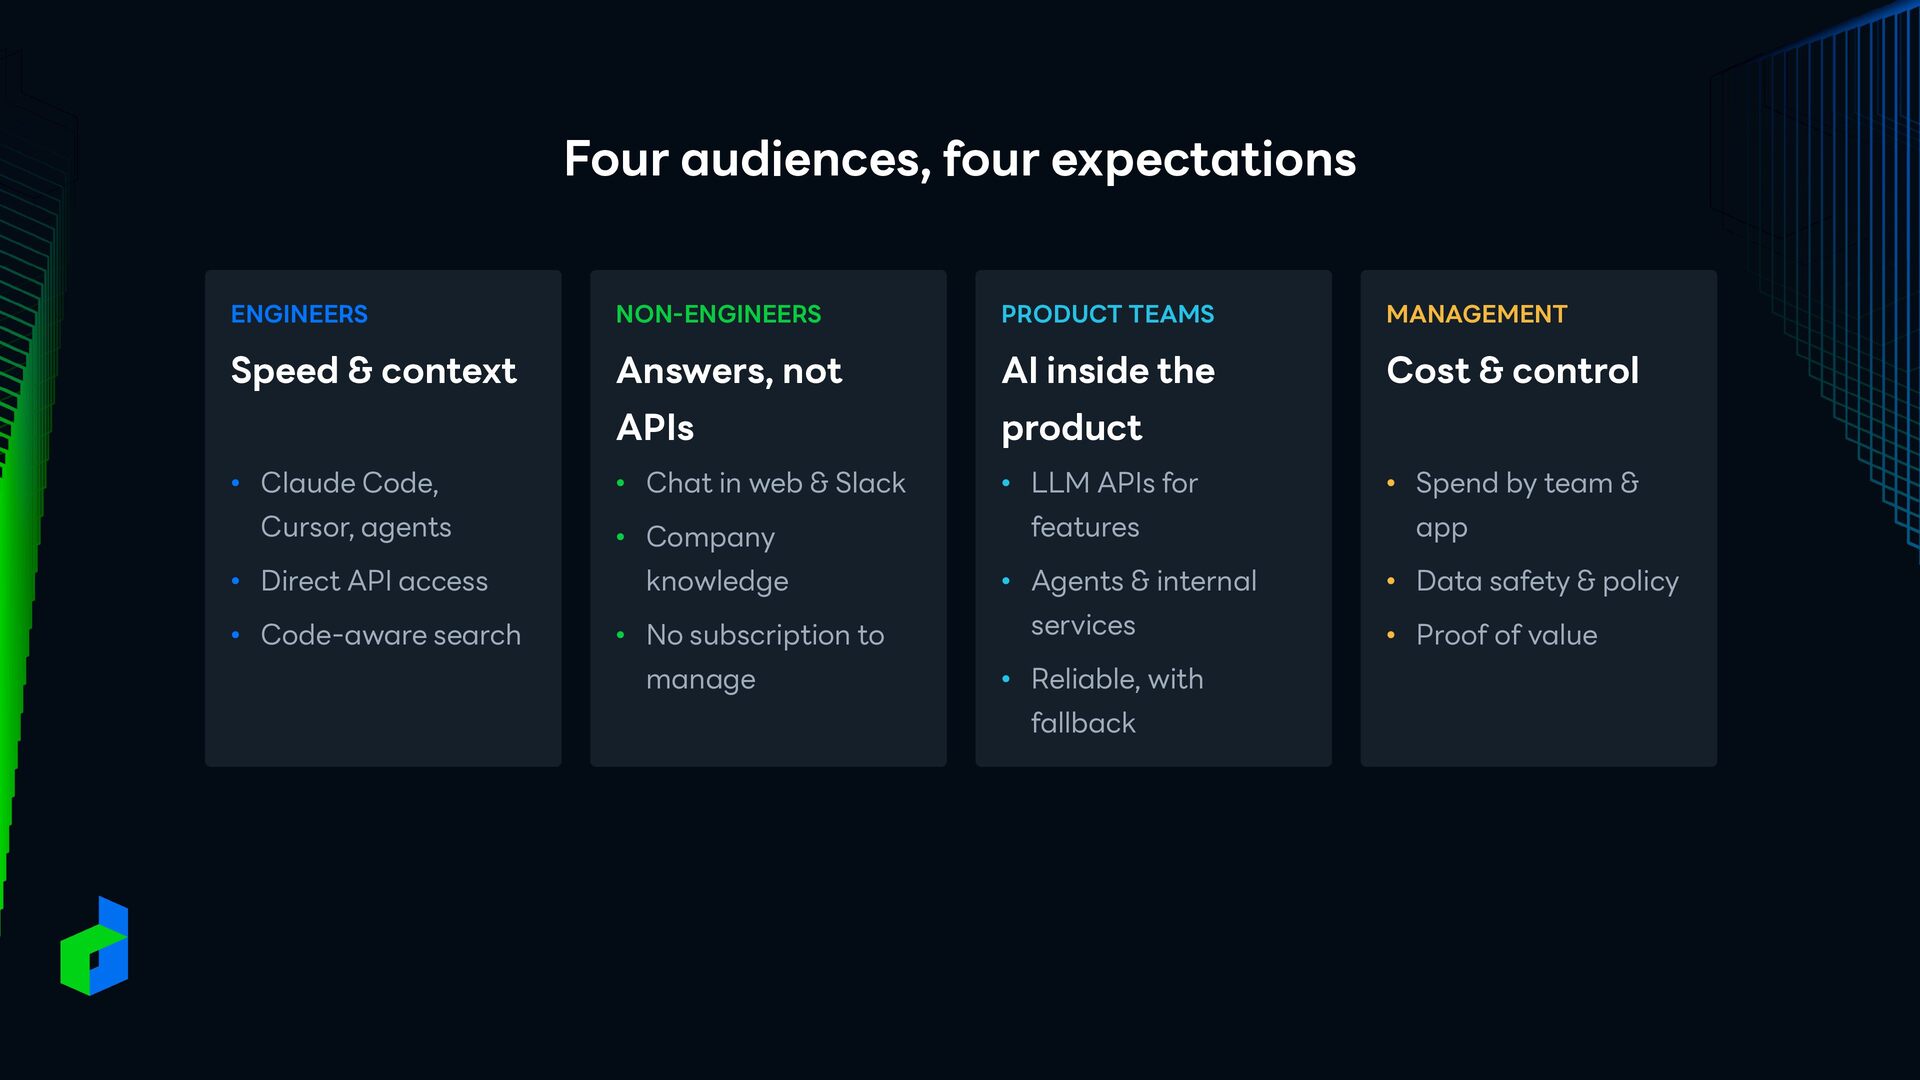
Four audiences, four expectations ENGINEERS NON-ENGINEERS PRODUCT TEAMS MANAGEMENT Speed
& context Answers, not AI inside the Cost & control • Claude Code, • Chat in web & Slack • LLM APIs for • Spend by team & • Agents & internal • Data safety & policy Cursor, agents • Direct API access • Code-aware search APIs • Company knowledge • No subscription to manage product features services • Reliable, with fallback app • Proof of value -
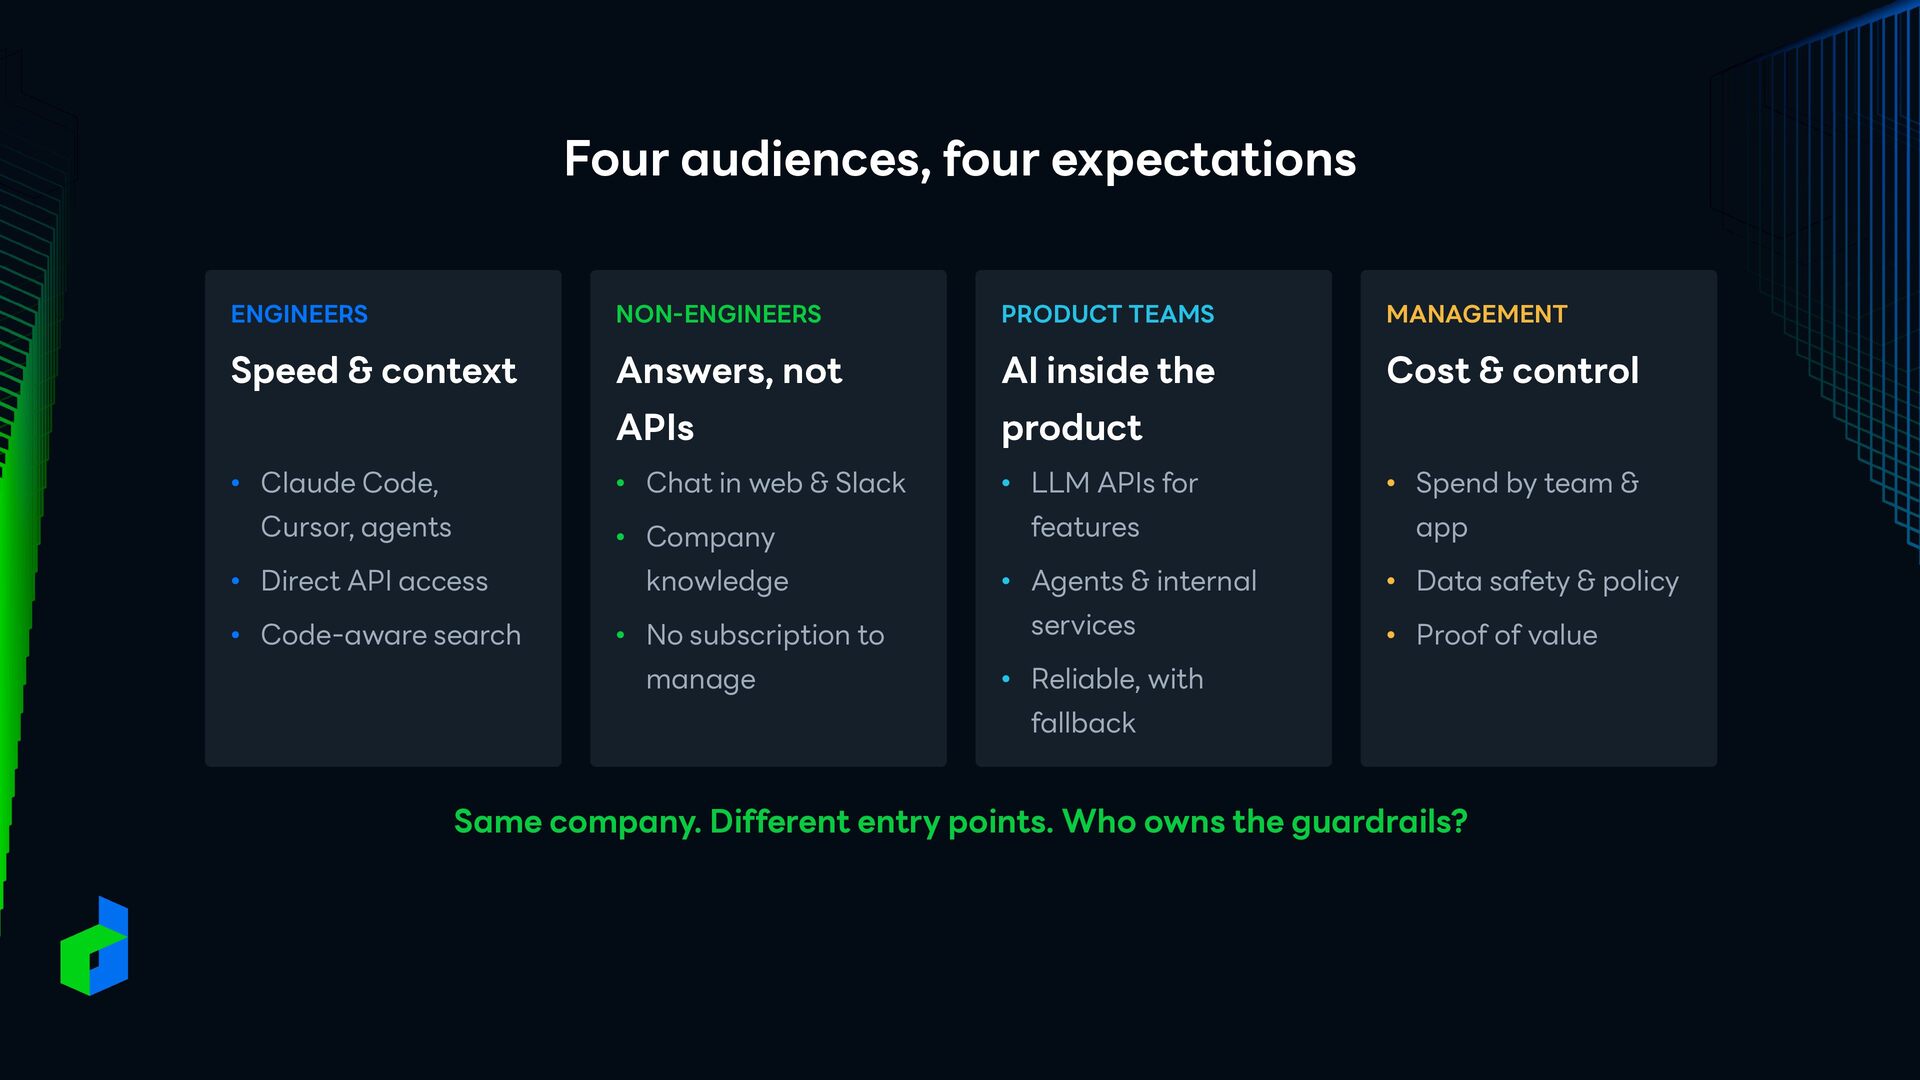
Four audiences, four expectations ENGINEERS NON-ENGINEERS PRODUCT TEAMS MANAGEMENT Speed
& context Answers, not AI inside the Cost & control • Claude Code, • Chat in web & Slack • LLM APIs for • Spend by team & • Agents & internal • Data safety & policy Cursor, agents • Direct API access • Code-aware search APIs • Company knowledge • No subscription to manage product features services • Reliable, with app • Proof of value fallback Same company. Different entry points. Who owns the guardrails? -
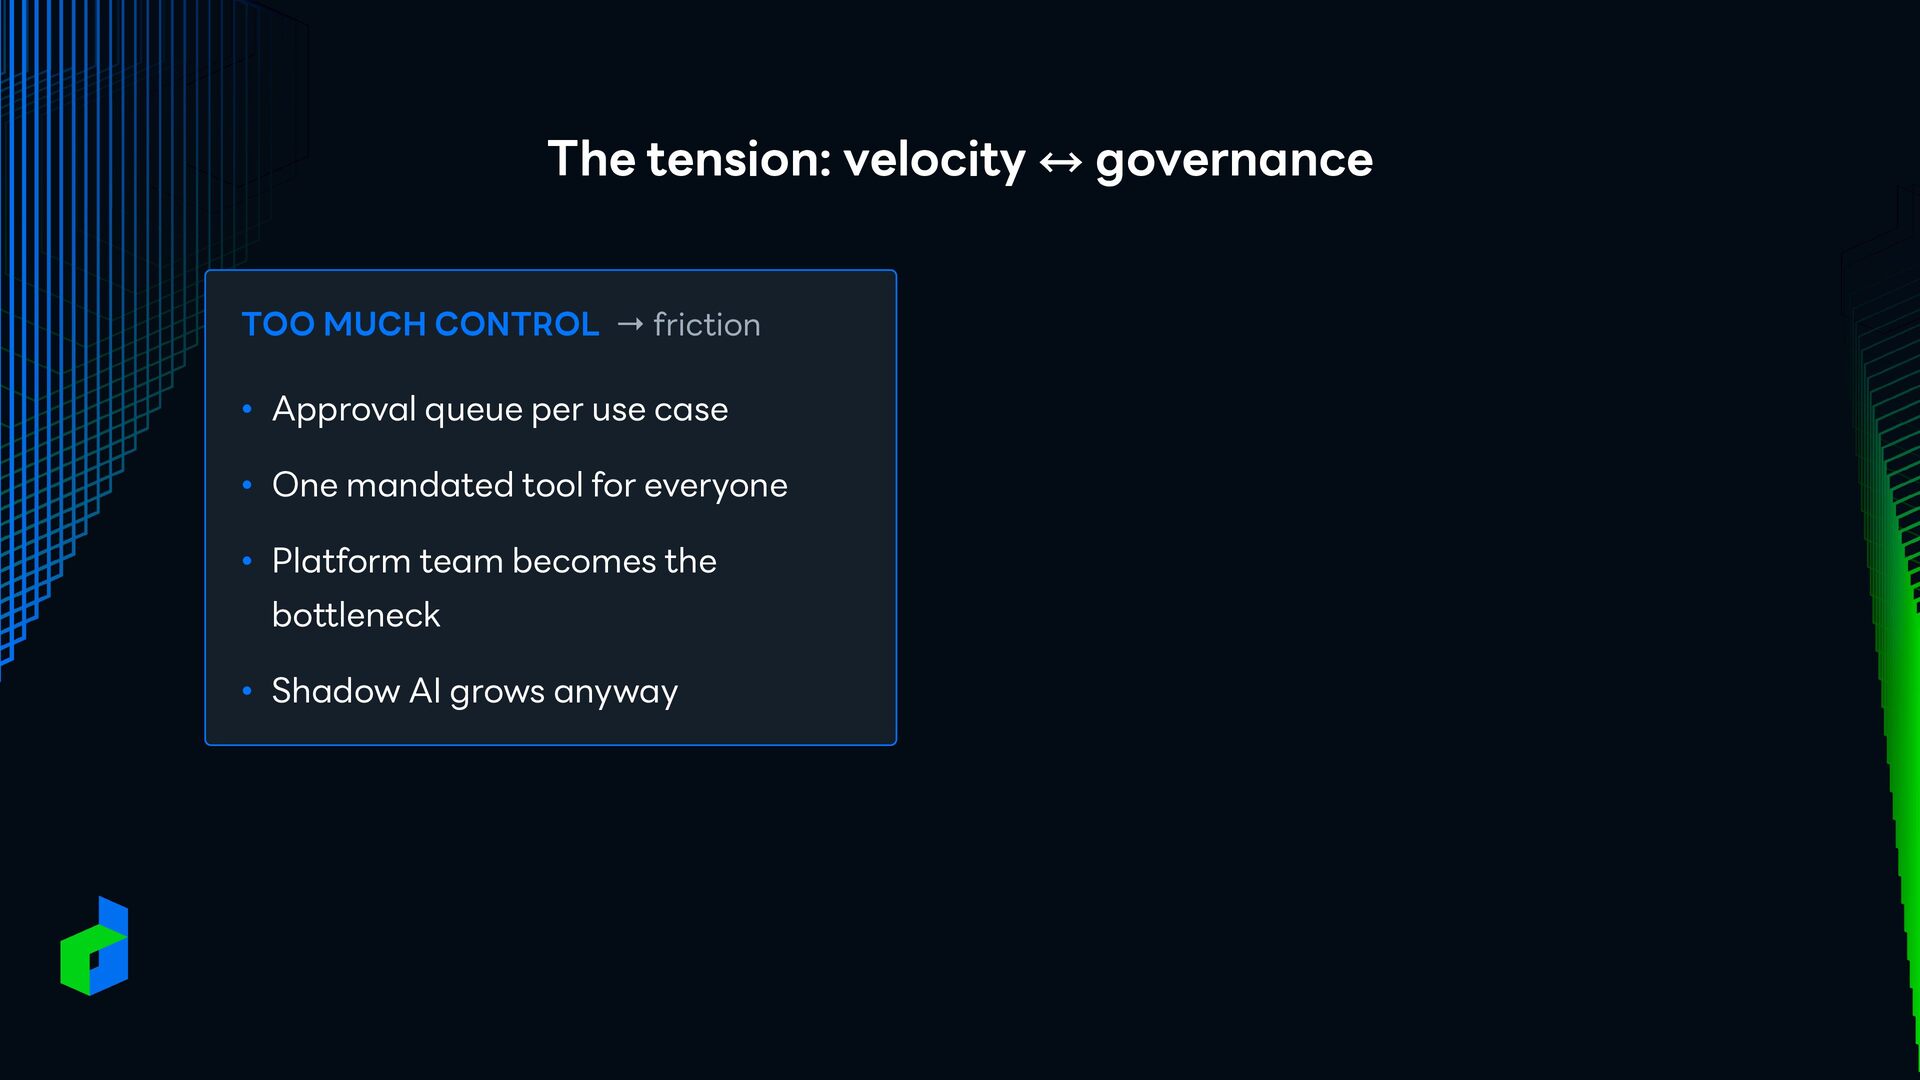
The tension: velocity TOO MUCH CONTROL → friction • Approval
queue per use case • One mandated tool for everyone • Platform team becomes the bottleneck • Shadow AI grows anyway governance -
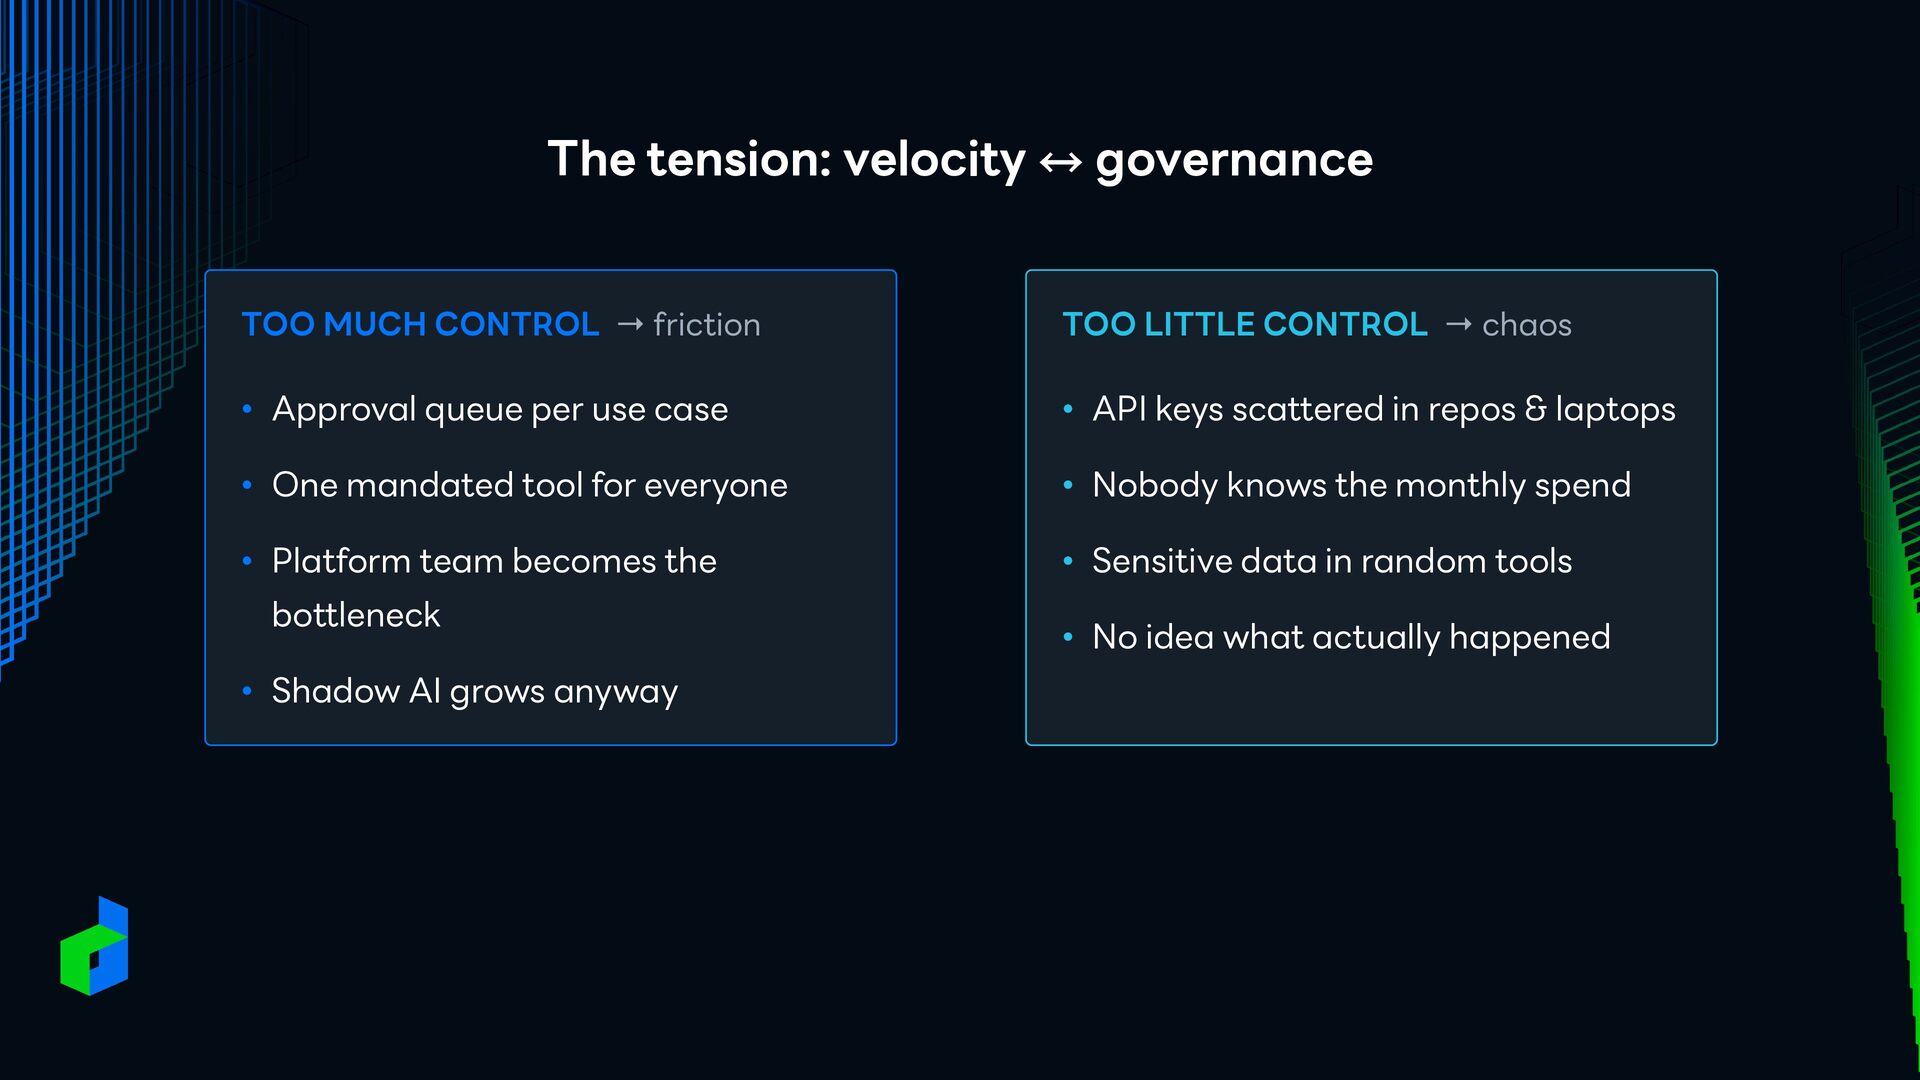
The tension: velocity governance TOO MUCH CONTROL → friction TOO
LITTLE CONTROL → chaos • Approval queue per use case • API keys scattered in repos & laptops • One mandated tool for everyone • Nobody knows the monthly spend • Platform team becomes the • Sensitive data in random tools bottleneck • Shadow AI grows anyway • No idea what actually happened -
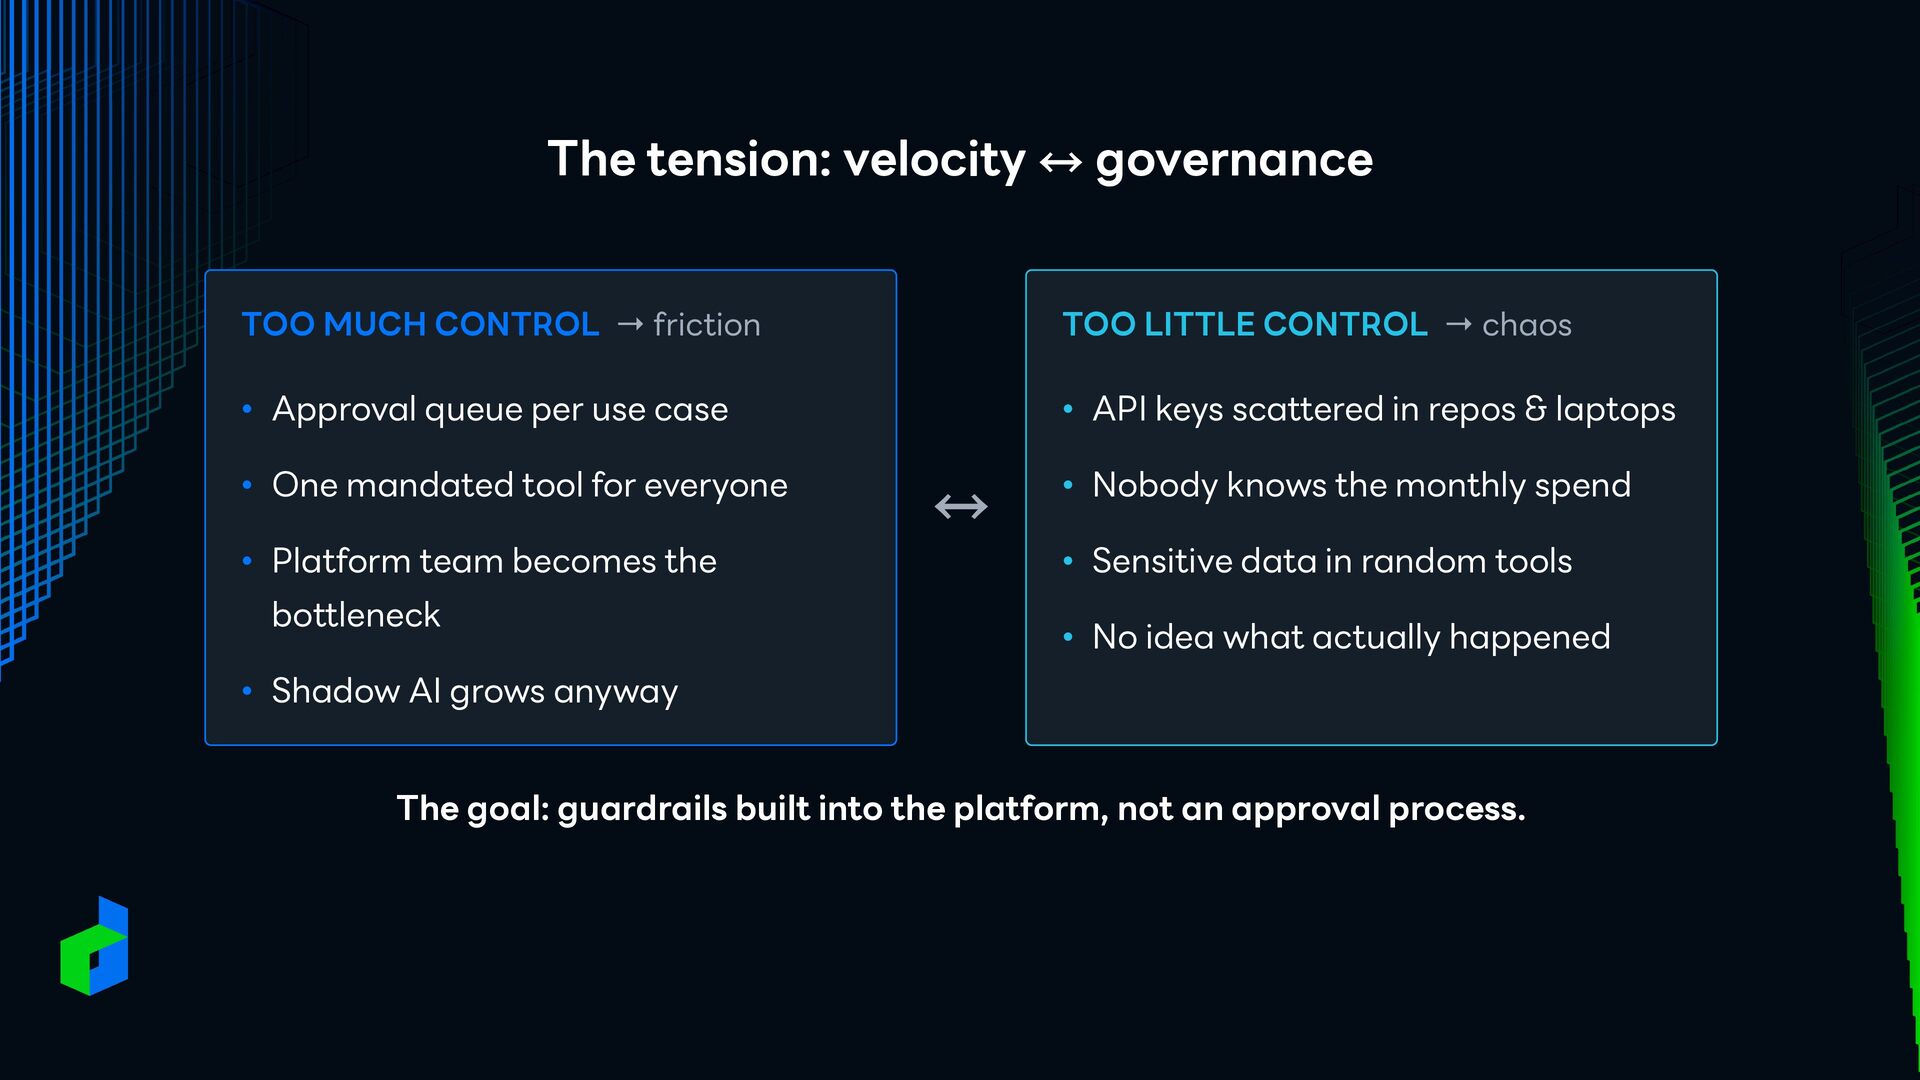
The tension: velocity governance TOO MUCH CONTROL → friction TOO
LITTLE CONTROL → chaos • Approval queue per use case • API keys scattered in repos & laptops • One mandated tool for everyone • Nobody knows the monthly spend • Platform team becomes the • Sensitive data in random tools bottleneck • No idea what actually happened • Shadow AI grows anyway The goal: guardrails built into the platform, not an approval process. -
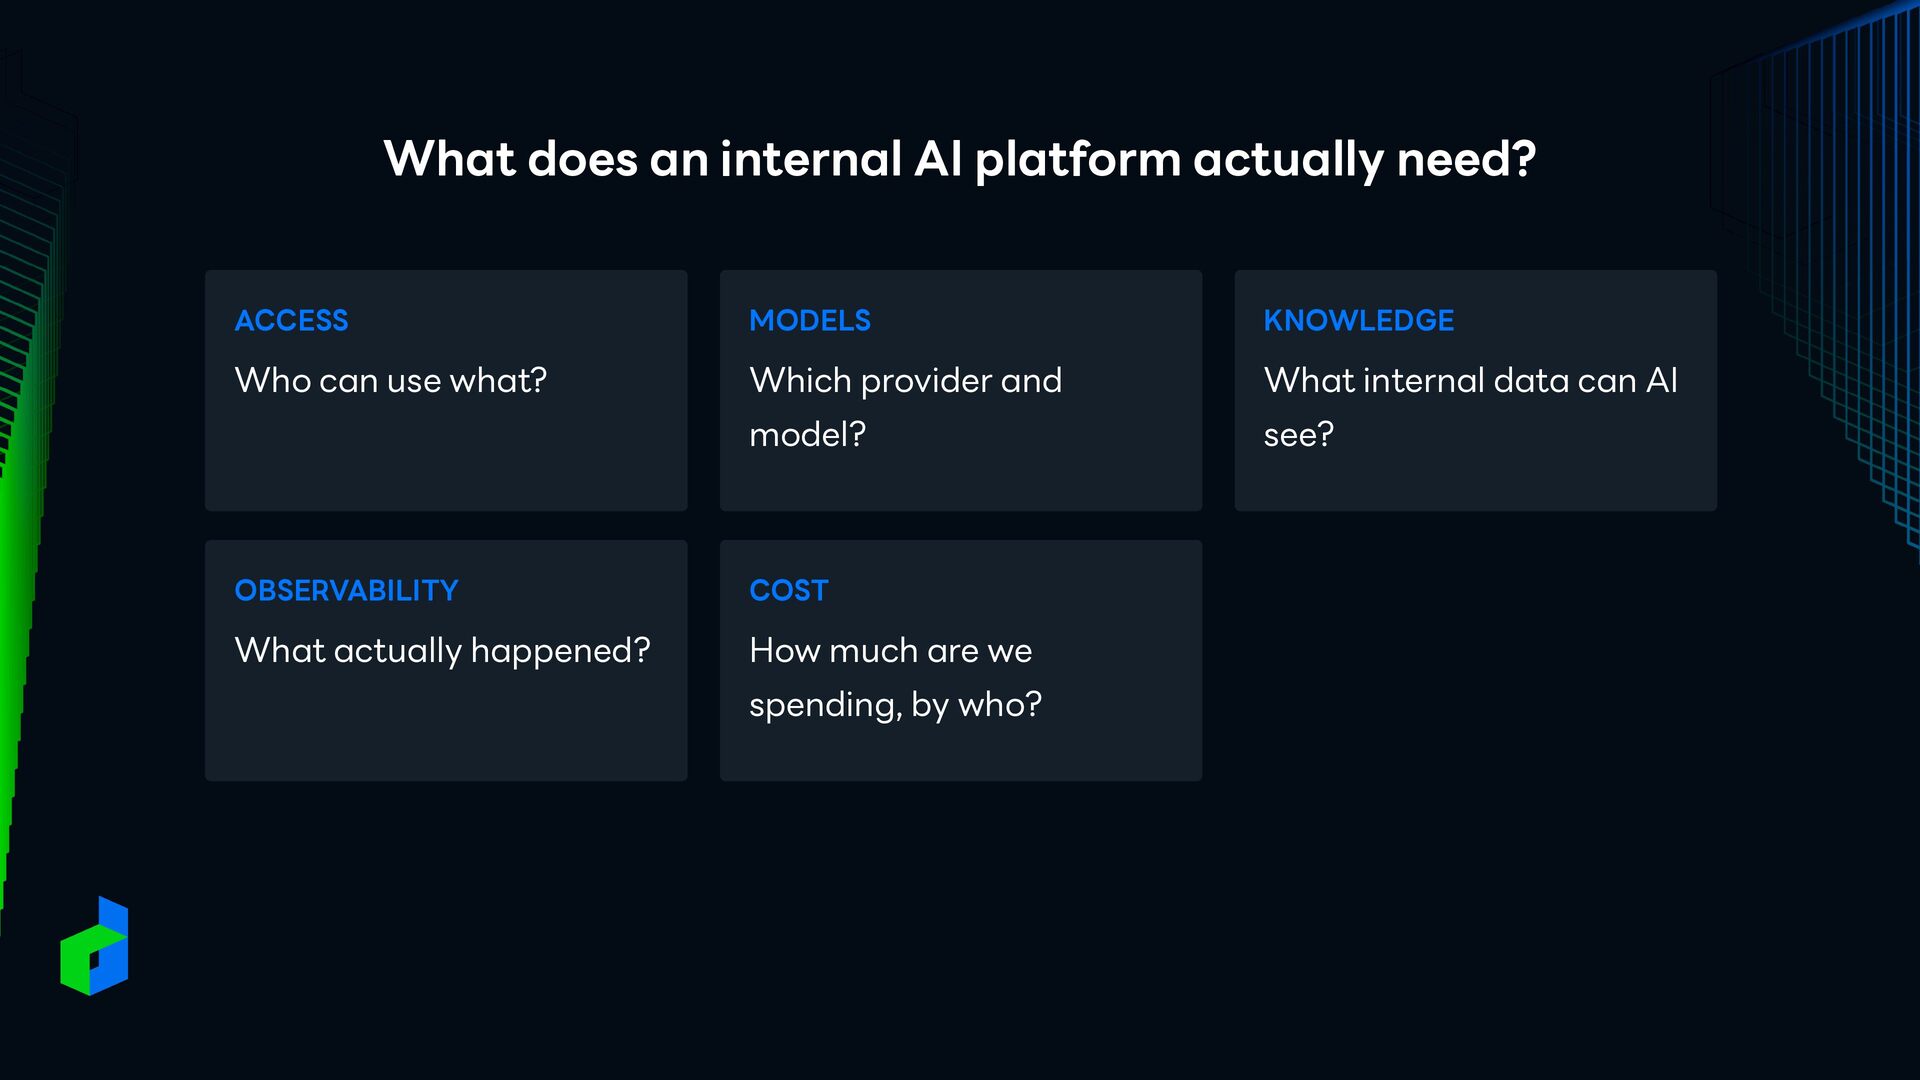
What does an internal AI platform actually need? ACCESS MODELS
Who can use what? Which provider and model? -
What does an internal AI platform actually need? ACCESS MODELS
KNOWLEDGE Who can use what? Which provider and What internal data can AI model? see? -
What does an internal AI platform actually need? ACCESS MODELS
KNOWLEDGE Who can use what? Which provider and What internal data can AI model? see? OBSERVABILITY What actually happened? -
What does an internal AI platform actually need? ACCESS MODELS
KNOWLEDGE Who can use what? Which provider and What internal data can AI model? see? OBSERVABILITY COST What actually happened? How much are we spending, by who? -
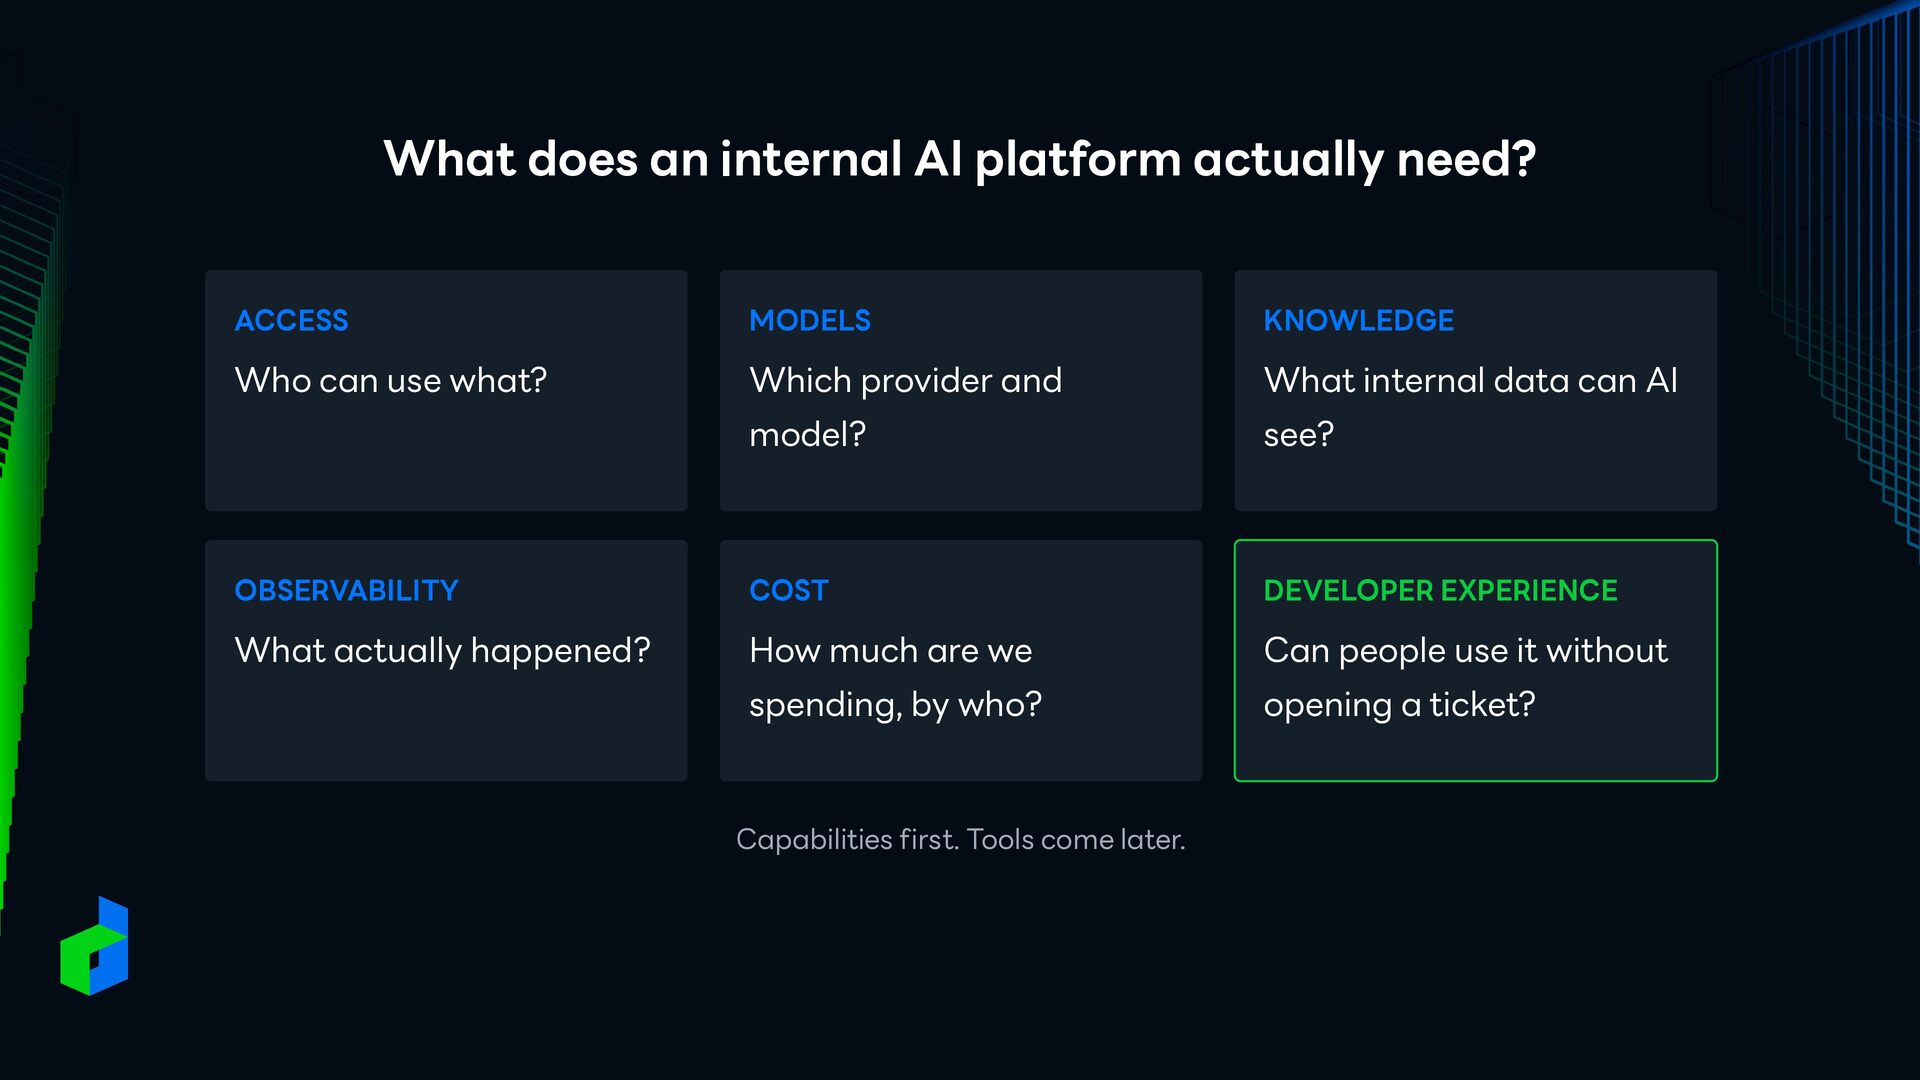
What does an internal AI platform actually need? ACCESS MODELS
KNOWLEDGE Who can use what? Which provider and What internal data can AI model? see? OBSERVABILITY COST DEVELOPER EXPERIENCE What actually happened? How much are we Can people use it without spending, by who? opening a ticket? Capabilities first. Tools come later. -
Our design principle Centralize governance. Decentralize the user experience. We
don't force everyone onto the same AI tool. We give different tools the same governance foundation. -
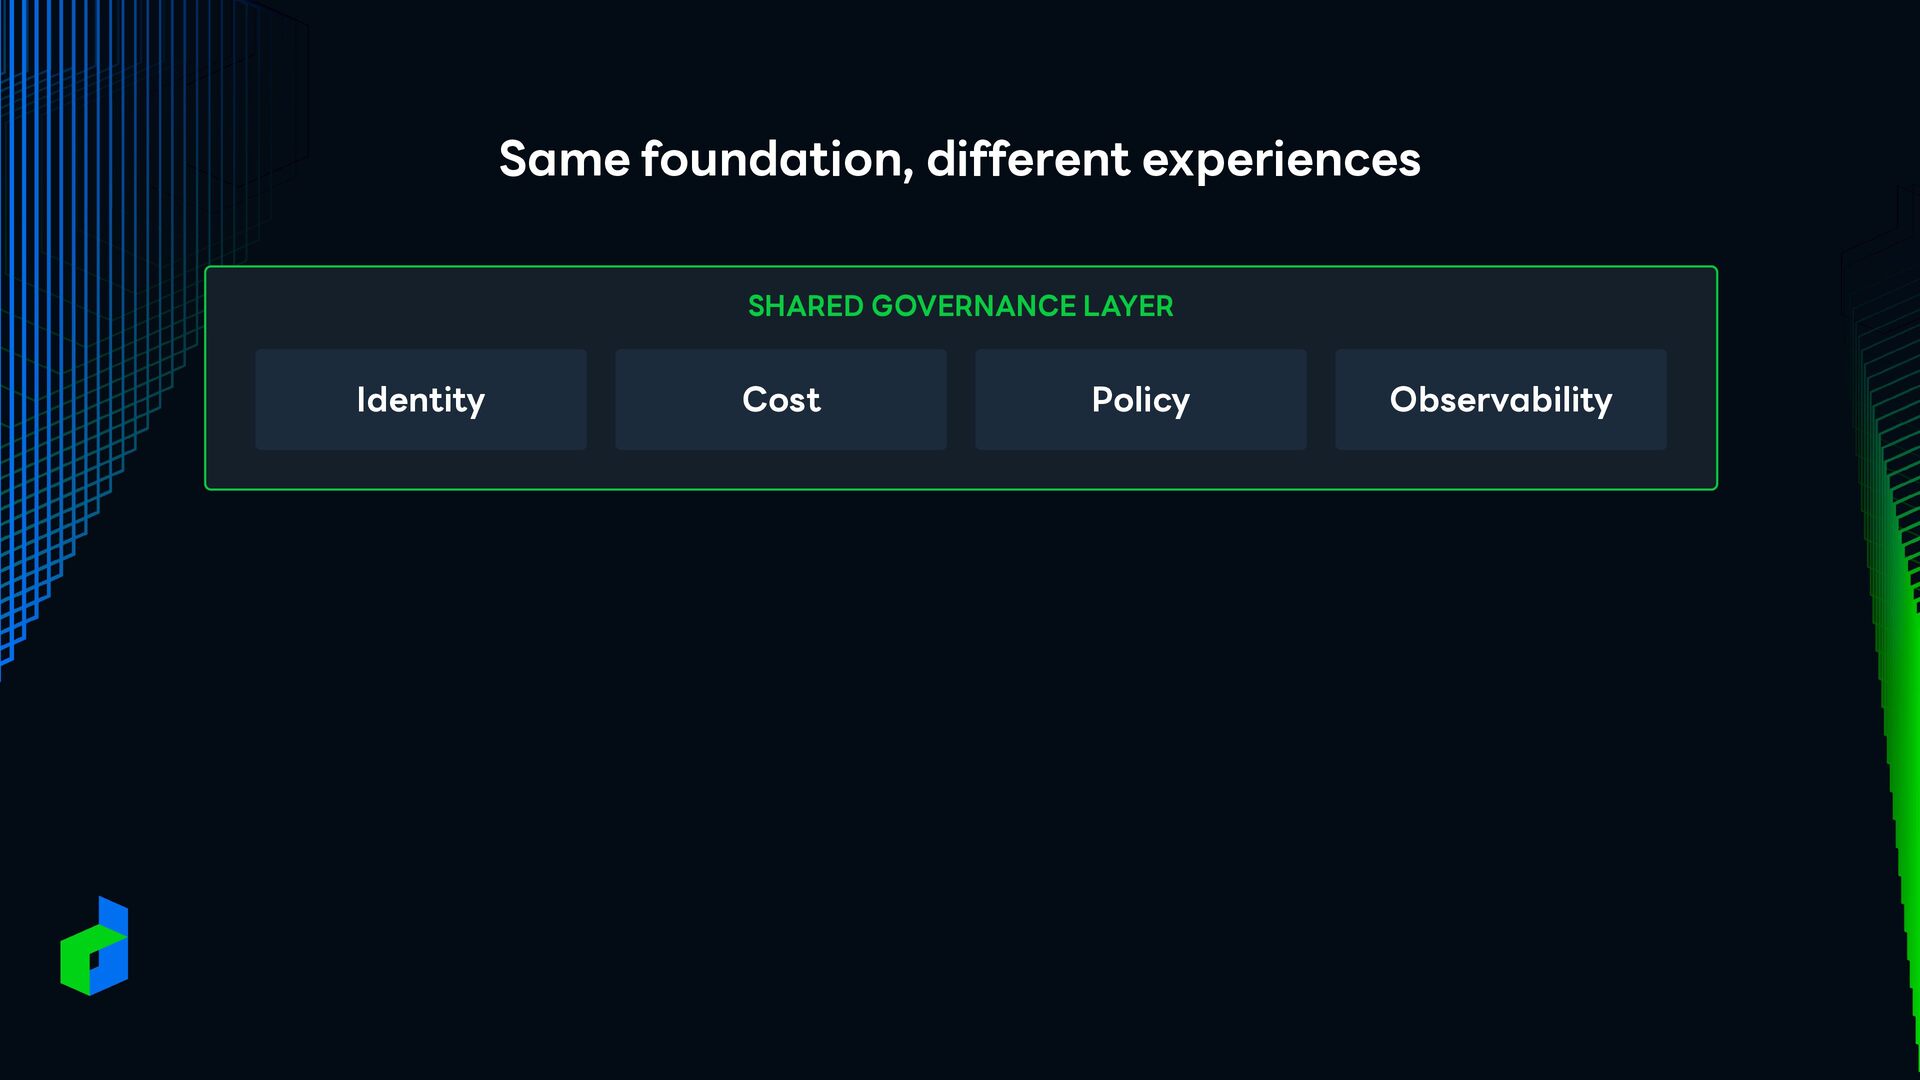
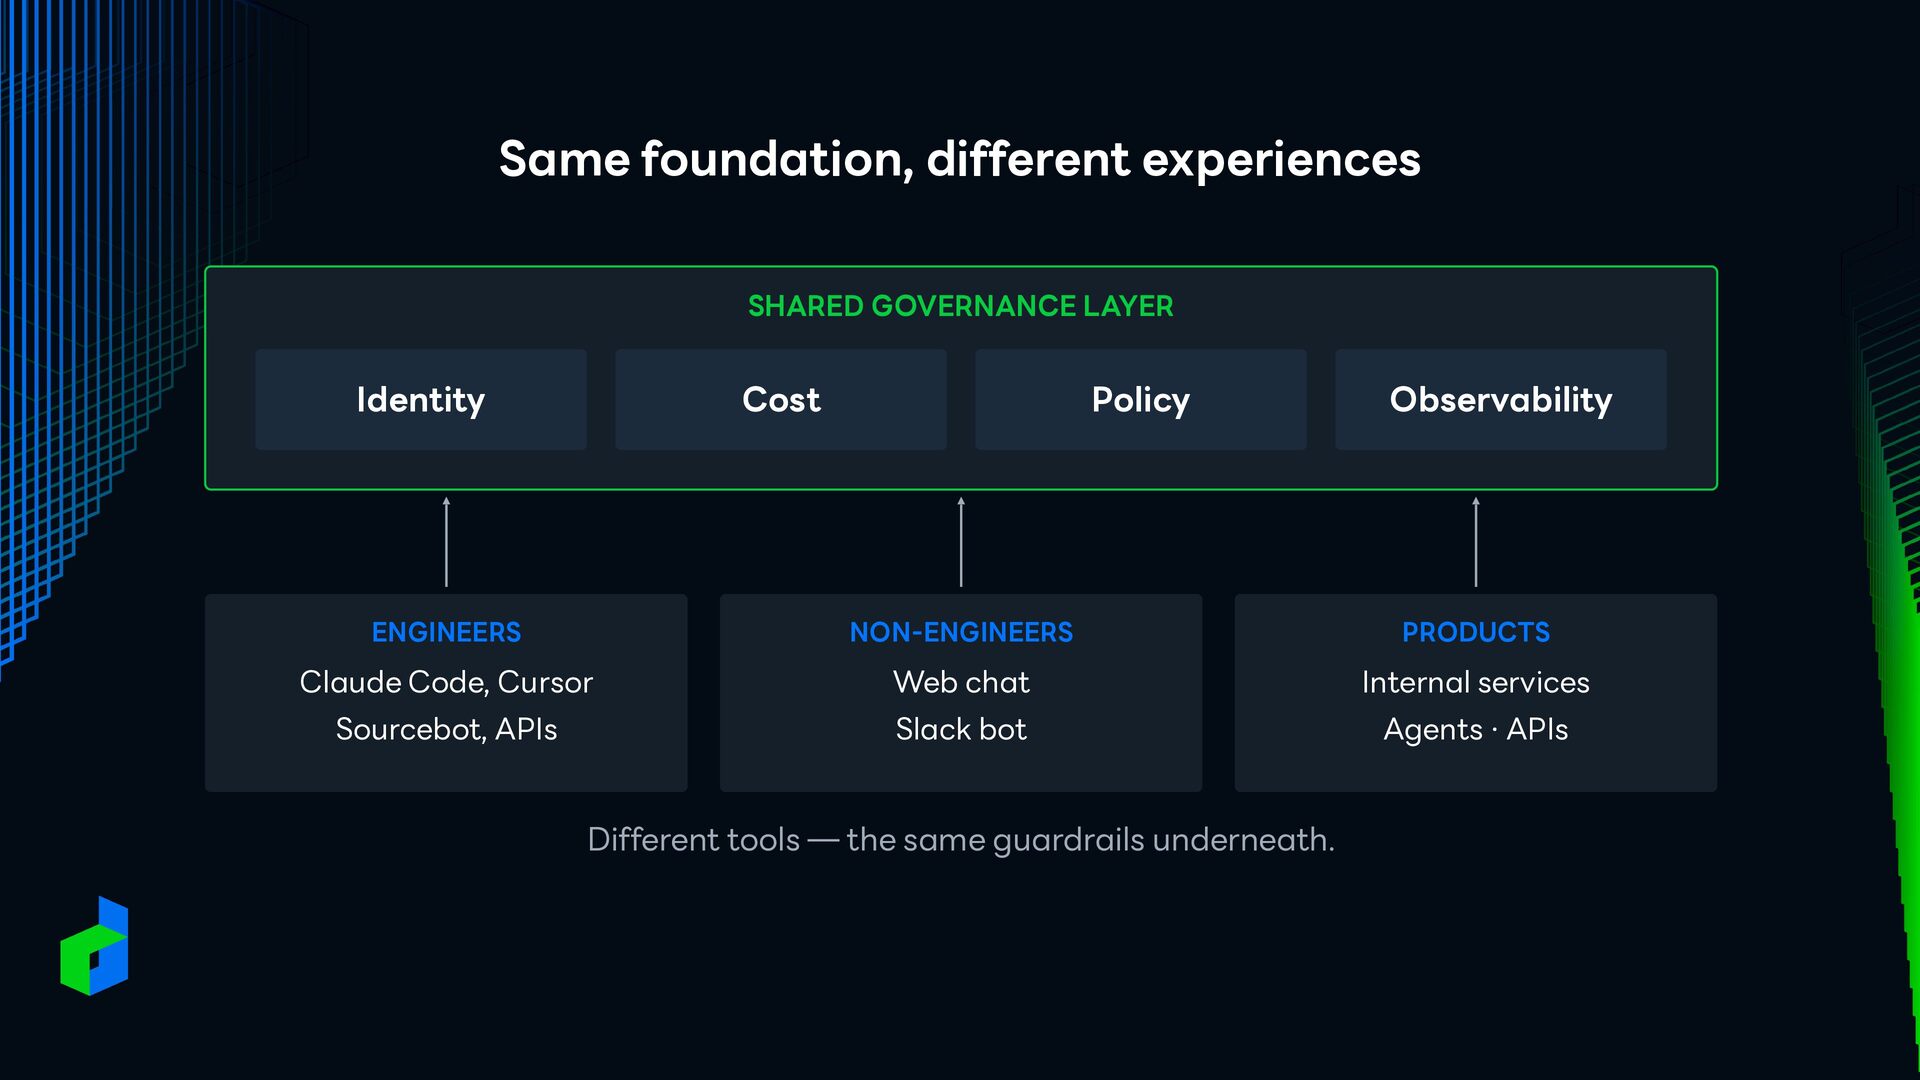
Same foundation, different experiences SHARED GOVERNANCE LAYER Identity Cost Policy
Observability ENGINEERS NON-ENGINEERS PRODUCTS Claude Code, Cursor Web chat Internal services Sourcebot, APIs Slack bot Different tools — the same guardrails underneath. Agents · APIs -
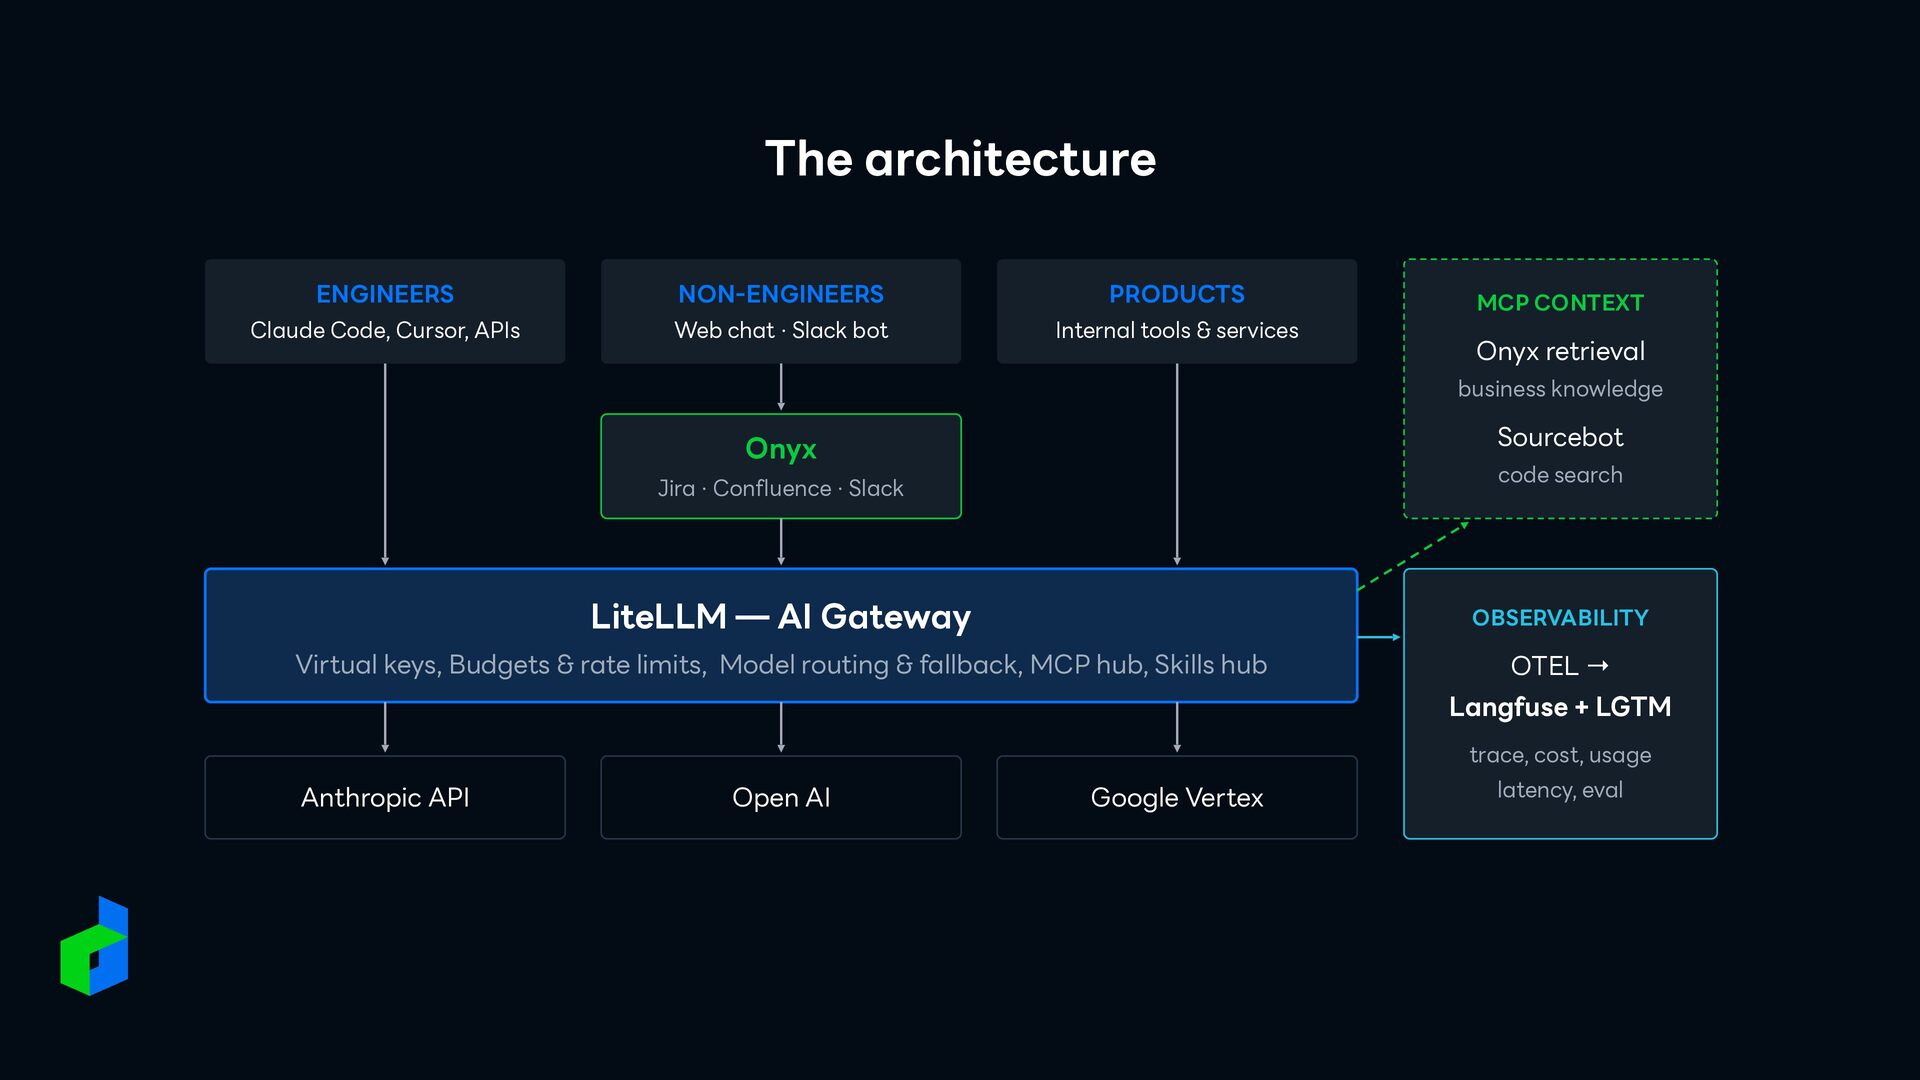
The architecture ENGINEERS NON-ENGINEERS PRODUCTS Claude Code, Cursor, APIs Web
chat · Slack bot Internal tools & services -
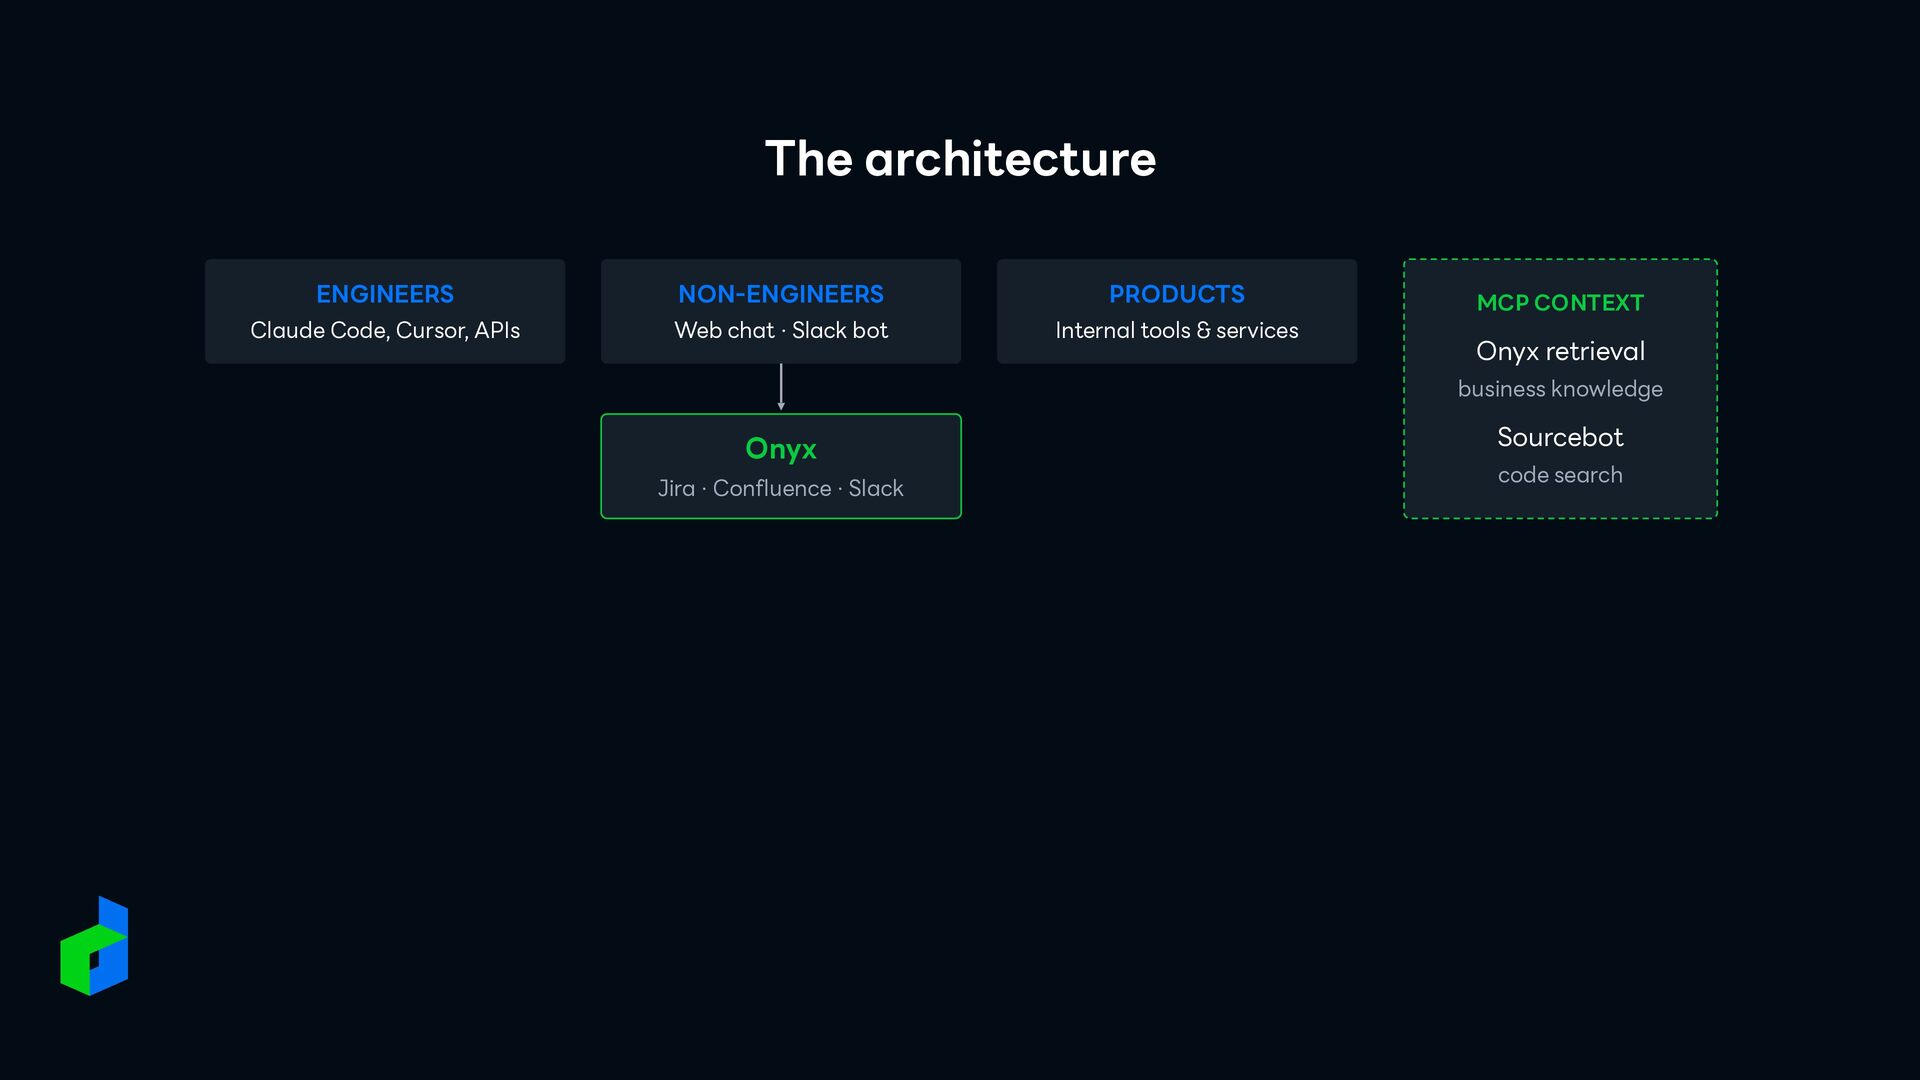
The architecture ENGINEERS NON-ENGINEERS PRODUCTS Claude Code, Cursor, APIs Web
chat · Slack bot Internal tools & services MCP CONTEXT Onyx retrieval business knowledge Onyx Jira · Confluence · Slack Sourcebot code search -
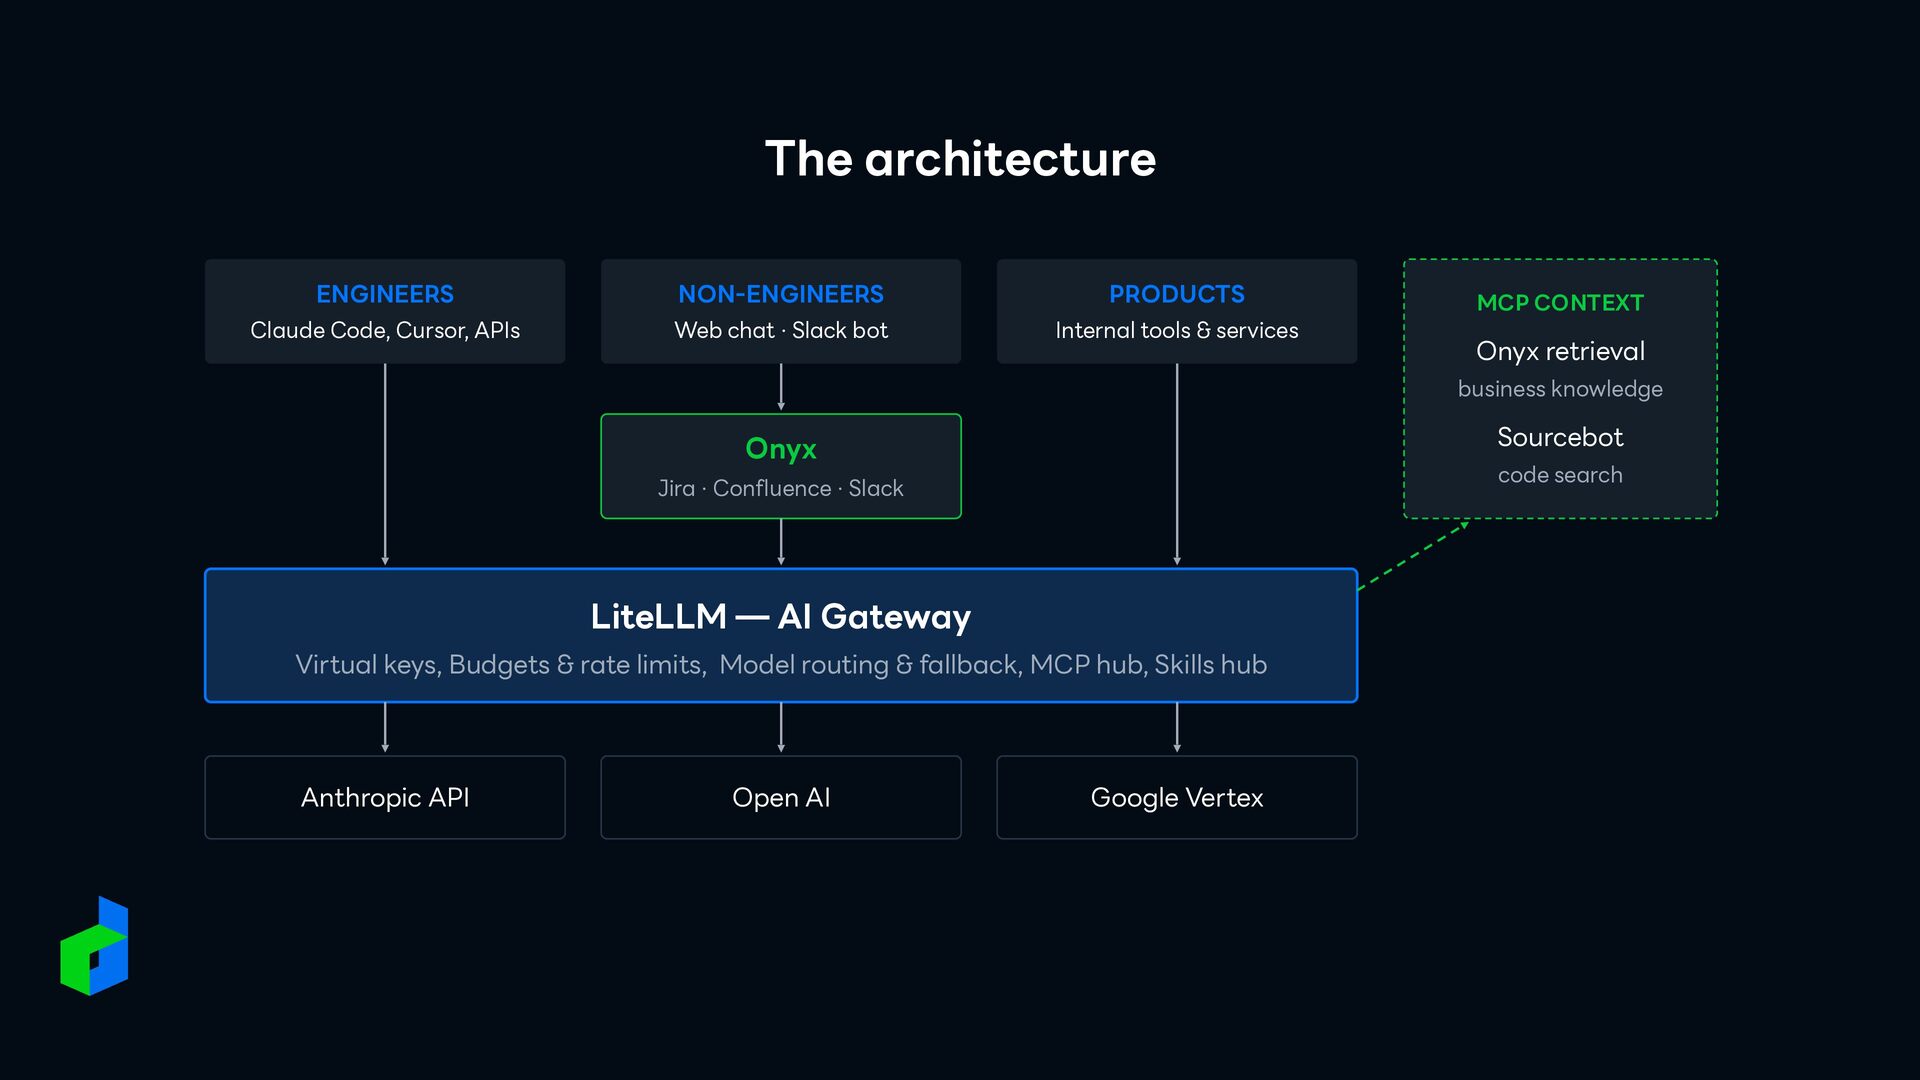
The architecture ENGINEERS NON-ENGINEERS PRODUCTS Claude Code, Cursor, APIs Web
chat · Slack bot Internal tools & services MCP CONTEXT Onyx retrieval business knowledge Sourcebot Onyx code search Jira · Confluence · Slack LiteLLM — AI Gateway Virtual keys, Budgets & rate limits, Model routing & fallback, MCP hub, Skills hub Anthropic API Open AI Google Vertex -
The architecture ENGINEERS NON-ENGINEERS PRODUCTS Claude Code, Cursor, APIs Web
chat · Slack bot Internal tools & services MCP CONTEXT Onyx retrieval business knowledge Sourcebot Onyx code search Jira · Confluence · Slack LiteLLM — AI Gateway OBSERVABILITY Virtual keys, Budgets & rate limits, Model routing & fallback, MCP hub, Skills hub OTEL → Langfuse + LGTM trace, cost, usage Anthropic API Open AI Google Vertex latency, eval -
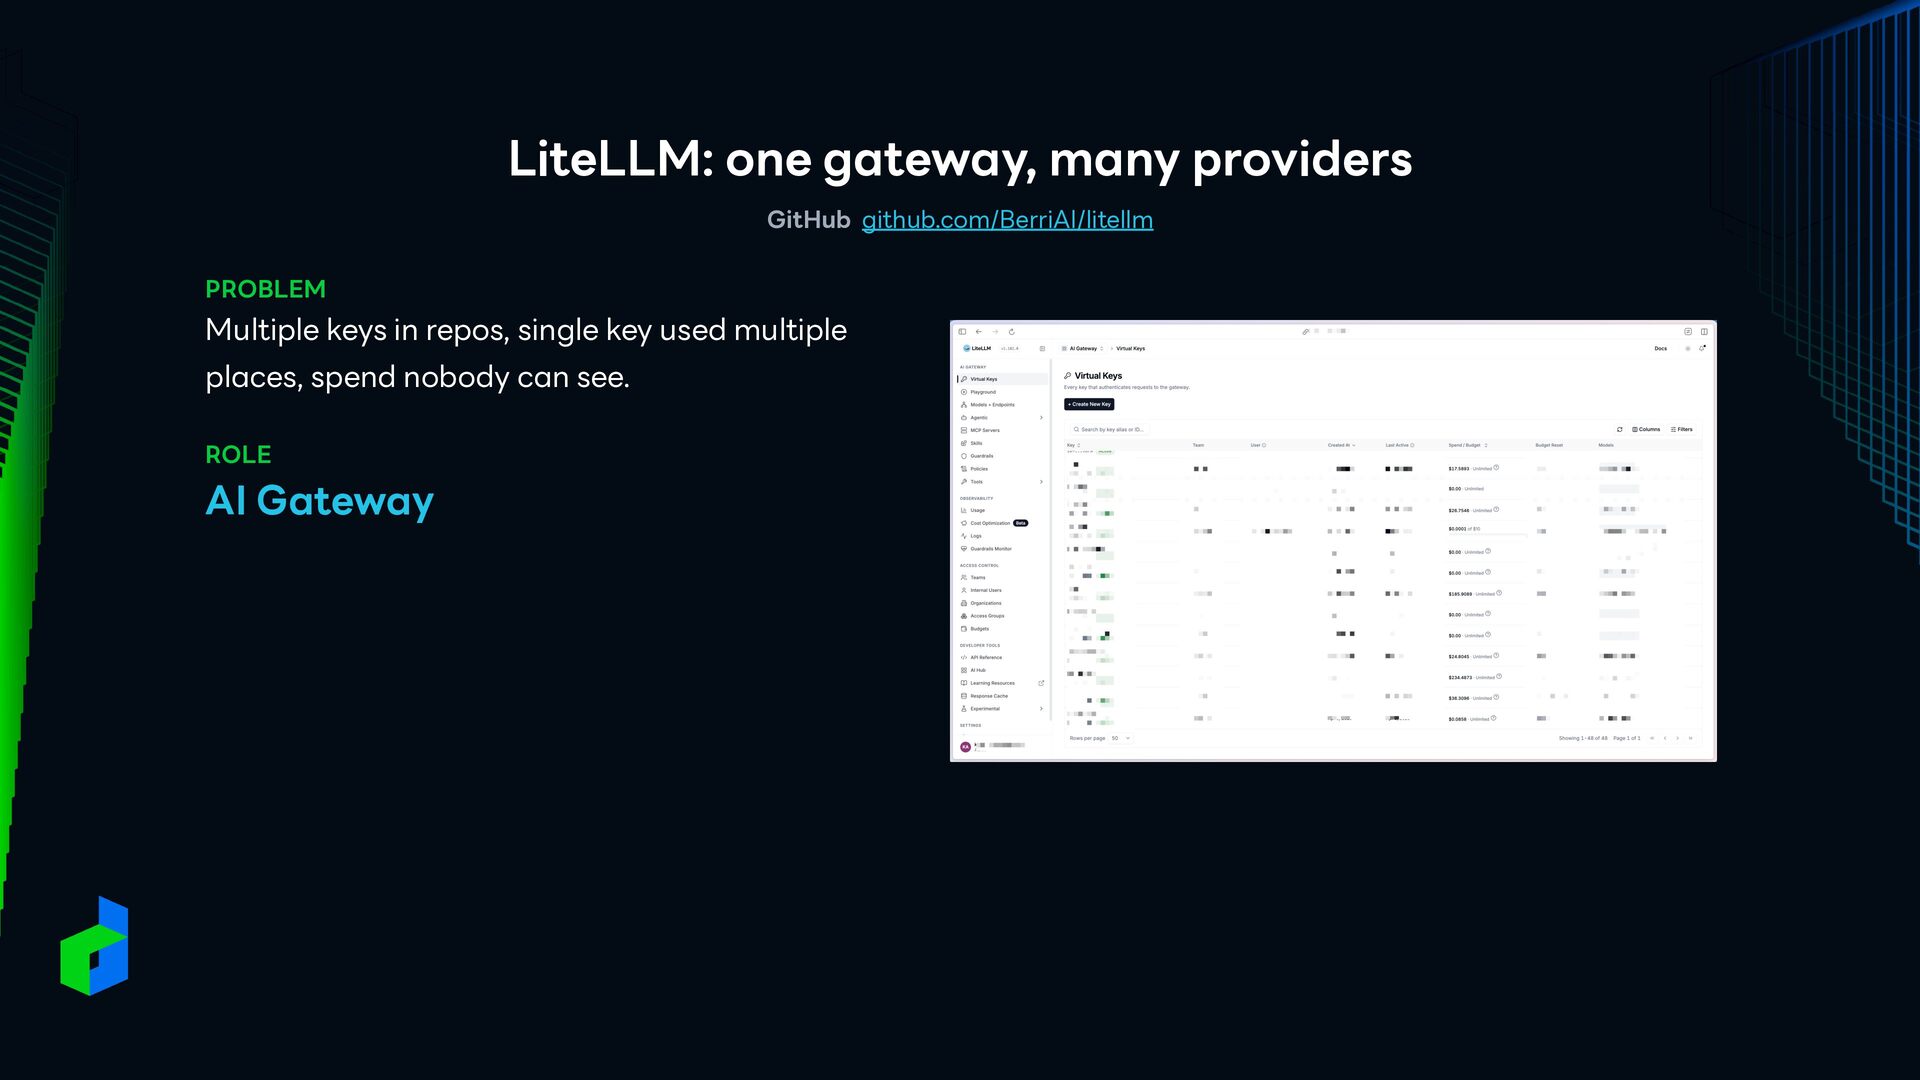
LiteLLM: one gateway, many providers GitHub github.com/BerriAI/litellm PROBLEM Multiple keys
in repos, single key used multiple places, spend nobody can see. ROLE AI Gateway -
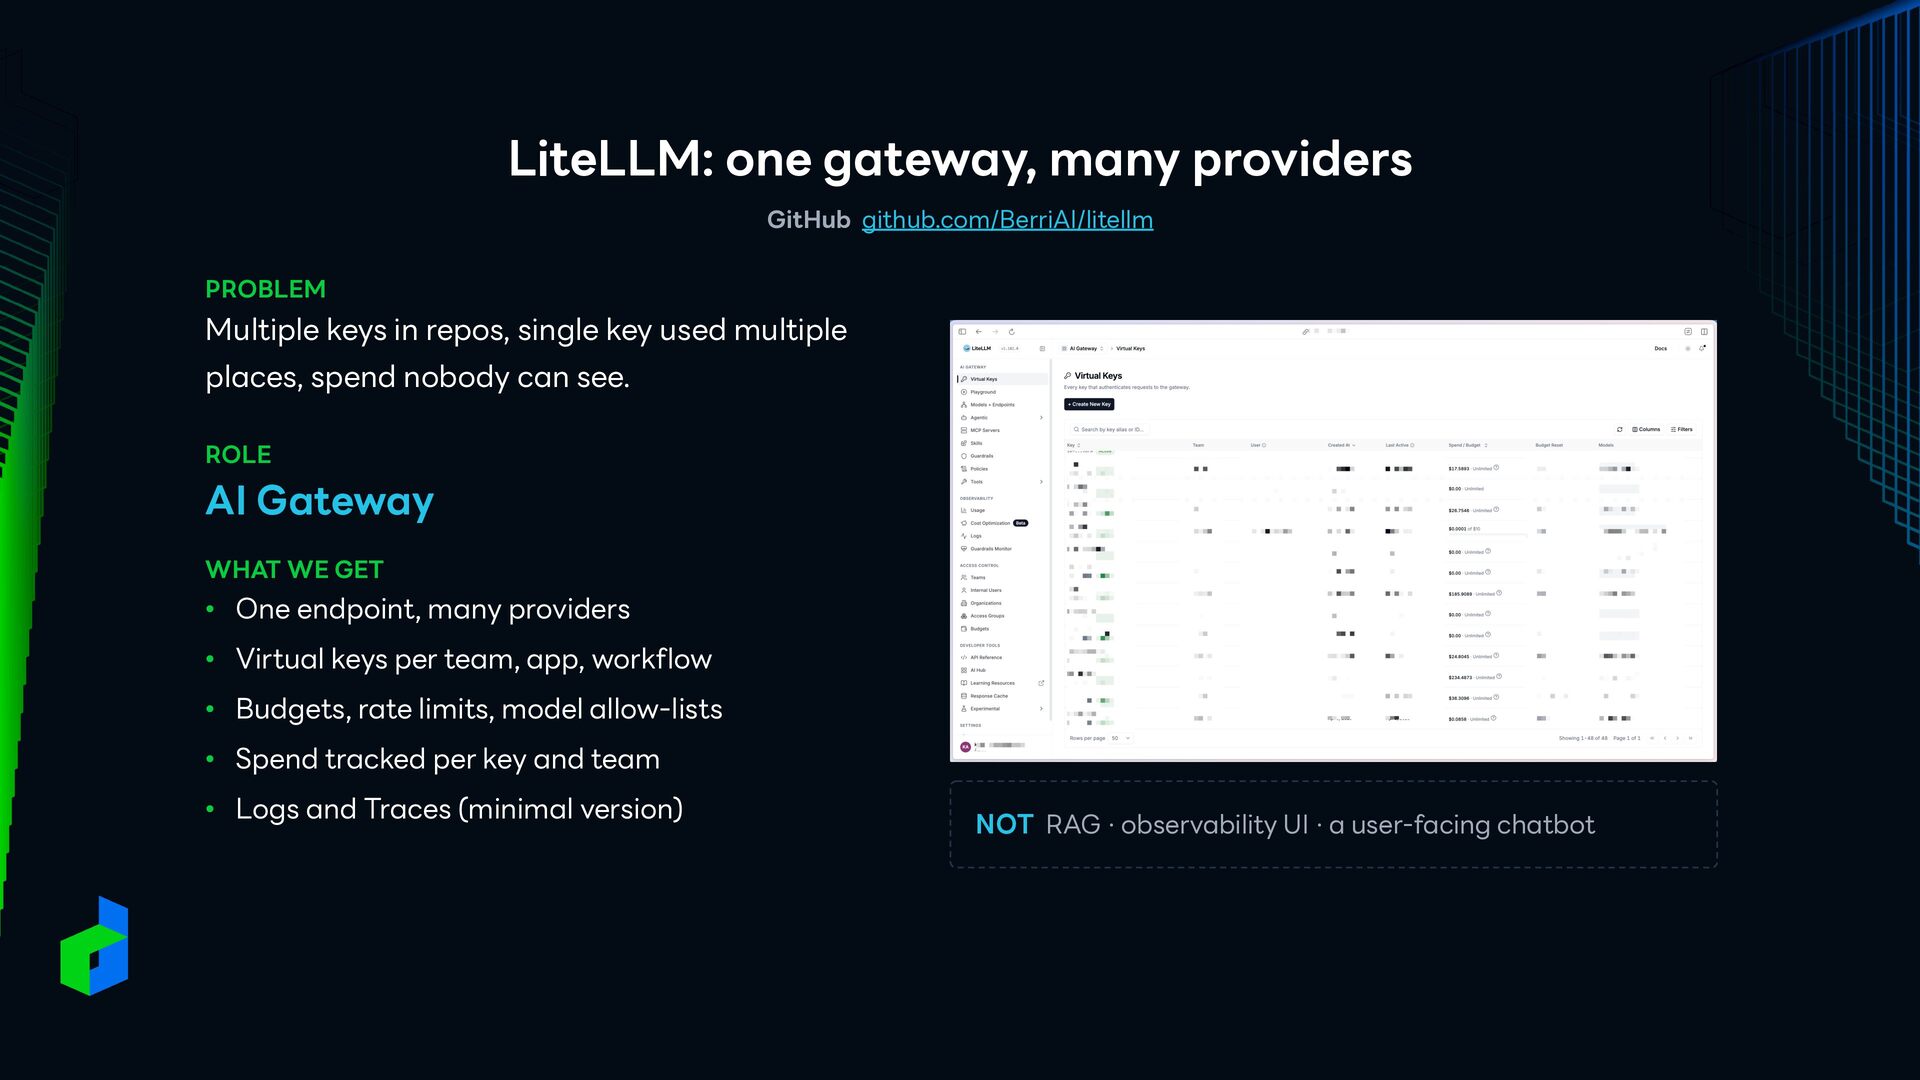
LiteLLM: one gateway, many providers GitHub github.com/BerriAI/litellm PROBLEM Multiple keys
in repos, single key used multiple places, spend nobody can see. ROLE AI Gateway WHAT WE GET • One endpoint, many providers • Virtual keys per team, app, workflow • Budgets, rate limits, model allow-lists • Spend tracked per key and team • Logs and Traces (minimal version) NOT RAG · observability UI · a user-facing chatbot -
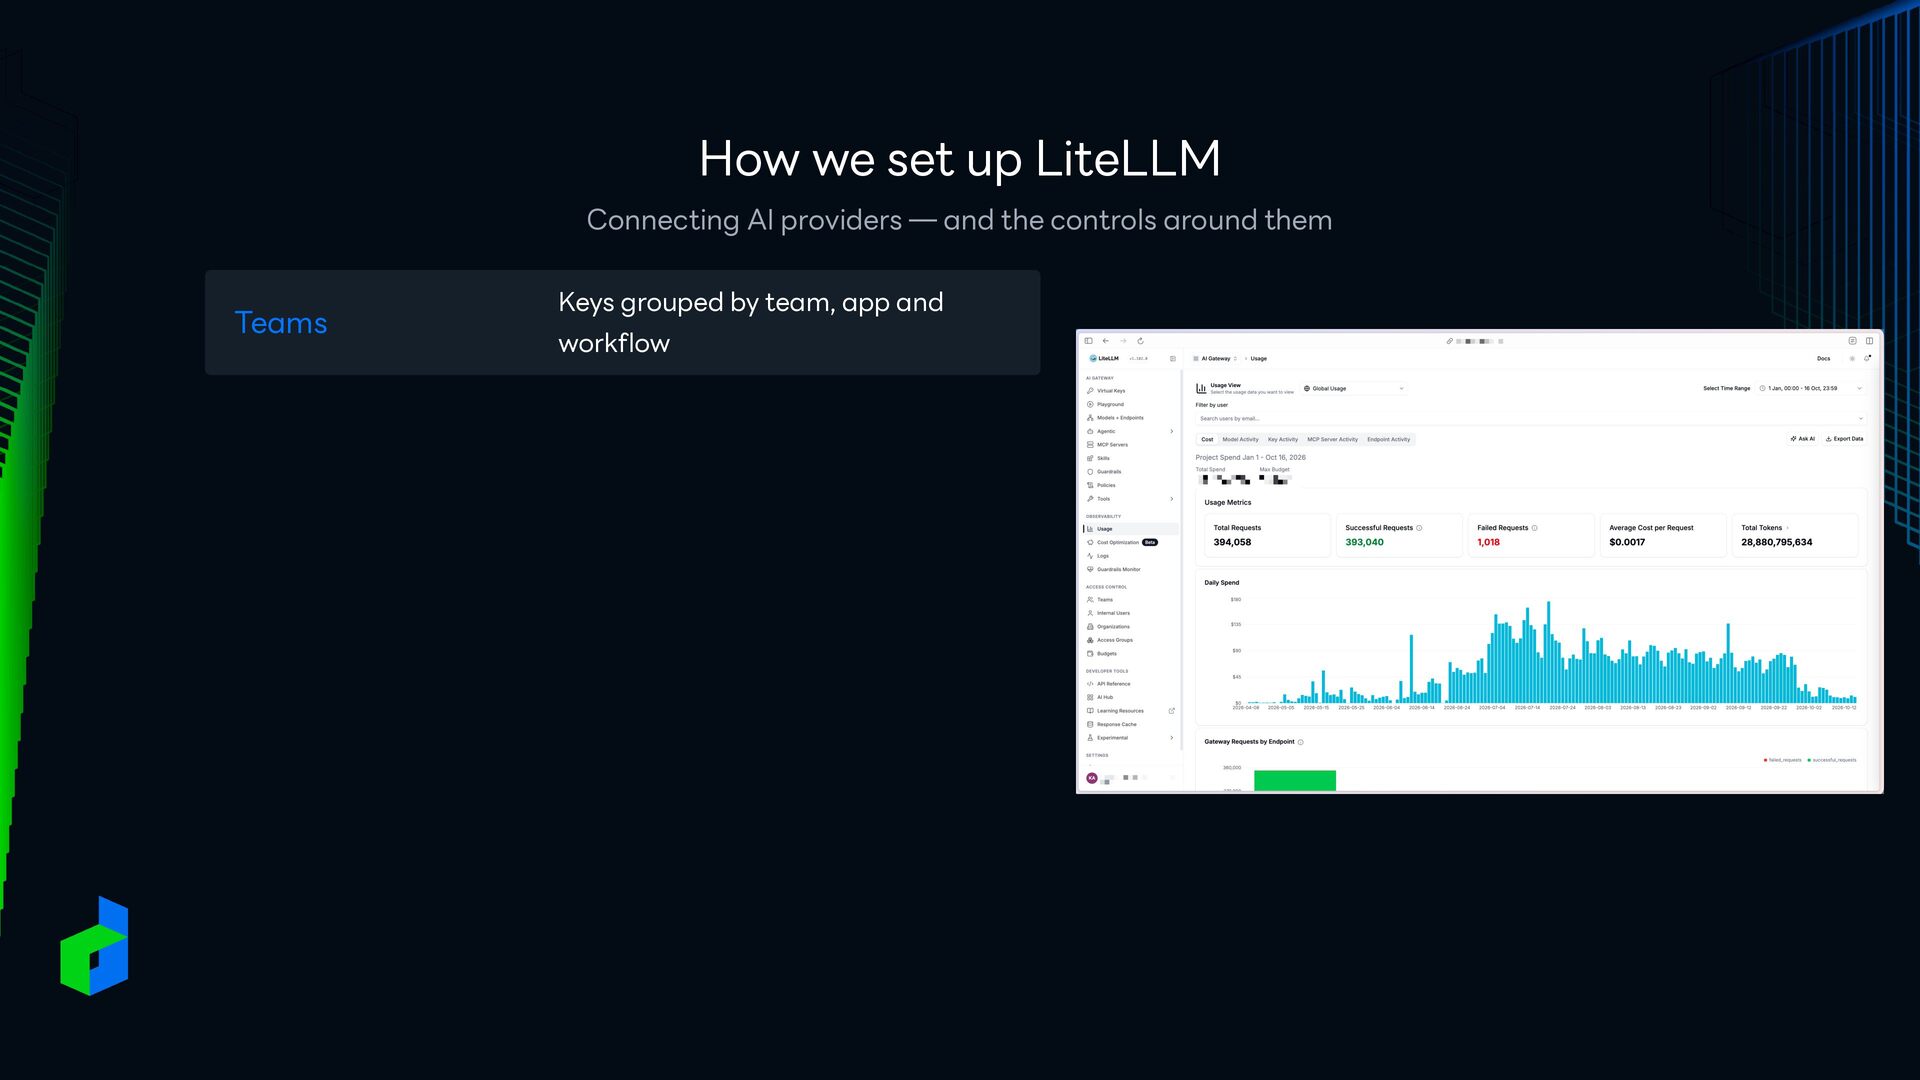
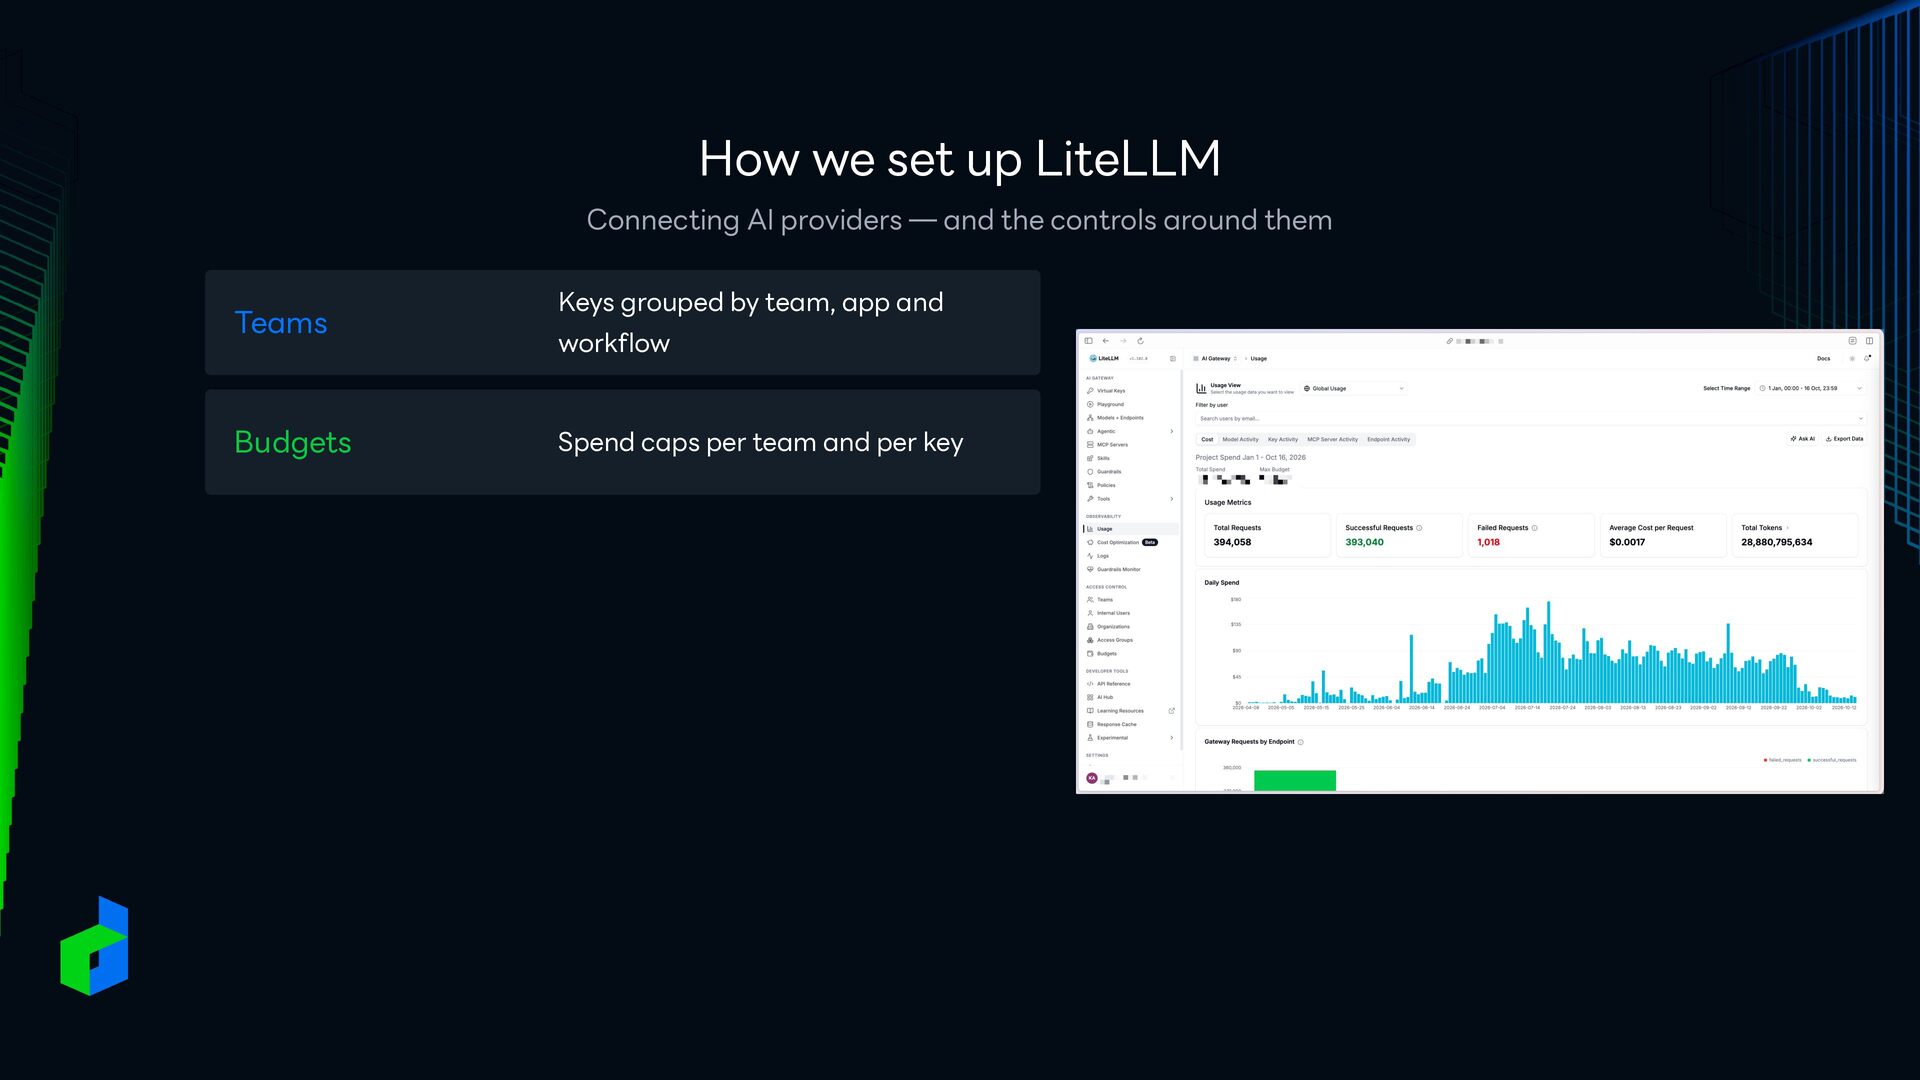
How we set up LiteLLM Connecting AI providers — and
the controls around them Teams Keys grouped by team, app and workflow -
How we set up LiteLLM Connecting AI providers — and
the controls around them Teams Budgets Keys grouped by team, app and workflow Spend caps per team and per key -
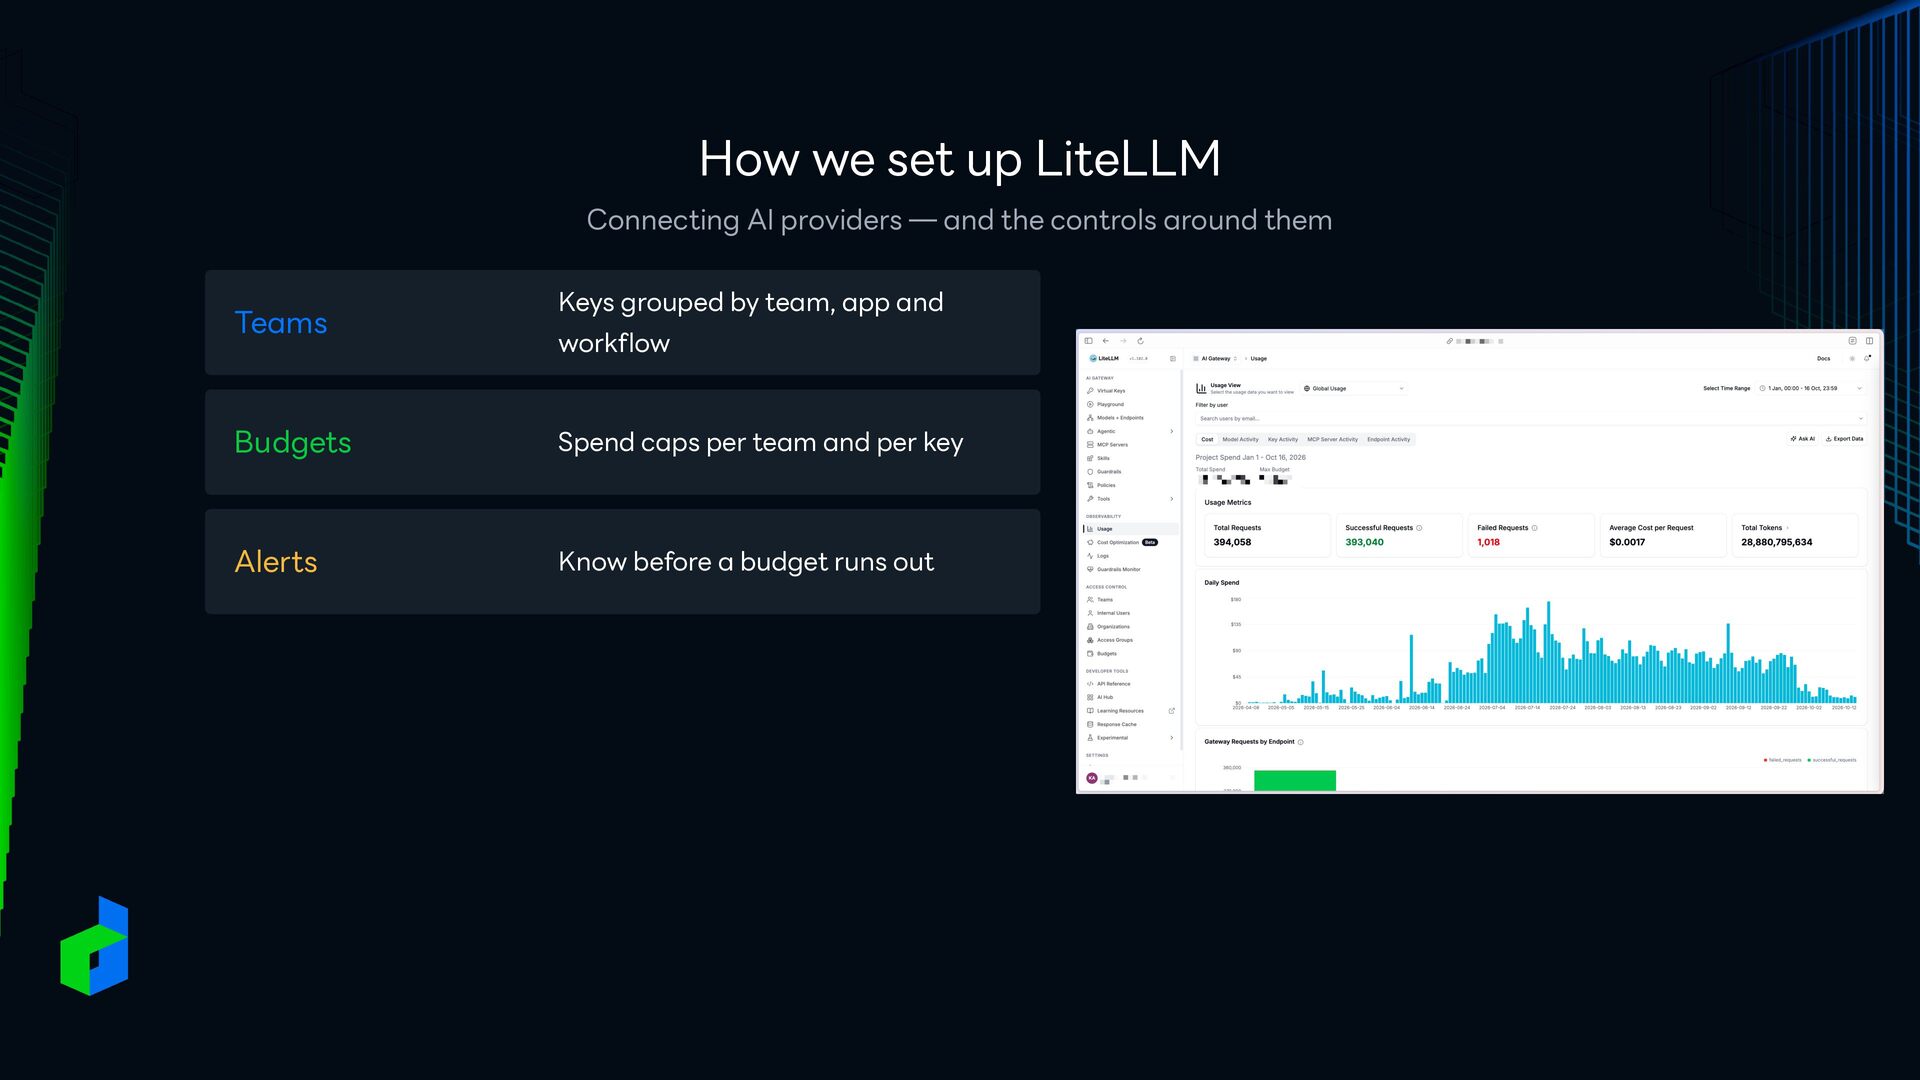
How we set up LiteLLM Connecting AI providers — and
the controls around them Teams Keys grouped by team, app and workflow Budgets Spend caps per team and per key Alerts Know before a budget runs out -
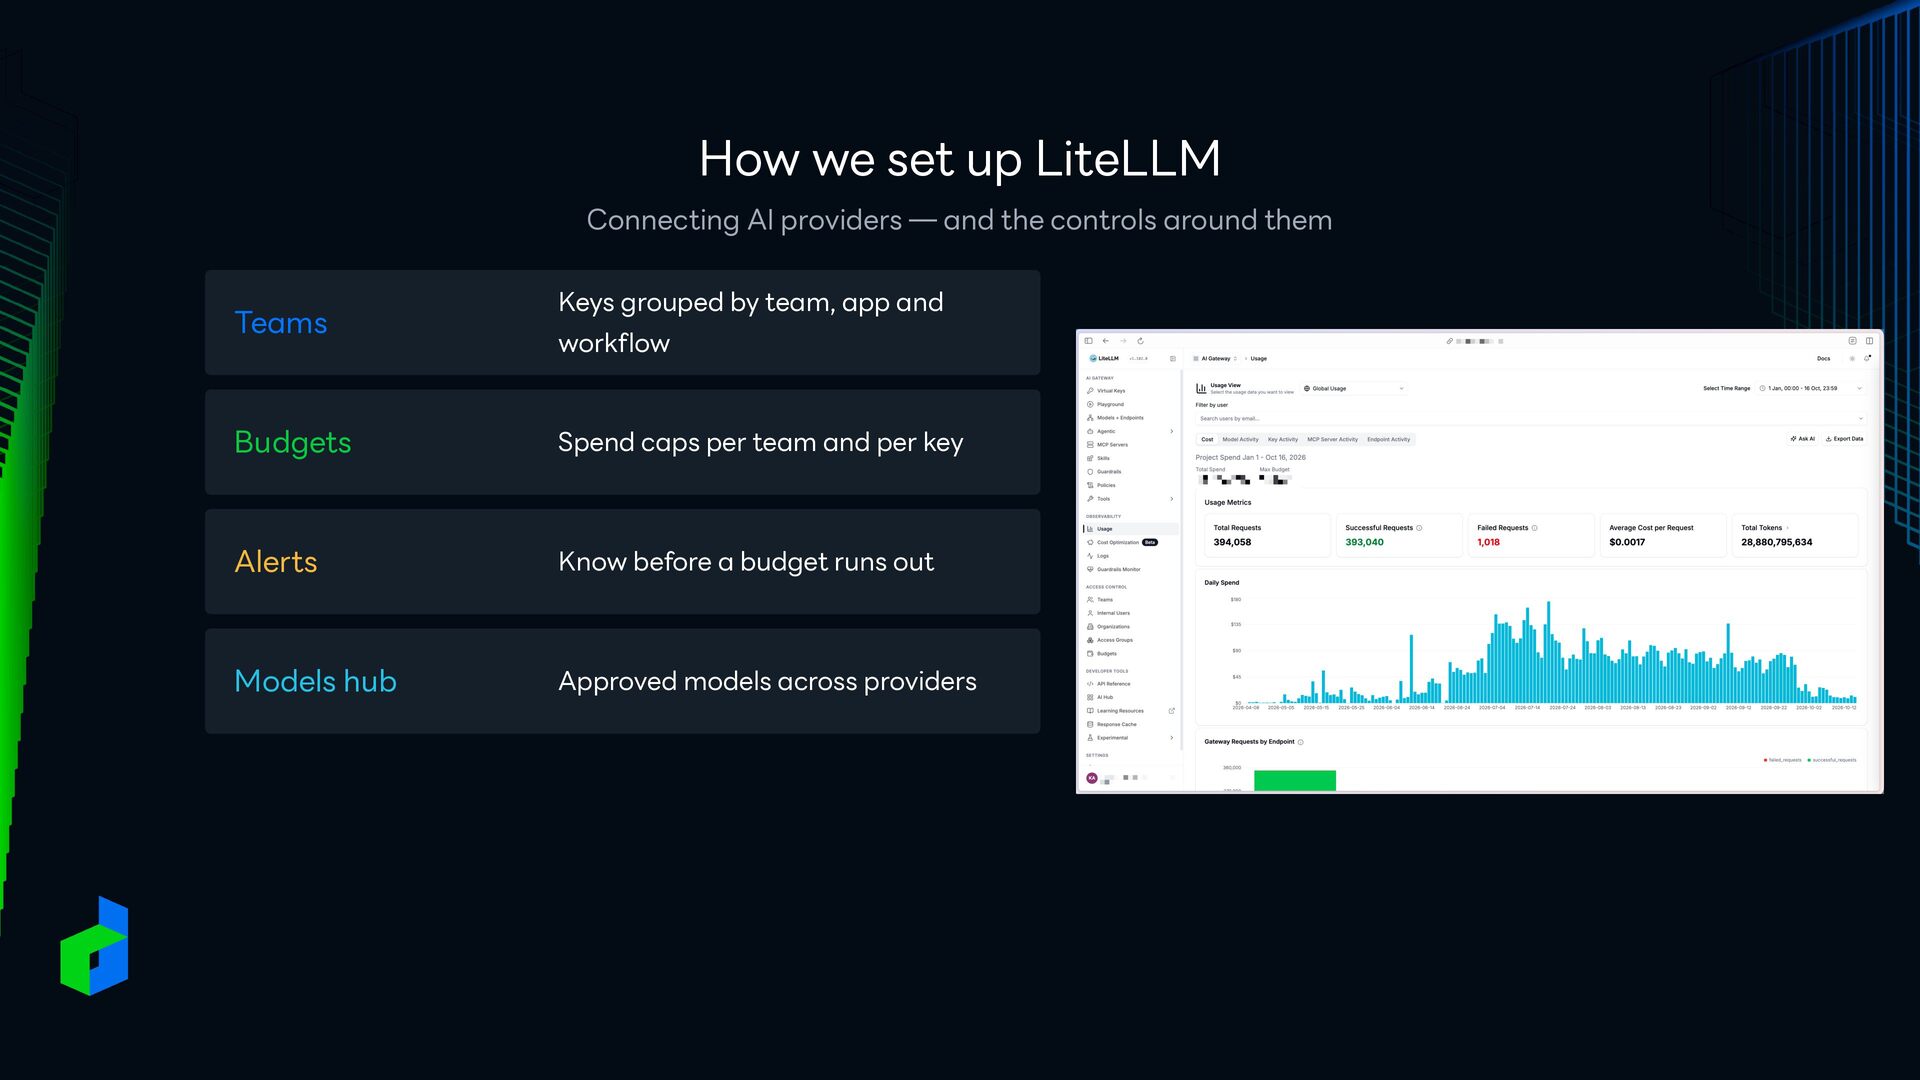
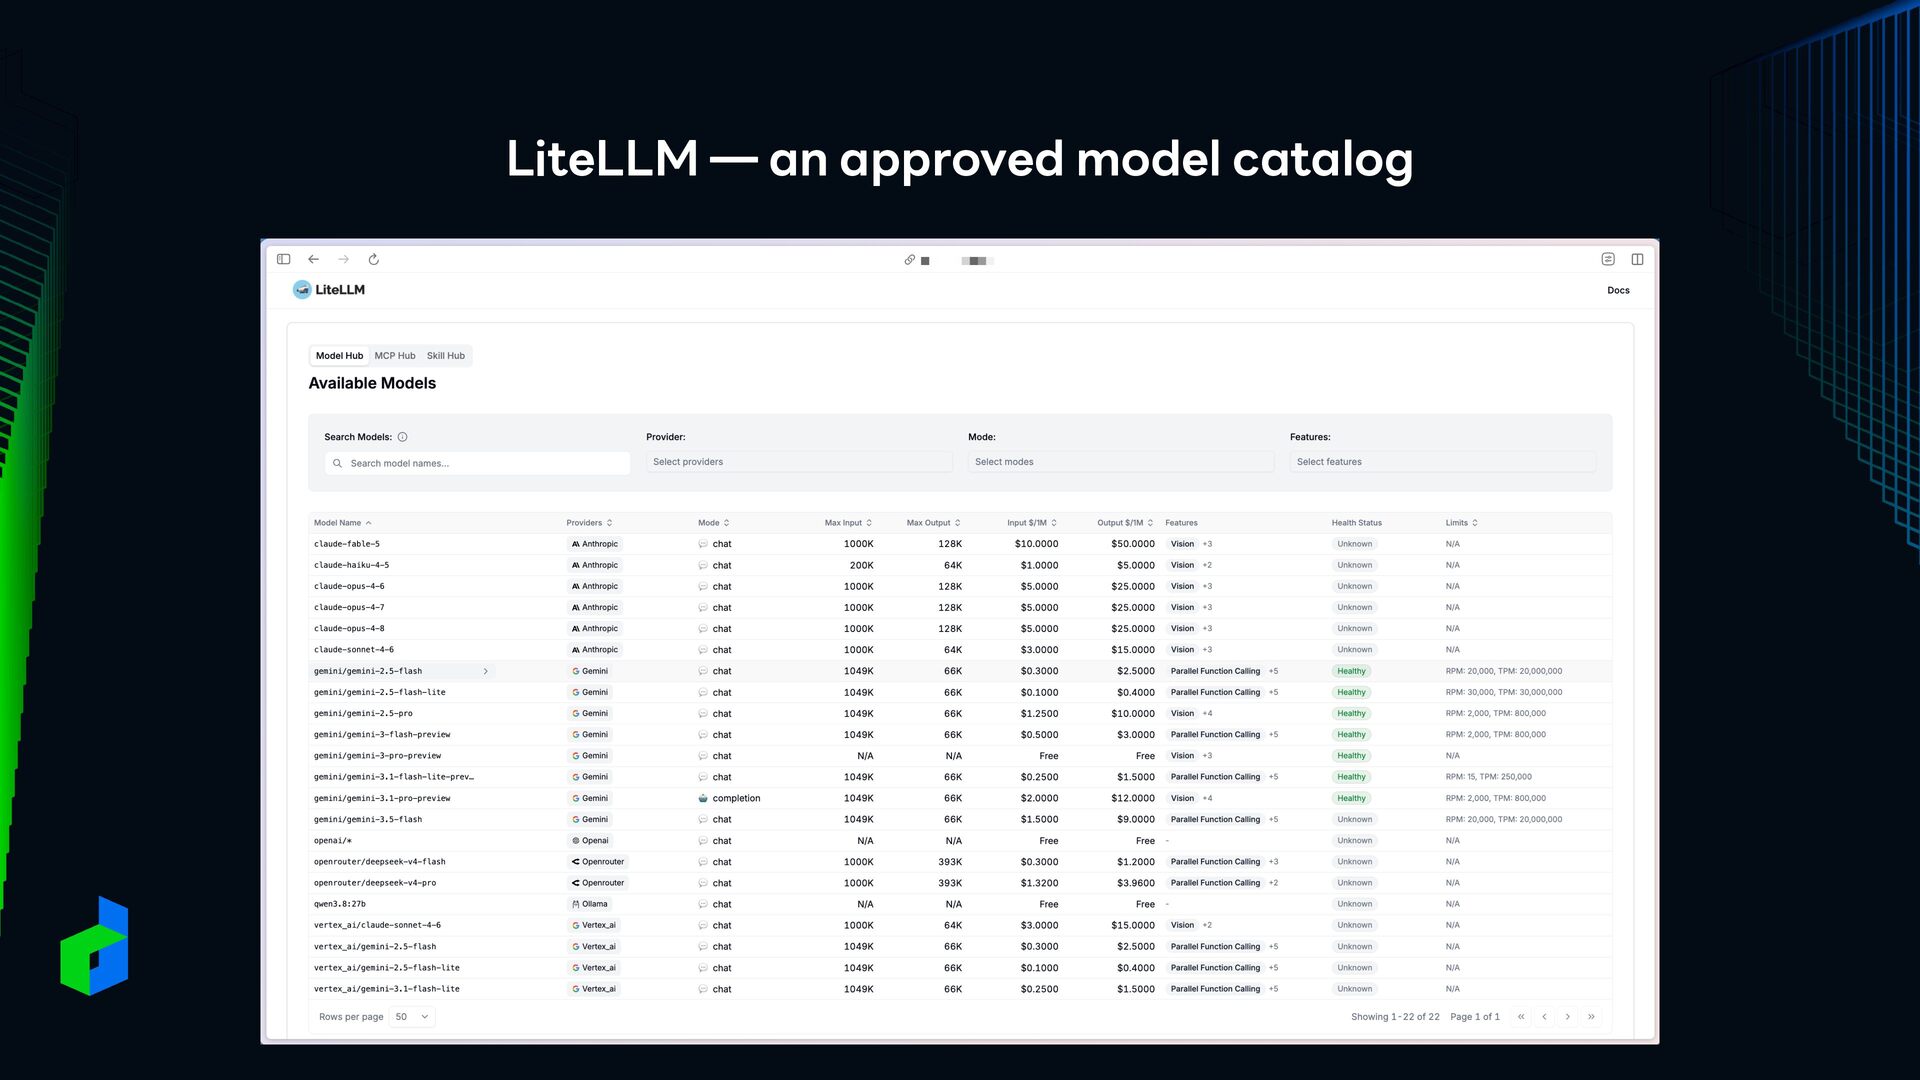
How we set up LiteLLM Connecting AI providers — and
the controls around them Teams Keys grouped by team, app and workflow Budgets Spend caps per team and per key Alerts Know before a budget runs out Models hub Approved models across providers -
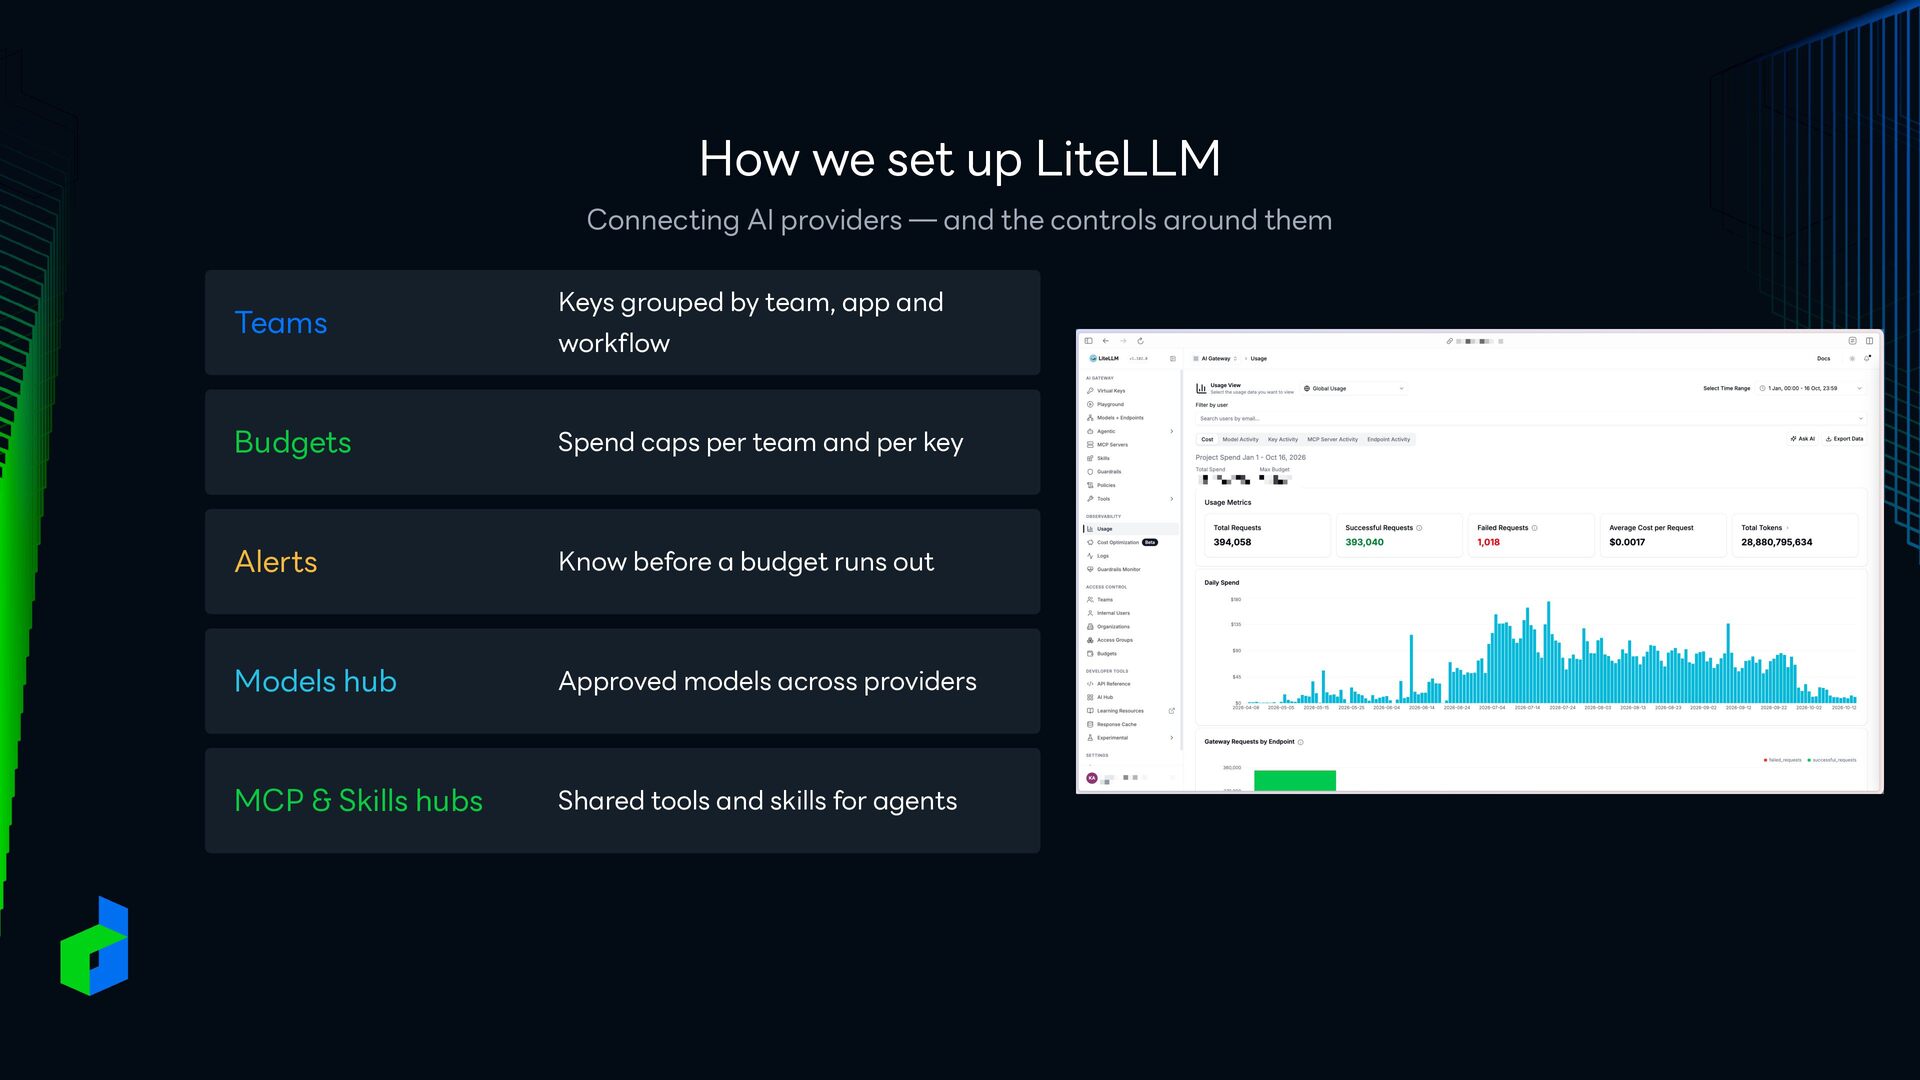
How we set up LiteLLM Connecting AI providers — and
the controls around them Teams Keys grouped by team, app and workflow Budgets Spend caps per team and per key Alerts Know before a budget runs out Models hub Approved models across providers MCP & Skills hubs Shared tools and skills for agents -
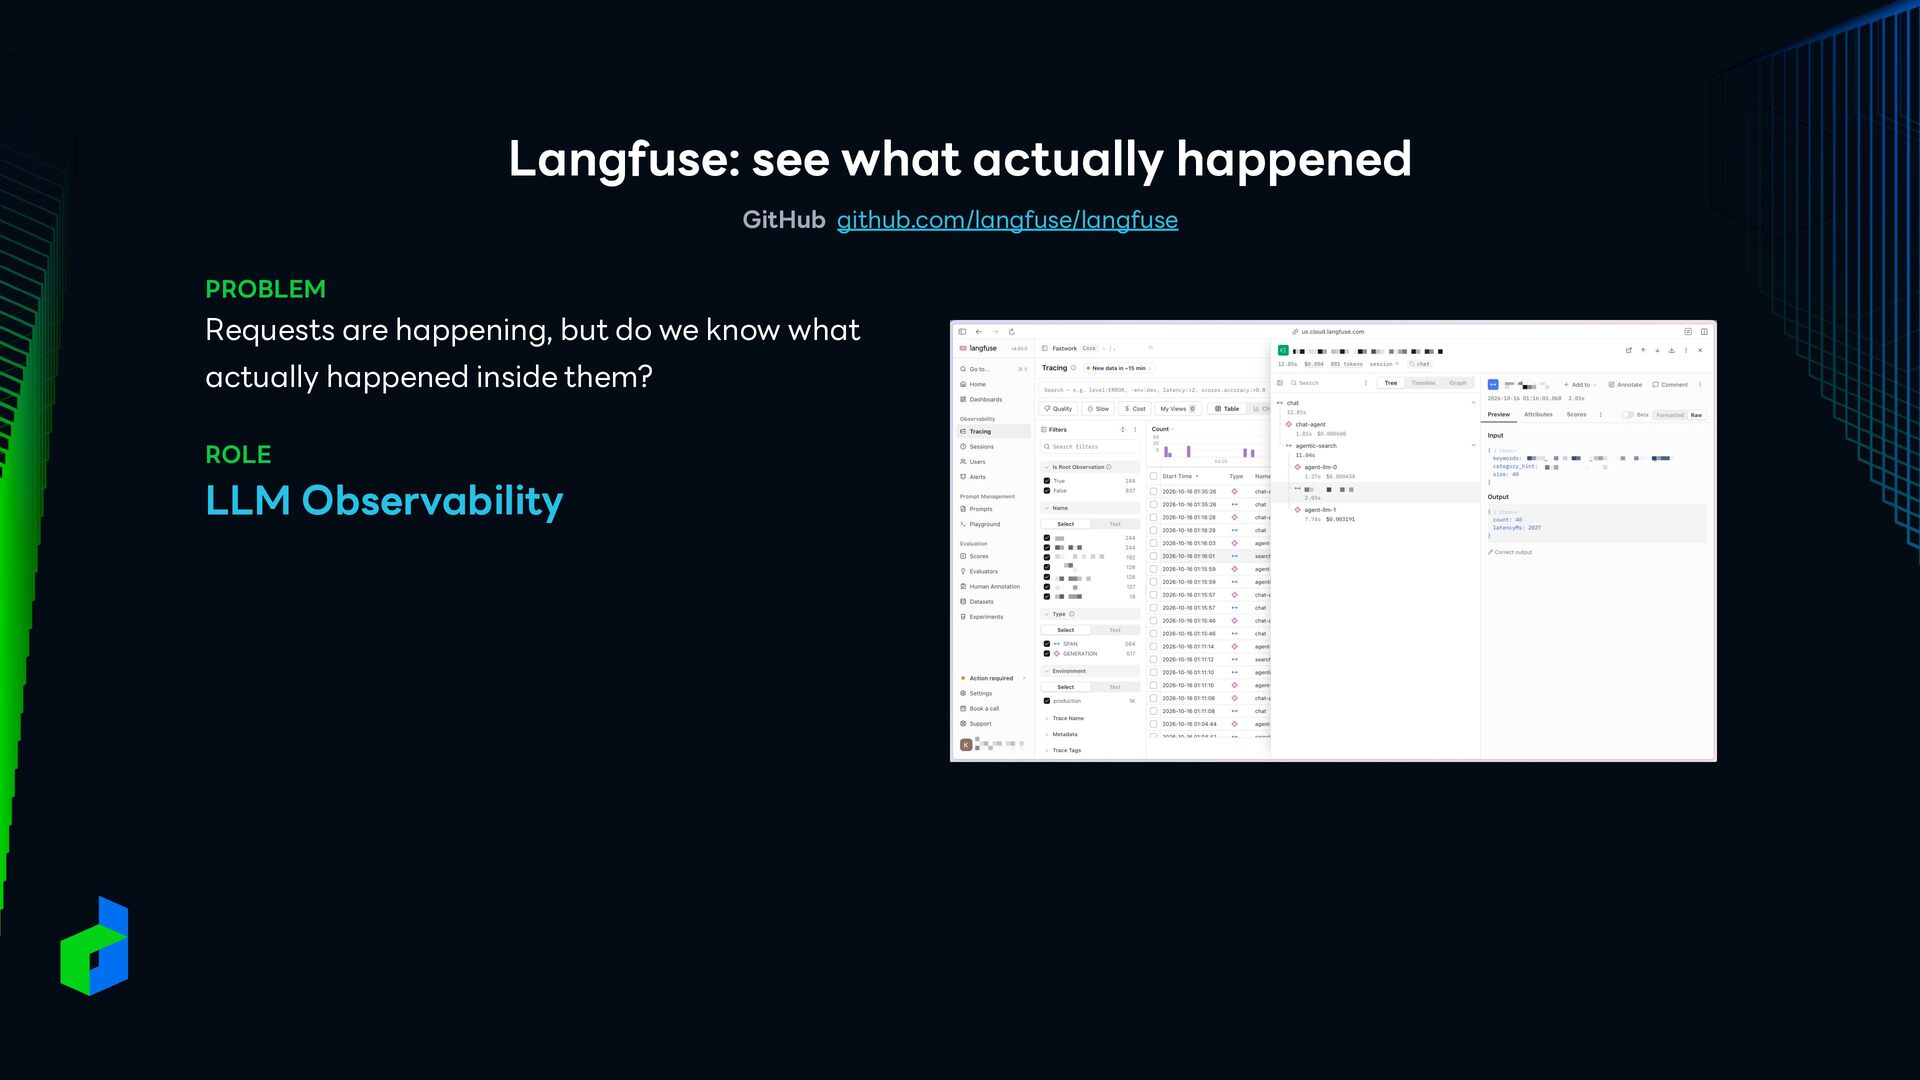
Langfuse: see what actually happened GitHub github.com/langfuse/langfuse PROBLEM Requests are
happening, but do we know what actually happened inside them? ROLE LLM Observability -
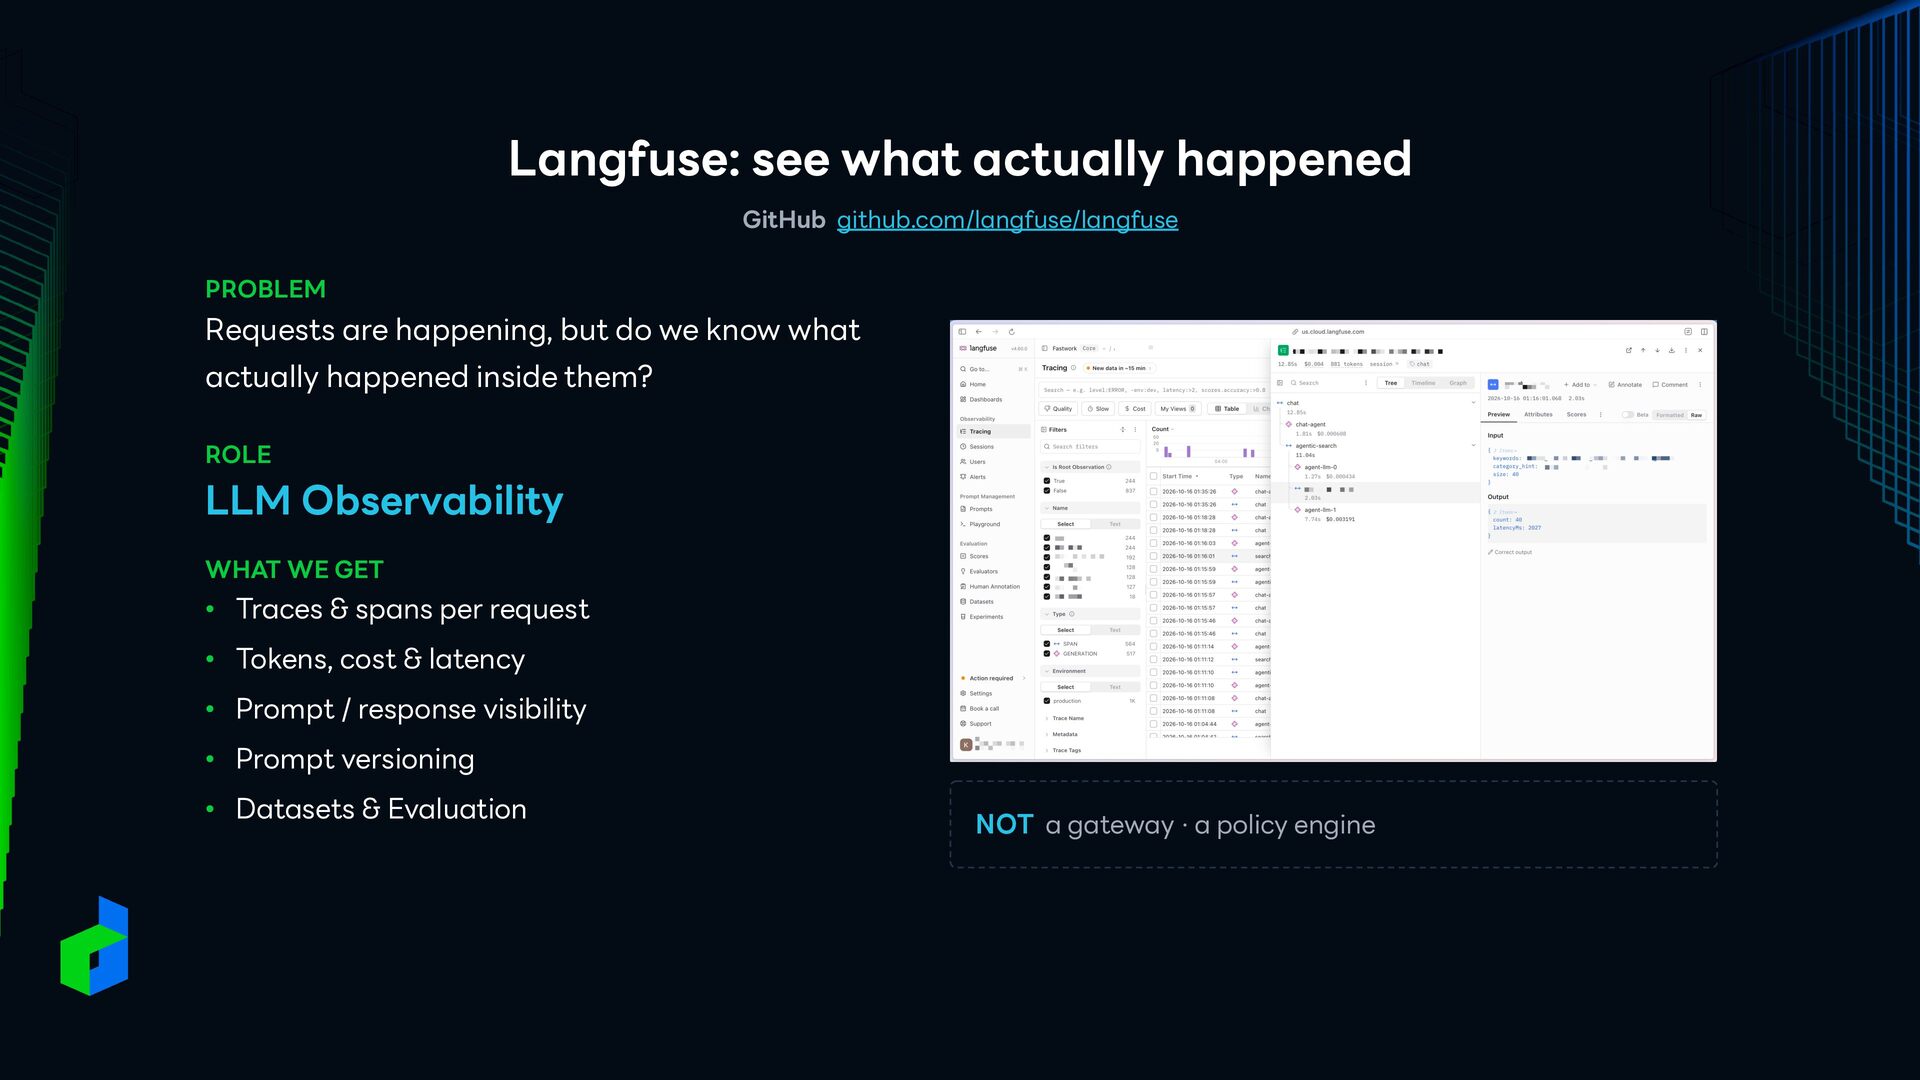
Langfuse: see what actually happened GitHub github.com/langfuse/langfuse PROBLEM Requests are
happening, but do we know what actually happened inside them? ROLE LLM Observability WHAT WE GET • Traces & spans per request • Tokens, cost & latency • Prompt / response visibility • Prompt versioning • Datasets & Evaluation NOT a gateway · a policy engine -
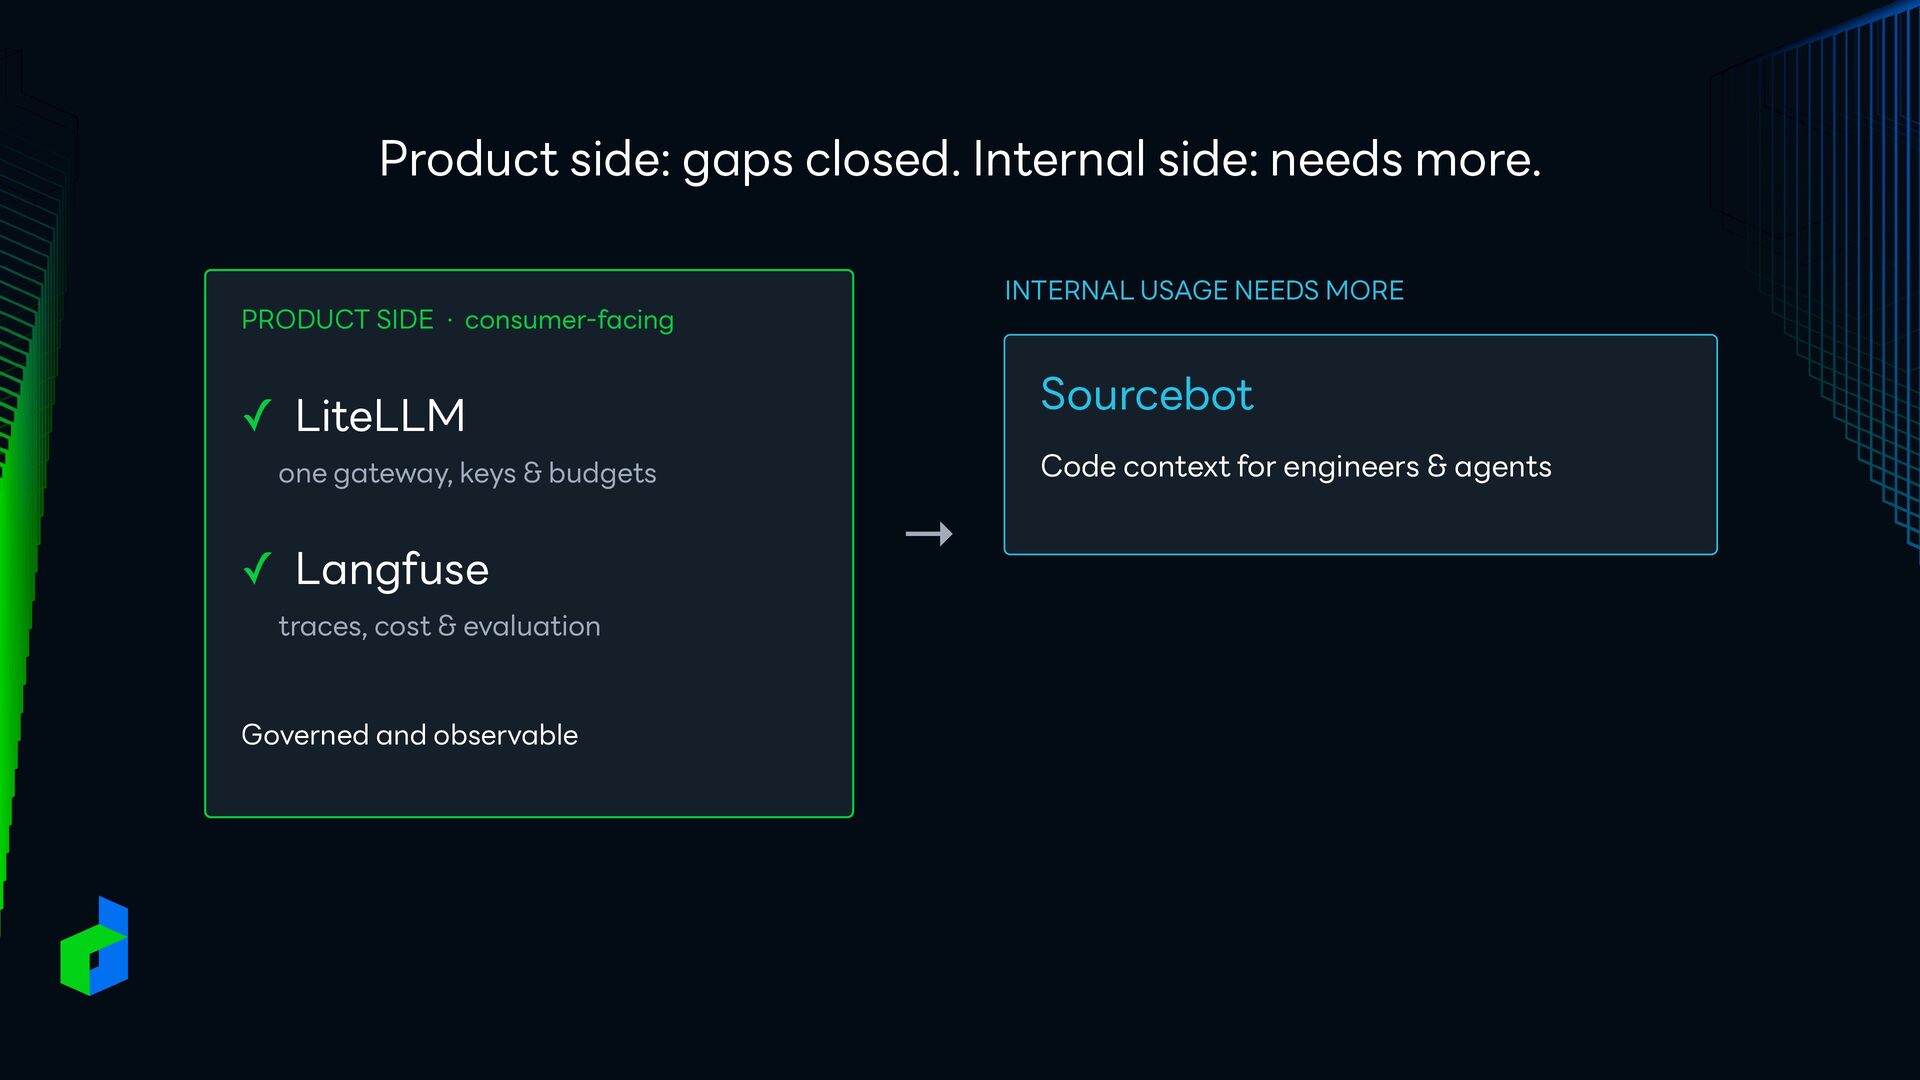
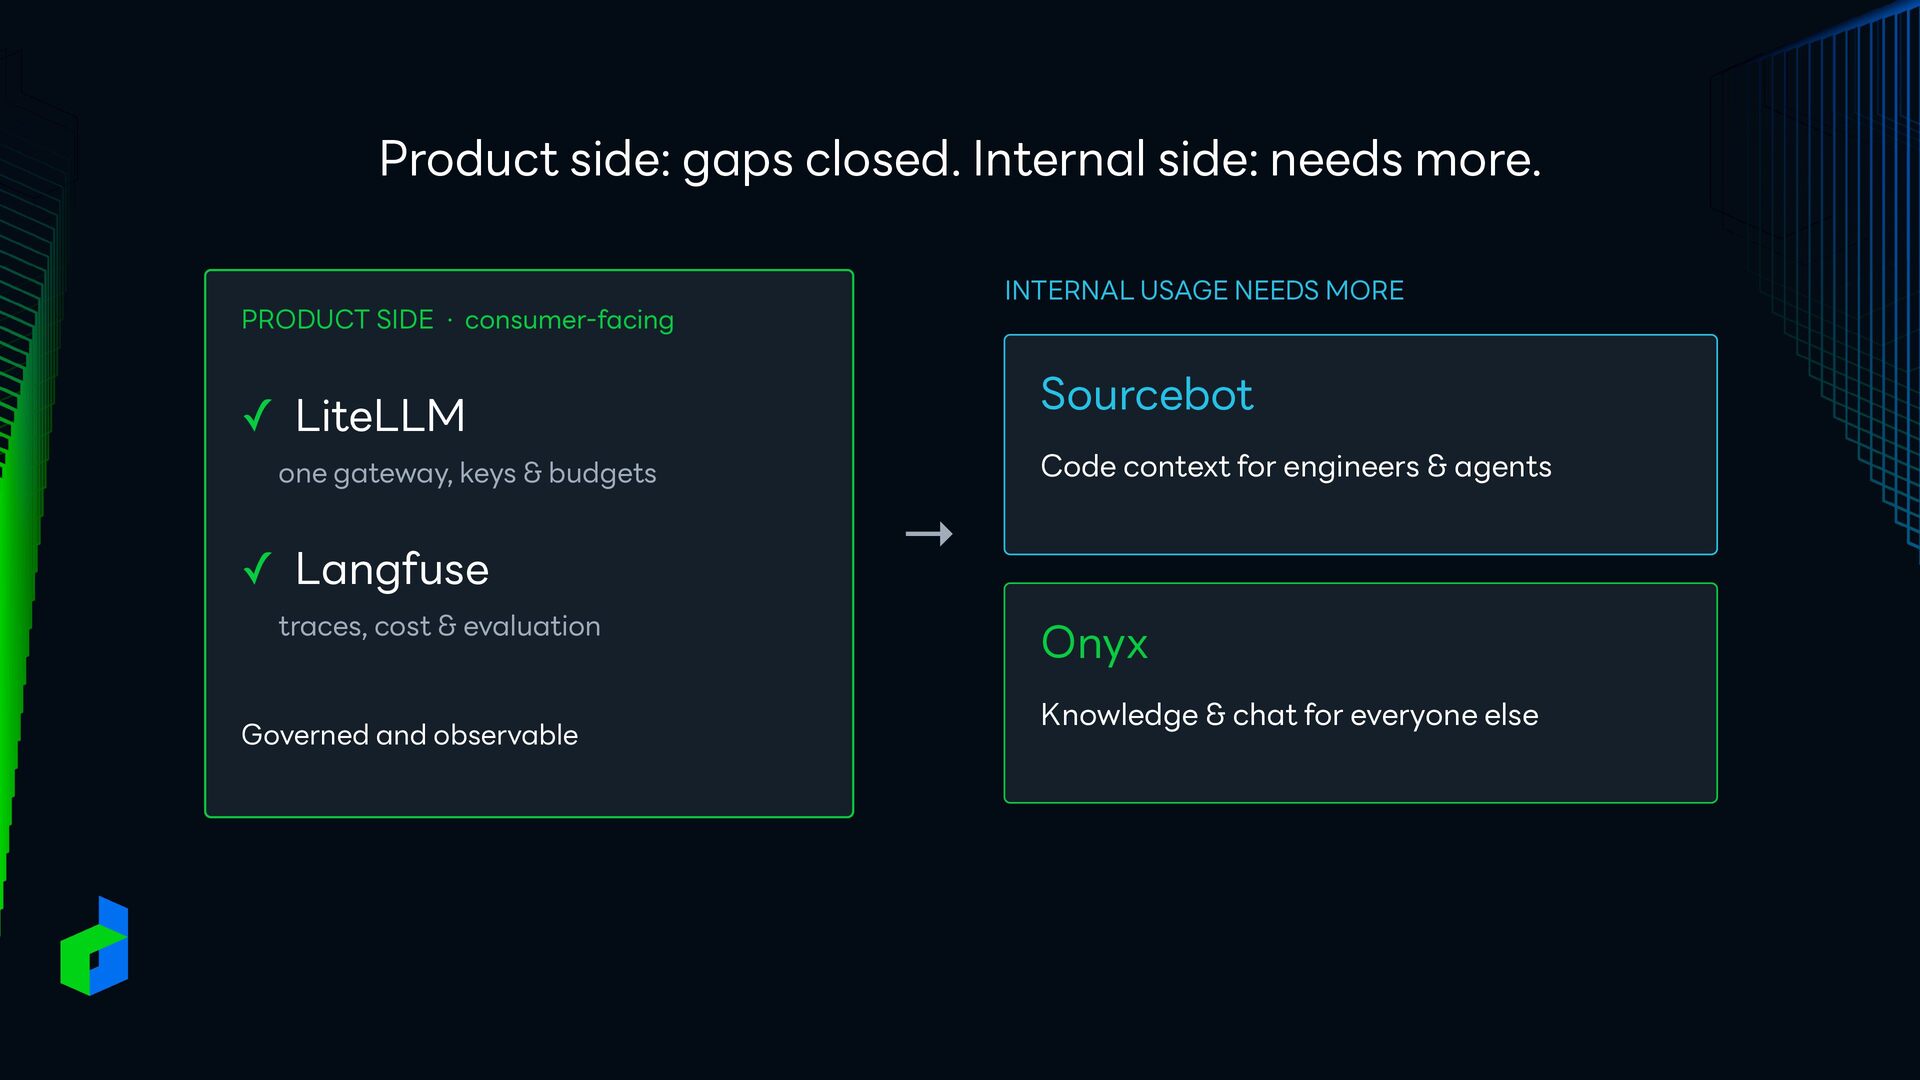
Product side: gaps closed. Internal side: needs more. PRODUCT SIDE
· consumer-facing ✓ LiteLLM one gateway, keys & budgets ✓ Langfuse traces, cost & evaluation Governed and observable -
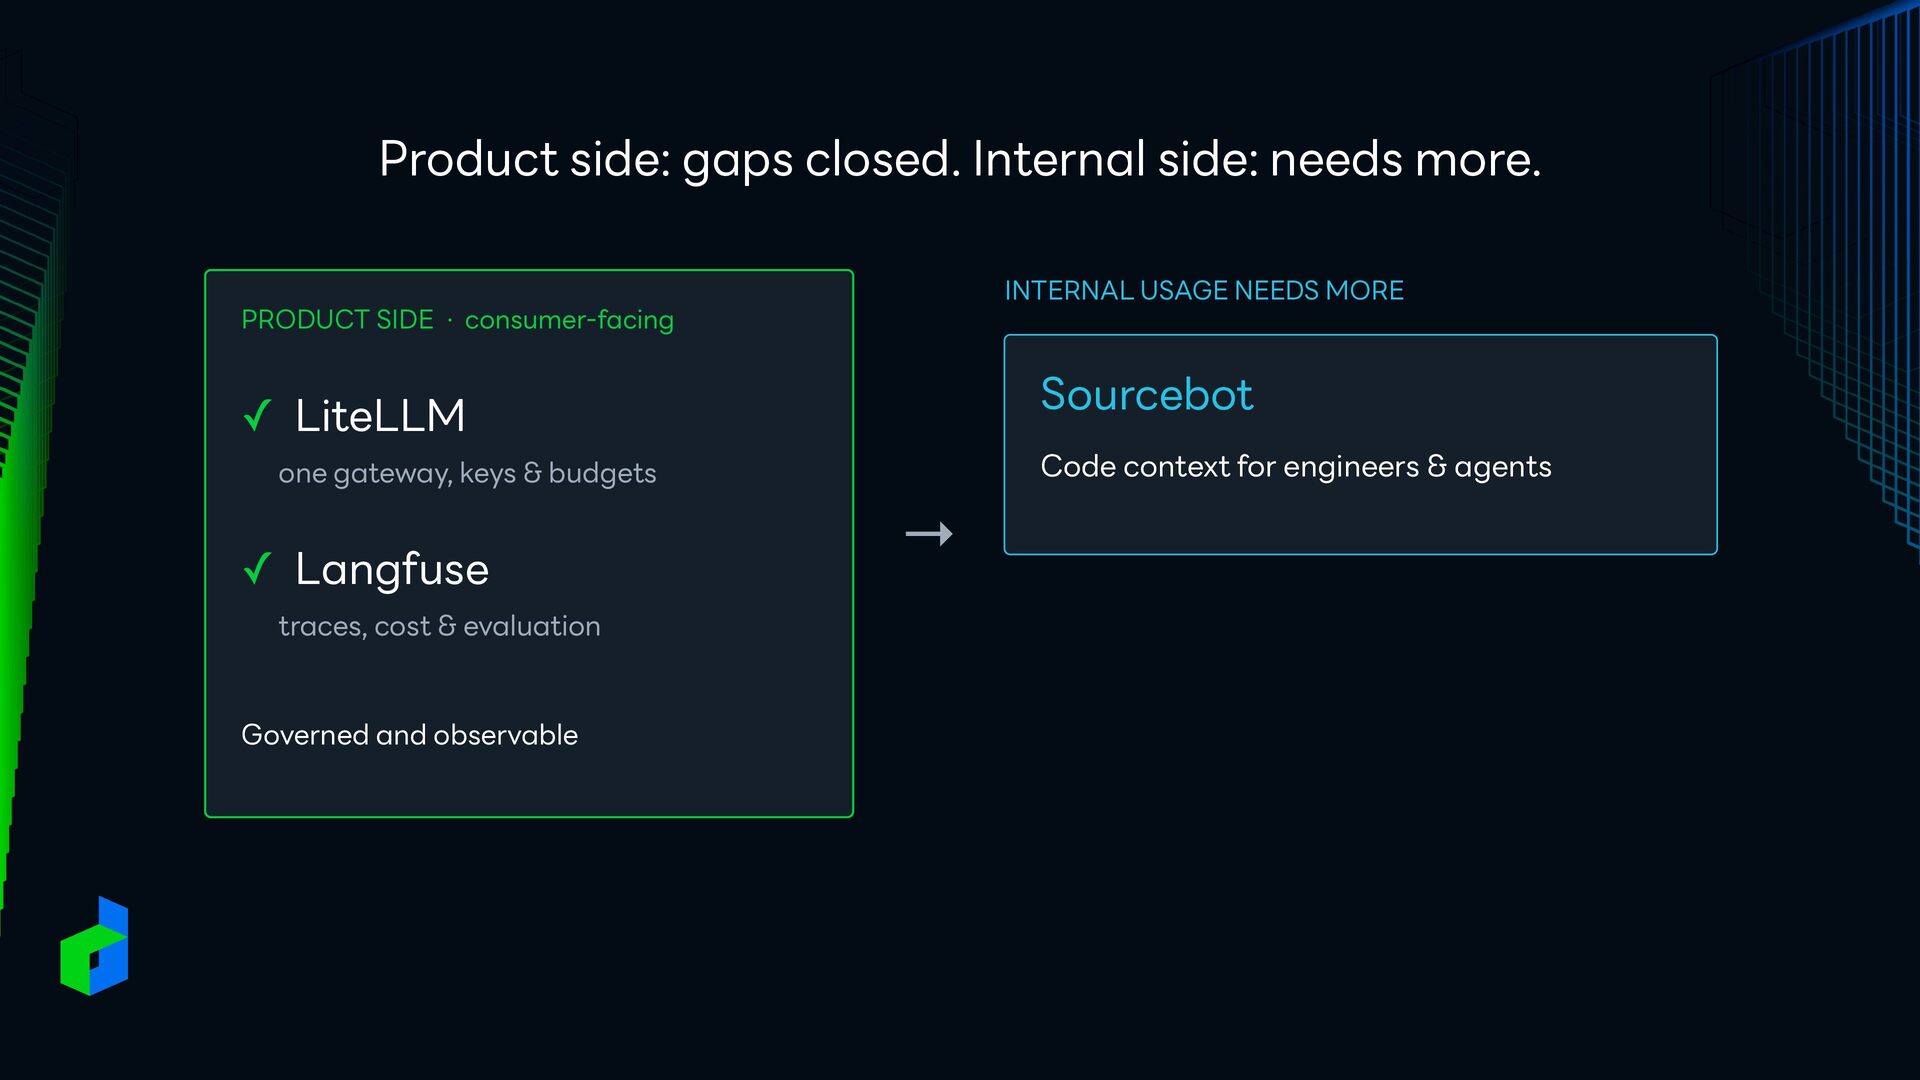
Product side: gaps closed. Internal side: needs more. INTERNAL USAGE
NEEDS MORE PRODUCT SIDE · consumer-facing Sourcebot ✓ LiteLLM Code context for engineers & agents one gateway, keys & budgets ✓ Langfuse traces, cost & evaluation Governed and observable → -
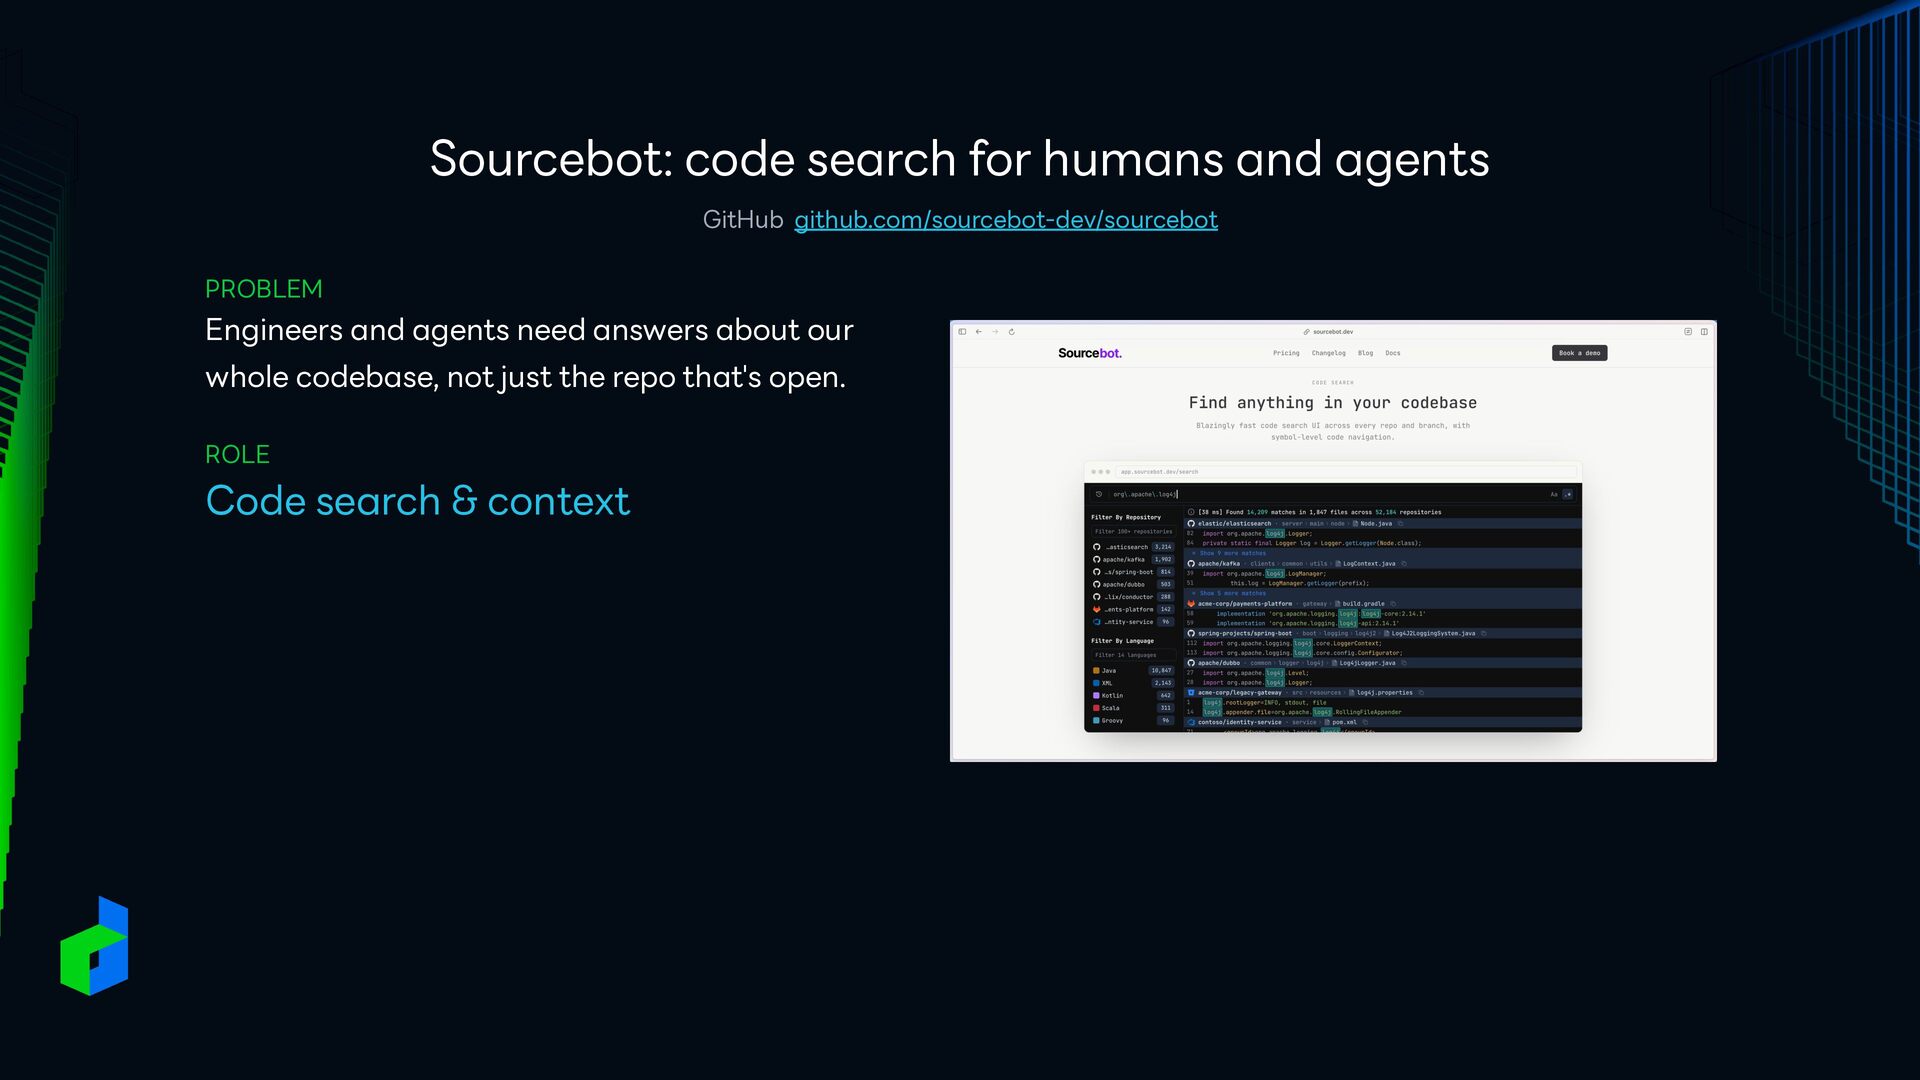
Sourcebot: code search for humans and agents GitHub github.com/sourcebot-dev/sourcebot PROBLEM
Engineers and agents need answers about our whole codebase, not just the repo that's open. ROLE Code search & context -
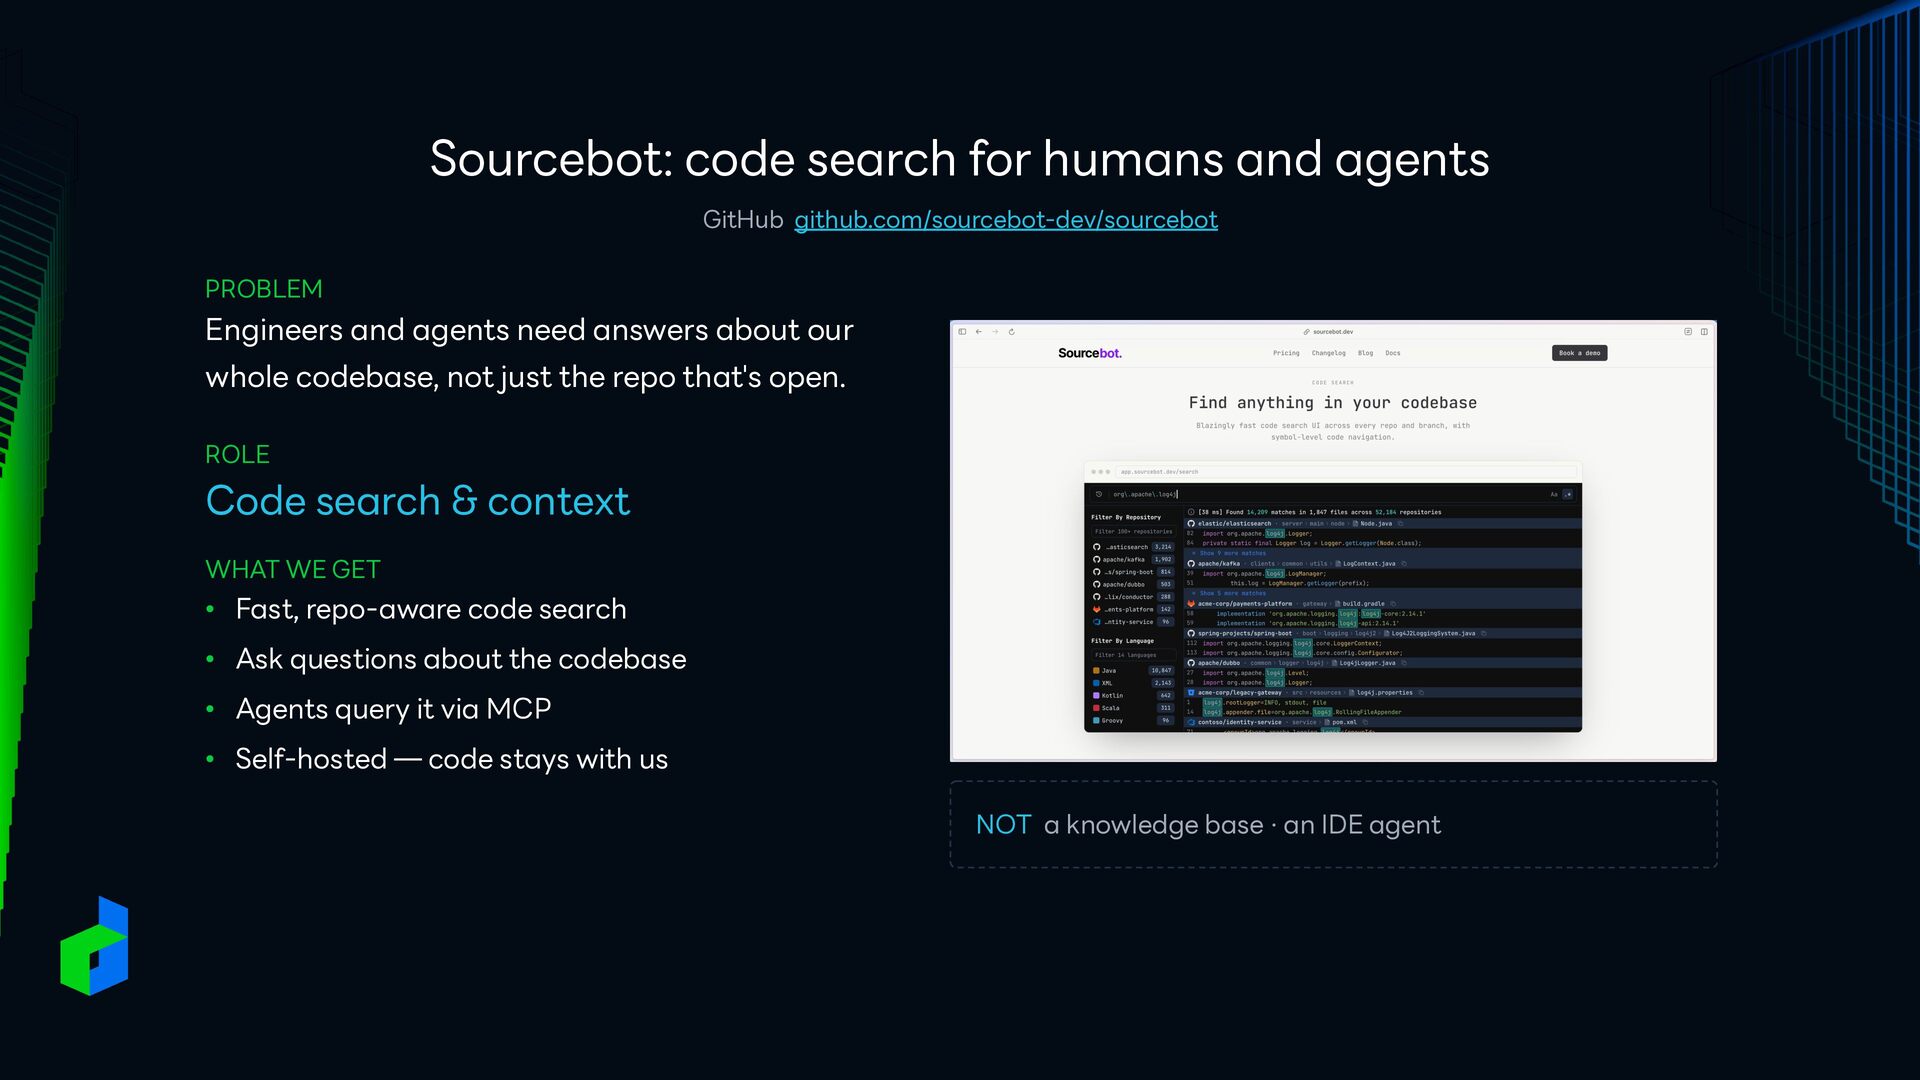
Sourcebot: code search for humans and agents GitHub github.com/sourcebot-dev/sourcebot PROBLEM
Engineers and agents need answers about our whole codebase, not just the repo that's open. ROLE Code search & context WHAT WE GET • Fast, repo-aware code search • Ask questions about the codebase • Agents query it via MCP • Self-hosted — code stays with us NOT a knowledge base · an IDE agent -
Product side: gaps closed. Internal side: needs more. INTERNAL USAGE
NEEDS MORE PRODUCT SIDE · consumer-facing Sourcebot ✓ LiteLLM Code context for engineers & agents one gateway, keys & budgets ✓ Langfuse traces, cost & evaluation Governed and observable → -
Product side: gaps closed. Internal side: needs more. INTERNAL USAGE
NEEDS MORE PRODUCT SIDE · consumer-facing Sourcebot ✓ LiteLLM Code context for engineers & agents one gateway, keys & budgets ✓ Langfuse traces, cost & evaluation Governed and observable → Onyx Knowledge & chat for everyone else -
Engineers aren't the only AI users ENGINEERS • API &
CLI • IDE & agents — Claude Code, Cursor • Sourcebot code search • MCP tools -
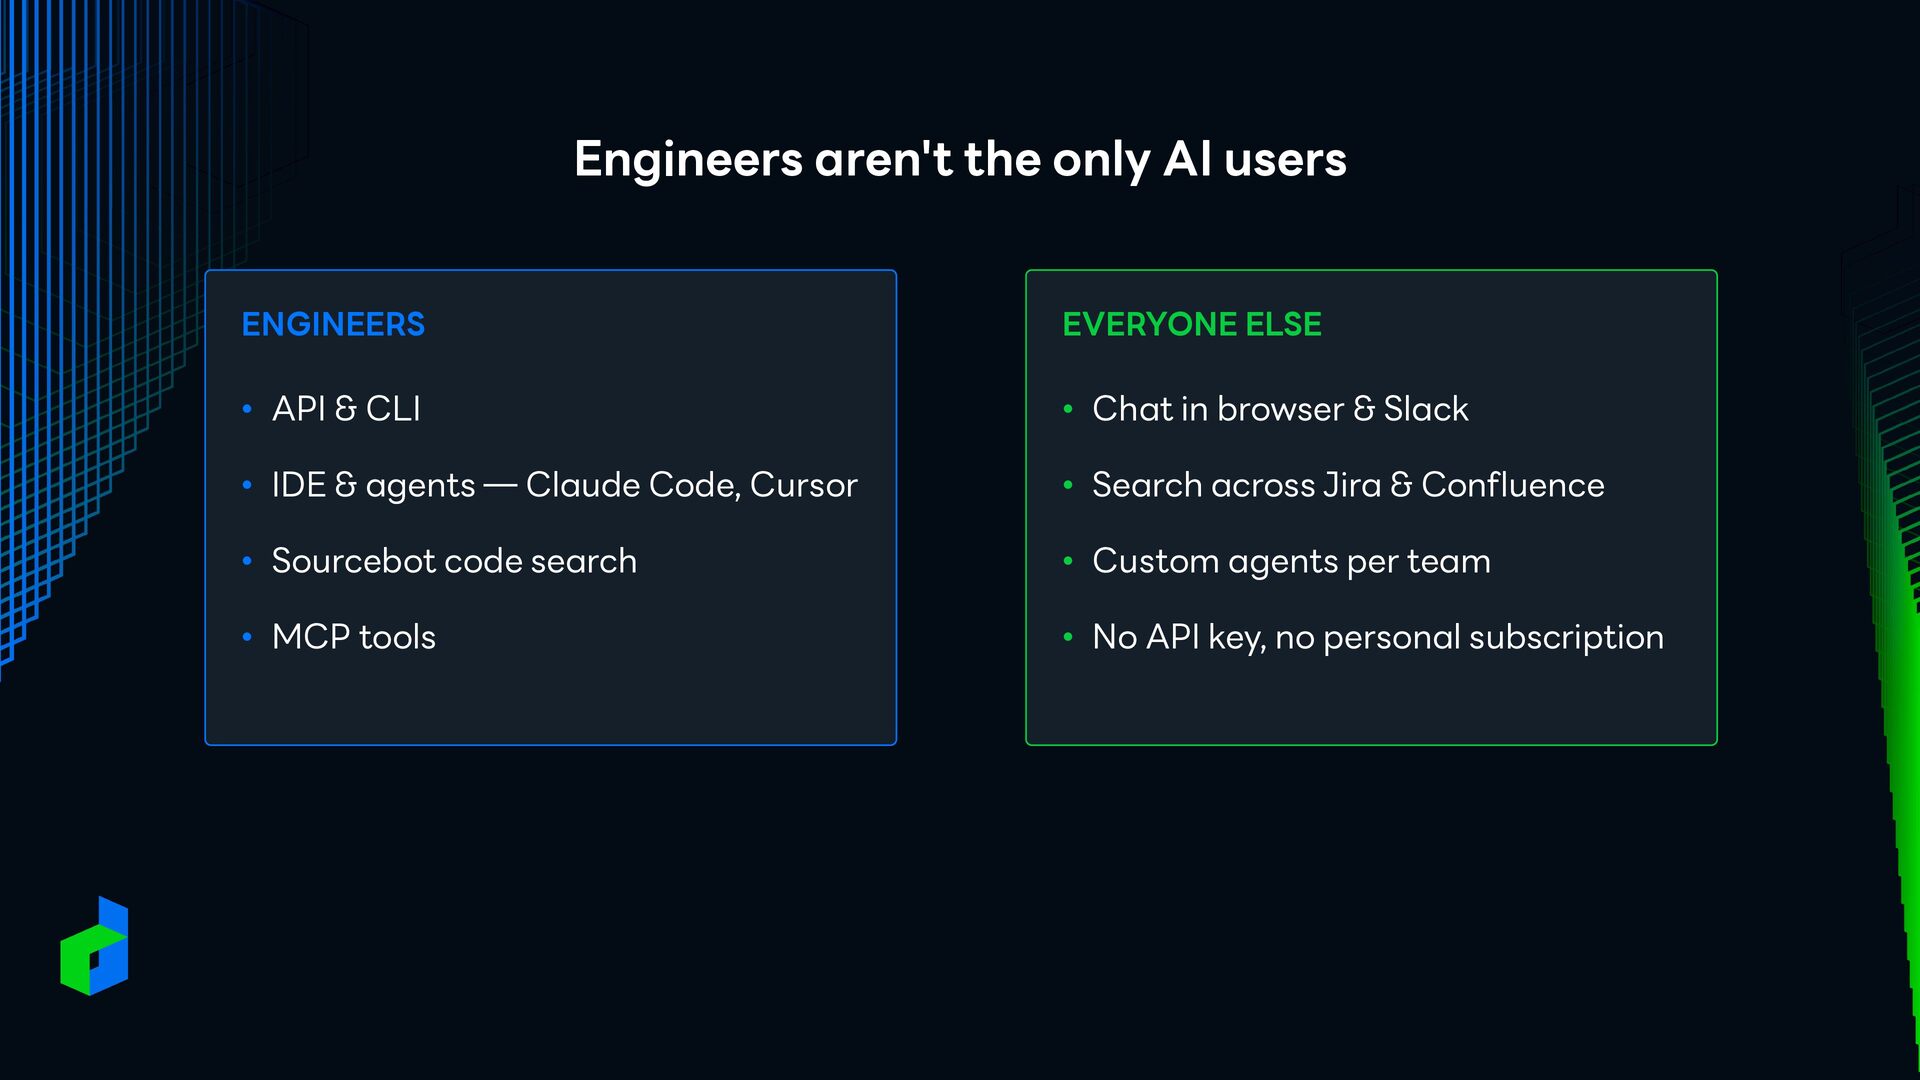
Engineers aren't the only AI users ENGINEERS EVERYONE ELSE •
API & CLI • Chat in browser & Slack • IDE & agents — Claude Code, Cursor • Search across Jira & Confluence • Sourcebot code search • Custom agents per team • MCP tools • No API key, no personal subscription -
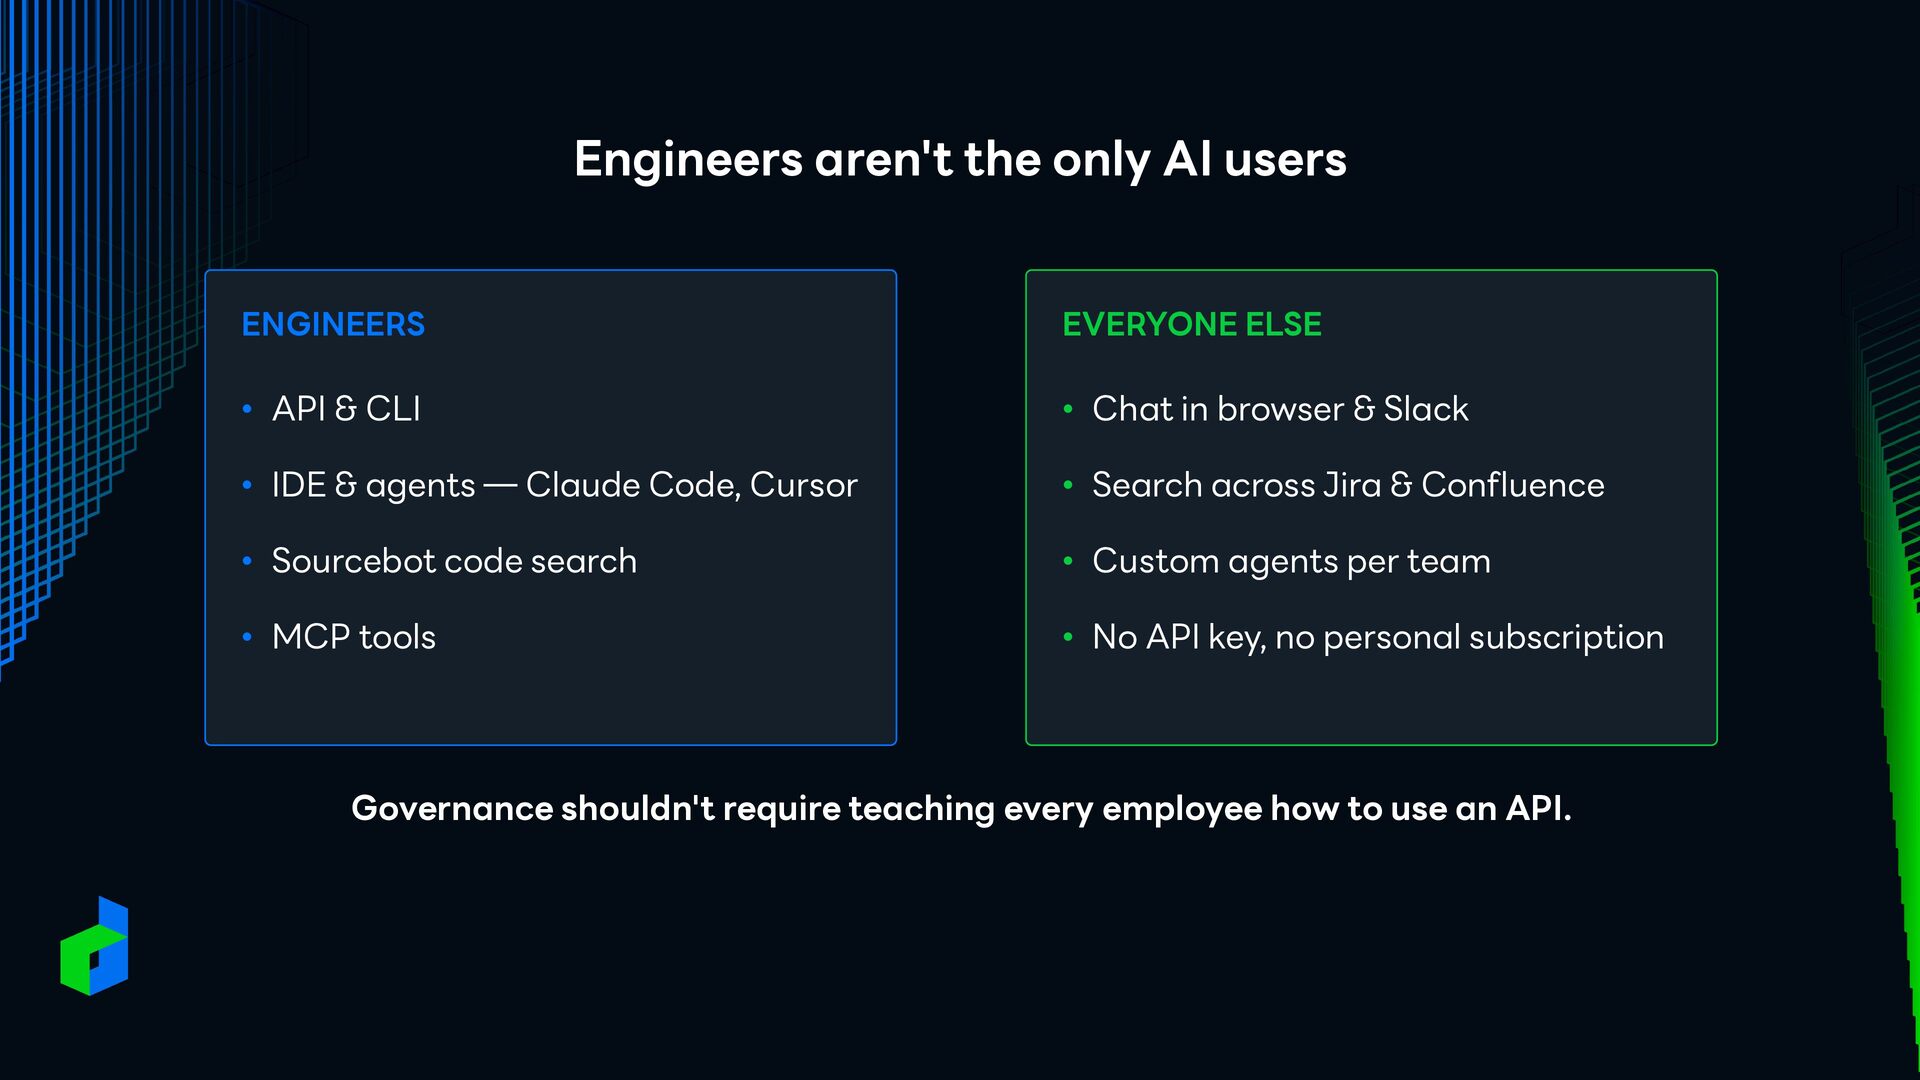
Engineers aren't the only AI users ENGINEERS EVERYONE ELSE •
API & CLI • Chat in browser & Slack • IDE & agents — Claude Code, Cursor • Search across Jira & Confluence • Sourcebot code search • Custom agents per team • MCP tools • No API key, no personal subscription Governance shouldn't require teaching every employee how to use an API. -
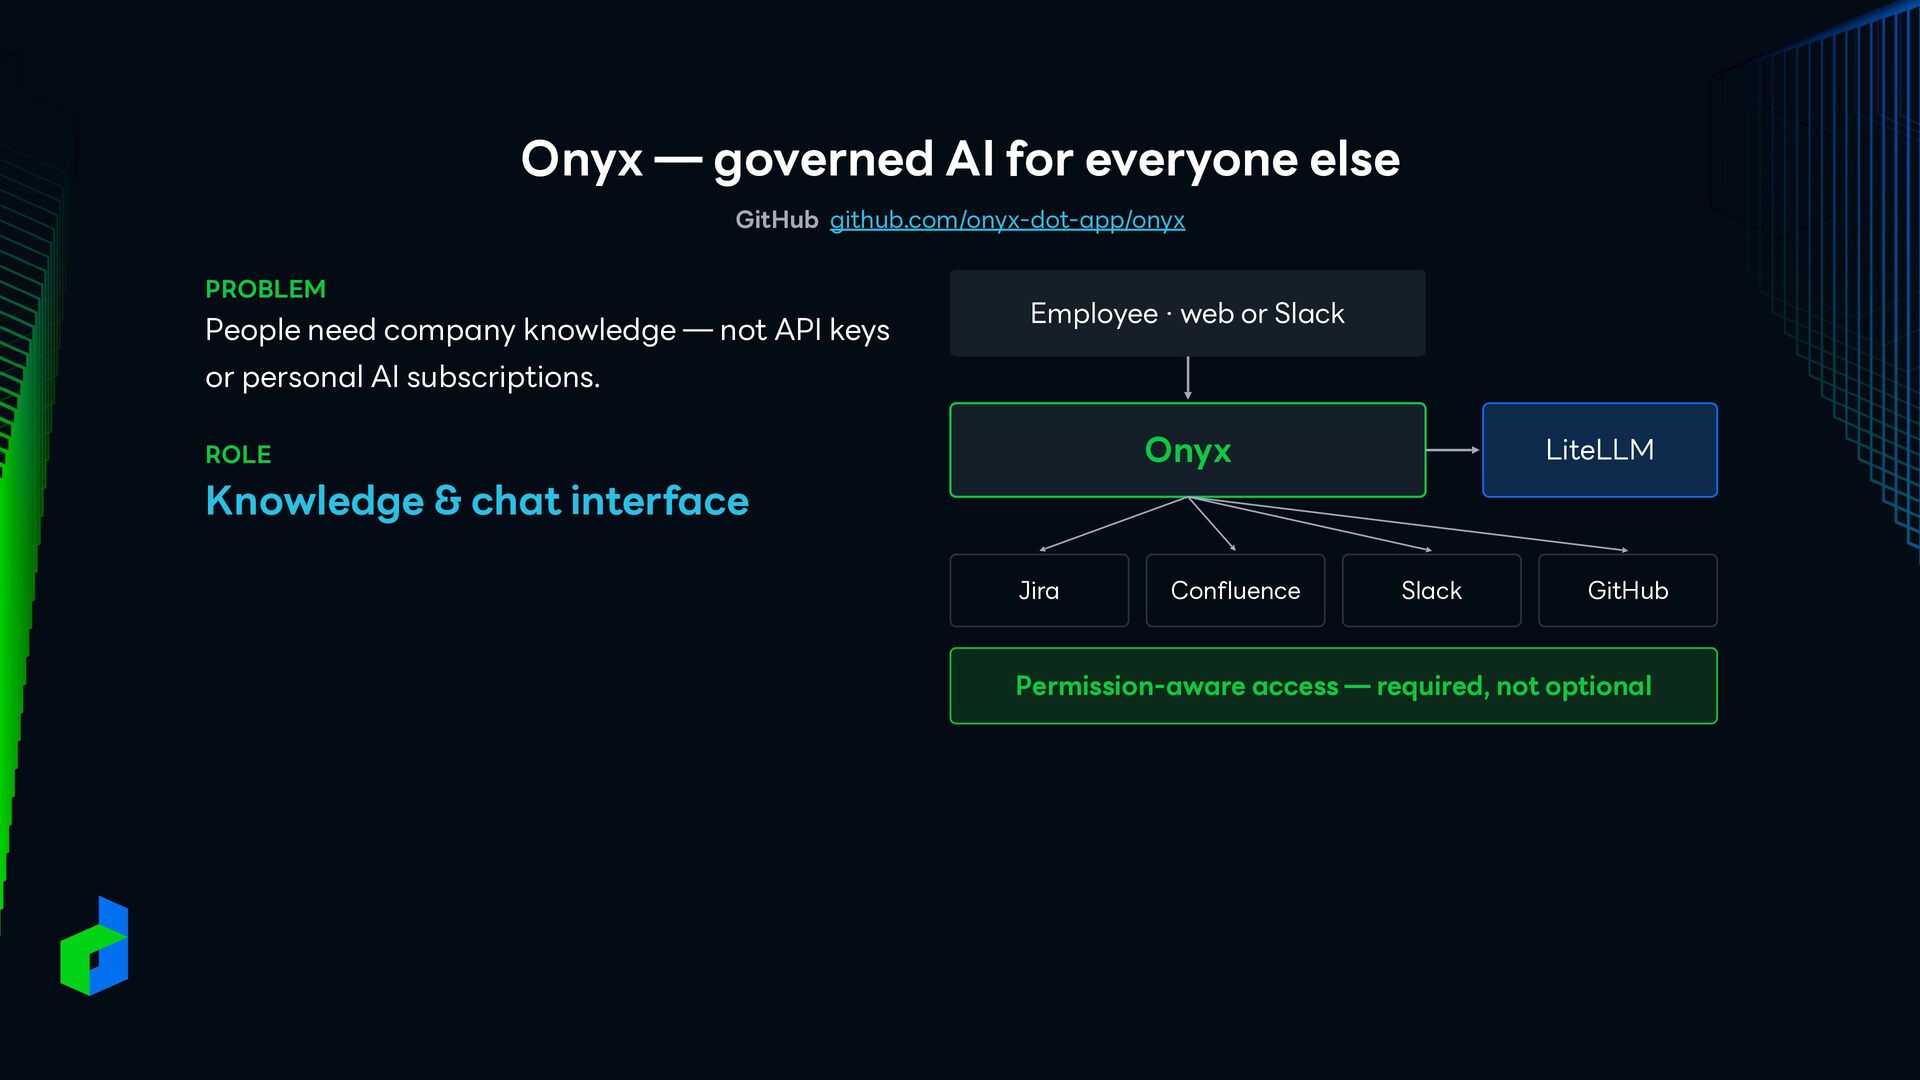
Onyx — governed AI for everyone else GitHub github.com/onyx-dot-app/onyx PROBLEM
People need company knowledge — not API keys Employee · web or Slack or personal AI subscriptions. Onyx ROLE Knowledge & chat interface Jira Confluence LiteLLM Slack GitHub Permission-aware access — required, not optional -
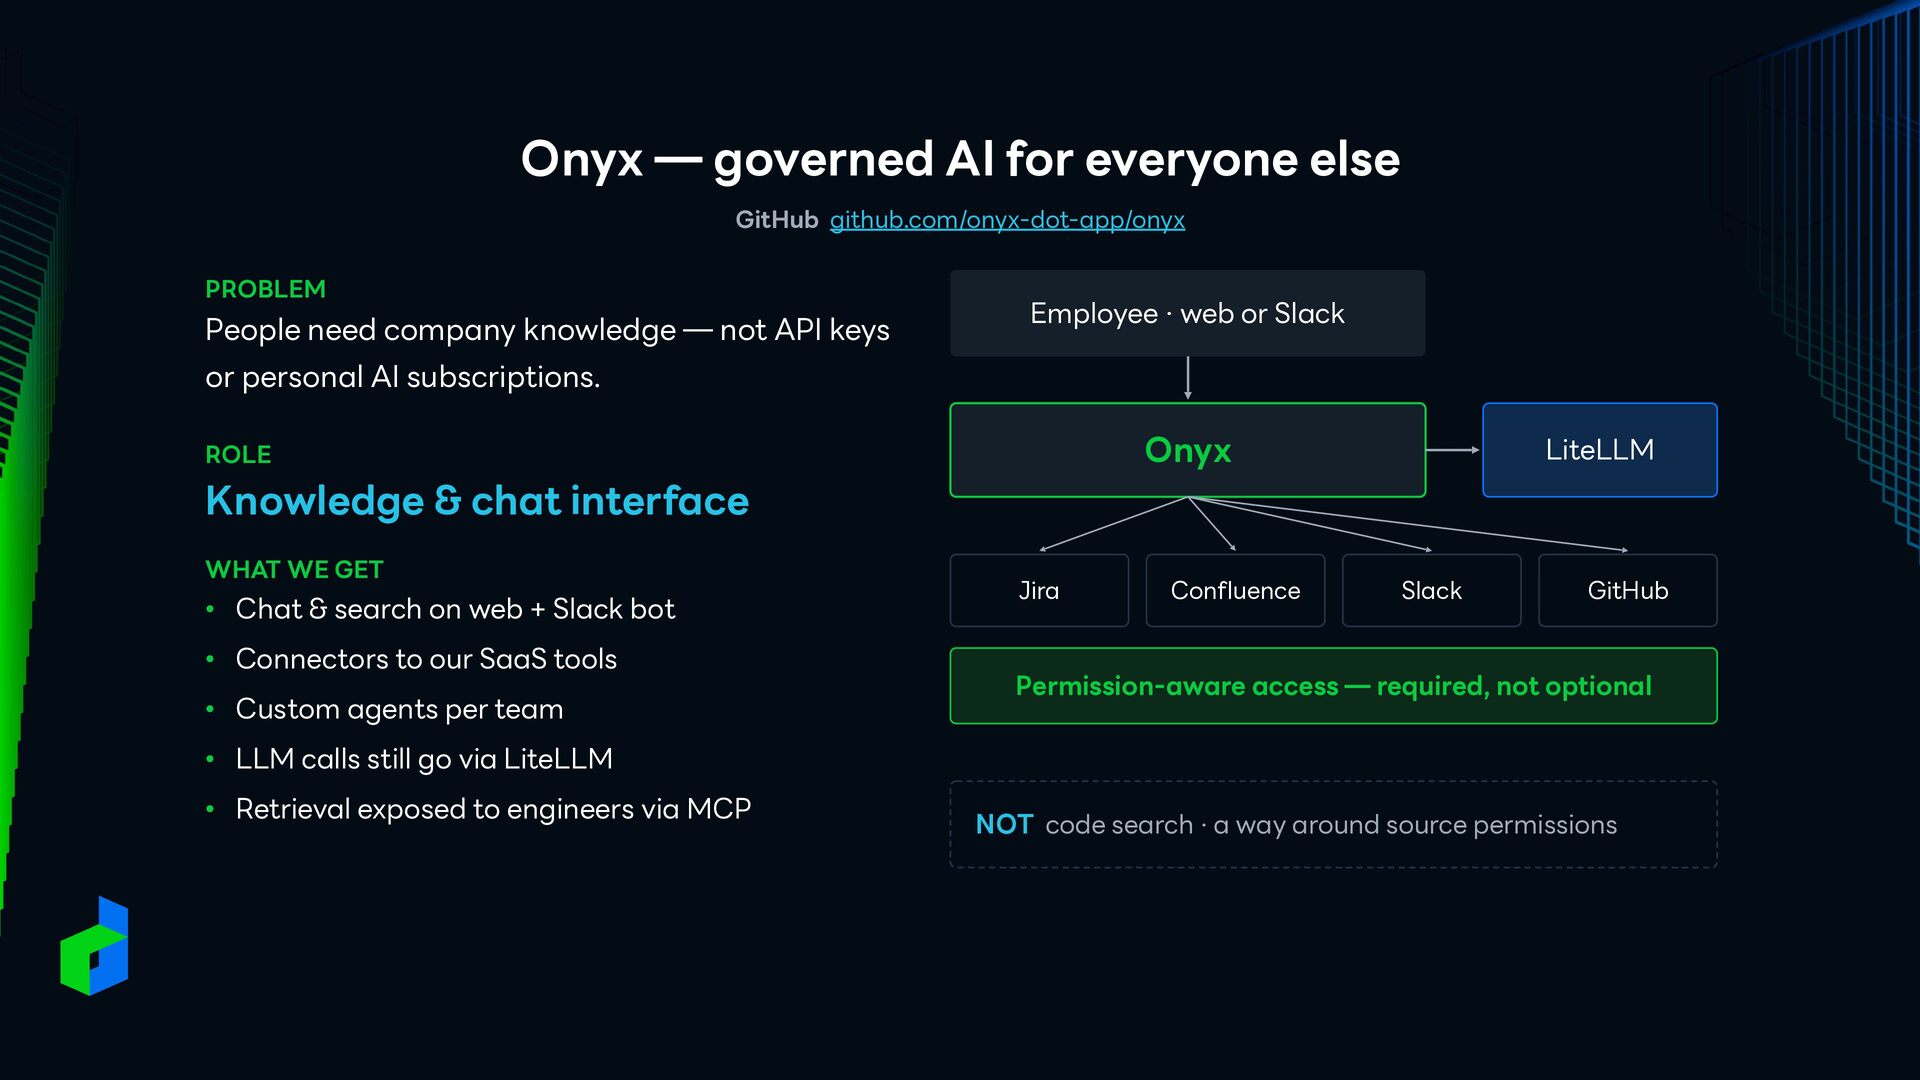
Onyx — governed AI for everyone else GitHub github.com/onyx-dot-app/onyx PROBLEM
People need company knowledge — not API keys Employee · web or Slack or personal AI subscriptions. Onyx ROLE Knowledge & chat interface WHAT WE GET • Chat & search on web + Slack bot • Connectors to our SaaS tools • Custom agents per team Jira Confluence LiteLLM Slack GitHub Permission-aware access — required, not optional • LLM calls still go via LiteLLM • Retrieval exposed to engineers via MCP NOT code search · a way around source permissions -
Why not put everything into one giant RAG? BUSINESS KNOWLEDGE
↓ Onyx • Docs, tickets, chat threads • Semantic search + chat answers • Permissions follow the source tool GitHub github.com/onyx-dot-app/onyx -
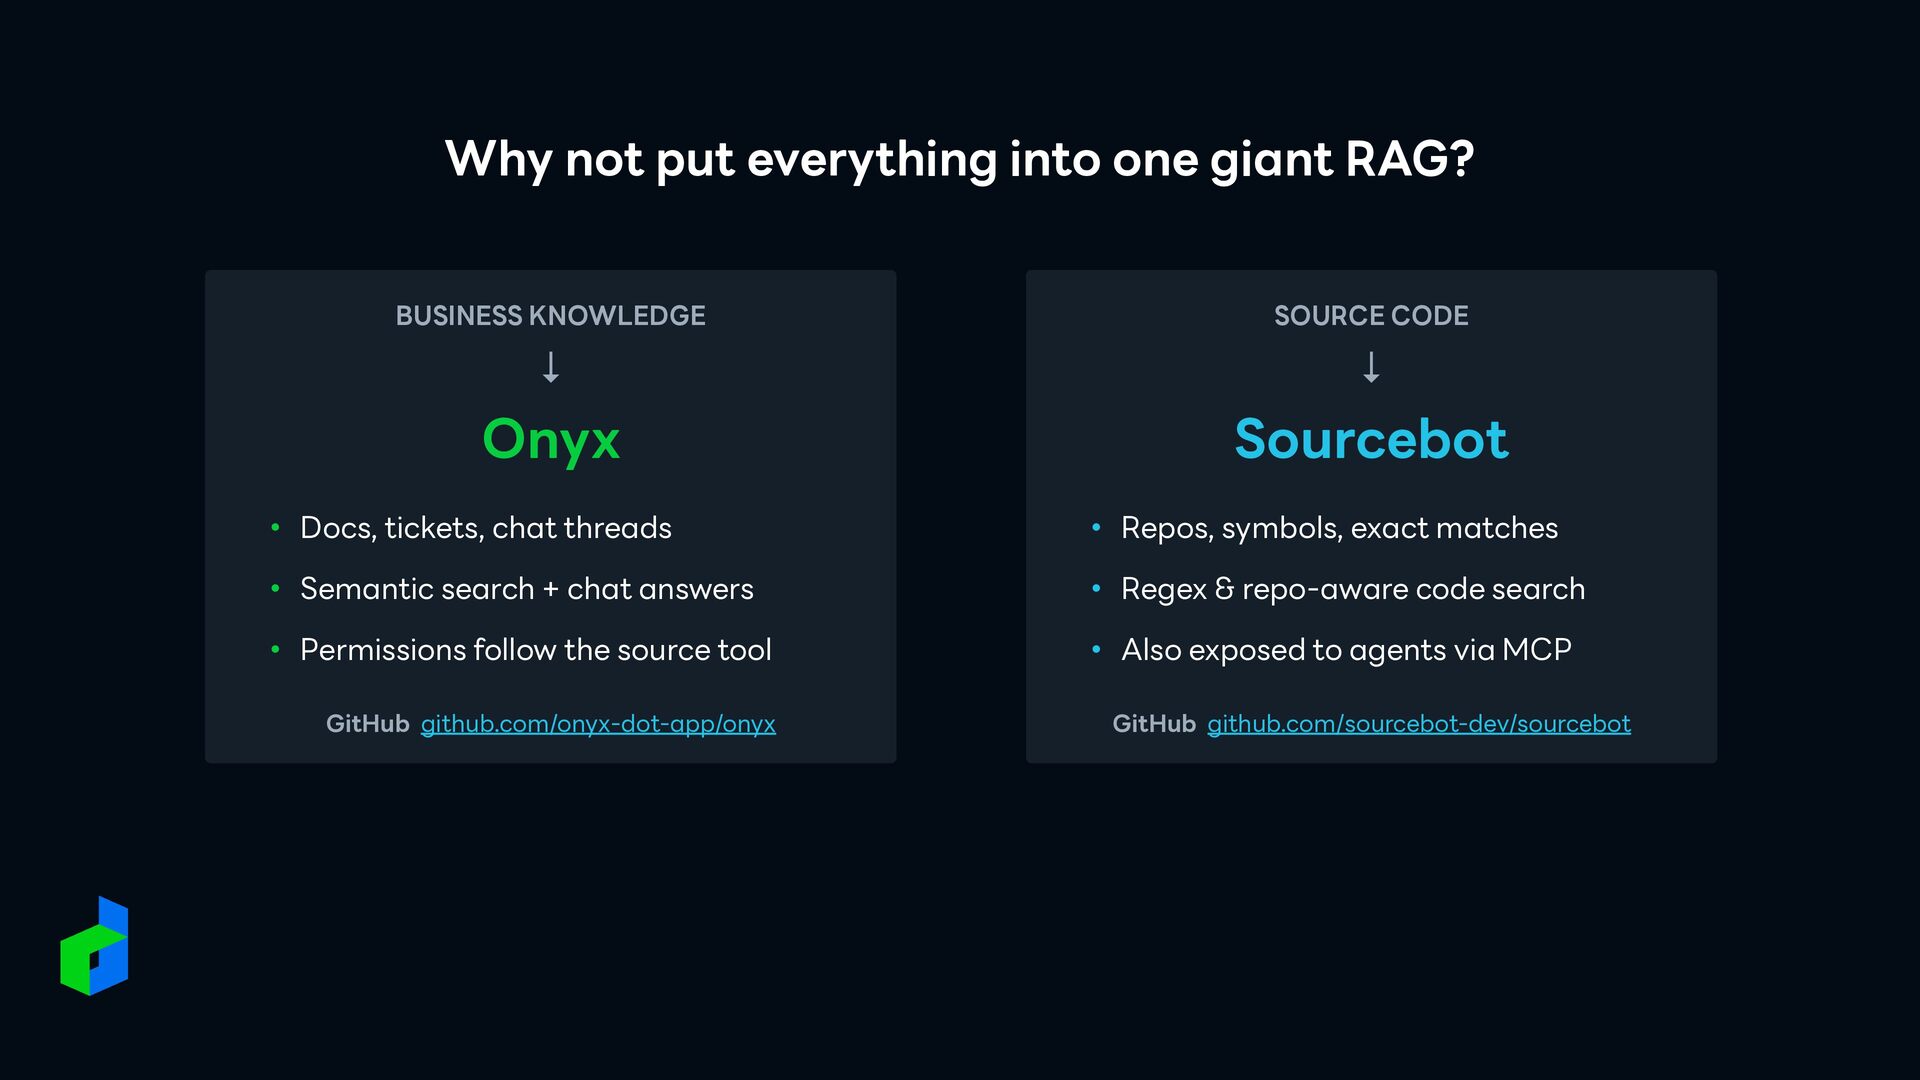
Why not put everything into one giant RAG? BUSINESS KNOWLEDGE
SOURCE CODE ↓ ↓ Onyx Sourcebot • Docs, tickets, chat threads • Repos, symbols, exact matches • Semantic search + chat answers • Regex & repo-aware code search • Permissions follow the source tool • Also exposed to agents via MCP GitHub github.com/onyx-dot-app/onyx GitHub github.com/sourcebot-dev/sourcebot -
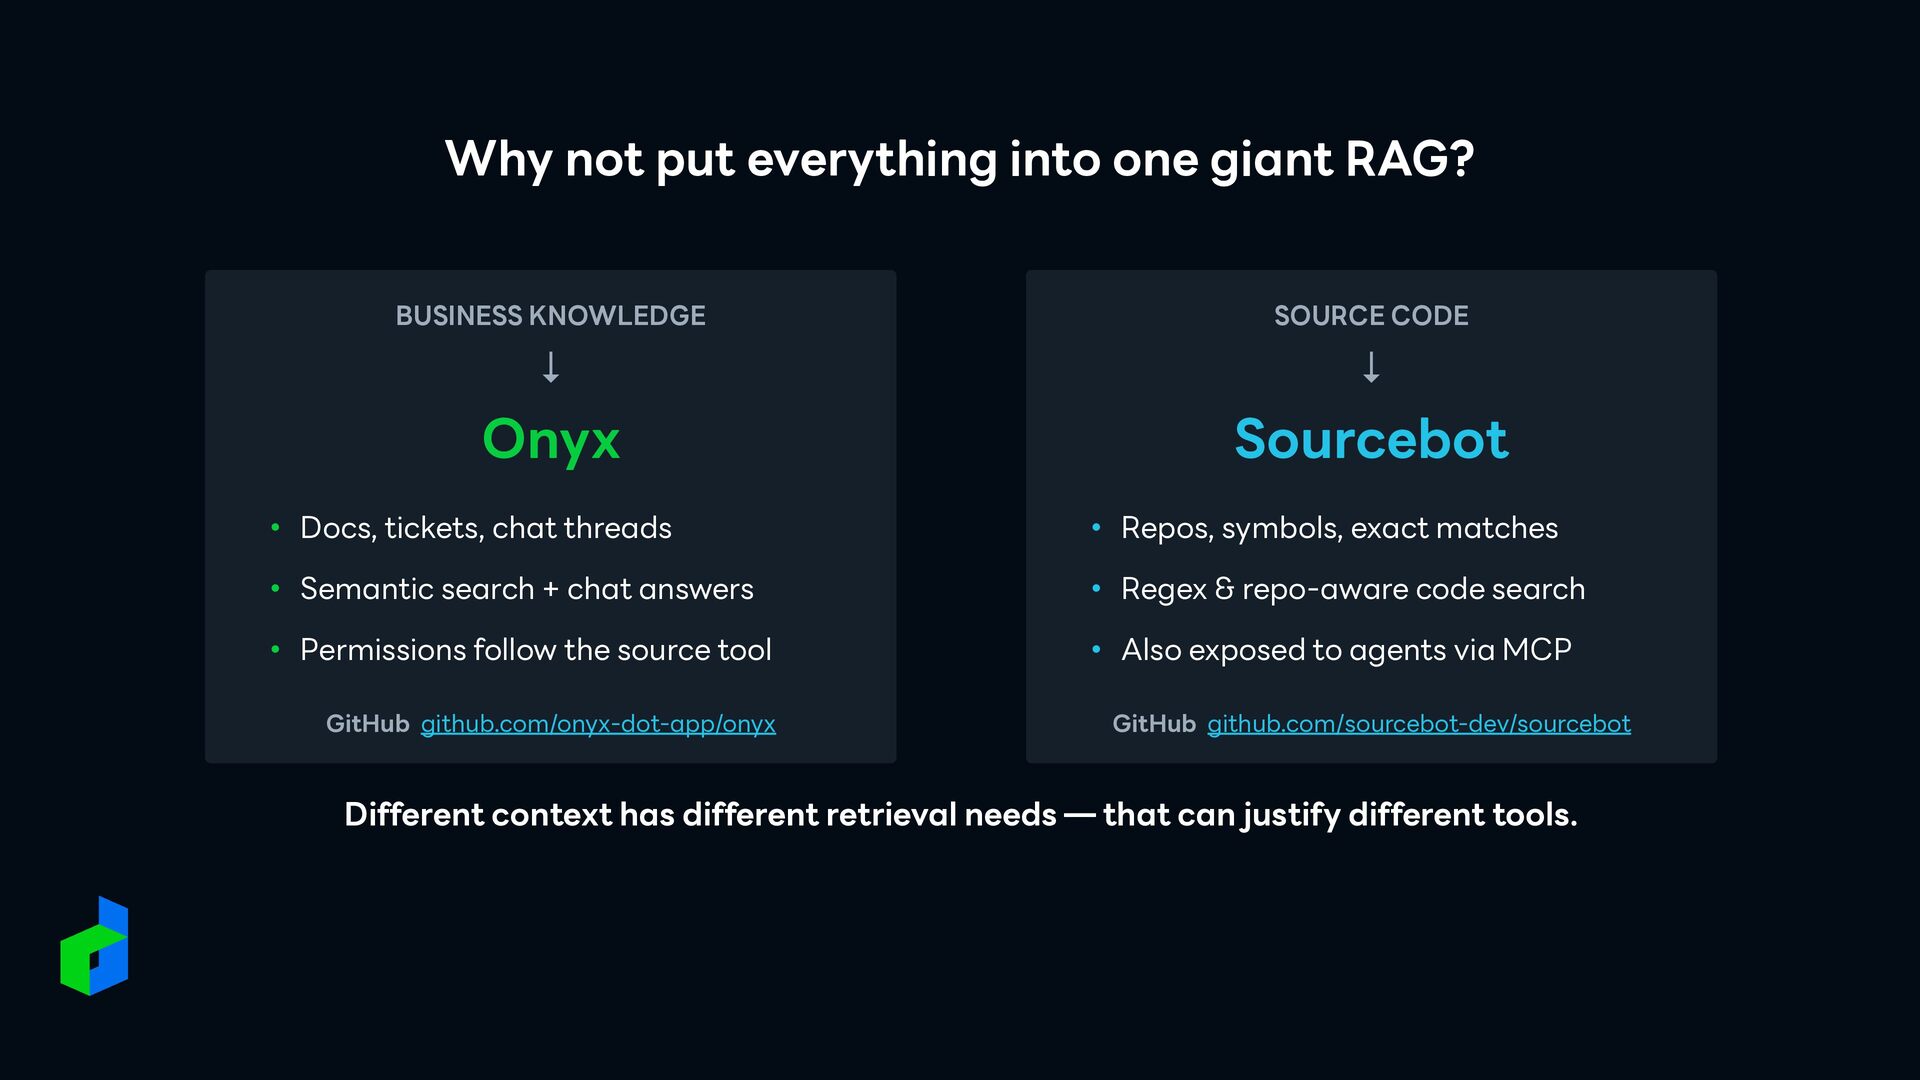
Why not put everything into one giant RAG? BUSINESS KNOWLEDGE
SOURCE CODE ↓ ↓ Onyx Sourcebot • Docs, tickets, chat threads • Repos, symbols, exact matches • Semantic search + chat answers • Regex & repo-aware code search • Permissions follow the source tool • Also exposed to agents via MCP GitHub github.com/onyx-dot-app/onyx GitHub github.com/sourcebot-dev/sourcebot Different context has different retrieval needs — that can justify different tools. -
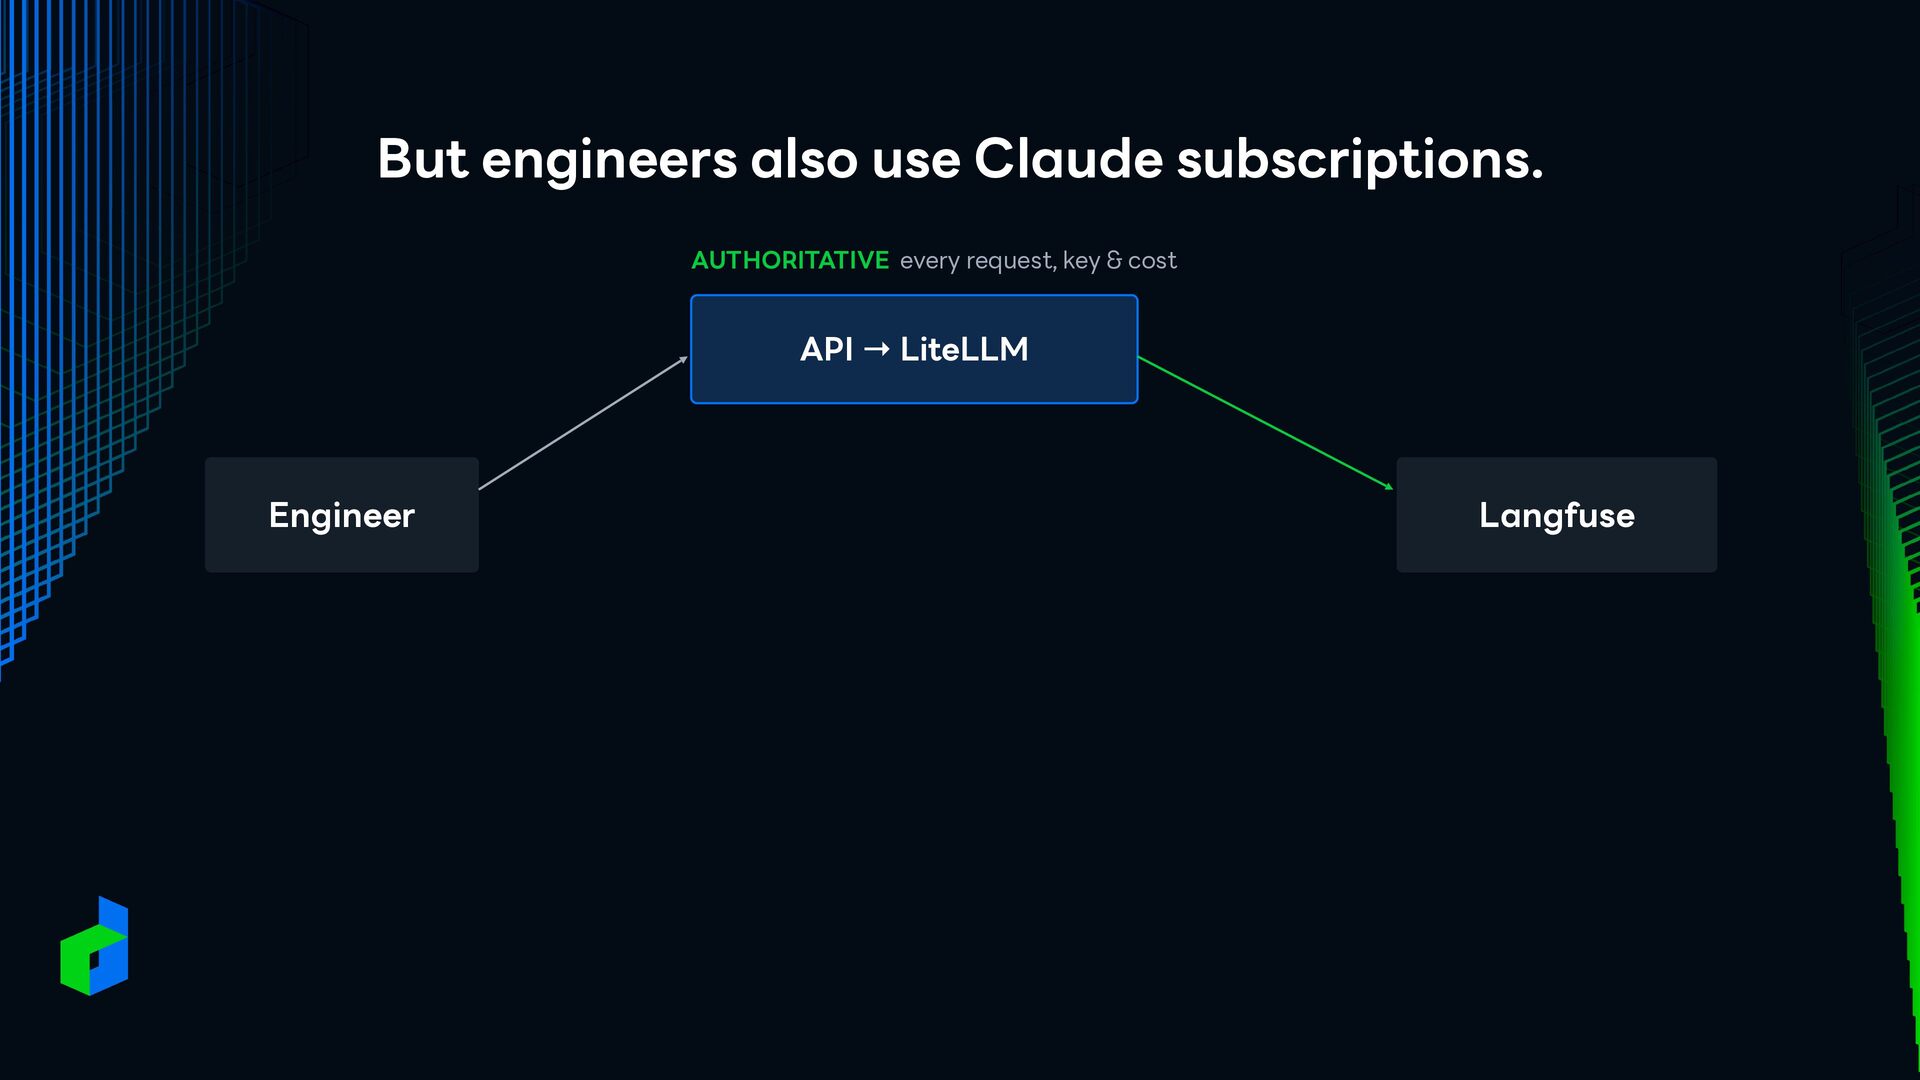
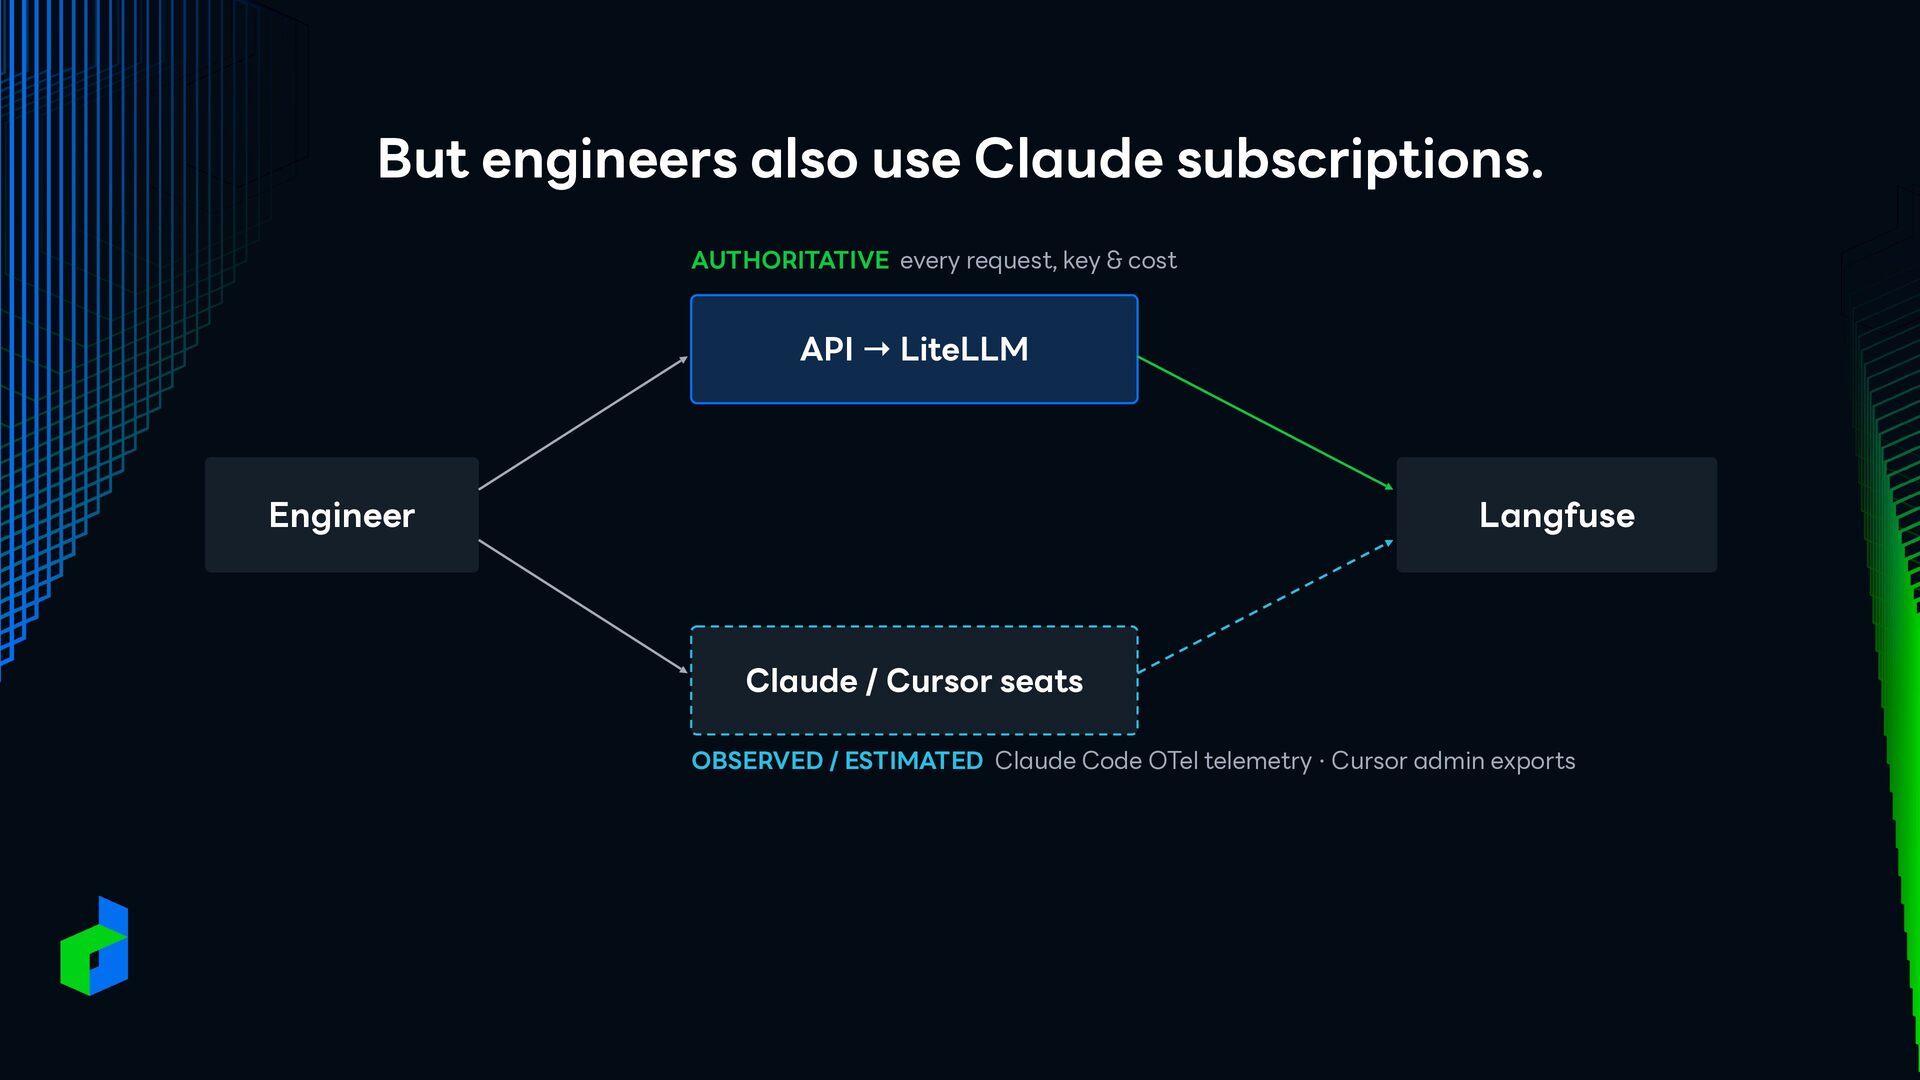
But engineers also use Claude subscriptions. AUTHORITATIVE every request, key
& cost API → LiteLLM Engineer Langfuse -
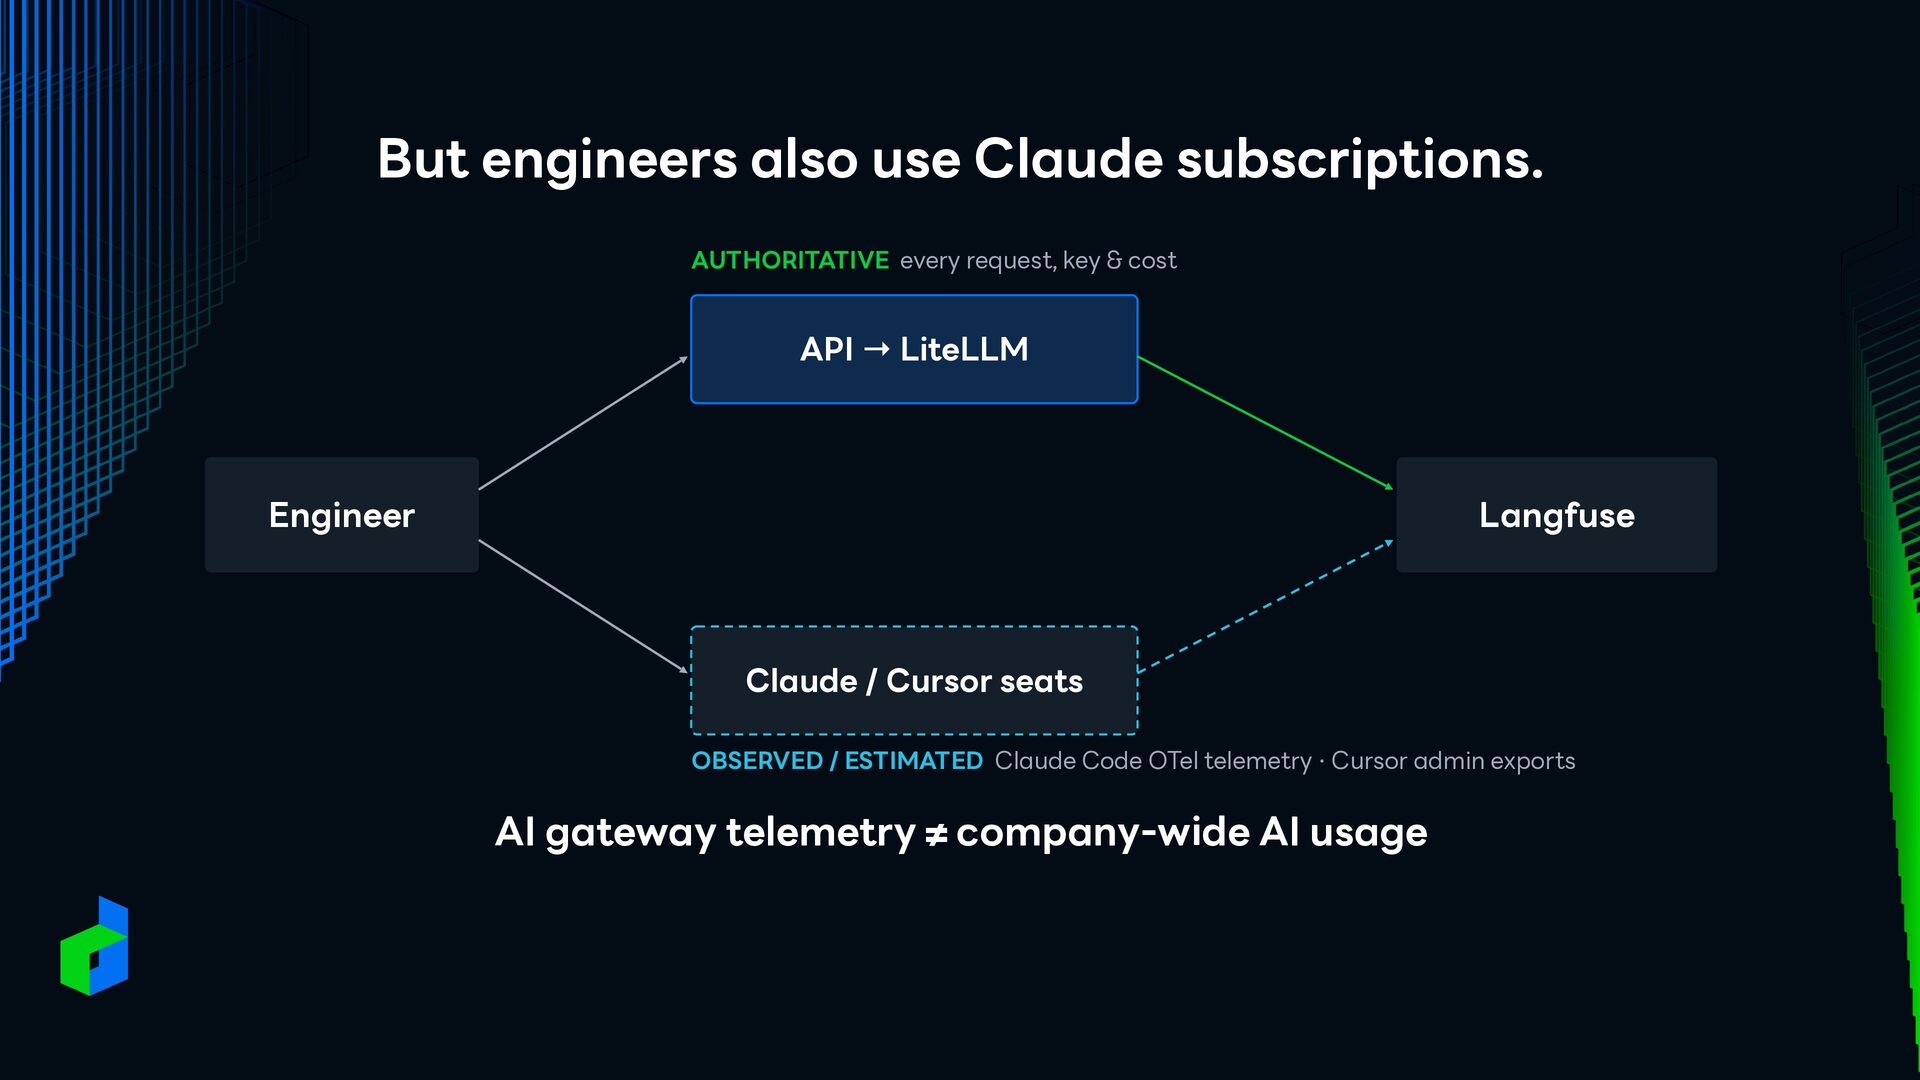
But engineers also use Claude subscriptions. AUTHORITATIVE every request, key
& cost API → LiteLLM Engineer Langfuse Claude / Cursor seats OBSERVED / ESTIMATED Claude Code OTel telemetry · Cursor admin exports -
But engineers also use Claude subscriptions. AUTHORITATIVE every request, key
& cost API → LiteLLM Engineer Langfuse Claude / Cursor seats OBSERVED / ESTIMATED Claude Code OTel telemetry · Cursor admin exports AI gateway telemetry ≠ company-wide AI usage -
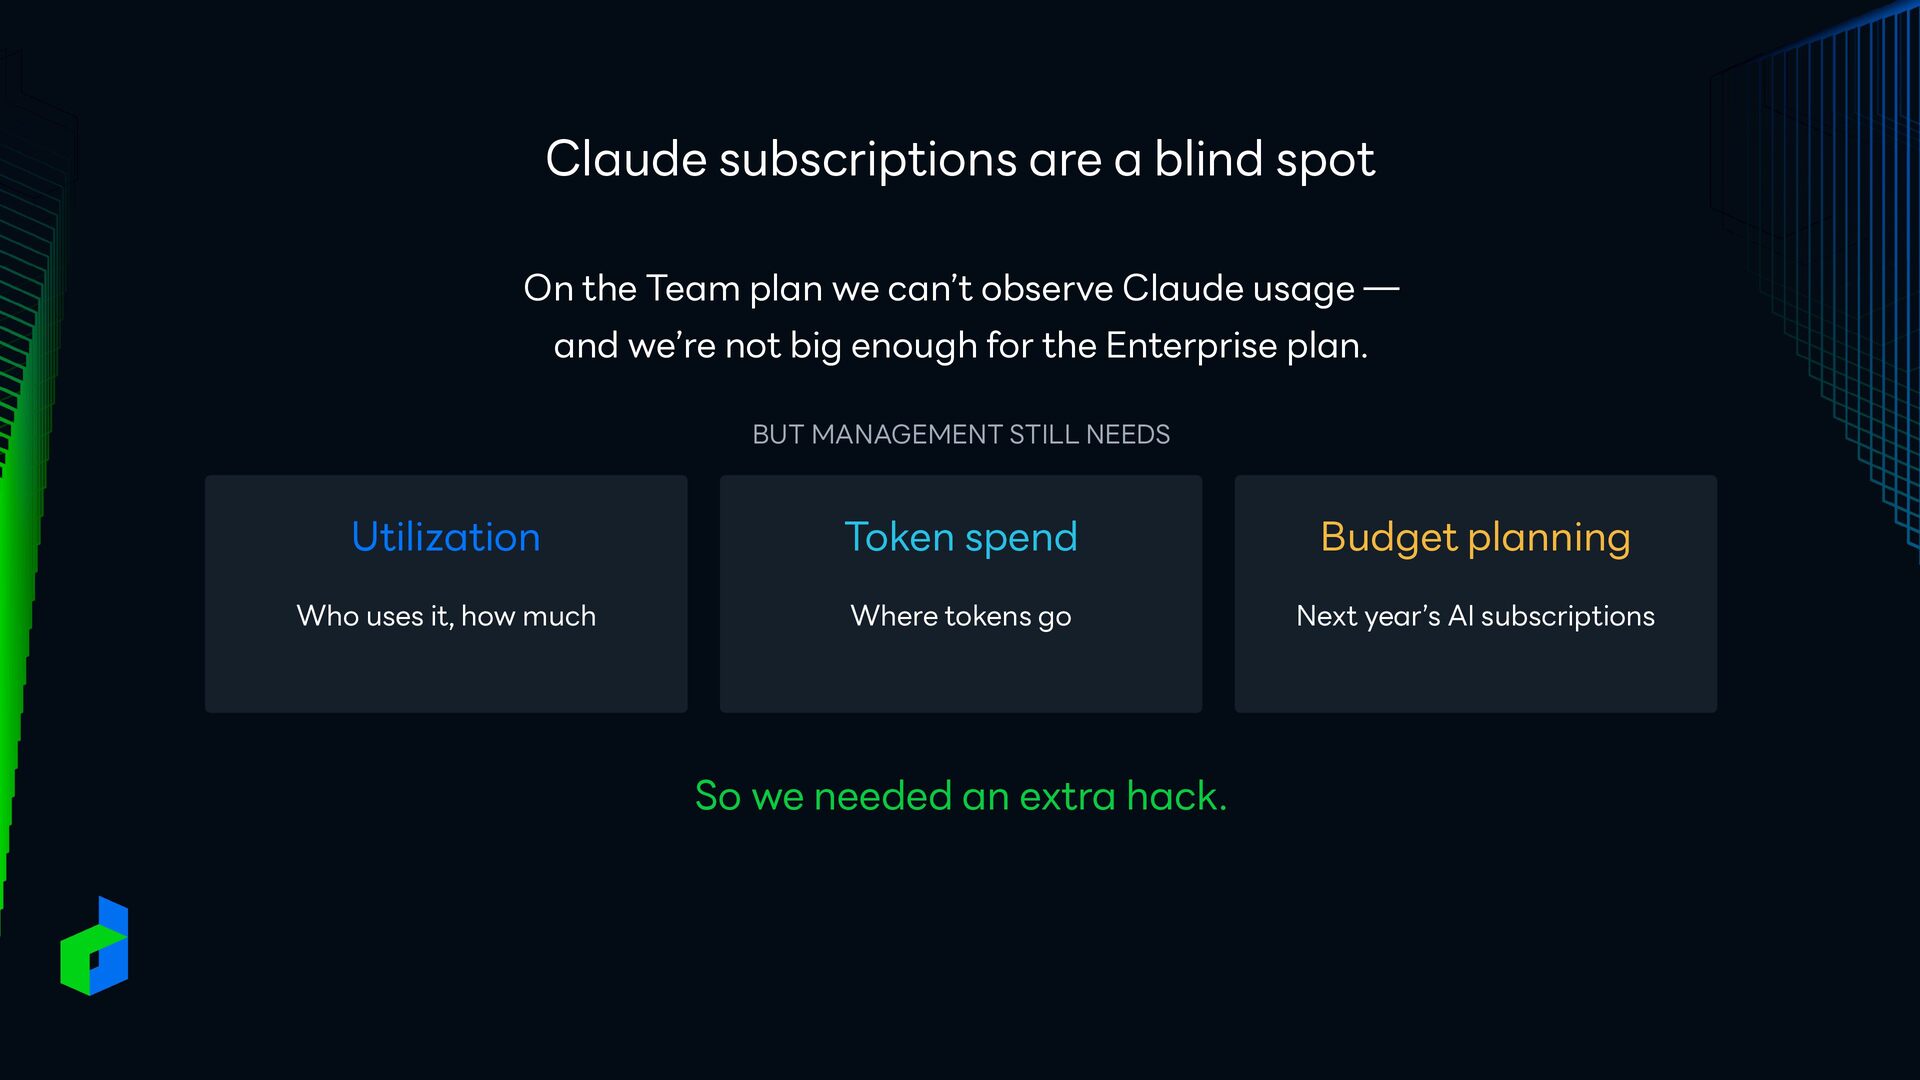
Claude subscriptions are a blind spot On the Team plan
we can’t observe Claude usage — and we’re not big enough for the Enterprise plan. -
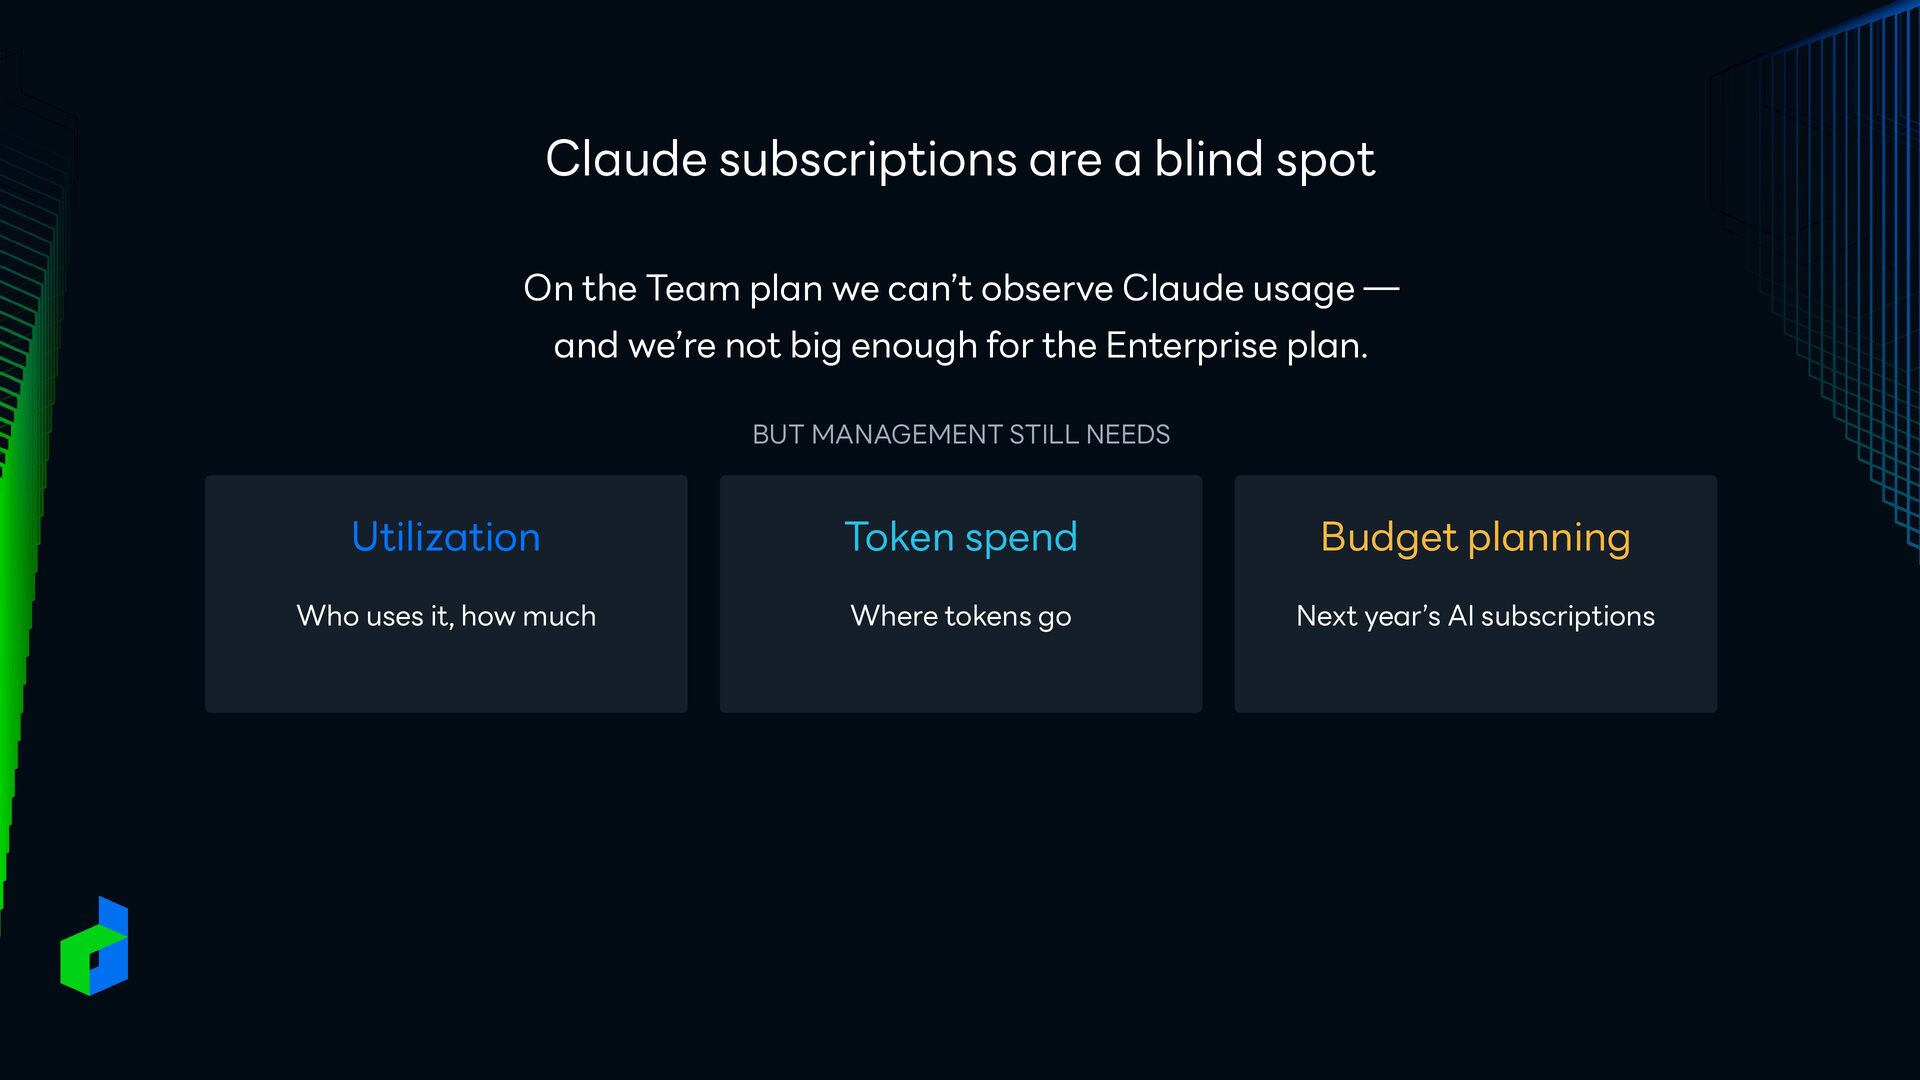
Claude subscriptions are a blind spot On the Team plan
we can’t observe Claude usage — and we’re not big enough for the Enterprise plan. BUT MANAGEMENT STILL NEEDS Utilization Token spend Budget planning Who uses it, how much Where tokens go Next year’s AI subscriptions -
Claude subscriptions are a blind spot On the Team plan
we can’t observe Claude usage — and we’re not big enough for the Enterprise plan. BUT MANAGEMENT STILL NEEDS Utilization Token spend Budget planning Who uses it, how much Where tokens go Next year’s AI subscriptions So we needed an extra hack. -
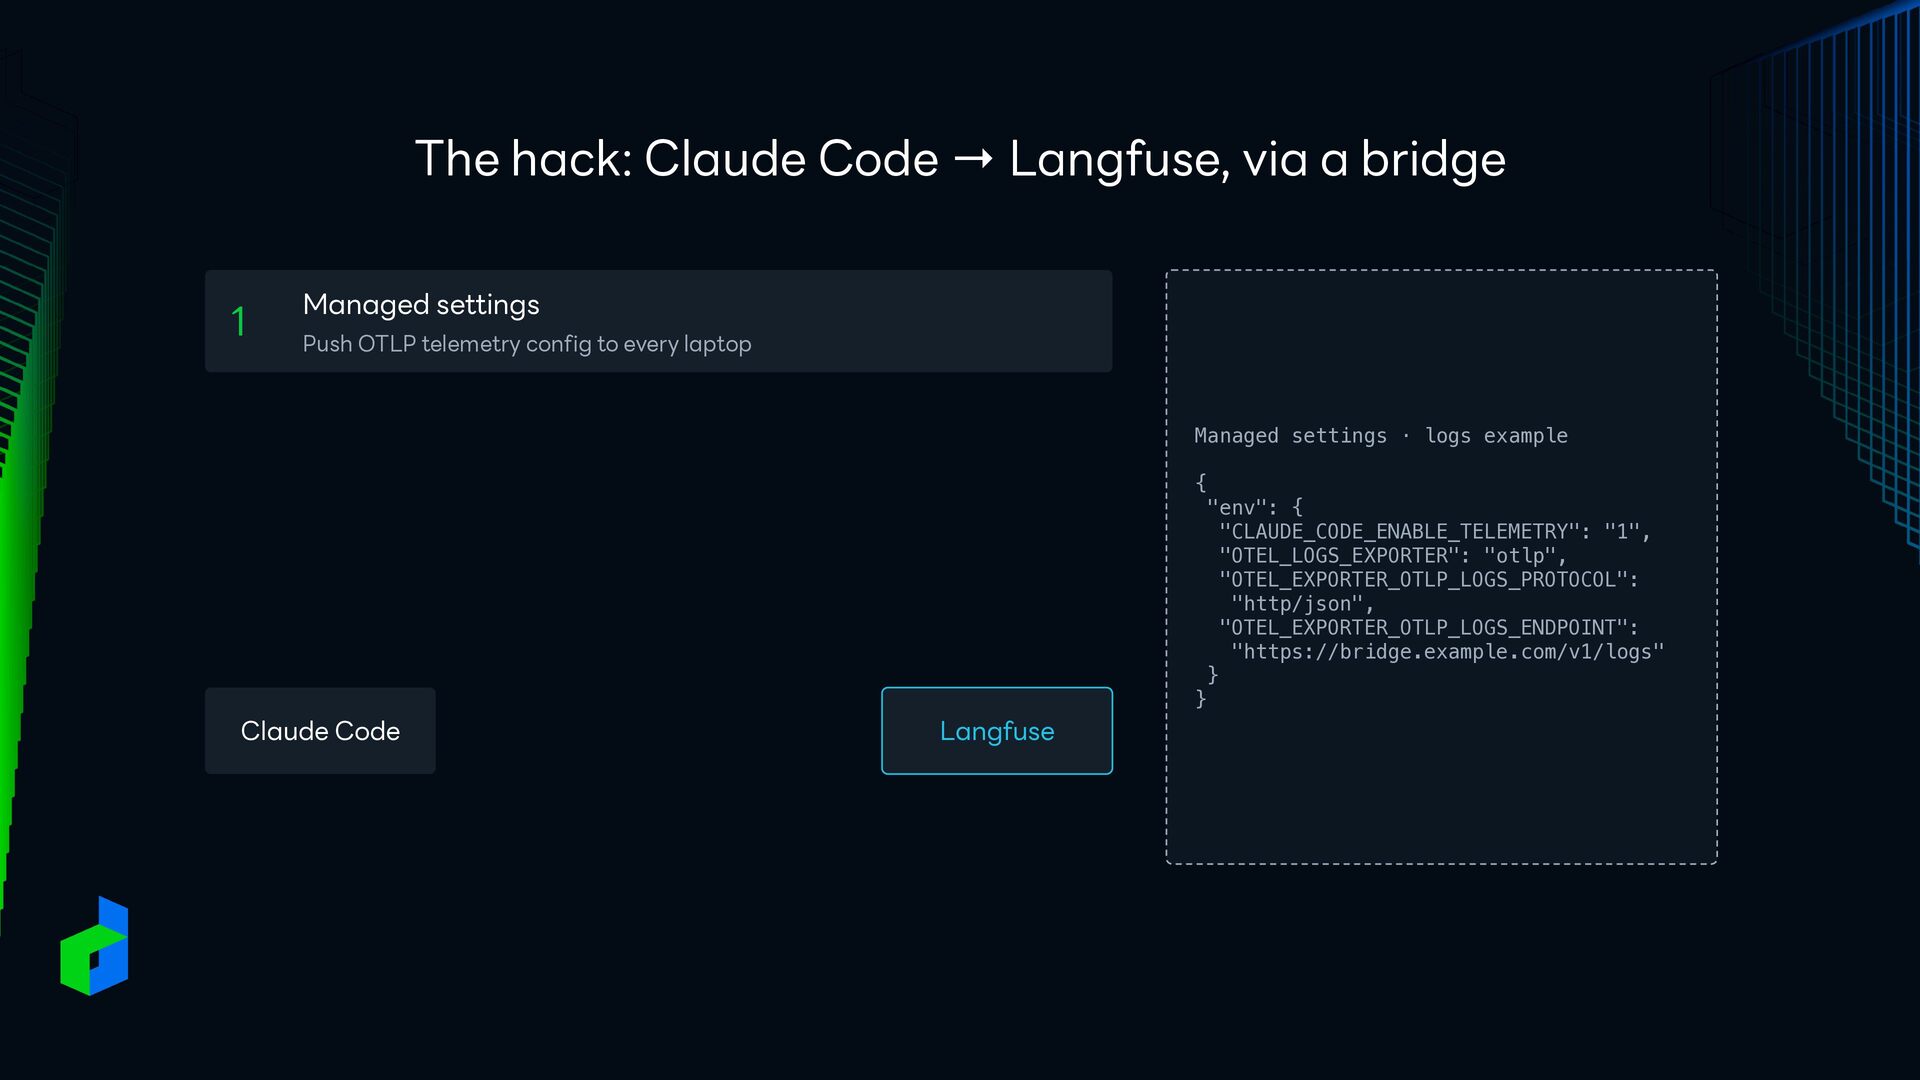
The hack: Claude Code → Langfuse, via a bridge 1
Managed settings Push OTLP telemetry config to every laptop Managed settings · logs example { "env": { "CLAUDE_CODE_ENABLE_TELEMETRY": "1", "OTEL_LOGS_EXPORTER": "otlp", "OTEL_EXPORTER_OTLP_LOGS_PROTOCOL": "http/json", "OTEL_EXPORTER_OTLP_LOGS_ENDPOINT": "https://bridge.example.com/v1/logs" } Claude Code Langfuse } -
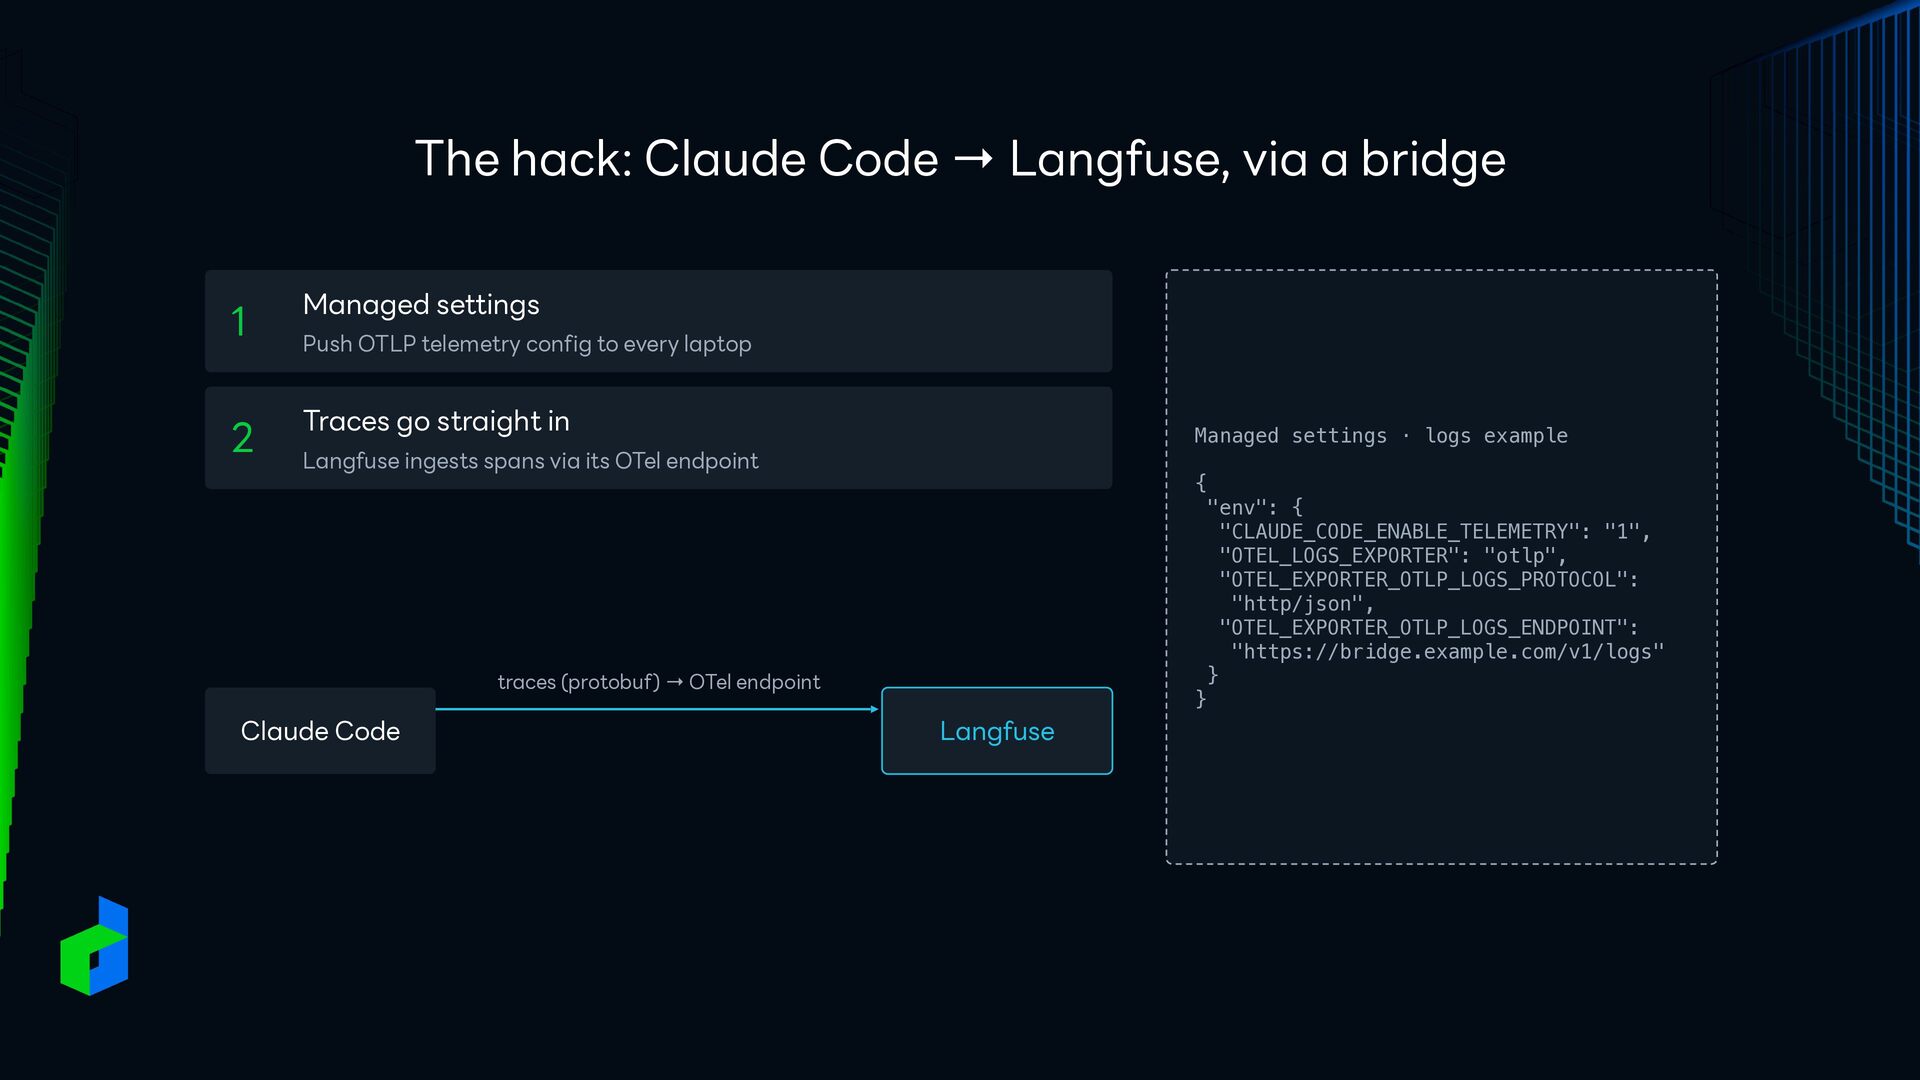
The hack: Claude Code → Langfuse, via a bridge 1
Managed settings 2 Traces go straight in Push OTLP telemetry config to every laptop Managed settings · logs example Langfuse ingests spans via its OTel endpoint { "env": { "CLAUDE_CODE_ENABLE_TELEMETRY": "1", "OTEL_LOGS_EXPORTER": "otlp", "OTEL_EXPORTER_OTLP_LOGS_PROTOCOL": "http/json", "OTEL_EXPORTER_OTLP_LOGS_ENDPOINT": "https://bridge.example.com/v1/logs" } traces (protobuf) → OTel endpoint Claude Code Langfuse } -
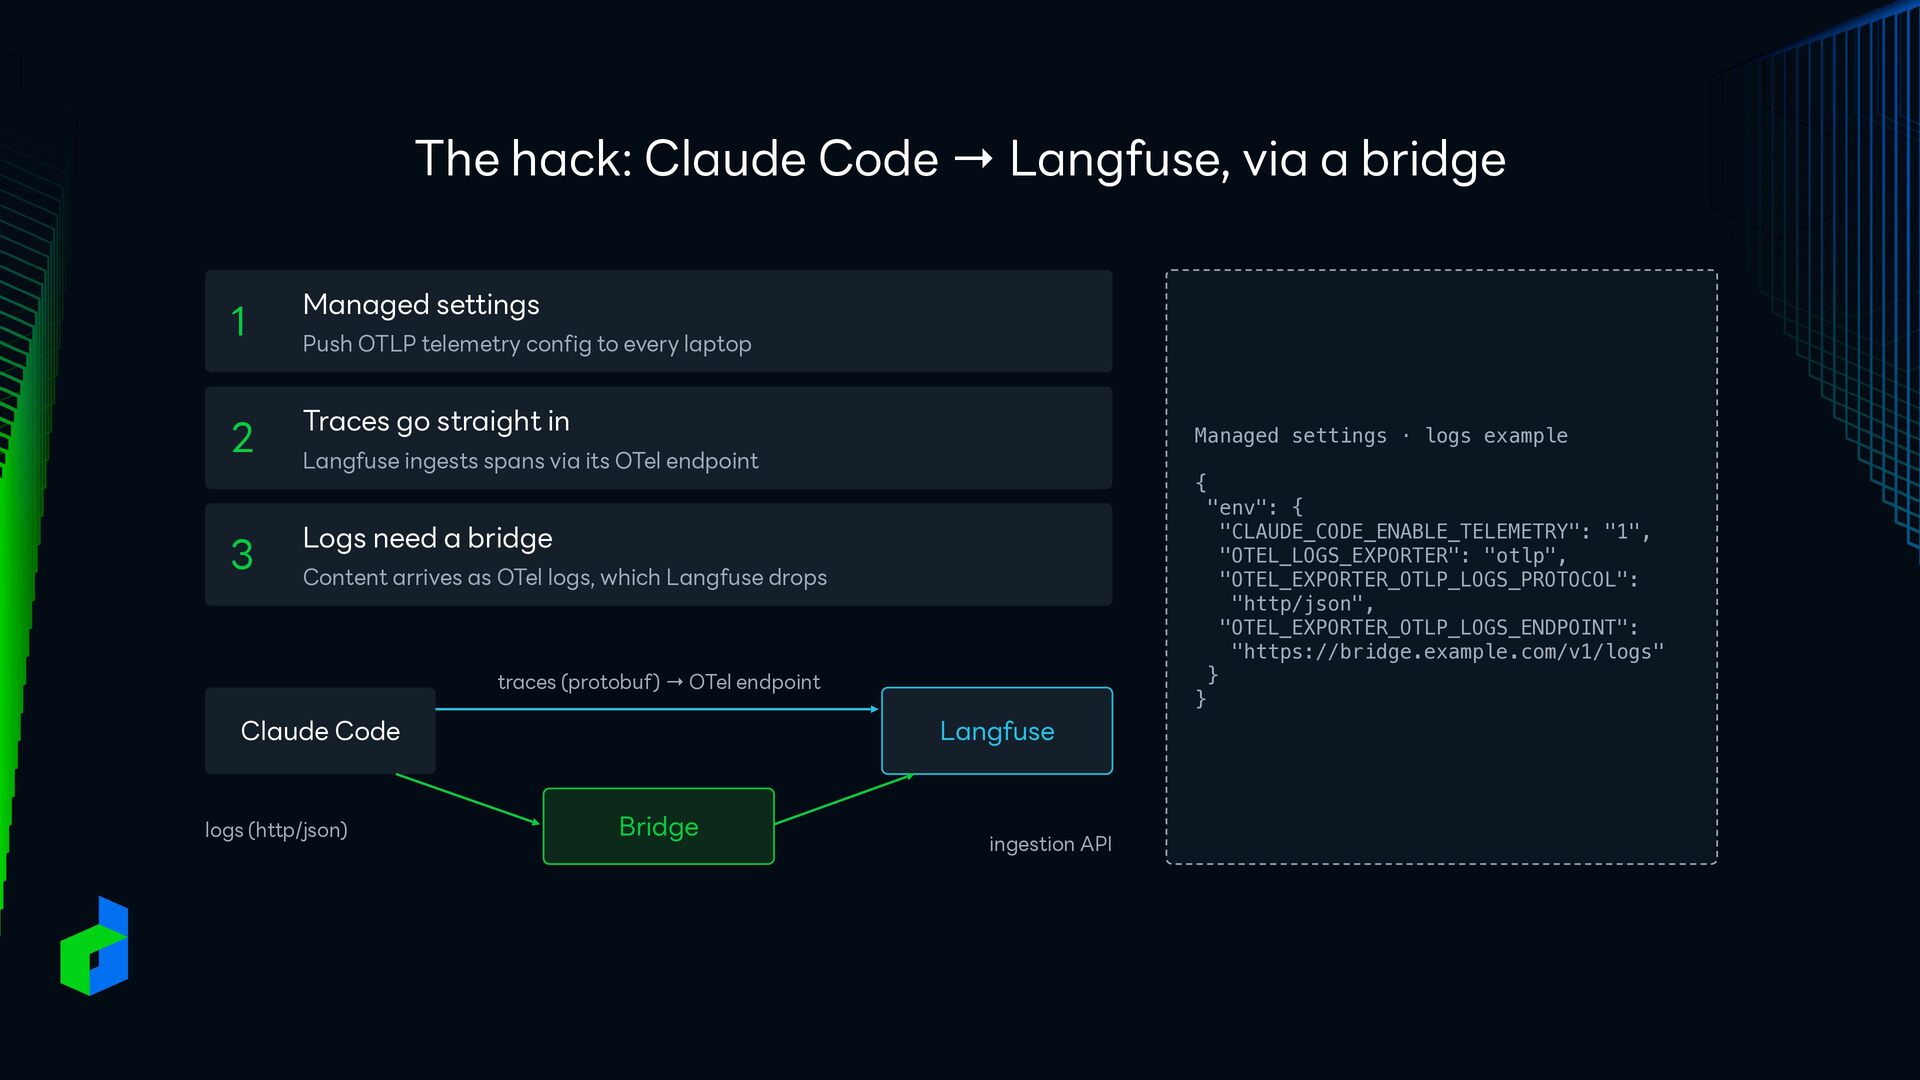
The hack: Claude Code → Langfuse, via a bridge 1
Managed settings 2 Traces go straight in 3 Push OTLP telemetry config to every laptop Managed settings · logs example Langfuse ingests spans via its OTel endpoint { "env": { "CLAUDE_CODE_ENABLE_TELEMETRY": "1", "OTEL_LOGS_EXPORTER": "otlp", "OTEL_EXPORTER_OTLP_LOGS_PROTOCOL": "http/json", "OTEL_EXPORTER_OTLP_LOGS_ENDPOINT": "https://bridge.example.com/v1/logs" } Logs need a bridge Content arrives as OTel logs, which Langfuse drops traces (protobuf) → OTel endpoint Claude Code logs (http/json) Langfuse Bridge ingestion API } -
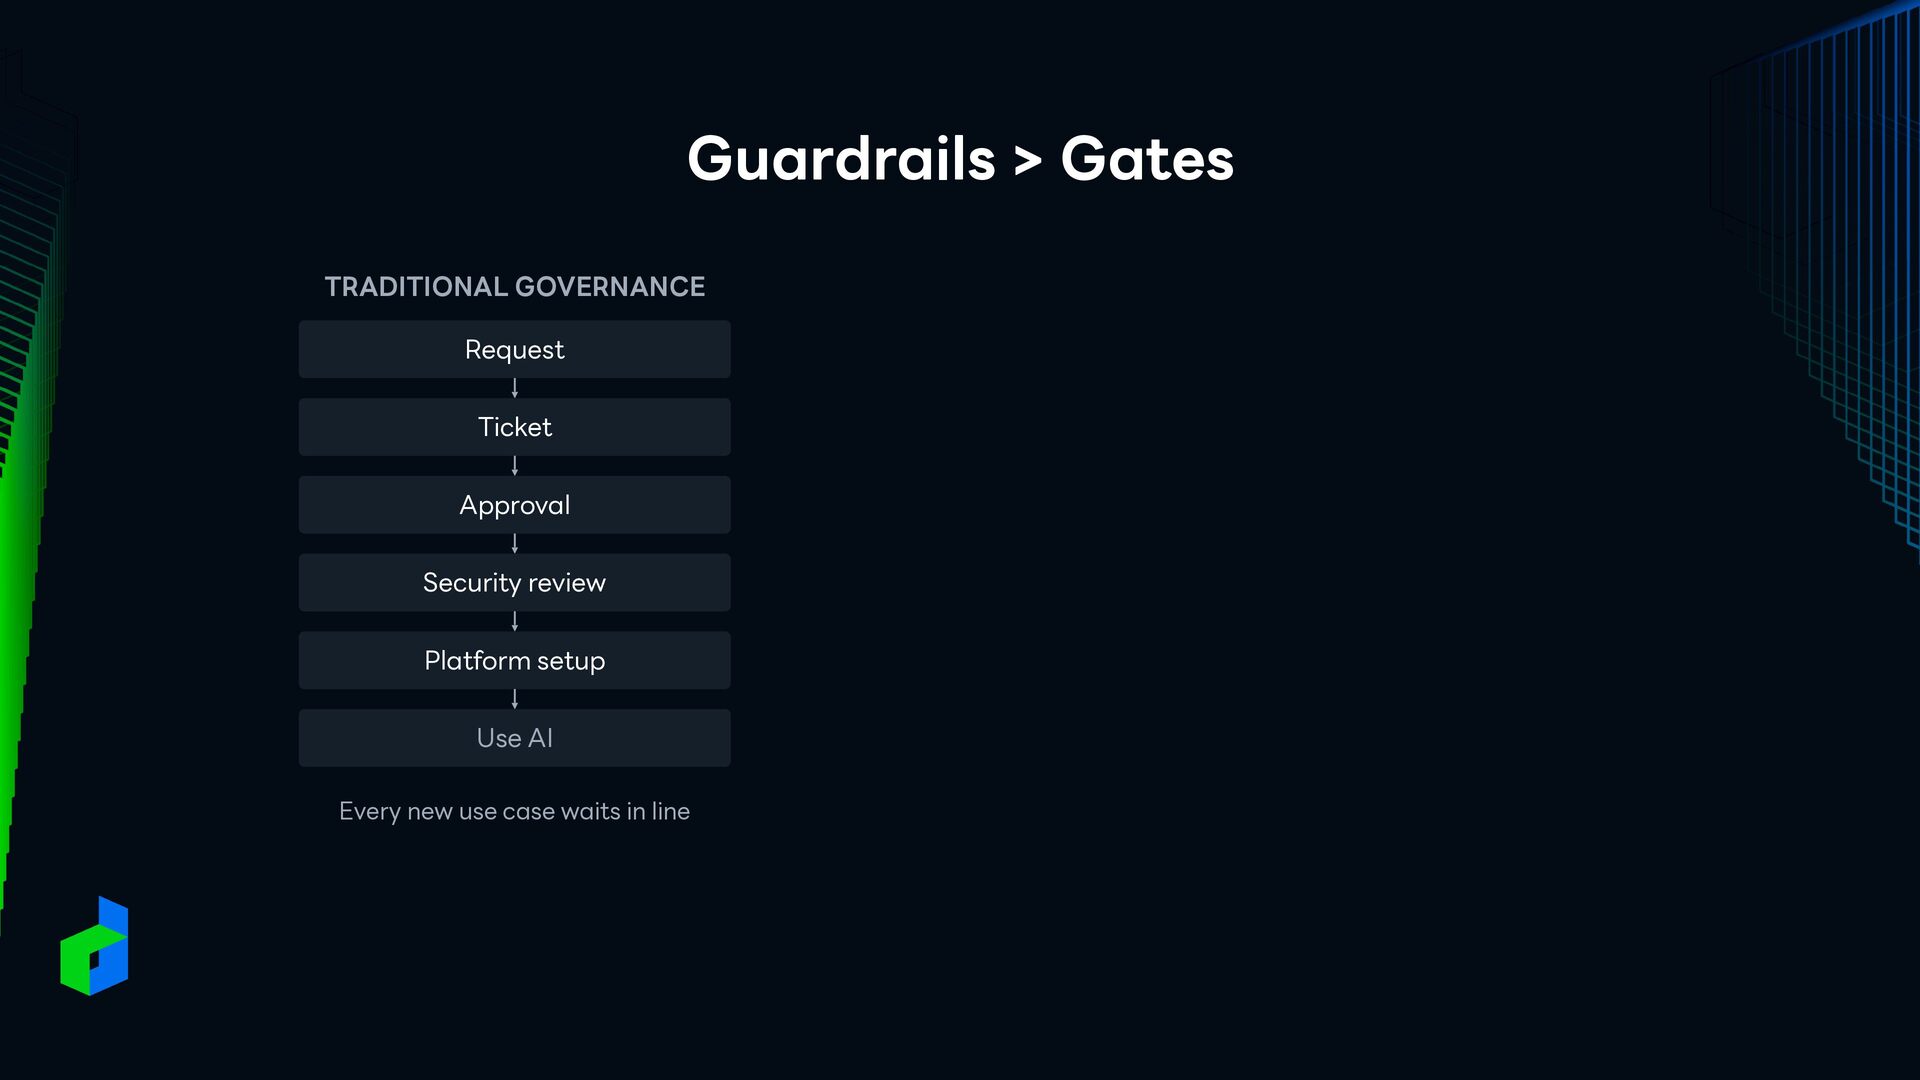
Guardrails > Gates TRADITIONAL GOVERNANCE Request Ticket Approval Security review
Platform setup Use AI Every new use case waits in line -
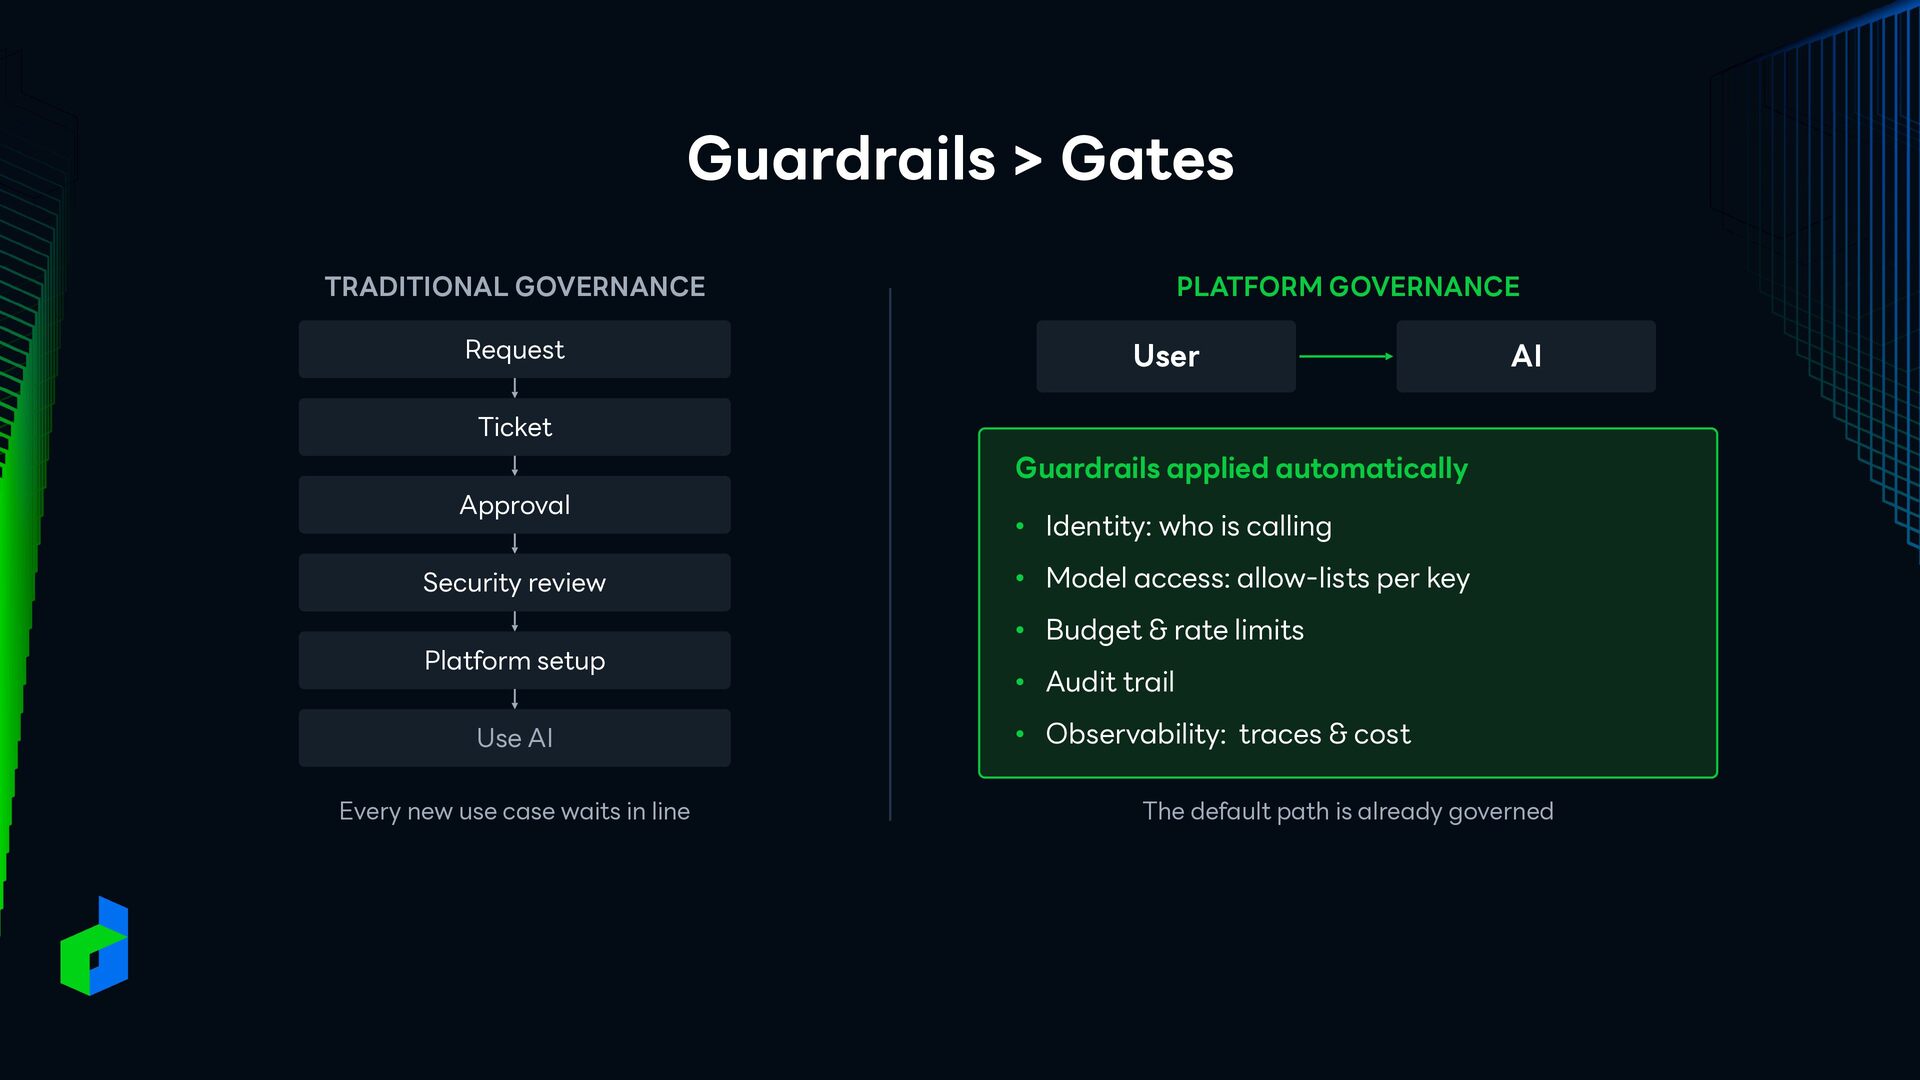
Guardrails > Gates TRADITIONAL GOVERNANCE Request Ticket Approval Security review
Platform setup Use AI Every new use case waits in line PLATFORM GOVERNANCE User AI Guardrails applied automatically • Identity: who is calling • Model access: allow-lists per key • Budget & rate limits • Audit trail • Observability: traces & cost The default path is already governed -
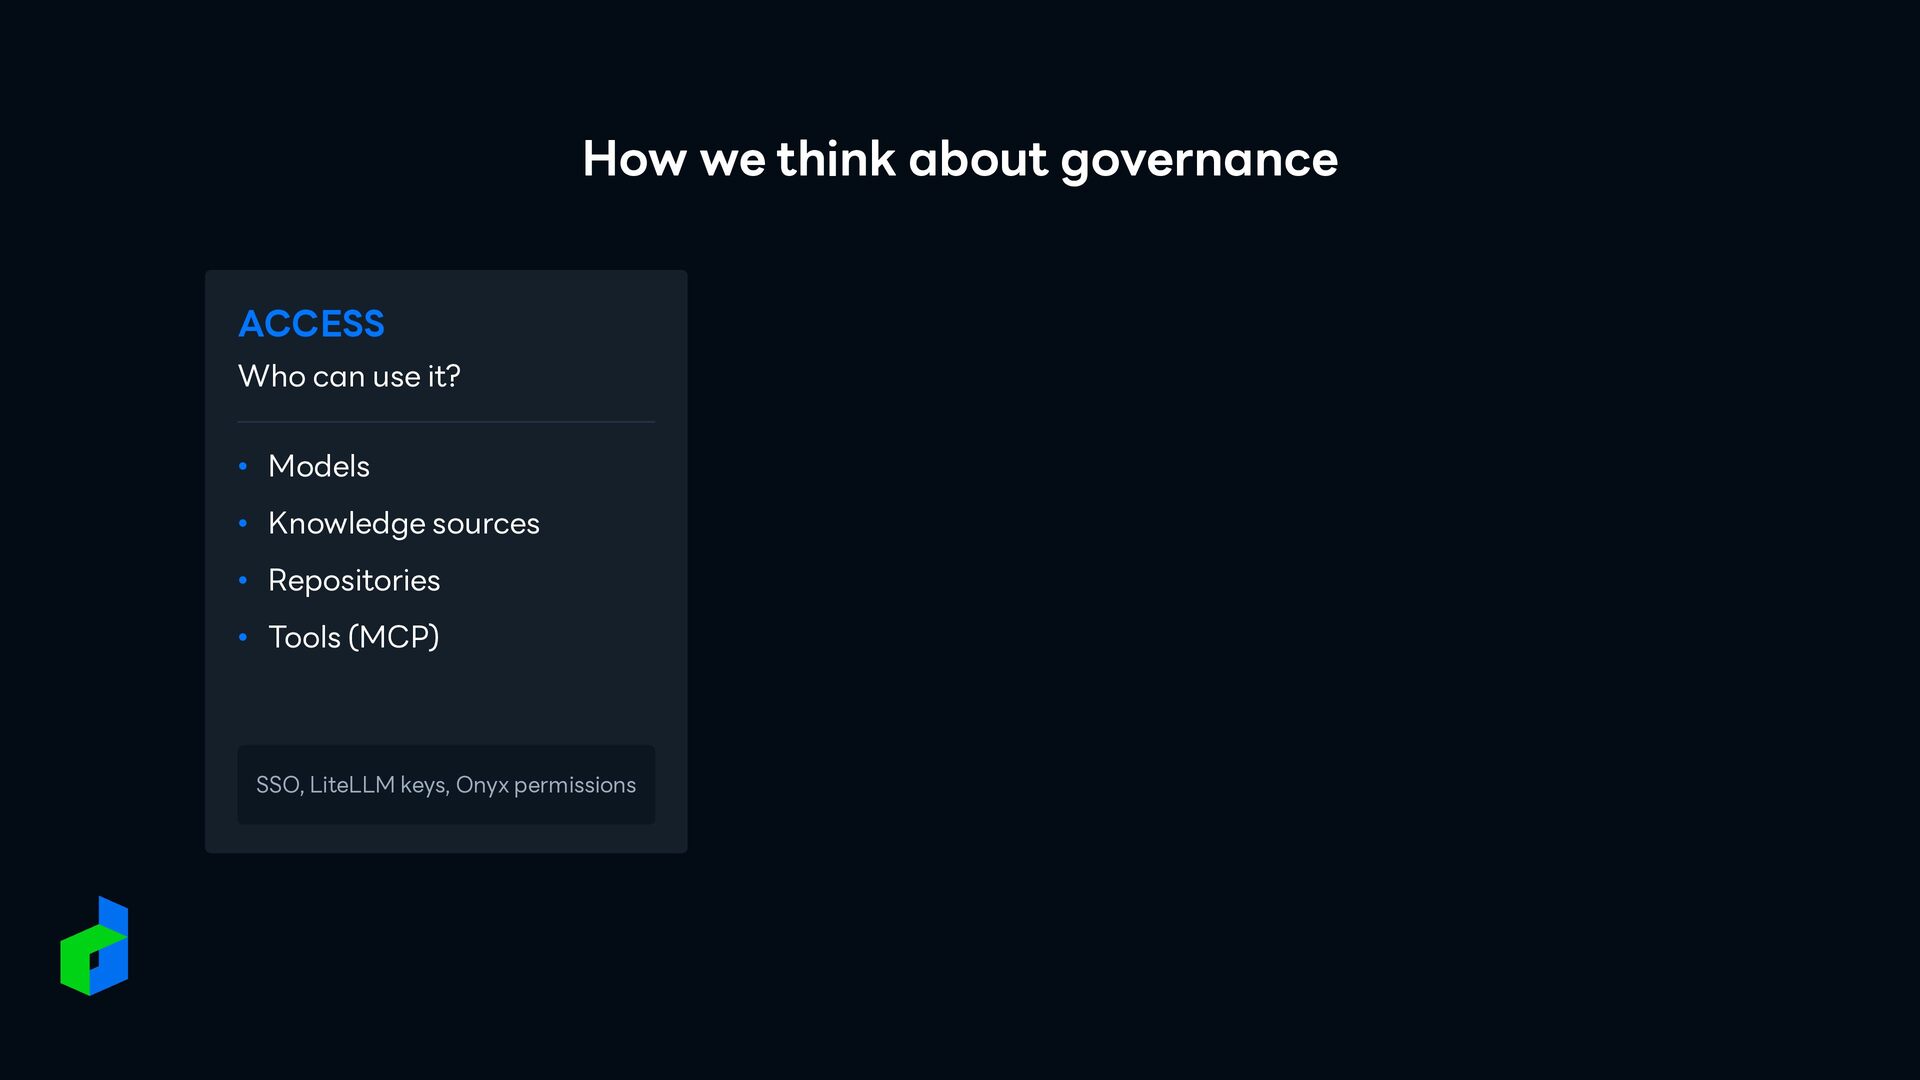
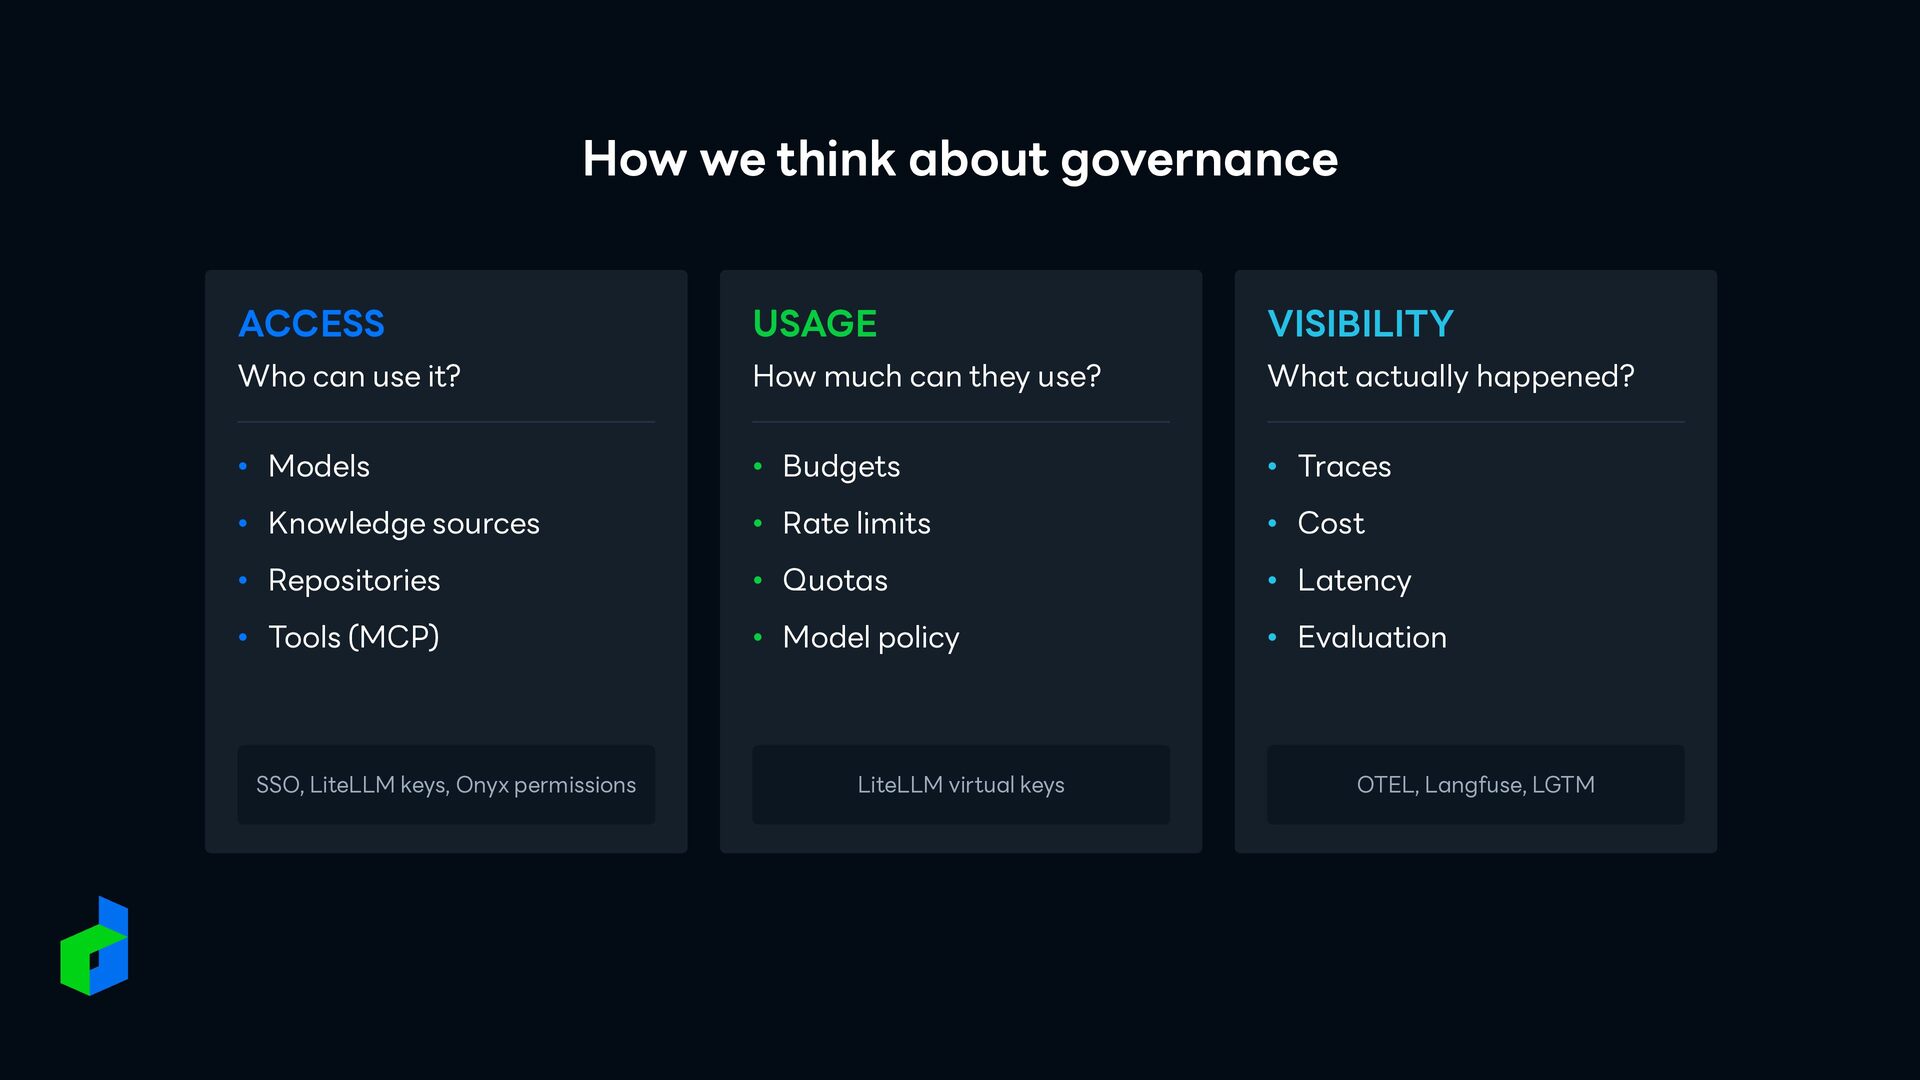
How we think about governance ACCESS Who can use it?
• Models • Knowledge sources • Repositories • Tools (MCP) SSO, LiteLLM keys, Onyx permissions -
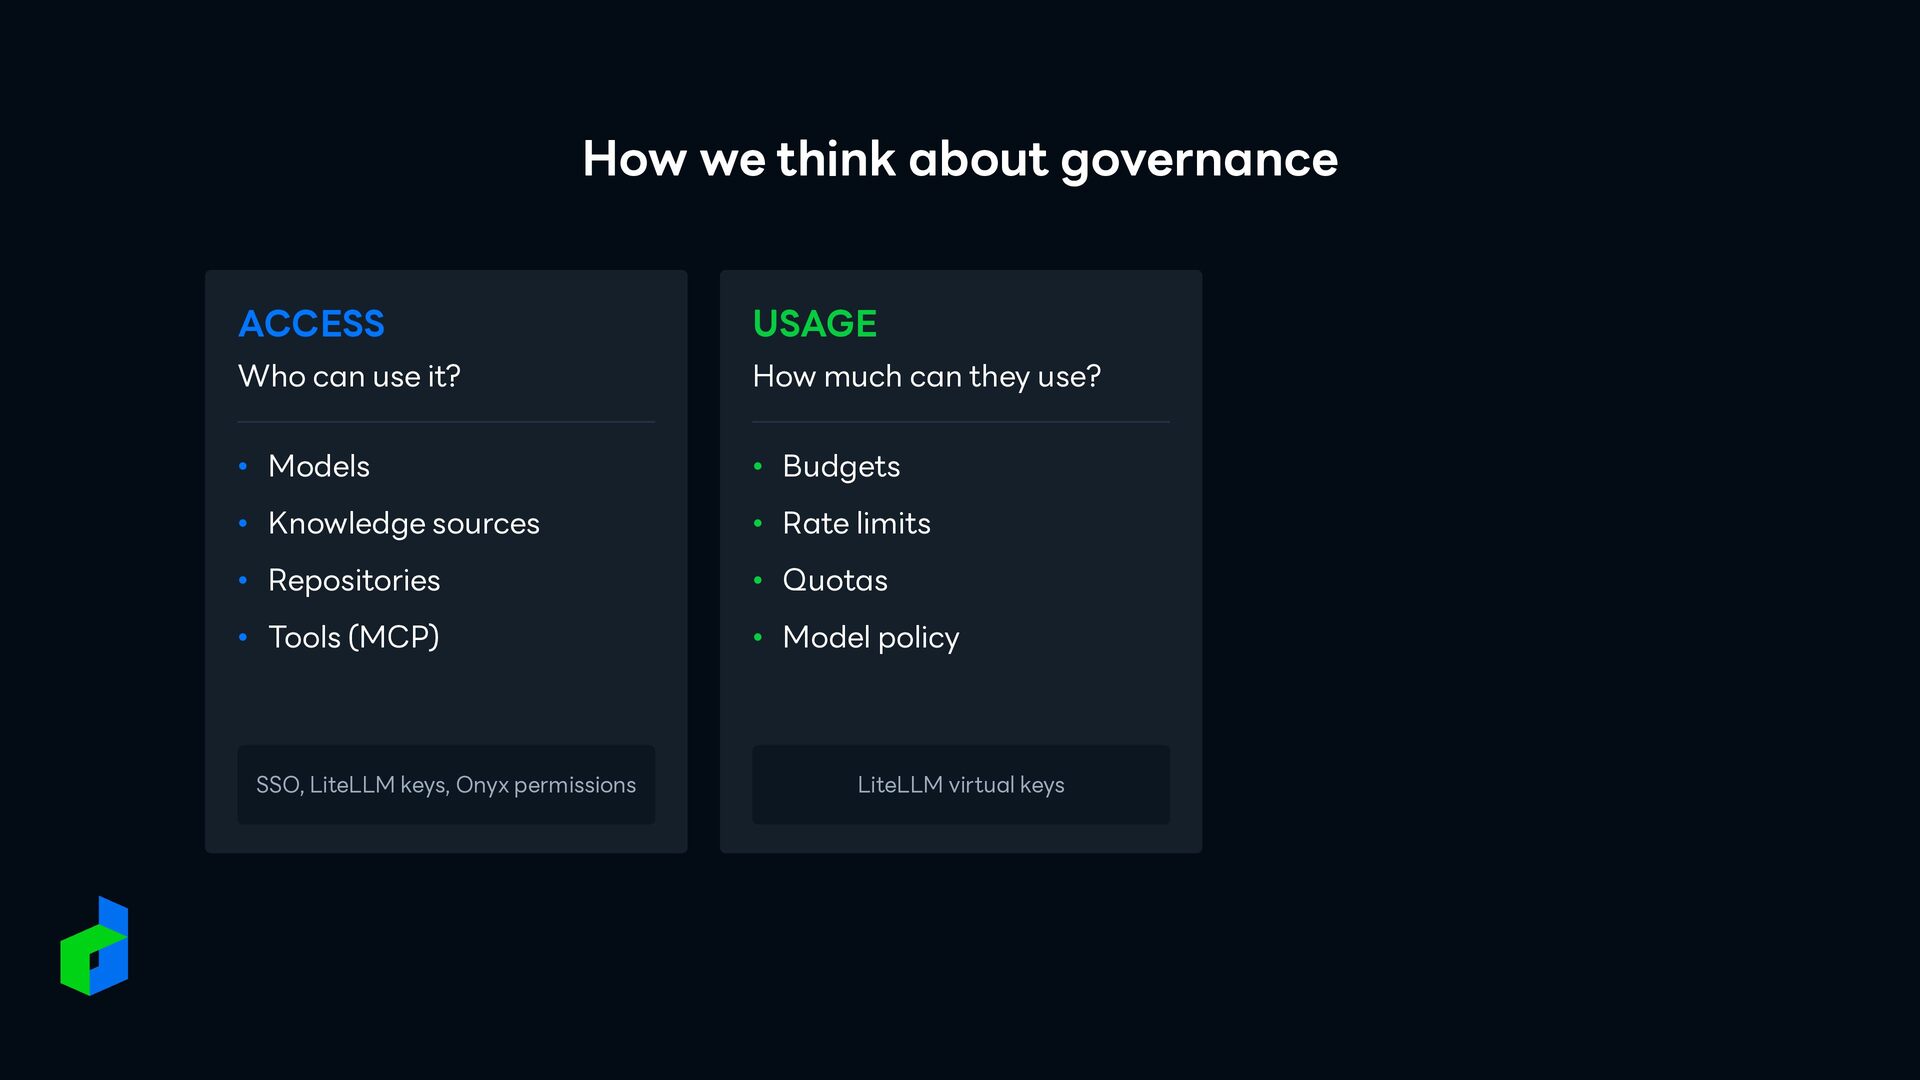
How we think about governance ACCESS USAGE Who can use
it? How much can they use? • Models • Budgets • Knowledge sources • Rate limits • Repositories • Quotas • Tools (MCP) • Model policy SSO, LiteLLM keys, Onyx permissions LiteLLM virtual keys -
How we think about governance ACCESS USAGE VISIBILITY Who can
use it? How much can they use? What actually happened? • Models • Budgets • Traces • Knowledge sources • Rate limits • Cost • Repositories • Quotas • Latency • Tools (MCP) • Model policy • Evaluation SSO, LiteLLM keys, Onyx permissions LiteLLM virtual keys OTEL, Langfuse, LGTM -
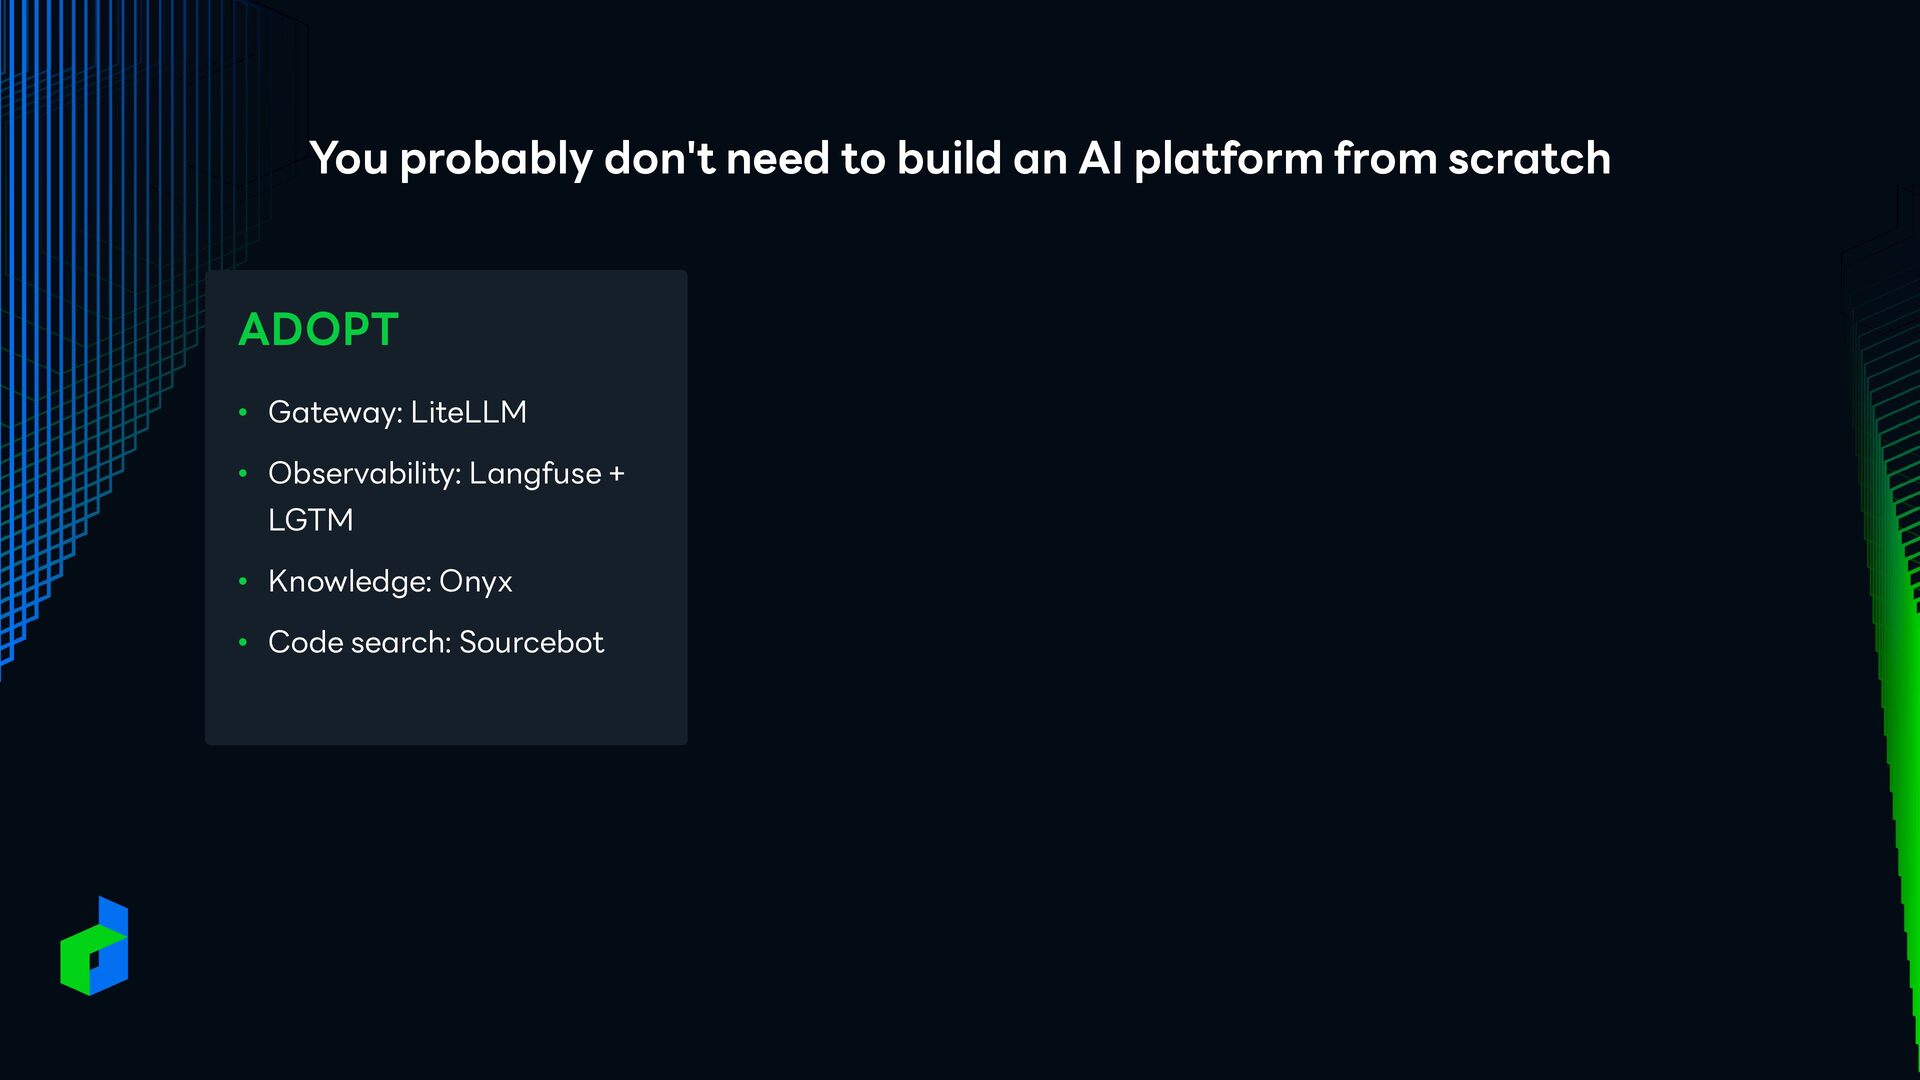
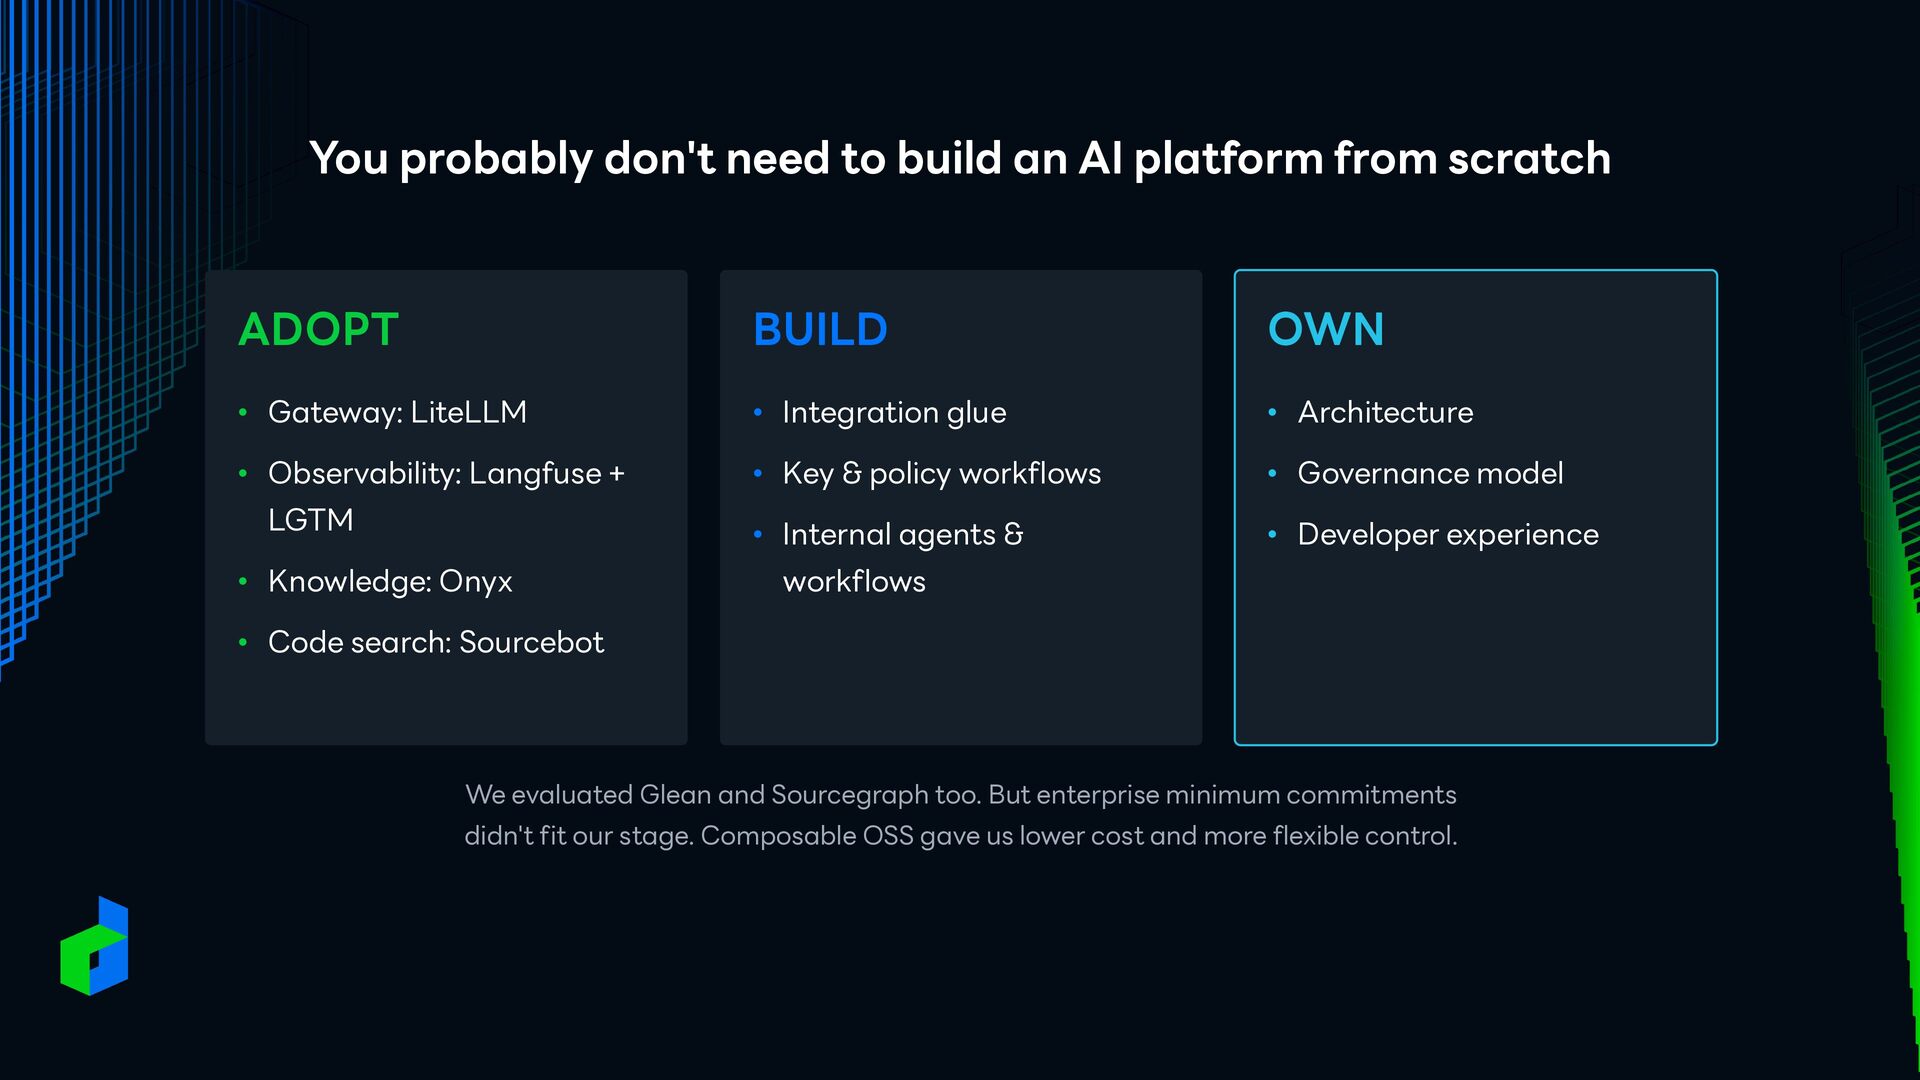
You probably don't need to build an AI platform from
scratch ADOPT • Gateway: LiteLLM • Observability: Langfuse + LGTM • Knowledge: Onyx • Code search: Sourcebot -
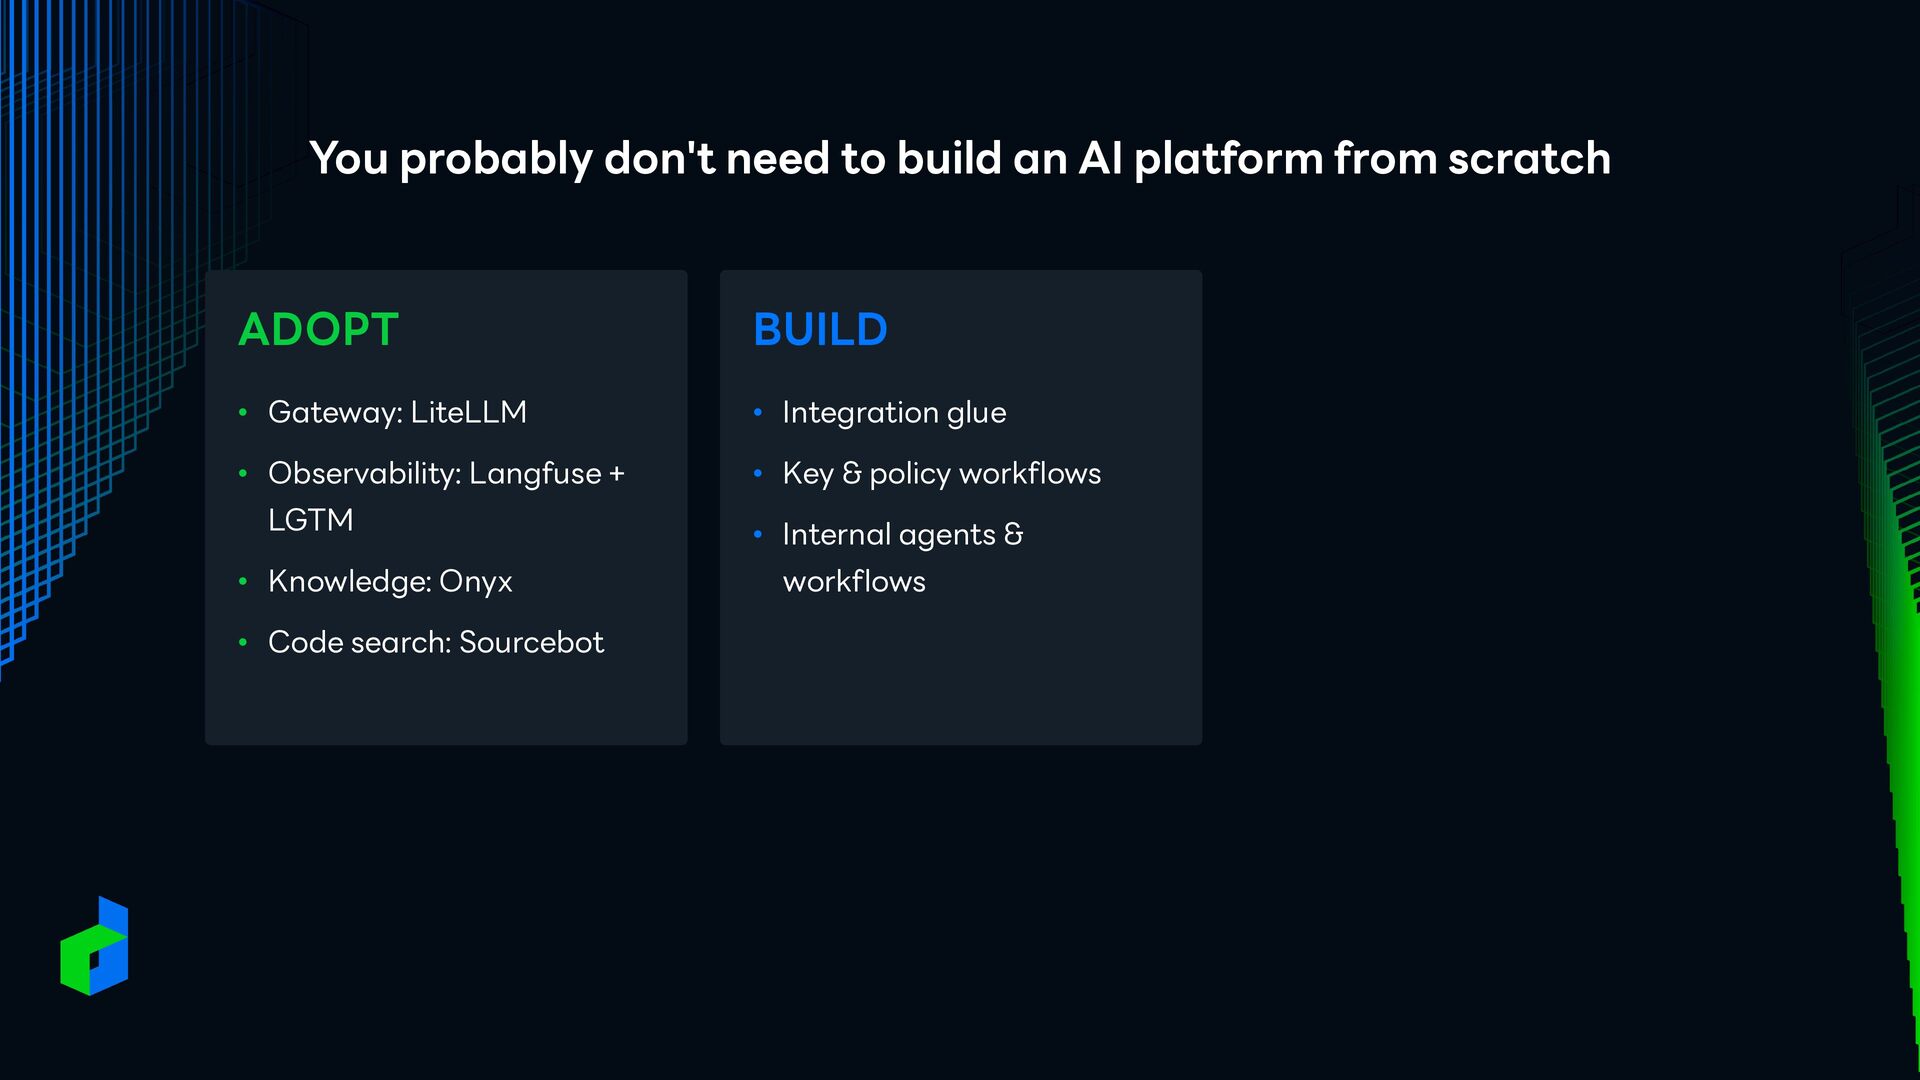
You probably don't need to build an AI platform from
scratch ADOPT BUILD • Gateway: LiteLLM • Integration glue • Observability: Langfuse + • Key & policy workflows LGTM • Knowledge: Onyx • Code search: Sourcebot • Internal agents & workflows -
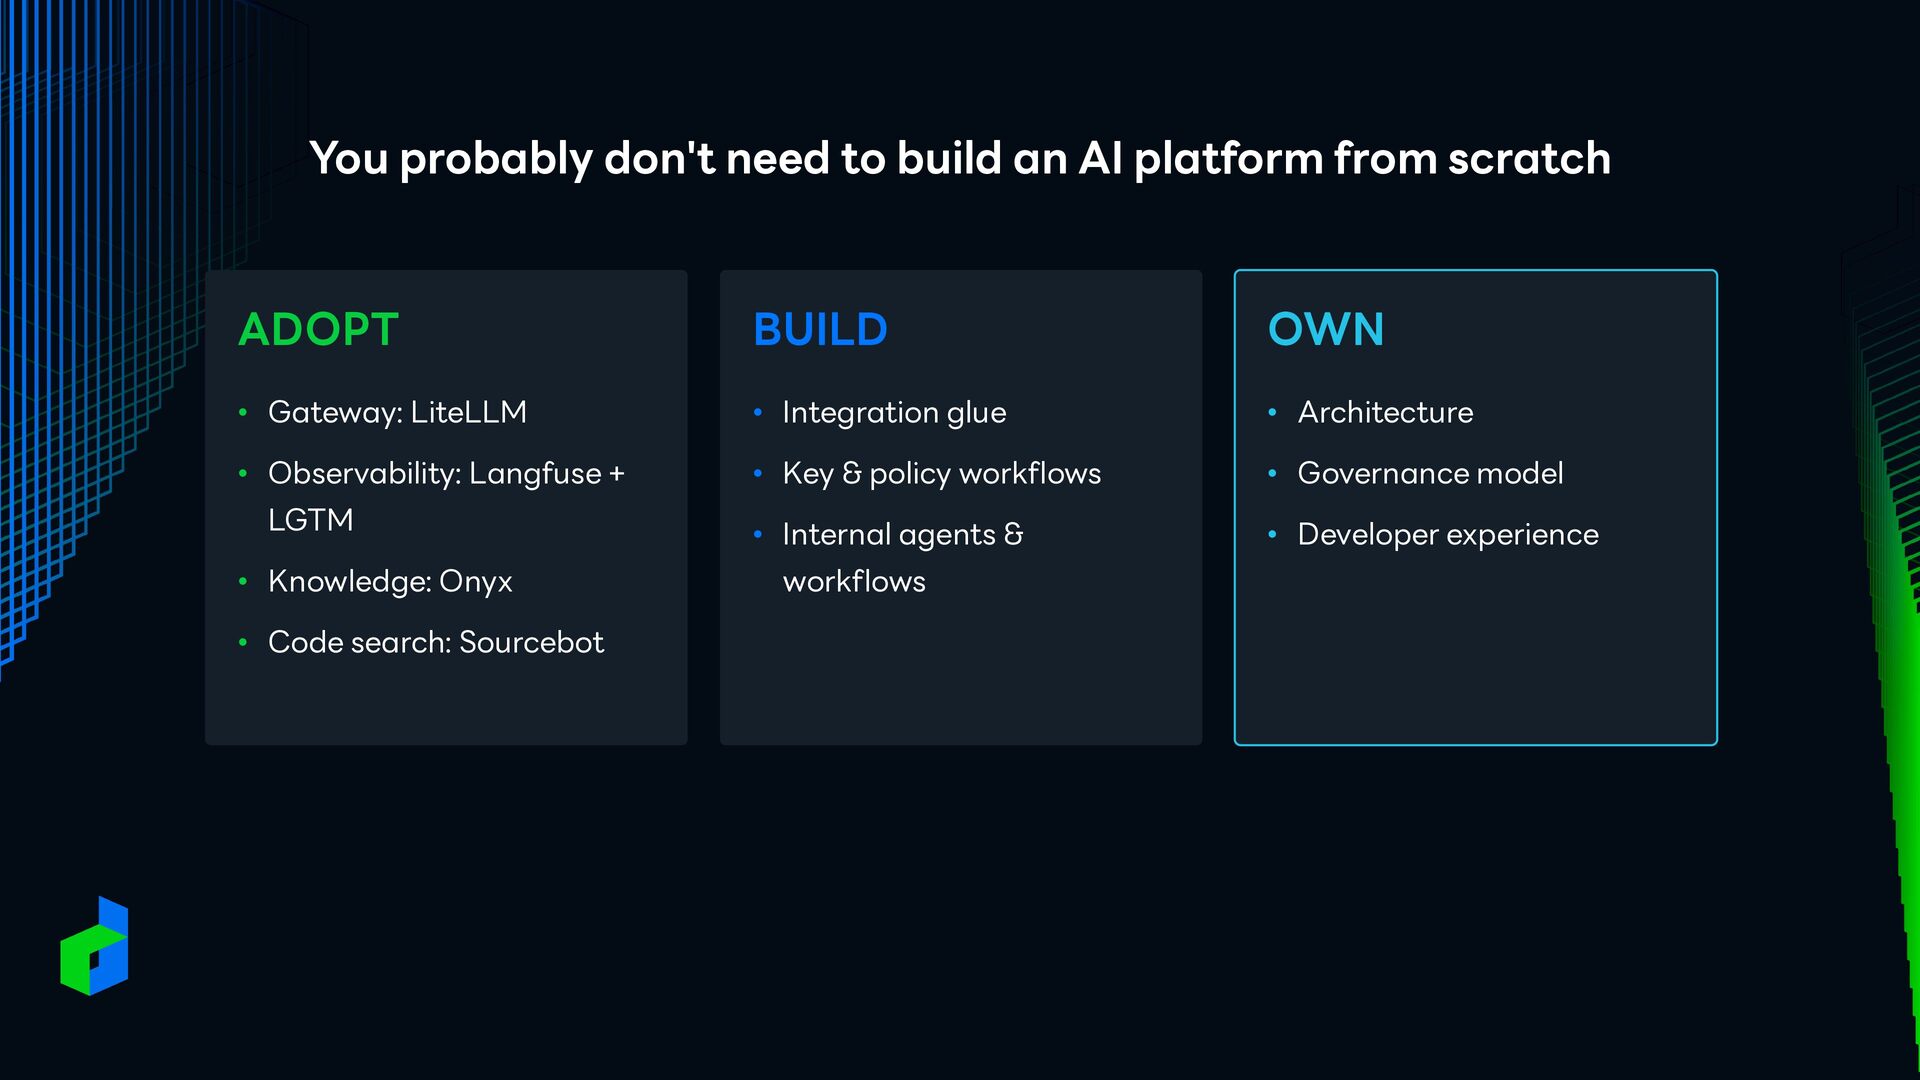
You probably don't need to build an AI platform from
scratch ADOPT BUILD OWN • Gateway: LiteLLM • Integration glue • Architecture • Observability: Langfuse + • Key & policy workflows • Governance model • Internal agents & • Developer experience LGTM • Knowledge: Onyx • Code search: Sourcebot workflows -
You probably don't need to build an AI platform from
scratch ADOPT BUILD OWN • Gateway: LiteLLM • Integration glue • Architecture • Observability: Langfuse + • Key & policy workflows • Governance model • Internal agents & • Developer experience LGTM • Knowledge: Onyx workflows • Code search: Sourcebot We evaluated Glean and Sourcegraph too. But enterprise minimum commitments didn't fit our stage. Composable OSS gave us lower cost and more flexible control. -
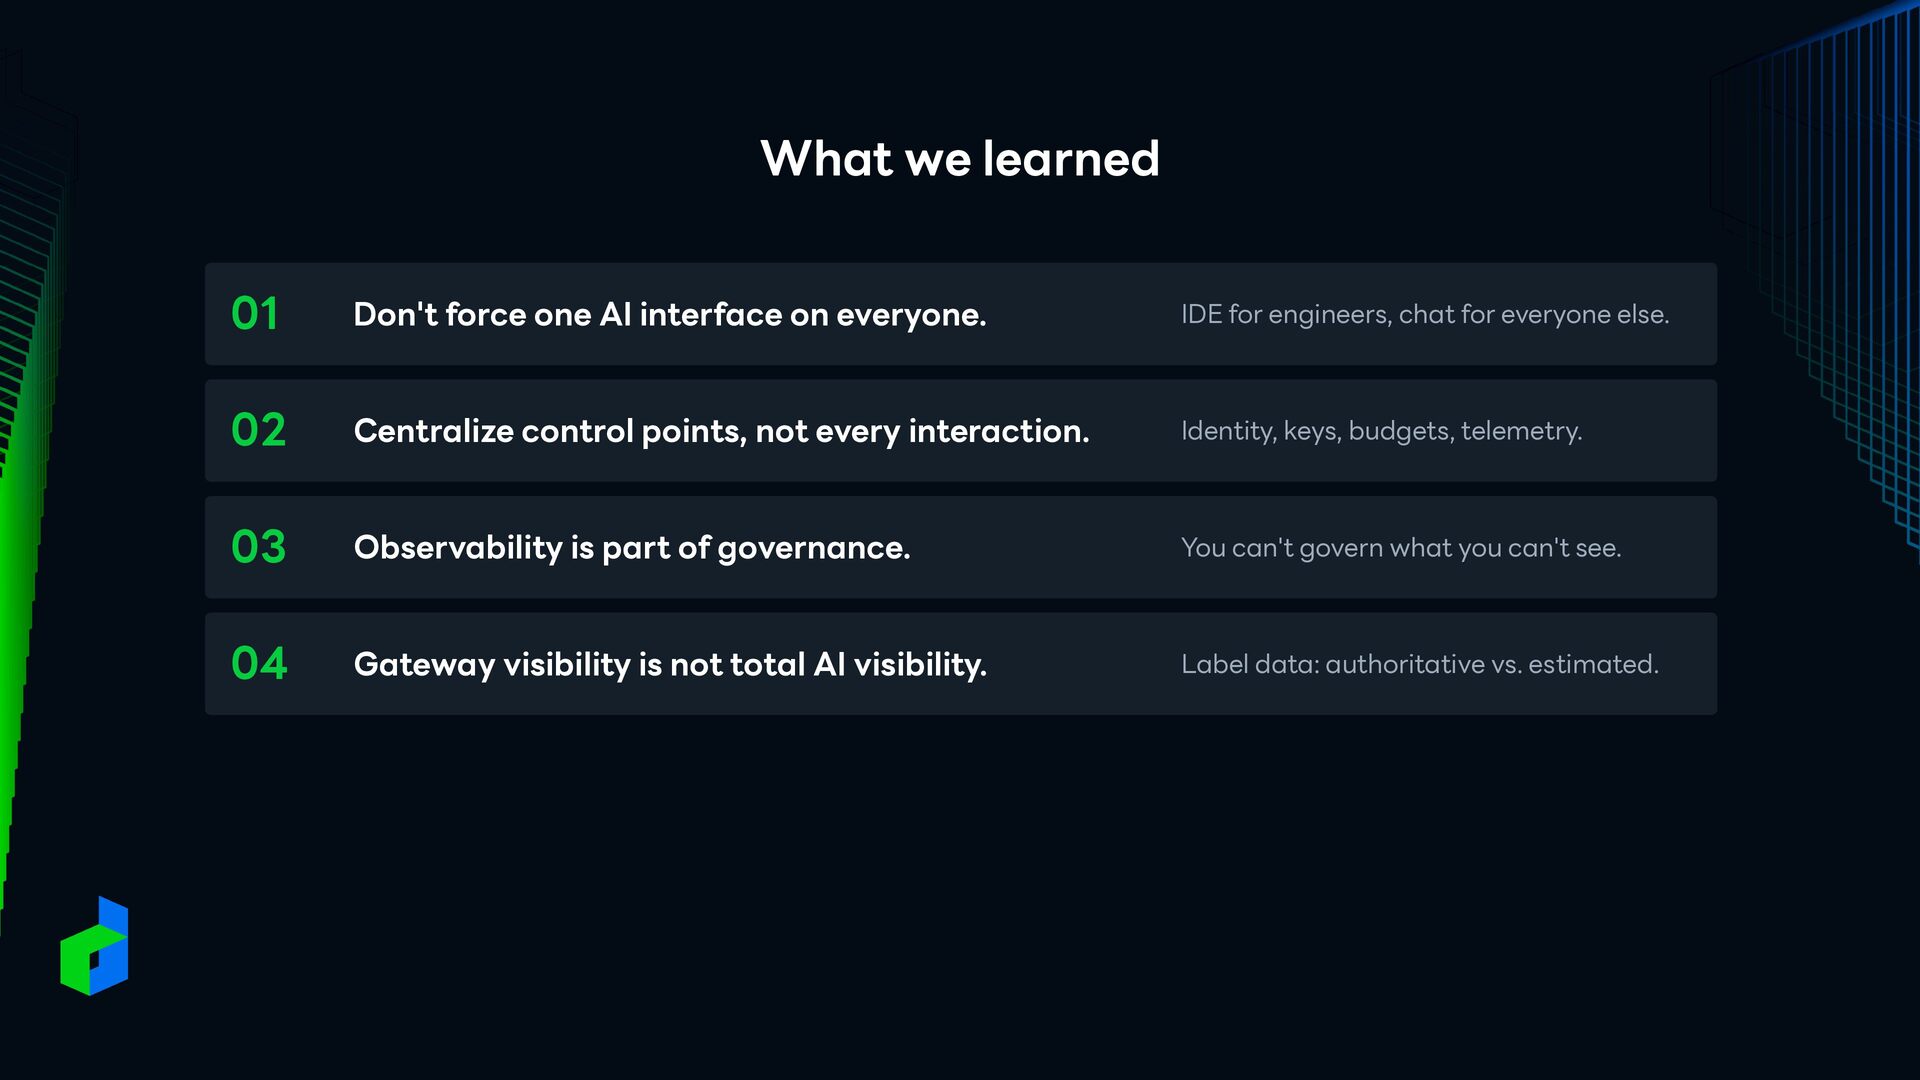
What we learned 01 Don't force one AI interface on
everyone. IDE for engineers, chat for everyone else. -
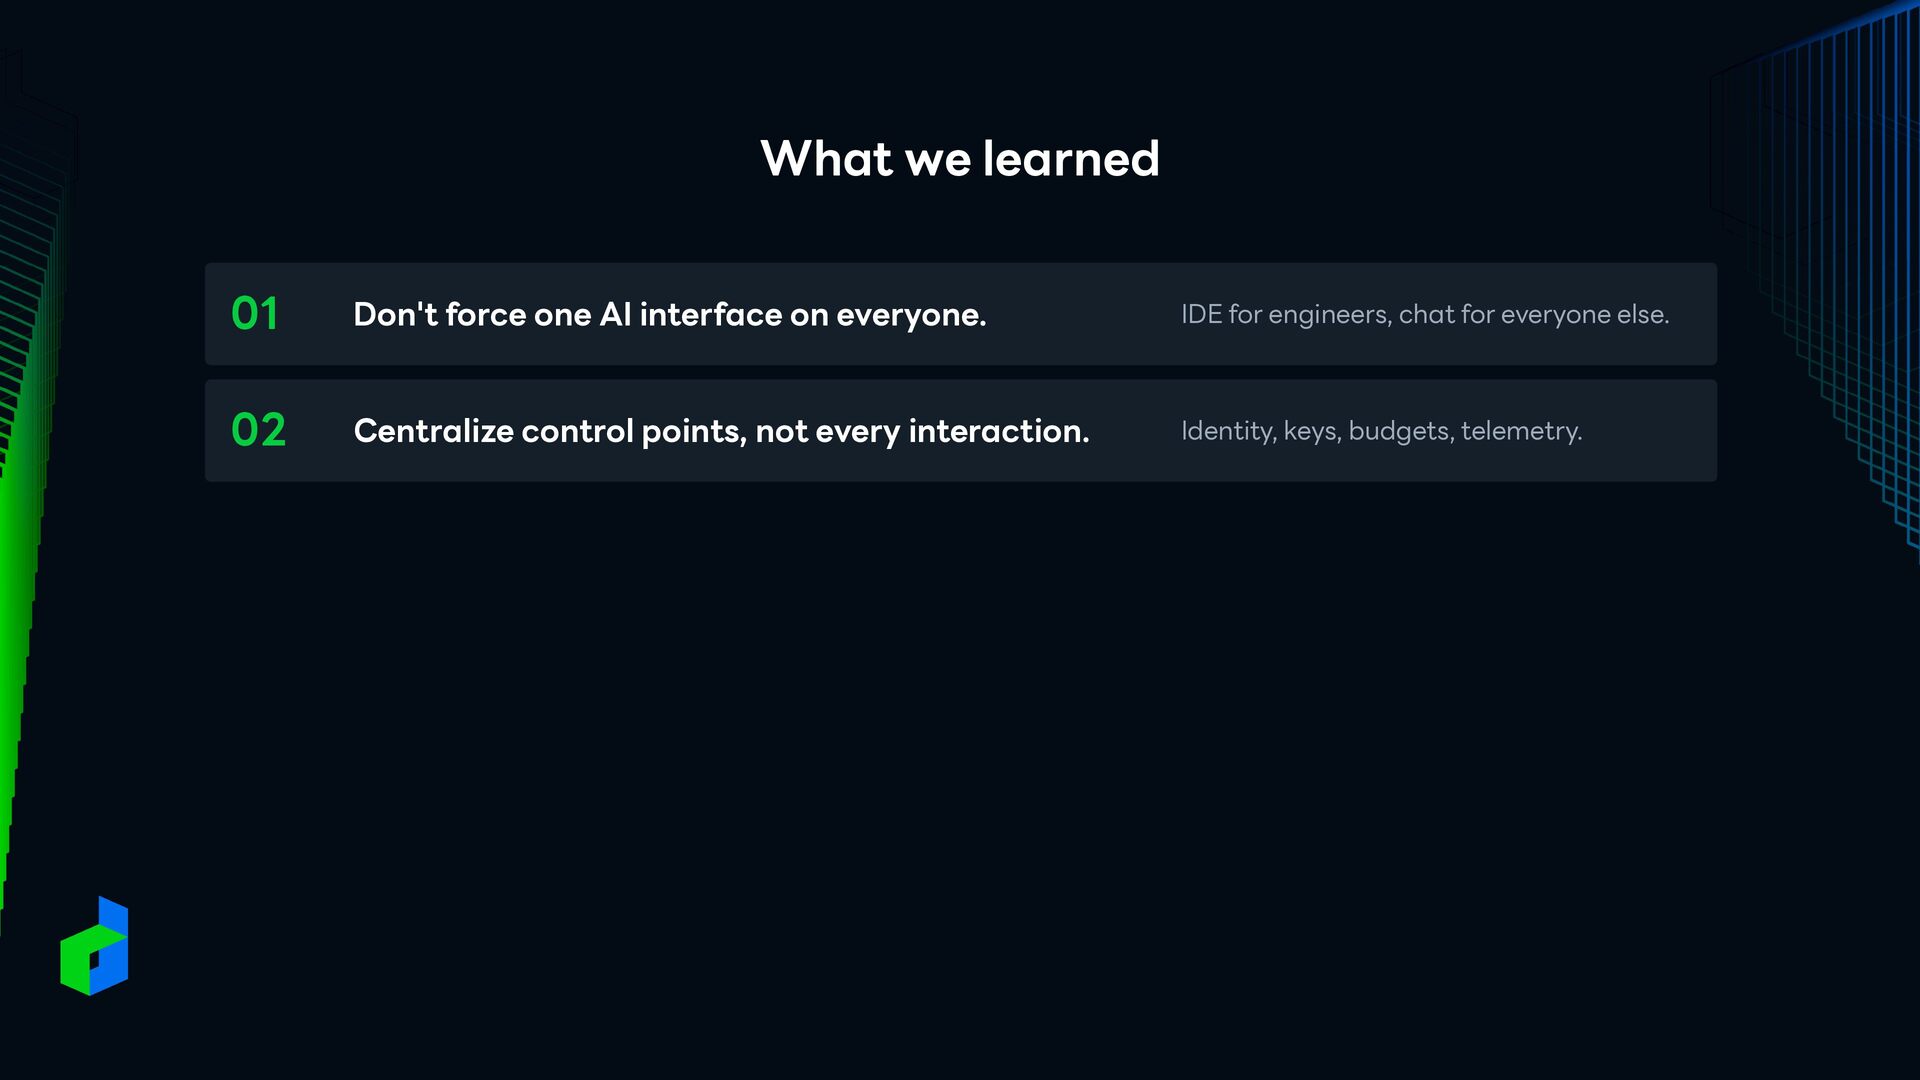
What we learned 01 Don't force one AI interface on
everyone. IDE for engineers, chat for everyone else. 02 Centralize control points, not every interaction. Identity, keys, budgets, telemetry. -
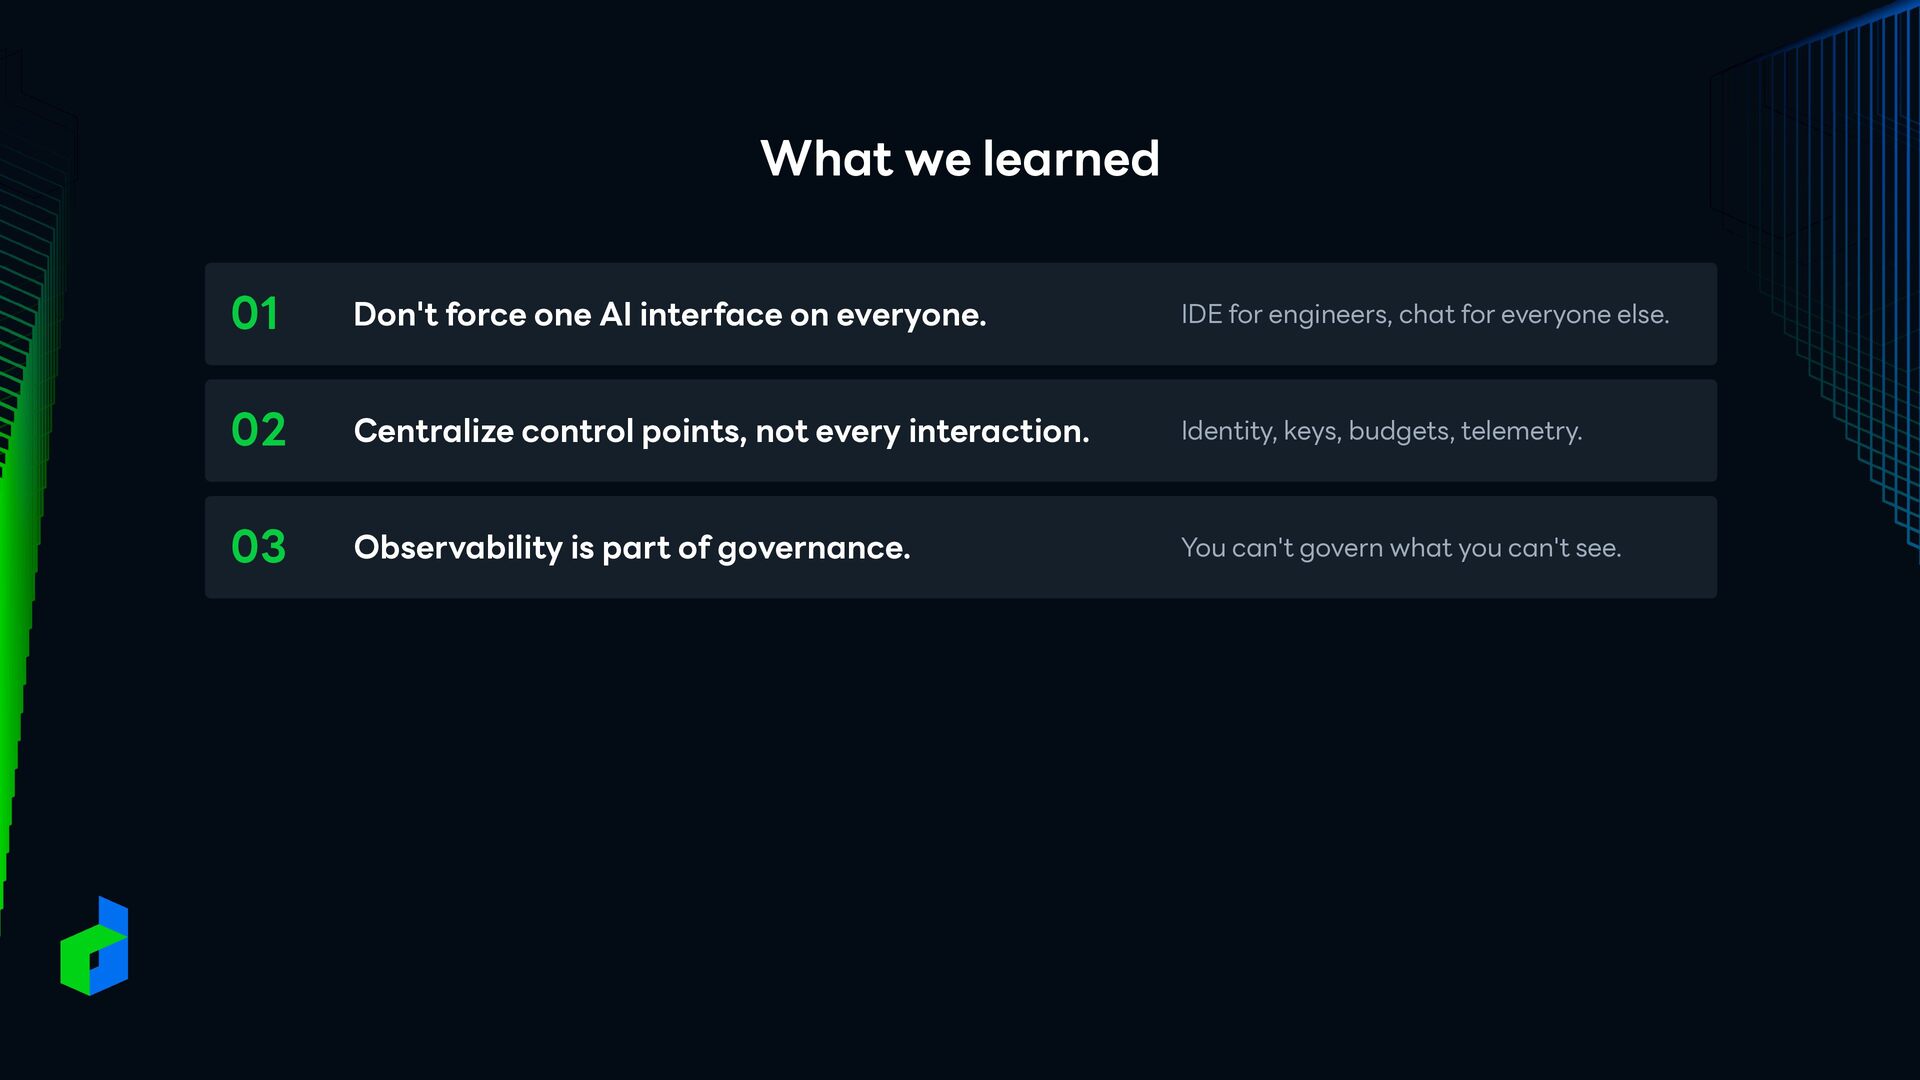
What we learned 01 Don't force one AI interface on
everyone. IDE for engineers, chat for everyone else. 02 Centralize control points, not every interaction. Identity, keys, budgets, telemetry. 03 Observability is part of governance. You can't govern what you can't see. -
What we learned 01 Don't force one AI interface on
everyone. IDE for engineers, chat for everyone else. 02 Centralize control points, not every interaction. Identity, keys, budgets, telemetry. 03 Observability is part of governance. You can't govern what you can't see. 04 Gateway visibility is not total AI visibility. Label data: authoritative vs. estimated. -
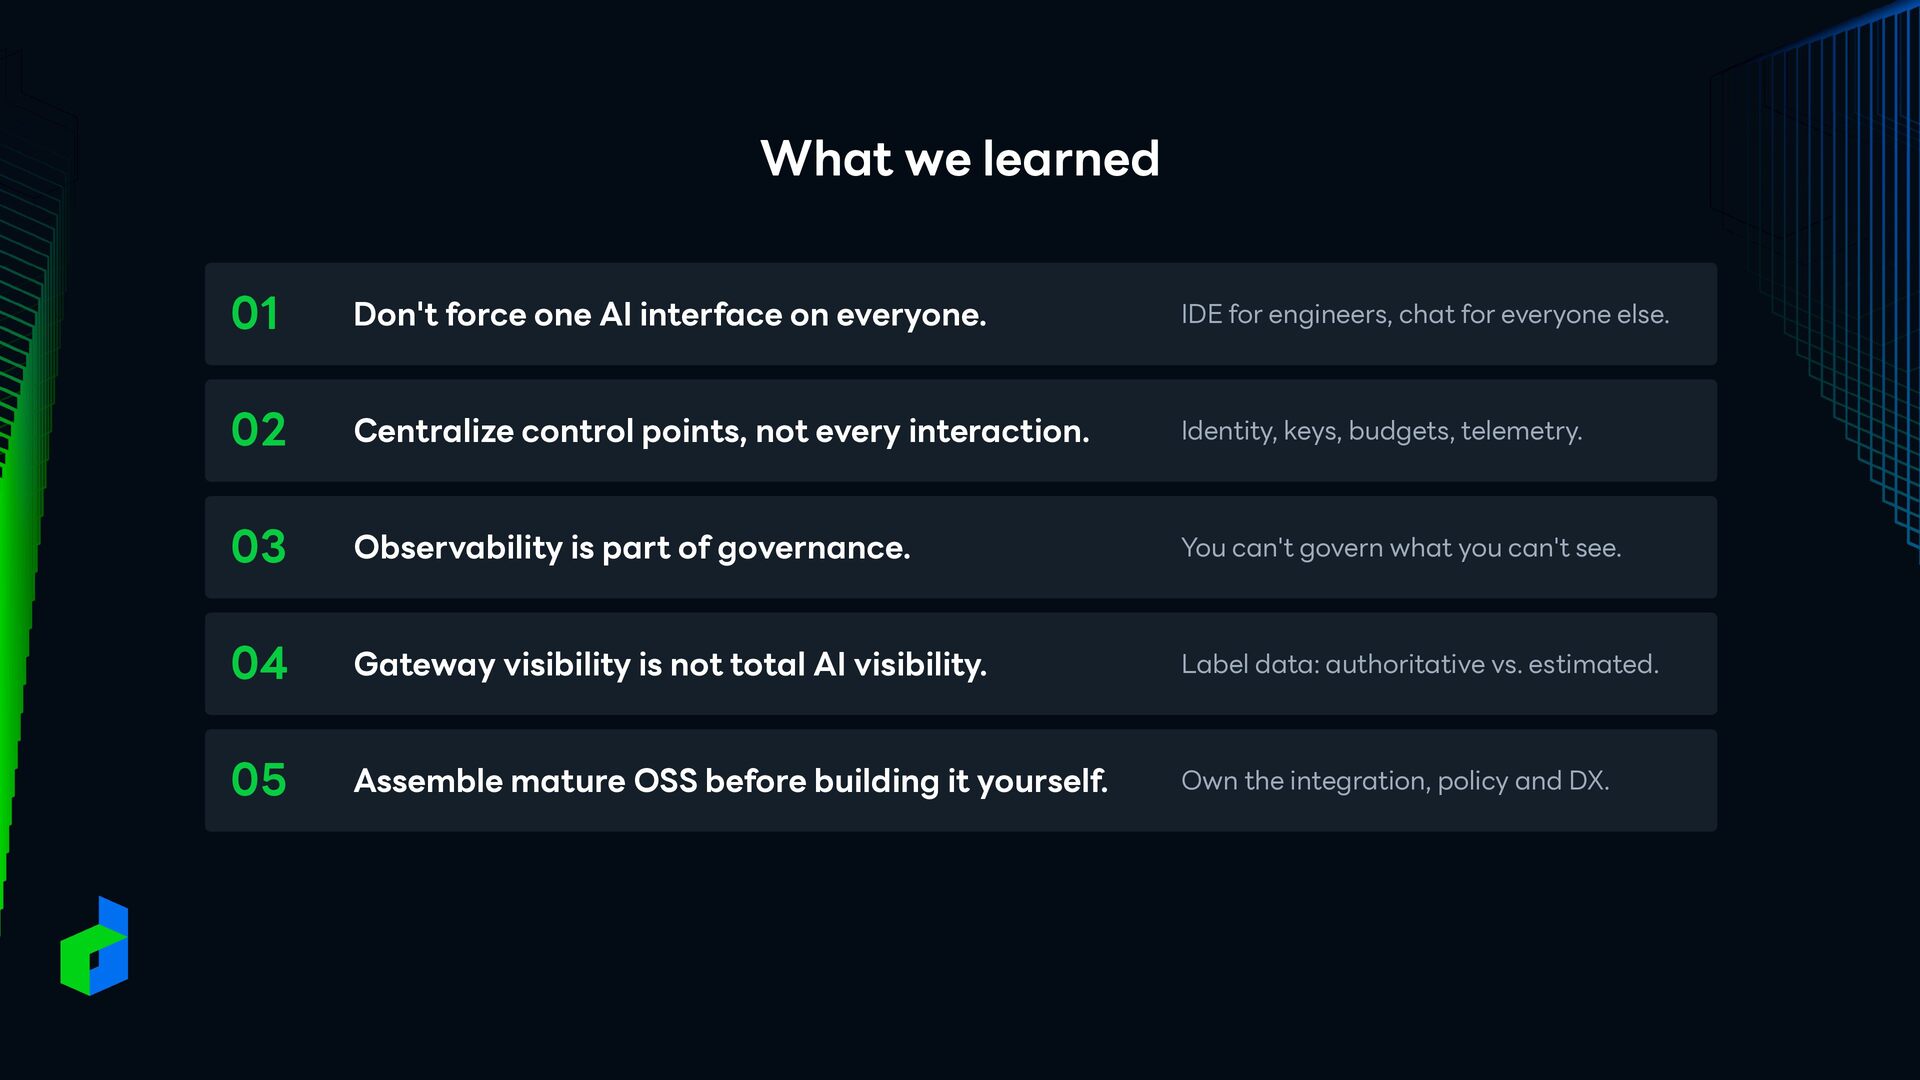
What we learned 01 Don't force one AI interface on
everyone. IDE for engineers, chat for everyone else. 02 Centralize control points, not every interaction. Identity, keys, budgets, telemetry. 03 Observability is part of governance. You can't govern what you can't see. 04 Gateway visibility is not total AI visibility. Label data: authoritative vs. estimated. 05 Assemble mature OSS before building it yourself. Own the integration, policy and DX. -
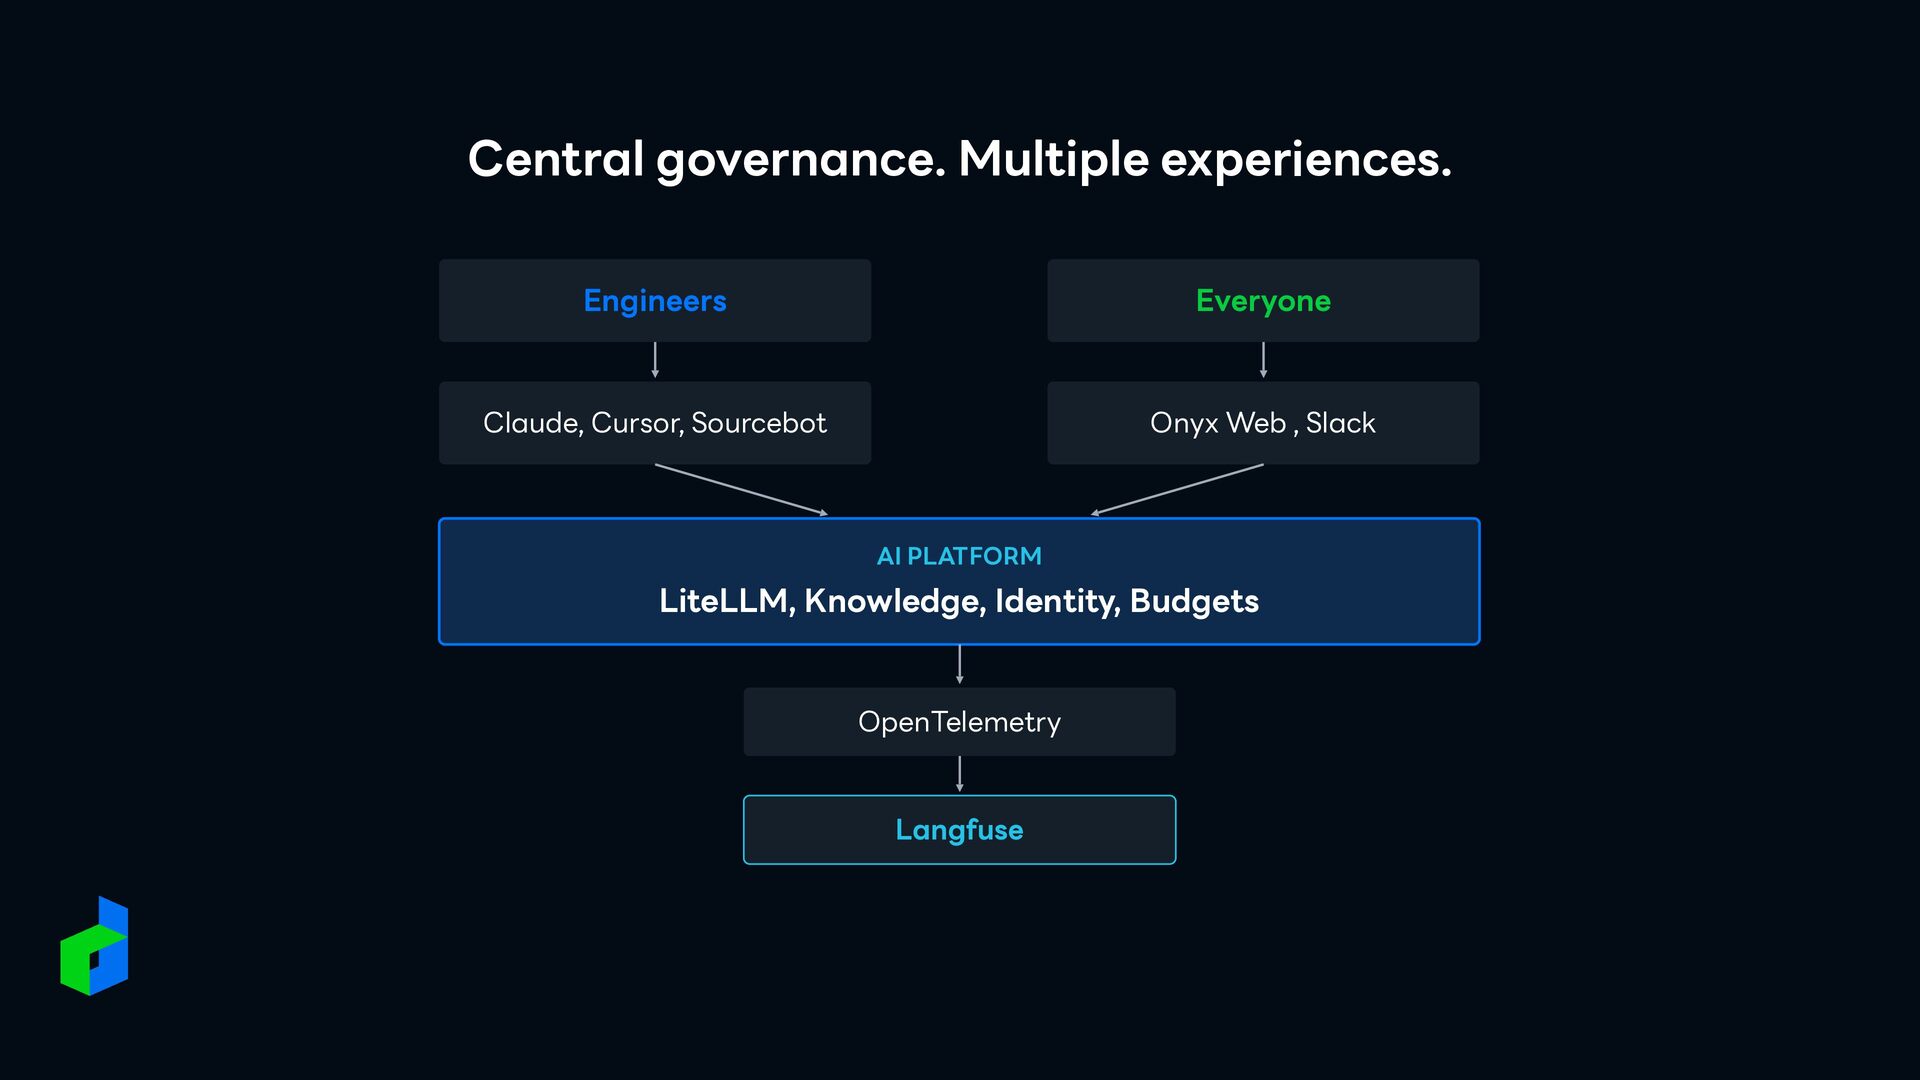
Central governance. Multiple experiences. Engineers Everyone Claude, Cursor, Sourcebot Onyx
Web , Slack AI PLATFORM LiteLLM, Knowledge, Identity, Budgets OpenTelemetry Langfuse -
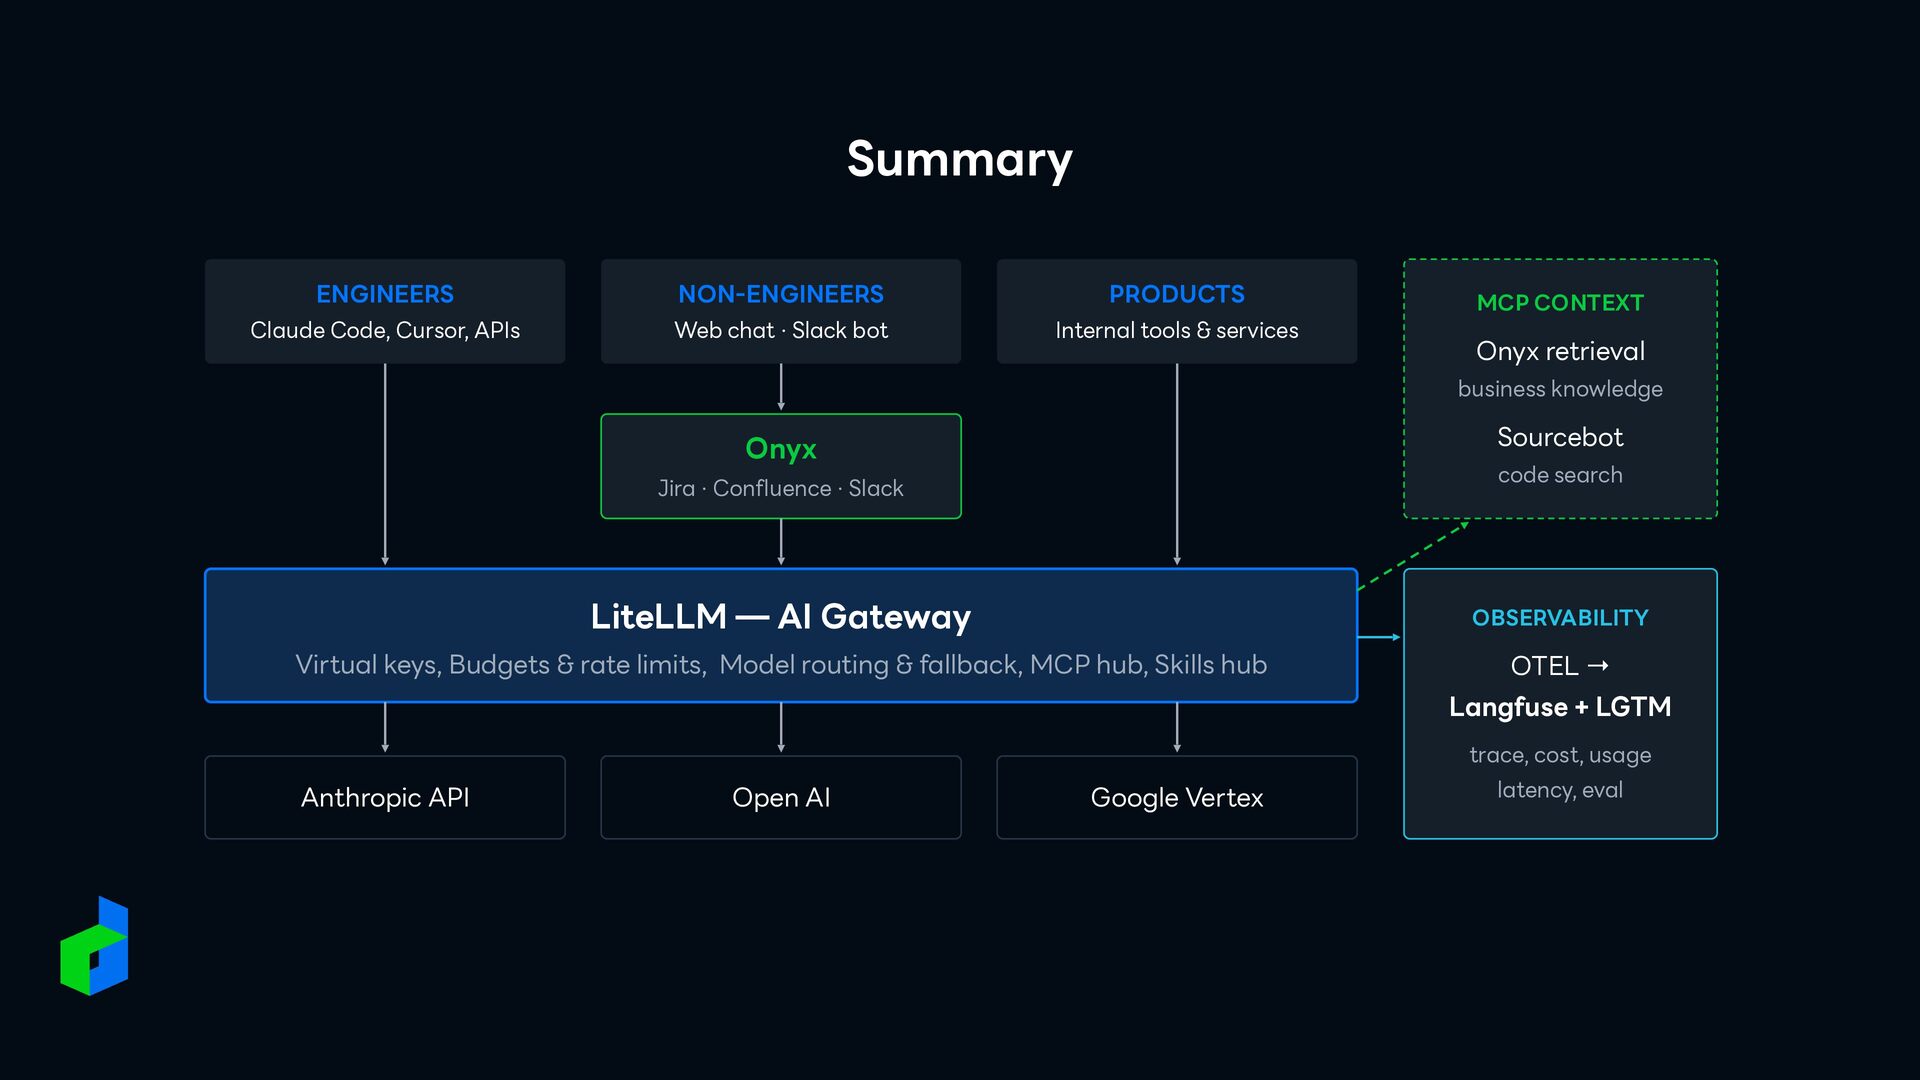
Summary ENGINEERS NON-ENGINEERS PRODUCTS Claude Code, Cursor, APIs Web chat
· Slack bot Internal tools & services MCP CONTEXT Onyx retrieval business knowledge Sourcebot Onyx code search Jira · Confluence · Slack LiteLLM — AI Gateway OBSERVABILITY Virtual keys, Budgets & rate limits, Model routing & fallback, MCP hub, Skills hub OTEL → Langfuse + LGTM trace, cost, usage Anthropic API Open AI Google Vertex latency, eval
 linedevth
 nagix
 inariku
 itosoft
 ryouto715
 ikki0006
 torounit
 amixedcolor
 y_matsubara
 demaecan
 oidfj
 atsushieno
 yoshidashingo
 kristinabergwall1
 62gerente
 charlesmeaden
 marcduiker
 marcoroth
 palkan
 jlugia
 sugarenia
 rasmusluckow
 codingconduct
 addyosmani
 tammyeverts