Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
NLTK Intro for PUGS
Search
Victor Neo
March 27, 2012
Programming
630
7
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
NLTK Intro for PUGS
Slides for the NLTK talk given on March 2012 for Python User Group SG Meetup.
Victor Neo
March 27, 2012
Transcript
36 slides
Natural Language Toolkit @victorneo
Natural Language Processing
"the process of a computer extracting meaningful information from natural
language input and/or producing natural language output"
None
Getting started with NLTK
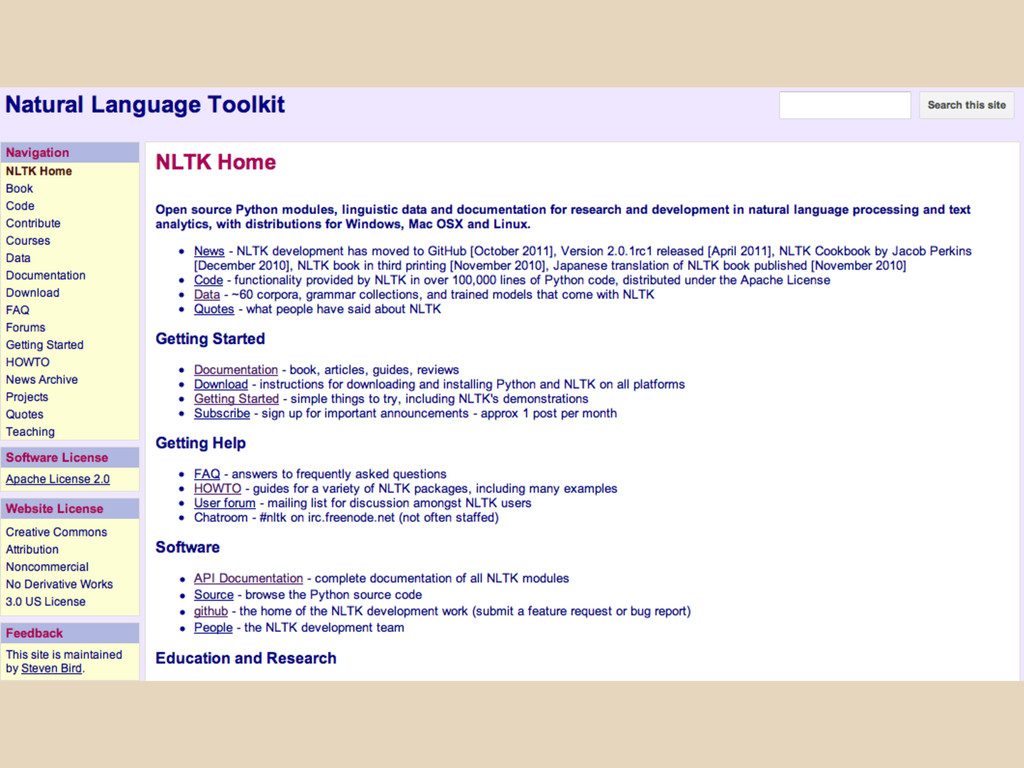
Open source Python modules, linguistic data and documentation for research
and development in natural language processing and text analytics, with distributions for Windows, Mac OSX and Linux. NLTK
None
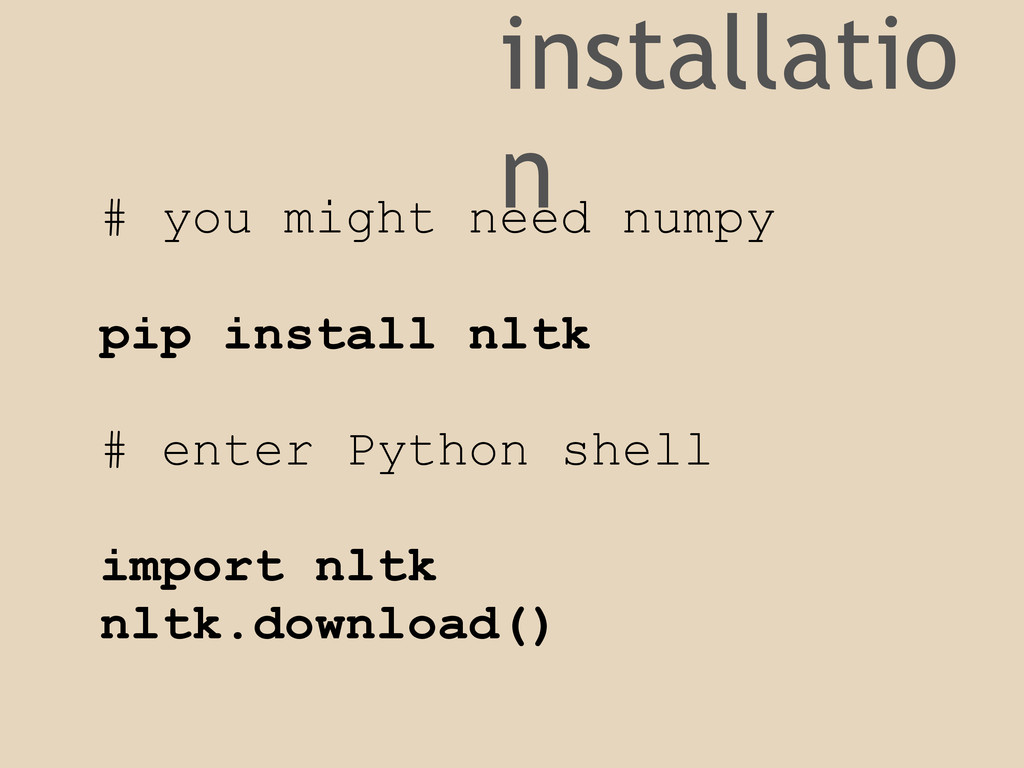
installatio n # you might need numpy pip install nltk
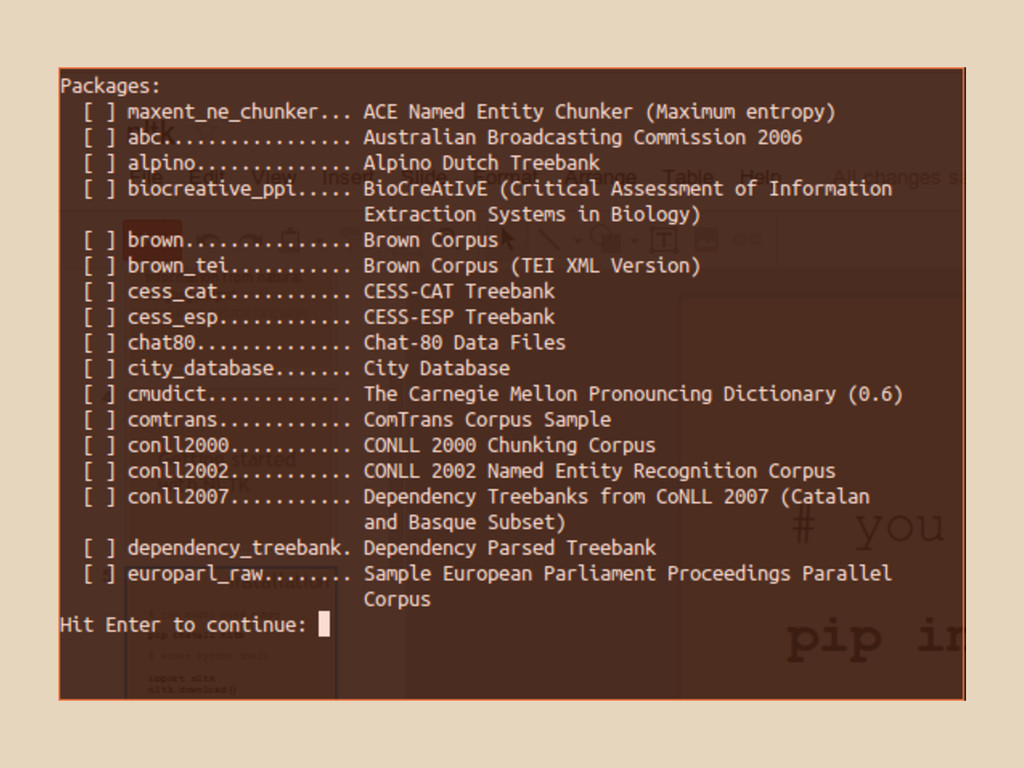
# enter Python shell import nltk nltk.download()
None
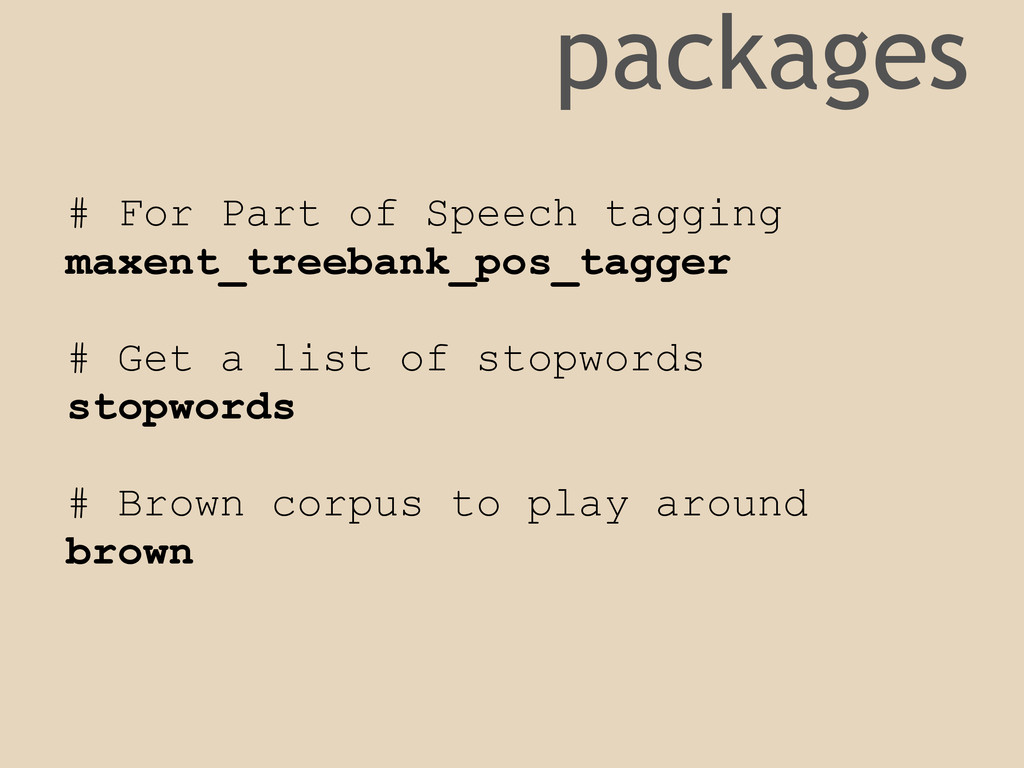
packages # For Part of Speech tagging maxent_treebank_pos_tagger # Get
a list of stopwords stopwords # Brown corpus to play around brown
Preparing data / corpus
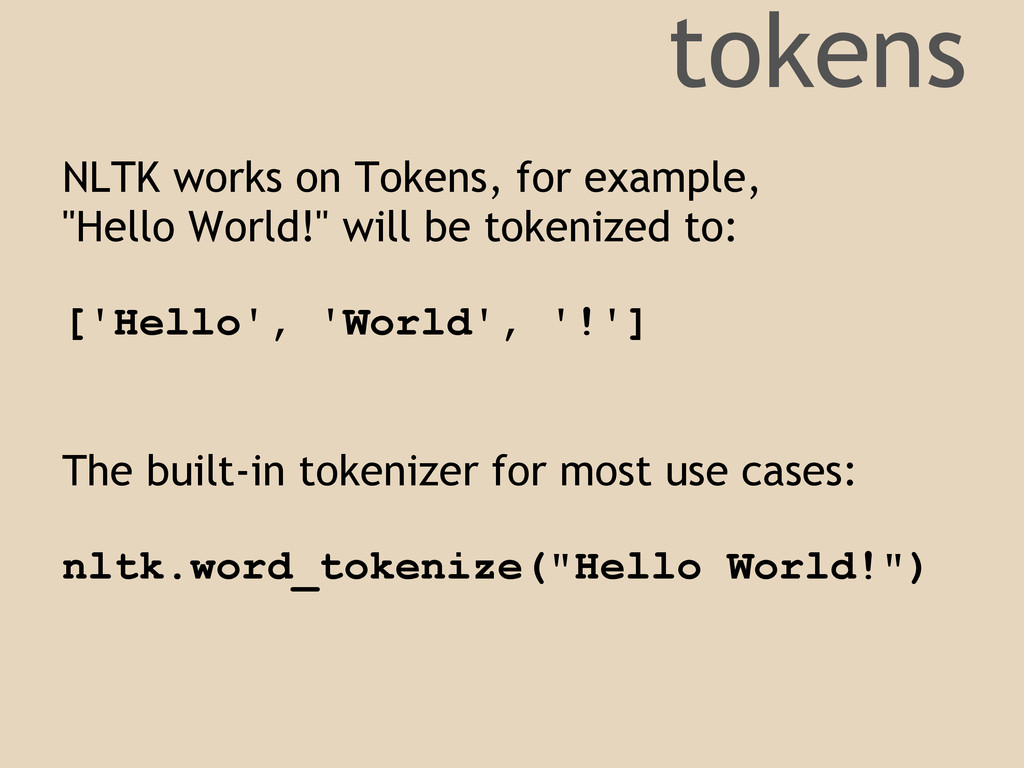
tokens NLTK works on Tokens, for example, "Hello World!" will
be tokenized to: ['Hello', 'World', '!'] The built-in tokenizer for most use cases: nltk.word_tokenize("Hello World!")
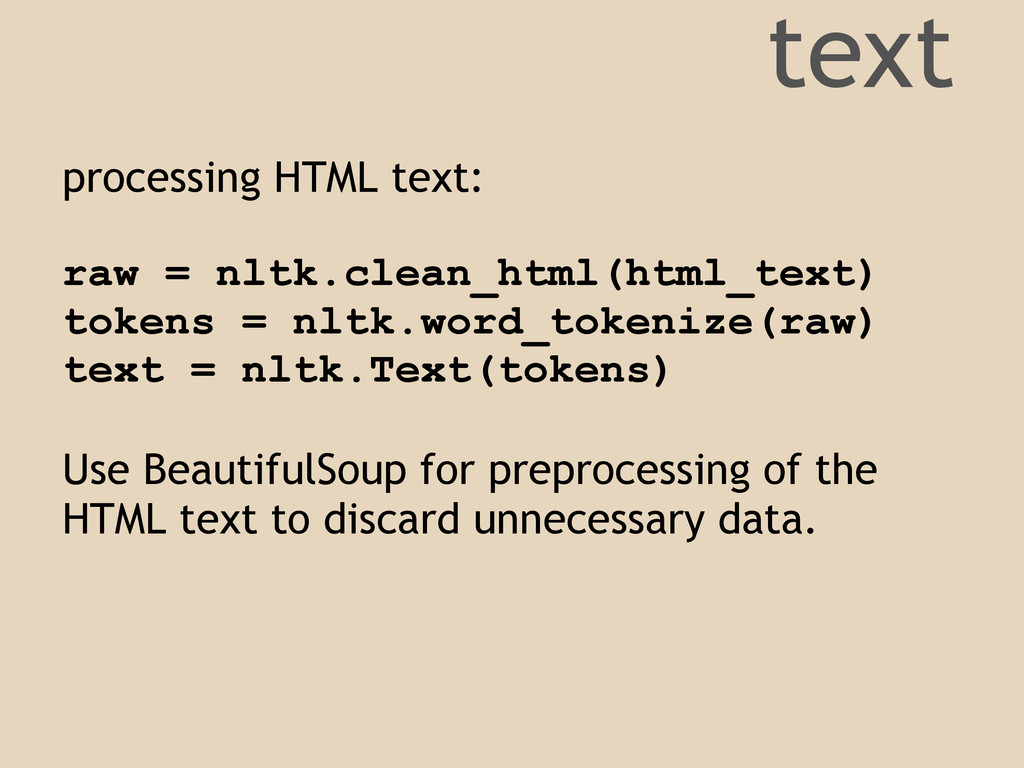
text processing HTML text: raw = nltk.clean_html(html_text) tokens = nltk.word_tokenize(raw)
text = nltk.Text(tokens) Use BeautifulSoup for preprocessing of the HTML text to discard unnecessary data.
Part-of-speech tagging
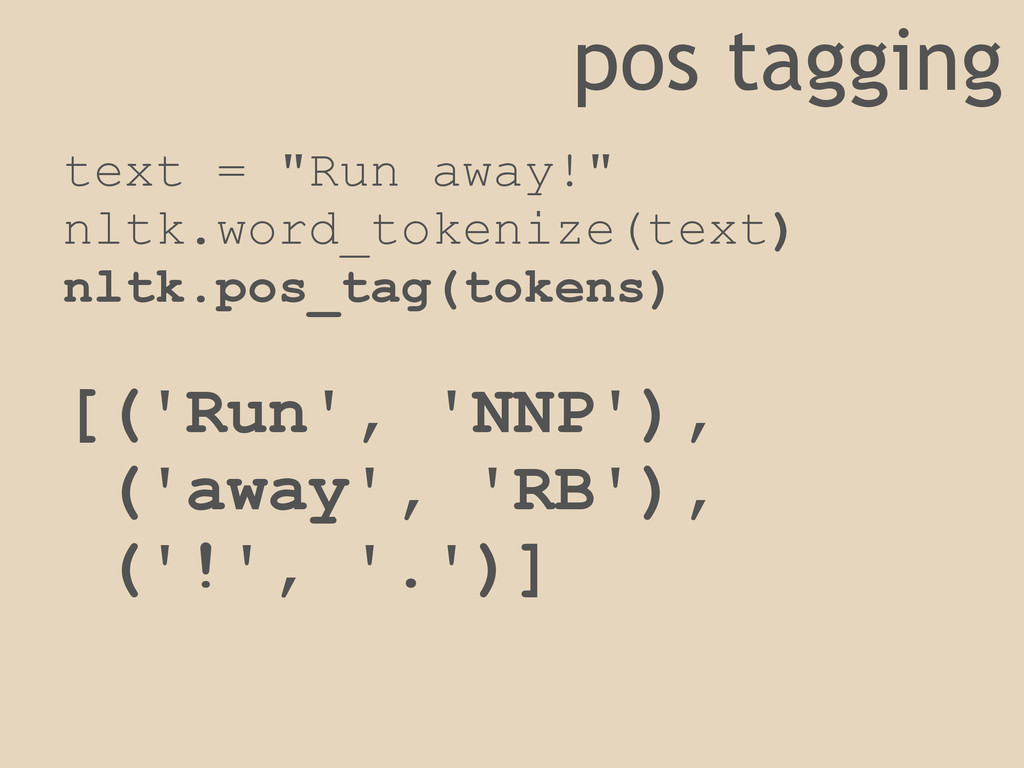
pos tagging text = "Run away!" nltk.word_tokenize(text) nltk.pos_tag(tokens) [('Run', 'NNP'),
('away', 'RB'), ('!', '.')]
pos tagging [('Run', 'NNP'), ('away', 'RB'), ('!', '.')] NNP: Proper
Noun, Singular RB : Adverb http://www.ling.upenn.edu/courses/Fall_2003/ling001/penn_treebank_pos. html
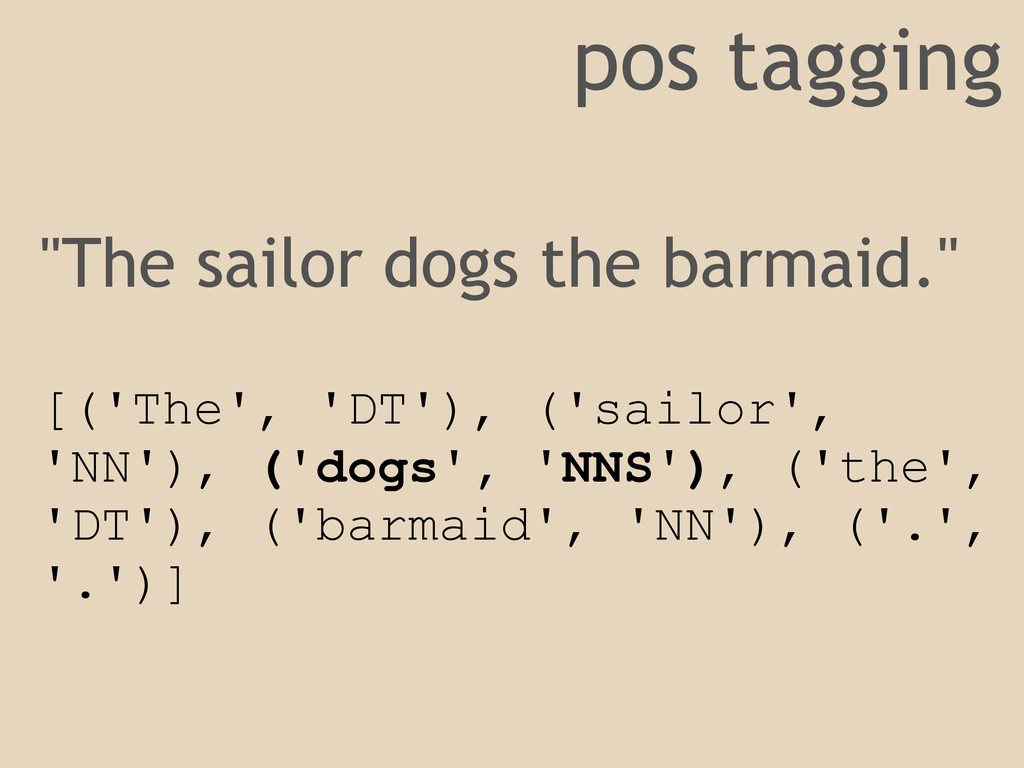
pos tagging "The sailor dogs the barmaid." [('The', 'DT'), ('sailor',
'NN'), ('dogs', 'NNS'), ('the', 'DT'), ('barmaid', 'NN'), ('.', '.')]
Sentiment Analysis Code: http://bit.ly/GLu2Q9
Differentiate between "happy" and "sad" tweets. Teach the classifier the
"features" of happy & sad tweets and test how good it is.
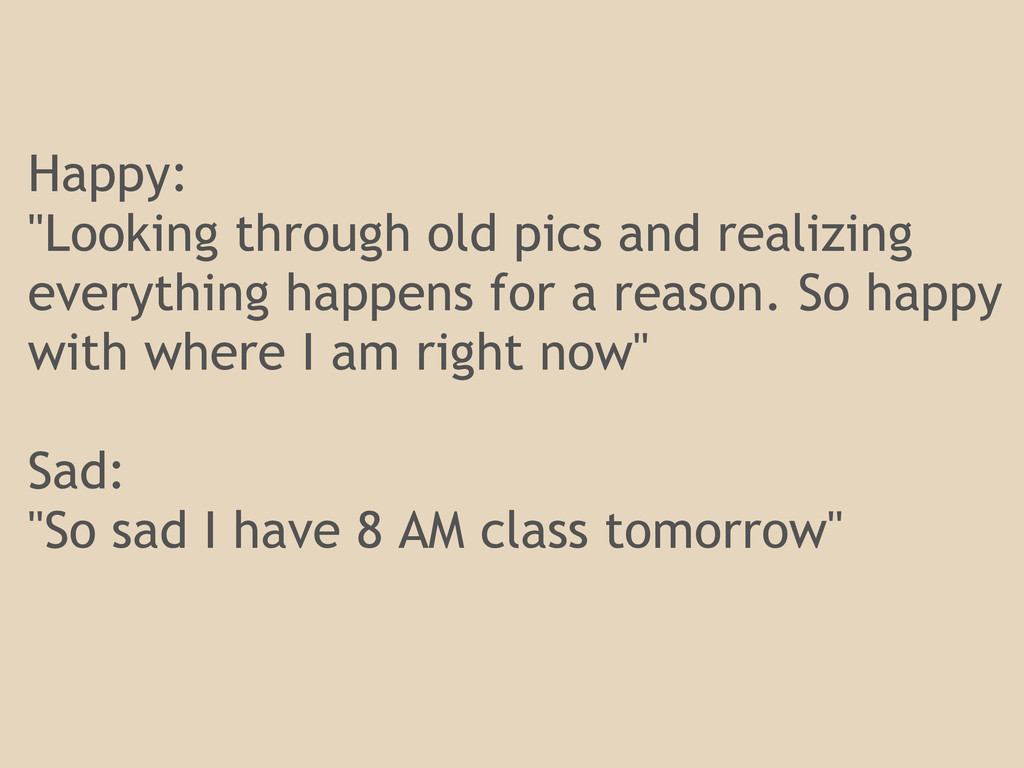
Happy: "Looking through old pics and realizing everything happens for
a reason. So happy with where I am right now" Sad: "So sad I have 8 AM class tomorrow"
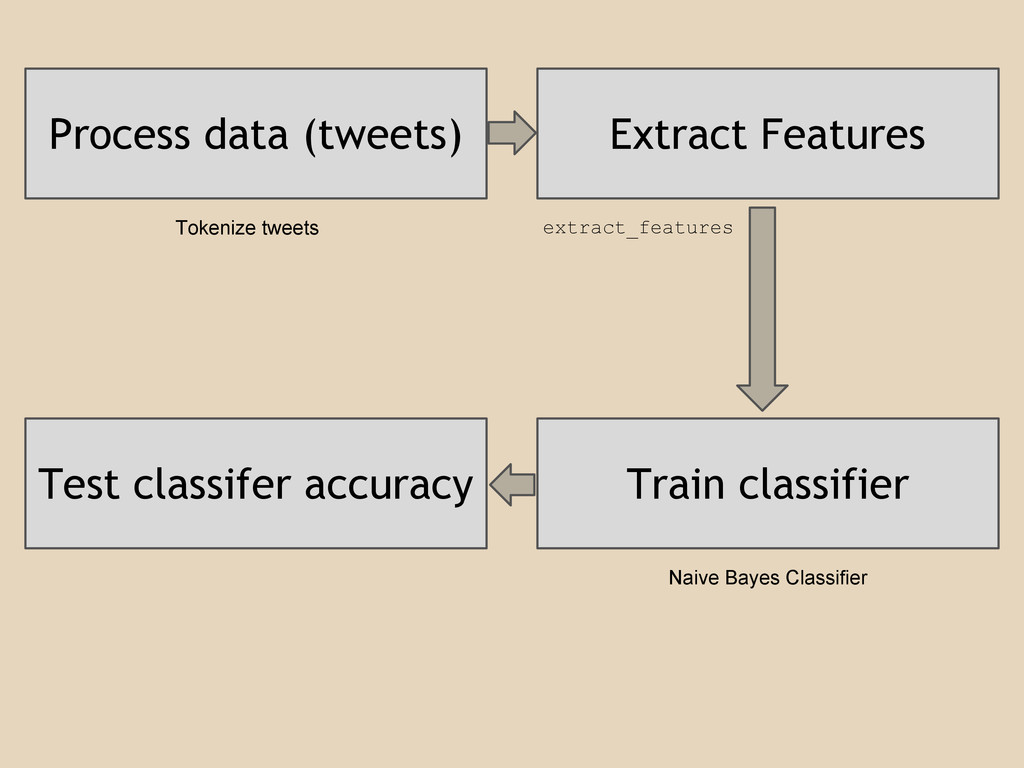
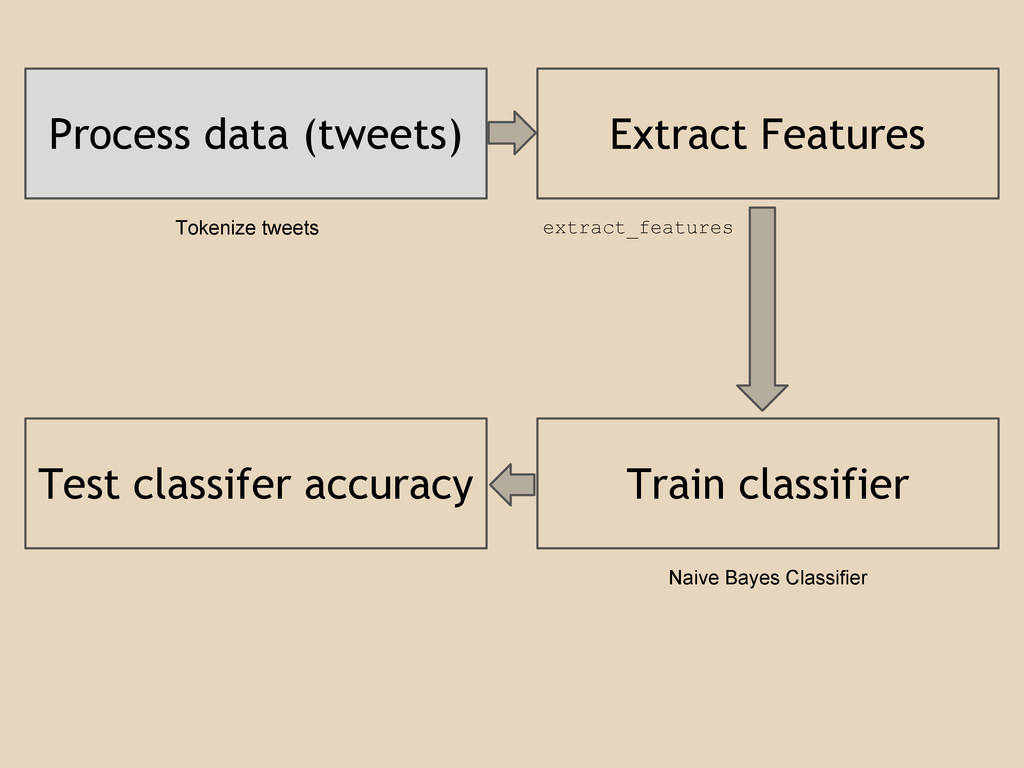
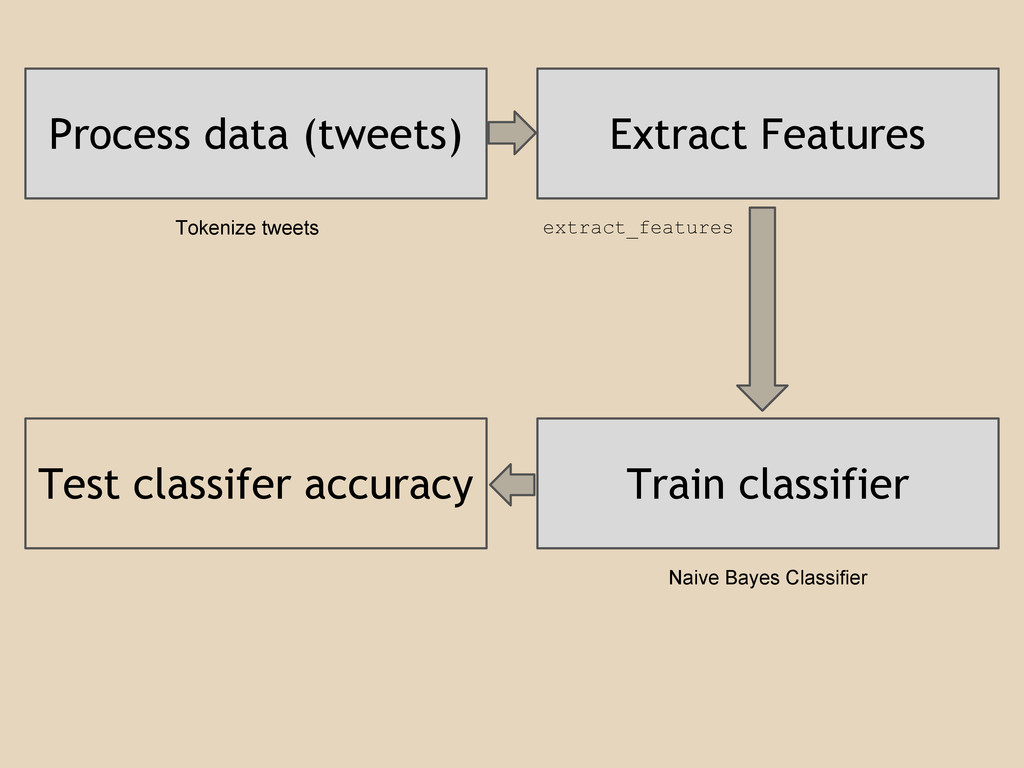
Process data (tweets) Extract Features Train classifier Test classifer accuracy
Tokenize tweets extract_features Naive Bayes Classifier
Process data (tweets) Extract Features Train classifier Test classifer accuracy
Tokenize tweets extract_features Naive Bayes Classifier
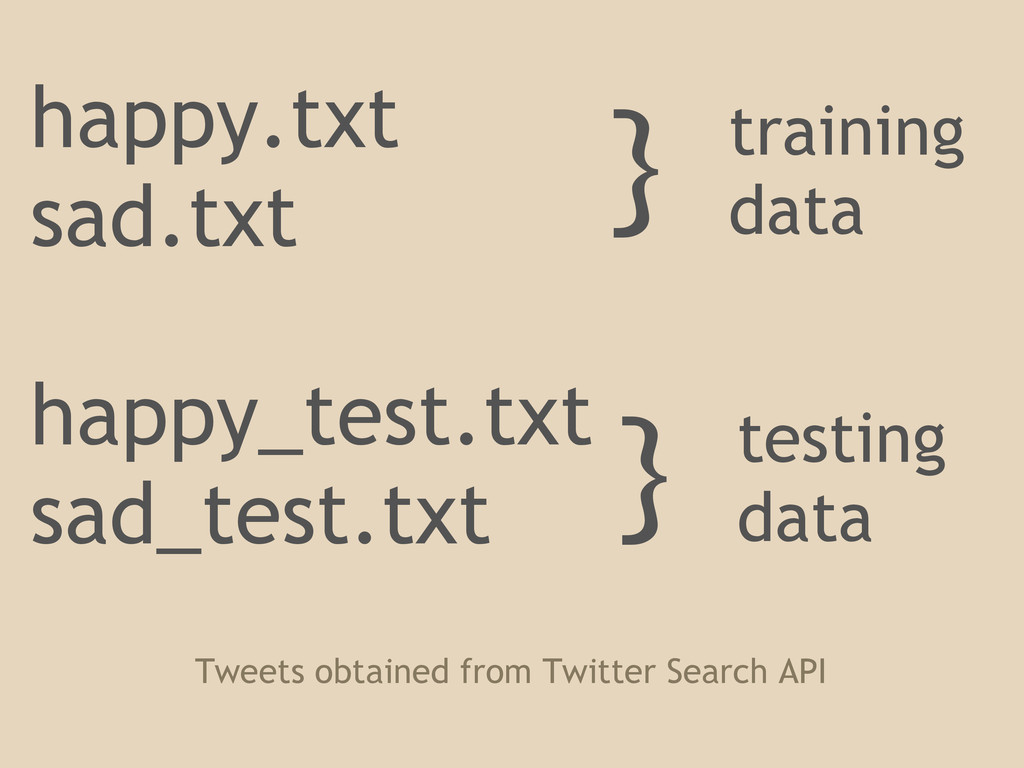
happy.txt sad.txt happy_test.txt sad_test.txt } training data } testing data
Tweets obtained from Twitter Search API
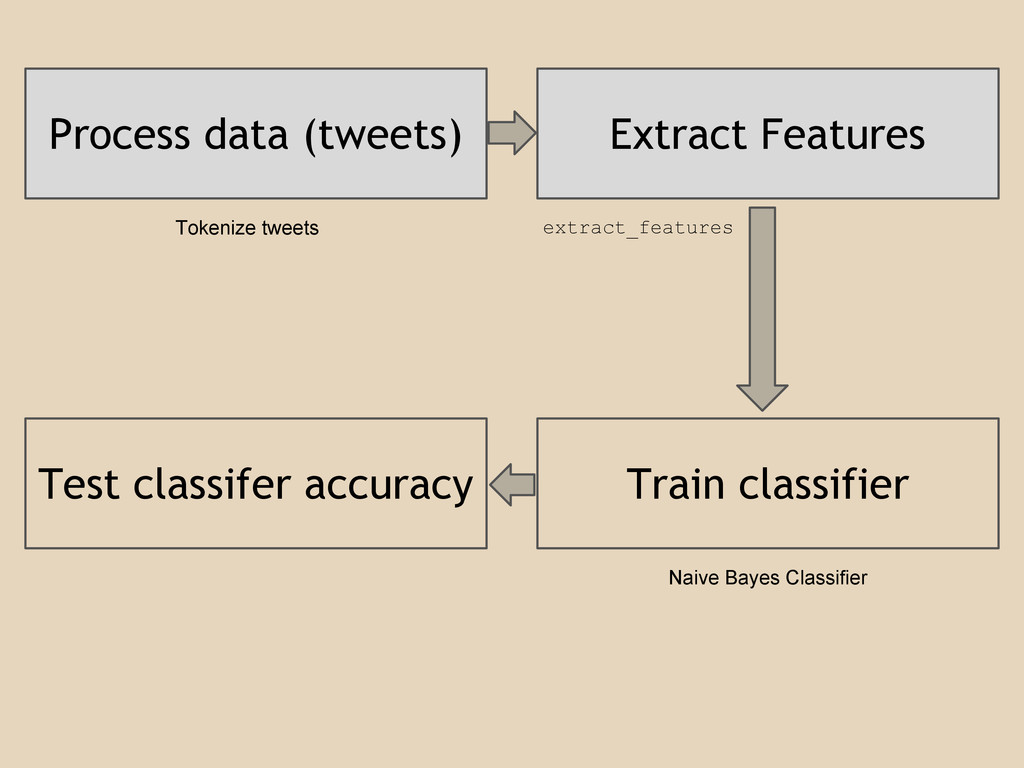
Process data (tweets) Extract Features Train classifier Test classifer accuracy
Tokenize tweets extract_features Naive Bayes Classifier
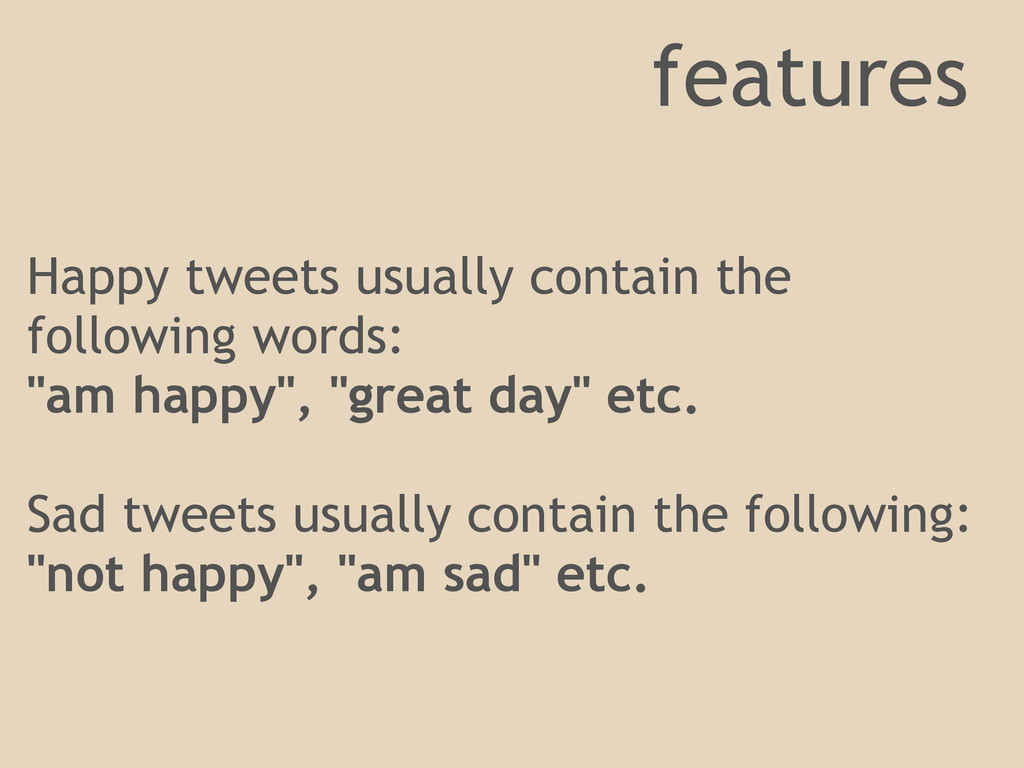
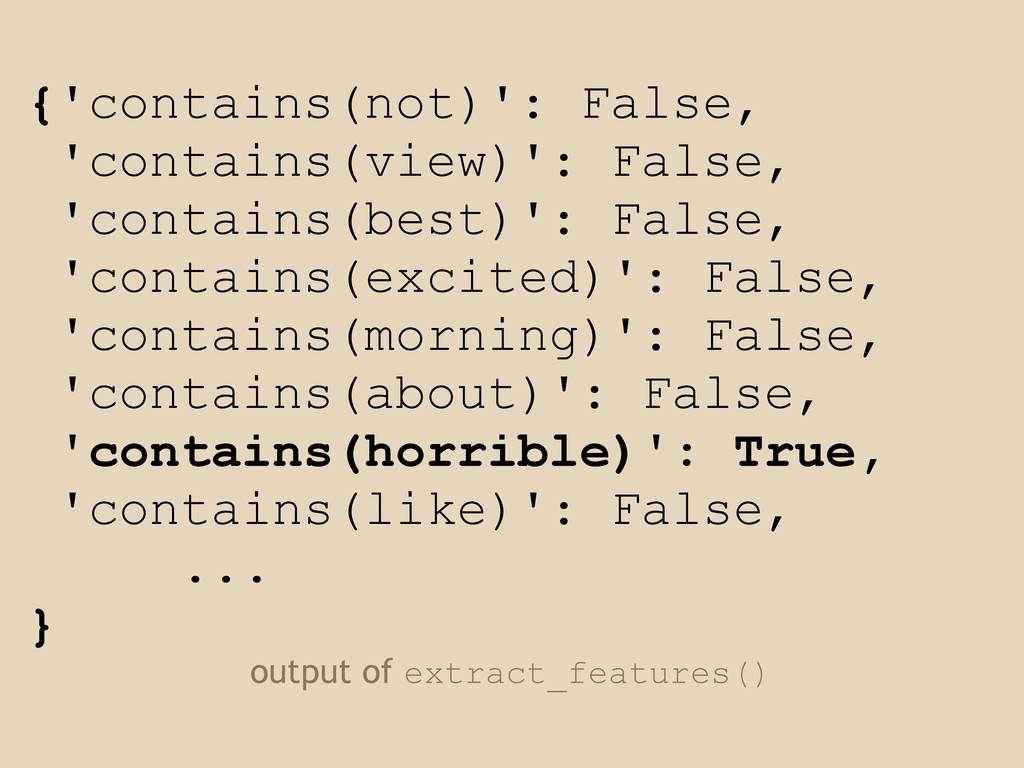
Happy tweets usually contain the following words: "am happy", "great
day" etc. Sad tweets usually contain the following: "not happy", "am sad" etc. features
{'contains(not)': False, 'contains(view)': False, 'contains(best)': False, 'contains(excited)': False, 'contains(morning)': False,
'contains(about)': False, 'contains(horrible)': True, 'contains(like)': False, ... } output of extract_features()
Process data (tweets) Extract Features Train classifier Test classifer accuracy
Tokenize tweets extract_features Naive Bayes Classifier
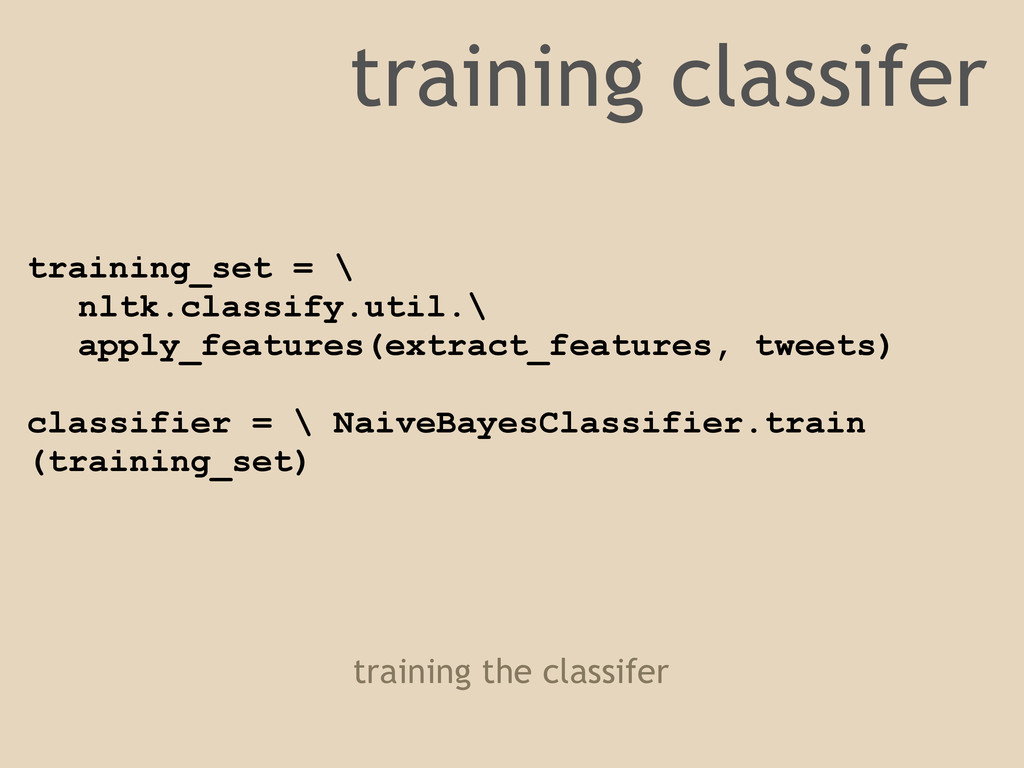
training_set = \ nltk.classify.util.\ apply_features(extract_features, tweets) classifier = \ NaiveBayesClassifier.train
(training_set) training the classifer training classifer
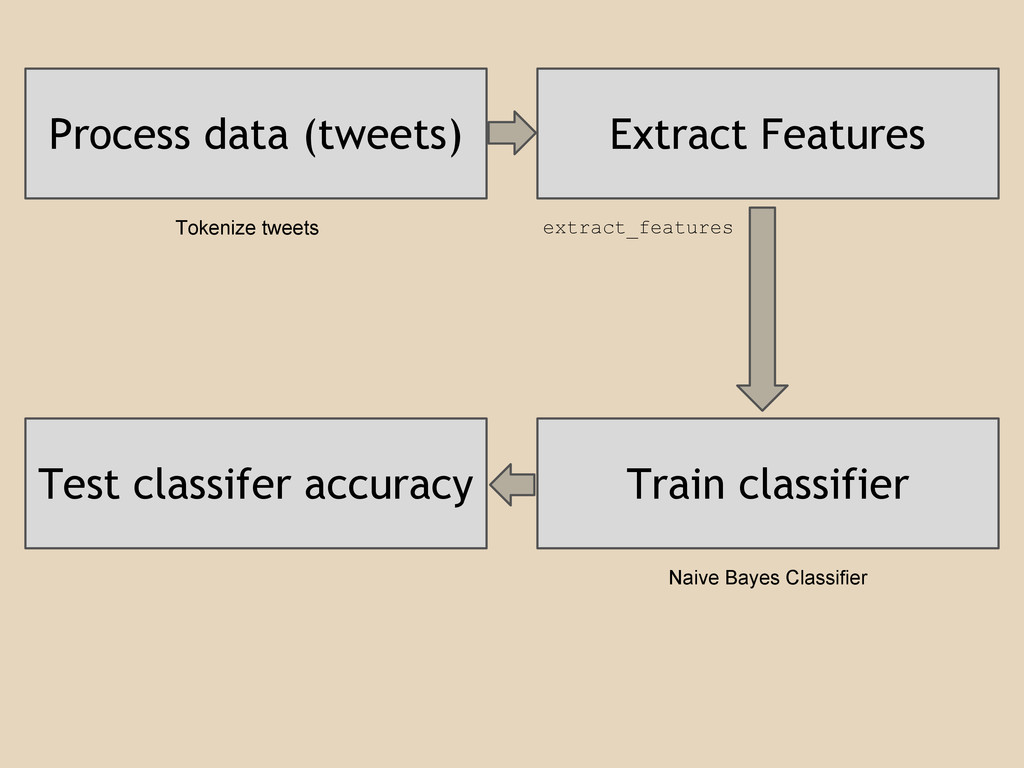
Process data (tweets) Extract Features Train classifier Test classifer accuracy
Tokenize tweets extract_features Naive Bayes Classifier
def classify_tweet(tweet): return \ classifier.classify(extract_features (tweet)) testing classifer
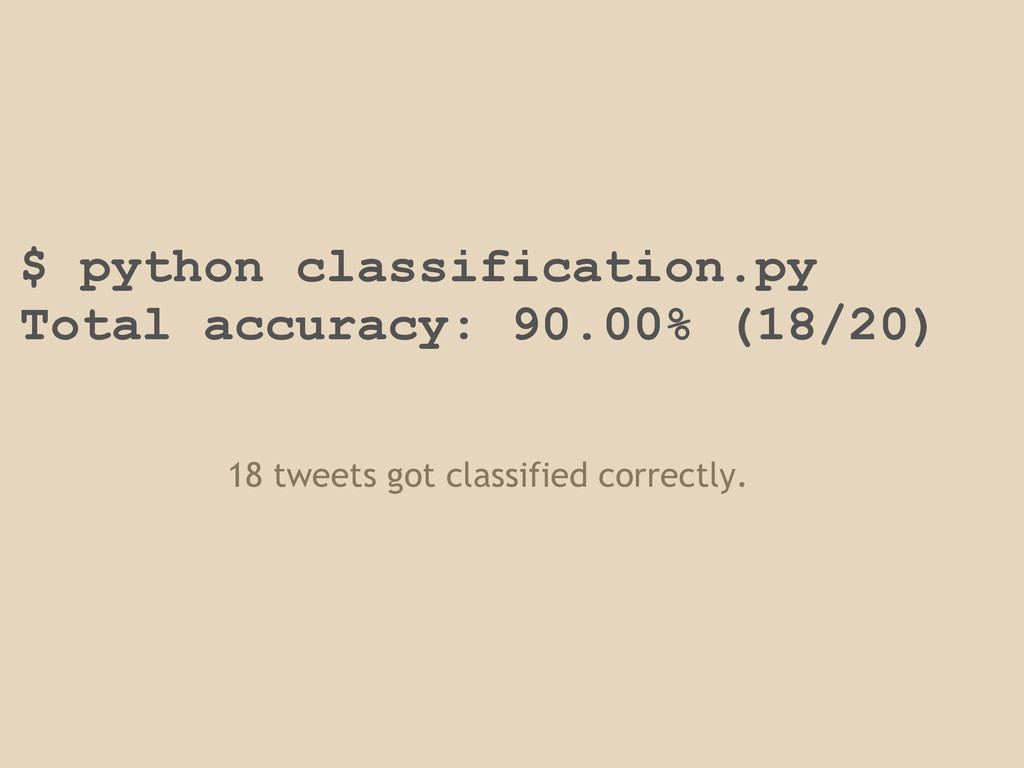
$ python classification.py Total accuracy: 90.00% (18/20) 18 tweets got
classified correctly.
Where to go from here.
http://www.nltk.org/book
https://class.coursera.org/nlp/auth/welcome
http://www.slideshare.net/shanbady/nltk-boston-text-analytics
[('Thank', 'NNP'), ('you', 'PRP'), ('.', '.')] @victorneo
More Decks by Victor Neo
See All by Victor Neo
Django - The Next Steps
victorneo
5
720
DevOps: Python tools to get started
victorneo
9
13k
Git and Python workshop
victorneo
2
830
Other Decks in Programming
See All in Programming
ビジネスロジックを堅牢に~Scala 3のドメインプリミティブ~
j5ik2o
0
150
現場と育てるRailsモデリング 〜Spreadsheetから始めたモデル設計〜
siroemk
2
1.2k
AI時代のIaC入門 〜なぜインフラをコードで管理したいのか?〜 / Introduction to IaC in the AI Era
akihisaikeda
6
1.5k
Enforcing Your Architecture with Unit Tests in the AI Era (Swift Connection X)
steliosf
PRO
1
170
Будущее локальных LLM – Алексей Голобурдин, PythoNN
sobolevn
0
120
Vapor Mode でアクセシビリティは 壊れないか検証した話
fuqda
1
340
Engineering Biometric UX Across Android Versions | DroidKnights 2026
ryunen344
1
200
Materialが消えた日 〜真っ白なFlutterキャンバスにRenderObjectで絵を描く〜
umigishiaoi
0
160
flutter_test のその先へ — Flutter アプリの LLM 機能に「評価」という品質保証を
kosukesaigusa
0
200
TanStack Vue Query と Pinia Colada から学ぶ非同期状態の型設計
aoshi
0
660
Next.js: The final boss of Web Performance
guaca
0
400
AIがコードを書いてくれる時代、我々は何を確かめるのか
yosuke_furukawa
PRO
13
5.9k
Featured
See All Featured
Stop Working from a Prison Cell
hatefulcrawdad
274
21k
The Straight Up "How To Draw Better" Workshop
denniskardys
239
140k
Automating Front-end Workflow
addyosmani
1370
210k
A Guide to Academic Writing Using Generative AI - A Workshop
ks91
PRO
1
570
What does AI have to do with Human Rights?
axbom
PRO
1
2.5k
Scaling GitHub
holman
464
140k
Become a Pro
speakerdeck
PRO
31
6.4k
svc-hook: hooking system calls on ARM64 by binary rewriting
retrage
2
670
Evolution of real-time – Irina Nazarova, EuRuKo, 2024
irinanazarova
9
1.7k
RailsConf & Balkan Ruby 2019: The Past, Present, and Future of Rails at GitHub
eileencodes
141
35k
How to build an LLM SEO readiness audit: a practical framework
nmsamuel
2
980
StorybookのUI Testing Handbookを読んだ
zakiyama
31
7.1k