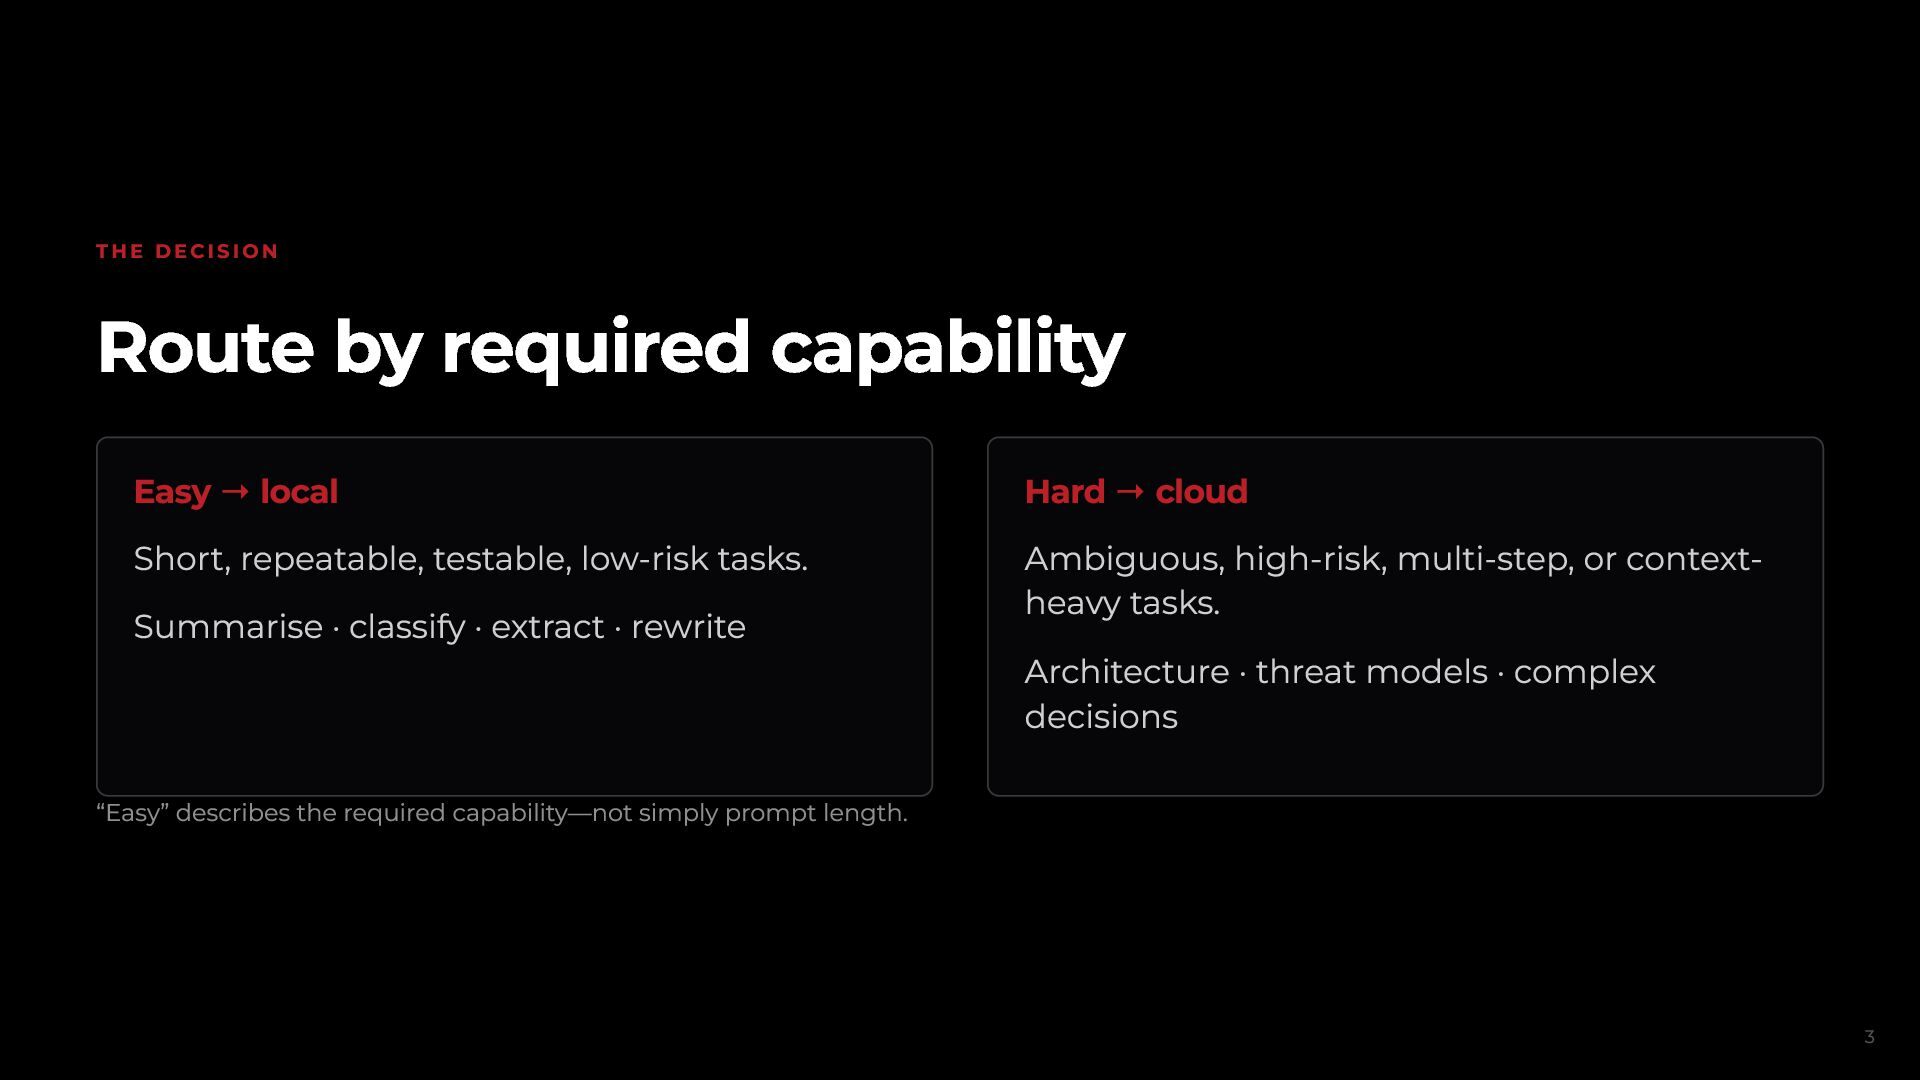
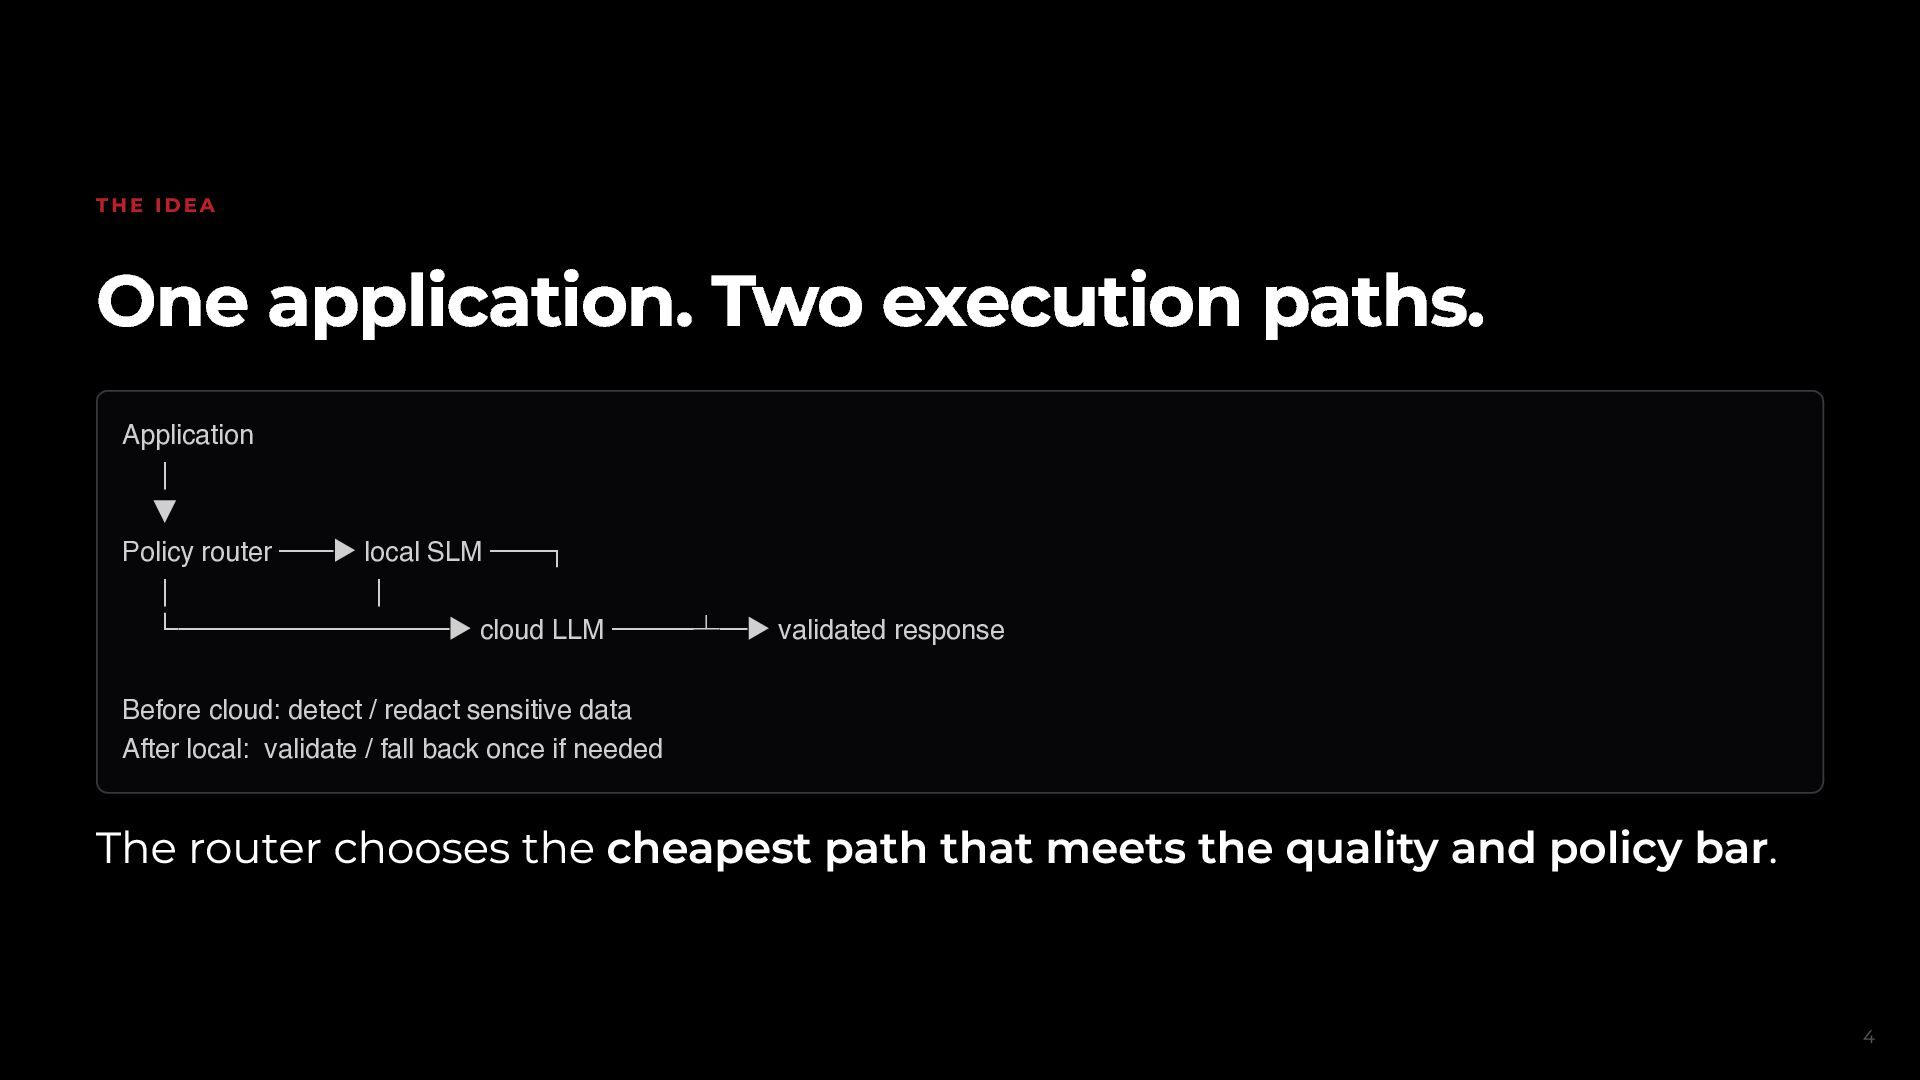
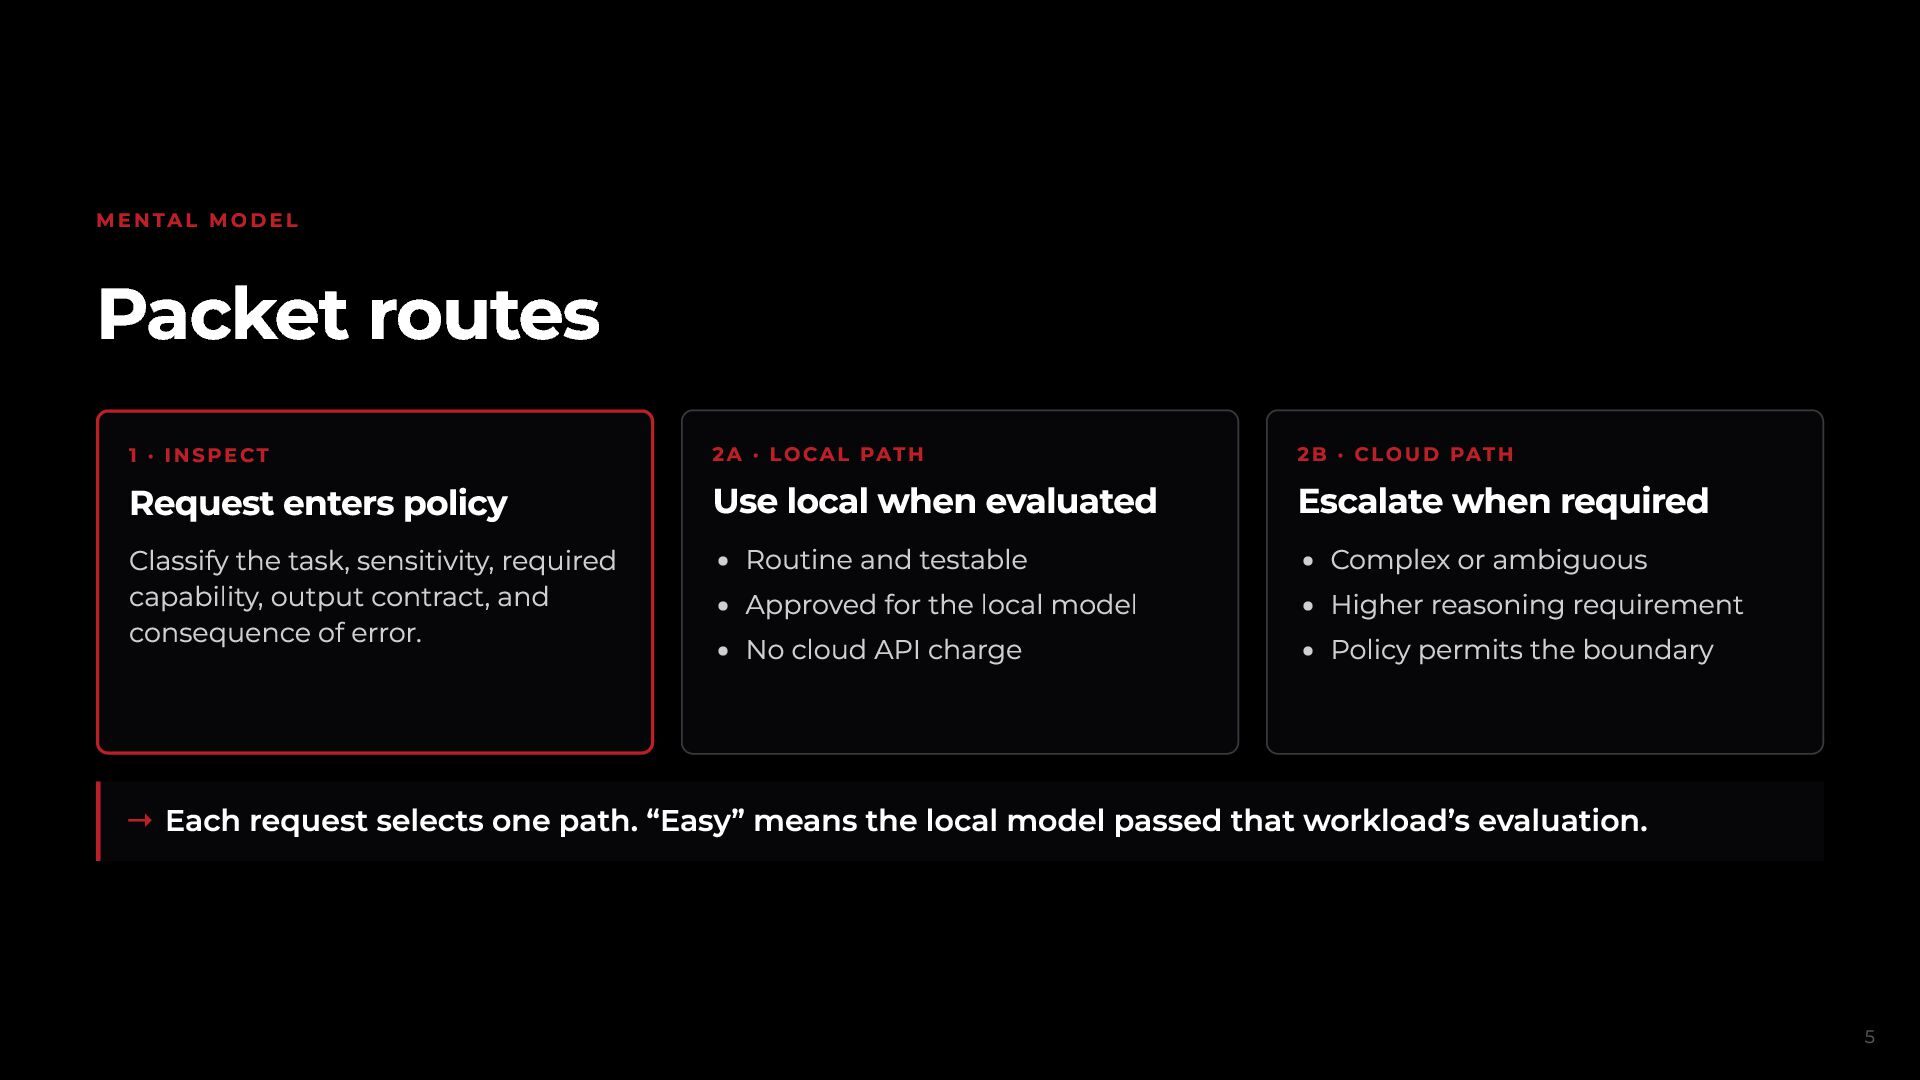
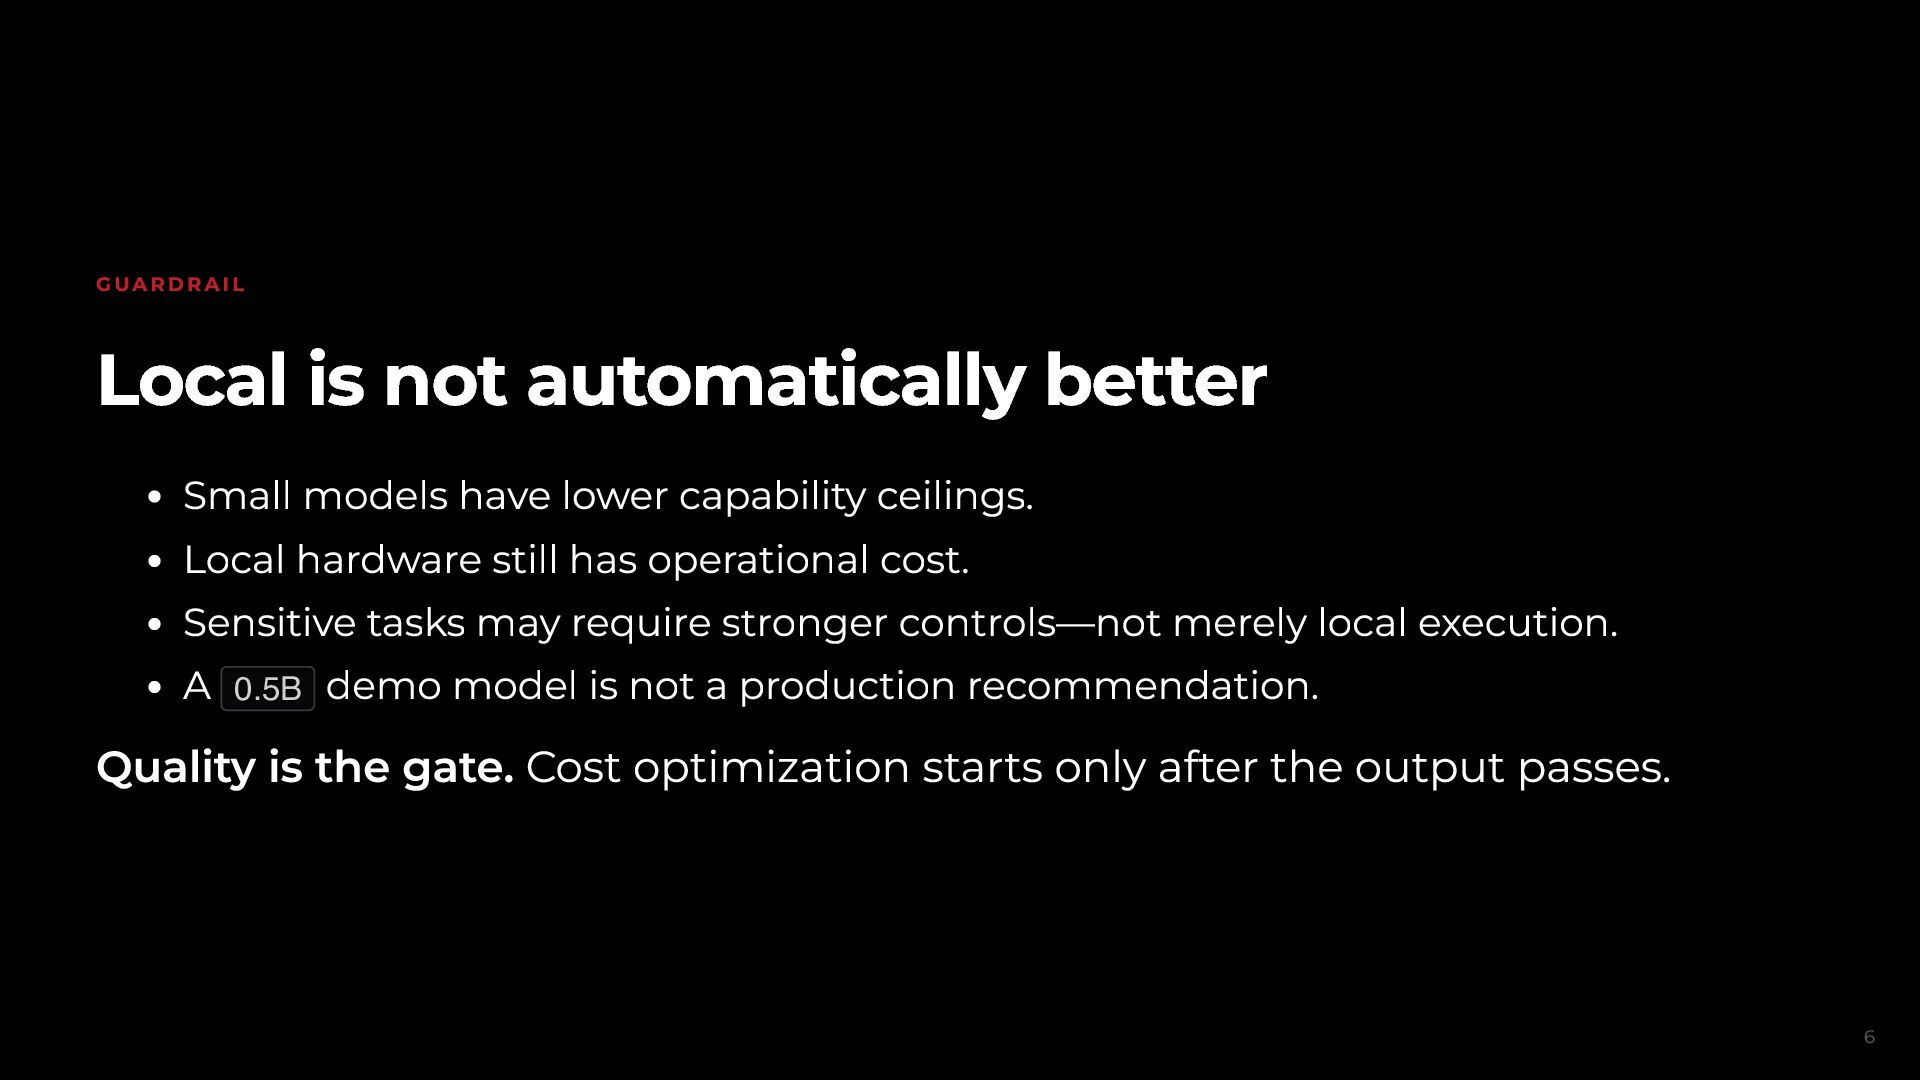
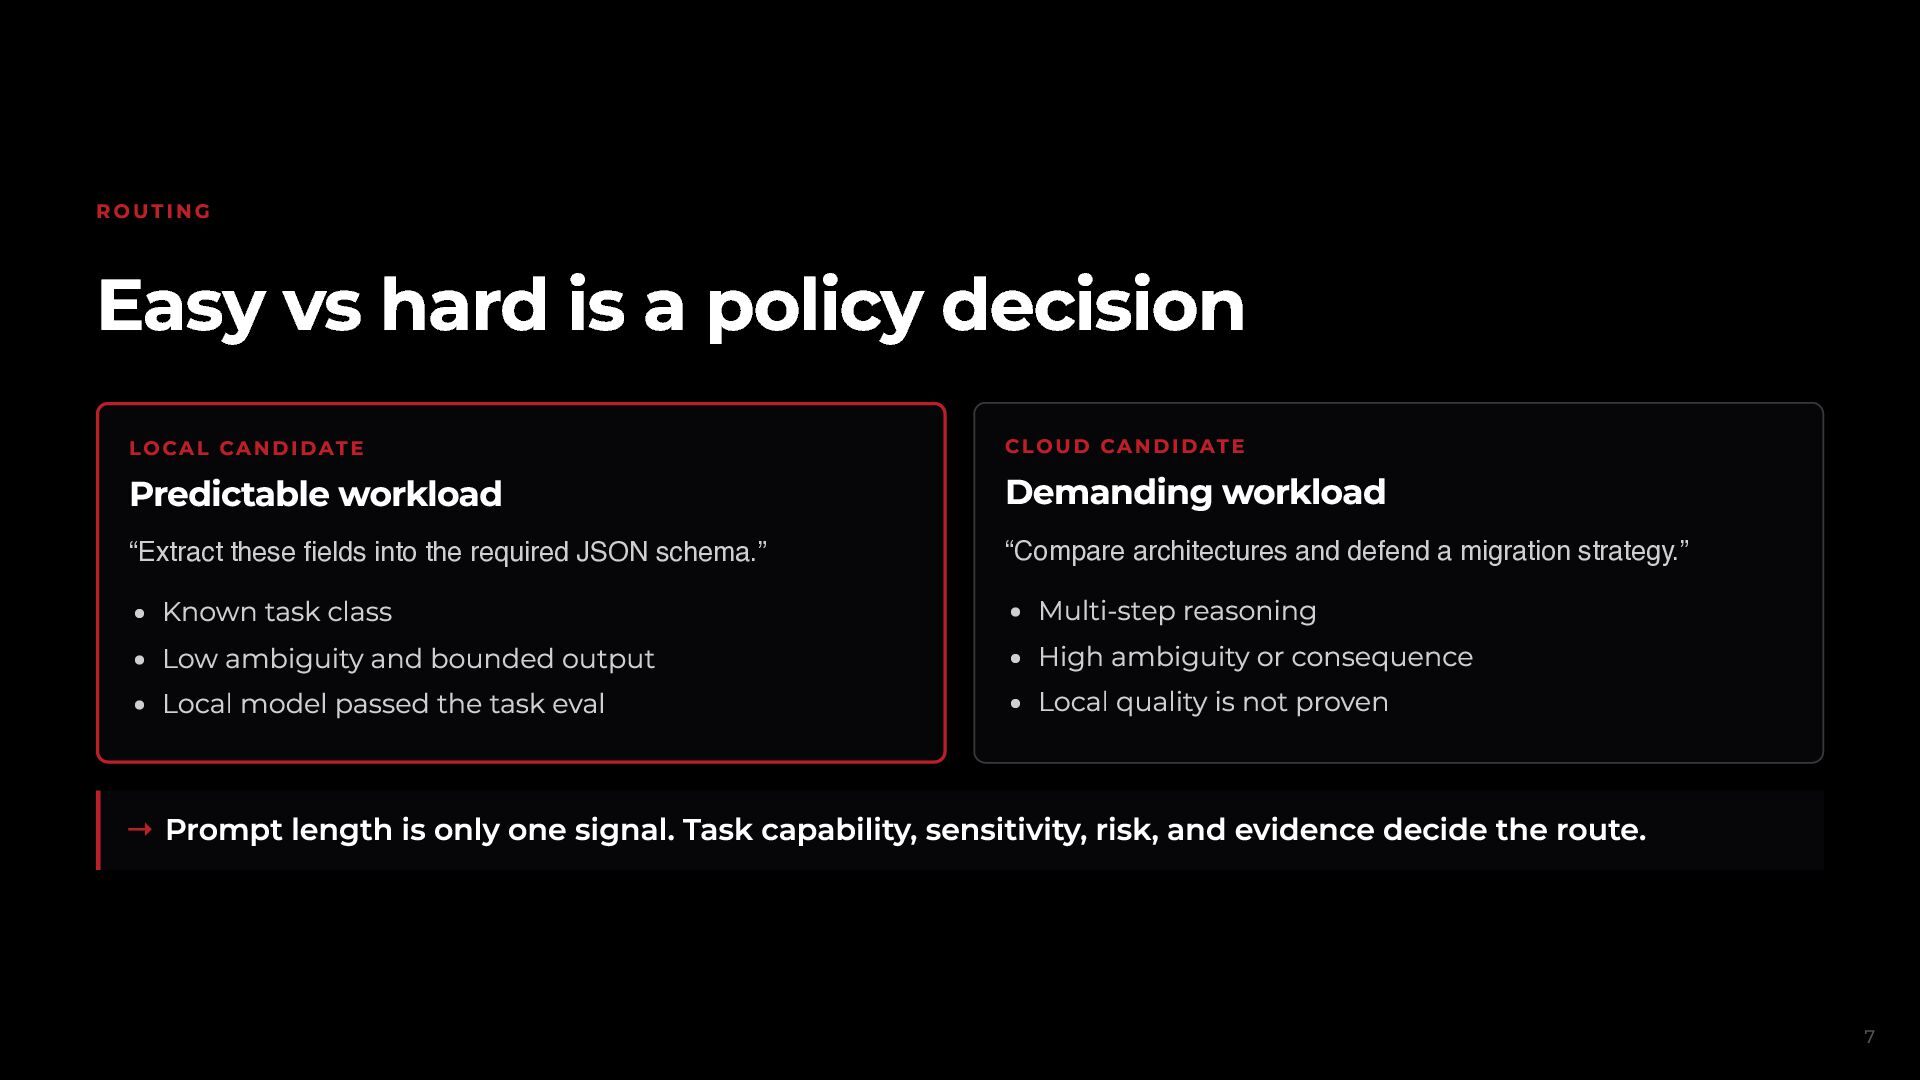
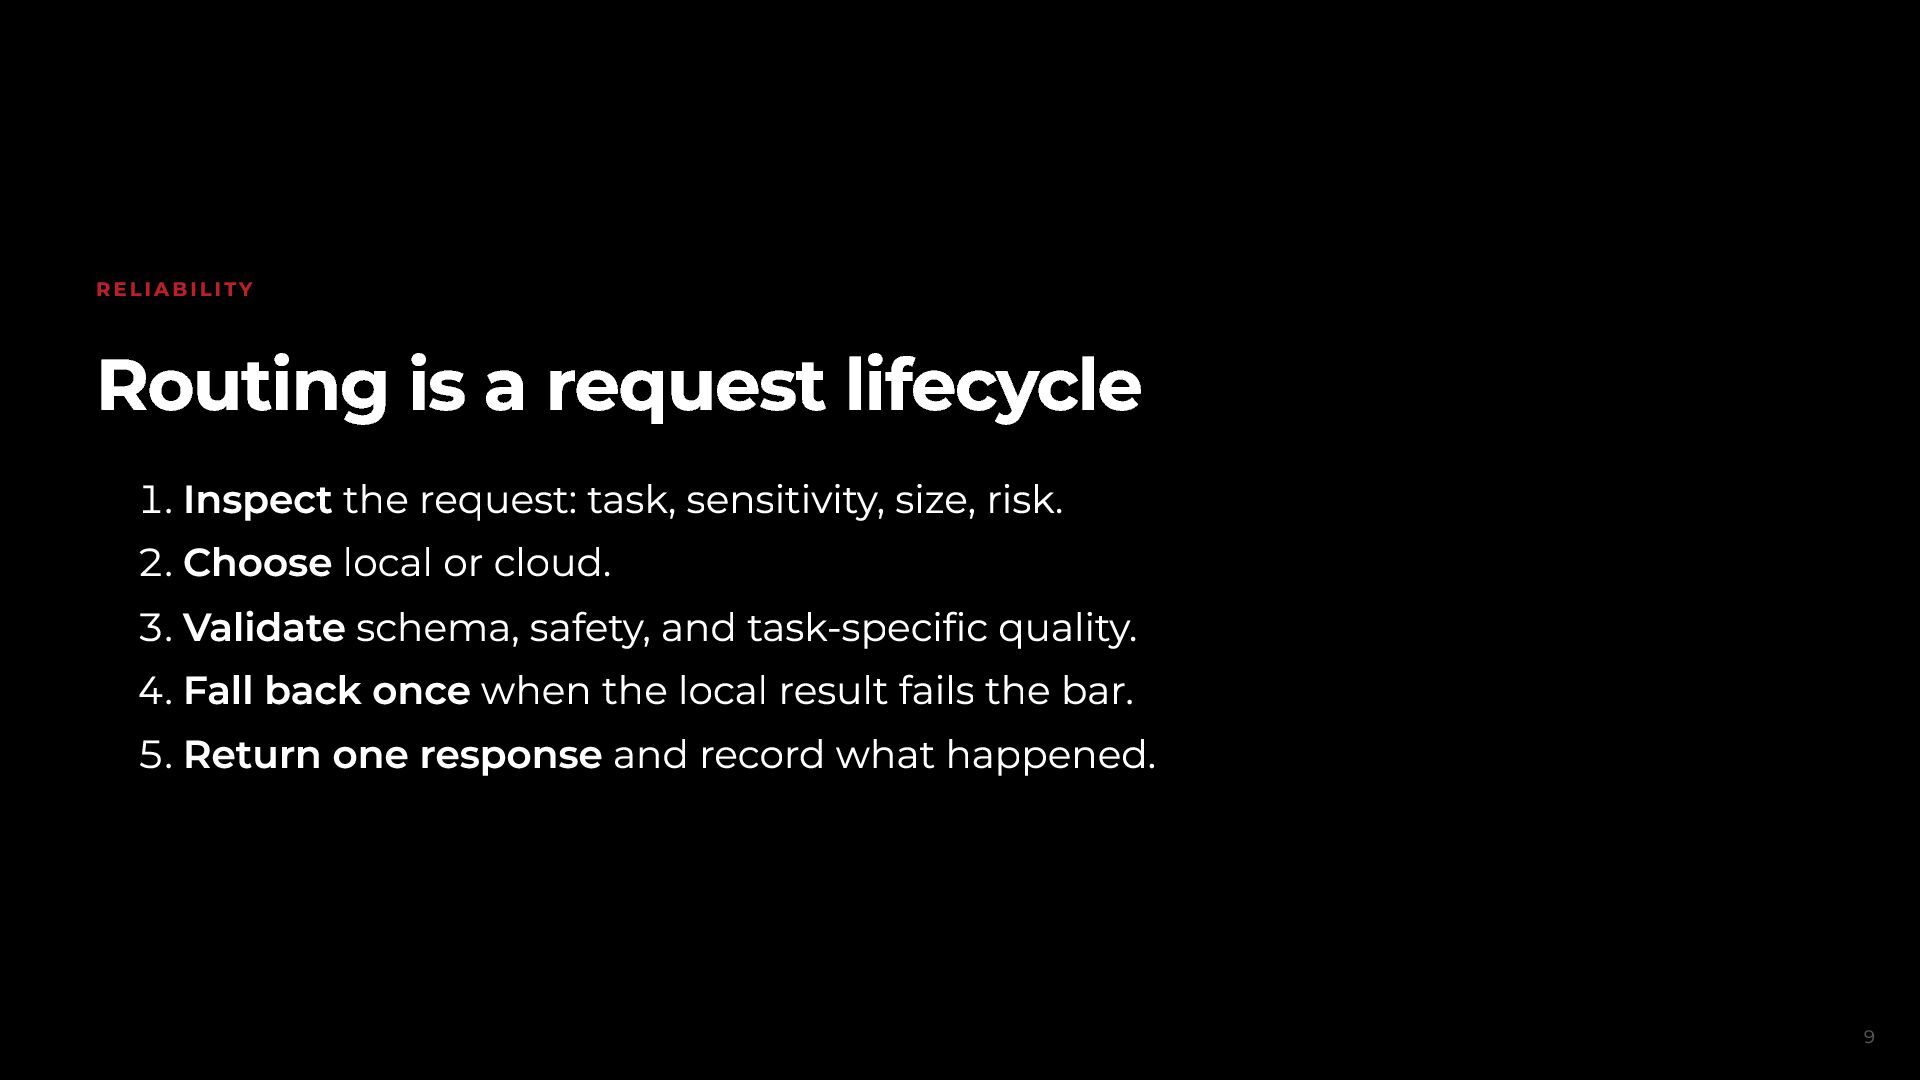
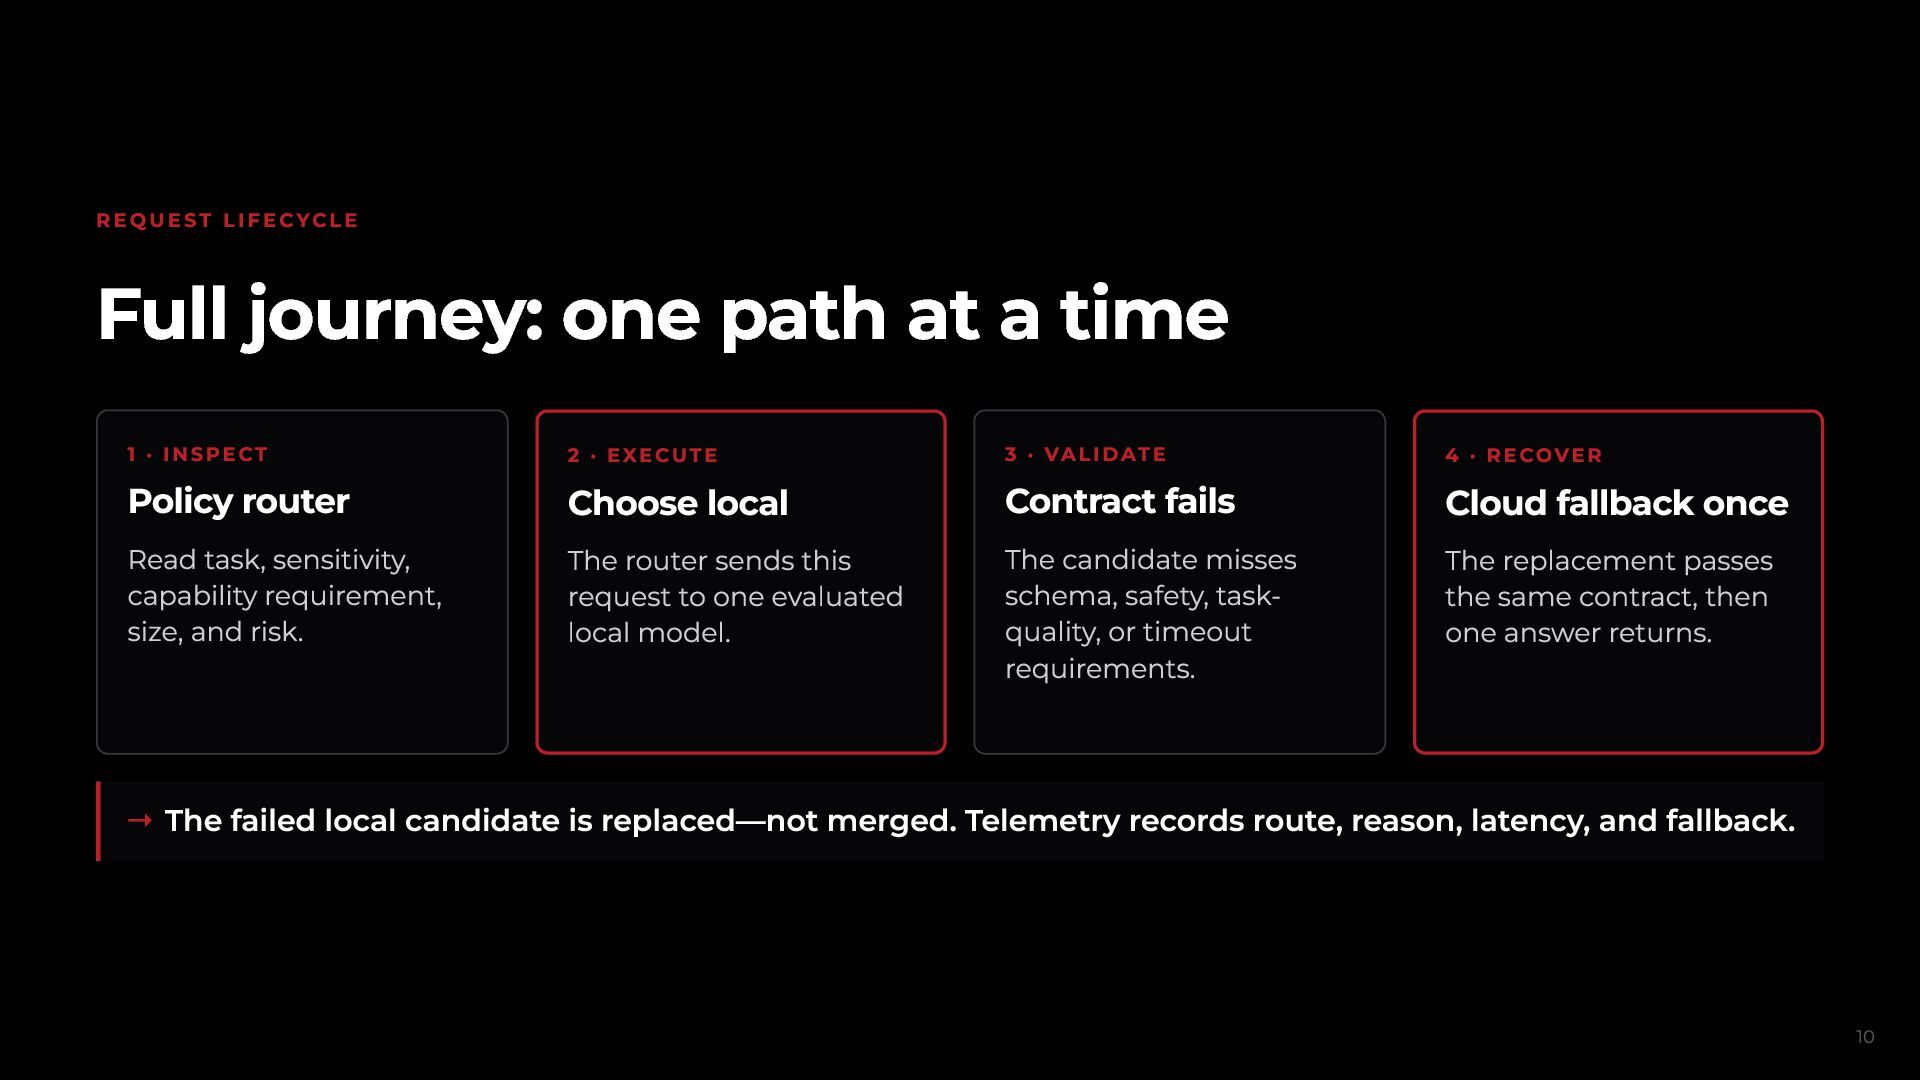
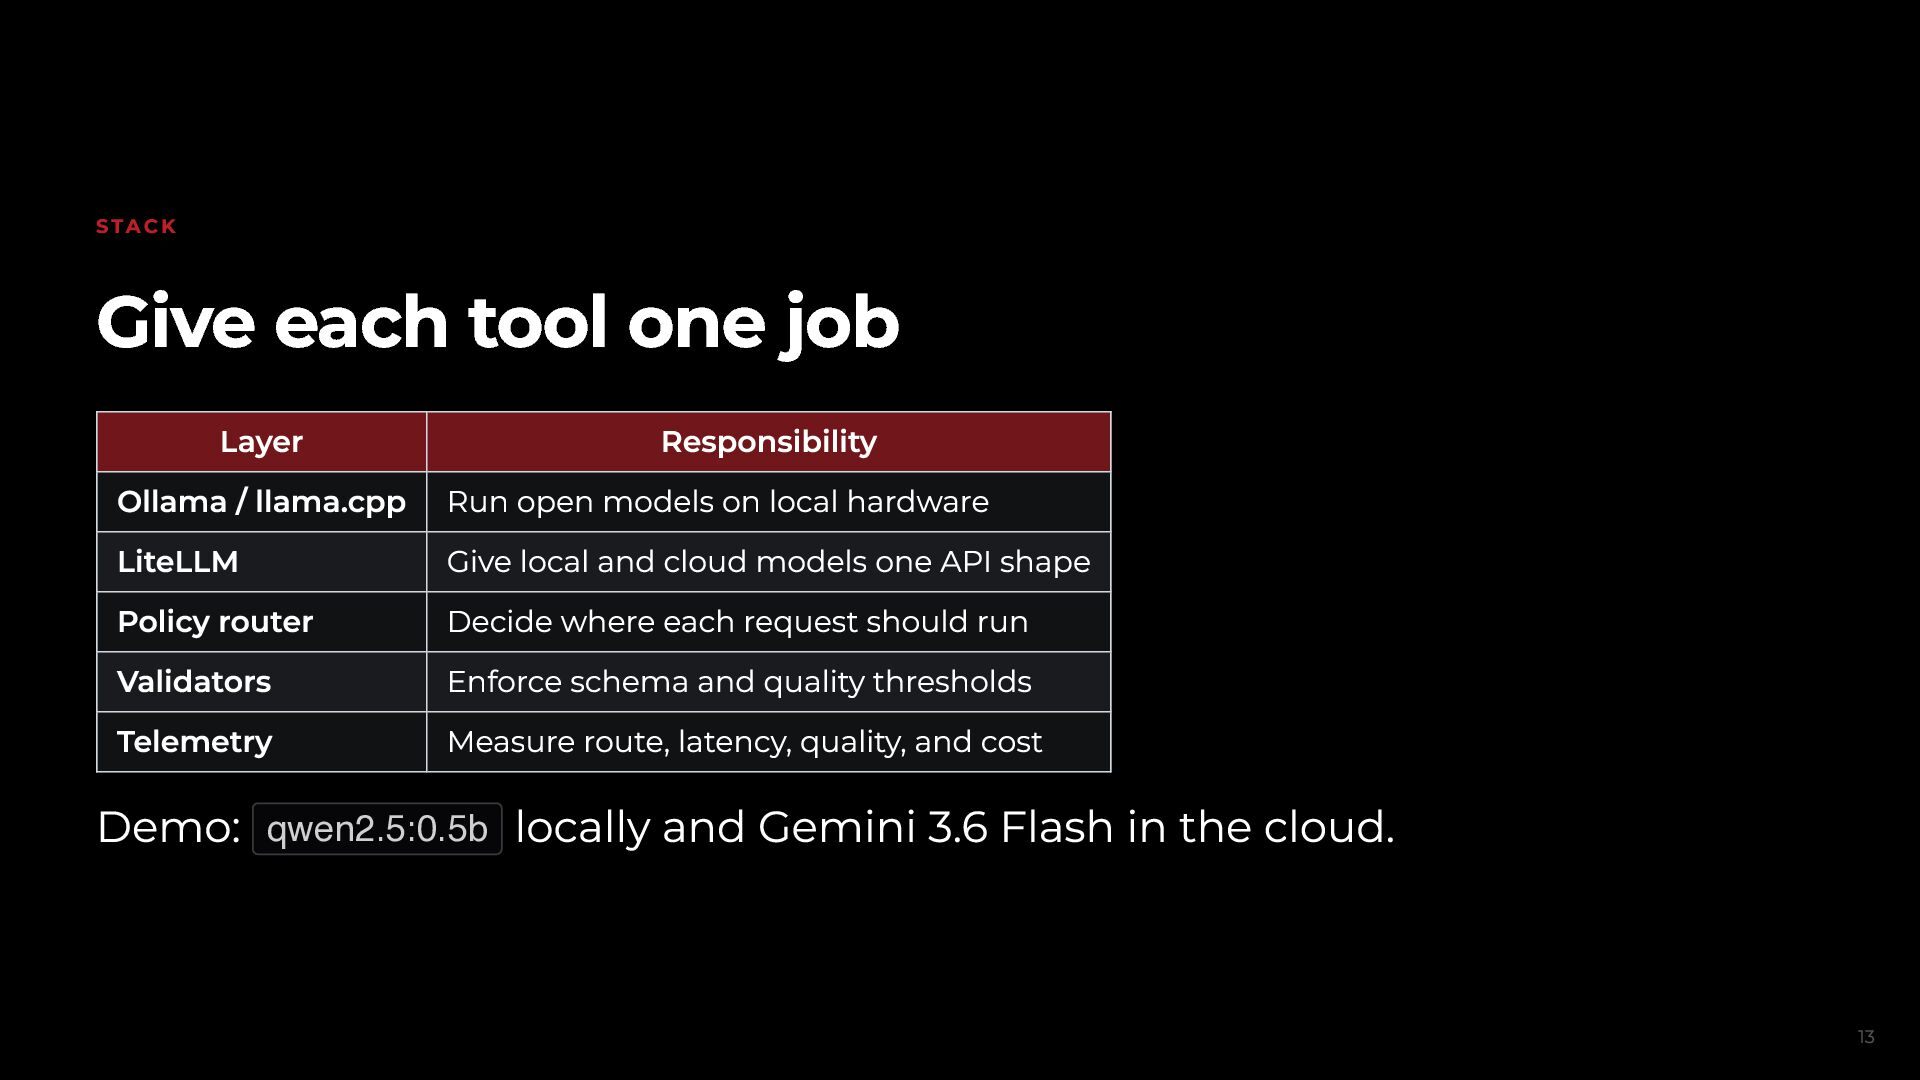
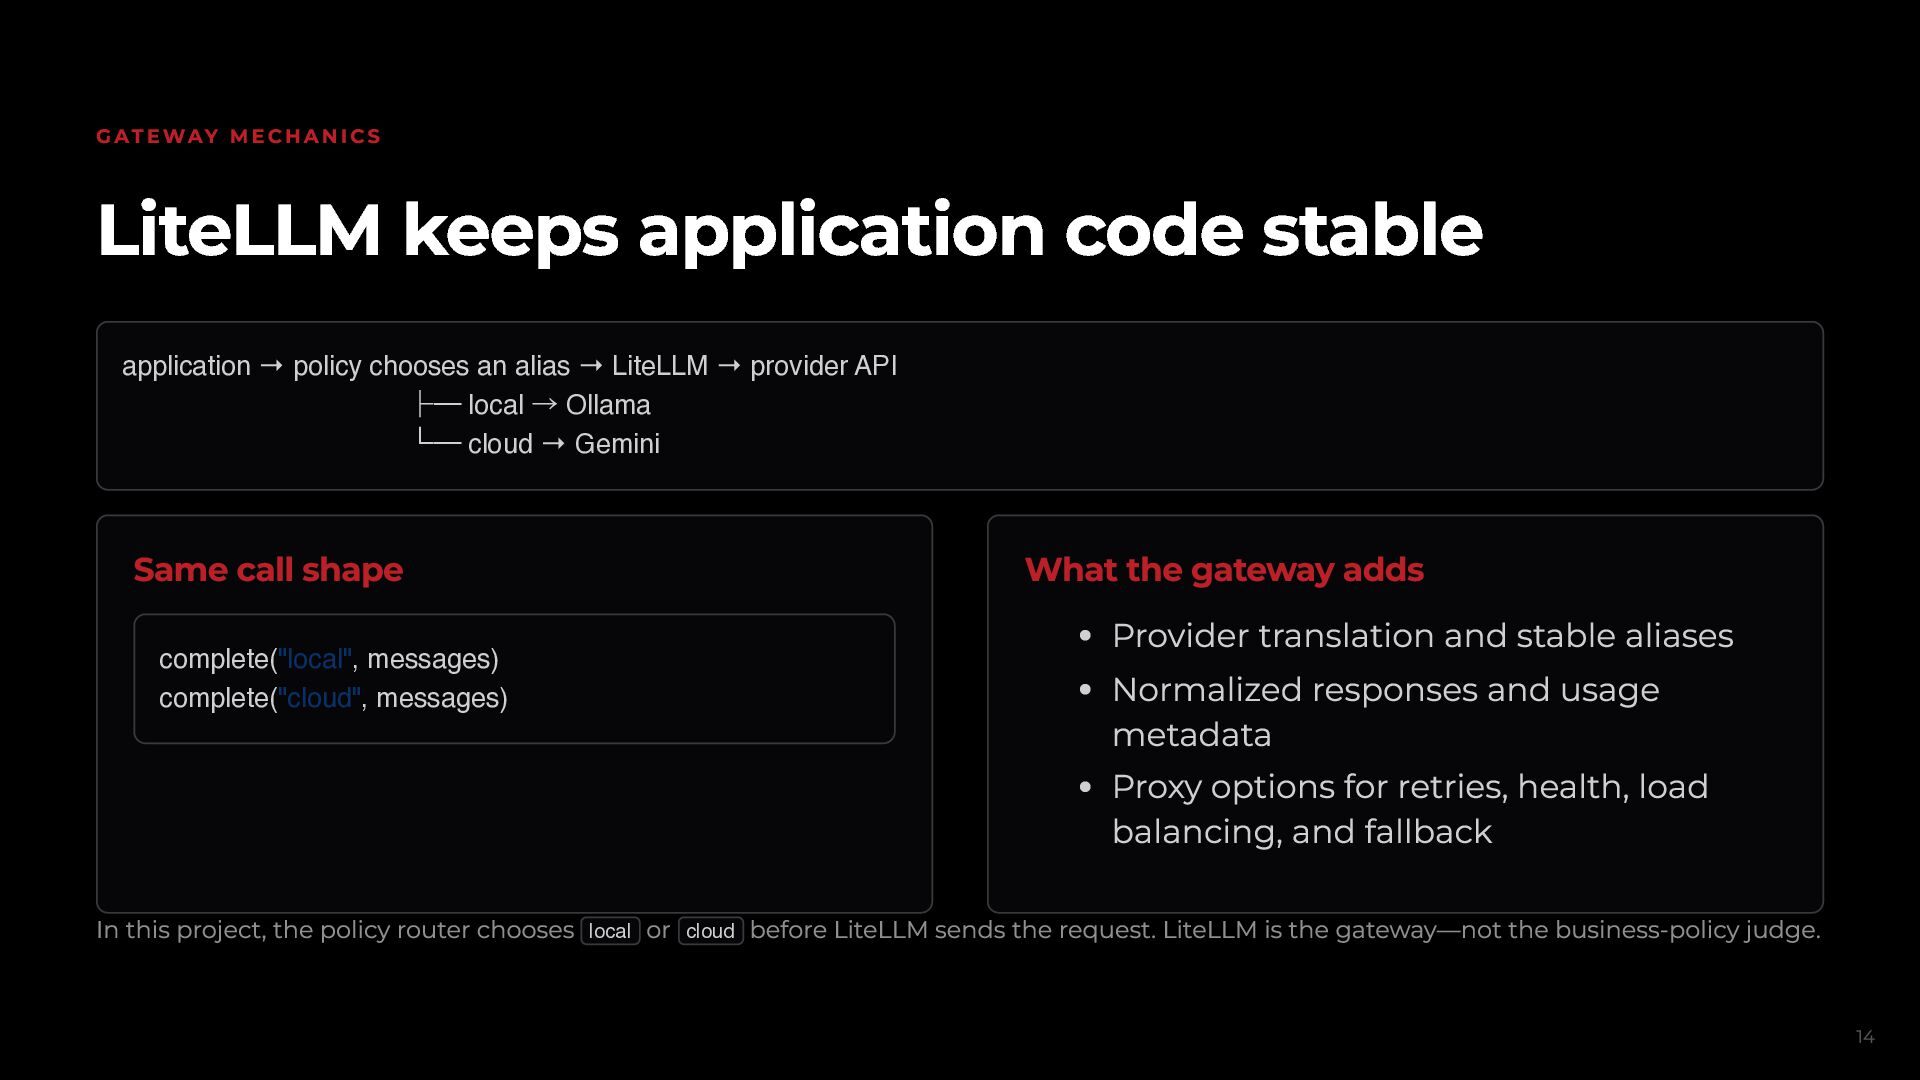
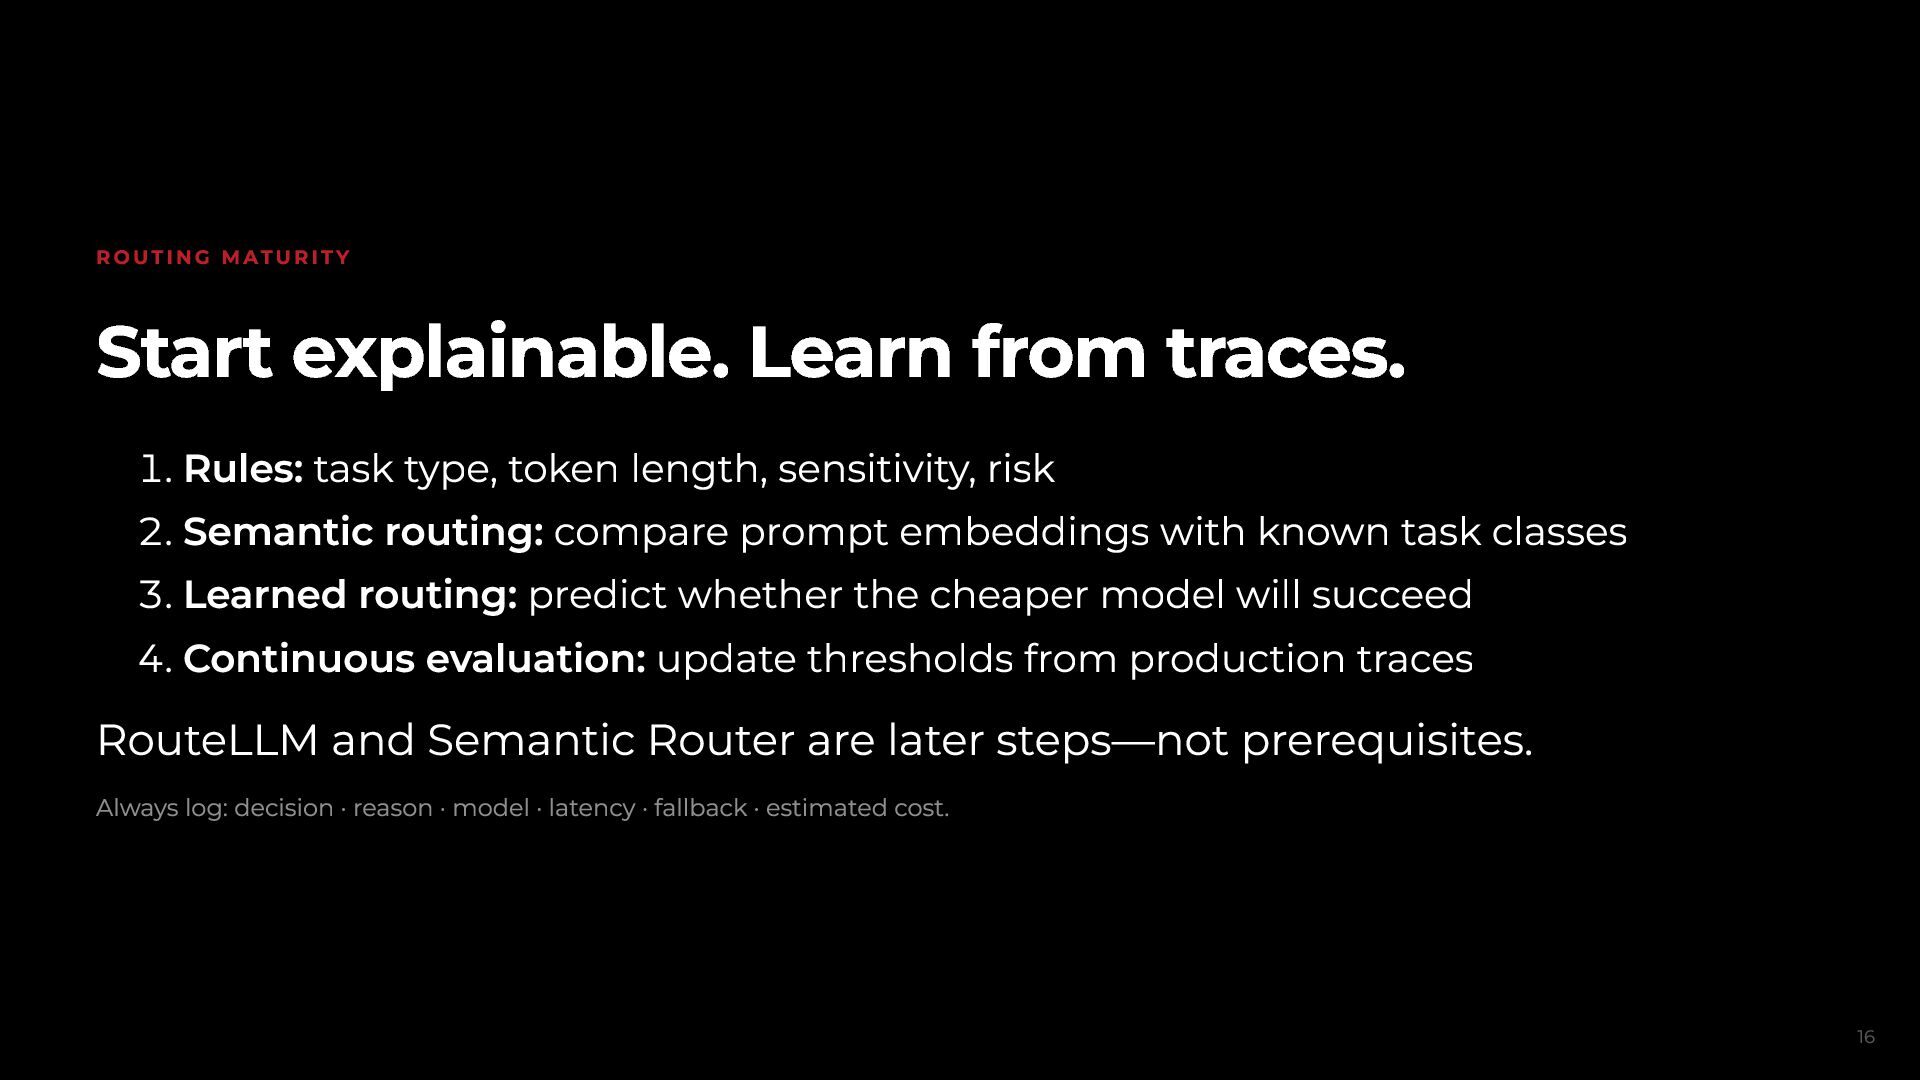
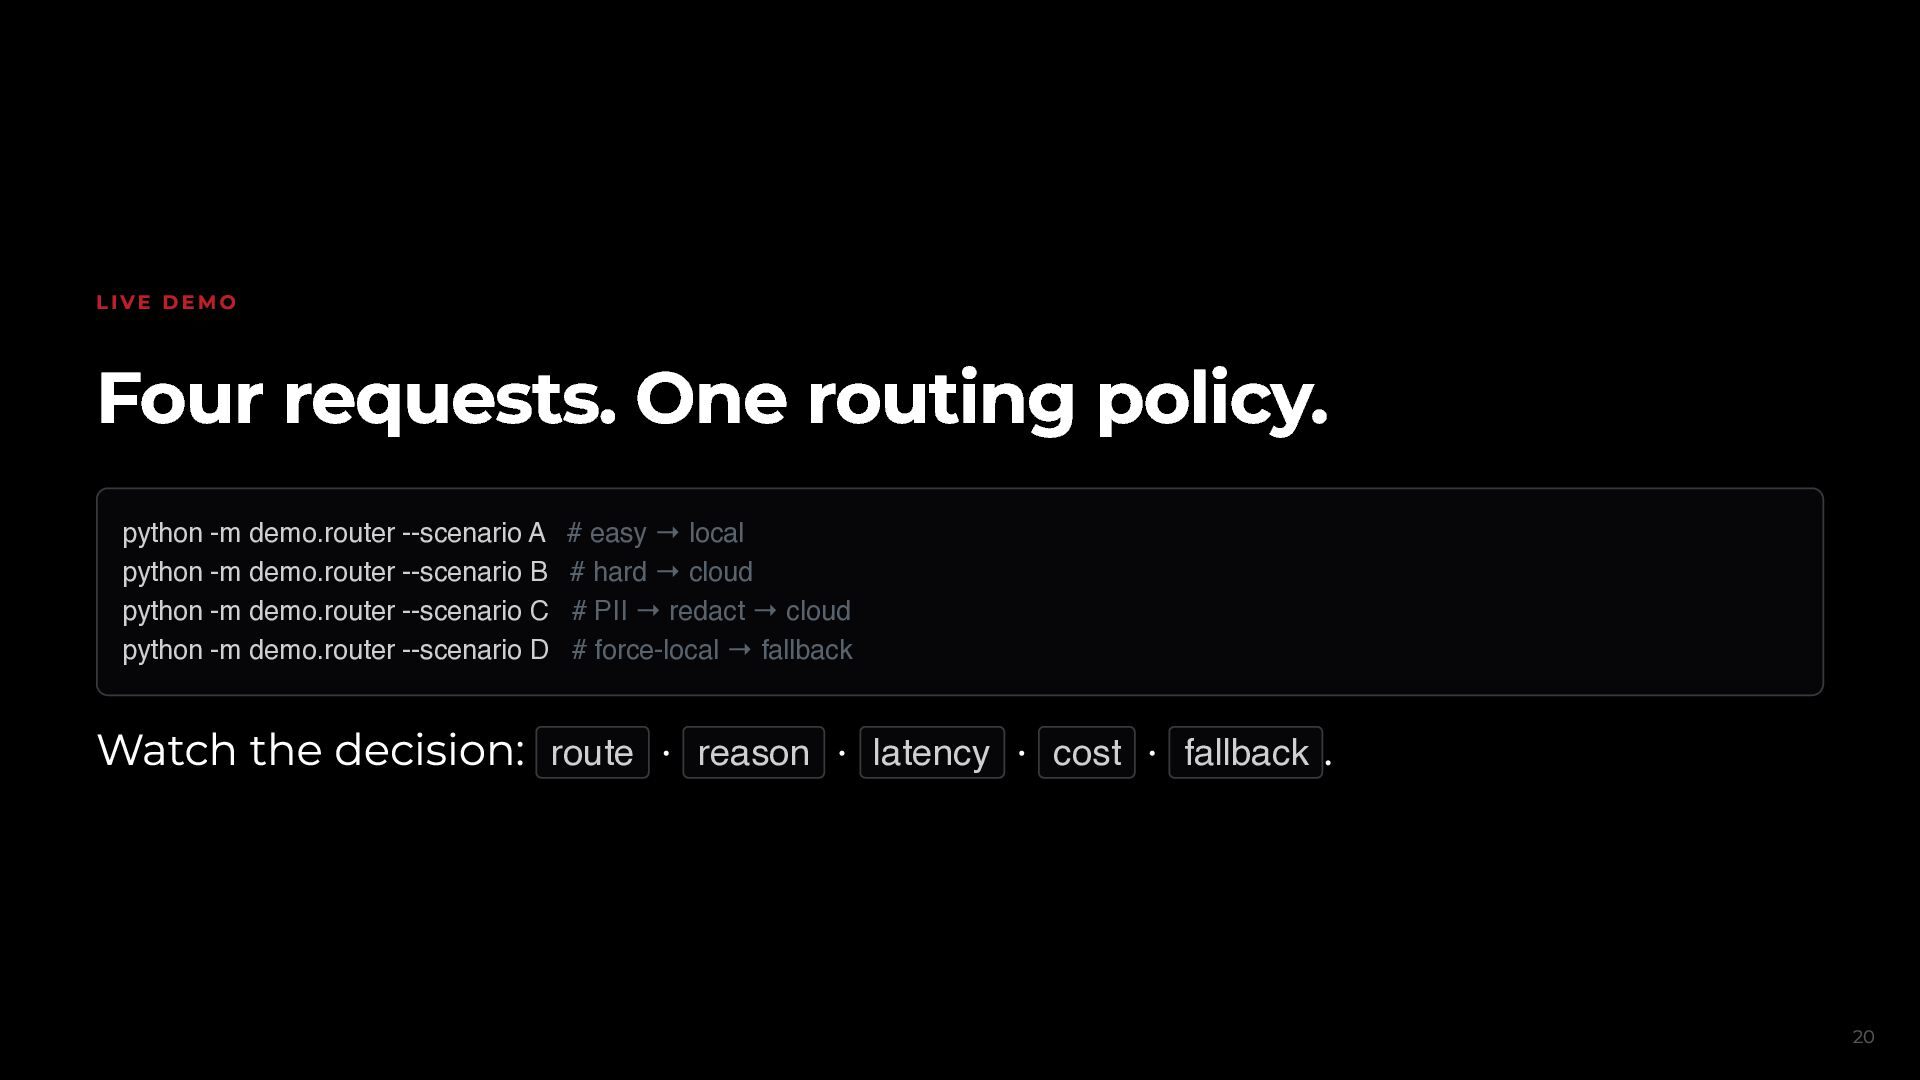
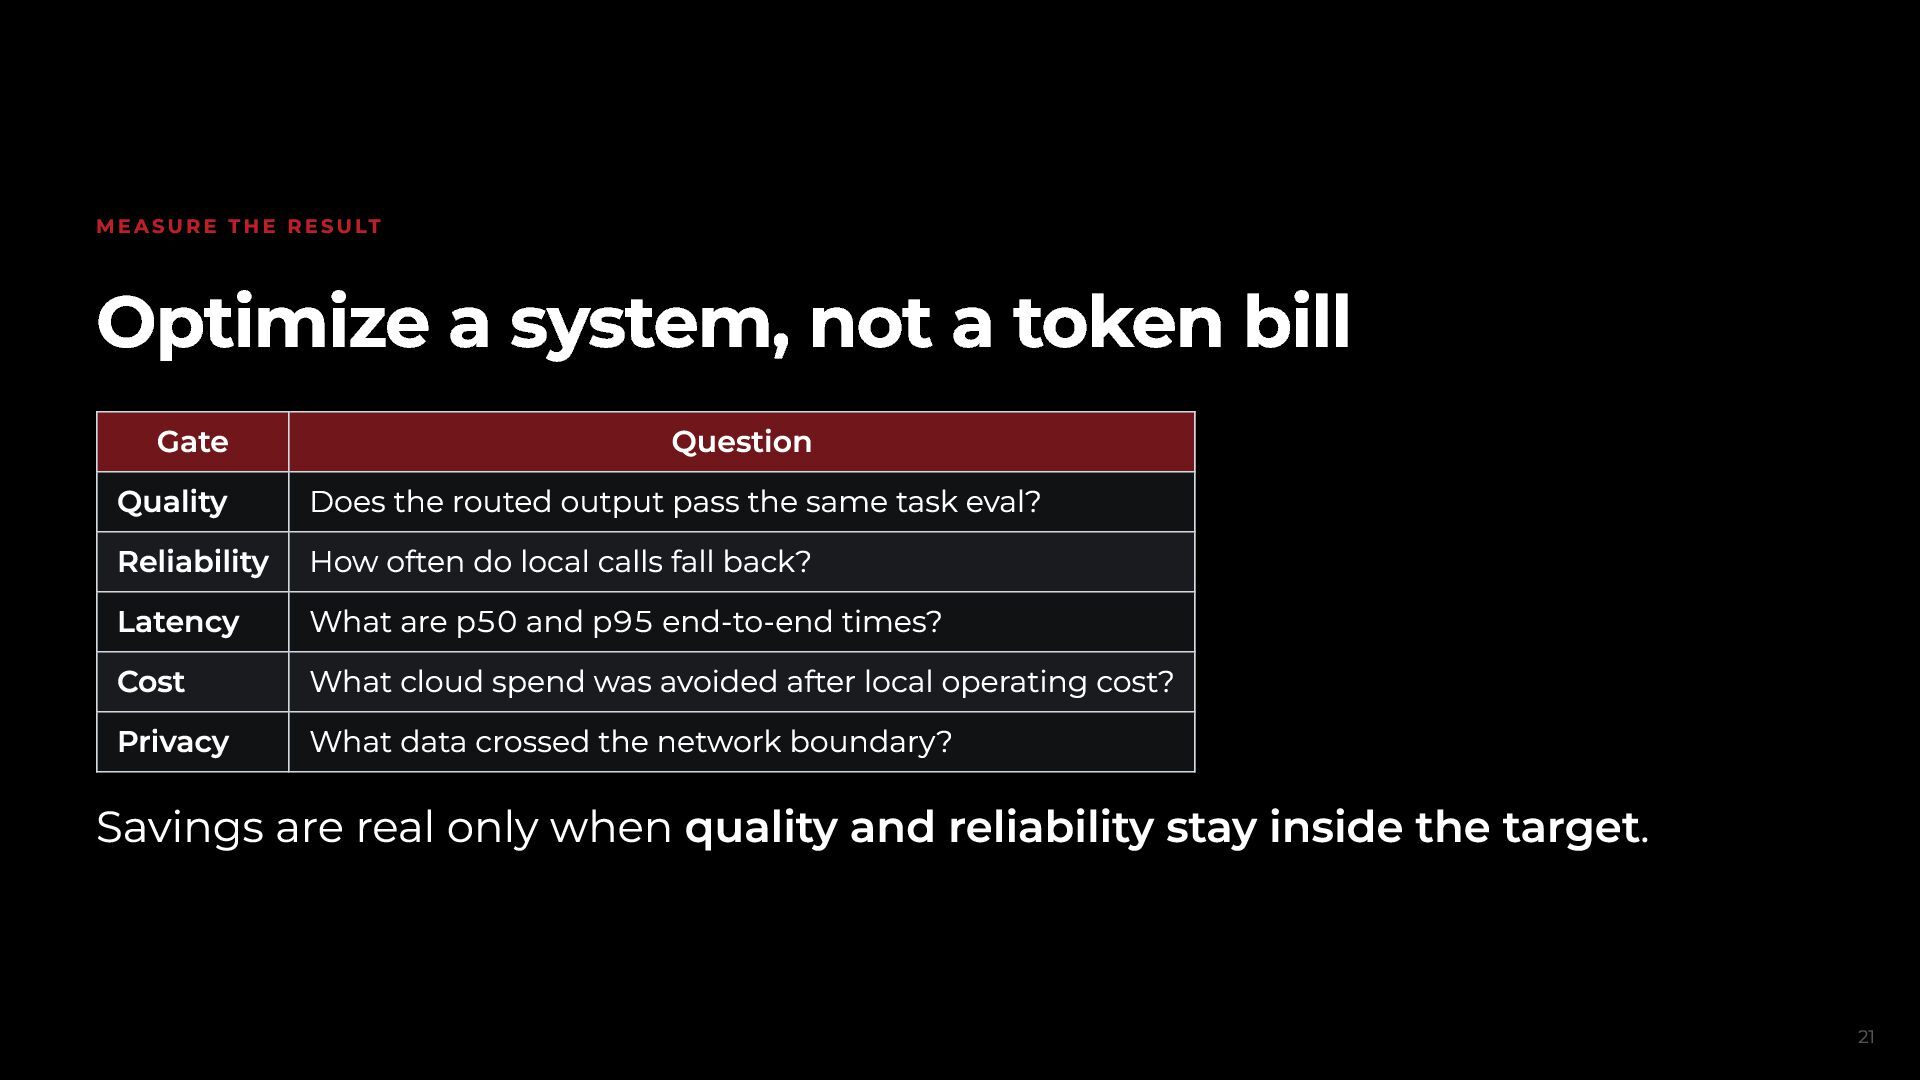
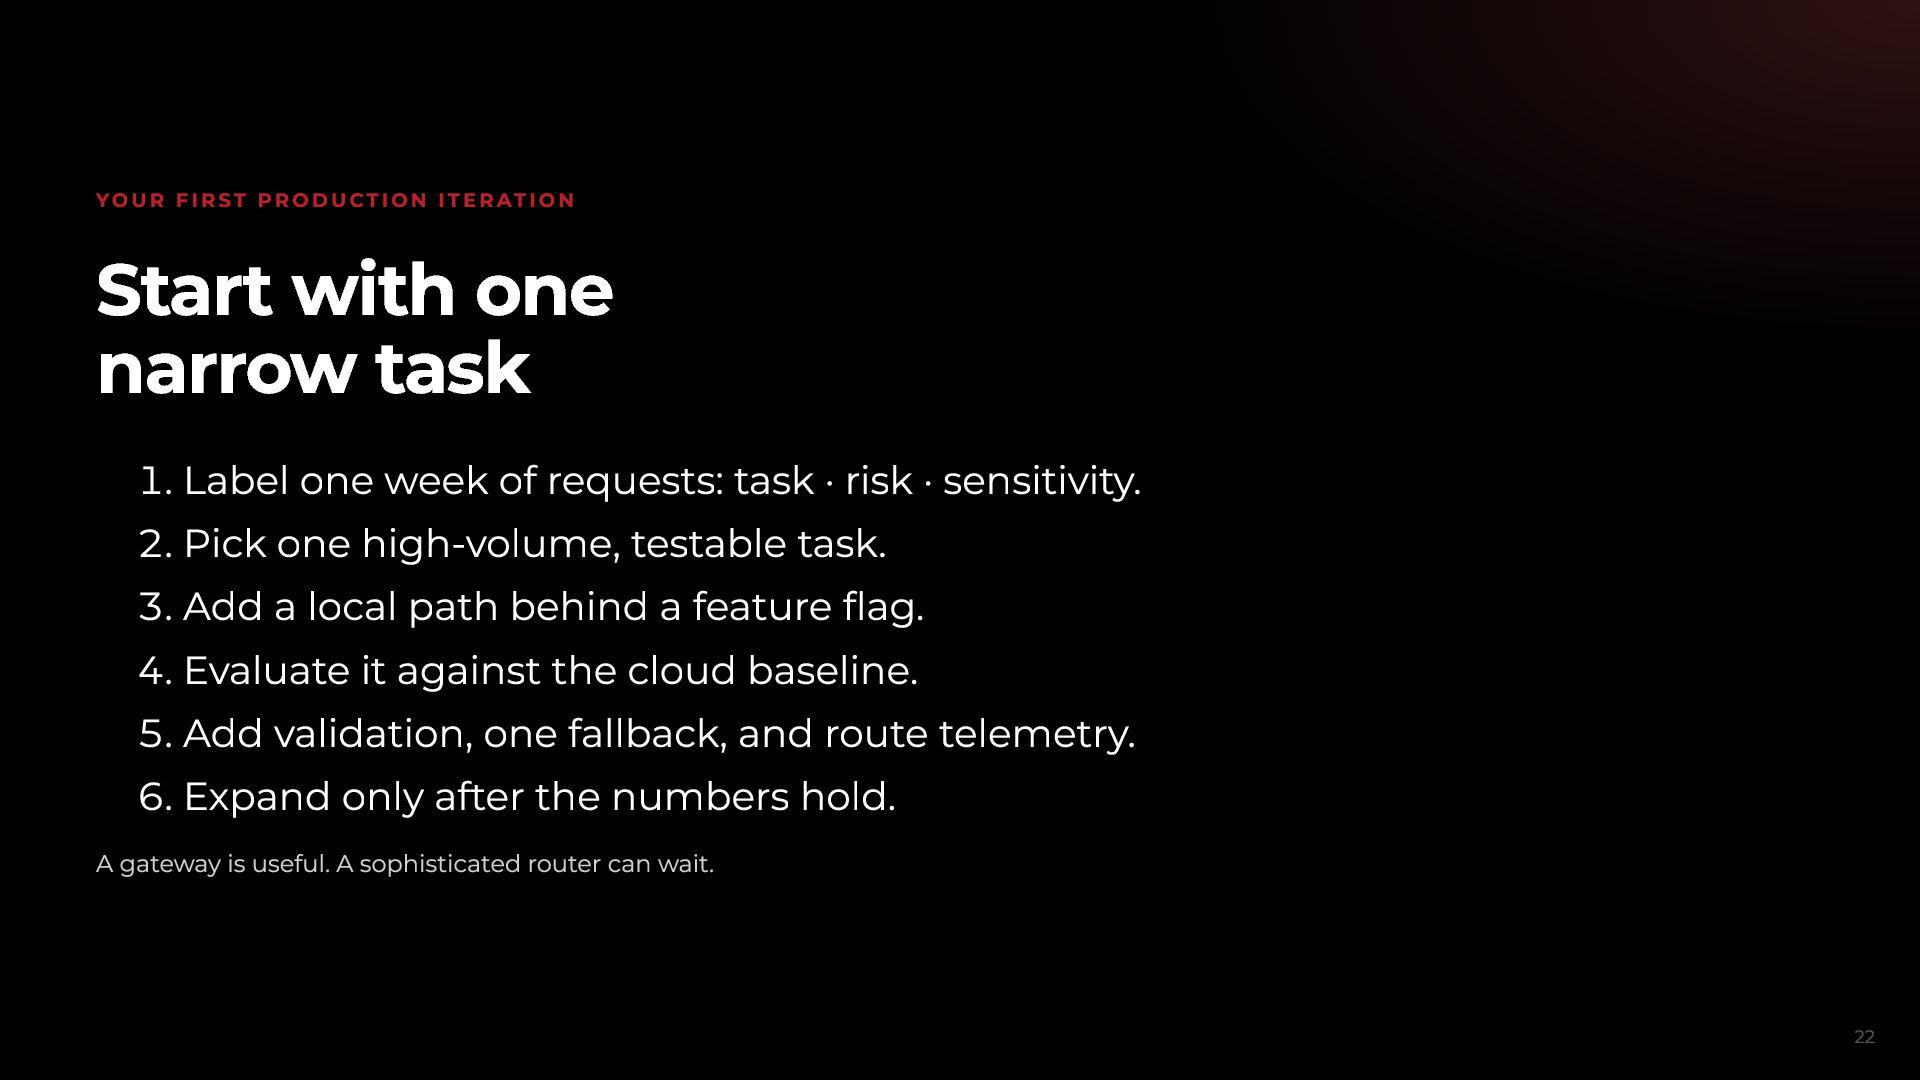
Not every AI request needs an expensive cloud model. This talk presents a practical architecture for routing predictable workloads to local models while reserving cloud LLMs for complex tasks.
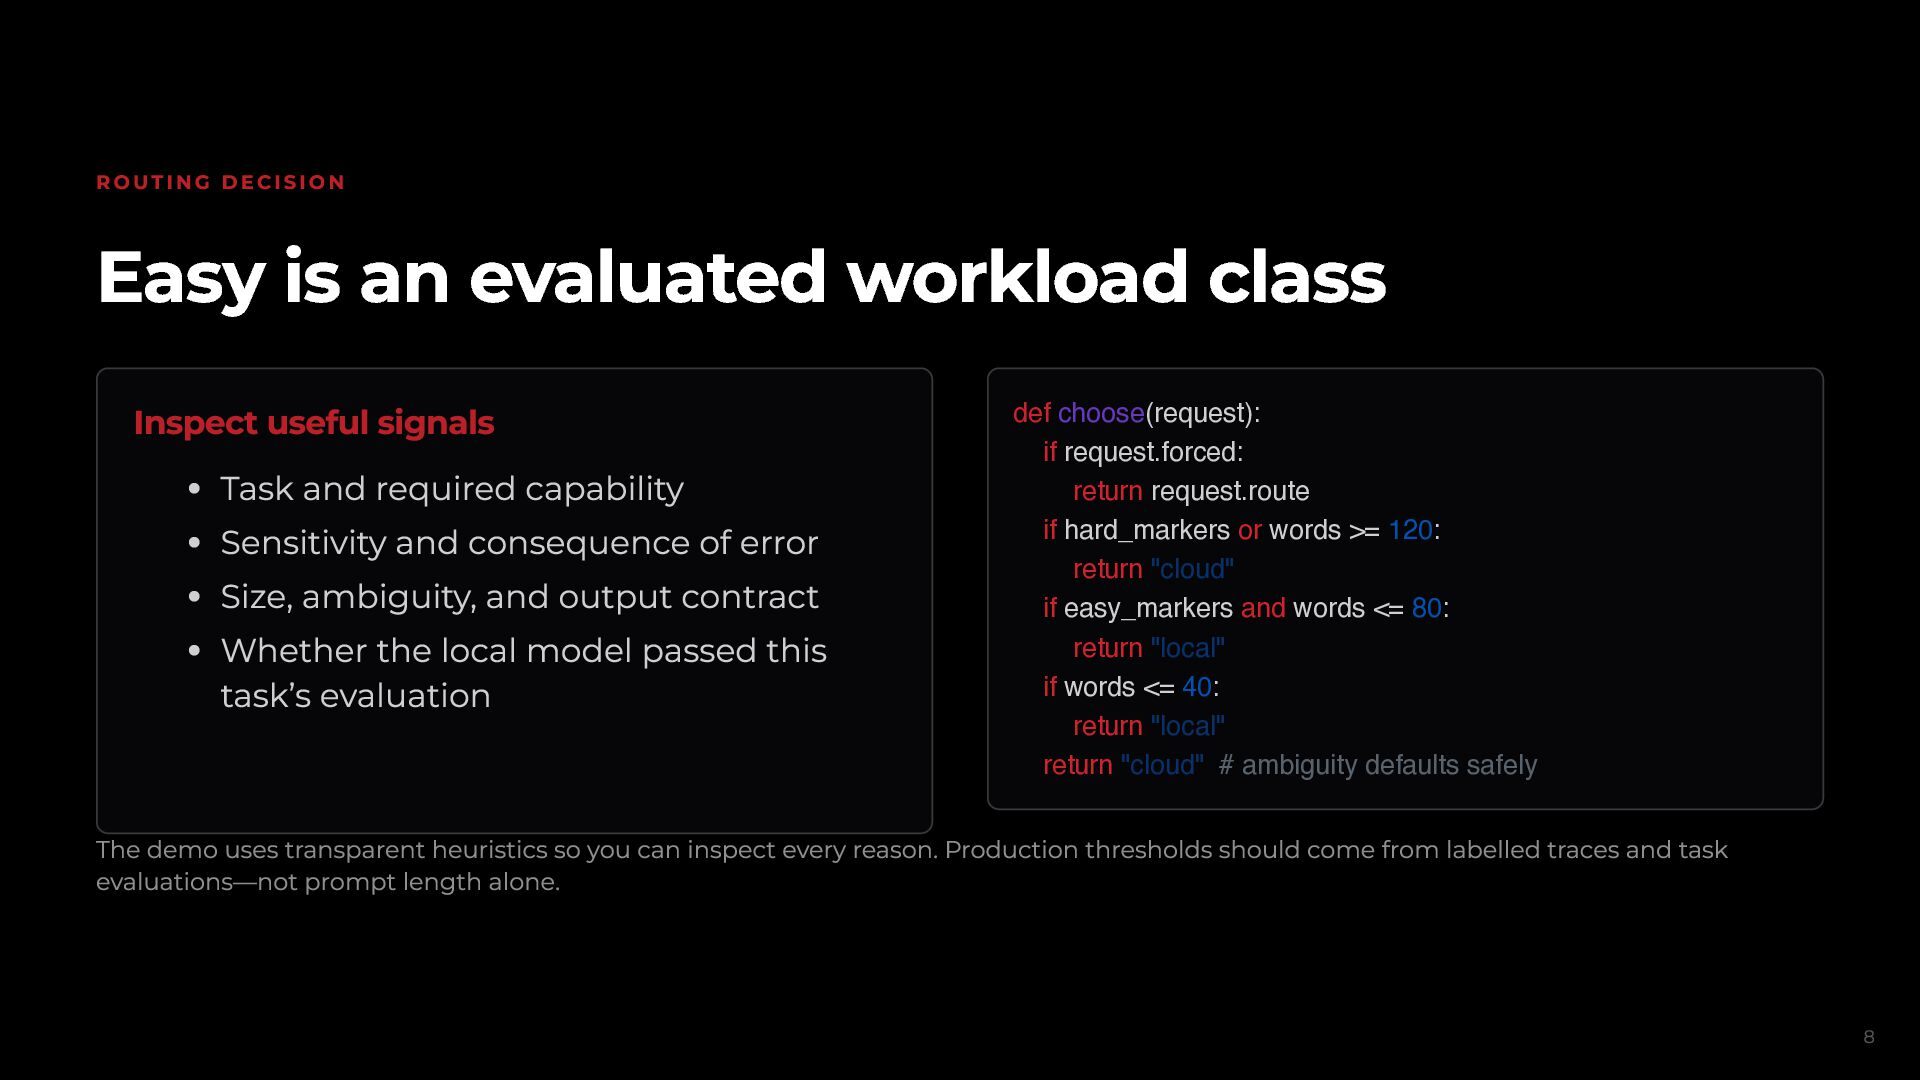
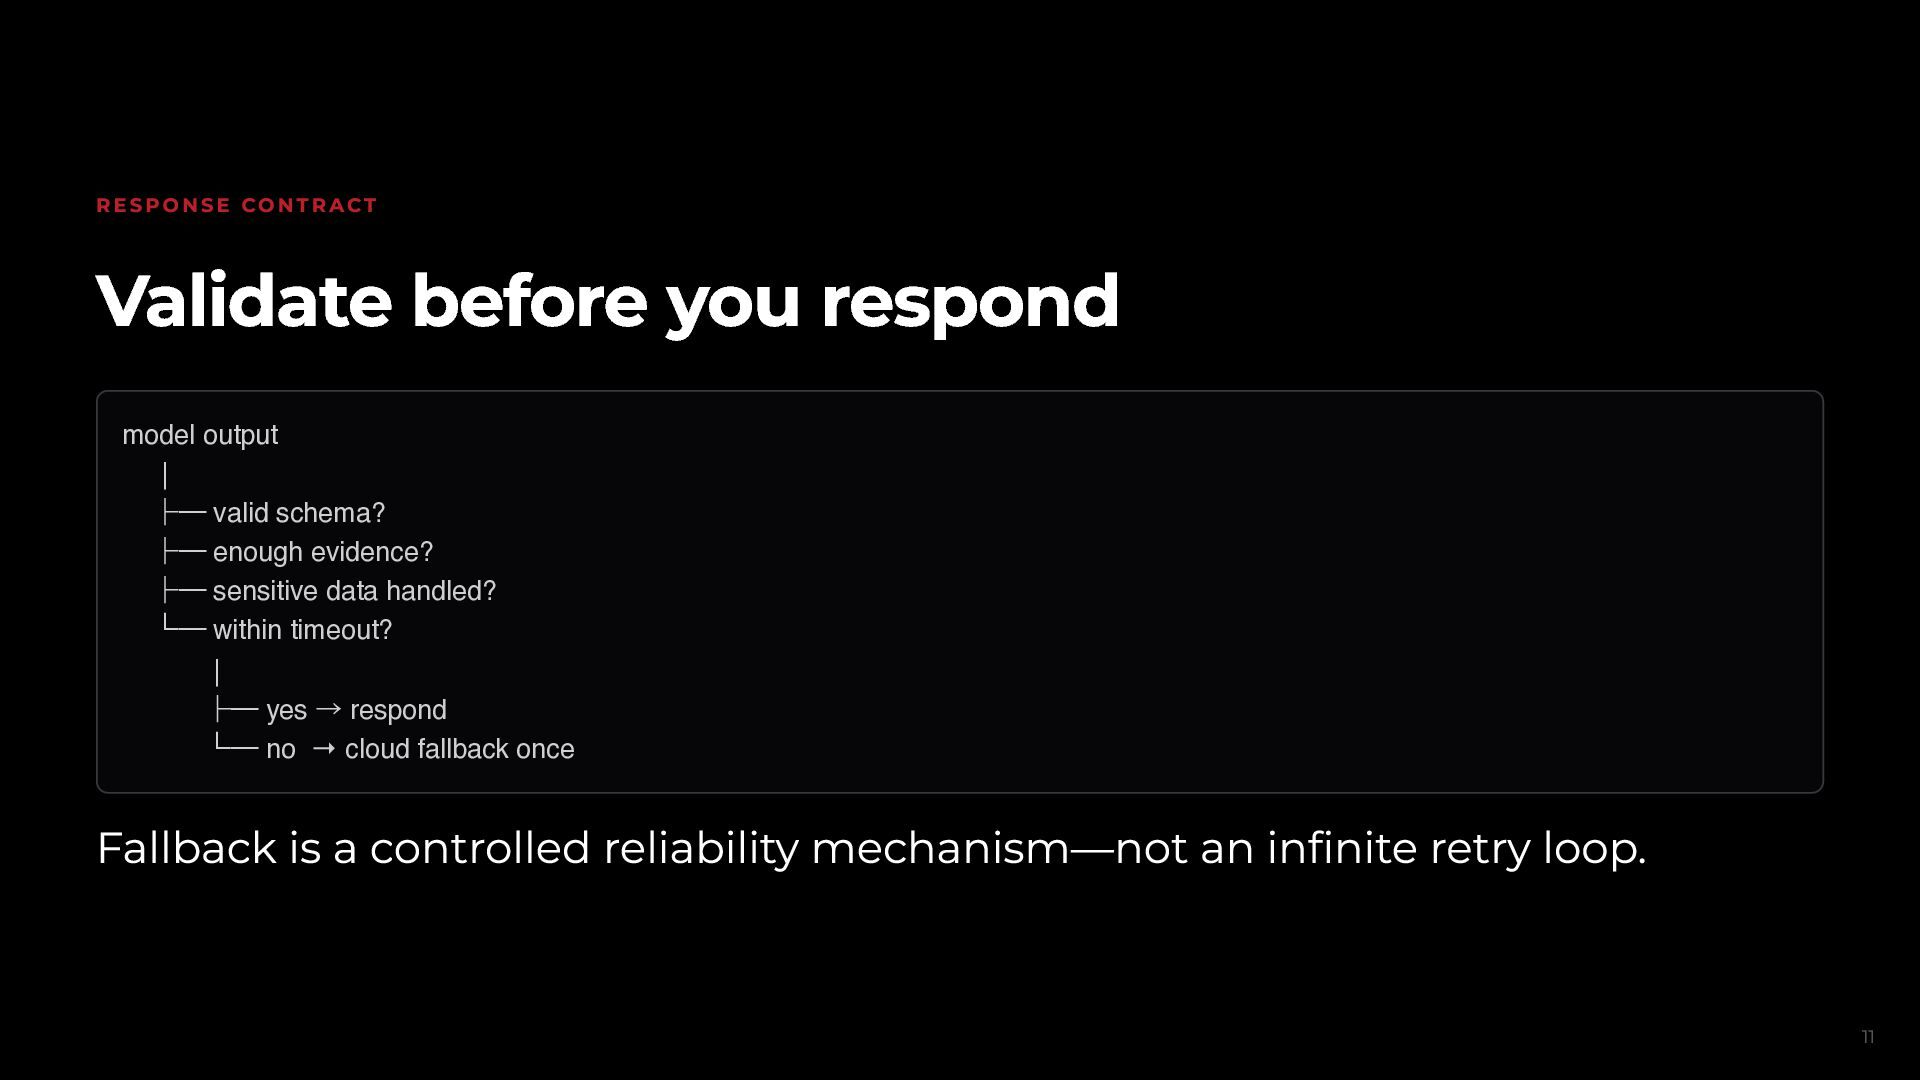
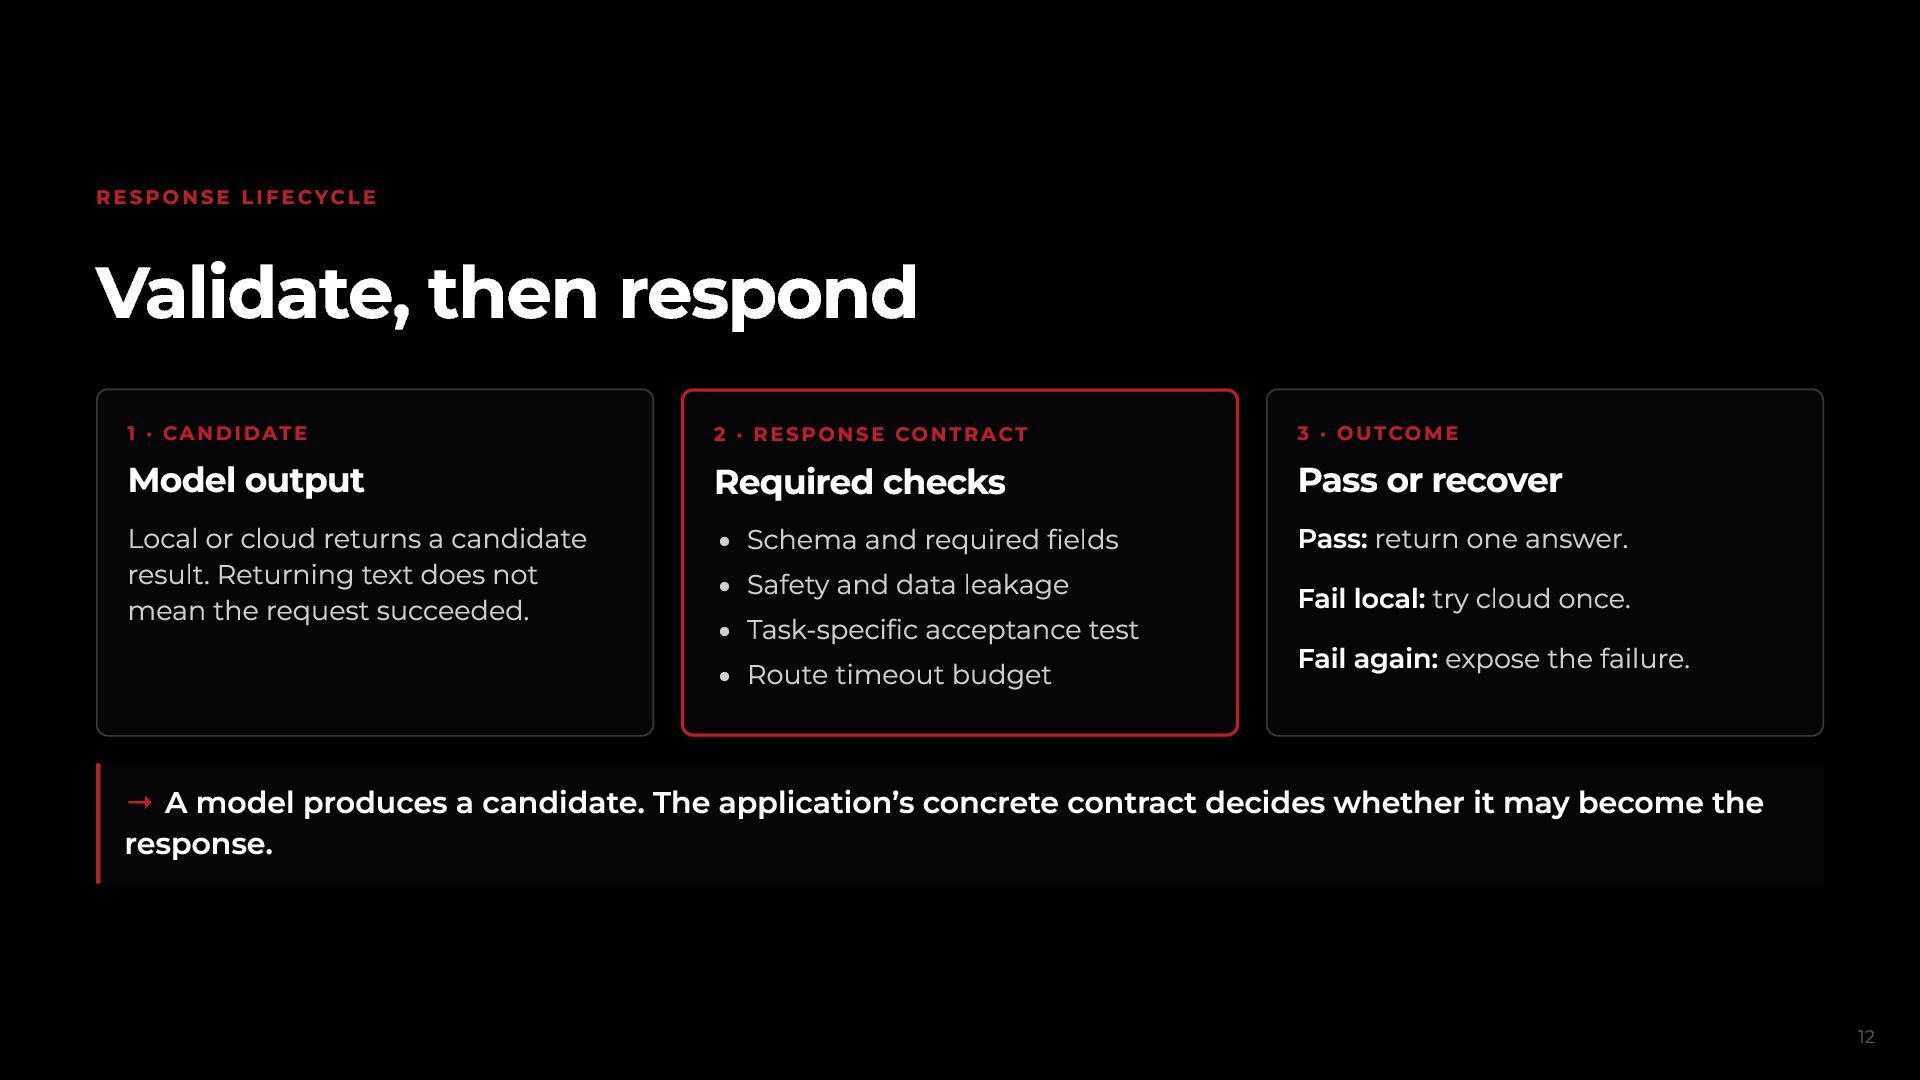
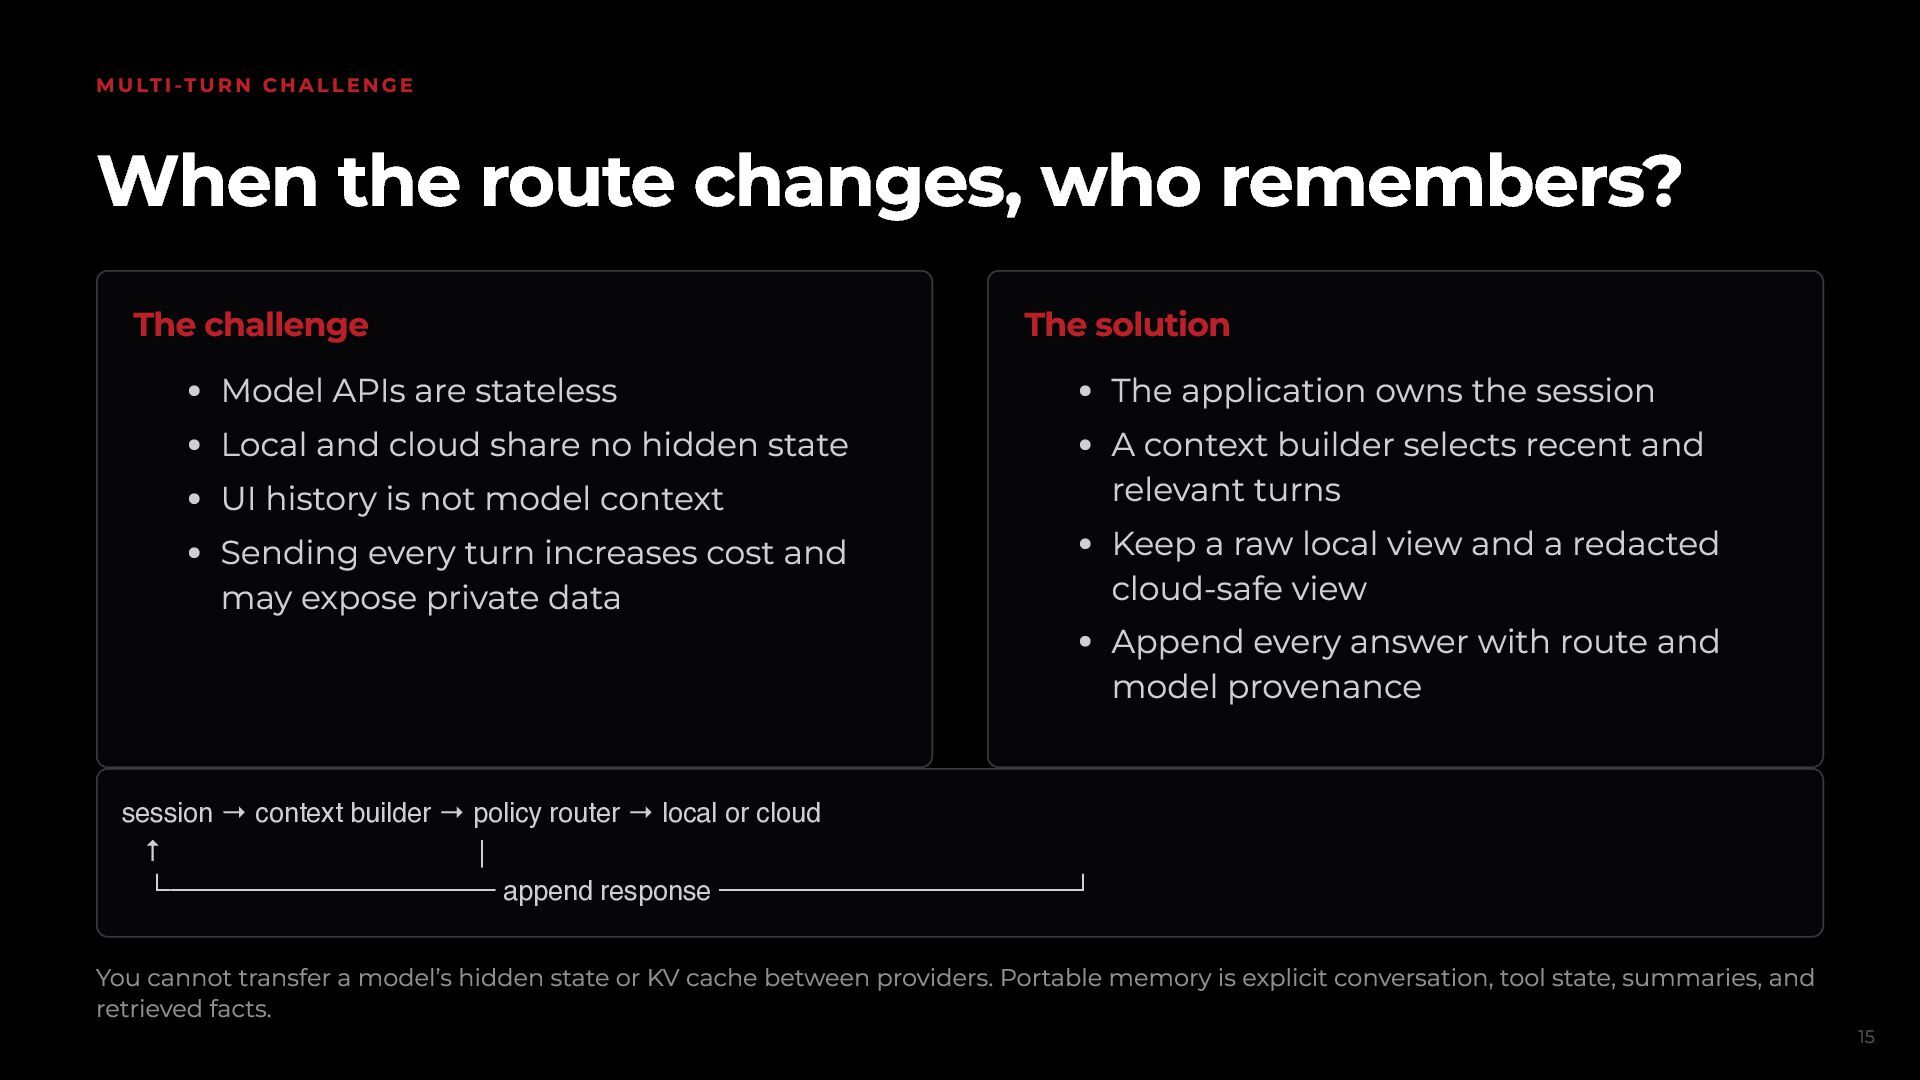
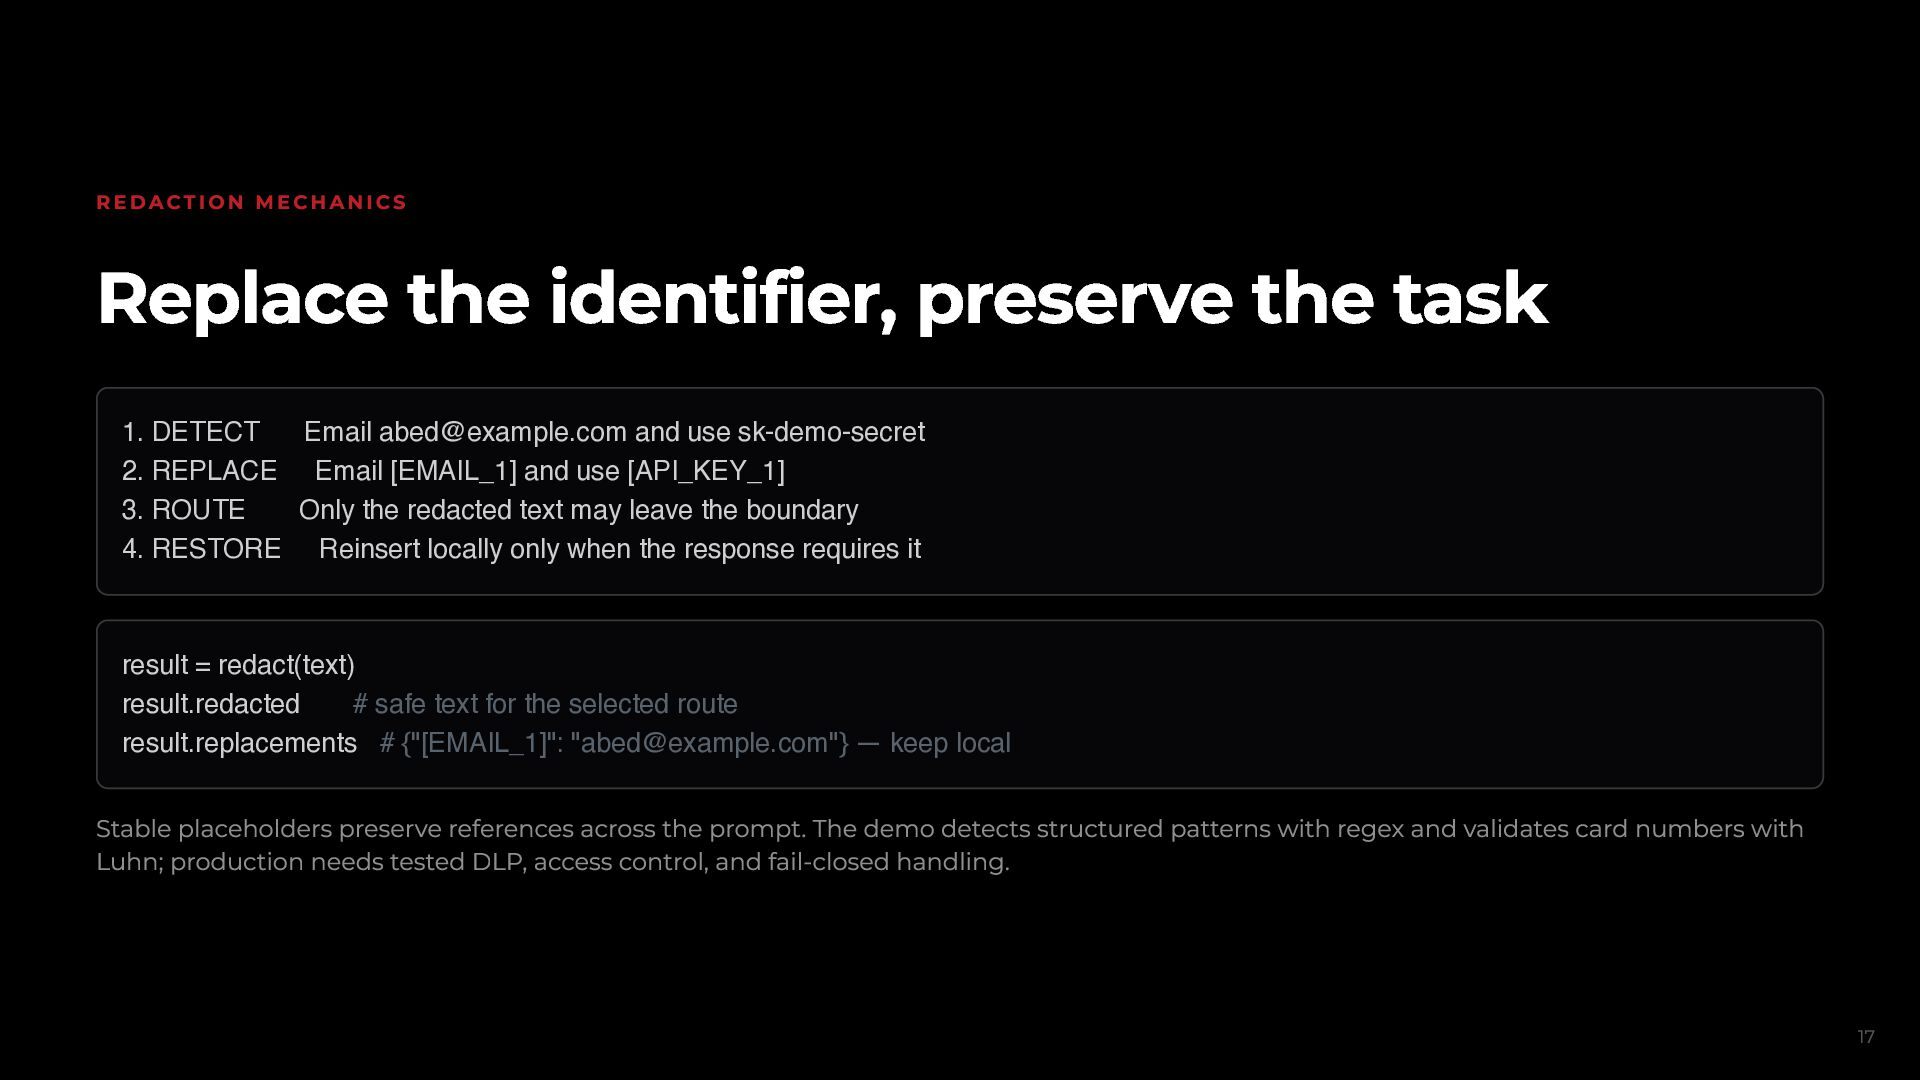
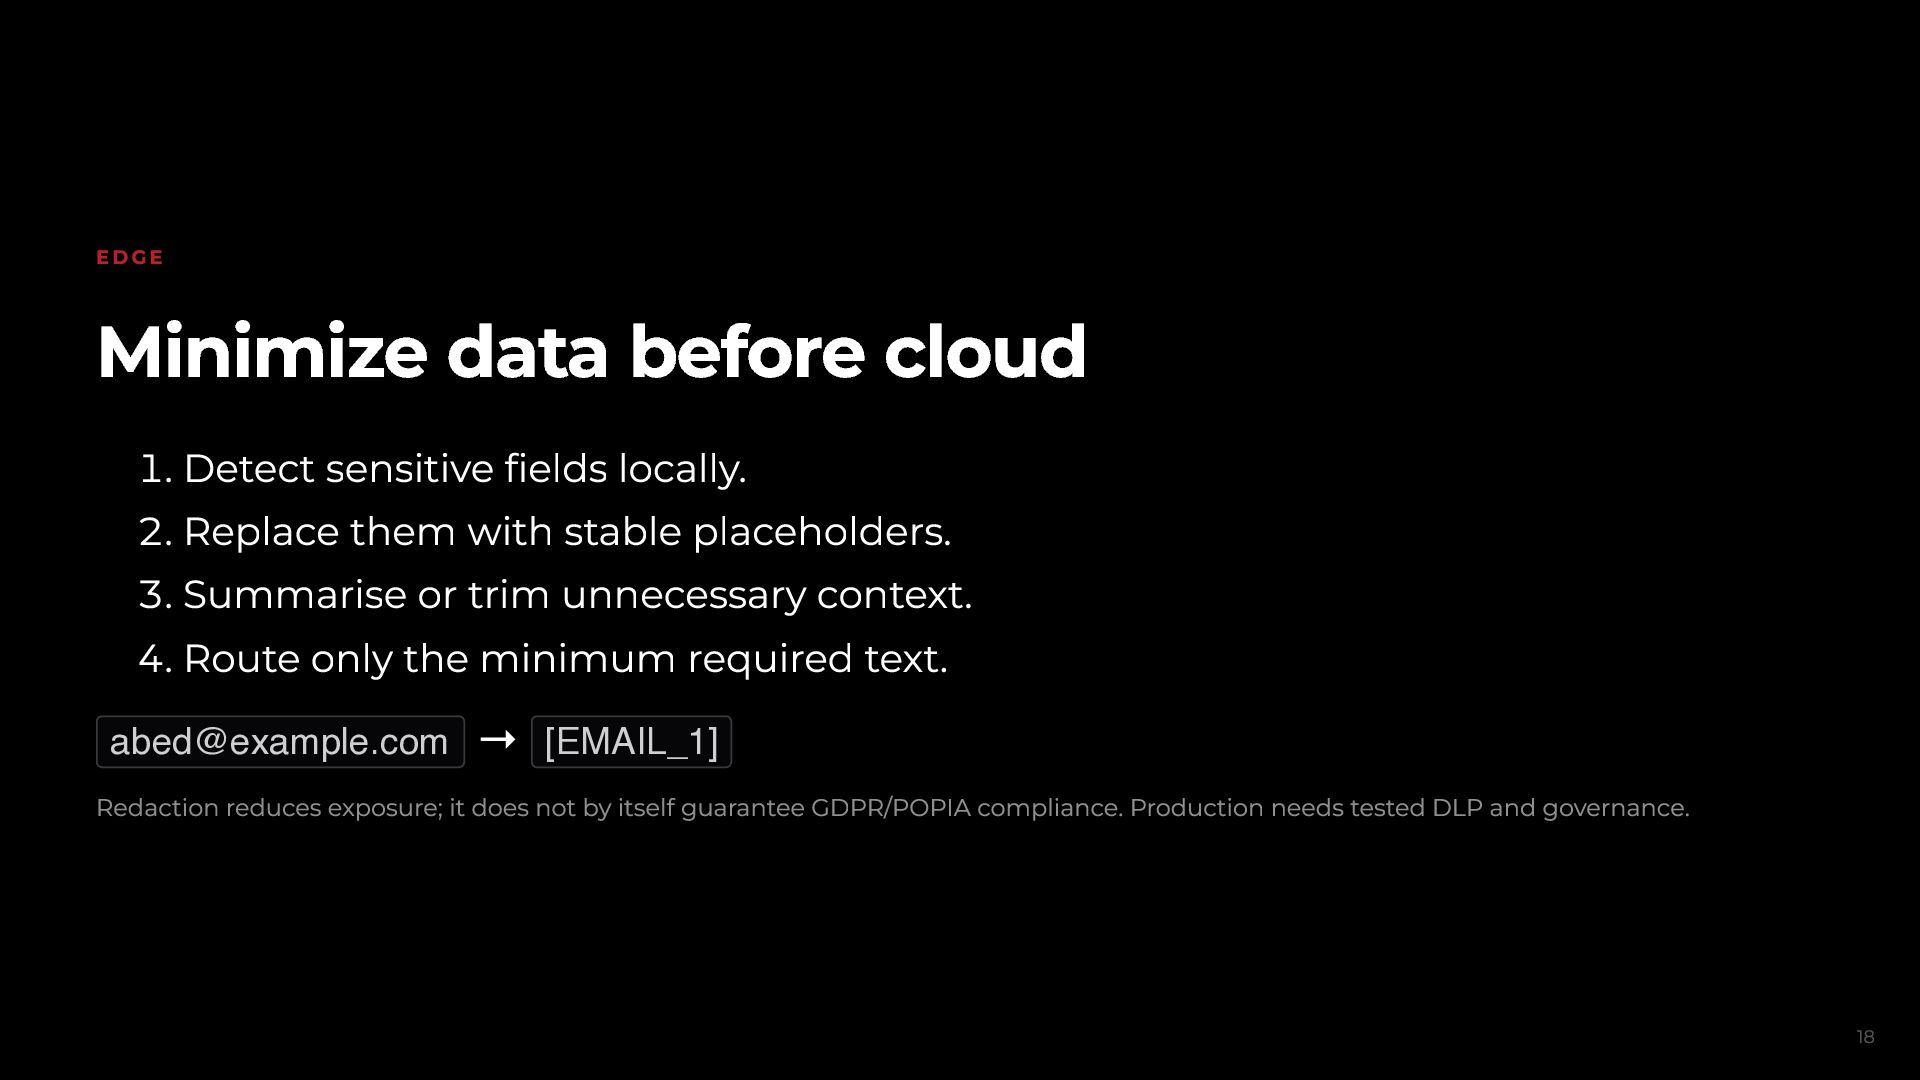
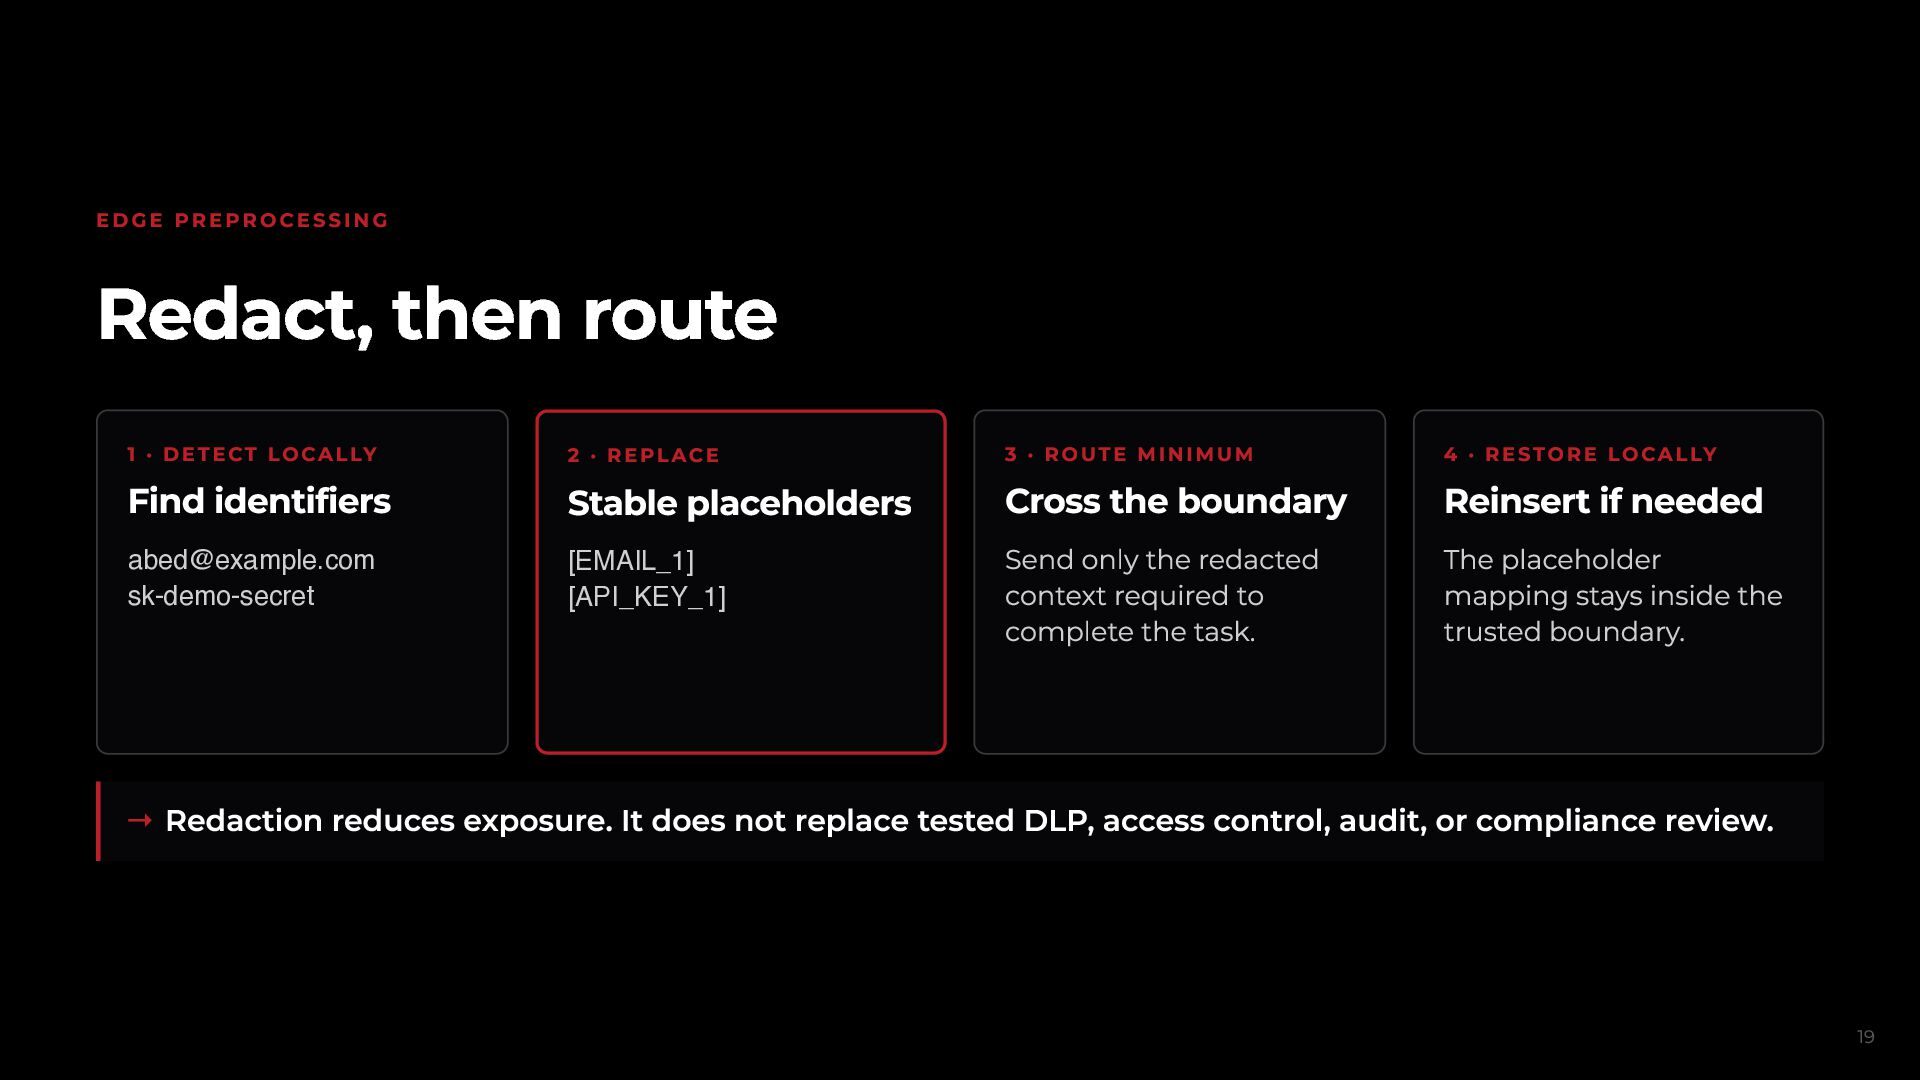
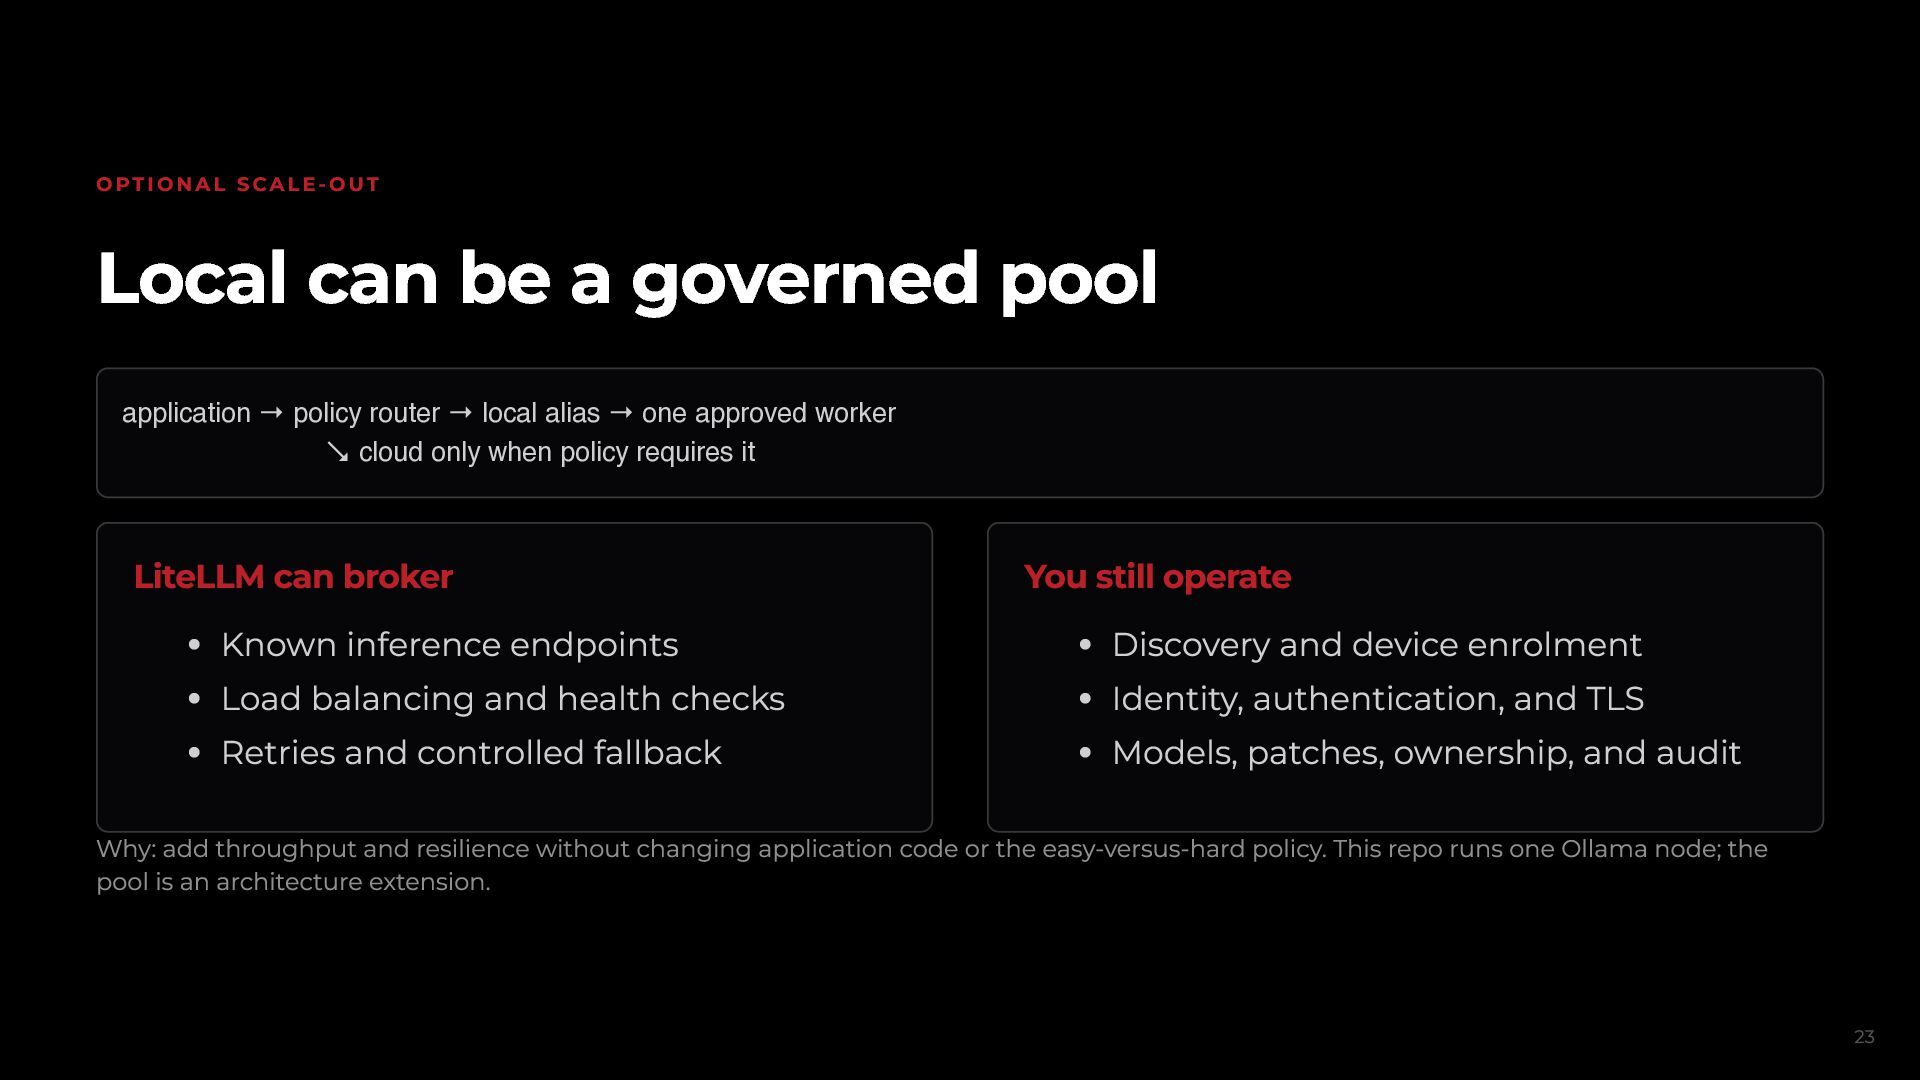
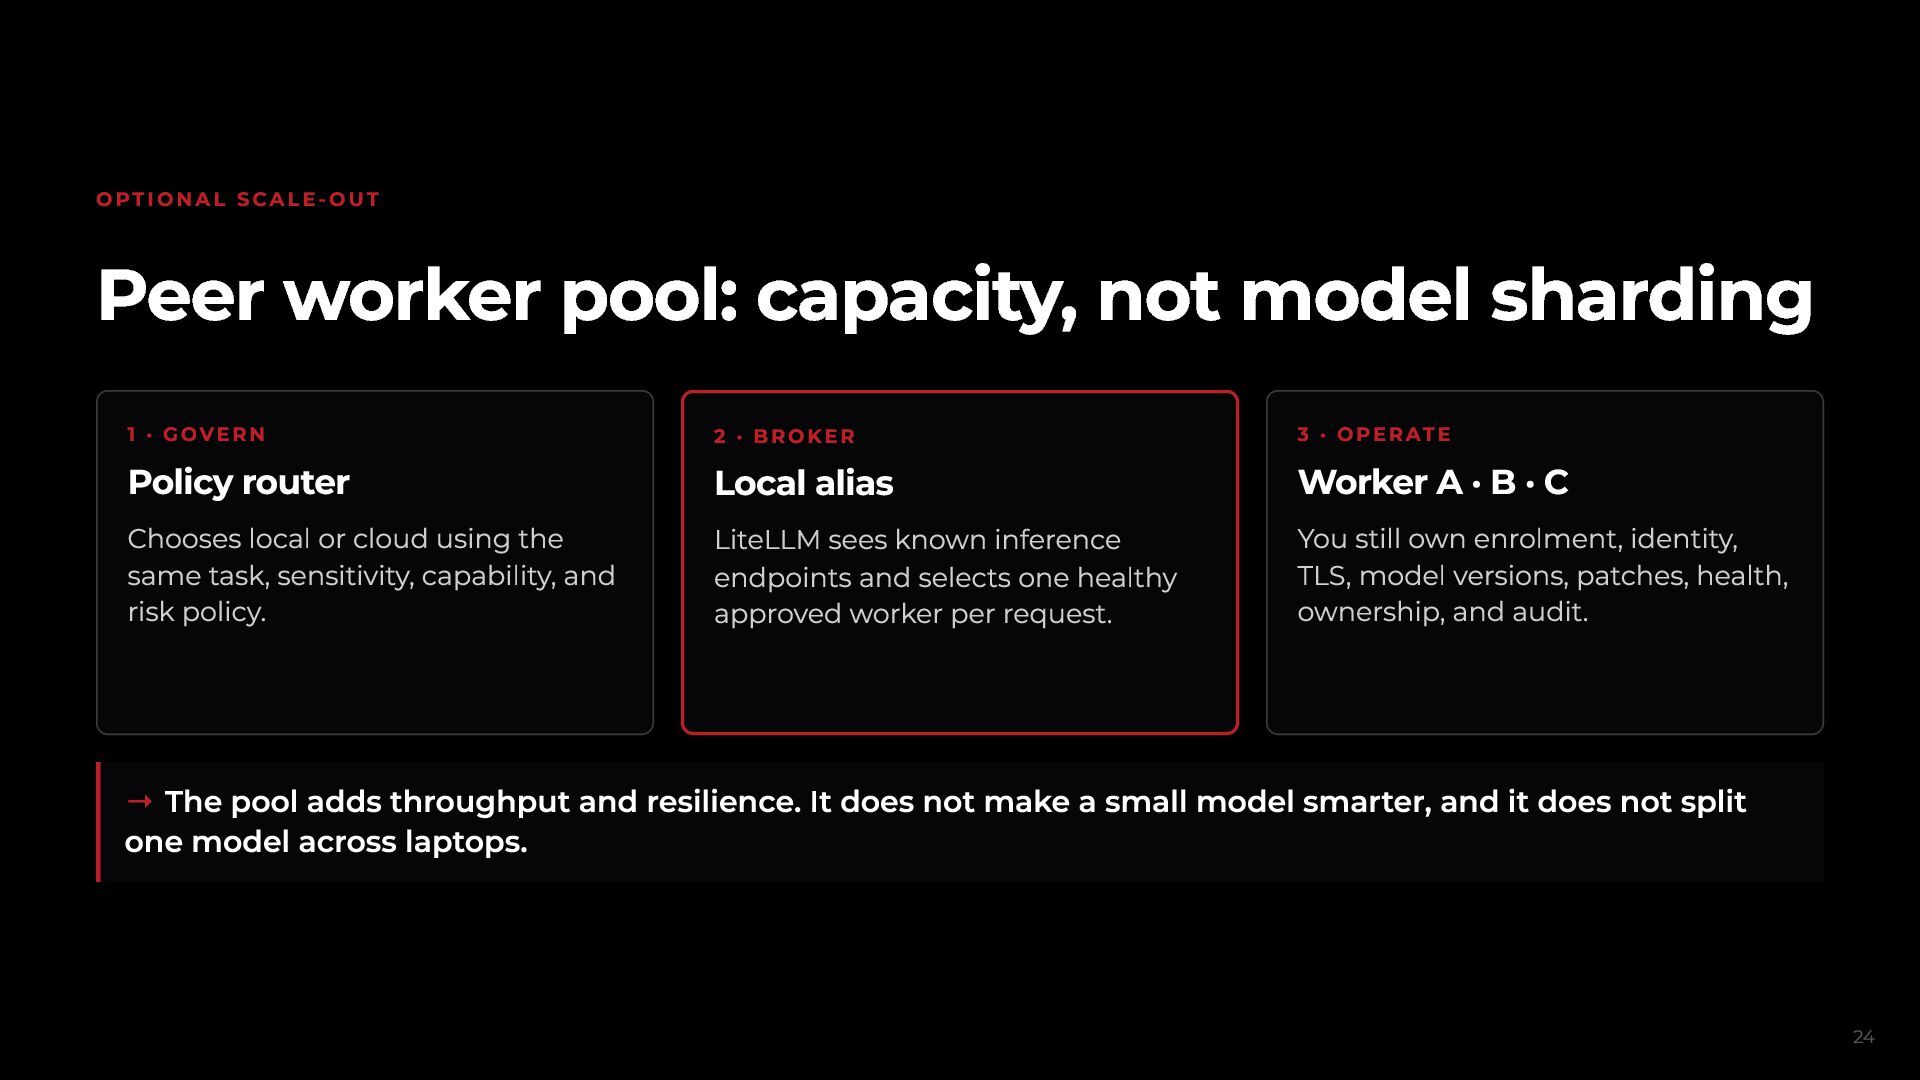
Learn how to design explainable routing, response validation, controlled fallback, sensitive-data redaction, conversation memory, telemetry, and governed local worker pools using tools such as Ollama and LiteLLM.


 abedmatini
 toru_kubota
 nasuvitz
 yutakaosada
 maimyyym
 logico_jp
 ysuzuki
 junkifurukawa
 judau
 aoto
 kentapapa
 kazukun0716
 ymiya55
 reverentgeek
 joshbly
 techseoconnect
 charlesmeaden
 scottboms
 ryanjones
 brettharned
 ivargrimstad
 mraible
 cassininazir
 gurzu