Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Intro to scikit-learn
Search
Olivier Grisel
August 27, 2017
Technology
760
5
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Intro to scikit-learn
EuroScipy 2017
Olivier Grisel
August 27, 2017
More Decks by Olivier Grisel
See All by Olivier Grisel
An Intro to Deep Learning
ogrisel
1
360
Predictive Modeling and Deep Learning
ogrisel
2
410
Intro to scikit-learn and what's new in 0.17
ogrisel
1
430
Big Data, Predictive Modeling and tools
ogrisel
2
360
Recent Developments in Deep Learning
ogrisel
3
740
Documentation
ogrisel
2
290
How to use scikit-learn to solve machine learning problems
ogrisel
0
1.1k
Build and test wheel packages on Linux, OSX and Windows
ogrisel
2
390
Big Data and Predictive Modeling
ogrisel
3
270
Other Decks in Technology
See All in Technology
LLM Content Moderationを支える評価・改善ループの実践
suikabar
2
320
AI時代、つくる力を自分たちの手に。 ──電通×KAG、アジャイルとAI駆動開発で挑む開発の変革
yuukiyo
2
160
国際カードブランドルール変更に伴うクレジットカード決済取引仕様変更について
k1style
0
180
How to Design Configuration for Rails Applications
willnet
1
1.1k
企画を Software Factory-ready にする——開発が高速になったとき、PdMの仕事はどう変わったか
yachibit
1
180
日本AIベンチャーレポート2026
kentarofujii
0
160
Draft AIエージェントの トークン消費を最小化する 8つの原則
kinopeee
1
780
「Learning Outcome」を書きたくない私が、Learning Outcomeと折り合いをつけるまで
mhlyc
0
150
価値について
gree_tech
PRO
0
160
初海外で注意すべきこと12選!!!安全快適なre:invent生活にするために
yuuuuuuu168
1
210
freeeにおける AI を用いた ブラウザ動作確認の自動化の取り組み
freee
PRO
0
170
Codex を使った障害対応机上演習の実際
orgachem
PRO
0
330
Featured
See All Featured
Six Lessons from altMBA
skipperchong
29
4.5k
How to build a perfect <img>
jonoalderson
1
6.2k
Intergalactic Javascript Robots from Outer Space
tanoku
273
28k
How to Build an AI Search Optimization Roadmap - Criteria and Steps to Take #SEOIRL
aleyda
1
2.2k
How to build an LLM SEO readiness audit: a practical framework
nmsamuel
2
960
Bootstrapping a Software Product
garrettdimon
PRO
306
120k
Learning to Love Humans: Emotional Interface Design
aarron
275
41k
Connecting the Dots Between Site Speed, User Experience & Your Business [WebExpo 2025]
tammyeverts
11
1.1k
AI Search: Where Are We & What Can We Do About It?
aleyda
0
8.1k
Keith and Marios Guide to Fast Websites
keithpitt
413
23k
Let's Do A Bunch of Simple Stuff to Make Websites Faster
chriscoyier
508
140k
Claude Code どこまでも/ Claude Code Everywhere
nwiizo
68
59k
Transcript
Intro to scikit-learn EuroScipy 2017 - Olivier Grisel - Tim
Head
Outline • Machine Learning refresher • scikit-learn • Hands on:
interactive predictive modeling on Census Data with Jupyter notebook / pandas / scikit-learn • Hands on: parameter tuning with scikit-optimize
Predictive modeling ~= machine learning • Make predictions of outcome
on new data • Extract the structure of historical data • Statistical tools to summarize the training data into a executable predictive model • Alternative to hard-coded rules written by experts
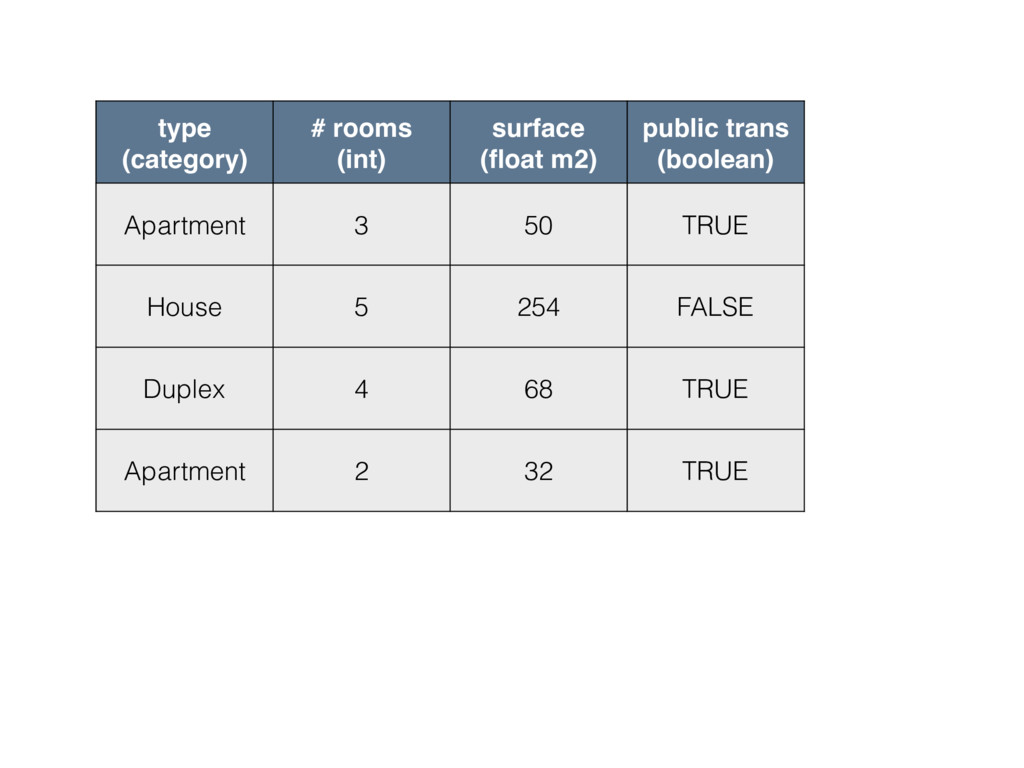
type (category) # rooms (int) surface (float m2) public trans
(boolean) Apartment 3 50 TRUE House 5 254 FALSE Duplex 4 68 TRUE Apartment 2 32 TRUE
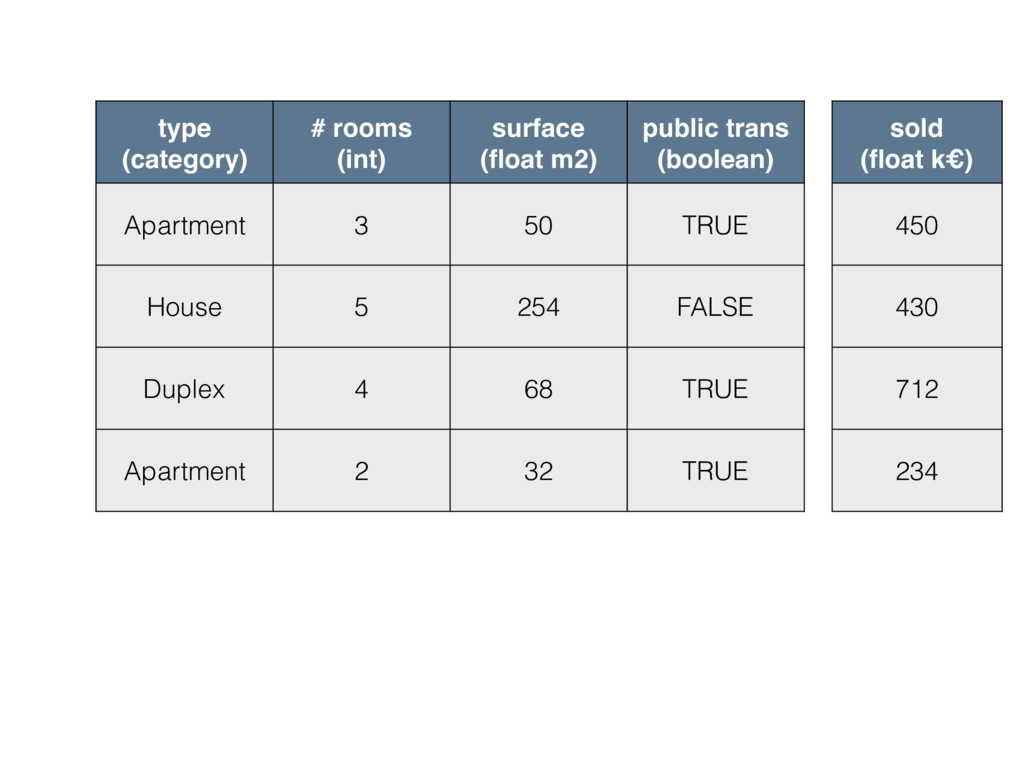
type (category) # rooms (int) surface (float m2) public trans
(boolean) Apartment 3 50 TRUE House 5 254 FALSE Duplex 4 68 TRUE Apartment 2 32 TRUE sold (float k€) 450 430 712 234
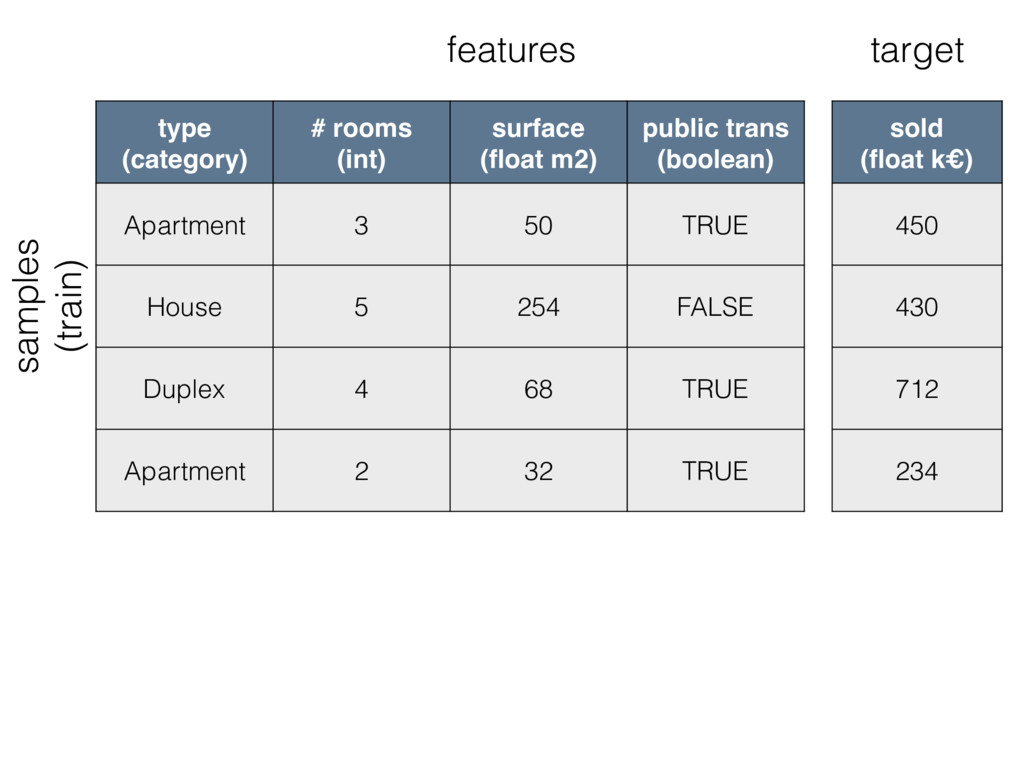
type (category) # rooms (int) surface (float m2) public trans
(boolean) Apartment 3 50 TRUE House 5 254 FALSE Duplex 4 68 TRUE Apartment 2 32 TRUE sold (float k€) 450 430 712 234 features target samples (train)
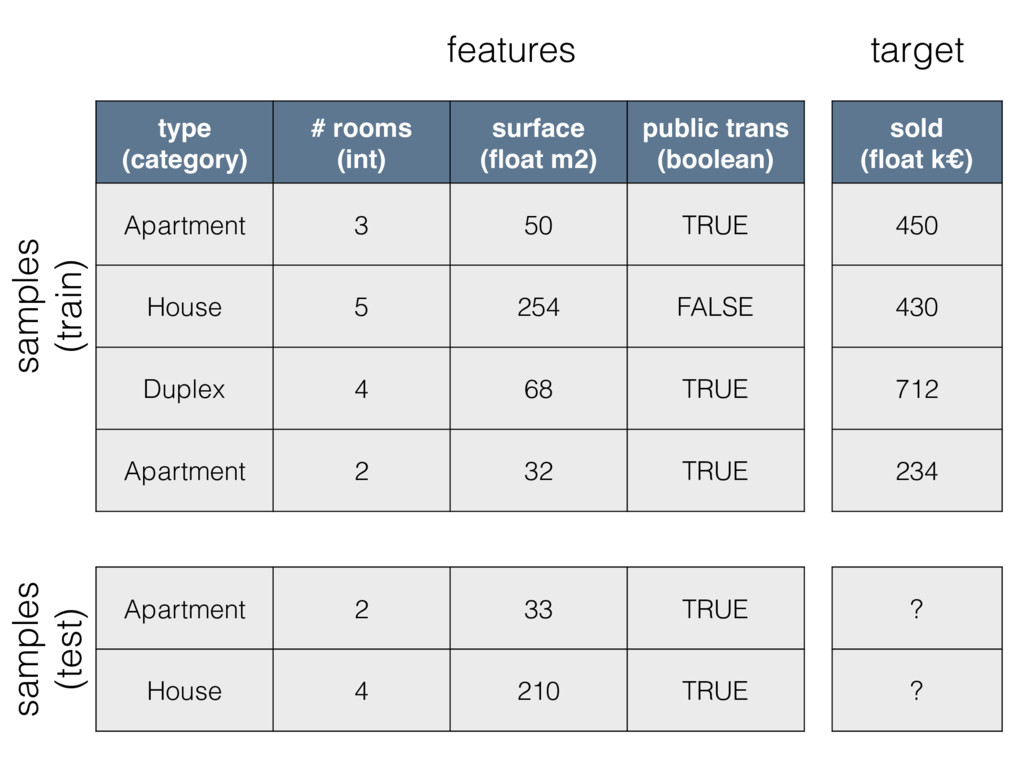
type (category) # rooms (int) surface (float m2) public trans
(boolean) Apartment 3 50 TRUE House 5 254 FALSE Duplex 4 68 TRUE Apartment 2 32 TRUE sold (float k€) 450 430 712 234 features target samples (train) Apartment 2 33 TRUE House 4 210 TRUE samples (test) ? ?
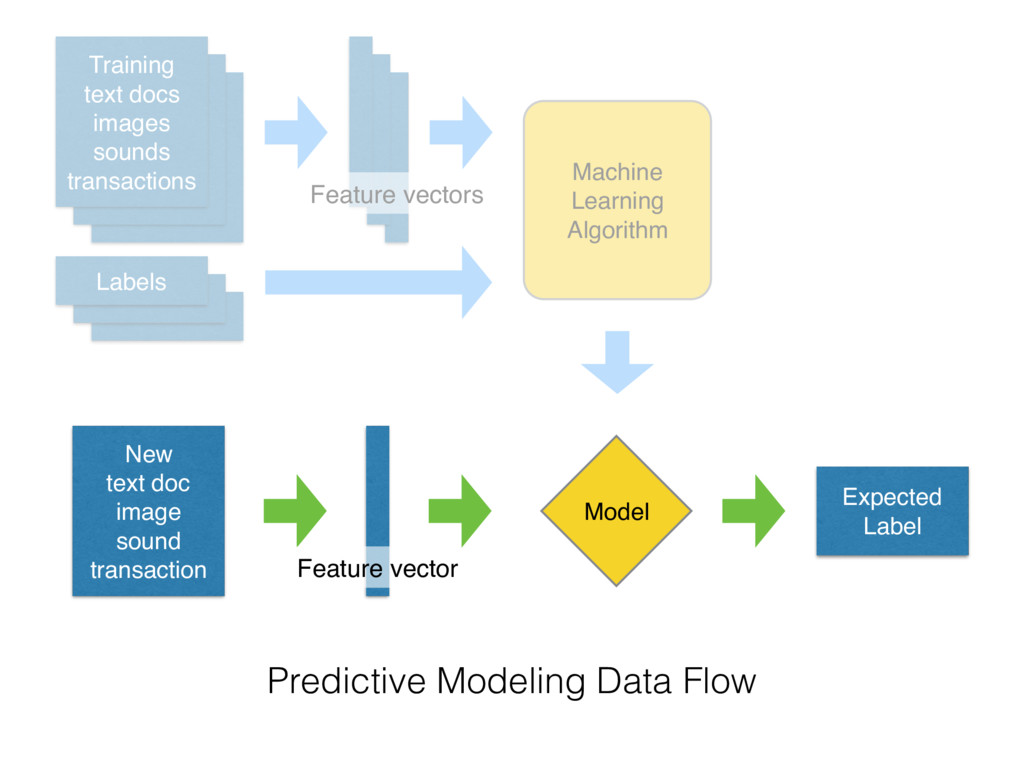
Training text docs images sounds transactions Labels Machine Learning Algorithm
Model Predictive Modeling Data Flow Feature vectors
New text doc image sound transaction Model Expected Label Predictive
Modeling Data Flow Feature vector Training text docs images sounds transactions Labels Machine Learning Algorithm Feature vectors
Inventory forecasting & trends detection Predictive modeling in the wild
Personalized radios Fraud detection Virality and readers engagement Predictive maintenance Personality matching
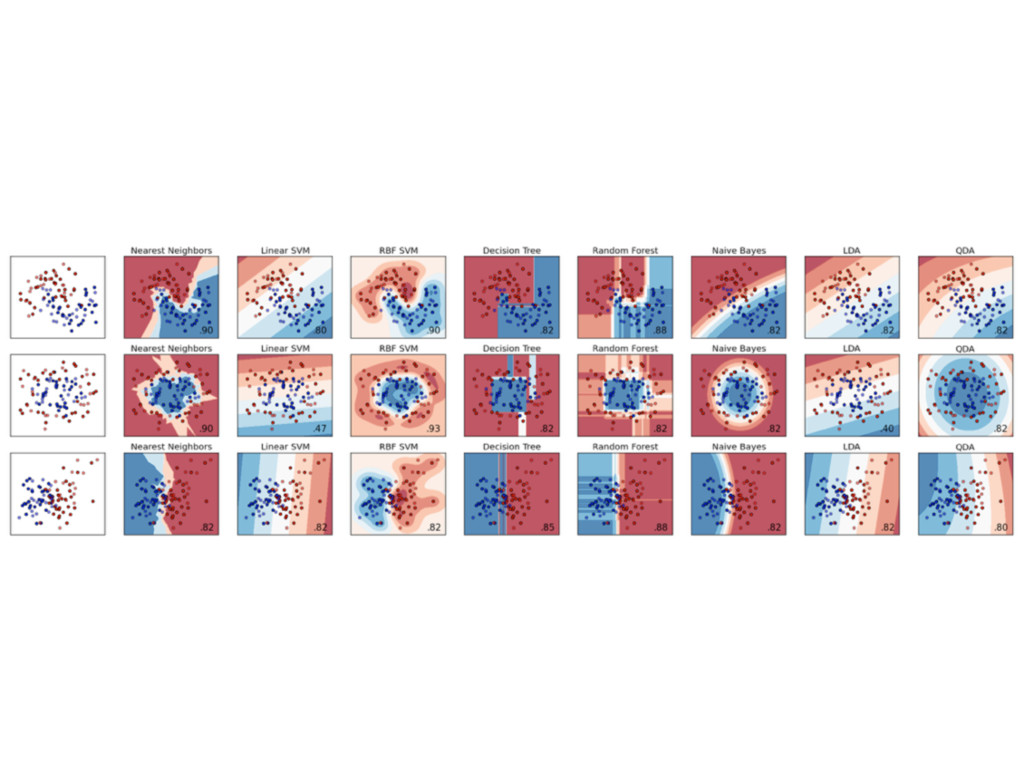
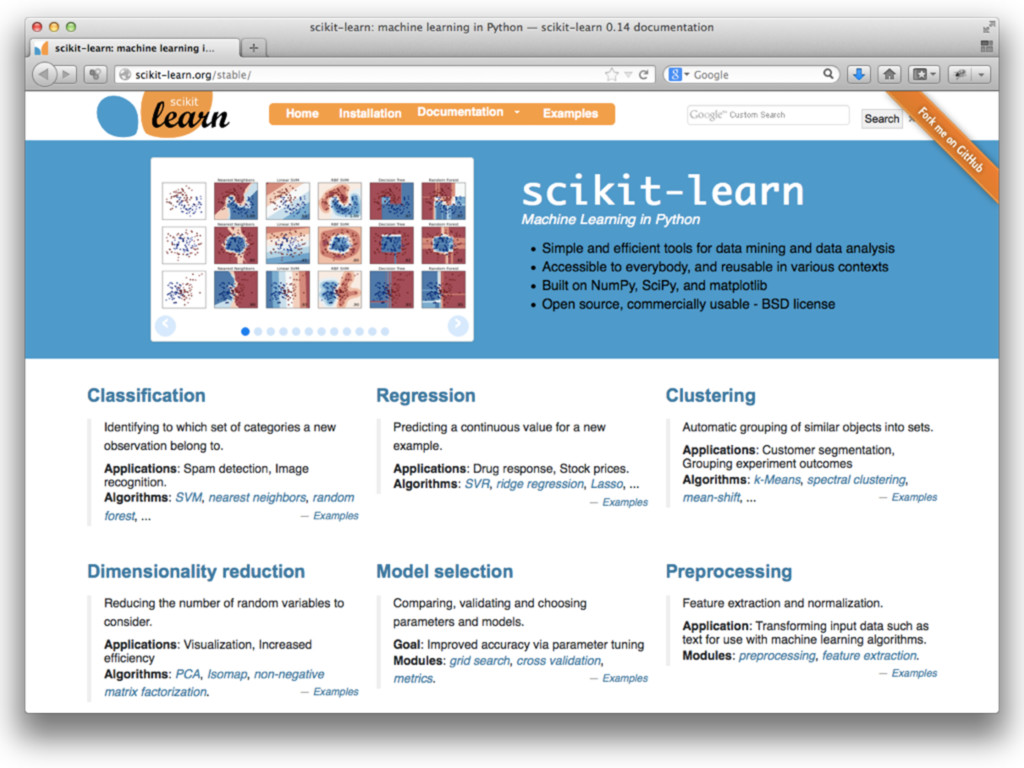
• Library of Machine Learning algorithms • Focus on established
methods (e.g. ESL-II) • Open Source (BSD) • Simple fit / predict / transform API • Python / NumPy / SciPy / Cython • Model Assessment, Selection & Ensembles
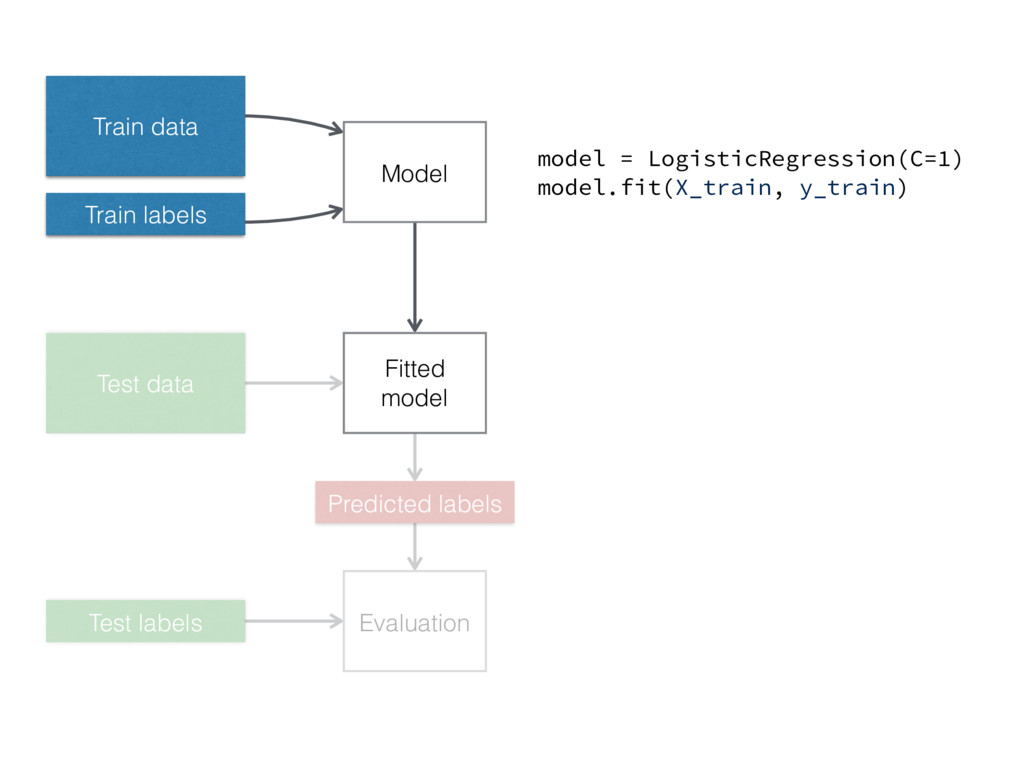
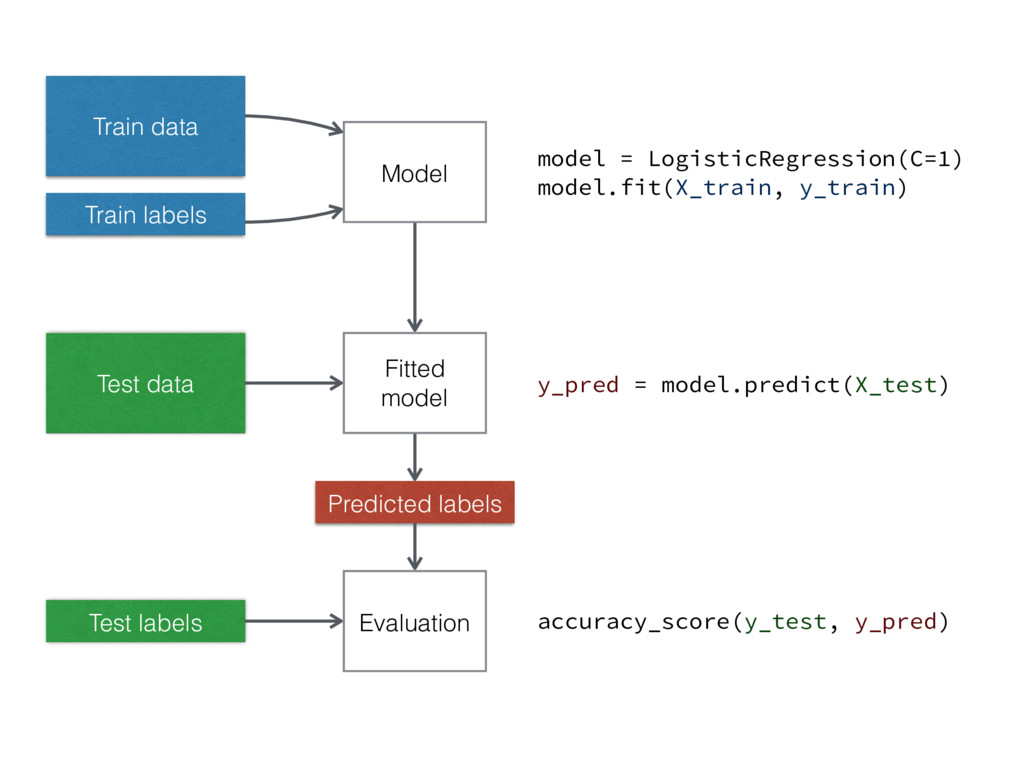
Train data Train labels Model Fitted model Test data Predicted
labels Test labels Evaluation model = LogisticRegression(C=1) model.fit(X_train, y_train)
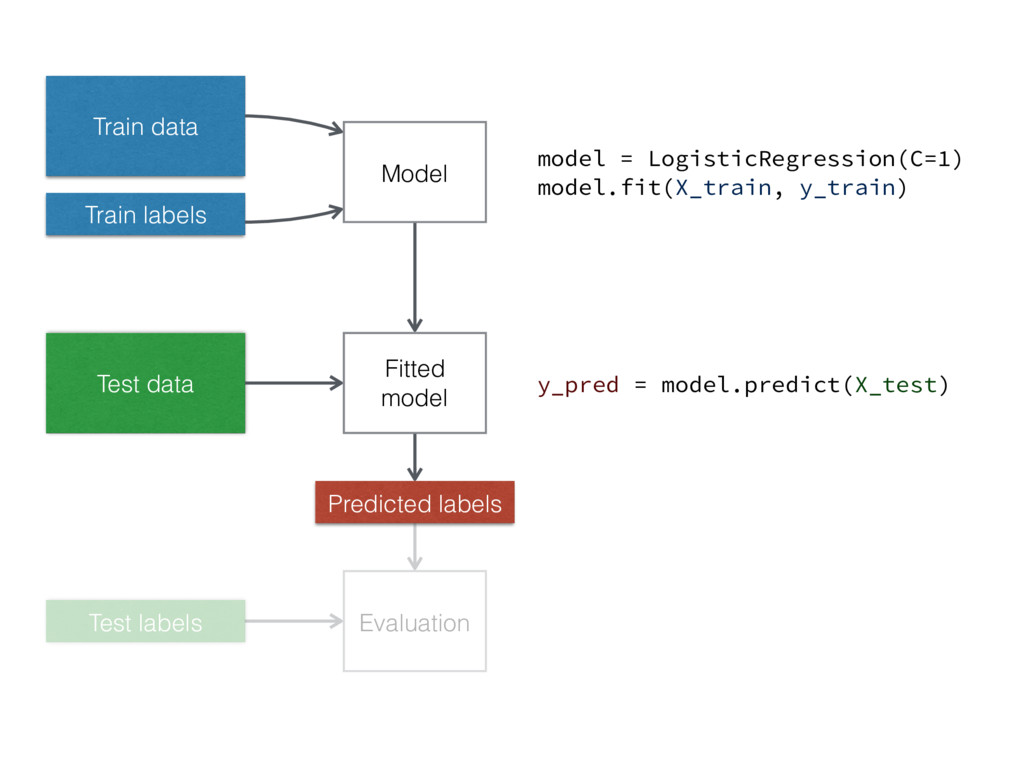
Train data Train labels Model Fitted model Test data Predicted
labels Test labels Evaluation model = LogisticRegression(C=1) model.fit(X_train, y_train) y_pred = model.predict(X_test)
Train data Train labels Model Fitted model Test data Predicted
labels Test labels Evaluation model = LogisticRegression(C=1) model.fit(X_train, y_train) y_pred = model.predict(X_test) accuracy_score(y_test, y_pred)
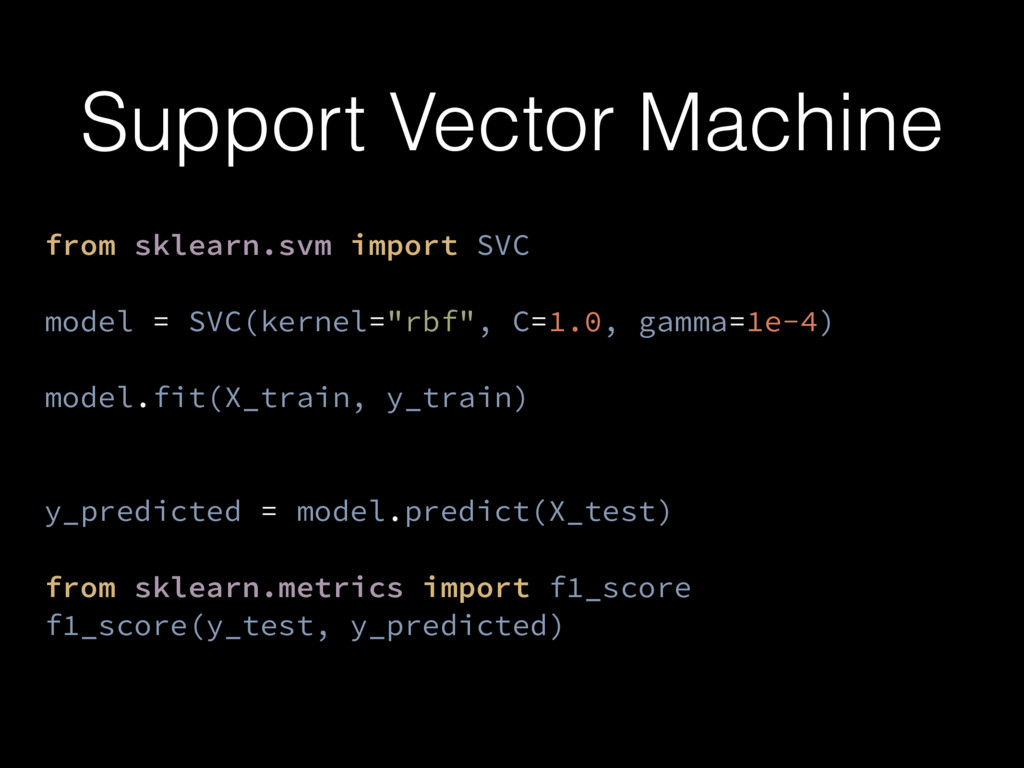
Support Vector Machine from sklearn.svm import SVC model = SVC(kernel="rbf",
C=1.0, gamma=1e-4) model.fit(X_train, y_train) y_predicted = model.predict(X_test) from sklearn.metrics import f1_score f1_score(y_test, y_predicted)
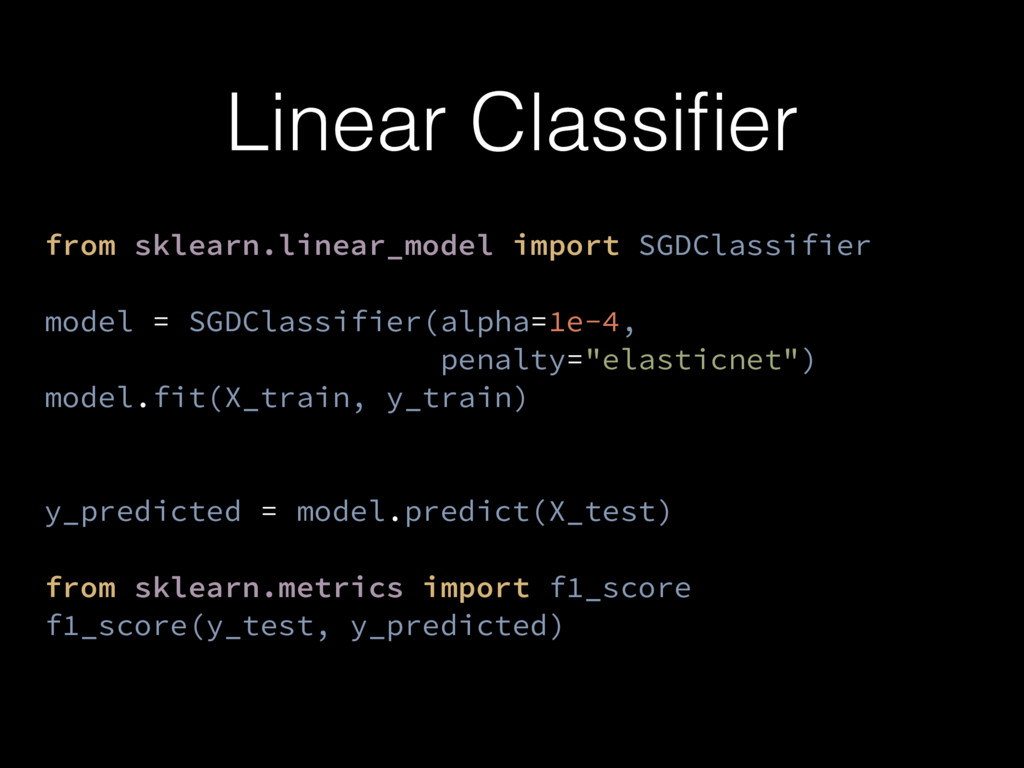
Linear Classifier from sklearn.linear_model import SGDClassifier model = SGDClassifier(alpha=1e-4, penalty="elasticnet")
model.fit(X_train, y_train) y_predicted = model.predict(X_test) from sklearn.metrics import f1_score f1_score(y_test, y_predicted)
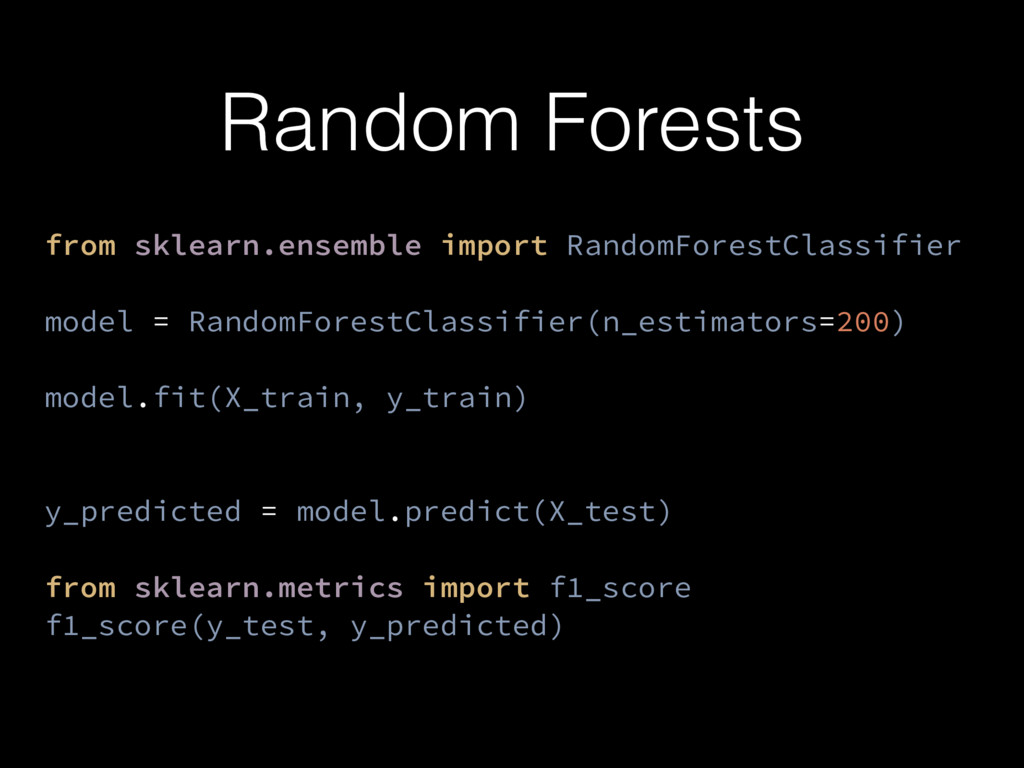
Random Forests from sklearn.ensemble import RandomForestClassifier model = RandomForestClassifier(n_estimators=200) model.fit(X_train,
y_train) y_predicted = model.predict(X_test) from sklearn.metrics import f1_score f1_score(y_test, y_predicted)
None
None
Workshop time! https://github.com/ogrisel/euroscipy_2017_sklearn
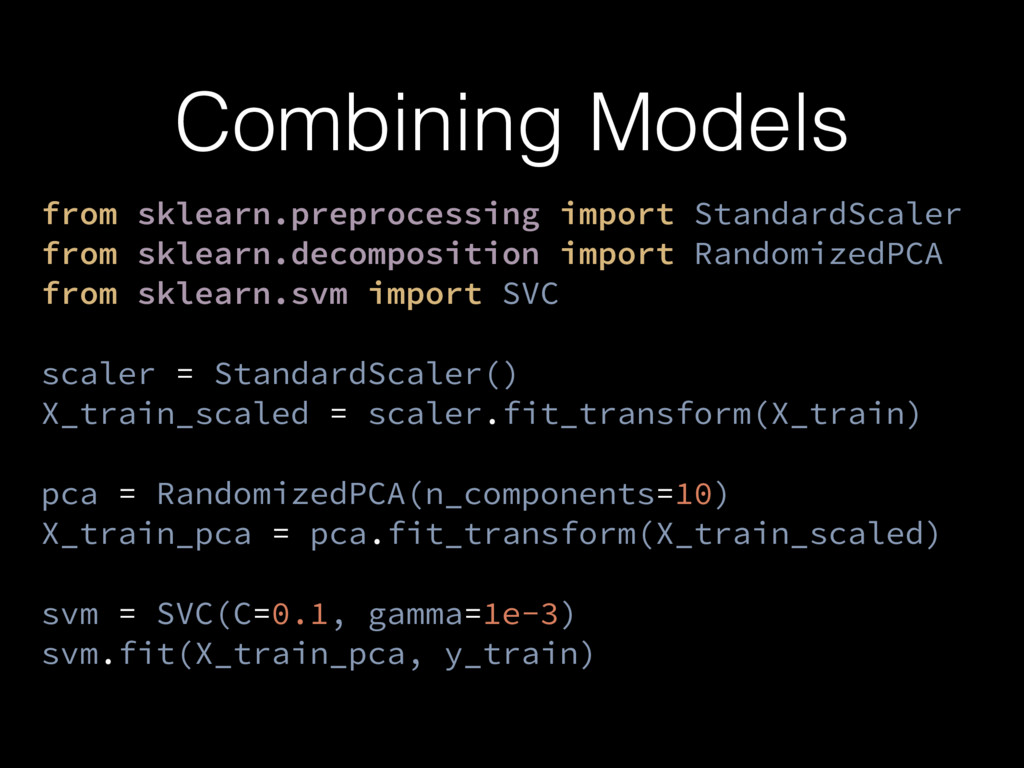
Combining Models from sklearn.preprocessing import StandardScaler from sklearn.decomposition import RandomizedPCA
from sklearn.svm import SVC scaler = StandardScaler() X_train_scaled = scaler.fit_transform(X_train) pca = RandomizedPCA(n_components=10) X_train_pca = pca.fit_transform(X_train_scaled) svm = SVC(C=0.1, gamma=1e-3) svm.fit(X_train_pca, y_train)
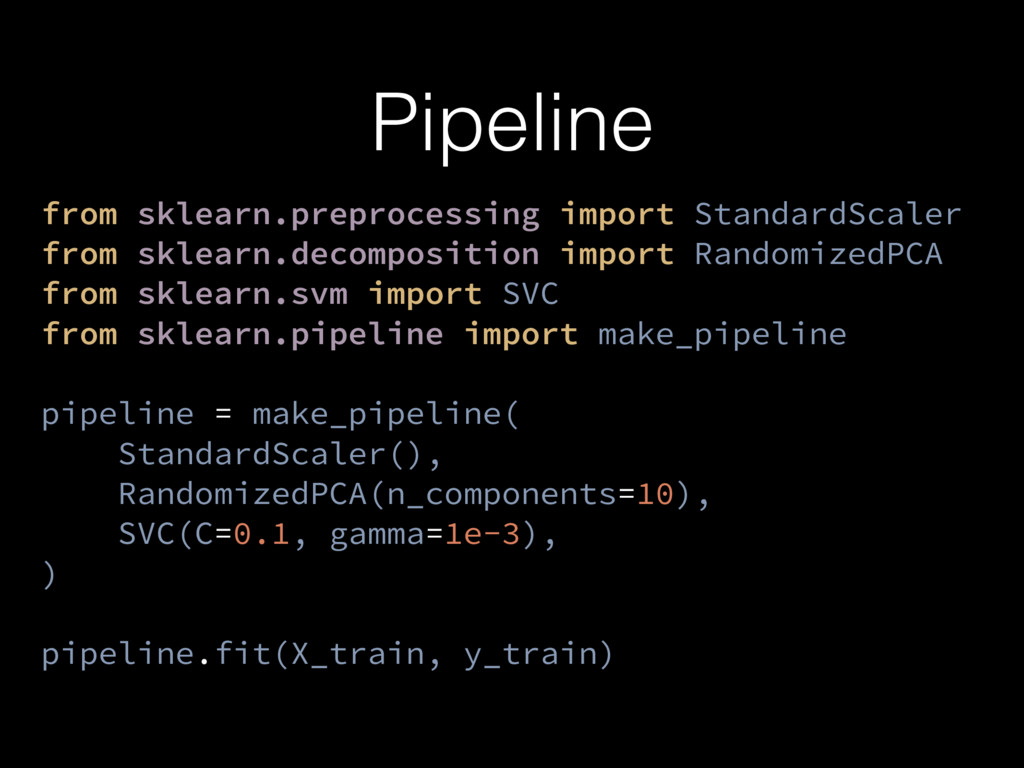
Pipeline from sklearn.preprocessing import StandardScaler from sklearn.decomposition import RandomizedPCA from
sklearn.svm import SVC from sklearn.pipeline import make_pipeline pipeline = make_pipeline( StandardScaler(), RandomizedPCA(n_components=10), SVC(C=0.1, gamma=1e-3), ) pipeline.fit(X_train, y_train)
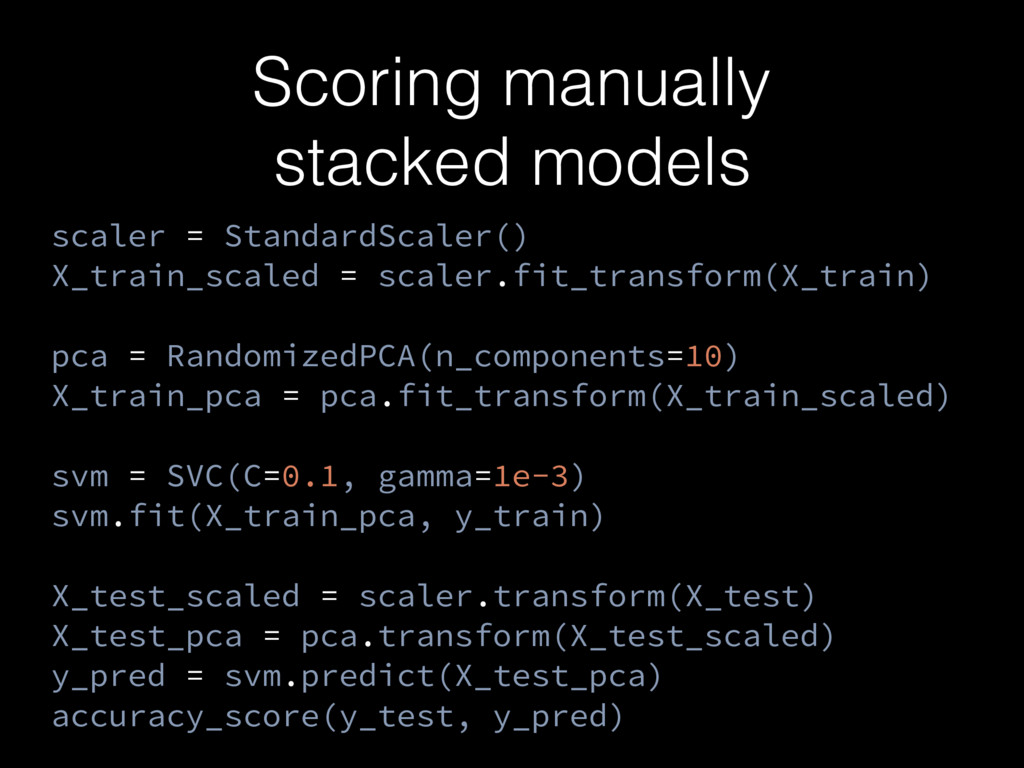
Scoring manually stacked models scaler = StandardScaler() X_train_scaled = scaler.fit_transform(X_train)
pca = RandomizedPCA(n_components=10) X_train_pca = pca.fit_transform(X_train_scaled) svm = SVC(C=0.1, gamma=1e-3) svm.fit(X_train_pca, y_train) X_test_scaled = scaler.transform(X_test) X_test_pca = pca.transform(X_test_scaled) y_pred = svm.predict(X_test_pca) accuracy_score(y_test, y_pred)
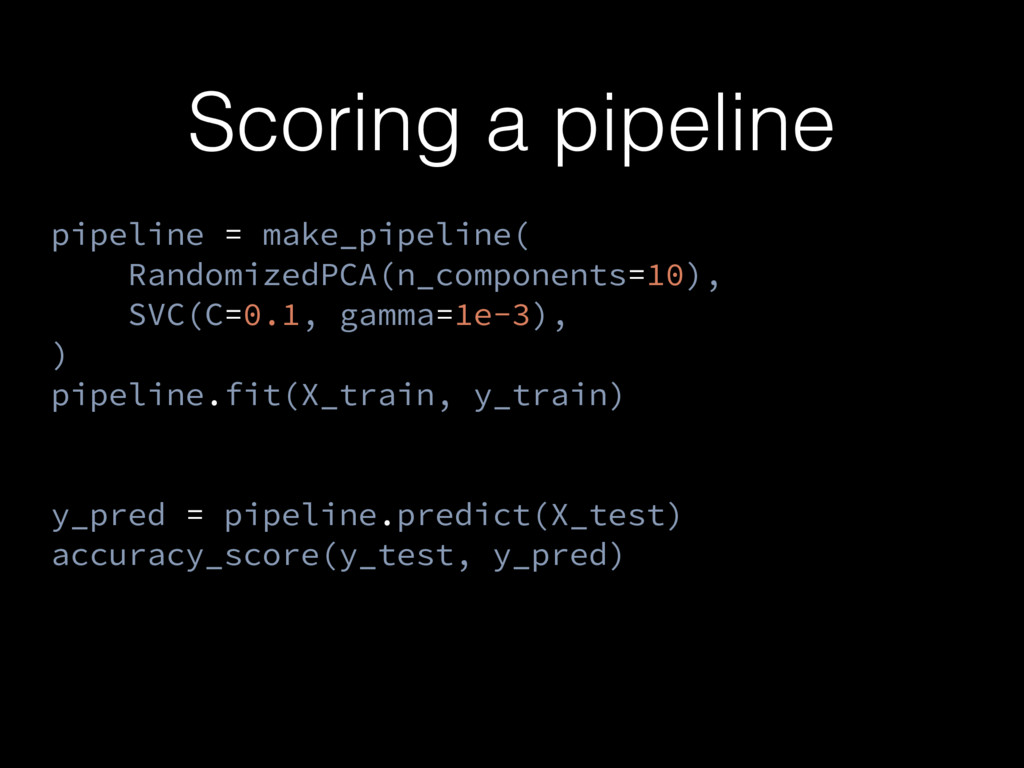
Scoring a pipeline pipeline = make_pipeline( RandomizedPCA(n_components=10), SVC(C=0.1, gamma=1e-3), )
pipeline.fit(X_train, y_train) y_pred = pipeline.predict(X_test) accuracy_score(y_test, y_pred)
Parameter search import numpy as np from sklearn.grid_search import RandomizedSearchCV
params = { 'randomizedpca__n_components': [5, 10, 20], 'svc__C': np.logspace(-3, 3, 7), 'svc__gamma': np.logspace(-6, 0, 7), } search = RandomizedSearchCV(pipeline, params, n_iter=30, cv=5) search.fit(X_train, y_train) # search.best_params_, search.grid_scores_
Thank you! • http://scikit-learn.org • https://github.com/scikit-learn/scikit-learn @ogrisel


 ogrisel
 suikabar
 yuukiyo
 k1style
 willnet
 yachibit
 kentarofujii
 kinopeee
 mhlyc
 gree_tech
 yuuuuuuu168
 freee
 orgachem
 skipperchong
 jonoalderson
 tanoku
 aleyda
 nmsamuel
 garrettdimon
 aarron
 tammyeverts
 keithpitt
 chriscoyier
 nwiizo