Share
Embed
Cloud-Native Data Formats for Big Scientific Data
Presentation at Next Generation Cloud Research Infrastructure Workshop.
https://sites.google.com/view/workshop-on-cloud-cri/agenda?authuser=0
Ryan Abernathey
November 12, 2019
Transcript
23 slides
-
B e y o n d H D F C
l o u d o p t i m i z e d s t o r a g e f o r B i g S c i e n t i f i c d a t a -
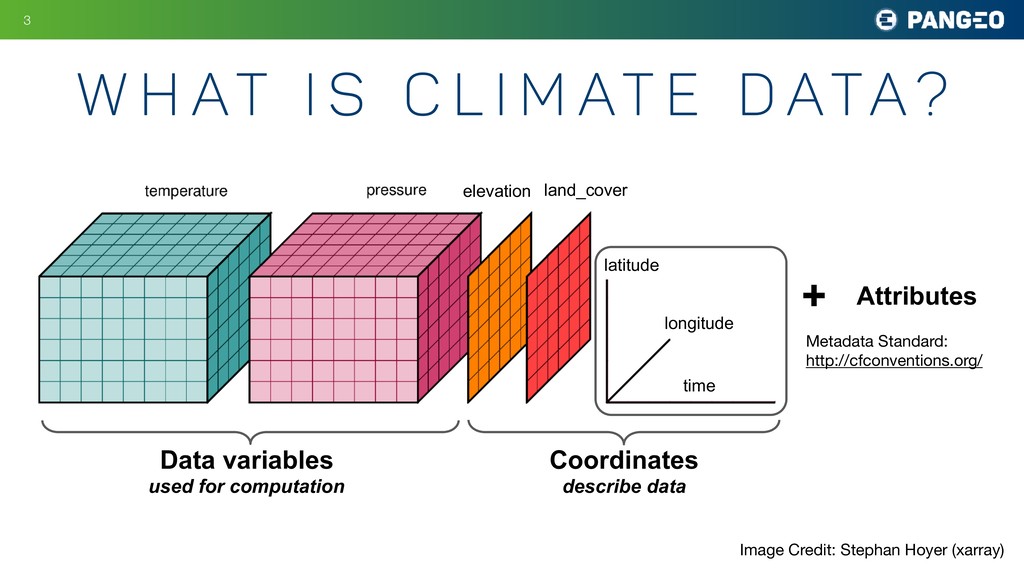
!3 W h at i s c l i m
at e d ata? time longitude latitude elevation Data variables used for computation Coordinates describe data Attributes + land_cover Metadata Standard: http://cfconventions.org/ Image Credit: Stephan Hoyer (xarray) -
W h at S c i e n c e
d o w e w a n t t o d o w i t h c l i m at e d ata? !4 -
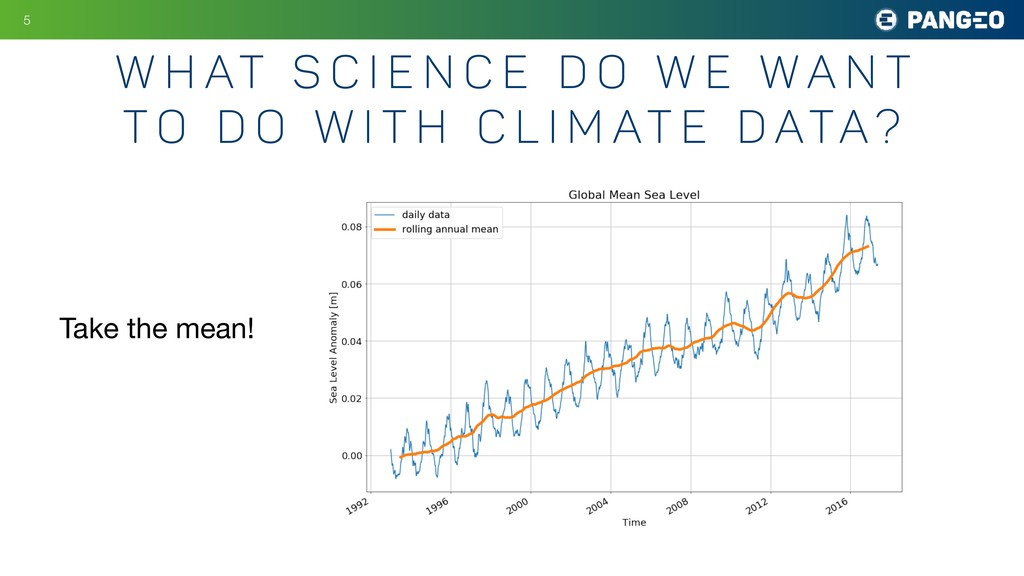
W h at S c i e n c e
d o w e w a n t t o d o w i t h c l i m at e d ata? !5 Take the mean! -
W h at S c i e n c e
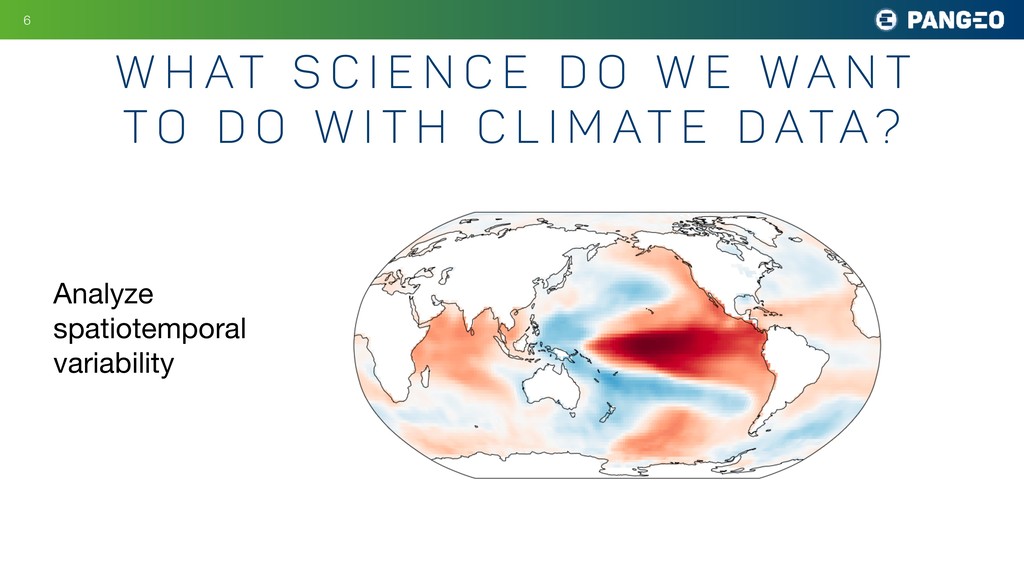
d o w e w a n t t o d o w i t h c l i m at e d ata? !6 Analyze spatiotemporal variability -
W h at S c i e n c e
d o w e w a n t t o d o w i t h c l i m at e d ata? !7 Machine learning! Credit: Berkeley Lab -
!8 H o w I s c l i m
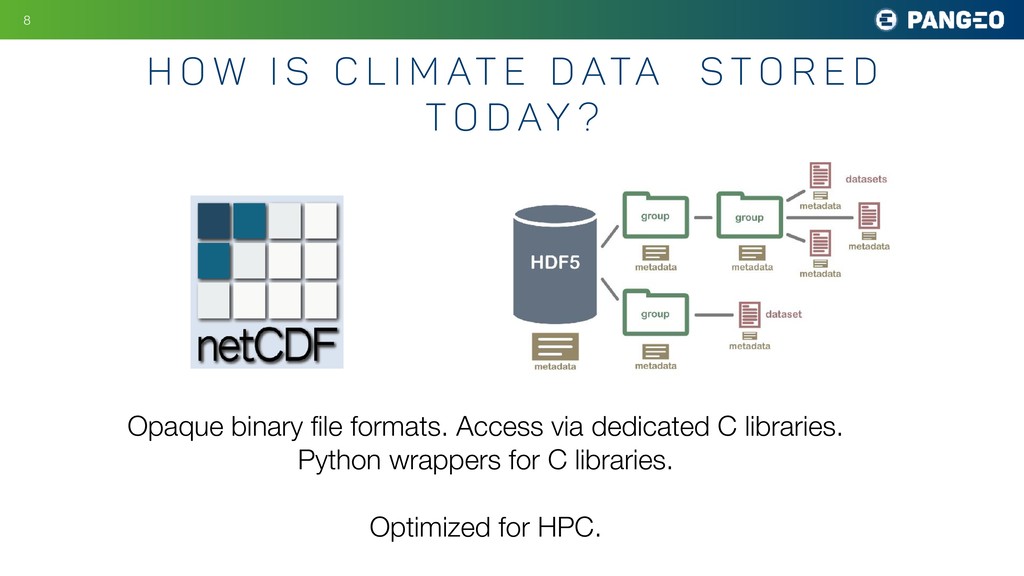
at e d ata s t o r e d t o d ay ? Opaque binary file formats. Access via dedicated C libraries. Python wrappers for C libraries. Optimized for HPC. -
!9 F i l e / B l o c
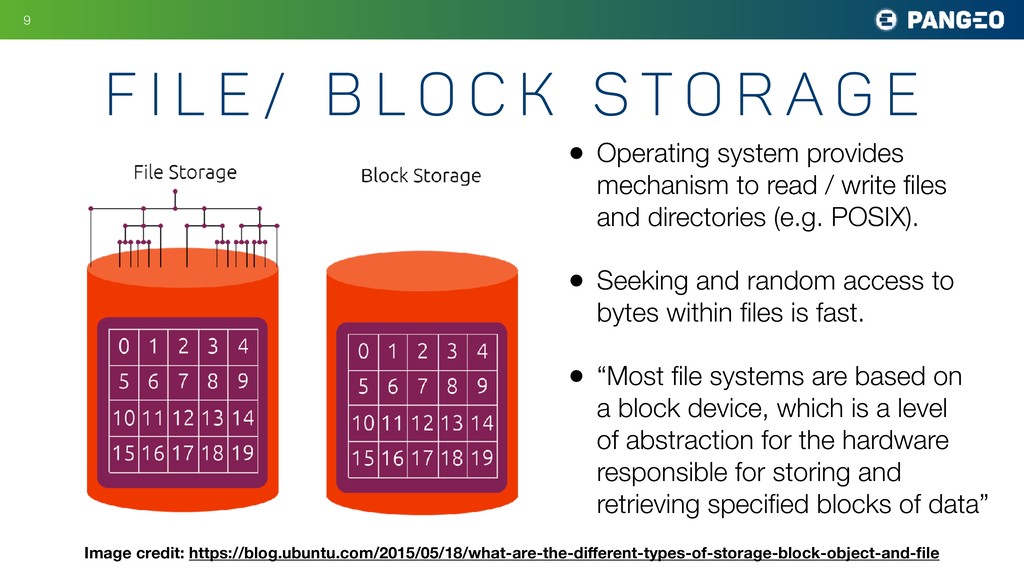
k s t o r a g e Image credit: https://blog.ubuntu.com/2015/05/18/what-are-the-different-types-of-storage-block-object-and-file • Operating system provides mechanism to read / write files and directories (e.g. POSIX). • Seeking and random access to bytes within files is fast. • “Most file systems are based on a block device, which is a level of abstraction for the hardware responsible for storing and retrieving specified blocks of data” -
!10 O b j e c t s t o
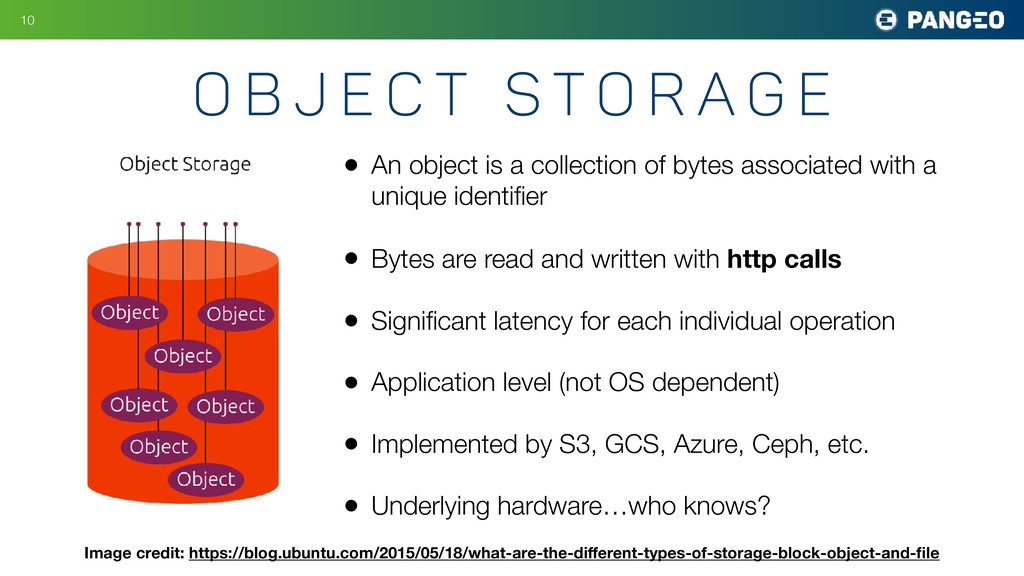
r a g e Image credit: https://blog.ubuntu.com/2015/05/18/what-are-the-different-types-of-storage-block-object-and-file • An object is a collection of bytes associated with a unique identifier • Bytes are read and written with http calls • Significant latency for each individual operation • Application level (not OS dependent) • Implemented by S3, GCS, Azure, Ceph, etc. • Underlying hardware…who knows? -
C e n t r a L P r o
b l e m : !11 We don’t know how issue an HTTP request to peek into an HDF file. HDF client library does not support this*. If we want to know what’s in it, we have to download the whole thing. -
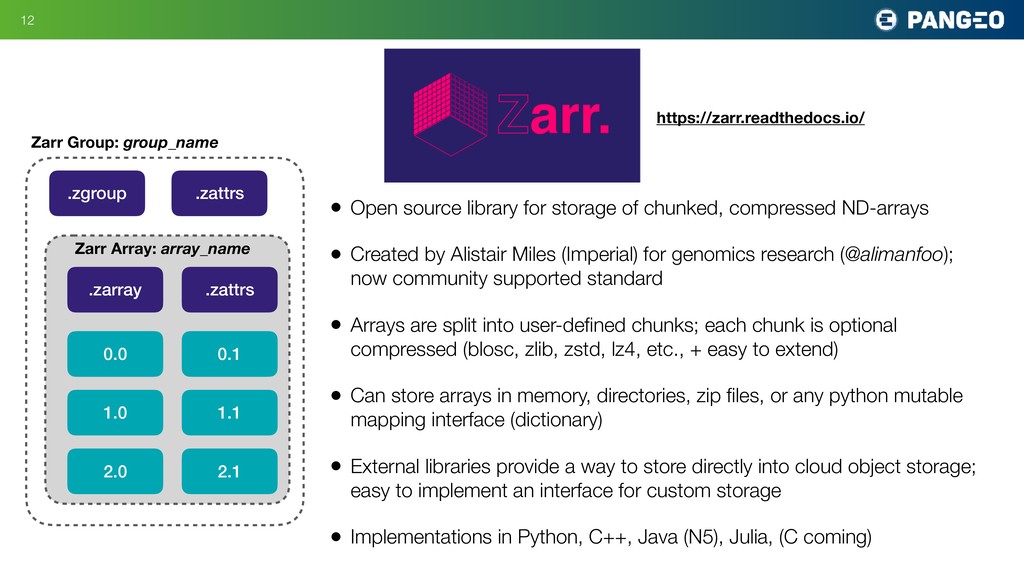
!12 Zarr Group: group_name .zgroup .zattrs .zarray .zattrs Zarr Array:
array_name 0.0 0.1 2.0 1.0 1.1 2.1 https://zarr.readthedocs.io/ • Open source library for storage of chunked, compressed ND-arrays • Created by Alistair Miles (Imperial) for genomics research (@alimanfoo); now community supported standard • Arrays are split into user-defined chunks; each chunk is optional compressed (blosc, zlib, zstd, lz4, etc., + easy to extend) • Can store arrays in memory, directories, zip files, or any python mutable mapping interface (dictionary) • External libraries provide a way to store directly into cloud object storage; easy to implement an interface for custom storage • Implementations in Python, C++, Java (N5), Julia, (C coming) -
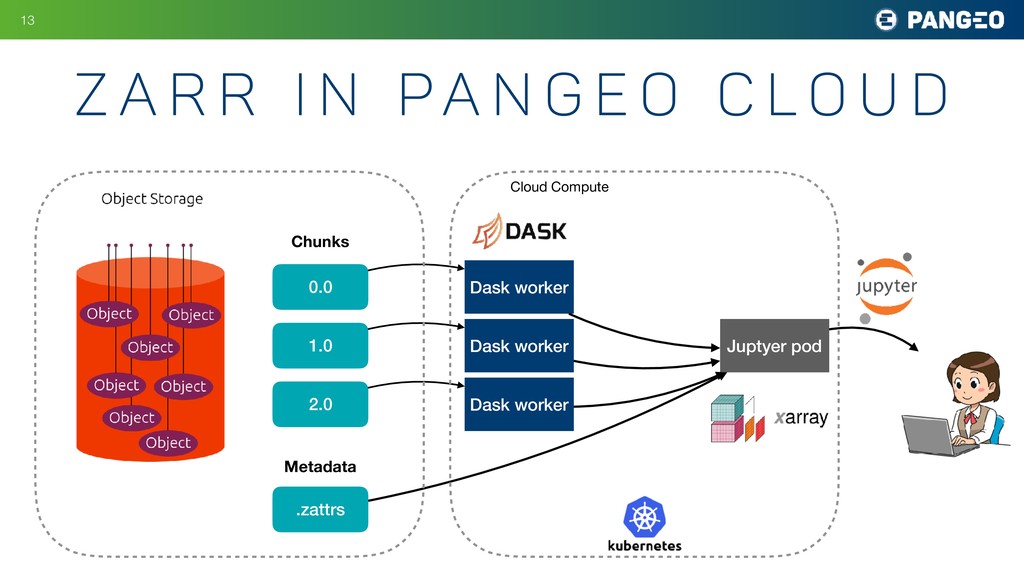
!13 z a r r i n Pa n g
e o C l o u d 0.0 2.0 1.0 Chunks .zattrs Metadata Dask worker Dask worker Dask worker Juptyer pod Cloud Compute -
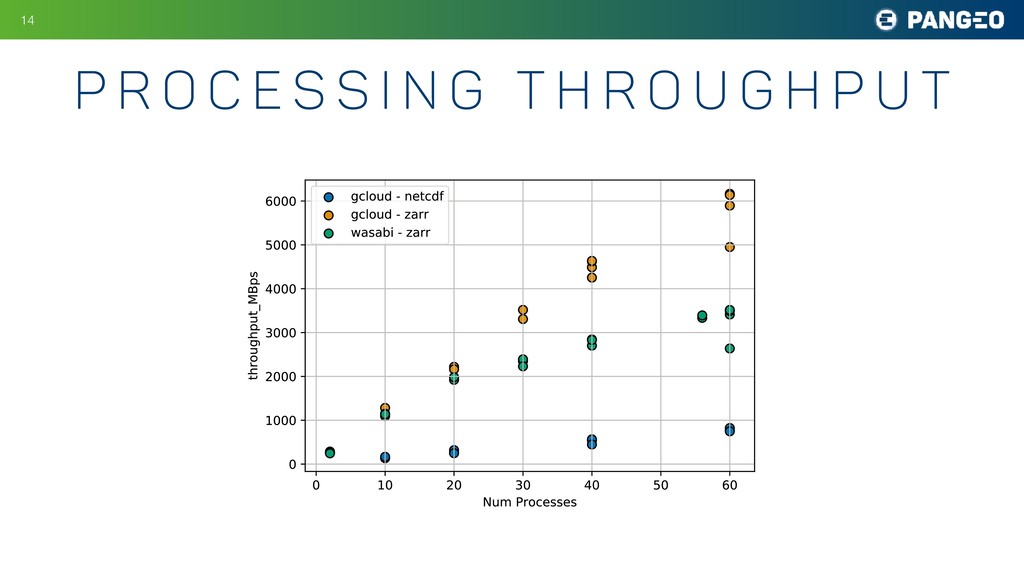
P r o c e s s i n g
T h r o u g h p u t !14 -
!15 S u m m a r y • Scientific
fields suddenly have many PB of data to analyze • Workflows vary widely, but most exciting applications involve processing all the data many times over in an interactive context • This work is strongly limited by storage / network throughput • We can get HPC-like performance on commodity cloud object storage with proper software abstractions -
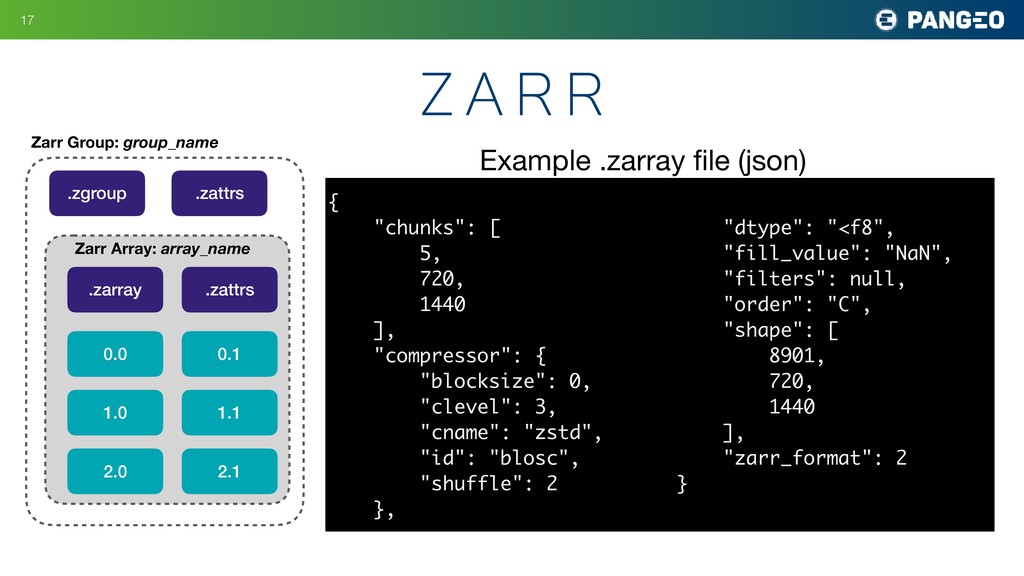
!17 z a r r Zarr Group: group_name .zgroup .zattrs
.zarray .zattrs Zarr Array: array_name 0.0 0.1 2.0 1.0 1.1 2.1 { "chunks": [ 5, 720, 1440 ], "compressor": { "blocksize": 0, "clevel": 3, "cname": "zstd", "id": "blosc", "shuffle": 2 }, "dtype": "<f8", "fill_value": "NaN", "filters": null, "order": "C", "shape": [ 8901, 720, 1440 ], "zarr_format": 2 } Example .zarray file (json) -
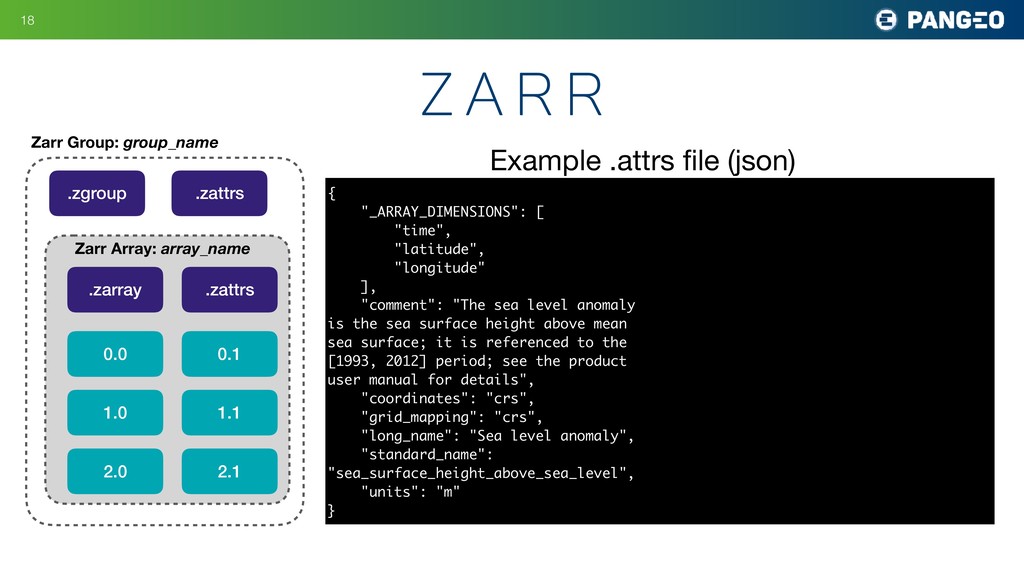
!18 z a r r Zarr Group: group_name .zgroup .zattrs
.zarray .zattrs Zarr Array: array_name 0.0 0.1 2.0 1.0 1.1 2.1 { "_ARRAY_DIMENSIONS": [ "time", "latitude", "longitude" ], "comment": "The sea level anomaly is the sea surface height above mean sea surface; it is referenced to the [1993, 2012] period; see the product user manual for details", "coordinates": "crs", "grid_mapping": "crs", "long_name": "Sea level anomaly", "standard_name": "sea_surface_height_above_sea_level", "units": "m" } Example .attrs file (json) -
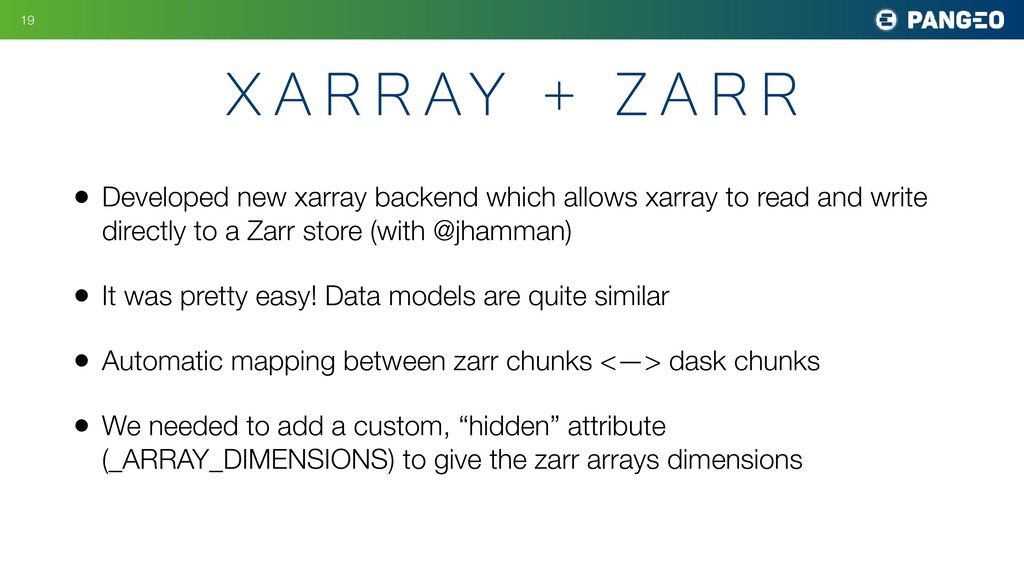
• Developed new xarray backend which allows xarray to read
and write directly to a Zarr store (with @jhamman) • It was pretty easy! Data models are quite similar • Automatic mapping between zarr chunks <—> dask chunks • We needed to add a custom, “hidden” attribute (_ARRAY_DIMENSIONS) to give the zarr arrays dimensions !19 X a r r ay + z a r r -
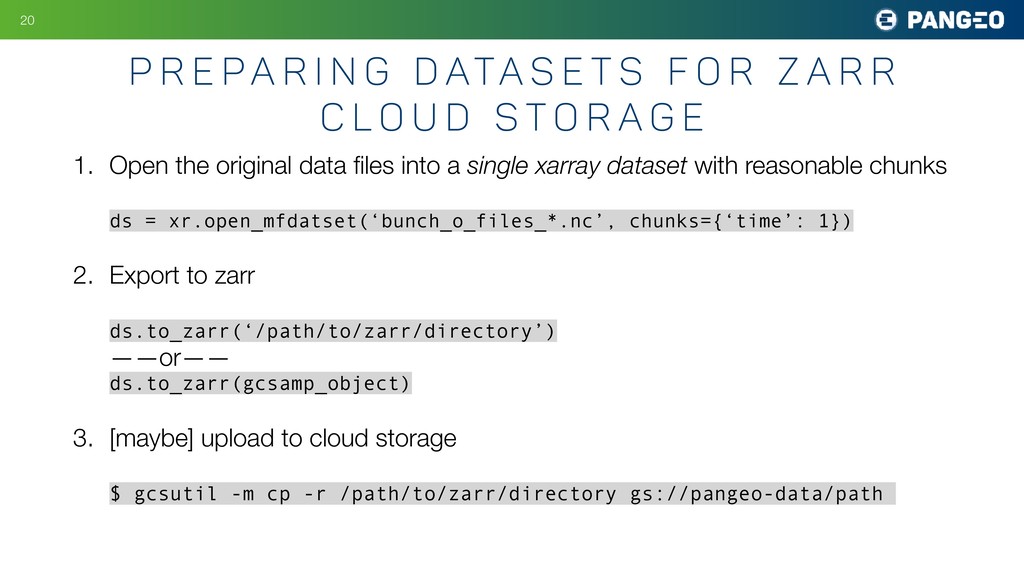
1. Open the original data files into a single xarray
dataset with reasonable chunks ds = xr.open_mfdatset(‘bunch_o_files_*.nc’, chunks={‘time’: 1}) 2. Export to zarr ds.to_zarr(‘/path/to/zarr/directory’) ——or—— ds.to_zarr(gcsamp_object) 3. [maybe] upload to cloud storage $ gcsutil -m cp -r /path/to/zarr/directory gs://pangeo-data/path !20 P r e pa r i n g d ata s e t s f o r z a r r c l o u d s t o r a g e -
!21 R e a d i n g z a
r R d ata f r o m pa n g e o c l o u d e n v i r o n m e n t s gcsmap = gcsfs.mapping.GCSMap('pangeo-data/dataset-duacs-rep-global-merged-allsat-phy-l4-v3-alt') ds = xr.open_zarr(gcsmap) <xarray.Dataset> Dimensions: (latitude: 720, longitude: 1440, nv: 2, time: 8901) Coordinates: crs int32 ... lat_bnds (time, latitude, nv) float32 dask.array<shape=(8901, 720, 2), chunksize=(5, 720, 2)> * latitude (latitude) float32 -89.875 -89.625 -89.375 -89.125 -88.875 ... lon_bnds (longitude, nv) float32 dask.array<shape=(1440, 2), chunksize=(1440, 2)> * longitude (longitude) float32 0.125 0.375 0.625 0.875 1.125 1.375 1.625 ... * nv (nv) int32 0 1 * time (time) datetime64[ns] 1993-01-01 1993-01-02 1993-01-03 ... Data variables: adt (time, latitude, longitude) float64 dask.array<shape=(8901, 720, 1440), chunksize=(5, 720, 1440)> err (time, latitude, longitude) float64 dask.array<shape=(8901, 720, 1440), chunksize=(5, 720, 1440)> sla (time, latitude, longitude) float64 dask.array<shape=(8901, 720, 1440), chunksize=(5, 720, 1440)> ugos (time, latitude, longitude) float64 dask.array<shape=(8901, 720, 1440), chunksize=(5, 720, 1440)> ugosa (time, latitude, longitude) float64 dask.array<shape=(8901, 720, 1440), chunksize=(5, 720, 1440)> vgos (time, latitude, longitude) float64 dask.array<shape=(8901, 720, 1440), chunksize=(5, 720, 1440)> vgosa (time, latitude, longitude) float64 dask.array<shape=(8901, 720, 1440), chunksize=(5, 720, 1440)> Attributes: Conventions: CF-1.6 Metadata_Conventions: Unidata Dataset Discovery v1.0 cdm_data_type: Grid comment: Sea Surface Height measured by Altimetry... contact: [email protected] creator_email: [email protected] creator_name: CMEMS - Sea Level Thematic Assembly Center creator_url: http://marine.copernicus.eu date_created: 2014-02-26T16:09:13Z date_issued: 2014-01-06T00:00:00Z date_modified: 2015-11-10T19:42:51Z -
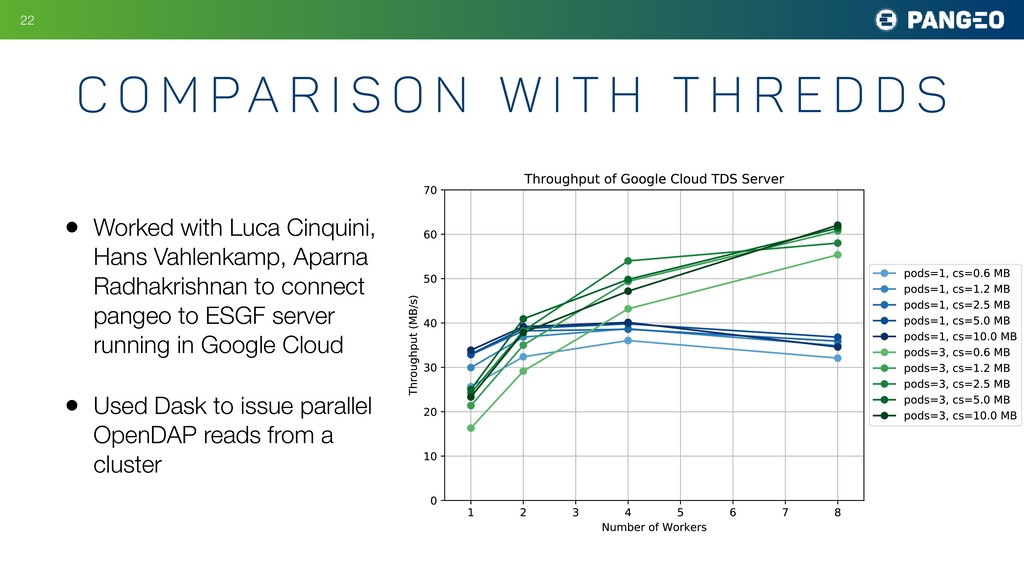
!22 C o m pa r i s o n
w i t h T H R E D D S • Worked with Luca Cinquini, Hans Vahlenkamp, Aparna Radhakrishnan to connect pangeo to ESGF server running in Google Cloud • Used Dask to issue parallel OpenDAP reads from a cluster -
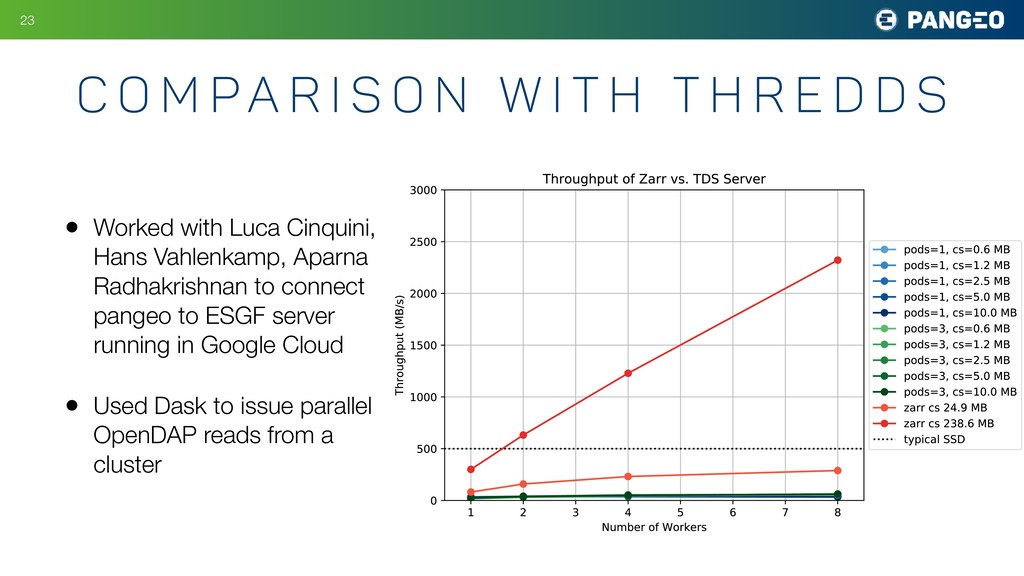
!23 C o m pa r i s o n
w i t h T H R E D D S • Worked with Luca Cinquini, Hans Vahlenkamp, Aparna Radhakrishnan to connect pangeo to ESGF server running in Google Cloud • Used Dask to issue parallel OpenDAP reads from a cluster