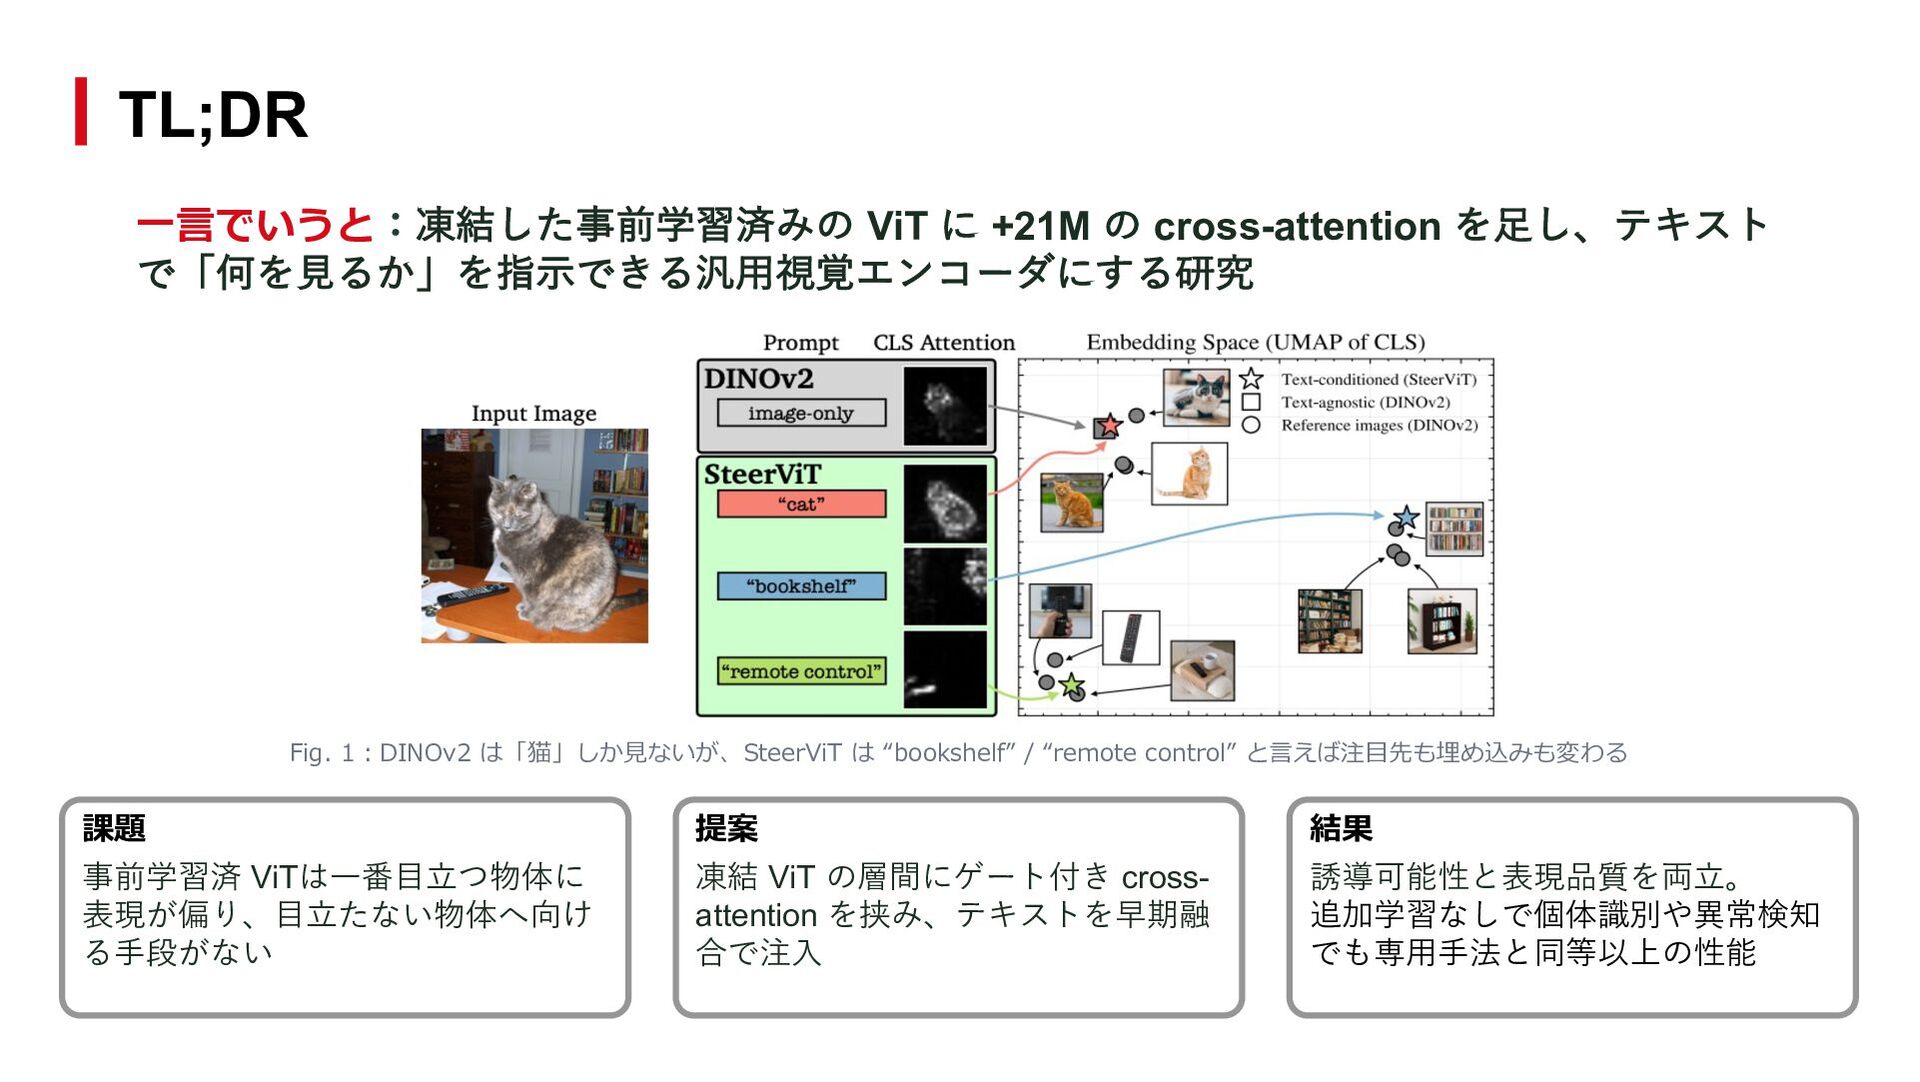
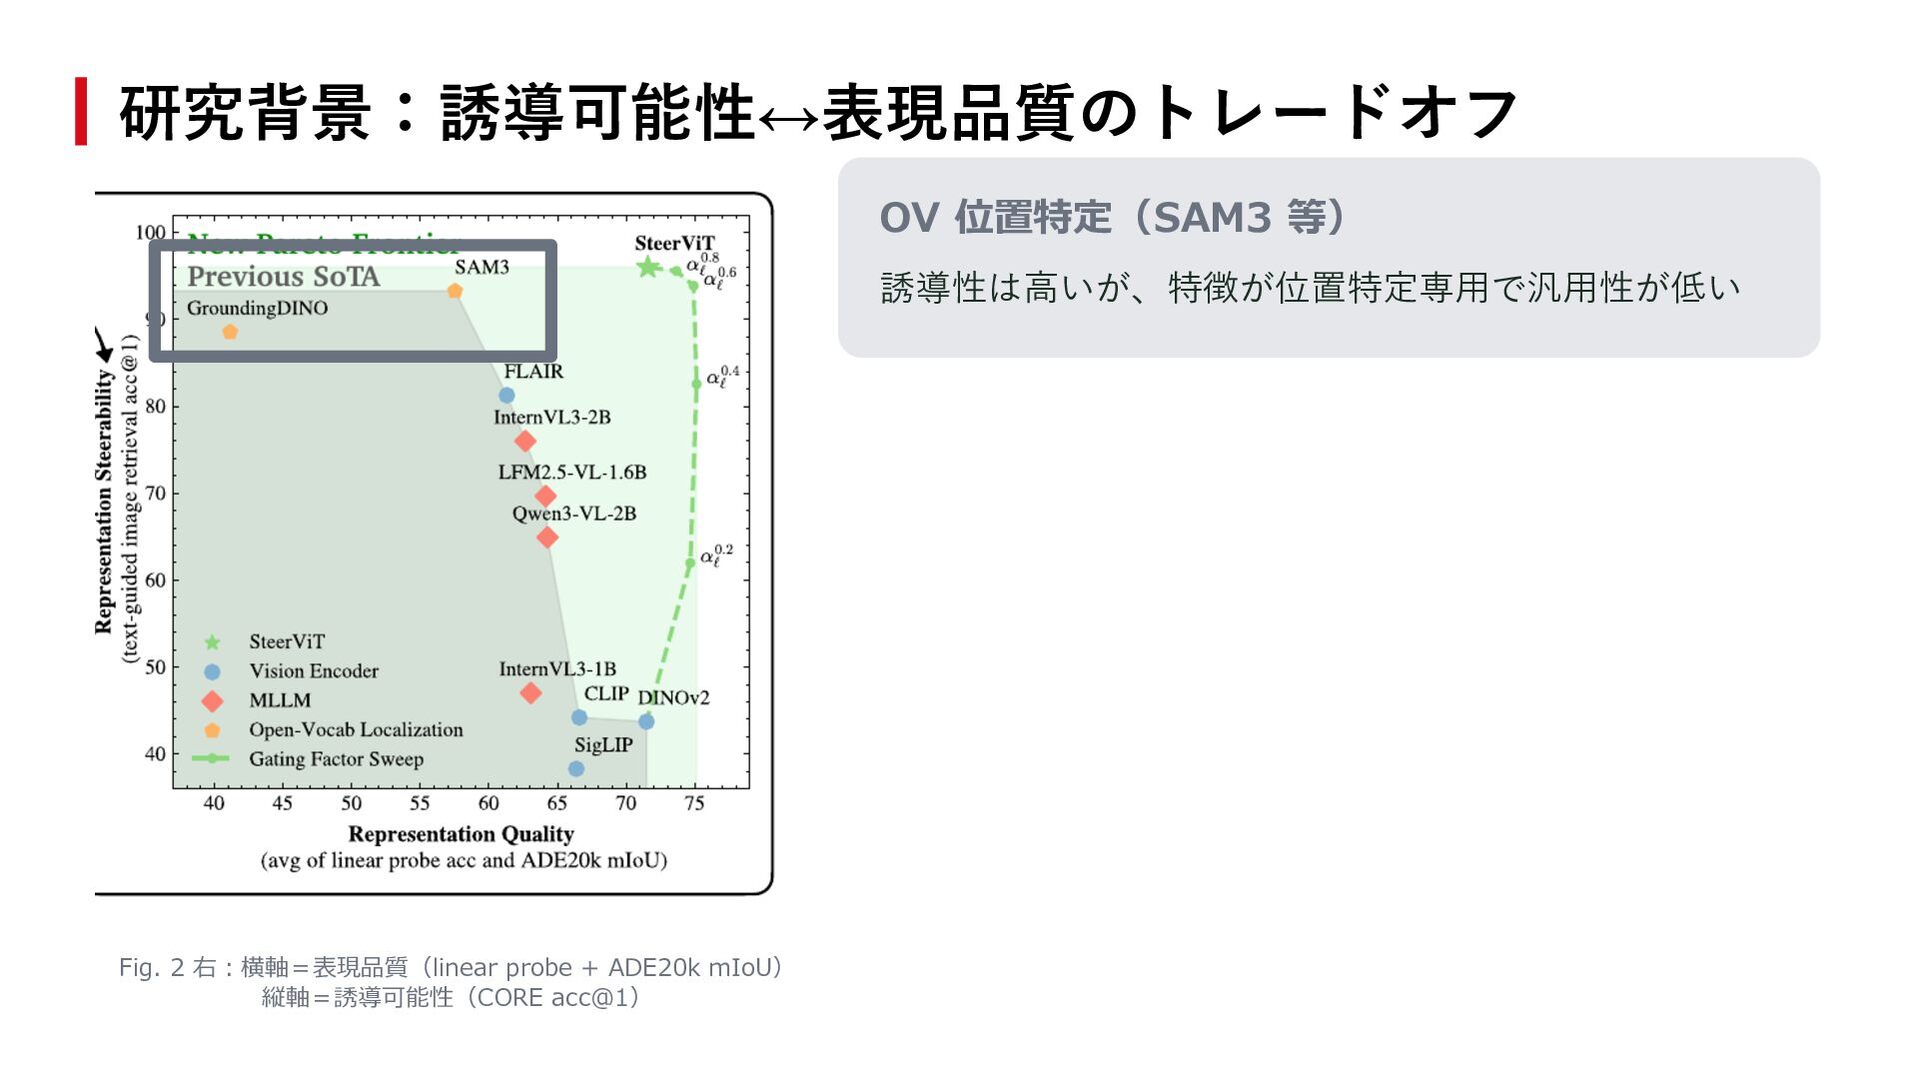
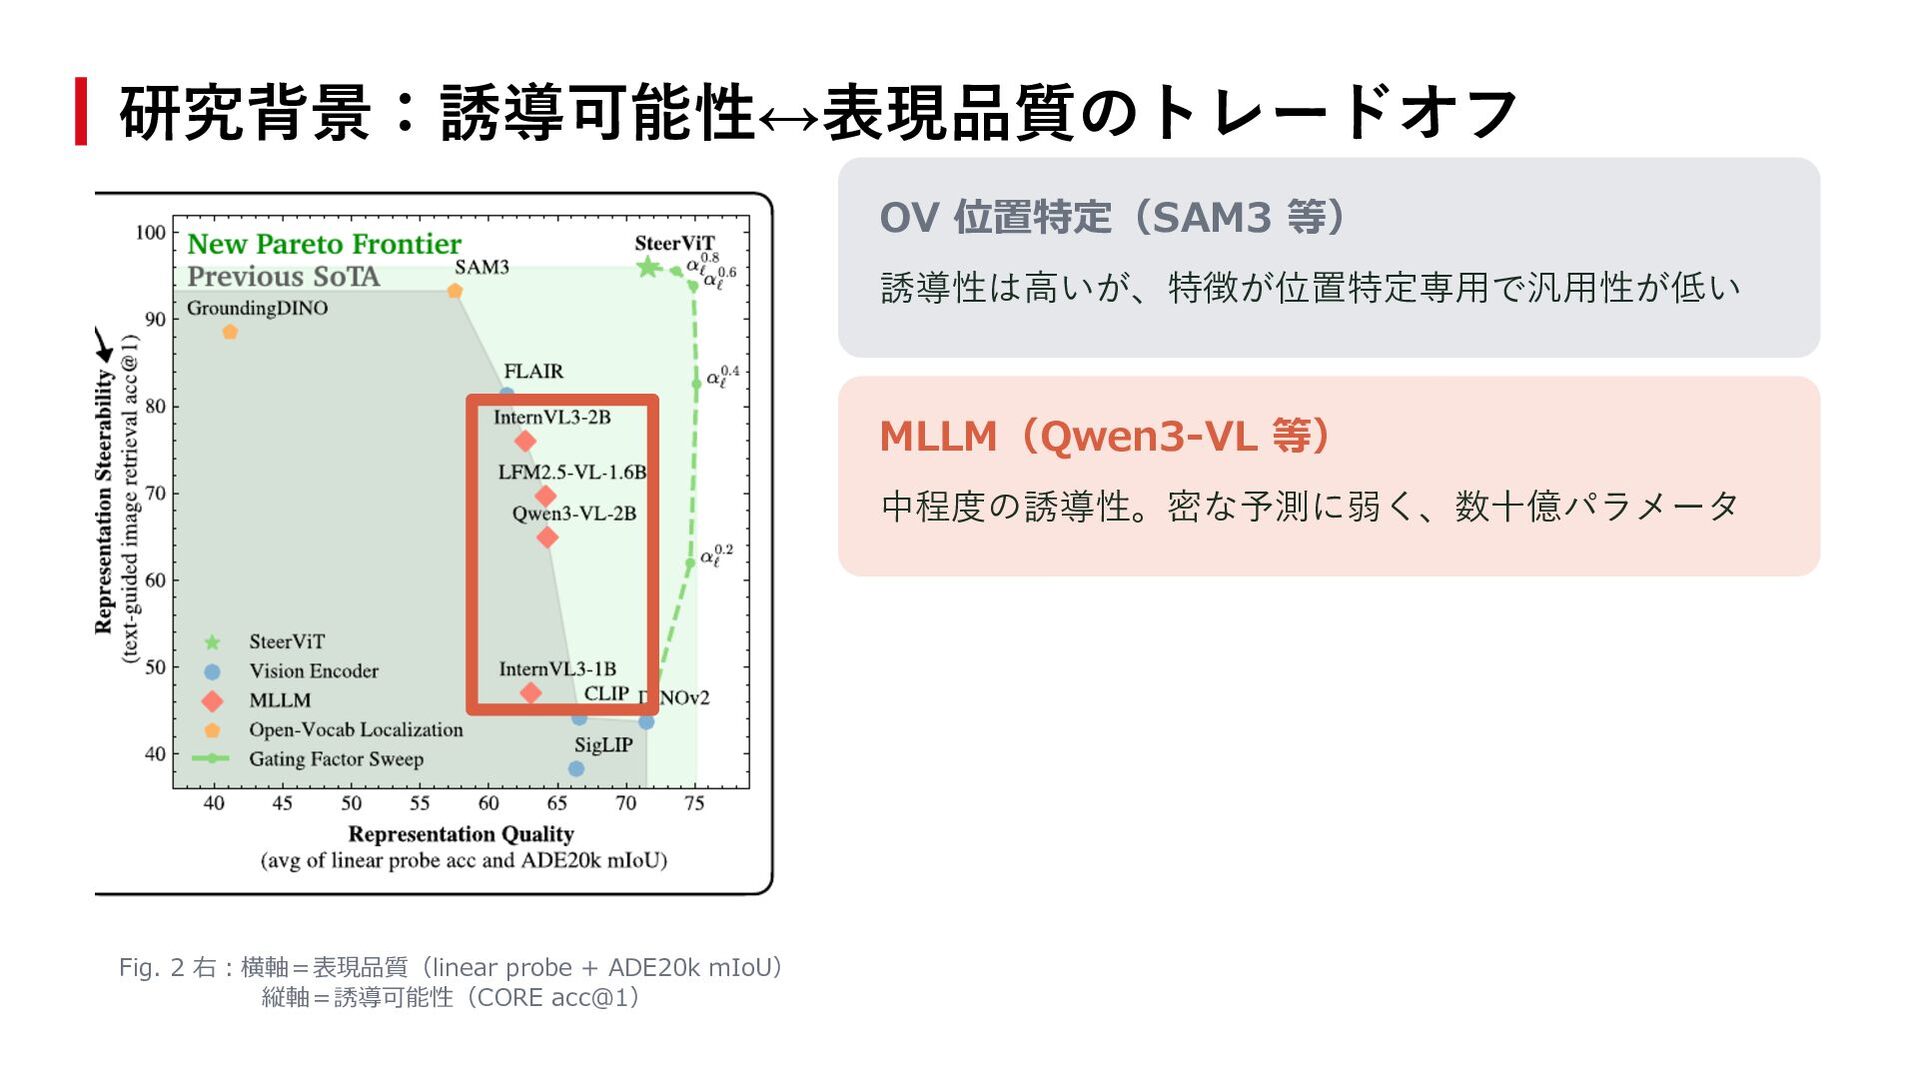
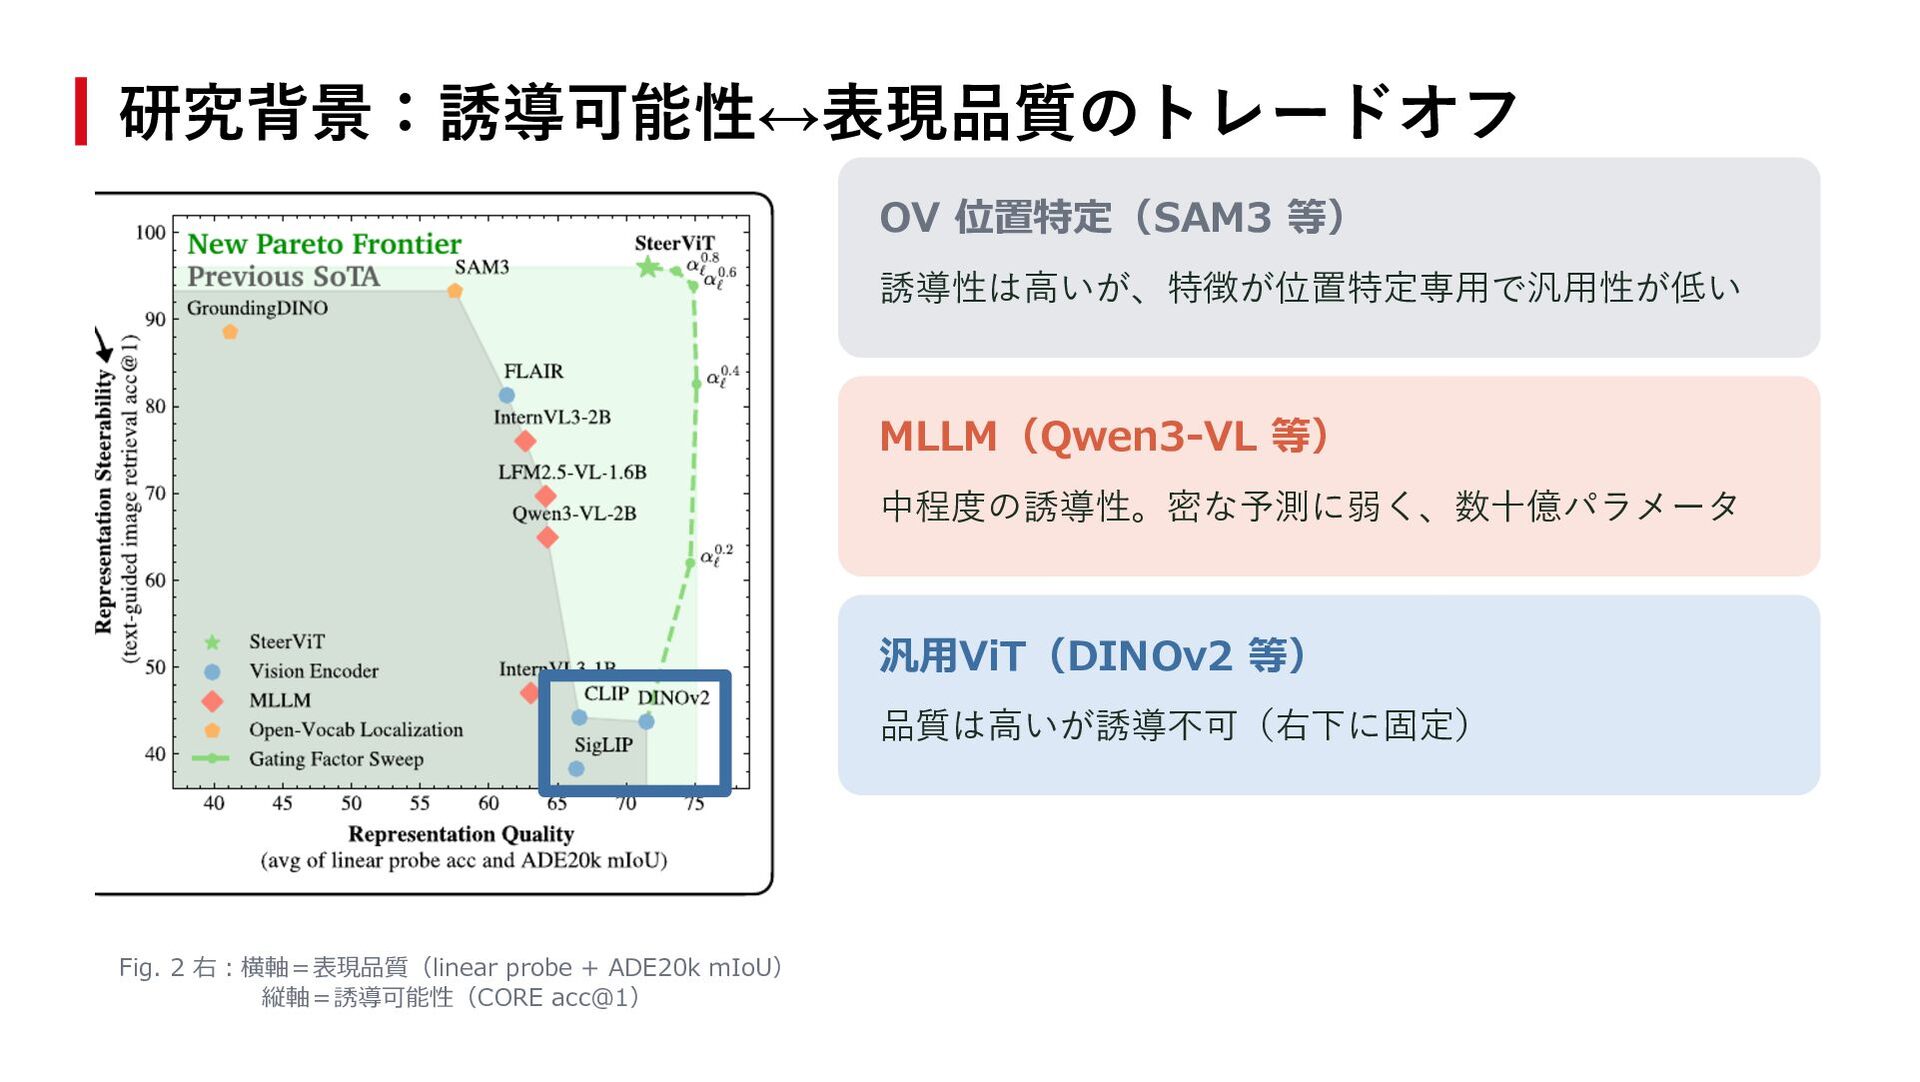
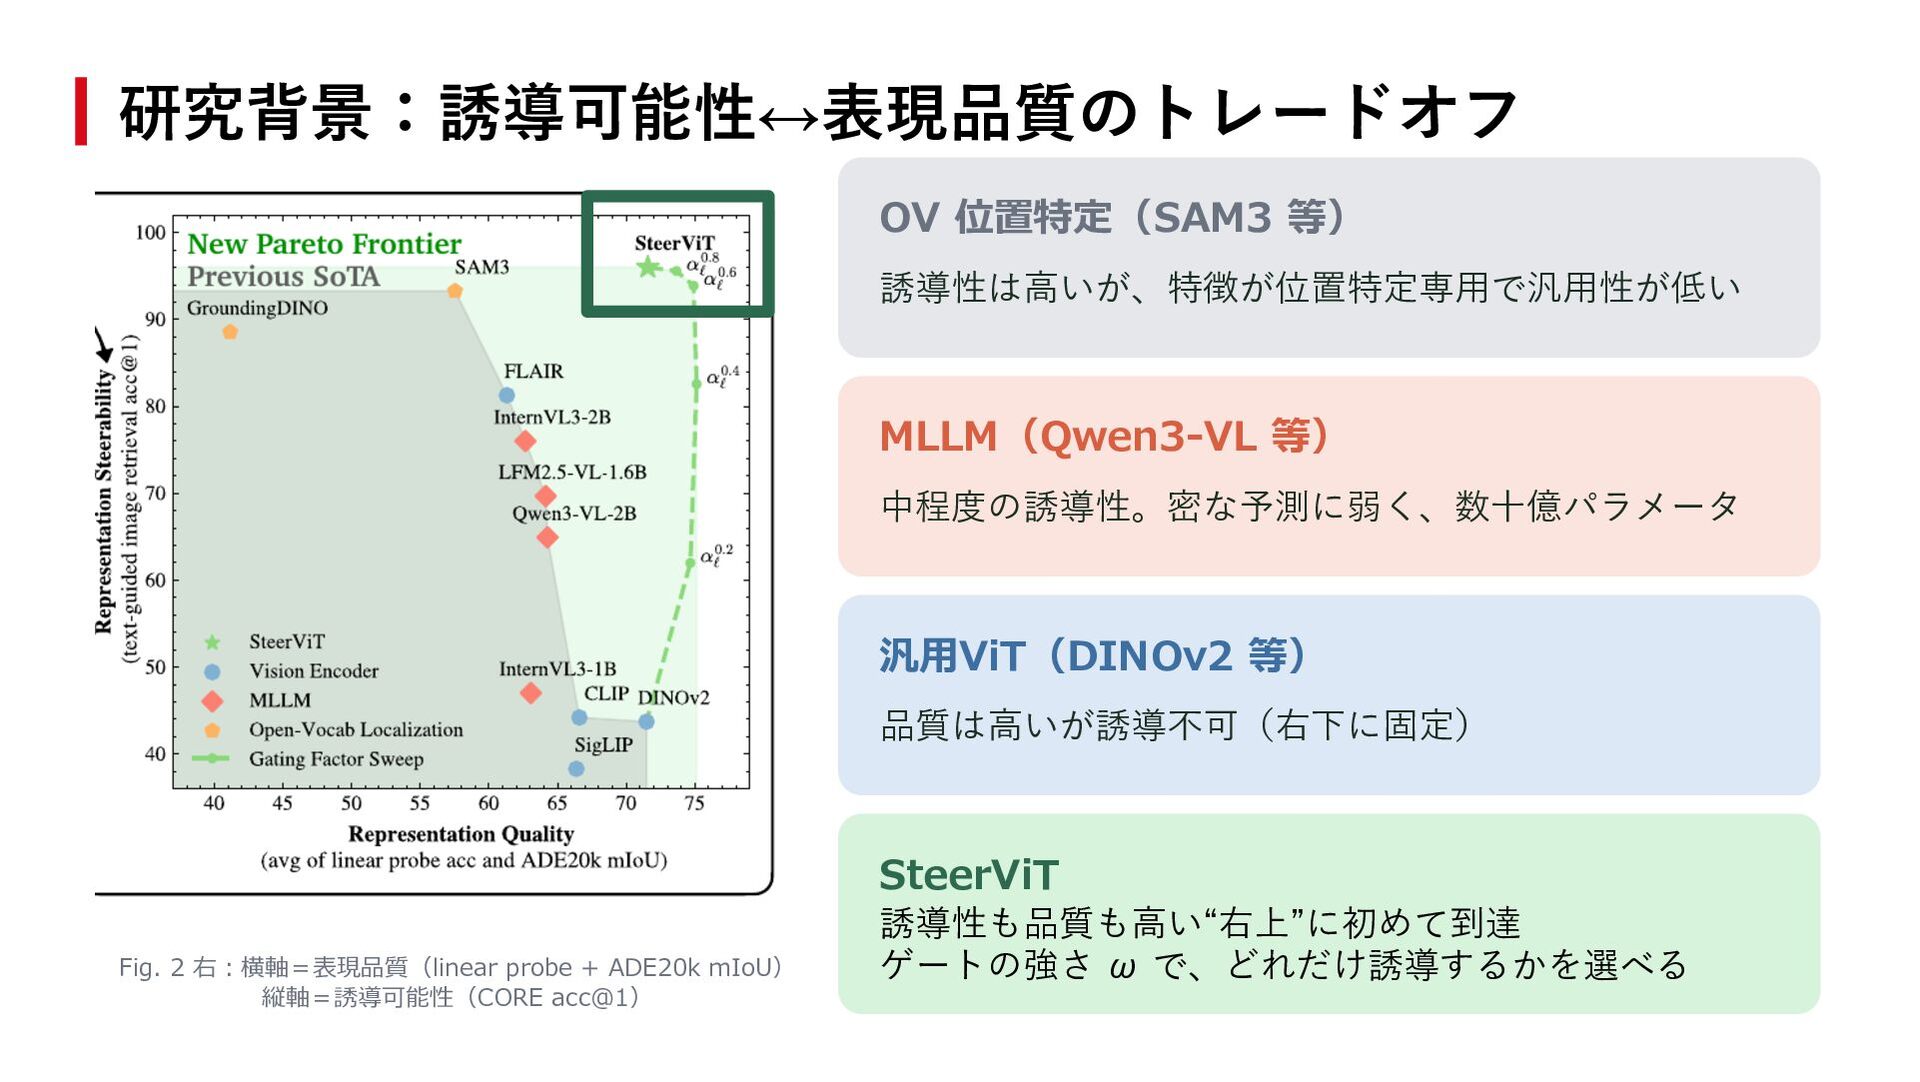
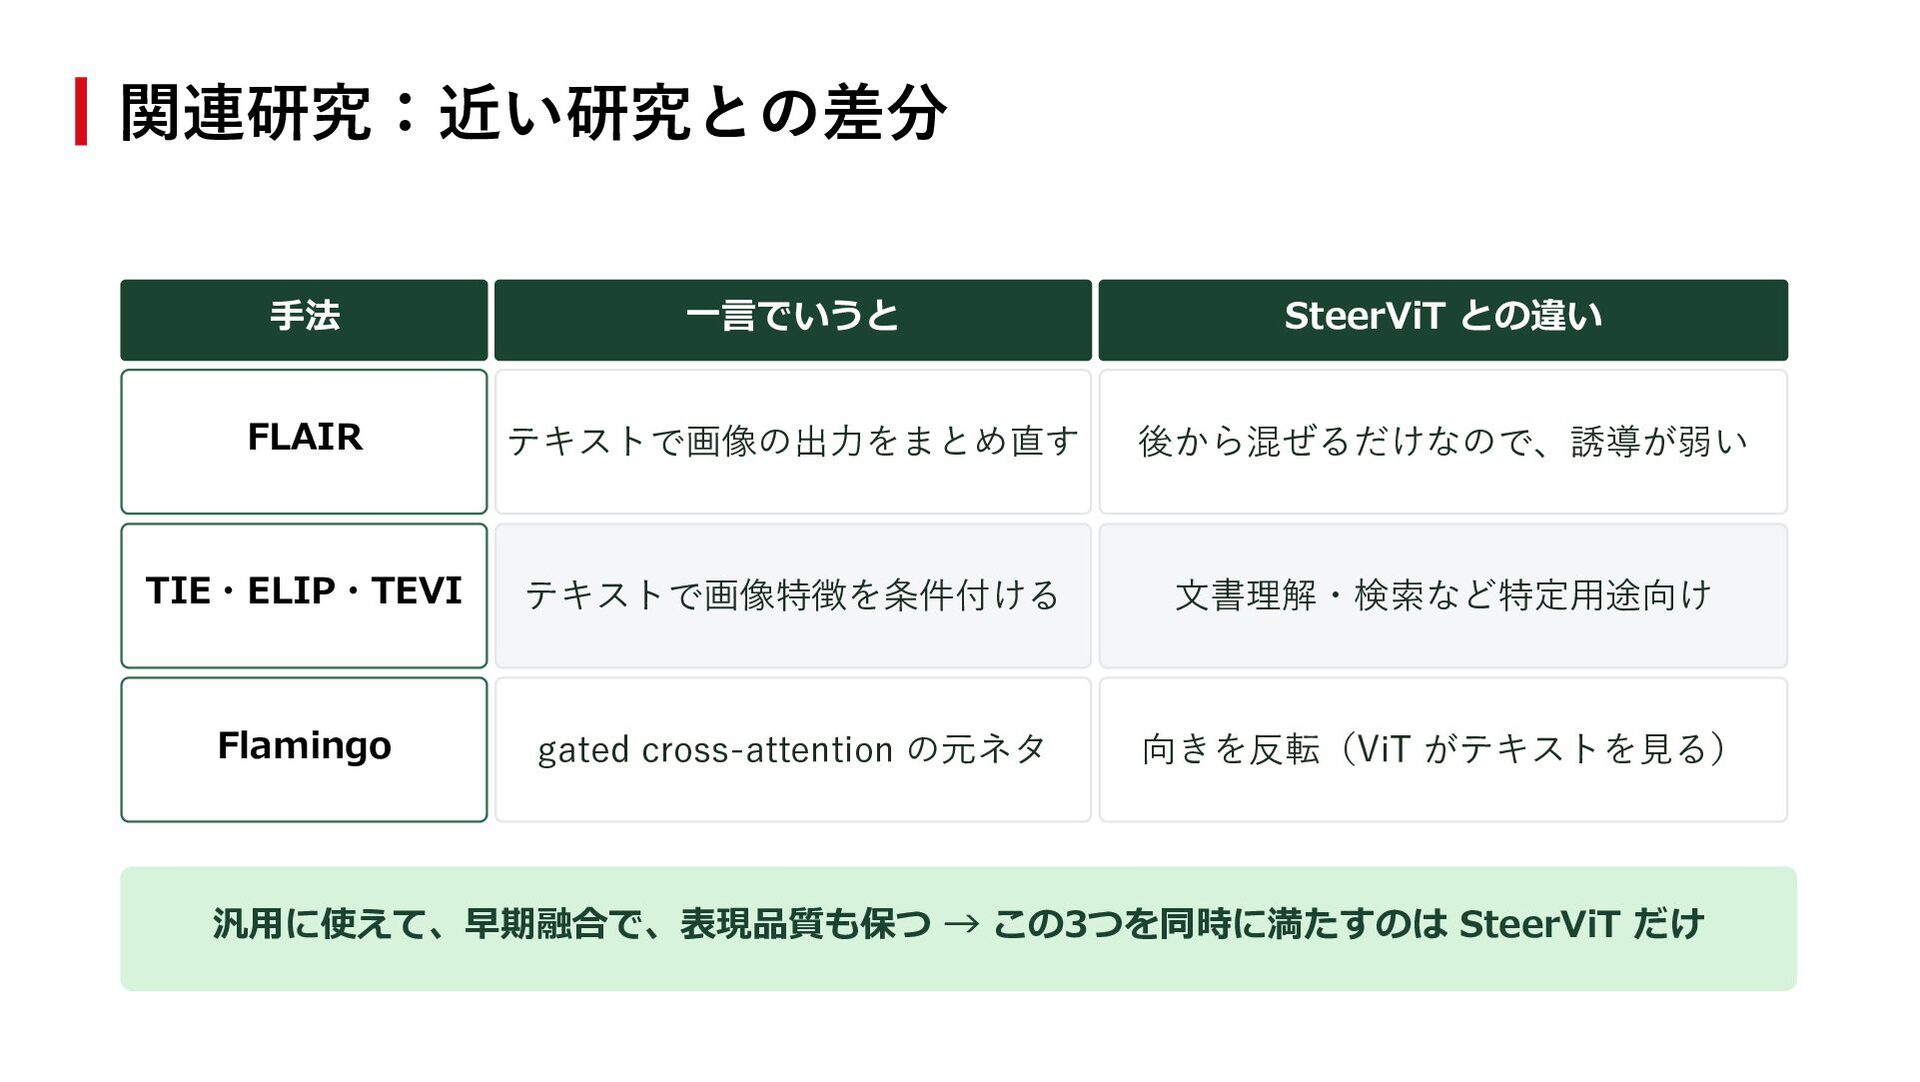
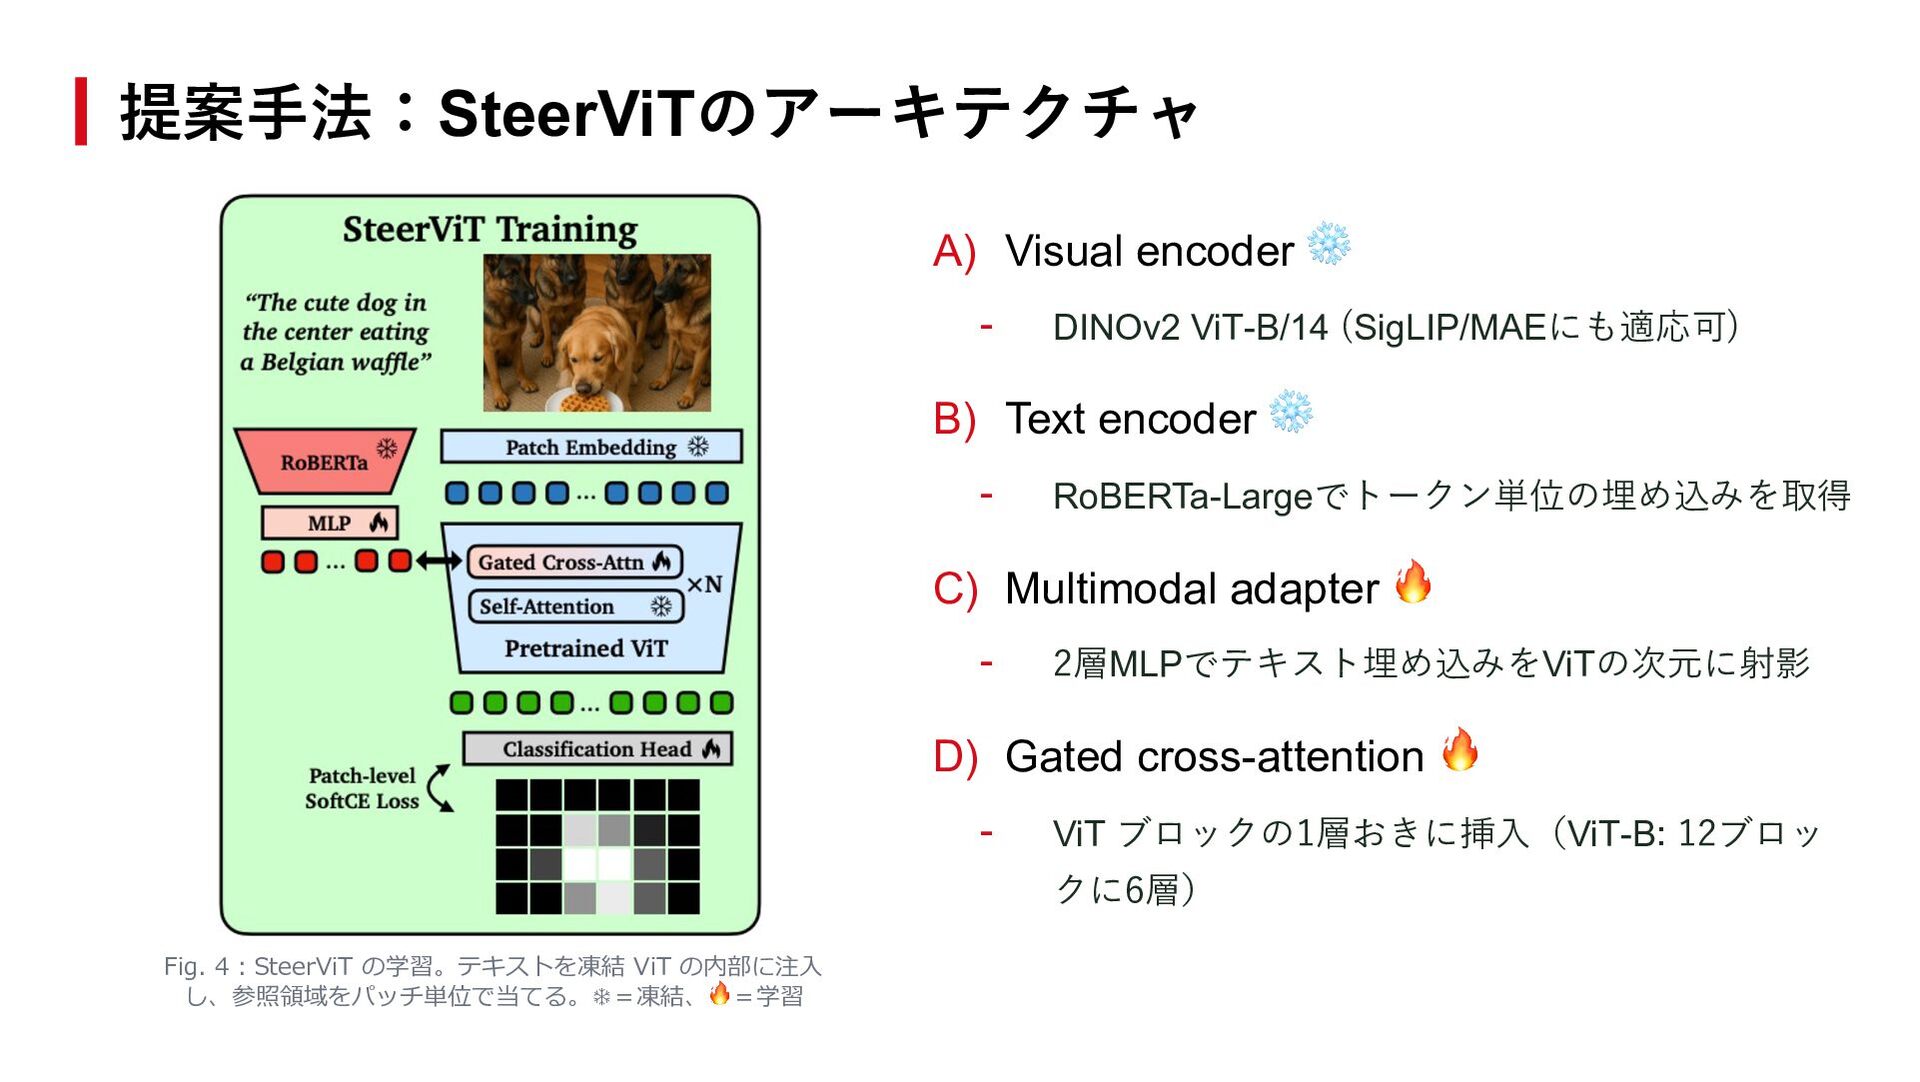
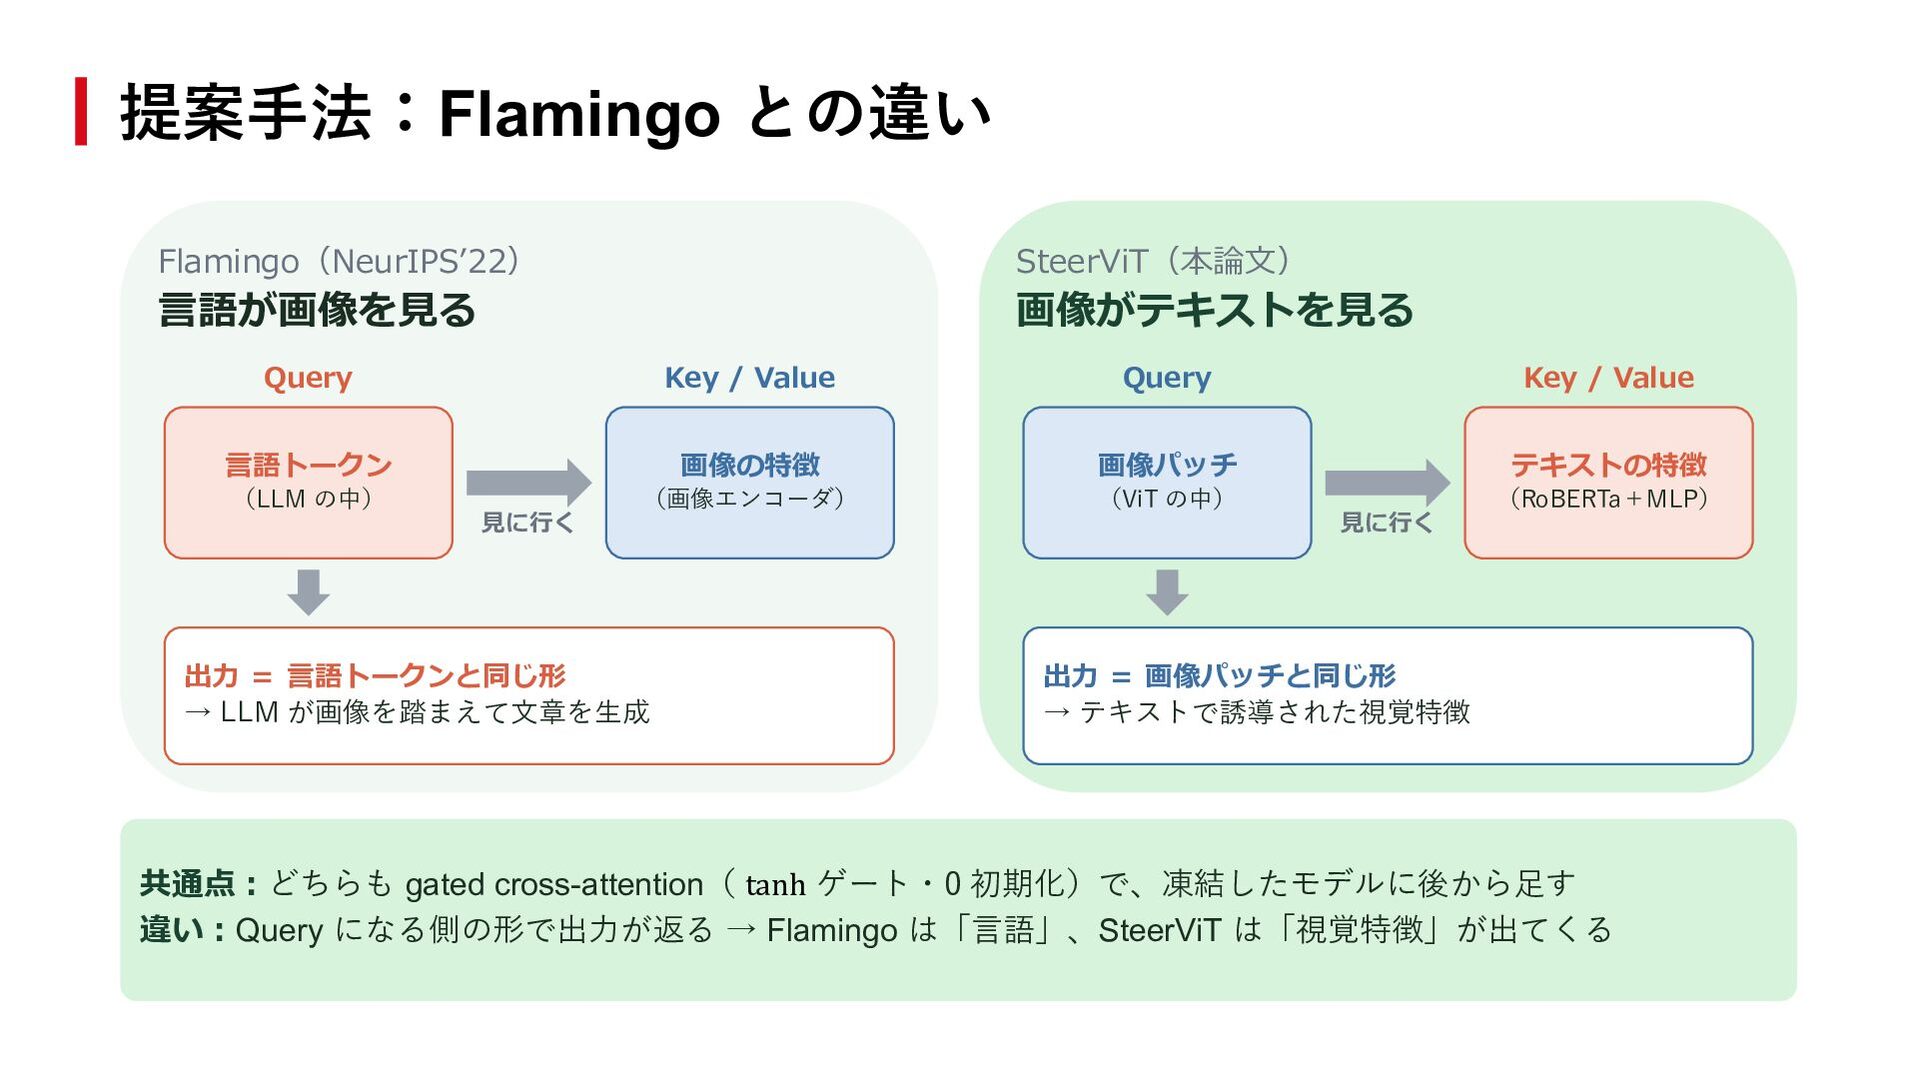
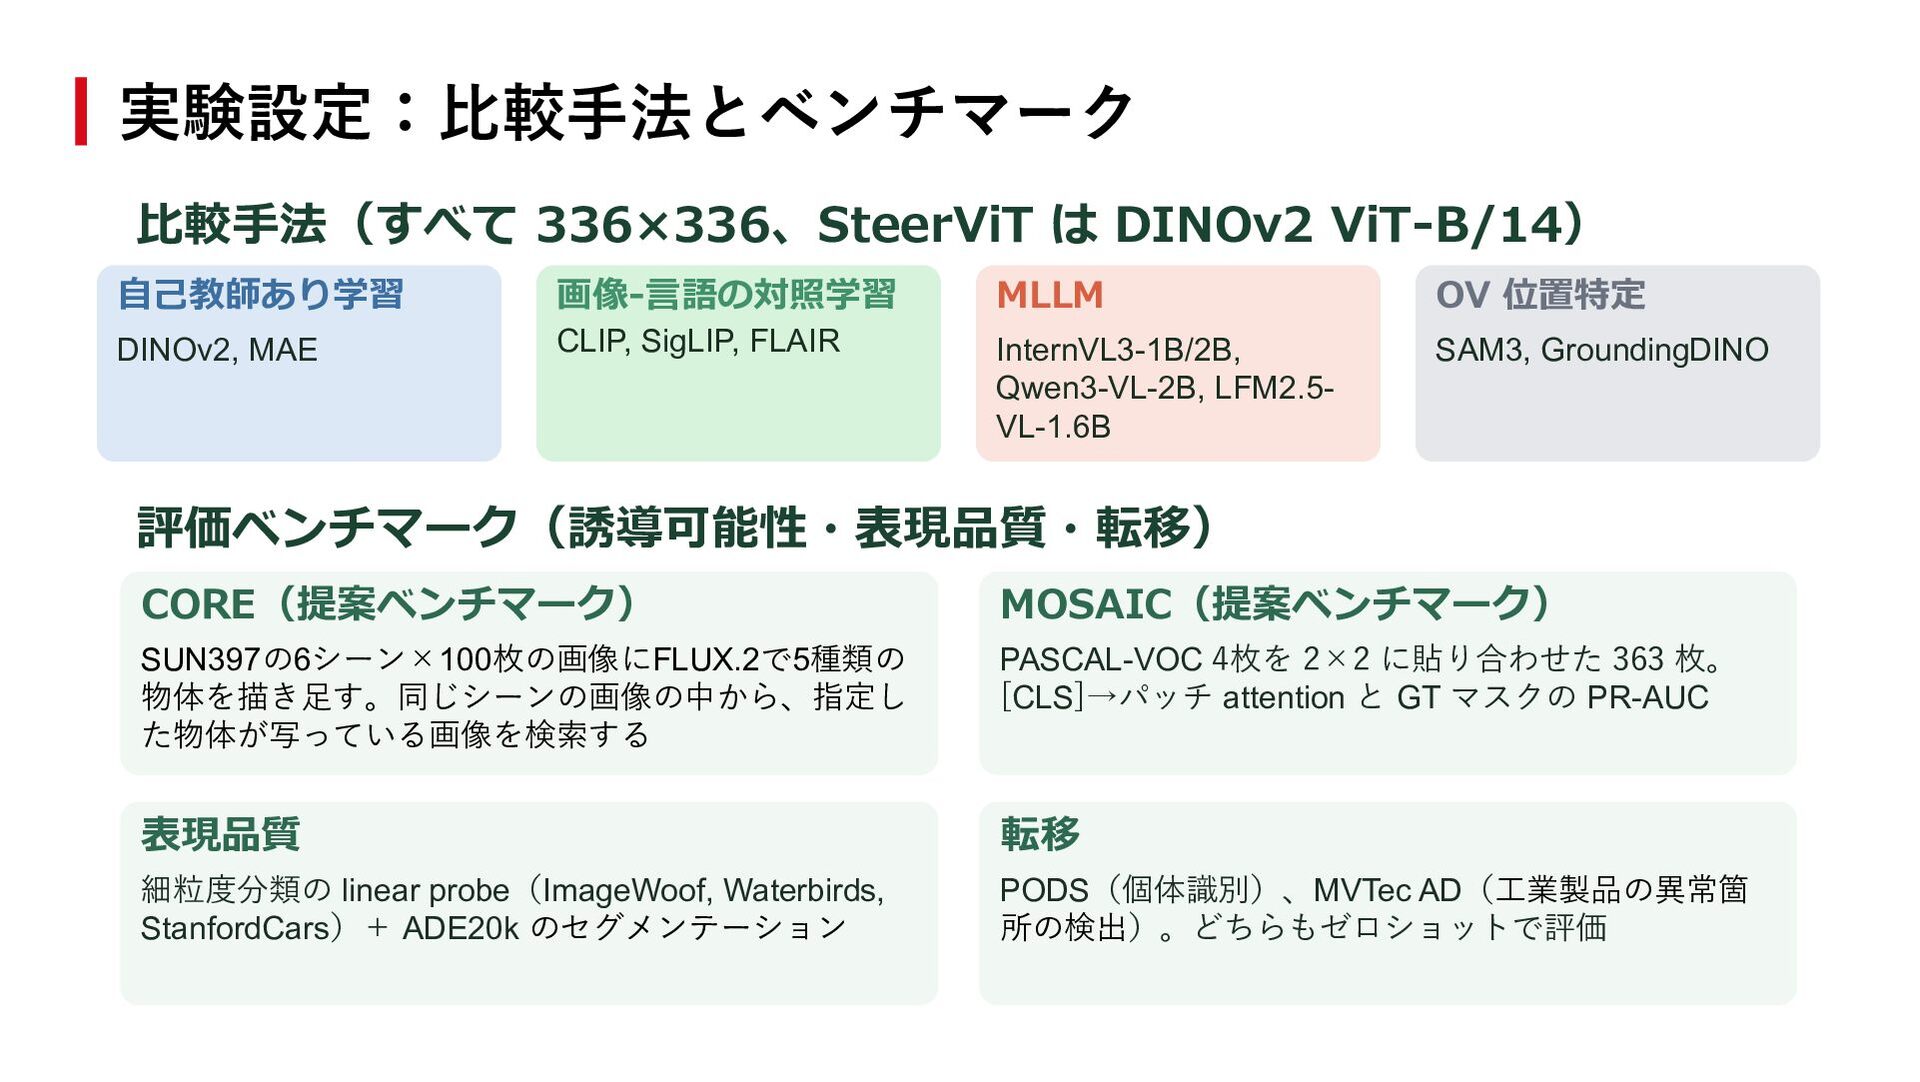
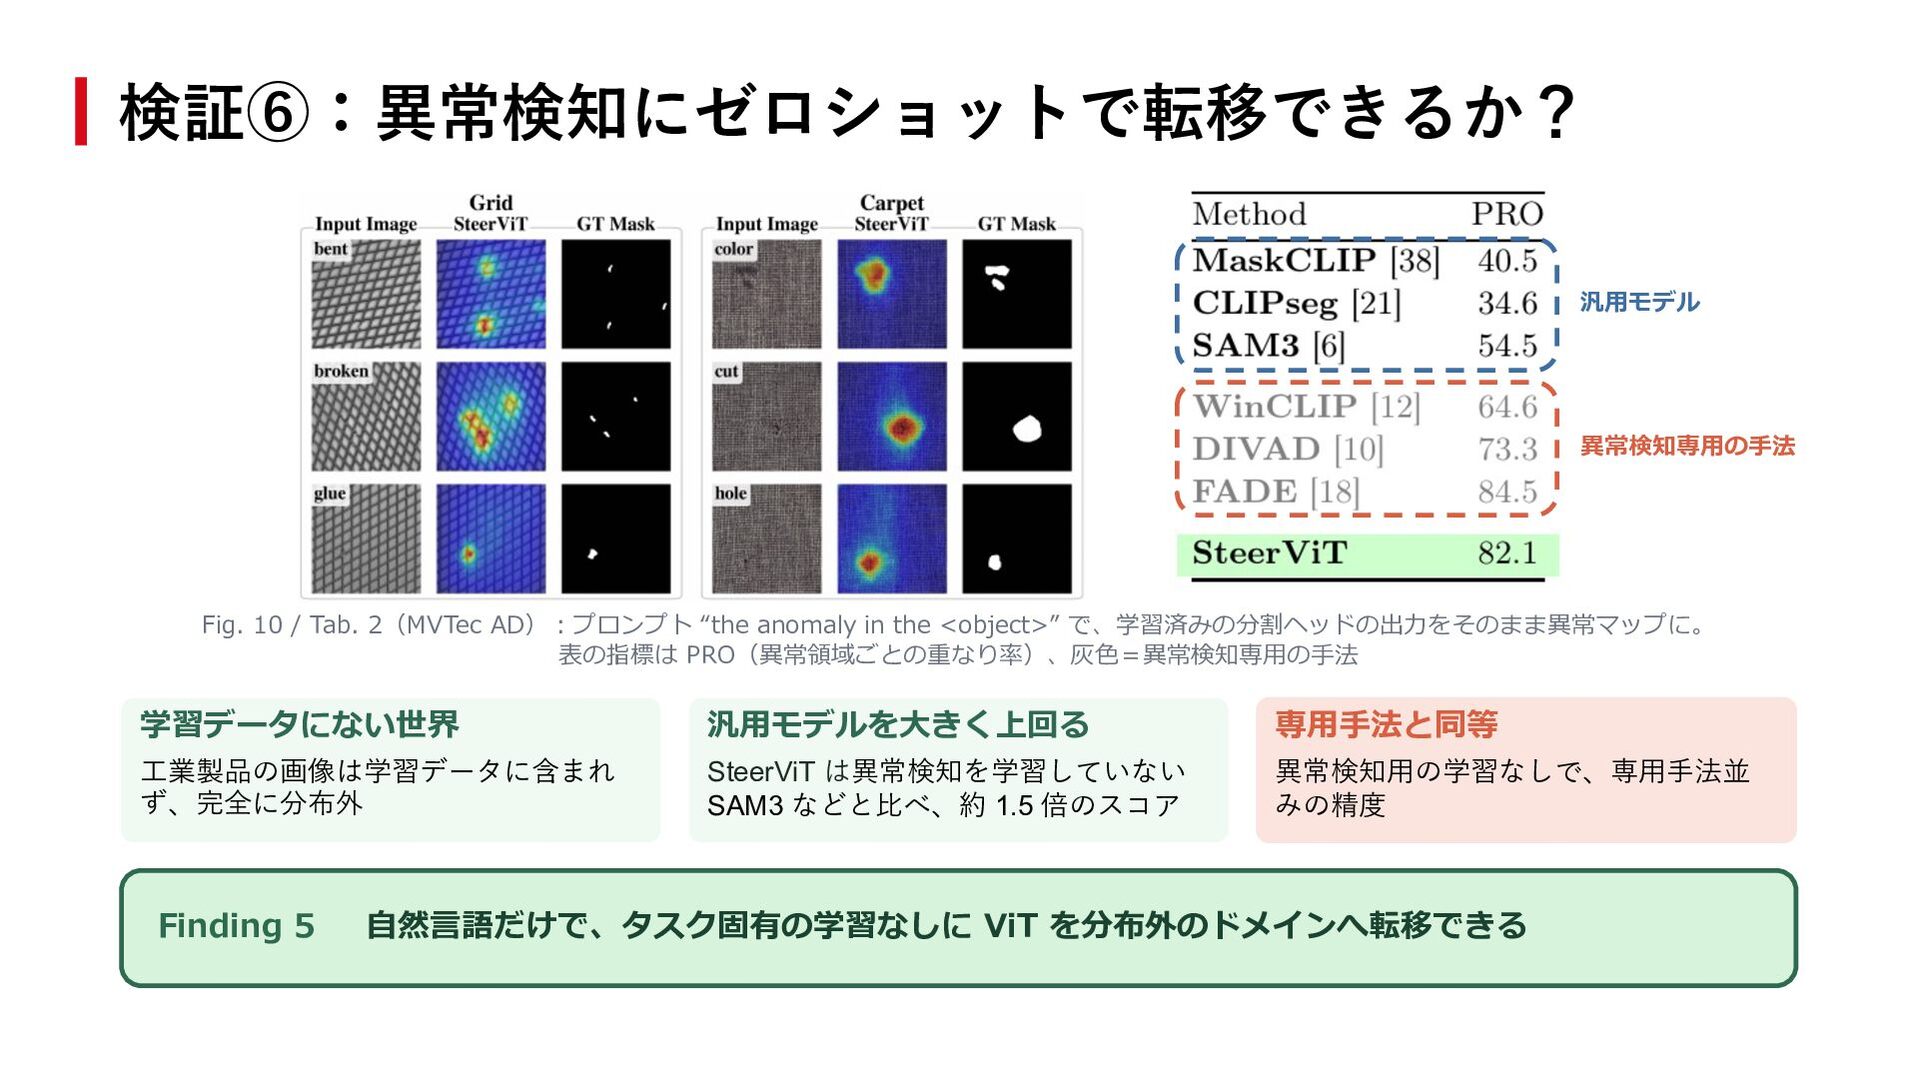
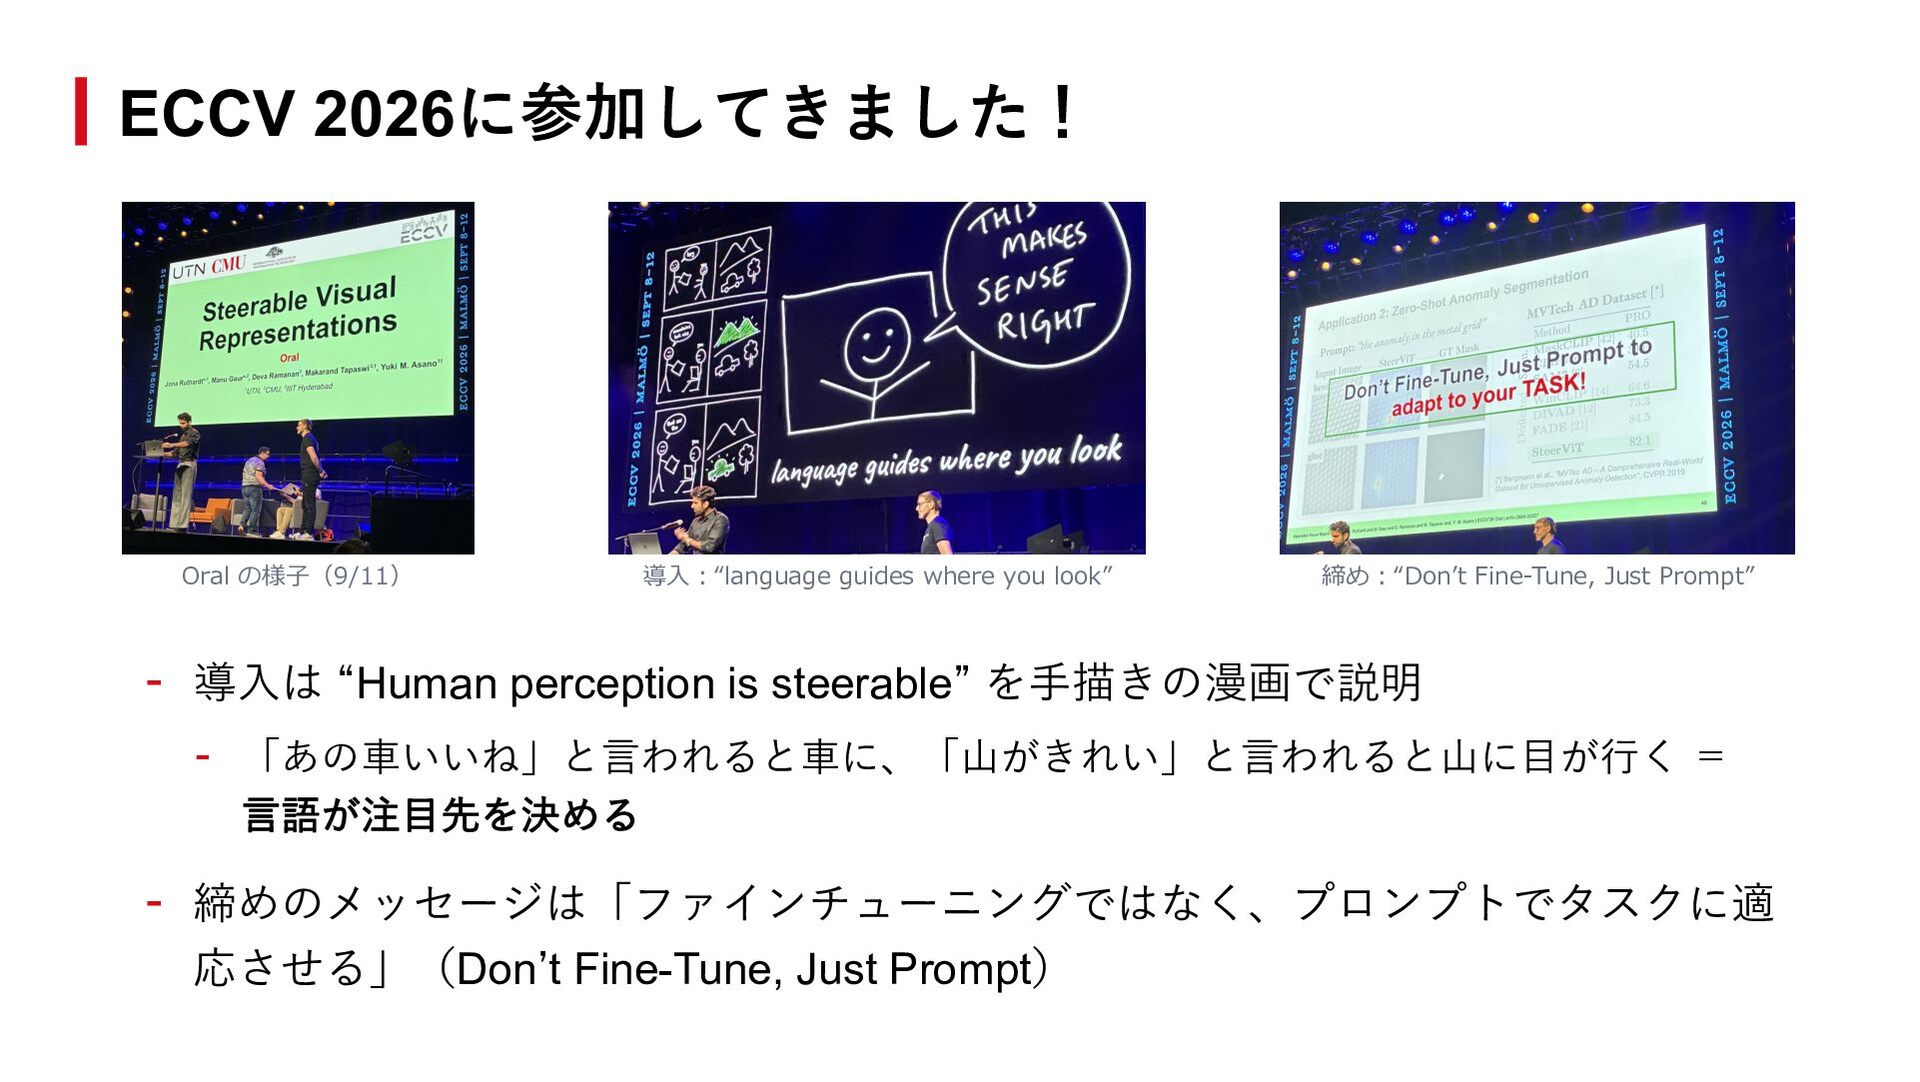
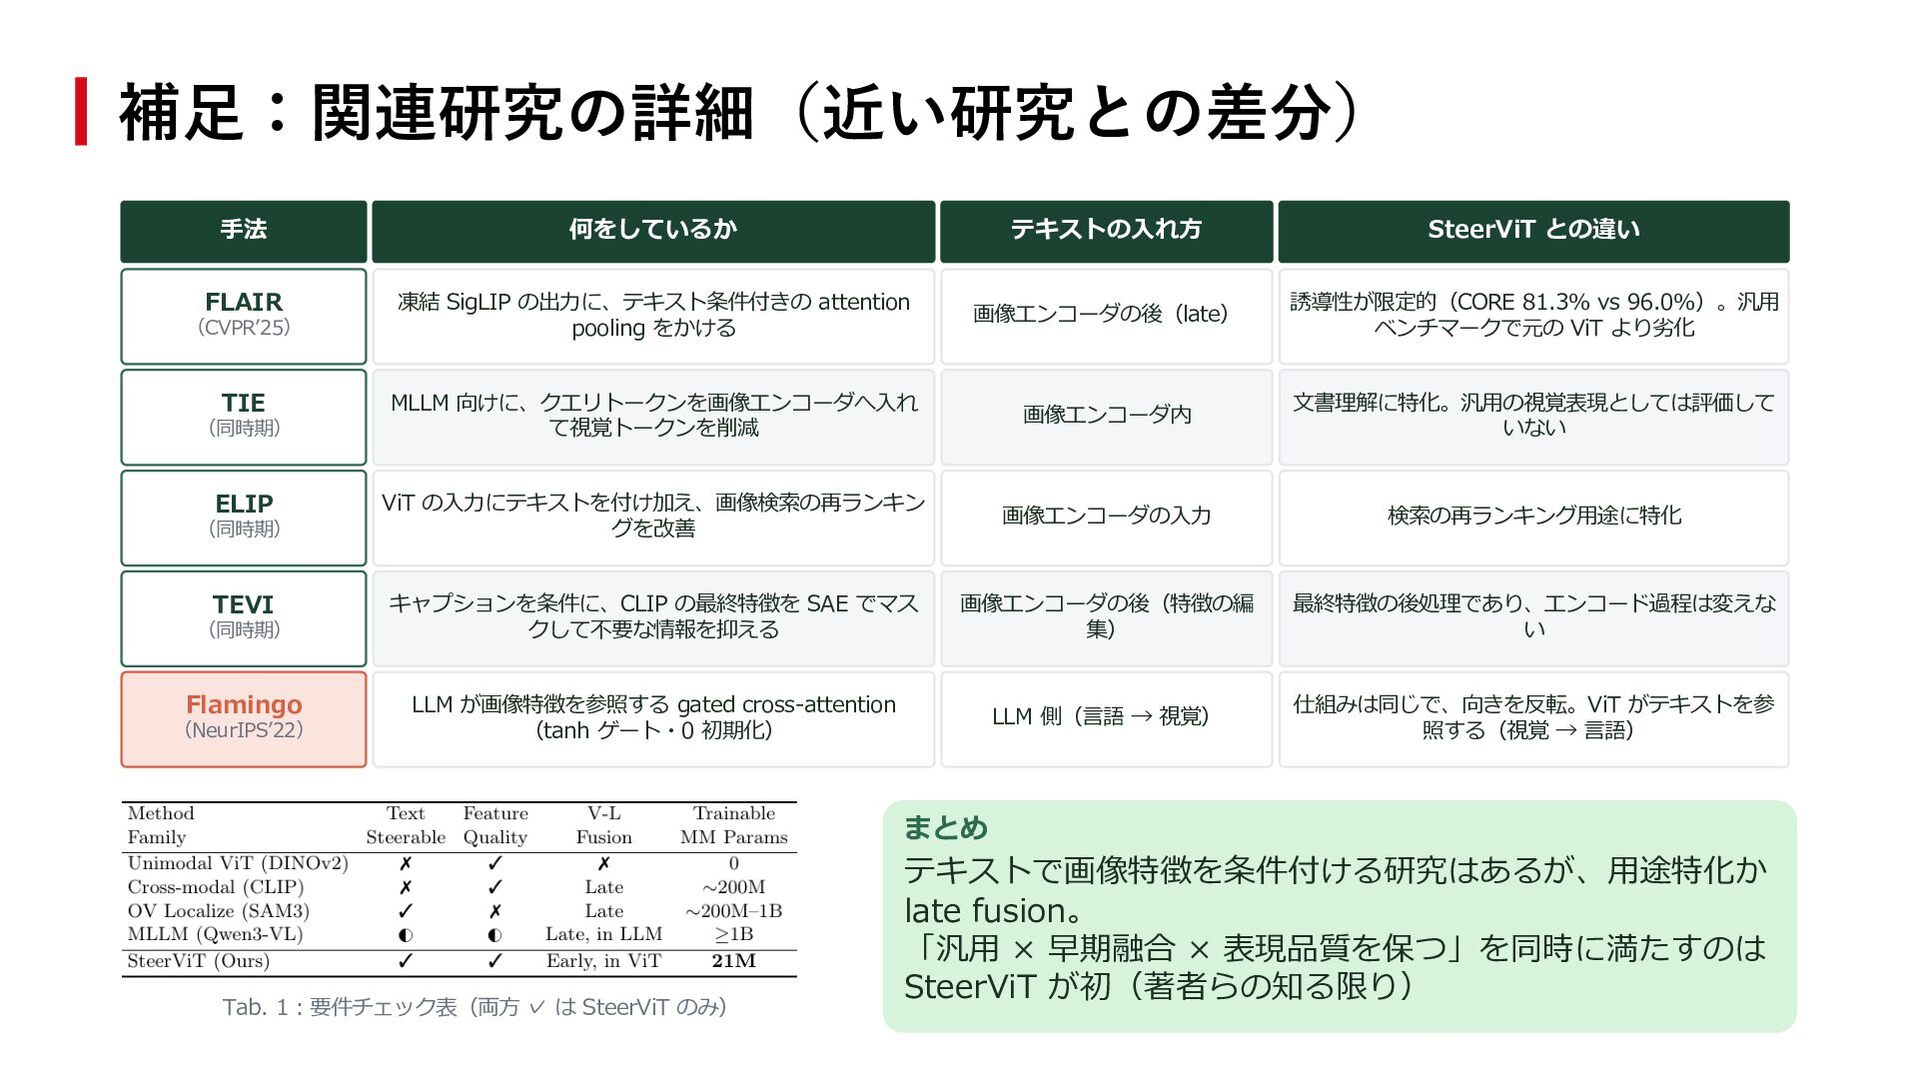
Report. arXiv:2511.23404, 2025 T. Jiang et al. E5-V: Universal Embeddings with Multimodal Large Language Models. arXiv:2407.12580, 2024 J. Ruthardt, M. Gaur, D. Ramanan, M. Tapaswi, Y. M. Asano. Steerable Visual Representations. ECCV 2026 (Oral). arXiv:2604.02327 プロジェクトページ・公式デモ︓jonaruthardt.github.io/project/SteerViT M. Oquab et al. DINOv2: Learning Robust Visual Features without Supervision. TMLR 2024 K. He et al. Masked Autoencoders Are Scalable Vision Learners. CVPR 2022 A. Radford et al. Learning Transferable Visual Models From Natural Language Supervision (CLIP). ICML 2021 X. Zhai et al. Sigmoid Loss for Language Image Pre-Training (SigLIP). ICCV 2023 Y. Liu et al. RoBERTa: A Robustly Optimized BERT Pretraining Approach. arXiv:1907.11692, 2019 関連研究 J.-B. Alayrac et al. Flamingo: a Visual Language Model for Few-Shot Learning. NeurIPS 2022 R. Xiao et al. FLAIR: VLM with Fine-grained Language-informed Image Representations. CVPR 2025 R. Thirukovalluru et al. Text-Guided Semantic Image Encoder (TIE). arXiv:2511.20770, 2025 G. Zhan et al. ELIP: Enhanced Visual-Language Foundation Models for Image Retrieval. CBMI 2025 S. Mahajan et al. TEVI: Text-conditioned Editing of Visual Representations via Sparse Autoencoders. arXiv:2606.07451, 2026 J. Zhu et al. InternVL3: Exploring Advanced Training and Test-time Recipes for Open-source Multimodal Models. arXiv:2504.10479, 2025 S. Bai et al. Qwen3-VL Technical Report. arXiv:2511.21631, 2025 Open-Vocabulary 位置特定 N. Carion et al. SAM 3: Segment Anything with Concepts. ICLR 2026 S. Liu et al. Grounding DINO: Marrying DINO with Grounded Pre-Training for Open-Set Object Detection. ECCV 2024 異常検知の⽐較⼿法 C. Zhou et al. Extract Free Dense Labels from CLIP (MaskCLIP). ECCV 2022 T. Lüddecke, A. Ecker. Image Segmentation Using Text and Image Prompts (CLIPSeg). CVPR 2022 J. Jeong et al. WinCLIP: Zero-/Few-Shot Anomaly Classification and Segmentation. CVPR 2023 S. Hicsonmez et al. Training Free Zero-Shot Visual Anomaly Localization via Diffusion Inversion (DIVAD). arXiv:2601.08022, 2026 Y. Li et al. FADE: Few-shot/zero-shot Anomaly Detection Engine using Large Vision-Language Model. BMVC 2024
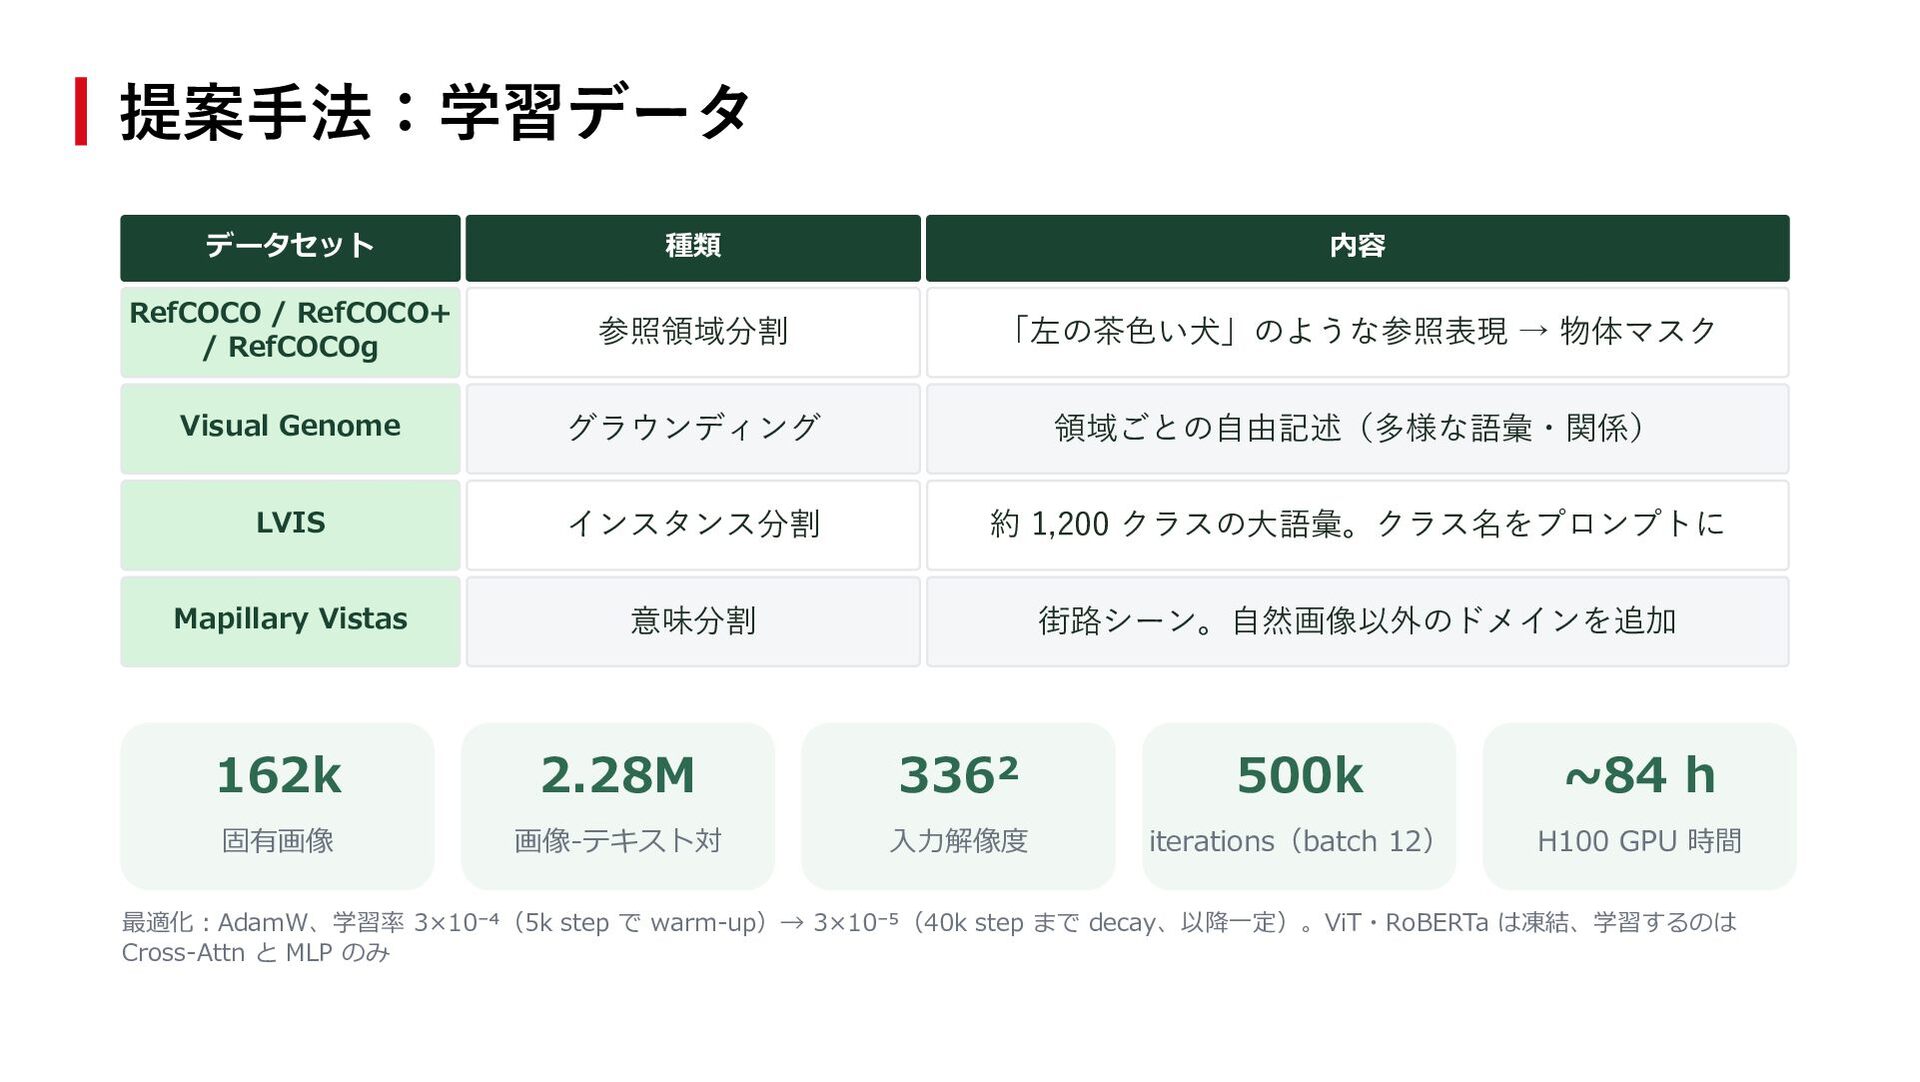
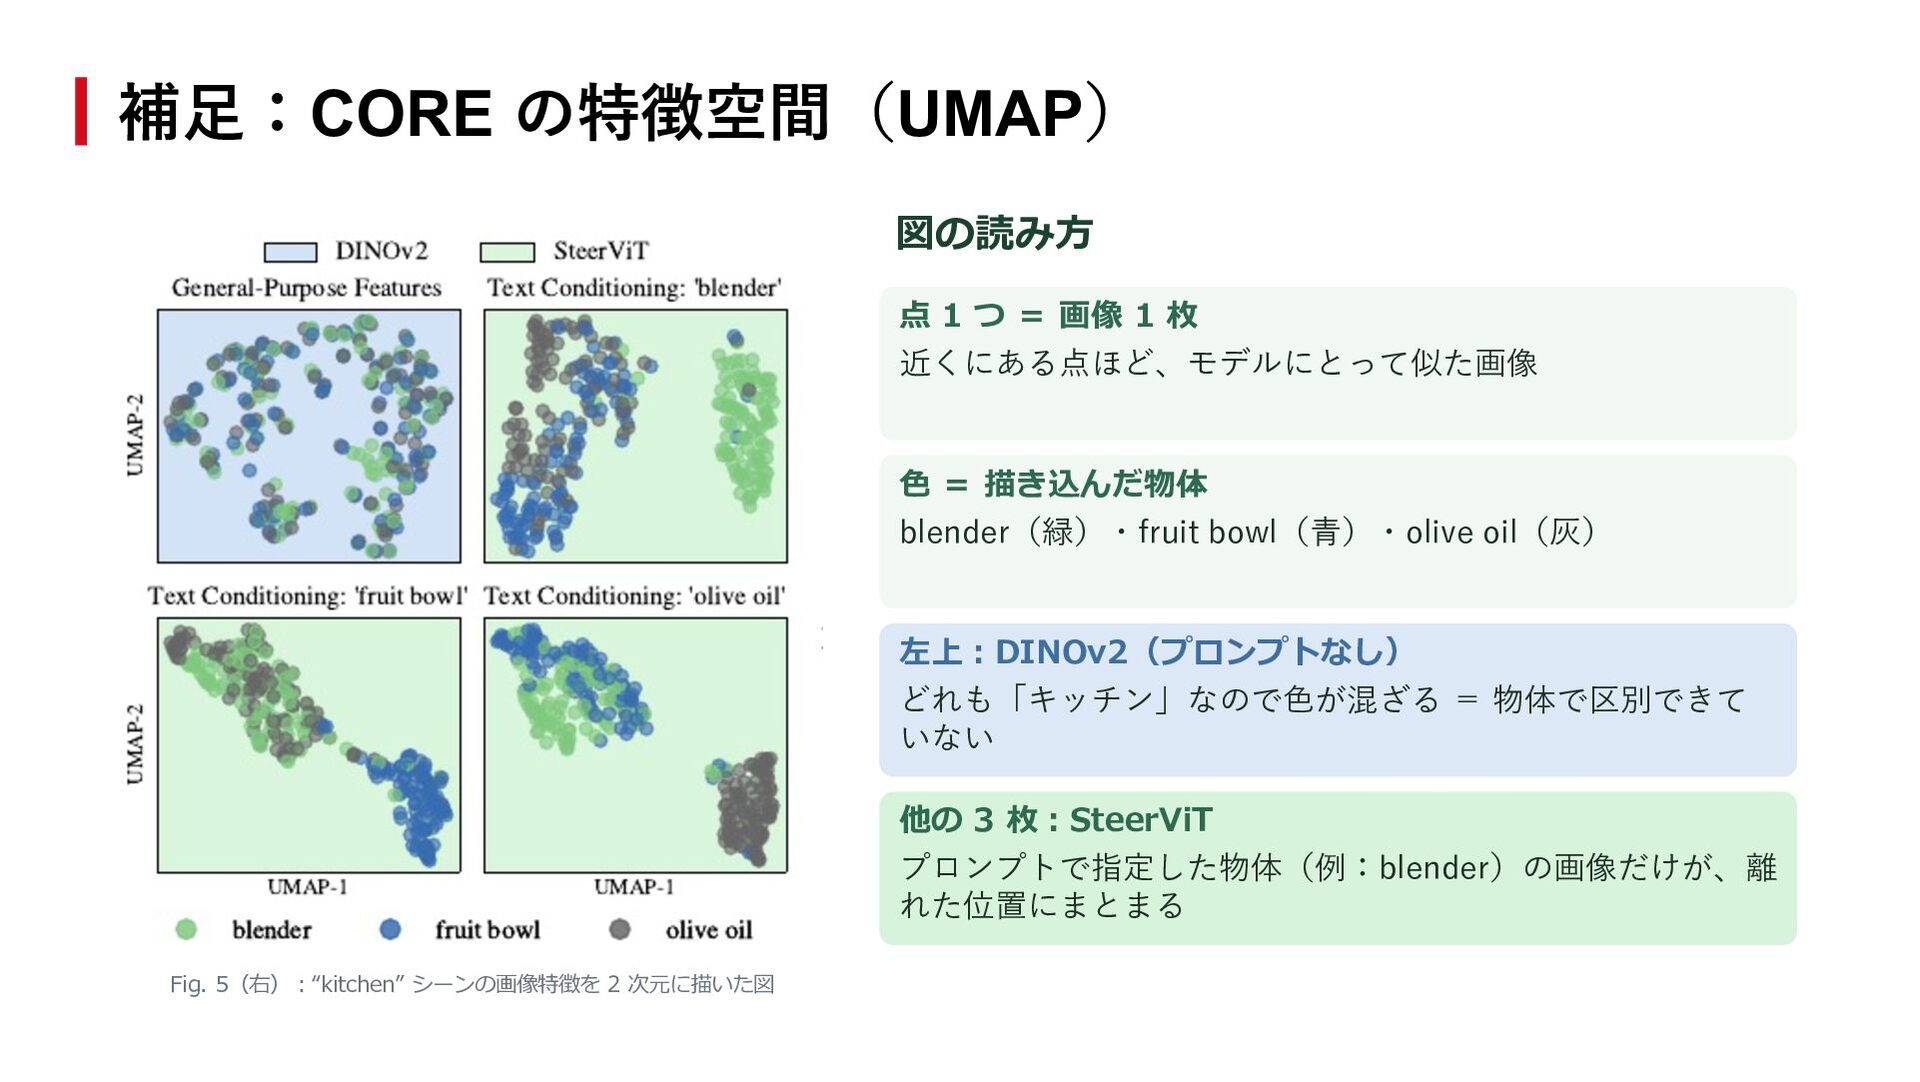
in Photographs of Natural Scenes (RefCOCO). EMNLP 2014 L. Yu et al. Modeling Context in Referring Expressions (RefCOCO+/g). ECCV 2016 R. Krishna et al. Visual Genome. IJCV 2017 A. Gupta et al. LVIS: A Dataset for Large Vocabulary Instance Segmentation. CVPR 2019 G. Neuhold et al. The Mapillary Vistas Dataset for Semantic Understanding of Street Scenes. ICCV 2017 ベンチマーク作成(CORE・MOSAIC) J. Xiao et al. SUN Database: Large-scale Scene Recognition from Abbey to Zoo (SUN397). CVPR 2010 Black Forest Labs. FLUX.2: Frontier Visual Intelligence. 2025 M. Everingham et al. The PASCAL Visual Object Classes (VOC) Challenge. IJCV 2010 表現品質の評価 J. Howard. Imagewoof: a subset of 10 classes from ImageNet. 2019 S. Sagawa et al. Distributionally Robust Neural Networks (Waterbirds). ICLR 2020 J. Krause et al. 3D Object Representations for Fine-Grained Categorization (StanfordCars). ICCVW 2013 B. Zhou et al. Scene Parsing through ADE20K Dataset. CVPR 2017 転移の評価 S. Sundaram et al. Personalized Representation from Personalized Generation (PODS). ICLR 2025 P. Bergmann et al. MVTec AD: A Comprehensive Real-World Dataset for Unsupervised Anomaly Detection. CVPR 2019 可視化 L. McInnes et al. UMAP: Uniform Manifold Approximation and Projection. JOSS 2018 画像について 図表は本論⽂より引⽤。会場写真・デモ結果は発表者が撮影・実⾏したもの


 sansantech
 bgpat
 pfn
 akhino
 takuroabe
 yazm
 satoshi7
 masakiokuda
 camiha
 ueponx
 yahonda
 kenichiodo
 katarinadahlin
 iamctodd
 raygrieselhuber
 skipperchong
 thekraken
 paigeccino
 morganepeng
 letsgokoyo
 tammyeverts
 mojombo
 lauravandoore
 reverentgeek