Wasserstein gradient flow of Moreau envelopes o...
Sponsored
·
 Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→

Share
Embed
Wasserstein gradient flow of Moreau envelopes of f-divergences in reproducing kernel Hilbert spaces (with Outlook)

Viktor Stein
April 28, 2025
Transcript
31 slides
-
Wasserstein Gradient Flows of Moreau Envelopes of f-Divergences in Reproducing
Kernel Hilbert Spaces joint work with Sebastian Neumayer, TU Chemnitz Nicolaj Rux, TU Berlin Gabriele Steidl, TU Berlin Viktor Stein - Talk at the University of Washington’s Department of Statistics -
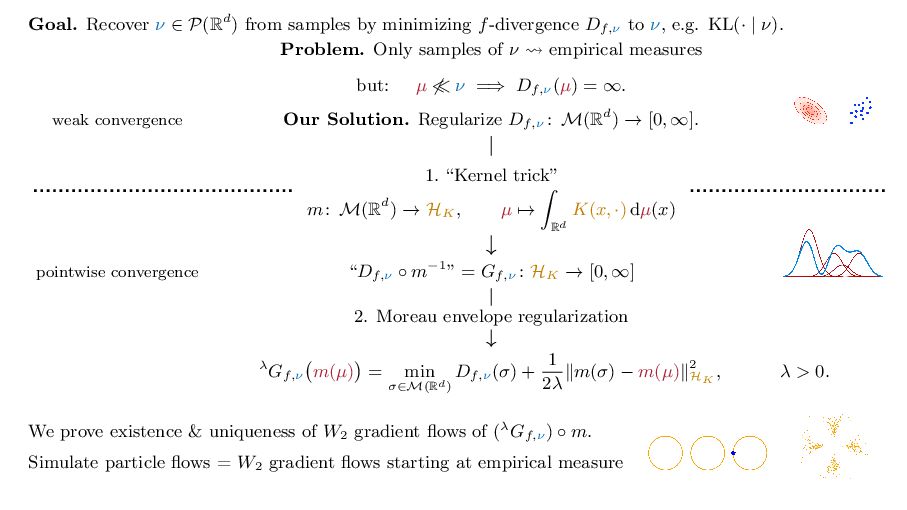
Goal. Recover ν ∈ P(Rd) from samples by minimizing f-divergence
Df,ν to ν, e.g. KL(· | ν). Problem. Only samples of ν ⇝ empirical measures but: µ ̸≪ ν =⇒ Df,ν (µ) = ∞. weak convergence Our Solution. Regularize Df,ν : M(Rd) → [0, ∞]. pointwise convergence “Df,ν ◦ m−1” = Gf,ν : HK → [0, ∞] λGf,ν m(µ) = min σ∈M(Rd) Df,ν (σ) + 1 2λ ∥m(σ) − m(µ)∥2 HK , λ > 0. 1. “Kernel trick” m: M(Rd) → HK , µ → Rd K(x, ·) dµ(x) 2. Moreau envelope regularization We prove existence & uniqueness of W2 gradient flows of (λGf,ν ) ◦ m. Simulate particle flows = W2 gradient flows starting at empirical measure -
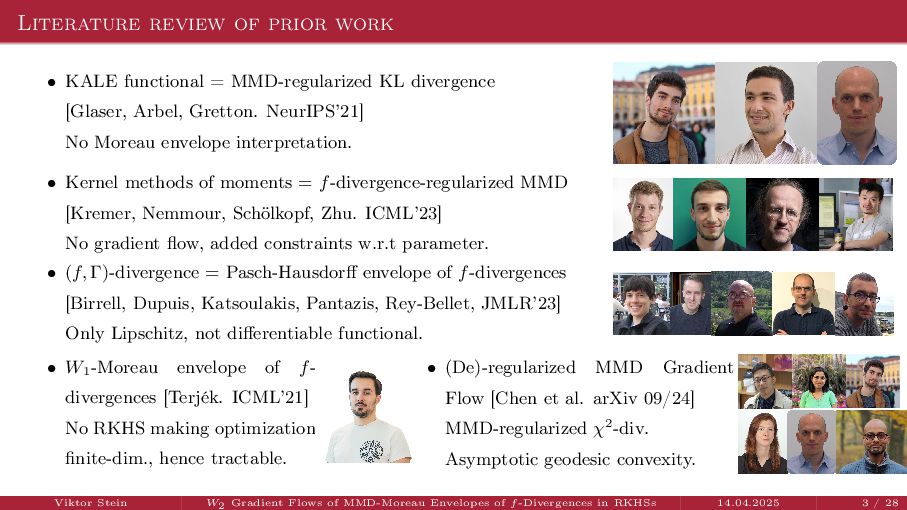
Literature review of prior work • KALE functional = MMD-regularized
KL divergence [Glaser, Arbel, Gretton. NeurIPS’21] No Moreau envelope interpretation. • Kernel methods of moments = f-divergence-regularized MMD [Kremer, Nemmour, Schölkopf, Zhu. ICML’23] No gradient flow, added constraints w.r.t parameter. • (f, Γ)-divergence = Pasch-Hausdorff envelope of f-divergences [Birrell, Dupuis, Katsoulakis, Pantazis, Rey-Bellet, JMLR’23] Only Lipschitz, not differentiable functional. • W1 -Moreau envelope of f- divergences [Terjék. ICML’21] No RKHS making optimization finite-dim., hence tractable. • (De)-regularized MMD Gradient Flow [Chen et al. arXiv 09/24] MMD-regularized χ2-div. Asymptotic geodesic convexity. Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 3 / 28 -
1. RKHS & MMD 2. Moreau envelopes 3. f-divergences 4.
MMD-Moreau envelopes of f-divergences 5. Wasserstein gradient flow 6. WGF of MMD-Moreau en- velopes of f-divergences -
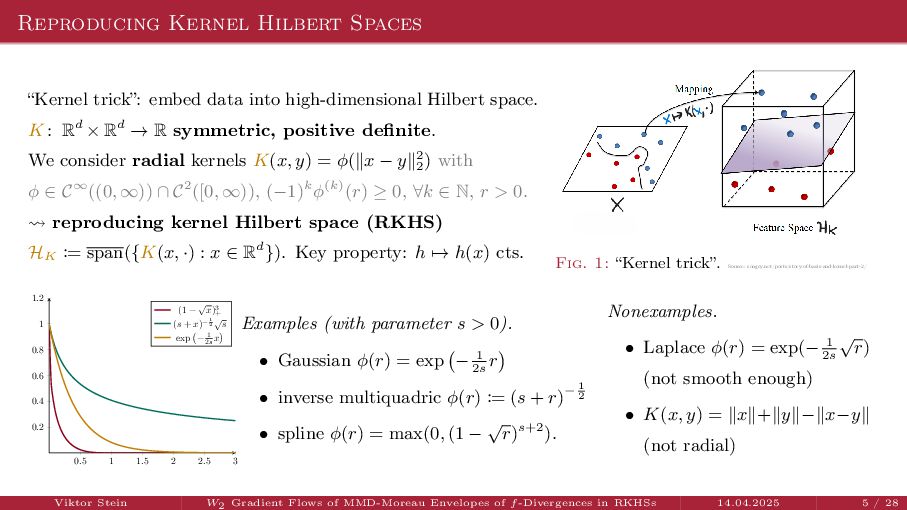
Reproducing Kernel Hilbert Spaces “Kernel trick”: embed data into high-dimensional
Hilbert space. K : Rd × Rd → R symmetric, positive definite. We consider radial kernels K(x, y) = ϕ(∥x − y∥2 2 ) with ϕ ∈ C∞((0, ∞)) ∩ C2([0, ∞)), (−1)kϕ(k)(r) ≥ 0, ∀k ∈ N, r > 0. ⇝ reproducing kernel Hilbert space (RKHS) HK := span({K(x, ·) : x ∈ Rd}). Key property: h → h(x) cts. Fig. 1: “Kernel trick”. Source: songcy.net/posts/story-of-basis-and-kernel-part-2/ 0.5 1 1.5 2 2.5 3 0.2 0.4 0.6 0.8 1 1.2 (1 − √ x)3 + (s + x)− 1 2 √ s exp − 1 2s x Examples (with parameter s > 0). • Gaussian ϕ(r) = exp − 1 2s r • inverse multiquadric ϕ(r) := (s + r)− 1 2 • spline ϕ(r) = max(0, (1 − √ r)s+2). Nonexamples. • Laplace ϕ(r) = exp(− 1 2s √ r) (not smooth enough) • K(x, y) = ∥x∥+∥y∥−∥x−y∥ (not radial) Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 5 / 28 -
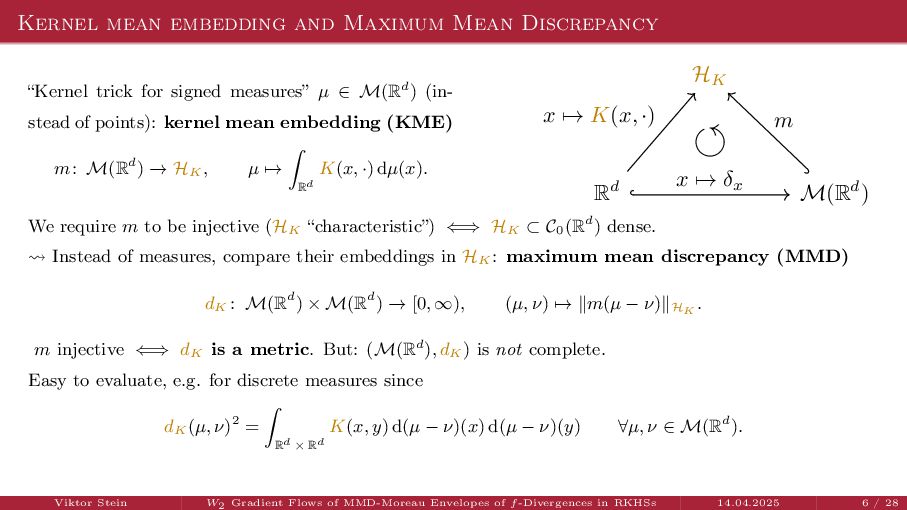
Kernel mean embedding and Maximum Mean Discrepancy “Kernel trick for
signed measures” µ ∈ M(Rd) (in- stead of points): kernel mean embedding (KME) m: M(Rd) → HK , µ → Rd K(x, ·) dµ(x). HK Rd M(Rd) ⟲ x → K(x, ·) x → δx m We require m to be injective (HK “characteristic”) ⇐⇒ HK ⊂ C0 (Rd) dense. ⇝ Instead of measures, compare their embeddings in HK : maximum mean discrepancy (MMD) dK : M(Rd) × M(Rd) → [0, ∞), (µ, ν) → ∥m(µ − ν)∥HK . m injective ⇐⇒ dK is a metric. But: (M(Rd), dK ) is not complete. Easy to evaluate, e.g. for discrete measures since dK (µ, ν)2 = Rd × Rd K(x, y) d(µ − ν)(x) d(µ − ν)(y) ∀µ, ν ∈ M(Rd). Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 6 / 28 -
1. RKHS & MMD 2. Moreau envelopes 3. f-divergences 4.
MMD-Moreau envelopes of f-divergences 5. Wasserstein gradient flow 6. WGF of MMD-Moreau en- velopes of f-divergences -
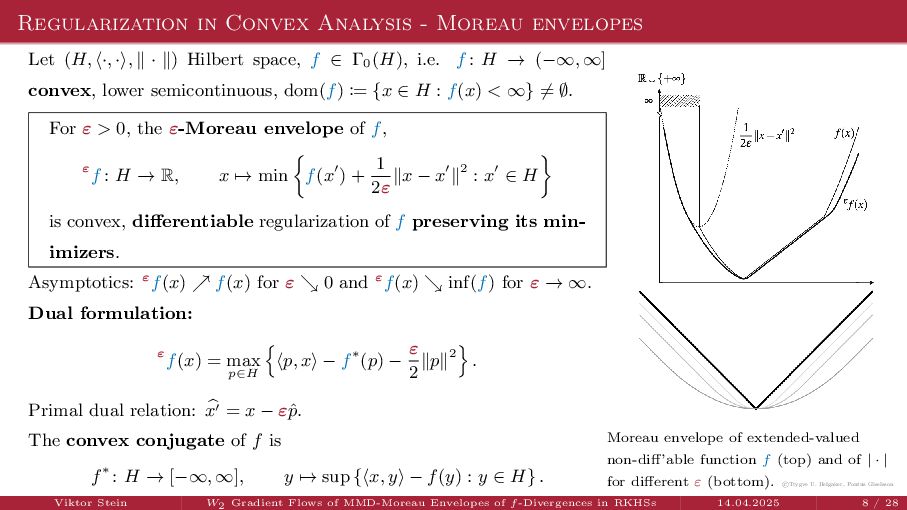
Regularization in Convex Analysis - Moreau envelopes Let (H, ⟨·,
·⟩, ∥ · ∥) Hilbert space, f ∈ Γ0 (H), i.e. f : H → (−∞, ∞] convex, lower semicontinuous, dom(f) := {x ∈ H : f(x) < ∞} ̸= ∅. For ε > 0, the ε-Moreau envelope of f, εf : H → R, x → min f(x′) + 1 2ε ∥x − x′∥2 : x′ ∈ H is convex, differentiable regularization of f preserving its min- imizers. Asymptotics: εf(x) ↗ f(x) for ε ↘ 0 and εf(x) ↘ inf(f) for ε → ∞. Dual formulation: εf(x) = max p∈H ⟨p, x⟩ − f∗(p) − ε 2 ∥p∥2 . Primal dual relation: x′ = x − εˆ p. The convex conjugate of f is f∗ : H → [−∞, ∞], y → sup {⟨x, y⟩ − f(y) : y ∈ H} . Moreau envelope of extended-valued non-diff’able function f (top) and of | · | for different ε (bottom). ©Trygve U. Helgaker, Pontus Giselsson Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 8 / 28 -
1. RKHS & MMD 2. Moreau envelopes 3. f-divergences 4.
MMD-Moreau envelopes of f-divergences 5. Wasserstein gradient flow 6. WGF of MMD-Moreau en- velopes of f-divergences -
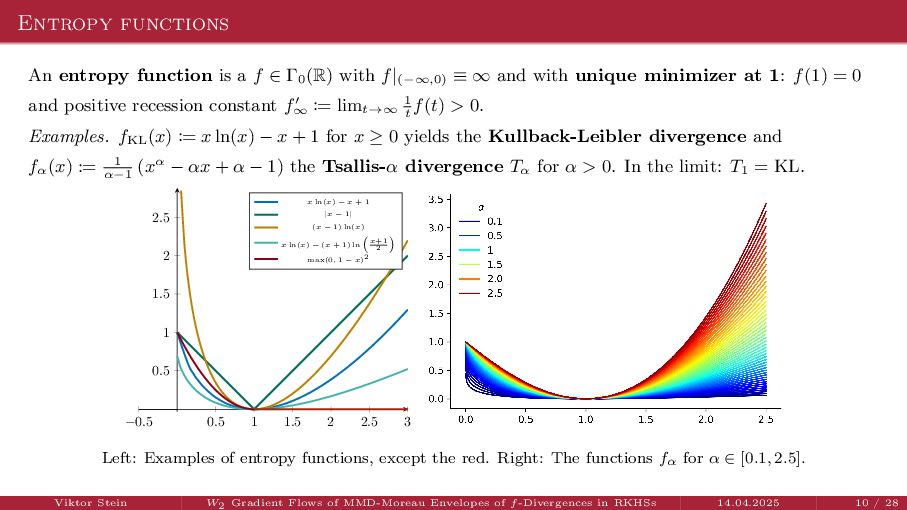
Entropy functions An entropy function is a f ∈ Γ0
(R) with f|(−∞,0) ≡ ∞ and with unique minimizer at 1: f(1) = 0 and positive recession constant f′ ∞ := limt→∞ 1 t f(t) > 0. Examples. fKL (x) := x ln(x) − x + 1 for x ≥ 0 yields the Kullback-Leibler divergence and fα (x) := 1 α−1 (xα − αx + α − 1) the Tsallis-α divergence Tα for α > 0. In the limit: T1 = KL. −0.5 0.5 1 1.5 2 2.5 3 0.5 1 1.5 2 2.5 x ln(x) − x + 1 |x − 1| (x − 1) ln(x) x ln(x) − (x + 1) ln x+1 2 max(0, 1 − x)2 Left: Examples of entropy functions, except the red. Right: The functions fα for α ∈ [0.1, 2.5]. Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 10 / 28 -
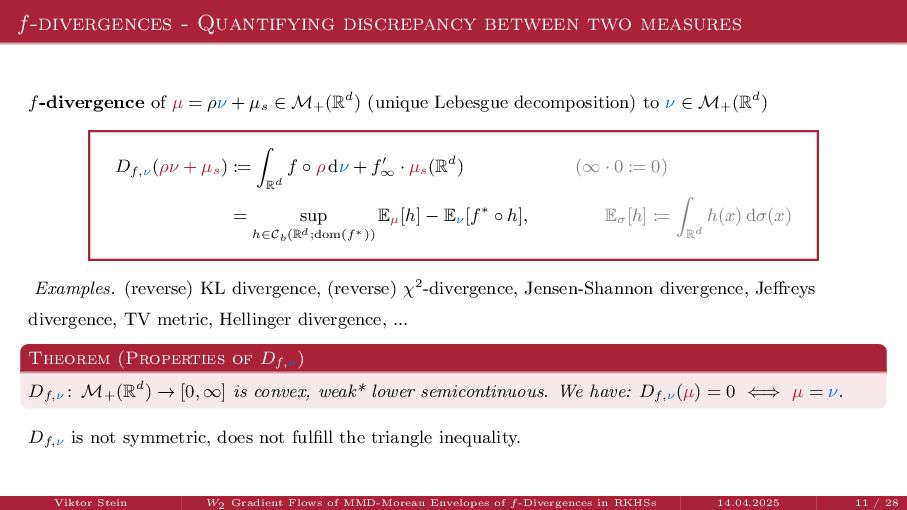
f-divergences - Quantifying discrepancy between two measures f-divergence of µ
= ρν + µs ∈ M+ (Rd) (unique Lebesgue decomposition) to ν ∈ M+ (Rd) Df,ν (ρν + µs ) := Rd f ◦ ρ dν + f′ ∞ · µs (Rd) (∞ · 0 := 0) = sup h∈Cb(Rd;dom(f∗)) E µ [h] − E ν [f∗ ◦ h], E σ [h] := Rd h(x) dσ(x) Examples. (reverse) KL divergence, (reverse) χ2-divergence, Jensen-Shannon divergence, Jeffreys divergence, TV metric, Hellinger divergence, ... Theorem (Properties of Df,ν ) Df,ν : M+ (Rd) → [0, ∞] is convex, weak* lower semicontinuous. We have: Df,ν (µ) = 0 ⇐⇒ µ = ν. Df,ν is not symmetric, does not fulfill the triangle inequality. Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 11 / 28 -
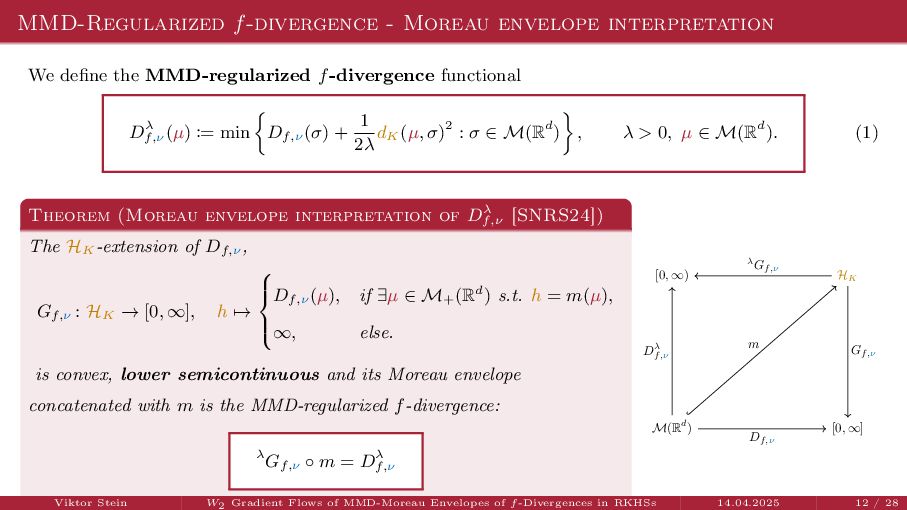
MMD-Regularized f-divergence - Moreau envelope interpretation We define the MMD-regularized
f-divergence functional Dλ f,ν (µ) := min Df,ν (σ) + 1 2λ dK (µ, σ)2 : σ ∈ M(Rd) , λ > 0, µ ∈ M(Rd). (1) Theorem (Moreau envelope interpretation of Dλ f,ν [SNRS24]) The HK -extension of Df,ν , Gf,ν : HK → [0, ∞], h → Df,ν (µ), if ∃µ ∈ M+ (Rd) s.t. h = m(µ), ∞, else. is convex, lower semicontinuous and its Moreau envelope concatenated with m is the MMD-regularized f-divergence: λGf,ν ◦ m = Dλ f,ν [0, ∞) HK M(Rd) [0, ∞] Gf,ν λGf,ν m Df,ν Dλ f,ν Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 12 / 28 -
Properties of Dλ f,ν [SNRS24] • Dual formulation Dλ f,ν
(µ) = max E µ [p] − E ν [f∗ ◦ p] − λ 2 ∥p∥2 HK : p ∈ HK , p ≤ f′ ∞ . (2) ˆ p ∈ HK maximizes (2) ⇐⇒ ˆ g = m(µ) − λˆ p is primal solution. λ 2 ∥ˆ p∥2 HK ≤ Dλ f,ν (µ) reverse PŁ-condition :( ≤ ∥ˆ p∥HK dK (µ, ν) =⇒ ∥ˆ p∥HK ≤ 2 λ dK (µ, ν). • Dλ f,ν is Fréchet differentiable on M(Rd) and its gradient is 1 λ -Lipschitz with respect to dK and ∇Dλ f,ν (µ) = argmax (2). Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 13 / 28 -
Theorem. (Properties of Dλ f,ν) [SNRS24] • Asymptotic regimes: Mosco
resp. pointwise convergence Dλ f,ν → Df,ν λ ↘ 0 and (1 + λ)Dλ f,ν → 1 2 dK (·, ν)2 λ → ∞ • Divergence property: Dλ f,ν (µ) = 0 ⇐⇒ µ = ν. • (µ, ν) → Dλ f,ν (µ) "metrizes" weak convergence (like dK ) on M+ (Rd)-balls. Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 14 / 28 -
1. RKHS & MMD 2. Moreau envelopes 3. f-divergences 4.
MMD-Moreau envelopes of f-divergences 5. Wasserstein gradient flow 6. WGF of MMD-Moreau en- velopes of f-divergences -
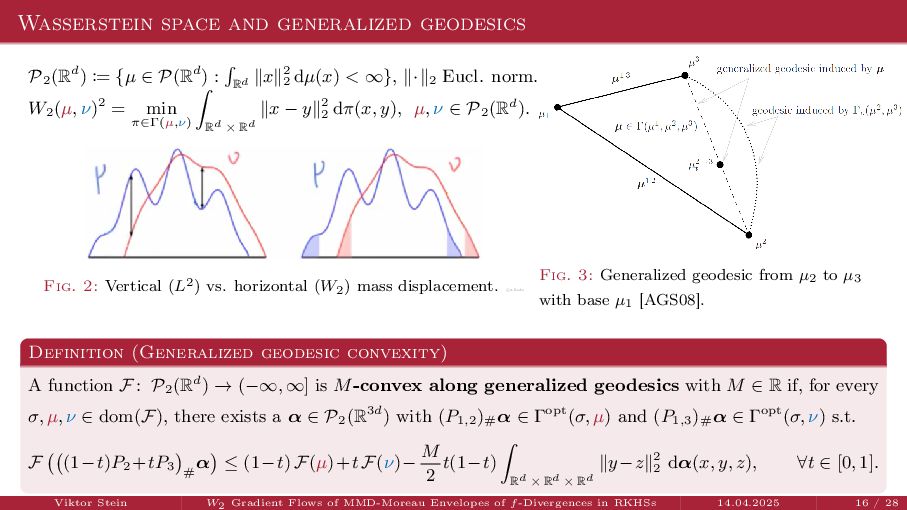
Wasserstein space and generalized geodesics P2 (Rd) := {µ ∈
P(Rd) : Rd ∥x∥2 2 dµ(x) < ∞}, ∥·∥2 Eucl. norm. W2 (µ, ν)2 = min π∈Γ(µ,ν) Rd × Rd ∥x − y∥2 2 dπ(x, y), µ, ν ∈ P2 (Rd). Fig. 2: Vertical (L2) vs. horizontal (W2 ) mass displacement. ©A. Korba Fig. 3: Generalized geodesic from µ2 to µ3 with base µ1 [AGS08]. Definition (Generalized geodesic convexity) A function F : P2 (Rd) → (−∞, ∞] is M-convex along generalized geodesics with M ∈ R if, for every σ, µ, ν ∈ dom(F), there exists a α ∈ P2 (R3d) with (P1,2 )# α ∈ Γopt(σ, µ) and (P1,3 )# α ∈ Γopt(σ, ν) s.t. F (1−t)P2 +tP3 # α ≤ (1−t) F(µ)+t F(ν)− M 2 t(1−t) Rd × Rd × Rd ∥y−z∥2 2 dα(x, y, z), ∀t ∈ [0, 1]. Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 16 / 28 -
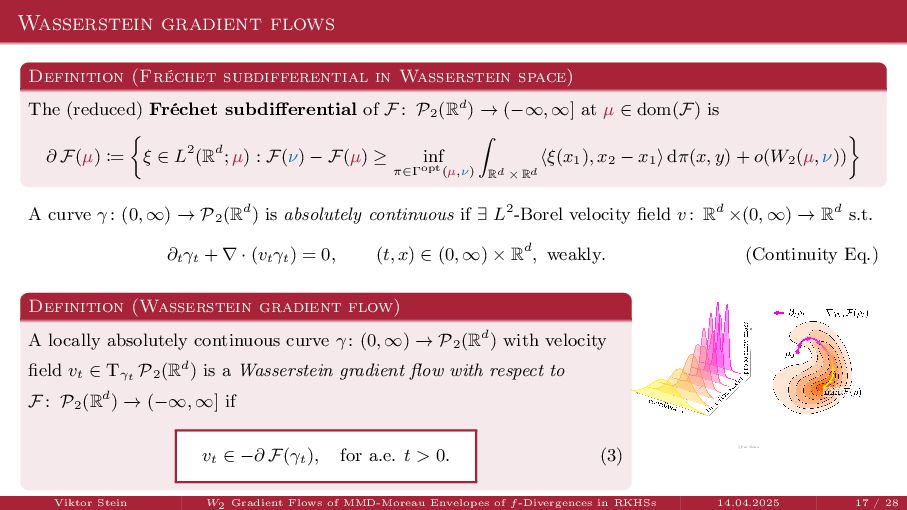
Wasserstein gradient flows Definition (Fréchet subdifferential in Wasserstein space) The
(reduced) Fréchet subdifferential of F : P2 (Rd) → (−∞, ∞] at µ ∈ dom(F) is ∂ F(µ) := ξ ∈ L2(Rd; µ) : F(ν) − F(µ) ≥ inf π∈Γopt(µ,ν) Rd × Rd ⟨ξ(x1 ), x2 − x1 ⟩ dπ(x, y) + o(W2 (µ, ν)) A curve γ : (0, ∞) → P2 (Rd) is absolutely continuous if ∃ L2-Borel velocity field v : Rd ×(0, ∞) → Rd s.t. ∂t γt + ∇ · (vt γt ) = 0, (t, x) ∈ (0, ∞) × Rd, weakly. (Continuity Eq.) Definition (Wasserstein gradient flow) A locally absolutely continuous curve γ : (0, ∞) → P2 (Rd) with velocity field vt ∈ Tγt P2 (Rd) is a Wasserstein gradient flow with respect to F : P2 (Rd) → (−∞, ∞] if vt ∈ −∂ F(γt ), for a.e. t > 0. (3) ©Petr Mokrov Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 17 / 28 -
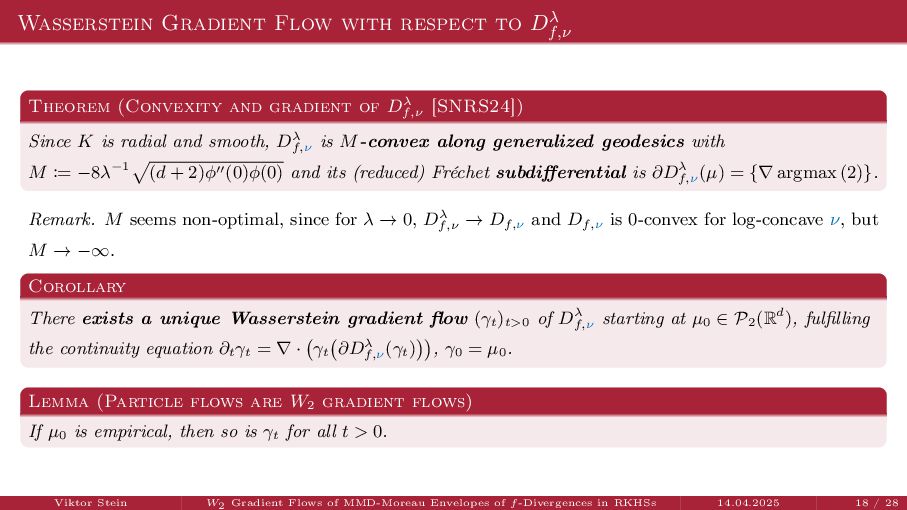
Wasserstein Gradient Flow with respect to Dλ f,ν Theorem (Convexity
and gradient of Dλ f,ν [SNRS24]) Since K is radial and smooth, Dλ f,ν is M-convex along generalized geodesics with M := −8λ−1 (d + 2)ϕ′′(0)ϕ(0) and its (reduced) Fréchet subdifferential is ∂Dλ f,ν (µ) = {∇ argmax (2)}. Remark. M seems non-optimal, since for λ → 0, Dλ f,ν → Df,ν and Df,ν is 0-convex for log-concave ν, but M → −∞. Corollary There exists a unique Wasserstein gradient flow (γt )t>0 of Dλ f,ν starting at µ0 ∈ P2 (Rd), fulfilling the continuity equation ∂t γt = ∇ · γt ∂Dλ f,ν (γt ) , γ0 = µ0 . Lemma (Particle flows are W2 gradient flows) If µ0 is empirical, then so is γt for all t > 0. Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 18 / 28 -
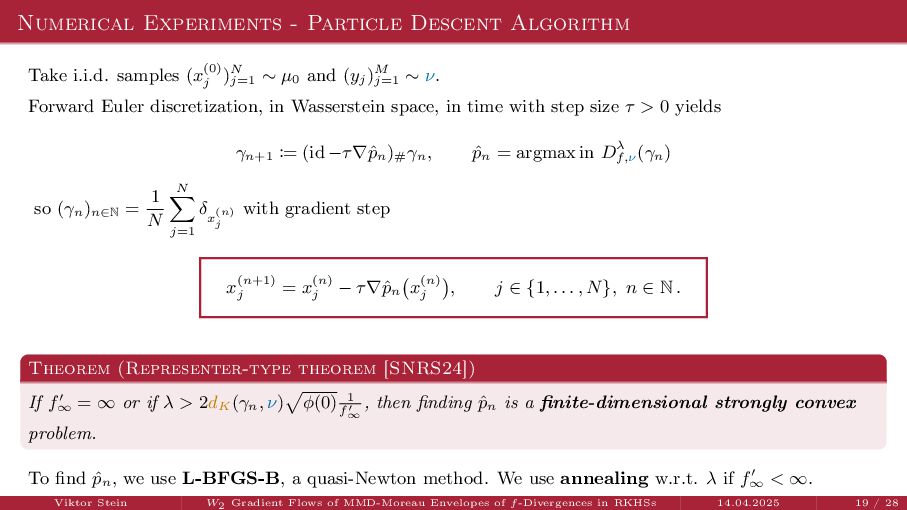
Numerical Experiments - Particle Descent Algorithm Take i.i.d. samples (x(0)
j )N j=1 ∼ µ0 and (yj )M j=1 ∼ ν. Forward Euler discretization, in Wasserstein space, in time with step size τ > 0 yields γn+1 := (id −τ∇ˆ pn )# γn , ˆ pn = argmax in Dλ f,ν (γn ) so (γn )n∈N = 1 N N j=1 δ x(n) j with gradient step x(n+1) j = x(n) j − τ∇ˆ pn x(n) j , j ∈ {1, . . . , N}, n ∈ N . Theorem (Representer-type theorem [SNRS24]) If f′ ∞ = ∞ or if λ > 2dK (γn , ν) ϕ(0) 1 f′ ∞ , then finding ˆ pn is a finite-dimensional strongly convex problem. To find ˆ pn , we use L-BFGS-B, a quasi-Newton method. We use annealing w.r.t. λ if f′ ∞ < ∞. Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 19 / 28 -
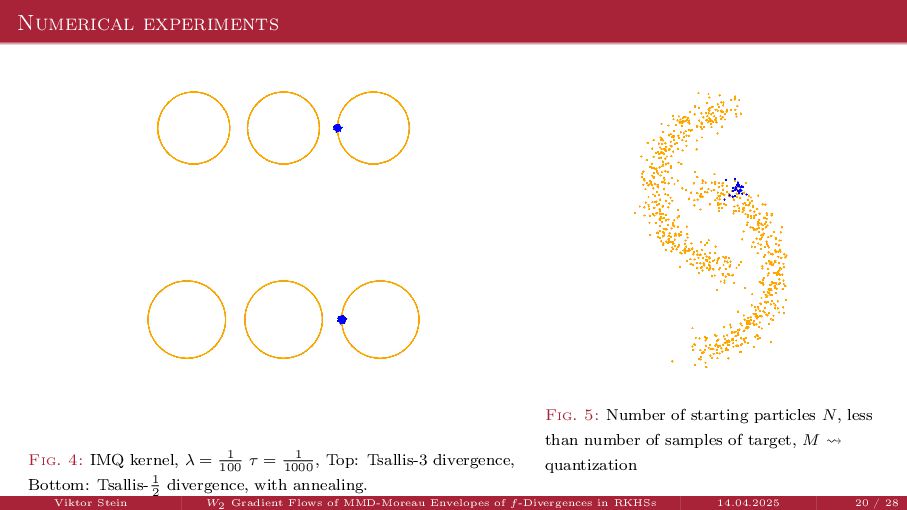
Numerical experiments Fig. 4: IMQ kernel, λ = 1 100
τ = 1 1000 , Top: Tsallis-3 divergence, Bottom: Tsallis- 1 2 divergence, with annealing. Fig. 5: Number of starting particles N, less than number of samples of target, M ⇝ quantization Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 20 / 28 -
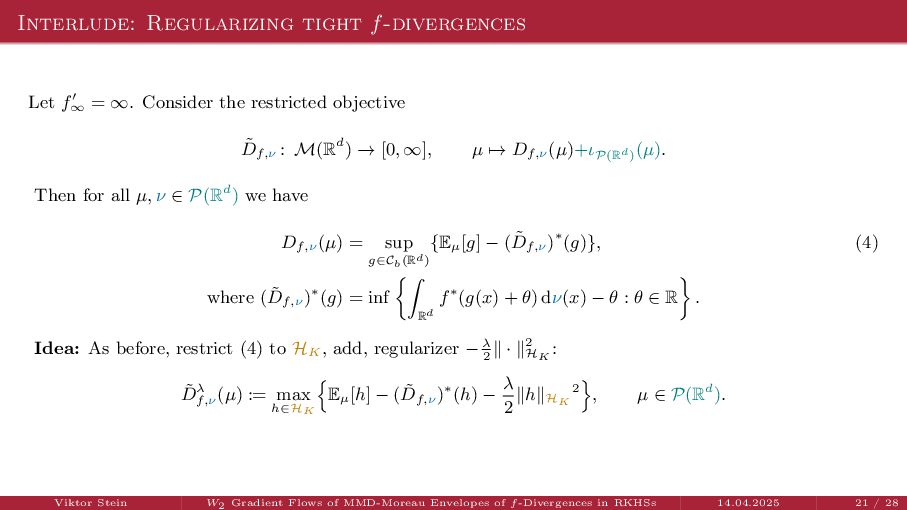
Interlude: Regularizing tight f-divergences Let f′ ∞ = ∞. Consider
the restricted objective ˜ Df,ν : M(Rd) → [0, ∞], µ → Df,ν (µ)+ιP(Rd) (µ). Then for all µ, ν ∈ P(Rd) we have Df,ν (µ) = sup g∈Cb(Rd) {E µ [g] − ( ˜ Df,ν )∗(g)}, (4) where ( ˜ Df,ν )∗(g) = inf Rd f∗(g(x) + θ) dν(x) − θ : θ ∈ R . Idea: As before, restrict (4) to HK , add, regularizer −λ 2 ∥ · ∥2 HK : ˜ Dλ f,ν (µ) := max h∈HK E µ [h] − ( ˜ Df,ν )∗(h) − λ 2 ∥h∥HK 2 , µ ∈ P(Rd). Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 21 / 28 -
Theorem (Regularized tight f-divergence [SNRS’25]) The function ˜ Gf,ν :
HK → [0, ∞], h → Df,ν (µ), if ∃µ ∈ P(Rd) such that h = mµ , ∞, else, is lower semicontinuous and ˜ Gf,ν ∈ Γ0 (HK ). We have ˜ Df,ν = ˜ Gf,ν ◦ m and ˜ Dλ f,ν = ˜ Gλ f,ν ◦ m. The primal formulation is ˜ Dλ f,ν (µ) = min σ∈P(Rd) Df,ν (σ) + 1 2λ dK (σ, ν)2 . Same gradient estimates & primal dual relationship hold. -
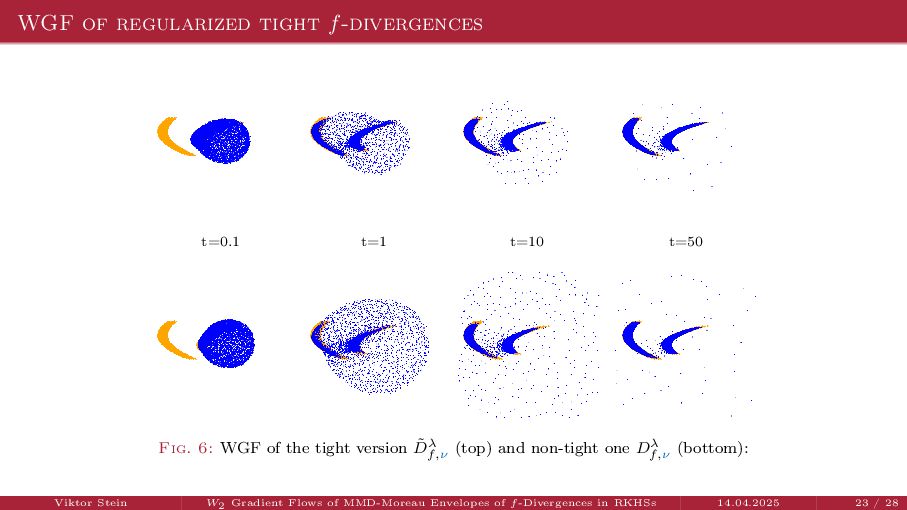
WGF of regularized tight f-divergences t=0.1 t=1 t=10 t=50 Fig.
6: WGF of the tight version ˜ Dλ f,ν (top) and non-tight one Dλ f,ν (bottom): Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 23 / 28 -
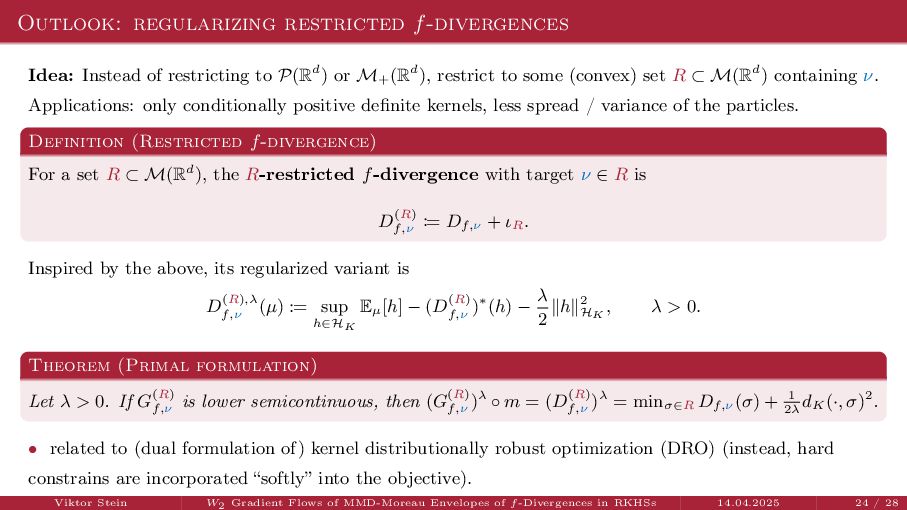
Outlook: regularizing restricted f-divergences Idea: Instead of restricting to P(Rd)
or M+ (Rd), restrict to some (convex) set R ⊂ M(Rd) containing ν. Applications: only conditionally positive definite kernels, less spread / variance of the particles. Definition (Restricted f-divergence) For a set R ⊂ M(Rd), the R-restricted f-divergence with target ν ∈ R is D(R) f,ν := Df,ν + ιR . Inspired by the above, its regularized variant is D(R),λ f,ν (µ) := sup h∈HK E µ [h] − (D(R) f,ν )∗(h) − λ 2 ∥h∥2 HK , λ > 0. Theorem (Primal formulation) Let λ > 0. If G(R) f,ν is lower semicontinuous, then (G(R) f,ν )λ ◦ m = (D(R) f,ν )λ = minσ∈R Df,ν (σ) + 1 2λ dK (·, σ)2. • related to (dual formulation of) kernel distributionally robust optimization (DRO) (instead, hard constrains are incorporated “softly” into the objective). Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 24 / 28 -
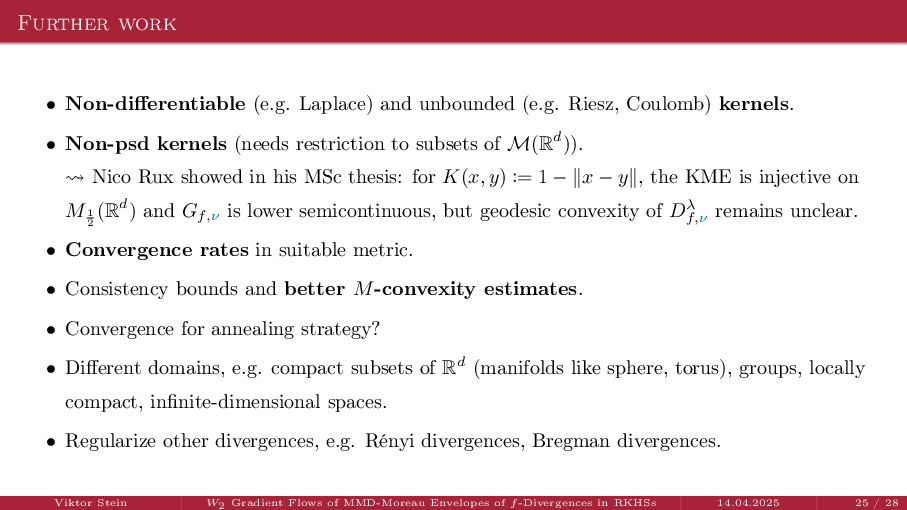
Further work • Non-differentiable (e.g. Laplace) and unbounded (e.g. Riesz,
Coulomb) kernels. • Non-psd kernels (needs restriction to subsets of M(Rd)). ⇝ Nico Rux showed in his MSc thesis: for K(x, y) := 1 − ∥x − y∥, the KME is injective on M1 2 (Rd) and Gf,ν is lower semicontinuous, but geodesic convexity of Dλ f,ν remains unclear. • Convergence rates in suitable metric. • Consistency bounds and better M-convexity estimates. • Convergence for annealing strategy? • Different domains, e.g. compact subsets of Rd (manifolds like sphere, torus), groups, locally compact, infinite-dimensional spaces. • Regularize other divergences, e.g. Rényi divergences, Bregman divergences. Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 25 / 28 -
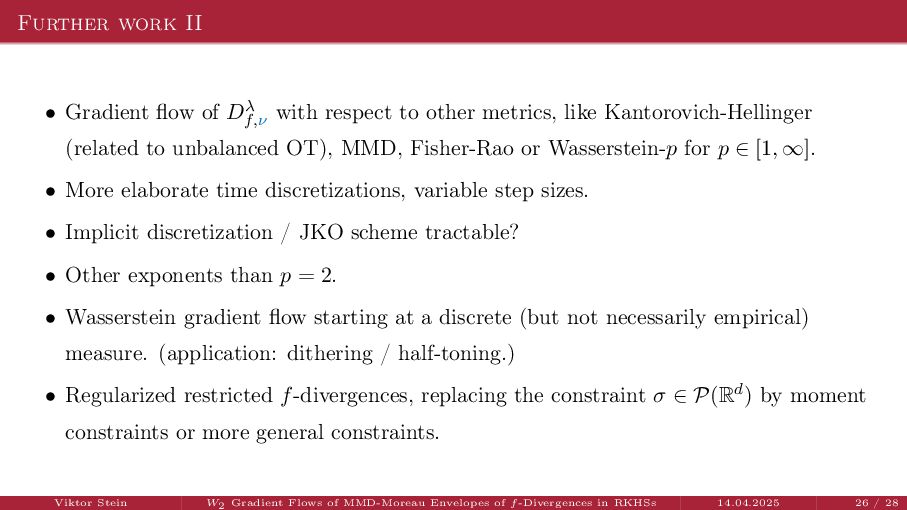
Further work II • Gradient flow of Dλ f,ν with
respect to other metrics, like Kantorovich-Hellinger (related to unbalanced OT), MMD, Fisher-Rao or Wasserstein-p for p ∈ [1, ∞]. • More elaborate time discretizations, variable step sizes. • Implicit discretization / JKO scheme tractable? • Other exponents than p = 2. • Wasserstein gradient flow starting at a discrete (but not necessarily empirical) measure. (application: dithering / half-toning.) • Regularized restricted f-divergences, replacing the constraint σ ∈ P(Rd) by moment constraints or more general constraints. Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 26 / 28 -
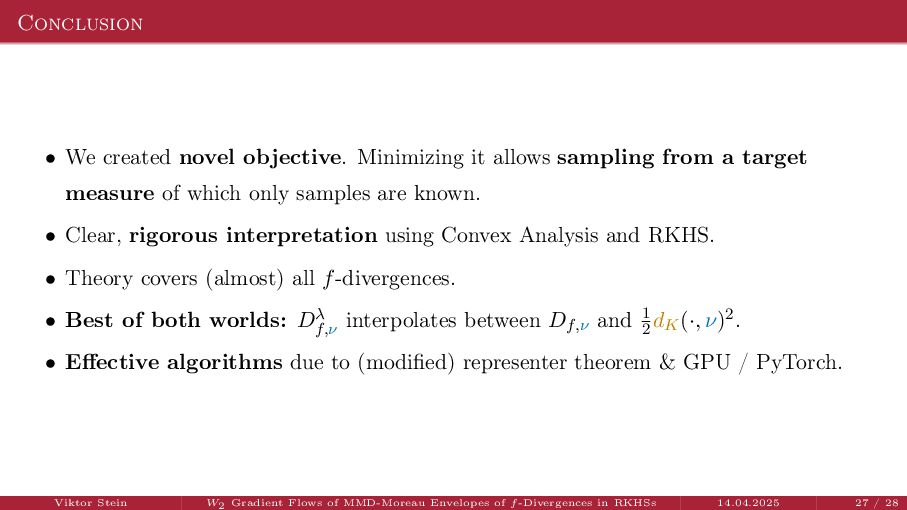
Conclusion • We created novel objective. Minimizing it allows sampling
from a target measure of which only samples are known. • Clear, rigorous interpretation using Convex Analysis and RKHS. • Theory covers (almost) all f-divergences. • Best of both worlds: Dλ f,ν interpolates between Df,ν and 1 2 dK (·, ν)2. • Effective algorithms due to (modified) representer theorem & GPU / PyTorch. Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 27 / 28 -
Thank you for your attention! I am happy to take
any questions. Paper link: arxiv.org/abs/2402.04613 My website: viktorajstein.github.io [AGS08, BDK+22, GAG21, HWAH24, KYSZ23, LMSS20, LMS17, Ter21] Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 28 / 28 -
References I [AGS08] Luigi Ambrosio, Nicola Gigli, and Giuseppe Savaré,
Gradient flows: in metric spaces and in the space of probability measures, 2 ed., Springer Science & Business Media, 2008. [BDK+22] Jeremiah Birrell, Paul Dupuis, Markos A. Katsoulakis, Yannis Pantazis, and Luc Rey-Bellet, (f, Γ)-divergences: Interpolating between f-divergences and integral probability metrics, J. Mach. Learn. Res. 23 (2022), no. 39, 1–70. [GAG21] Pierre Glaser, Michael Arbel, and Arthur Gretton, KALE flow: A relaxed KL gradient flow for probabilities with disjoint support, Advances in Neural Information Processing Systems (Virtual event), vol. 34, 6–14 Dec 2021, pp. 8018–8031. [HWAH24] J. Hertrich, C. Wald, F. Altekrüger, and P. Hagemann, Generative sliced MMD flows with Riesz kernels, International Conference on Learning Representations (ICLR) (Vienna, Austria), 7 – 11 May 2024. Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 1 / 3 -
References II [KYSZ23] H. Kremer, Nemmour Y., B. Schölkopf, and
J.-J. Zhu, Estimation beyond data reweighting: kernel methods of moments, ICML’23: Proceedings of the 40th International Conference on Machine Learning (Honolulu, Hawaii, USA), vol. 202, July 23 - 29 2023, p. 17745–17783. [LMS17] Matthias Liero, Alexander Mielke, and Giuseppe Savaré, Optimal entropy-transport problems and a new Hellinger–Kantorovich distance between positive measures, Invent. Math. 211 (2017), no. 3, 969–1117. [LMSS20] Hugo Leclerc, Quentin Mérigot, Filippo Santambrogio, and Federico Stra, Lagrangian discretization of crowd motion and linear diffusion, SIAM J. Numer. Anal. 58 (2020), no. 4, 2093–2118. MR 4123686 [Ter21] Dávid Terjék, Moreau-Yosida f-divergences, International Conference on Machine Learning (ICML) (Virtual event), PMLR, Jul 18–24 2021, pp. 10214–10224. Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 2 / 3 -
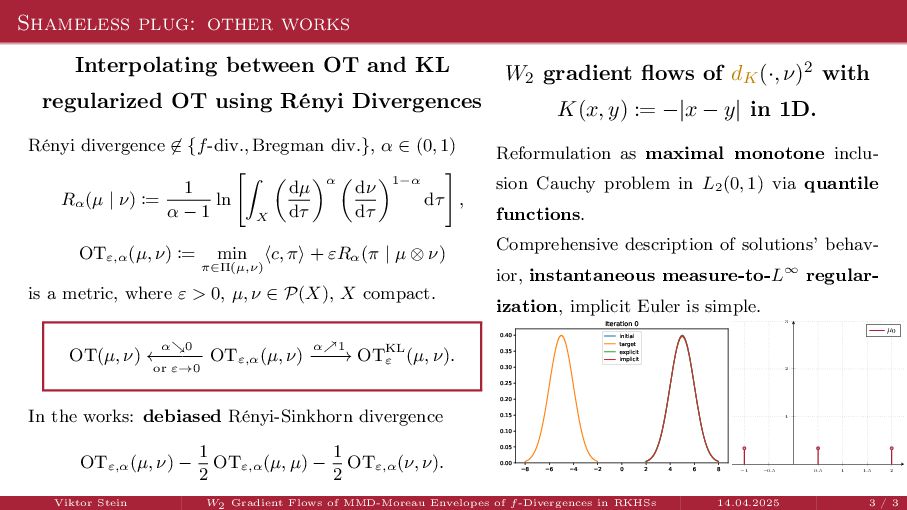
Shameless plug: other works Interpolating between OT and KL regularized
OT using Rényi Divergences Rényi divergence ̸∈ {f-div., Bregman div.}, α ∈ (0, 1) Rα (µ | ν) := 1 α − 1 ln X dµ dτ α dν dτ 1−α dτ , OTε,α (µ, ν) := min π∈Π(µ,ν) ⟨c, π⟩ + εRα (π | µ ⊗ ν) is a metric, where ε > 0, µ, ν ∈ P(X), X compact. OT(µ, ν) α↘0 ← − − − − or ε→0 OTε,α (µ, ν) α↗1 − − − → OTKL ε (µ, ν). In the works: debiased Rényi-Sinkhorn divergence OTε,α (µ, ν) − 1 2 OTε,α (µ, µ) − 1 2 OTε,α (ν, ν). W2 gradient flows of dK (·, ν)2 with K(x, y) := −|x − y| in 1D. Reformulation as maximal monotone inclu- sion Cauchy problem in L2 (0, 1) via quantile functions. Comprehensive description of solutions’ behav- ior, instantaneous measure-to-L∞ regular- ization, implicit Euler is simple. Viktor Stein W2 Gradient Flows of MMD-Moreau Envelopes of f-Divergences in RKHSs 14.04.2025 3 / 3 −1 −0.5 0.5 1 1.5 2 1 2 3 µ0 8 6 4 2 0 2 4 6 8 0.00 0.05 0.10 0.15 0.20 0.25 0.30 0.35 0.40 Iteration 0 initial target explicit implicit
 viktorajstein
 beale
 ftakahashi
 enochan
 shibuiwilliam
 hellosct1
 taniai
 youten622
 institutdelelevage
 tkng
 kzmssk
 yukiar
 watany
 bkeepers
 nonsquared
 soudai
 akihiro_kokubo
 palkan
 jct
 apolaine
 pedronauck
 reverentgeek
 productmarketing
 orderedlist