Share
Peter Mika - Making the Web searchable
The key idea of the Semantic Web is to make information on the Web easily consumable by machines. As machines start to understand web pages as sources of data that can be easily combined with other public data on the Web, the promise is that search on the Web will move well beyond the current paradigm of retrieving pages by keywords. Instead, search engines will start to answer complex queries based on the cumulative knowledge of the Web.
In this presentation, we overview the basic set of technologies that can be used to annotate web pages so that they can be processed by data-aware search engines. In particular, we discuss the RDFa and microdata standards of the W3C designed for marking up data in HTML pages. We look at the ways in which this information is currently used by search engines, including the latest schema.org collaboration between Bing, Google, and Yahoo!, which provides a basic set of vocabulary items understood by all three major search engines on the Web.
Web Directions
Transcript
59 slides
-
Making the Web Searchable Peter Mika Senior Researcher and Data
Architect Yahoo! Inc. -
- 2 - Agenda • Web Directions – Convergence of
Search and Online Media • Semantic technologies (th)at work – Semantics for search • RDFa, microdata – Semantics for data integration • RDF, OWL, SPARQL • Take home: use what works! -
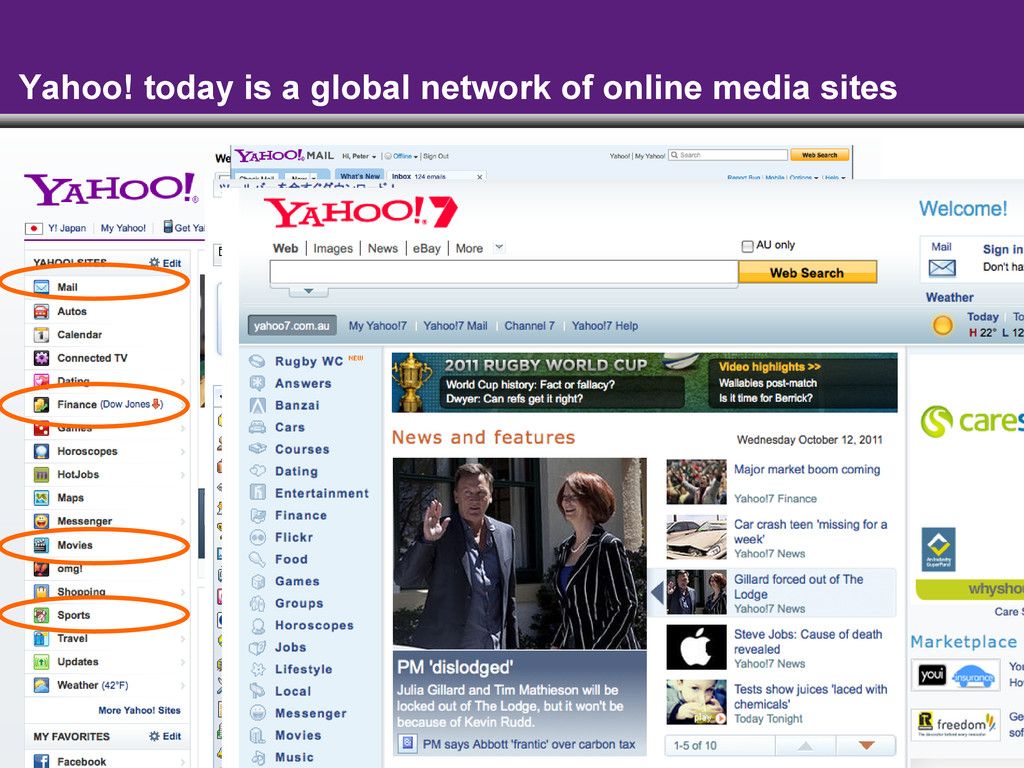
- 5 - Yahoo! today is a global network of
online media sites -
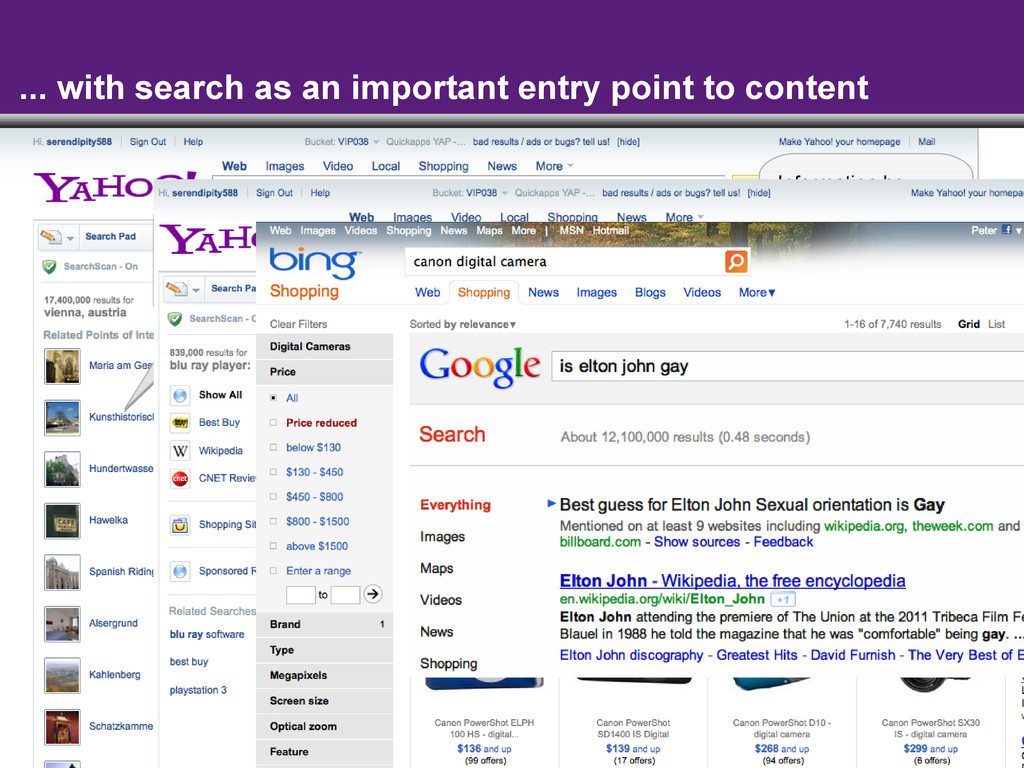
- 6 - Information box with content from and links
to Yahoo! Travel ... with search as an important entry point to content Points of interest in Vienna, Austria Since Aug, 2010, ‘regular’ search results are ‘Powered by Bing’ Shopping results from Yahoo! Shopping -
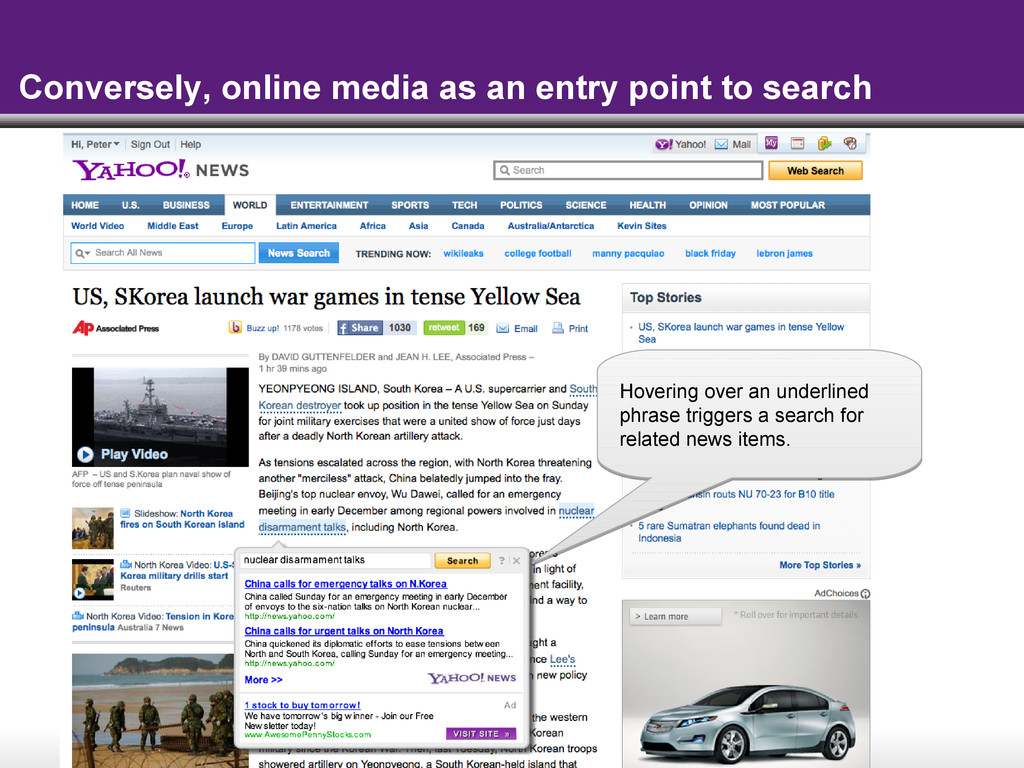
- 7 - Conversely, online media as an entry point
to search Hovering over an underlined phrase triggers a search for related news items. -
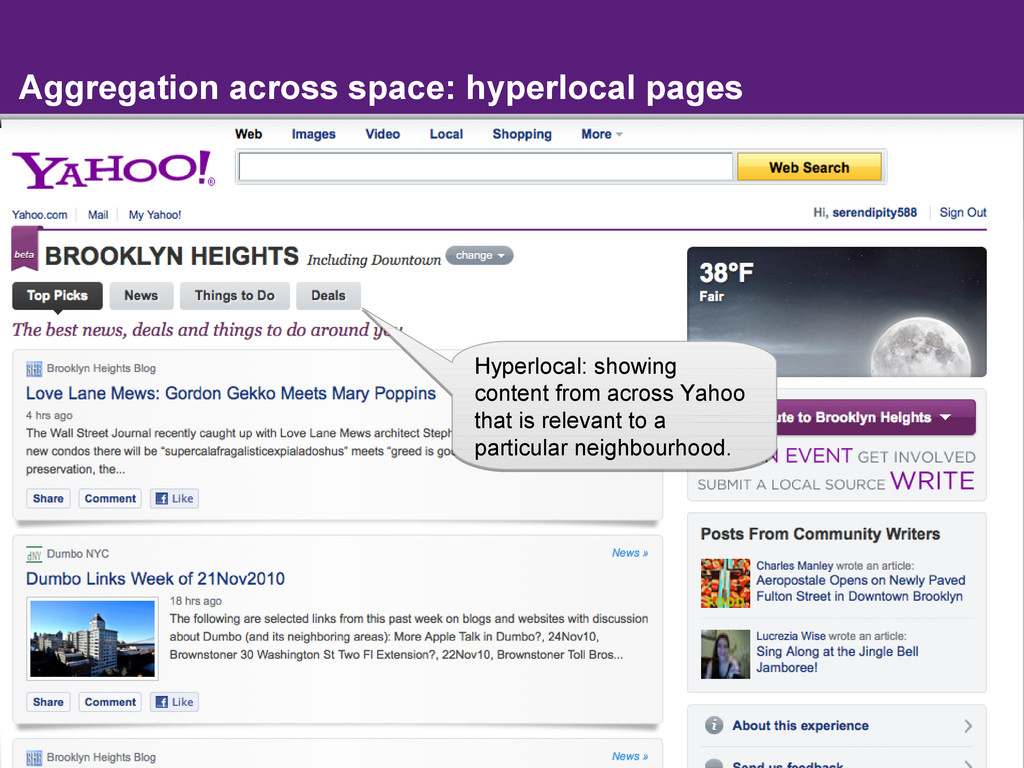
- 8 - Aggregation across space: hyperlocal pages Hyperlocal: showing
content from across Yahoo that is relevant to a particular neighbourhood. -
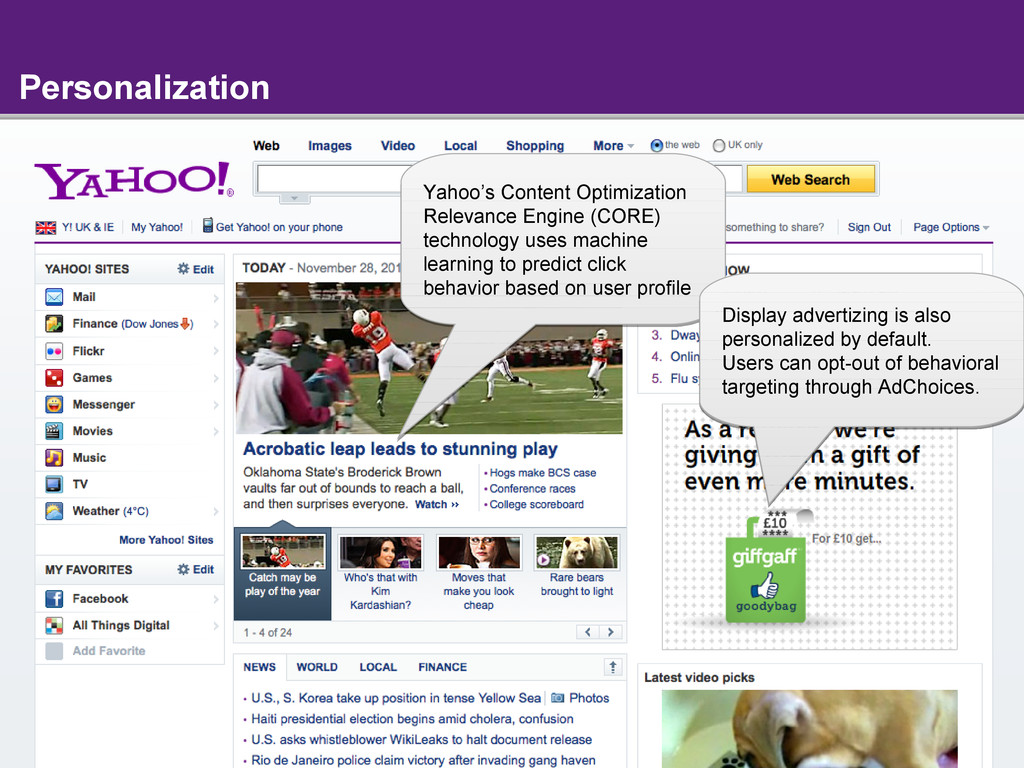
- 10 - Personalization Yahoo’s Content Optimization Relevance Engine (CORE)
technology uses machine learning to predict click behavior based on user profile Display advertizing is also personalized by default. Users can opt-out of behavioral targeting through AdChoices. -
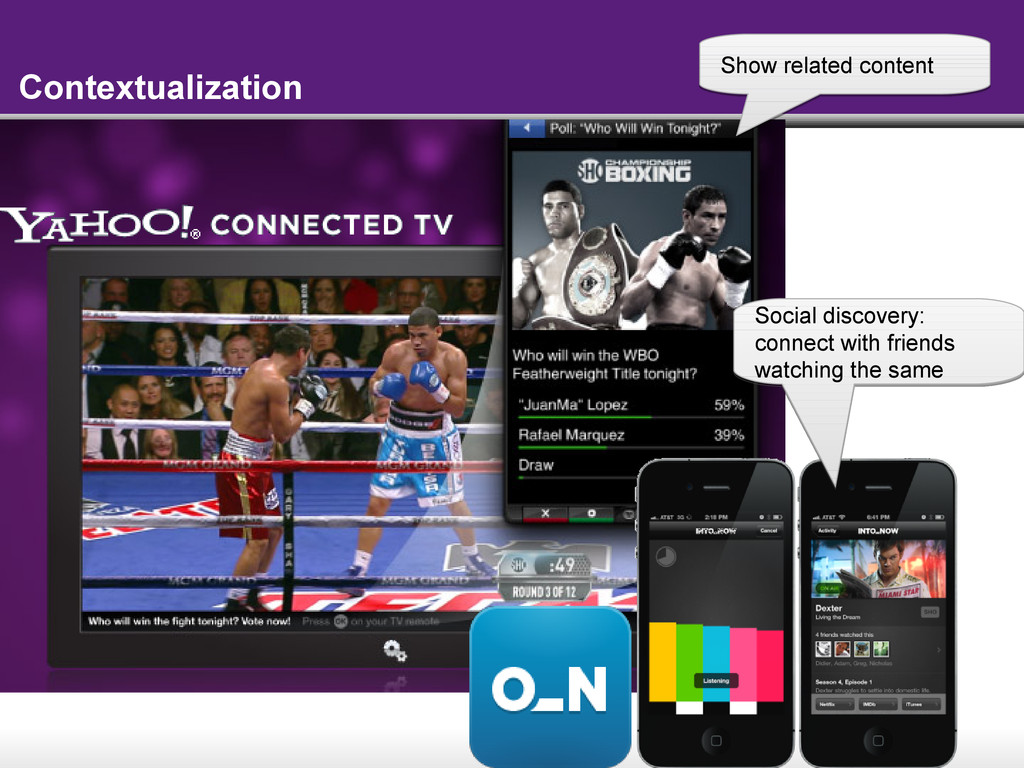
- 11 - Contextualization Show related content Social discovery: connect
with friends watching the same -
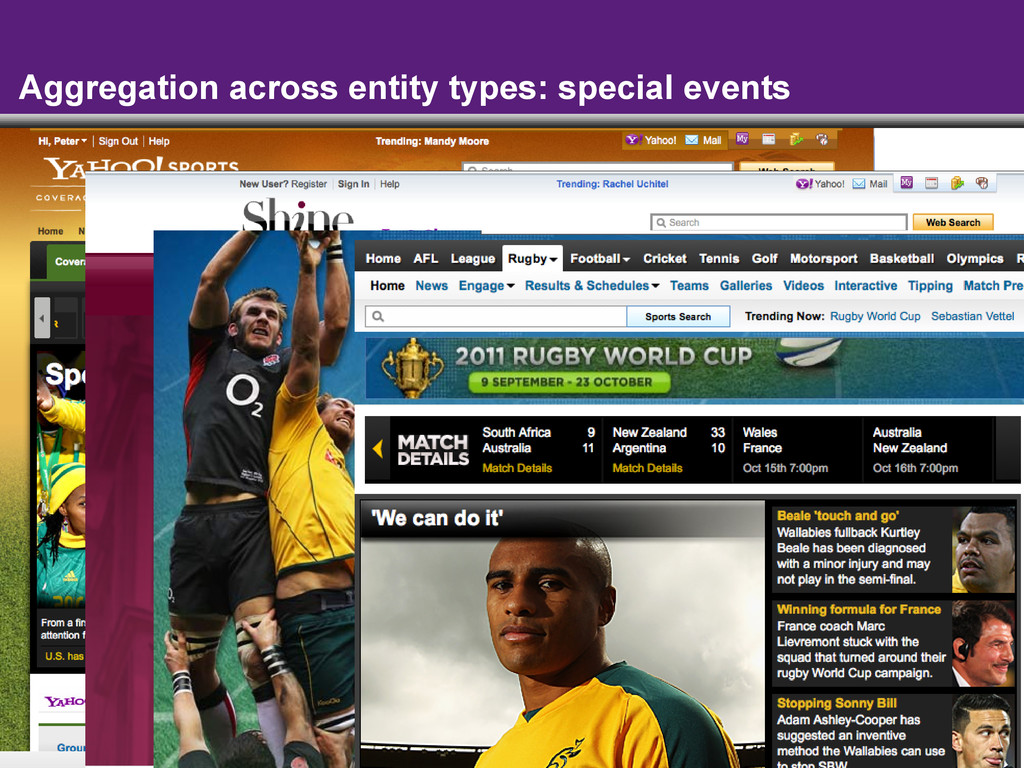
- 12 - Convergence of search and online media •
Complex answers in search – Using structured data, not just text – Search over owned content and the best of the Web • Aggregation – Content aggregation around events, persons, other entities – From creating topic pages to creating entire new websites • Personalization and contextualization – Understand user interests at a fine grained level – Build and carry user profiles across search and media • Common to these is a need for a more advanced understanding of the Web and our content -
- 15 - State of Search • Improvements in search
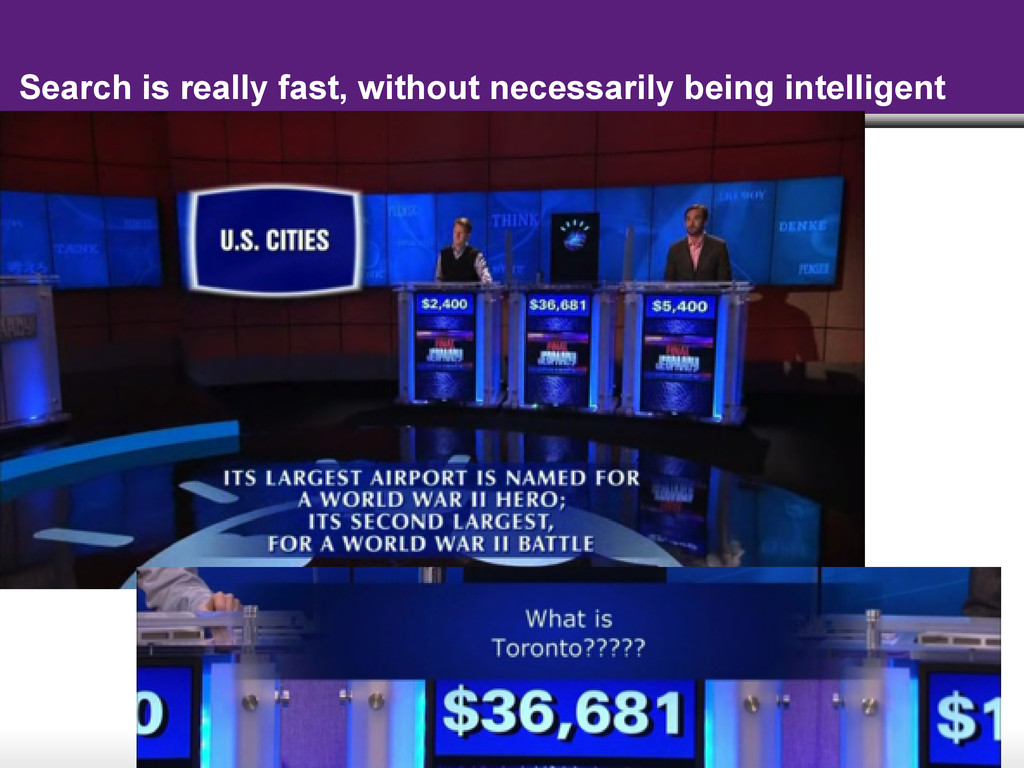
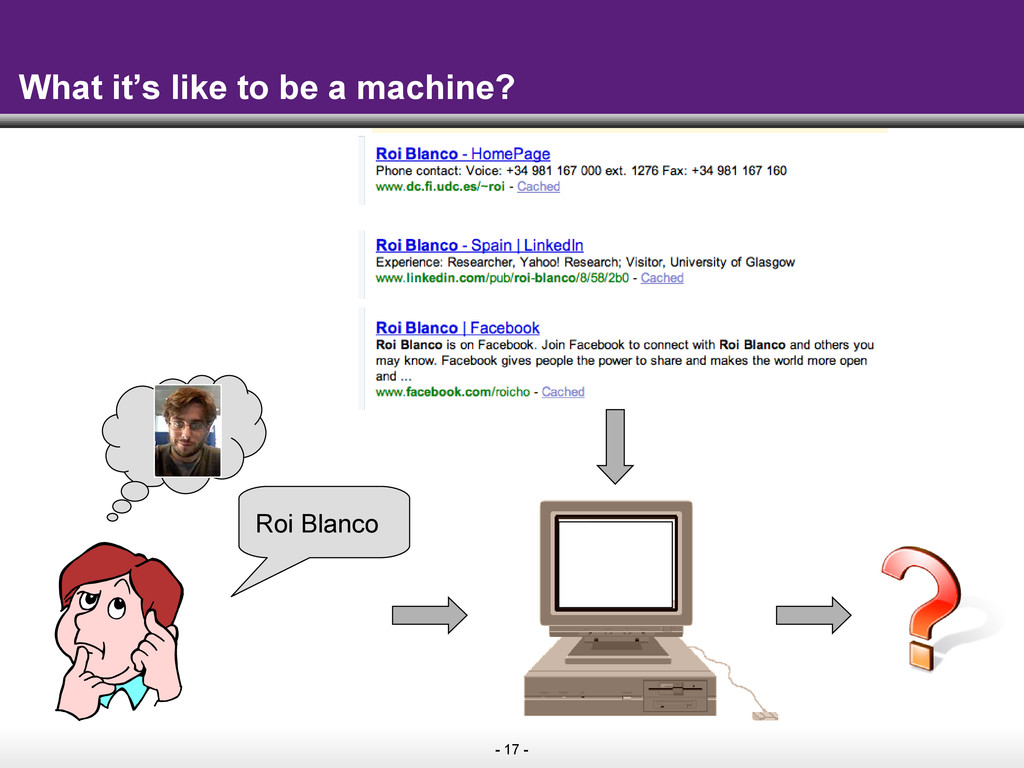
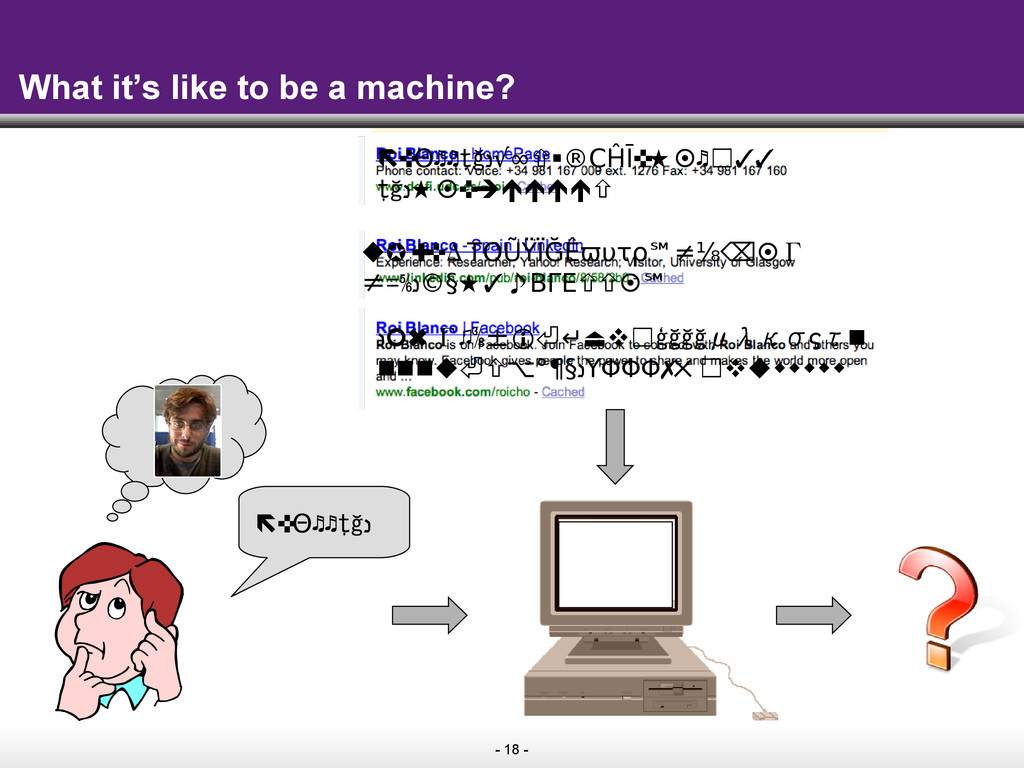
are harder and harder to come by – Machine learning using hundreds of signals • From text to the web graph – Heavy investment in computational power • e.g. real-time indexing and instant search • Remaining challenges are not computational, but in modeling human understanding – A machine is intelligent if it reasons and acts the way we would – But could Watson explain why the answer is Toronto? • How do we teach the computer about our world? – How do we give meaning to documents and data? -
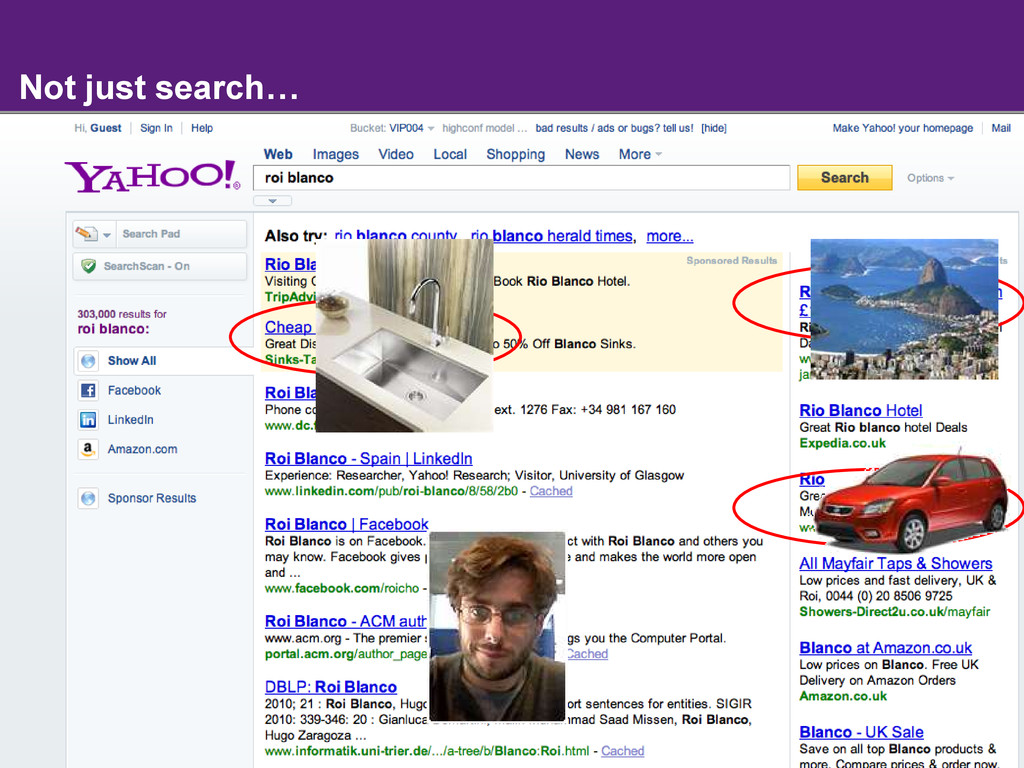
- 17 - What it’s like to be a machine?
Roi Blanco -
- 18 - What it’s like to be a machine?
(Θ♬♬ţğ (Θ♬♬ţğ √∞ ®ÇĤĪ(5 ♬☐ ţğ5 ( 7 &(ΔΤΟŨŸÏĞÊϖυτρ℠≠⅛⌫Γ ≠=⅚ ©§ 5 ♪ΒΓΕ℠ " Γ♫⅜±⏎↵⏏☐ģğğğμλκσςτ ⏎⌥°¶§ ΥΦΦΦ #! ☐ -
- 19 - If machines are dumb, how to make
their job easier? • HTML is intended for human consumption – A mix of text, data and styling • Let’s make it easier to process for machines – Languages to publish data in HTML • Agree between publishers and search engines on the meaning of certain symbols (ontologies) • e.g. ⏎ ¥ ⅙ means that this page describes a Person – Annotate HTML pages using these symbols – (This is just an example… the actual markup is human readable) • For data in particular, agree on what the types of objects are in the world, and what their attributes are – e.g. between §℗ and §⌥⌘ is the age of the Person • Leverage this understanding for more precise matching and ranking -
- 20 - Enter the Semantic Web • Sharing information
across the Web – Publish data in standard formats (RDF, RDFa) – Share the meaning using powerful, logic-based languages (OWL, RIF) – Query using standard languages and protocols (HTTP, SPARQL) • Two main forms of publishing – Linked Data • Data published as RDF documents linked to other RDF documents and/or using SPARQL end-points • Community effort to re-publish large public datasets (e.g. Dbpedia, open government data) – Embedding metadata in HTML pages • Preferred by search engines that already process HTML pages -
- 21 - History of metadata in HTML • 1995:
HTML meta tags • 1998: RDF/XML – RDF/XML in HTML – RDF linked from HTML • 2003: Web 2.0 – Tagging, machine tags – Microformats • 2005: eRDF • 2008: RDFa 1.0 • 2011: RDFa 1.1, Microdata -
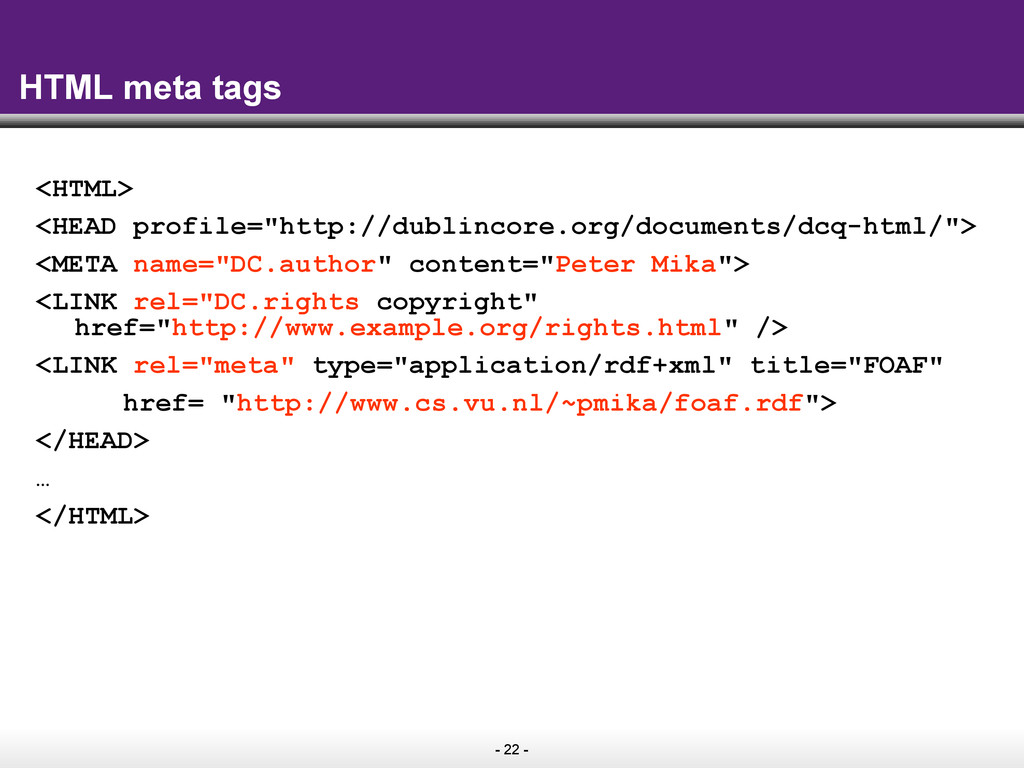
- 22 - HTML meta tags <HTML> <HEAD profile="http://dublincore.org/documents/dcq-html/"> <META
name="DC.author" content="Peter Mika"> <LINK rel="DC.rights copyright" href="http://www.example.org/rights.html" /> <LINK rel="meta" type="application/rdf+xml" title="FOAF" href= "http://www.cs.vu.nl/~pmika/foaf.rdf"> </HEAD> … </HTML> -
- 23 - Microformats (μf) • Agreements on the way
to encode describe certain objects in HTML (persons, events, recipes…) – Reuse of semantic-bearing HTML elements, e.g. class – Based on existing standards, e.g. hCard – Minimal: small number of types, most common attributes • Community centered around microformats.org – Centralized process, but not a formal standards body – Wiki for specifications, mailing list -
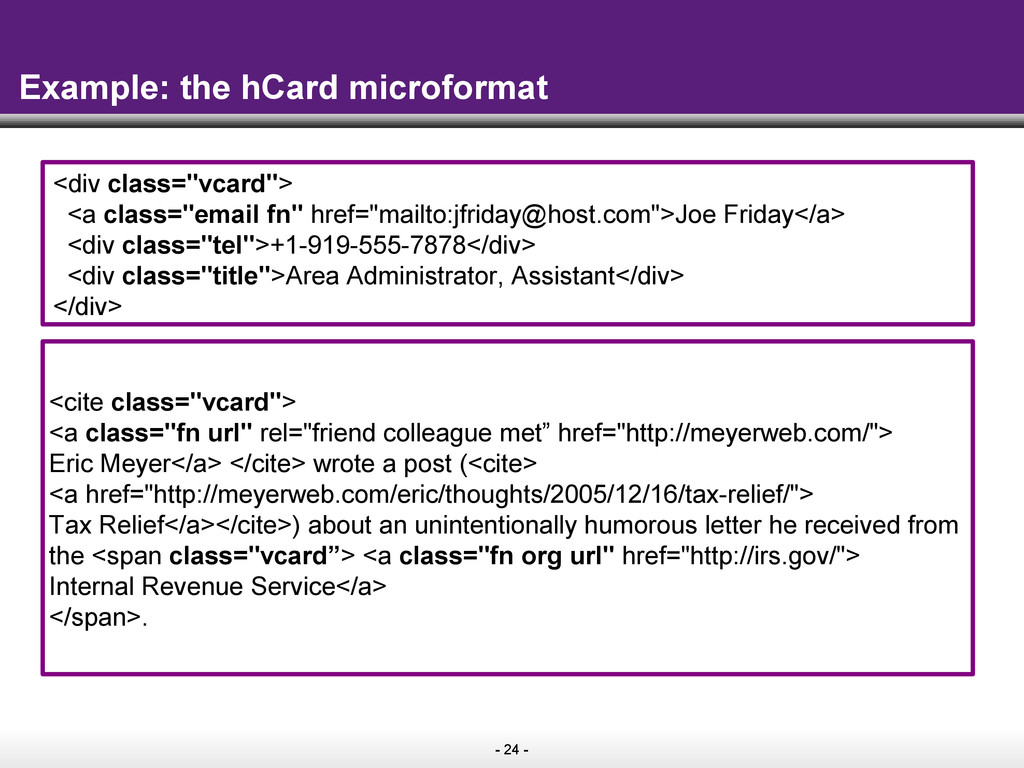
- 24 - Example: the hCard microformat <cite class="vcard"> <a
class="fn url" rel="friend colleague met” href="http://meyerweb.com/"> Eric Meyer</a> </cite> wrote a post (<cite> <a href="http://meyerweb.com/eric/thoughts/2005/12/16/tax-relief/"> Tax Relief</a></cite>) about an unintentionally humorous letter he received from the <span class="vcard”> <a class="fn org url" href="http://irs.gov/"> Internal Revenue Service</a> </span>. <div class="vcard"> <a class="email fn" href="mailto:[email protected]">Joe Friday</a> <div class="tel">+1-919-555-7878</div> <div class="title">Area Administrator, Assistant</div> </div> -
- 25 - Microformats: limitations • Syntax shared with HTML
– You need to implement extraction for each microformat separately • Lack of formal schemas – Limited reuse, extensibility of schemas – Unclear which combinations are allowed • Lack of a datatype system • No unique identifiers (URIs) – No linking, e.g. sameAs • Always appears in the HTML <body> – Not always clear how it relates to the main topic of the page • Instability • Everything is a draft… • Varying degrees of support -
- 26 - RDFa • W3C standard for embedding RDF
data in HTML documents – A set of new HTML attributes to be used in head or body – A specification of how to extract the data from these attributes – RDFa is just a syntax, you have to choose (or create) a vocabulary separately • Addresses the limitations of microformats – Syntax different from HTML – Semantic Web schema languages (reuse, extend schemas) – Unique identifiers for objects (interlinking, sameAs) – Markup in head or body • Alternative to publishing data as RDF/XML (Linked Data) – Search engine friendly -
- 27 - RDFa evolution • RDFa 1.0 is a
W3C Recommendation since October, 2008 • RDFa 1.1 is a small update on RDFa to reduce complexity, make it compatible with HTML5 – Working Draft (March 31, 2011) – Updated version of the RDFa Primer (April 19, 2011) – HTML+RDFa Working Draft (May 25, 2011) • New in RDFa 1.1 – New vocab attribute to define the default namespace for the document or subtree – Profile documents to define multiple namespace prefixes – The prefix attribute as a recommended replacement of xmlns – You can use URIs even where only CURIEs were allowed before • RDFa API for accessing RDFa data in a webpage in the browser from JavaScript – Currently Working Draft (April 19, 2011) -
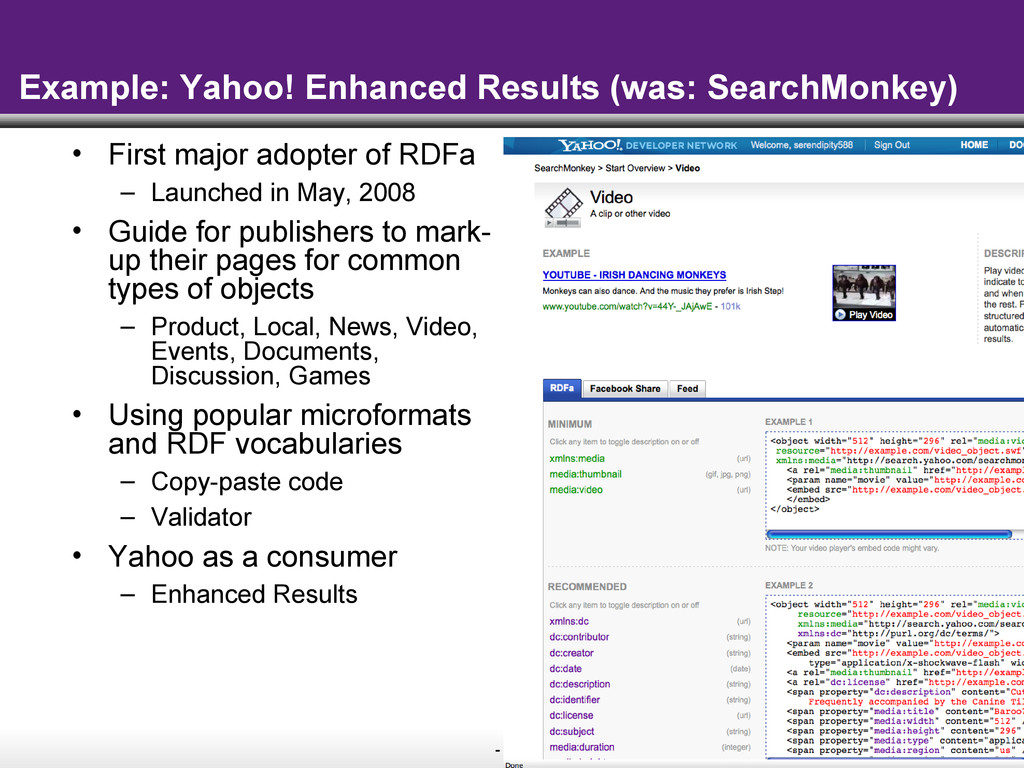
- 28 - Example: Yahoo! Enhanced Results (was: SearchMonkey) •
First major adopter of RDFa – Launched in May, 2008 • Guide for publishers to mark- up their pages for common types of objects – Product, Local, News, Video, Events, Documents, Discussion, Games • Using popular microformats and RDF vocabularies – Copy-paste code – Validator • Yahoo as a consumer – Enhanced Results -
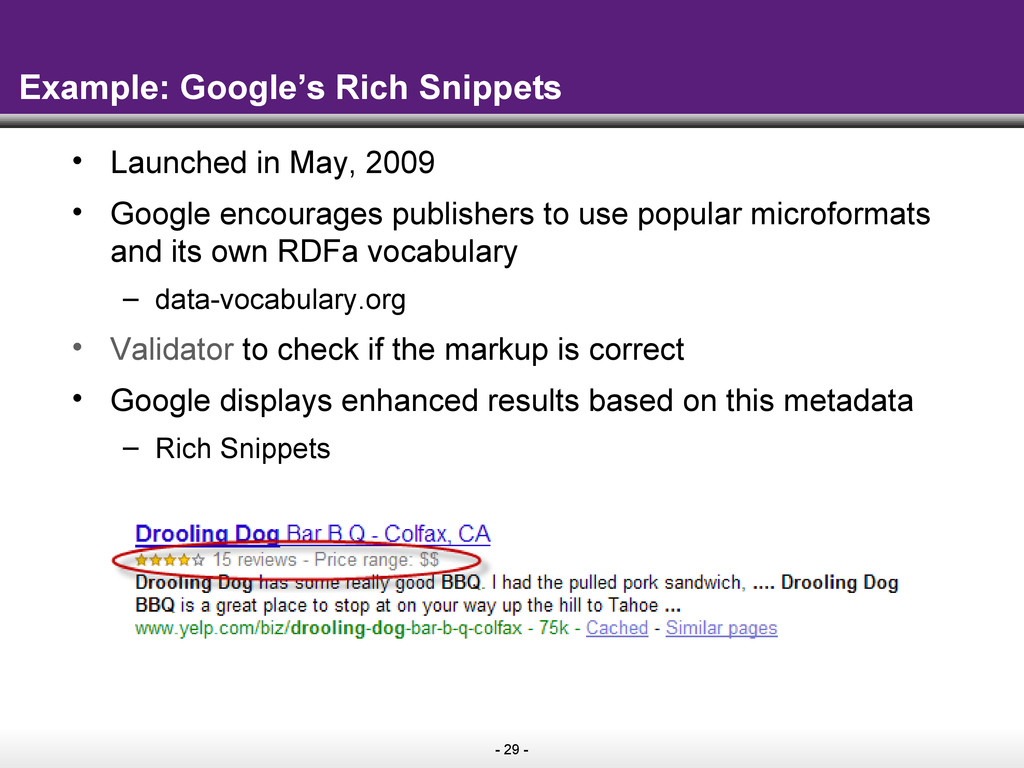
- 29 - Example: Google’s Rich Snippets • Launched in
May, 2009 • Google encourages publishers to use popular microformats and its own RDFa vocabulary – data-vocabulary.org • Validator to check if the markup is correct • Google displays enhanced results based on this metadata – Rich Snippets -
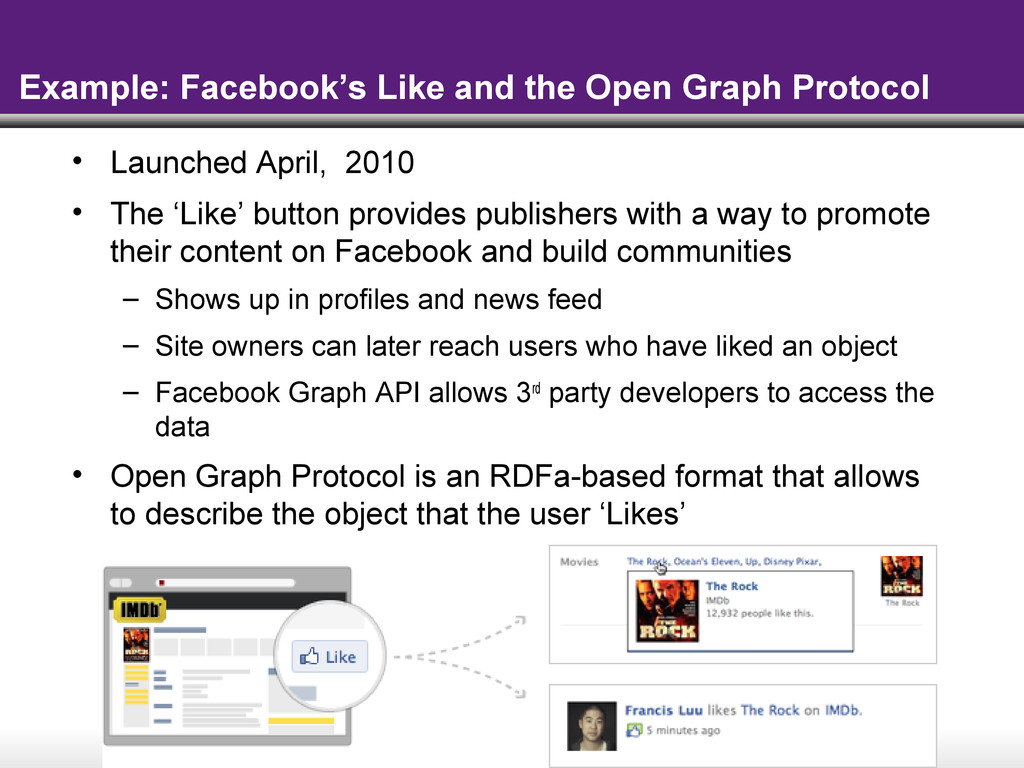
- 30 - Example: Facebook’s Like and the Open Graph
Protocol • Launched April, 2010 • The ‘Like’ button provides publishers with a way to promote their content on Facebook and build communities – Shows up in profiles and news feed – Site owners can later reach users who have liked an object – Facebook Graph API allows 3rd party developers to access the data • Open Graph Protocol is an RDFa-based format that allows to describe the object that the user ‘Likes’ -
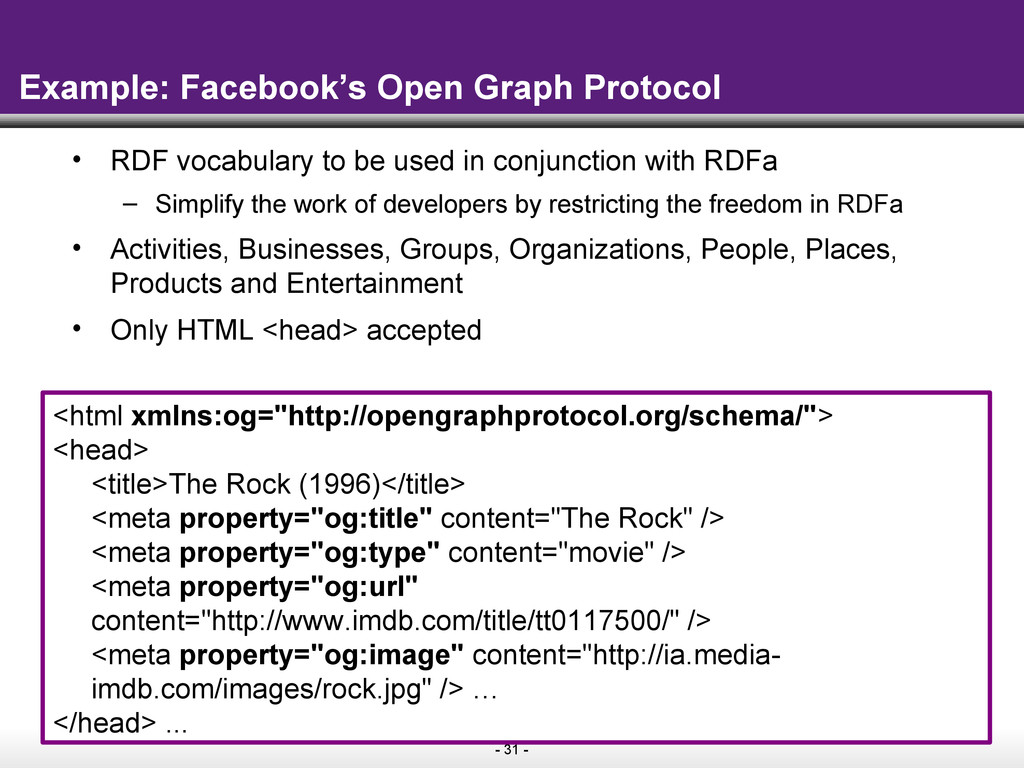
- 31 - Example: Facebook’s Open Graph Protocol • RDF
vocabulary to be used in conjunction with RDFa – Simplify the work of developers by restricting the freedom in RDFa • Activities, Businesses, Groups, Organizations, People, Places, Products and Entertainment • Only HTML <head> accepted <html xmlns:og="http://opengraphprotocol.org/schema/"> <head> <title>The Rock (1996)</title> <meta property="og:title" content="The Rock" /> <meta property="og:type" content="movie" /> <meta property="og:url" content="http://www.imdb.com/title/tt0117500/" /> <meta property="og:image" content="http://ia.media- imdb.com/images/rock.jpg" /> … </head> ... -
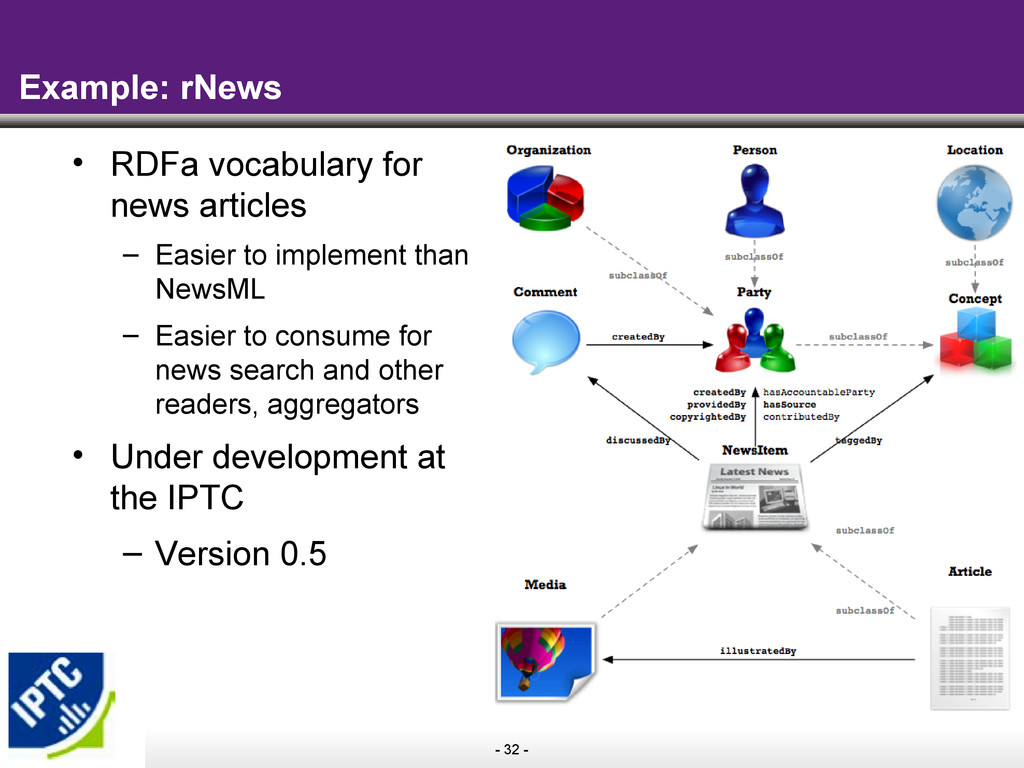
- 32 - Example: rNews • RDFa vocabulary for news
articles – Easier to implement than NewsML – Easier to consume for news search and other readers, aggregators • Under development at the IPTC – Version 0.5 -
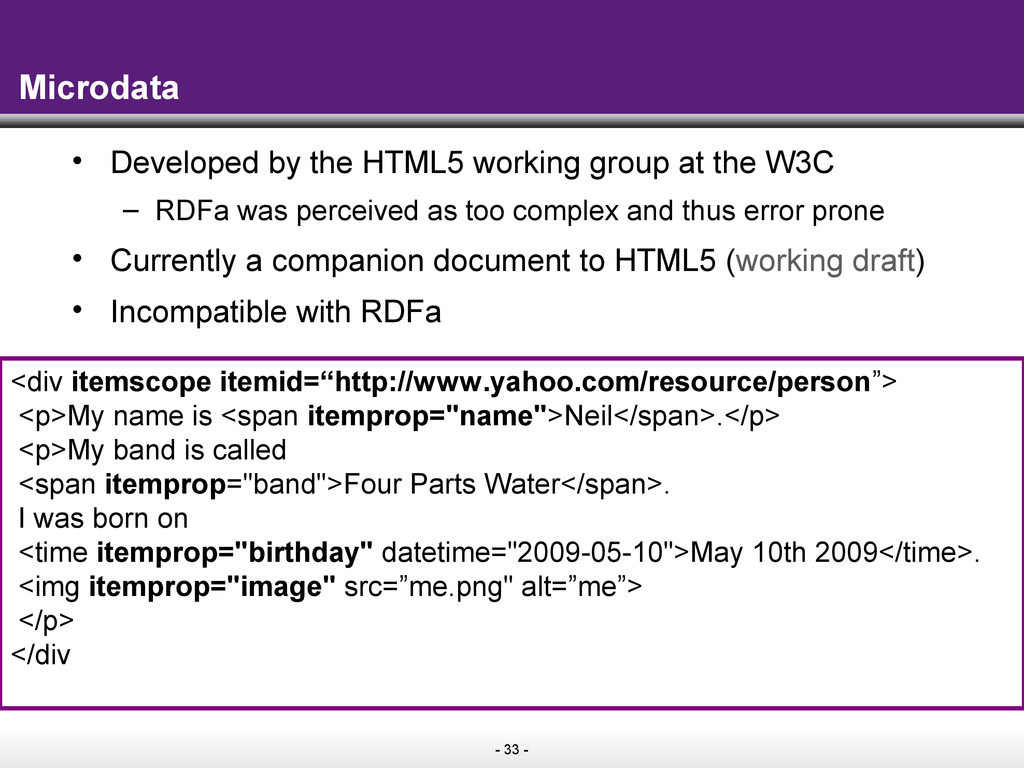
- 33 - Microdata • Developed by the HTML5 working
group at the W3C – RDFa was perceived as too complex and thus error prone • Currently a companion document to HTML5 (working draft) • Incompatible with RDFa <div itemscope itemid=“http://www.yahoo.com/resource/person”> <p>My name is <span itemprop="name">Neil</span>.</p> <p>My band is called <span itemprop="band">Four Parts Water</span>. I was born on <time itemprop="birthday" datetime="2009-05-10">May 10th 2009</time>. <img itemprop="image" src=”me.png" alt=”me”> </p> </div -
- 34 - Competing formats, competing schemas • Multiple incompatible
formats: microformats, RDFa, microdata – Varying degrees of adoption – Not all formats are supported by all search engines • Multiple competing schemas (ontologies) – Different schemas for marking up the same information (RDFa and microdata) • Major search engines support different existing alternatives or create their own (Google, Facebook) – Not clear which schemas have adoption, who is responsible for maintaining them – Slow convergence -
- 35 - schema.org • Agreement on a common set
of schemas – Bing, Google, and Yahoo as initial supporters – Similar in intent to sitemaps.org (2006) • Use a single format to communicate the same information to all three search engines • Support for microdata • schema.org covers areas of interest to all search engines – Business listings (local), creative works (video), recipes, reviews – User defined extensions • Each search engine continues to develop its products -
- 36 - 1st schema.org workshop (Sept 21, 2011) •
Palo Alto, CA – 75 attendees – Standard groups, large content publishers, search engines, tool providers • Discussion on both syntax and vocabulary related issues – New RDFa Lite 1.1 proposal – New extensions e.g. rNews – W3C announced the creation of wo new W3C Task Forces (TFs) within the Semantic Web Interest Group • Web schemas TF for collaborations on schema design, mappings, tooling etc. • HTML Data TF to provide guidance on how to use RDFa and microdata in combination, and how to translate from one format to the other • Interest from both Baidu and Yandex in supporting schema.org -
- 37 - Current state of semantic search • Limited
usage in commercial search engines – Enhanced results – Faceted search • Google’s Recipe Search – Navigation to related entities • Yahoo’s Vertical Intent Search • Positive SEO effects – Enhanced results are clicked more – Enhanced results help users find relevant results • Increased adoption of data markup -
- 38 - RDFa on the rise Percentage of URLs
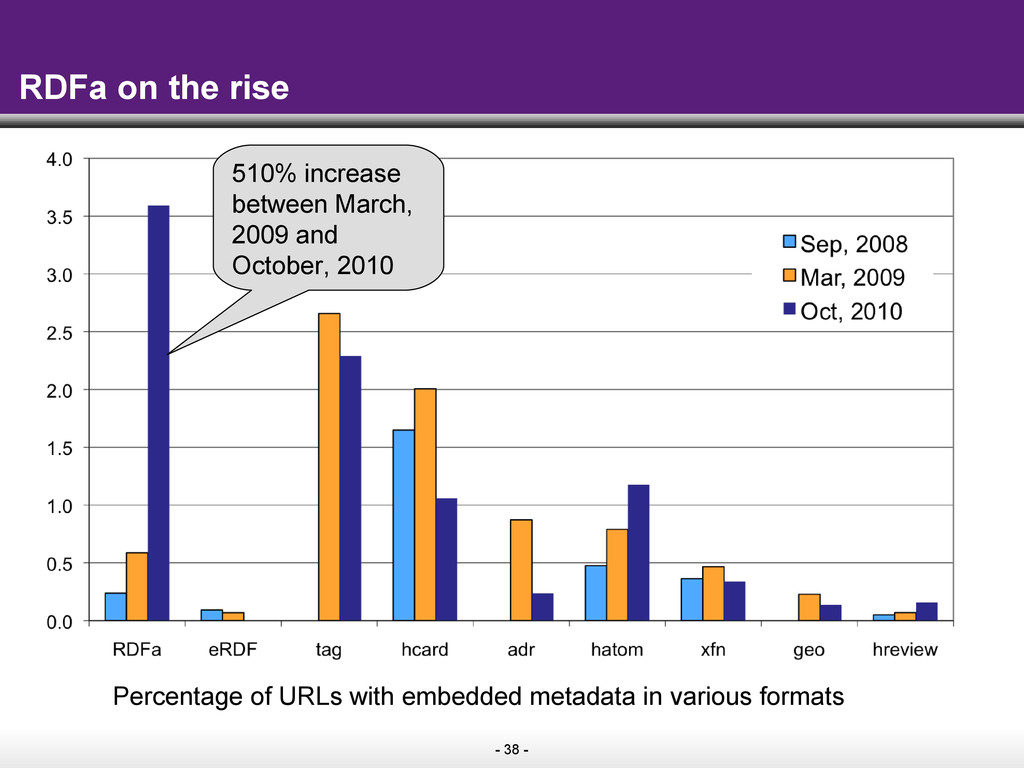
with embedded metadata in various formats 510% increase between March, 2009 and October, 2010 -
- 39 - Semantic Search development • Research – RDF
indexing and ranking – Searching over annotated web pages – Search result summarization – Question answering – Task completion – Semantic log analysis • Prototype ‘pure’ RDF search engines – Sindice and Sig.ma from DERI -
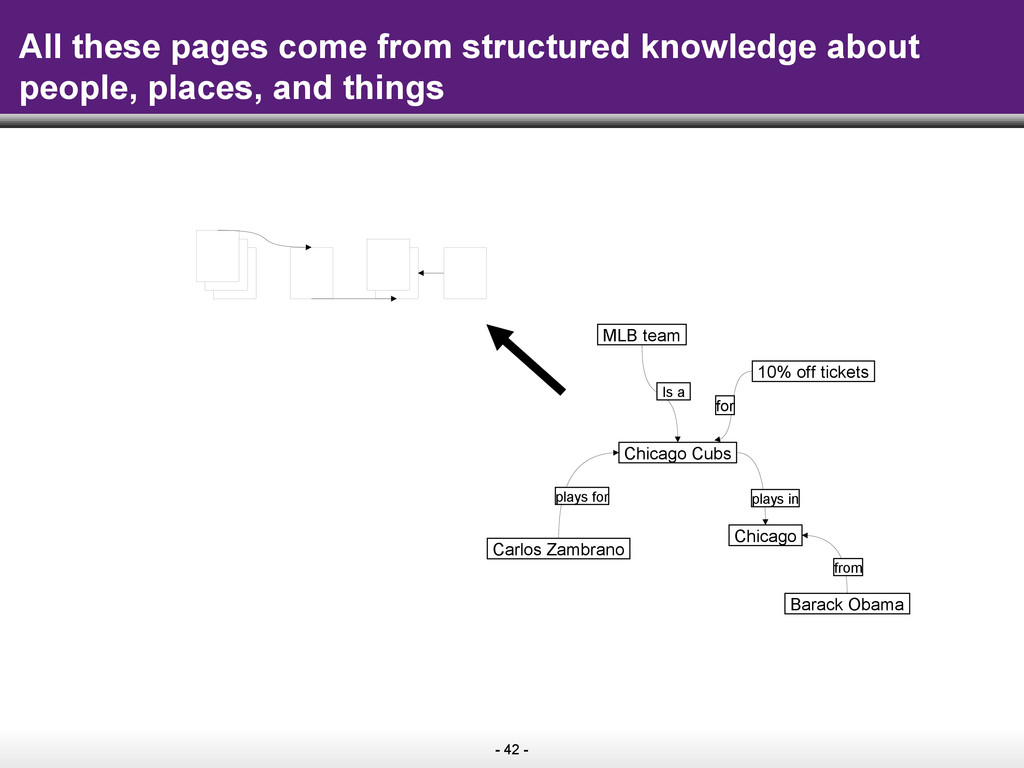
- 42 - All these pages come from structured knowledge
about people, places, and things MLB team Chicago Cubs Is a Chicago Barack Obama Carlos Zambrano 10% off tickets for plays for plays in from -
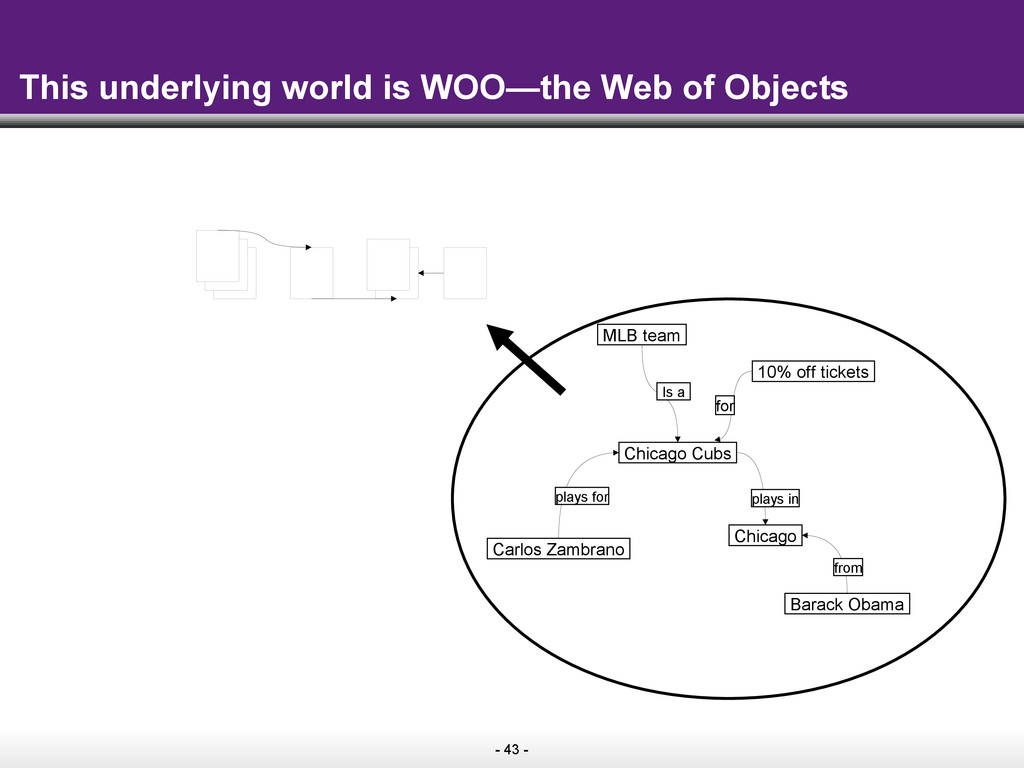
- 43 - This underlying world is WOO—the Web of
Objects MLB team Chicago Cubs Is a Chicago Barack Obama Carlos Zambrano 10% off tickets for plays for plays in from -
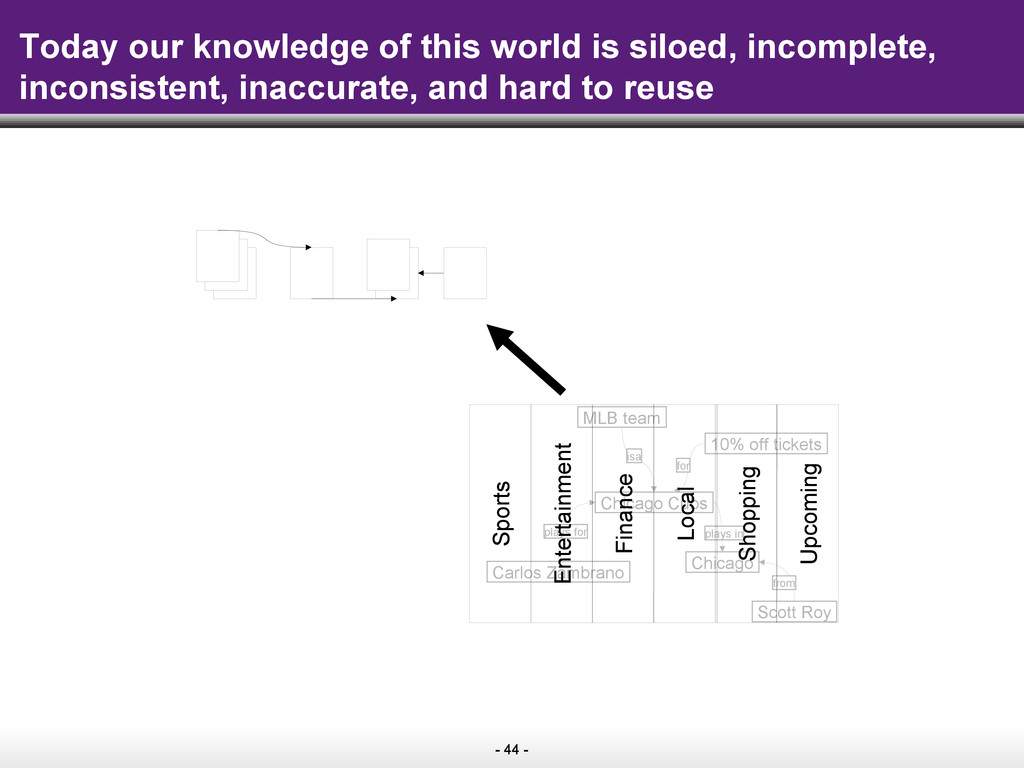
- 44 - Today our knowledge of this world is
siloed, incomplete, inconsistent, inaccurate, and hard to reuse MLB team Chicago Cubs isa Chicago Scott Roy Carlos Zambrano 10% off tickets for plays for plays in from Sports Entertainment Finance Local Shopping Upcoming -
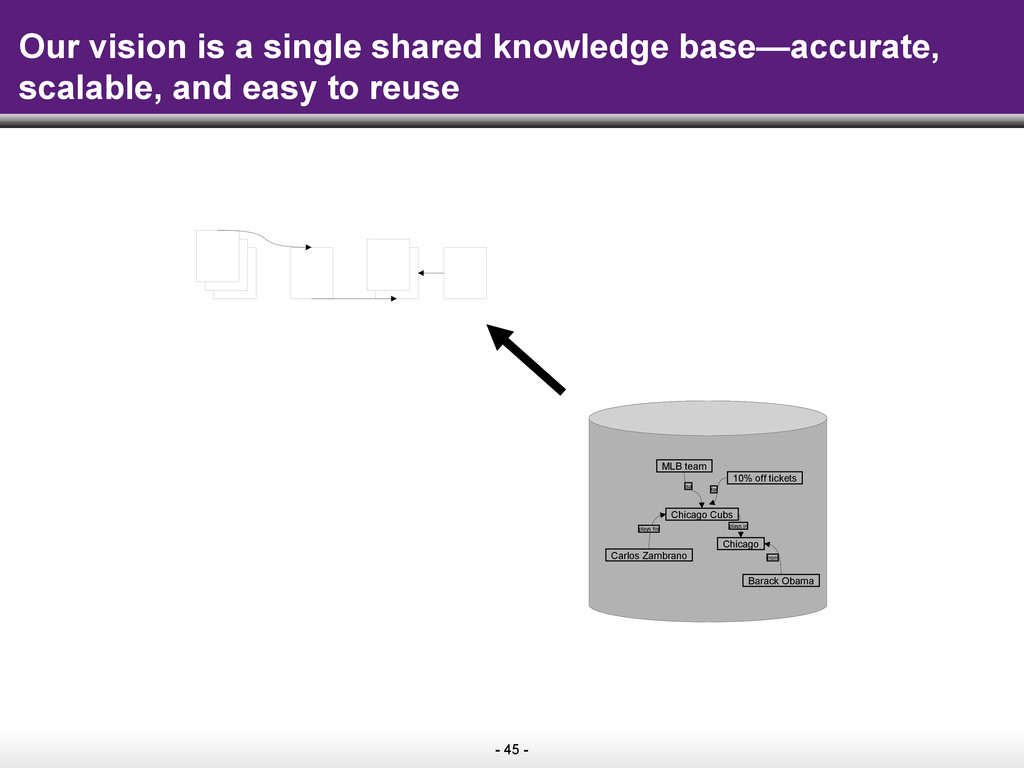
- 45 - Our vision is a single shared knowledge
base—accurate, scalable, and easy to reuse MLB team Chicago Cubs isa Chicago Barack Obama Carlos Zambrano 10% off tickets for plays for plays in from -
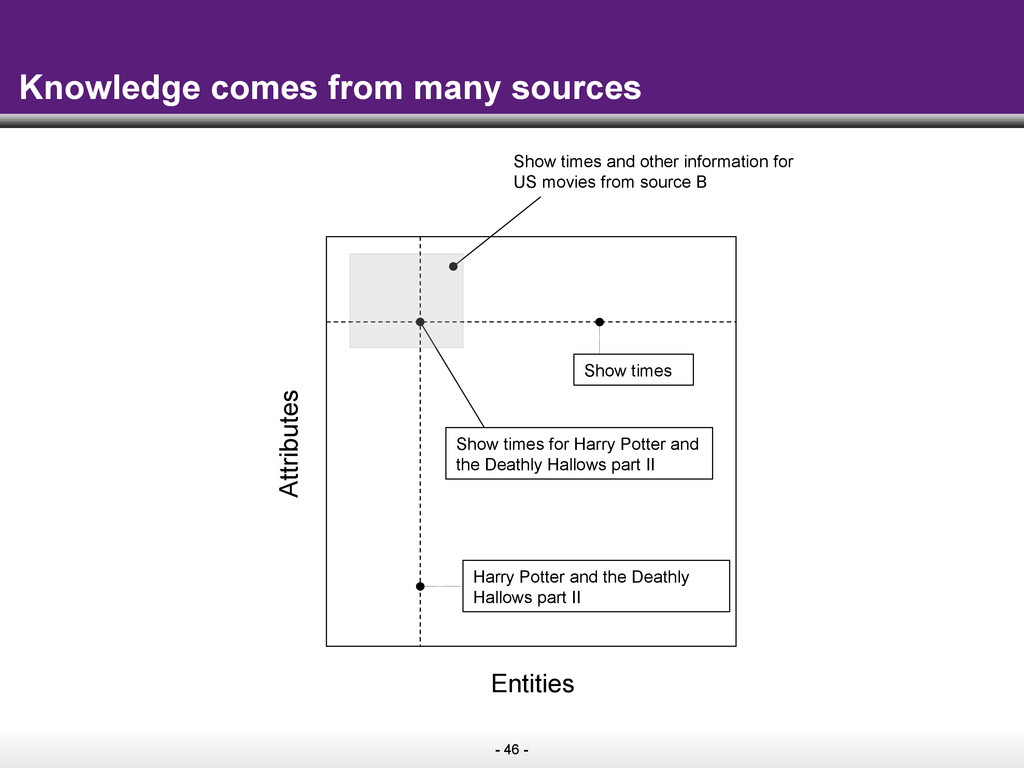
- 46 - Knowledge comes from many sources Entities Attributes
Show times and other information for US movies from source B Harry Potter and the Deathly Hallows part II Show times Show times for Harry Potter and the Deathly Hallows part II -
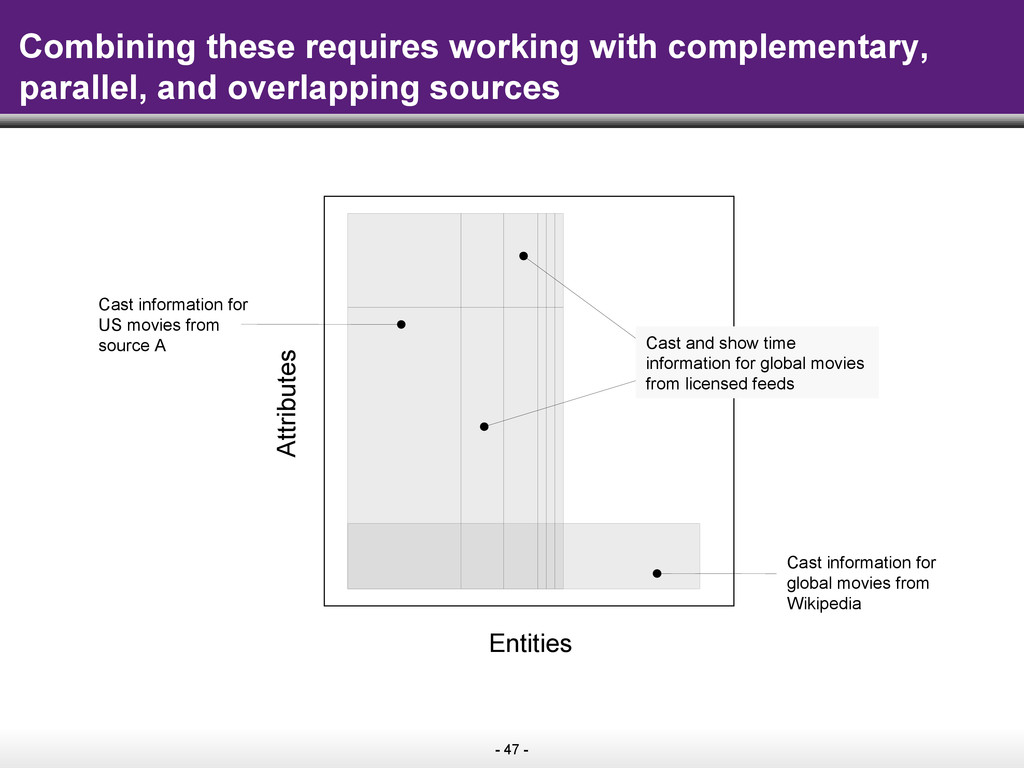
- 47 - Combining these requires working with complementary, parallel,
and overlapping sources Attributes Entities Cast information for global movies from Wikipedia Cast information for US movies from source A Cast and show time information for global movies from licensed feeds -
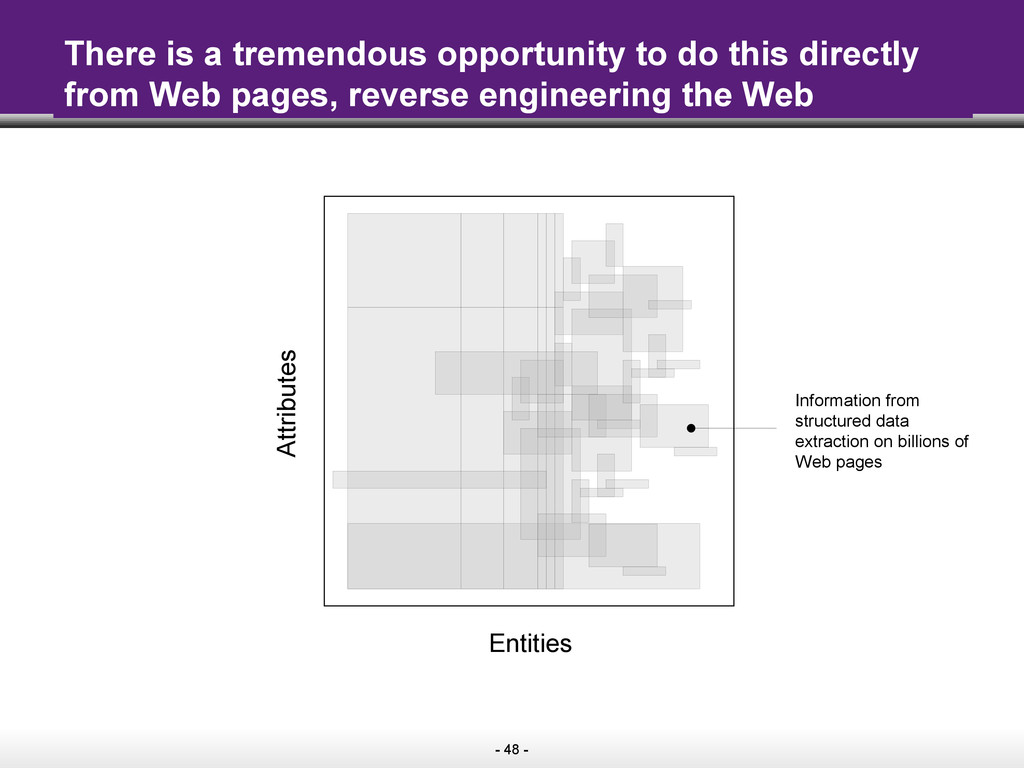
- 48 - There is a tremendous opportunity to do
this directly from Web pages, reverse engineering the Web Attributes Entities Information from structured data extraction on billions of Web pages -
- 49 - Semantic technologies for data integration • Semantic
Web provides the basic technologies for Linked Data – URIs as unique identifiers • Retrieve data from the (internal) web • Follow links in the data that is returned – RDF as a common data format – OWL as a powerful schema language for validation and reasoning – SPARQL for queries, reasoning and transformations -
- 50 - Components • Data is ingested from web
extraction, feeds, editorial content (billions of objects) • Data integration using Hadoop clusters – Schema matching to the WOO ontology – Object reconciliation – Blending • Data quality assessment • Information extraction – Text, e.g. news content – Webpages • Enrichment – Feature computation based on user behavior, social signals and web content • Serving and ranking – Selecting the right objects to show by query, user, geography etc. -
- 51 - WOO ontology • Primary use case is
data validation – During information extraction and throughout the WOO platform – No reasoning • OWL2 ontology – Automatic documentation – Change management – Conversion to Yahoo internal schema language – Protégé OWL as editorial tool -
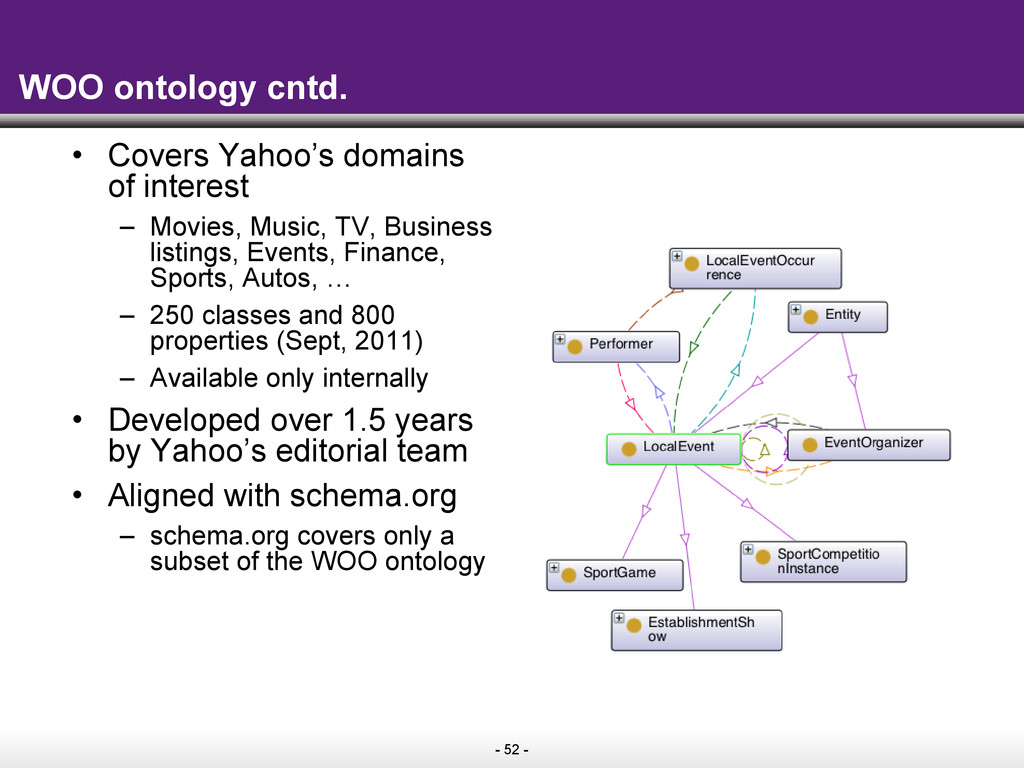
- 52 - WOO ontology cntd. • Covers Yahoo’s domains
of interest – Movies, Music, TV, Business listings, Events, Finance, Sports, Autos, … – 250 classes and 800 properties (Sept, 2011) – Available only internally • Developed over 1.5 years by Yahoo’s editorial team • Aligned with schema.org – schema.org covers only a subset of the WOO ontology -
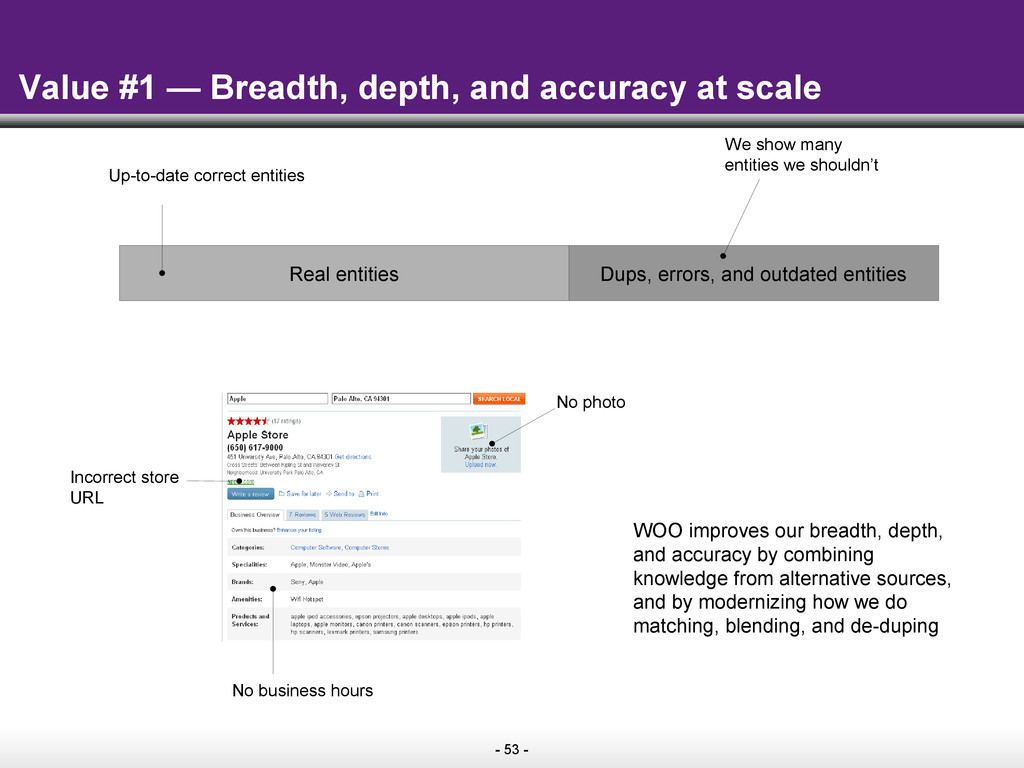
- 53 - Value #1 — Breadth, depth, and accuracy
at scale Real entities Dups, errors, and outdated entities Up-to-date correct entities Incorrect store URL No photo We show many entities we shouldn’t No business hours WOO improves our breadth, depth, and accuracy by combining knowledge from alternative sources, and by modernizing how we do matching, blending, and de-duping -
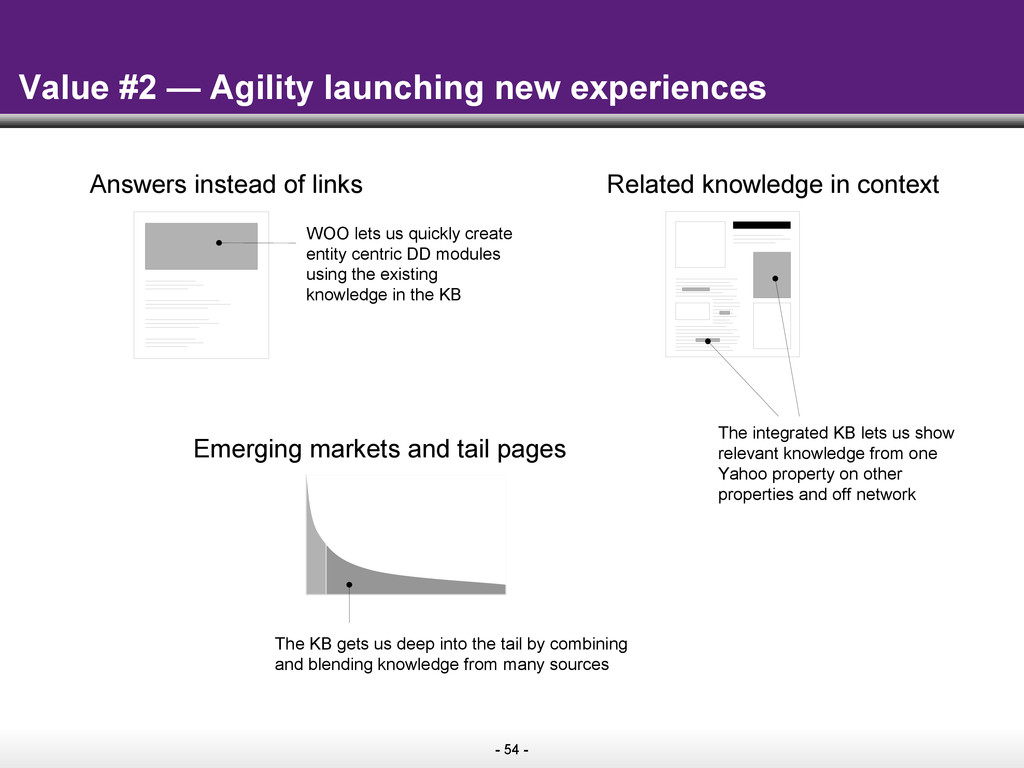
- 54 - Value #2 — Agility launching new experiences
Answers instead of links WOO lets us quickly create entity centric DD modules using the existing knowledge in the KB Related knowledge in context The integrated KB lets us show relevant knowledge from one Yahoo property on other properties and off network Emerging markets and tail pages The KB gets us deep into the tail by combining and blending knowledge from many sources -
- 55 - Other potential benefits • Dynamic interlinking of
content – E.g. direct links from Yahoo! News to background information in Yahoo! Music about an artist • Dynamic composition of web pages – Topic-entity pages • Better understanding of user intent – Semantic analysis of query logs – Semantic analysis of navigation paths • Exposure of Yahoo! content using standard technologies – Linking to external sources to make it part of the Linked Data cloud -
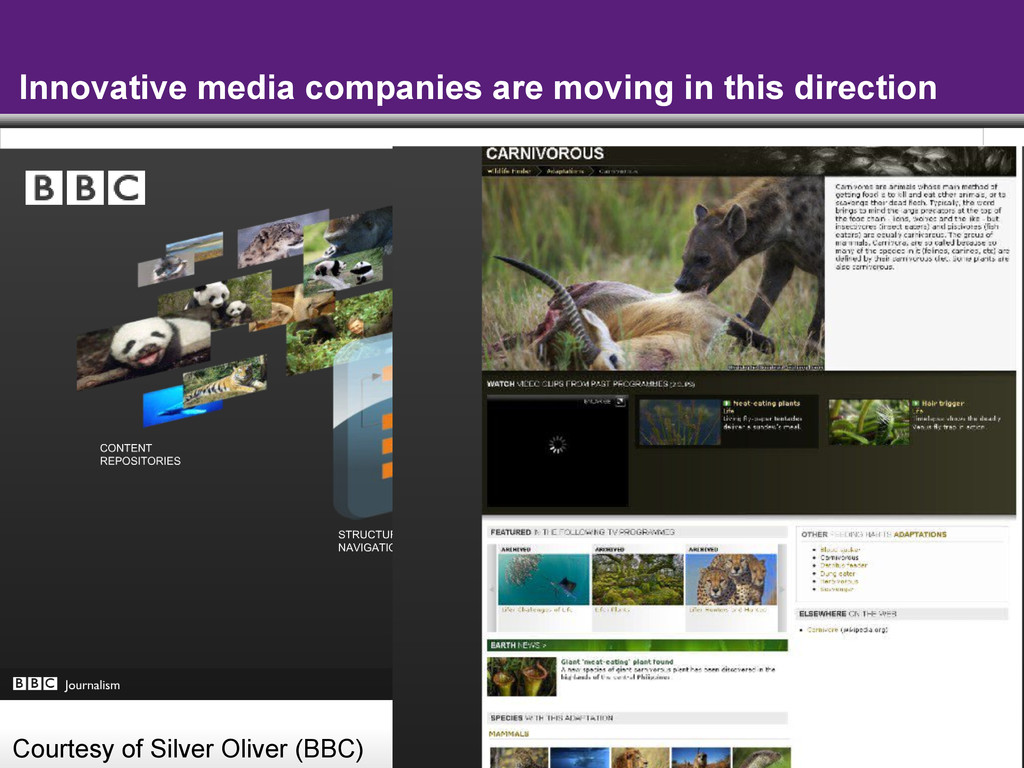
- 56 - Innovative media companies are moving in this
direction Courtesy of Silver Oliver (BBC) -
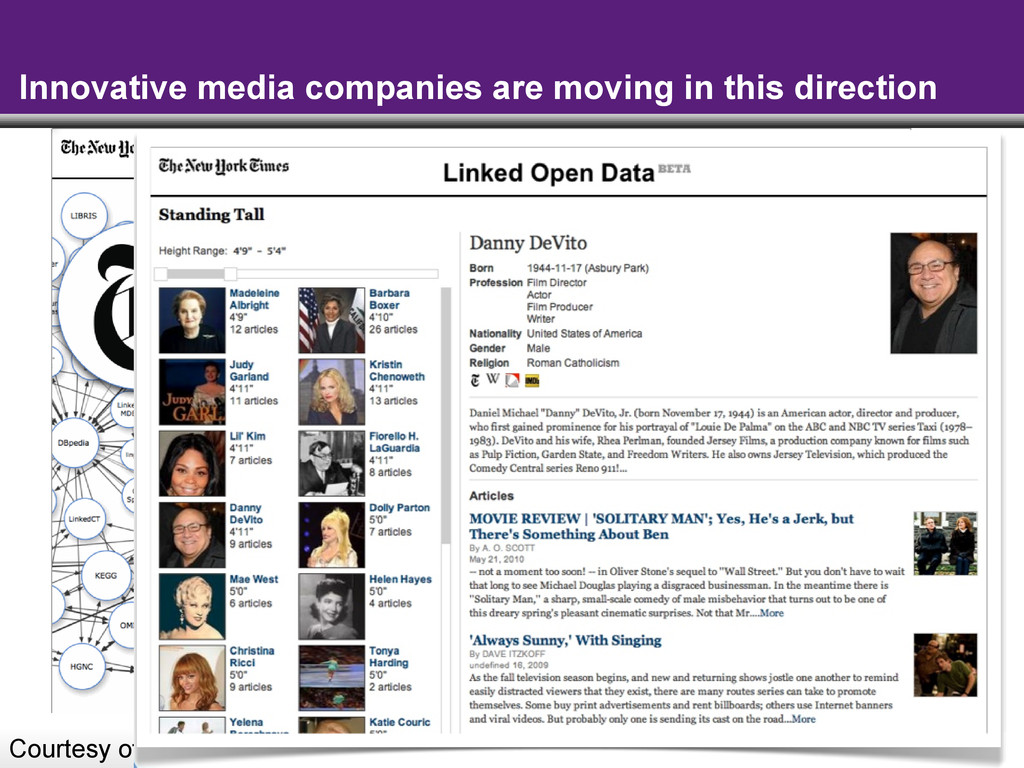
- 57 - Innovative media companies are moving in this
direction Courtesy of Evan Sandhaus (NYT). -
- 58 - Take home: use what works! • The
W3C’s semantic technology stack is daunting – The basics are simple: • URIs for entity identifiers, RDF for data exchange • Standards for embedding data in HTML – Useful in search and at other points of content consumption • Standards for expressing the meaning of data – Useful in data integration • Do your bit! -
- 59 - The End • Credits to many people
from Yahoo! around the world • Contact me at – [email protected]