Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Extending Pandas using Apache Arrow and Numba

Sponsored · SiteGround - Reliable hosting with speed, security, and support you can count on. →

Extending Pandas using Apache Arrow and Numba

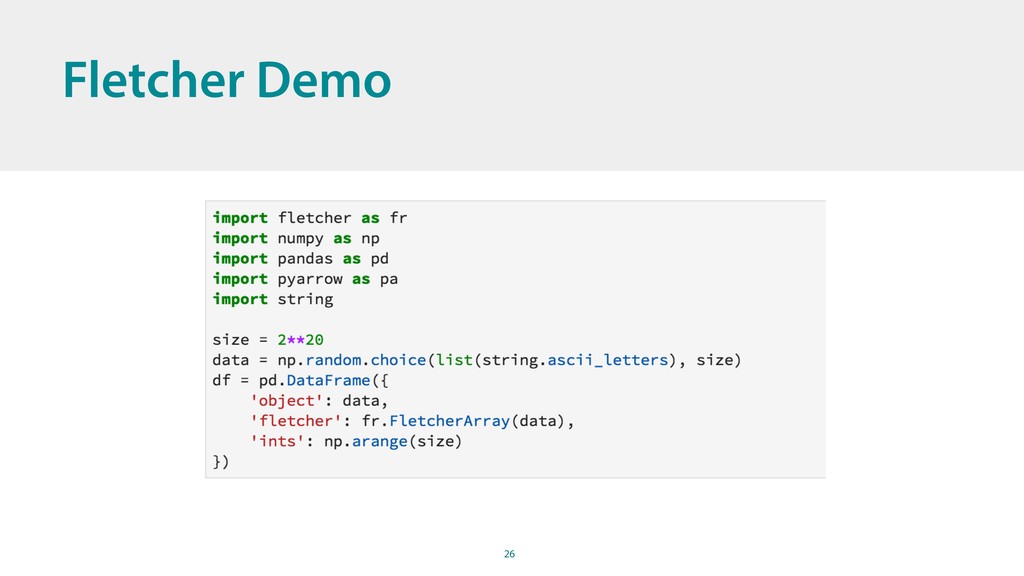
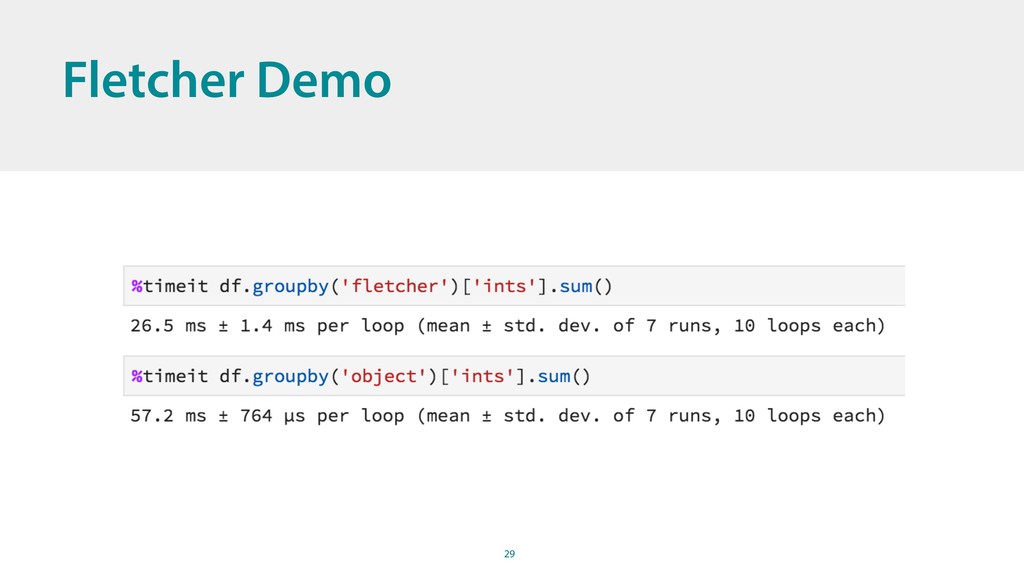
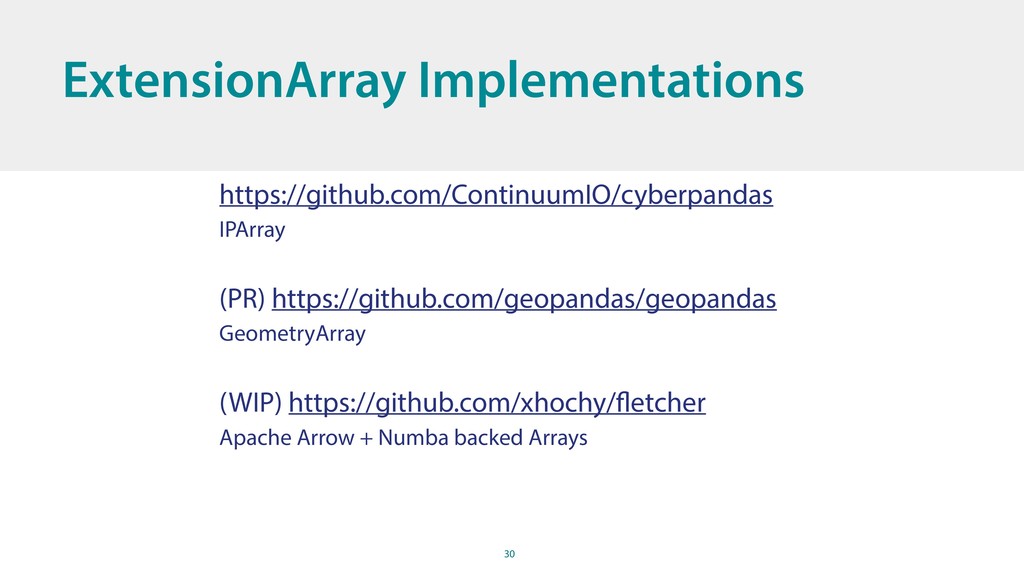
With the latest release of Pandas the ability to extend it with custom dtypes was introduced. Using Apache Arrow as the in-memory storage and Numba for fast, vectorized computations on these memory regions, it is possible to extend Pandas in pure Python while achieving the same performance of the built-in types. In the talk we implement a native string type as an example.

Avatar for Uwe L. Korn

Uwe L. Korn

July 08, 2018

More Decks by Uwe L. Korn

Other Decks in Programming

Transcript

  1. 4 • Senior Data Scientist at Blue Yonder (@BlueYonderTech) •

    Apache {Arrow, Parquet} PMC • Data Engineer and Architect with heavy focus around Pandas About me xhochy [email protected]
  2. 5 1. Shortcomings of Pandas 2. ExtensionArrays 3. Arrow for

    storage 4. Numba for compute 5. All the stuff Agenda
  3. 6 Pandas Series • Payload stored in a numpy.ndarray •

    Index for data alignment • Rich analytical API • Accessors like .dt or .str
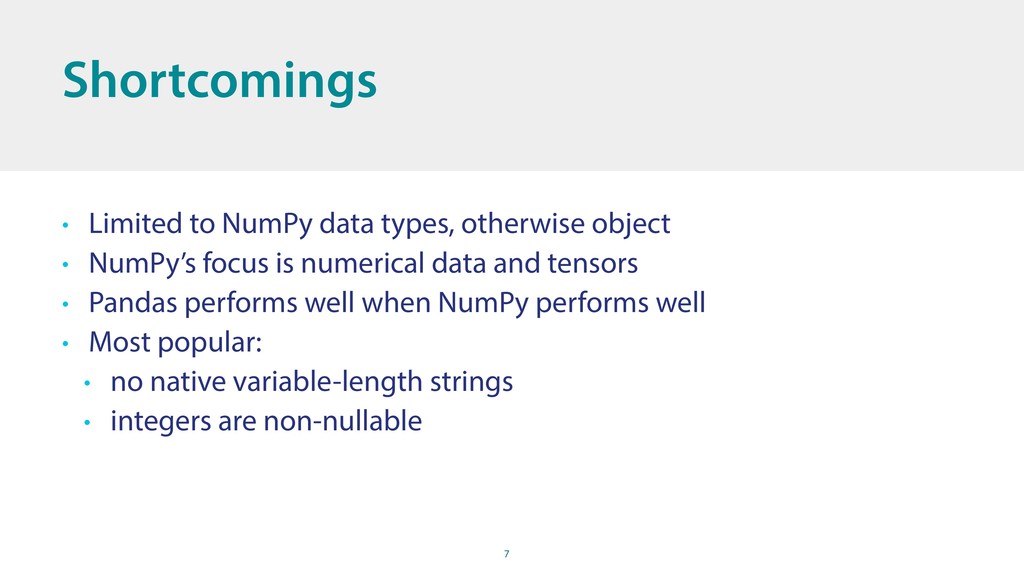
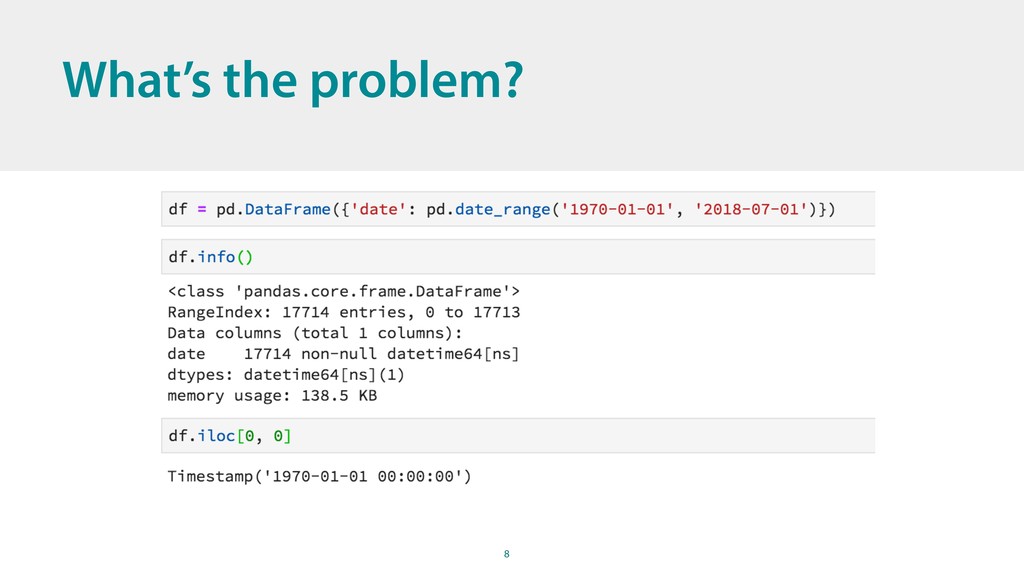
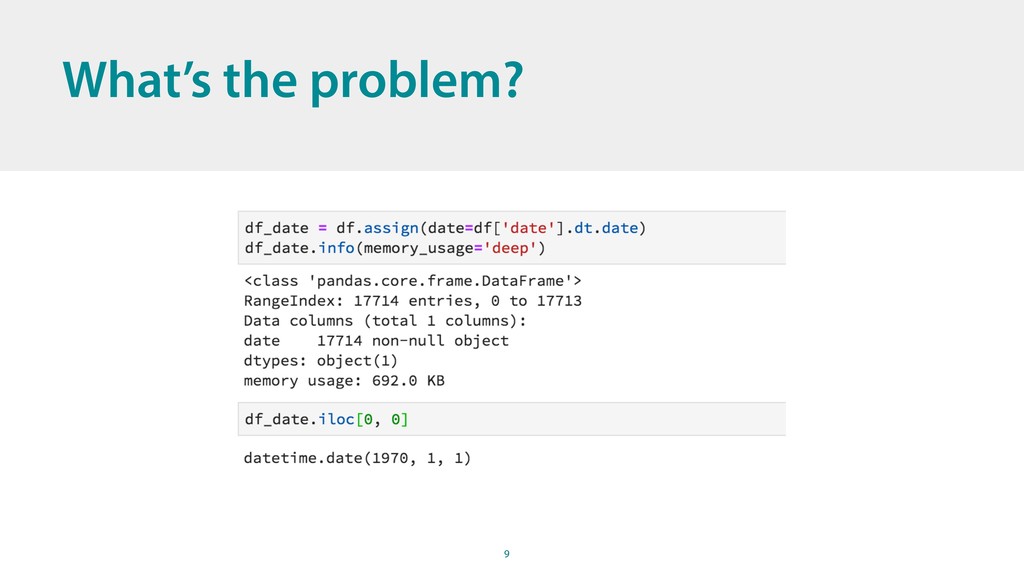
  4. 7 Shortcomings • Limited to NumPy data types, otherwise object

    • NumPy’s focus is numerical data and tensors • Pandas performs well when NumPy performs well • Most popular: • no native variable-length strings • integers are non-nullable
  5. 10 Why are objects bad? Python Data Science Handbook, Jake

    VanderPlas; O’Reilly Media, Nov 2016 https://jakevdp.github.io/PythonDataScienceHandbook/02.01-understanding-data-types.html
  6. 11 Extending Pandas (0.23+) • Two new interfaces: • ExtensionDtype

    • What type of scalars? • ExtensionArray • Implement basic array ops • Pandas provides algorithms on top
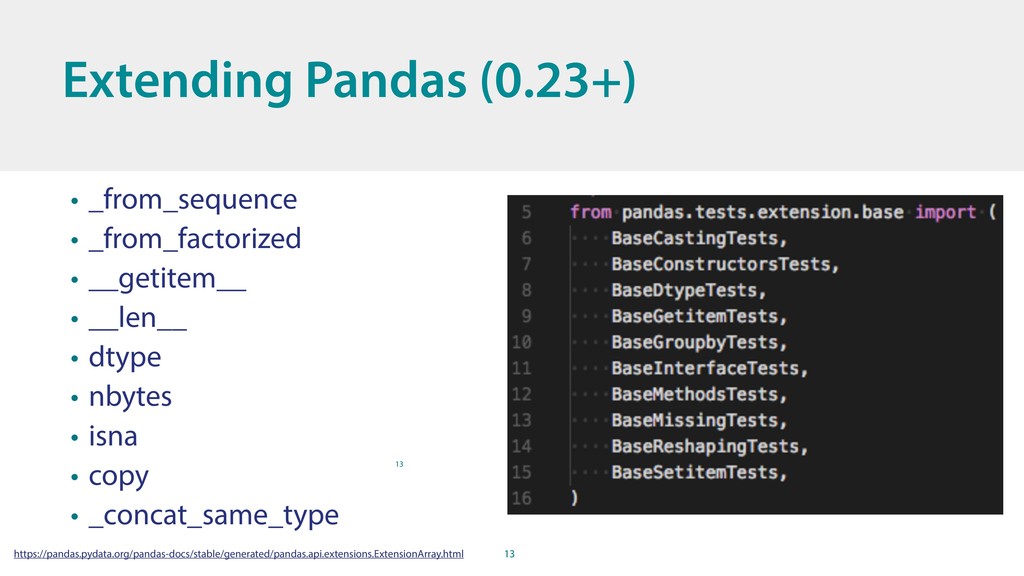
  7. 13 Extending Pandas (0.23+) • _from_sequence • _from_factorized • __getitem__

    • __len__ • dtype • nbytes • isna • copy • _concat_same_type https://pandas.pydata.org/pandas-docs/stable/generated/pandas.api.extensions.ExtensionArray.html 13
  8. 14 Apache Arrow • Specification for in-memory columnar data layout

    • No overhead for cross-system communication • Designed for efficiency (exploit SIMD, cache locality, ..) • Exchange data without conversion between Python, C++, C(glib), Ruby, Lua, R, JavaScript, Go, Rust, Matlab and the JVM • Brought Parquet to Pandas and made PySpark fast (@pandas_udf)
  9. 15 Nice properties • More native datatypes: string, date, nullable

    int, list of X, … • Everything is nullable • Memory can be chunked • Zero-copy to other ecosystems like Java / R • Highly efficient I/O
  10. 16 Not so nice properties • Still a young project

    • Not much analytic on top (yet!) • Core is in modern C++ • Extremely fast but hard to extend in Python
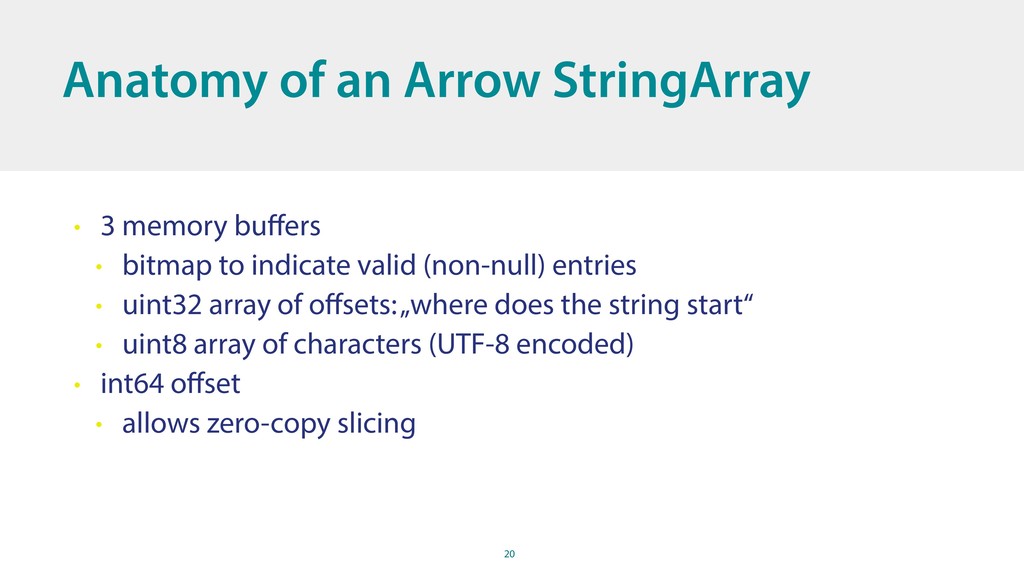
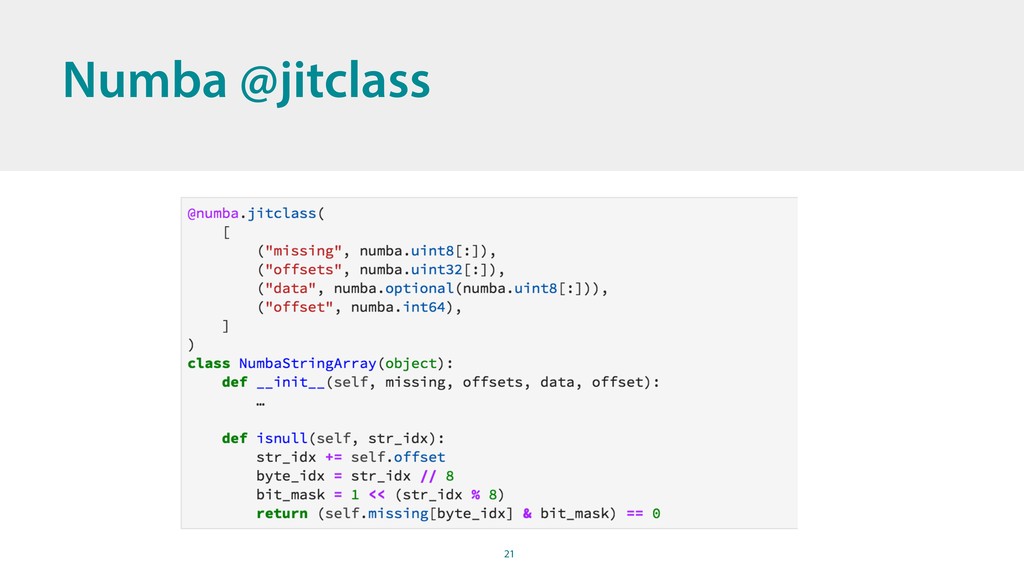
  11. 20 Anatomy of an Arrow StringArray • 3 memory buffers

    • bitmap to indicate valid (non-null) entries • uint32 array of offsets: „where does the string start“ • uint8 array of characters (UTF-8 encoded) • int64 offset • allows zero-copy slicing
  12. 32 By JOEXX (Own work) [CC BY-SA 3.0 (http://creativecommons.org/licenses/by-sa/3.0)], via

    Wikimedia Commons By JOEXX (Own work) [CC BY-SA 3.0 (http://creativecommons.org/licenses/by-sa/3.0)], via Wikimedia Commons 24. - 26. October + 2 days of sprints (27/28.10.) ZKM Karlsruhe, DE Karlsruhe Call for Participation opens next week.