Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Planning to Fail

Dave Gardner
February 23, 2013

Planning to Fail

How to build resilient and reliable services by embracing failure.

Dave Gardner

February 23, 2013

Transcript

68 slides
  1. • Launched  in  London   November  2011   • Now  in  5

     ci@es  in  3  countries   (30%+  growth  every  month)   • A  Hailo  hail  is  accepted  around   the  world  every  5  seconds  
  2. “..  Brooks  [1]  reveals  that  the  complexity   of  a

     soTware  project  grows  as  the  square   of  the  number  of  engineers  and  Leveson   [17]  cites  evidence  that  most  failures  in   complex  systems  result  from  unexpected   inter-­‐component  interac@on  rather  than   intra-­‐component  bugs,  we  conclude  that   less  machinery  is  (quadra@cally)  beYer.”     hYp://lab.mscs.mu.edu/Dist2012/lectures/HarvestYield.pdf  
  3. • SOA  (10+  services)   • AWS  (3  regions,  9  AZs,  lots

     of   instances)   • 10+  engineers  building  services   and you?! (hailo is hiring)!
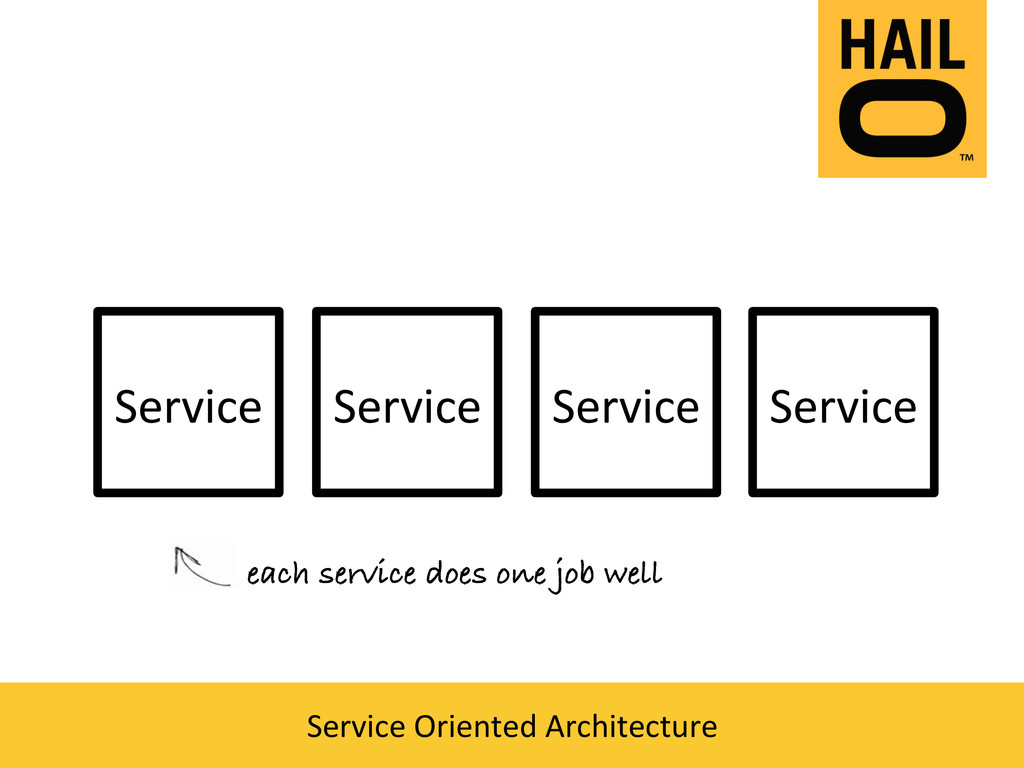
  4. Service   each service does one job well! Service  

    Service   Service   Service  Oriented  Architecture  
  5. • Fewer  lines  of  code   • Fewer  responsibili@es   • Changes  less

     frequently   • Can  swap  en@re  implementa@on   if  needed  
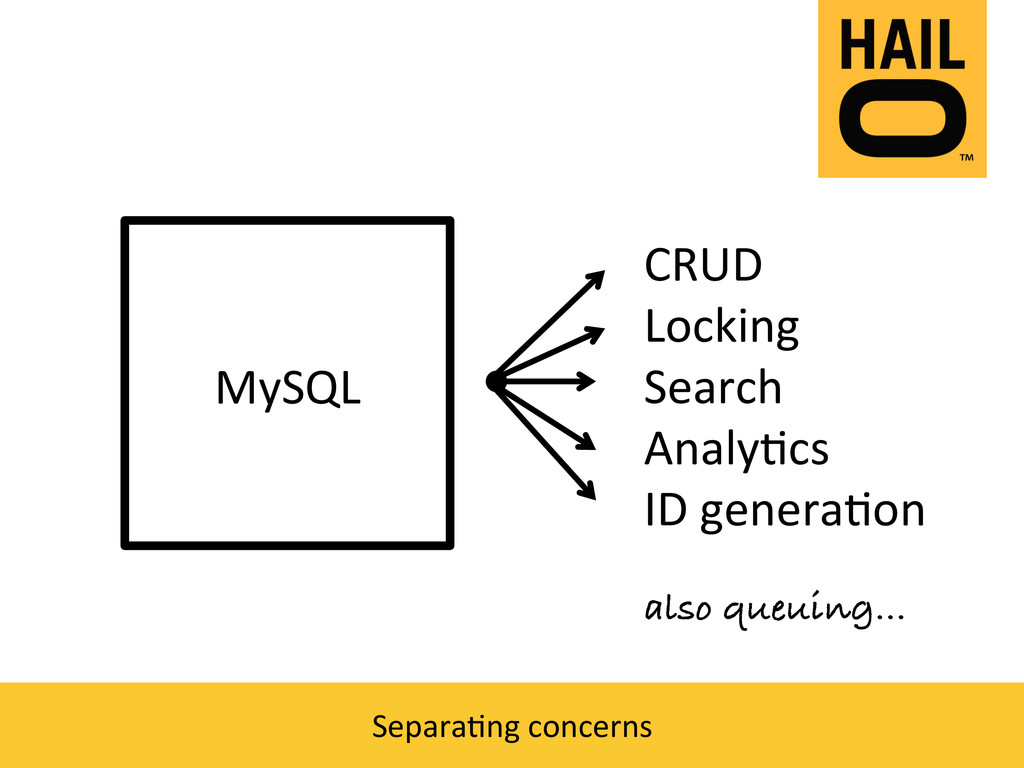
  6. MySQL   Separa@ng  concerns   CRUD   Locking   Search

      Analy@cs   ID  genera@on   also queuing…!
  7. At  Hailo  we  look  for  technologies  that  are:   • Distributed

      run  on  more  than  one  machine   • Homogenous   all  nodes  look  the  same   • Resilient   can  cope  with  the  loss  of  node(s)  with  no   loss  of  data  
  8. “There  is  no  such  thing  as  standby   infrastructure:  there

     is  stuff  you   always  use  and  stuff  that  won’t   work  when  you  need  it.”       hYp://blog.b3k.us/2012/01/24/some-­‐rules.html  
  9. • Highly  performant,  scalable  and   resilient  data  store   • Underpins

     much  of  what  we  do   at  Hailo   • Makes  mul@-­‐DC  easy!  
  10. • Highly  reliable  distributed   coordina@on   • We  implement  locking  and

      leadership  elec@on  on  top  of  ZK   and  use  sparingly   ZooKeeper
  11. • Distributed,  RESTful,  Search   Engine  built  on  top  of  Apache

      Lucene   • Replaced  basic  foo  LIKE  ‘%bar%’   queries  (so  much  beYer)  
  12. • Real@me  message  processing   system  designed  to  handle   billions

     of  messages  per  day   • Fault  tolerant,  highly  available   with  reliable  message  delivery   guarantee   NSQ
  13. • All  these  technologies  have   similar  proper@es  of  distribu@on  

    and  resilience     • They  are  designed  to  cope  with   failure   • They  are  not  broken  by  design  
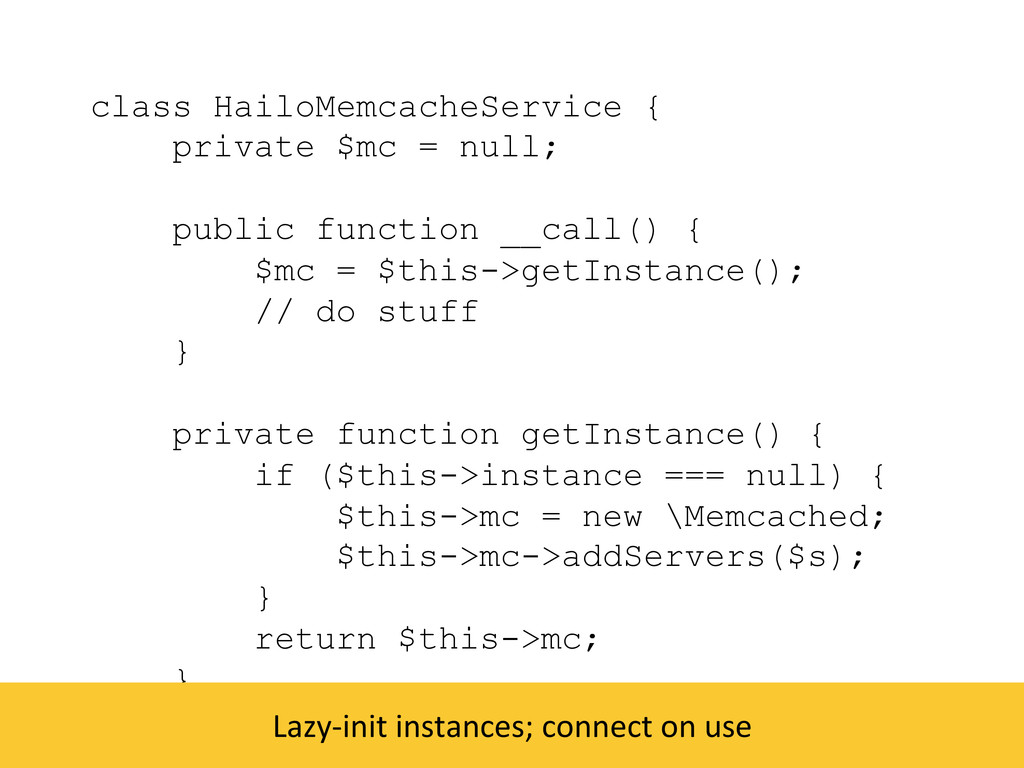
  14. class HailoMemcacheService { private $mc = null; public function __call()

    { $mc = $this->getInstance(); // do stuff } private function getInstance() { if ($this->instance === null) { $this->mc = new \Memcached; $this->mc->addServers($s); } return $this->mc; } } Lazy-­‐init  instances;  connect  on  use  
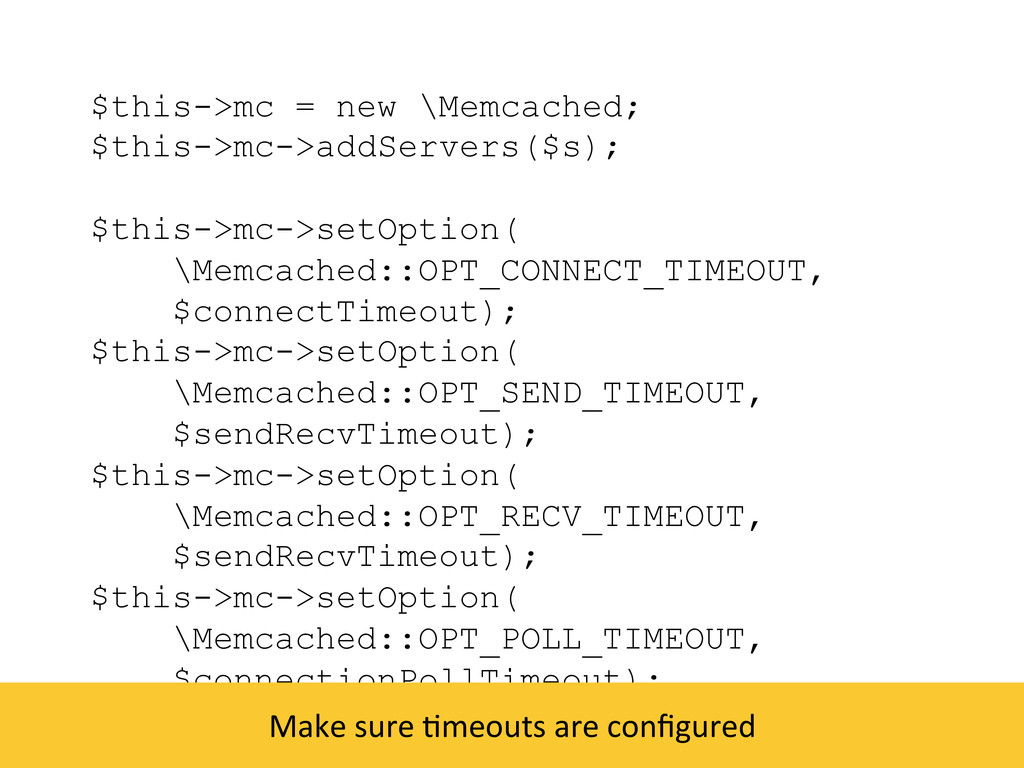
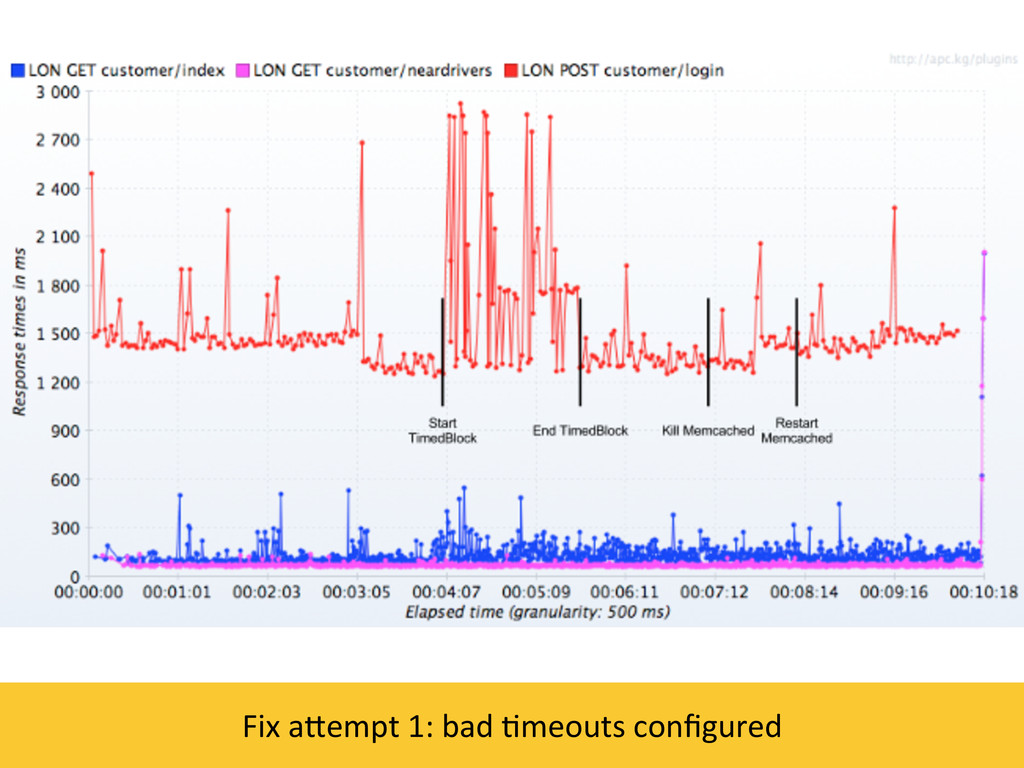
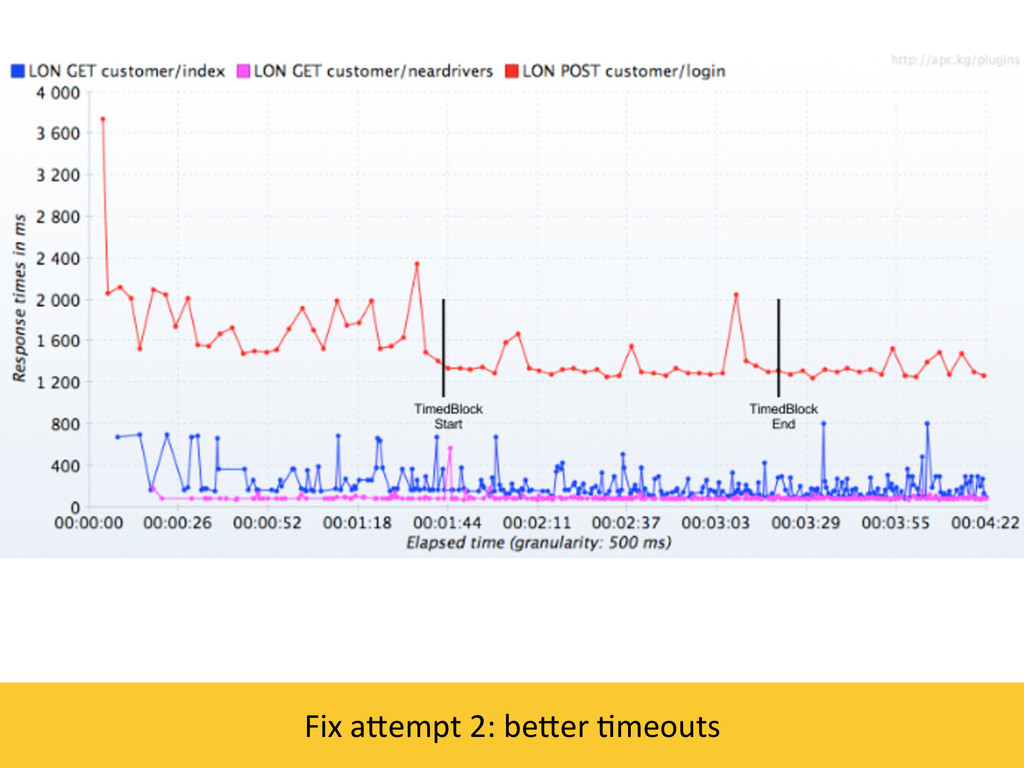
  15. $this->mc = new \Memcached; $this->mc->addServers($s); $this->mc->setOption( \Memcached::OPT_CONNECT_TIMEOUT, $connectTimeout); $this->mc->setOption( \Memcached::OPT_SEND_TIMEOUT,

    $sendRecvTimeout); $this->mc->setOption( \Memcached::OPT_RECV_TIMEOUT, $sendRecvTimeout); $this->mc->setOption( \Memcached::OPT_POLL_TIMEOUT, $connectionPollTimeout); Make  sure  @meouts  are  configured  
  16. “Fail  Fast:  Set  aggressive  @meouts   such  that  failing  components

      don’t  make  the  en@re  system   crawl  to  a  halt.”       hYp://techblog.neslix.com/2011/04/lessons-­‐ neslix-­‐learned-­‐from-­‐aws-­‐outage.html  
  17. • Kill  memcache  on  box  A,   measure  impact  on  applica@on

      • Kill  memcache  on  box  B,   measure  impact  on  applica@on     All  fine..  we’ve  got  this  covered!  
  18. • Box  A,  running  in  AWS,  locks  up   • Any  parts

     of  applica@on  that   touch  Memcache  stop  working  
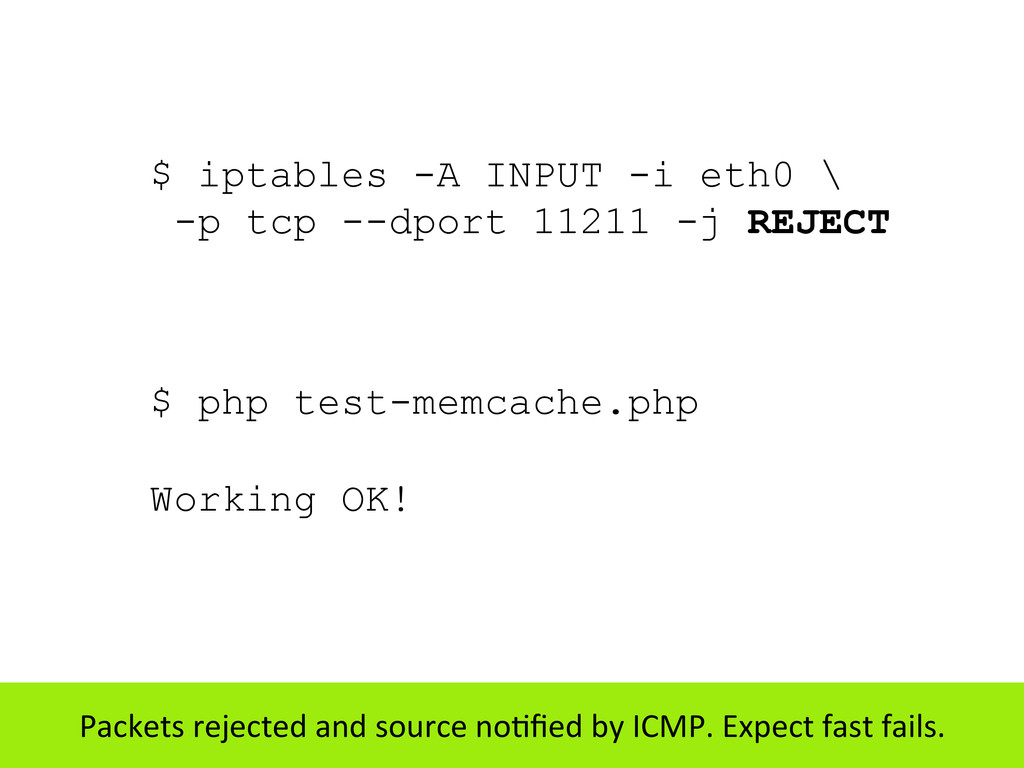
  19. $ iptables -A INPUT -i eth0 \ -p tcp --dport
    11211 -j REJECT $ php test-memcache.php Working OK! Packets  rejected  and  source  no@fied  by  ICMP.  Expect  fast  fails.  
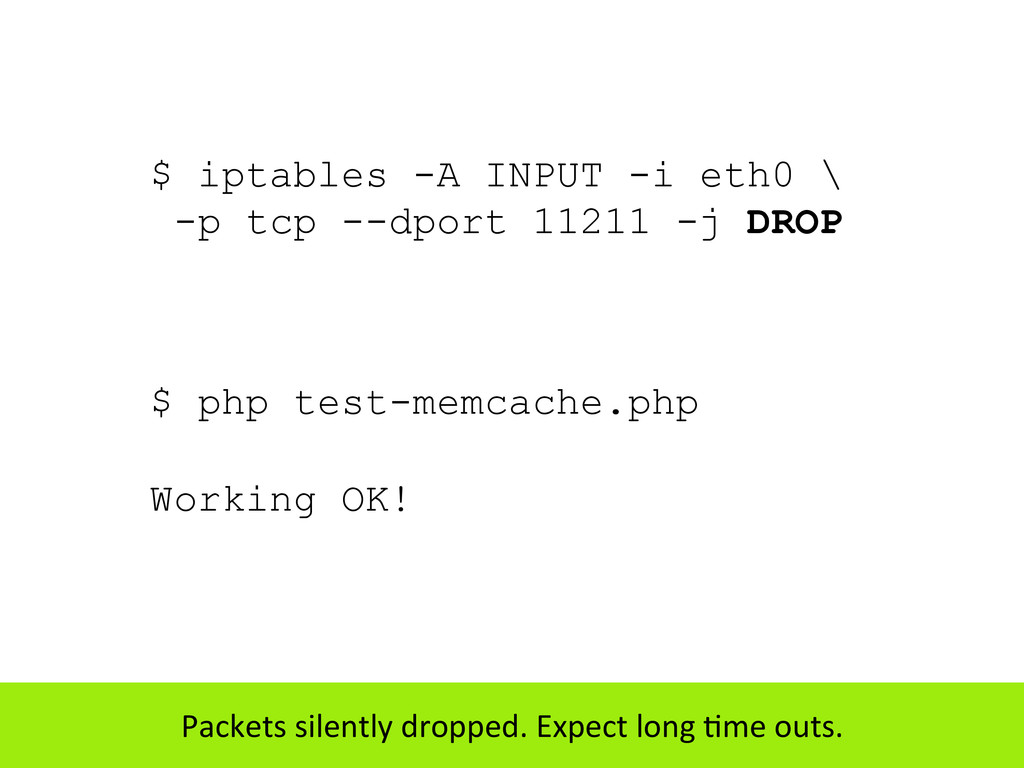
  20. $ iptables -A INPUT -i eth0 \ -p tcp --dport

    11211 -j DROP $ php test-memcache.php Working OK! Packets  silently  dropped.  Expect  long  @me  outs.  
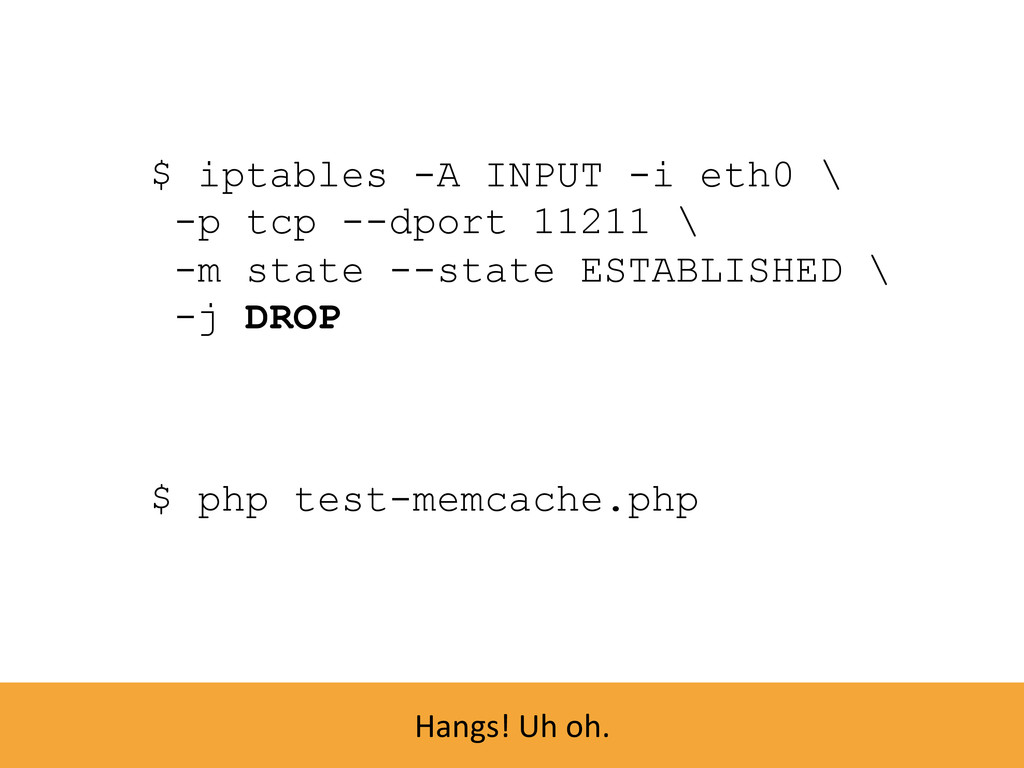
  21. $ iptables -A INPUT -i eth0 \ -p tcp --dport

    11211 \ -m state --state ESTABLISHED \ -j DROP $ php test-memcache.php Hangs!  Uh  oh.  
  22. • When  AWS  instances  hang  they   appear  to  accept  connec@ons

      but  drop  packets   • Bug!     hYps://bugs.launchpad.net/libmemcached/ +bug/583031  
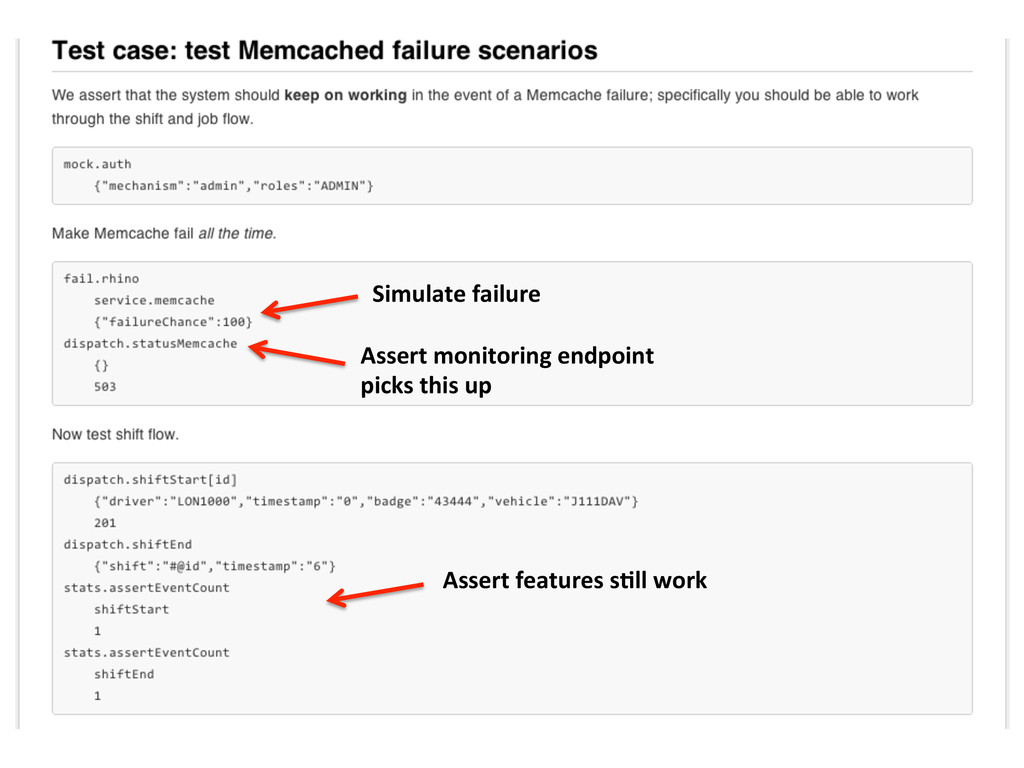
  23. • Hailo  run  a  dedicated  automated   test  environment   • Powered

     by  bash,  JMeter  and   Graphite   • Con@nuous  automated  tes@ng   with  failure  simula@ons  
  24. “the  best  way  to  avoid   failure  is  to  fail

     constantly.”         hYp://www.codinghorror.com/blog/2011/04/ working-­‐with-­‐the-­‐chaos-­‐monkey.html  
  25. Thanks     SoTware  used  at  Hailo   hYp://cassandra.apache.org/  

    hYp://zookeeper.apache.org/   hYp://[email protected]/   hYp://www.acunu.com/acunu-­‐[email protected]   hYps://github.com/bitly/nsq   hYps://github.com/davegardnerisme/cruTflake   hYps://github.com/davegardnerisme/nsqphp   Plus  a  load  of  other  things  I’ve  not  men@oned.  
  26. Further  reading   Hystrix:  Latency  and  Fault  Tolerance  for  Distributed

     Systems   hYps://github.com/Neslix/Hystrix   Timelike:  a  network  simulator   hYp://aphyr.com/posts/277-­‐@melike-­‐a-­‐network-­‐simulator   Notes  on  distributed  systems  for  young  bloods   hYp://www.somethingsimilar.com/2013/01/14/notes-­‐on-­‐distributed-­‐ systems-­‐for-­‐young-­‐bloods/   Stream  de-­‐duplica@on  (relevant  to  NSQ)   hYp://www.davegardner.me.uk/blog/2012/11/06/stream-­‐de-­‐ duplica@on/    ID  genera@on  in  distributed  systems   hYp://www.slideshare.net/davegardnerisme/unique-­‐id-­‐genera@on-­‐in-­‐ distributed-­‐systems  

More Decks by Dave Gardner

Other Decks in Technology