Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
[論文紹介] wav2vec 2.0: A Framework for Self-Superv...
Search
jumon
June 12, 2021
Research
2.3k
1
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
[論文紹介] wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations
jumon
June 12, 2021
Other Decks in Research
See All in Research
横浜市長(山中氏)の言動にかかる第三者による調査報告書
sishi2026
0
570
CVPR2026論文紹介_VLMにとって良いvision encoderとは何か?Rethinking Model Selection in VLM Through the Lens of Gromov-Wasserstein Distance
kobayashi31
1
250
RS-Agent: Automating Remote Sensing Tasks through Intelligent Agent
satai
3
590
[ACL 2026 Demo] Fast-MIA: Efficient and Scalable Membership Inference for LLMs
upura
0
130
Ghost in the 7‑Zip: The Shadow of Residential Proxies Creeping into Your Life
nttcom
0
2.1k
Language and AI
ayaniwa
0
310
[最先端NLP勉強会2026] Agentic Rubrics as Contextual Verifiers for SWE Agents
rfujii
1
370
SAKURAONE: An Open Ethernet-based AI HPC System And Its Observed Workload Dynamics in a Single-Tenant LLM Development Environment
yuukit
1
640
Evaluating LLM Reliability Across Facts, Evidence, and Cultures
yukiar
0
200
PGDM: Physically Guided Diffusion Model for L Downscaling
satai
3
510
量子サマースクール2026「量子計算機アーキテクチャ分野の概観」
youten622
1
950
最先端NLP勉強会2026 論文紹介:Reasoning with Sampling: Your Base Model is Smarter Than You Think (ICLR 2026 paper)
kogoro
4
660
Featured
See All Featured
Typedesign – Prime Four
hannesfritz
42
3.2k
It's Worth the Effort
3n
188
29k
Jess Joyce - The Pitfalls of Following Frameworks
techseoconnect
PRO
1
420
Fantastic passwords and where to find them - at NoRuKo
philnash
52
3.9k
A brief & incomplete history of UX Design for the World Wide Web: 1989–2019
jct
2
520
How Fast Is Fast Enough? [PerfNow 2025]
tammyeverts
3
910
Building Better People: How to give real-time feedback that sticks.
wjessup
370
20k
How to optimise 3,500 product descriptions for ecommerce in one day using ChatGPT
katarinadahlin
PRO
3
3.8k
Building AI with AI
inesmontani
PRO
1
1.3k
Winning Ecommerce Organic Search in an AI Era - #searchnstuff2025
aleyda
2
2.2k
Public Speaking Without Barfing On Your Shoes - THAT 2023
reverentgeek
1
580
How To Stay Up To Date on Web Technology
chriscoyier
790
250k
Transcript
1 野崎 樹⽂(Jumon Nozaki) 2021 年 6 ⽉ 9 ⽇
研究室輪講 wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations [Baevski et al. NeurIPS2020] 京都⼤学 ⾳声メディア研究室 修⼠⼀回⽣
研究概要 • ⾳声データに対する新たな⾃⼰教師あり学習の枠組みである wav2vec 2.0 を提案 • ⾃⼰教師あり学習を⾏った wav2vec 2.0
をラベル付きデータで ファインチューニングすることで⾼い⾳声認識精度を達成 • Librispeech コーパスのわずか 10 分の教師データで学習し, 単語誤り率 4.8% の認識精度 2
研究背景 • 学習データを減らしたい • ディープラーニングの学習には⼤量のデータが必要 • 世界の多くの⾔語では学習に⼗分な量のデータの確保は困難 Ø ラベルなしデータから汎⽤的な表現を学習する⾃⼰教師あり学習へ •
⾃⼰教師あり学習の興隆 q ⾃然⾔語処理 • BERT [Delvin+, 2018], GPT-2 [Radford+, 2018] q コンピュータビジョン [Henfaff+, 2019] q ⾳声 • wav2vec [Schneider+, 2019], vq-wav2vec [Baevski+, 2020] Ø よりよい⾃⼰教師あり学習へ 3
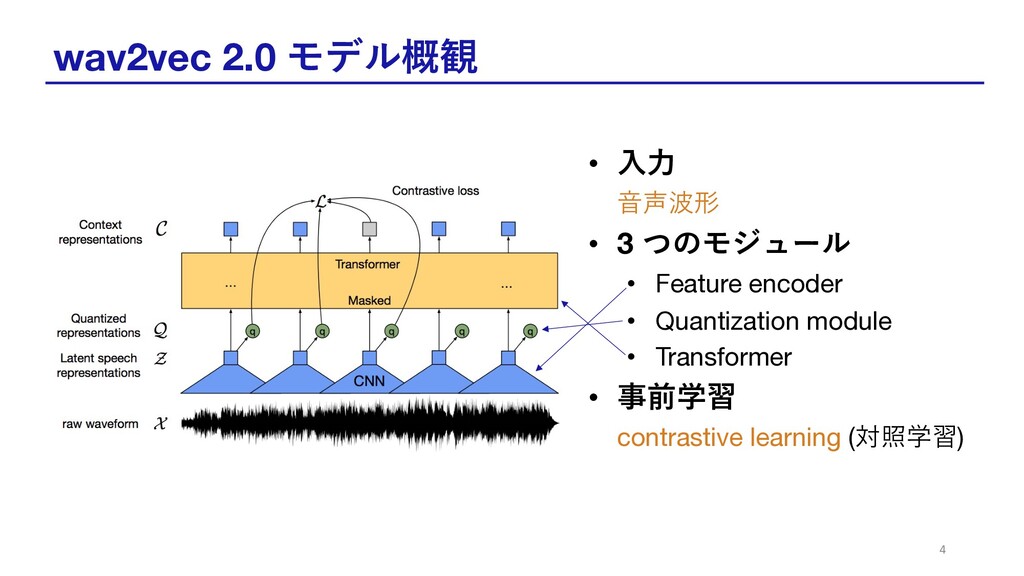
wav2vec 2.0 モデル概観 • ⼊⼒ ⾳声波形 • 3 つのモジュール •
Feature encoder • Quantization module • Transformer • 事前学習 contrastive learning (対照学習) 4
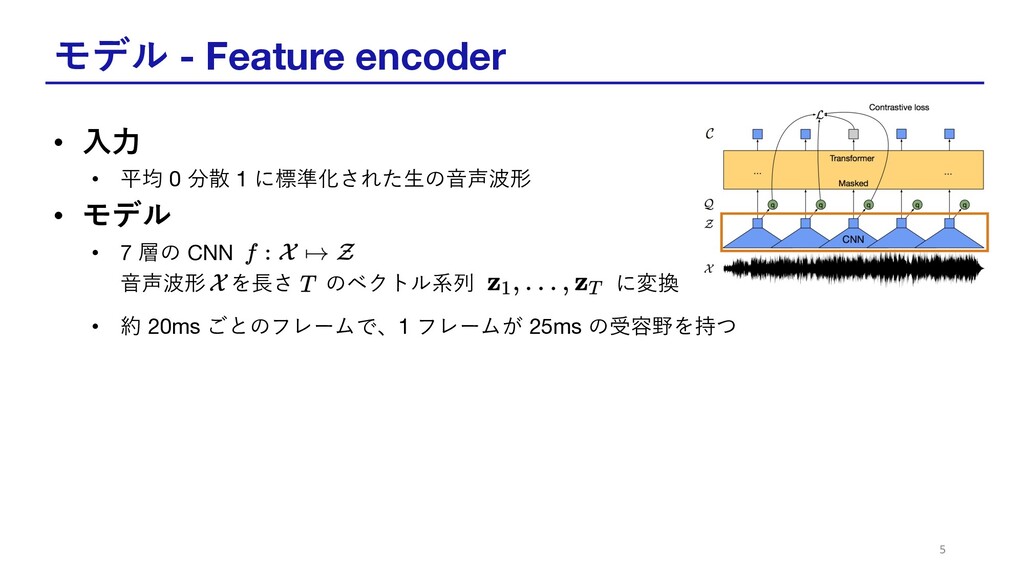
モデル - Feature encoder • ⼊⼒ • 平均 0 分散
1 に標準化された⽣の⾳声波形 • モデル • 7 層の CNN ⾳声波形 を⻑さ のベクトル系列 に変換 • 約 20ms ごとのフレームで、1 フレームが 25ms の受容野を持つ 5
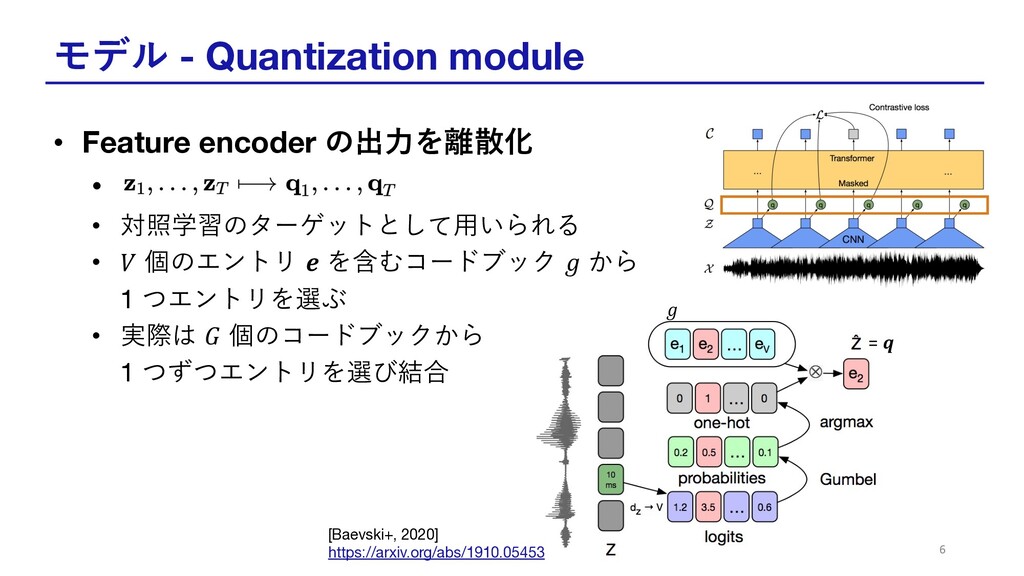
モデル - Quantization module • Feature encoder の出⼒を離散化 • •
対照学習のターゲットとして⽤いられる • 𝑉 個のエントリ 𝒆 を含むコードブック 𝑔 から 1 つエントリを選ぶ • 実際は 𝐺 個のコードブックから 1 つずつエントリを選び結合 6 = 𝒒 𝑔 [Baevski+, 2020] https://arxiv.org/abs/1910.05453
モデル - Quantization module – Gumbel-Softmax • Gumbel-Softmax [Jang+, 2016]
の使⽤ • 微分可能な形でコードブックからのサンプリングを⾏う • Feature encoder の出⼒ 𝑧 を線形層で に変換(𝑉: エントリ数) • 学習時はエントリ 𝑗 を選ぶ確率 を以下の様に求める • : (0, 1) の⼀様分布からのサンプル • : softmax 温度, ハイパーパラメータ • forward 時は の argmax をとる backward 時は で勾配を近似 ( : one-hot vector) = straight-through estimator 7 = 𝒒 𝑔 [Baevski+, 2020] https://arxiv.org/abs/1910.05453 ,
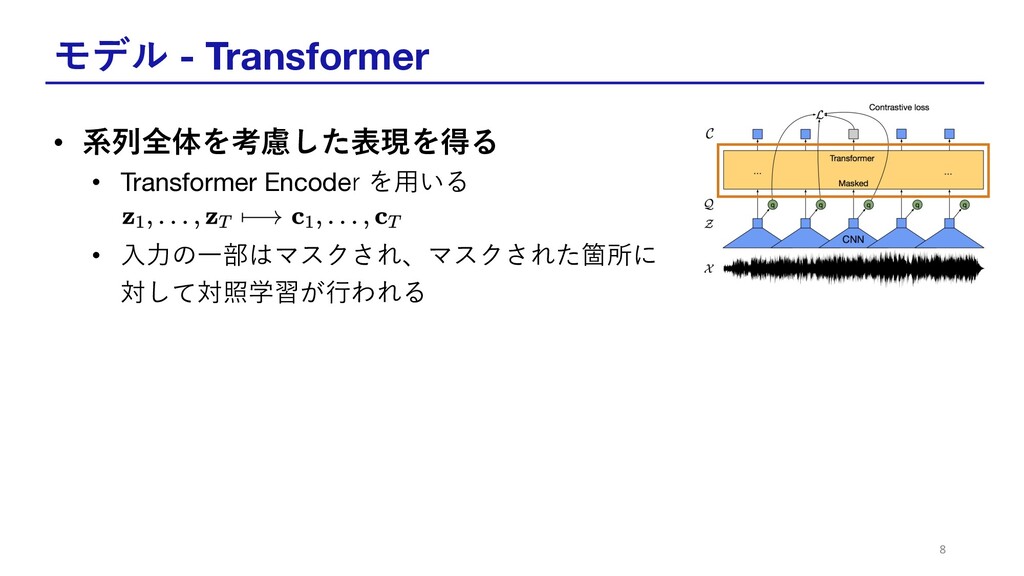
モデル - Transformer • 系列全体を考慮した表現を得る • Transformer Encoder を⽤いる •
⼊⼒の⼀部はマスクされ、マスクされた箇所に 対して対照学習が⾏われる 8
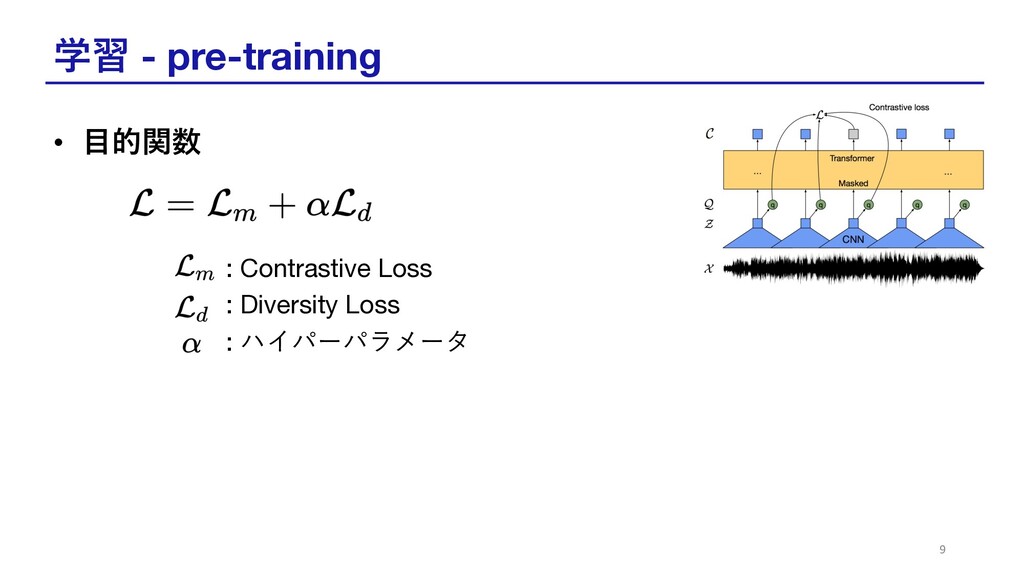
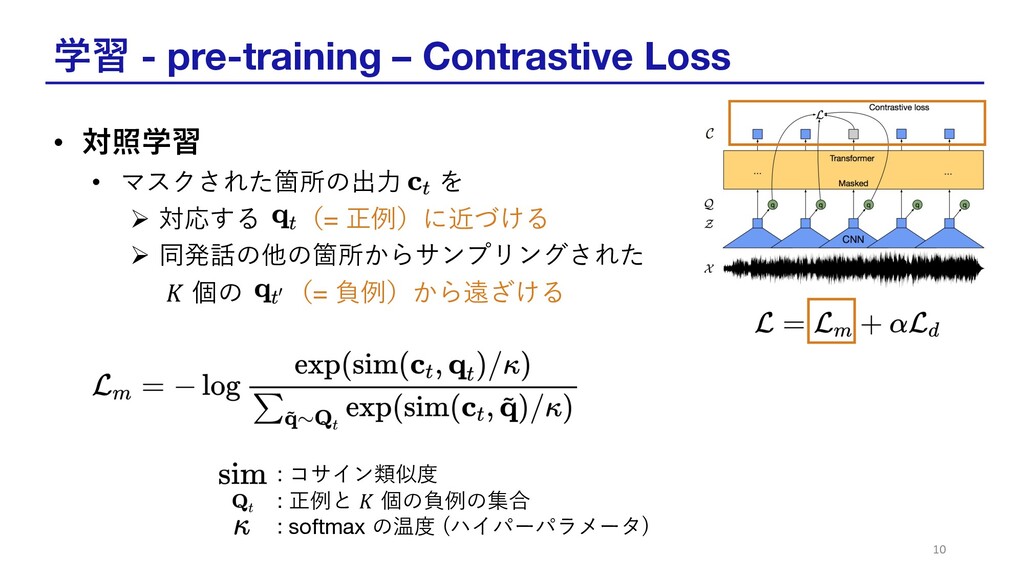
学習 - pre-training • ⽬的関数 : Contrastive Loss : Diversity
Loss : ハイパーパラメータ 9
学習 - pre-training – Contrastive Loss • 対照学習 • マスクされた箇所の出⼒
を Ø 対応する (= 正例)に近づける Ø 同発話の他の箇所からサンプリングされた 𝐾 個の (= 負例)から遠ざける 10 : コサイン類似度 : 正例と 𝐾 個の負例の集合 : softmax の温度 (ハイパーパラメータ)
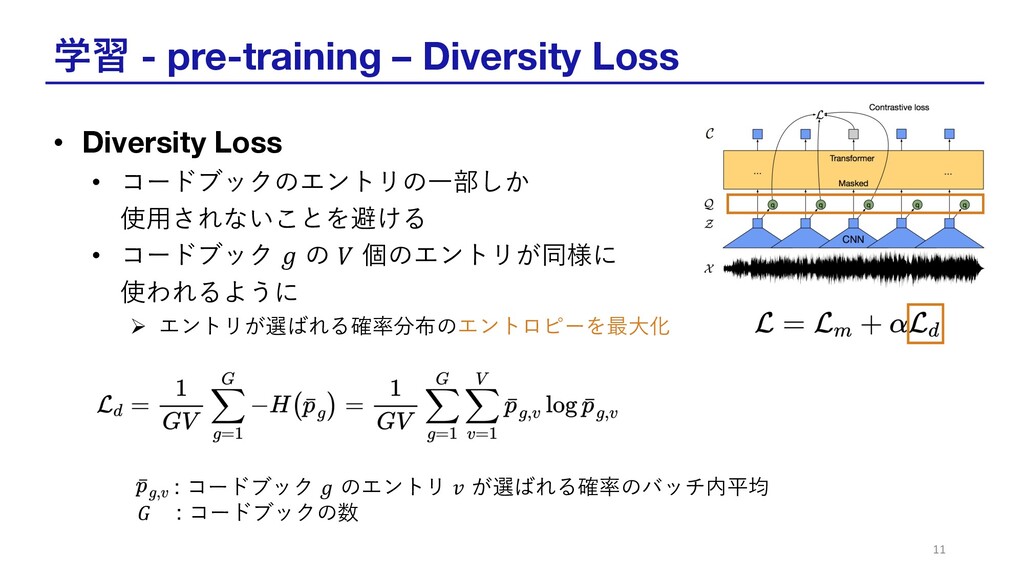
学習 - pre-training – Diversity Loss • Diversity Loss •
コードブックのエントリの⼀部しか 使⽤されないことを避ける • コードブック 𝑔 の 𝑉 個のエントリが同様に 使われるように Ø エントリが選ばれる確率分布のエントロピーを最⼤化 11 : コードブック 𝑔 のエントリ 𝑣 が選ばれる確率のバッチ内平均 𝐺 : コードブックの数
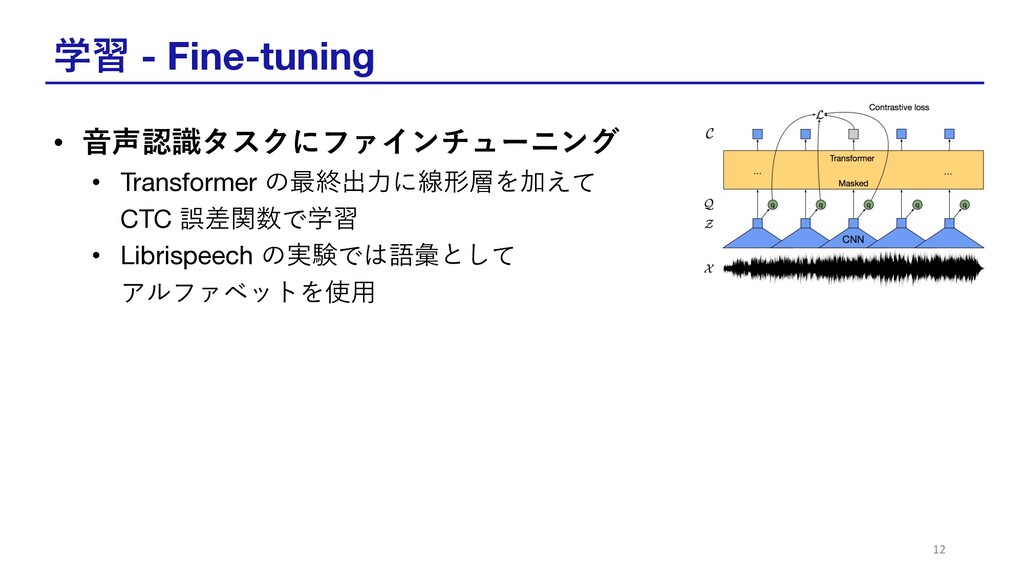
学習 - Fine-tuning • ⾳声認識タスクにファインチューニング • Transformer の最終出⼒に線形層を加えて CTC 誤差関数で学習
• Librispeech の実験では語彙として アルファベットを使⽤ 12
実験 – データセット • 事前学習 • ⾳声のみを使⽤(ラベルは使わない) • データ量の異なる 2
パターンの設定 • Librispeech (960 時間) • LisbriVox (約 60,000 時間) • ファインチューニング • ⾳声とラベルを使⽤ • データ量の異なる 5 パターンの Librispeech サブセット • 960 時間, 100 時間, 10 時間, 1 時間, 10 分 13
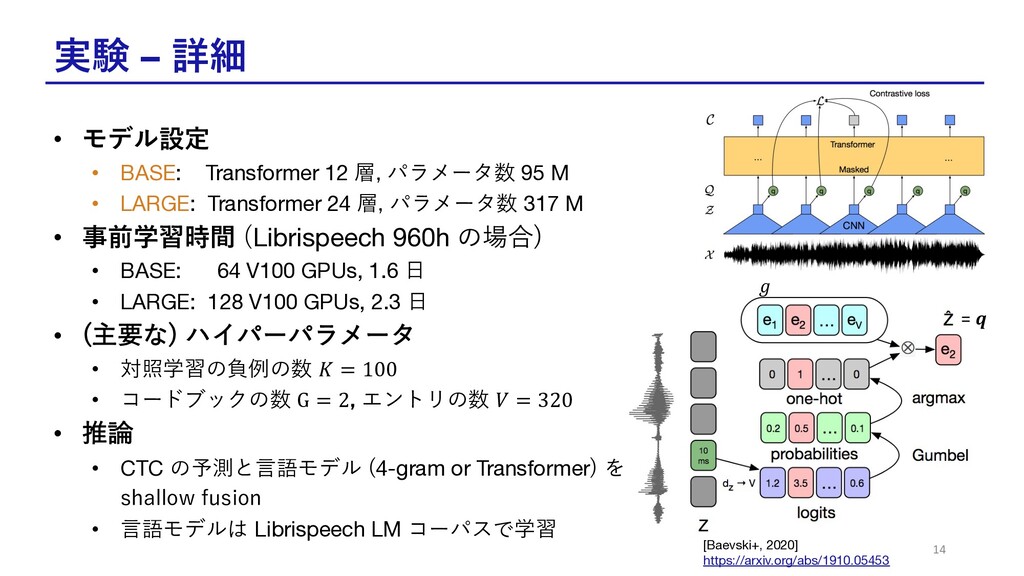
実験 – 詳細 • モデル設定 • BASE: Transformer 12 層,
パラメータ数 95 M • LARGE: Transformer 24 層, パラメータ数 317 M • 事前学習時間 (Librispeech 960h の場合) • BASE: 64 V100 GPUs, 1.6 ⽇ • LARGE: 128 V100 GPUs, 2.3 ⽇ • (主要な) ハイパーパラメータ • 対照学習の負例の数 𝐾 = 100 • コードブックの数 G = 2, エントリの数 𝑉 = 320 • 推論 • CTC の予測と⾔語モデル (4-gram or Transformer) を shallow fusion • ⾔語モデルは Librispeech LM コーパスで学習 14 = 𝒒 𝑔 [Baevski+, 2020] https://arxiv.org/abs/1910.05453
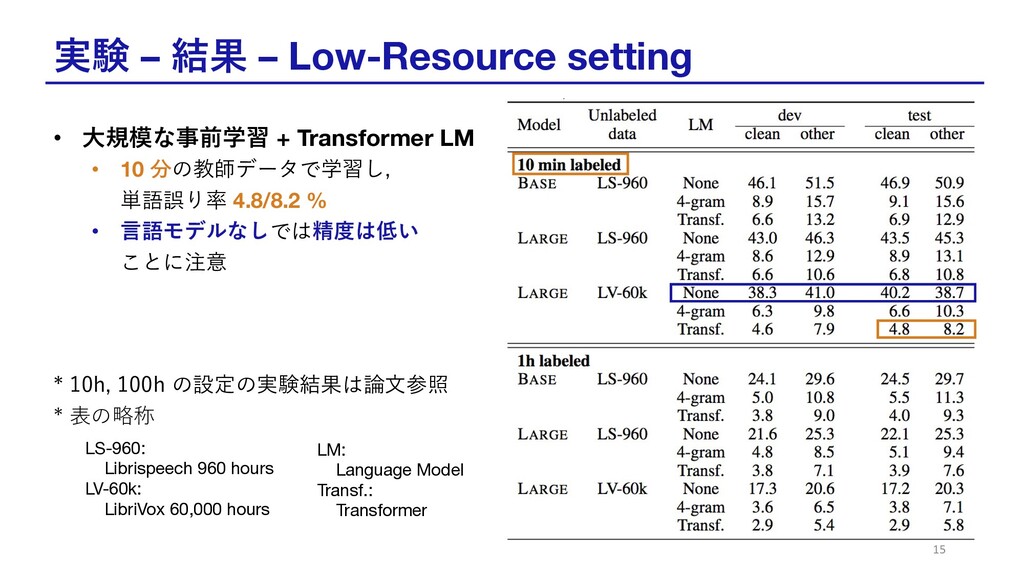
実験 – 結果 – Low-Resource setting • ⼤規模な事前学習 + Transformer
LM • 10 分の教師データで学習し, 単語誤り率 4.8/8.2 % • ⾔語モデルなしでは精度は低い ことに注意 * 10h, 100h の設定の実験結果は論⽂参照 * 表の略称 15 LM: Language Model Transf.: Transformer LS-960: Librispeech 960 hours LV-60k: LibriVox 60,000 hours
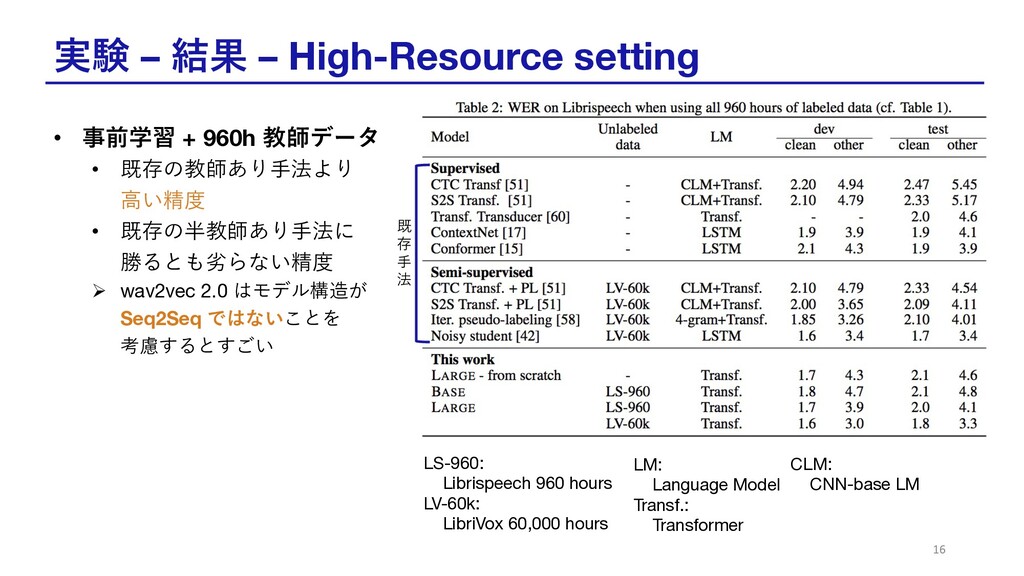
実験 – 結果 – High-Resource setting • 事前学習 + 960h
教師データ • 既存の教師あり⼿法より ⾼い精度 • 既存の半教師あり⼿法に 勝るとも劣らない精度 Ø wav2vec 2.0 はモデル構造が Seq2Seq ではないことを 考慮するとすごい 16 LM: Language Model Transf.: Transformer LS-960: Librispeech 960 hours LV-60k: LibriVox 60,000 hours CLM: CNN-base LM 既 存 ⼿ 法
まとめ • ⾳声データに対する新たな⾃⼰教師あり学習の枠組みである wav2vec 2.0 を提案 • 事前学習では離散化した⾳声をターゲットとした対照学習を⾏う • 事前学習後に
CTC Loss でファインチューニングすることで ⾼い⾳声認識精度を達成 • Librispeech コーパスのわずか 10 分の教師データで学習し, 単語誤り率 4.8% の認識精度 • ⼤量の教師データを⽤いた場合も事前学習の効果がある 17


 sishi2026
 kobayashi31
 satai
 upura
 nttcom
 ayaniwa
 rfujii
 yuukit
 yukiar
 youten622
 kogoro
 hannesfritz
 3n
 techseoconnect
 philnash
 jct
 tammyeverts
 wjessup
 katarinadahlin
 inesmontani
 aleyda
 reverentgeek
 chriscoyier