Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
[ACL 2026 Demo] Fast-MIA: Efficient and Scalabl...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Shotaro Ishihara
May 12, 2026
Research
160
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
[ACL 2026 Demo] Fast-MIA: Efficient and Scalable Membership Inference for LLMs
https://aclanthology.org/2026.acl-demo.9/
https://github.com/Nikkei/fast-mia
Shotaro Ishihara
May 12, 2026
Transcript
9 slides
Hiromu Takahashi and Shotaro Ishihara ACL 2026 System Demonstrations Fast-MIA:
Efficient and Scalable Membership Inference for LLMs
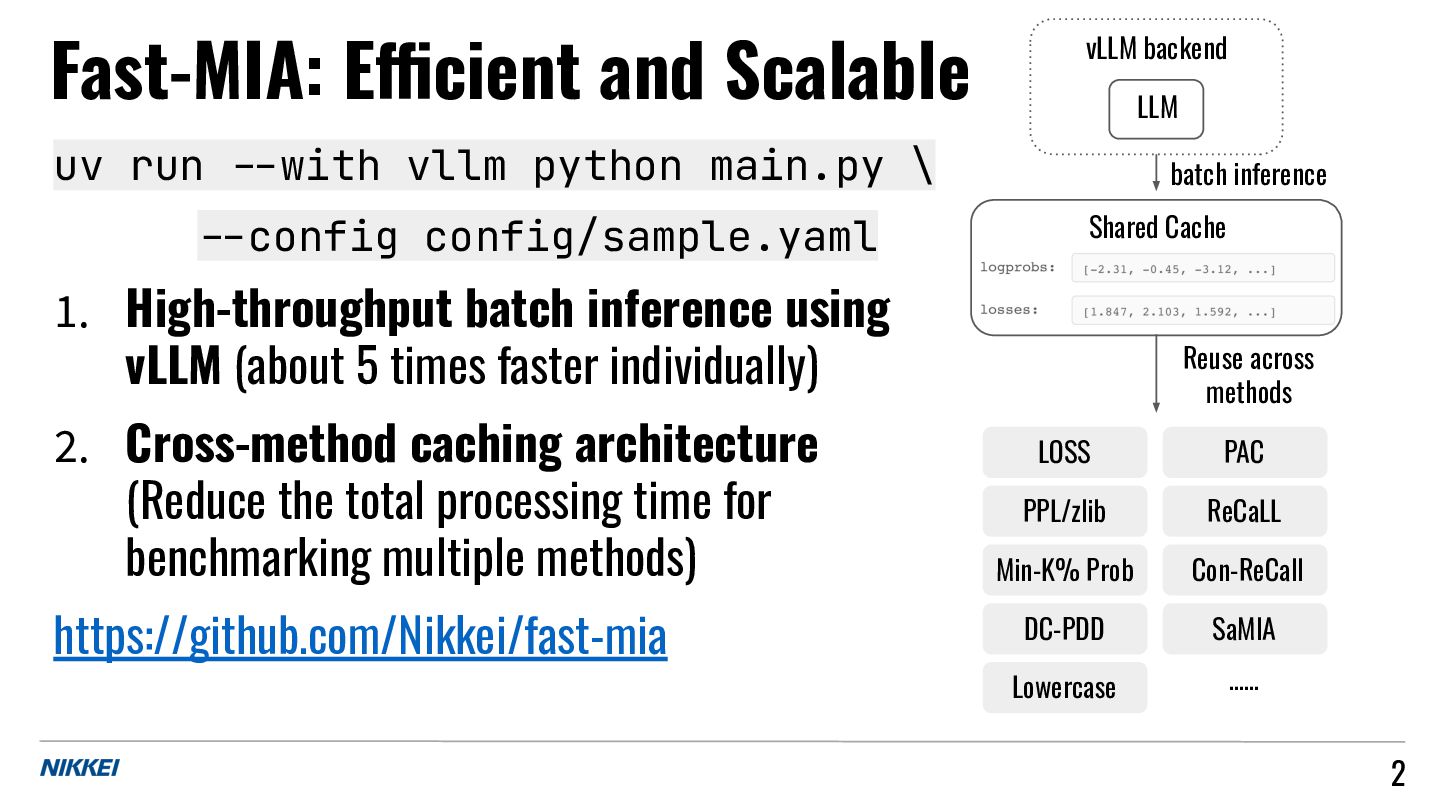
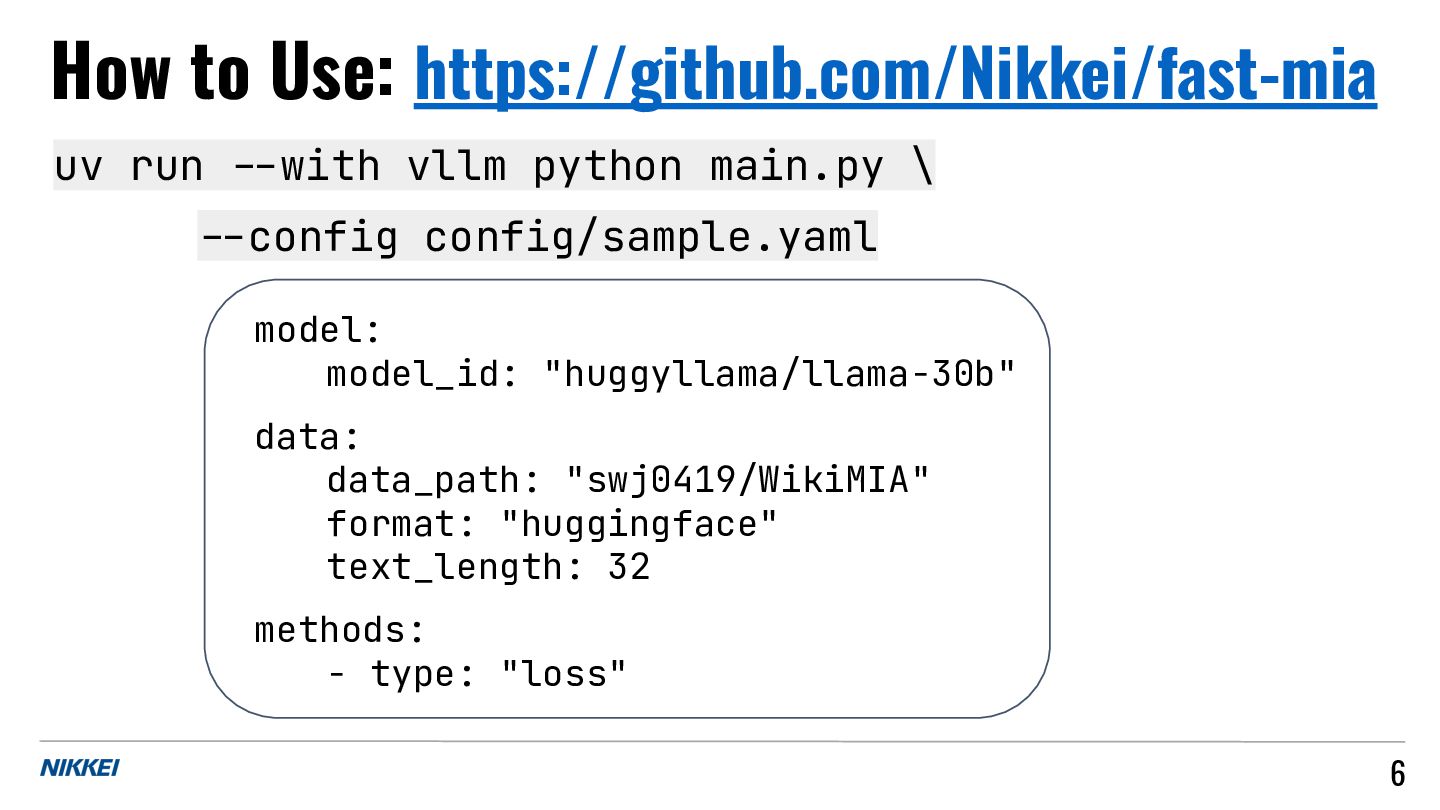
uv run --with vllm python main.py \ --config config/sample.yaml 1.
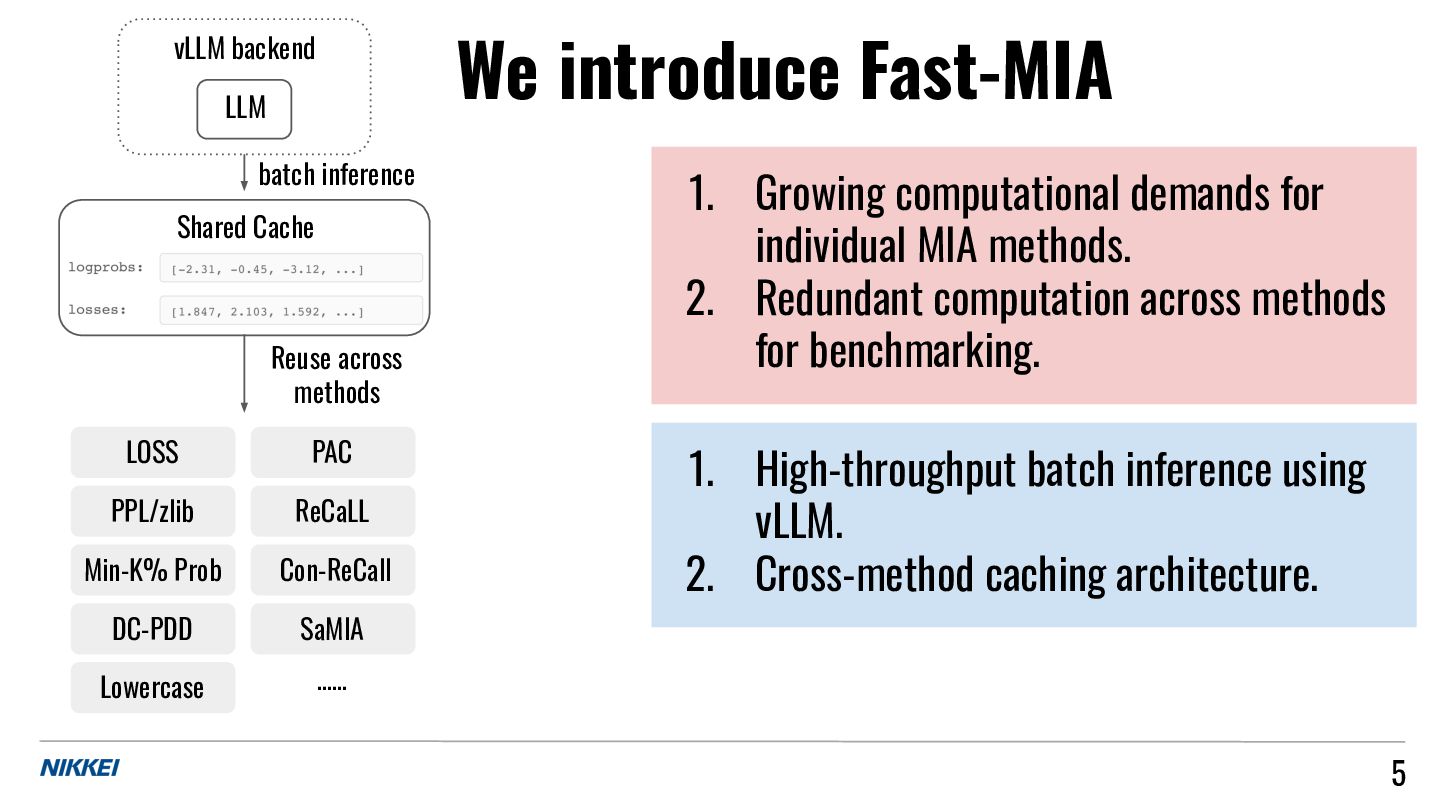
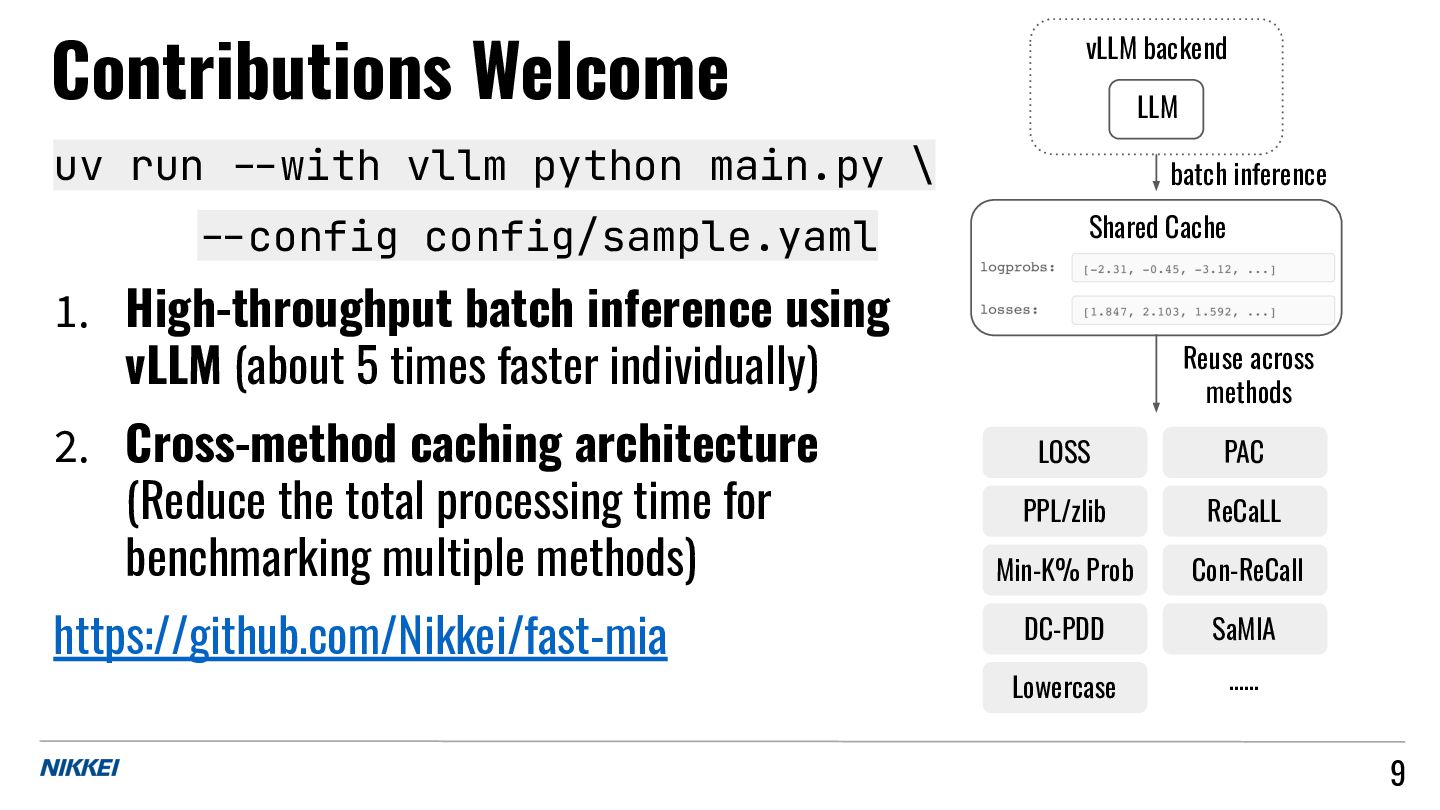
High-throughput batch inference using vLLM (about 5 times faster individually) 2. Cross-method caching architecture (Reduce the total processing time for benchmarking multiple methods) https://github.com/Nikkei/fast-mia Fast-MIA: Efficient and Scalable 2 LLM LOSS vLLM backend batch inference Shared Cache Reuse across methods PPL/zlib Min-K% Prob DC-PDD Lowercase PAC ReCaLL Con-ReCall SaMIA ……
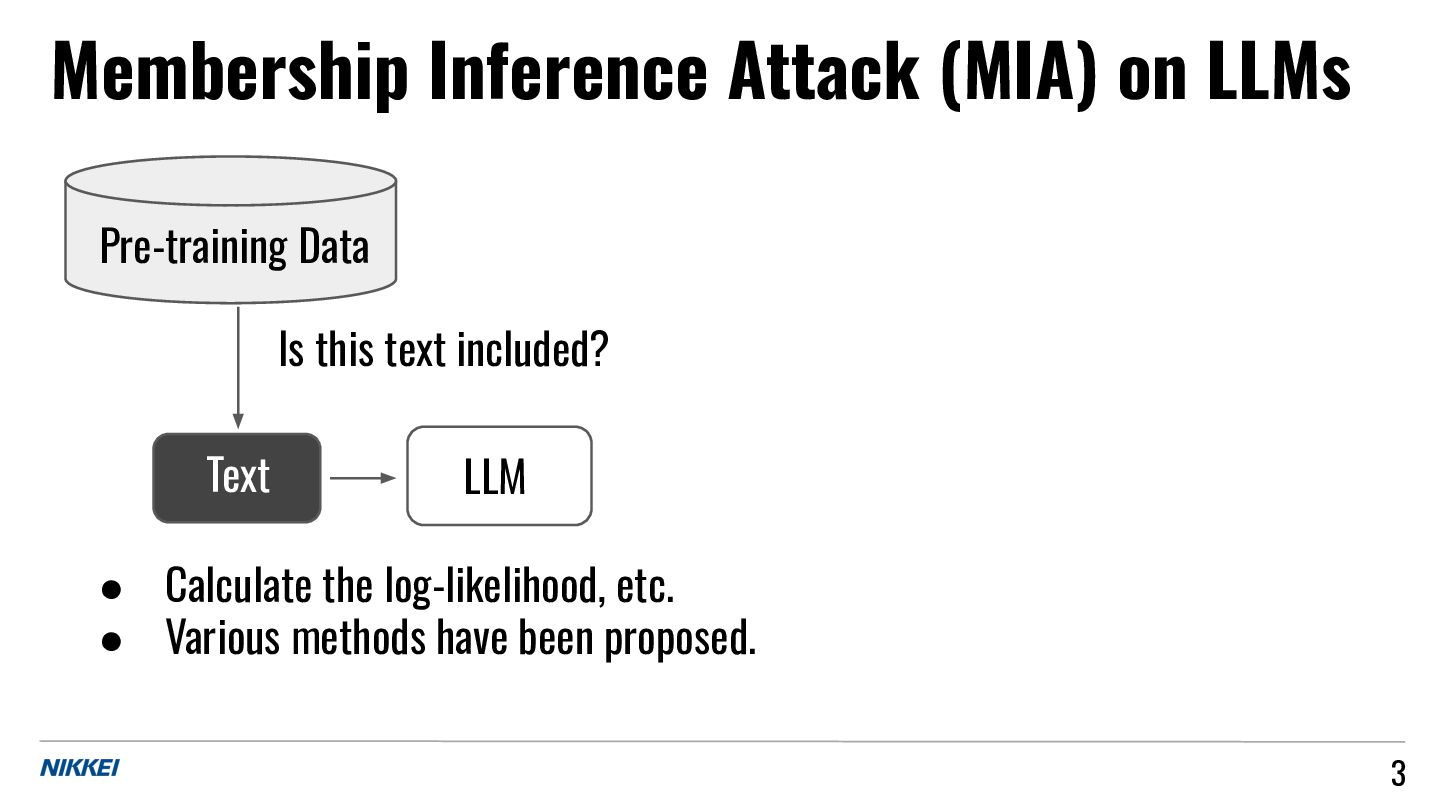
Membership Inference Attack (MIA) on LLMs 3 LLM Is this
text included? Text Pre-training Data • Calculate the log-likelihood, etc. • Various methods have been proposed.
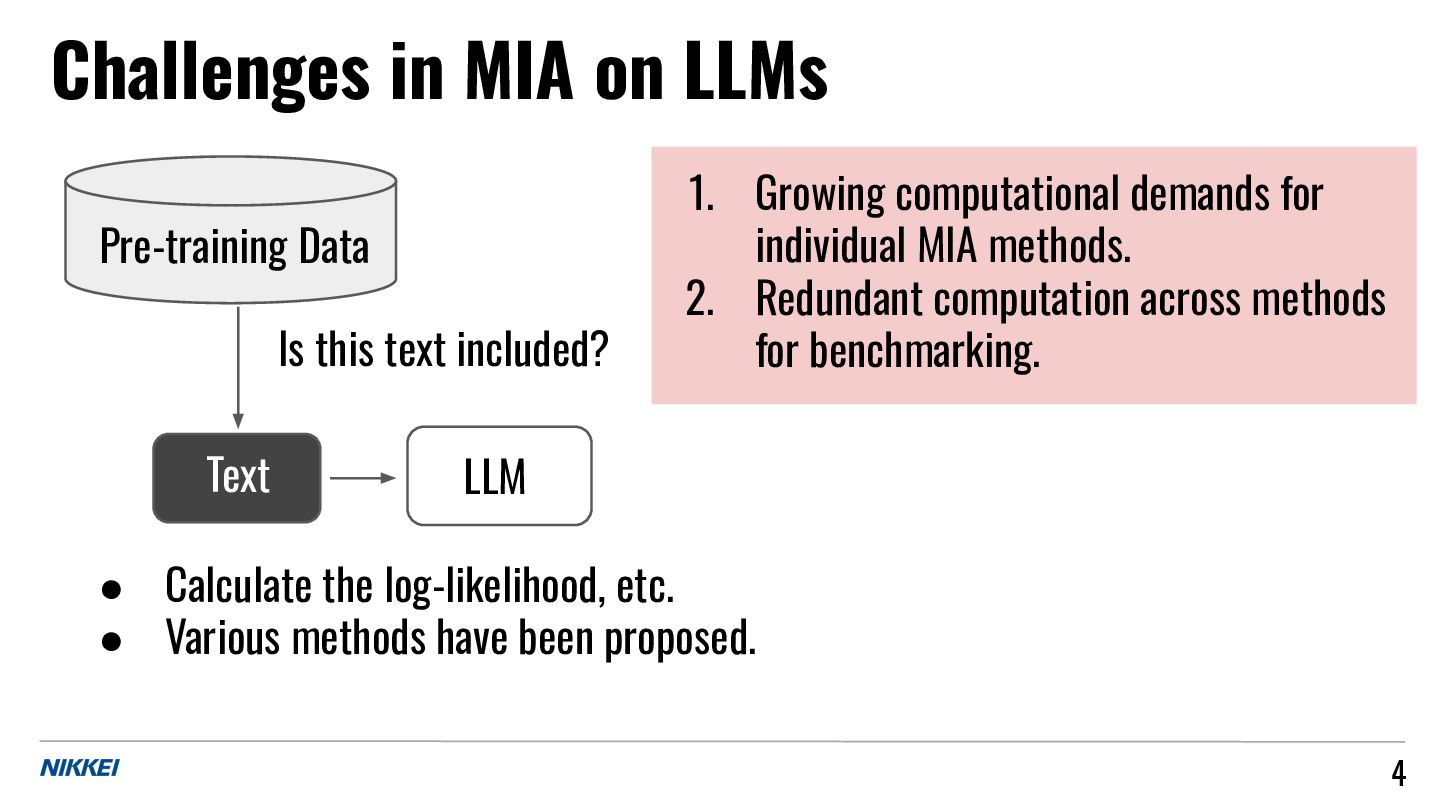
Challenges in MIA on LLMs 4 LLM Is this text
included? Text Pre-training Data • Calculate the log-likelihood, etc. • Various methods have been proposed. 1. Growing computational demands for individual MIA methods. 2. Redundant computation across methods for benchmarking.
We introduce Fast-MIA 5 1. Growing computational demands for individual
MIA methods. 2. Redundant computation across methods for benchmarking. LLM LOSS vLLM backend batch inference Shared Cache Reuse across methods PPL/zlib Min-K% Prob DC-PDD Lowercase PAC ReCaLL Con-ReCall SaMIA …… 1. High-throughput batch inference using vLLM. 2. Cross-method caching architecture.
uv run --with vllm python main.py \ --config config/sample.yaml How
to Use: https://github.com/Nikkei/fast-mia 6 model: model_id: "huggyllama/llama-30b" data: data_path: "swj0419/WikiMIA" format: "huggingface" text_length: 32 methods: - type: "loss"
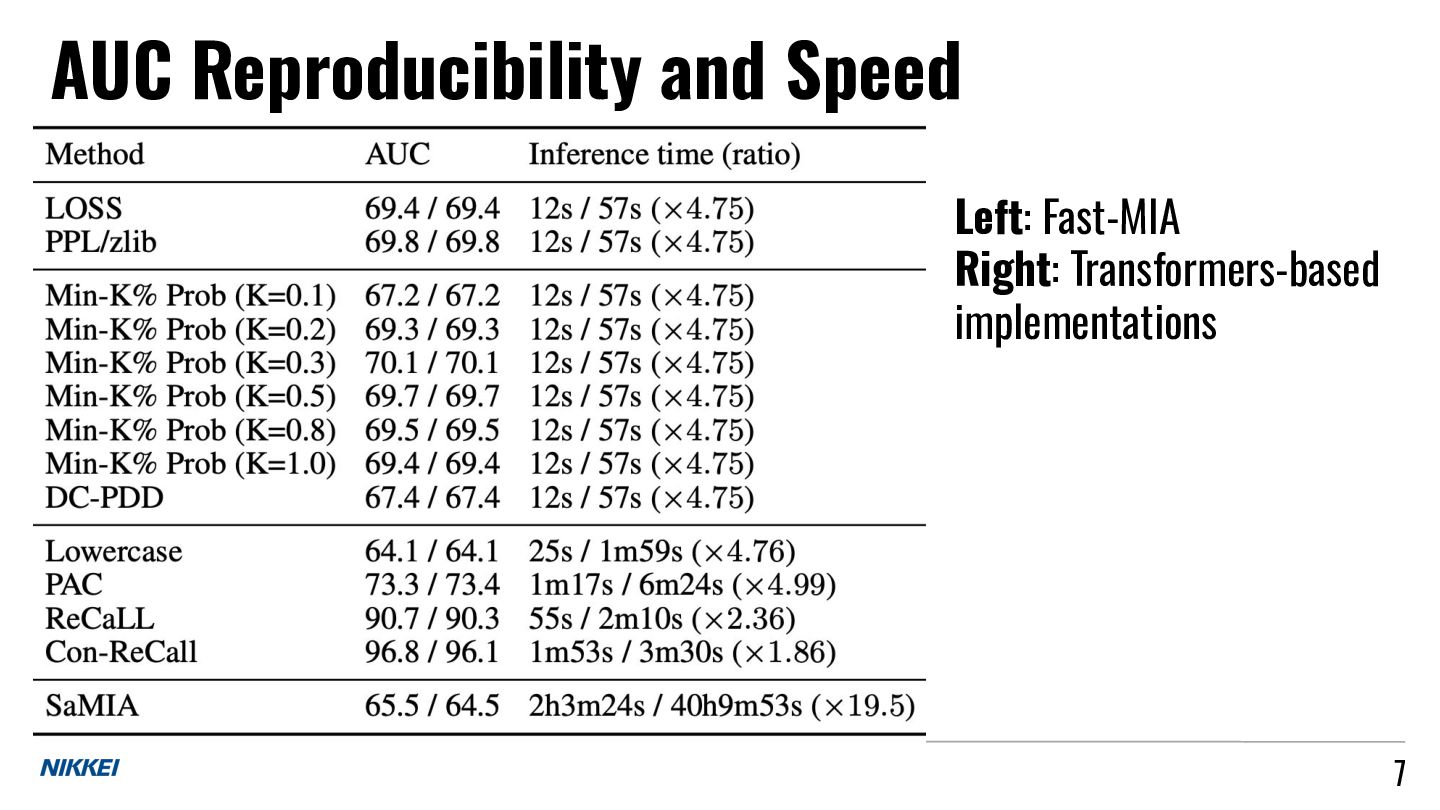
AUC Reproducibility and Speed 7 Left: Fast-MIA Right: Transformers-based implementations
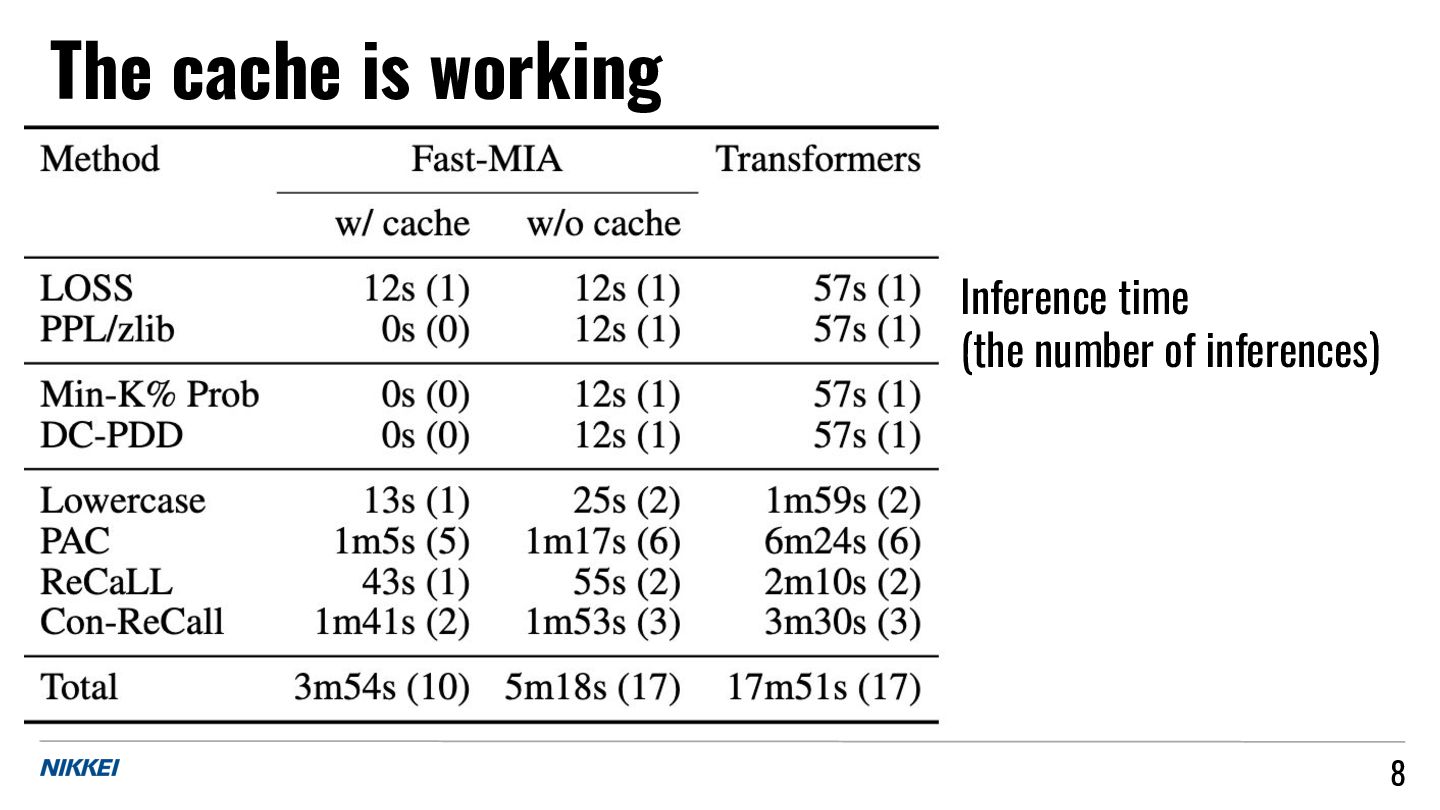
Inference time (the number of inferences) The cache is working
8
uv run --with vllm python main.py \ --config config/sample.yaml 1.
High-throughput batch inference using vLLM (about 5 times faster individually) 2. Cross-method caching architecture (Reduce the total processing time for benchmarking multiple methods) https://github.com/Nikkei/fast-mia Contributions Welcome 9 LLM LOSS vLLM backend batch inference Shared Cache Reuse across methods PPL/zlib Min-K% Prob DC-PDD Lowercase PAC ReCaLL Con-ReCall SaMIA ……
More Decks by Shotaro Ishihara
See All by Shotaro Ishihara
Generative News Recommendation Reproduces Popularity: A Memorization-Based Analysis
upura
0
18
Agent 時代の Kaggle 展望 / kaggle-in-the-agentic-era
upura
1
1.5k
大規模言語モデルは誰を覚えているか / Who Do Large Language Models Memorize?
upura
0
250
Fast-MIA: Efficient and Scalable Membership Inference for LLMs
upura
0
120
JAPAN AI CUP Prediction Tutorial
upura
2
1.4k
情報技術の社会実装に向けた応用と課題:ニュースメディアの事例から / appmech-jsce 2025
upura
0
500
日本語新聞記事を用いた大規模言語モデルの暗記定量化 / LLMC2025
upura
0
850
Quantifying Memorization in Continual Pre-training with Japanese General or Industry-Specific Corpora
upura
1
170
JOAI2025講評 / joai2025-review
upura
0
1.9k
Other Decks in Research
See All in Research
湯村研究室の紹介2026 / yumulab2026
yumulab
PRO
0
260
JPA2026_NetworkTutorial_JunKashihara
junkashihara
0
280
[SNLP2026] Scaling up Test-Time Compute with Latent Reasoning: A Recurrent Depth Approach
wataruuuuu
0
380
Bilan travail en élevage : première restitution des enquêtes 2025-2026
institutdelelevage
PRO
0
220
最先端NLP 2026 論文紹介: Wait, Wait, Wait... Why Do Reasoning Models Loop? / SNLP Paper Review: Wait, Wait, Wait... Why Do Reasoning Models Loop?
tkng
0
280
Santé et fertilité des sols : ce que nous disent les pratiques dans les systèmes de polyculture-élevage
institutdelelevage
PRO
0
160
GeoAgent勉強会 論文紹介と強い推論モデルが与えるインパクト
satai
5
510
論文紹介:Doc-to-LoRA: Learning to Instantly Internalize Contexts
yukako_nakano
0
240
Kunai: Toward a Verifier-Safe Layered DSL for Nested Encapsulation Packet Filtering on eBPF
takehaya
1
210
Who’s Behind the Divide?
sirmatrixpage
1
1.6k
Byzantine Eventual Consistency for Reliable Local-First Software
ept
0
420
ふとした出会いで生まれたSkillが、 社内利用1位になるまで
mikimhk
22
25k
Featured
See All Featured
What Being in a Rock Band Can Teach Us About Real World SEO
427marketing
0
1.1k
Become a Pro
speakerdeck
PRO
31
6.4k
Dealing with People You Can't Stand - Big Design 2015
cassininazir
367
27k
Google's AI Overviews - The New Search
badams
0
1.7k
Chasing Engaging Ingredients in Design
codingconduct
0
400
How to Talk to Developers About Accessibility
jct
2
630
Money Talks: Using Revenue to Get Sh*t Done
nikkihalliwell
0
570
StorybookのUI Testing Handbookを読んだ
zakiyama
31
7.1k
How Software Deployment tools have changed in the past 20 years
geshan
3
35k
The Language of Interfaces
destraynor
162
27k
Marketing to machines
jonoalderson
1
6k
Visualization
eitanlees
153
17k


 upura
 yumulab
 junkashihara
 wataruuuuu
 institutdelelevage
 tkng
 satai
 yukako_nakano
 takehaya
 sirmatrixpage
 ept
 mikimhk
 427marketing
 speakerdeck
 cassininazir
 badams
 codingconduct
 jct
 nikkihalliwell
 zakiyama
 geshan
 destraynor
 jonoalderson
 eitanlees