Upgrade to Pro — share decks privately, control downloads, hide ads and more …

秒間30万リクエストを捌く オンプレ広告配信システムの Kubernetes移行

秒間30万リクエストを捌く オンプレ広告配信システムの Kubernetes移行

2026/10/21 CloudNative Days Winter 2026 プレイベント
秒間30万リクエストを捌く オンプレ広告配信システムの Kubernetes移行

More Decks by 株式会社マイクロアド(システム開発部)

Transcript

  1. 今日話すこと • はじめに ◦ ◦ ◦ • • • 自己紹介

    広告配信システムについて マイクロアドのインフラ環境 HW ピンニングの話 ネットワークの話(今日のメイン) まとめ 2
  2. 自己紹介 名前 齊藤 大貴(さいとう だいき) 会社情報 株式会社マイクロアド(東証グロース: 9553) データプラットフォーム事業 所属

    システム開発部/ Platform Engineering Unit 趣味 カラオケ、ウォーキング Linkedin https://www.linkedin.com/in/daiki-saito/ 3
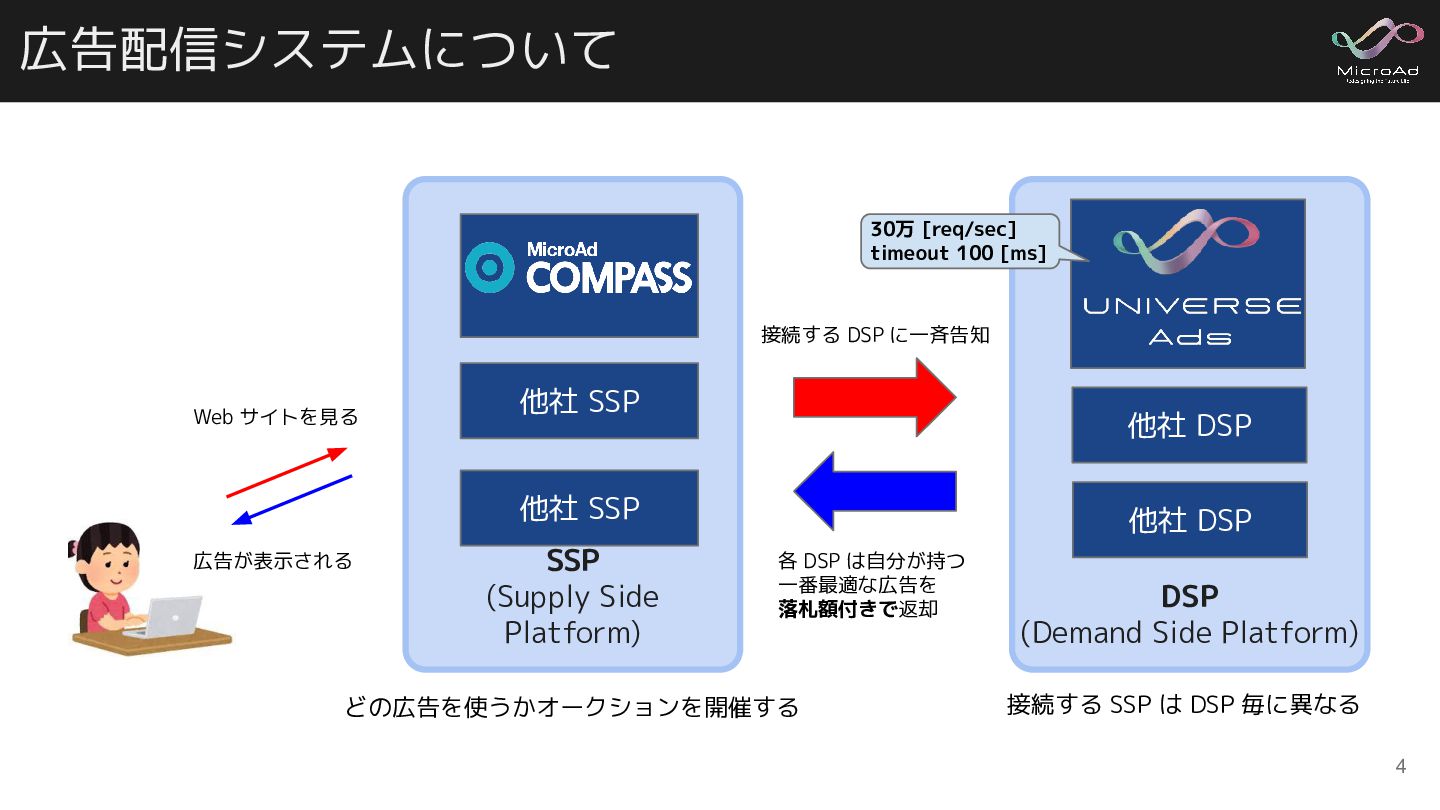
  3. 広告配信システムについて 30万 [req/sec] timeout 100 [ms] 接続する DSP に一斉告知 Web

    サイトを見る 他社 SSP 他社 DSP 他社 SSP 広告が表示される SSP (Supply Side Platform) 他社 DSP 各 DSP は自分が持つ 一番最適な広告を 落札額付きで返却 どの広告を使うかオークションを開催する DSP (Demand Side Platform) 接続する SSP は DSP 毎に異なる 4
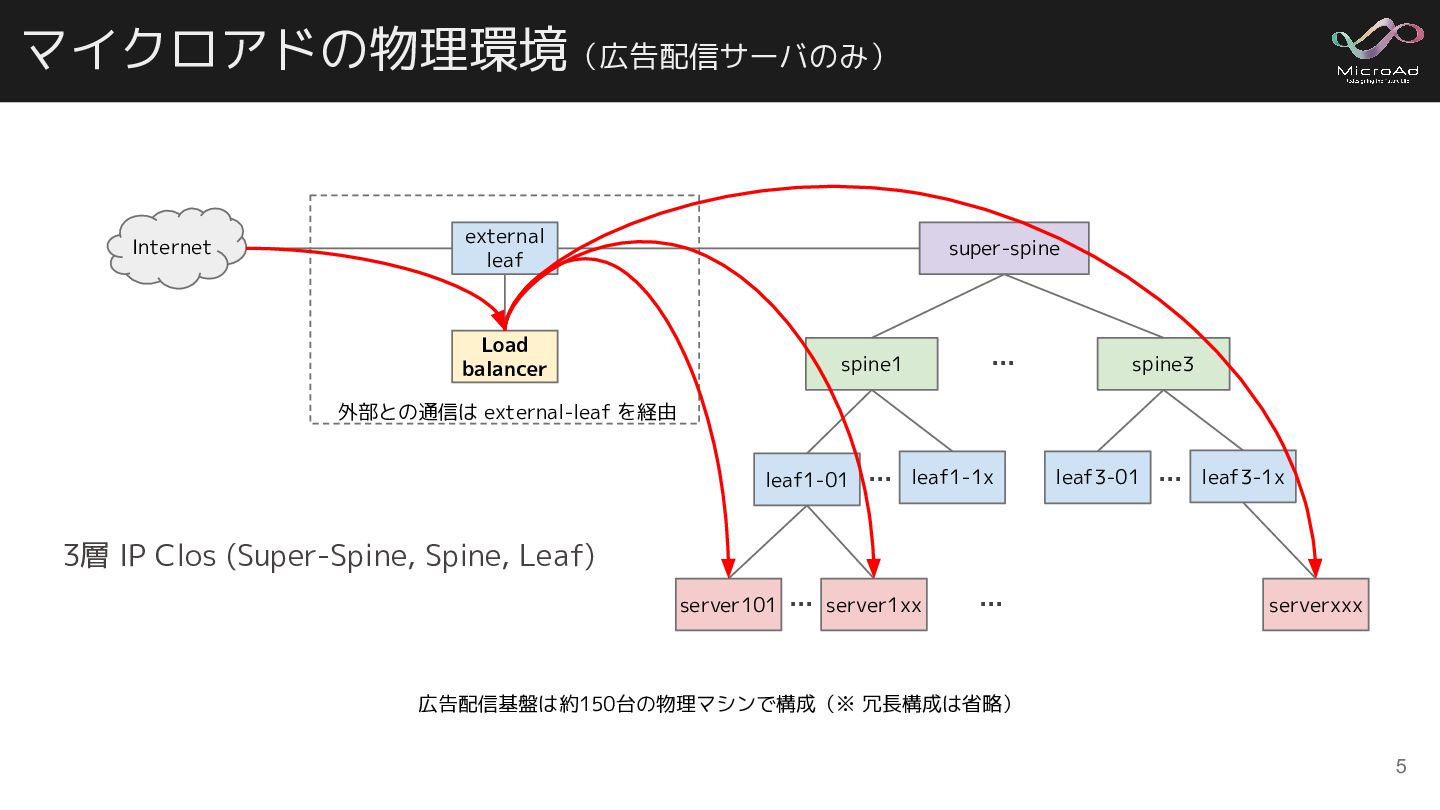
  4. マイクロアドの物理環境(広告配信サーバのみ) Internet external leaf Load balancer super-spine spine1 … spine3

    外部との通信は external-leaf を経由 leaf1-01 … leaf1-1x leaf3-01 … leaf3-1x 3層 IP Clos (Super-Spine, Spine, Leaf) server101 … server1xx … serverxxx 広告配信基盤は約150台の物理マシンで構成(※ 冗長構成は省略) 5
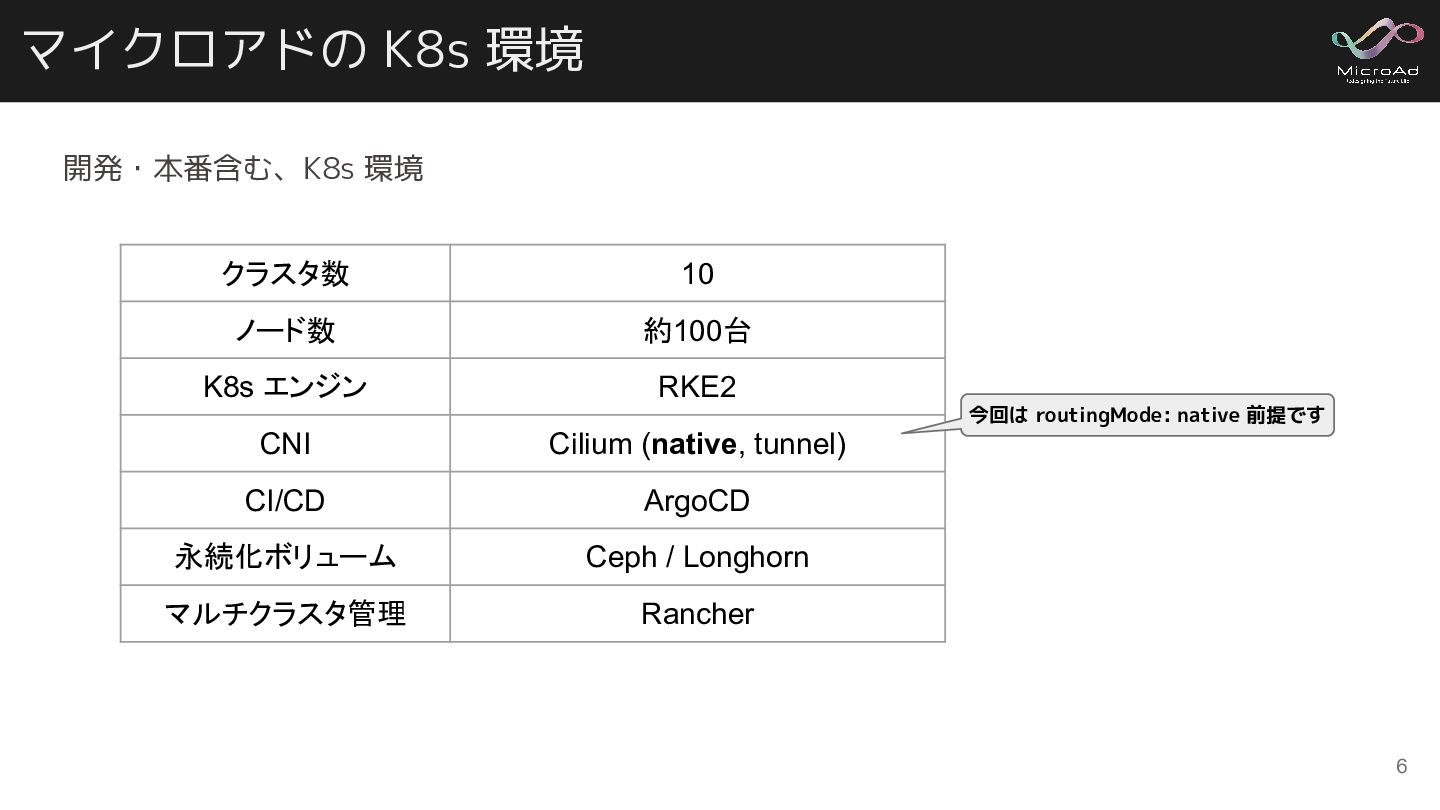
  5. マイクロアドの K8s 環境 開発・本番含む、K8s 環境 クラスタ数 10 ノード数 約100台 K8s

    エンジン RKE2 今回は routingMode: native 前提です CNI Cilium (native, tunnel) CI/CD ArgoCD 永続化ボリューム Ceph / Longhorn マルチクラスタ管理 Rancher 6
  6. K8s 化が動きだした当初の「きめごと」 • ベアメタ構成の現環境から逸脱しないこと ◦ • アプリや NW 機器で、大きな変更が必要にならないようにする K8s

    起因のオーバーヘッドを最小限に抑えること ◦ ◦ ◦ ホップ数を増やさない HW をピンニングして応答時間のブレを小さくする DSR でレスポンスする(🤫そもそも DSR しなくて良くね?) 9
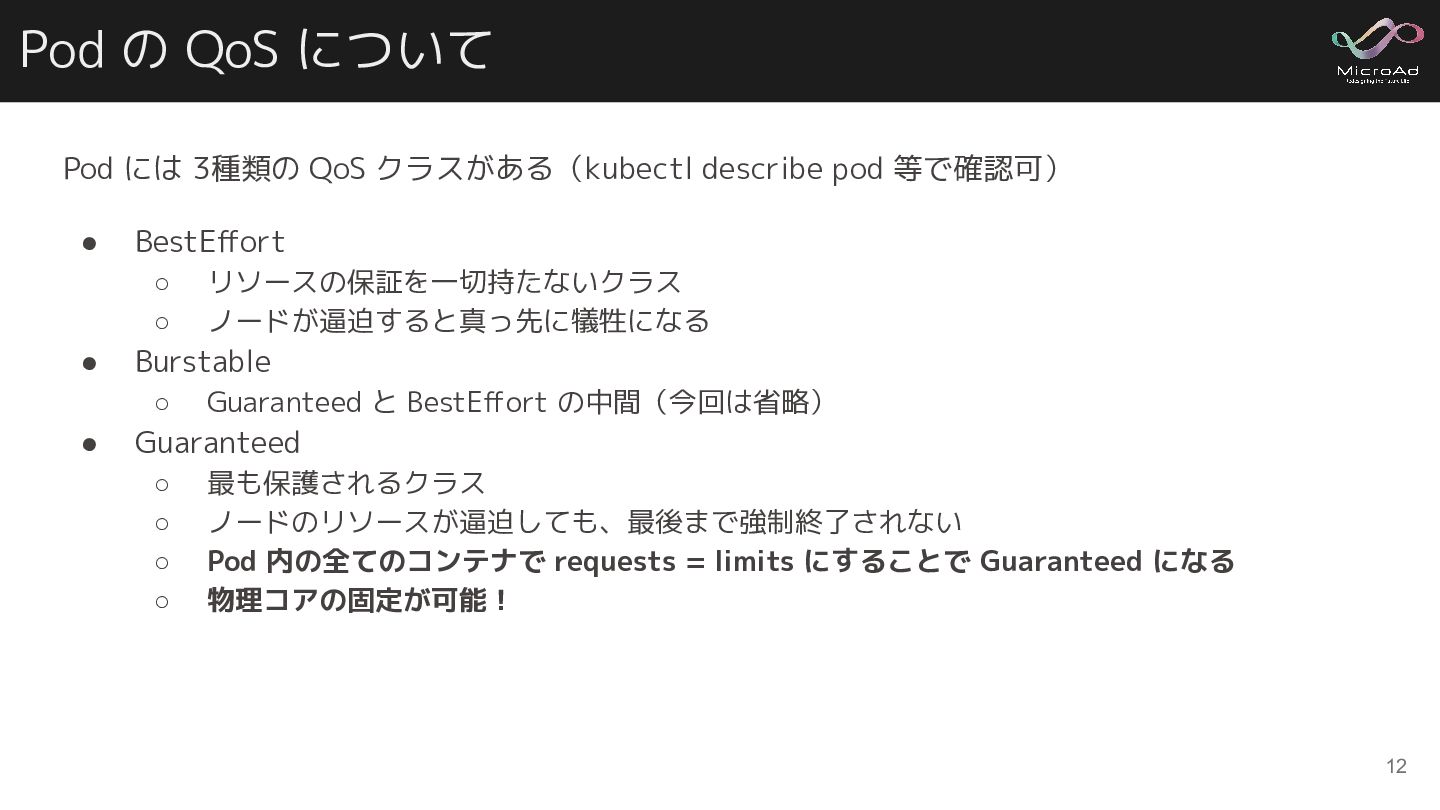
  7. Pod の QoS について Pod には 3種類の QoS クラスがある(kubectl describe

    pod 等で確認可) • BestEffort ◦ ◦ • Burstable ◦ • リソースの保証を一切持たないクラス ノードが逼迫すると真っ先に犠牲になる Guaranteed と BestEffort の中間(今回は省略) Guaranteed ◦ ◦ ◦ ◦ 最も保護されるクラス ノードのリソースが逼迫しても、最後まで強制終了されない Pod 内の全てのコンテナで requests = limits にすることで Guaranteed になる 物理コアの固定が可能! 12
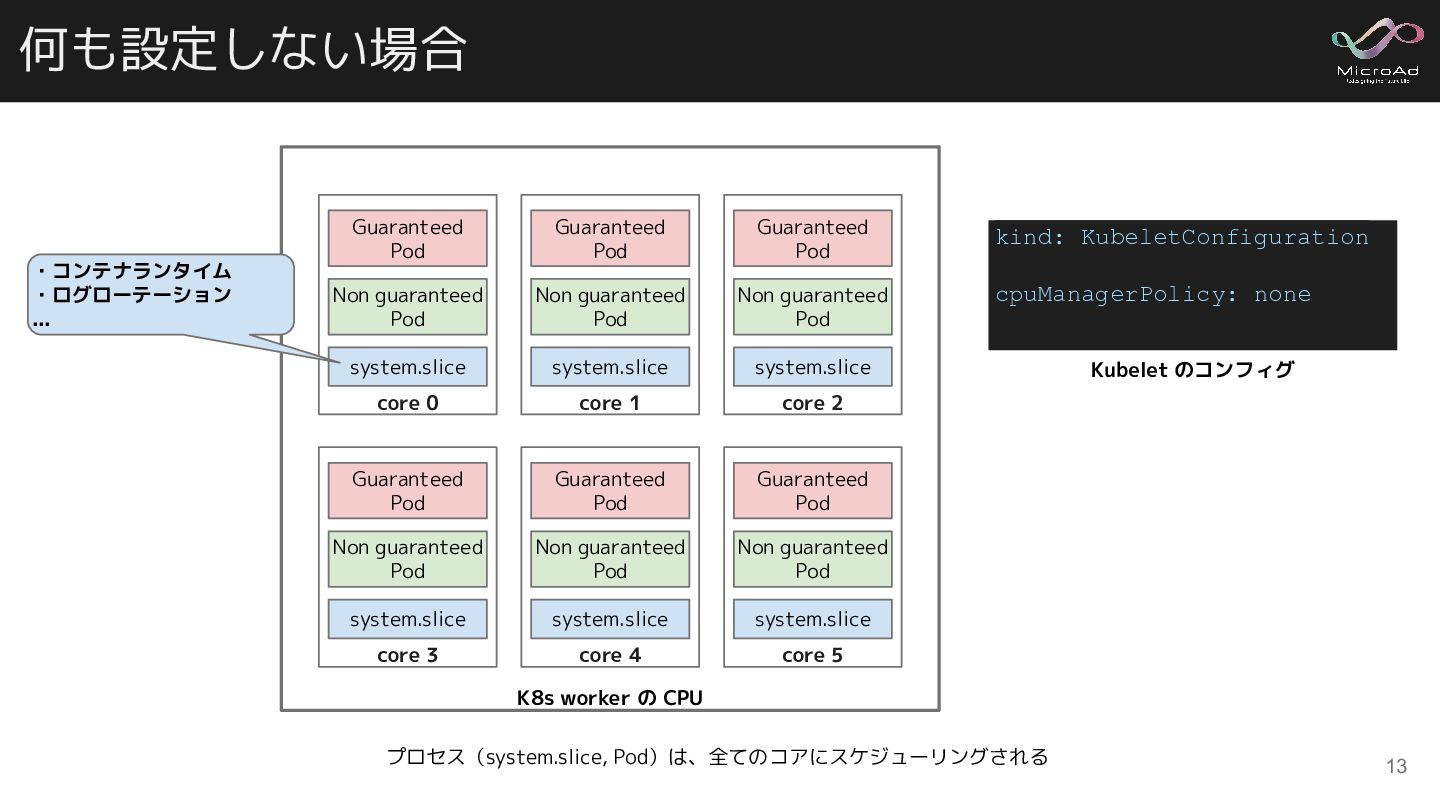
  8. 何も設定しない場合 ・コンテナランタイム ・ログローテーション ... Guaranteed Pod Guaranteed Pod Guaranteed Pod

    Non guaranteed Pod Non guaranteed Pod Non guaranteed Pod system.slice system.slice system.slice core 0 core 1 core 2 Guaranteed Pod Guaranteed Pod Guaranteed Pod Non guaranteed Pod Non guaranteed Pod Non guaranteed Pod system.slice system.slice system.slice core 3 core 4 core 5 kind: KubeletConfiguration cpuManagerPolicy: none Kubelet のコンフィグ K8s worker の CPU プロセス(system.slice, Pod)は、全てのコアにスケジューリングされる 13
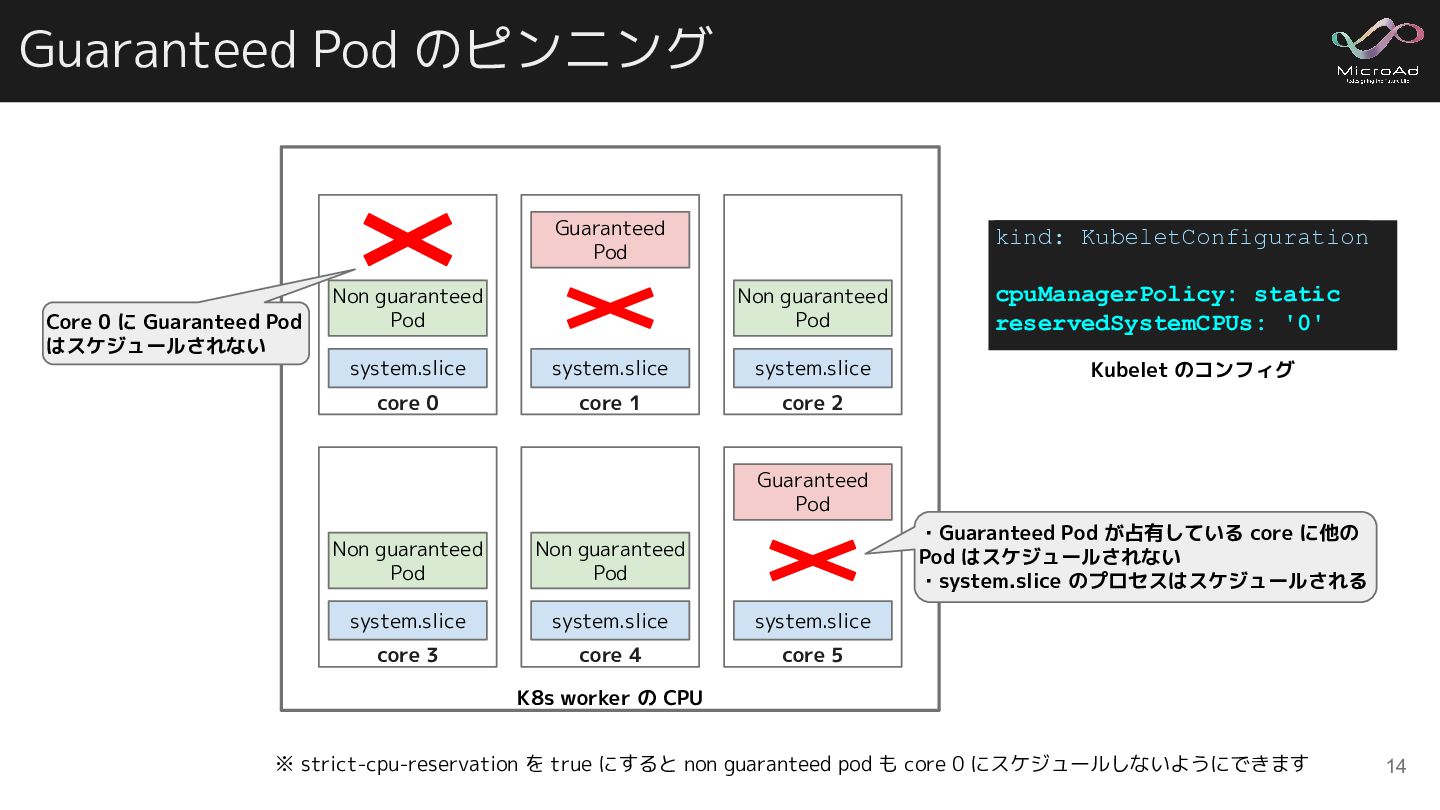
  9. Guaranteed Pod のピンニング Guaranteed Pod Core 0 に Guaranteed Pod

    はスケジュールされない Non guaranteed Pod kind: KubeletConfiguration Non guaranteed Pod system.slice system.slice system.slice core 0 core 1 core 2 cpuManagerPolicy: static reservedSystemCPUs: '0' Kubelet のコンフィグ Guaranteed Pod ・Guaranteed Pod が占有している core に他の Pod はスケジュールされない ・system.slice のプロセスはスケジュールされる Non guaranteed Pod Non guaranteed Pod system.slice system.slice system.slice core 3 core 4 core 5 K8s worker の CPU ※ strict-cpu-reservation を true にすると non guaranteed pod も core 0 にスケジュールしないようにできます 14
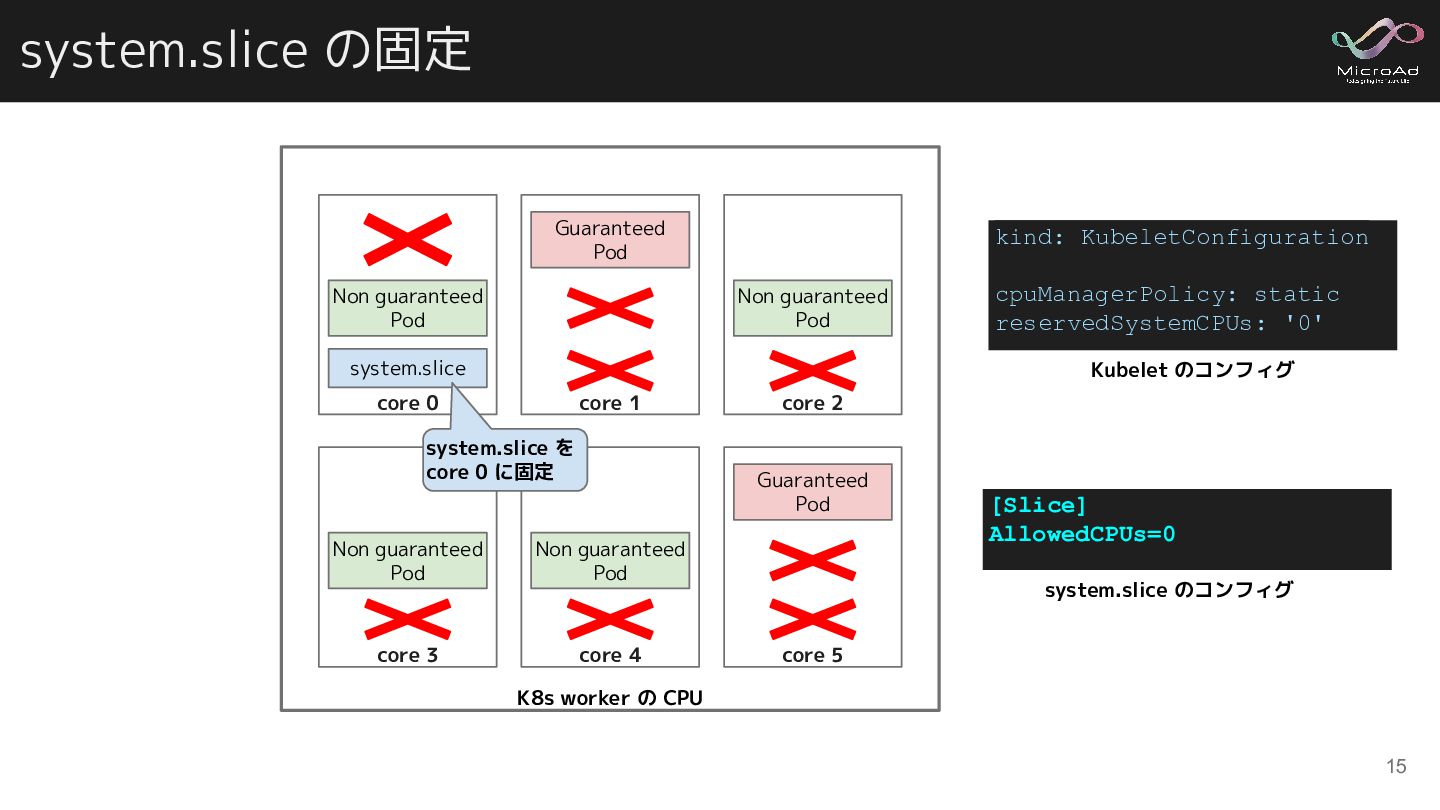
  10. system.slice の固定 Guaranteed Pod Non guaranteed Pod kind: KubeletConfiguration Non

    guaranteed Pod system.slice cpuManagerPolicy: static reservedSystemCPUs: '0' Kubelet のコンフィグ core 0 core 1 system.slice を core 0 に固定 core 2 Guaranteed Pod Non guaranteed Pod Non guaranteed Pod core 3 core 4 [Slice] AllowedCPUs=0 system.slice のコンフィグ core 5 K8s worker の CPU 15
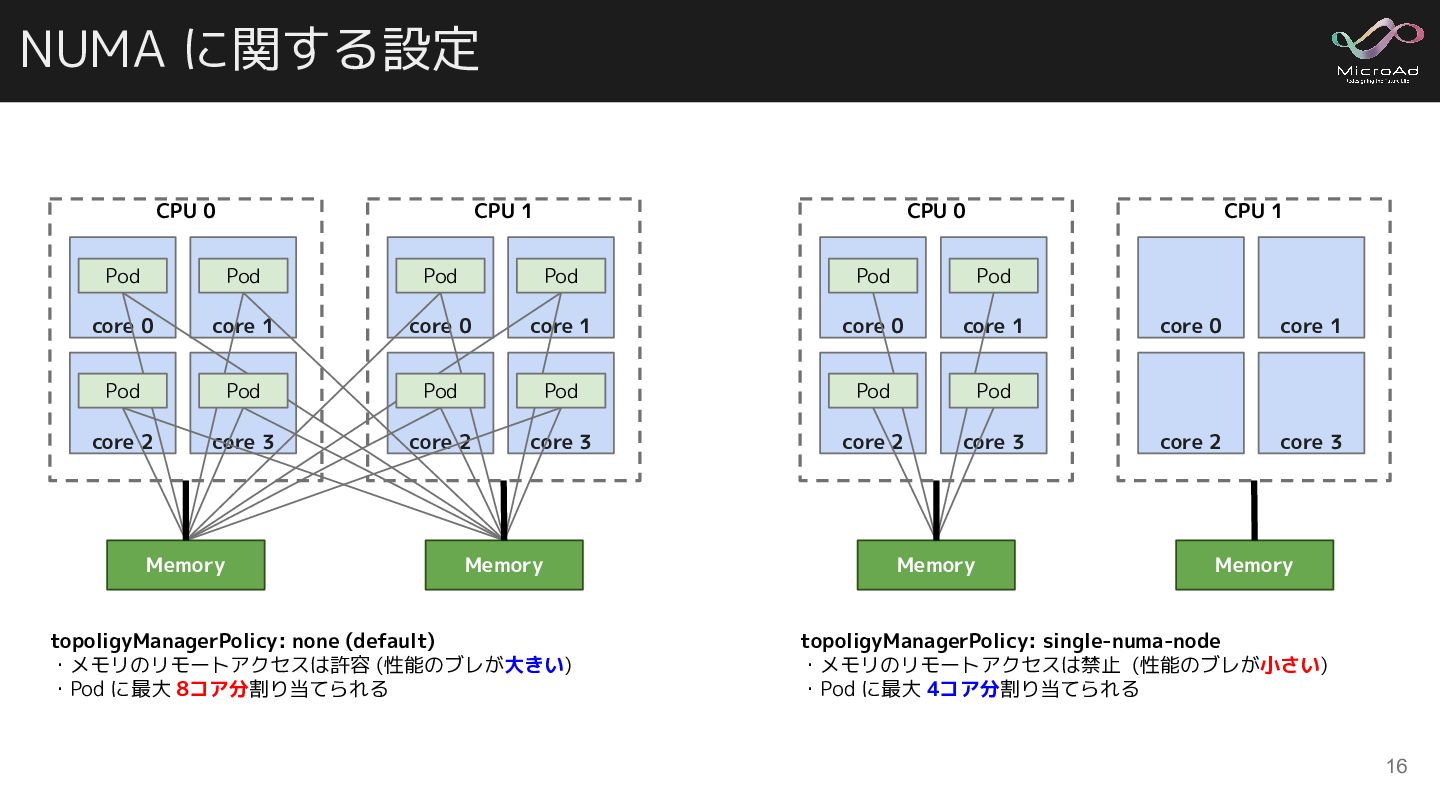
  11. NUMA に関する設定 CPU 0 CPU 1 CPU 0 CPU 1

    Pod Pod Pod Pod Pod Pod core 0 core 1 core 0 core 1 core 0 core 1 Pod Pod Pod Pod Pod Pod core 2 core 3 core 2 core 3 core 2 core 3 Memory Memory topoligyManagerPolicy: none (default) ・メモリのリモートアクセスは許容 (性能のブレが大きい) ・Pod に最大 8コア分割り当てられる Memory core 0 core 1 core 2 core 3 Memory topoligyManagerPolicy: single-numa-node ・メモリのリモートアクセスは禁止 (性能のブレが小さい) ・Pod に最大 4コア分割り当てられる 16
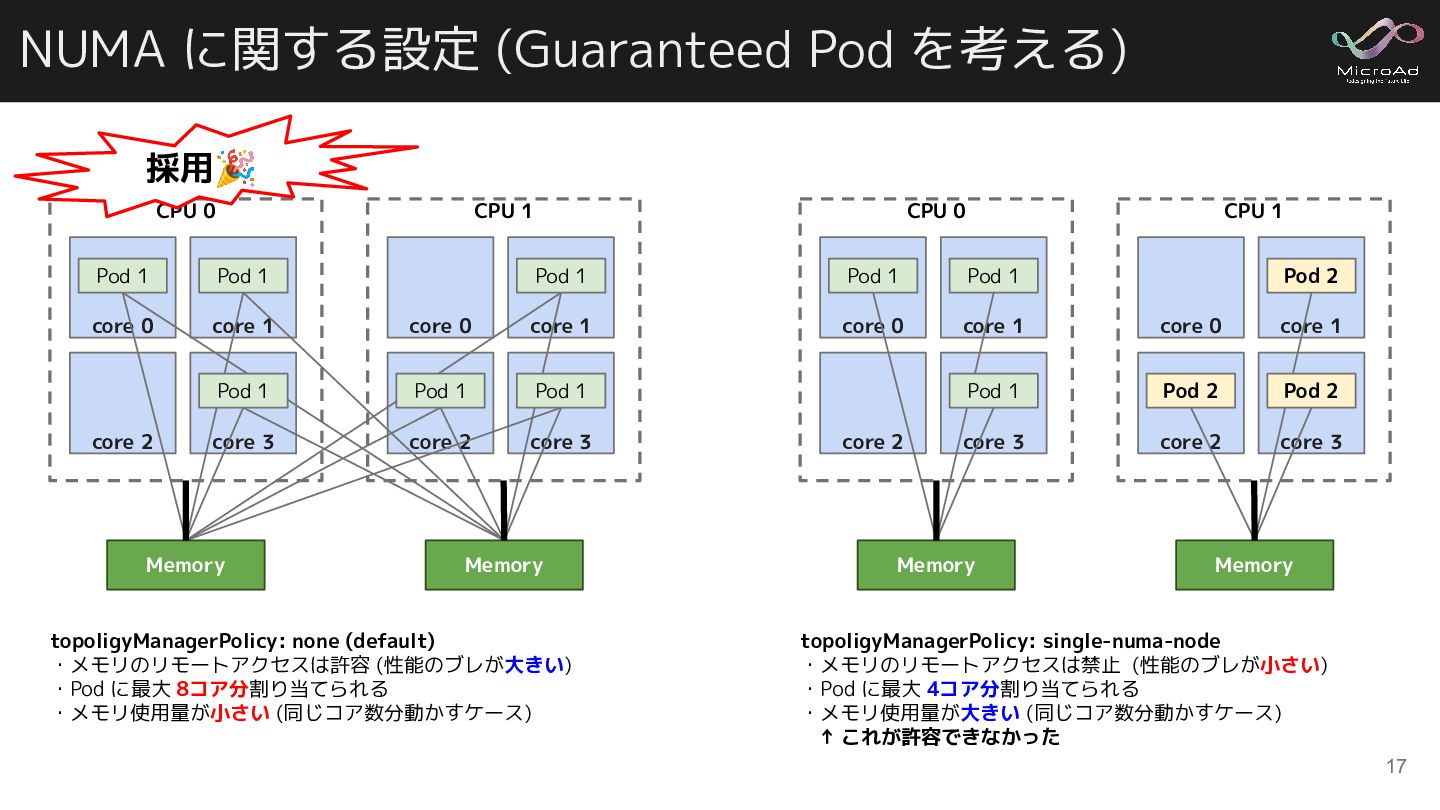
  12. NUMA に関する設定 (Guaranteed Pod を考える) 採用🎉 CPU 0 CPU 1

    Pod 1 Pod 1 core 0 core 1 core 2 CPU 0 CPU 1 Pod 1 Pod 1 Pod 1 core 0 core 1 core 0 core 1 core 0 core 1 Pod 1 Pod 1 Pod 1 Pod 1 Pod 2 Pod 2 core 3 core 2 core 3 core 3 core 2 core 3 Memory Memory topoligyManagerPolicy: none (default) ・メモリのリモートアクセスは許容 (性能のブレが大きい) ・Pod に最大 8コア分割り当てられる ・メモリ使用量が小さい (同じコア数分動かすケース) core 2 Memory Pod 2 Memory topoligyManagerPolicy: single-numa-node ・メモリのリモートアクセスは禁止 (性能のブレが小さい) ・Pod に最大 4コア分割り当てられる ・メモリ使用量が大きい (同じコア数分動かすケース) ↑ これが許容できなかった 17
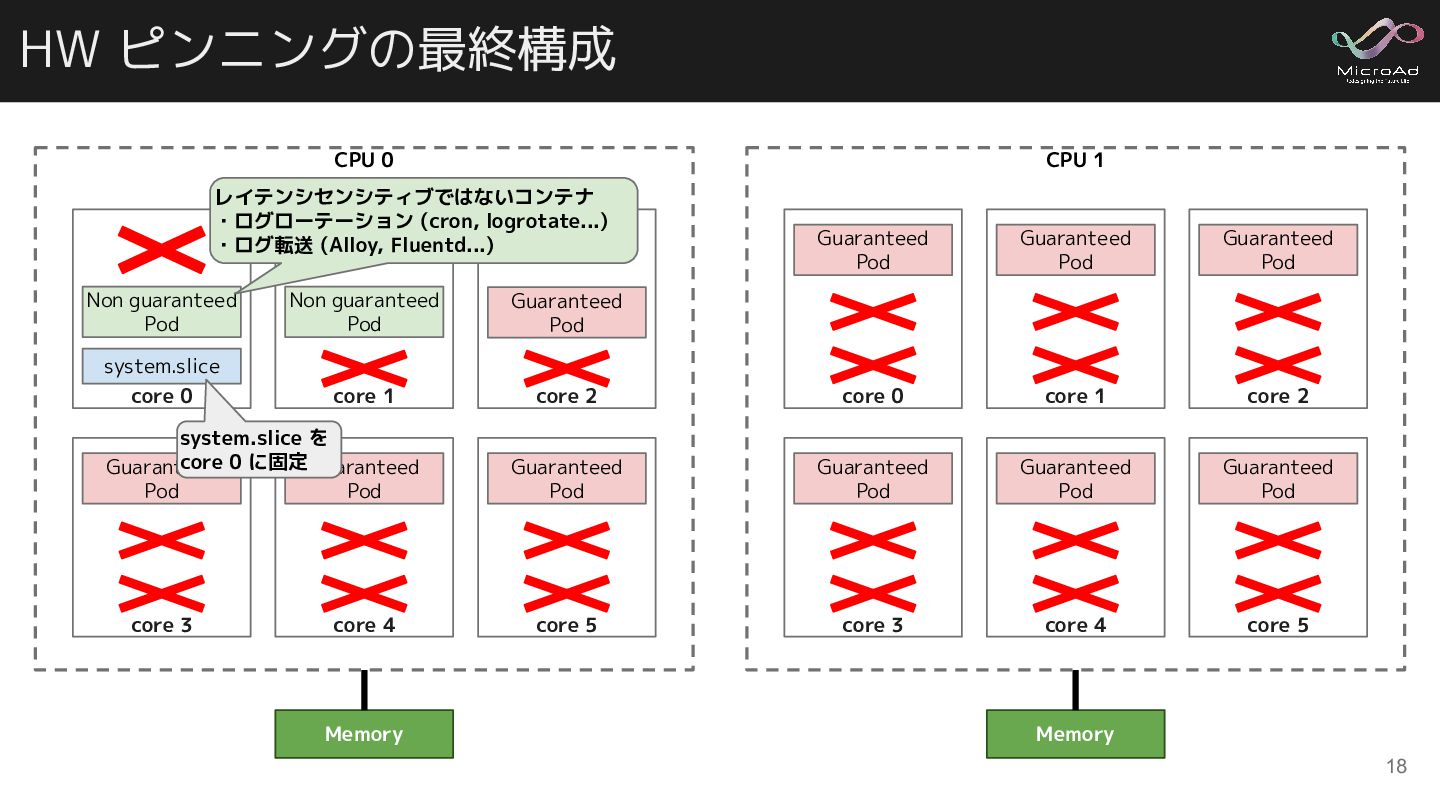
  13. HW ピンニングの最終構成 CPU 0 CPU 1 レイテンシセンシティブではないコンテナ ・ログローテーション (cron, logrotate...)

    ・ログ転送 (Alloy, Fluentd...) Guaranteed Pod Guaranteed Pod Guaranteed Pod Non guaranteed Pod Non guaranteed Pod Guaranteed Pod system.slice core 0 core 1 core 2 core 0 core 1 core 2 Guaranteed Pod Guaranteed Pod Guaranteed Pod Guaranteed Pod core 5 core 3 core 4 core 5 system.slice を core 0 に固定Guaranteed Guaranteed Pod Pod core 3 core 4 Memory Memory 18
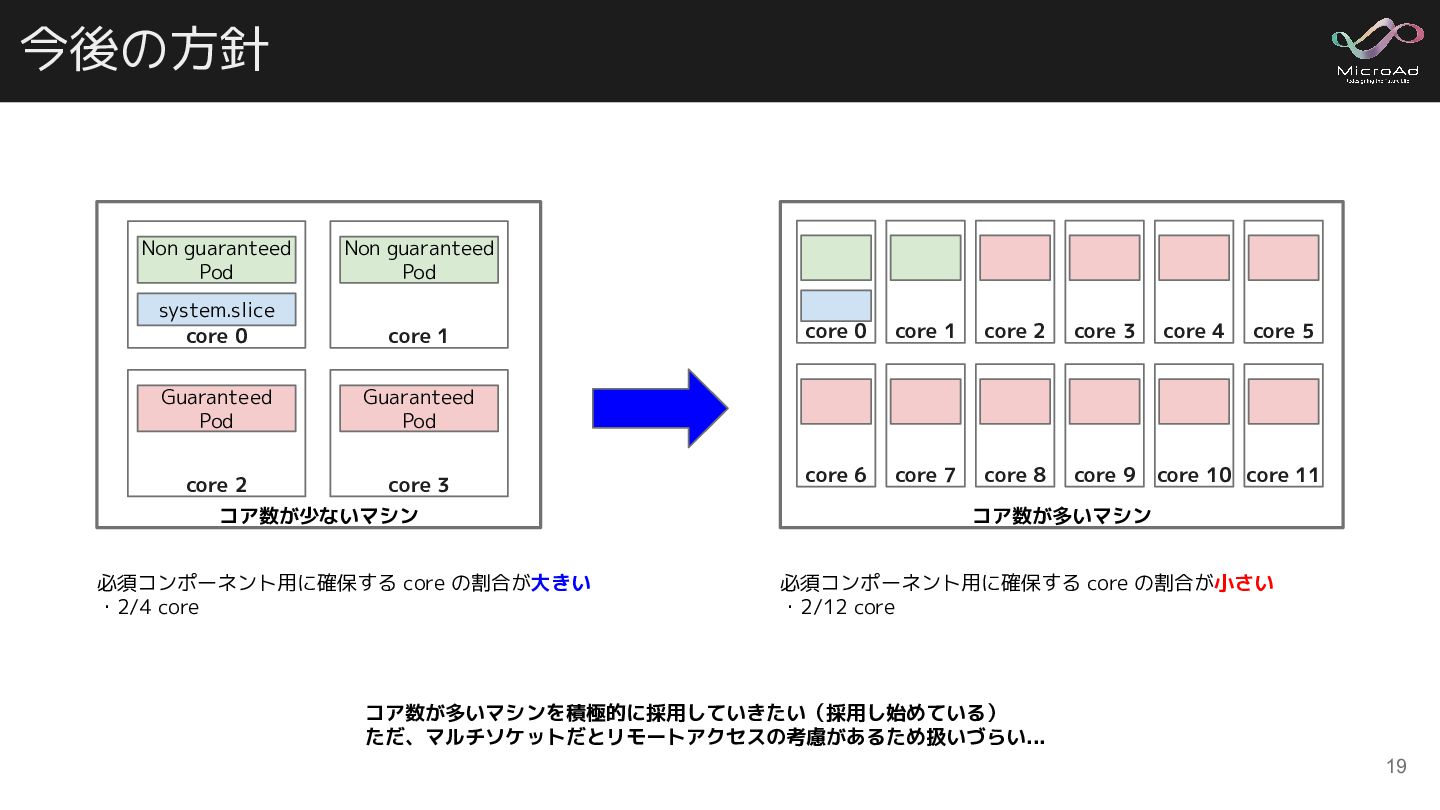
  14. 今後の方針 Non guaranteed Pod Non guaranteed Pod system.slice core 0

    core 1 Guaranteed Pod Guaranteed Pod core 2 core 3 コア数が少ないマシン 必須コンポーネント用に確保する core の割合が大きい ・2/4 core core 0 core 1 core 2 core 3 core 4 core 5 core 6 core 7 core 8 core 9 core 10 core 11 コア数が多いマシン 必須コンポーネント用に確保する core の割合が小さい ・2/12 core コア数が多いマシンを積極的に採用していきたい(採用し始めている) ただ、マルチソケットだとリモートアクセスの考慮があるため扱いづらい... 19
  15. 今後やりたいこと CPU と NUMA トポロジーの他にも、制御の余地がある HW はいくつかある • • •

    • CPU Cache メモリ帯域 NIC ストレージ帯域 今回は、手が回らず検証できなかったので、今後はここら辺にも取り組んで高速化したい 20
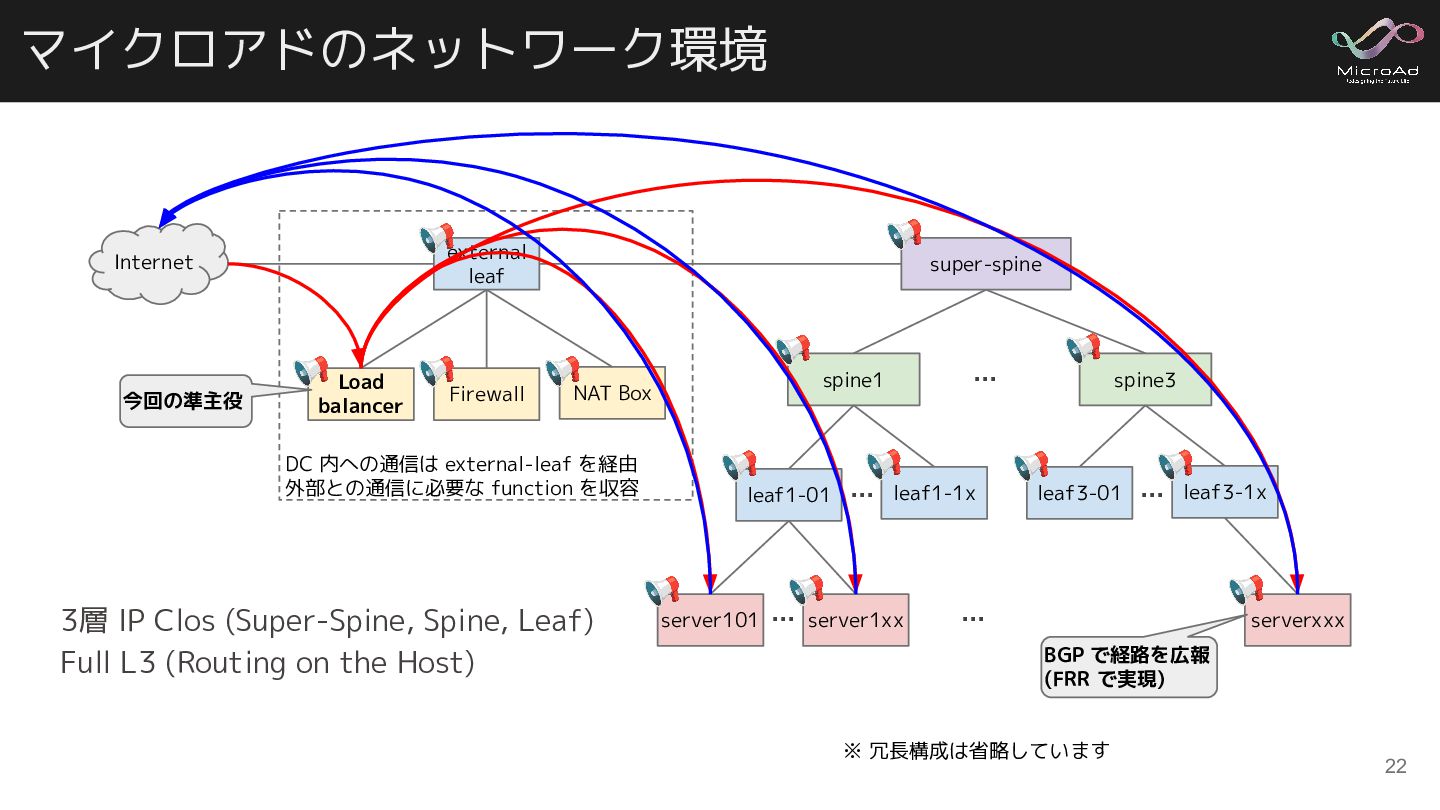
  16. マイクロアドのネットワーク環境 今回の準主役 📢 📢external Internet leaf 📢 Load balancer 📢

    📢Firewall 📢NAT Box DC 内への通信は external-leaf を経由 外部との通信に必要な function を収容 3層 IP Clos (Super-Spine, Spine, Leaf) Full L3 (Routing on the Host) spine1 📢 leaf1-01 📢 📢 super-spine 📢 … leaf1-1x server101 … server1xx 📢 … 📢 spine3 leaf3-01 📢 … leaf3-1x 📢 … serverxxx BGP で経路を広報 (FRR で実現) ※ 冗長構成は省略しています 22
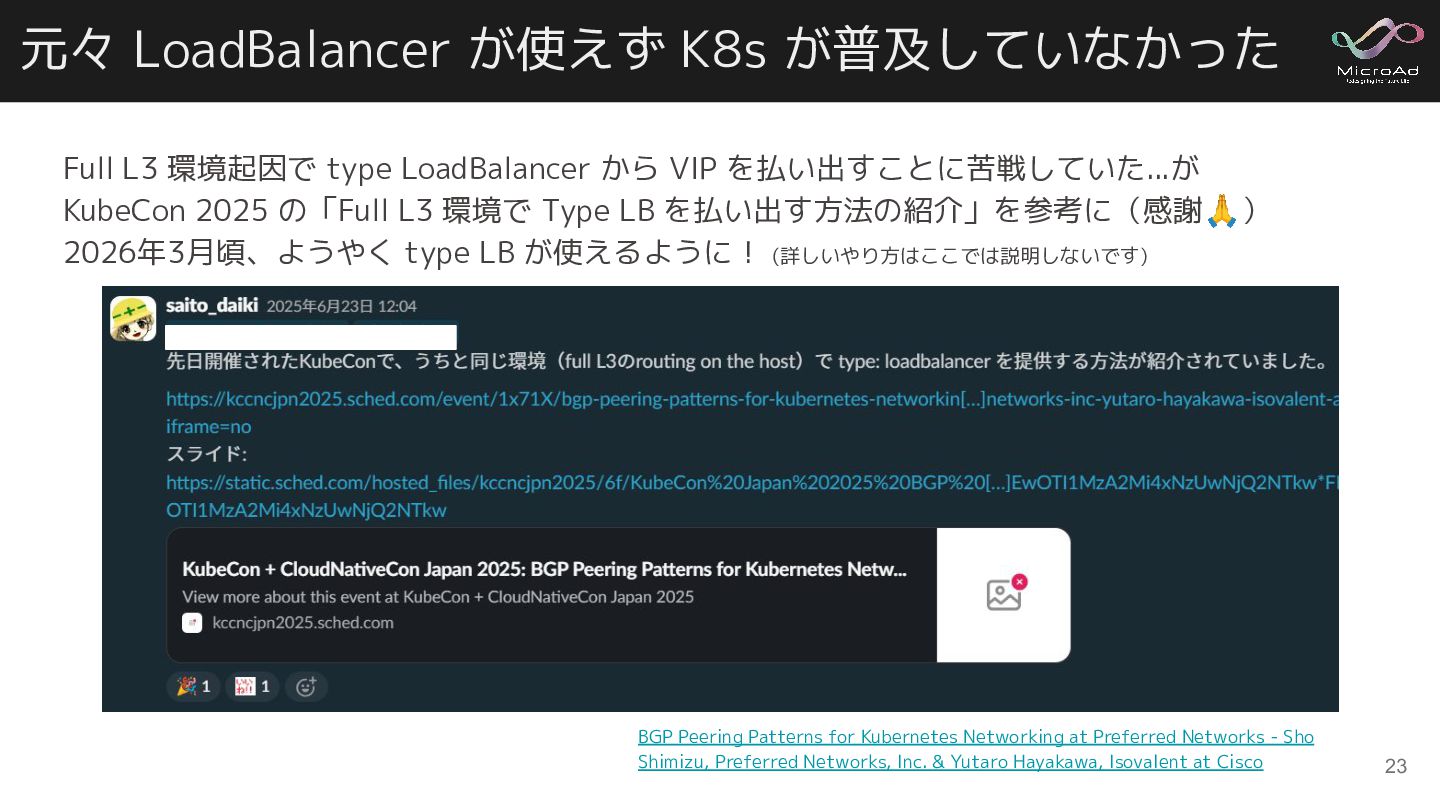
  17. 元々 LoadBalancer が使えず K8s が普及していなかった Full L3 環境起因で type LoadBalancer

    から VIP を払い出すことに苦戦していた...が KubeCon 2025 の「Full L3 環境で Type LB を払い出す方法の紹介」を参考に(感謝🙏) 2026年3月頃、ようやく type LB が使えるように! (詳しいやり方はここでは説明しないです) BGP Peering Patterns for Kubernetes Networking at Preferred Networks - Sho Shimizu, Preferred Networks, Inc. & Yutaro Hayakawa, Isovalent at Cisco 23
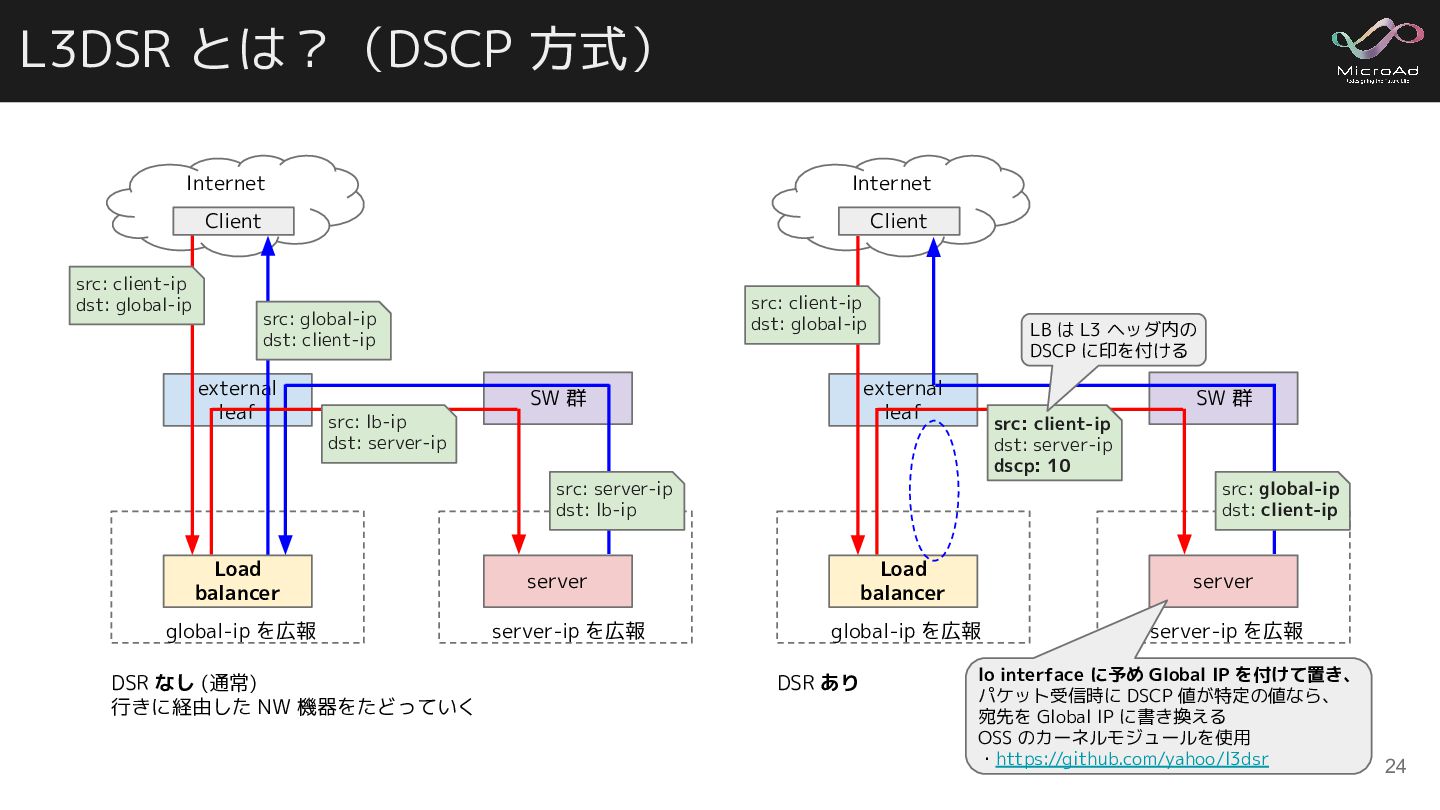
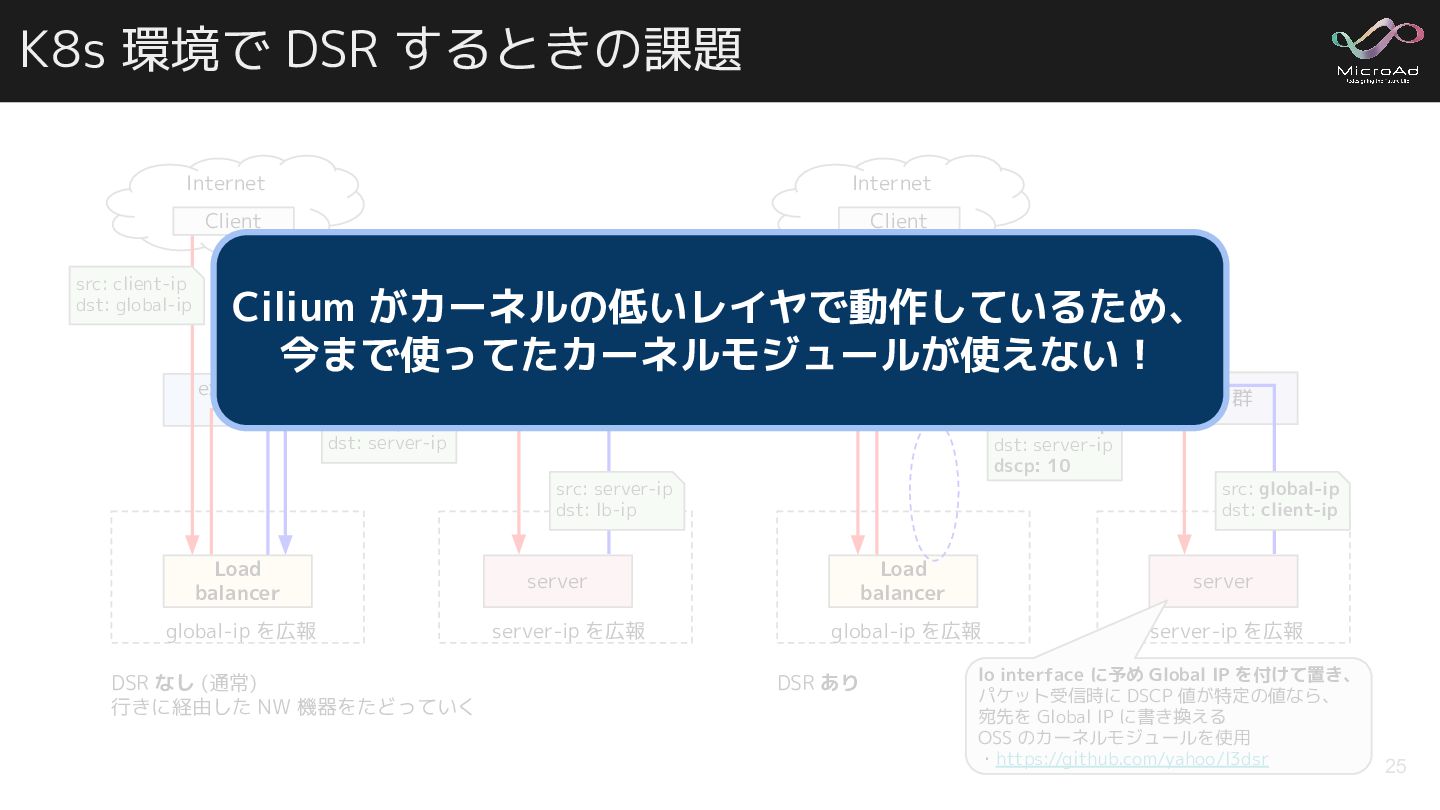
  18. L3DSR とは?(DSCP 方式) Internet Internet Client Client src: client-ip dst:

    global-ip src: client-ip dst: global-ip src: global-ip dst: client-ip external leaf LB は L3 ヘッダ内の DSCP に印を付ける external leaf SW 群 src: lb-ip dst: server-ip SW 群 src: client-ip dst: server-ip dscp: 10 src: server-ip dst: lb-ip src: global-ip dst: client-ip Load balancer server Load balancer server global-ip を広報 server-ip を広報 global-ip を広報 server-ip を広報 DSR なし (通常) 行きに経由した NW 機器をたどっていく DSR あり lo interface に予め Global IP を付けて置き、 パケット受信時に DSCP 値が特定の値なら、 宛先を Global IP に書き換える OSS のカーネルモジュールを使用 ・https://github.com/yahoo/l3dsr 24
  19. K8s 環境で DSR するときの課題 Internet Internet Client Client src: client-ip

    dst: global-ip src: client-ip Cilium src: global-ipがカーネルの低いレイヤで動作しているため、 dst: global-ip LB は L3 ヘッダ内の dst: client-ip DSCP に印を付ける 今まで使ってたカーネルモジュールが使えない! external leaf external leaf SW 群 src: lb-ip dst: server-ip SW 群 src: client-ip dst: server-ip dscp: 10 src: server-ip dst: lb-ip src: global-ip dst: client-ip Load balancer server Load balancer server global-ip を広報 server-ip を広報 global-ip を広報 server-ip を広報 DSR なし (通常) 行きに経由した NW 機器をたどっていく DSR あり lo interface に予め Global IP を付けて置き、 パケット受信時に DSCP 値が特定の値なら、 宛先を Global IP に書き換える OSS のカーネルモジュールを使用 ・https://github.com/yahoo/l3dsr 25
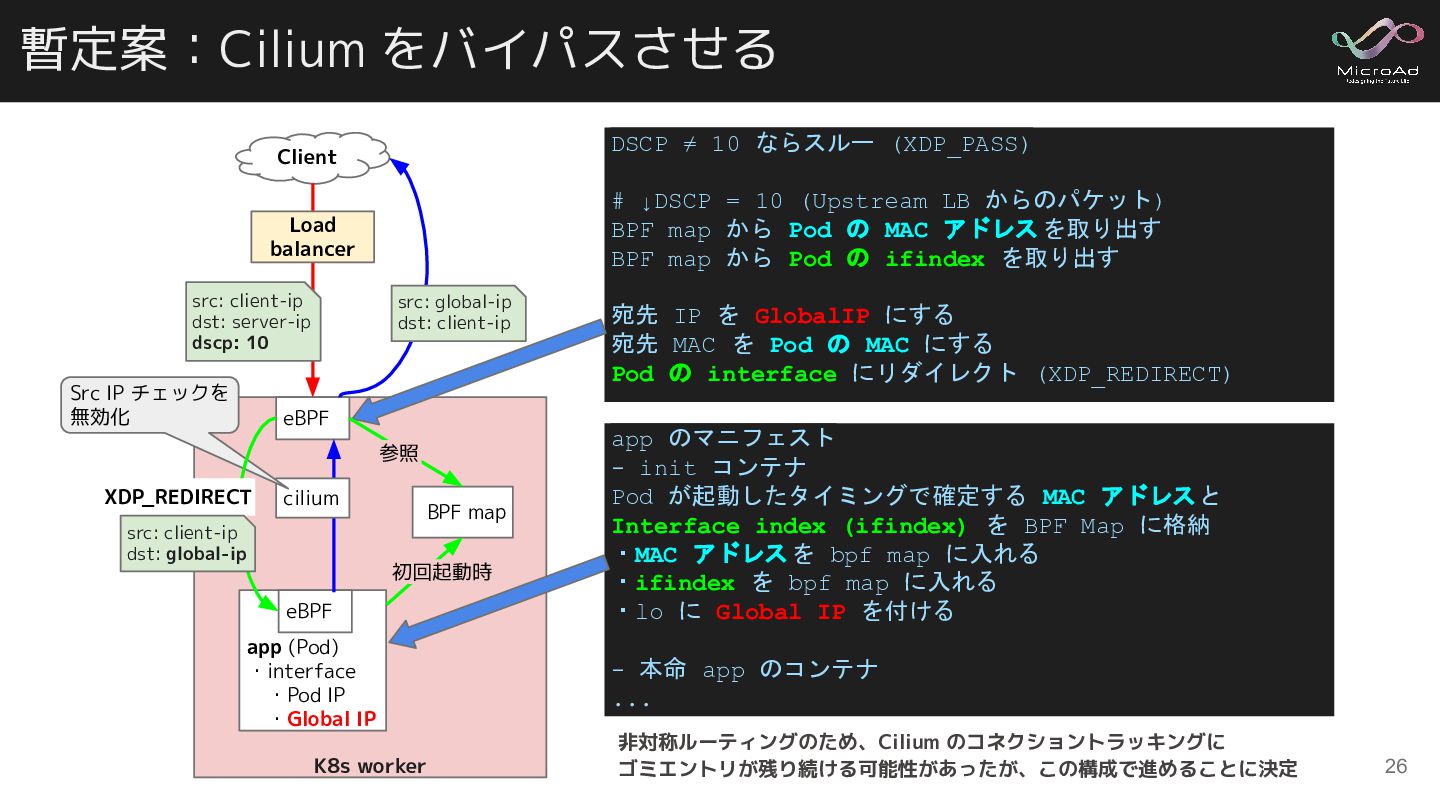
  20. 暫定案:Cilium をバイパスさせる DSCP ≠ 10 ならスルー (XDP_PASS) Client # ↓DSCP

    = 10 (Upstream LB からのパケット) BPF map から Pod の MAC アドレス を取り出す BPF map から Pod の ifindex を取り出す Load balancer src: client-ip dst: server-ip dscp: 10 Src IP チェックを 無効化 src: global-ip dst: client-ip eBPF 参照 XDP_REDIRECT cilium src: client-ip dst: global-ip BPF map 初回起動時 eBPF app (Pod) ・interface ・Pod IP ・Global IP K8s worker 宛先 IP を GlobalIP にする 宛先 MAC を Pod の MAC にする Pod の interface にリダイレクト (XDP_REDIRECT) app のマニフェスト - init コンテナ Pod が起動したタイミングで確定する MAC アドレス と Interface index (ifindex) を BPF Map に格納 ・MAC アドレス を bpf map に入れる ・ifindex を bpf map に入れる ・lo に Global IP を付ける - 本命 app のコンテナ ... 非対称ルーティングのため、Cilium のコネクショントラッキングに ゴミエントリが残り続ける可能性があったが、この構成で進めることに決定 26
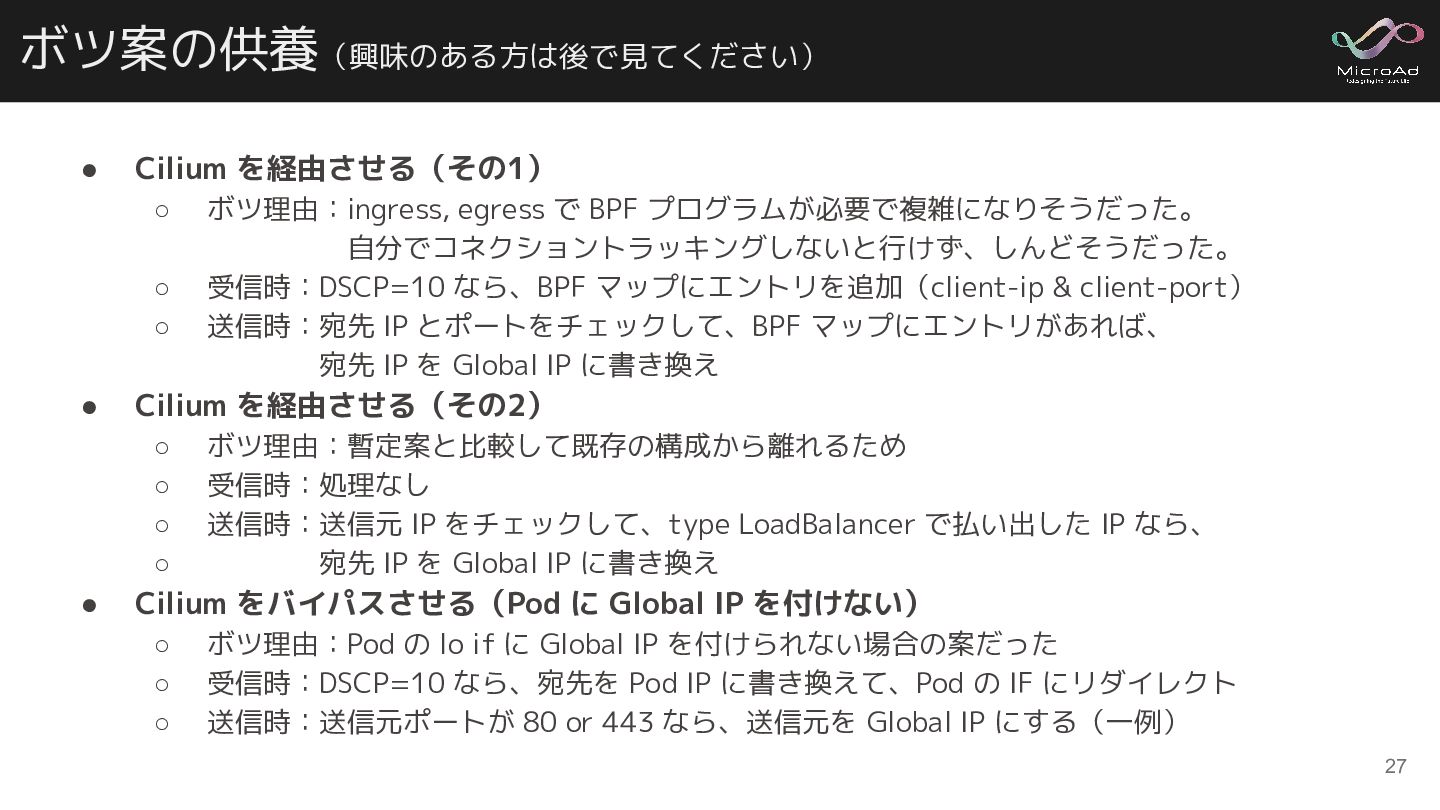
  21. ボツ案の供養(興味のある方は後で見てください) • Cilium を経由させる(その1) ◦ ◦ ◦ • Cilium を経由させる(その2)

    ◦ ◦ ◦ ◦ • ボツ理由:ingress, egress で BPF プログラムが必要で複雑になりそうだった。 自分でコネクショントラッキングしないと行けず、しんどそうだった。 受信時:DSCP=10 なら、BPF マップにエントリを追加(client-ip & client-port) 送信時:宛先 IP とポートをチェックして、BPF マップにエントリがあれば、 宛先 IP を Global IP に書き換え ボツ理由:暫定案と比較して既存の構成から離れるため 受信時:処理なし 送信時:送信元 IP をチェックして、type LoadBalancer で払い出した IP なら、 宛先 IP を Global IP に書き換え Cilium をバイパスさせる(Pod に Global IP を付けない) ◦ ◦ ◦ ボツ理由:Pod の lo if に Global IP を付けられない場合の案だった 受信時:DSCP=10 なら、宛先を Pod IP に書き換えて、Pod の IF にリダイレクト 送信時:送信元ポートが 80 or 443 なら、送信元を Global IP にする(一例) 27
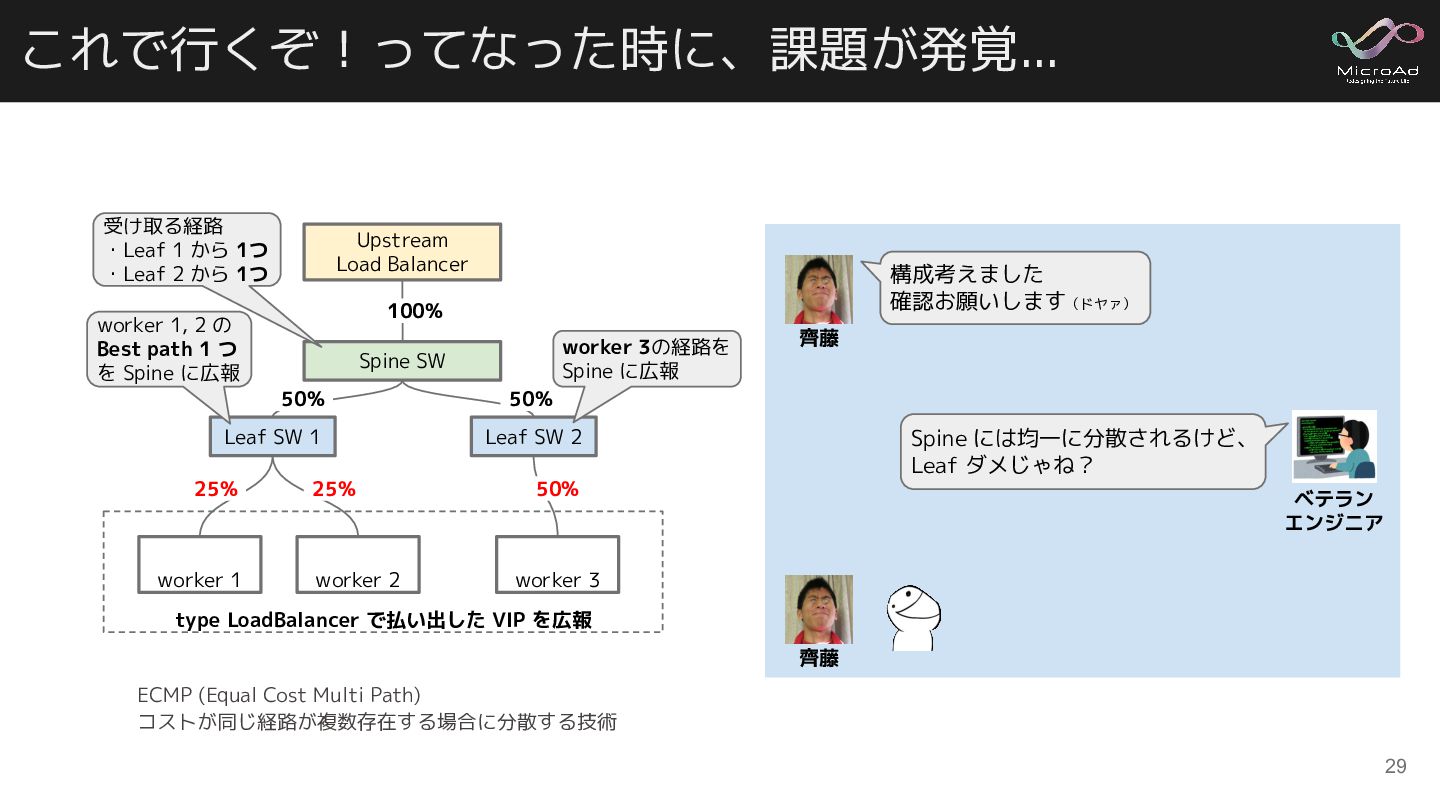
  22. これで行くぞ!ってなった時に、課題が発覚... 受け取る経路 ・Leaf 1 から 1つ ・Leaf 2 から 1つ

    Upstream Load Balancer 100% worker 1, 2 の Best path 1 つ を Spine に広報 Leaf SW 1 worker 1 worker 3の経路を Spine に広報 Spine SW 50% 25% 構成考えました 確認お願いします(ドヤァ) 25% worker 2 齊藤 50% Leaf SW 2 Spine には均一に分散されるけど、 Leaf ダメじゃね? 50% ベテラン エンジニア worker 3 type LoadBalancer で払い出した VIP を広報 齊藤 ECMP (Equal Cost Multi Path) コストが同じ経路が複数存在する場合に分散する技術 29
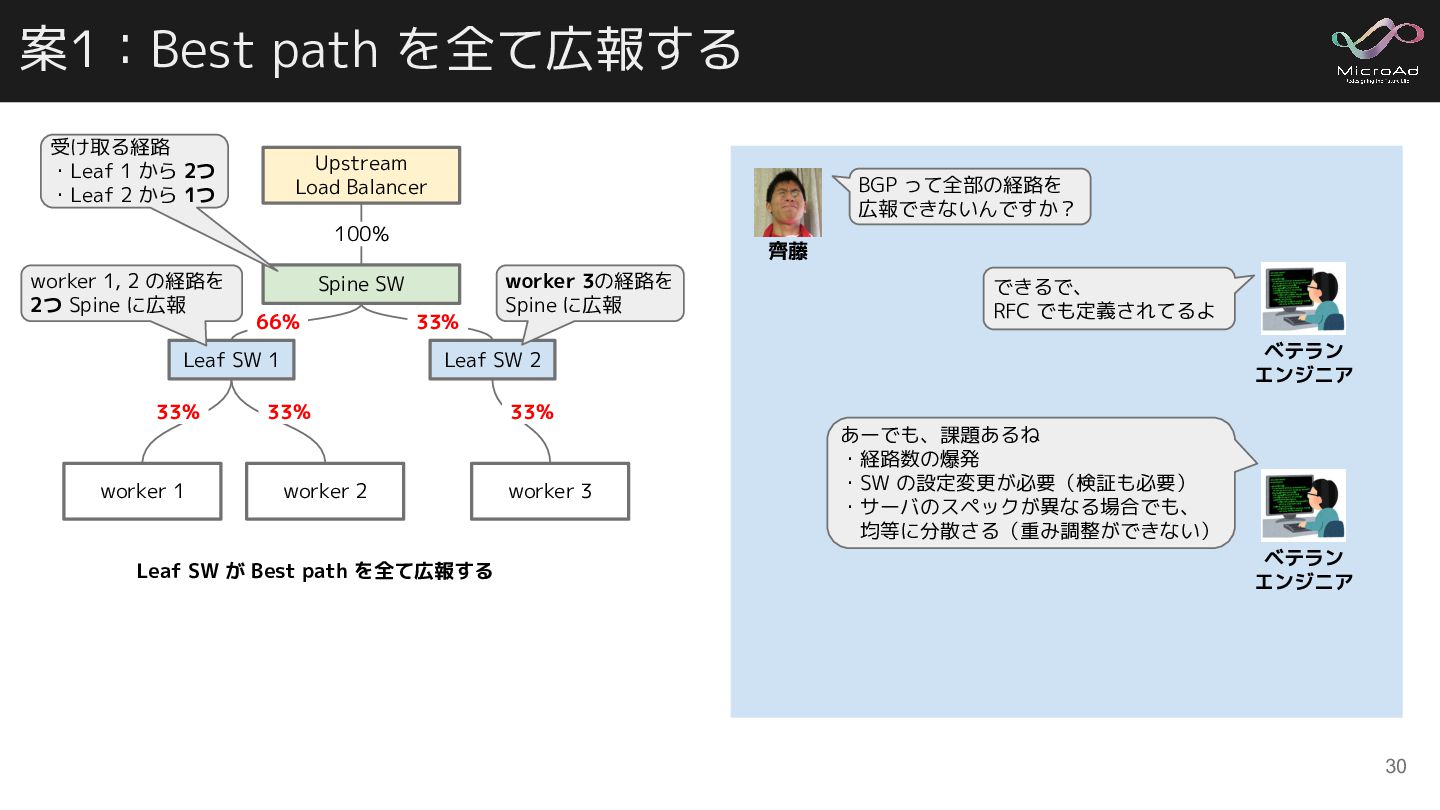
  23. 案1:Best path を全て広報する 受け取る経路 ・Leaf 1 から 2つ ・Leaf 2

    から 1つ Upstream Load Balancer BGP って全部の経路を 広報できないんですか? 100% worker 1, 2 の経路を 2つ Spine に広報 Spine SW 66% Leaf SW 1 33% worker 1 齊藤 33% worker 3の経路を Spine に広報 できるで、 RFC でも定義されてるよ ベテラン エンジニア Leaf SW 2 33% worker 2 Leaf SW が Best path を全て広報する 33% worker 3 あーでも、課題あるね ・経路数の爆発 ・SW の設定変更が必要(検証も必要) ・サーバのスペックが異なる場合でも、 均等に分散さる(重み調整ができない) ベテラン エンジニア 30
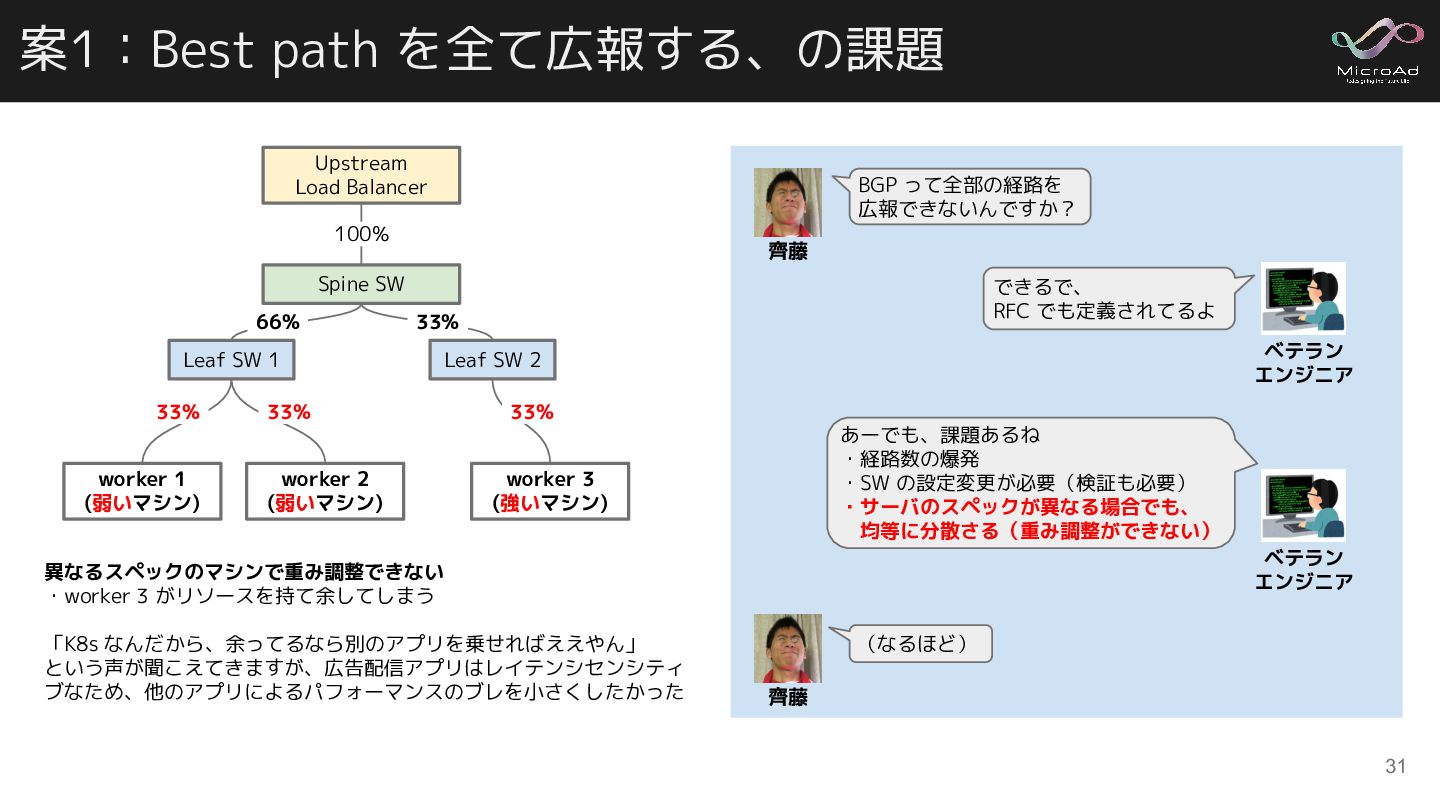
  24. 案1:Best path を全て広報する、の課題 Upstream Load Balancer BGP って全部の経路を 広報できないんですか? 100%

    齊藤 Spine SW 66% Leaf SW 1 33% worker 1 (弱いマシン) できるで、 RFC でも定義されてるよ 33% ベテラン エンジニア Leaf SW 2 33% worker 2 (弱いマシン) 33% あーでも、課題あるね ・経路数の爆発 ・SW の設定変更が必要(検証も必要) ・サーバのスペックが異なる場合でも、 均等に分散さる(重み調整ができない) worker 3 (強いマシン) ベテラン エンジニア 異なるスペックのマシンで重み調整できない ・worker 3 がリソースを持て余してしまう 「K8s なんだから、余ってるなら別のアプリを乗せればええやん」 という声が聞こえてきますが、広告配信アプリはレイテンシセンシティ ブなため、他のアプリによるパフォーマンスのブレを小さくしたかった (なるほど) 齊藤 31
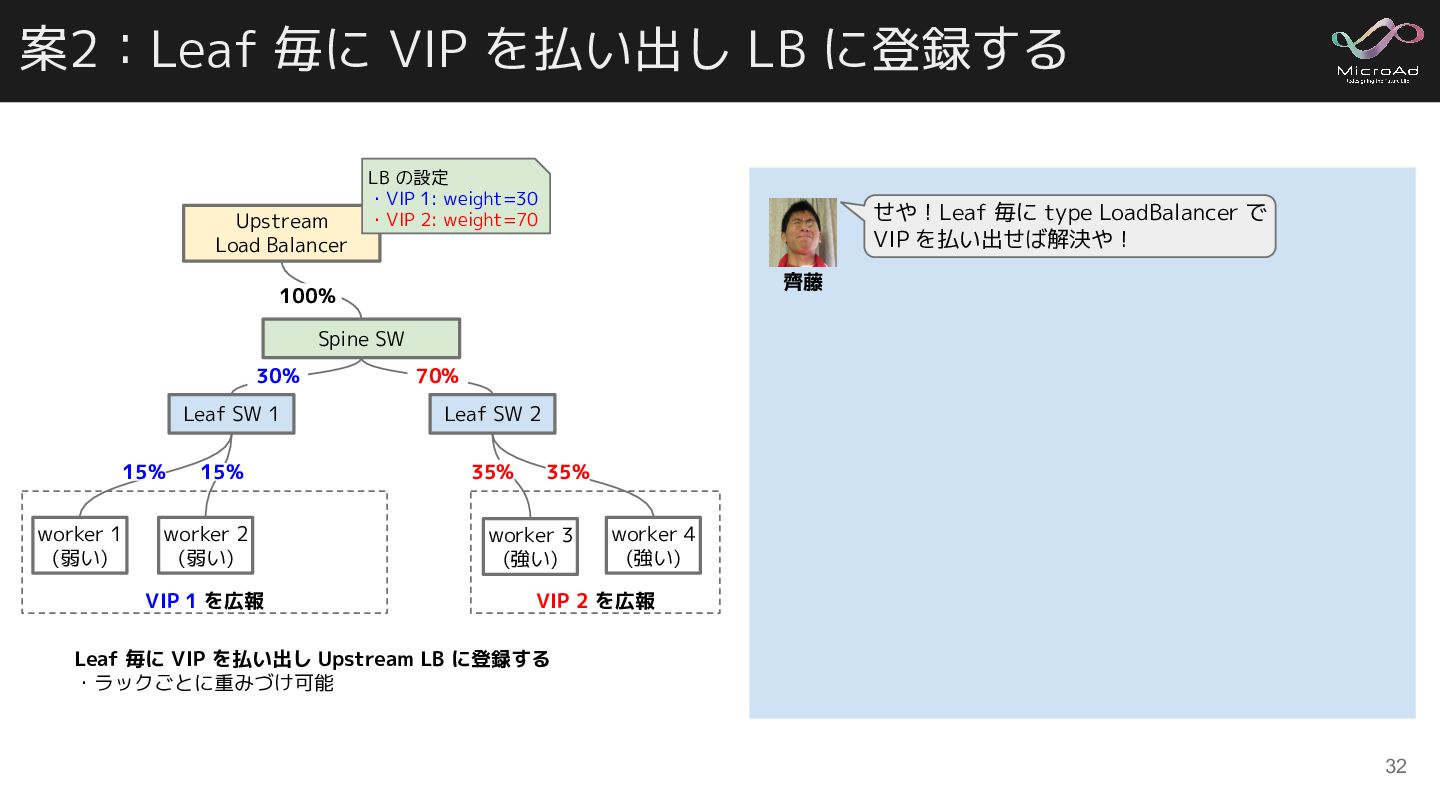
  25. 案2:Leaf 毎に VIP を払い出し LB に登録する Upstream Load Balancer LB

    の設定 ・VIP 1: weight=30 ・VIP 2: weight=70 せや!Leaf 毎に type LoadBalancer で VIP を払い出せば解決や! 齊藤 100% Spine SW 30% 15% worker 1 (弱い) 70% Leaf SW 1 Leaf SW 2 15% 35% worker 2 (弱い) VIP 1 を広報 35% worker 3 (強い) worker 4 (強い) VIP 2 を広報 Leaf 毎に VIP を払い出し Upstream LB に登録する ・ラックごとに重みづけ可能 32
  26. 案2:Leaf 毎に VIP を払い出し LB に登録する、の課題 Upstream Load Balancer LB

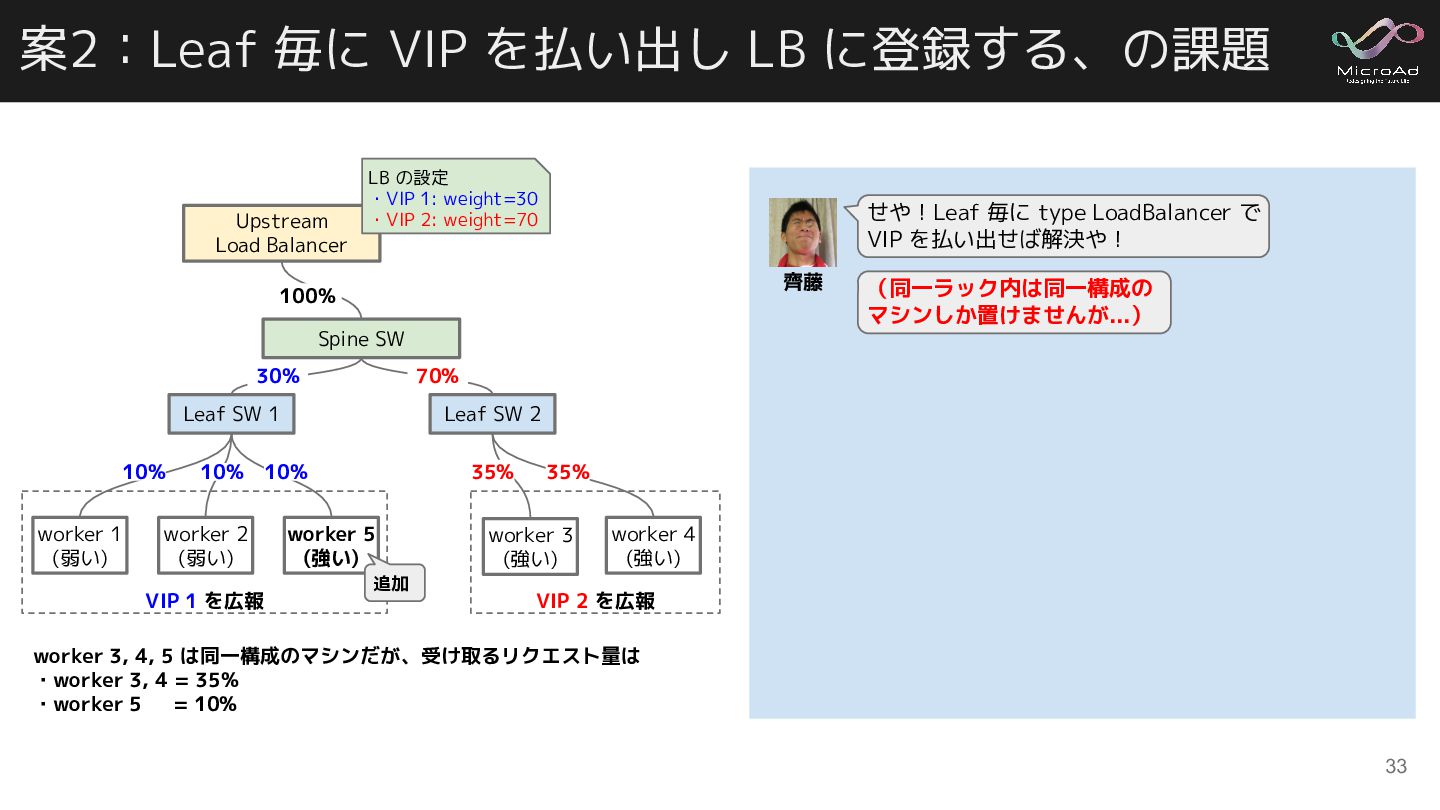
    の設定 ・VIP 1: weight=30 ・VIP 2: weight=70 せや!Leaf 毎に type LoadBalancer で VIP を払い出せば解決や! 齊藤 100% (同一ラック内は同一構成の マシンしか置けませんが...) Spine SW 30% 10% worker 1 (弱い) 70% Leaf SW 1 Leaf SW 2 10% 35% worker 2 (弱い) VIP 1 を広報 10% worker 5 (強い) 追加 35% worker 3 (強い) worker 4 (強い) VIP 2 を広報 worker 3, 4, 5 は同一構成のマシンだが、受け取るリクエスト量は ・worker 3, 4 = 35% ・worker 5 = 10% 33
  27. 案2:Leaf 毎に VIP を払い出し LB に登録する、の課題 Upstream Load Balancer LB

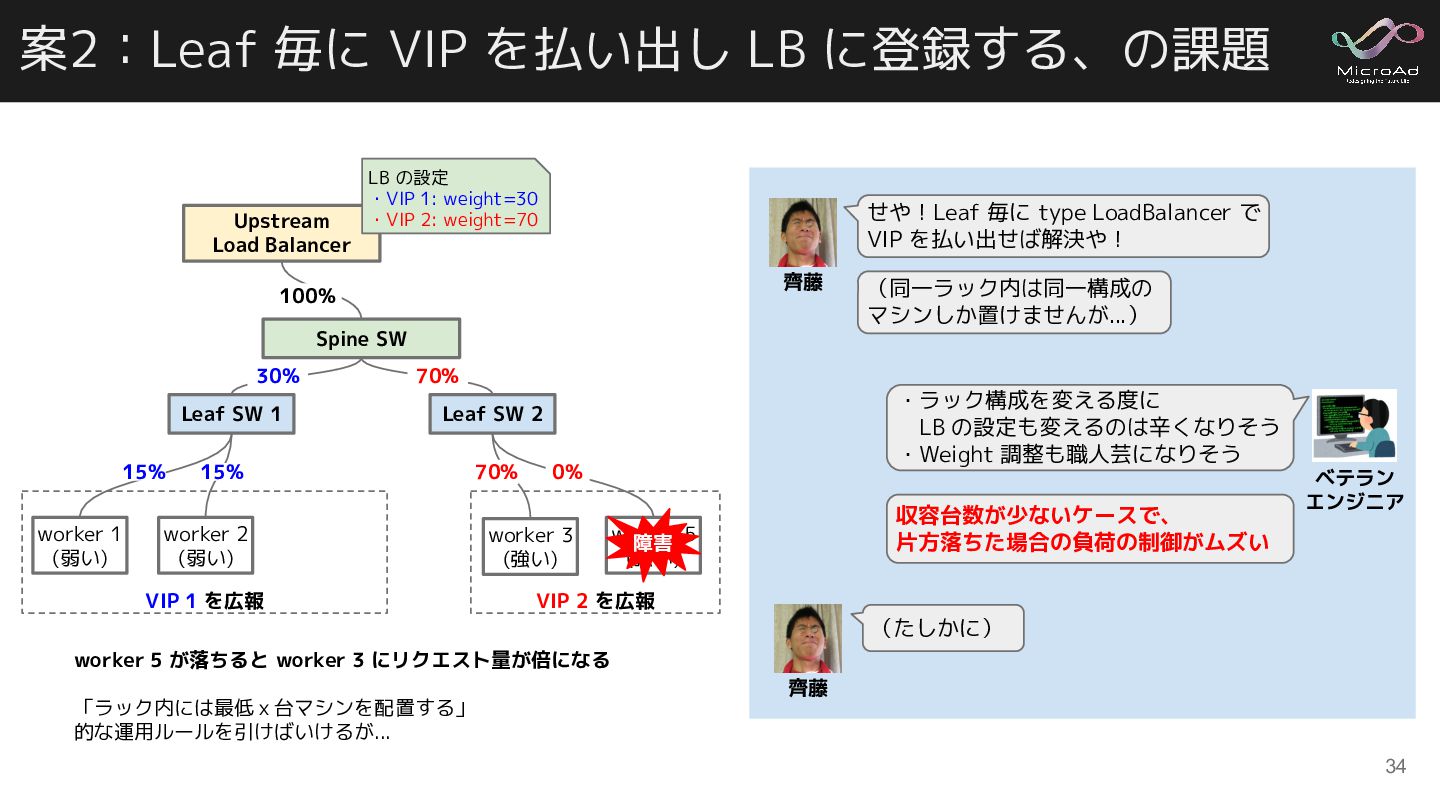
    の設定 ・VIP 1: weight=30 ・VIP 2: weight=70 せや!Leaf 毎に type LoadBalancer で VIP を払い出せば解決や! 齊藤 100% (同一ラック内は同一構成の マシンしか置けませんが...) Spine SW 30% 15% worker 1 (弱い) 70% Leaf SW 1 Leaf SW 2 15% 70% worker 2 (弱い) VIP 1 を広報 ・ラック構成を変える度に LB の設定も変えるのは辛くなりそう ・Weight 調整も職人芸になりそう 0% worker 3 (強い) 収容台数が少ないケースで、 片方落ちた場合の負荷の制御がムズい worker 障害 5 (強い) ベテラン エンジニア VIP 2 を広報 (たしかに) worker 5 が落ちると worker 3 にリクエスト量が倍になる 齊藤 「ラック内には最低x台マシンを配置する」 的な運用ルールを引けばいけるが... 34
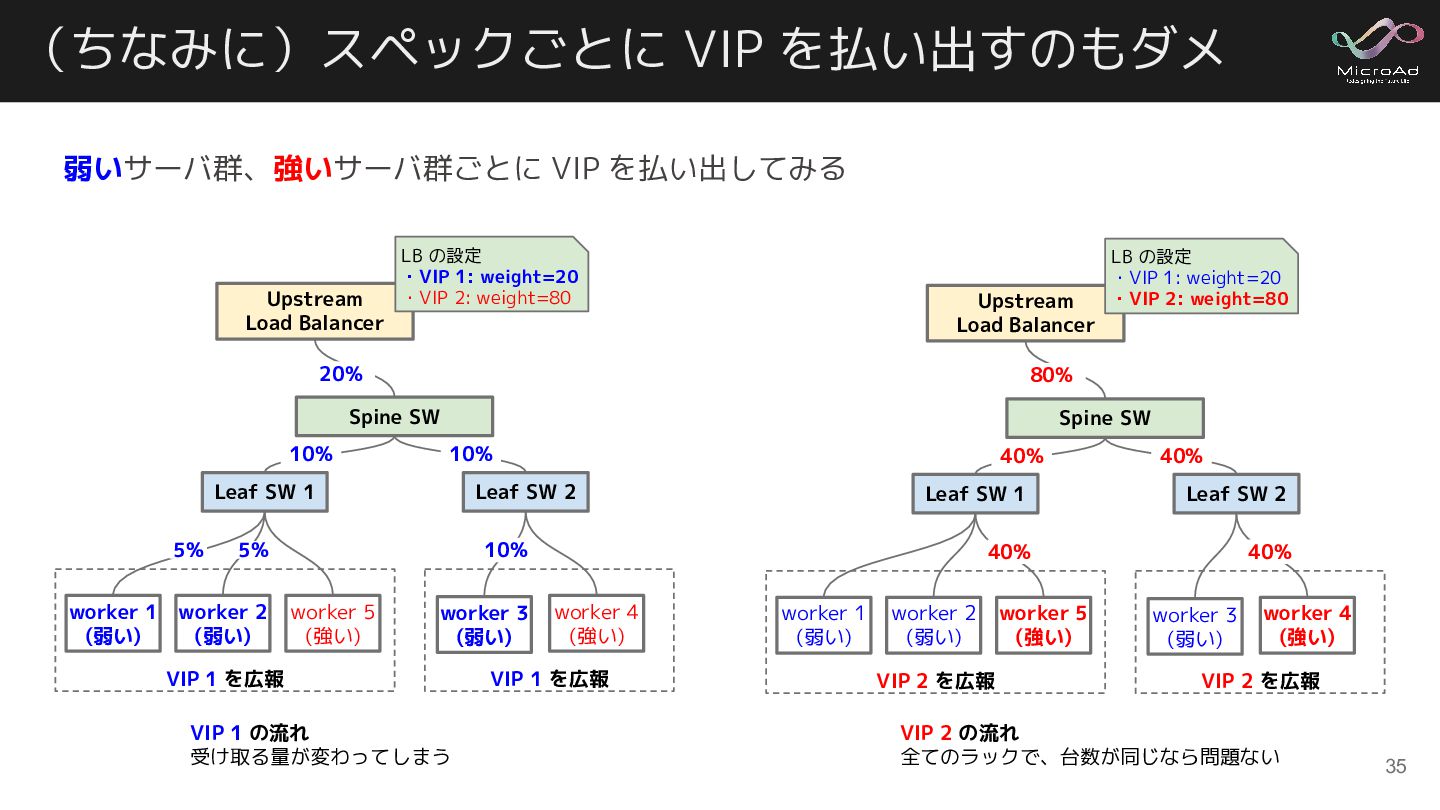
  28. (ちなみに)スペックごとに VIP を払い出すのもダメ 弱いサーバ群、強いサーバ群ごとに VIP を払い出してみる Upstream Load Balancer LB

    の設定 ・VIP 1: weight=20 ・VIP 2: weight=80 Upstream Load Balancer 20% 80% Spine SW 10% Spine SW 10% Leaf SW 1 5% worker 1 (弱い) 40% Leaf SW 2 worker 5 (強い) worker 3 (弱い) VIP 1 を広報 VIP 1 の流れ 受け取る量が変わってしまう worker 4 (強い) VIP 1 を広報 worker 1 (弱い) 40% Leaf SW 1 Leaf SW 2 40% 40% 10% 5% worker 2 (弱い) LB の設定 ・VIP 1: weight=20 ・VIP 2: weight=80 worker 2 (弱い) VIP 2 を広報 worker 5 (強い) worker 3 (弱い) worker 4 (強い) VIP 2 を広報 VIP 2 の流れ 全てのラックで、台数が同じなら問題ない 35
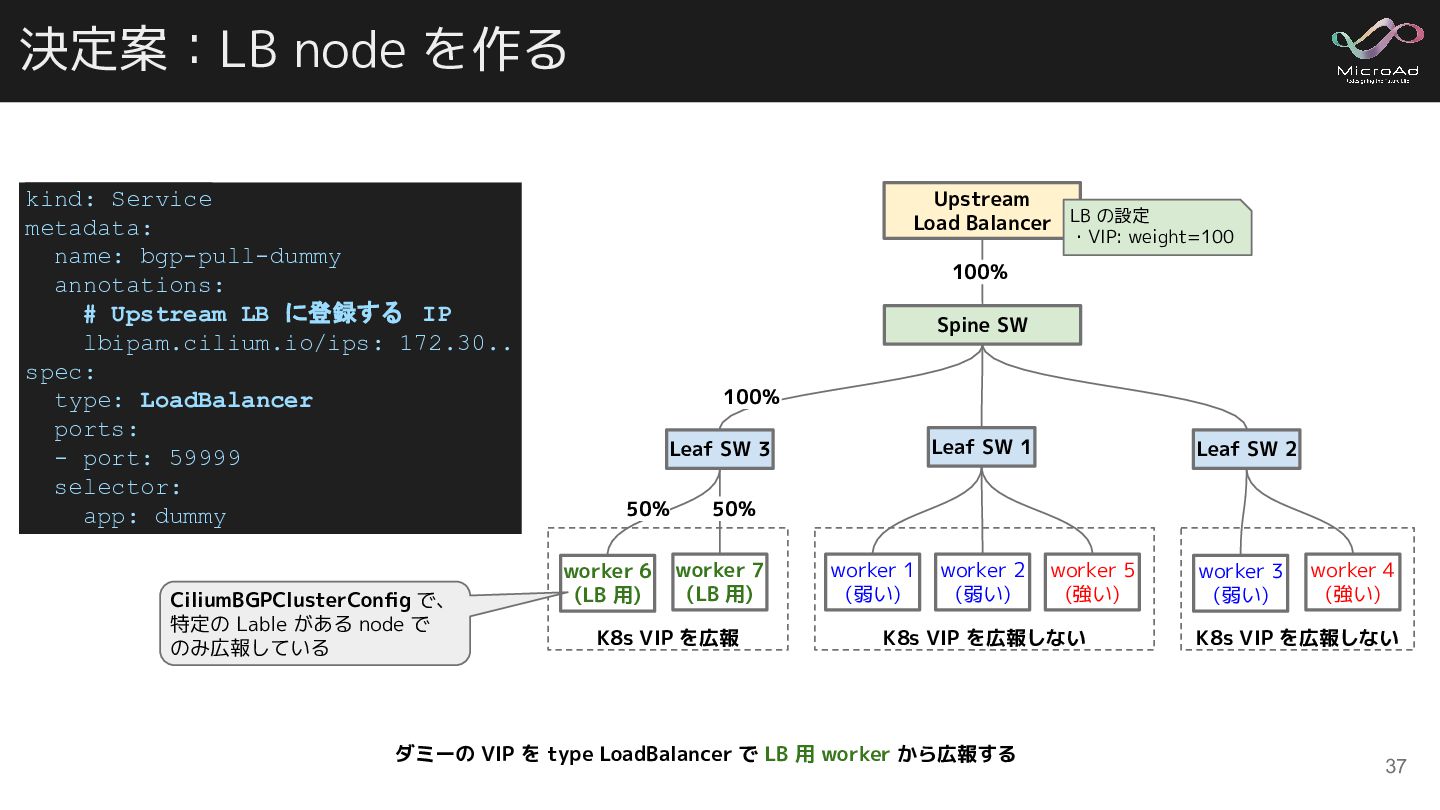
  29. 決定案:LB node を作る kind: Service metadata: name: bgp-pull-dummy annotations: #

    Upstream LB に登録する IP lbipam.cilium.io/ips: 172.30.. spec: type: LoadBalancer ports: - port: 59999 selector: app: dummy CiliumBGPClusterConfig で、 特定の Lable がある node で のみ広報している Upstream Load Balancer LB の設定 ・VIP: weight=100 100% Spine SW 100% Leaf SW 1 Leaf SW 3 50% worker 6 (LB 用) Leaf SW 2 50% worker 7 (LB 用) K8s VIP を広報 worker 1 (弱い) worker 2 (弱い) worker 5 (強い) K8s VIP を広報しない ダミーの VIP を type LoadBalancer で LB 用 worker から広報する worker 3 (弱い) worker 4 (強い) K8s VIP を広報しない 37
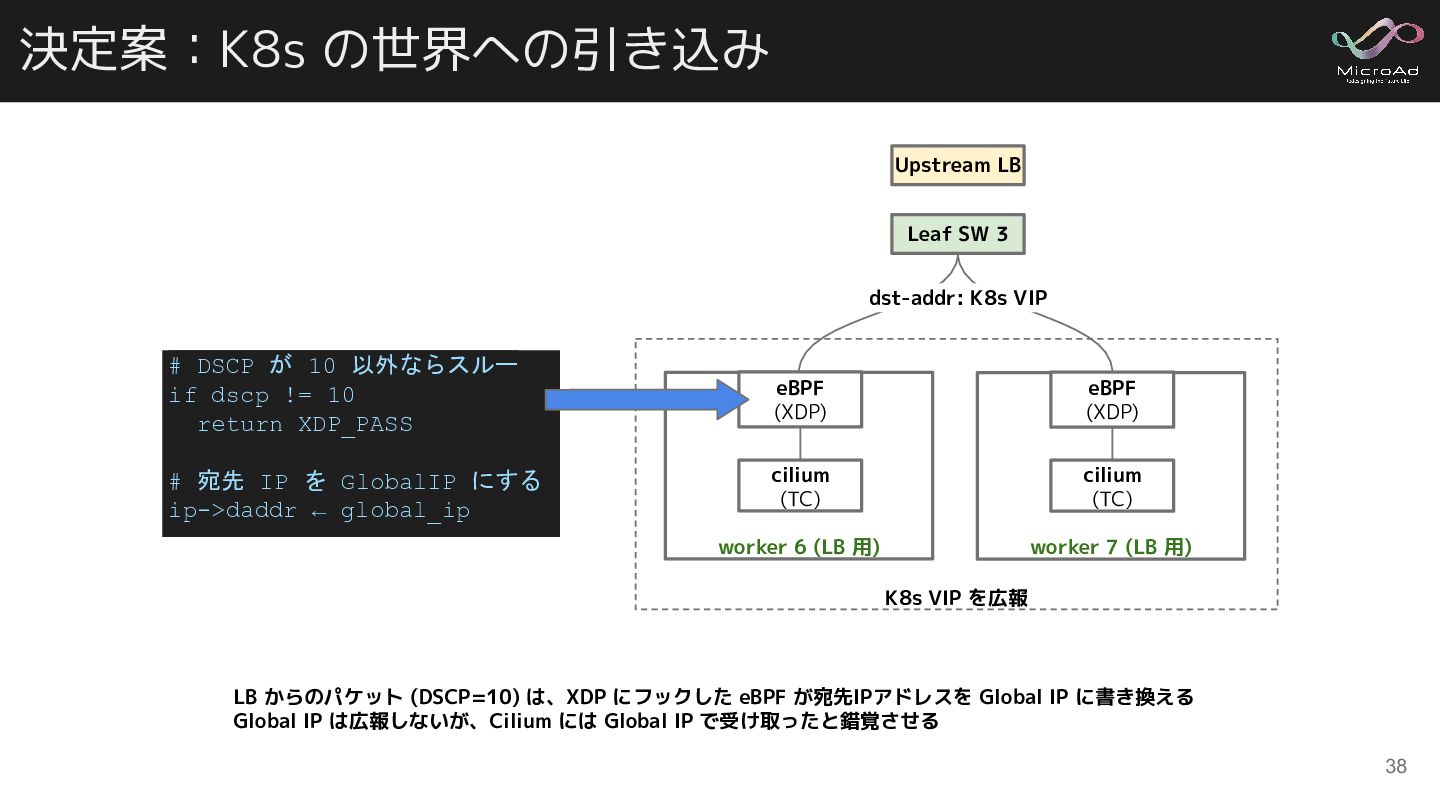
  30. 決定案:K8s の世界への引き込み Upstream LB Leaf SW 3 dst-addr: K8s VIP

    # DSCP が 10 以外ならスルー if dscp != 10 return XDP_PASS eBPF (XDP) eBPF (XDP) # 宛先 IP を GlobalIP にする ip->daddr ← global_ip cilium (TC) cilium (TC) worker 6 (LB 用) worker 7 (LB 用) K8s VIP を広報 LB からのパケット (DSCP=10) は、XDP にフックした eBPF が宛先IPアドレスを Global IP に書き換える Global IP は広報しないが、Cilium には Global IP で受け取ったと錯覚させる 38
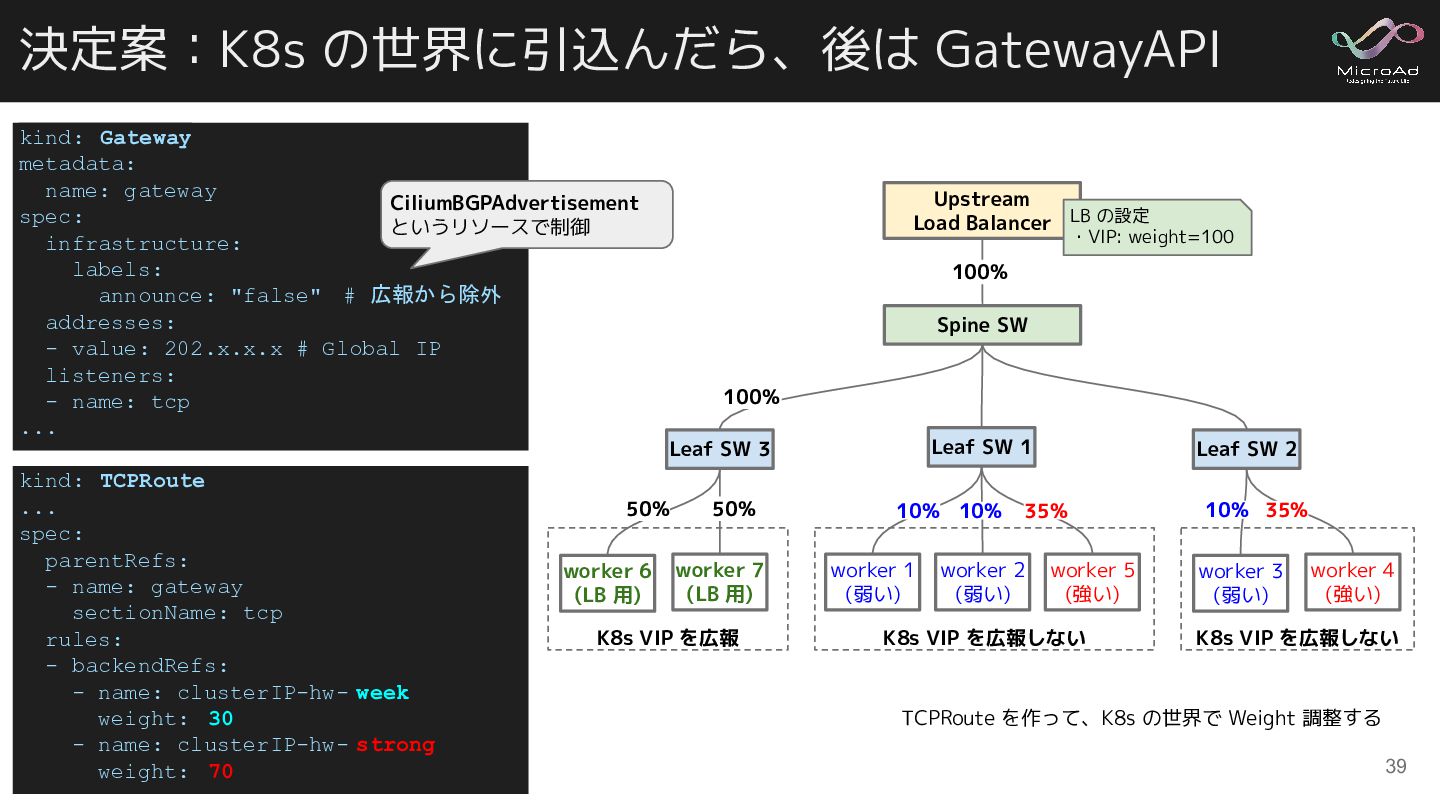
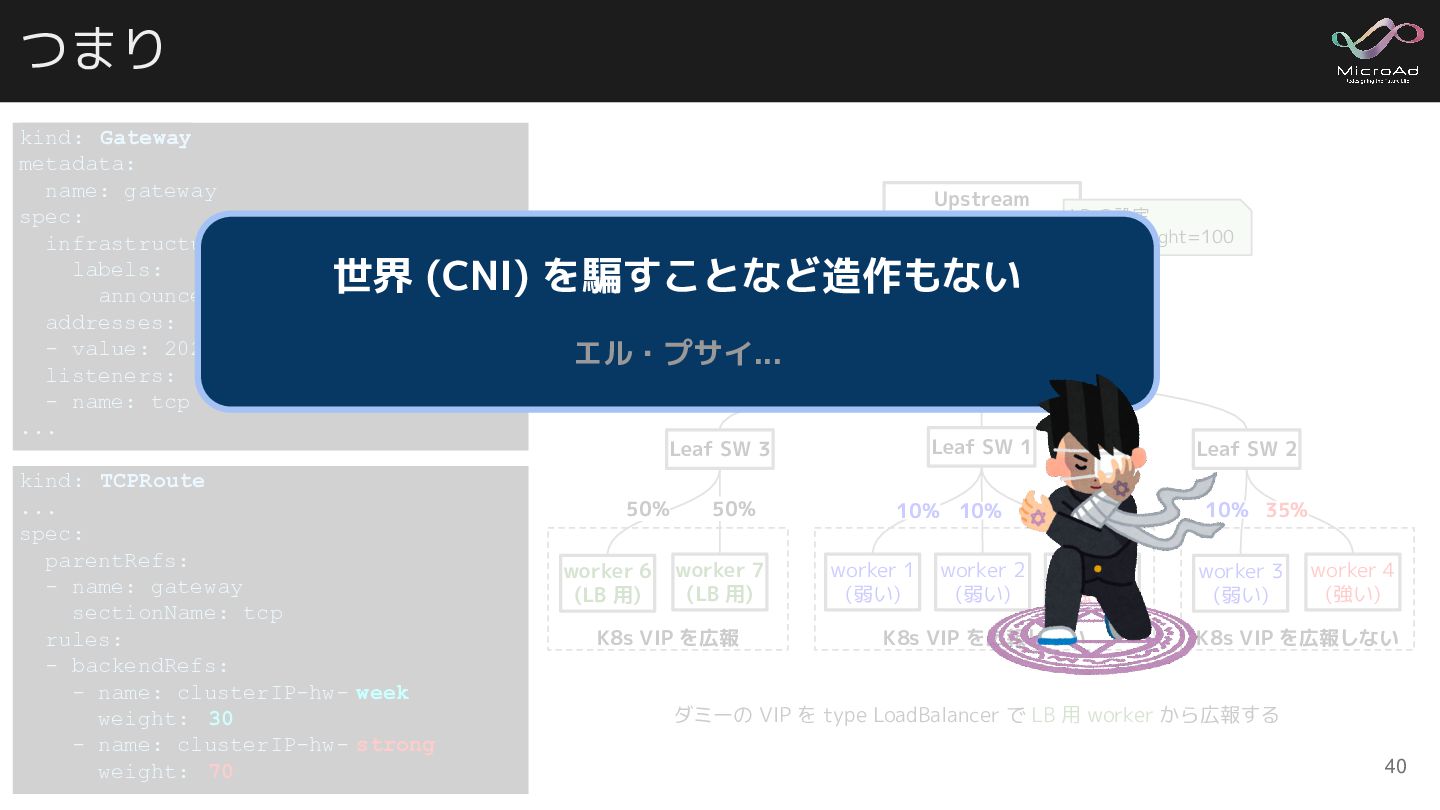
  31. 決定案:K8s の世界に引込んだら、後は GatewayAPI kind: Gateway metadata: name: gateway CiliumBGPAdvertisement spec:

    というリソースで制御 infrastructure: labels: announce: "false" # 広報から除外 addresses: - value: 202.x.x.x # Global IP listeners: - name: tcp ... Upstream Load Balancer LB の設定 ・VIP: weight=100 100% Spine SW 100% Leaf SW 1 Leaf SW 3 kind: TCPRoute ... spec: parentRefs: - name: gateway sectionName: tcp rules: - backendRefs: - name: clusterIP-hw- week weight: 30 - name: clusterIP-hw- strong weight: 70 50% worker 6 (LB 用) 50% worker 7 (LB 用) K8s VIP を広報 10% 10% worker 1 (弱い) Leaf SW 2 35% worker 2 (弱い) worker 5 (強い) K8s VIP を広報しない 10% 35% worker 3 (弱い) worker 4 (強い) K8s VIP を広報しない TCPRoute を作って、K8s の世界で Weight 調整する 39
  32. つまり kind: Gateway metadata: name: gateway spec: infrastructure: labels: announce:

    "false" # 広報から除外 addresses: - value: 202.x.x.x # Global IP listeners: - name: tcp ... Upstream Load Balancer LB の設定 ・VIP: weight=100 100% 世界 (CNI) を騙すことなど造作もない Spine SW エル・プサイ... 100% Leaf SW 1 Leaf SW 3 kind: TCPRoute ... spec: parentRefs: - name: gateway sectionName: tcp rules: - backendRefs: - name: clusterIP-hw- week weight: 30 - name: clusterIP-hw- strong weight: 70 50% worker 6 (LB 用) 50% worker 7 (LB 用) K8s VIP を広報 10% 10% worker 1 (弱い) Leaf SW 2 35% worker 2 (弱い) worker 5 (強い) K8s VIP を広報しない 10% 35% worker 3 (弱い) worker 4 (強い) K8s VIP を広報しない ダミーの VIP を type LoadBalancer で LB 用 worker から広報する 40
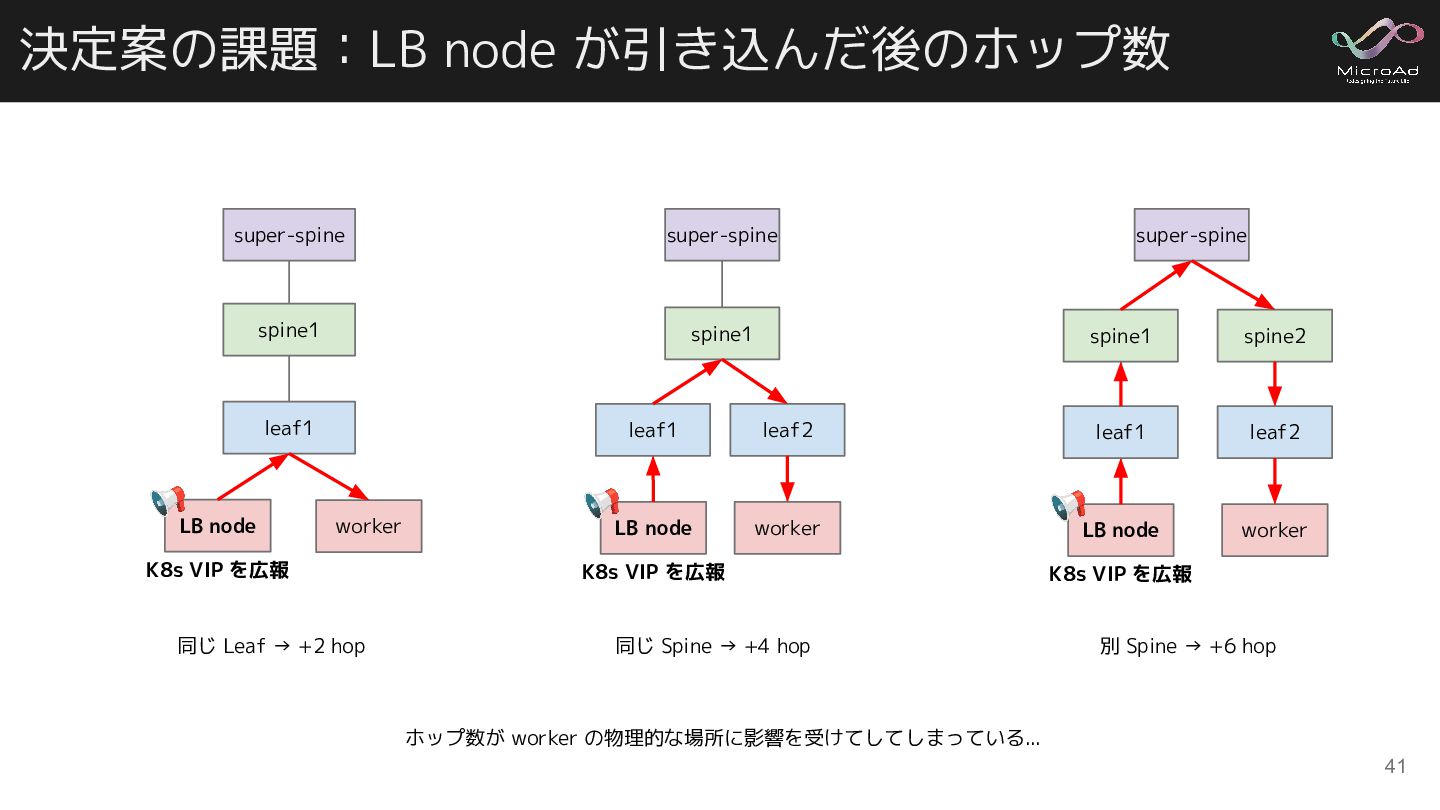
  33. 決定案の課題:LB node が引き込んだ後のホップ数 super-spine super-spine spine1 spine1 leaf1 📢 LB

    node worker K8s VIP を広報 同じ Leaf → +2 hop leaf1 leaf2 LB node worker 📢 K8s VIP を広報 同じ Spine → +4 hop super-spine spine1 spine2 leaf1 leaf2 LB node worker 📢 K8s VIP を広報 別 Spine → +6 hop ホップ数が worker の物理的な場所に影響を受けてしてしまっている... 41
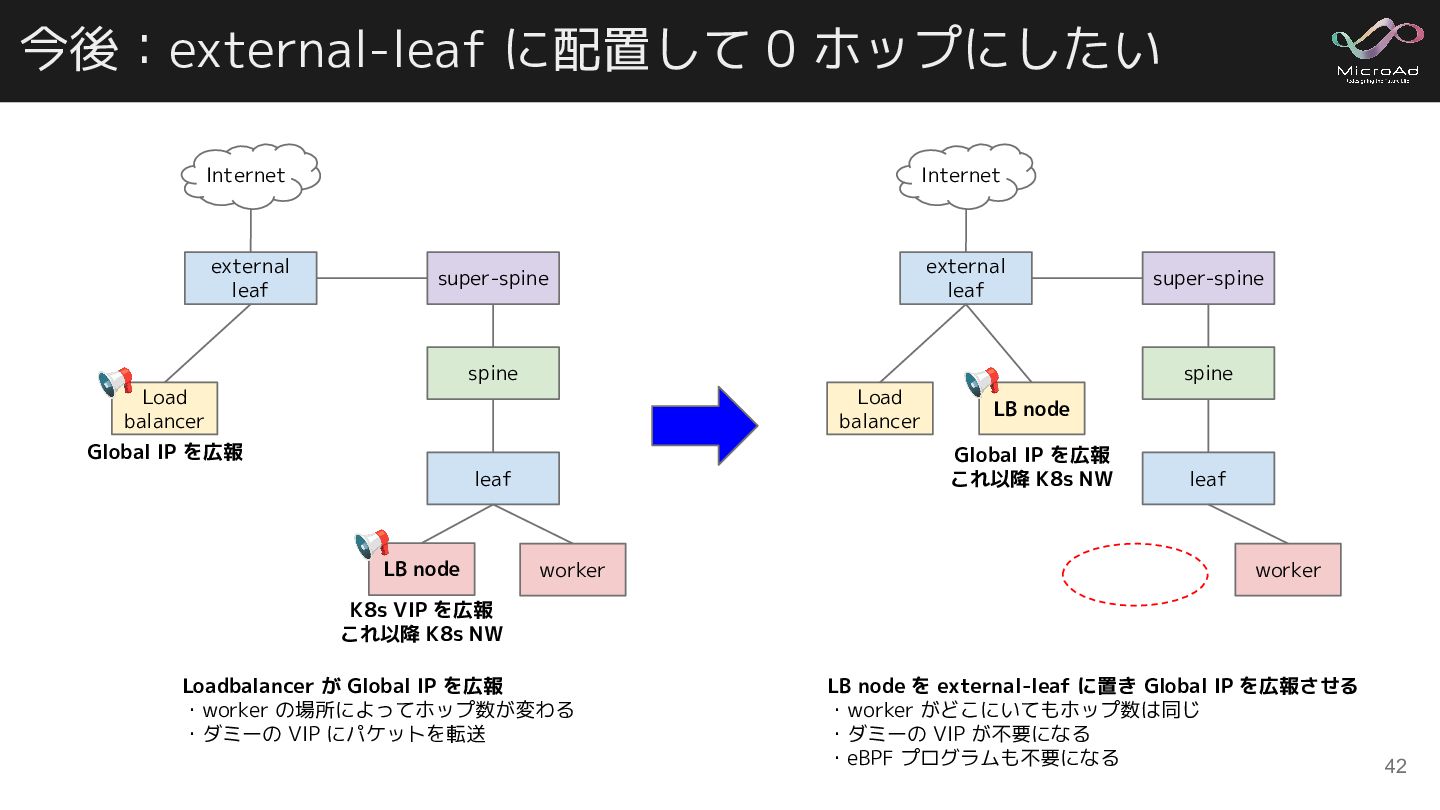
  34. 今後:external-leaf に配置して 0 ホップにしたい Internet Internet external leaf external leaf

    super-spine spine 📢 Load Load balancer balancer Global IP を広報 LB node worker spine LB node Global IP を広報 これ以降 K8s NW leaf 📢 📢 super-spine leaf worker K8s VIP を広報 これ以降 K8s NW Loadbalancer が Global IP を広報 ・worker の場所によってホップ数が変わる ・ダミーの VIP にパケットを転送 LB node を external-leaf に置き Global IP を広報させる ・worker がどこにいてもホップ数は同じ ・ダミーの VIP が不要になる ・eBPF プログラムも不要になる 42
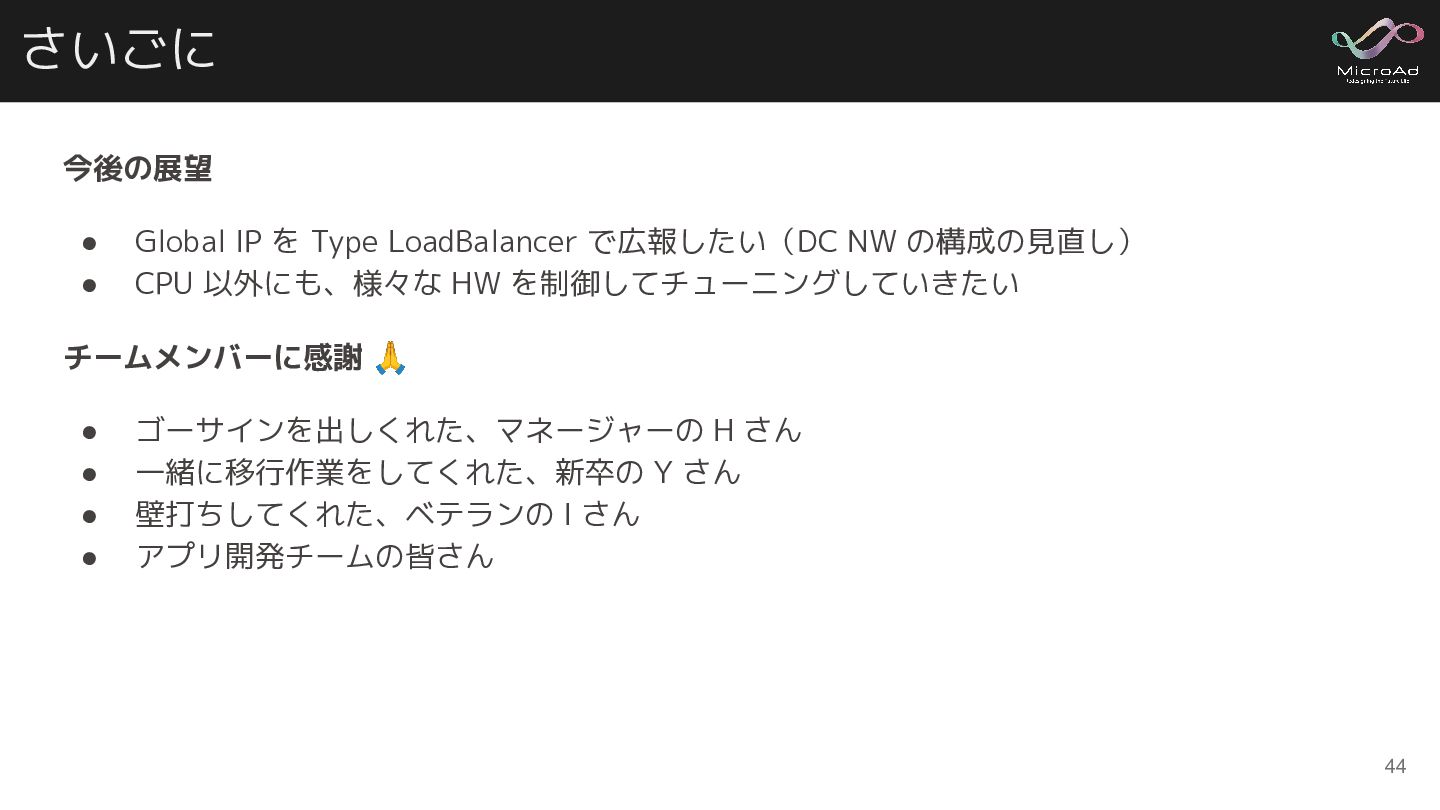
  35. さいごに 今後の展望 • • Global IP を Type LoadBalancer で広報したい(DC

    NW の構成の見直し) CPU 以外にも、様々な HW を制御してチューニングしていきたい チームメンバーに感謝 🙏 • • • • ゴーサインを出しくれた、マネージャーの H さん 一緒に移行作業をしてくれた、新卒の Y さん 壁打ちしてくれた、ベテランの I さん アプリ開発チームの皆さん 44