Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
When Does a Local Qwen Start to Break
Search
Sponsored
·
Ship Features Fearlessly
Turn features on and off without deploys. Used by thousands of Ruby developers.
→
Shoto
September 04, 2026
Technology
38
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
When Does a Local Qwen Start to Break
Shoto
September 04, 2026
More Decks by Shoto
See All by Shoto
When Does a Local Qwen Start to Break
morshoto
0
250
Other Decks in Technology
See All in Technology
10年後、Engineering 行為を剥奪されるとして、わたしたちは、どう、何を創ればいいだろうか。 / If Engineering Is Taken Away in 10 Years, How and What Should We Create?
bitkey
PRO
1
220
[JAWS-UG彩の国埼玉#12]そろそろ準備する?re:Invent2026をやさしく解説 / reinvent2026-sainokuni
sh_fk2
1
370
Running Kotlin + Quarkus with Lambda
nealle
1
4.1k
【データ横丁主催】AI エージェント時代のTranslytical Data Platform
shisyu_gaku
0
180
LLM-as-a-Judgeは本当に信頼できるのか――評価器を評価する話
taka_aki
2
1k
スプシの手作業からの解脱 ~更新はClaude Codeに、見せ方と使い方はGASアプリに任せる~
kentarofujii
0
170
Kiro Crewで「みのるん式」仕事術やってみた
minorun365
PRO
3
980
ウォンテッドリーの最近のプロダクトと技術の紹介
stomk
0
310
DBについての基礎説明(MySQL編) - コロプラ 2026年度 新卒研修
colopl
0
160
Browser Spec: Testing Hotwire with Ruby
takahashim
1
150
Tofu-Controller lightning talk @ Containerday 2026
gionn
0
150
価値について
gree_tech
PRO
0
140
Featured
See All Featured
Evolution of real-time – Irina Nazarova, EuRuKo, 2024
irinanazarova
9
1.6k
Fireside Chat
paigeccino
43
4.1k
AI: The stuff that nobody shows you
jnunemaker
PRO
10
1.2k
職位にかかわらず全員がリーダーシップを発揮するチーム作り / Building a team where everyone can demonstrate leadership regardless of position
madoxten
69
67k
The Success of Rails: Ensuring Growth for the Next 100 Years
eileencodes
47
8.4k
<Decoding/> the Language of Devs - We Love SEO 2024
nikkihalliwell
1
360
jQuery: Nuts, Bolts and Bling
dougneiner
66
8.6k
Building Better People: How to give real-time feedback that sticks.
wjessup
371
20k
Site-Speed That Sticks
csswizardry
13
1.6k
Exploring the Power of Turbo Streams & Action Cable | RailsConf2023
kevinliebholz
37
6.6k
The Cult of Friendly URLs
andyhume
79
7k
Building a Modern Day E-commerce SEO Strategy
aleyda
45
9.3k
Transcript
QWEN MEETUP TOKYO · LOCAL LLM EXPERIMENTS When Does a
Local Qwen Start to Break? 量子化して、長い文脈を入れて、それでも使えるのか? Qwen3.8-27B / llama.cpp / Apple Silicon 64GB Quantization × Context × Evaluation × Agent History
WHOAMI 2
Qwen Model とは? Sources: Qwen official blog / Qwen3.8-27B official
Hugging Face model repository (checked 2026-09-03) 3
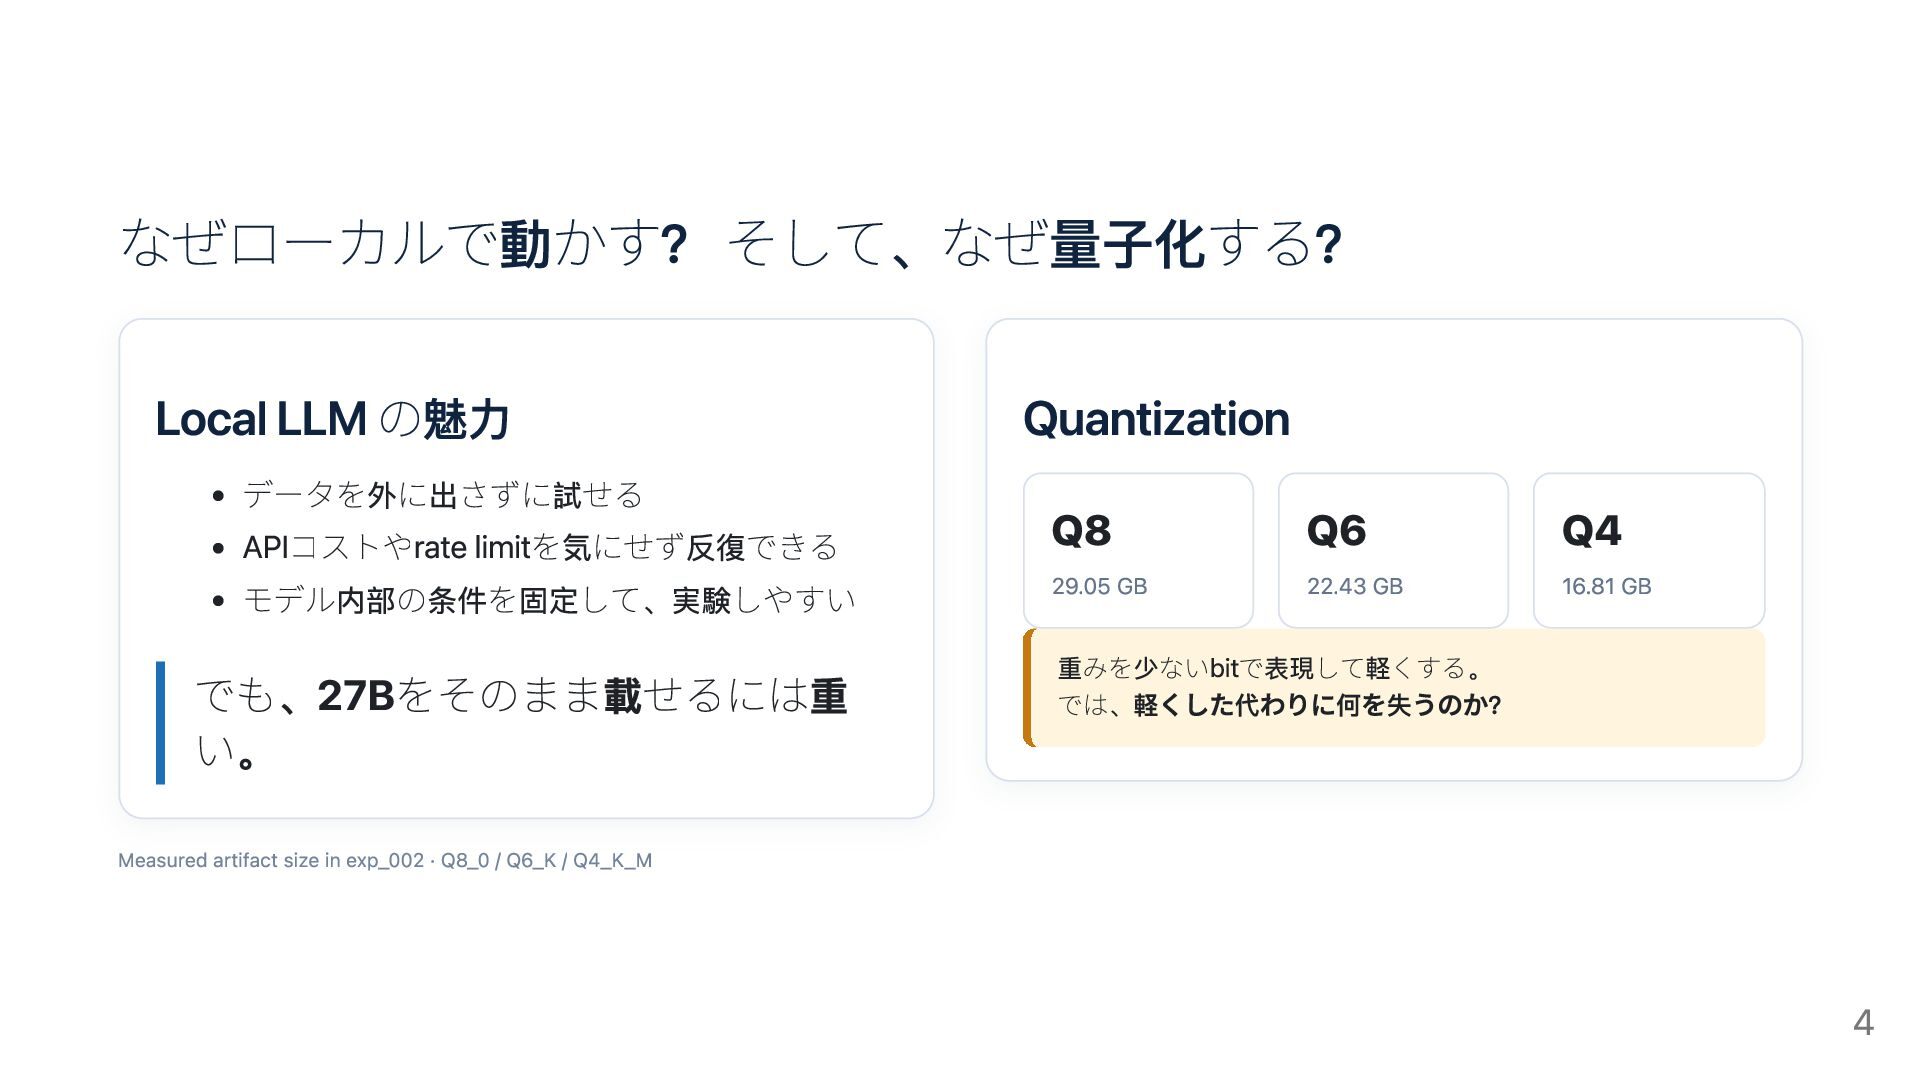
なぜローカルで動かす? そして、なぜ量子化する? Local LLM の魅力 データを外に出さずに試せる APIコストやrate limitを気にせず反復できる モデル内部の条件を固定して、実験しやすい でも、27Bをそのまま載せるには重
い。 Quantization Q8 29.05 GB Q6 22.43 GB Q4 16.81 GB 重みを少ないbitで表現して軽くする。 では、軽くした代わりに何を失うのか? Measured artifact size in exp_002 · Q8_0 / Q6_K / Q4_K_M 4
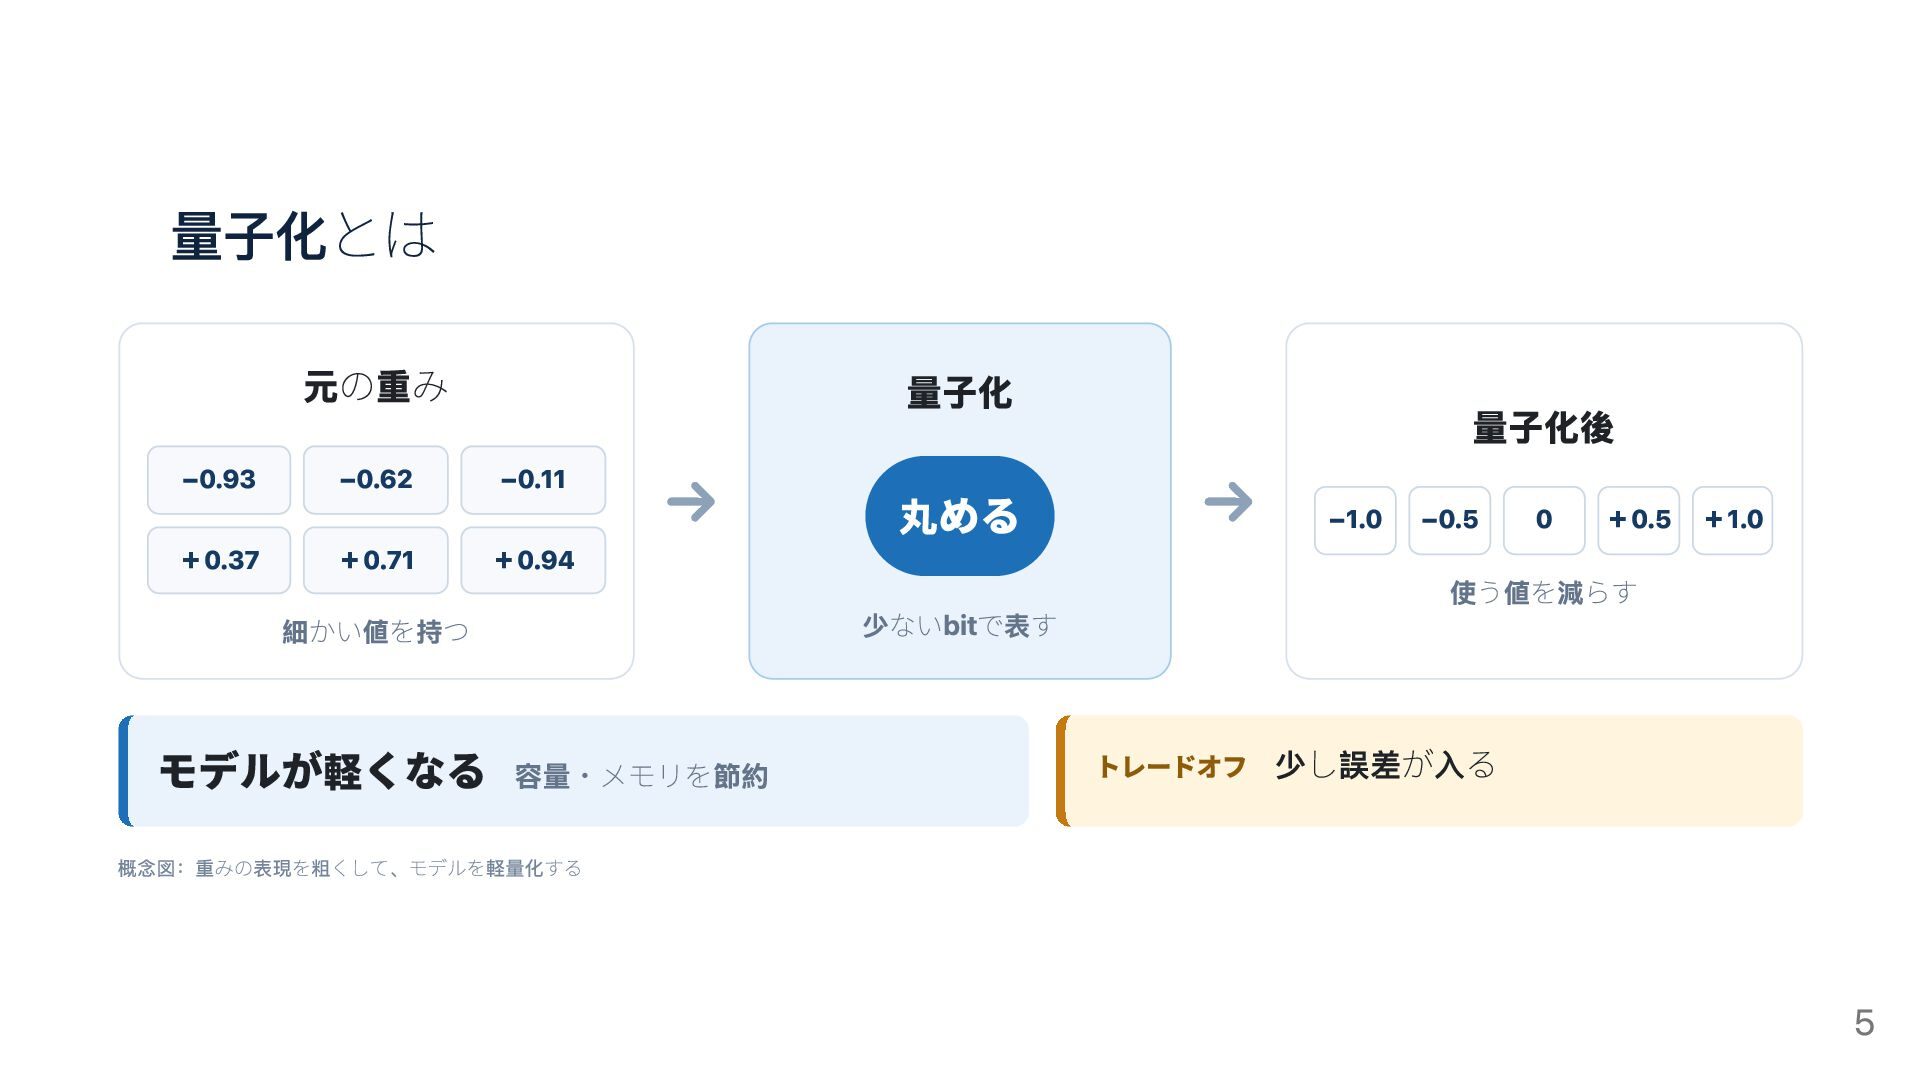
量子化とは 元の重み → 0.94 −0.93 −0.62 −0.11 +0.37 +0.71 +
細かい値を持つ モデルが軽くなる 容量・メモリを節約 量子化 丸める 少ないbitで表す 量子化後 → −1.0 −0.5 0 0.5 1.0 + + 使う値を減らす トレードオフ 少し誤差が入る 概念図:重みの表現を粗くして、モデルを軽量化する 5
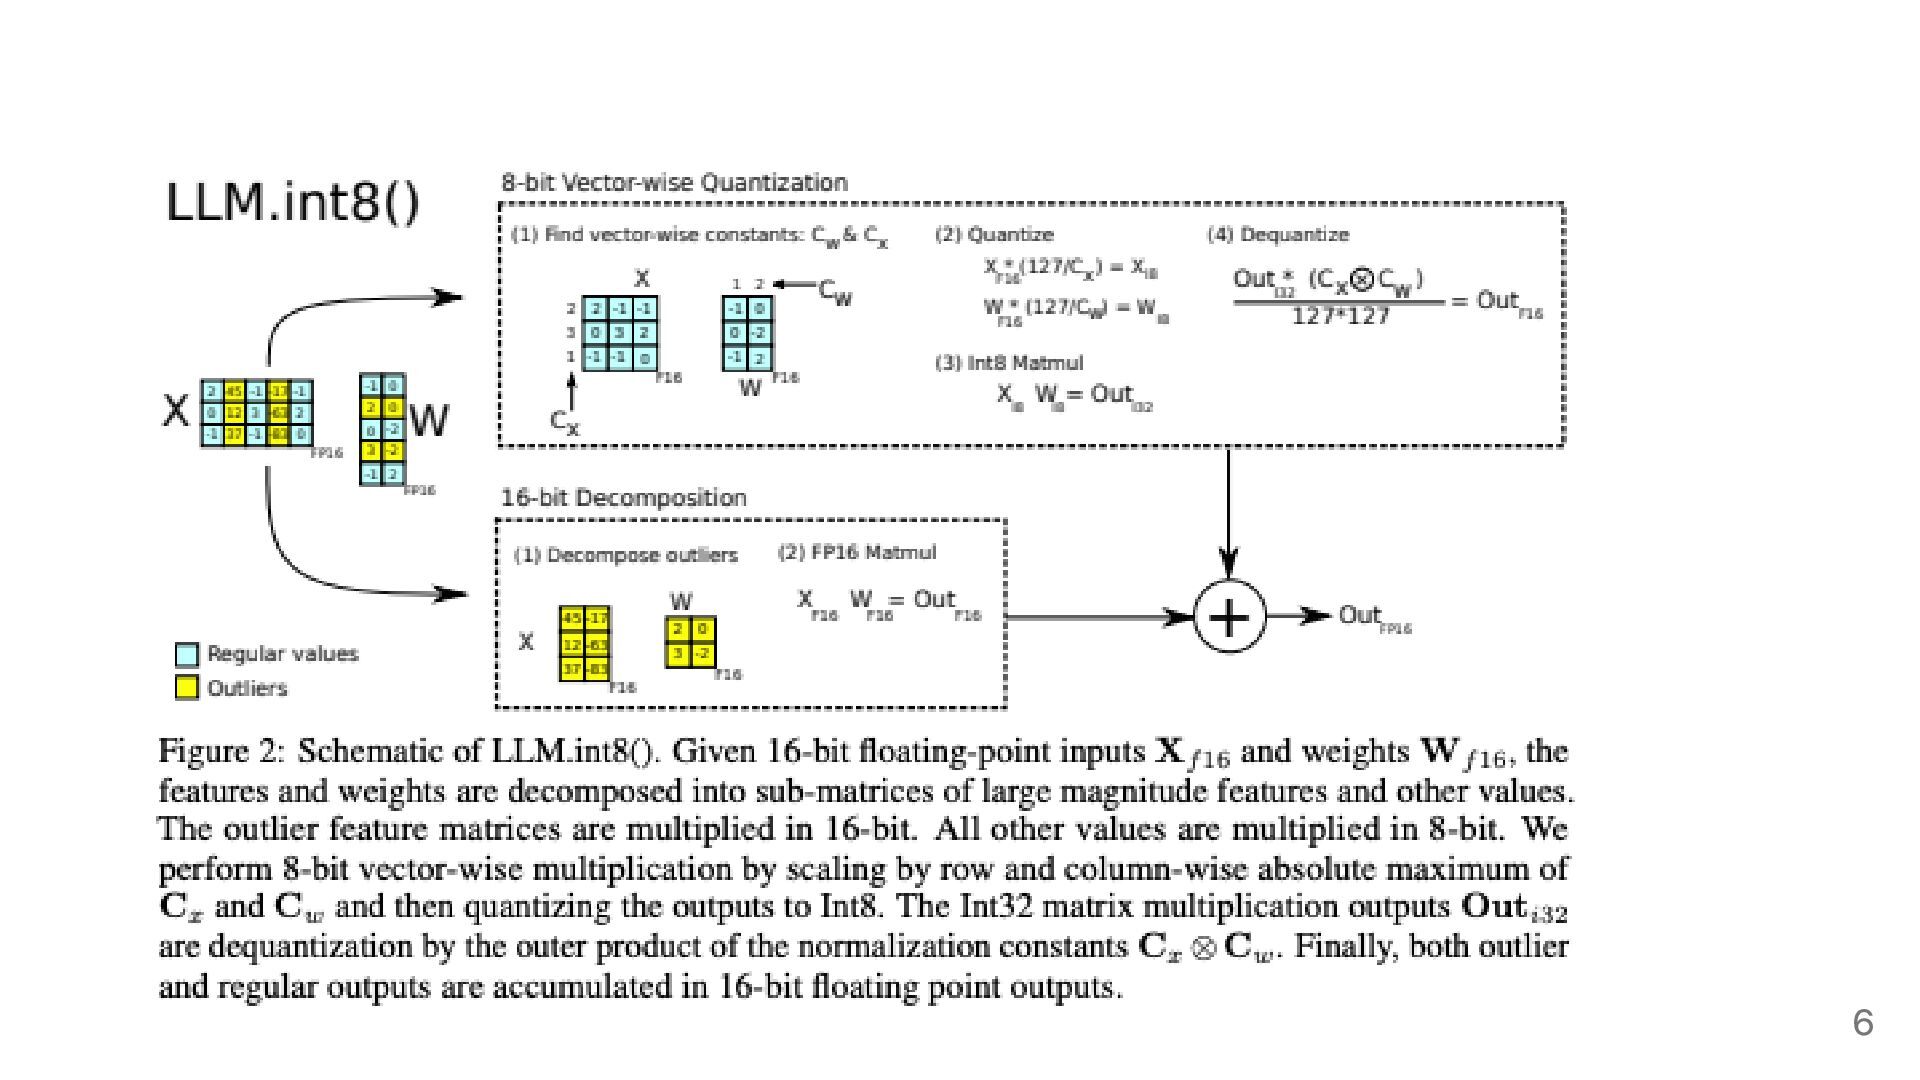
6
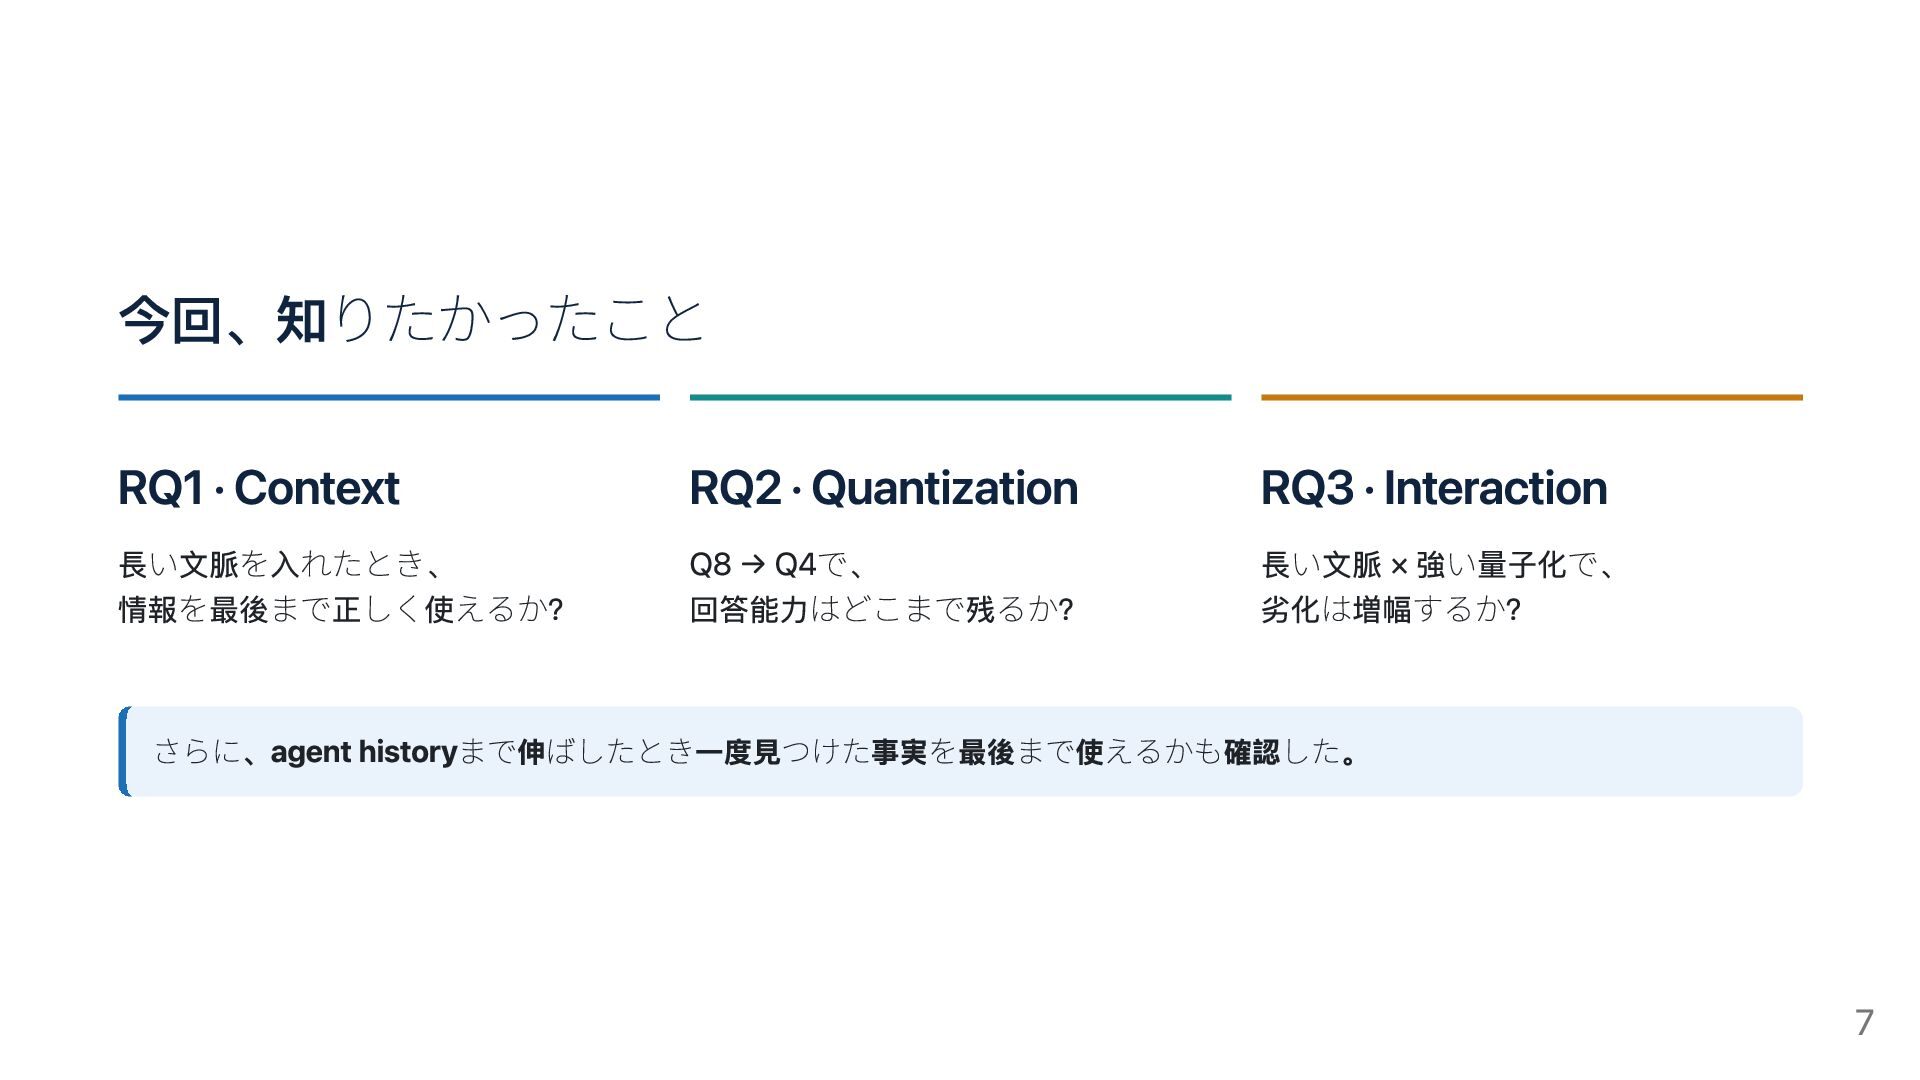
今回、知りたかったこと RQ1 · Context 長い文脈を入れたとき、 情報を最後まで正しく使えるか? RQ2 · Quantization Q8
→ Q4で、 回答能力はどこまで残るか? RQ3 · Interaction 長い文脈 × 強い量子化で、 劣化は増幅するか? さらに、agent historyまで伸ばしたとき一度見つけた事実を最後まで使えるかも確認した。 7
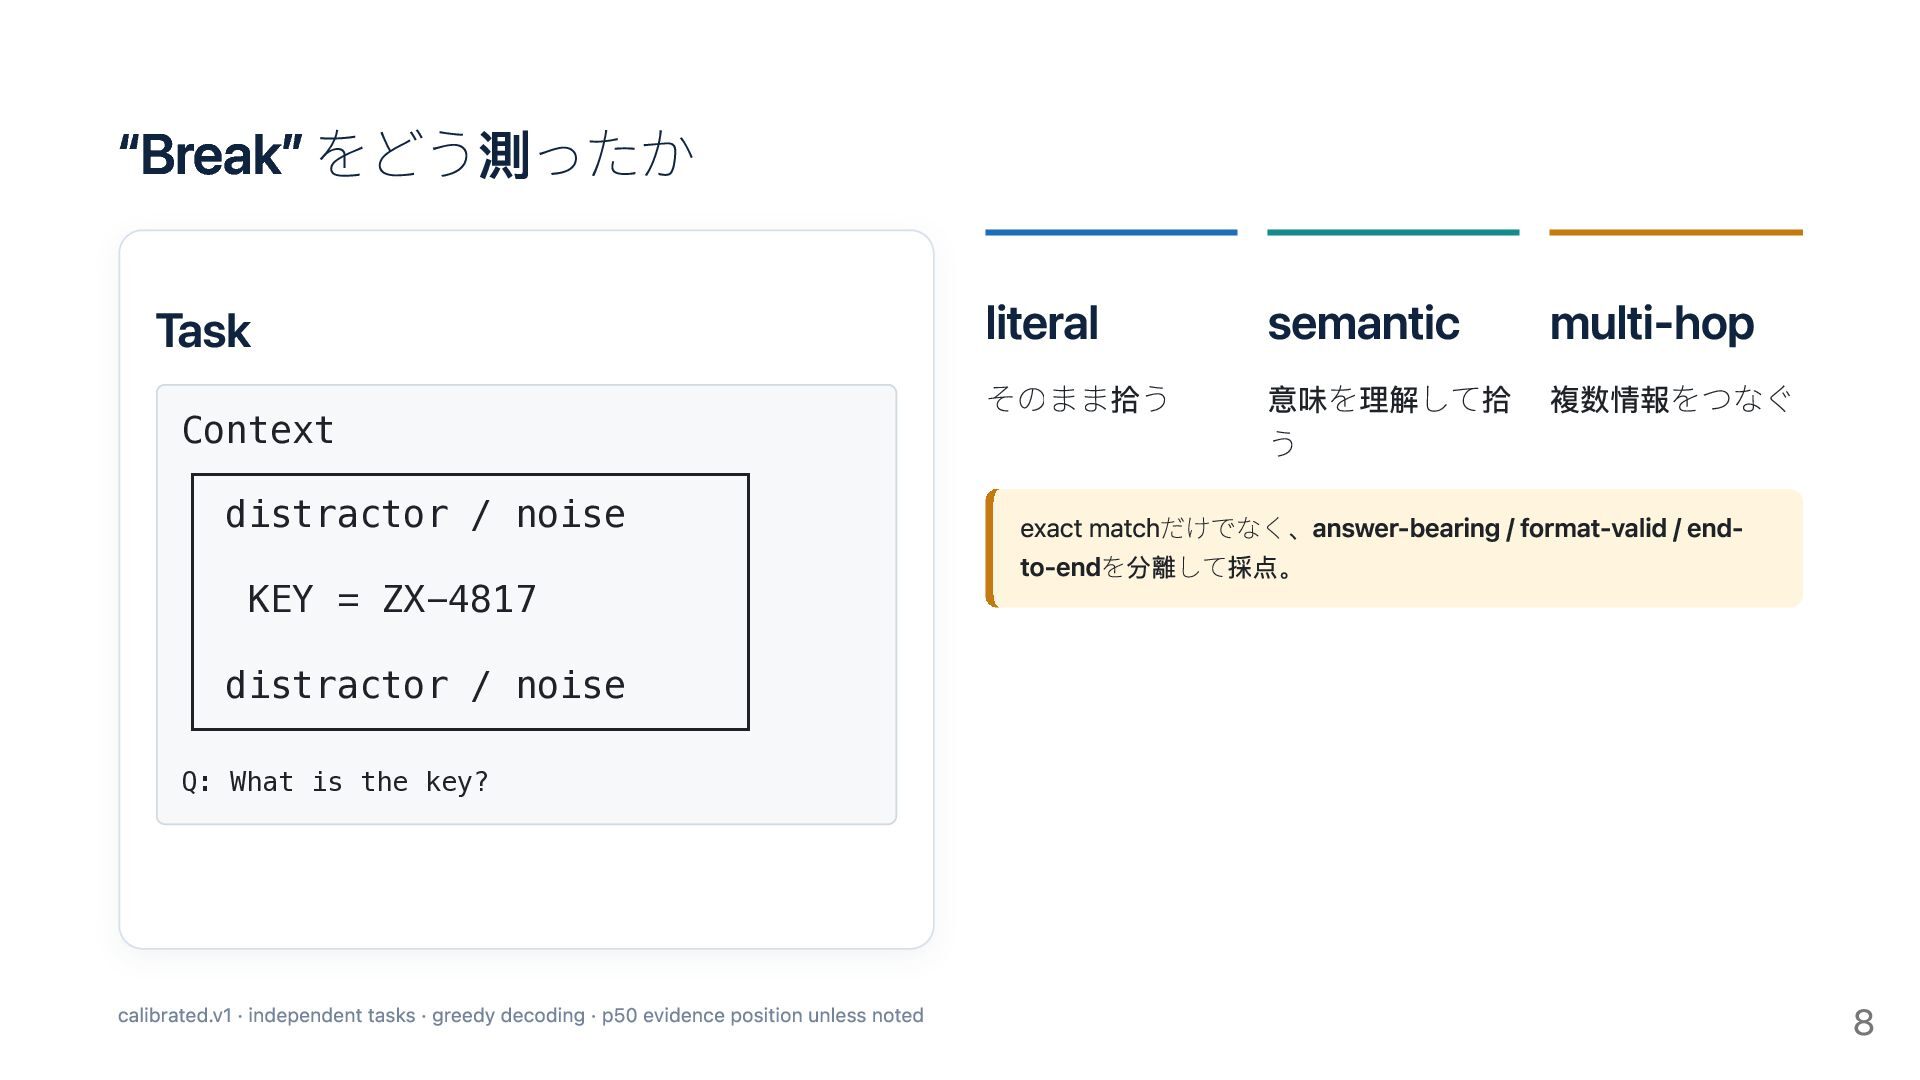
“Break” をどう測ったか Task Context ┌────────────────────────┐ │ distractor / noise │
│ │ │ KEY = ZX-4817 │ │ │ │ distractor / noise │ └────────────────────────┘ literal そのまま拾う semantic multi-hop 意味を理解して拾 複数情報をつなぐ う exact matchだけでなく、answer-bearing / format-valid / endto-endを分離して採点。 Q: What is the key? calibrated.v1 · independent tasks · greedy decoding · p50 evidence position unless noted 8
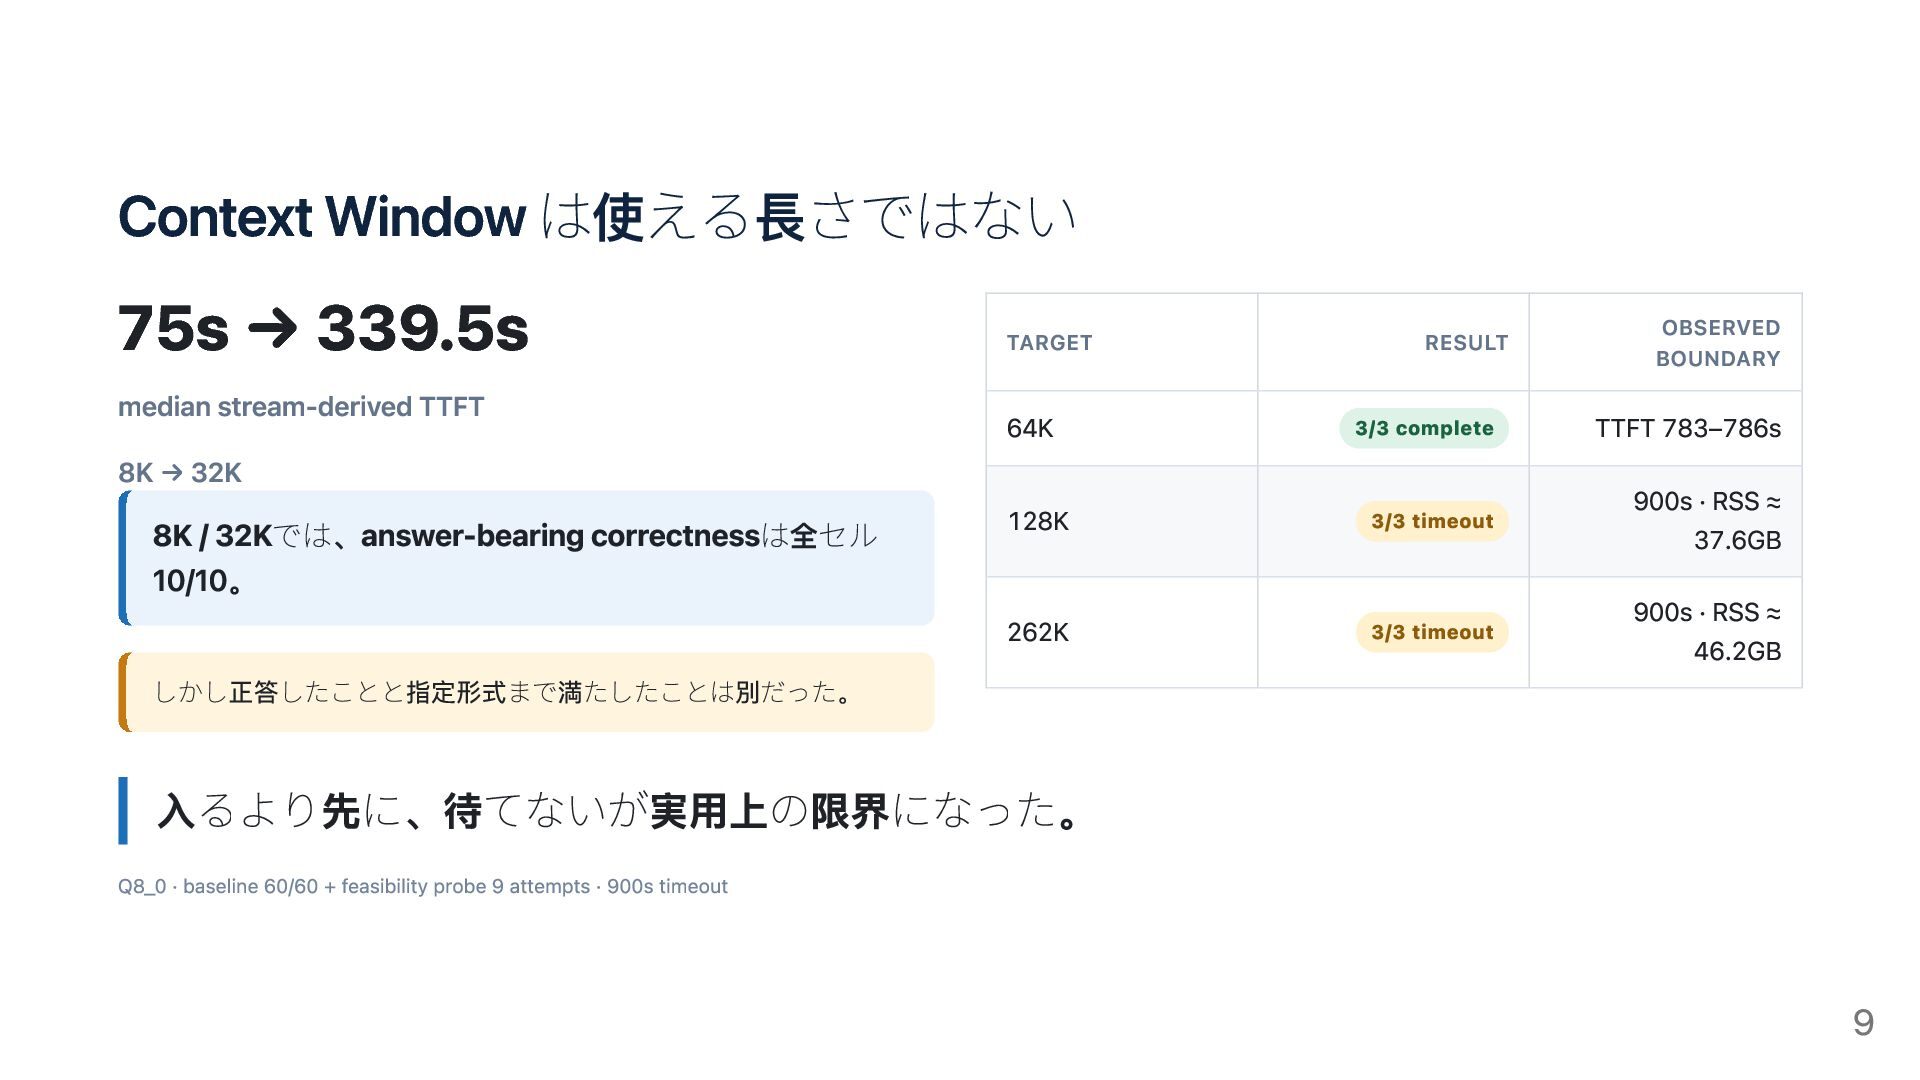
Context Window は使える長さではない 75s → 339.5s median stream-derived TTFT 8K
→ 32K 8K / 32Kでは、answer-bearing correctnessは全セル 10/10。 しかし正答したことと指定形式まで満たしたことは別だった。 RESULT OBSERVED BOUNDARY 64K 3/3 complete 128K 3/3 timeout 262K 3/3 timeout TTFT 783–786s 900s · RSS ≈ 37.6GB 900s · RSS ≈ 46.2GB TARGET 入るより先に、待てないが実用上の限界になった。 Q8_0 · baseline 60/60 + feasibility probe 9 attempts · 900s timeout 9
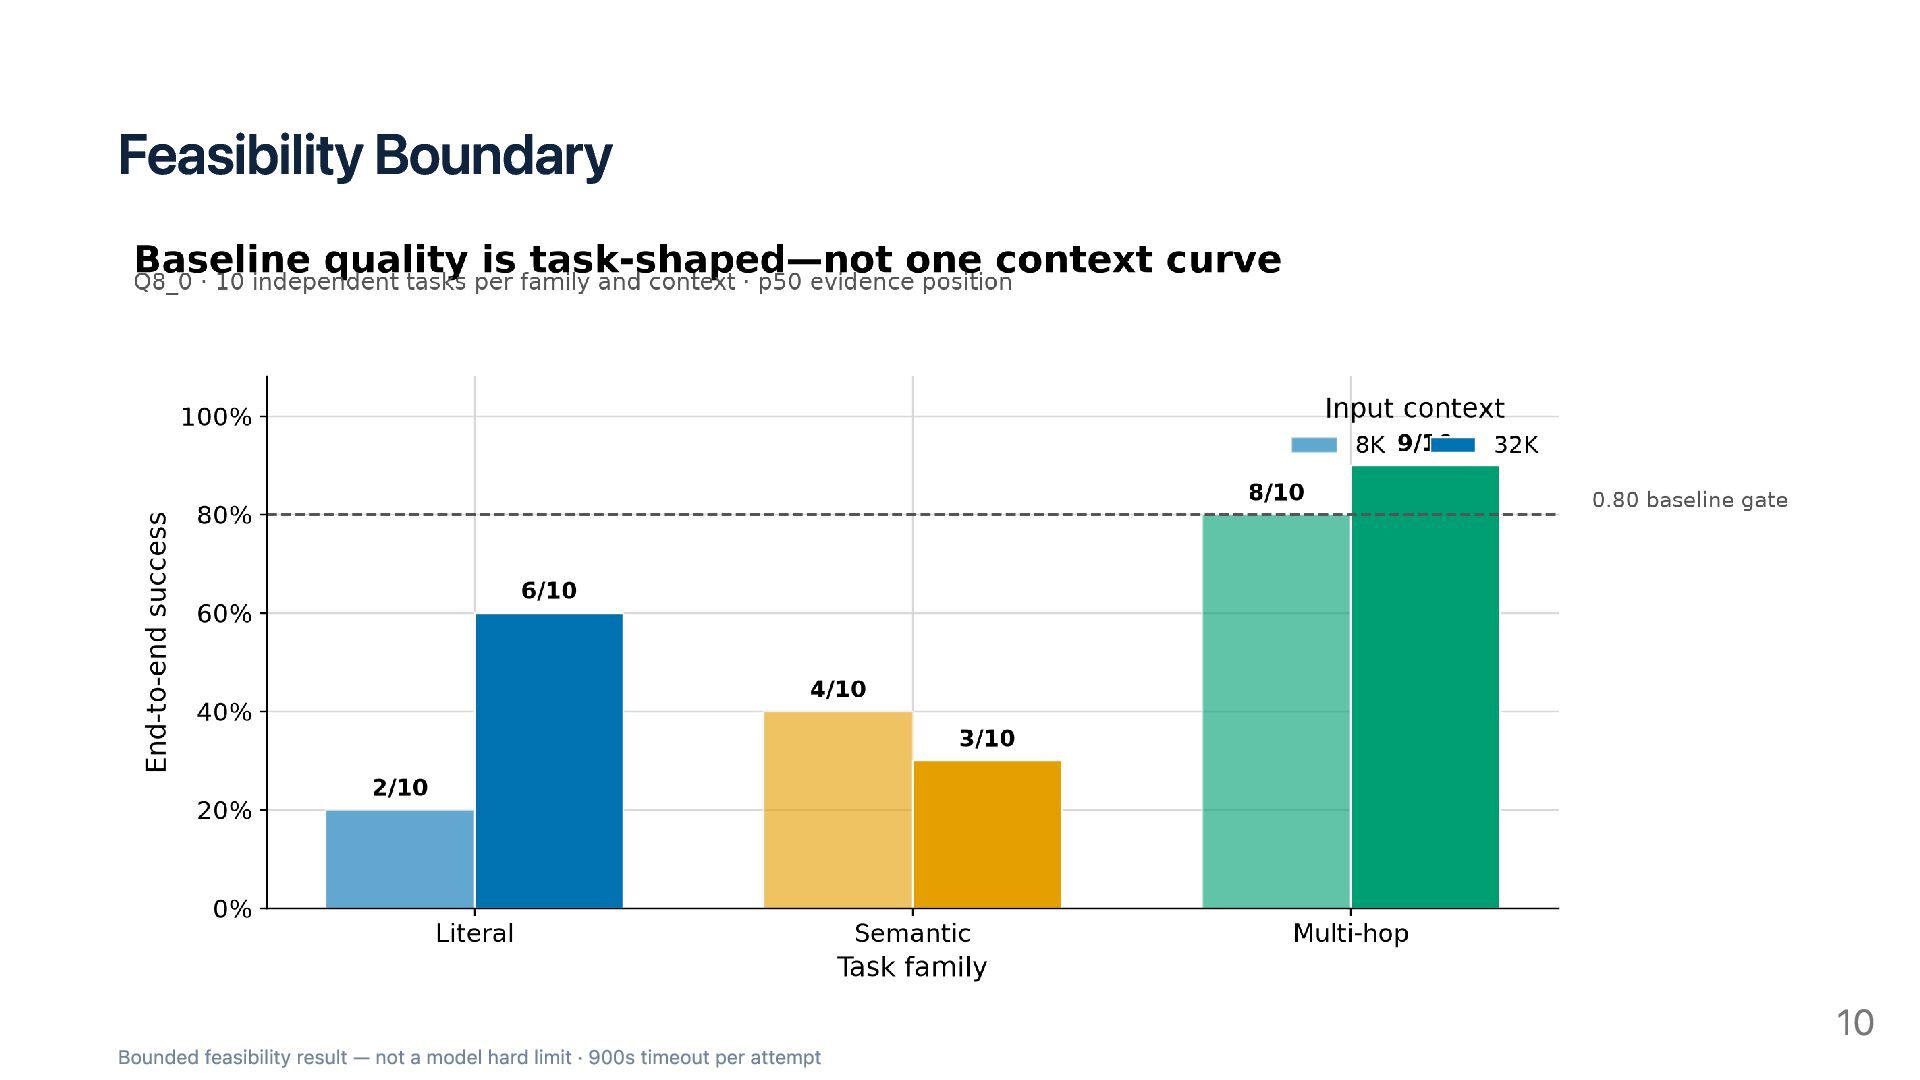
Feasibility Boundary Bounded feasibility result — not a model hard
limit · 900s timeout per attempt 10
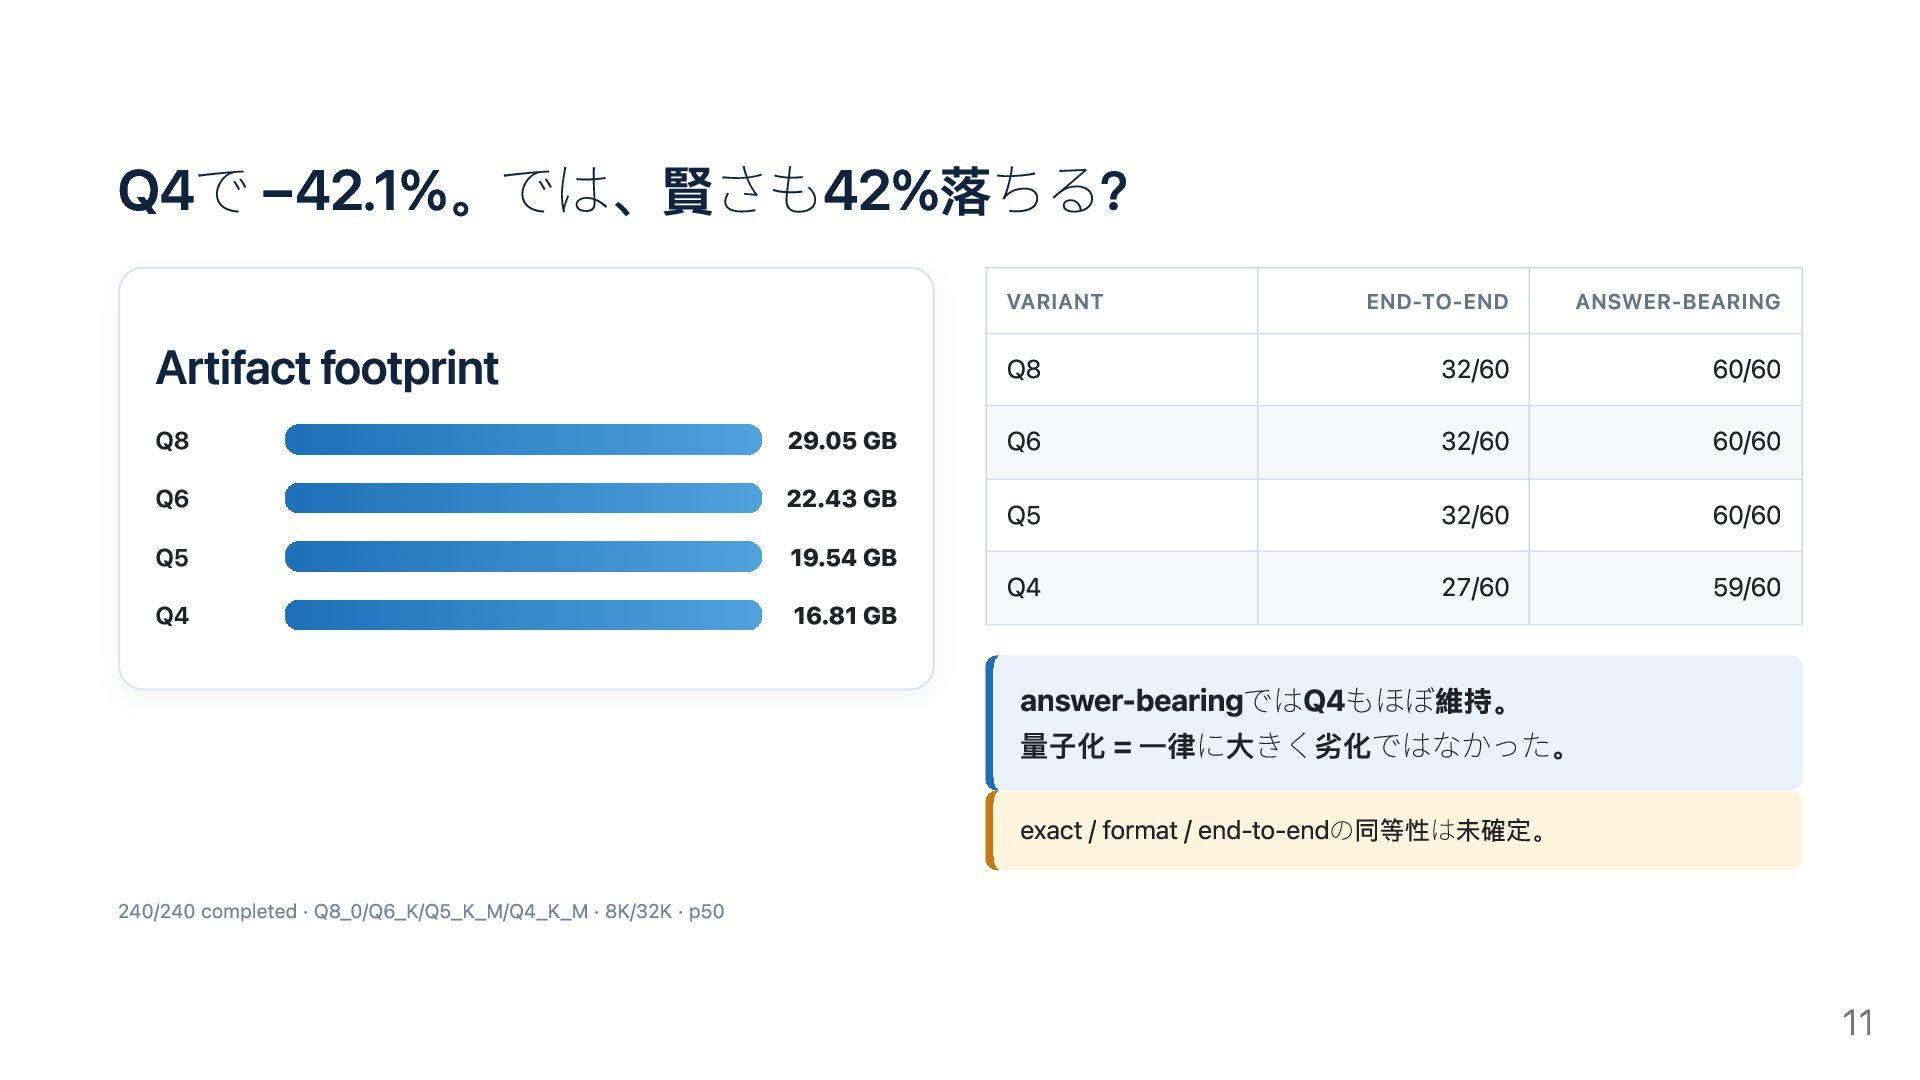
Q4で −42.1%。では、賢さも42%落ちる? Artifact footprint Q8 Q6 Q5 Q4 VARIANT 29.05
GB 22.43 GB 19.54 GB 16.81 GB Q8 Q6 Q5 Q4 END-TO-END ANSWER-BEARING 32/60 32/60 32/60 27/60 60/60 60/60 60/60 59/60 answer-bearingではQ4もほぼ維持。 量子化 = 一律に大きく劣化ではなかった。 exact / format / end-to-endの同等性は未確定。 240/240 completed · Q8_0/Q6_K/Q5_K_M/Q4_K_M · 8K/32K · p50 11
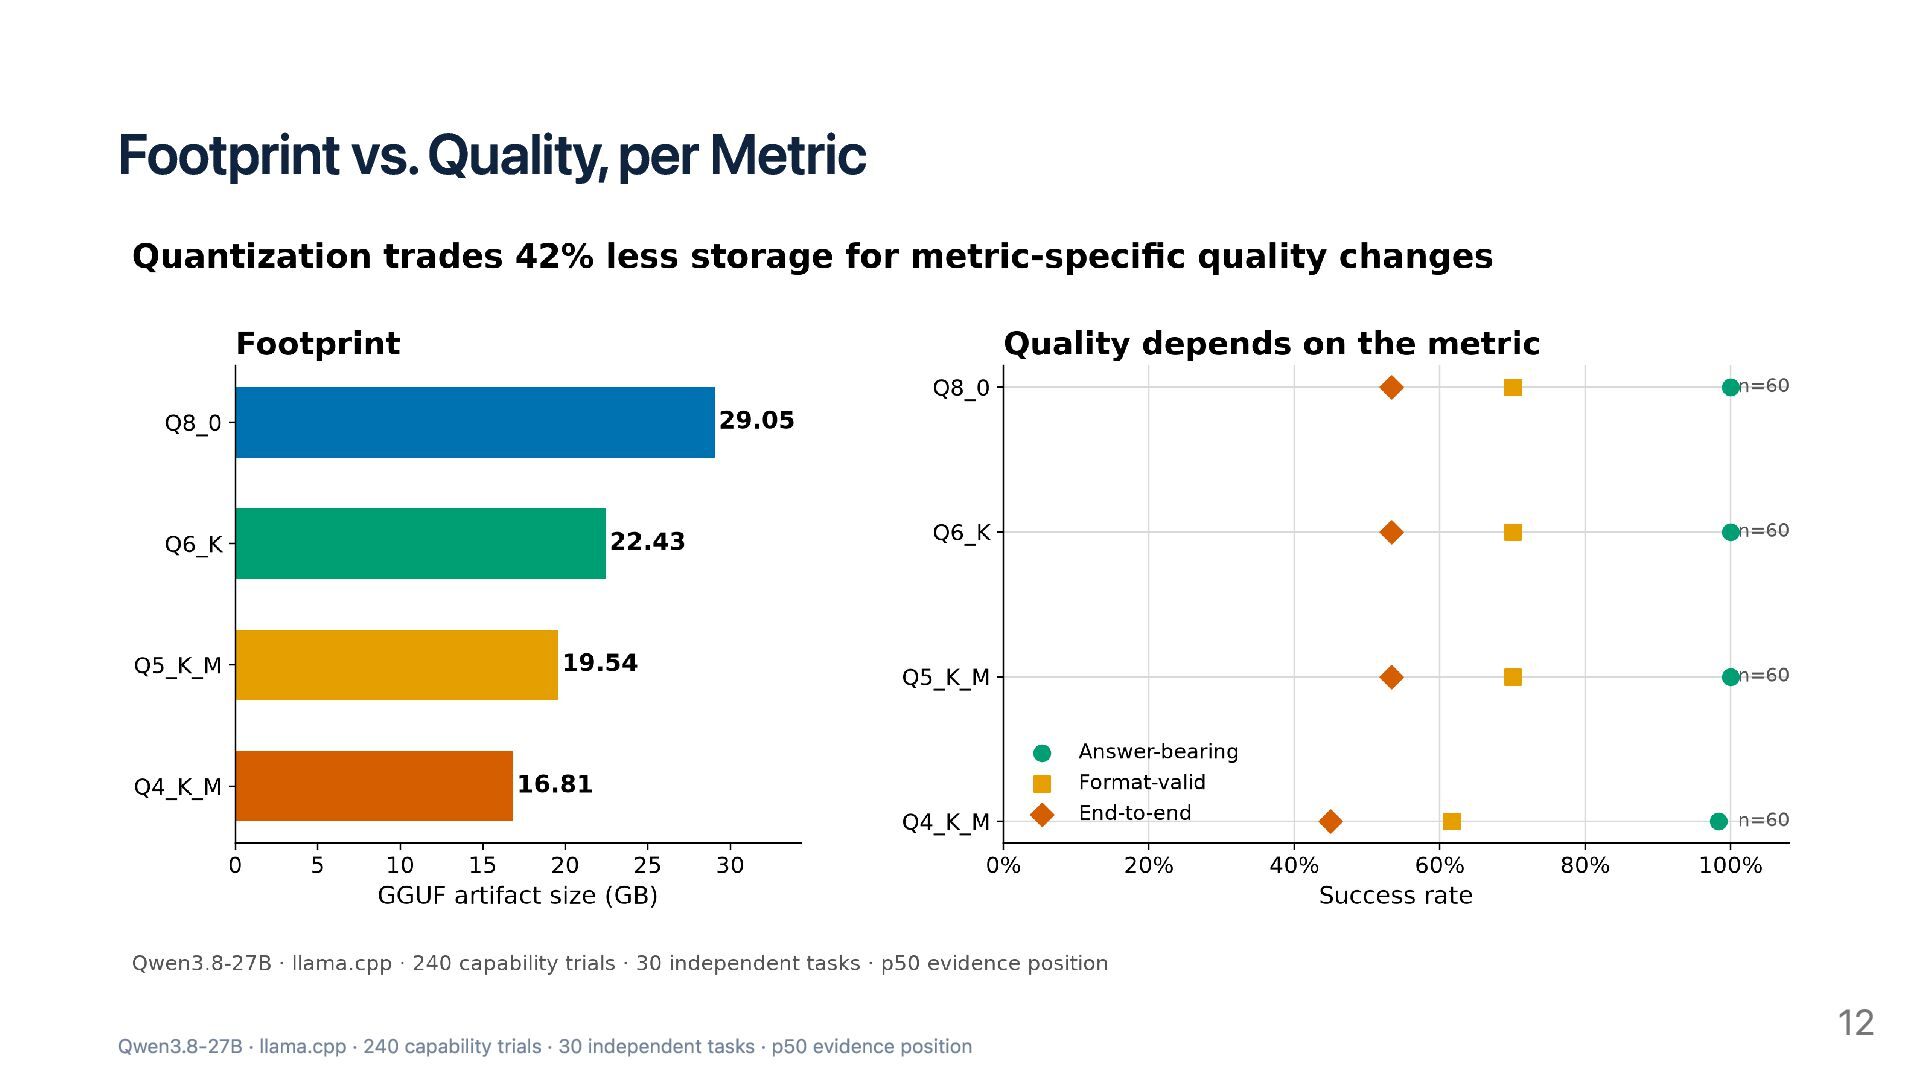
Footprint vs. Quality, per Metric Qwen3.8-27B · llama.cpp · 240
capability trials · 30 independent tasks · p50 evidence position 12
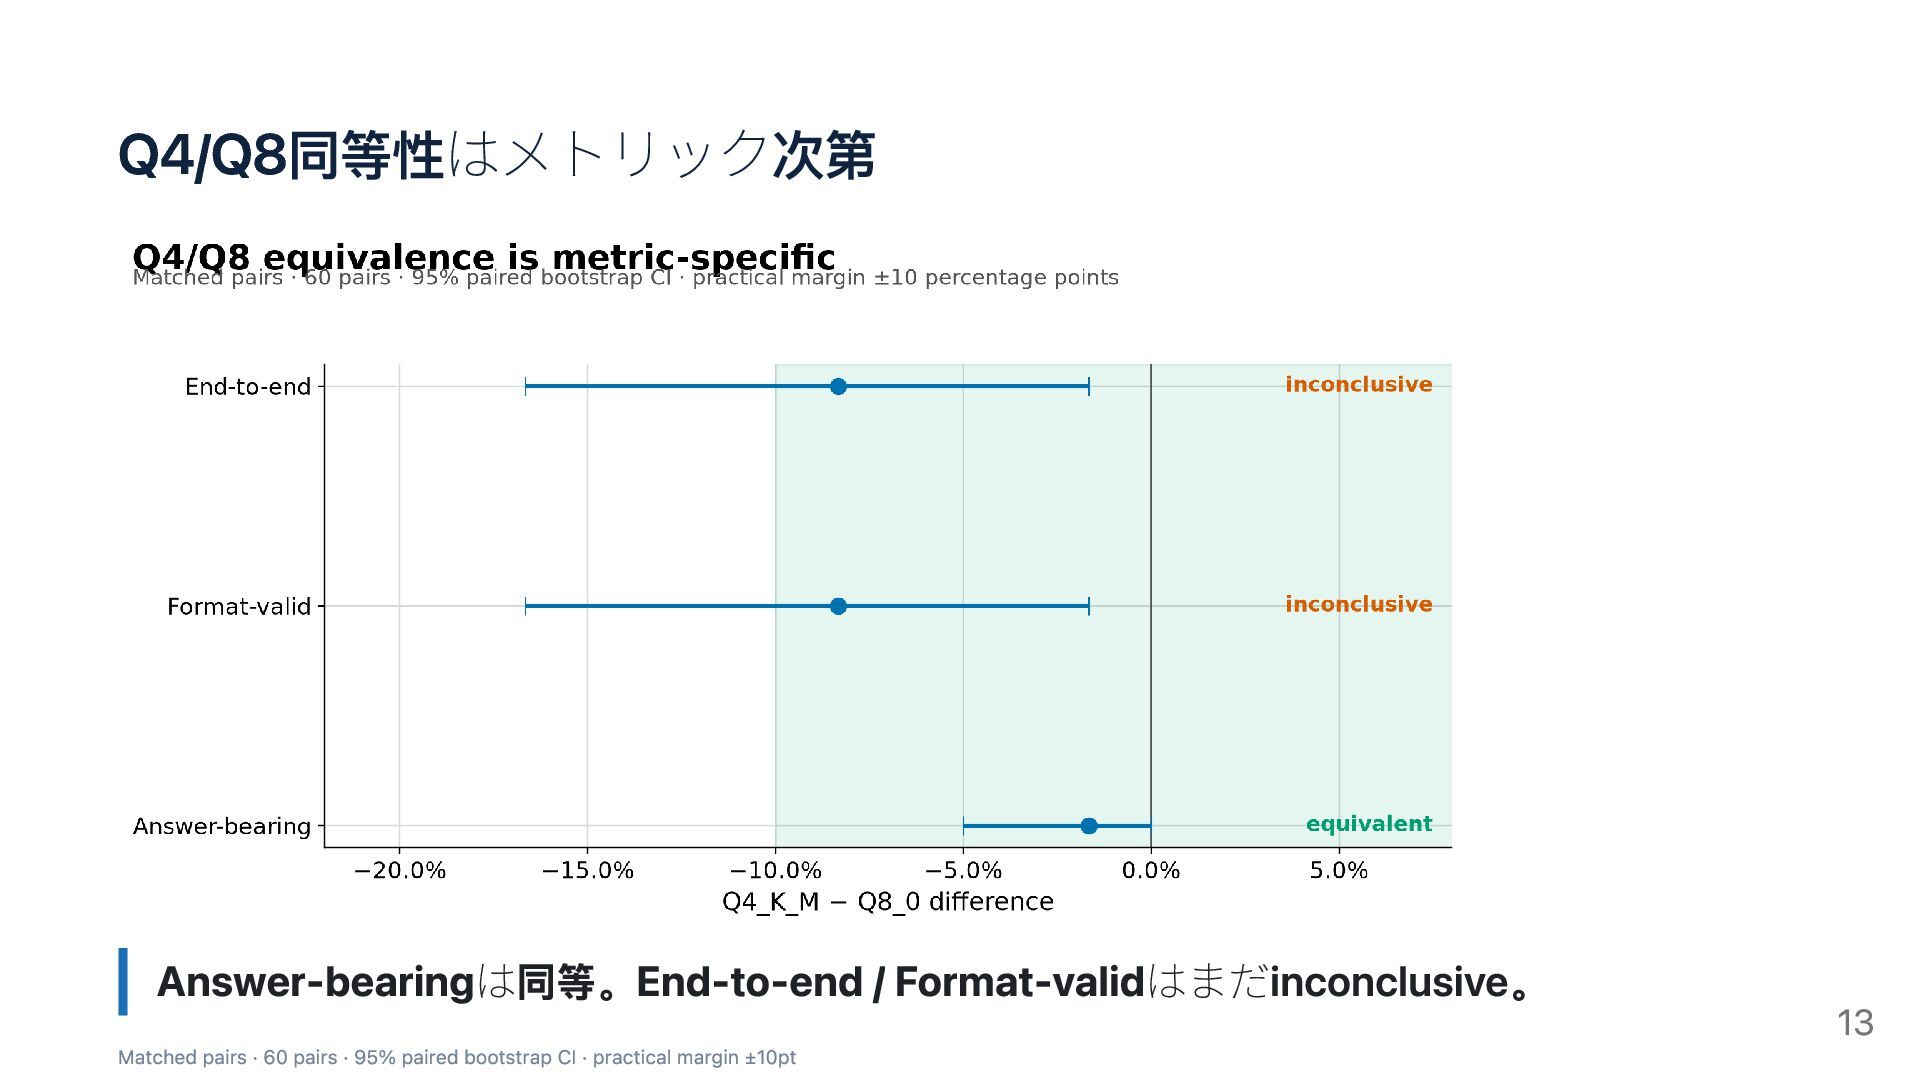
Q4/Q8同等性はメトリック次第 Answer-bearingは同等。End-to-end / Format-validはまだinconclusive。 Matched pairs · 60 pairs ·
95% paired bootstrap CI · practical margin ±10pt 13
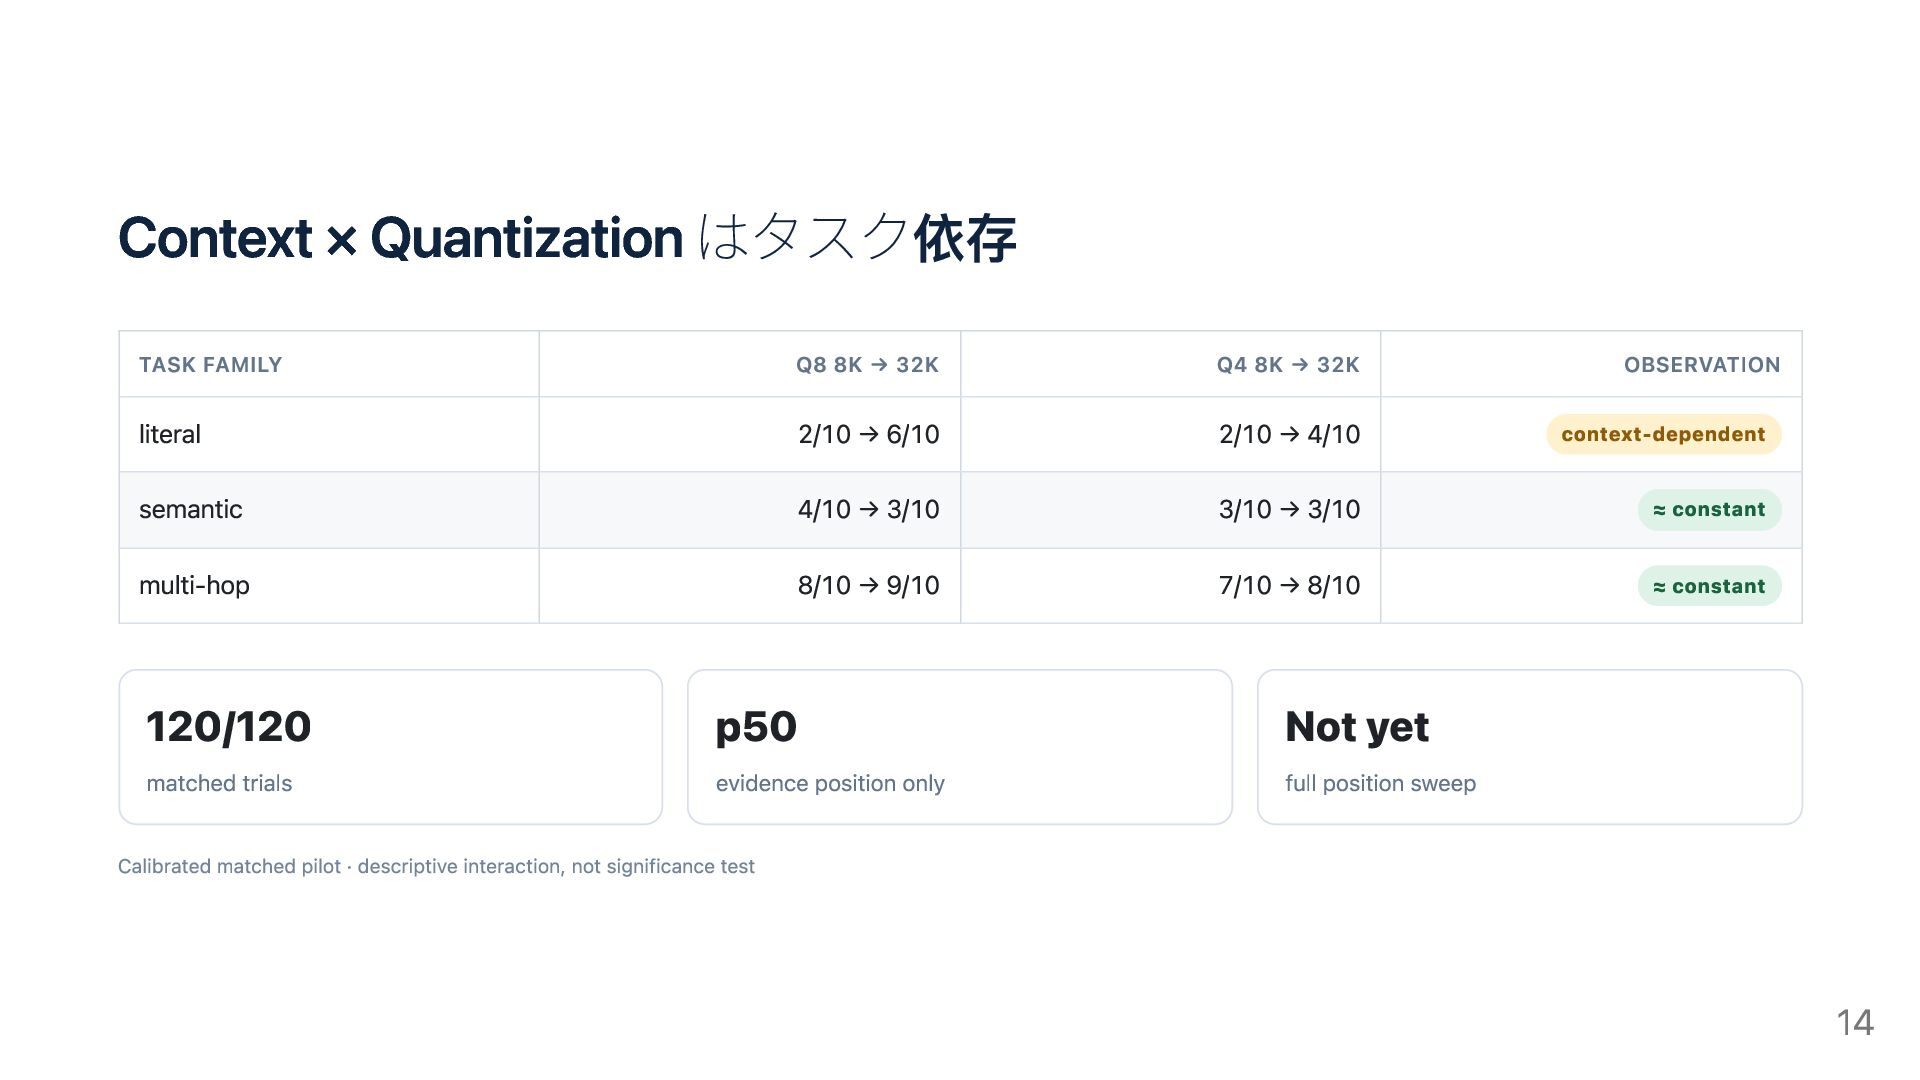
Context × Quantization はタスク依存 TASK FAMILY Q8 8K → 32K
Q4 8K → 32K OBSERVATION literal semantic multi-hop 2/10 → 6/10 4/10 → 3/10 8/10 → 9/10 2/10 → 4/10 3/10 → 3/10 7/10 → 8/10 context-dependent 120/120 matched trials p50 evidence position only ≈ constant ≈ constant Not yet full position sweep Calibrated matched pilot · descriptive interaction, not significance test 14
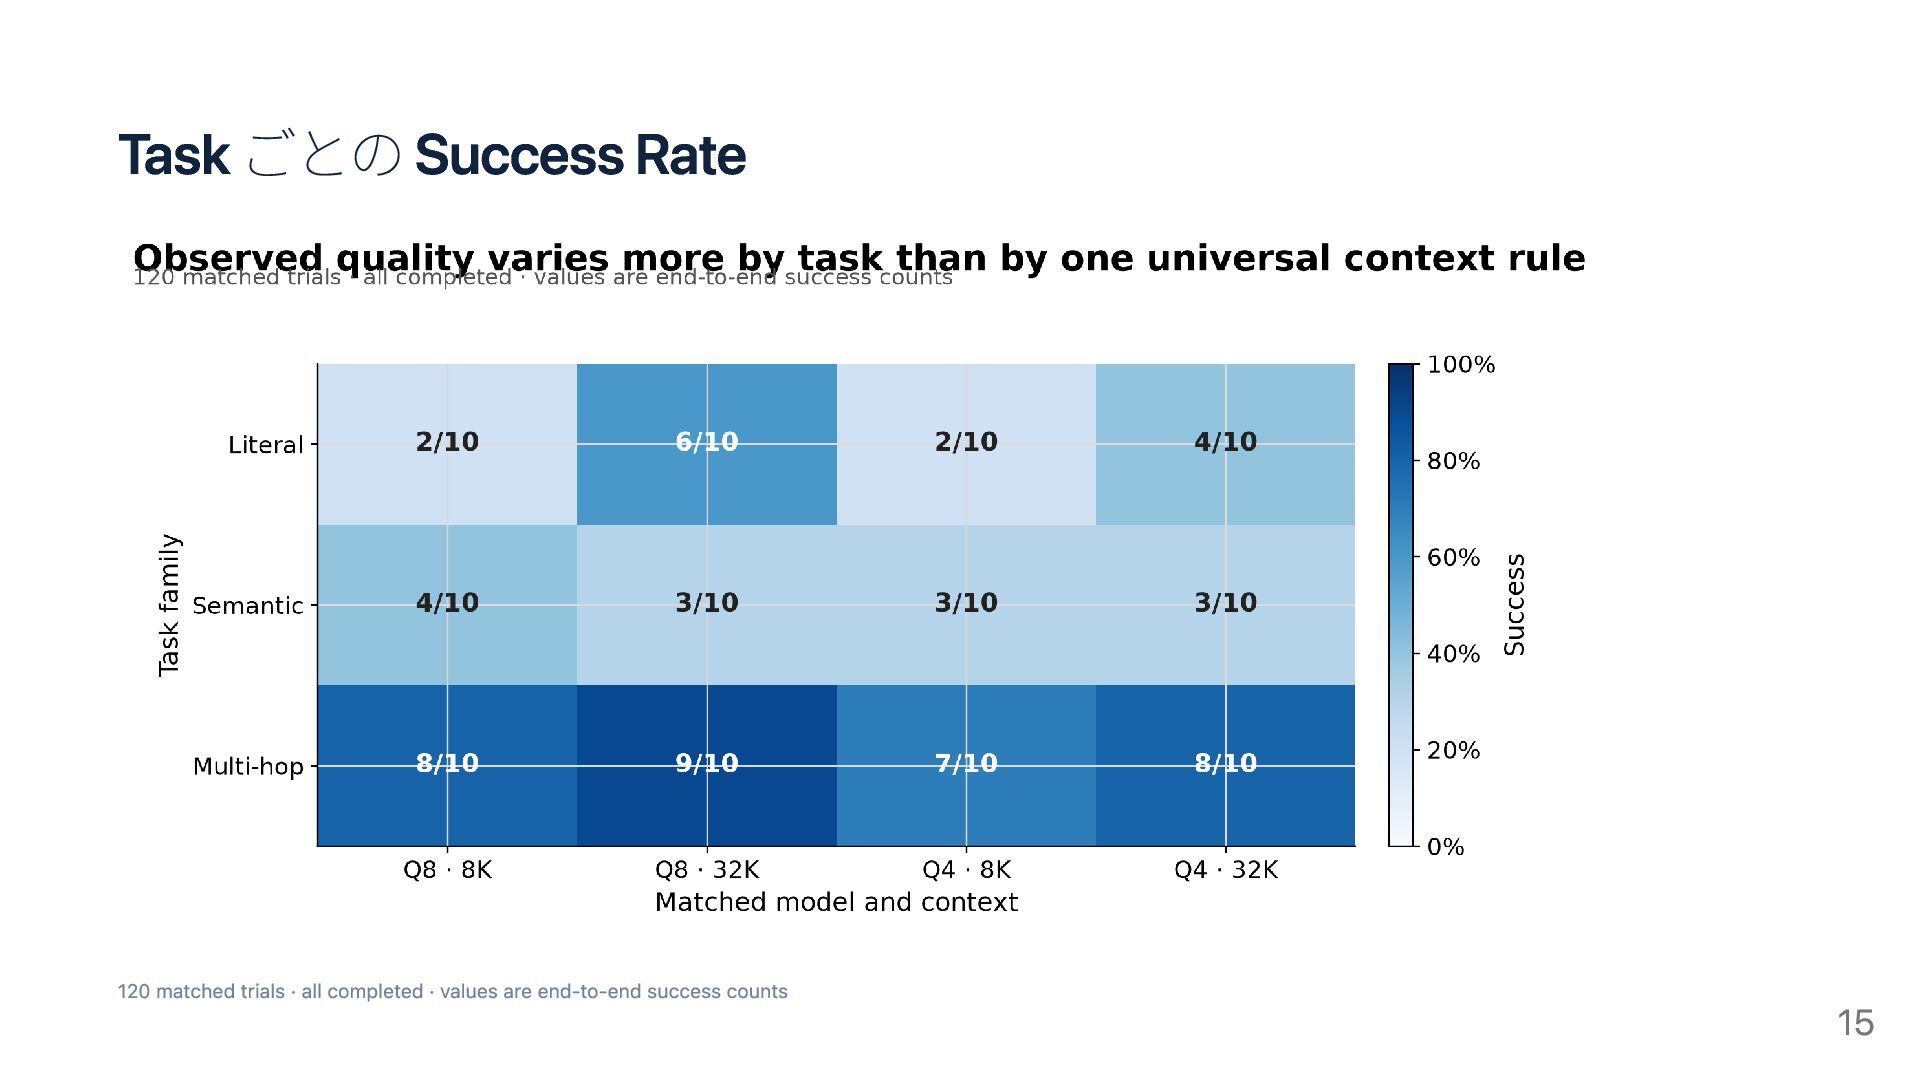
Task ごとの Success Rate 120 matched trials · all completed
· values are end-to-end success counts 15
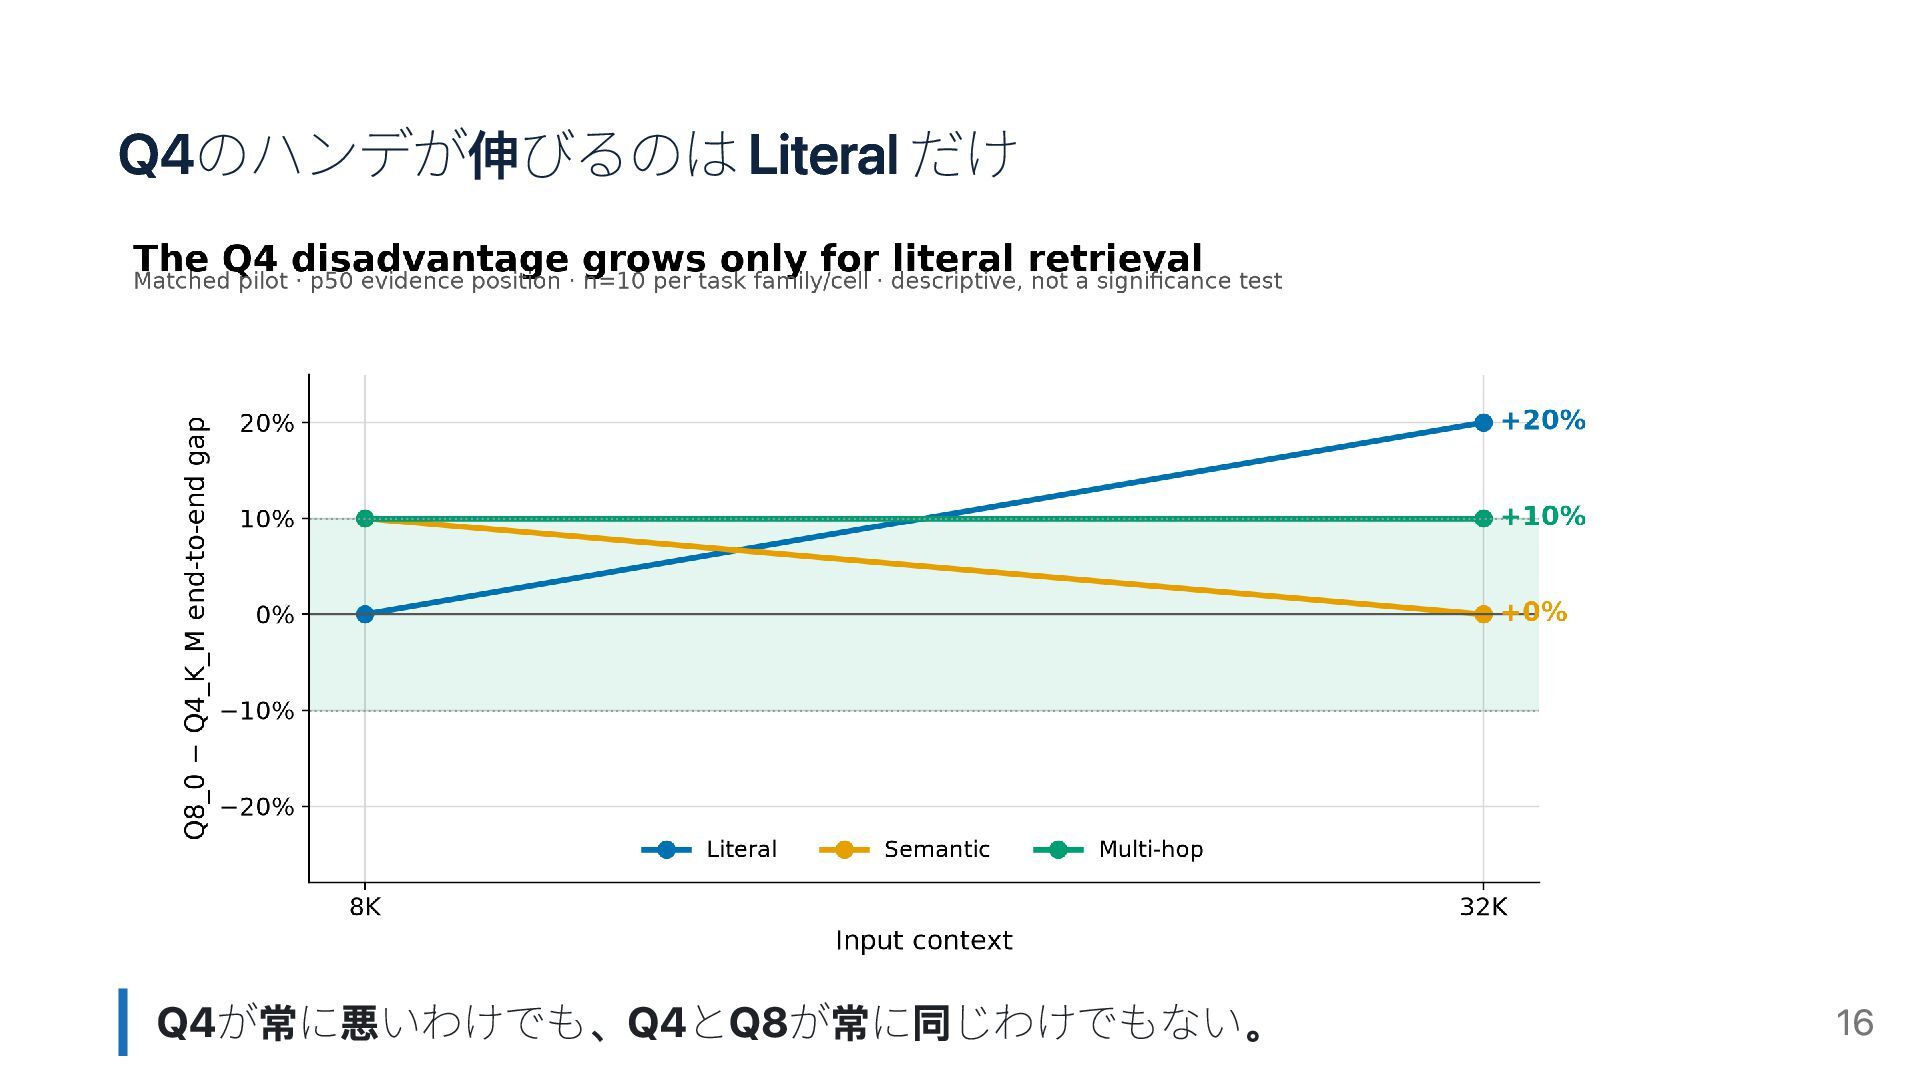
Q4のハンデが伸びるのは Literal だけ Q4が常に悪いわけでも、Q4とQ8が常に同じわけでもない。 16
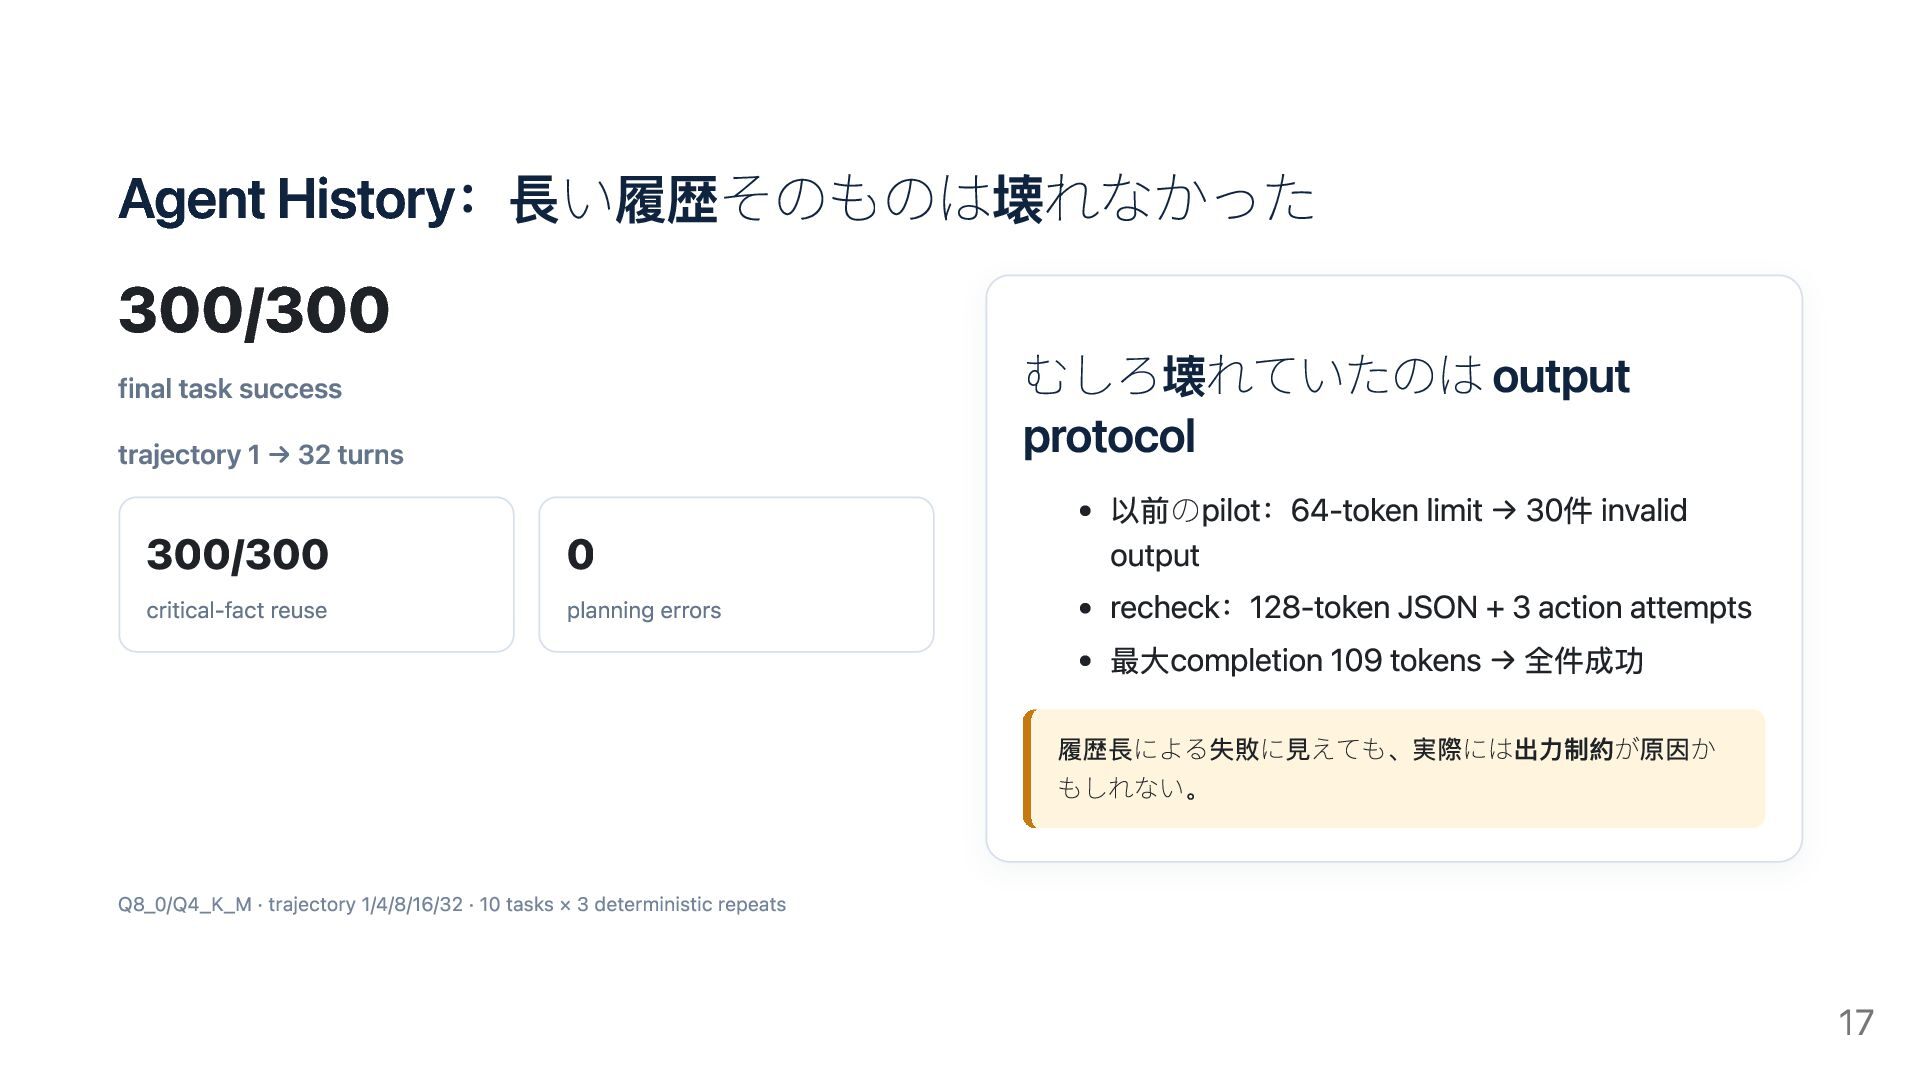
Agent History:長い履歴そのものは壊れなかった 300/300 むしろ壊れていたのは output protocol final task success trajectory
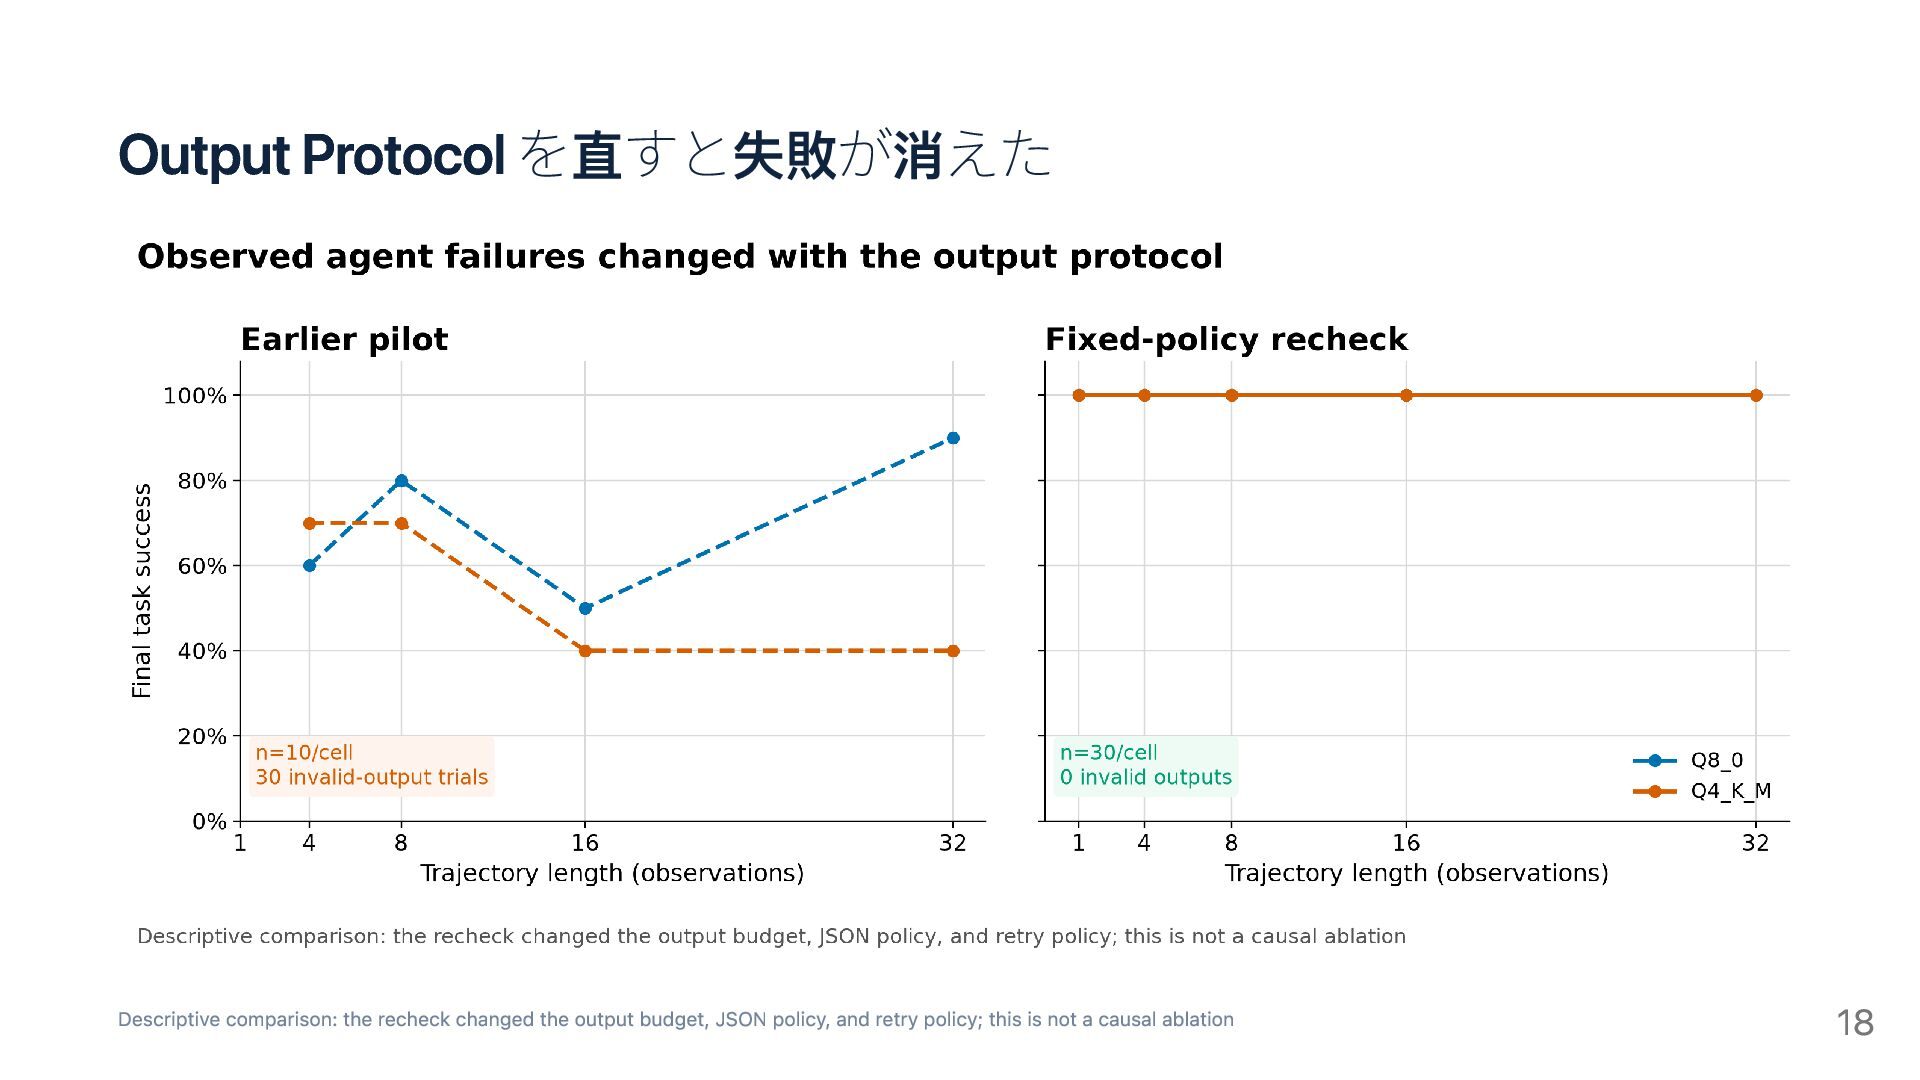
1 → 32 turns 300/300 critical-fact reuse 0 planning errors 以前のpilot:64-token limit → 30件 invalid output recheck:128-token JSON + 3 action attempts 最大completion 109 tokens → 全件成功 履歴長による失敗に見えても、実際には出力制約が原因か もしれない。 Q8_0/Q4_K_M · trajectory 1/4/8/16/32 · 10 tasks × 3 deterministic repeats 17
Output Protocol を直すと失敗が消えた Descriptive comparison: the recheck changed the output
budget, JSON policy, and retry policy; this is not a causal ablation 18
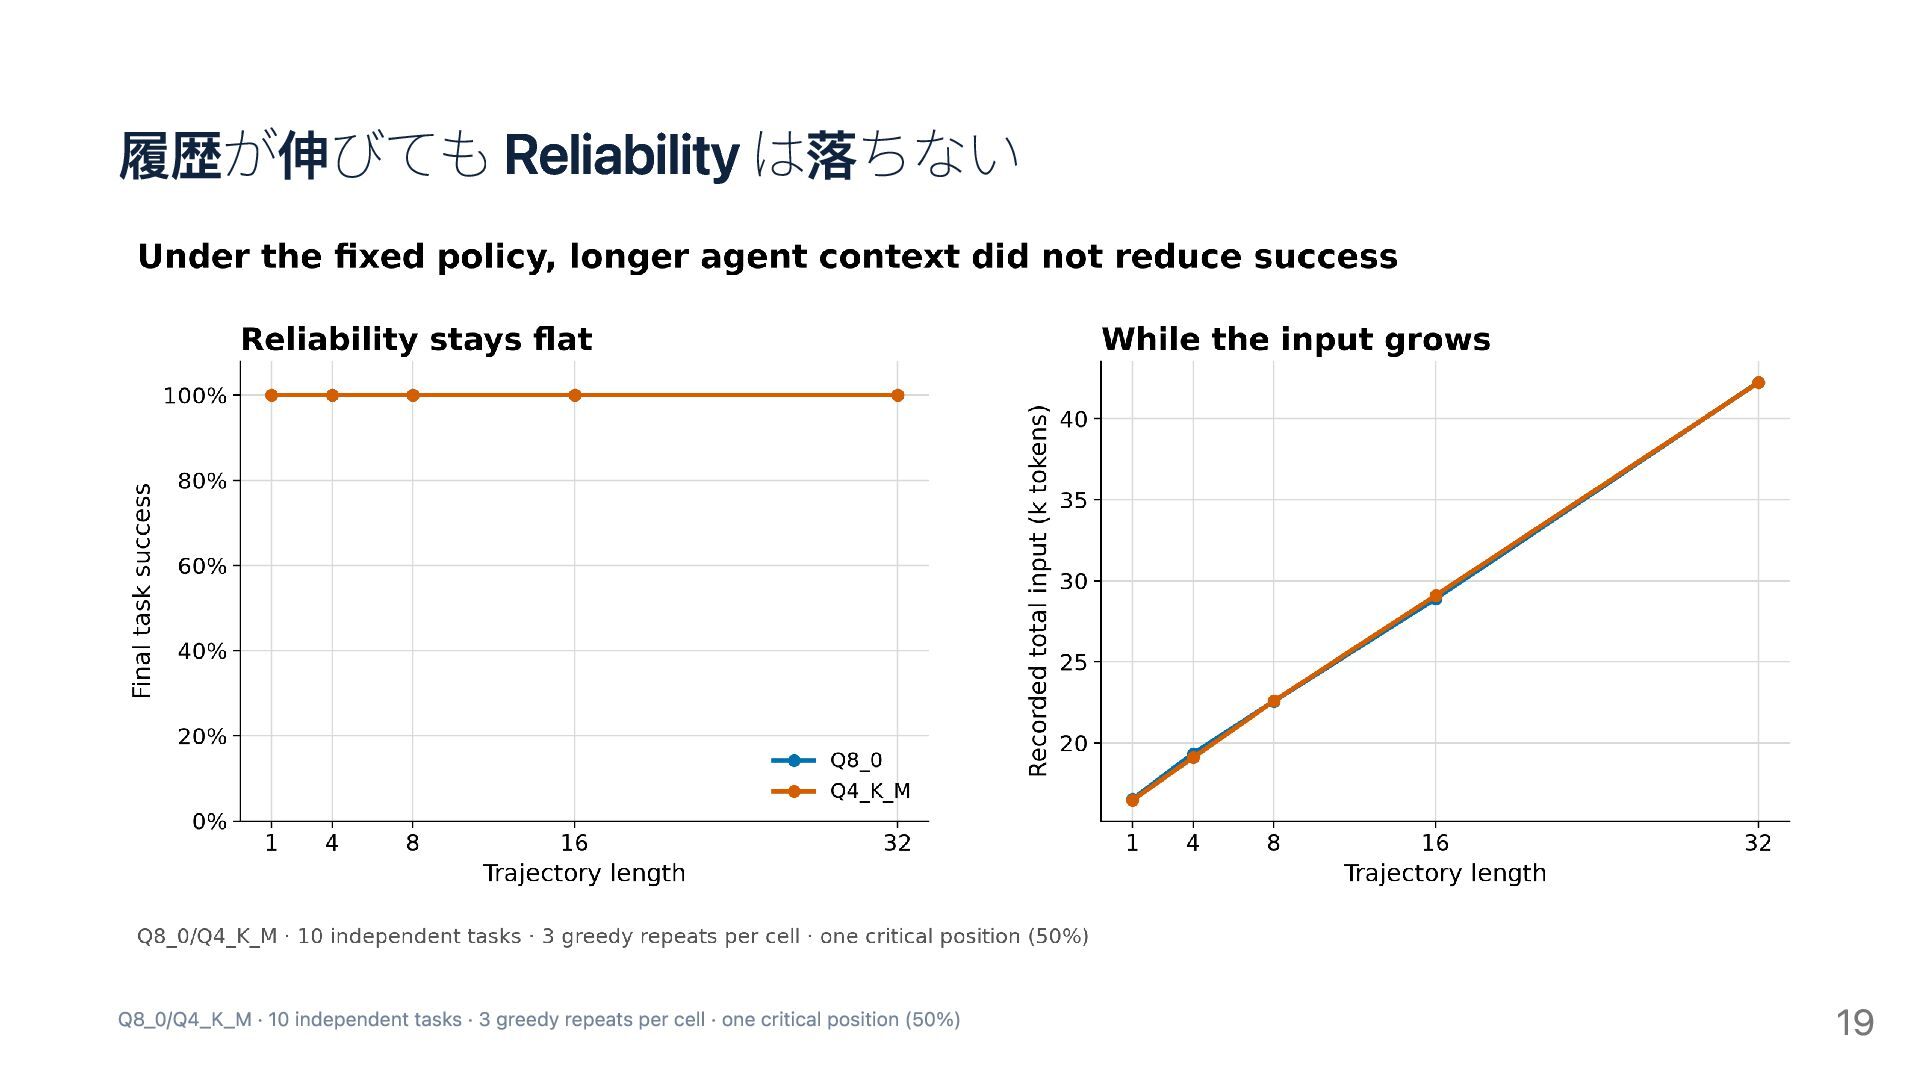
履歴が伸びても Reliability は落ちない Q8_0/Q4_K_M · 10 independent tasks · 3
greedy repeats per cell · one critical position (50%) 19
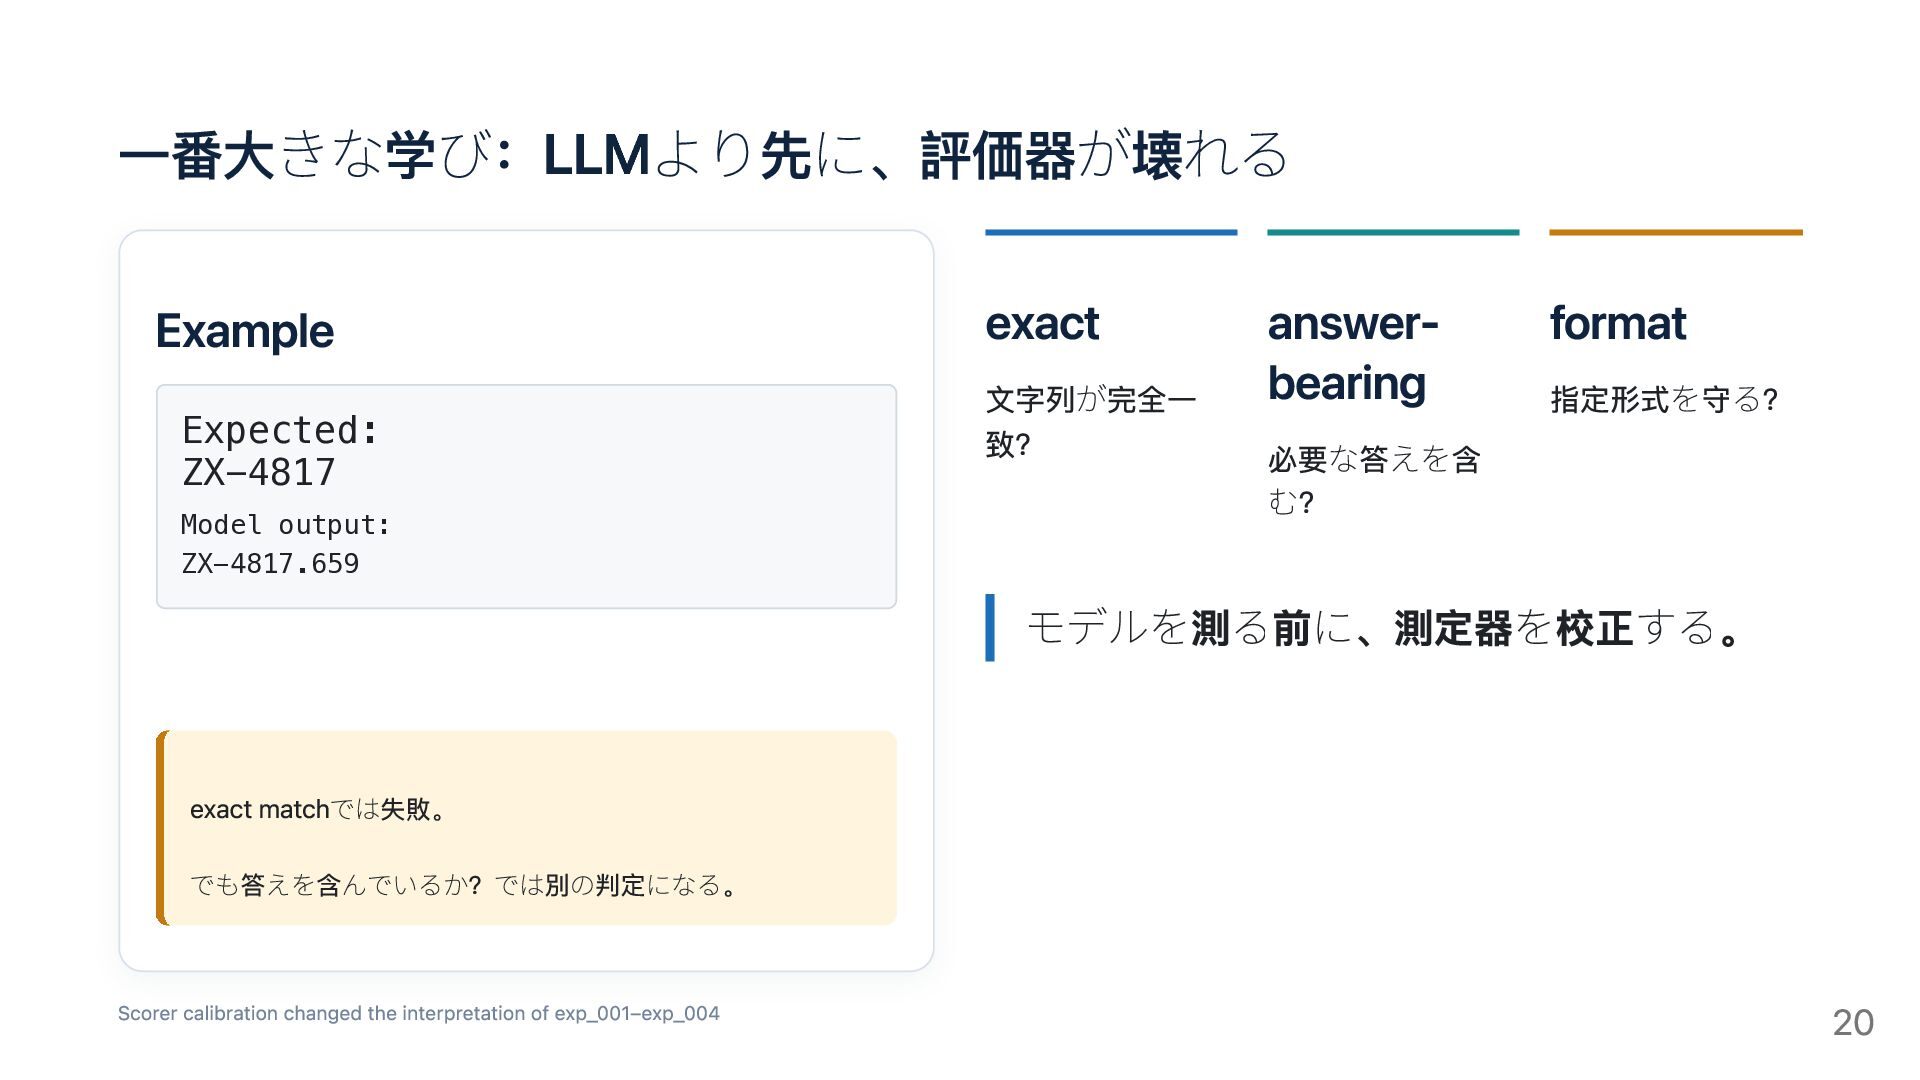
一番大きな学び:LLMより先に、評価器が壊れる Example Expected: ZX-4817 Model output: ZX-4817.659 exact 文字列が完全一 致?
answerbearing 必要な答えを含 む? format 指定形式を守る? モデルを測る前に、測定器を校正する。 exact matchでは失敗。 でも答えを含んでいるか?では別の判定になる。 Scorer calibration changed the interpretation of exp_001–exp_004 20
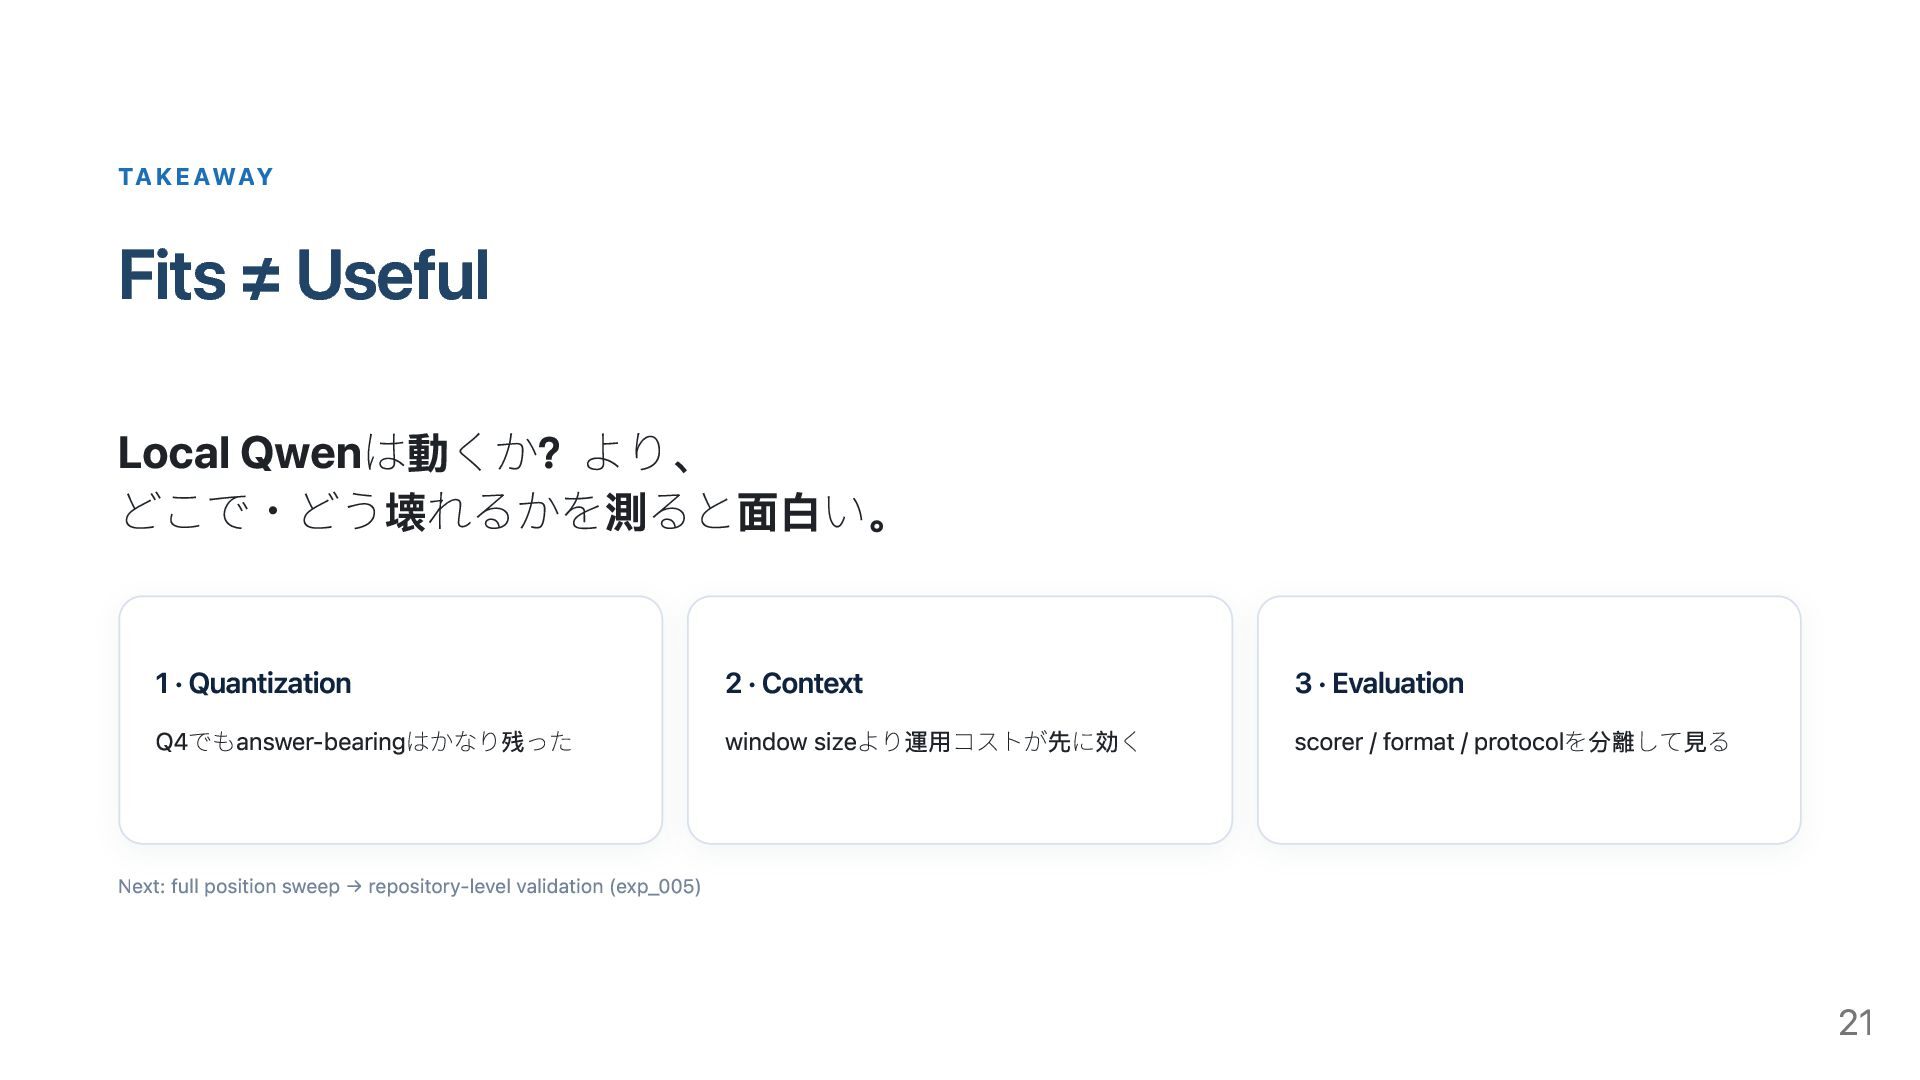
TAKEAWAY Fits ≠ Useful Local Qwenは動くか?より、 どこで・どう壊れるかを測ると面白い。 1 · Quantization
Q4でもanswer-bearingはかなり残った 2 · Context window sizeより運用コストが先に効く 3 · Evaluation scorer / format / protocolを分離して見る Next: full position sweep → repository-level validation (exp_005) 21
22
宣伝 23


 morshoto
 bitkey
 sh_fk2
 nealle
 shisyu_gaku
 taka_aki
 kentarofujii
 minorun365
 stomk
 colopl
 takahashim
 gionn
 gree_tech
 irinanazarova
 paigeccino
 jnunemaker
 madoxten
 eileencodes
 nikkihalliwell
 dougneiner
 wjessup
 csswizardry
 kevinliebholz
 andyhume
 aleyda