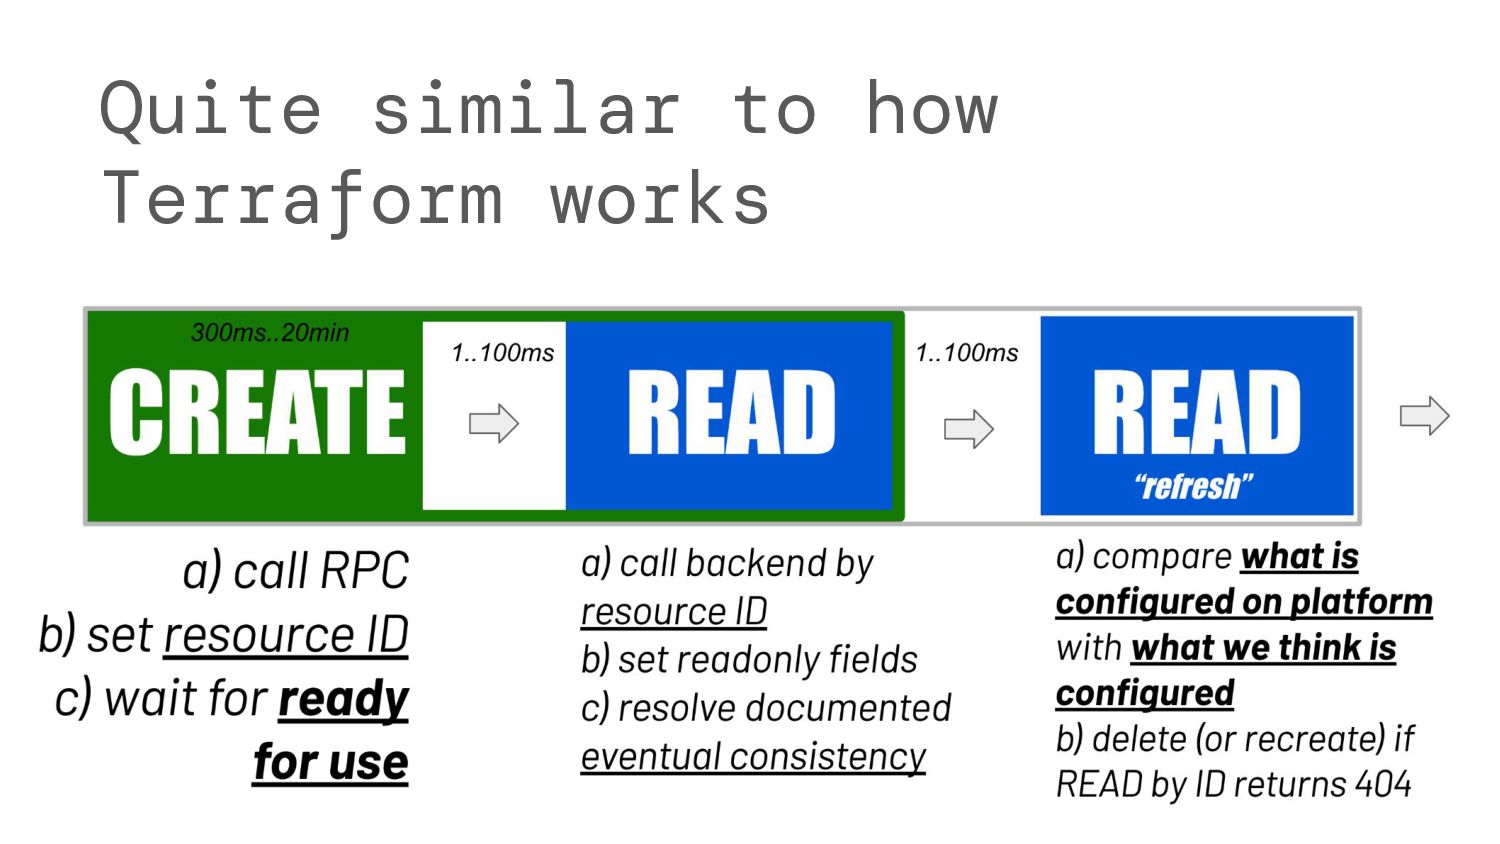
Building robust Python applications on top of D...
Sponsored
·
 Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→

Share
Embed
Building robust Python applications on top of Databricks: UCX case study

Serge Smertin
June 12, 2024
Transcript
66 slides
-
©2024 Databricks Inc. — All rights reserved 1 Robust Python
apps on Databricks: UCX case study Serge Smertin -
©2024 Databricks Inc. — All rights reserved 2 WHAT PROBLEMS
DID WE HIT, SO YOU DON’T HAVE TO. -
This information is provided to outline Databricks’ general product direction
and is for informational purposes only. Customers who purchase Databricks services should make their purchase decisions relying solely upon services, features, and functions that are currently available. Unreleased features or functionality described in forward-looking statements are subject to change at Databricks discretion and may not be delivered as planned or at all Product safe harbor statement -
©2024 Databricks Inc. — All rights reserved ©2022 Databricks Inc.
— All rights reserved 4 About Serge ▪ Using Apache Spark since ~2015 ▪ At Databricks since 2019 ▪ Created Databricks Terraform Provider ▪ Author of Databricks SDKs ▪ Driving Databricks Labs ▪ Years in cybersecurity and payments before that -
©2024 Databricks Inc. — All rights reserved - OVERVIEW -
GROUP MIGRATION - TABLE MIGRATION - CODE MIGRATION -
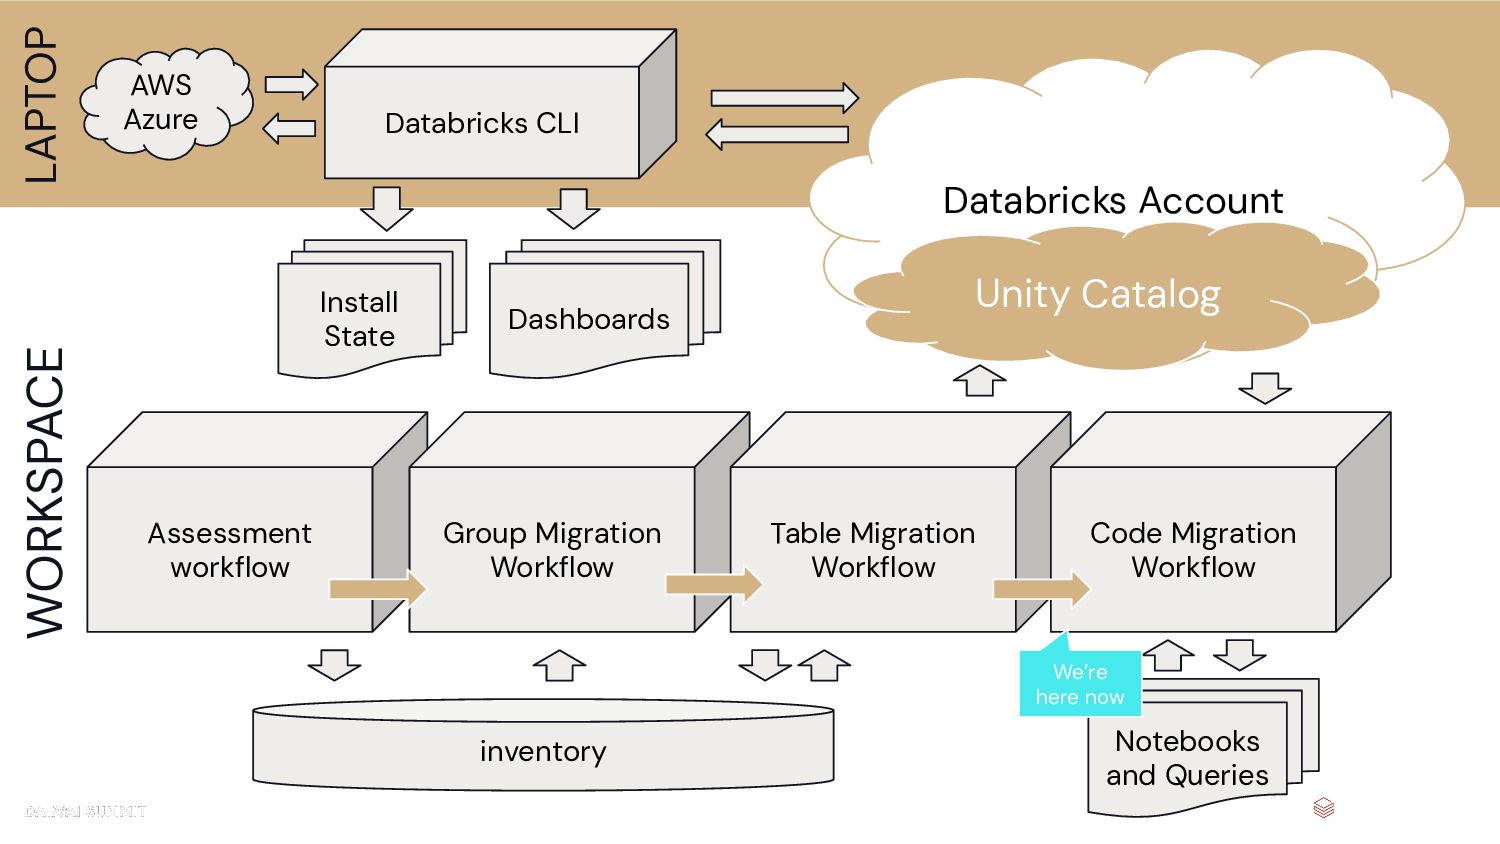
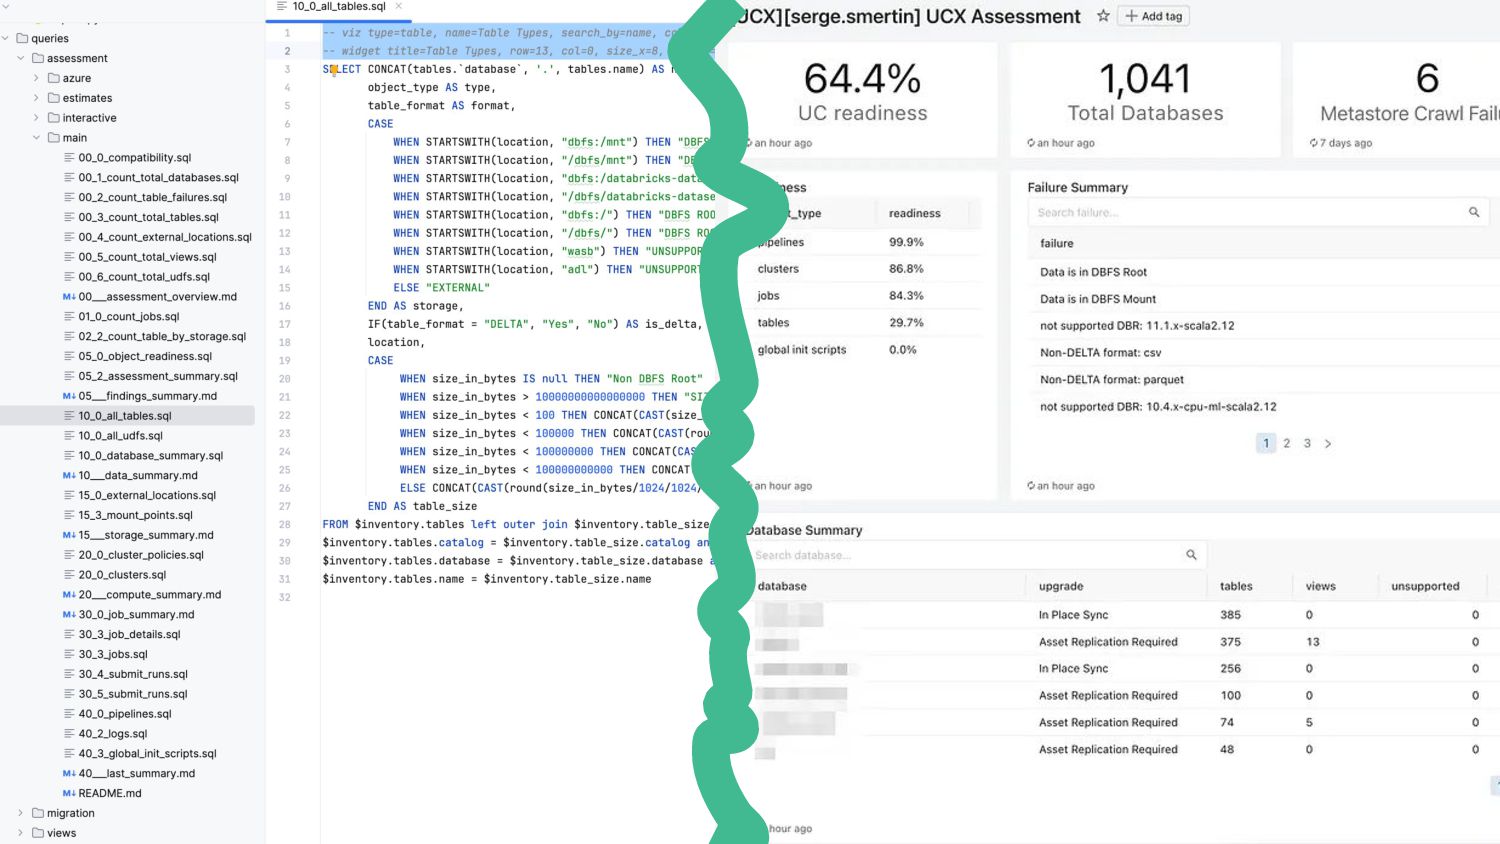
©2024 Databricks Inc. — All rights reserved inventory Assessment workflow
Group Migration Workflow Table Migration Workflow Code Migration Workflow Databricks CLI AWS Azure Install State Dashboards Notebooks and Queries Databricks Account Unity Catalog WORKSPACE LAPTOP We’re here now -
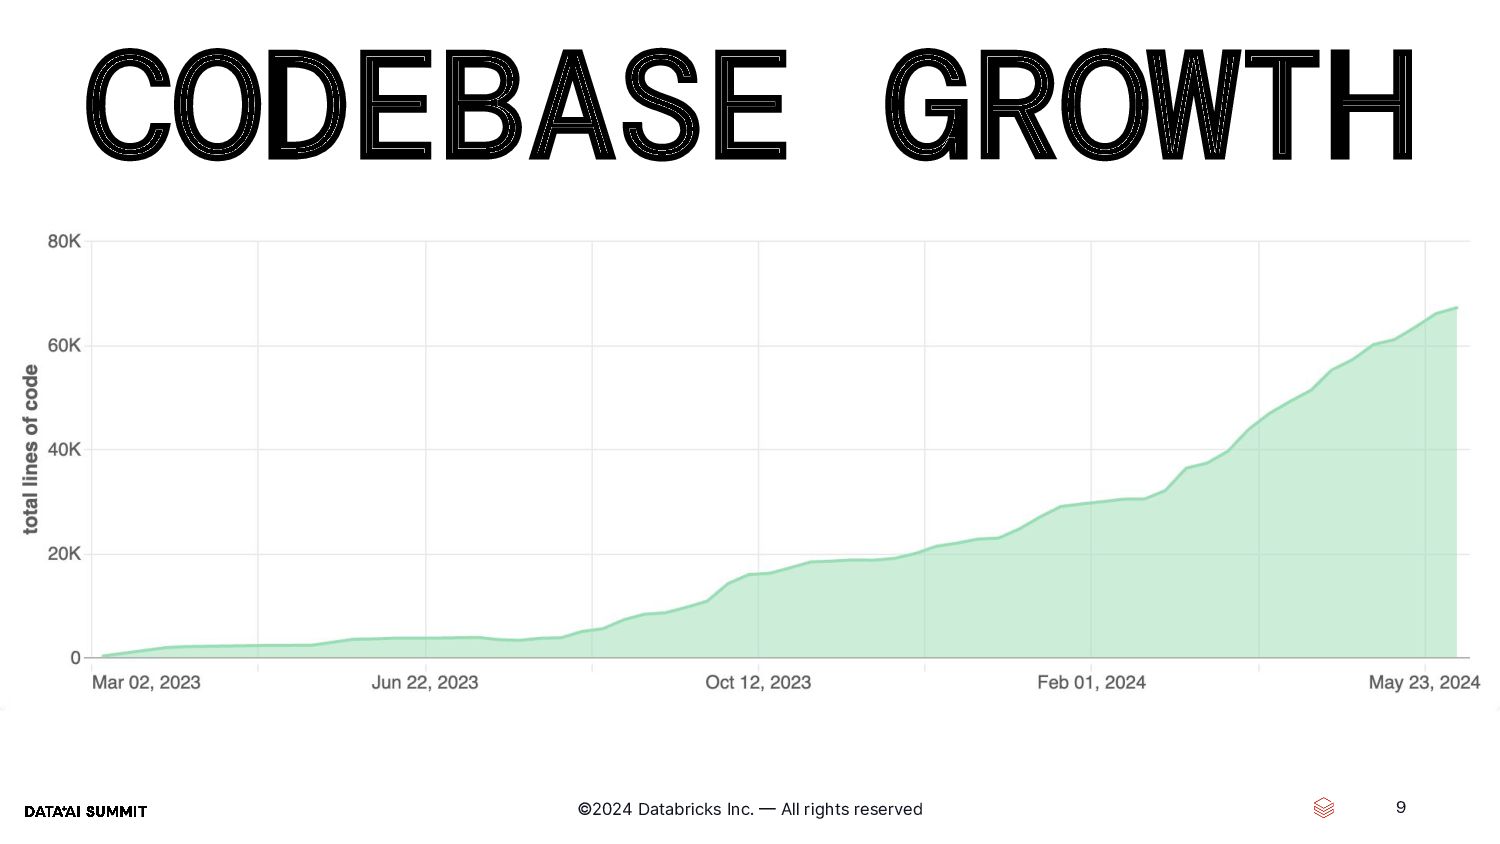
©2024 Databricks Inc. — All rights reserved ©2024 Databricks Inc.
— All rights reserved 9 CODEBASE GROWTH -
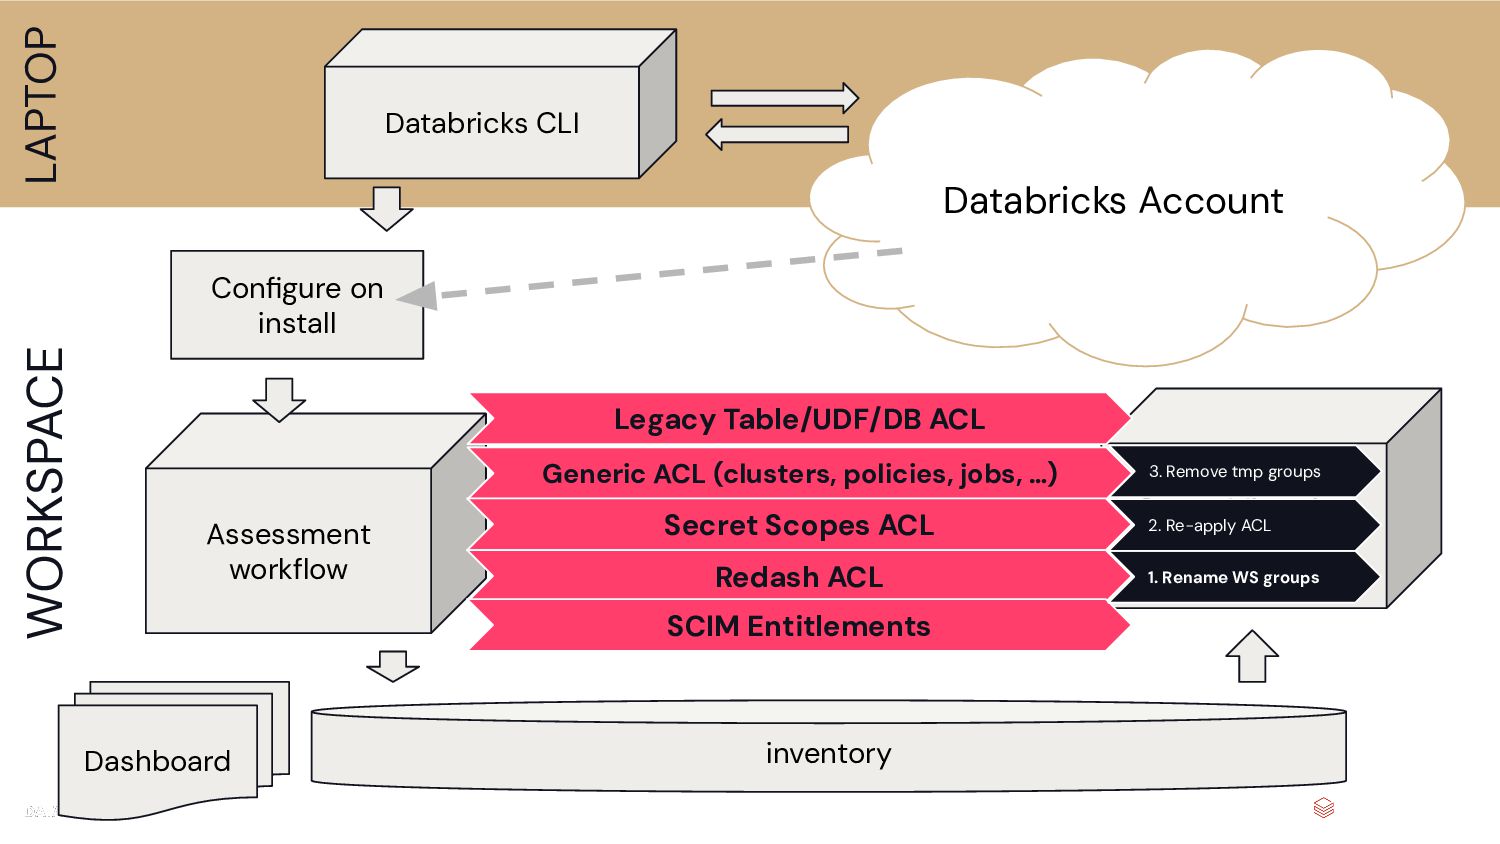
©2024 Databricks Inc. — All rights reserved inventory Assessment workflow
Group Migration Workflow Databricks CLI Dashboard Databricks Account WORKSPACE LAPTOP Configure on install Generic ACL (clusters, policies, jobs, …) Legacy Table/UDF/DB ACL Secret Scopes ACL Redash ACL SCIM Entitlements 1. Rename WS groups 2. Re-apply ACL 3. Remove tmp groups -
©2024 Databricks Inc. — All rights reserved ©2024 Databricks Inc.
— All rights reserved 13 CHALLENGES: -CALLING API -LOGGING -ERROR RECOVERY -
©2024 Databricks Inc. — All rights reserved 19 USE DATABRICKS
SDK (FOR PYTHON) TO SAVE MONTHS OF EFFORT. -
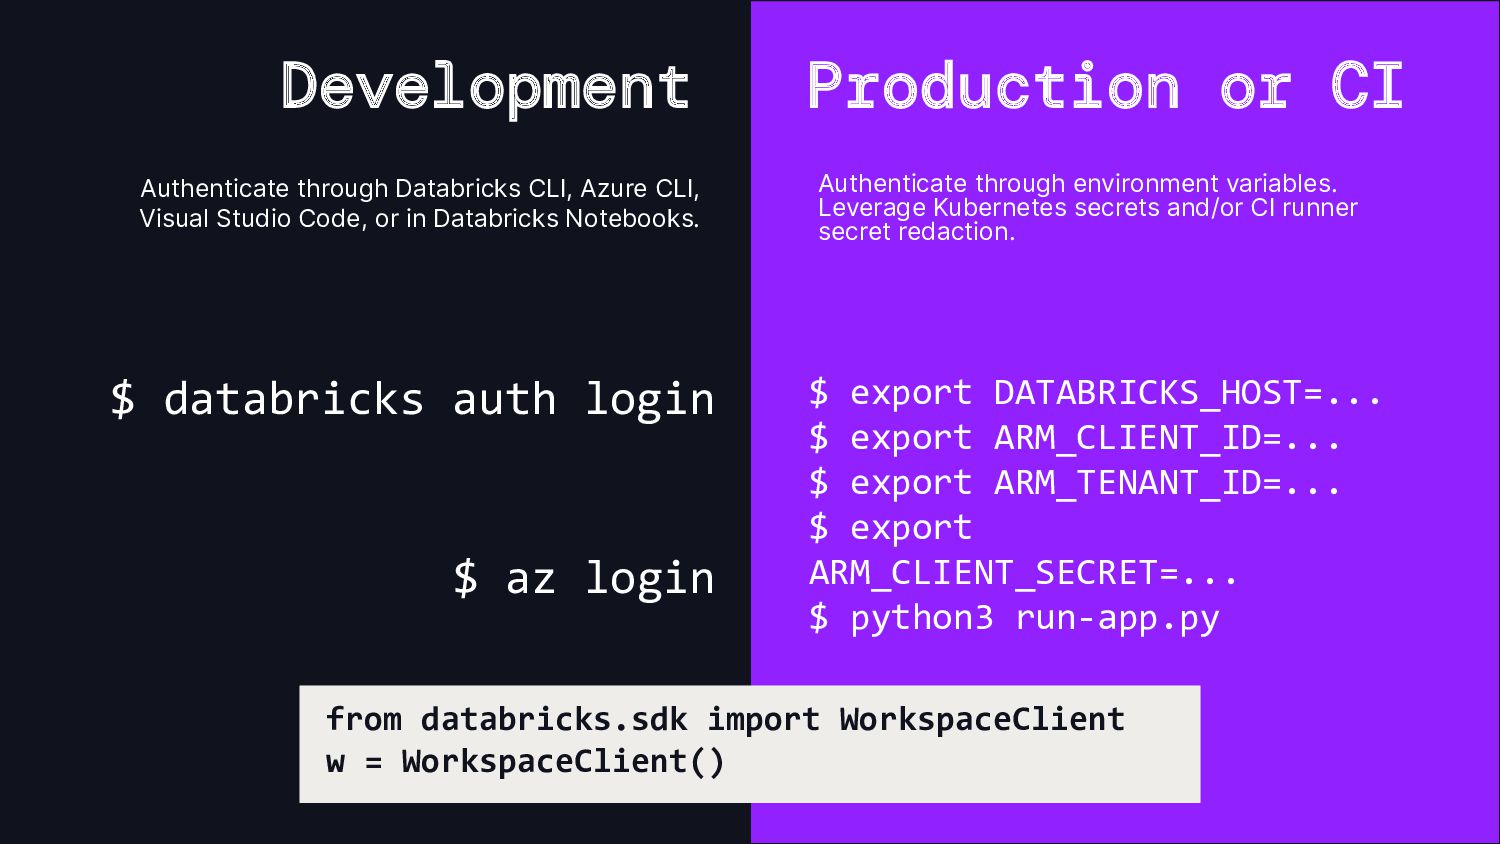
©2024 Databricks Inc. — All rights reserved Development Production or
CI Authenticate through environment variables. Leverage Kubernetes secrets and/or CI runner secret redaction. Authenticate through Databricks CLI, Azure CLI, Visual Studio Code, or in Databricks Notebooks. $ az login $ databricks auth login $ export DATABRICKS_HOST=... $ export ARM_CLIENT_ID=... $ export ARM_TENANT_ID=... $ export ARM_CLIENT_SECRET=... $ python3 run-app.py from databricks.sdk import WorkspaceClient w = WorkspaceClient() -
©2024 Databricks Inc. — All rights reserved ©2024 Databricks Inc.
— All rights reserved 21 21 DATABRICKS SDK FOR PYTHON -
©2024 Databricks Inc. — All rights reserved ©2024 Databricks Inc.
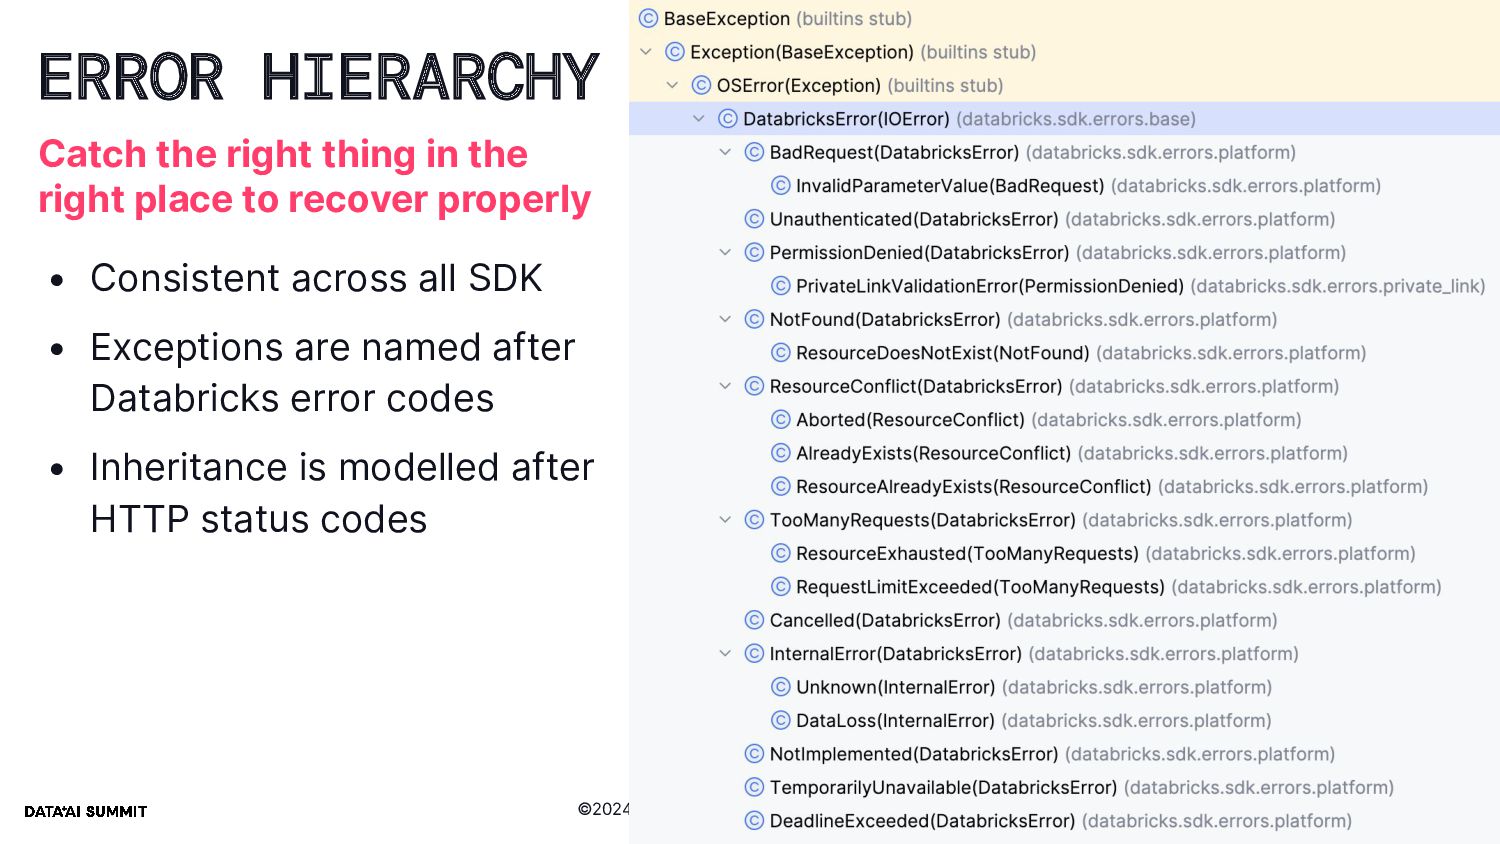
— All rights reserved • Consistent across all SDK • Exceptions are named after Databricks error codes • Inheritance is modelled after HTTP status codes 22 ERROR HIERARCHY Catch the right thing in the right place to recover properly -
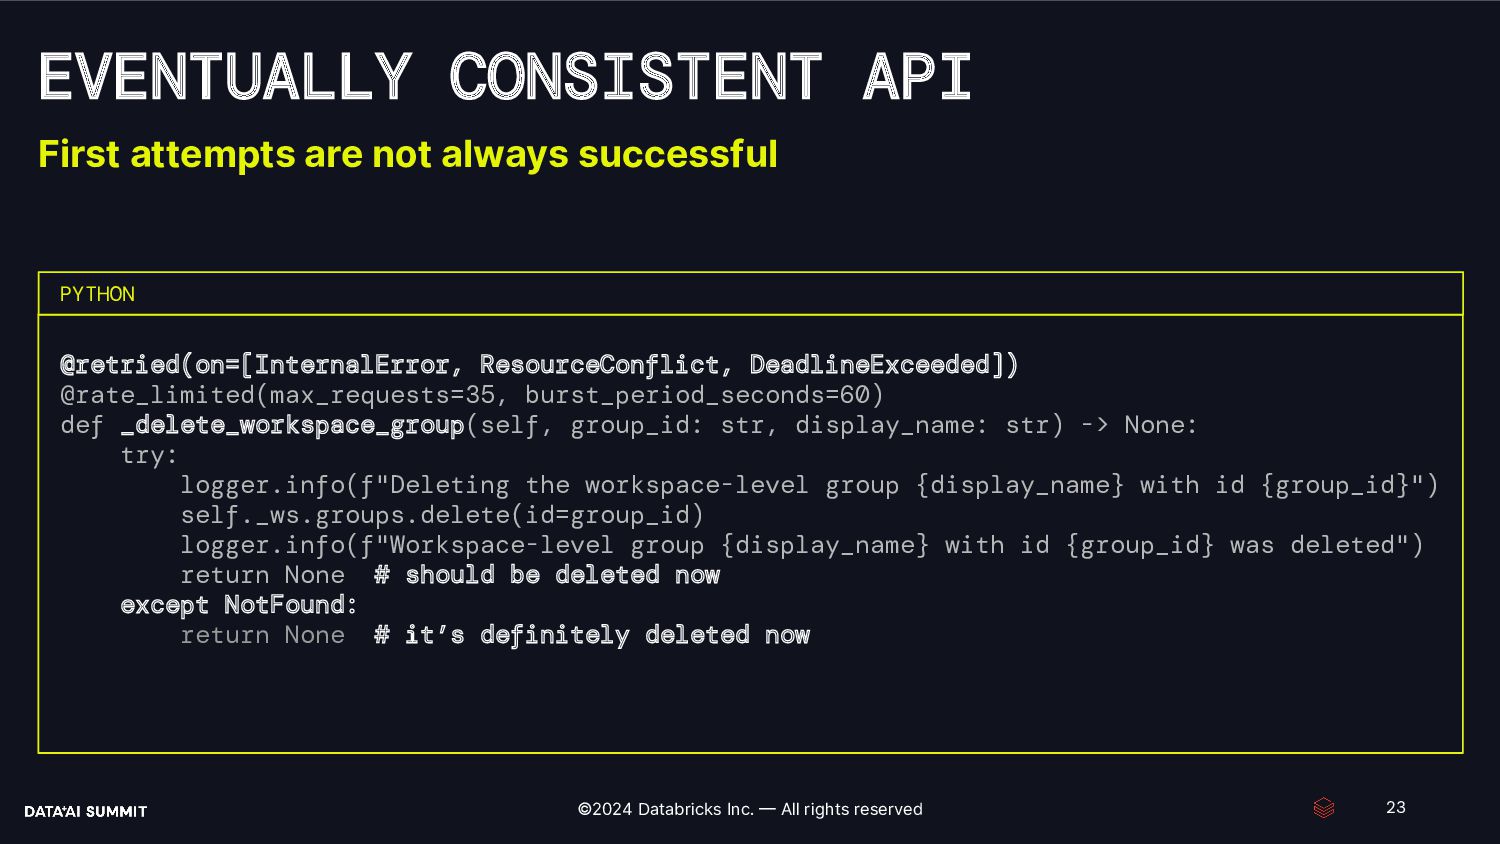
©2024 Databricks Inc. — All rights reserved PYTHON First attempts
are not always successful @retried(on=[InternalError, ResourceConflict, DeadlineExceeded]) @rate_limited(max_requests=35, burst_period_seconds=60) def _delete_workspace_group(self, group_id: str, display_name: str) -> None: try: logger.info(f"Deleting the workspace-level group {display_name} with id {group_id}") self._ws.groups.delete(id=group_id) logger.info(f"Workspace-level group {display_name} with id {group_id} was deleted") return None # should be deleted now except NotFound: return None # it’s definitely deleted now EVENTUALLY CONSISTENT API 23 -
… robust Python code starts to look like any code
in GoLang, where we explicitly check for error returns for every single method call func (s *computeScanTask) Run( ctx context.Context) ([]alerts.Alert, error) { err := s.scanPools(ctx) if err != nil { return nil, err } allJobs, err := s.allJobs(ctx) if err != nil { return nil, err } err = s.scanClusters(ctx) if err != nil { return nil, err } err = s.scanClusterLibraries(ctx) if err != nil { return nil, err } err = s.scanJobs(ctx, allJobs) if err != nil { return nil, err } err = s.scanJobRuns(ctx) if err != nil { return nil, err } err = s.scanWarehouses(ctx) if err != nil { return nil, err } return s.alerts, nil } -
… most of our time is spent operating applications in
production rather than constructing the code itself -
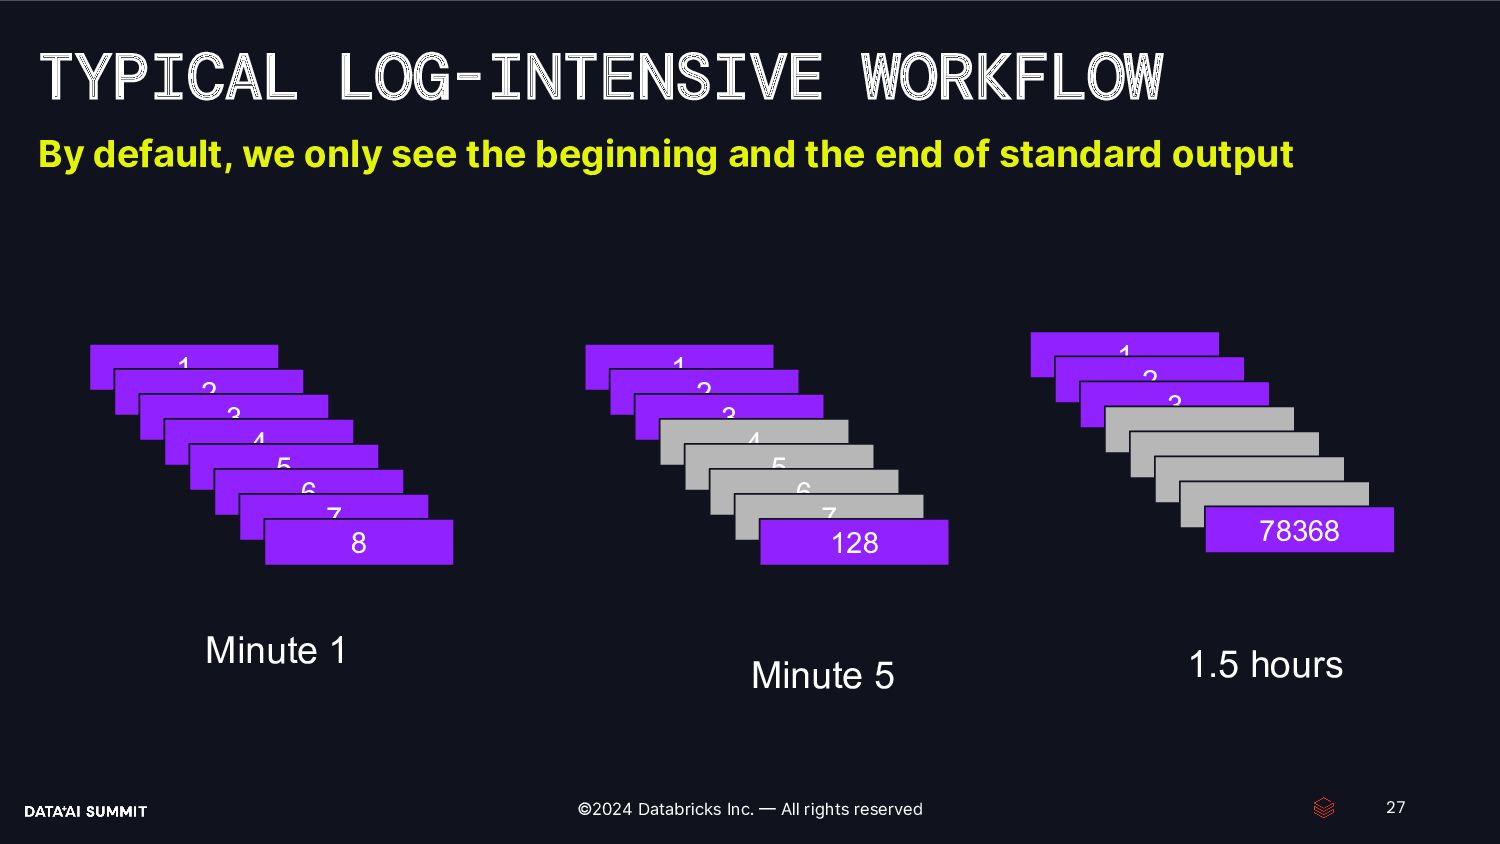
©2024 Databricks Inc. — All rights reserved 27 TYPICAL LOG-INTENSIVE
WORKFLOW By default, we only see the beginning and the end of standard output 1 2 3 4 5 6 7 8 1 2 3 4 5 6 7 128 1 2 3 … . .. .. 78368 Minute 1 1.5 hours Minute 5 -
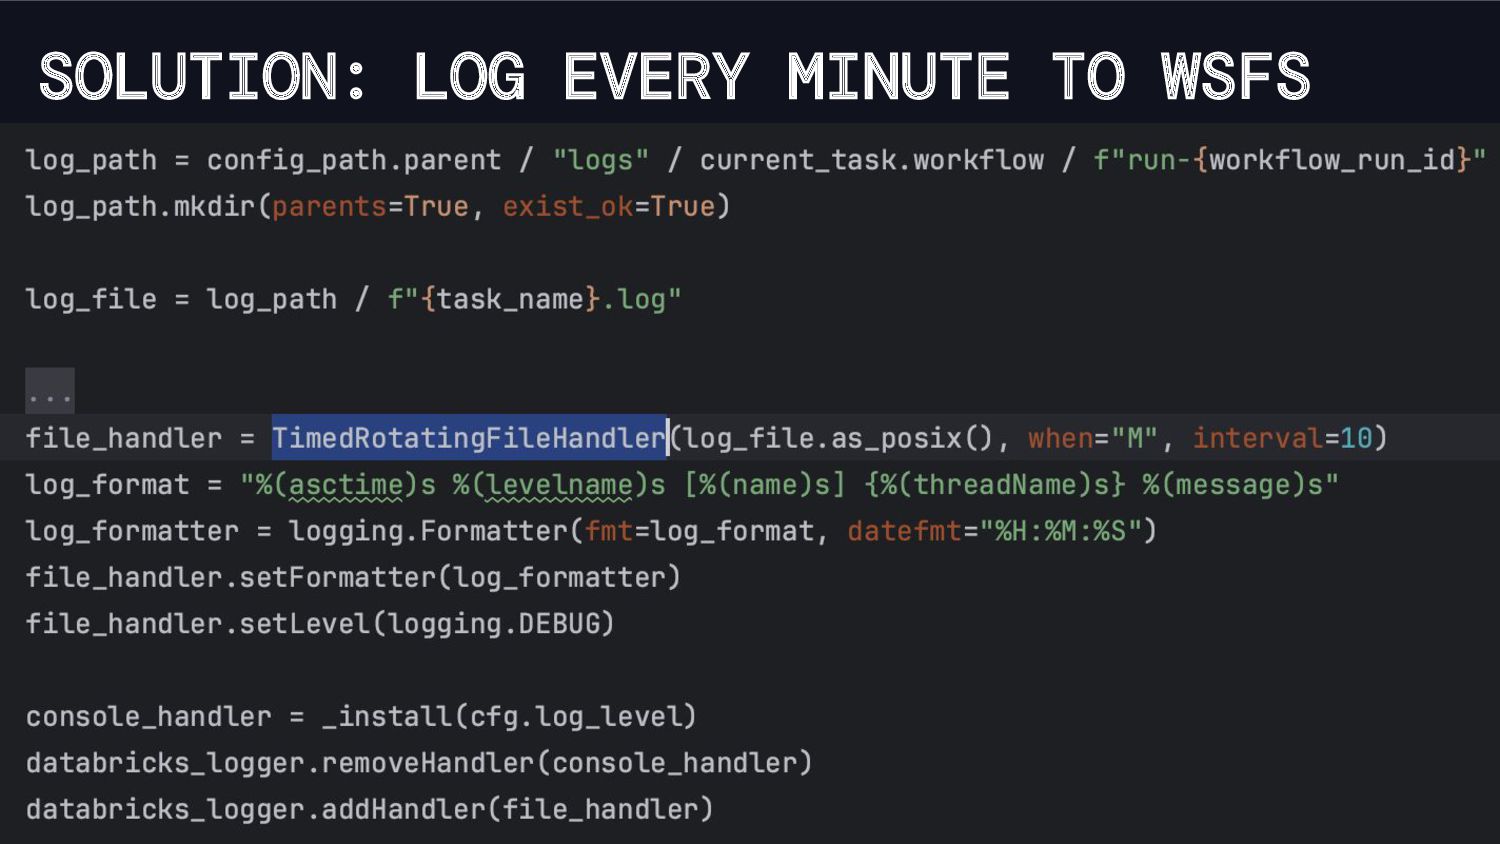
©2024 Databricks Inc. — All rights reserved … or use
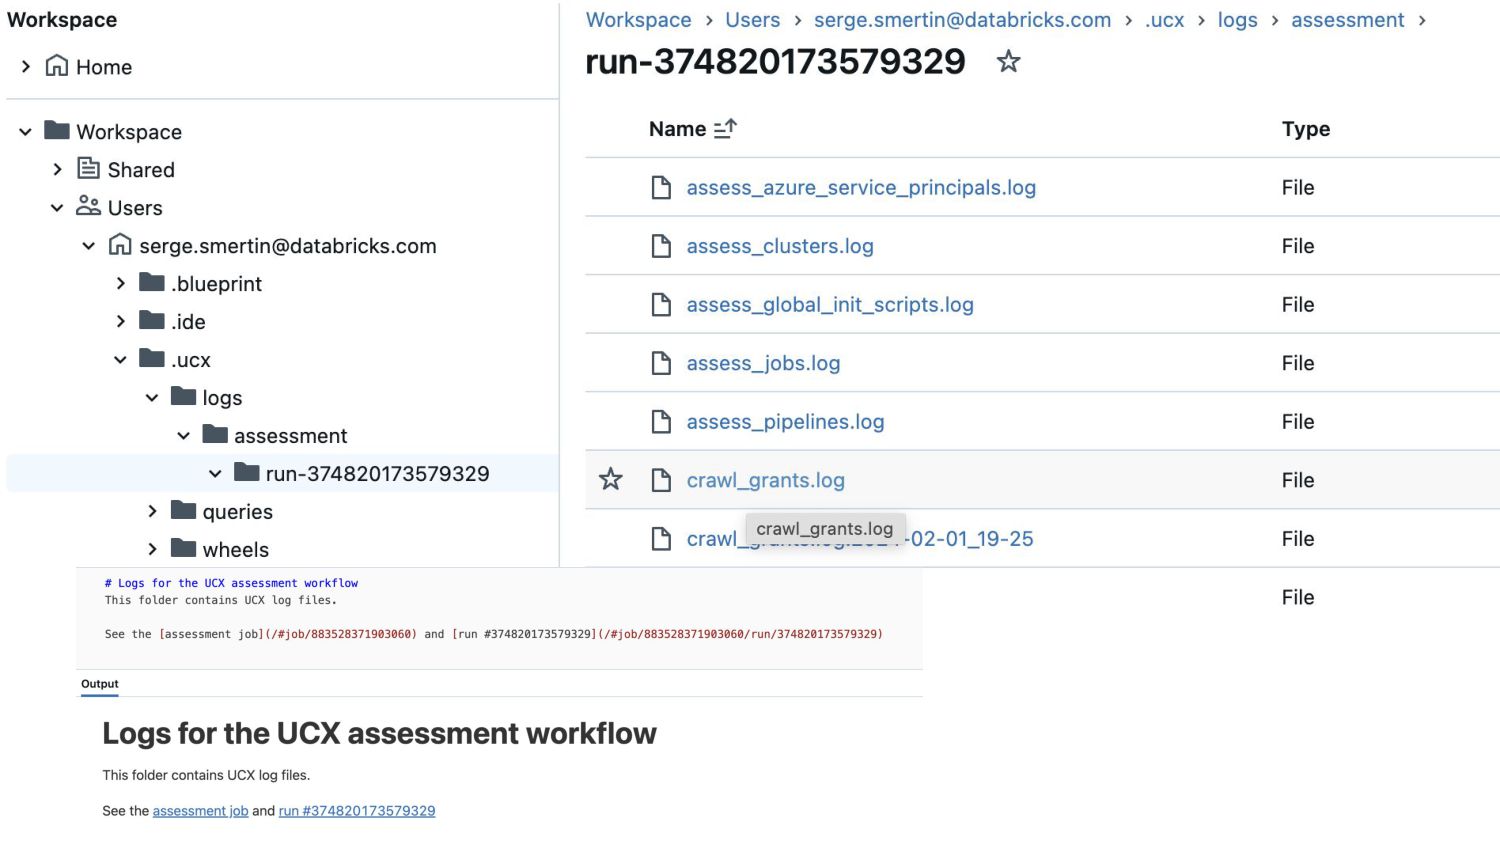
proper ELK/Splunk/Kusto centralized logging infrastructure SOLUTION: LOG EVERY MINUTE TO WSFS 28 -
©2024 Databricks Inc. — All rights reserved ©2024 Databricks Inc.
— All rights reserved 30 TABLE MIGRATION -
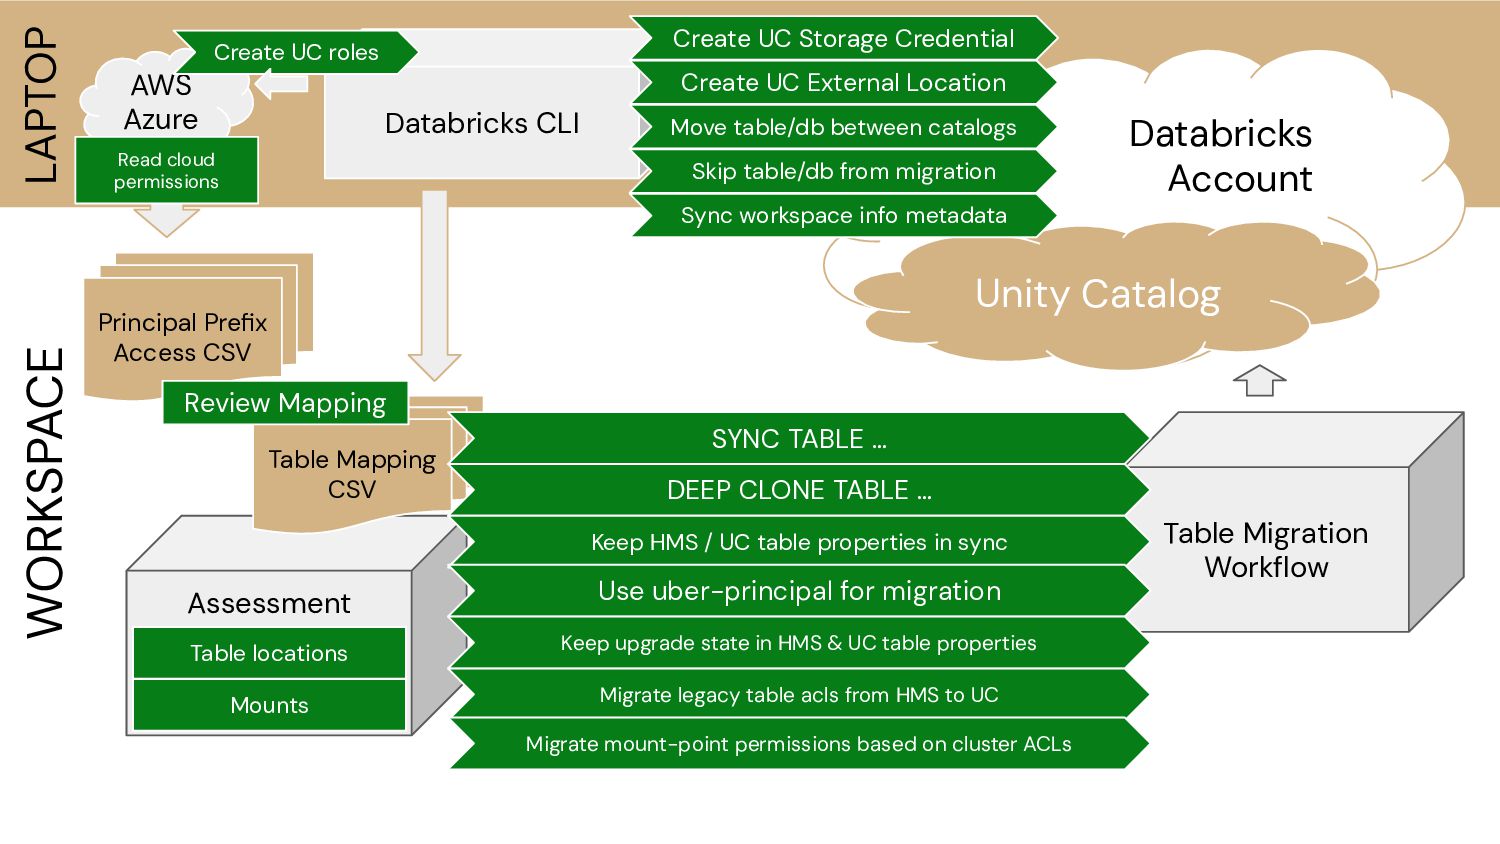
Assessment workflow Table Migration Workflow Databricks CLI AWS Azure Table
Mapping CSV Databricks Account Unity Catalog WORKSPACE LAPTOP Table locations Mounts Principal Prefix Access CSV Review Mapping SYNC TABLE … DEEP CLONE TABLE … Keep HMS / UC table properties in sync Use uber-principal for migration Create UC roles Read cloud permissions Create UC Storage Credential Create UC External Location Keep upgrade state in HMS & UC table properties Move table/db between catalogs Skip table/db from migration Sync workspace info metadata Migrate legacy table acls from HMS to UC Migrate mount-point permissions based on cluster ACLs -
©2024 Databricks Inc. — All rights reserved ©2024 Databricks Inc.
— All rights reserved 32 CHALLENGES: -DASHBOARDS -INTEGRATION TESTS -UNRELEASED WHEELS -
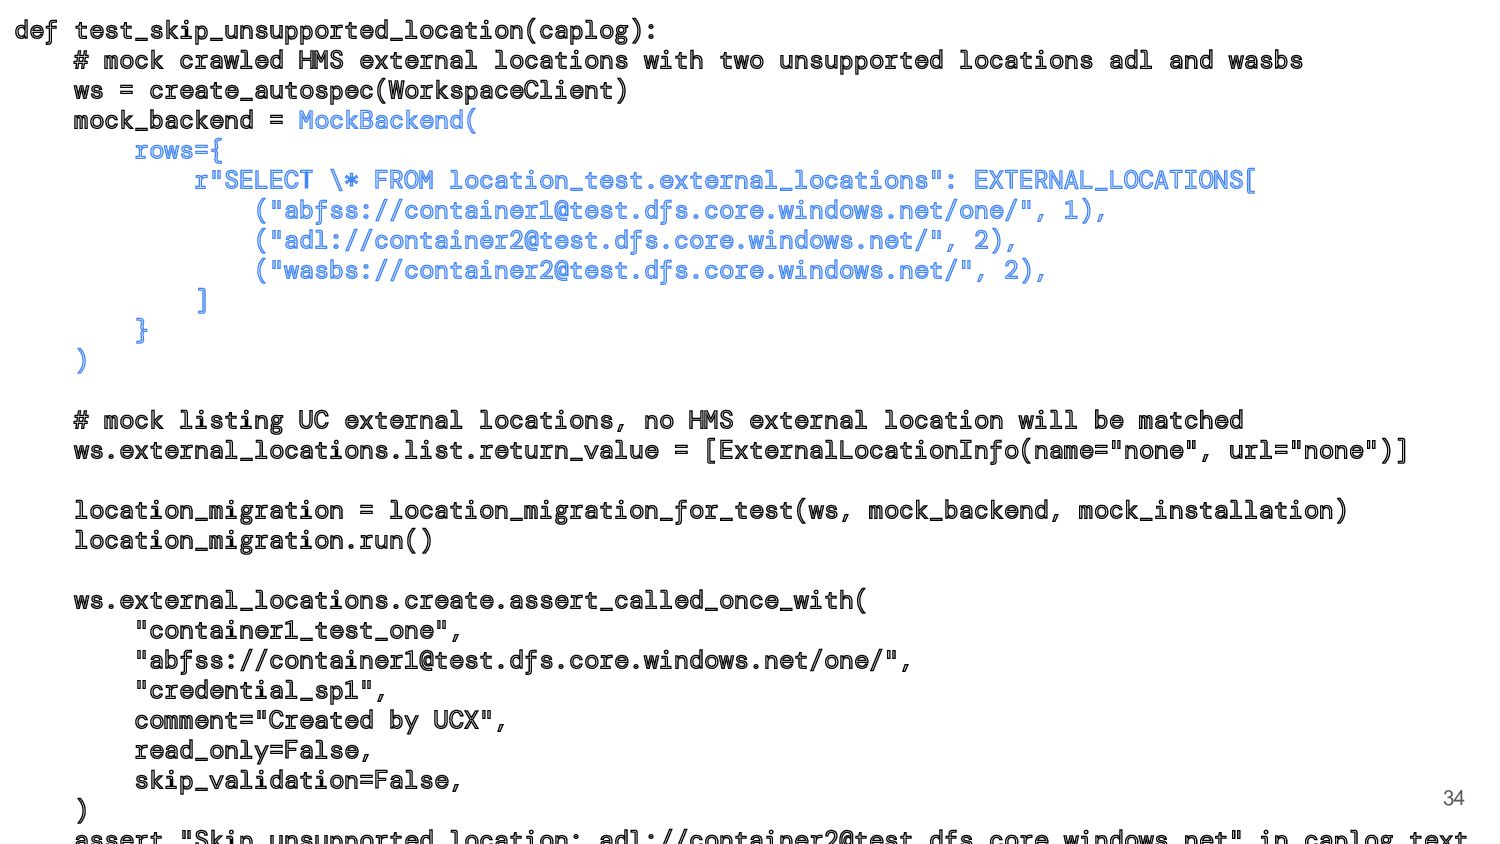
def test_skip_unsupported_location(caplog): # mock crawled HMS external locations with two
unsupported locations adl and wasbs ws = create_autospec(WorkspaceClient) mock_backend = MockBackend( rows={ r"SELECT \* FROM location_test.external_locations": EXTERNAL_LOCATIONS[ ("abfss://[email protected]/one/", 1), ("adl://[email protected]/", 2), ("wasbs://[email protected]/", 2), ] } ) # mock listing UC external locations, no HMS external location will be matched ws.external_locations.list.return_value = [ExternalLocationInfo(name="none", url="none")] location_migration = location_migration_for_test(ws, mock_backend, mock_installation) location_migration.run() ws.external_locations.create.assert_called_once_with( "container1_test_one", "abfss://[email protected]/one/", "credential_sp1", comment="Created by UCX", read_only=False, skip_validation=False, ) 34 -
©2024 Databricks Inc. — All rights reserved ©2024 Databricks Inc.
— All rights reserved 35 35 DATABRICKS LABS LSQL: LIGHTWEIGHT SQL ABSTRACTIONS -
©2024 Databricks Inc. — All rights reserved 36 FINDING HIDDEN
BUGS WITH PYLINT (... and mypy, and ruff, …) -
©2024 Databricks Inc. — All rights reserved from airflow.providers.databricks.operators.databricks import
DatabricksCreateJobsOperator tasks = [ { "task_key": "banana", "notebook_task": { "notebook_path": "/Shared/test", }, 'new_cluster': { # [missing-data-security-mode] banana cluster missing `data_security_mode` # required for Unity Catalog compatibility "spark_version": "7.3.x-scala2.12", "node_type_id": "i3.xlarge", "num_workers": 2, }, }, ] DatabricksCreateJobsOperator( #@ task_id="jobs_create_named", tasks=tasks ) 37 -
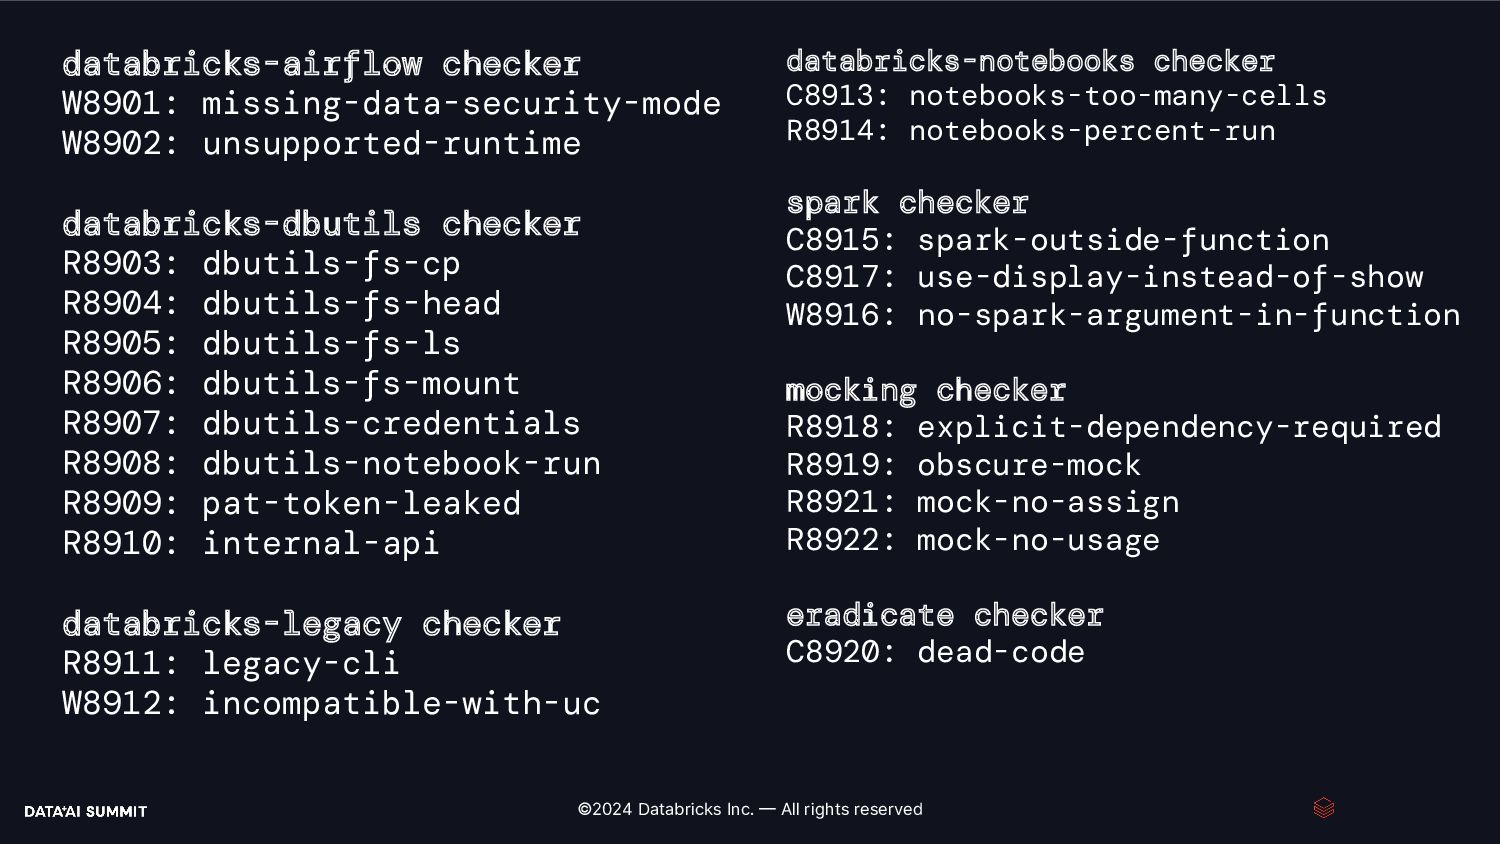
©2024 Databricks Inc. — All rights reserved databricks-airflow checker W8901:
missing-data-security-mode W8902: unsupported-runtime databricks-dbutils checker R8903: dbutils-fs-cp R8904: dbutils-fs-head R8905: dbutils-fs-ls R8906: dbutils-fs-mount R8907: dbutils-credentials R8908: dbutils-notebook-run R8909: pat-token-leaked R8910: internal-api databricks-legacy checker R8911: legacy-cli W8912: incompatible-with-uc databricks-notebooks checker C8913: notebooks-too-many-cells R8914: notebooks-percent-run spark checker C8915: spark-outside-function C8917: use-display-instead-of-show W8916: no-spark-argument-in-function mocking checker R8918: explicit-dependency-required R8919: obscure-mock R8921: mock-no-assign R8922: mock-no-usage eradicate checker C8920: dead-code -
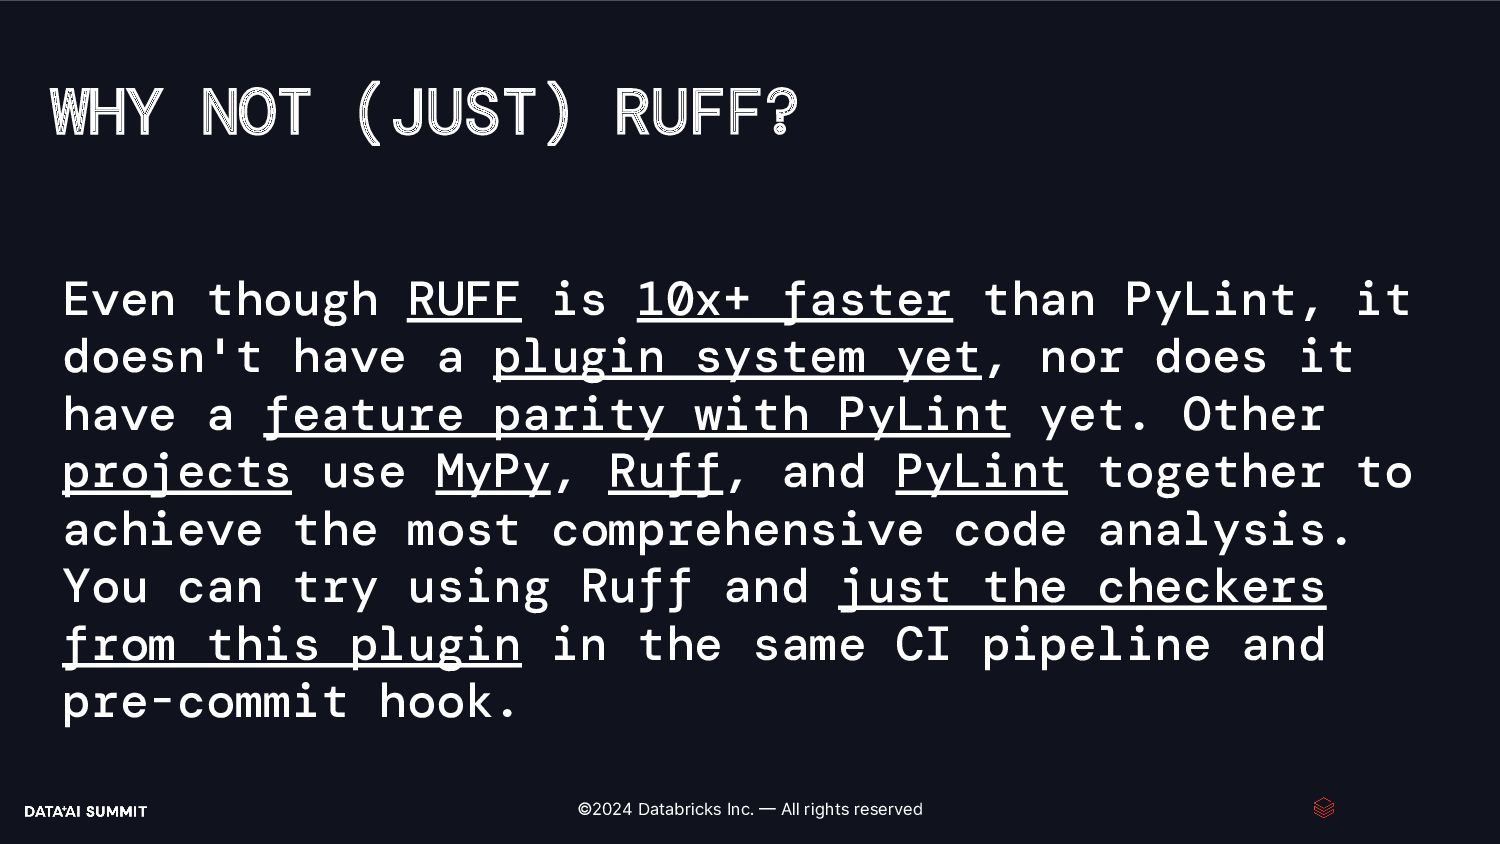
©2024 Databricks Inc. — All rights reserved WHY NOT (JUST)
RUFF? Even though RUFF is 10x+ faster than PyLint, it doesn't have a plugin system yet, nor does it have a feature parity with PyLint yet. Other projects use MyPy, Ruff, and PyLint together to achieve the most comprehensive code analysis. You can try using Ruff and just the checkers from this plugin in the same CI pipeline and pre-commit hook. -
©2024 Databricks Inc. — All rights reserved ©2024 Databricks Inc.
— All rights reserved 40 40 PYLINT PLUGIN FOR DATABRICKS -
©2024 Databricks Inc. — All rights reserved 41 INVERSION OF
CONTROL / DEPENDENCY INJECTION -
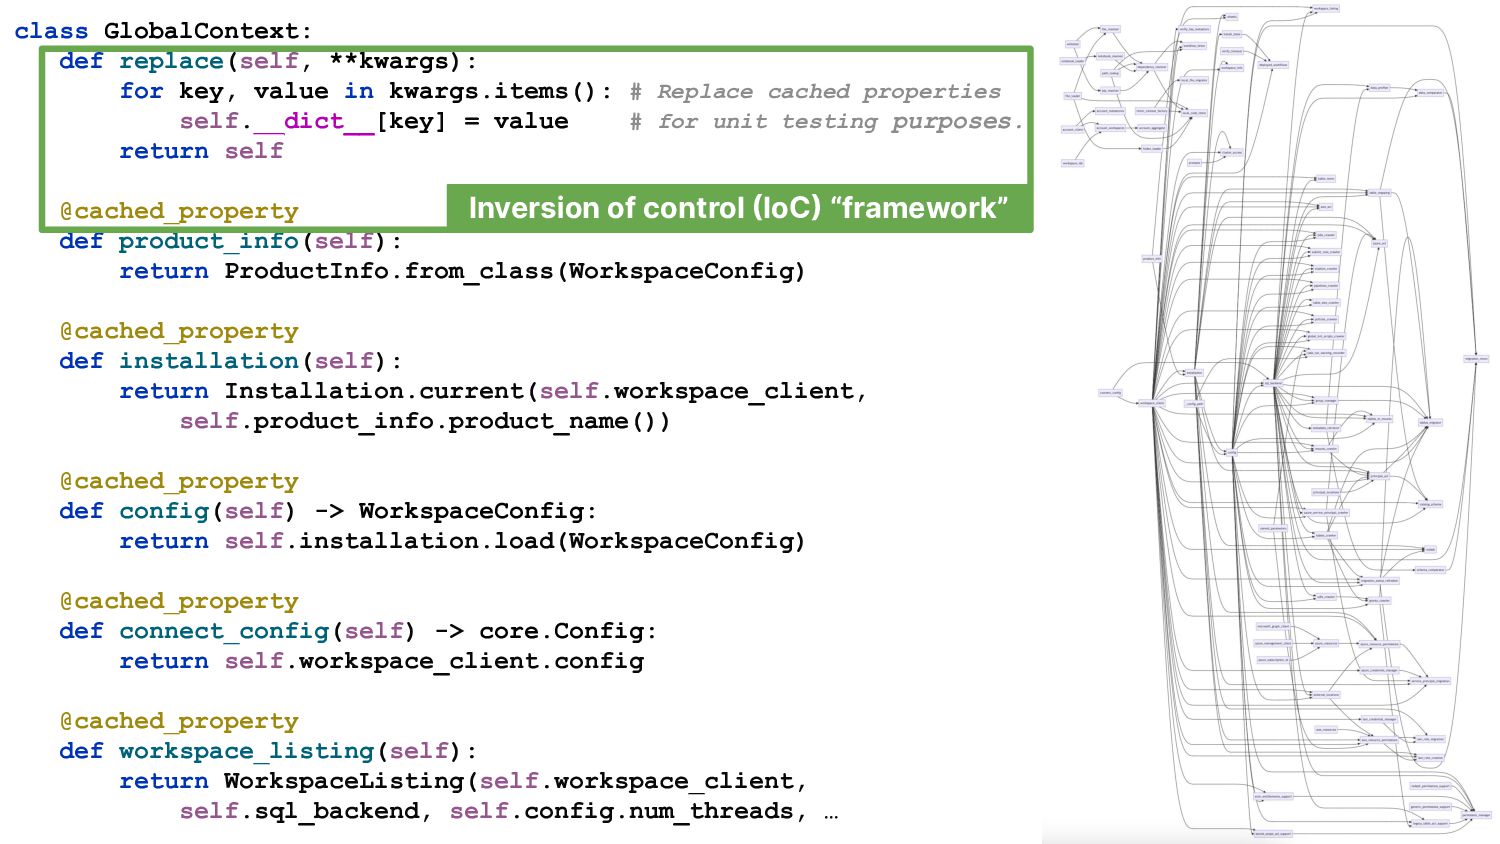
©2024 Databricks Inc. — All rights reserved 42 class GlobalContext:
def replace(self, **kwargs): for key, value in kwargs.items(): # Replace cached properties self.__dict__[key] = value # for unit testing purposes. return self @cached_property def product_info(self): return ProductInfo.from_class(WorkspaceConfig) @cached_property def installation(self): return Installation.current(self.workspace_client, self.product_info.product_name()) @cached_property def config(self) -> WorkspaceConfig: return self.installation.load(WorkspaceConfig) @cached_property def connect_config(self) -> core.Config: return self.workspace_client.config @cached_property def workspace_listing(self): return WorkspaceListing(self.workspace_client, self.sql_backend, self.config.num_threads, … Inversion of control (IoC) “framework” -
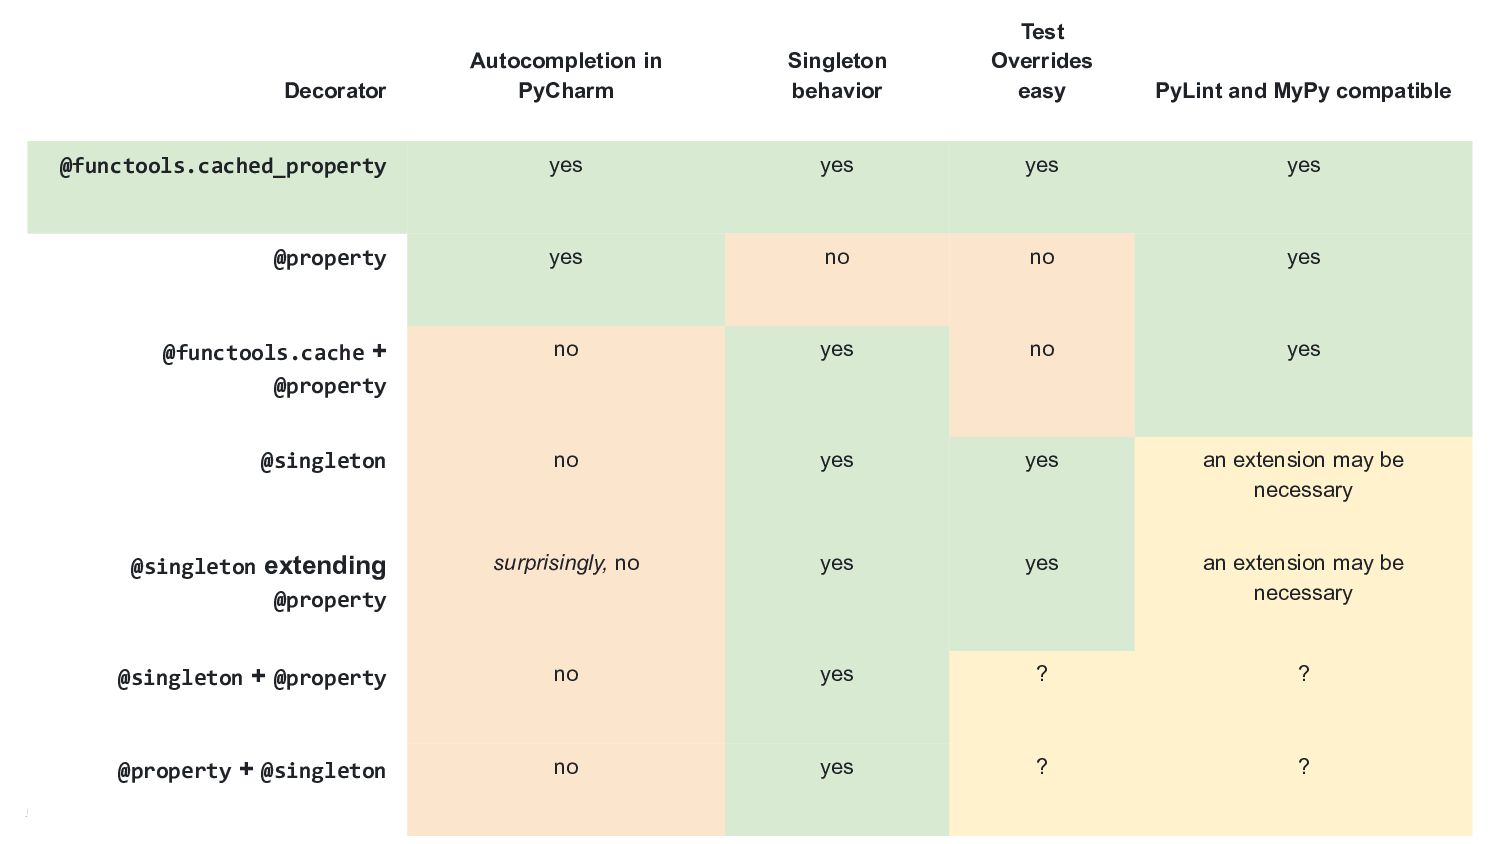
©2024 Databricks Inc. — All rights reserved 43 Decorator Autocompletion
in PyCharm Singleton behavior Test Overrides easy PyLint and MyPy compatible @functools.cached_property yes yes yes yes @property yes no no yes @functools.cache + @property no yes no yes @singleton no yes yes an extension may be necessary @singleton extending @property surprisingly, no yes yes an extension may be necessary @singleton + @property no yes ? ? @property + @singleton no yes ? ? -
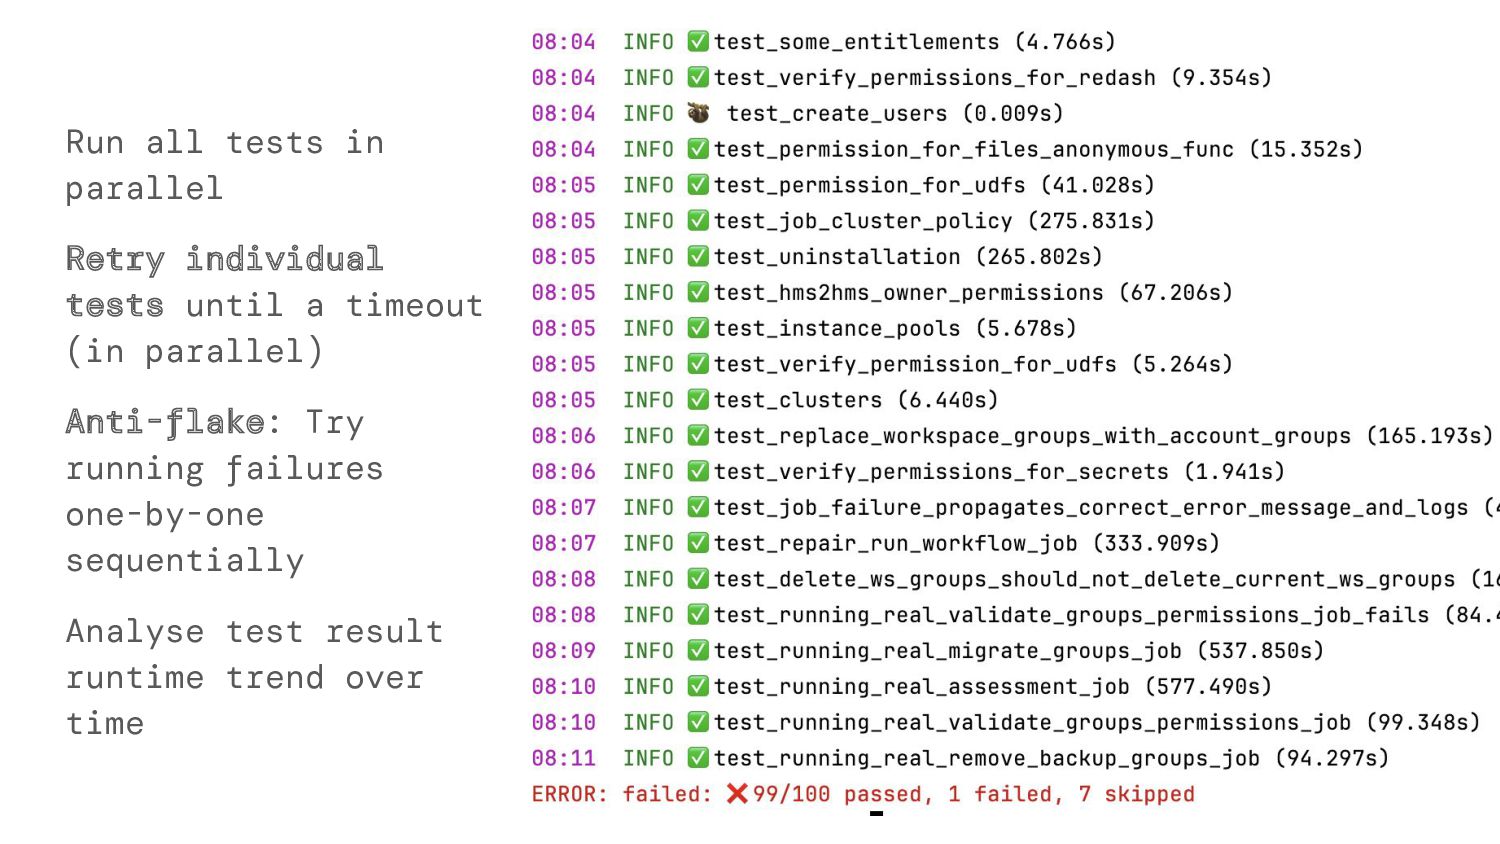
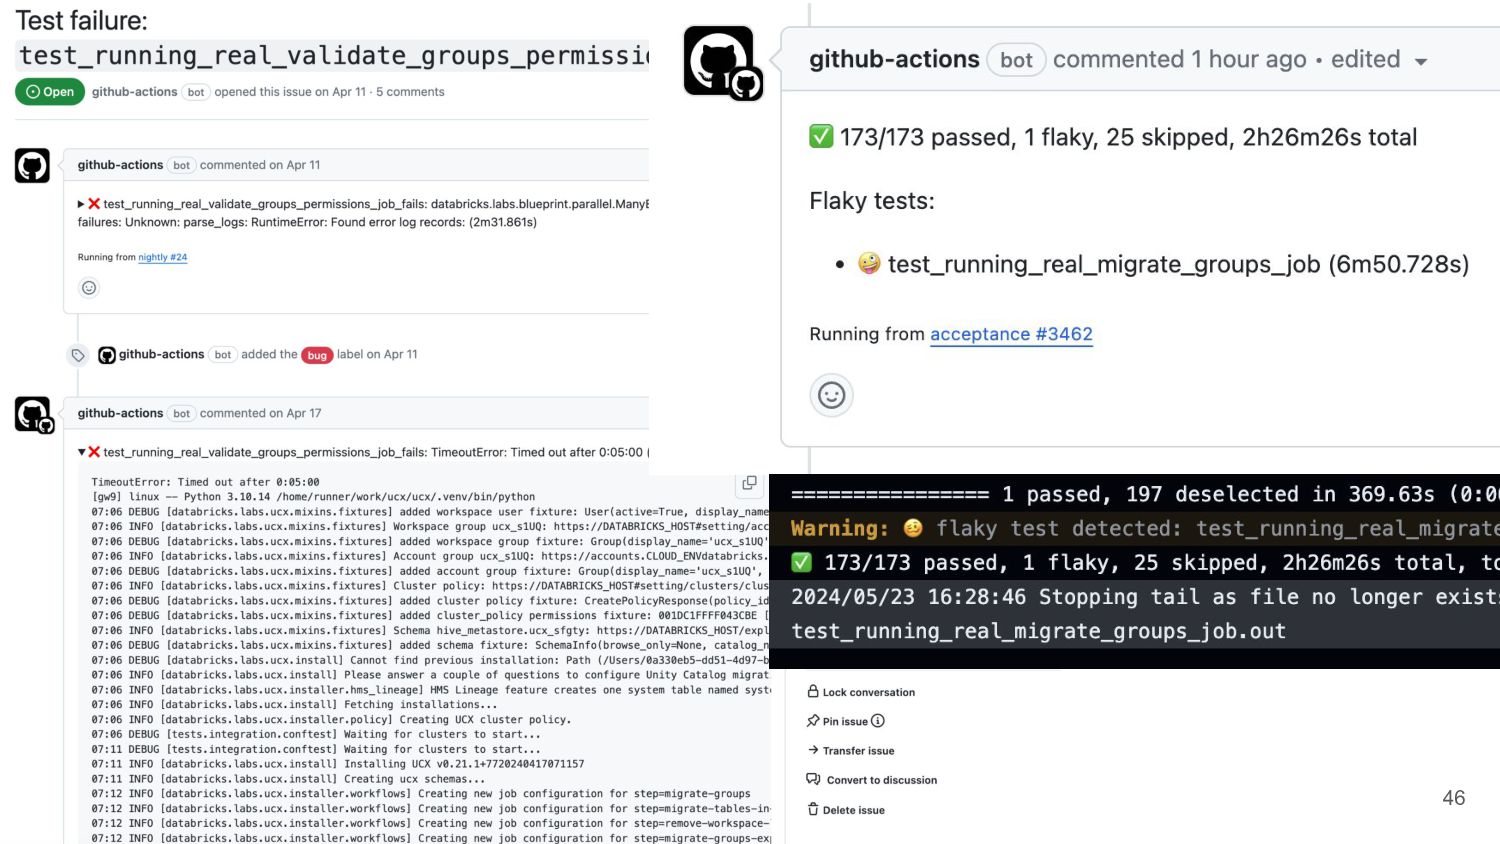
Run all tests in parallel Retry individual tests until a
timeout (in parallel) Anti-flake: Try running failures one-by-one sequentially Analyse test result runtime trend over time -
@retried(on=[NotFound, Unknown, InvalidParameterValue], timeout=timedelta(minutes=20)) def test_running_real_assessment_job ( ws, new_installation, make_ucx_group,
make_cluster_policy, make_cluster_policy_permissions ): ws_group_a, acc_group_a = make_ucx_group() cluster_policy = make_cluster_policy() make_cluster_policy_permissions( object_id=cluster_policy.policy_id, permission_level=PermissionLevel.CAN_USE, group_name=ws_group_a.display_name, ) install = new_installation(lambda wc: replace(wc, include_group_names =[ws_group_a.display_name])) install.run_workflow("assessment") generic_permissions = GenericPermissionsSupport(ws, []) after = generic_permissions .load_as_dict("cluster-policies" , cluster_policy.policy_id) assert after[ws_group_a.display_name] == PermissionLevel.CAN_USE -
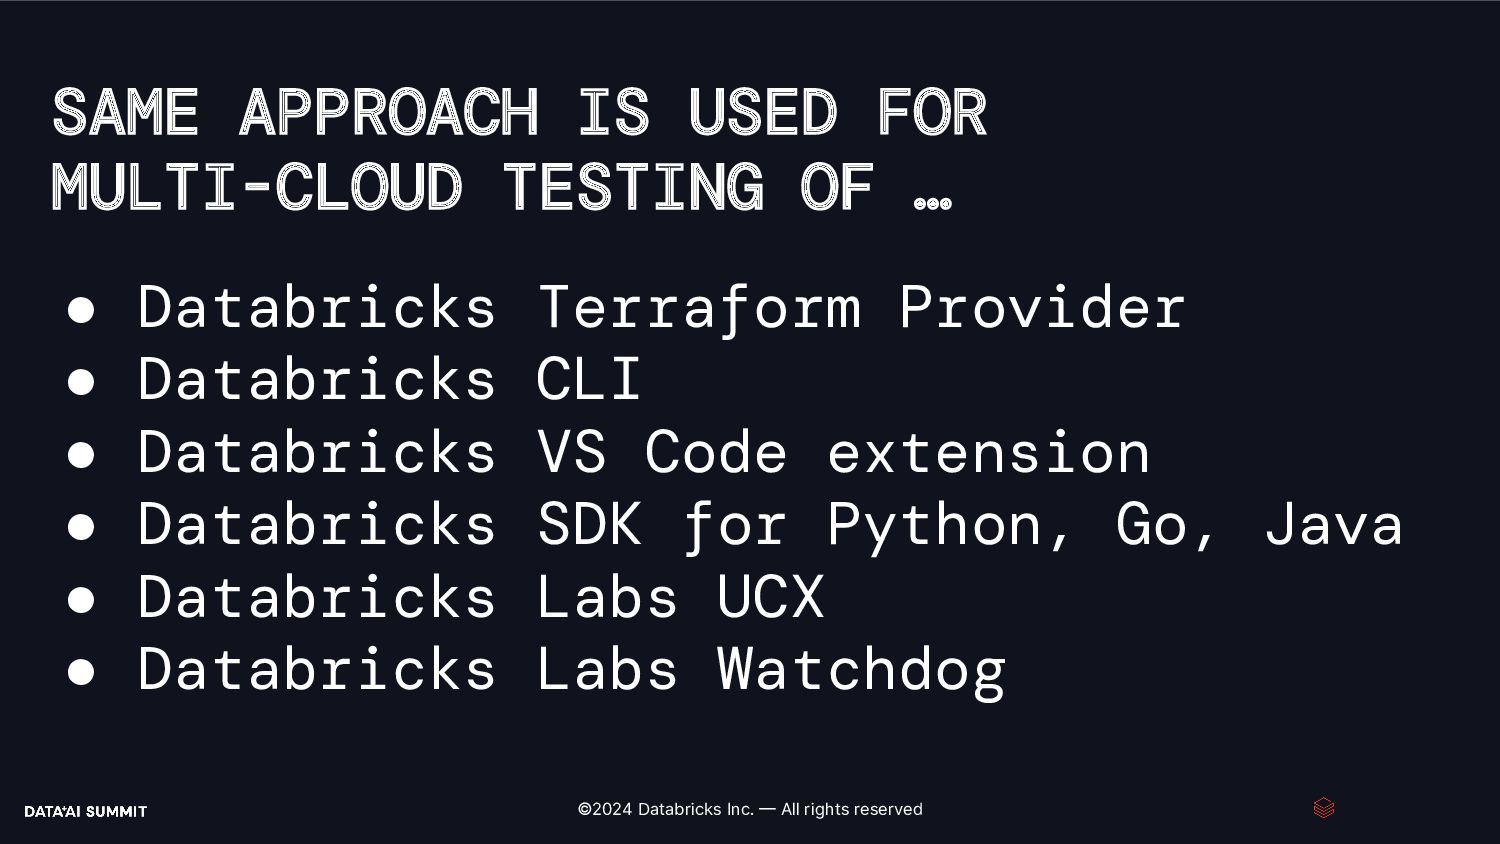
©2024 Databricks Inc. — All rights reserved SAME APPROACH IS
USED FOR MULTI-CLOUD TESTING OF … • Databricks Terraform Provider • Databricks CLI • Databricks VS Code extension • Databricks SDK for Python, Go, Java • Databricks Labs UCX • Databricks Labs Watchdog -
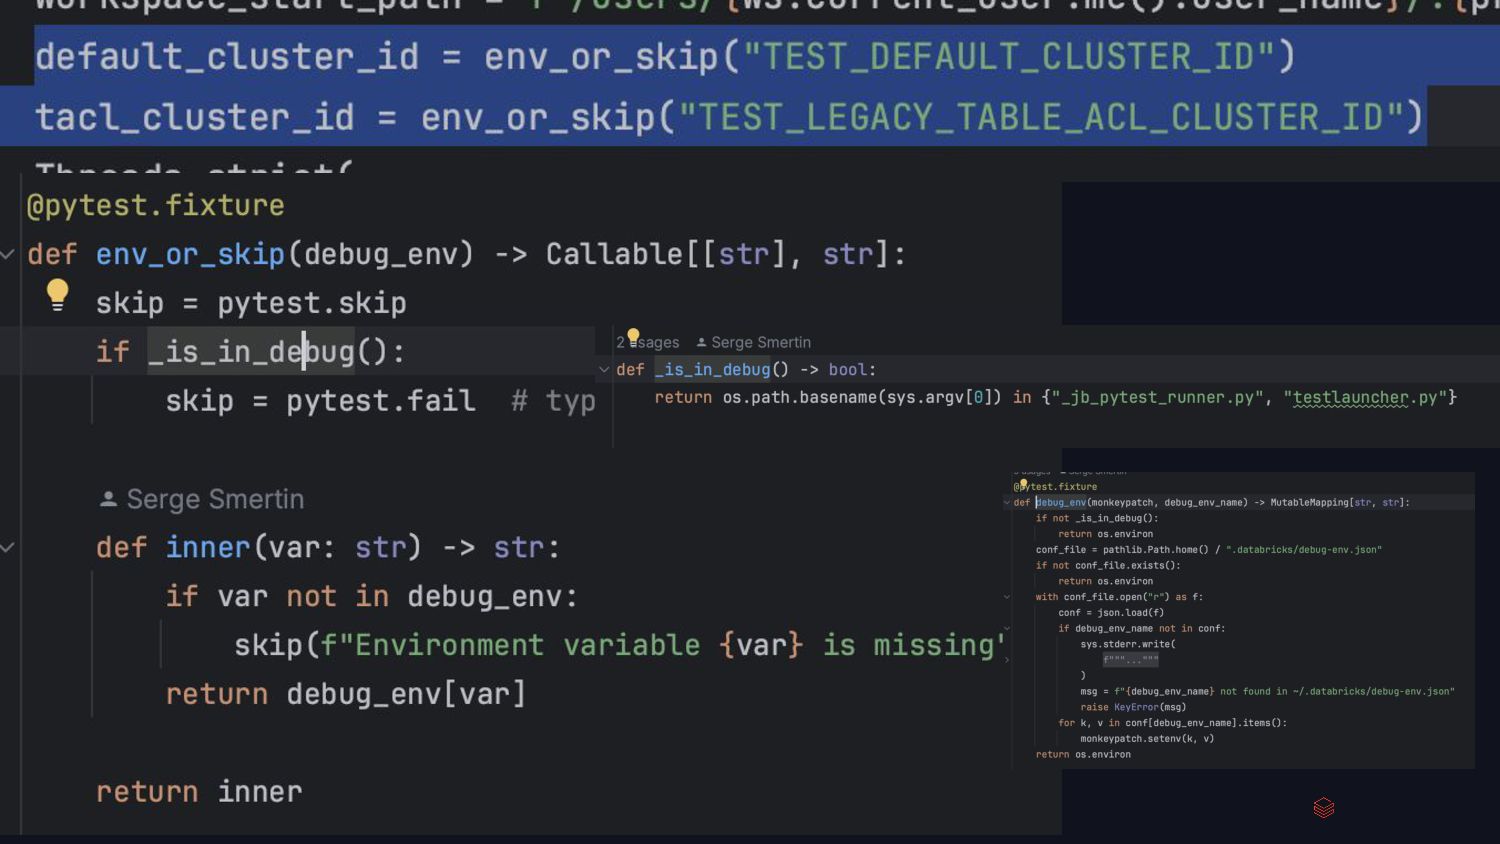
“dynamic fixtures” that require a cleanup by Databricks Labs Very
rough equivalent of something between “Chaos Monkey” and “Cloud Custodian” -
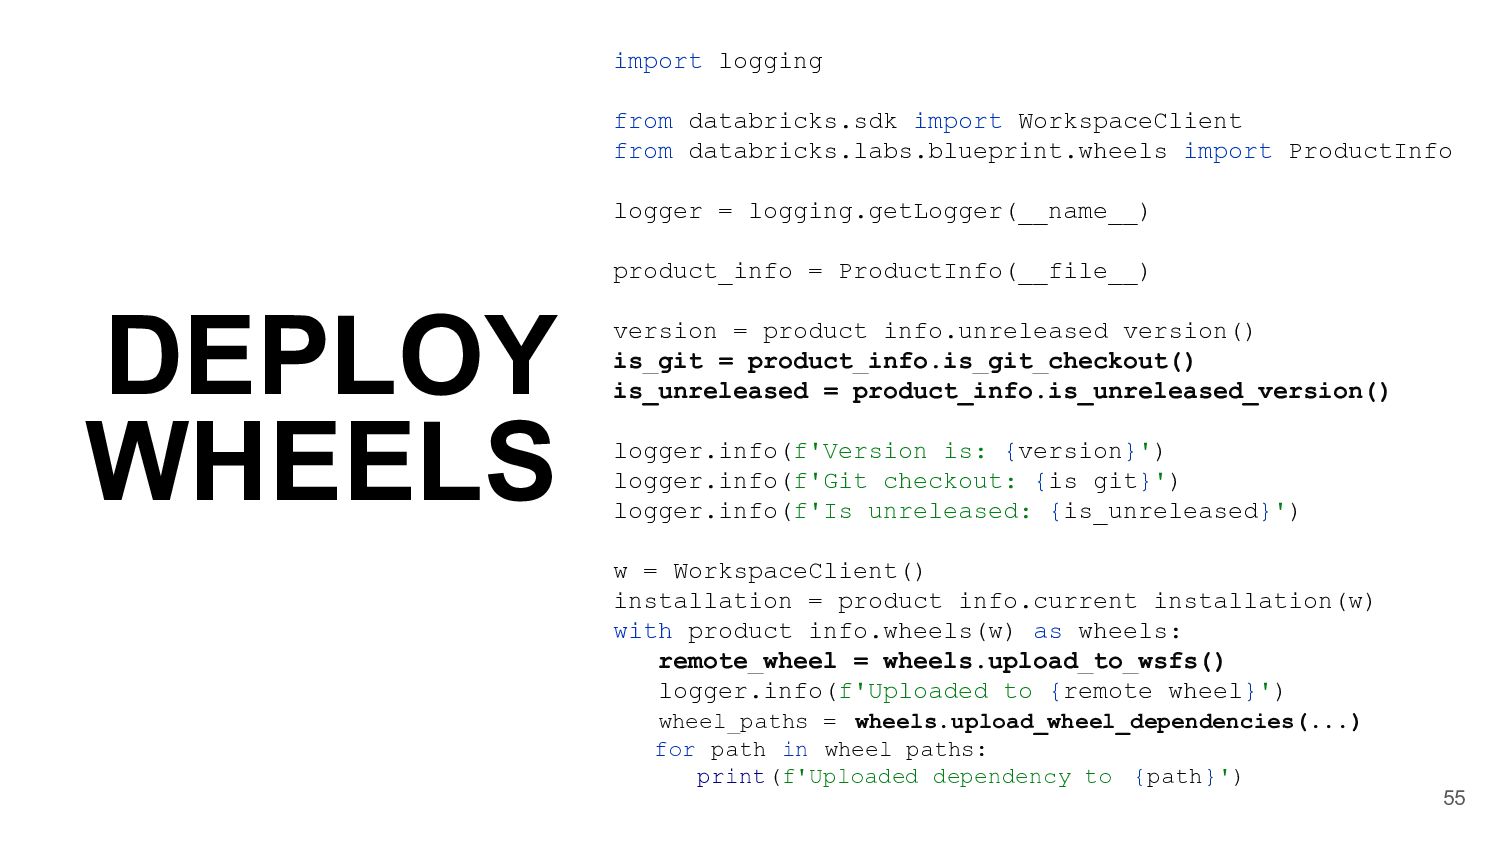
55 import logging from databricks.sdk import WorkspaceClient from databricks.labs.blueprint.wheels import
ProductInfo logger = logging.getLogger(__name__) product_info = ProductInfo(__file__) version = product_info.unreleased_version() is_git = product_info.is_git_checkout() is_unreleased = product_info.is_unreleased_version() logger.info(f'Version is: {version}') logger.info(f'Git checkout: {is_git}') logger.info(f'Is unreleased: {is_unreleased}') w = WorkspaceClient() installation = product_info.current_installation(w) with product_info.wheels(w) as wheels: remote_wheel = wheels.upload_to_wsfs() logger.info(f'Uploaded to {remote_wheel}') wheel_paths = wheels.upload_wheel_dependencies(...) for path in wheel_paths: print(f'Uploaded dependency to {path}') DEPLOY WHEELS -
56 from databricks.labs.blueprint.installation import Installation @dataclass class EvolvedConfig : __file__
= "config.yml" __version__ = 3 initial: int added_in_v1: int added_in_v2: int @staticmethod def v1_migrate(raw: dict) -> dict: raw["added_in_v1"] = 111 raw["version"] = 2 return raw @staticmethod def v2_migrate(raw: dict) -> dict: raw["added_in_v2"] = 222 raw["version"] = 3 return raw installation = Installation.current(WorkspaceClient(), "blueprint" ) cfg = installation.load(EvolvedConfig) assert 999 == cfg.initial assert 111 == cfg.added_in_v1 # <-- added by v1_migrate() CONFIG EVOLUTION -
57 from ... import Config from databricks.sdk import WorkspaceClient from
databricks.labs.blueprint.upgrades import Upgrades from databricks.labs.blueprint.wheels import ProductInfo product_info = ProductInfo.from_class(Config) ws = WorkspaceClient( product=product_info.product_name(), product_version =product_info.version()) installation = product_info.current_installation(ws) config = installation.load(Config) upgrades = Upgrades(product_info, installation) upgrades.apply(ws) # and in v0.0.1_add_service.py: from ... import Config import logging, dataclasses from databricks.sdk import WorkspaceClient from databricks.labs.blueprint.installation import Installation upgrade_logger = logging.getLogger(__name__) def upgrade(installation: Installation, ws: WorkspaceClient): upgrade_logger.info( "creating new automated service user" ) config = installation.load(Config) service_principal = ws.service_principals.create( display_name ='blueprint-service' ) new_config = dataclasses.replace( config, application_id =service_principal .application_id) installation.save(new_config) APP (OR DATABASE) EVOLUTION -
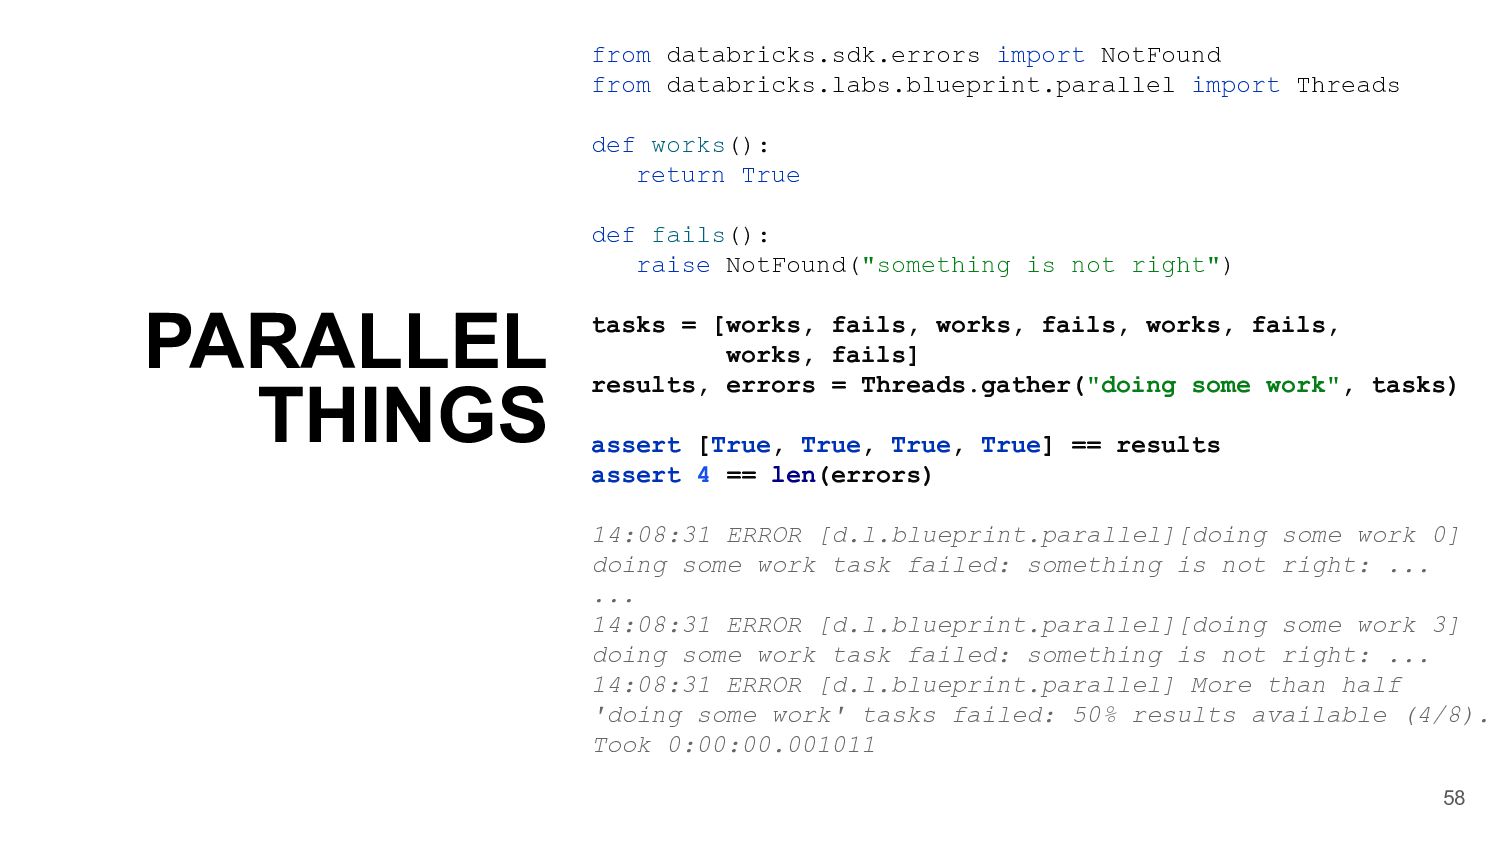
58 from databricks.sdk.errors import NotFound from databricks.labs.blueprint.parallel import Threads def
works(): return True def fails(): raise NotFound("something is not right") tasks = [works, fails, works, fails, works, fails, works, fails] results, errors = Threads.gather("doing some work", tasks) assert [True, True, True, True] == results assert 4 == len(errors) 14:08:31 ERROR [d.l.blueprint.parallel][doing_some_work_0] doing some work task failed: something is not right: ... ... 14:08:31 ERROR [d.l.blueprint.parallel][doing_some_work_3] doing some work task failed: something is not right: ... 14:08:31 ERROR [d.l.blueprint.parallel] More than half 'doing some work' tasks failed: 50% results available (4/8). Took 0:00:00.001011 PARALLEL THINGS -
©2024 Databricks Inc. — All rights reserved ©2024 Databricks Inc.
— All rights reserved 59 59 DATABRICKS LABS BLUEPRINT: PRODUCTION -FOCUSED UTILITIES -
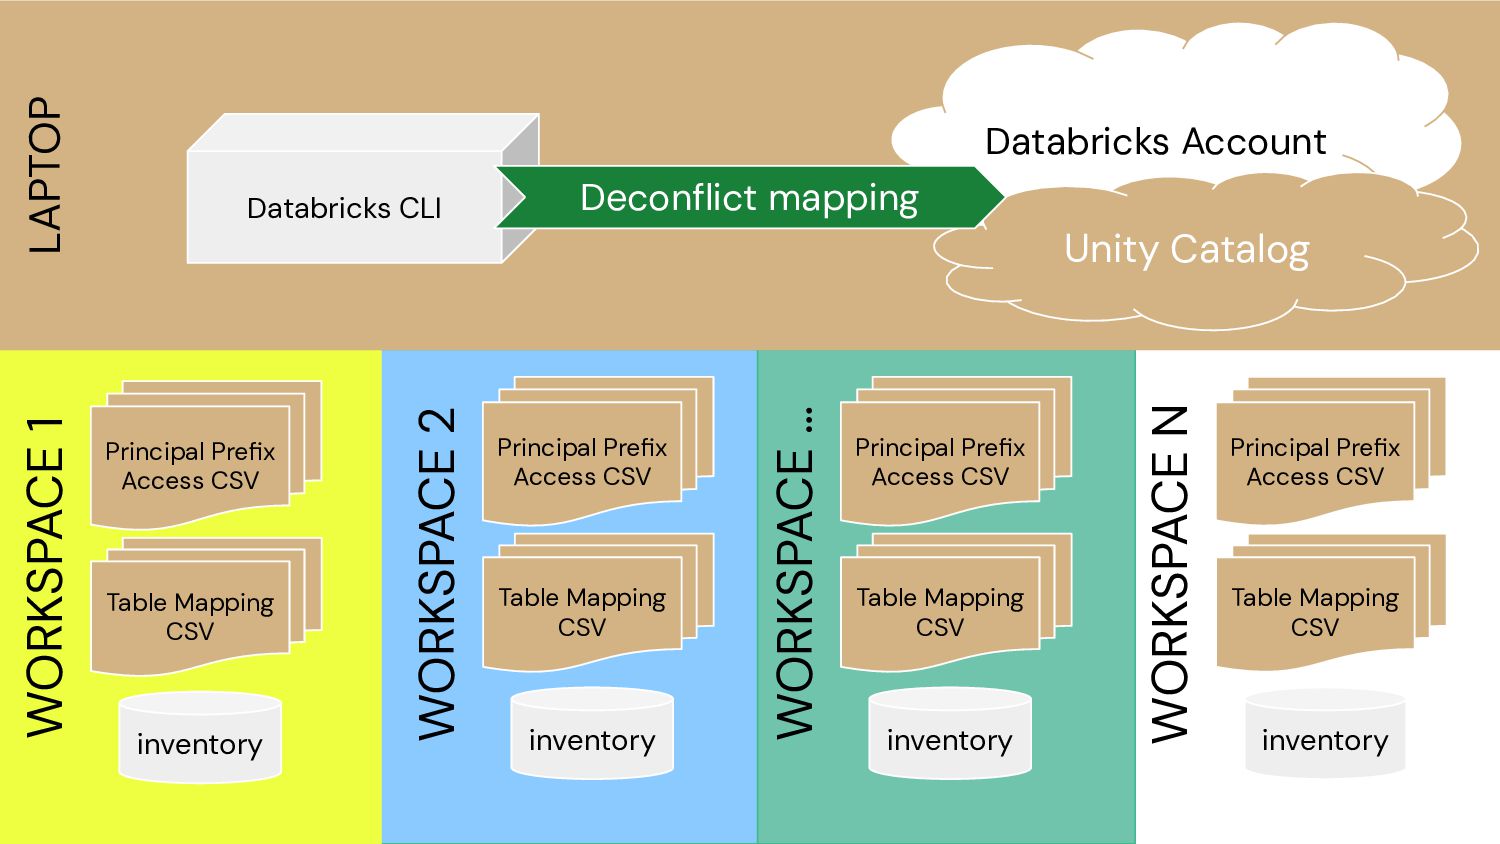
Databricks CLI Table Mapping CSV Databricks Account Unity Catalog WORKSPACE
1 LAPTOP Principal Prefix Access CSV inventory Table Mapping CSV WORKSPACE 2 Principal Prefix Access CSV inventory Table Mapping CSV WORKSPACE … Principal Prefix Access CSV inventory Table Mapping CSV WORKSPACE N Principal Prefix Access CSV inventory Deconflict mapping -
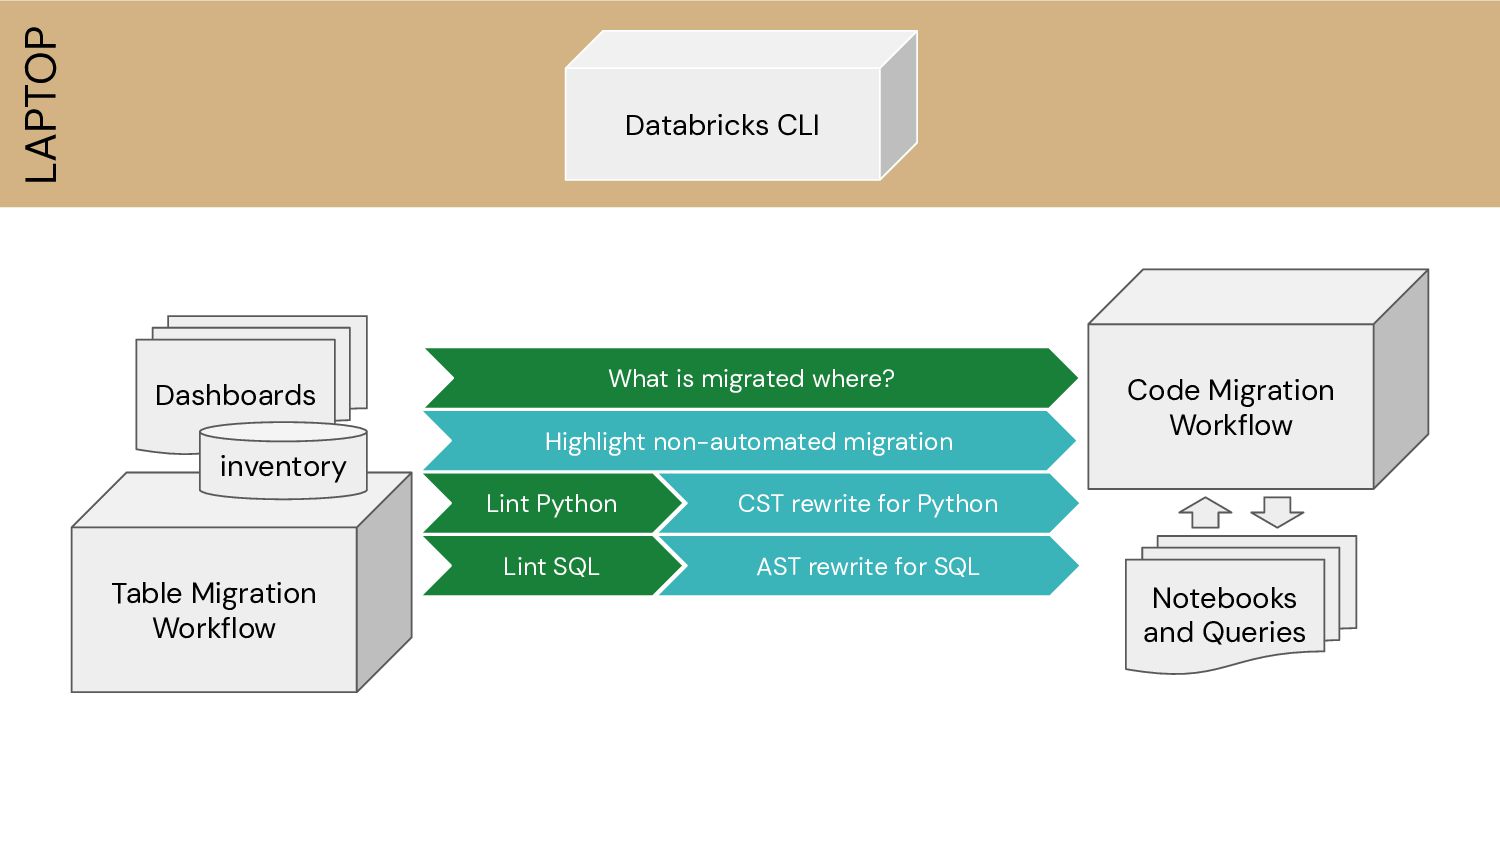
Table Migration Workflow Code Migration Workflow Databricks CLI Notebooks and
Queries LAPTOP CST rewrite for Python AST rewrite for SQL Lint Python Lint SQL Highlight non-automated migration What is migrated where? Dashboards inventory -
63 dist/ioc-matching/10_discoverx_ioc_search.py:96:0: [jvm-access-in-shared-clusters] Cannot access Spark Driver JVM on UC
Shared Clusters dist/ioc-matching/10_discoverx_ioc_search.py:96:0: [legacy-context-in-shared-clusters] sc is not supported on UC Shared Clusters. Rewrite it using spark dist/ioc-matching/10_discoverx_ioc_search.py:97:0: [jvm-access-in-shared-clusters] Cannot access Spark Driver JVM on UC Shared Clusters dist/ioc-matching/10_discoverx_ioc_search.py:106:4: [table-migrate] Can't migrate 'saveAsTable' because its table name argument is not a constant dist/ioc-matching/10_discoverx_ioc_search.py:106:4: [table-migrate] The default format changed in Databricks Runtime 8.0, from Parquet to Delta dist/ioc-matching/10_discoverx_ioc_search.py:118:8: [table-migrate] Can't migrate table_name argument in 'spark.sql(sql_str)' because its value cannot be computed dist/campaign-effectiveness/_resources/00-setup.py:66:2: [table-migrate] Can't migrate table_name argument in 'spark.sql(f'DROP DATABASE IF EXISTS {dbName} CASCADE')' because its value cannot be computed dist/campaign-effectiveness/_resources/00-setup.py:70:0: [table-migrate] Can't migrate table_name argument in 'spark.sql(f"create database if not exists {dbName} LOCATION '{cloud_storage_path}/tables' ")' because its value cannot be computed dist/campaign-effectiveness/01a_Identifying Campaign Effectiveness For Forecasting Foot Traffic: ETL.py:40:87: [dbfs-usage] Deprecated file system path: dbfs:/databricks-datasets/identifying-campaign-effectiveness/subway_foot_traffic/foot_traffic.csv dist/campaign-effectiveness/01a_Identifying Campaign Effectiveness For Forecasting Foot Traffic: ETL.py:64:13: [direct-filesystem-access] The use of direct filesystem references is deprecated: dbfs:/databricks-datasets/identifying-campaign-effectiveness/subway_foot_traffic/foot_traffic.csv -
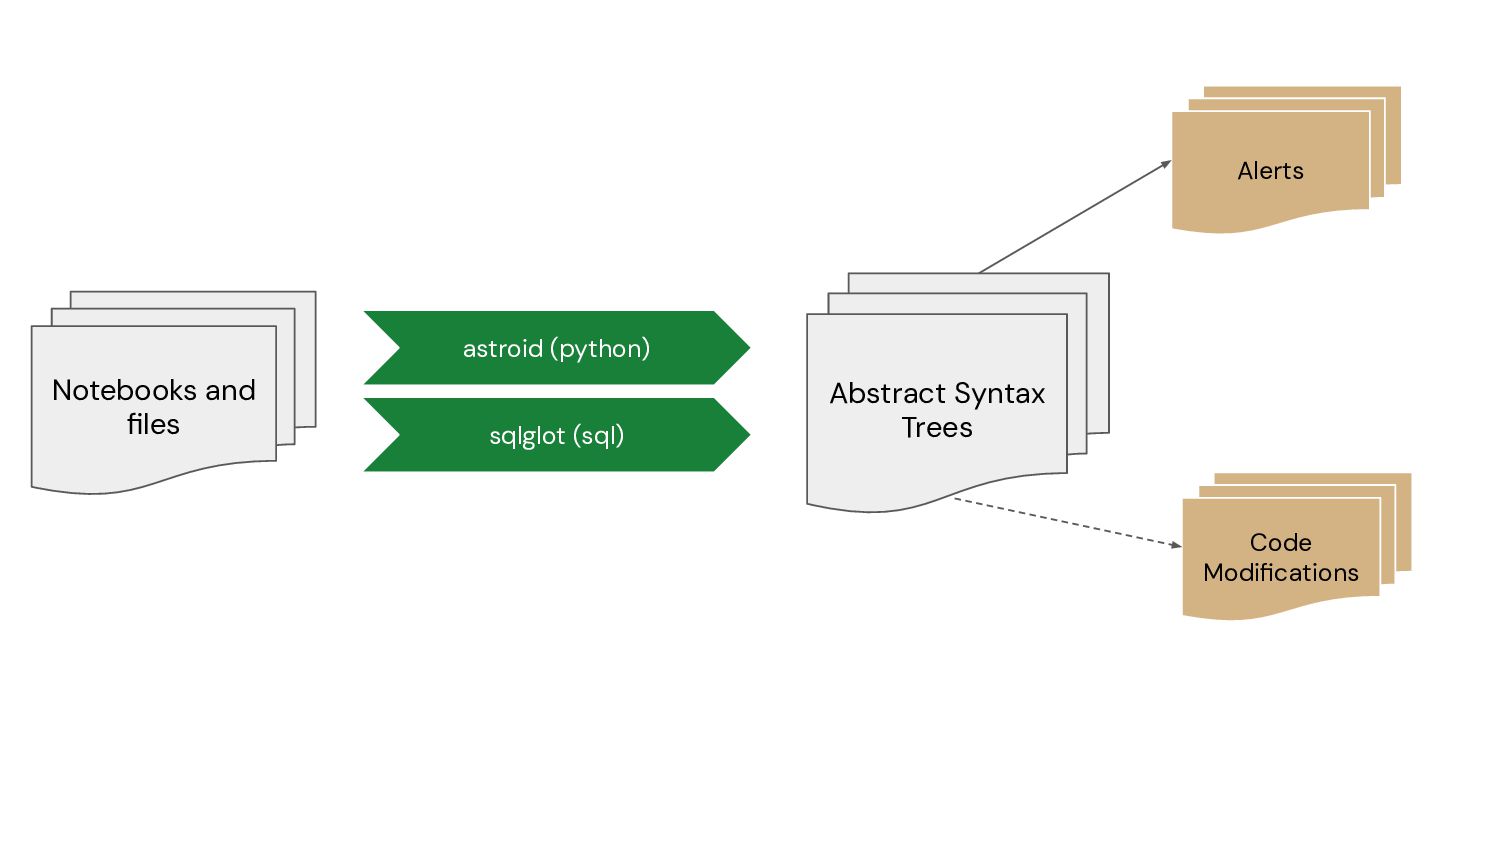
astroid (python) Notebooks and files sqlglot (sql) Abstract Syntax Trees
Alerts Code Modifications -
Learn more at the summit! • We kindly request your
valuable feedback on this session. • Please take a moment to rate and share your thoughts about it. • You can conveniently provide your feedback and rating through the Mobile App. Tells us what you think What to do next? • Visit the Learning Hub Experience at Moscone West, 2nd Floor! • Take complimentary certification at the event; come by the Certified Lounge • Visit our Databricks Learning website for more training, courses and workshops! databricks.com/learn Get trained and certified • Discover more related sessions in the mobile app! • Visit the Demo Booth: Experience innovation firsthand! • More Activities: Engage and connect further at the Databricks Zone! Databricks Events App
 nfx
 sobolevn
 jame2408
 kumaiu
 onozaty
 simas
 raeminkang
 leegeunhyeok
 miccheng
 ostk0069
 fuqda
 ivargrimstad
 j5ik2o
 nikkihalliwell
 tammyeverts
 tonyrice
 jonoalderson
 holman
 aleyda
 rakko
 frankvandijk
 michielstock
 panda_program
 rkendrick25
 ryanjones