Share
Embed
Oracle Database Development Best Practices
A presentation describing some of the common development practices that may cause database performance or scalability issues.

Seán Scott PRO
November 01, 2024
Transcript
65 slides
-
Database Reliability Engineering MAA ⁘ RAC ⁘ RMAN Data Guard
⁘ Sharding ⁘ Partitioning Information Lifecycle Management Exadata & Engineered Systems Database Modernization Upgrades ⁘ Patching ⁘ Migrations Cloud ⁘ Hybrid Automation DevOps ⁘ IaC ⁘ Containers ⁘ Terraform Vagrant ⁘ Ansible Observability AHF ⁘ TFA ⁘ CHA ⁘ CHM -
Production environments should be entirely free of errors or exceptions!
www.viscosityna.com @ViscosityNA -
Every error or exception in production is a problem waiting
to happen. www.viscosityna.com @ViscosityNA -
Maintaining a zero-error baseline makes it easier to identify problems.
www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Invalid code can't be used • "Noise"
that makes troubleshooting issues more dif fi • Is the invalid code a cause or a symptom? • Easy to miss real issues when there are many "expected" errors • Exceptions for "known" conditions can prevent alerts for real problems Invalid and orphaned objects www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Failed updates, deployments • Inadequate testing •
Missing rollback/cleanup procedures • Developing/testing in production • In user schemas, often a sign of poor coding practices/cleanliness • May be accompanied by security issues (overprivileged users) • Endangers performance, stability, security of application data/code Causes of invalid objects www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Constraints maintain referential integrity; they are rules
for the database • The optimizer can't know data meets a condition w/o validated constraints • If a constraint is disabled, why? • Code failure: either the code or the rule is wrong • Prevented deletion: orphans are signs of broken relationships • The optimizer won't understand relationships • May lead to poor/wrong joins, index choices Disabled, not validated constraints www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • A FK constraint and index are necessary
for performance • Joining parent/child tables using the FK • Updating parent PK/deleting a parent record locks the child table • Exception: • Parent records are never deleted • The parent PK value never changes • Parent and child tables are never joined Foreign keys without indexes www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • [DBA|ALL|USER]_ERRORS lists stored code with errors or
warnings • PLSQL_WARNINGS defaults to DISABLE:ALL • Warning categories: SEVERE, PERFORMANCE, INFORMATIONAL • PL/SQL with warnings compiles successfully but can still be "bad" • Fail during execution • Using wrong variables • Unreachable code PL/SQL Errors • Inef fi cient code • Variable conversions • Missing/incorrect exception handling www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Oracle advisors will scan for these conditions
and make recommendations • When space in a disk block isn't optimized/maximized: • I/O increases (reads get empty space, not data) • Cached objects consume more space in buffer cache • Increase in Global Cache waits (more hot blocks) • Less ef fi Oversized and fragmented objects www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Just what they sound like—a reverse key
"mirrors" the key value • Reverse key indexes are not ordered & do not support: • Predicates using BETWEEN, LIKE, <, ≤, >, ≥ • Ordinary range scans • Useful for bypassing two very speci fi • Index block contention on right-leaning indexes • Sparsely populated indexes (fragmentation) caused by key deletion Reverse key indexes www.viscosityna.com @ViscosityNA -
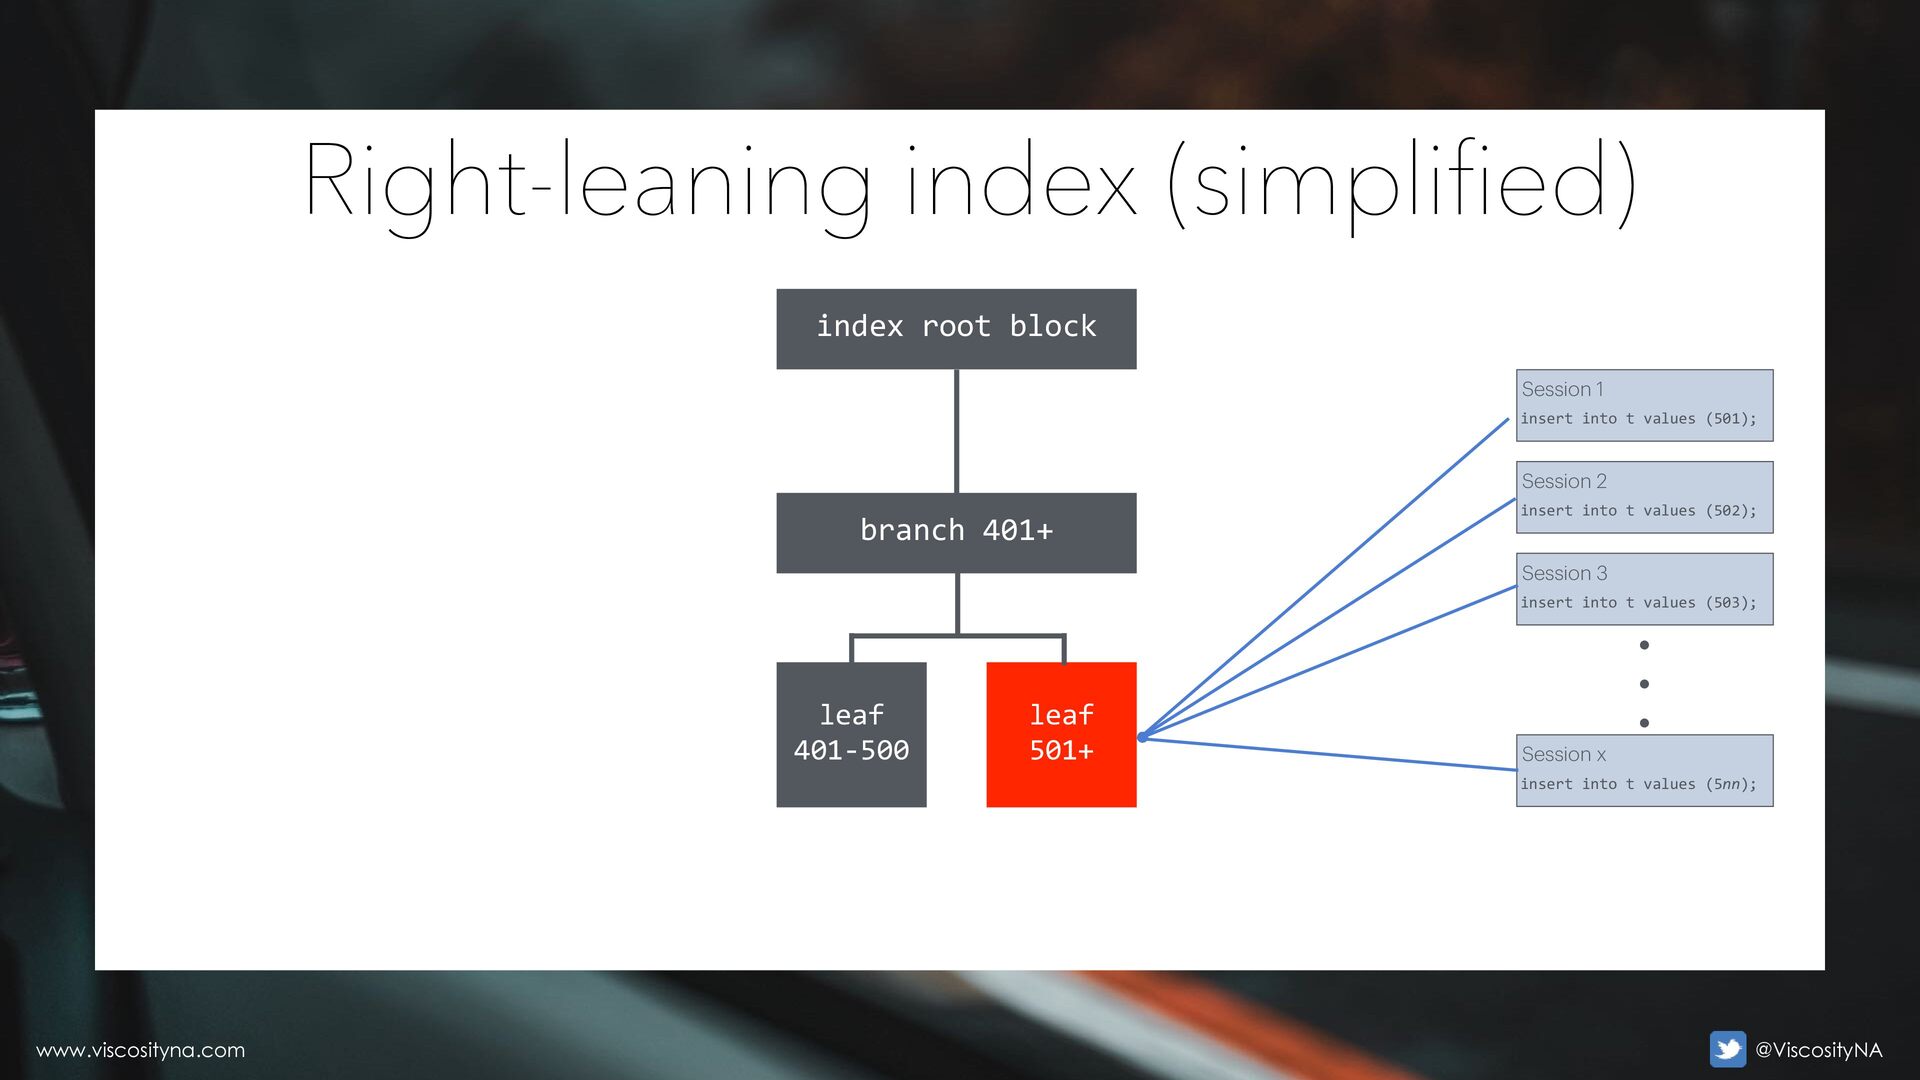
www.viscosityna.com @ViscosityNA • Characterized by buffer • Conditions: • Monotonically
increasing/right-leaning index (PK using a sequence) • High insert concurrency (sometimes also update, delete) • RAC can aggravate the situation Right-leaning indexes www.viscosityna.com @ViscosityNA -
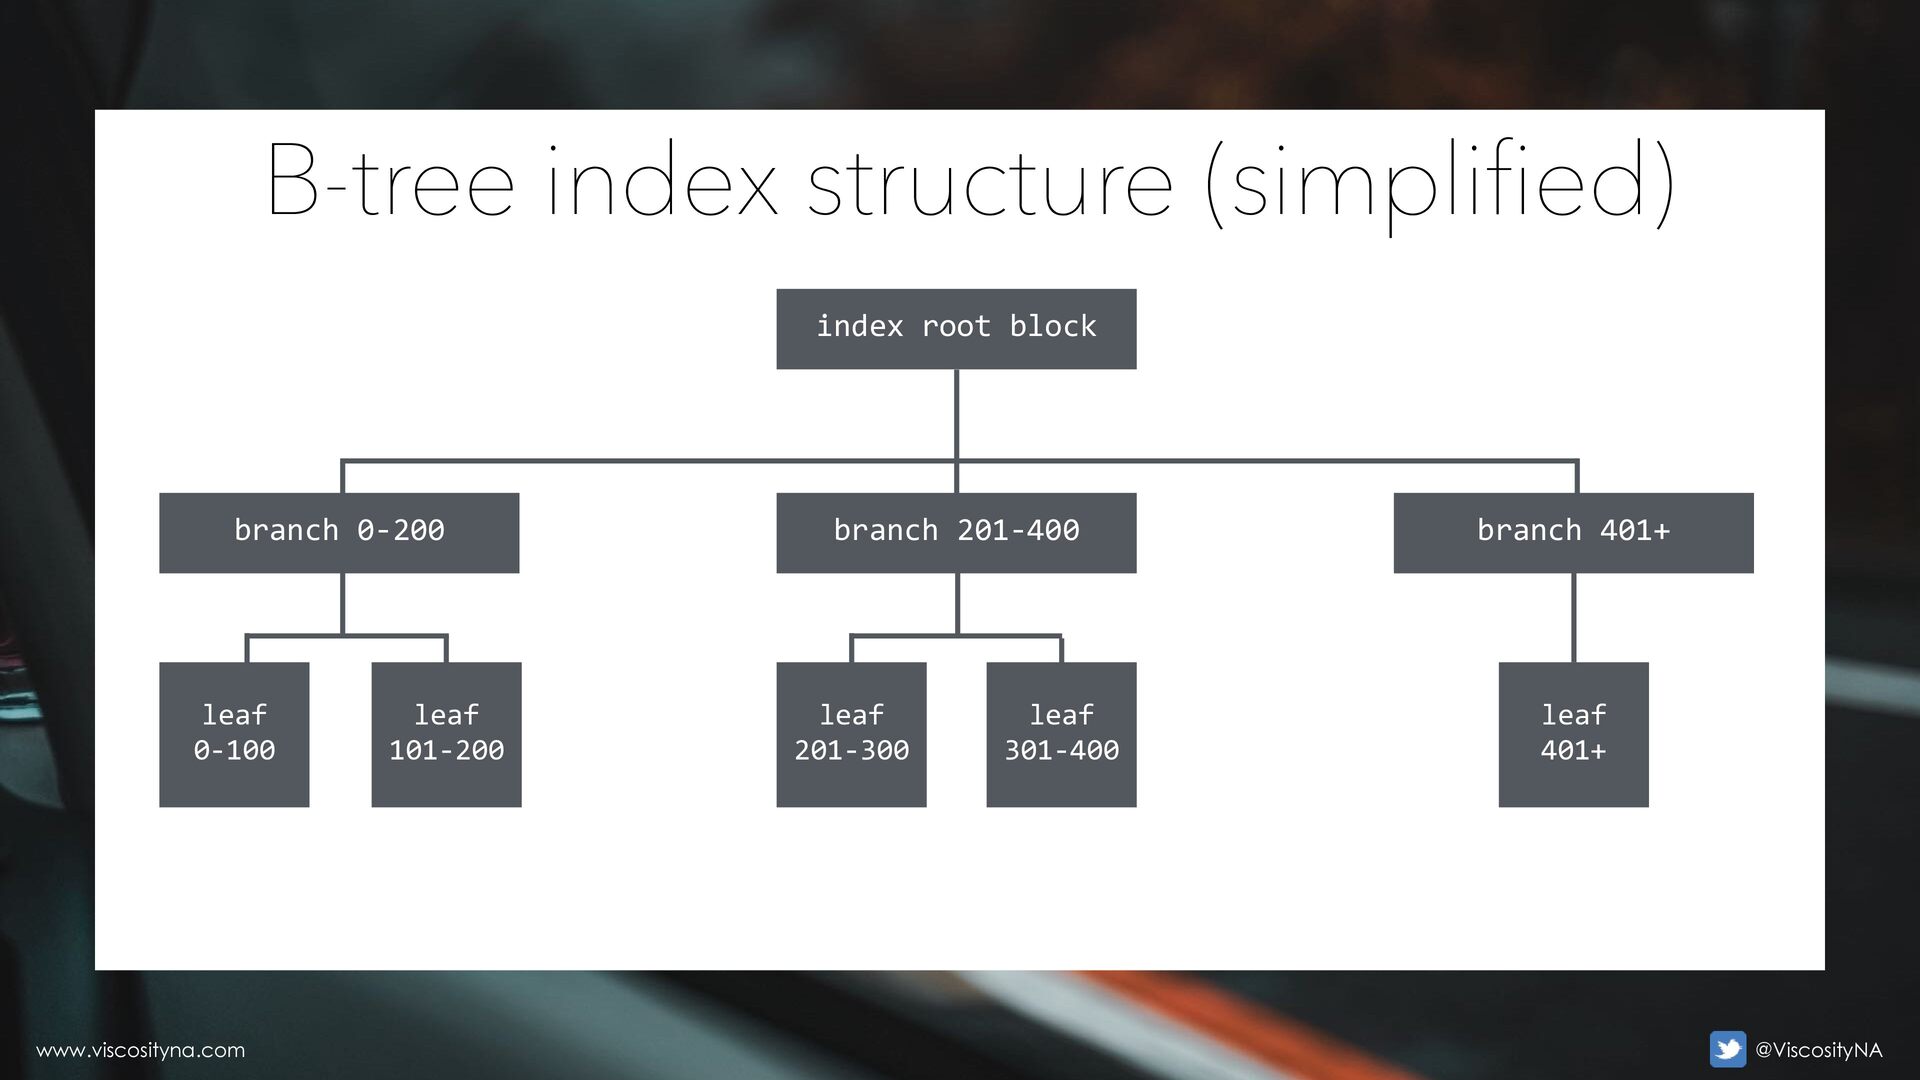
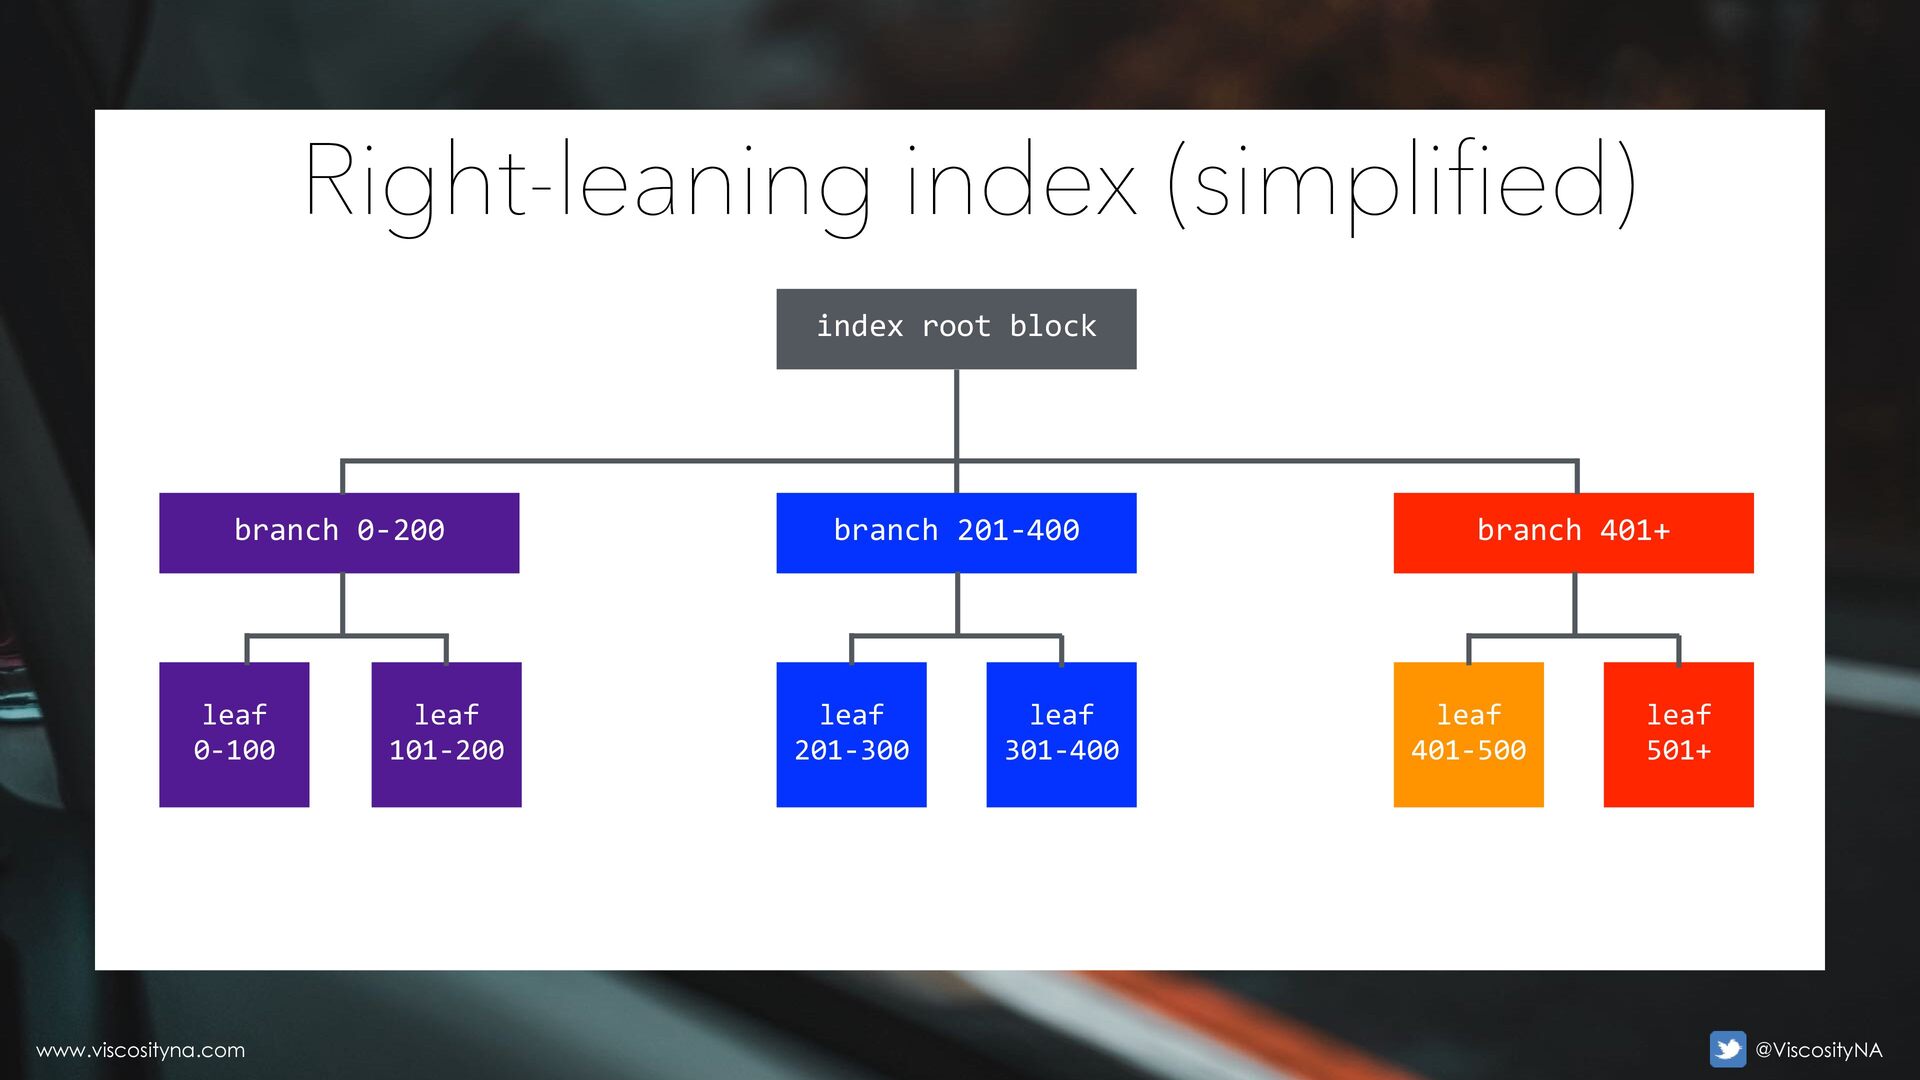
www.viscosityna.com @ViscosityNA B-tree index structure (simplified) branch 201-400 branch 0-200
branch 401+ leaf 0-100 leaf 101-200 leaf 201-300 leaf 301-400 leaf 401+ index root block www.viscosityna.com @ViscosityNA -
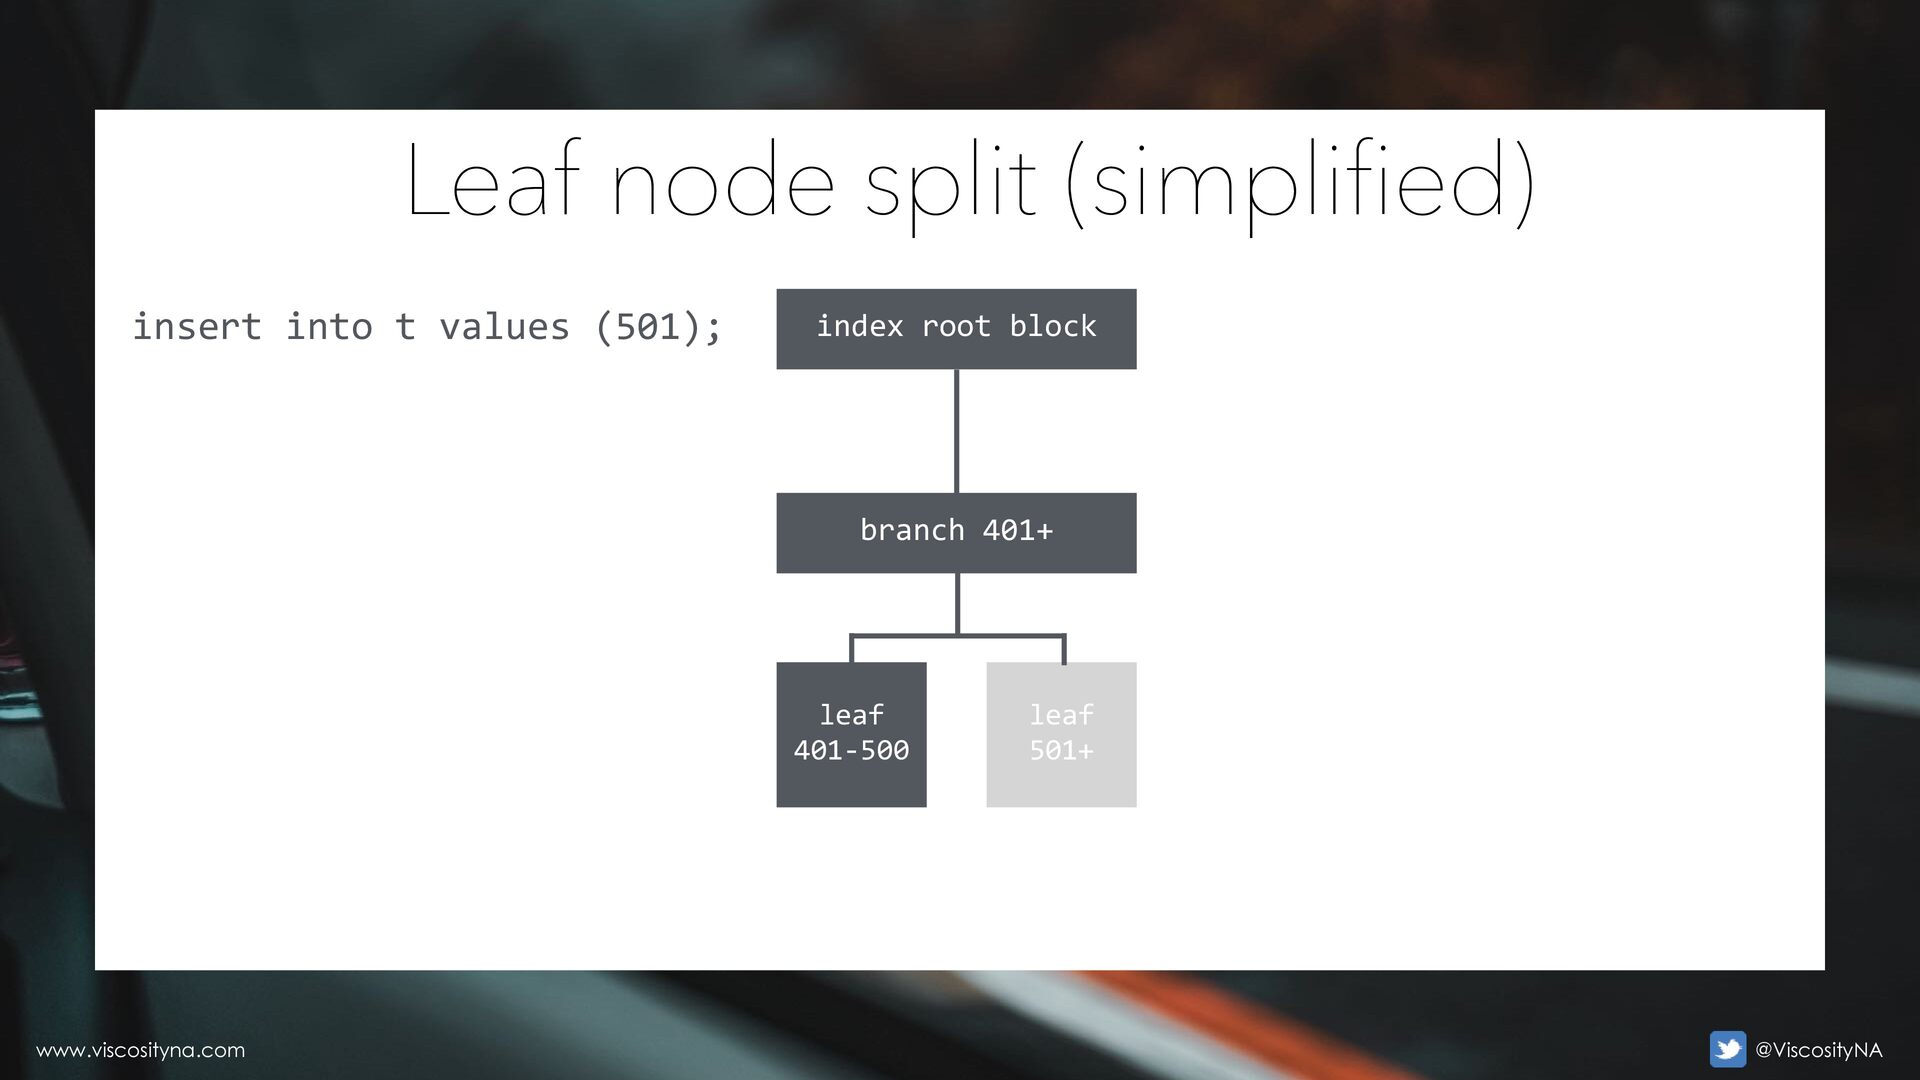
www.viscosityna.com @ViscosityNA Leaf node split (simplified) branch 401+ leaf 401-500
leaf 501+ index root block insert into t values (501); www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA Right-leaning index (simplified) branch 401+ leaf 401-500 leaf
501+ index root block Session 1 insert into t values (501); Session 2 insert into t values (502); Session 3 insert into t values (503); Session x insert into t values (5nn); • • • www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA Right-leaning index (simplified) branch 201-400 branch 0-200 branch
401+ leaf 0-100 leaf 101-200 leaf 201-300 leaf 301-400 index root block leaf 401-500 leaf 501+ www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Contention caused by multiple values with identical
pre fi • Reverse key distributes similar values across multiple blocks • 1001 remains 1001, goes to leaf 1000+ • 1002 becomes 2001, goes to leaf 2000+ • 1005 becomes 5001, goes to leaf 5000+, etc. • Equivalent to hash partitioning over 10 buckets (for numeric values) Reverse keys for right-leaning values www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Indexes with frequent updates/deletes • Index pre
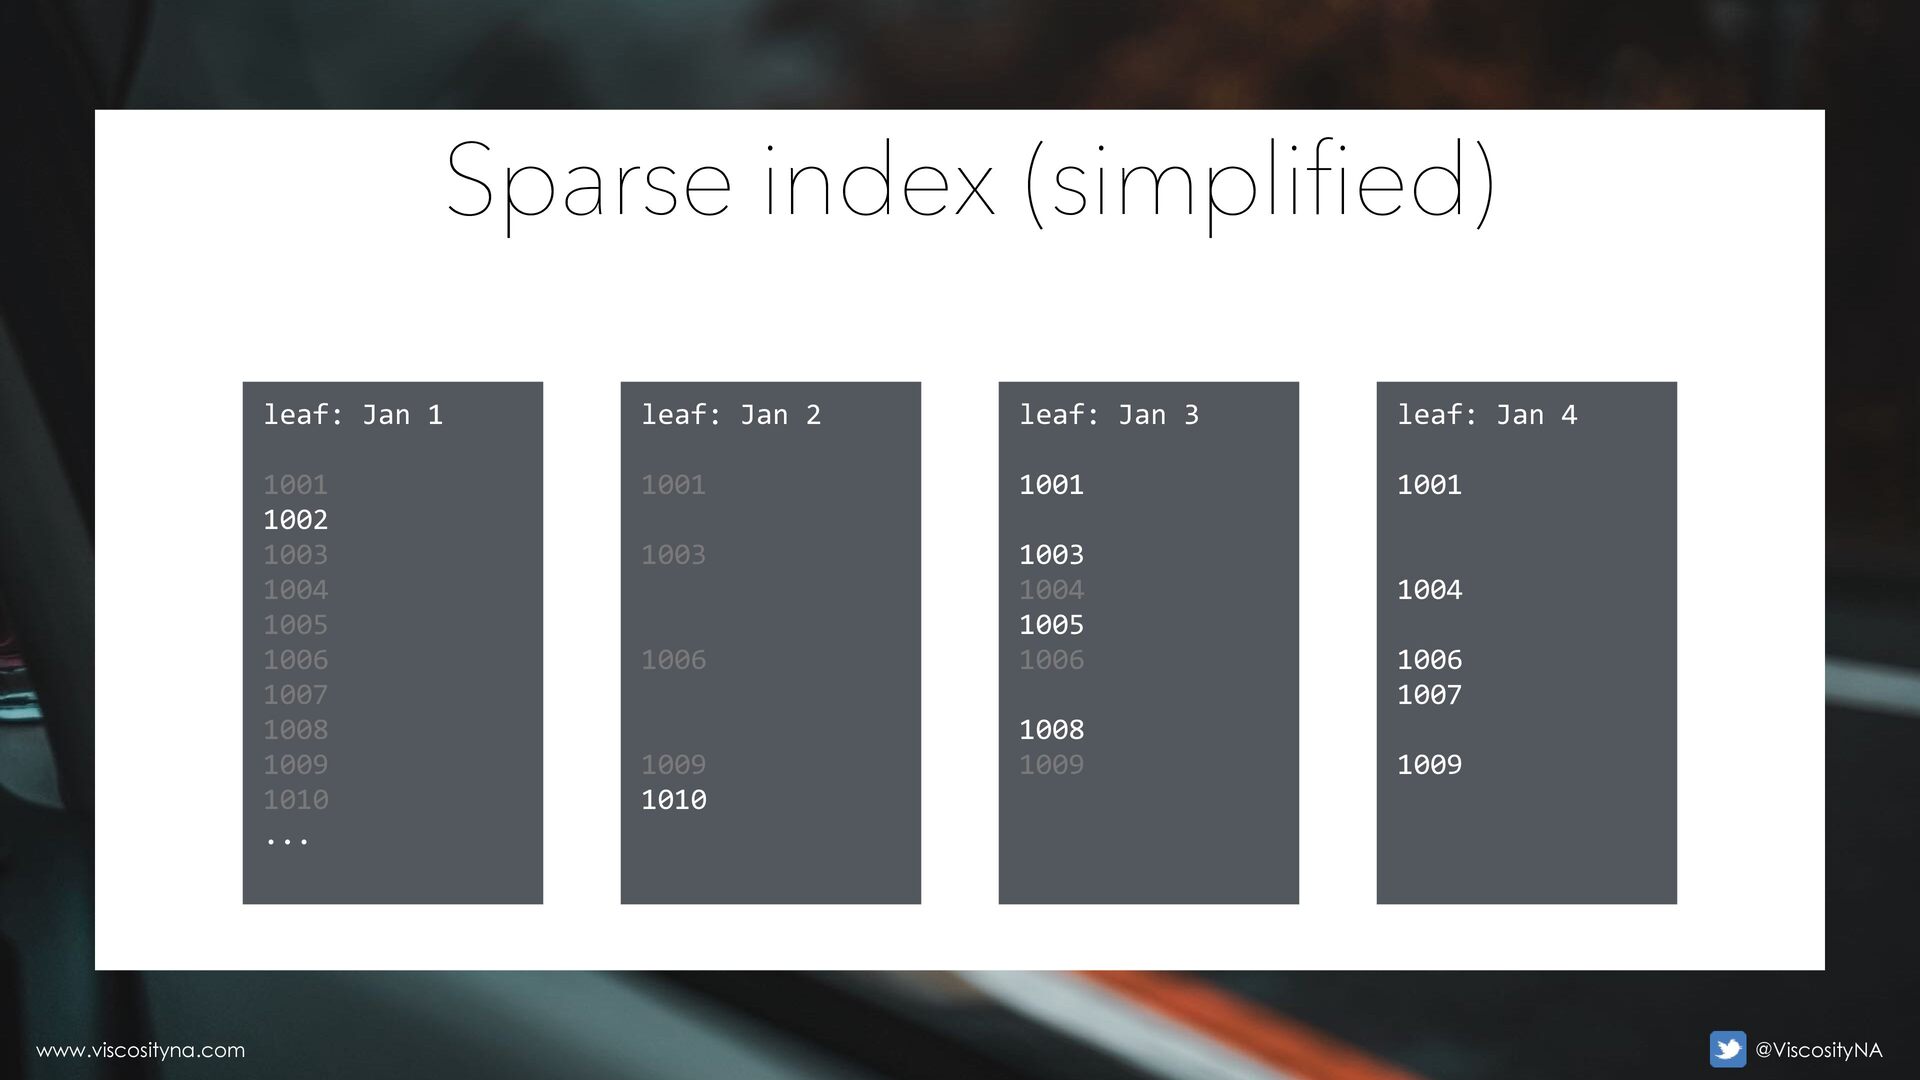
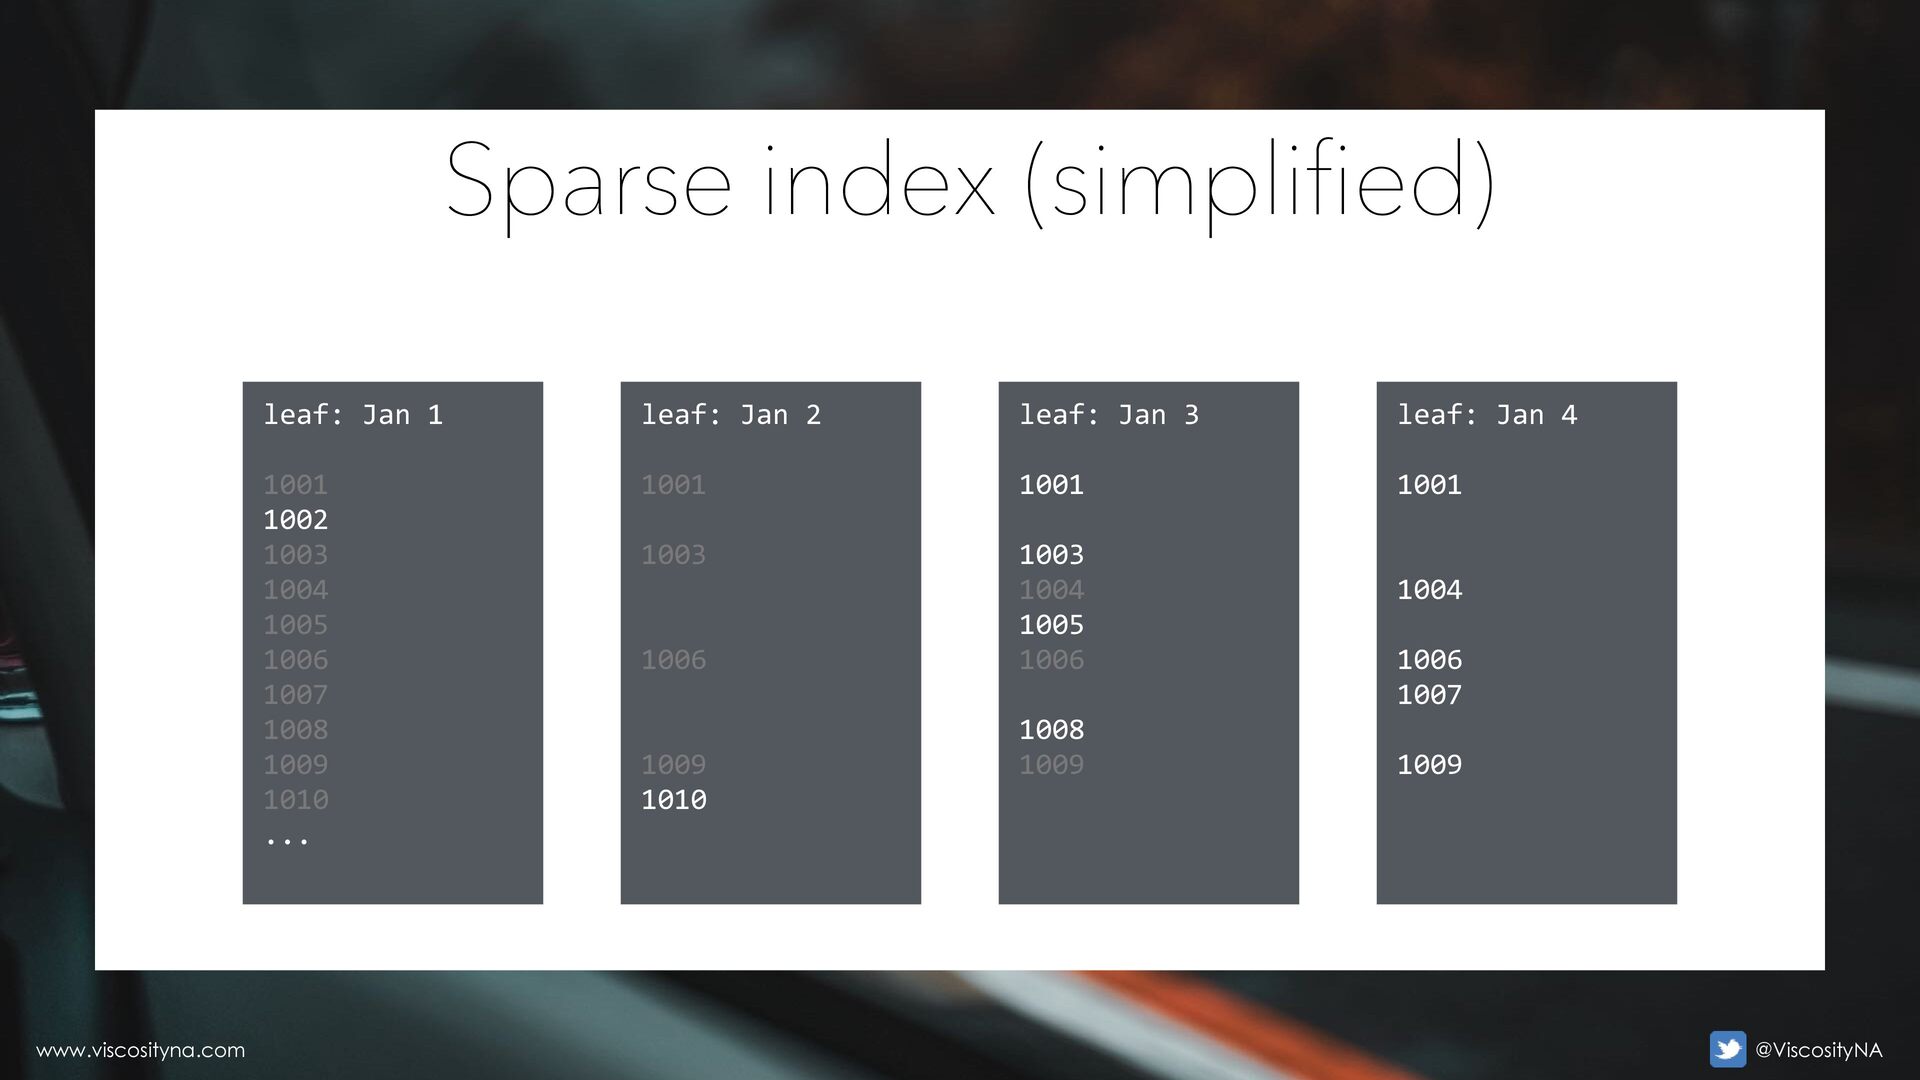
fi • New values "move to the right" • Old values "empty from the left" • Think claims processing with index on last_updated_date • Updates remove the old value; new value goes to the right • Space where "old" value was isn't reused (can't update to the past) Sparse (fragmented) indexes www.viscosityna.com @ViscosityNA -
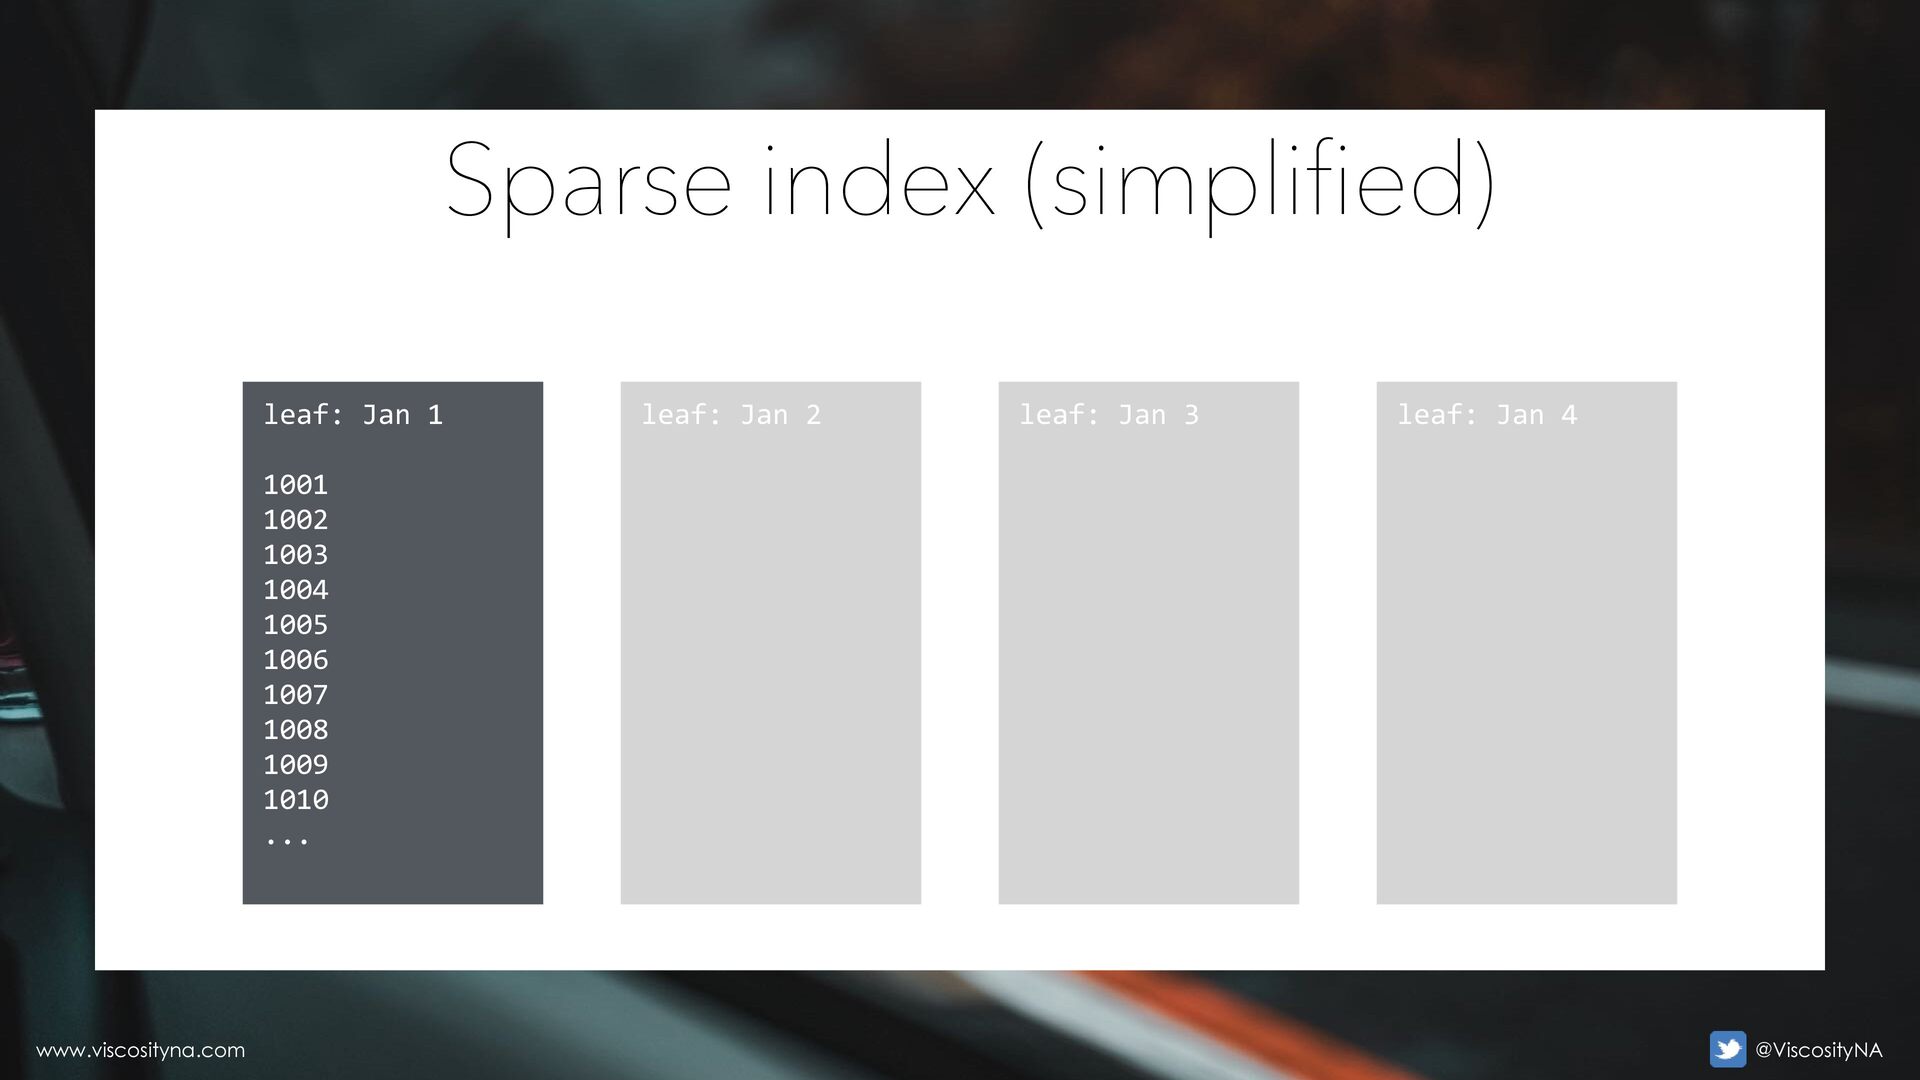
www.viscosityna.com @ViscosityNA Sparse index (simplified) leaf: Jan 1 1001 1002
1003 1004 1005 1006 1007 1008 1009 1010 ... leaf: Jan 2 leaf: Jan 3 leaf: Jan 4 www.viscosityna.com @ViscosityNA -
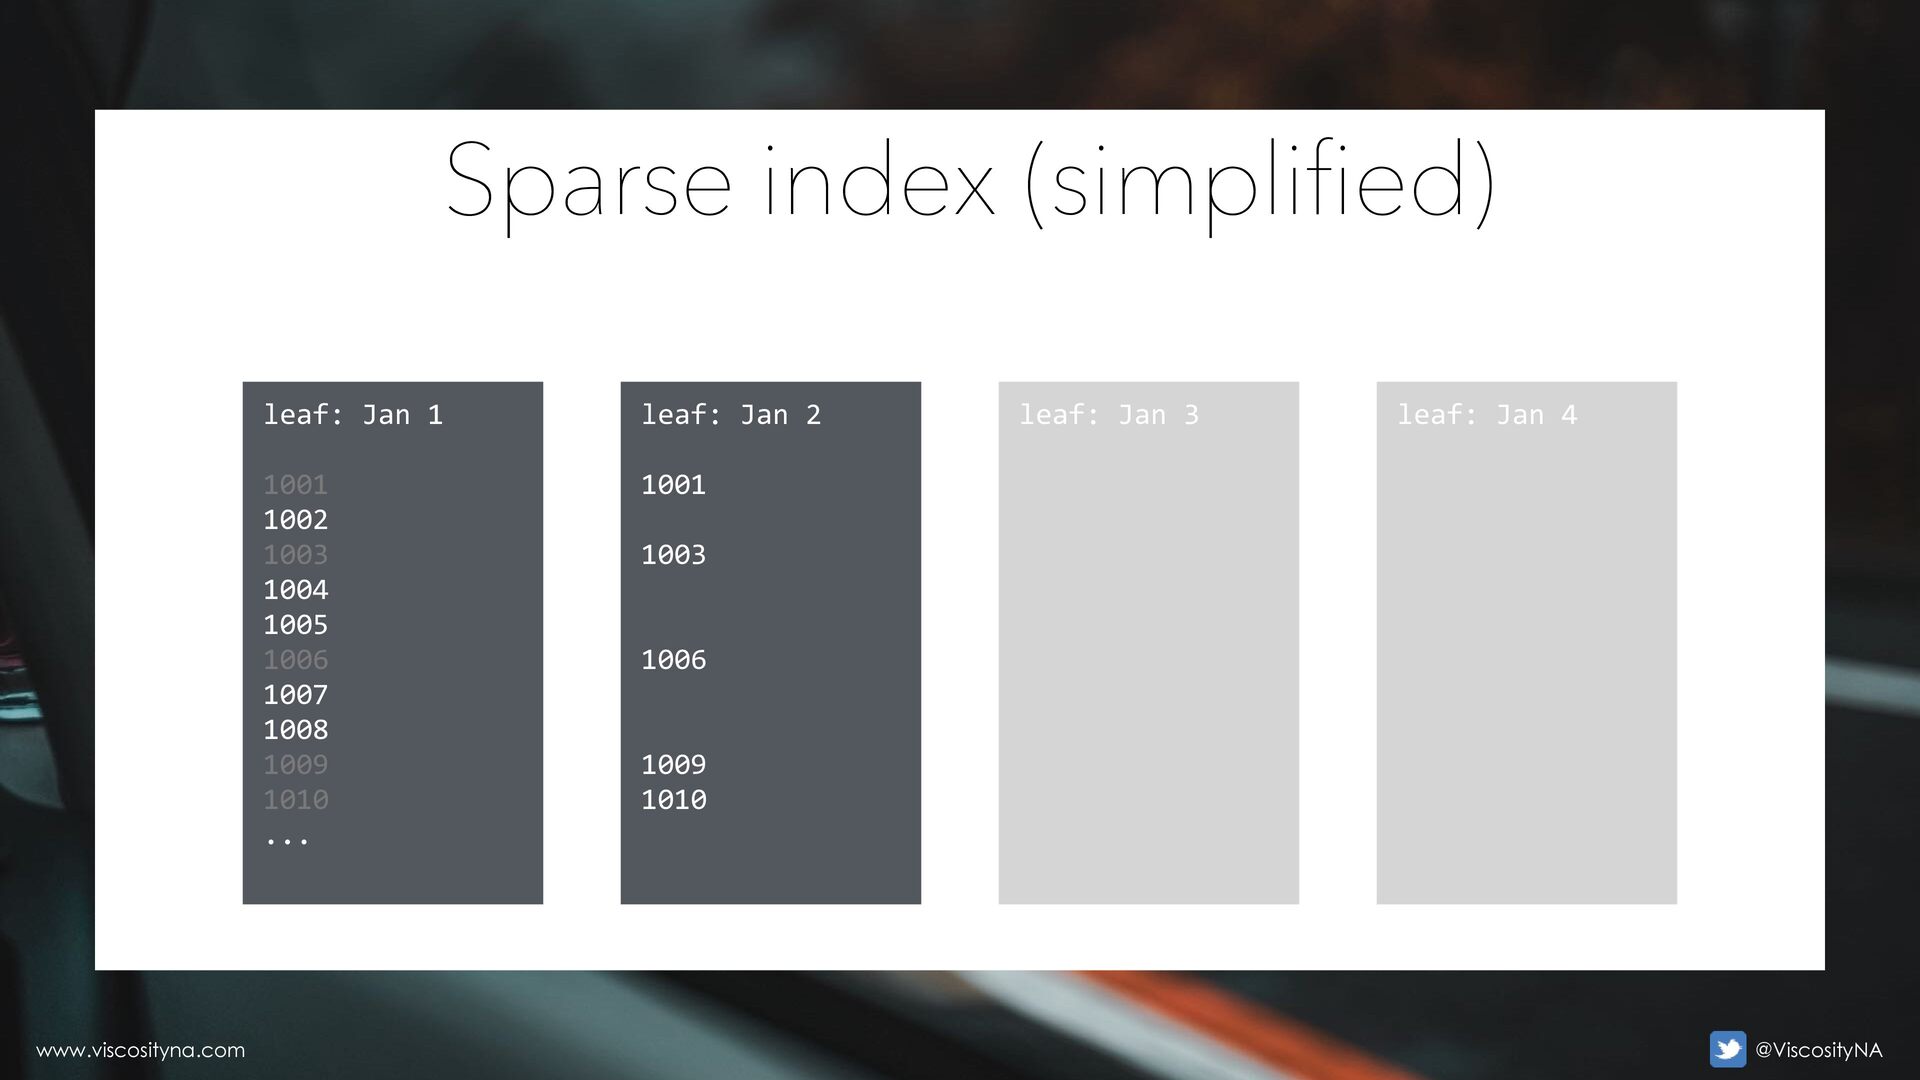
www.viscosityna.com @ViscosityNA Sparse index (simplified) leaf: Jan 1 1001 1002
1003 1004 1005 1006 1007 1008 1009 1010 ... leaf: Jan 2 1001 1003 1006 1009 1010 leaf: Jan 3 leaf: Jan 4 www.viscosityna.com @ViscosityNA -
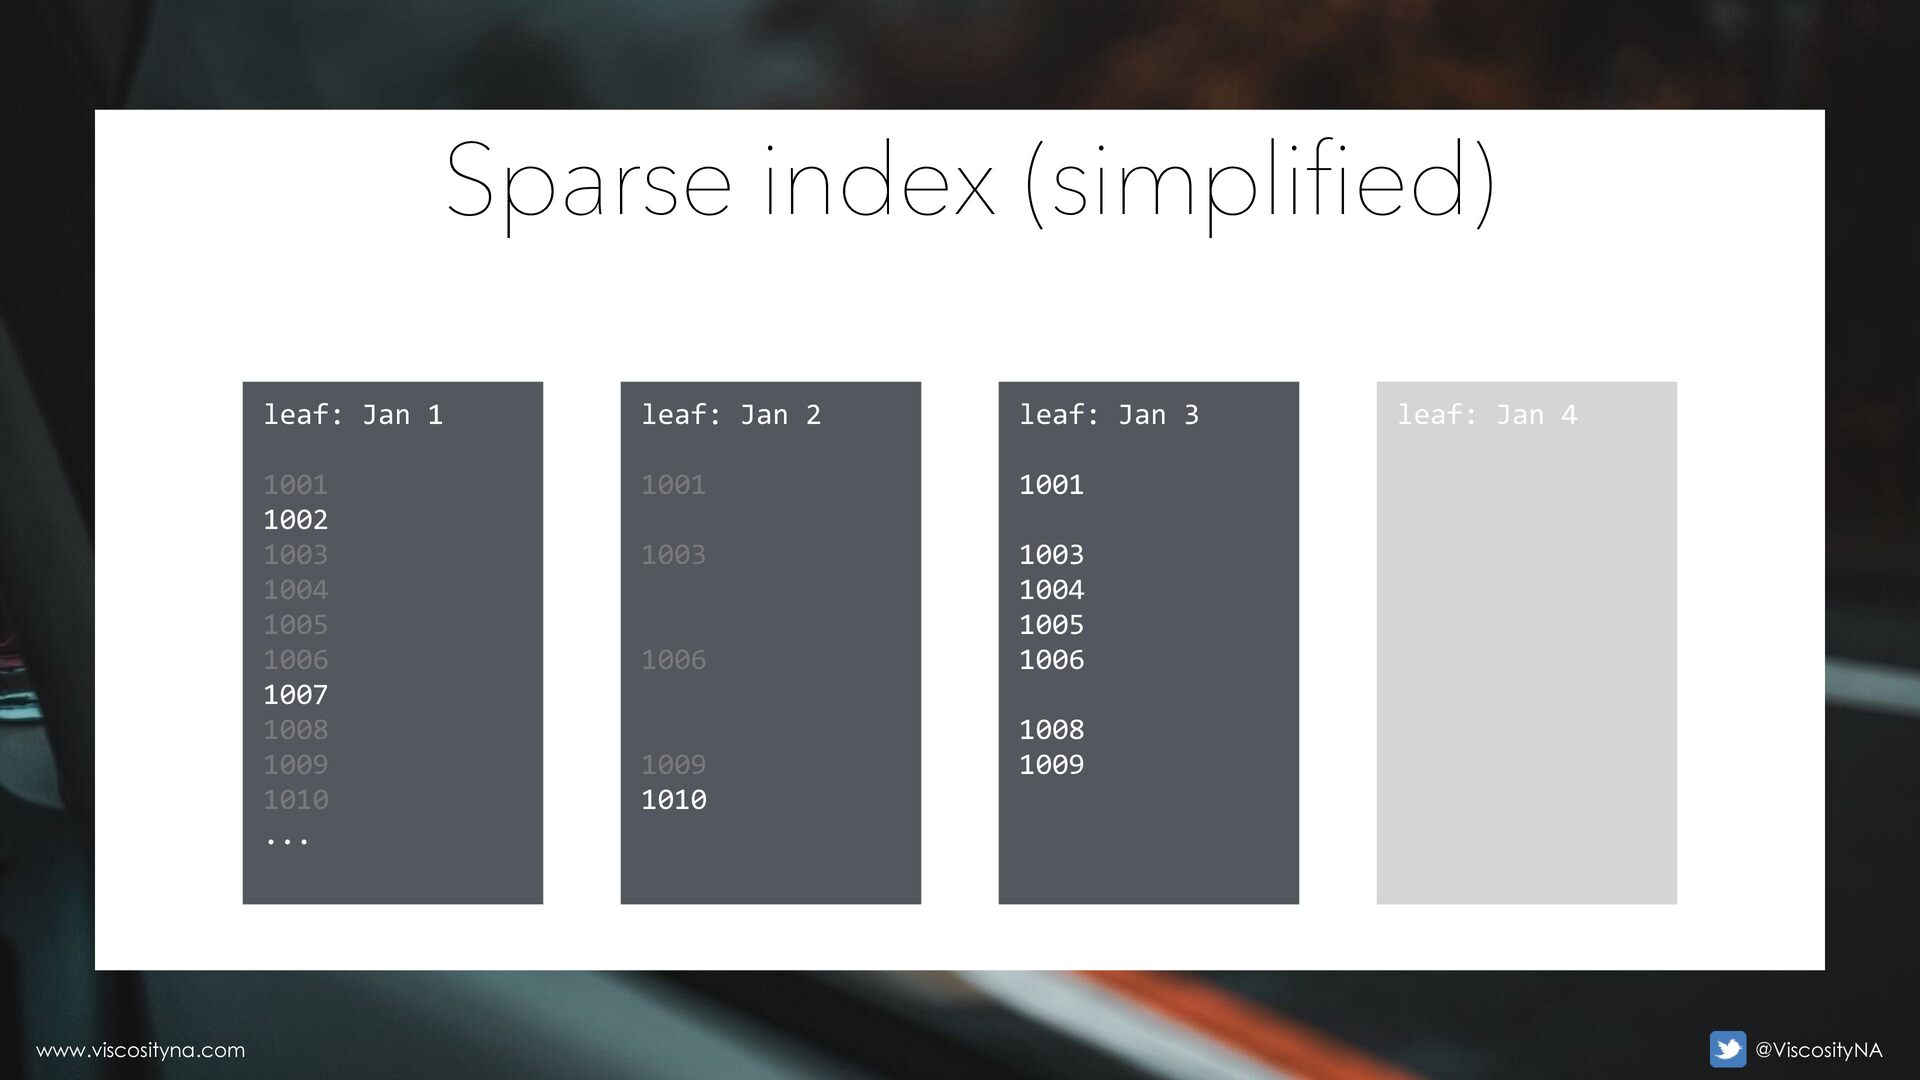
www.viscosityna.com @ViscosityNA Sparse index (simplified) leaf: Jan 2 1001 1003
1006 1009 1010 leaf: Jan 3 1001 1003 1004 1005 1006 1008 1009 leaf: Jan 4 leaf: Jan 1 1001 1002 1003 1004 1005 1006 1007 1008 1009 1010 ... www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA Sparse index (simplified) leaf: Jan 2 1001 1003
1006 1009 1010 leaf: Jan 3 1001 1003 1004 1005 1006 1008 1009 leaf: Jan 4 1001 1004 1006 1007 1009 leaf: Jan 1 1001 1002 1003 1004 1005 1006 1007 1008 1009 1010 ... www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA Sparse index (simplified) leaf: Jan 2 1001 1003
1006 1009 1010 leaf: Jan 3 1001 1003 1004 1005 1006 1008 1009 leaf: Jan 4 1001 1004 1006 1007 1009 leaf: Jan 1 1001 1002 1003 1004 1005 1006 1007 1008 1009 1010 ... www.viscosityna.com @ViscosityNA -
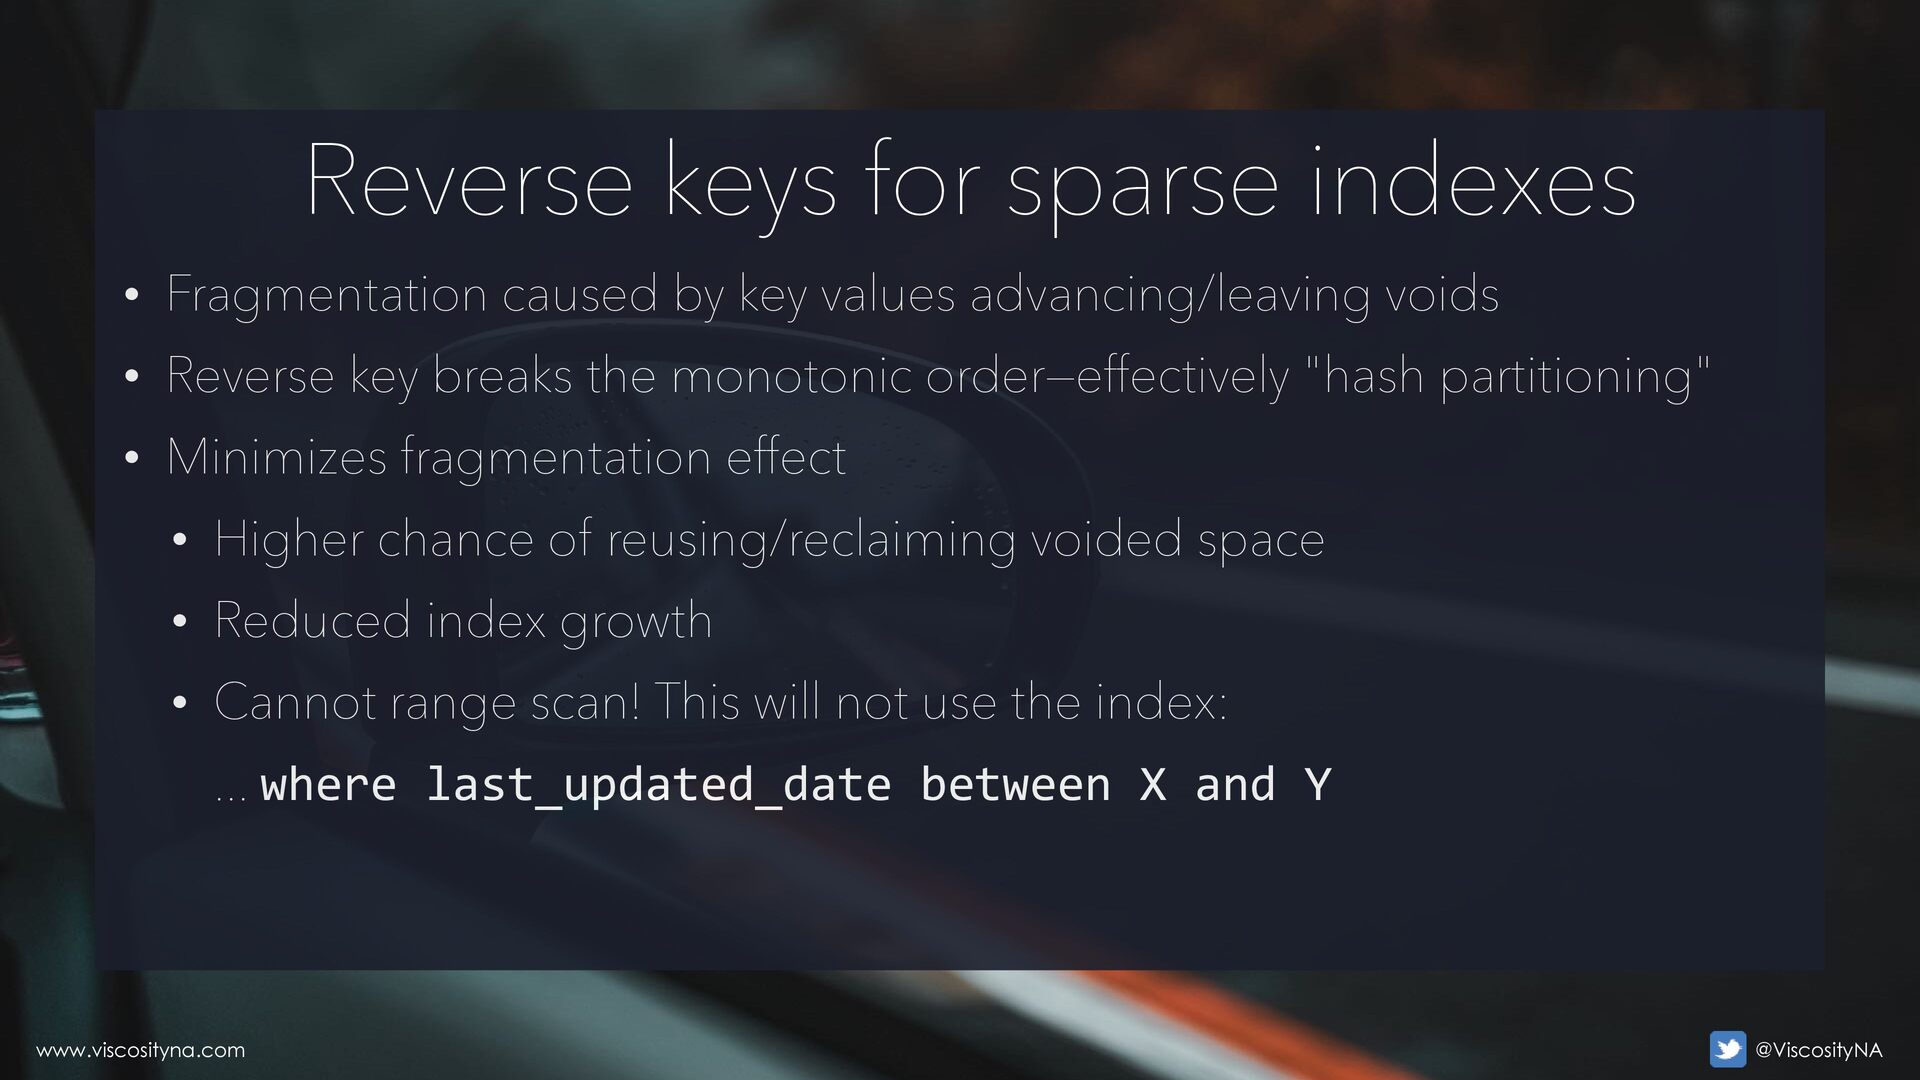
www.viscosityna.com @ViscosityNA • Fragmentation caused by key values advancing/leaving voids
• Reverse key breaks the monotonic order—effectively "hash partitioning" • Minimizes fragmentation effect • Higher chance of reusing/reclaiming voided space • Reduced index growth • Cannot range scan! This will not use the index: ... where Reverse keys for sparse indexes www.viscosityna.com @ViscosityNA -
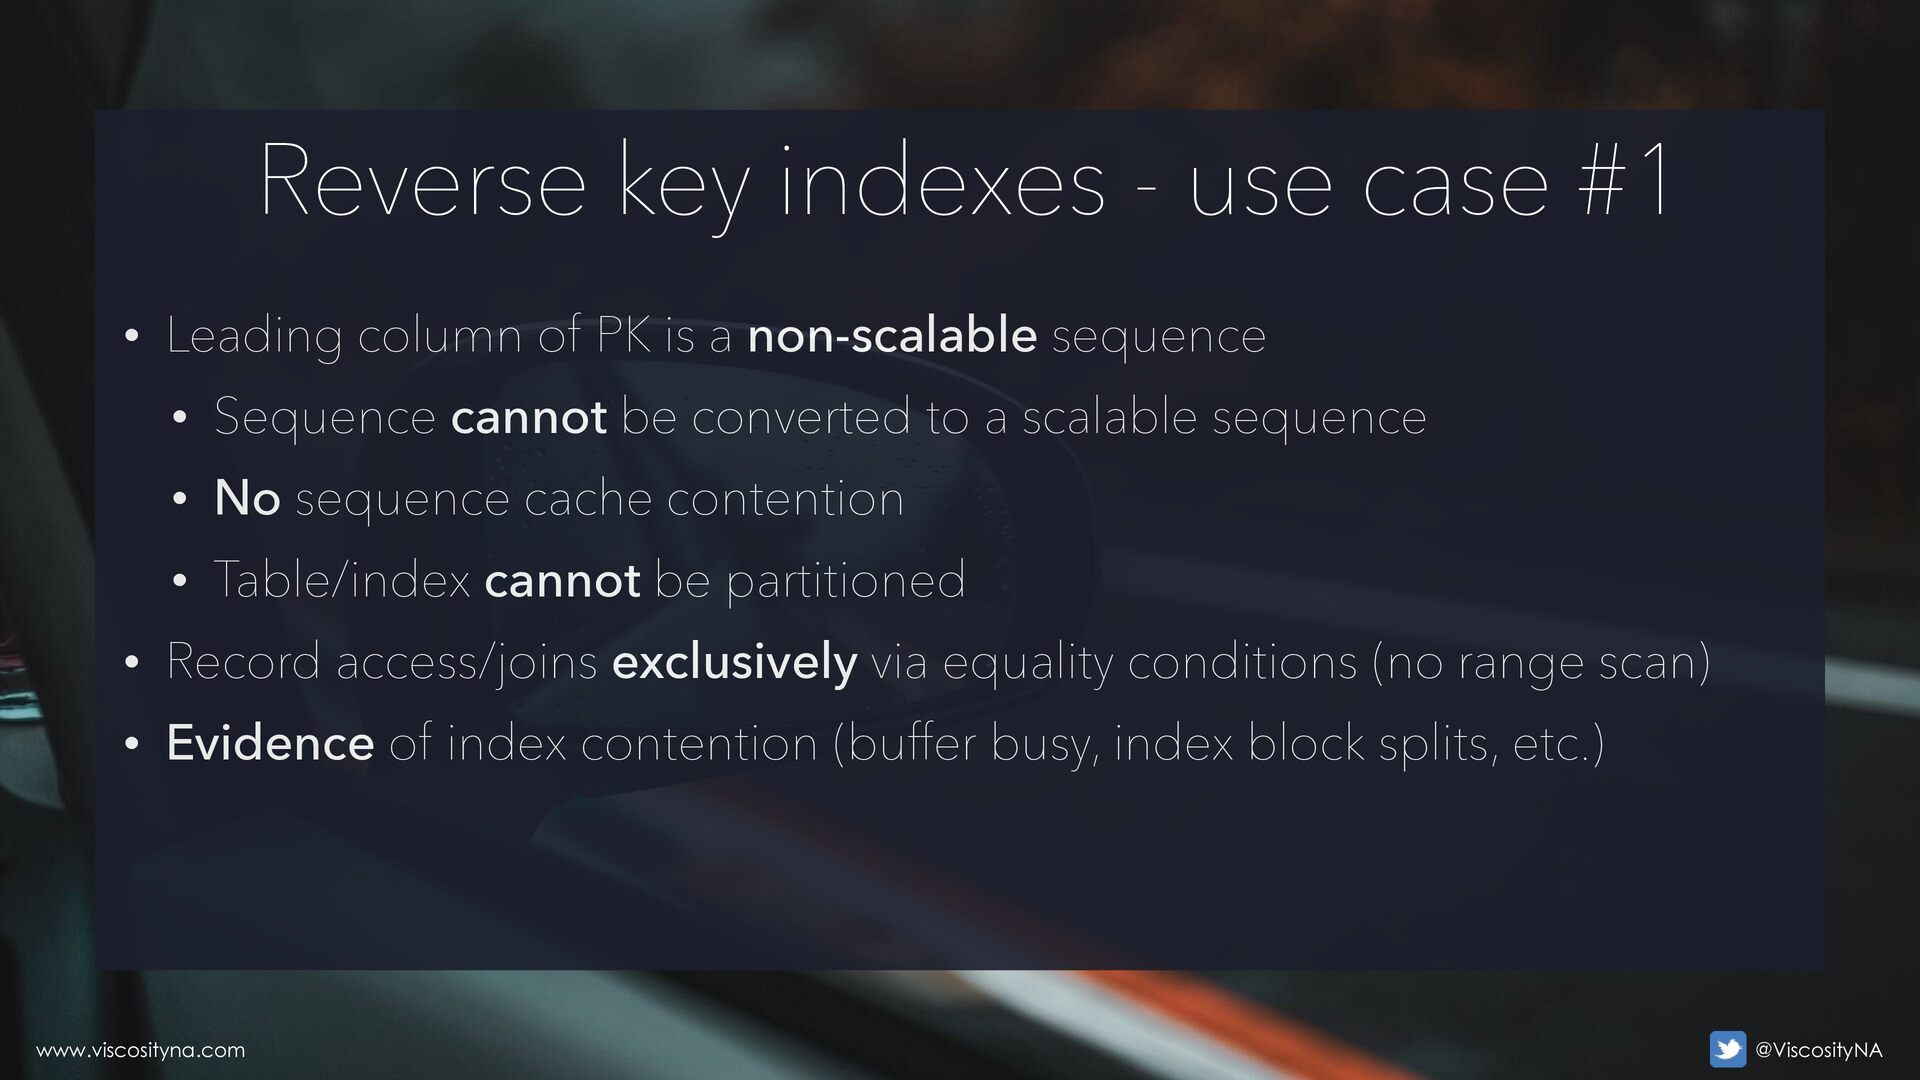
www.viscosityna.com @ViscosityNA • Leading column of PK is a non-scalable
sequence • Sequence cannot be converted to a scalable sequence • No sequence cache contention • Table/index cannot be partitioned • Record access/joins exclusively via equality conditions (no range scan) • Evidence of index contention (buffer busy, index block splits, etc.) Reverse key indexes - use case #1 www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Leading column of UK is a non-scalable
sequence, number, or date • If a sequence, it cannot be converted to a scalable sequence • No sequence cache contention • If number or date, the values advance monotonically and aren't reused • The leading column is updated frequently to a larger/later value • Table/index cannot be partitioned • Record access exclusively via equality condition on the key (no range scan) • The index is heavily fragmented Reverse key indexes - use case #2 www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Sequences are typically monotonically increasing numeric value
• Often used as surrogate keys to guarantee uniqueness • Calculating new values is expensive, especially when concurrency is high • Oracle computes a block of sequence values and caches them • The sequence cache size = how many sequences are created at once Sequence cache www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • A small sequence cache means more frequent
sequence calculation • Calculating the next sequence block requires a lock on the sequence • A busy sequence is more likely to cause concurrency issues • In RAC, a single node locks all others out of the sequence Sequence cache www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • "Why not just generate a huge sequence
cache?" • Sequence cache is per-instance on RAC • Instance failure/restart = loss of unused/cached sequences • Causes sequence gaps and arti fi Sequence cache www.viscosityna.com @ViscosityNA -
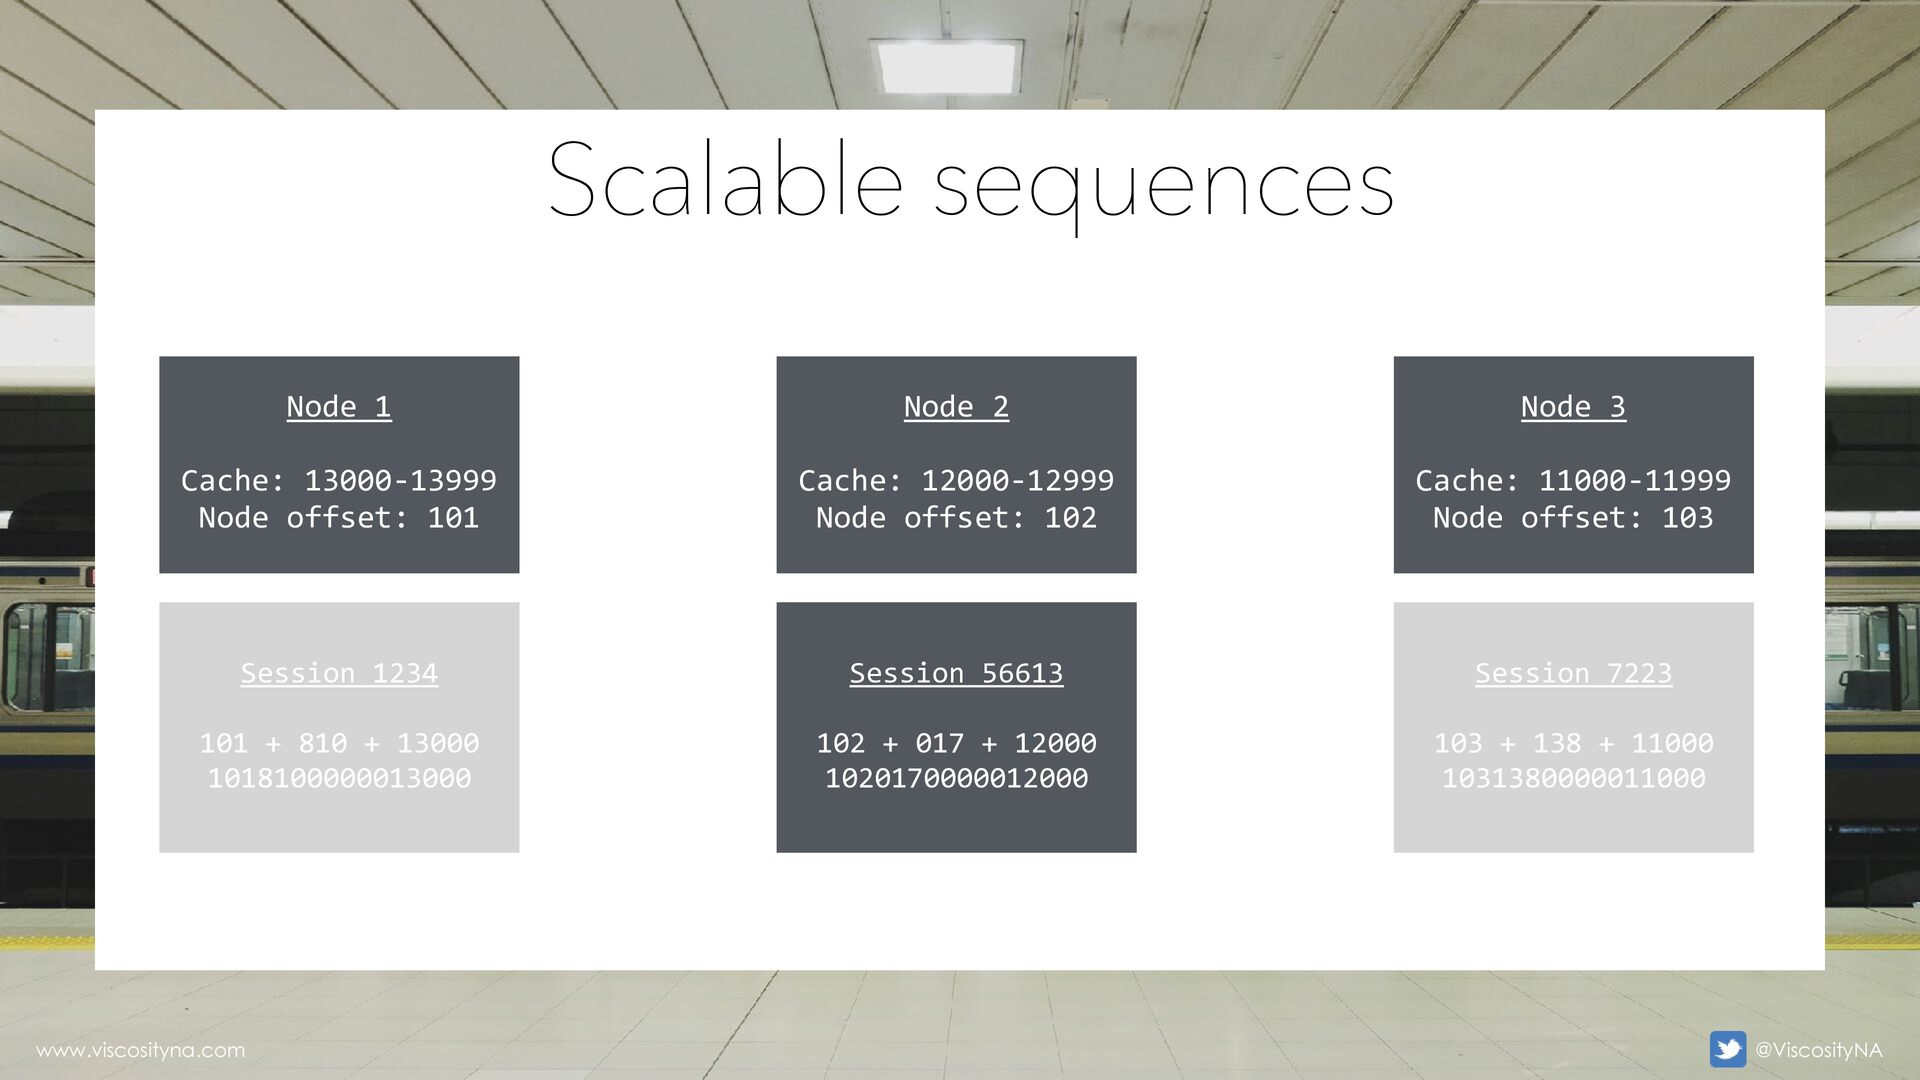
www.viscosityna.com @ViscosityNA • Available from 18c onward • Adds a
(default) 6-digit pre fi • Pre fi • Sequence component is padded w/0 to keep a consistent length • The pre fi Scalable sequences www.viscosityna.com @ViscosityNA -
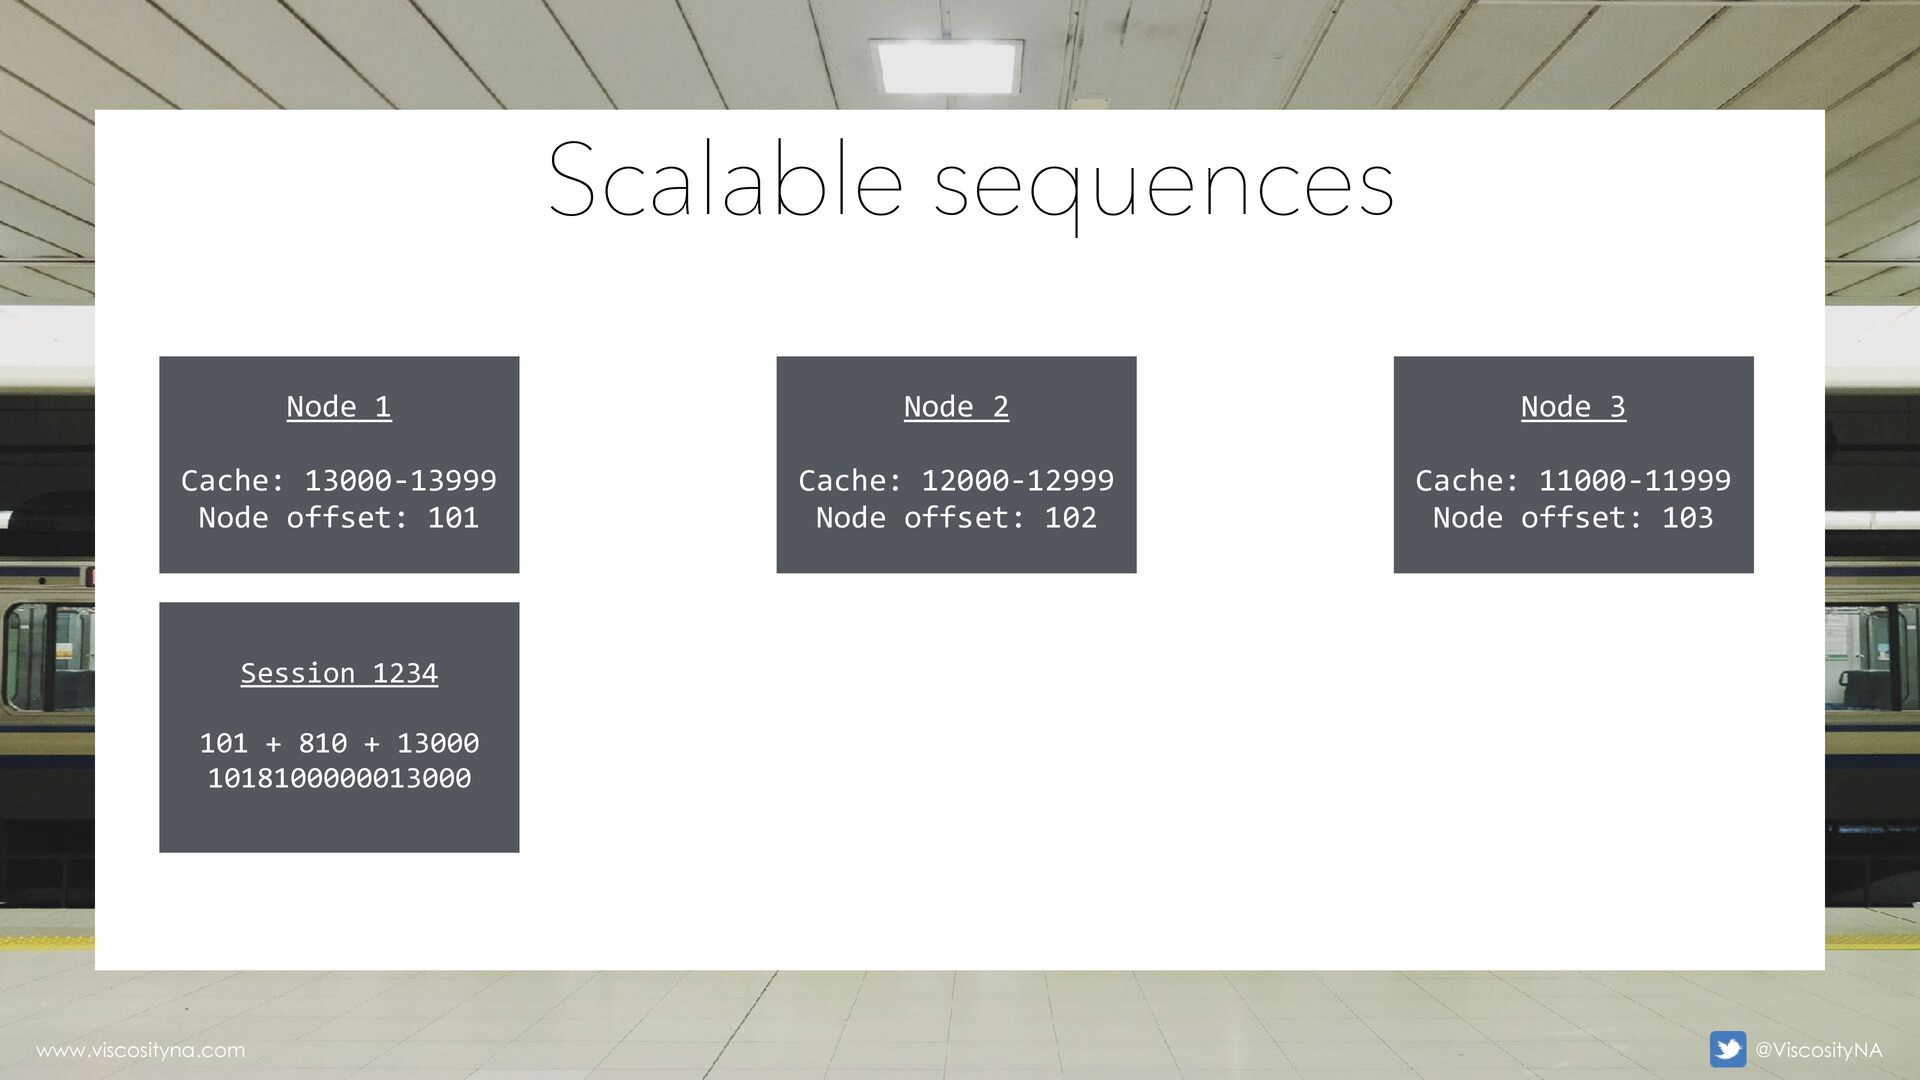
www.viscosityna.com @ViscosityNA Scalable sequences Node 2 Cache: 12000-12999 Node offset:
102 Node 1 Cache: 13000-13999 Node offset: 101 Node 3 Cache: 11000-11999 Node offset: 103 Session 1234 101 + 810 + 13000 1018100000013000 www.viscosityna.com @ViscosityNA -
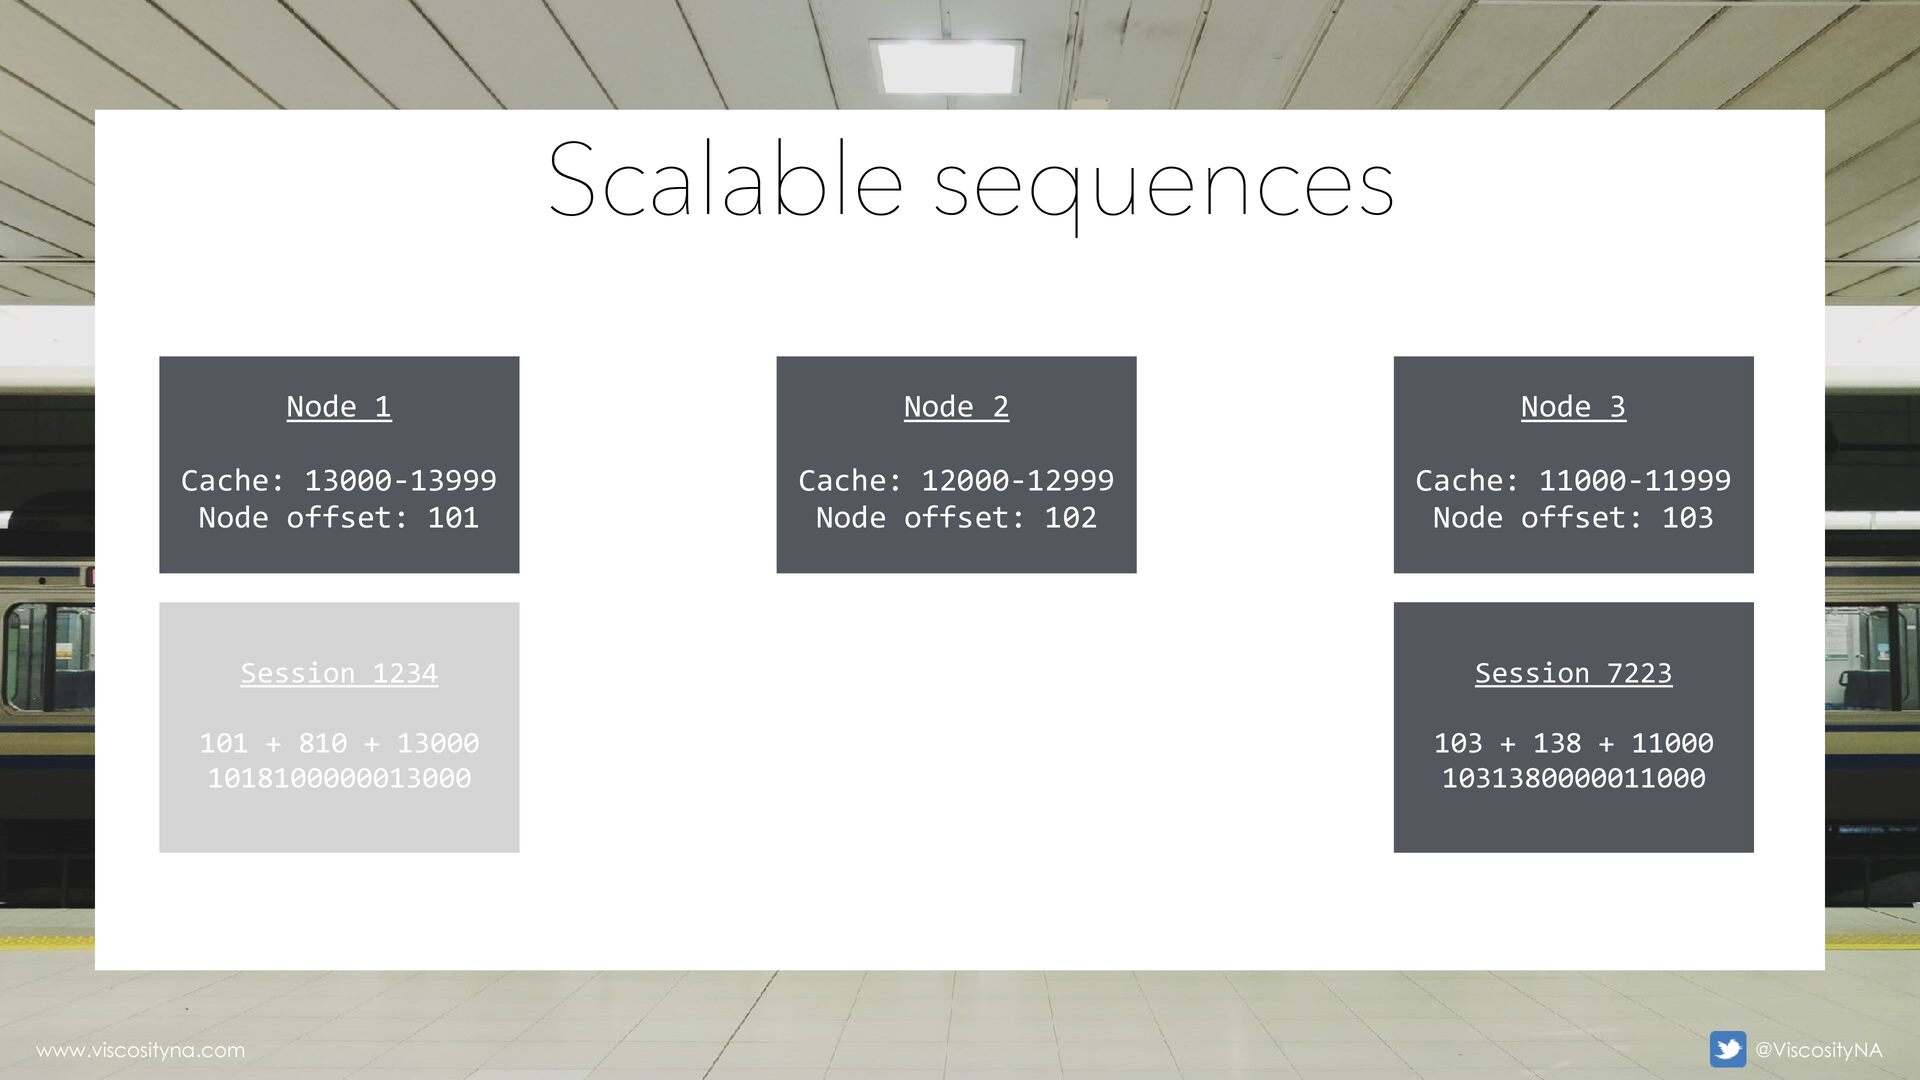
www.viscosityna.com @ViscosityNA Scalable sequences Node 2 Cache: 12000-12999 Node offset:
102 Node 1 Cache: 13000-13999 Node offset: 101 Node 3 Cache: 11000-11999 Node offset: 103 Session 1234 101 + 810 + 13000 1018100000013000 Session 7223 103 + 138 + 11000 1031380000011000 www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA Scalable sequences Node 2 Cache: 12000-12999 Node offset:
102 Node 1 Cache: 13000-13999 Node offset: 101 Node 3 Cache: 11000-11999 Node offset: 103 Session 1234 101 + 810 + 13000 1018100000013000 Session 7223 103 + 138 + 11000 1031380000011000 Session 56613 102 + 017 + 12000 1020170000012000 www.viscosityna.com @ViscosityNA -
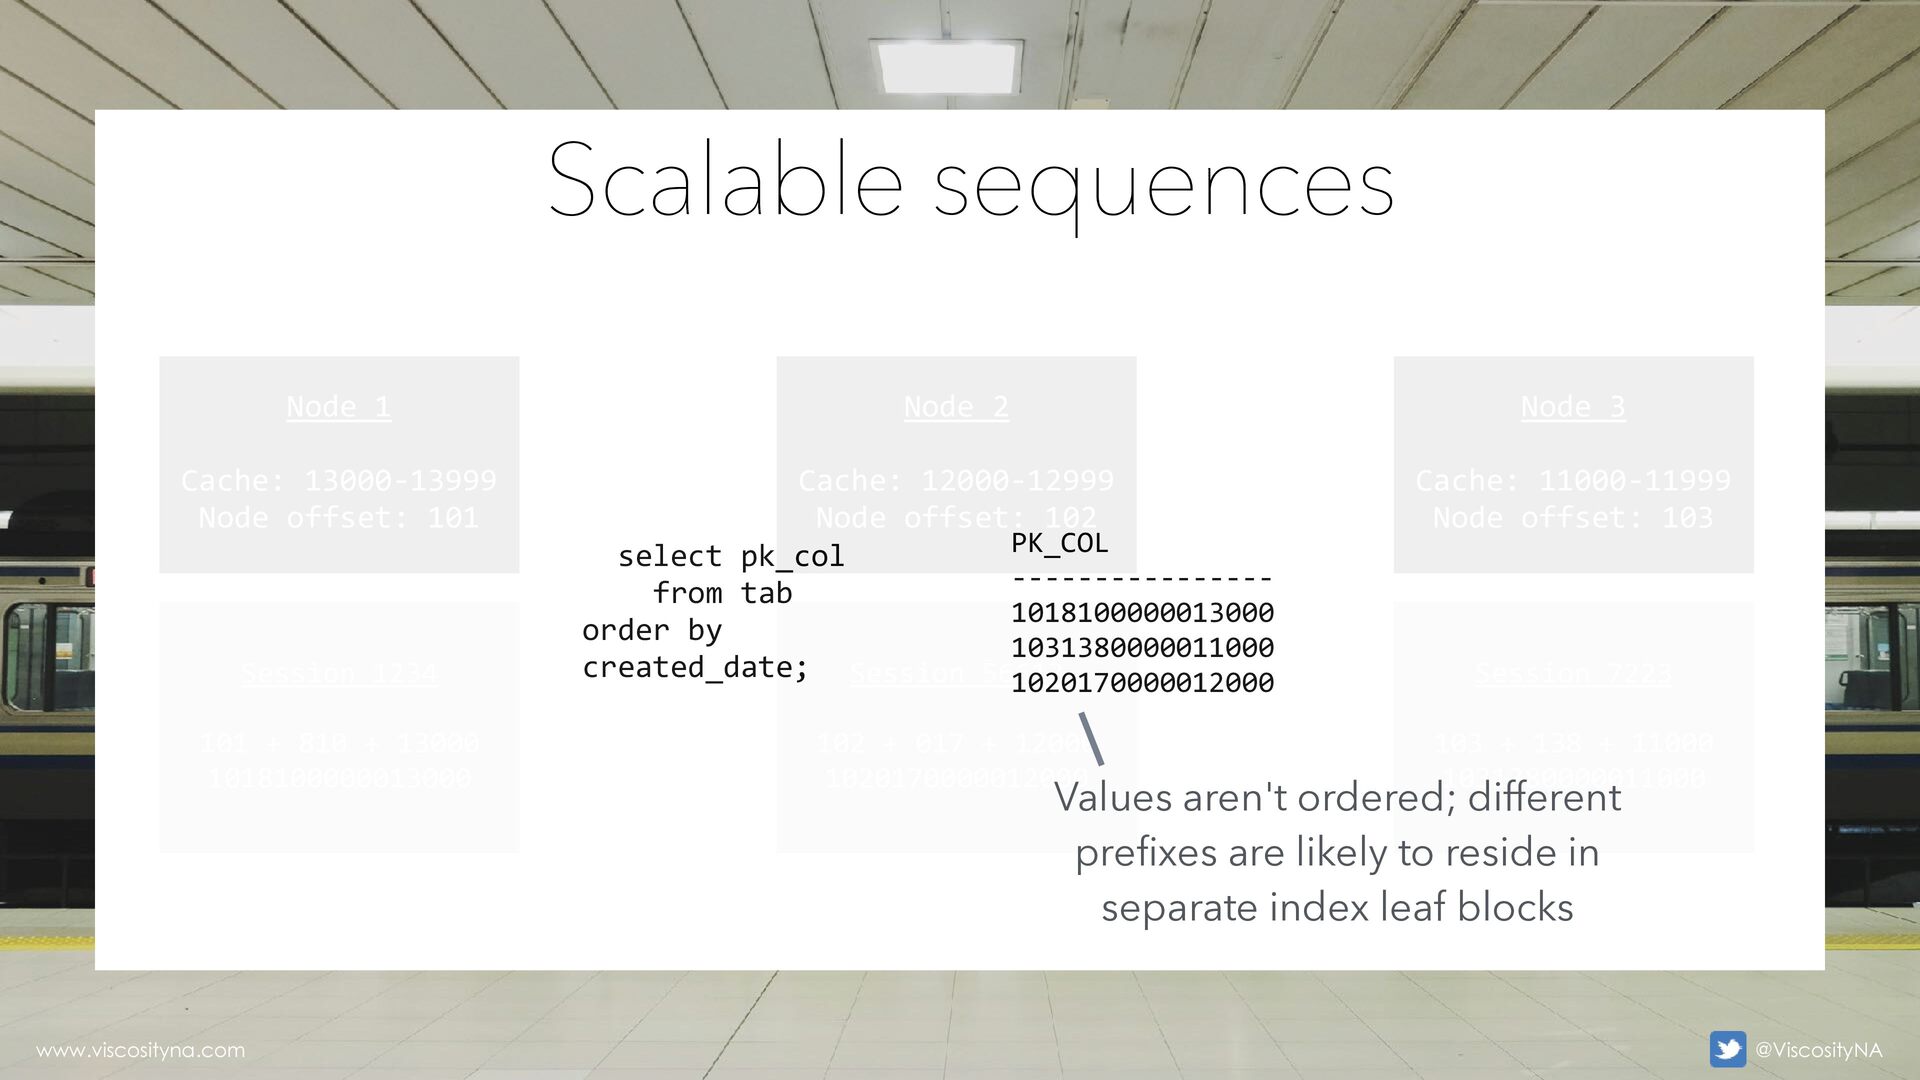
www.viscosityna.com @ViscosityNA Scalable sequences Node 2 Cache: 12000-12999 Node offset:
102 Node 1 Cache: 13000-13999 Node offset: 101 Node 3 Cache: 11000-11999 Node offset: 103 Session 1234 101 + 810 + 13000 1018100000013000 Session 7223 103 + 138 + 11000 1031380000011000 Session 56613 102 + 017 + 12000 1020170000012000 order PK_COL ---------------- 1018100000013000 1031380000011000 1020170000012000 Values aren't ordered; different pre fi xes are likely to reside in separate index leaf blocks www.viscosityna.com @ViscosityNA -
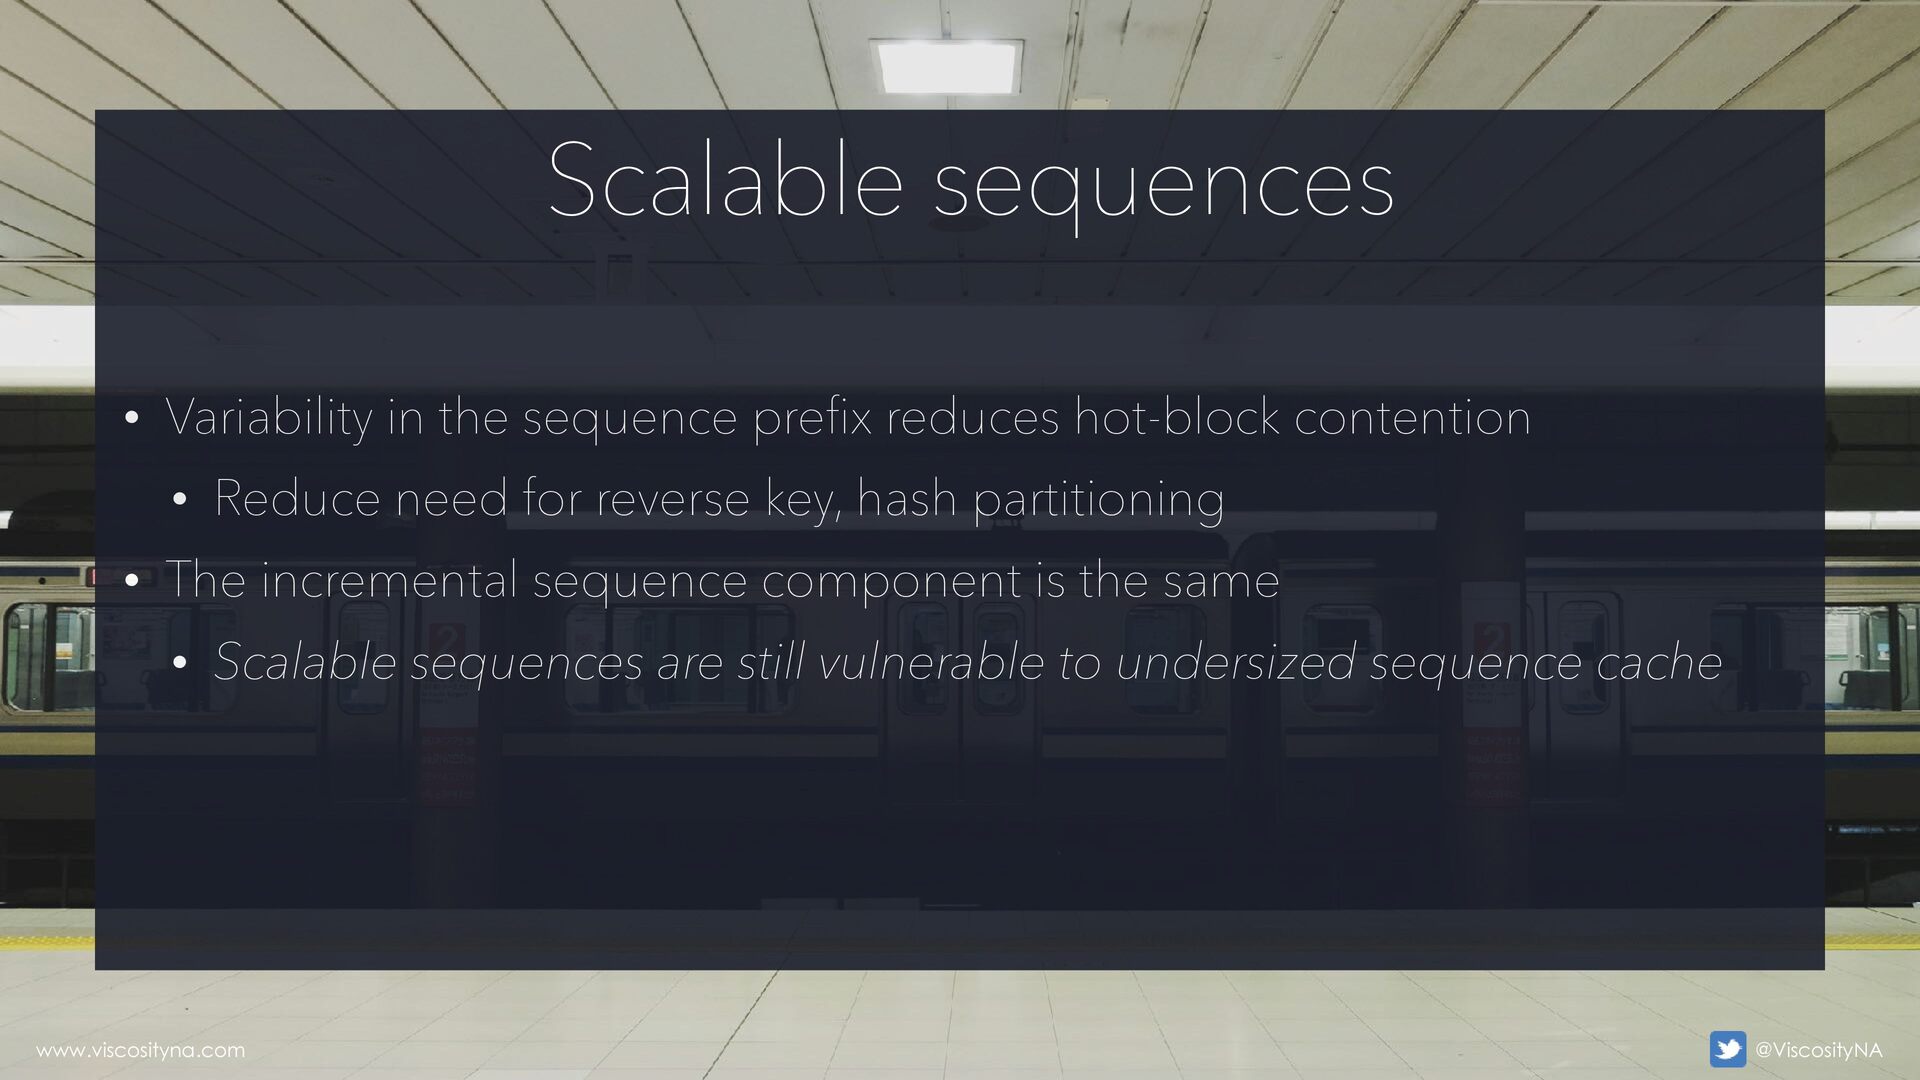
www.viscosityna.com @ViscosityNA • Variability in the sequence pre fi •
Reduce need for reverse key, hash partitioning • The incremental sequence component is the same • Scalable sequences are still vulnerable to undersized sequence cache Scalable sequences www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Concurrency management mechanisms • Serialize access to
resources • Guarantee consistency • Spinlocks: waiters "spin" on CPU • Latch: prone to false contention (one latch controls many objects) • Mutex: precise and faster; part of the object's memory structure Latches and mutexes www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Latch = lock • Managed by the
database • Fully instrumented through Oracle's wait event interface • (Relatively) easy to troubleshoot Latches www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • A latch protects multiple, independent resources •
One to many relationship is prone to false latch contention • Latch count, location, status are always known ($latch, Latches www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Mutex = MUTual EXclusion • Lighter and
more precise than latches • Often implemented directly under hardware = FAST • Dynamic—part of/internal to the object it protects • Not tracked/instrumented individually to reduce overhead Mutexes www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Unlike latches, mutexes are not instrumented comprehensively
• Oracle collects statistics on mutex activity, not individual mutexes • Sleeping is a wait event • Spinning is not a wait—it is registered as CPU time • Mutex sleeps indicate a concurrency problem... ...but not necessarily a database concurrency problem Mutexes www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Mutex issues can arise from interfering/manipulating sequential
processing • Non-database sources of mutex sleeps/concurrency: • Oversubscribed CPU • Bad PL/SQL, deadlocking, triggers • Altering OS process priority • Bugs Mutexes www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Parsing SQL creates a cursor • Hashing
a SQL statement generates a hash value • Cursors are saved in the SGA's (shared) Library Cache • The Library Cache is organized as a hash tree • The SQL hash value is the cursor's address in the Library Cache What is a cursor? www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • High CPU cost • Performs syntax, semantic,
permission checks • Evaluates access paths, performs cost-based optimization • Creates an executable version of the cursor (think: compiled) Parsing: Hard Parse www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Hard parsing creates two objects in the
Library Cache: • The parent cursor with static/de fi • A child cursor of dynamic metadata (e.g. variables/bind values) Parsing: Hard Parse www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Hard parsing is expensive • Identical SQL
always gets the same hash • BUT... queries with different variables are not identical! Cursor Sharing and Soft Parsing www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Bind variables allow identical SQL with different
metadata • Bind variables in the SQL text produce identical SQL hashes • Saves space in the Library Cache • Reduces impact of hard parsing • Soft parsing evaluates bind values • Oracle reuses the existing execution plan if possible Cursor Sharing and Soft Parsing www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • SQL w/different bind values may bene fi
• The SQL is the same, but existing cursors can't be shared, so: • The SQL hash maps to an existing address in the Library Cache • The dynamic metadata creates a new child cursor under the parent Cursor Sharing www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Parents can have multiple child cursors with
different execution plans • A parent cursor can be marked: • Bind-sensitive: Cursor can be re-parsed to improve the plan • Bind-aware: Child execution plans are based on bind values • Bind-aware cursors are parsed differently: • A soft parse isn't adequate but a full, hard parse is too much • Optimizer reviews children for potential reuse based on bind values Cursor Sharing www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • A semi-hard parse inspects bind values on
every parse • Parsing can skip a (legitimately) compatible child for many reasons: • NLS settings • Different schemas • Cardinality feedback • Bind mismatch Child Cursor Misses • DDL • Statistics www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Altering object metadata used by a child
cursor invalidates the cursor • Collecting/over-collecting statistics • Bulk updates that alter cardinality • Refreshing, reorganizing, rebuilding objects • Adding/dropping indexes • Changing index visibility Cursor Invalidation www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Altering object metadata used by a child
cursor invalidates the cursor • Changing column names, datatypes, scale • Adding or dropping columns • TRUNCATEs, GRANTs Cursor Invalidation www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Physically separates database objects along logical boundaries
• Improves performance, reduces cost, eases data lifecycle management • Partition by range, list, hash • Composite partitioning combines two methods, e.g. list + range Partitioning www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Each partition is assigned a range •
e.g. from Jan 1, 2024 until Feb 1, 2024 • Reporting on January 2024 selects one partition • All other partitions are eliminated • Older (unused) data can be moved to low-cost storage • Inactive partitions can be marked read-only • Reduces backup size, time Range partitioning www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Speci fi • e.g., populous states (CA,
NY, TX) get dedicated partitions • Smaller states (MT, NH, NM) grouped in a single partition • Allows fi • Queries realize the same partition-elimination bene fi List partitioning www.viscosityna.com @ViscosityNA -
www.viscosityna.com @ViscosityNA • Key value passed through a hash function
and assigned to a bucket • Sequential values are distributed across hash partitions • Effective for eliminating hot blocks/records • Queries on sequential ranges will likely hit multiple partitions • Often useful for transactional environments w/lookups by key value • Not always a good choice for reporting Hash partitioning www.viscosityna.com @ViscosityNA
 oraclesean
 inariku
 littlehands
 daishukojima
 itosoft
 hatahata021
 demaecan
 ama_ch
 masasuzu
 yusuke427
 kota2and3kan
 tkito
 bethany
 michielstock
 jacobian
 axbom
 marcoroth
 rakko
 wayneb77
 sabderemane
 destraynor
 brad_frost
 szymonslowik
 bkeepers