Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
【ローカルAIに向き合う展示会vol.2】液体時間定数型モジュールを用いた オリジナルの双方向...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Rikka Botan
June 30, 2026
Research
200
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
【ローカルAIに向き合う展示会vol.2】液体時間定数型モジュールを用いた オリジナルの双方向エンコーダーモデルNexteraBERT 推論速度向上検討並びにダウンストリーム評価
ローカルAIに向き合う展示会 vol.2における発表スライドです。
双方向エンコーダーモデルの研究進捗に関する発表です。
Rikka Botan
June 30, 2026
More Decks by Rikka Botan
See All by Rikka Botan
HackSick vol.7 LT資料【LLMアーキテクチャ入門・事前学習時の躓き所解説】 スパースなAttention・状態空間モデル
rikkabotan7
0
180
【生成AIなんでも展示会vol.5 LT登壇】NexteraBERT発表資料
rikkabotan7
1
190
SSE: Stable Static Embedding
rikkabotan7
0
43
【ローカルAI LT大会】SSE: Stable Static Embedding ー速度低下を伴わず 静的埋め込みモデルの潜在能力を引き出す Dynamic Tanh手法の提案
rikkabotan7
0
120
SEA Model series Op.1: Saint Lupinus pre-release
rikkabotan7
0
160
Other Decks in Research
See All in Research
LA-Bench 2025:実験指示から 実行可能手順を生成するためのデータセット/LA-Bench 2025: A Dataset for Generating Executable Experimental Procedures from Experimental Instructions
stktu
0
180
ふとした出会いで生まれたSkillが、 社内利用1位になるまで
mikimhk
21
24k
GLIM とMegaParticles:正規分布近似の限界とタイトカップリング&パーティクルフィルタの進展 / GLIM and MegaParticles : Progress of the distribution representation in SLAM
koide3
0
860
論文読み会 SNLP2026 Tau2-Bench: Evaluating Conversational Agents in a Dual-Control Environment
s_mizuki_nlp
0
250
秋葉原ウォーカブル基礎調査報告書
izumiyama_lab
1
120
Source Code Diff Revolution
tsantalis
0
150
FORAGRO,
fstepman
0
240
2025年度秋葉原ウォーカブルプロジェクト調査報告 「アキバらしいウォーカブル」とは何か
izumiyama_lab
1
220
Anthropic が提案する LLM の内部状態を自然言語で説明可能にした Natural Language Autoencoders / Natural Language Autoencoders Produce Unsupervised Explanations of LLM Activations
shunk031
0
250
AARINENA’s Role in Agricultural Research and Innovation
fstepman
0
360
多様なデータを許容し学習し続ける模倣学習 / Advanced Imitation Learning for VLA
prinlab
0
320
某助成金プロジェクト採択に向けて企業研究所のアウトリーチ専任者がやったこと
afroscript
0
180
Featured
See All Featured
A Tale of Four Properties
chriscoyier
163
24k
Practical Tips for Bootstrapping Information Extraction Pipelines
honnibal
25
2.1k
Odyssey Design
rkendrick25
PRO
2
810
Collaborative Software Design: How to facilitate domain modelling decisions
baasie
1
320
Building Applications with DynamoDB
mza
96
7.2k
The Cult of Friendly URLs
andyhume
79
7k
Navigating Team Friction
lara
192
16k
Rails Girls Zürich Keynote
gr2m
96
14k
Design of three-dimensional binary manipulators for pick-and-place task avoiding obstacles (IECON2024)
konakalab
0
590
Facilitating Awesome Meetings
lara
57
7.1k
GraphQLの誤解/rethinking-graphql
sonatard
75
12k
So, you think you're a good person
axbom
PRO
2
2.2k
Transcript
液体時間定数型モジュールを用いた オリジナルの双方向エンコーダーモデルNexteraBERT 推論速度向上検討並びにダウンストリーム評価 NexteraBERT: Rethinking Bidirectional Encoder Models with Liquid
Time-Constant Modules, Modern Self-Attention, and Separable Dynamic Tanh normalization
Vol.2 ローカルAIに向き合う 展示会
◆趣味 お菓子作り・紅茶・クラシック鑑賞・お洋服 ◆最近の活動 Silver Award: Liquid AI Hackathon Series |
Tokyo 記事執筆(Mamba, LFM2 (LTCs) 関連) SSE Modelシリーズの公開 自己紹介 / About us 独立研究者(機械学習 / 代数学 / 数理論理学) Independent researcher (machine learning / algebra / mathematical logic) り っ か ぼ た ん 六花 牡丹 Rikka Botan X(Twitter) Portfolio
目録 / Contents 1 NexteraBERTについて / Introduction 2 3 4
評価・考察 / Evaluations 手法/ Method モジュール構築の考え方 / Principle
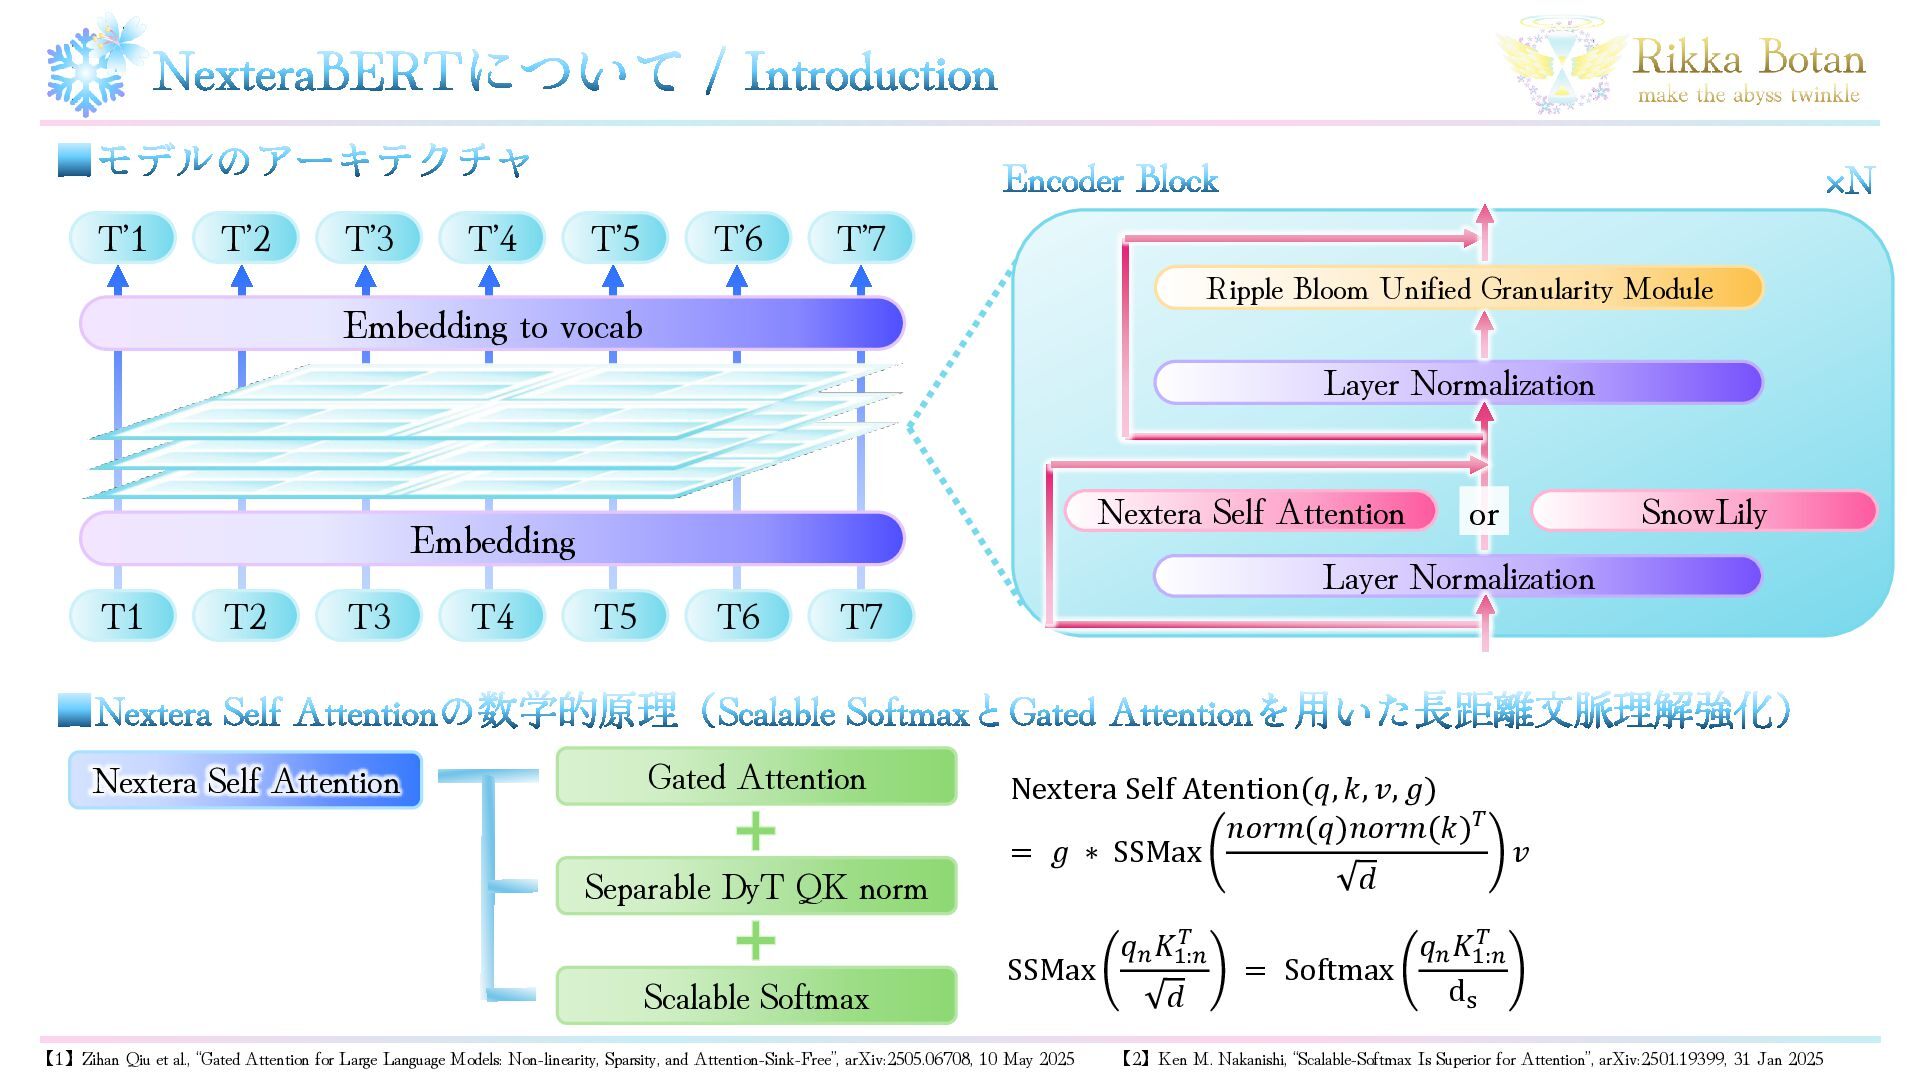
NexteraBERTについて / Introduction ▪モデルのアーキテクチャ T’1 T’2 T’3 T’4 T’5 T’6
T’7 T1 T2 T3 T4 T5 T6 T7 Embedding to vocab Embedding Encoder Block Ripple Bloom Unified Granularity Module Nextera Self Attention Layer Normalization Layer Normalization ×N SnowLily or Nextera Self Attention Scalable Softmax Gated Attention Separable DyT QK norm Nextera Self Atention(𝑞, 𝑘, 𝑣, 𝑔) = 𝑔 ∗ SSMax 𝑛𝑜𝑟𝑚(𝑞)𝑛𝑜𝑟𝑚(𝑘)𝑇 𝑑 𝑣 ▪Nextera Self Attentionの数学的原理(Scalable SoftmaxとGated Attentionを用いた長距離文脈理解強化) SSMax 𝑞𝑛 𝐾1:𝑛 𝑇 𝑑 = Softmax 𝑞𝑛 𝐾1:𝑛 𝑇 ds 【1】Zihan Qiu et al., “Gated Attention for Large Language Models: Non-linearity, Sparsity, and Attention-Sink-Free”, arXiv:2505.06708, 10 May 2025 【2】Ken M. Nakanishi, “Scalable-Softmax Is Superior for Attention”, arXiv:2501.19399, 31 Jan 2025
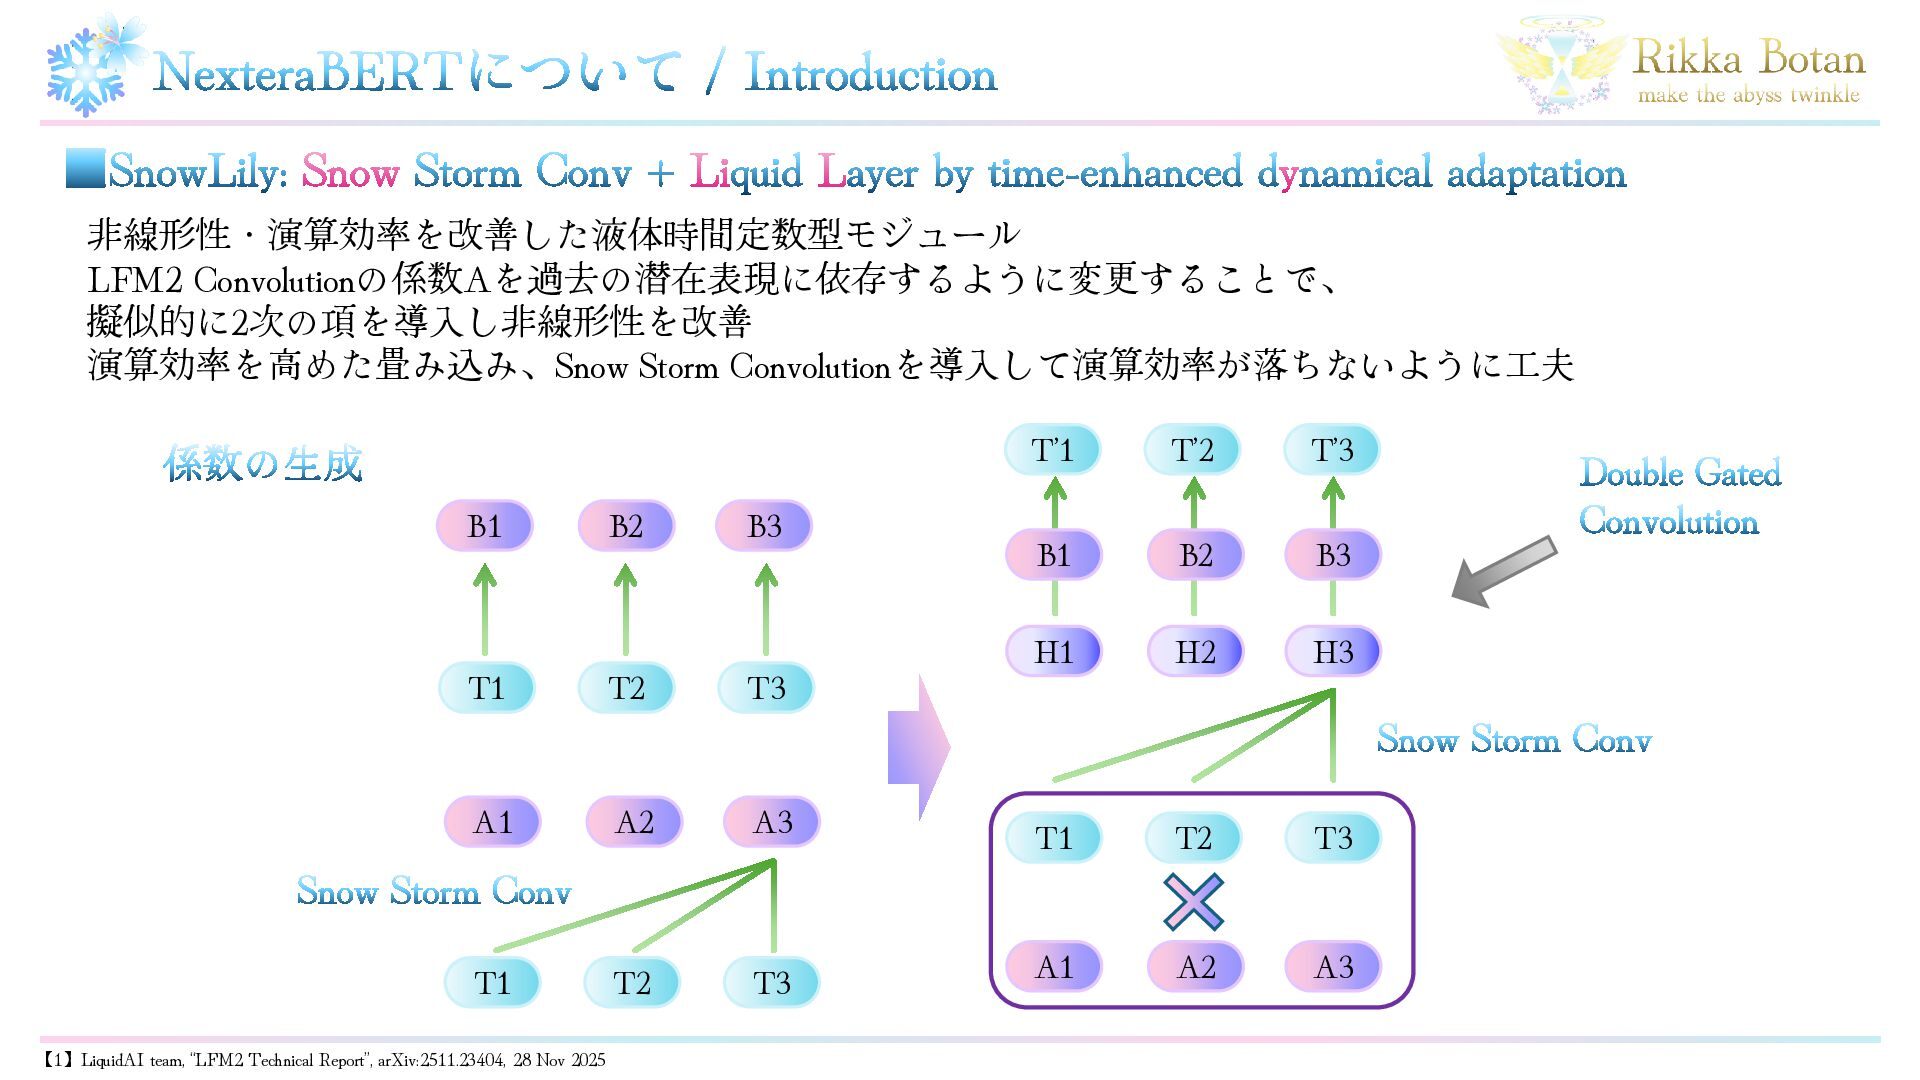
NexteraBERTについて / Introduction 非線形性・演算効率を改善した液体時間定数型モジュール LFM2 Convolutionの係数Aを過去の潜在表現に依存するように変更することで、 擬似的に2次の項を導入し非線形性を改善 演算効率を高めた畳み込み、Snow Storm Convolutionを導入して演算効率が落ちないように工夫
▪SnowLily: Snow Storm Conv + Liquid Layer by time-enhanced dynamical adaptation T1 T2 T3 A3 A2 A1 T’1 T’2 T’3 T1 T2 T3 H3 H2 H1 A3 A2 A1 B3 B2 B1 B3 B2 B1 T1 T2 T3 Snow Storm Conv Snow Storm Conv 係数の生成 Double Gated Convolution 【1】LiquidAI team, “LFM2 Technical Report”, arXiv:2511.23404, 28 Nov 2025
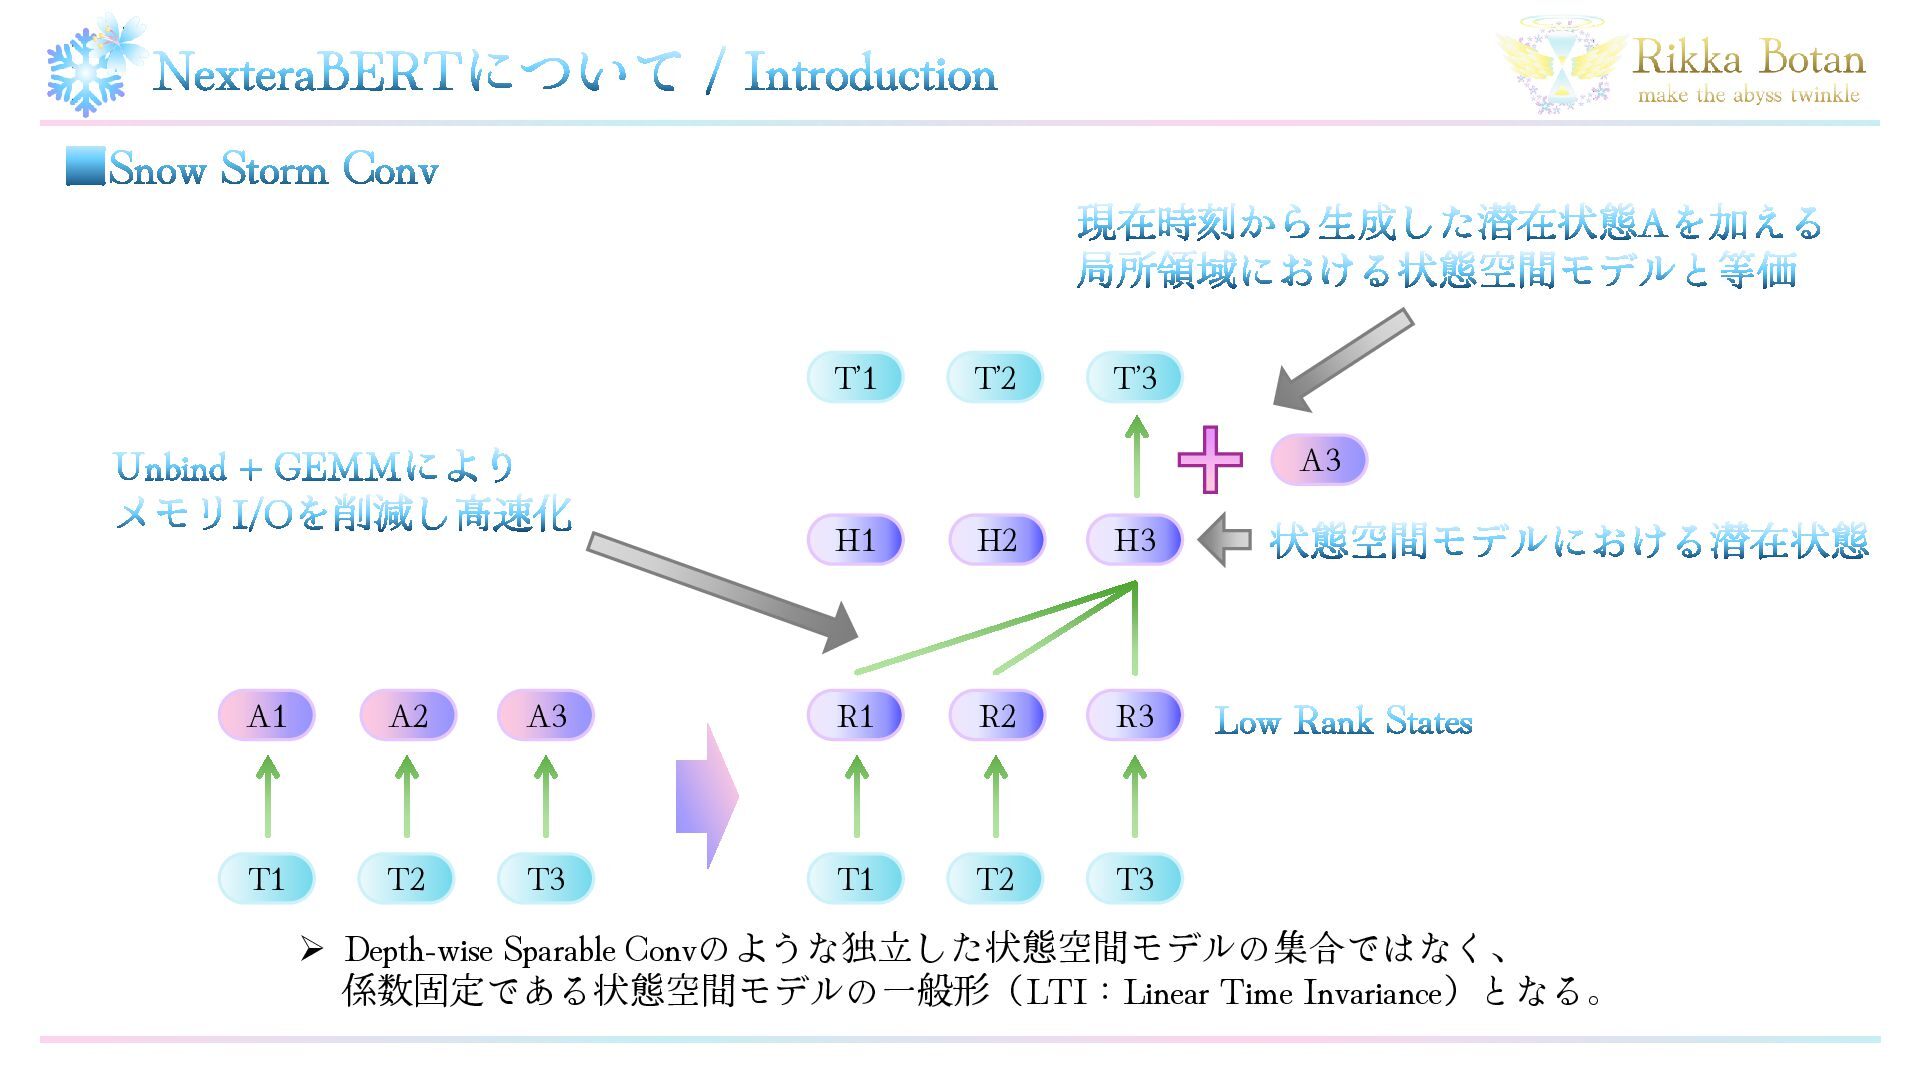
NexteraBERTについて / Introduction ▪Snow Storm Conv T’1 T’2 T’3 T1
T2 T3 R3 R2 R1 Low Rank States A3 A2 A1 T1 T2 T3 H3 H2 H1 A3 ➢ Depth-wise Sparable Convのような独立した状態空間モデルの集合ではなく、 係数固定である状態空間モデルの一般形(LTI:Linear Time Invariance)となる。 Unbind + GEMMにより メモリI/Oを削減し高速化 現在時刻から生成した潜在状態Aを加える 局所領域における状態空間モデルと等価 状態空間モデルにおける潜在状態
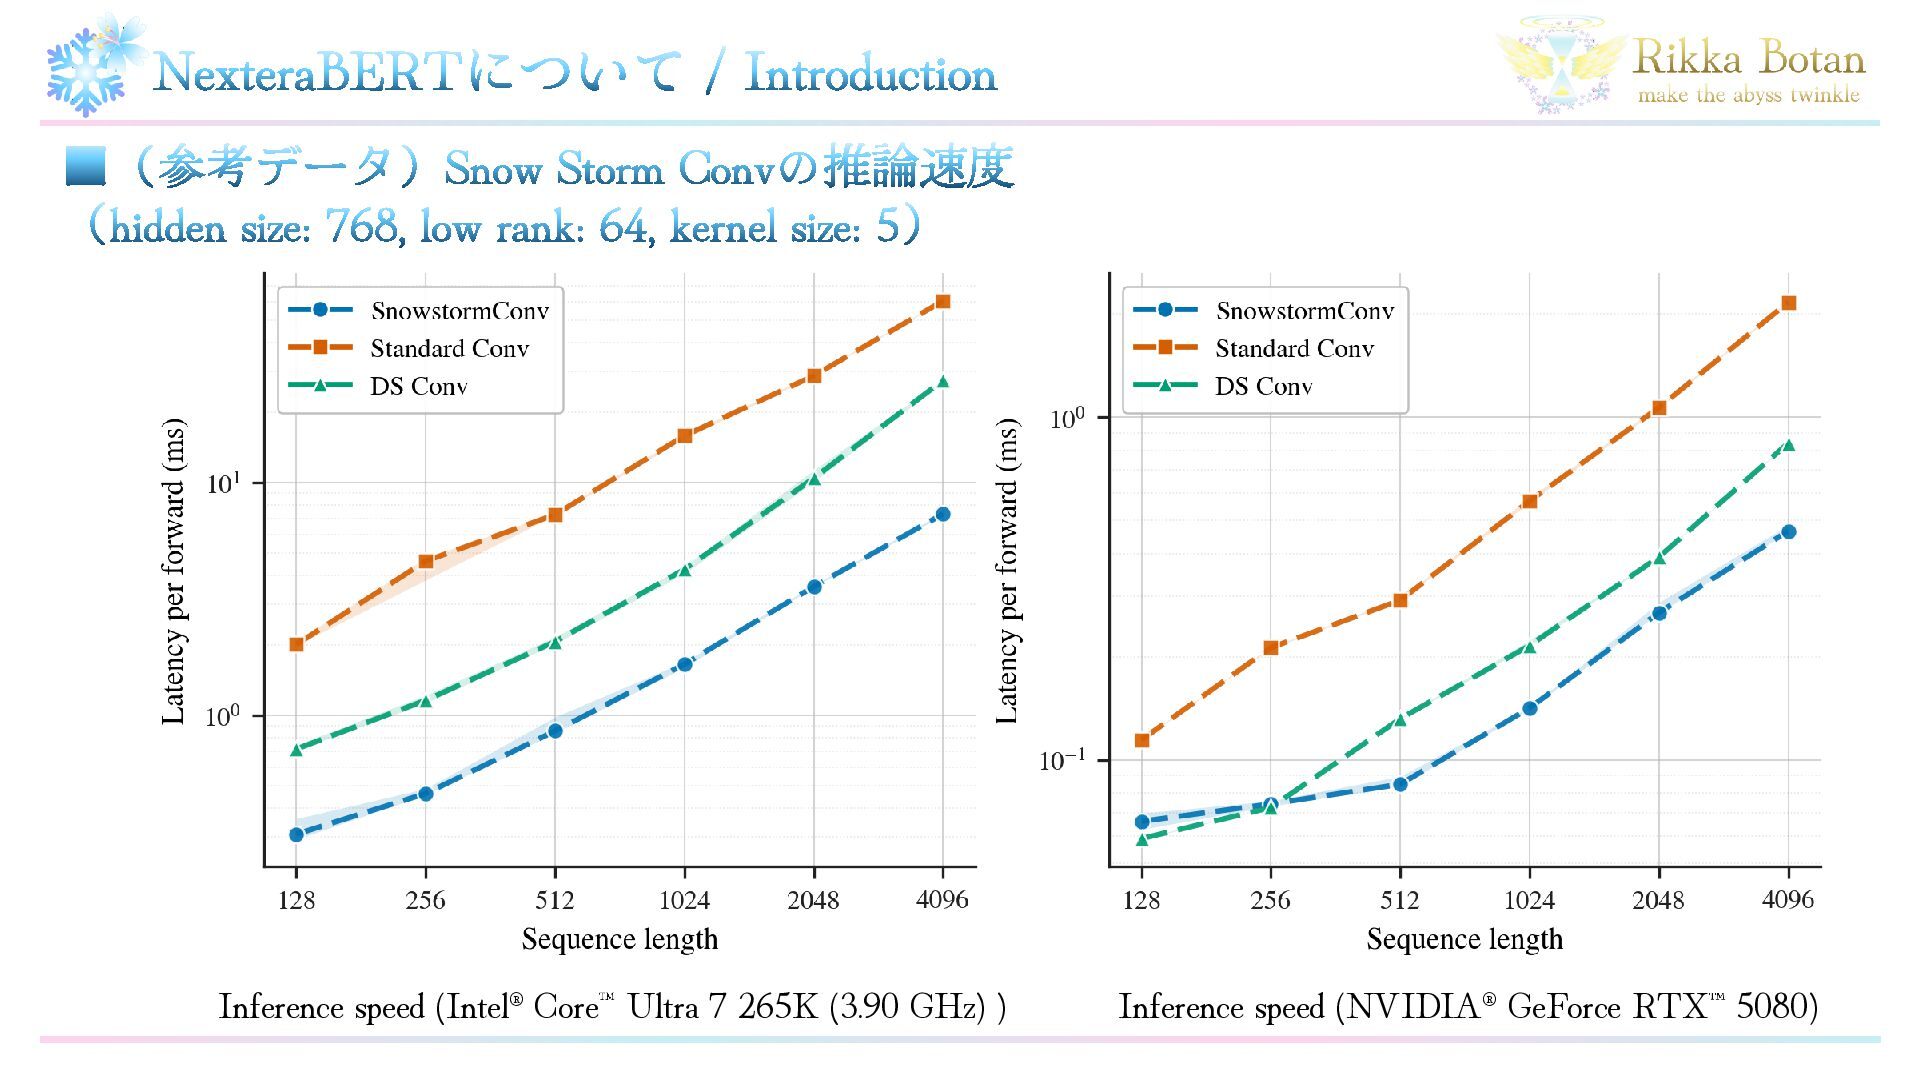
NexteraBERTについて / Introduction ▪(参考データ)Snow Storm Convの推論速度 (hidden size: 768, low
rank: 64, kernel size: 5) Inference speed (Intel® Core Ultra 7 265K (3.90 GHz) ) Inference speed (NVIDIA® GeForce RTX 5080)
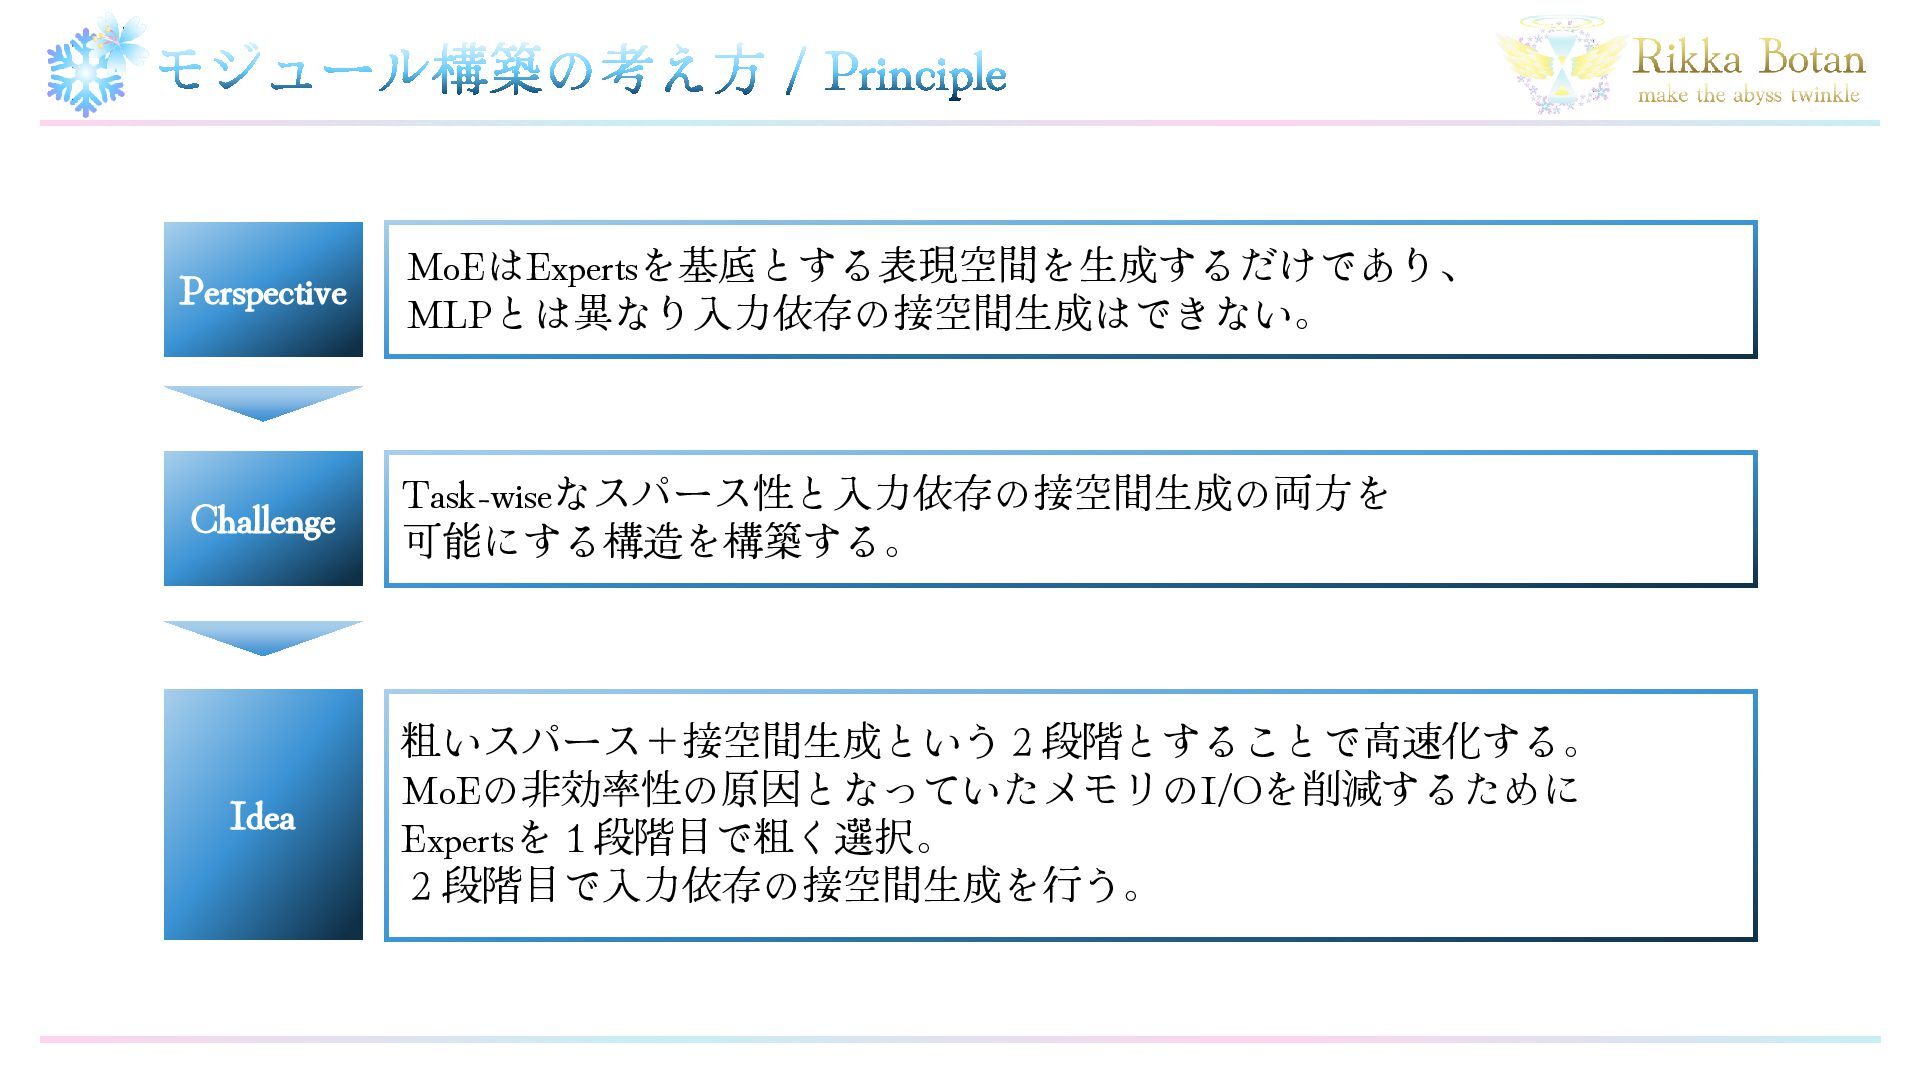
モジュール構築の考え方 / Principle Perspective MoEはExpertsを基底とする表現空間を生成するだけであり、 MLPとは異なり入力依存の接空間生成はできない。 Challenge Task-wiseなスパース性と入力依存の接空間生成の両方を 可能にする構造を構築する。 Idea
粗いスパース+接空間生成という2段階とすることで高速化する。 MoEの非効率性の原因となっていたメモリのI/Oを削減するために Expertsを1段階目で粗く選択。 2段階目で入力依存の接空間生成を行う。
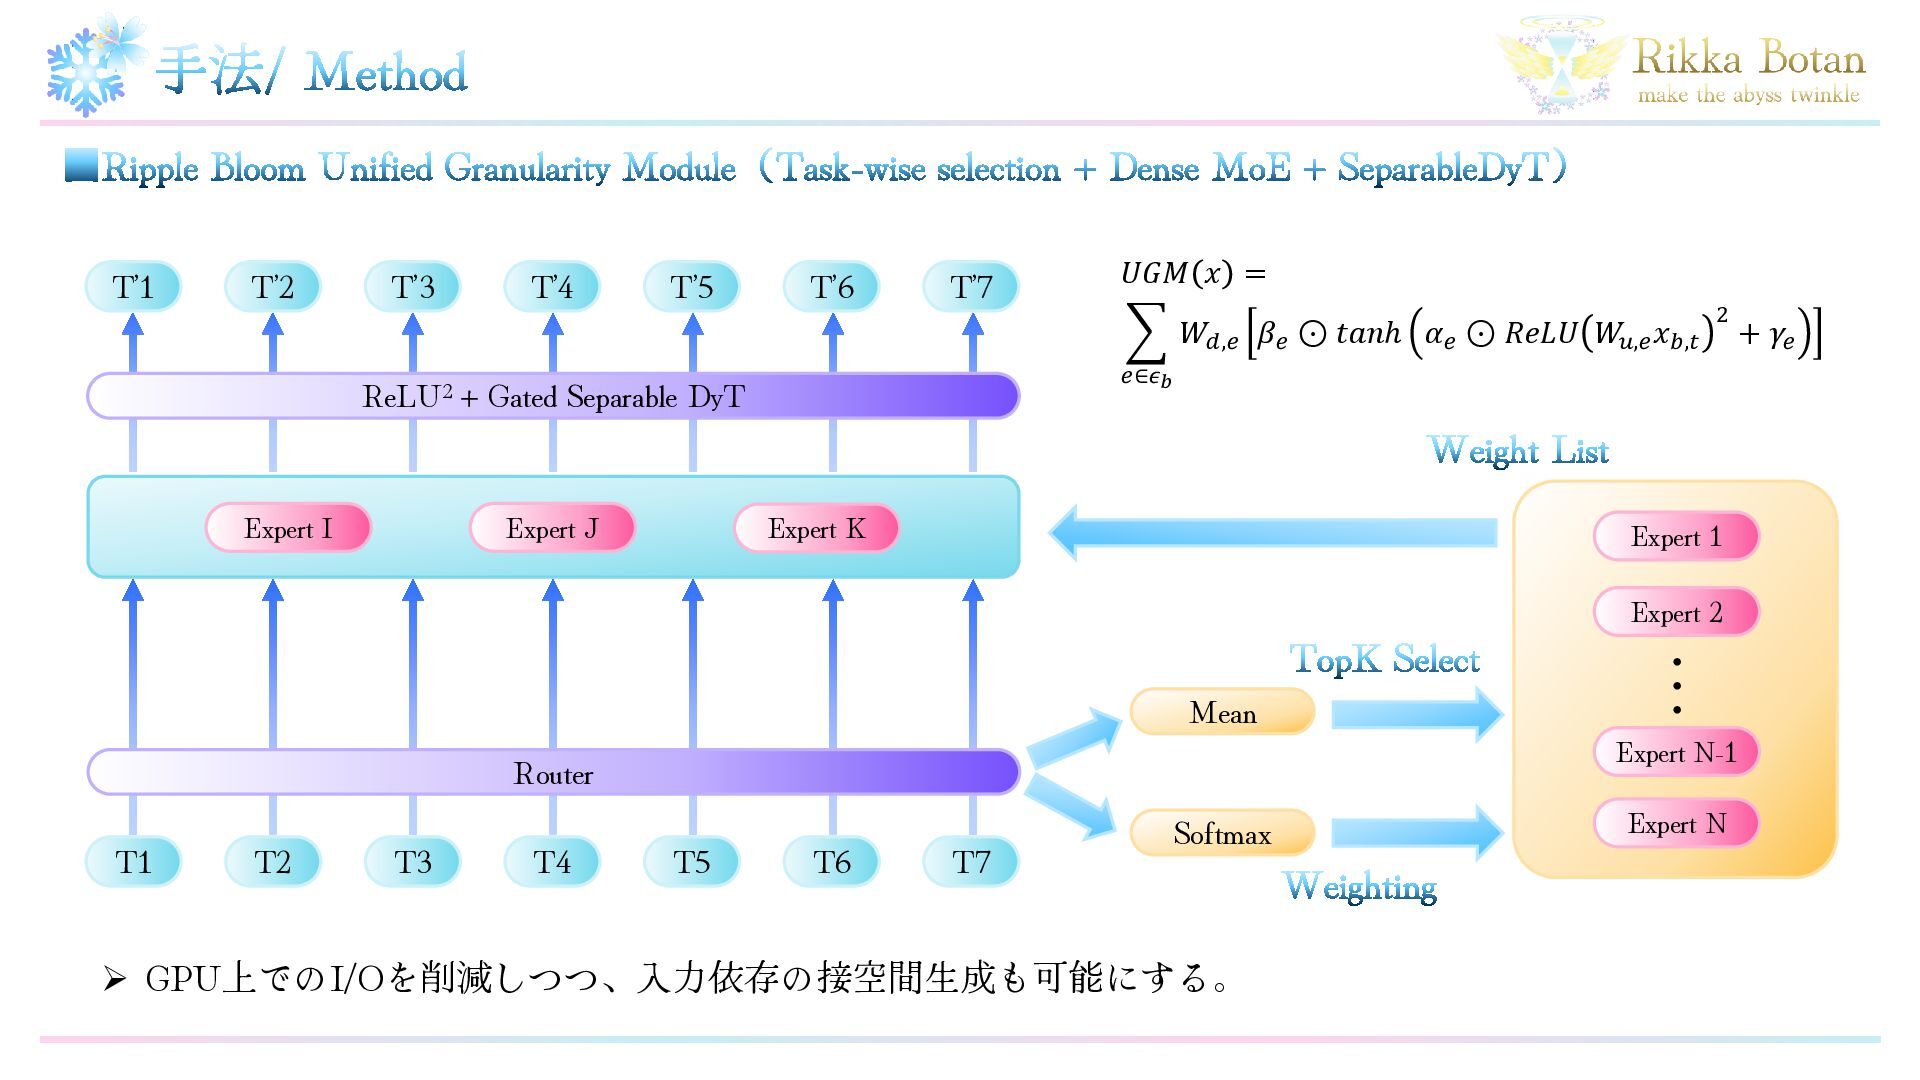
手法/ Method T’1 T’2 T’3 T’4 T’5 T’6 T’7 Expert
I Expert J Expert K T1 T2 T3 T4 T5 T6 T7 Router Weight List Expert 1 Expert 2 Expert N Expert N-1 ・ ・ ・ TopK Select Mean Softmax Weighting ReLU2 + Gated Separable DyT ▪Ripple Bloom Unified Granularity Module(Task-wise selection + Dense MoE + SeparableDyT) ➢ GPU上でのI/Oを削減しつつ、入力依存の接空間生成も可能にする。 𝑈𝐺𝑀 𝑥 = 𝑒∈𝜖𝑏 𝑊𝑑,𝑒 𝛽𝑒 ⊙ 𝑡𝑎𝑛ℎ 𝛼𝑒 ⊙ 𝑅𝑒𝐿𝑈 𝑊 𝑢,𝑒 𝑥𝑏,𝑡 2 + 𝛾𝑒
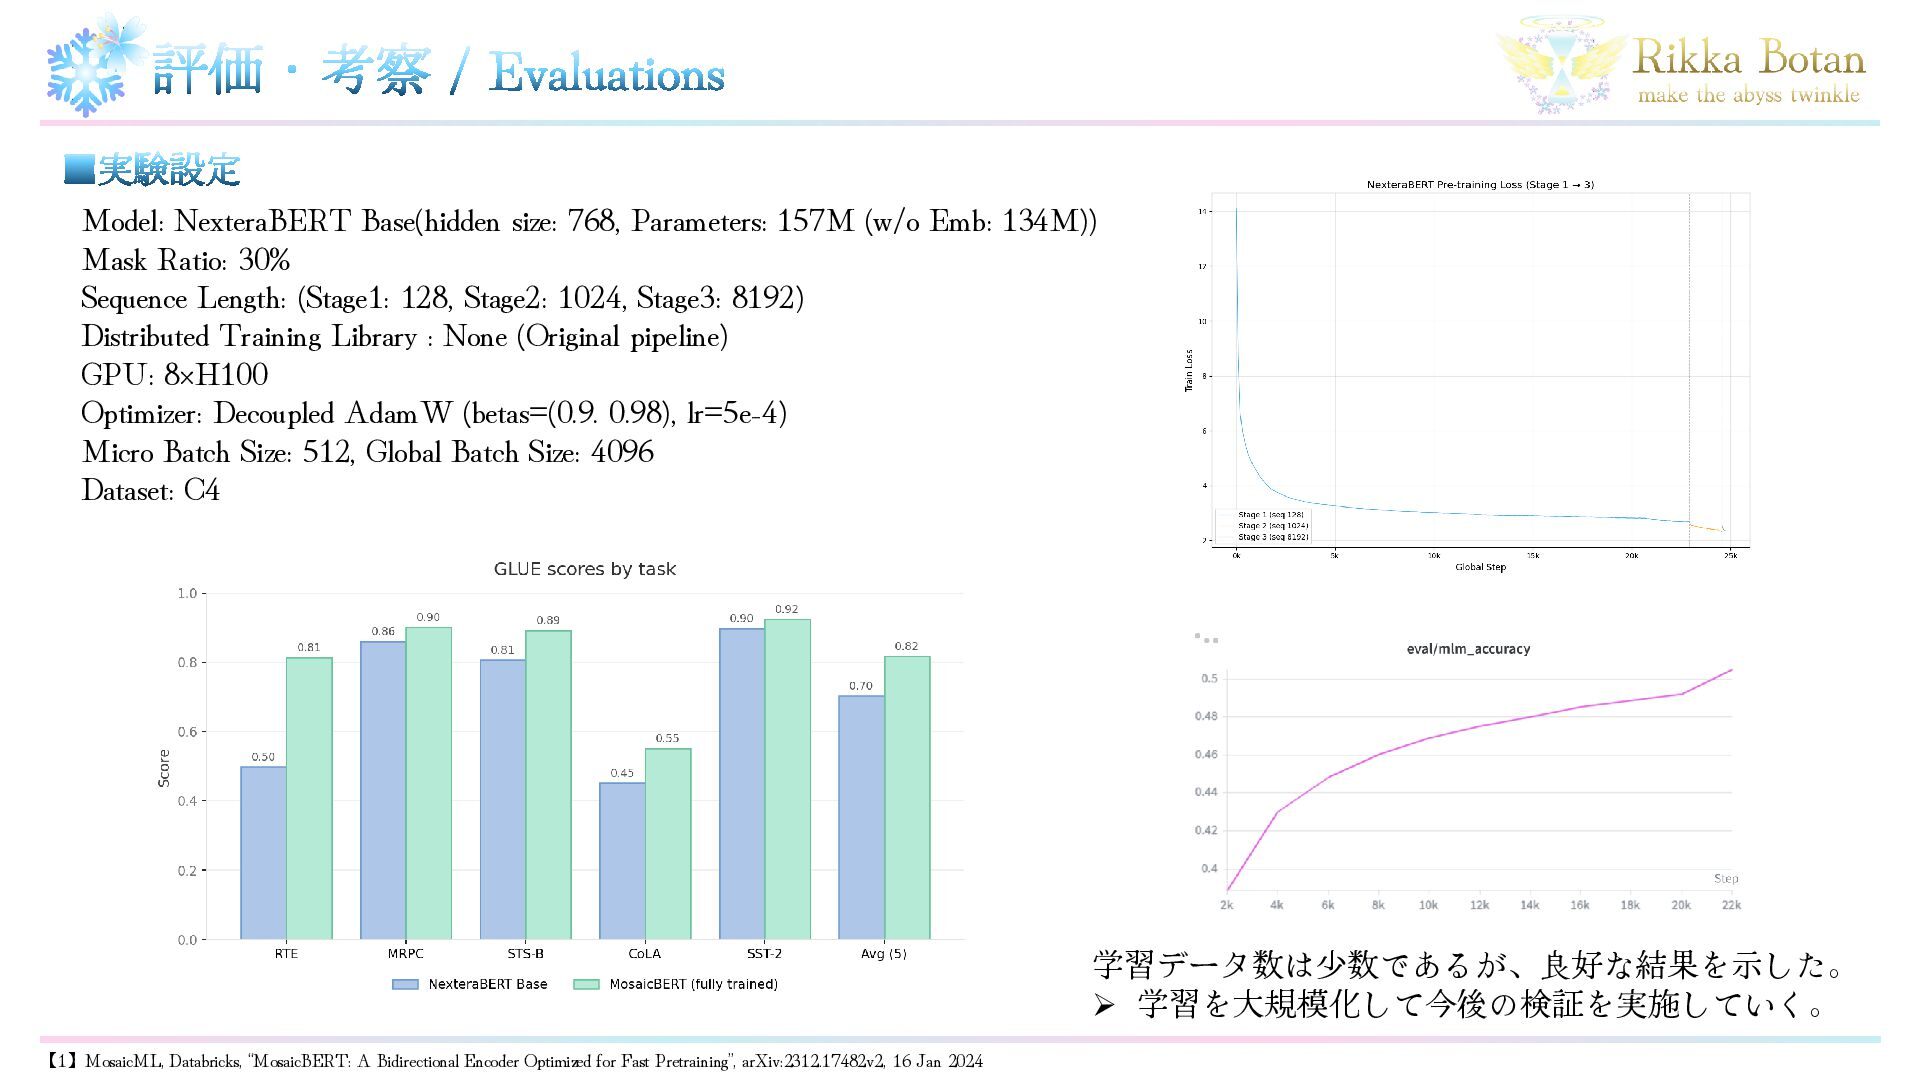
▪実験設定 評価・考察 / Evaluations Model: NexteraBERT Base(hidden size: 768, Parameters:
157M (w/o Emb: 134M)) Mask Ratio: 30% Sequence Length: (Stage1: 128, Stage2: 1024, Stage3: 8192) Distributed Training Library : None (Original pipeline) GPU: 8×H100 Optimizer: Decoupled AdamW (betas=(0.9. 0.98), lr=5e-4) Micro Batch Size: 512, Global Batch Size: 4096 Dataset: C4 学習データ数は少数であるが、良好な結果を示した。 ➢ 学習を大規模化して今後の検証を実施していく。 【1】MosaicML, Databricks, “MosaicBERT: A Bidirectional Encoder Optimized for Fast Pretraining”, arXiv:2312.17482v2, 16 Jan 2024
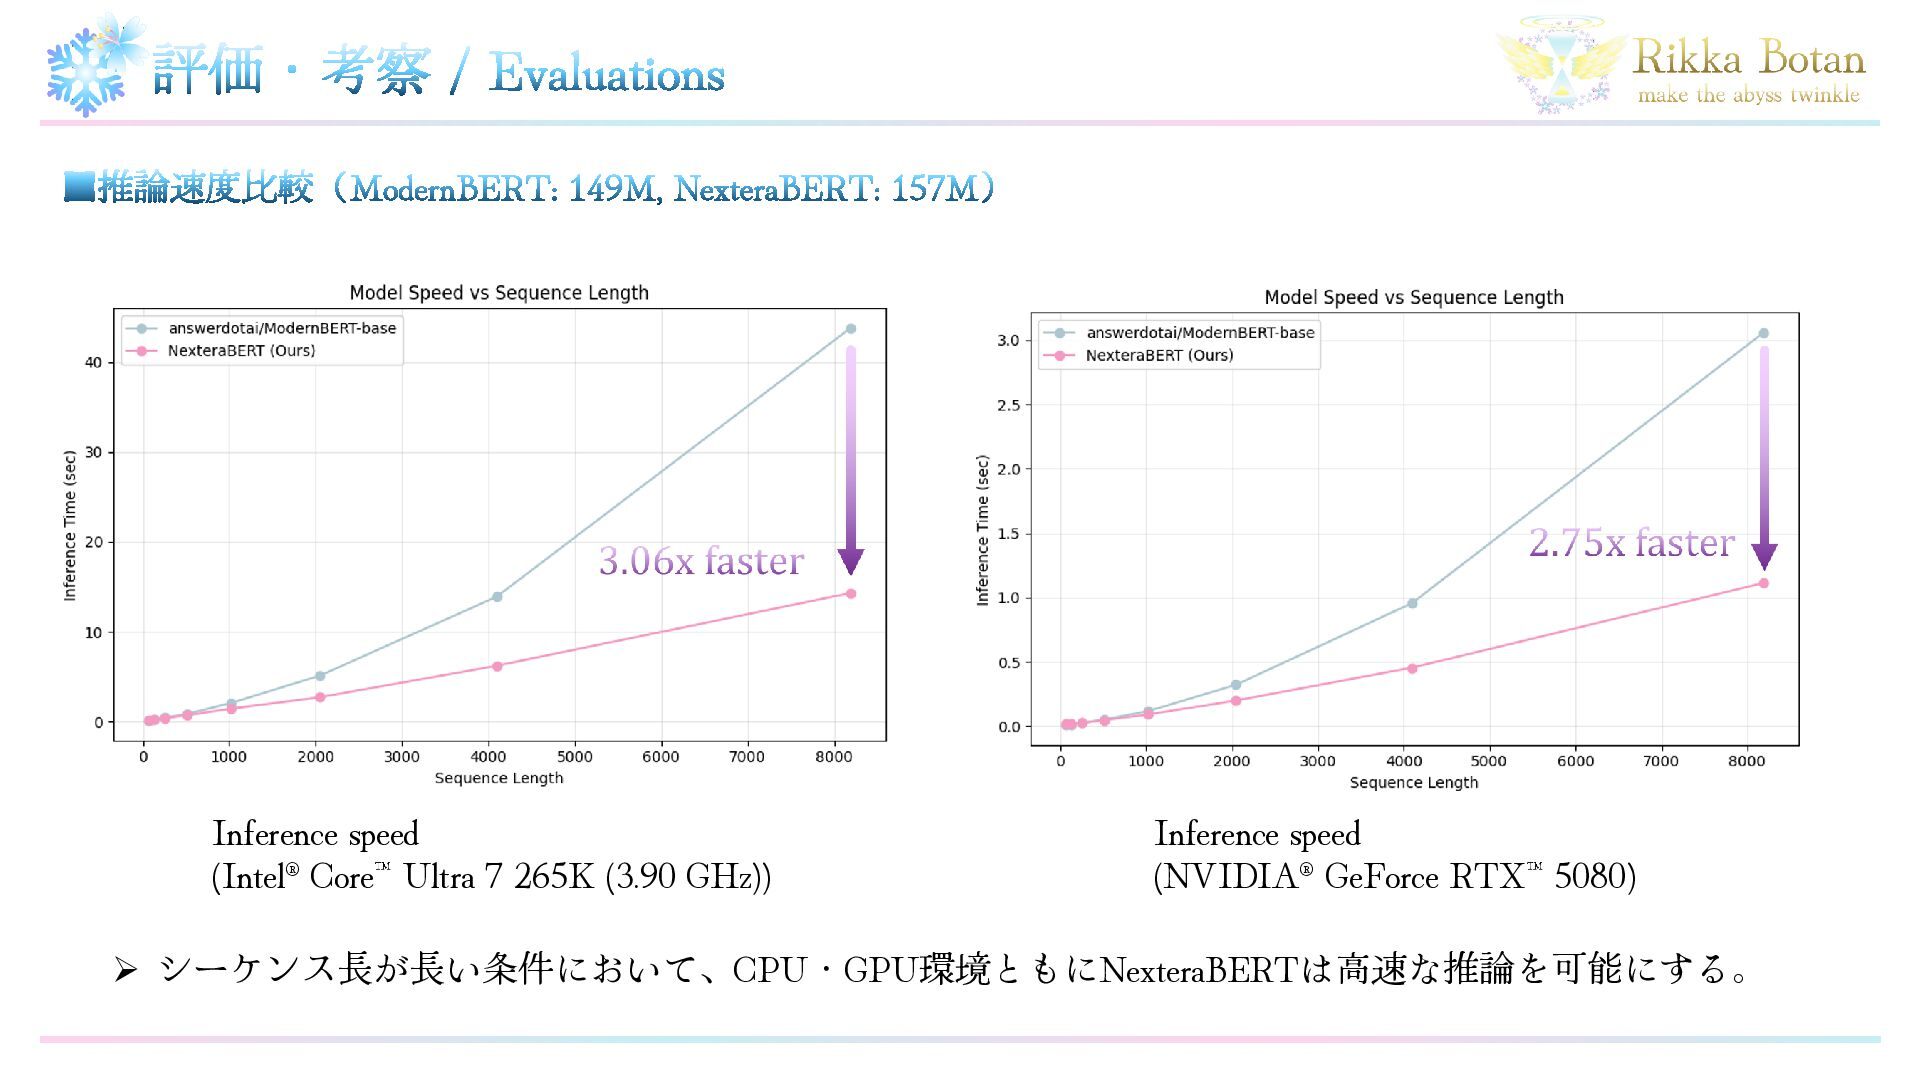
▪推論速度比較(ModernBERT: 149M, NexteraBERT: 157M) 評価・考察 / Evaluations ➢ シーケンス長が長い条件において、CPU・GPU環境ともにNexteraBERTは高速な推論を可能にする。 Inference
speed (Intel® Core Ultra 7 265K (3.90 GHz)) Inference speed (NVIDIA® GeForce RTX 5080)
13


 rikkabotan7
 stktu
 mikimhk
 koide3
 s_mizuki_nlp
 izumiyama_lab
 tsantalis
 fstepman
 shunk031
 prinlab
 afroscript
 chriscoyier
 honnibal
 rkendrick25
 baasie
 mza
 andyhume
 lara
 gr2m
 konakalab
 sonatard
 axbom