Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Hybrid Autoregressive Transducer [輪講発表資料]
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
shibutani
June 22, 2022
Research
470
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Hybrid Autoregressive Transducer [輪講発表資料]
Hybrid Autoregressive Transducer に関する輪講発表資料です。
shibutani
June 22, 2022
More Decks by shibutani
See All by shibutani
AIで進めるQA自動化の現在地 - E2Eリグレッションテストの整備と維持 -
shibukazu
8
3.2k
越境するAIのために、境界を取り払う - AI 時代の開発体験向上に向けたリポジトリ統合の取り組み -
shibukazu
1
720
メッセージキュー型の非同期処理から Temporal 移行へ
shibukazu
4
5.9k
はじめてのOSS開発からみえたGo言語の強み
shibukazu
4
1.5k
全自動コードレビューの夢 〜実際に活用されるAIコードレビューの実現に向けて〜
shibukazu
11
5.7k
Perceiver: General Perception with Iterative [輪講発表資料]
shibukazu
0
150
Other Decks in Research
See All in Research
Source Code Diff Revolution
tsantalis
0
160
Pretrain Where? Investigating How Pretraining Data Diversity Impacts Geospatial Foundation Model Performance
satai
3
130
クラウド・AI 時代の研究開発 DX / R&D Digital Transformation
hariby
0
150
量子サマースクール2026「量子計算機アーキテクチャ分野の概観」
youten622
1
910
XDPerf: A High-Performance Traffic Generator Built with WASM and eBPF
takehaya
1
310
The story of RefactoringMiner. Slow research, long-term impact
tsantalis
0
160
GLIM とMegaParticles:正規分布近似の限界とタイトカップリング&パーティクルフィルタの進展 / GLIM and MegaParticles : Progress of the distribution representation in SLAM
koide3
0
870
SOTAのさらに先へ:厳しい推論制約下での高性能モデルのPost-Training
analokmaus
0
1.5k
論文読み会 SNLP2026 Tau2-Bench: Evaluating Conversational Agents in a Dual-Control Environment
s_mizuki_nlp
0
250
HAKARI-Bench - 実運用視点での情報検索モデル評価ベンチマーク
hotchpotch
1
760
敵対生成プロンプト同時探索による内省型プロンプト最適化
kinoue_smarthr
0
420
Apache Gravitinoで実現する Icebergカタログ統合とアクセスの一元化
matsumooon
0
530
Featured
See All Featured
How To Stay Up To Date on Web Technology
chriscoyier
790
250k
Mozcon NYC 2025: Stop Losing SEO Traffic
samtorres
1
550
The MySQL Ecosystem @ GitHub 2015
samlambert
251
13k
Ecommerce SEO: The Keys for Success Now & Beyond - #SERPConf2024
aleyda
1
2.2k
The AI Revolution Will Not Be Monopolized: How open-source beats economies of scale, even for LLMs
inesmontani
PRO
3
3.7k
The Director’s Chair: Orchestrating AI for Truly Effective Learning
tmiket
1
300
Groundhog Day: Seeking Process in Gaming for Health
codingconduct
0
360
The Hidden Cost of Media on the Web [PixelPalooza 2025]
tammyeverts
2
500
The Cost Of JavaScript in 2023
addyosmani
55
10k
Navigating the moral maze — ethical principles for Al-driven product design
skipperchong
2
560
Put a Button on it: Removing Barriers to Going Fast.
kastner
60
4.6k
Designing Dashboards & Data Visualisations in Web Apps
destraynor
232
55k
Transcript
Hybrid Autoregressive Transducer (HAT) [Variani, Rybach+ 2020] 京都大学 音声メディア研究室 M1
渋谷和樹 1
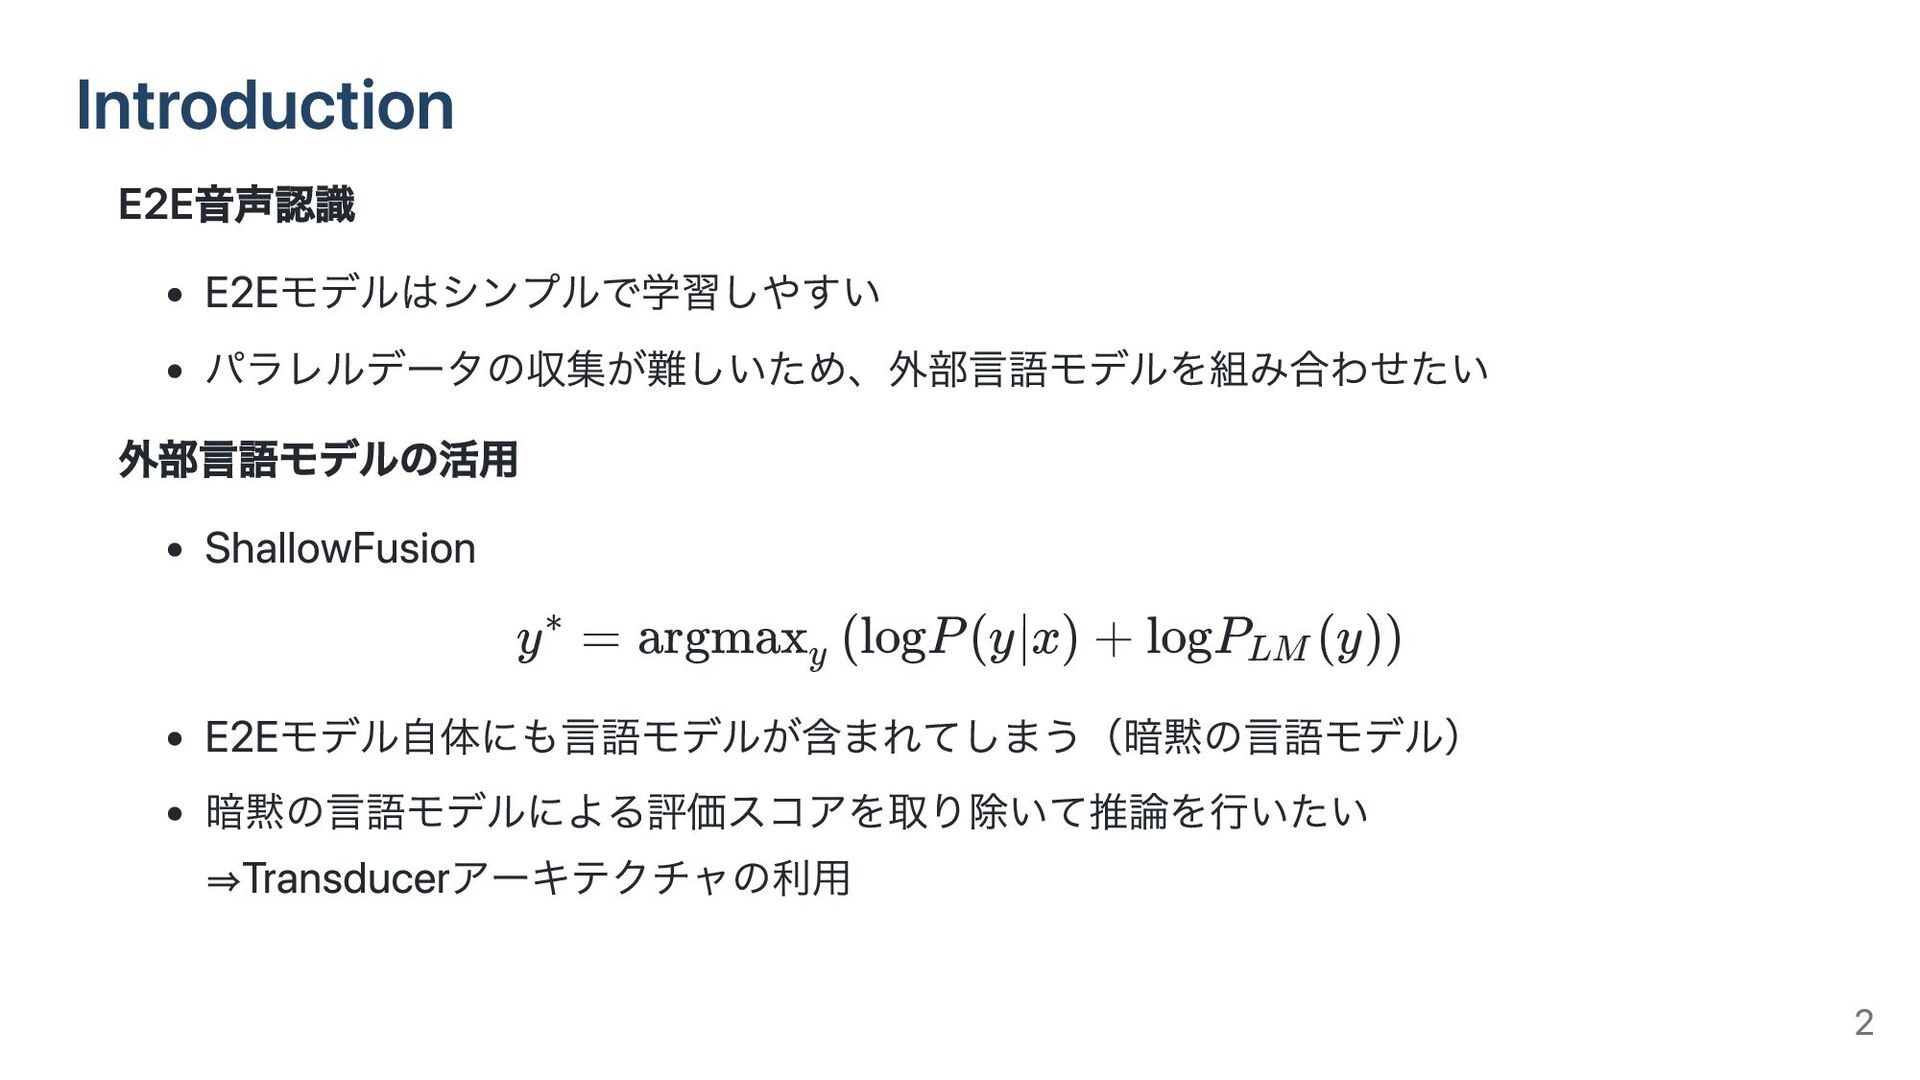
E2E音声認識 E2Eモデルはシンプルで学習しやすい パラレルデータの収集が難しいため、外部言語モデルを組み合わせたい 外部言語モデルの活用 ShallowFusion y = ∗ argmax
logP(y∣x) + logP (y) y ( LM ) E2Eモデル自体にも言語モデルが含まれてしまう(暗黙の言語モデル) 暗黙の言語モデルによる評価スコアを取り除いて推論を行いたい ⇒Transducerアーキテクチャの利用 Introduction 2
Transducer 3
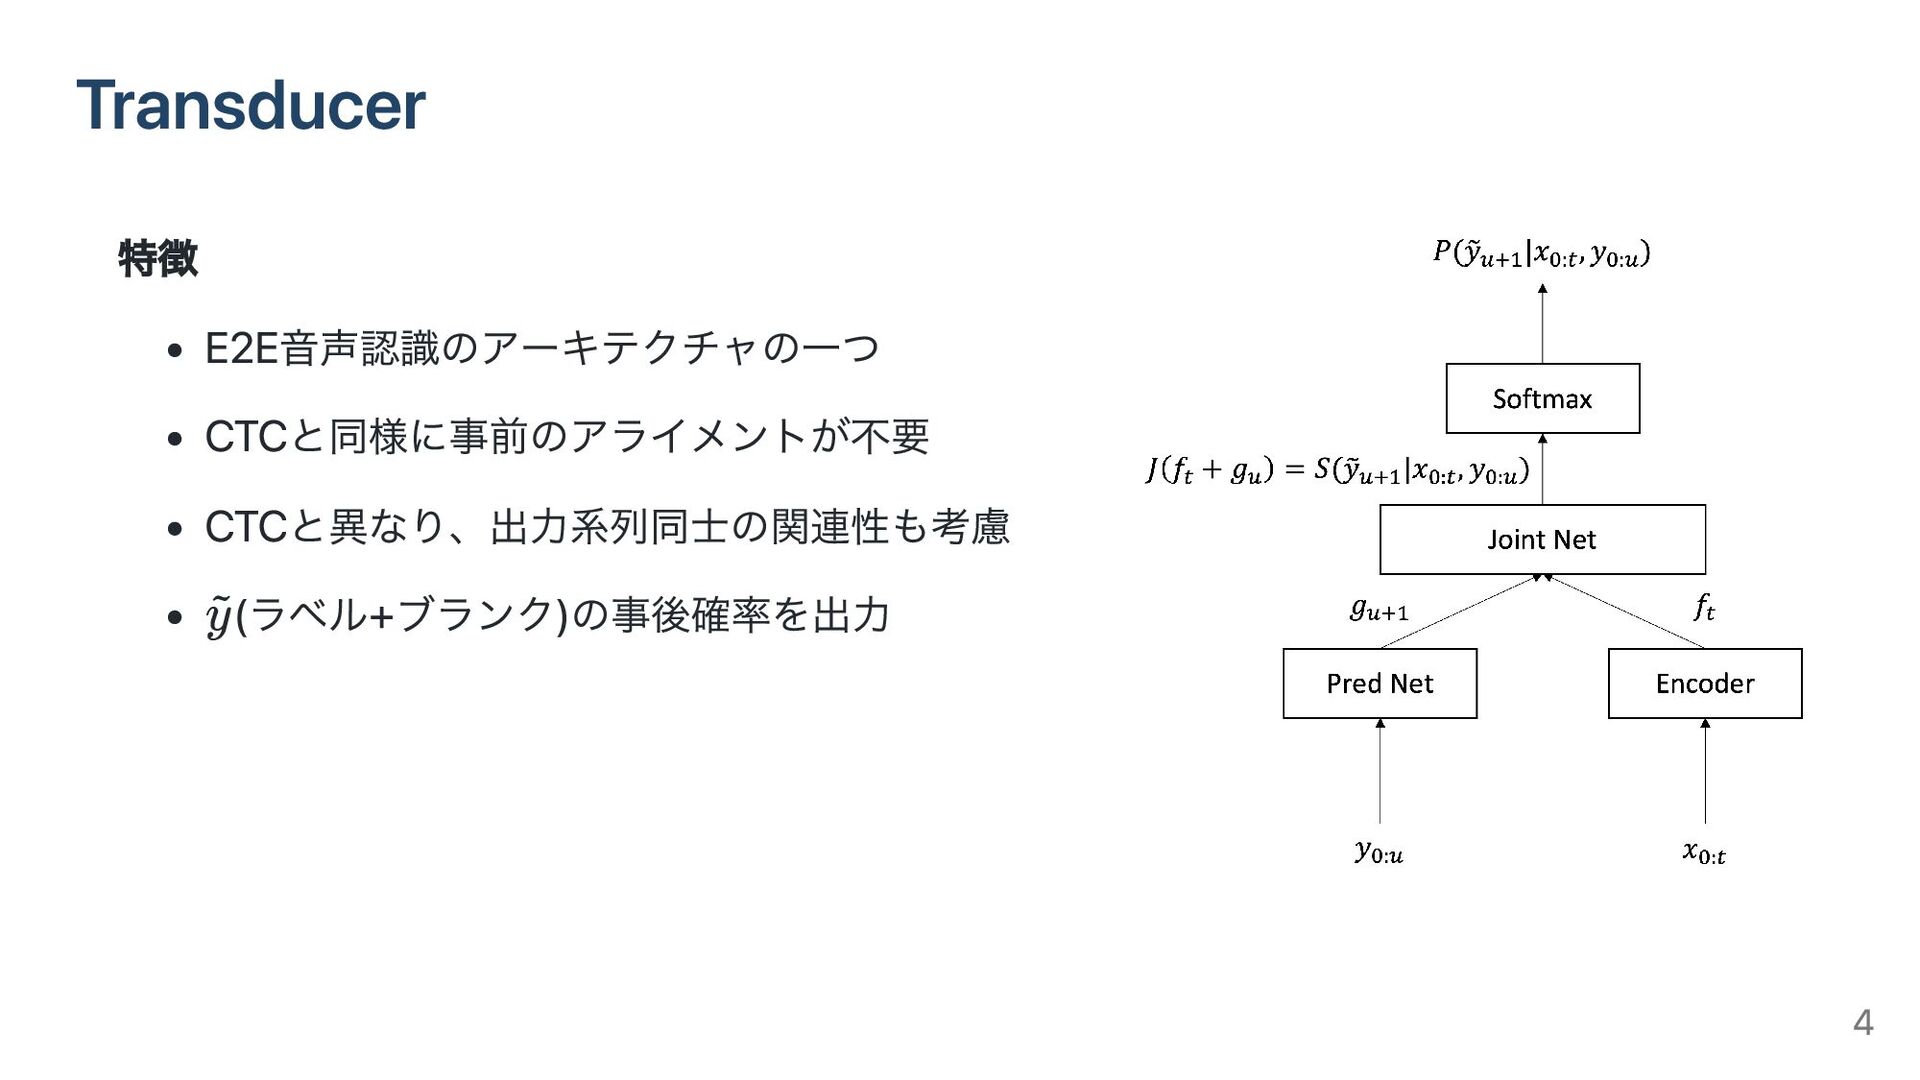
Transducer 特徴 E2E音声認識のアーキテクチャの一つ CTCと同様に事前のアライメントが不要 CTCと異なり、出力系列同士の関連性も考慮 (ラベル+ブランク)の事後確率を出力 y ~ 4
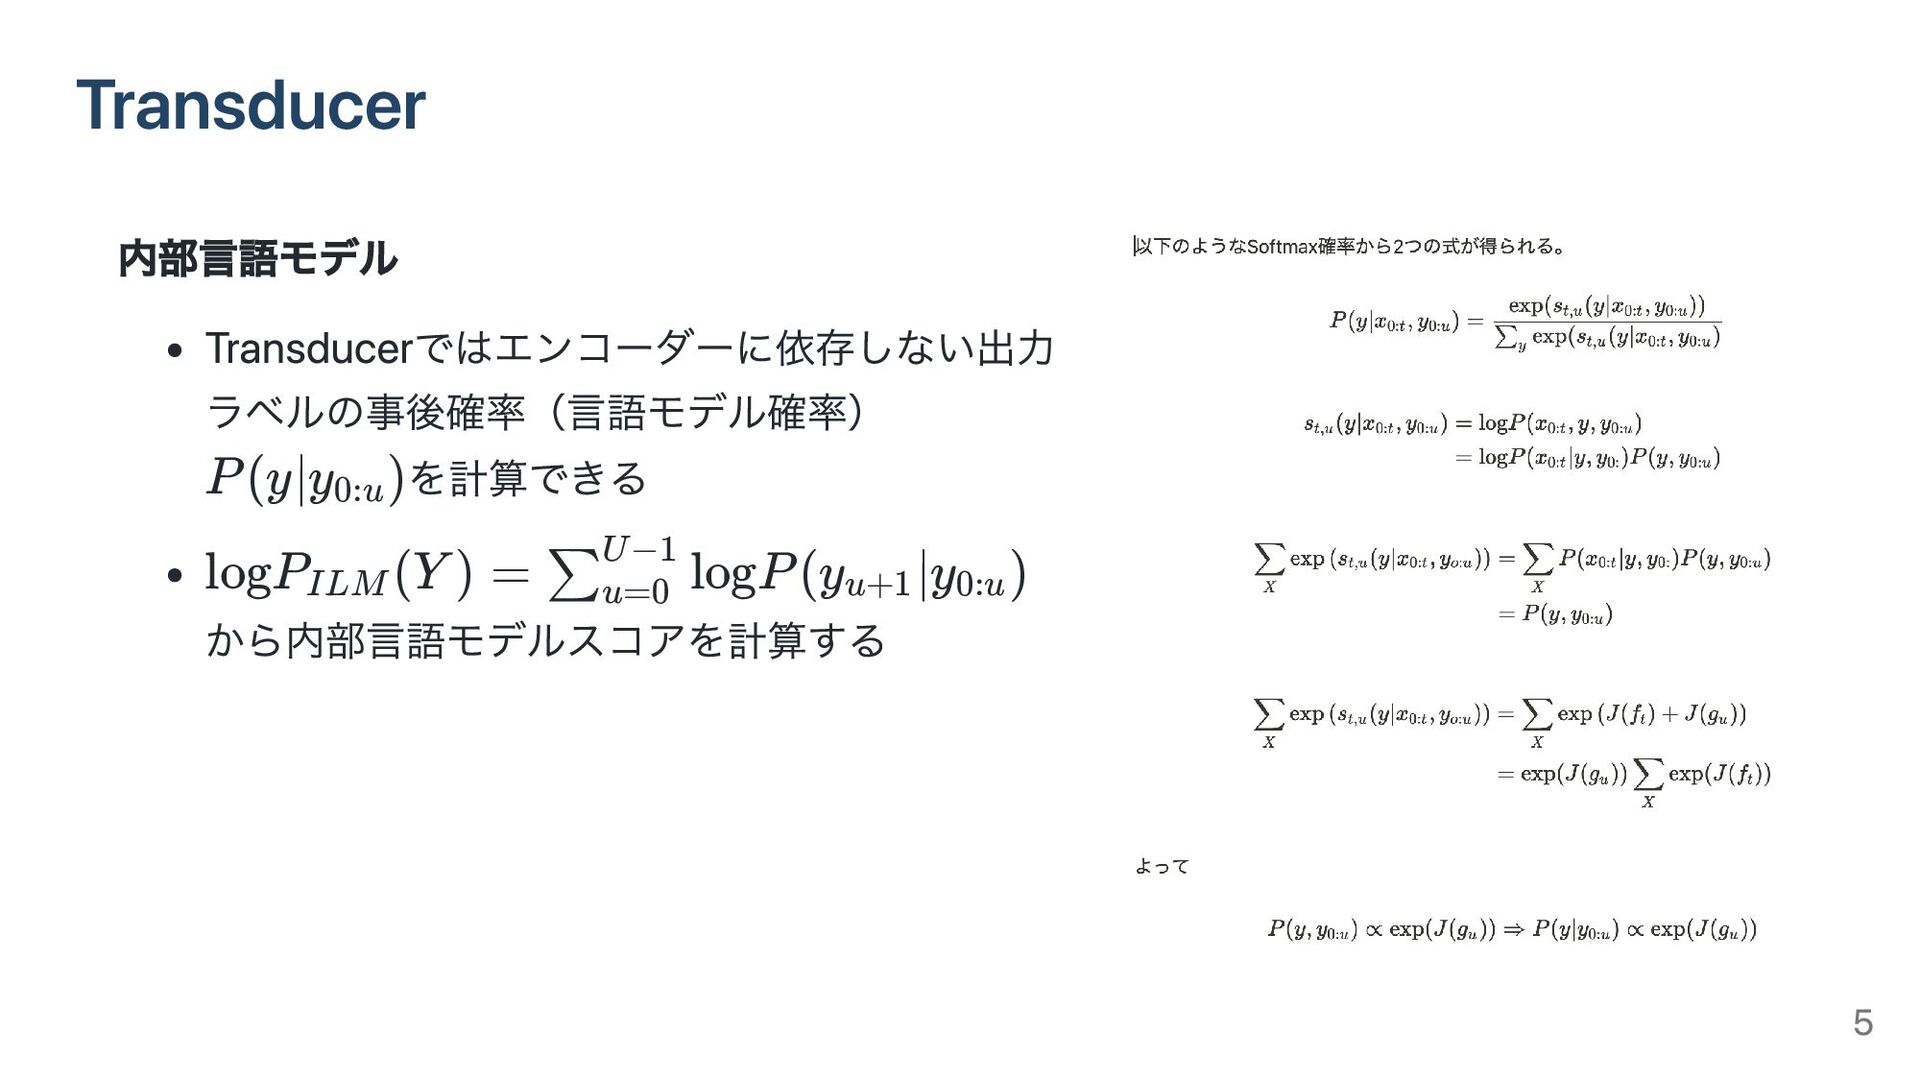
Transducer 内部言語モデル Transducerではエンコーダーに依存しない出力 ラベルの事後確率(言語モデル確率) を計算できる から内部言語モデルスコアを計算する P(y∣y ) 0:u
logP (Y ) = ILM logP(y ∣y ) ∑ u=0 U−1 u+1 0:u 5
HAT 6
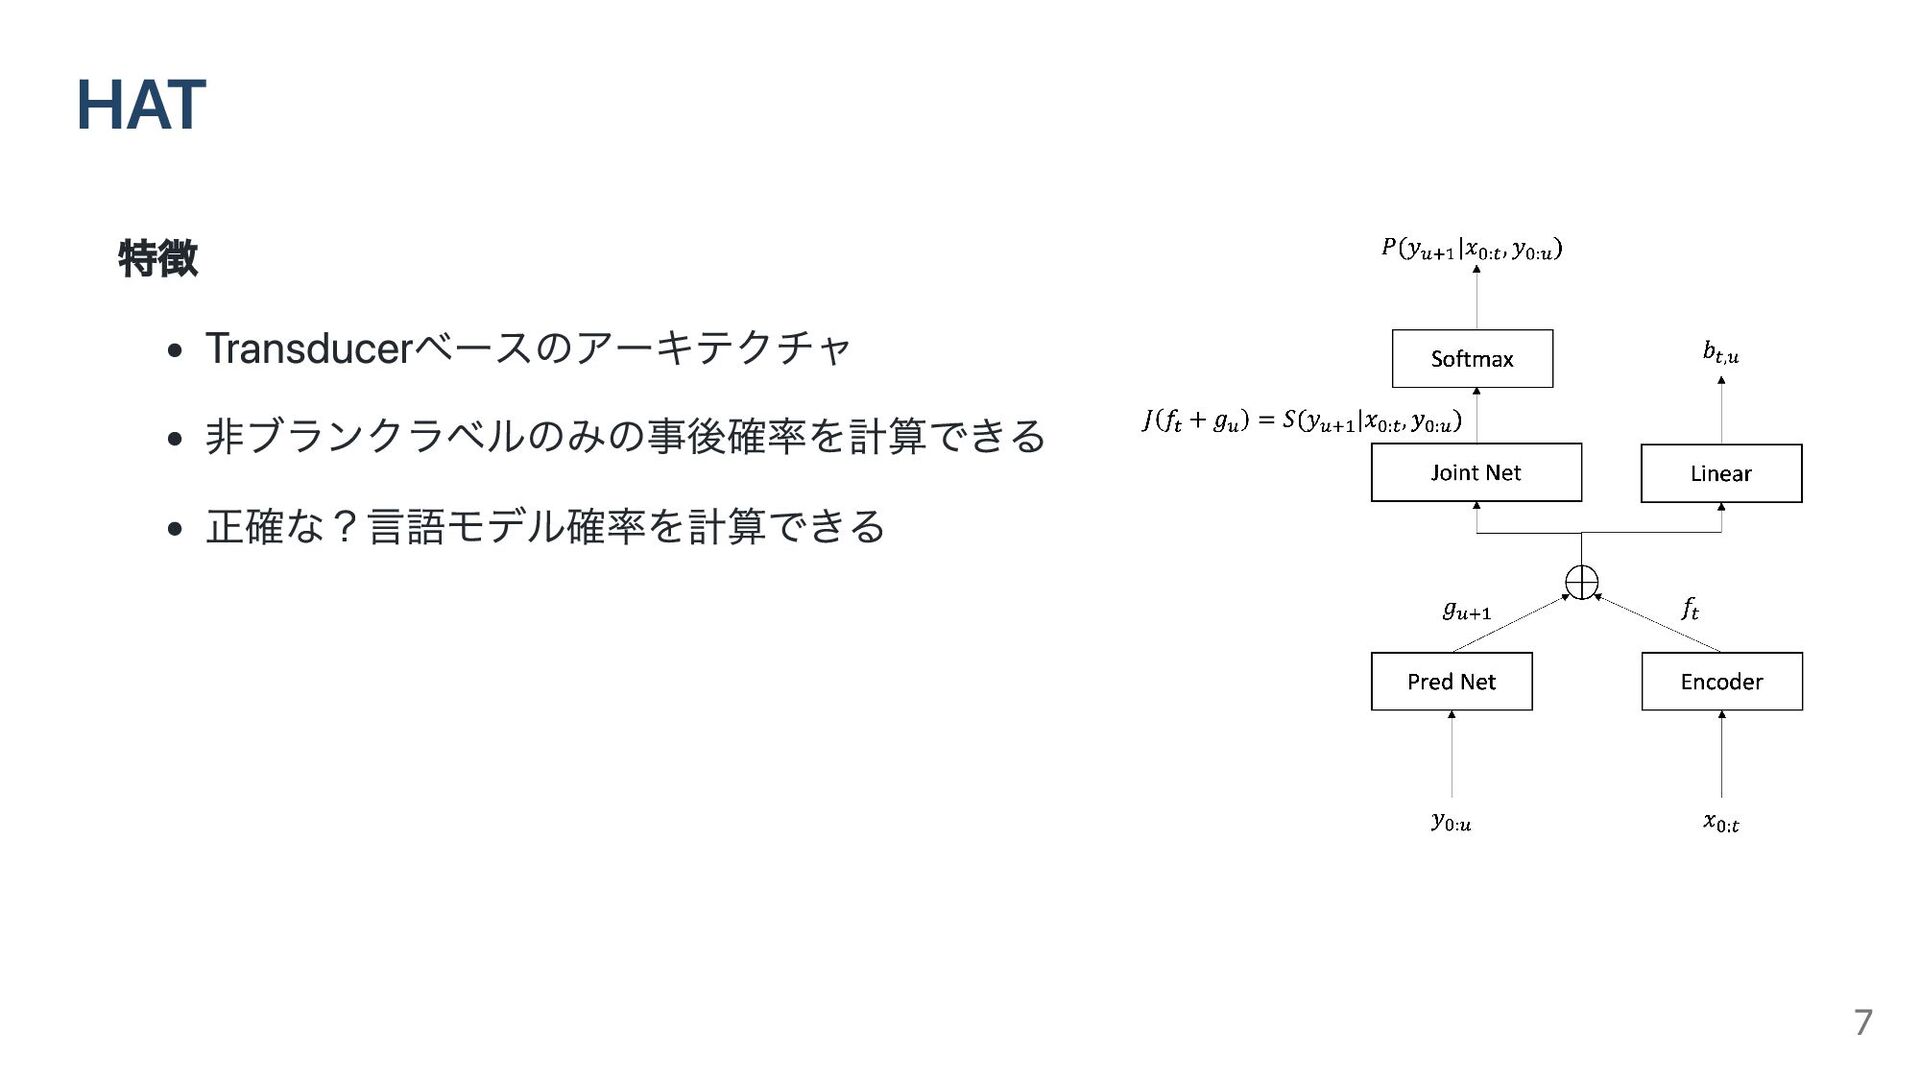
HAT 特徴 Transducerベースのアーキテクチャ 非ブランクラベルのみの事後確率を計算できる 正確な?言語モデル確率を計算できる 7
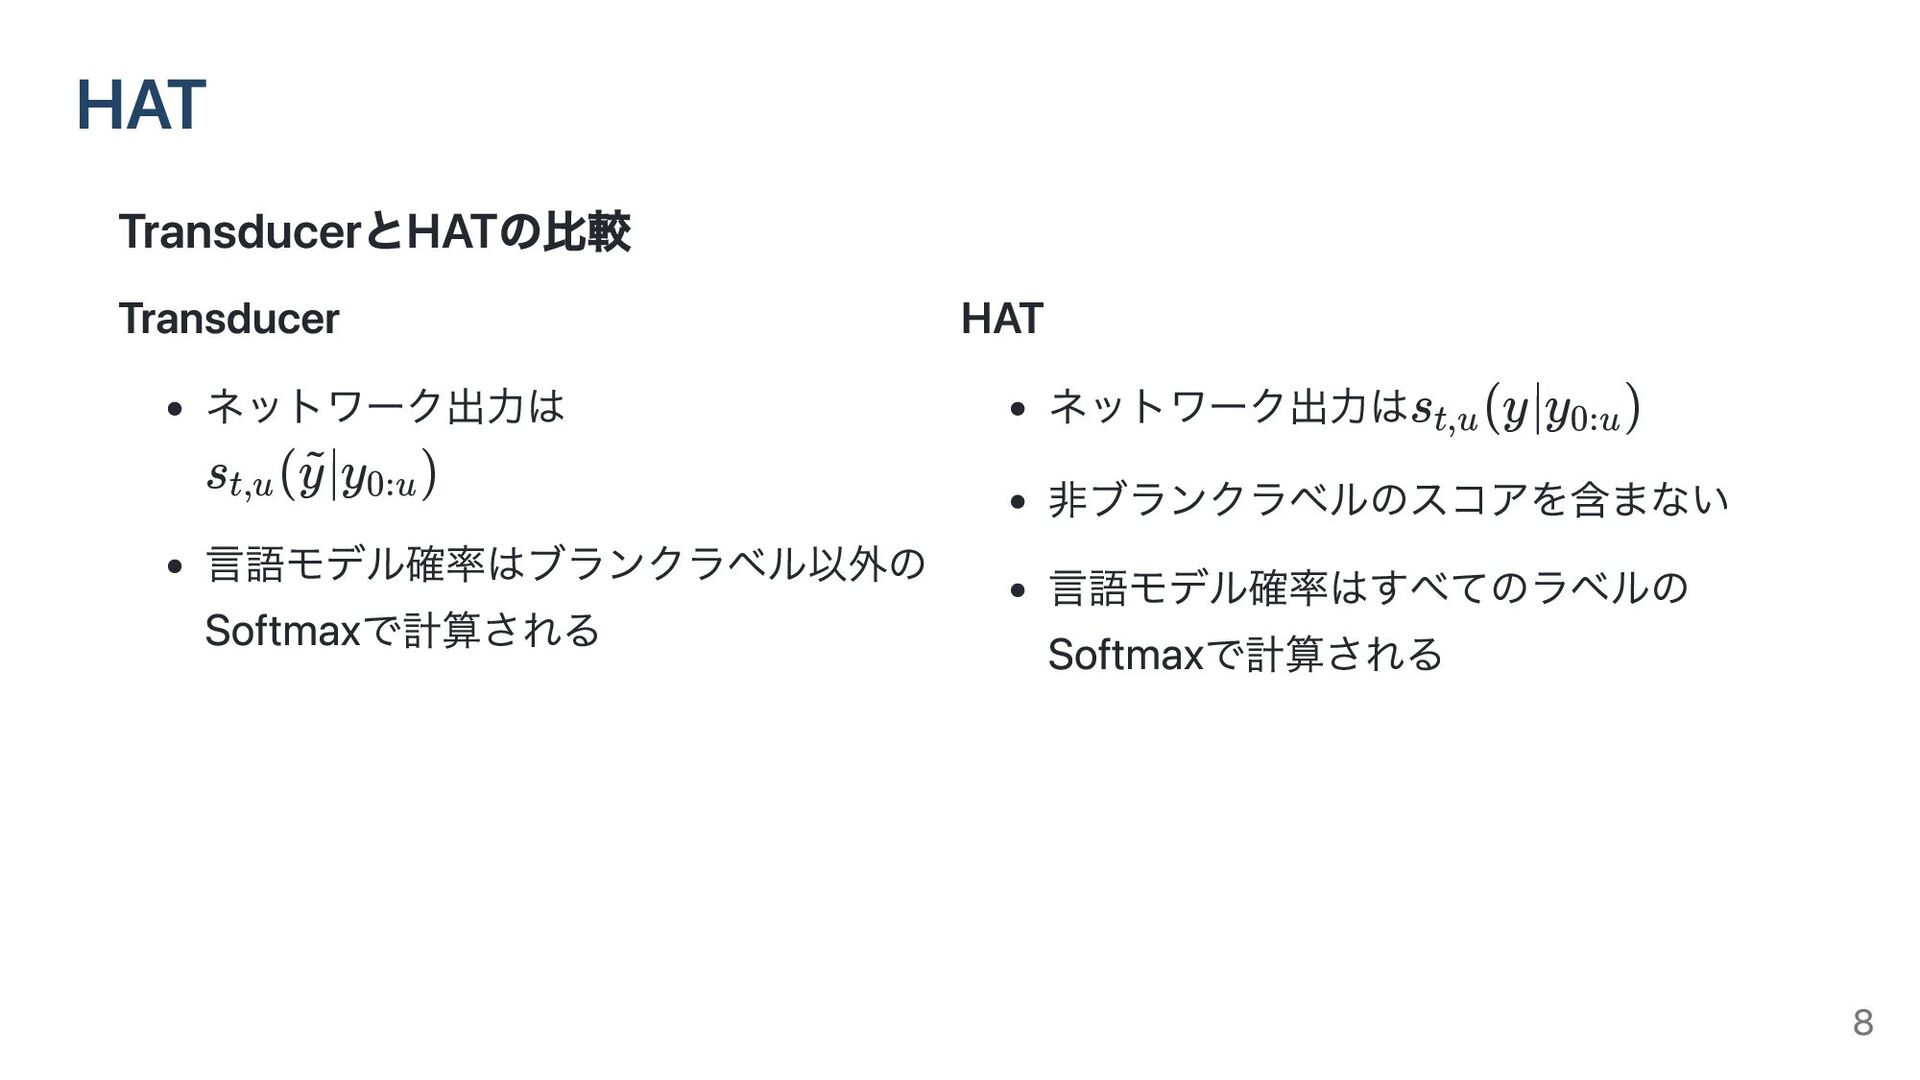
TransducerとHATの比較 HAT Transducer ネットワーク出力は 言語モデル確率はブランクラベル以外の Softmaxで計算される s (
∣y ) t,u y ~ 0:u HAT ネットワーク出力は 非ブランクラベルのスコアを含まない 言語モデル確率はすべてのラベルの Softmaxで計算される s (y∣y ) t,u 0:u 8
結果 9
実験設定 データセット: Google VoiceSearch Traffic 評価指標: WER アーキテクチャ: Encoder: 5layer,
2048cells/layerのLSTM Pred Net: 2layer, 256cells/layerのLSTM Joint Net: 1layerの線形層 入力: 対数メルスペクトログラム 結果 10
学習 強制アライメントを行い、教師ラベル(文章)の音素列を得る 各モデルは42種類の音素の事後確率を予測 各モデル単体で学習を行う(学習時は外部言語モデルを利用しない) 推論 各モデルを音響モデルとして使用 WFSTとして発音辞書・外部言語モデルを組み合わせてデコーディング 結果 11
各手法のデコード方法 Cross-Entropy CTC, RNN-T HAT 結果 = y ~∗
argmax λ log P(x ∣ ) + y ~ 1 (∏ t=1 T t y ~ t ) logP (B( )) LM y ~ = y ~∗ argmax λ logP ( ∣x) + y ~ 1 ′ y ~ logP (B( )) + LM y ~ λ v( ) 2 y ~ = y ~∗ argmax λ logP( ∣x) + y ~ 1 y ~ logP (B( )) − LM y ~ λ logP (B( )) 2 ILM y ~ 12
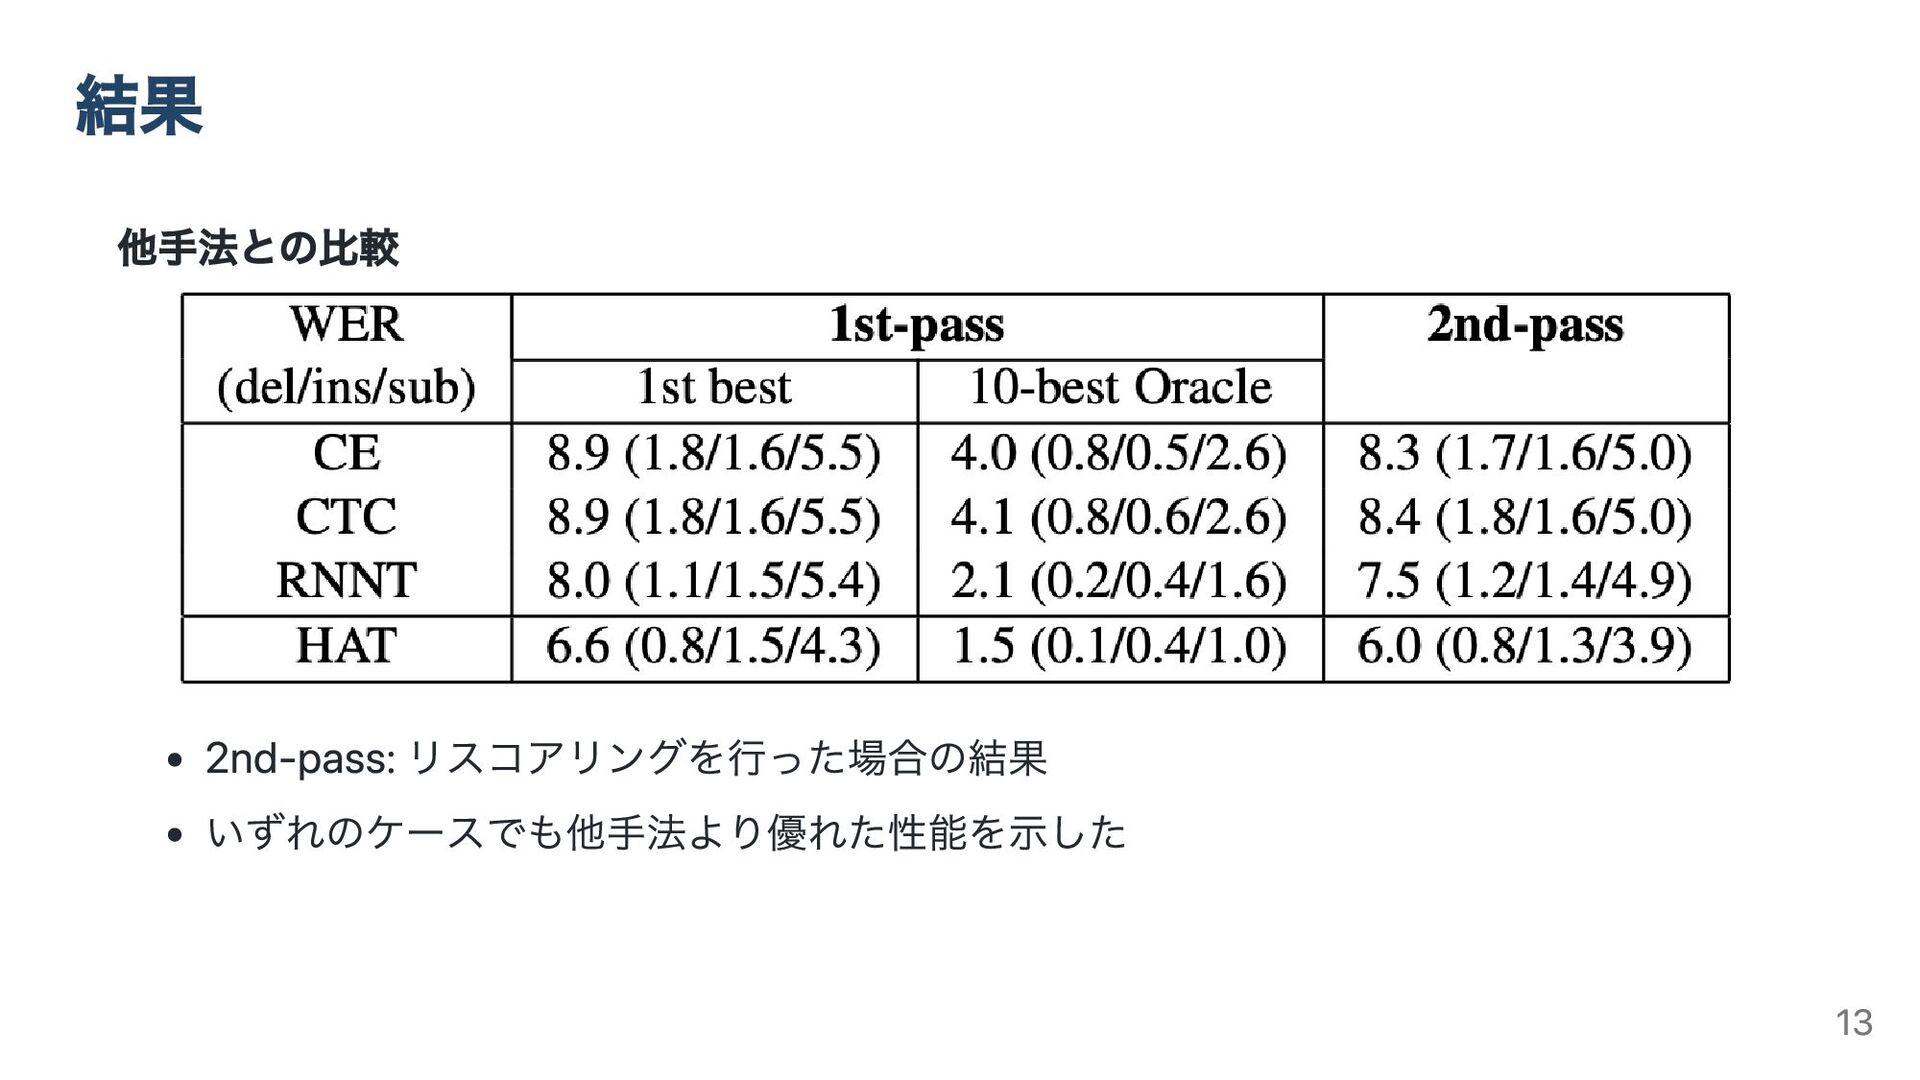
他手法との比較 2nd-pass: リスコアリングを行った場合の結果 いずれのケースでも他手法より優れた性能を示した 結果 13
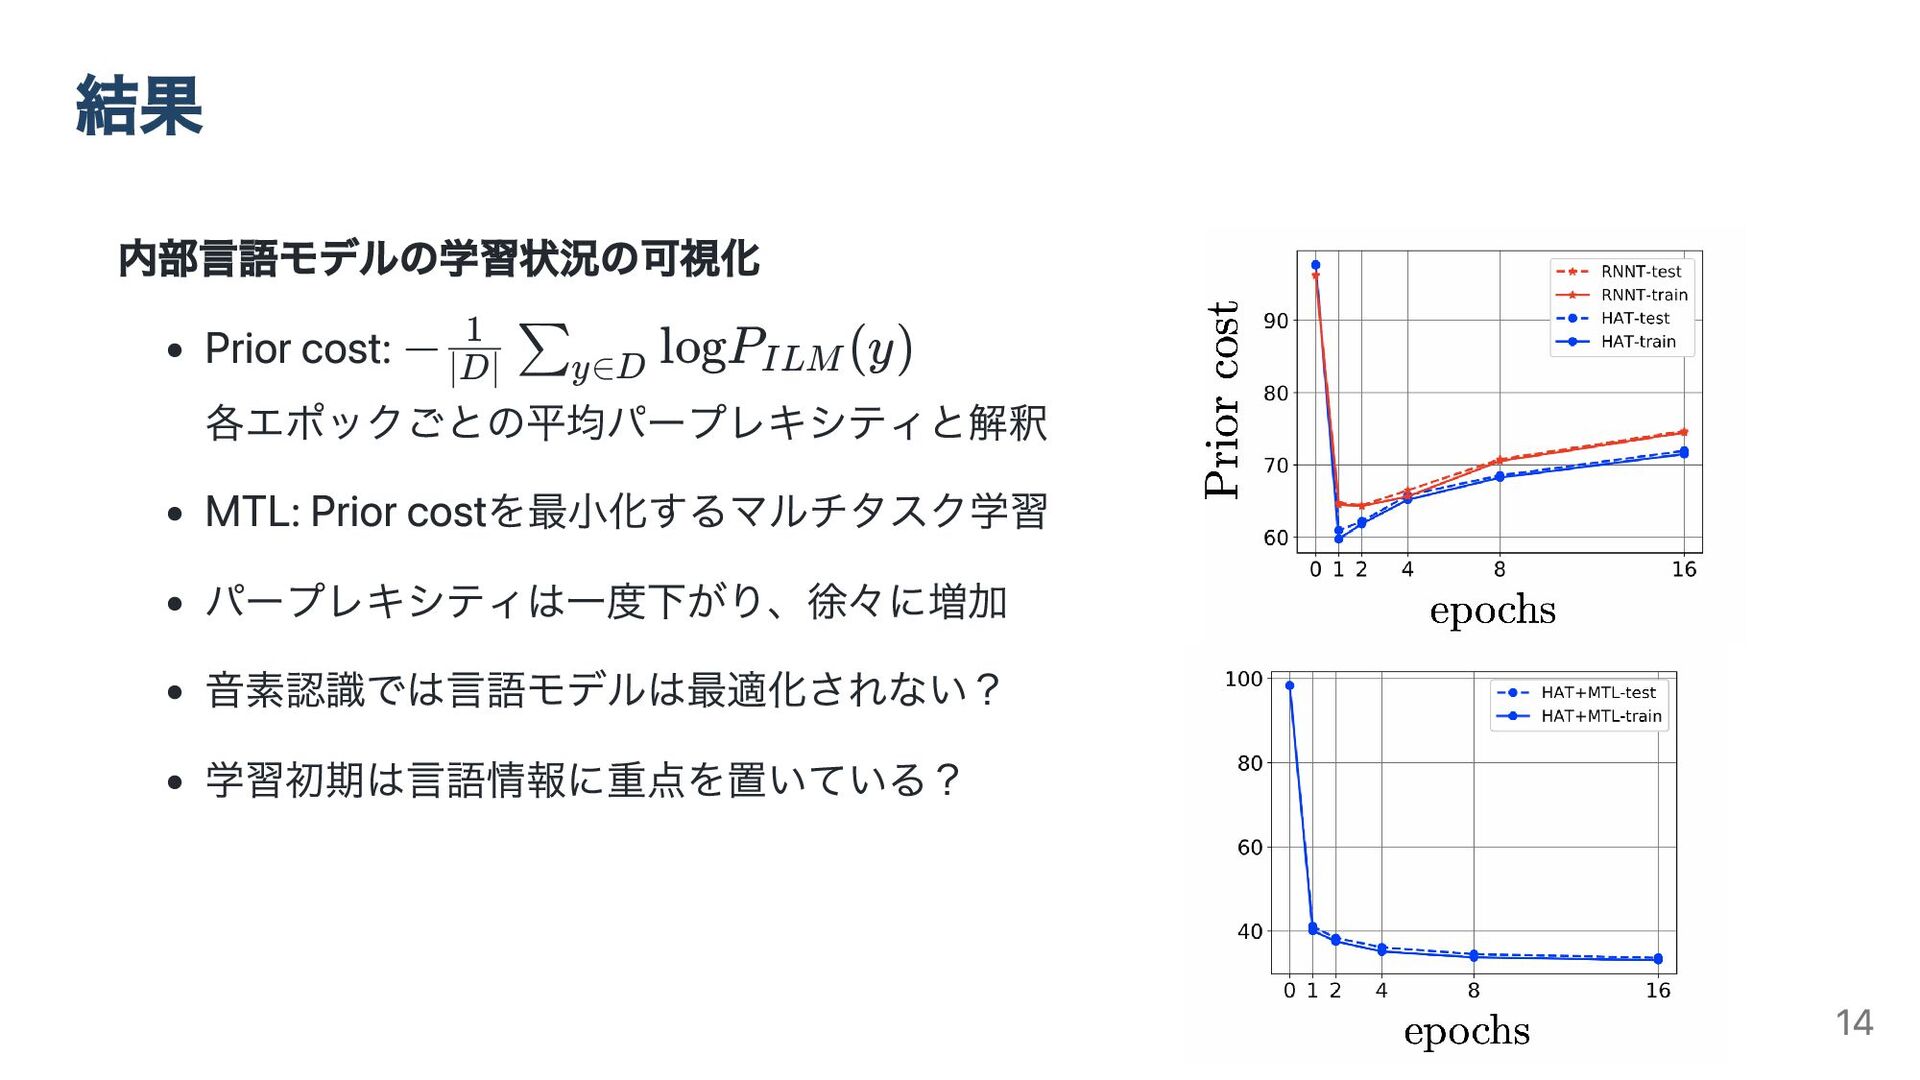
結果 内部言語モデルの学習状況の可視化 Prior cost: 各エポックごとの平均パープレキシティと解釈 MTL: Prior costを最小化するマルチタスク学習 パープレキシティは一度下がり、徐々に増加 音素認識では言語モデルは最適化されない?
学習初期は言語情報に重点を置いている? − logP (y) ∣D∣ 1 ∑ y∈D ILM 14
結果 内部言語モデルの寄与率とWER HAT 付近で最も良い性能 ただのShallowFusionではなく、内部言語 モデルの影響を取り除くことが重要 HAT+MTL Prior costを最小化しているが性能はあまり 向上していない
よい内部言語モデルを構築することは重要 ではないということ? λ = 2 1 15
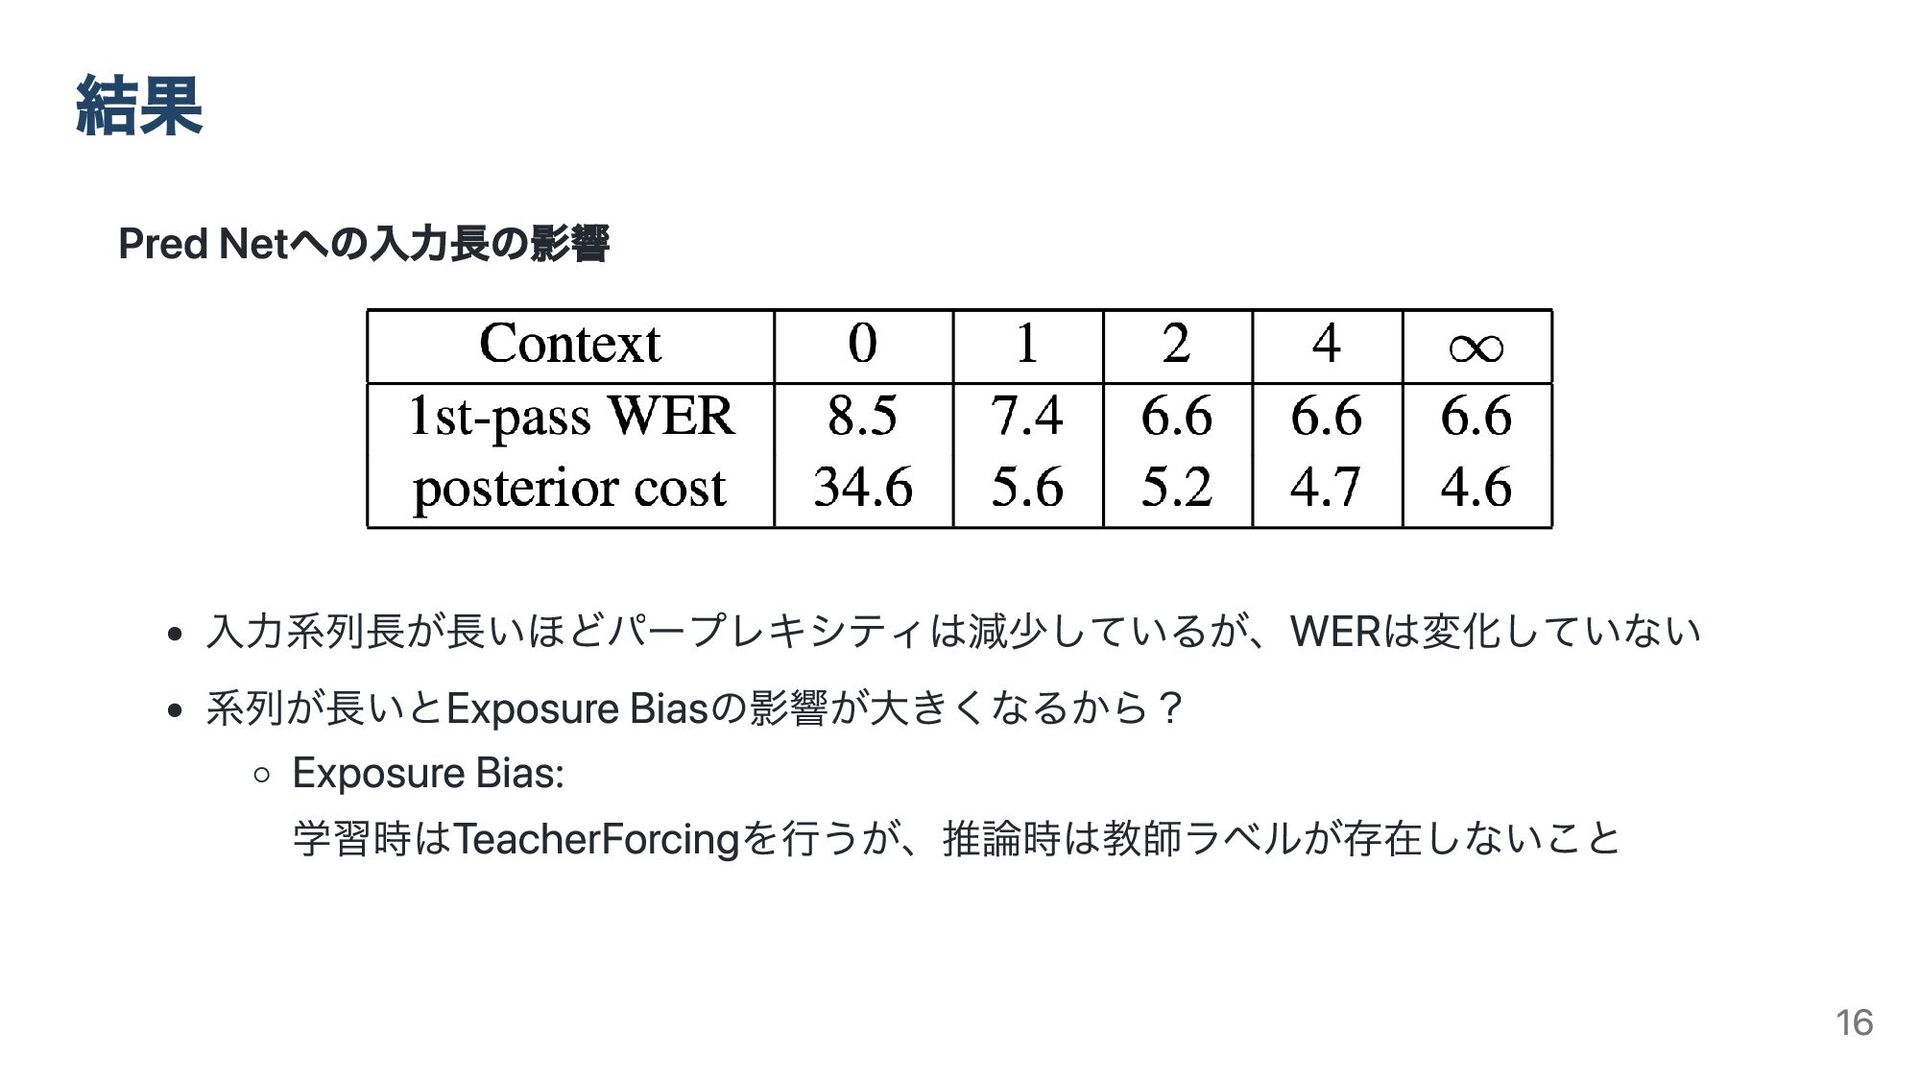
Pred Netへの入力長の影響 入力系列長が長いほどパープレキシティは減少しているが、WERは変化していない 系列が長いとExposure Biasの影響が大きくなるから? Exposure Bias: 学習時はTeacherForcingを行うが、推論時は教師ラベルが存在しないこと 結果 16
まとめ 17
E2Eモデルを音響モデルとして利用するためのアプローチであるHATを提案 内部言語モデルのパープレキシティを評価できるようになった →外部言語モデルの必要性の判断基準となる まとめ 18

 Your Podcast. Everywhere. Effortlessly.


 shibukazu
 tsantalis
 satai
 hariby
 youten622
 takehaya
 koide3
 analokmaus
 s_mizuki_nlp
 hotchpotch
 kinoue_smarthr
 matsumooon
 chriscoyier
 samtorres
 samlambert
 aleyda
 inesmontani
 tmiket
 codingconduct
 tammyeverts
 addyosmani
 skipperchong
 kastner
 destraynor