Share
Embed
The Theory of Relational Databases
Sperasoft workshop presentation: The Theory of Relational Databases
Sperasoft
July 19, 2016
Transcript
13 slides
-
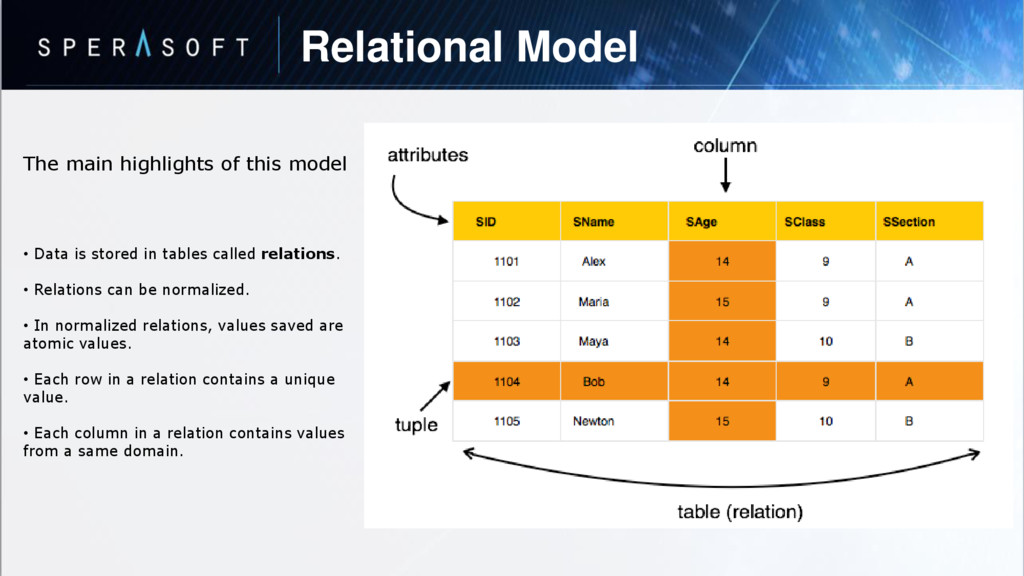
Relational Model The main highlights of this model • Data
is stored in tables called relations. • Relations can be normalized. • In normalized relations, values saved are atomic values. • Each row in a relation contains a unique value. • Each column in a relation contains values from a same domain. -
Concepts Concepts Tables − In relational data model, relations are
saved in the format of Tables. This format stores the relation among entities. A table has rows and columns, where rows represents records and columns represent the attributes. Tuple − A single row of a table, which contains a single record for that relation is called a tuple. Relation instance − A finite set of tuples in the relational database system represents relation instance. Relation instances do not have duplicate tuples. Relation schema − A relation schema describes the relation name (table name), attributes, and their names. Relation key − Each row has one or more attributes, known as relation key, which can identify the row in the relation (table) uniquely. Attribute domain − Every attribute has some pre-defined value scope, known as attribute domain. -
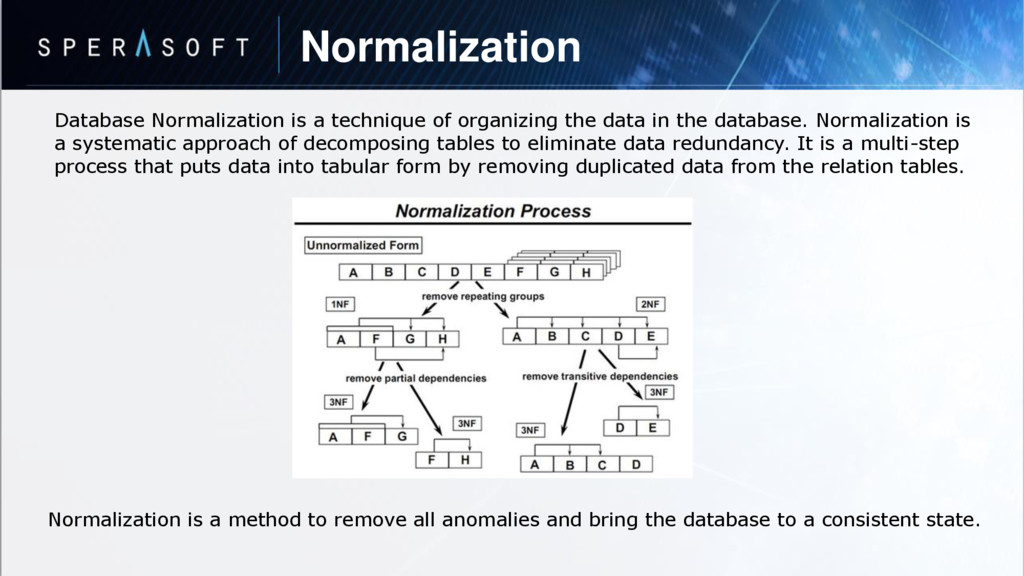
Normalization Database Normalization is a technique of organizing the data
in the database. Normalization is a systematic approach of decomposing tables to eliminate data redundancy. It is a multi-step process that puts data into tabular form by removing duplicated data from the relation tables. Normalization is a method to remove all anomalies and bring the database to a consistent state. -
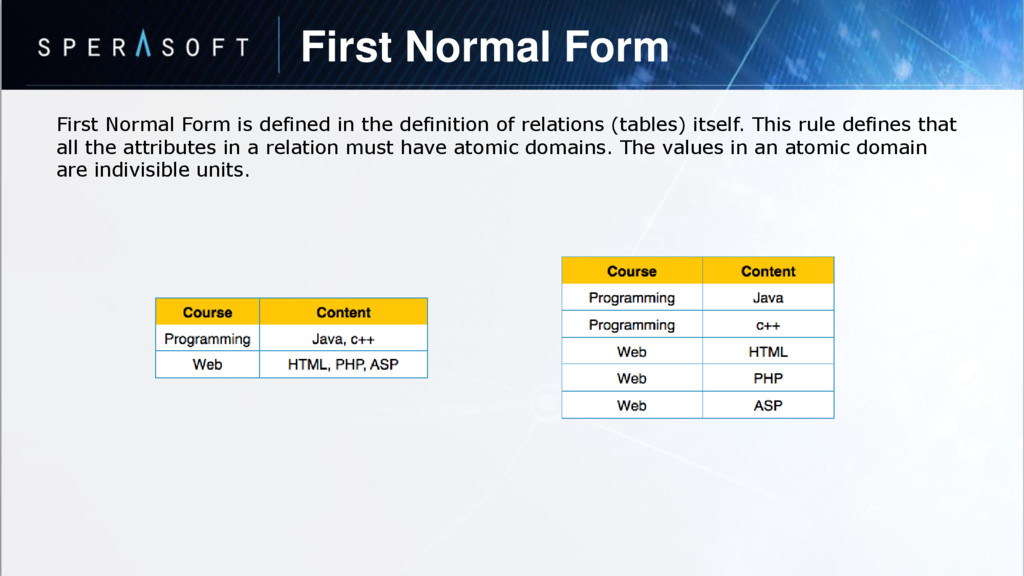
First Normal Form First Normal Form is defined in the
definition of relations (tables) itself. This rule defines that all the attributes in a relation must have atomic domains. The values in an atomic domain are indivisible units. -
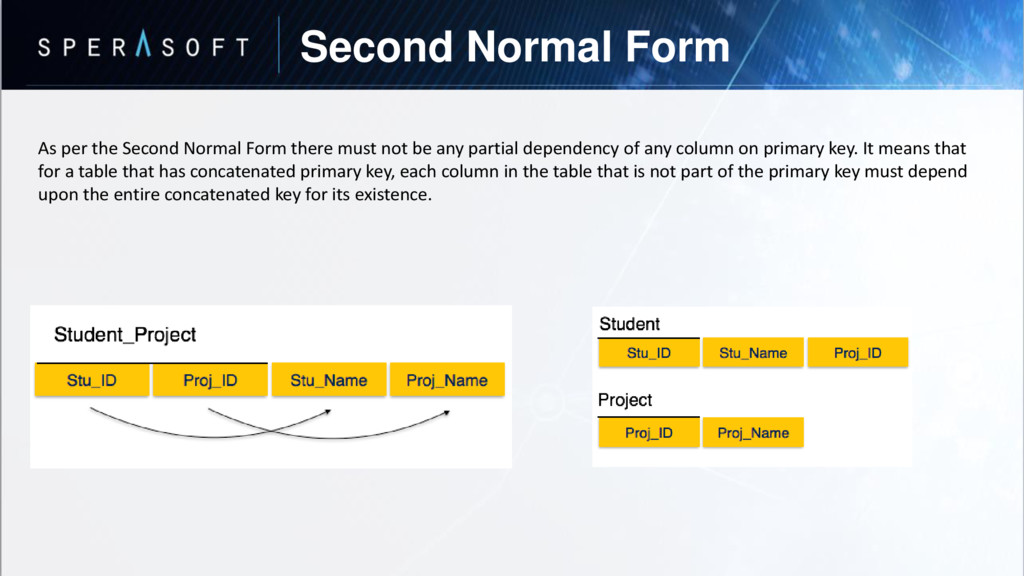
Second Normal Form As per the Second Normal Form there
must not be any partial dependency of any column on primary key. It means that for a table that has concatenated primary key, each column in the table that is not part of the primary key must depend upon the entire concatenated key for its existence. -
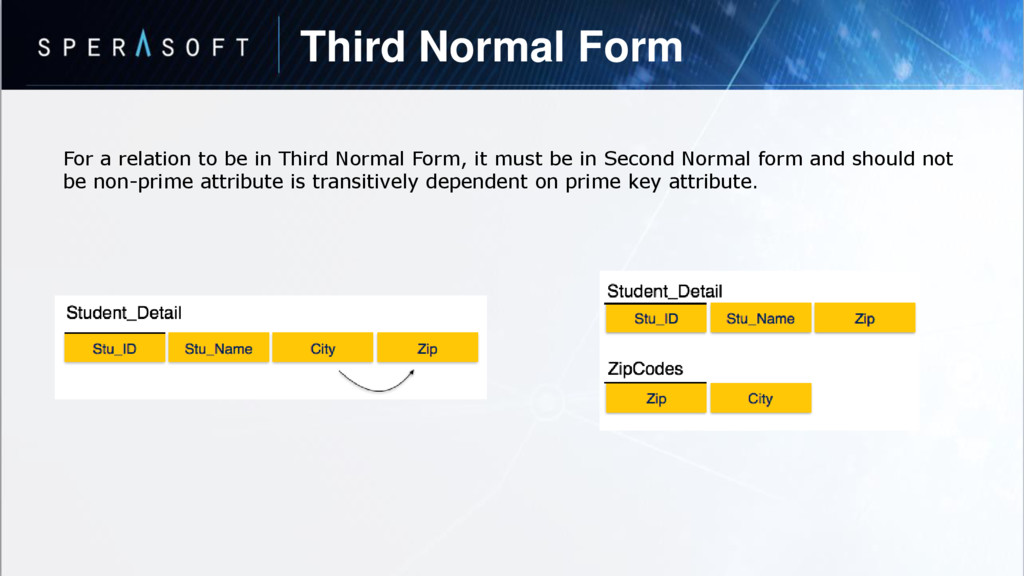
Third Normal Form For a relation to be in Third
Normal Form, it must be in Second Normal form and should not be non-prime attribute is transitively dependent on prime key attribute. -
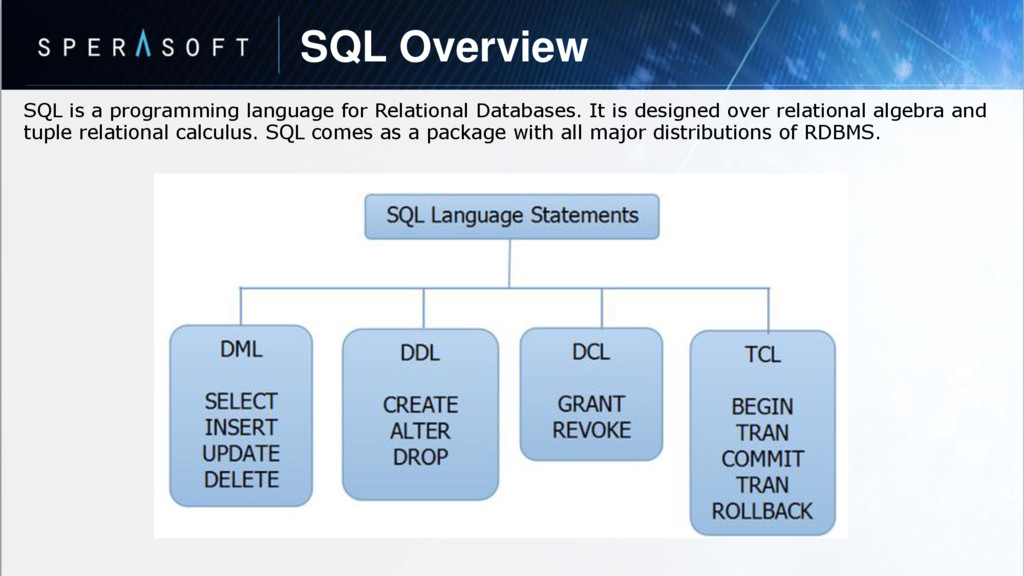
SQL Overview SQL is a programming language for Relational Databases.
It is designed over relational algebra and tuple relational calculus. SQL comes as a package with all major distributions of RDBMS. -
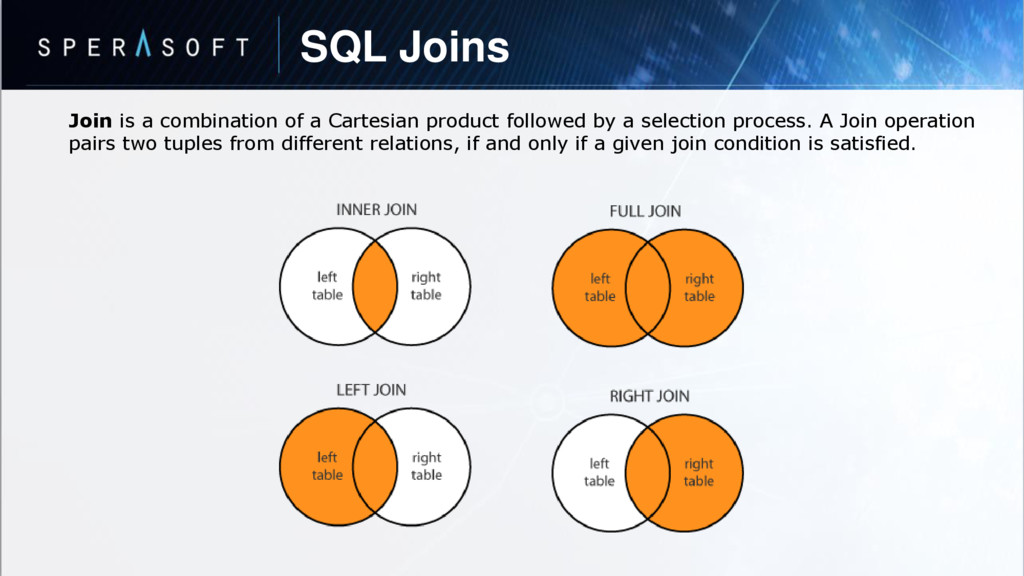
SQL Joins Join is a combination of a Cartesian product
followed by a selection process. A Join operation pairs two tuples from different relations, if and only if a given join condition is satisfied. -
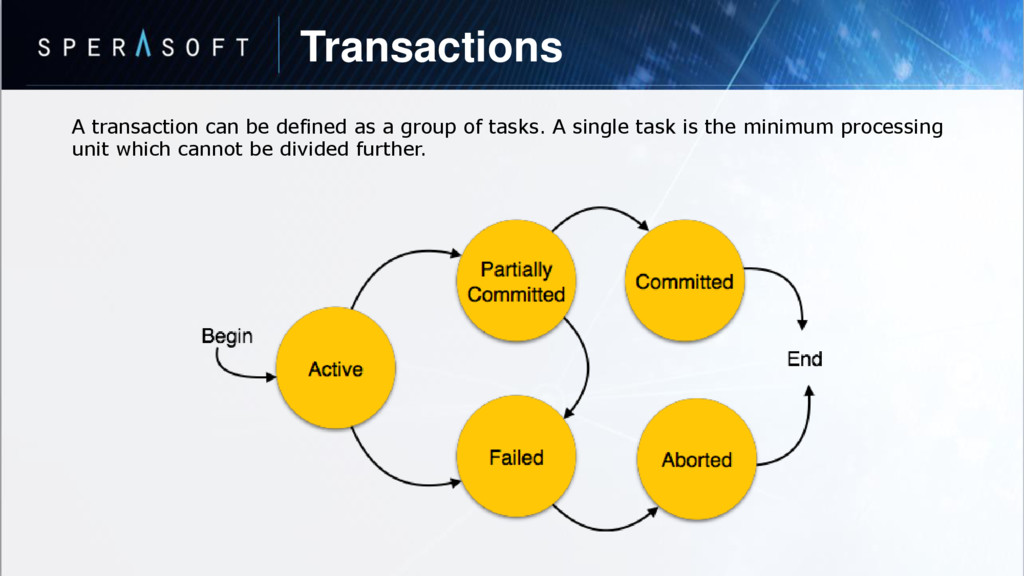
Transactions A transaction can be defined as a group of
tasks. A single task is the minimum processing unit which cannot be divided further. -
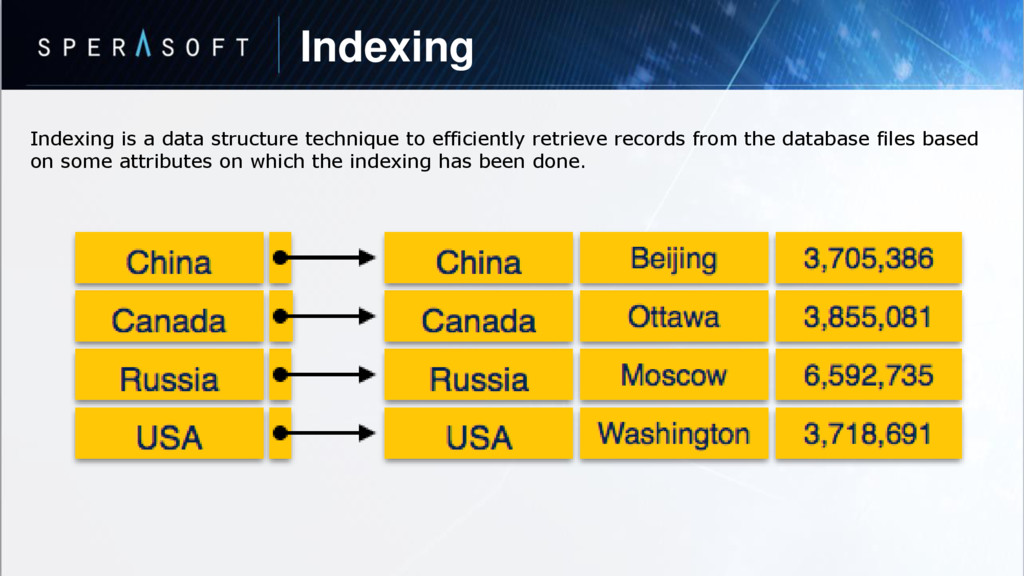
Indexing Indexing is a data structure technique to efficiently retrieve
records from the database files based on some attributes on which the indexing has been done. -
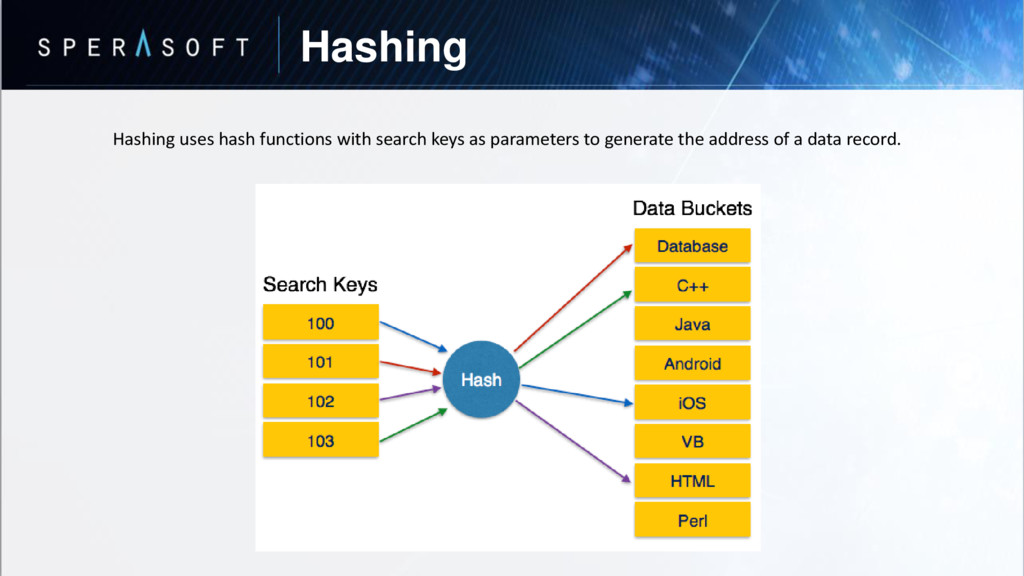
Hashing Hashing uses hash functions with search keys as parameters
to generate the address of a data record.