Share
Embed
Introduction to Elasticsearch
Sperasoft talks about main principles of using Elastcisearch search server
elasticsearch, queries, search, server, lucene. RESTful, JSON, index, Apache, crossplatform
Sperasoft
September 04, 2014
Transcript
47 slides
-
Search lucene inside ranked searching proximity matches
wildcard queries range queries sorting typo-tolerant flexible faceting simultaneous update and searching high performance highlighting aggregations geolocations -
Elasticsearch distributed hi available RESTful crossplatform
open source apache 2 licenced powerful -
Dealing with human language Remove diacritics like ´, ^ and
¨ (normalizing) Get root form of a word (stemming) number Tense Gender Aspect (ate, eaten) etc remove stopwords from search Take synonyms into account Check for misspelling (fuzzy matching) Check for homophones -
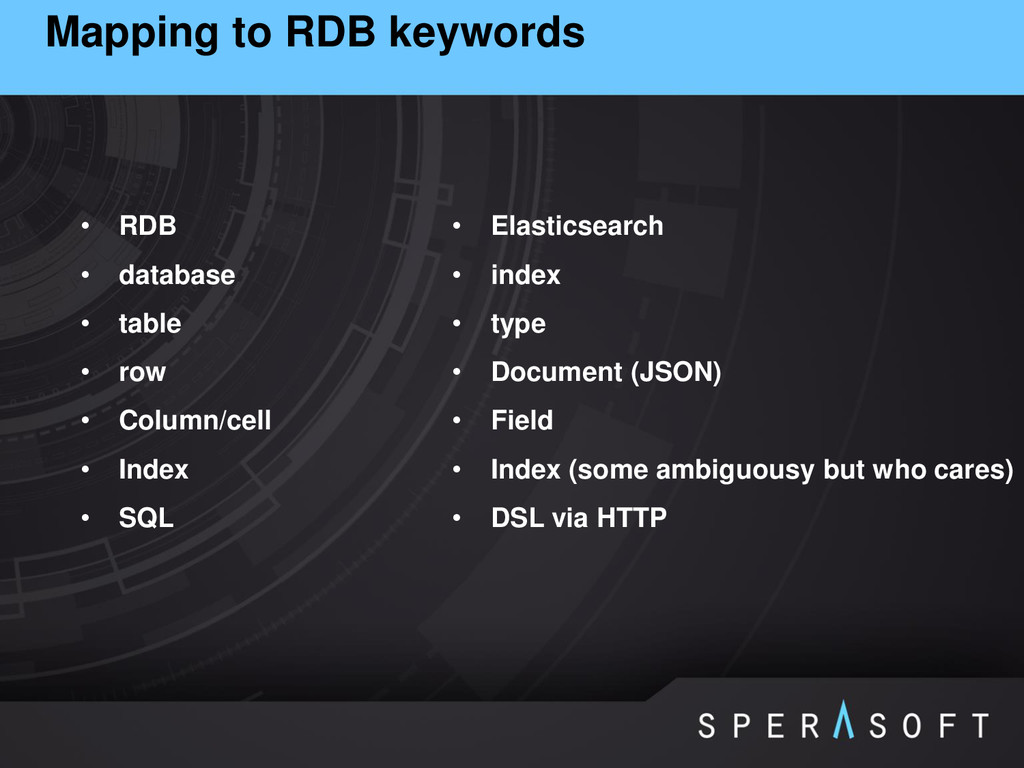
Mapping to RDB keywords • RDB • database • table
• row • Column/cell • Index • SQL • Elasticsearch • index • type • Document (JSON) • Field • Index (some ambiguousy but who cares) • DSL via HTTP -
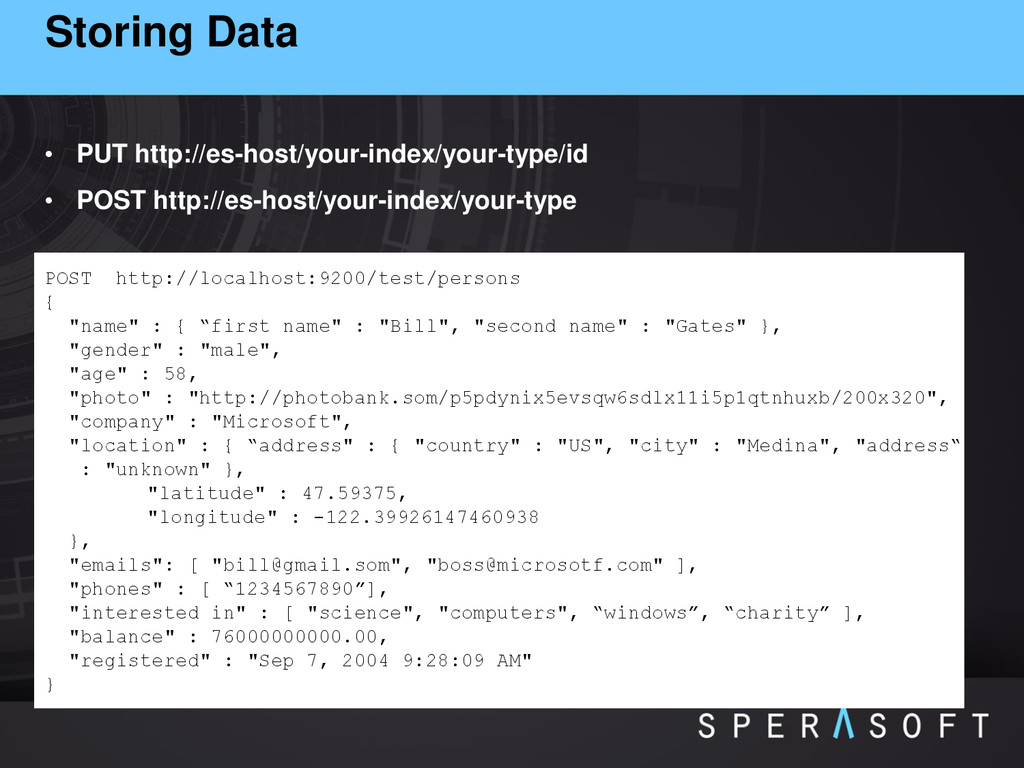
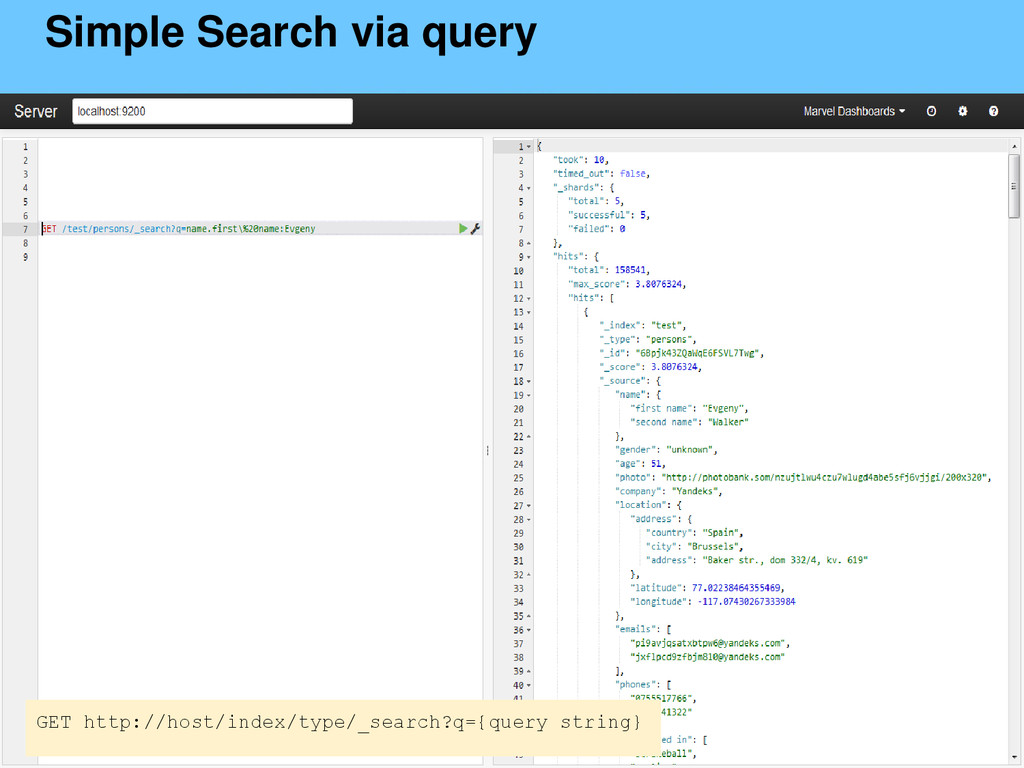
Storing Data • PUT http://es-host/your-index/your-type/id • POST http://es-host/your-index/your-type POST http://localhost:9200/test/persons
{ "name" : { “first name" : "Bill", "second name" : "Gates" }, "gender" : "male", "age" : 58, "photo" : "http://photobank.som/p5pdynix5evsqw6sdlx11i5p1qtnhuxb/200x320", "company" : "Microsoft", "location" : { “address" : { "country" : "US", "city" : "Medina", "address“ : "unknown" }, "latitude" : 47.59375, "longitude" : -122.39926147460938 }, "emails": [ "[email protected]", "[email protected]" ], "phones" : [ “1234567890”], "interested in" : [ "science", "computers", “windows”, “charity” ], "balance" : 76000000000.00, "registered" : "Sep 7, 2004 9:28:09 AM" } -
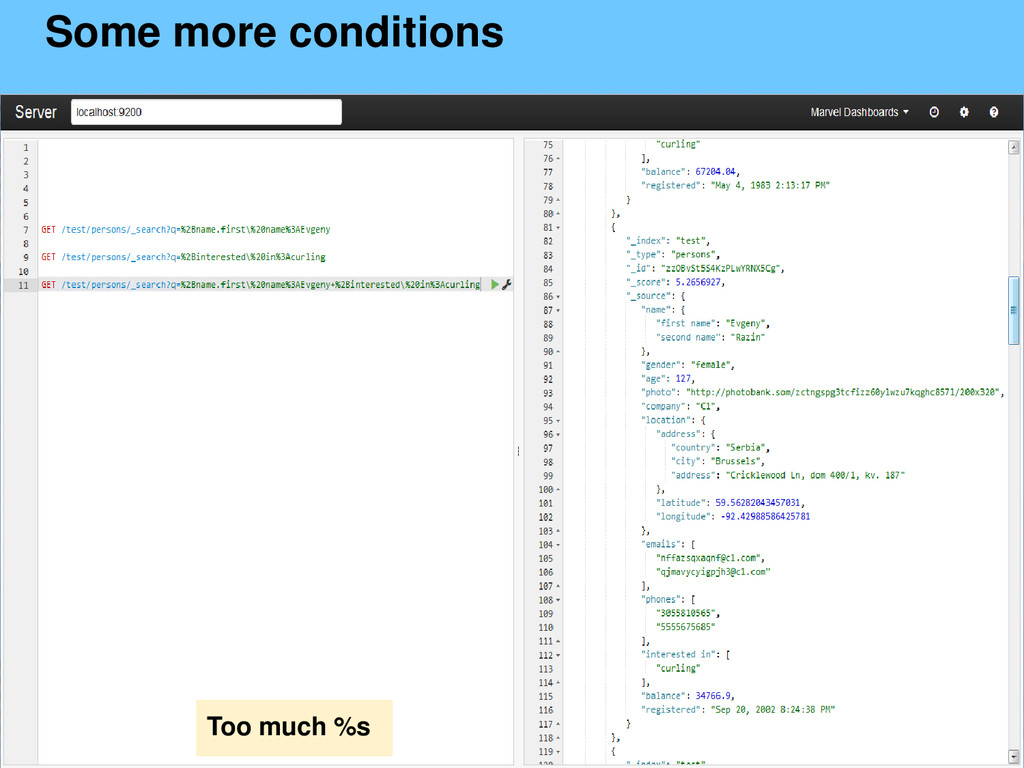
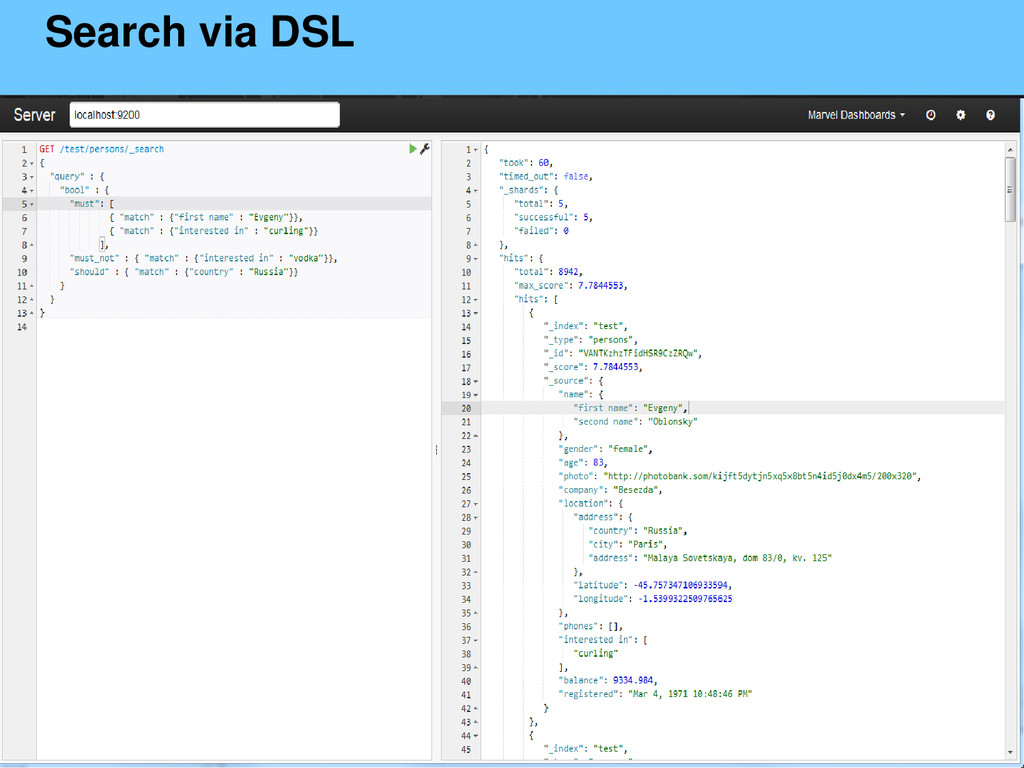
Some more conditions first name = Evgeny AND interested in
= curling: GET /test/persons/_search?q=%2Bname.first\%20name%3AEvgeny+%2Binterested\%20in%3Acurling Too much %s -
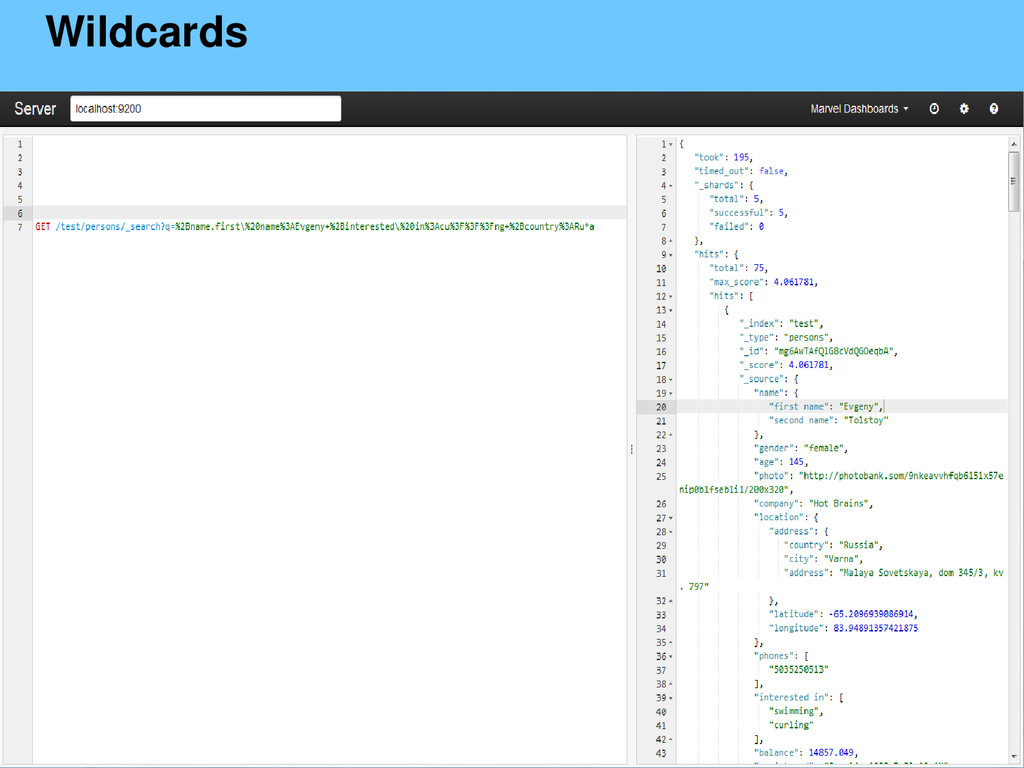
Wildcards first name = Evgeny AND interested in = cu???ng
AND country = Ru*a GET /test/persons/_search?q=%2Bname.first\%20name%3AEvgeny+%2Binterested\%20in%3Acu%3F%3 F%3Fng+%2Bcountry%3ARu*a -
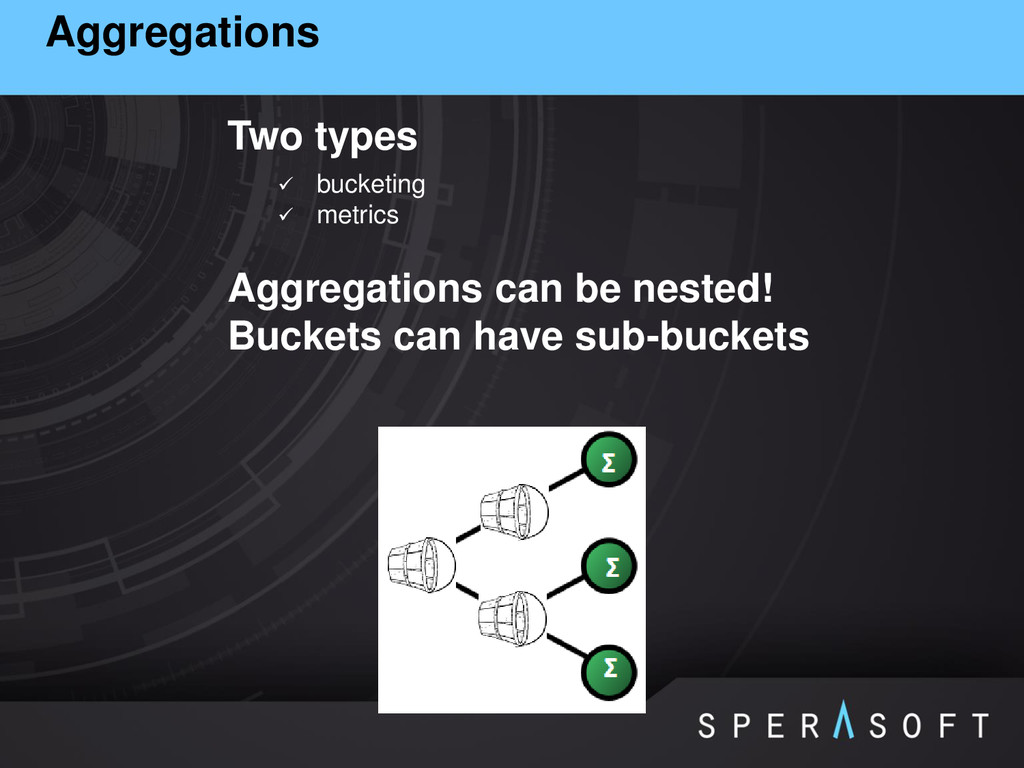
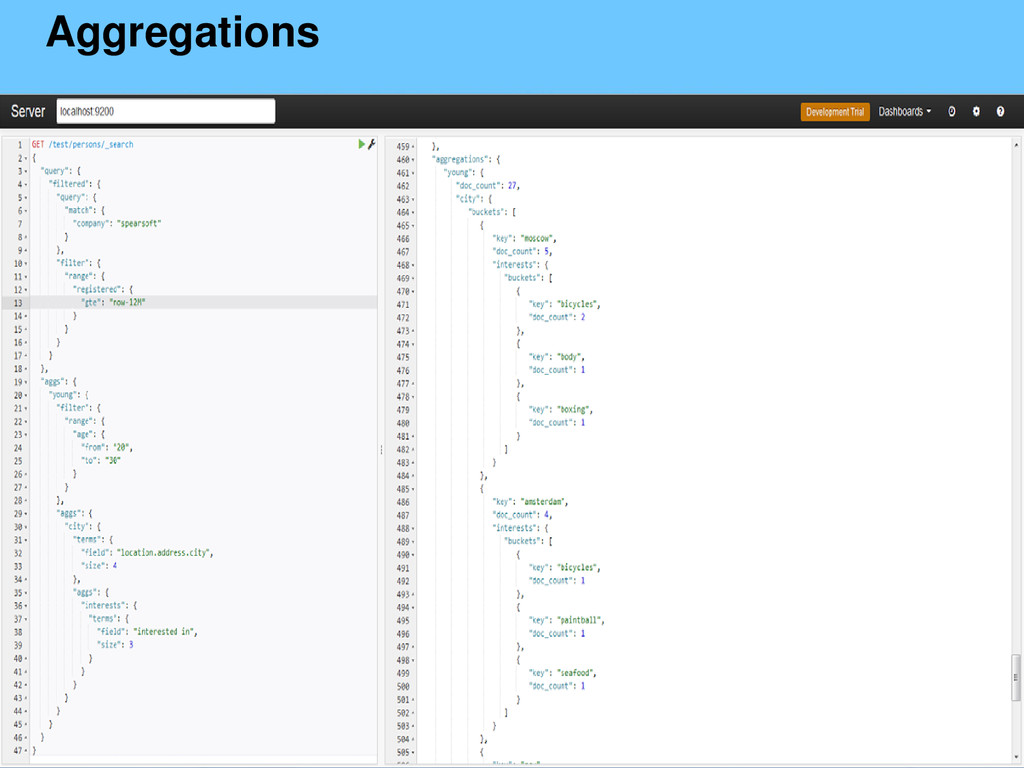
Aggregations Two types bucketing metrics Aggregations can be
nested! Buckets can have sub-buckets -
Have a question? Like this deck? Just follow us on
twitter @Sperasoft -
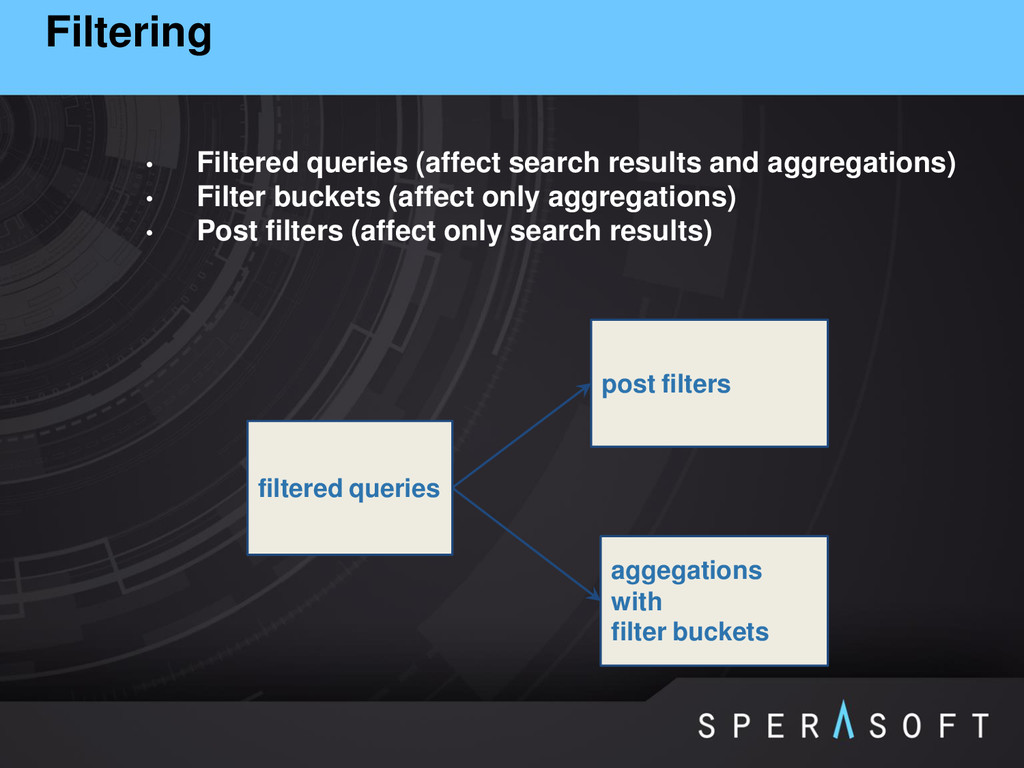
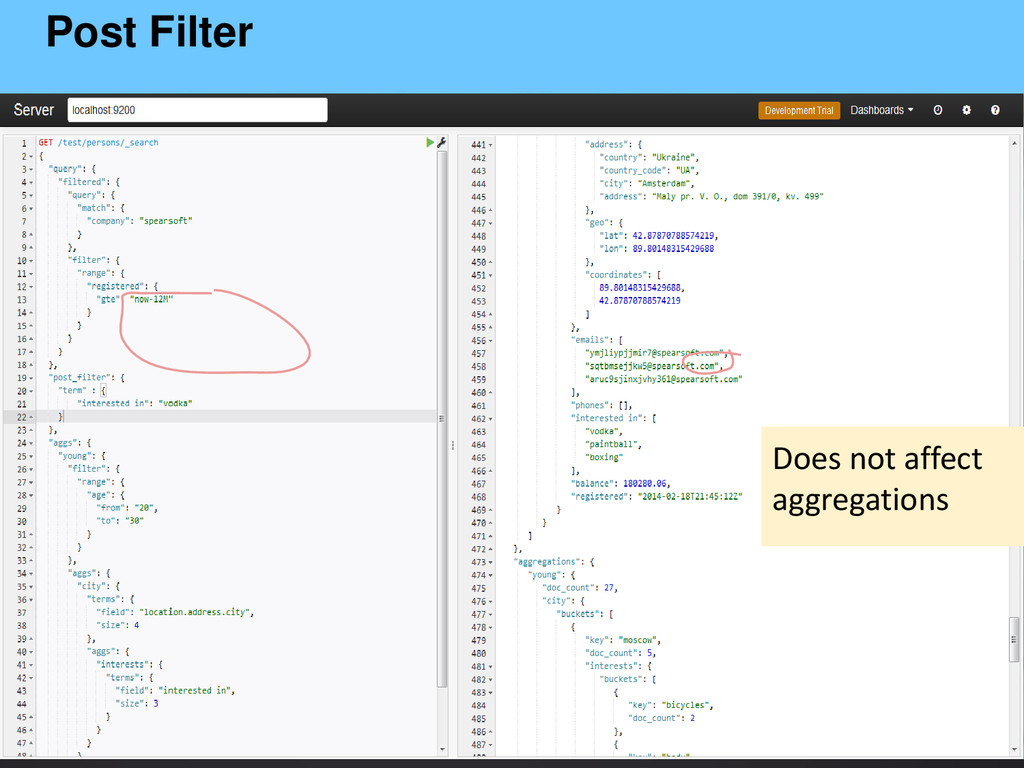
Filtering • Filtered queries (affect search results and aggregations) •
Filter buckets (affect only aggregations) • Post filters (affect only search results) filtered queries aggegations with filter buckets post filters -
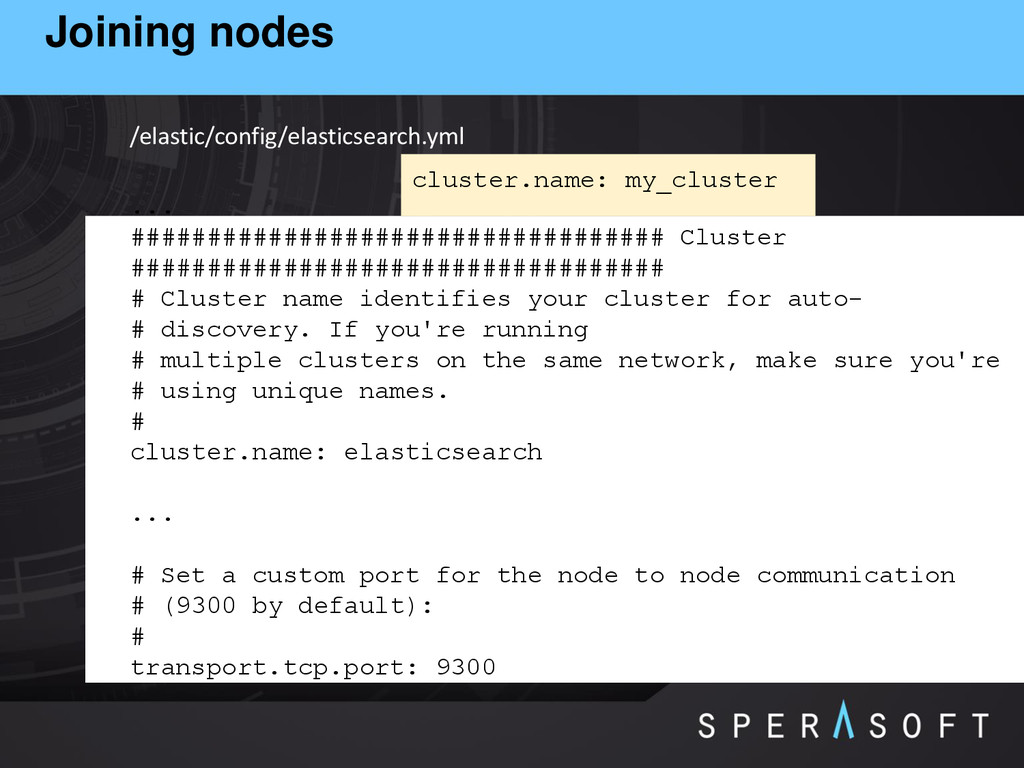
Joining nodes ... ################################### Cluster ################################### # Cluster name identifies
your cluster for auto- # discovery. If you're running # multiple clusters on the same network, make sure you're # using unique names. # cluster.name: elasticsearch ... # Set a custom port for the node to node communication # (9300 by default): # transport.tcp.port: 9300 /elastic/config/elasticsearch.yml cluster.name: my_cluster -
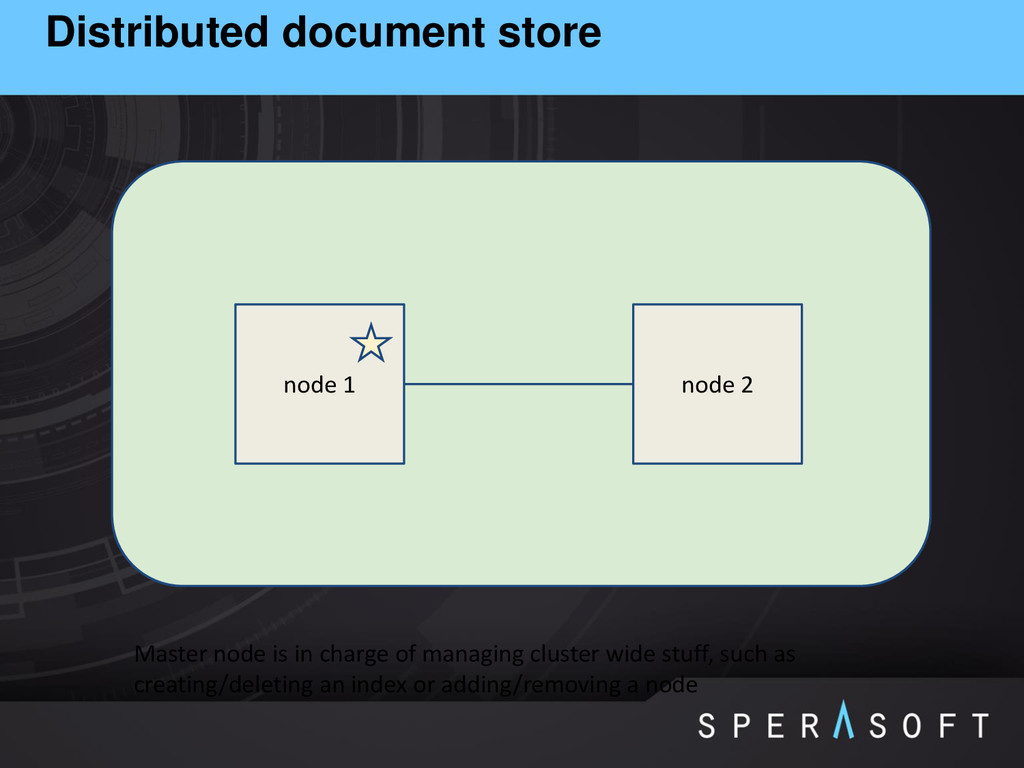
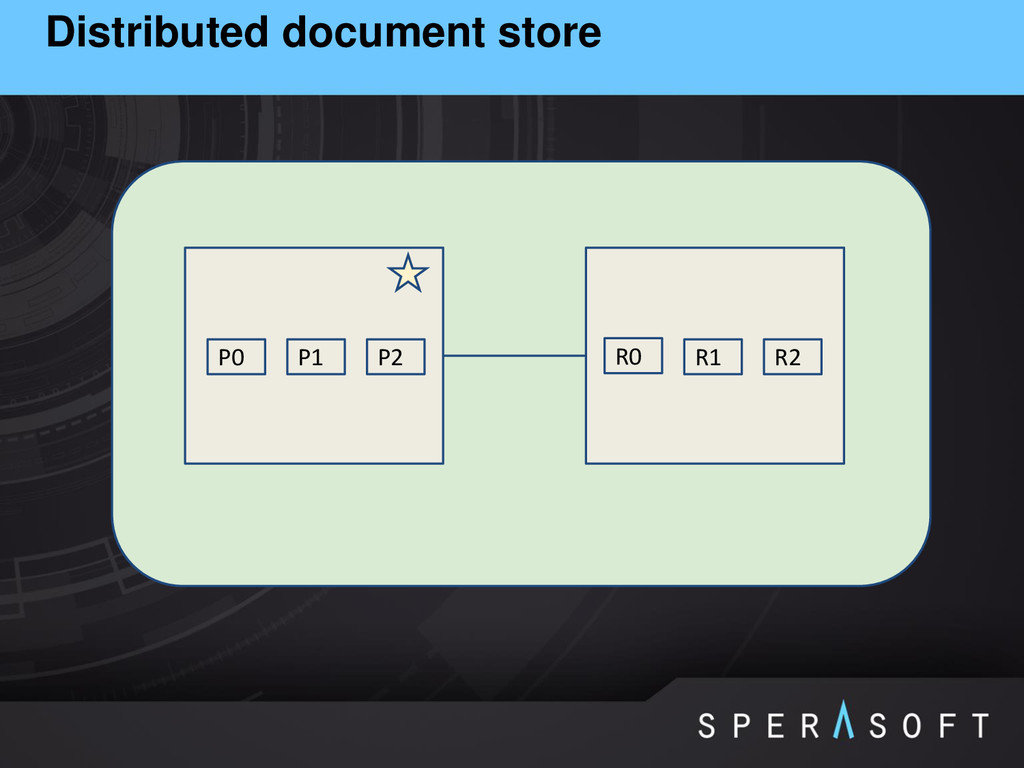
Distributed document store node 1 node 2 Master node is
in charge of managing cluster wide stuff, such as creating/deleting an index or adding/removing a node -
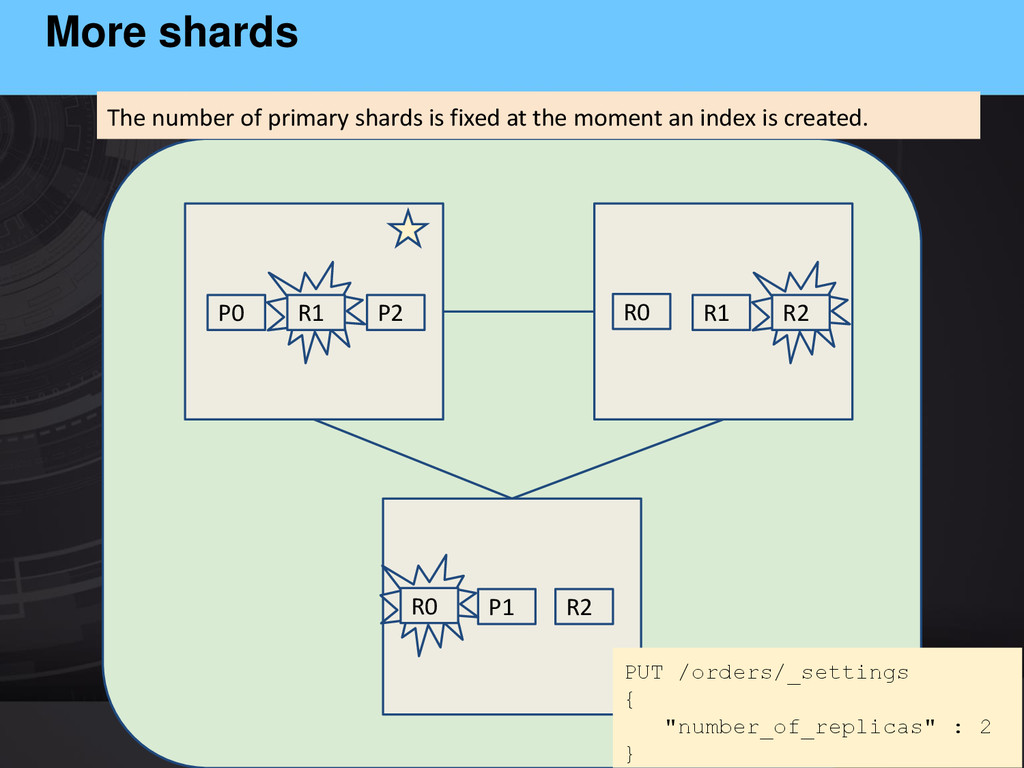
More shards P0 P1 P2 R0 R1 R2 The number
of primary shards is fixed at the moment an index is created. PUT /orders/_settings { "number_of_replicas" : 2 } R1 R0 R2 -
Extensible ✓ plugins (rivers, ui and others) ✓ scripts (scoring,
script fields etc) ✓ custom analyzers and tokenizers ✓ open source -
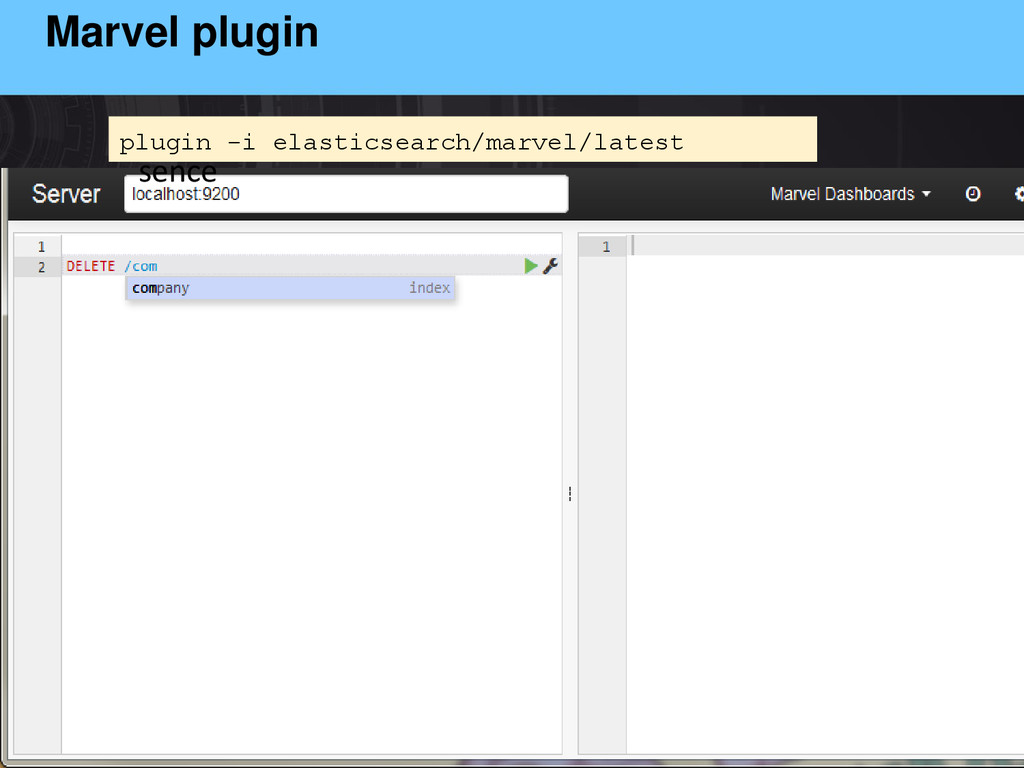
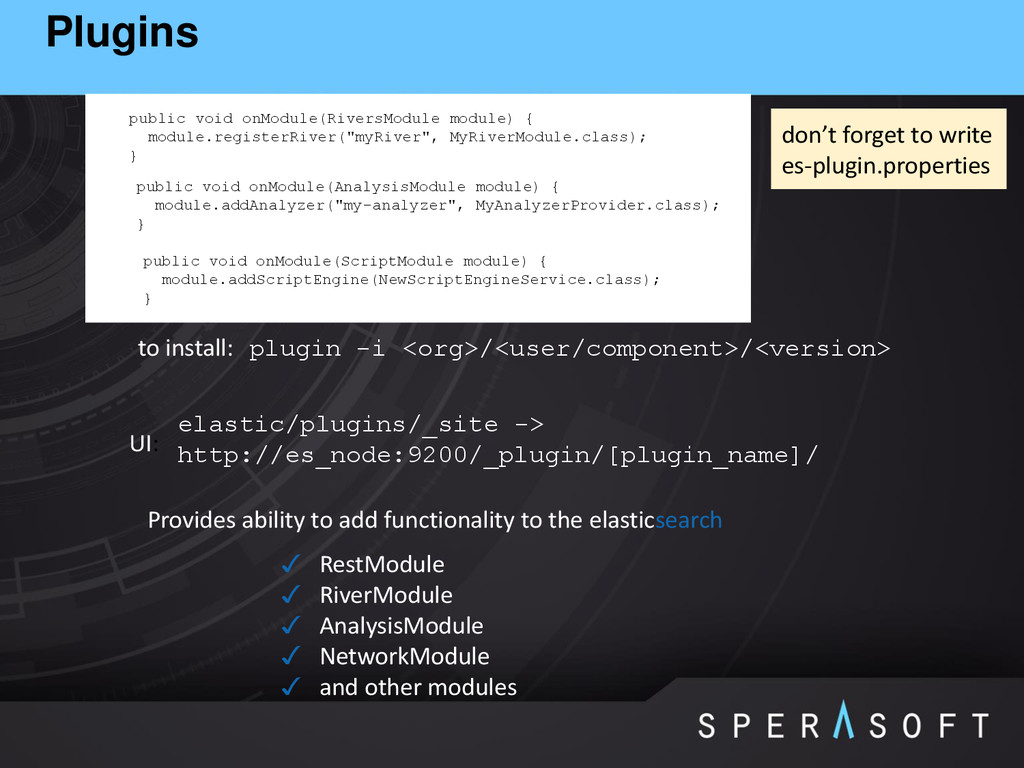
Plugins Provides ability to add functionality to the elasticsearch ✓
RestModule ✓ RiverModule ✓ AnalysisModule ✓ NetworkModule ✓ and other modules to install: plugin -i <org>/<user/component>/<version> elastic/plugins/_site -> http://es_node:9200/_plugin/[plugin_name]/ UI: public void onModule(RiversModule module) { module.registerRiver("myRiver", MyRiverModule.class); } public void onModule(AnalysisModule module) { module.addAnalyzer("my-analyzer", MyAnalyzerProvider.class); } public void onModule(ScriptModule module) { module.addScriptEngine(NewScriptEngineService.class); } don’t forget to write es-plugin.properties -
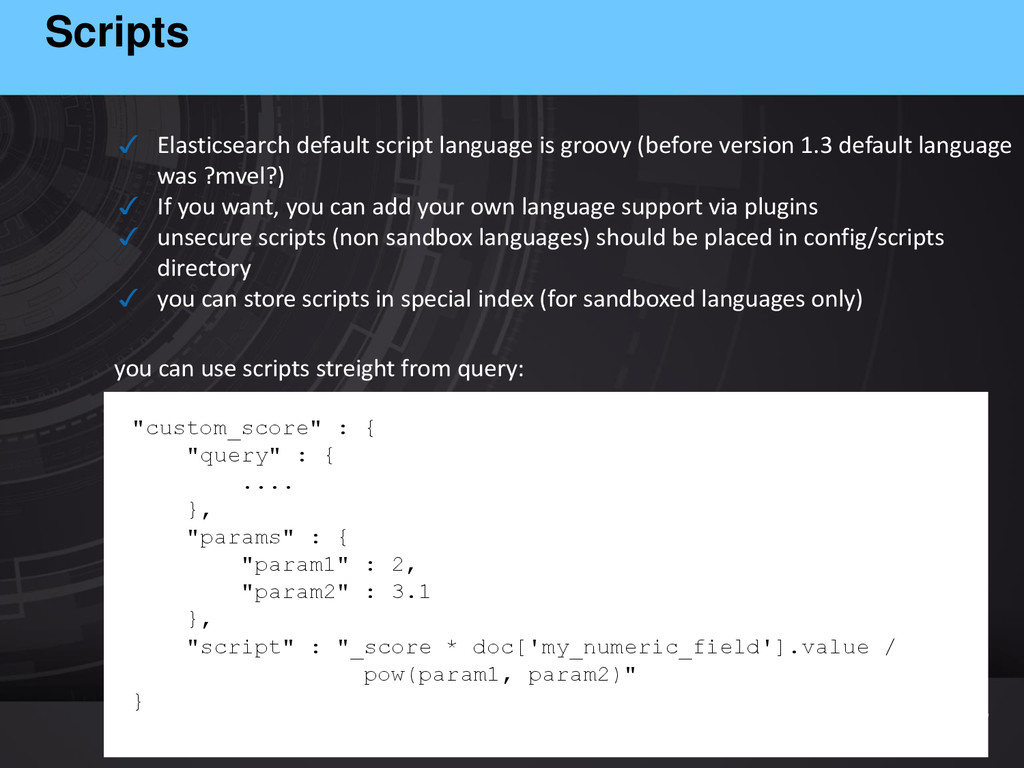
Scripts ✓ Elasticsearch default script language is groovy (before version
1.3 default language was ?mvel?) ✓ If you want, you can add your own language support via plugins ✓ unsecure scripts (non sandbox languages) should be placed in config/scripts directory ✓ you can store scripts in special index (for sandboxed languages only) "custom_score" : { "query" : { .... }, "params" : { "param1" : 2, "param2" : 3.1 }, "script" : "_score * doc['my_numeric_field'].value / pow(param1, param2)" } you can use scripts streight from query: -
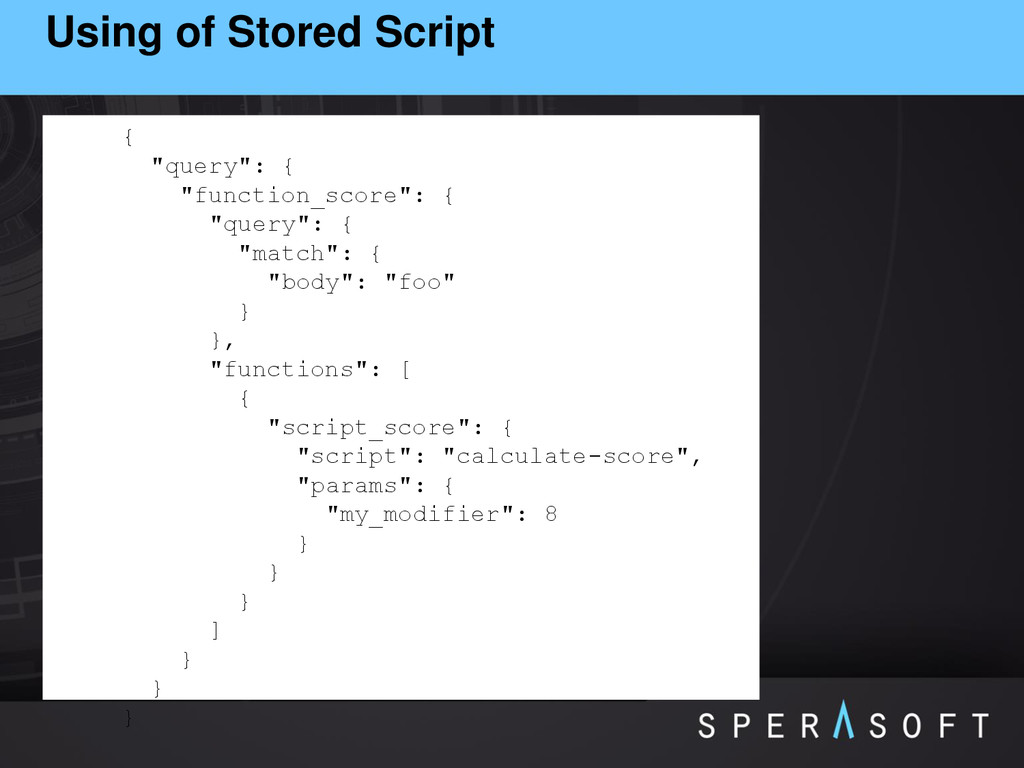
Using of Stored Script { "query": { "function_score": { "query":
{ "match": { "body": "foo" } }, "functions": [ { "script_score": { "script": "calculate-score", "params": { "my_modifier": 8 } } } ] } } } -
Some Other Scripts Field scripts: { "query" : { ...
}, "script_fields" : { "test1" : { "script" : "doc['my_field_name'].value * 2" }, "test2" : { "script" : "doc['my_field_name'].value * factor", "params" : { "factor" : 2.0 } } } } sort scripts { "query" : { .... }, "sort" : { "_script" : { "script" : "doc['field_name'].value * factor", "type" : "number", "params" : { "factor" : 1.1 }, "order" : "asc" } } } -
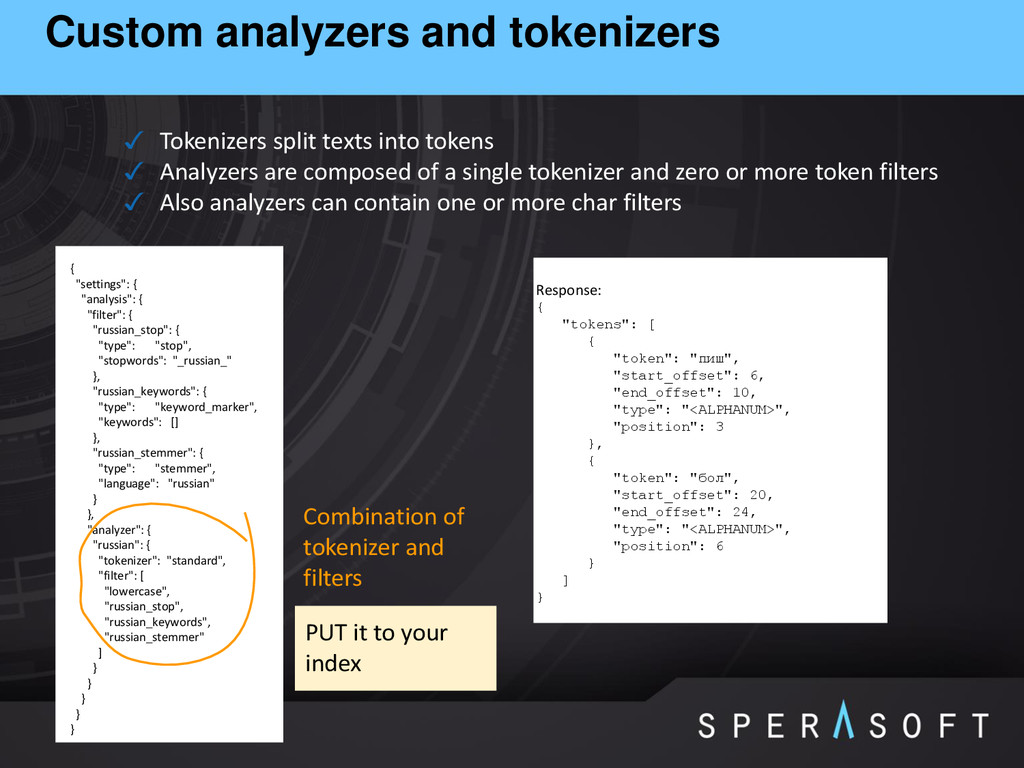
Custom analyzers and tokenizers ✓ Tokenizers split texts into tokens
✓ Analyzers are composed of a single tokenizer and zero or more token filters ✓ Also analyzers can contain one or more char filters { "settings": { "analysis": { "filter": { "russian_stop": { "type": "stop", "stopwords": "_russian_" }, "russian_keywords": { "type": "keyword_marker", "keywords": [] }, "russian_stemmer": { "type": "stemmer", "language": "russian" } }, "analyzer": { "russian": { "tokenizer": "standard", "filter": [ "lowercase", "russian_stop", "russian_keywords", "russian_stemmer" ] } } } } } PUT it to your index Combination of tokenizer and filters Response: { "tokens": [ { "token": "пиш", "start_offset": 6, "end_offset": 10, "type": "<ALPHANUM>", "position": 3 }, { "token": "бол", "start_offset": 20, "end_offset": 24, "type": "<ALPHANUM>", "position": 6 } ] } -
Other Features ✓ bulk operations ✓ result sorting ✓ parent-children
relations support ✓ custom filters score query ✓ function score query ✓ percolation ✓ more like this document api ✓ numeric aggregation scripts ✓ and others