Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
情報処理学会-全国大会2024-大規模言語モデルの分散並列学習
Search
Kazuki Fujii
December 14, 2025
Research
51
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
情報処理学会-全国大会2024-大規模言語モデルの分散並列学習
Kazuki Fujii
December 14, 2025
More Decks by Kazuki Fujii
See All by Kazuki Fujii
IHPCSS2025-Kazuki-Fujii
fujiikazuki2000
0
57
2024-02-Tokyo-Tech-大規模言語モデルの事前学習知見
fujiikazuki2000
0
52
言語処理学会2024-継続事前学習による日本語に強い大規模言語モデルの構築
fujiikazuki2000
0
110
AWS Summit Japan 2025 Amazon SageMaker HyperPodを利用した日本語LLM(Swallow)の構築 (CUS-02)
fujiikazuki2000
0
77
合成データパイプラインを利用したSwallowProjectに おけるLLM性能向上
fujiikazuki2000
1
330
論文では語られないLLM開発において重要なこと Swallow Projectを通して
fujiikazuki2000
8
2.1k
大規模言語モデルの学習知見
fujiikazuki2000
0
250
自然言語処理のための分散並列学習
fujiikazuki2000
1
790
Other Decks in Research
See All in Research
論文紹介: Understanding Epistemic Language with a Language-augmented Bayesian Theory of Mind
hisaokatsumi
0
210
Adapter les bergeries aux fortes chaleurs
institutdelelevage
PRO
0
170
GeoAgent勉強会 論文紹介と強い推論モデルが与えるインパクト
satai
5
450
【令和7年度版】内航船 VS 外航船 早見表
anikisencyo
0
160
20261101GISA-FOSS4G
tosseto
1
110
Top 4セキュリティ会議に一通り論文が採択されるまでの道のりと展望 / Top 4 Security Grand Slam
takaomurakami
0
1.1k
[IEICE-Soceity-Conf2026] セマンティック通信を見据えたマルチスケールセンシングと 学習の融合によるデジタルツイン基盤 / Digital Twin Infrastructure via the Fusion of Multi-Scale Sensing and Learning toward Semantic Communications
pman0214
0
130
Easy to Guess, Hard to Verify: Lessons from AIMO 3 for Olympiad-Level AI Mathematics
corochann
0
150
[webinaire du Ciirpo] Agnelages plein air : des éleveurs partagent leurs pratiques
institutdelelevage
PRO
0
290
Hitting the buffers
beale
0
370
Kaggle|AI Agent Security — しくじり先生、俺みたいになるな
pomcho555
1
130
Physical AIでモデリングはどう変わるか/How Physical AI Will Change Modeling
stktu
0
330
Featured
See All Featured
Creating an realtime collaboration tool: Agile Flush - .NET Oxford
marcduiker
35
2.6k
Designing for humans not robots
tammielis
254
26k
Paper Plane (Part 1)
katiecoart
PRO
2
12k
SERP Conf. Vienna - Web Accessibility: Optimizing for Inclusivity and SEO
sarafernandez
2
1.6k
Building AI with AI
inesmontani
PRO
1
1.3k
Docker and Python
trallard
47
4.2k
What the history of the web can teach us about the future of AI
inesmontani
PRO
2
770
[Rails World 2023 - Day 1 Closing Keynote] - The Magic of Rails
eileencodes
38
3.1k
Building the Perfect Custom Keyboard
takai
2
930
<Decoding/> the Language of Devs - We Love SEO 2024
nikkihalliwell
1
380
Stop Working from a Prison Cell
hatefulcrawdad
274
21k
The #1 spot is gone: here's how to win anyway
tamaranovitovic
4
1.2k
Transcript
大規模言語モデルの分散並列学習 東京工業大学 藤井一喜 横田理央 5J-02
2 概要 • Llama 2をベースに日本語コーパスで継続事前学習 • 7B, 13B, 70B のモデル規模にて分散並列学習
• メモリ効率化のための工夫を行った3D Parallelism
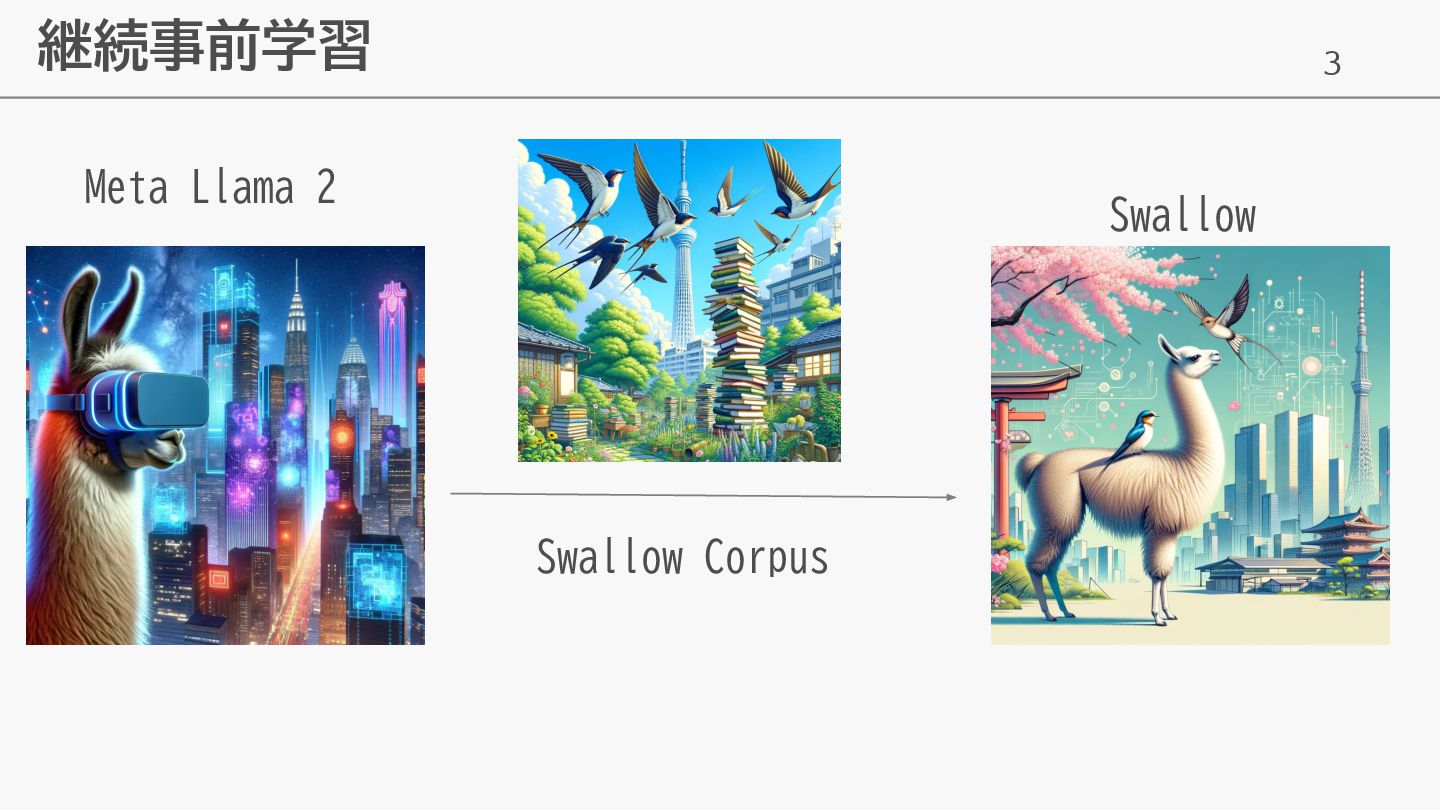
3 継続事前学習 Meta Llama 2 Swallow Swallow Corpus
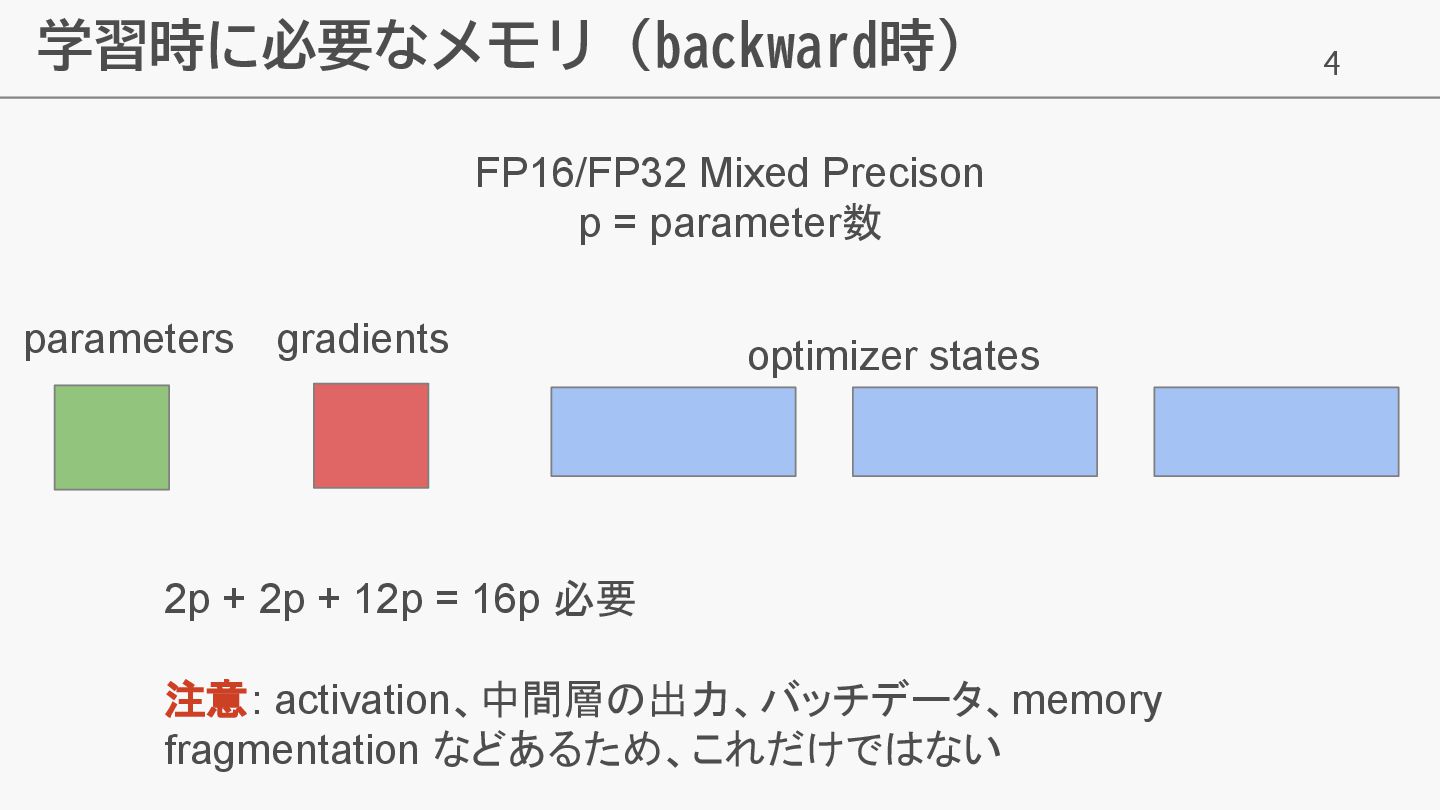
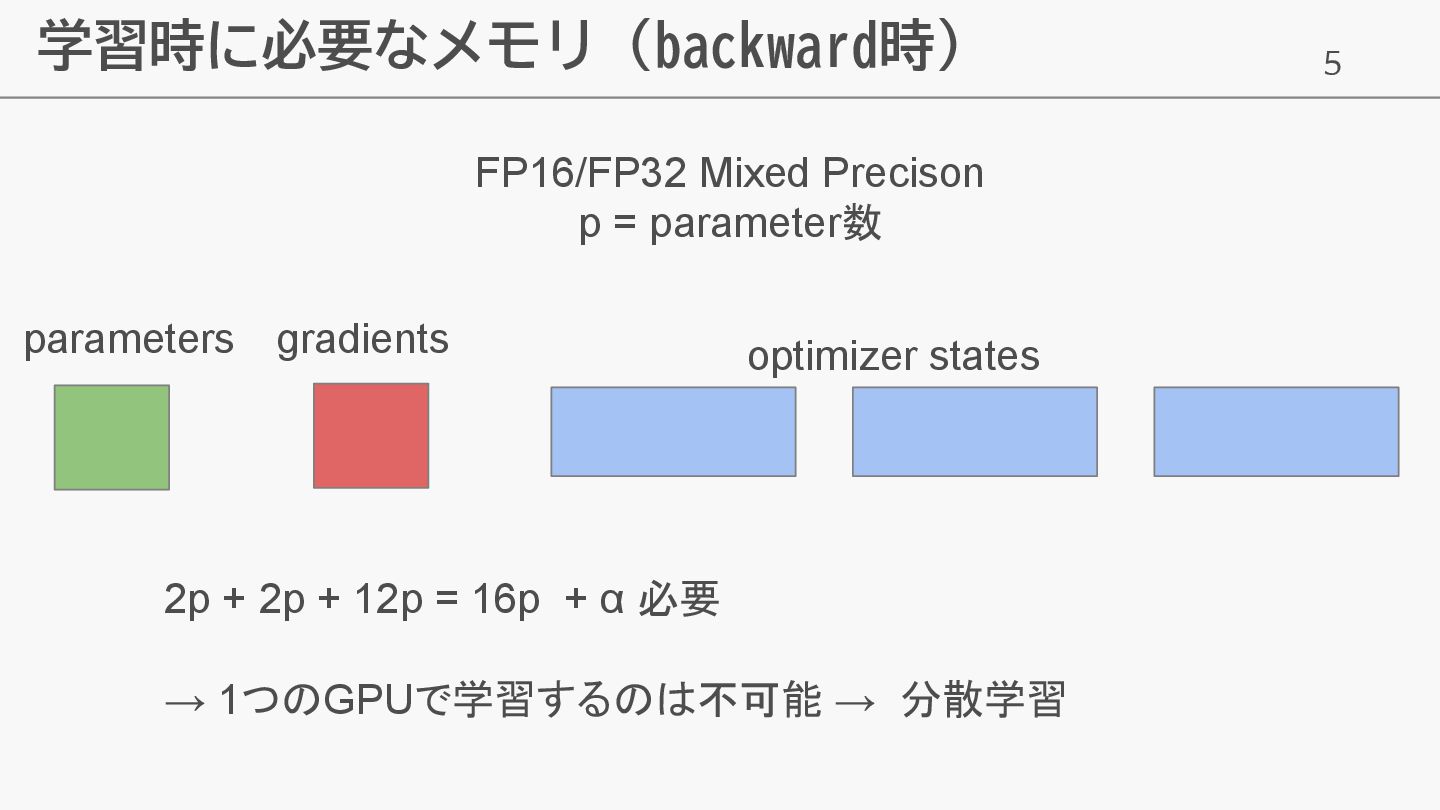
4 学習時に必要なメモリ (backward時) FP16/FP32 Mixed Precison p = parameter数 parameters
gradients optimizer states 2p + 2p + 12p = 16p 必要 注意: activation、中間層の出力、バッチデータ、memory fragmentation などあるため、これだけではない
5 学習時に必要なメモリ (backward時) FP16/FP32 Mixed Precison p = parameter数 parameters
gradients optimizer states 2p + 2p + 12p = 16p + α 必要 → 1つのGPUで学習するのは不可能 → 分散学習
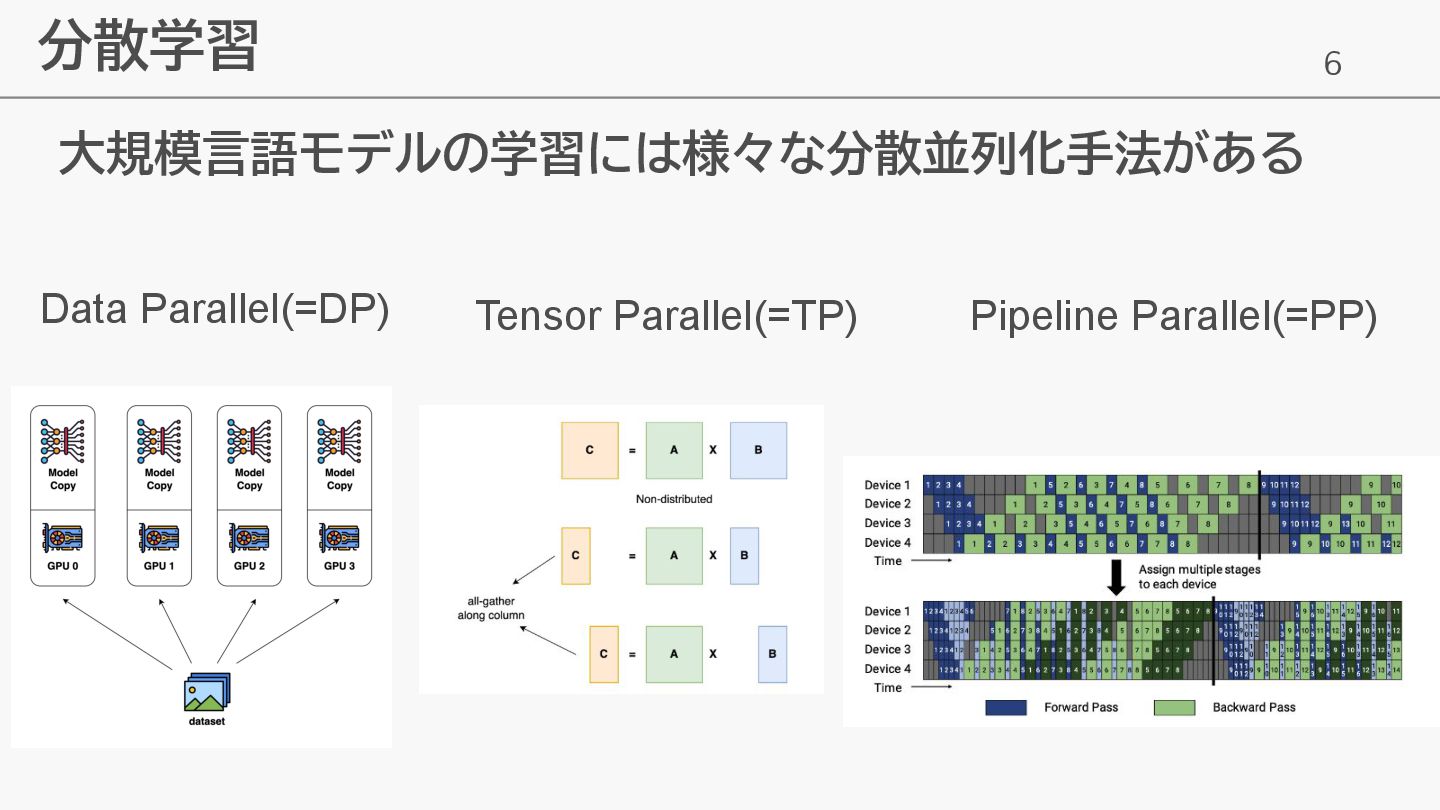
6 分散学習 大規模言語モデルの学習には様々な分散並列化手法がある Data Parallel(=DP) Tensor Parallel(=TP) Pipeline Parallel(=PP)
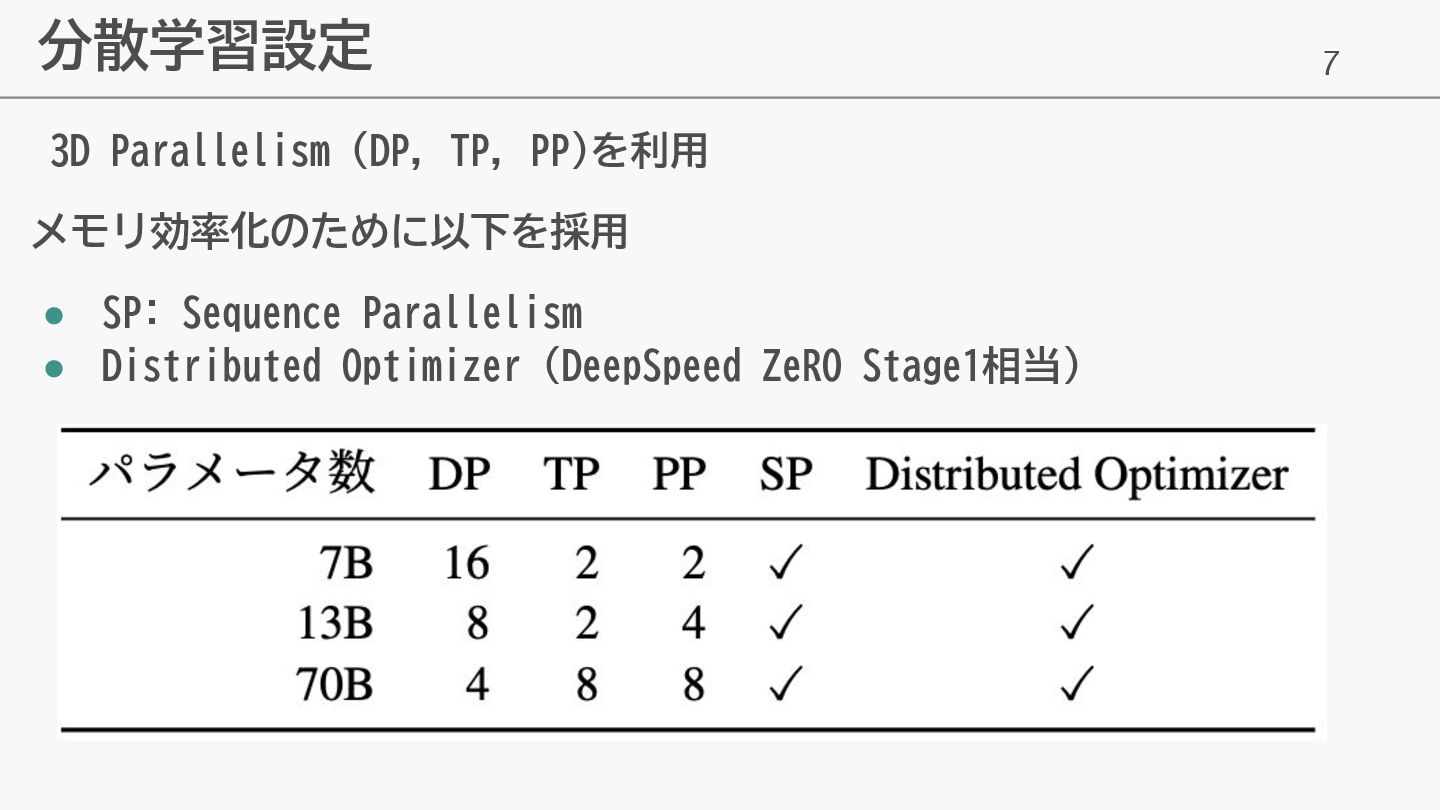
7 分散学習設定 3D Parallelism (DP, TP, PP)を利用 メモリ効率化のために以下を採用 • SP:
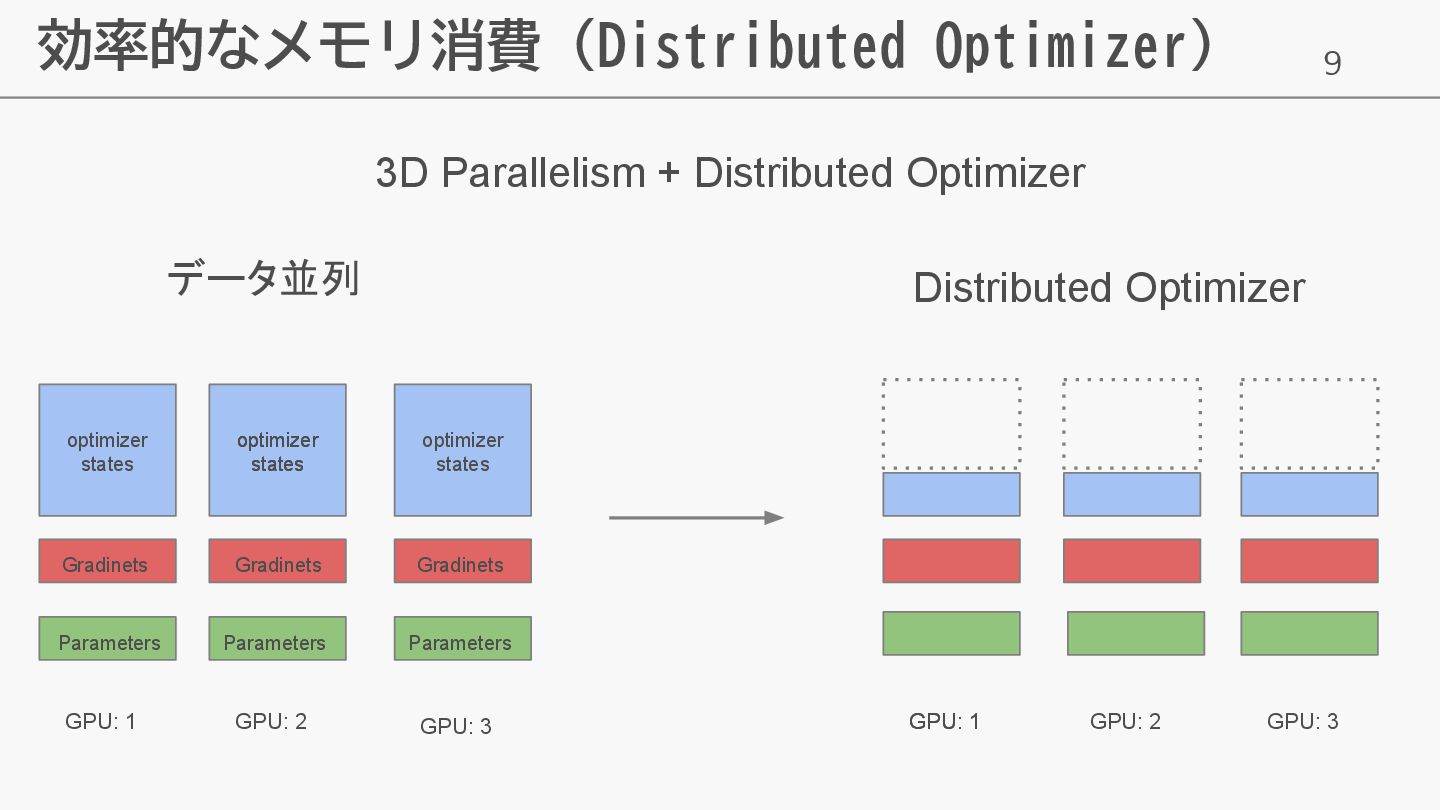
Sequence Parallelism • Distributed Optimizer (DeepSpeed ZeRO Stage1相当)
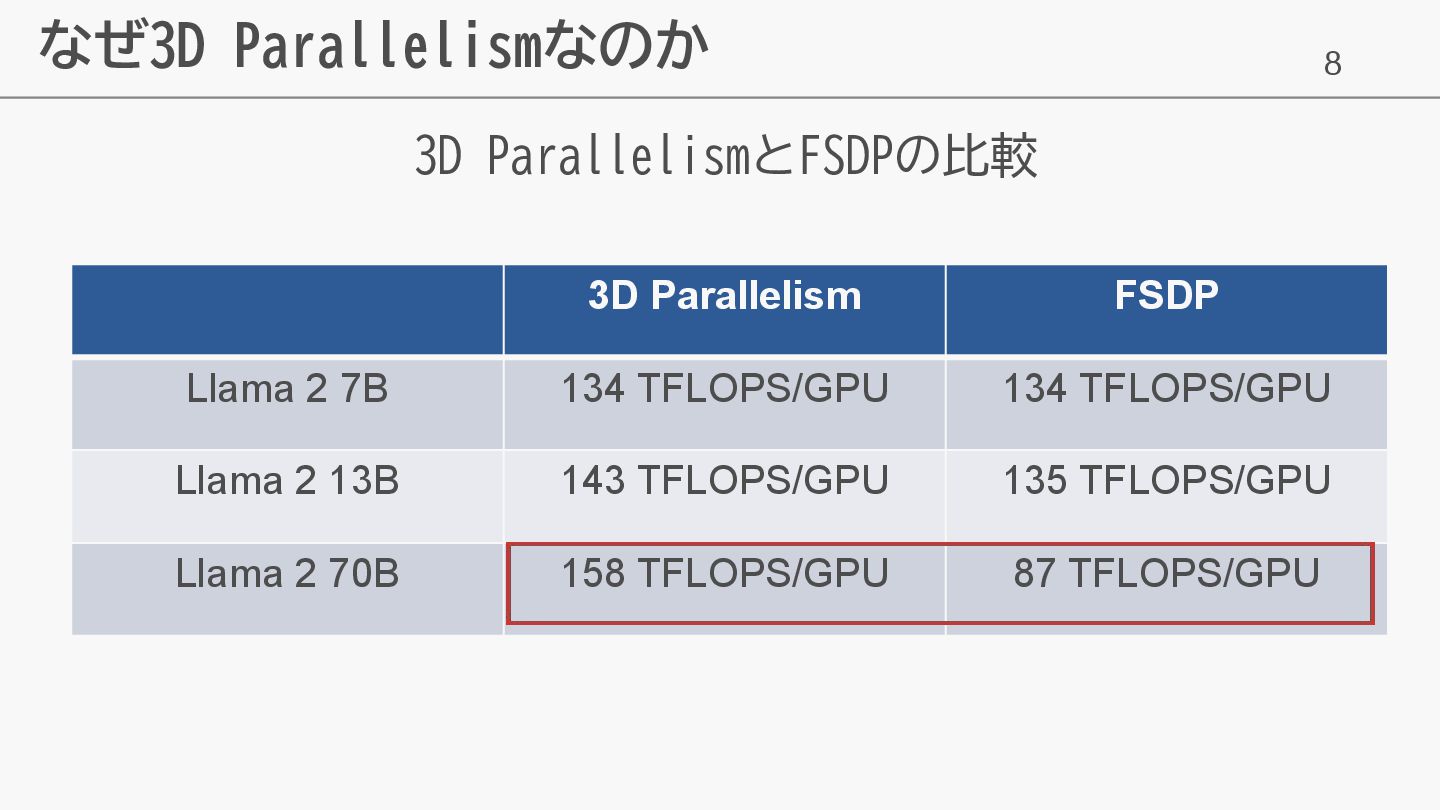
8 なぜ3D Parallelismなのか 3D ParallelismとFSDPの比較 3D Parallelism FSDP Llama 2
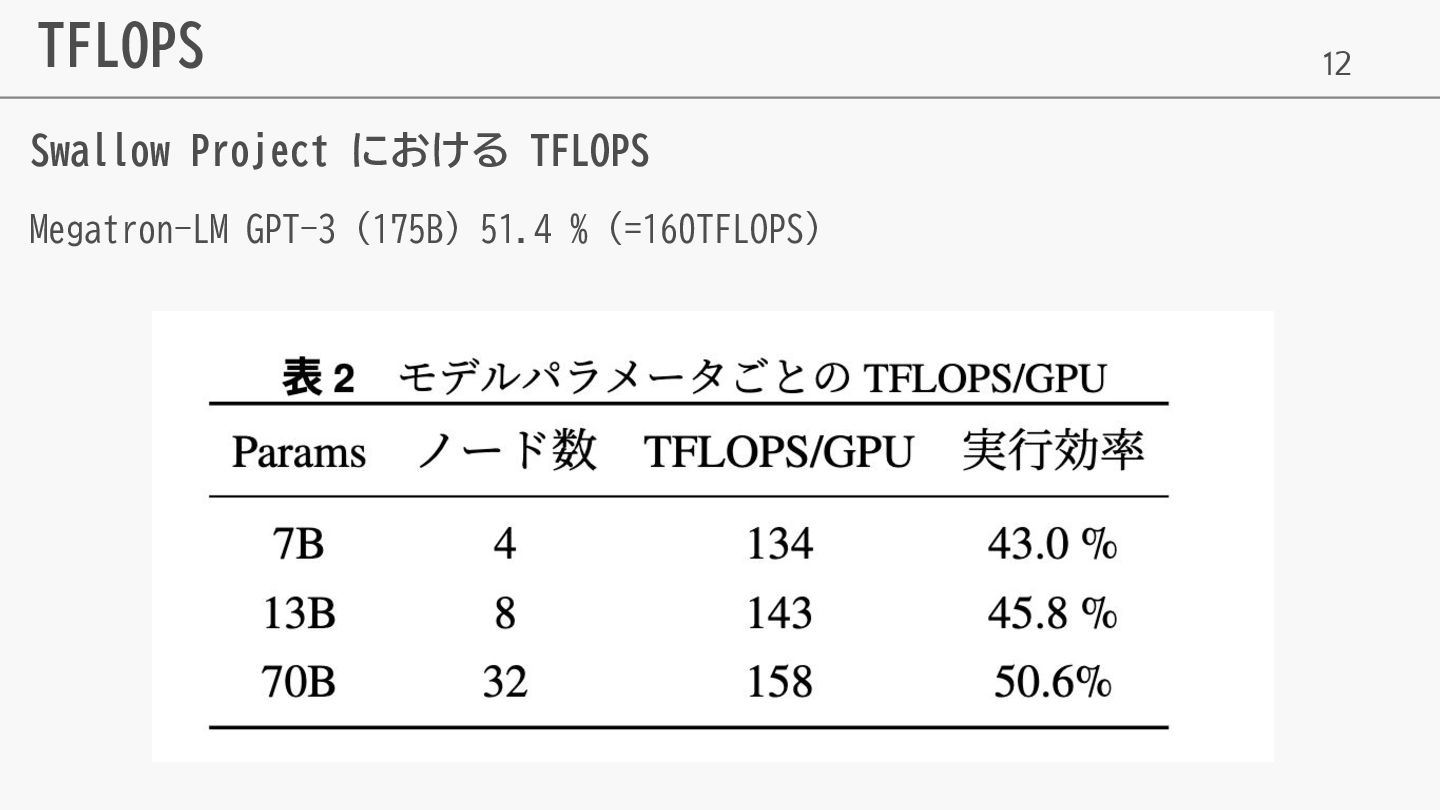
7B 134 TFLOPS/GPU 134 TFLOPS/GPU Llama 2 13B 143 TFLOPS/GPU 135 TFLOPS/GPU Llama 2 70B 158 TFLOPS/GPU 87 TFLOPS/GPU
9 効率的なメモリ消費 (Distributed Optimizer) データ並列 Distributed Optimizer GPU: 1 GPU:
2 GPU: 3 GPU: 1 GPU: 1 GPU: 2 GPU: 3 3D Parallelism + Distributed Optimizer optimizer states optimizer states optimizer states Gradinets optimizer states Gradinets Gradinets Parameters Parameters Parameters
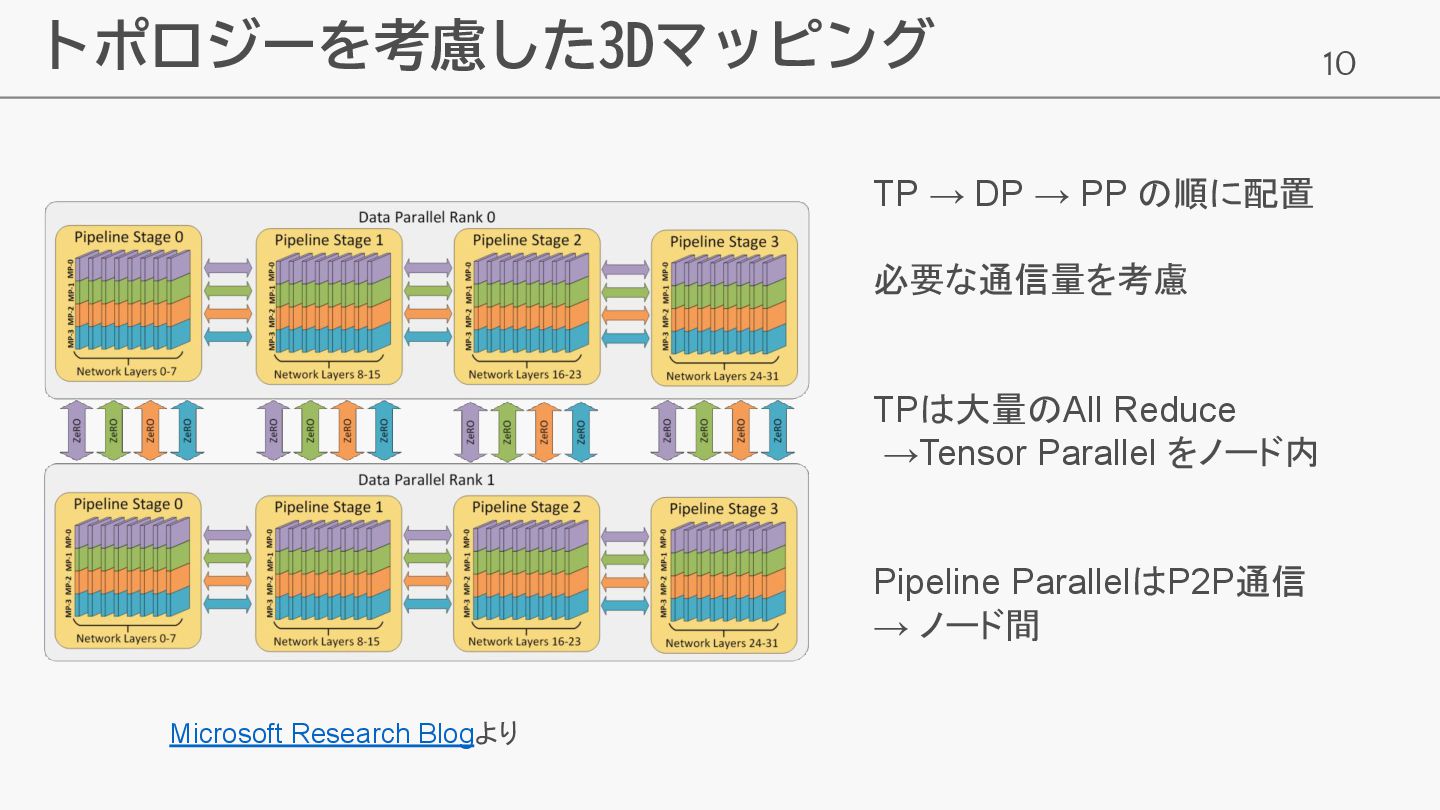
10 トポロジーを考慮した3Dマッピング TP → DP → PP の順に配置 必要な通信量を考慮 TPは大量のAll
Reduce →Tensor Parallel をノード内 Pipeline ParallelはP2P通信 → ノード間 Microsoft Research Blogより
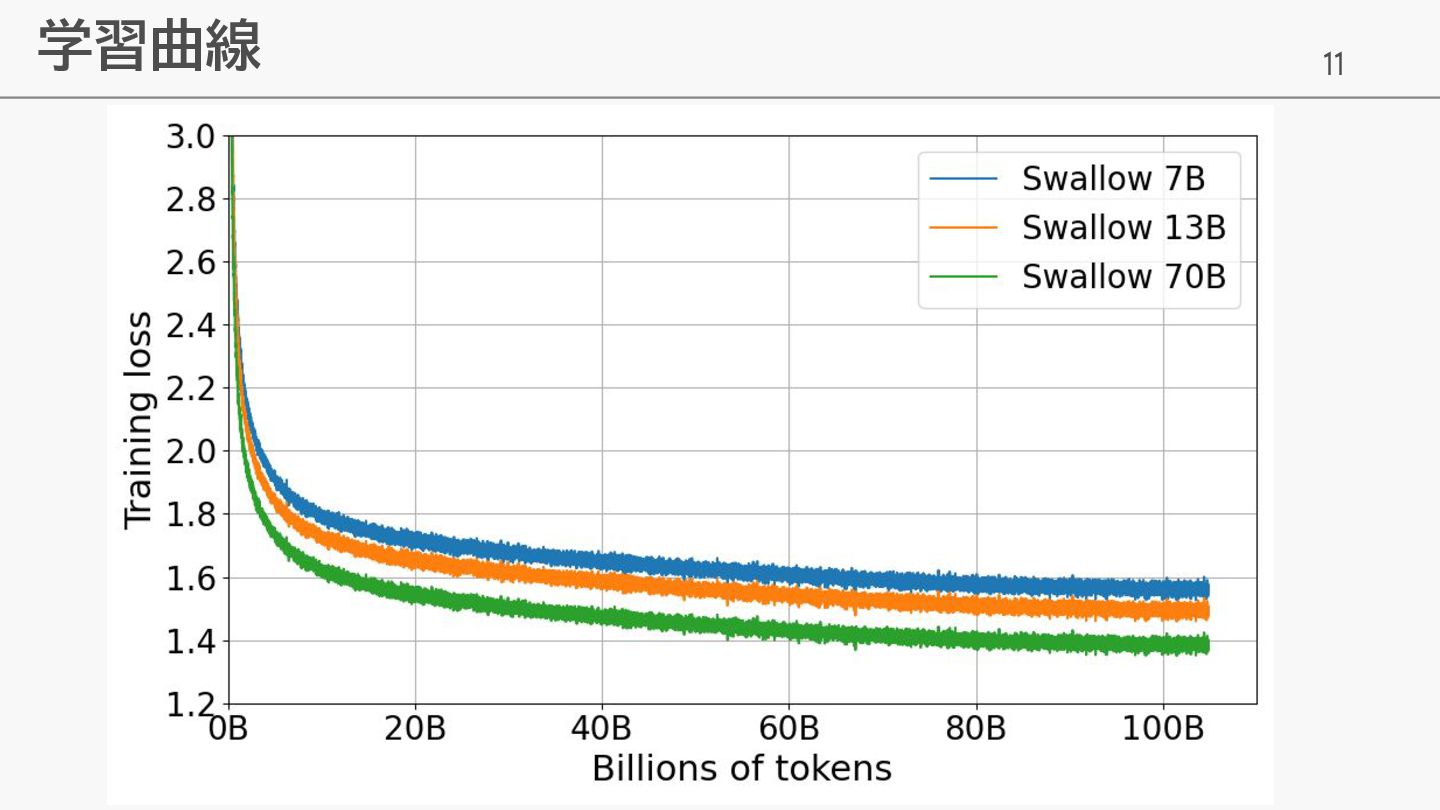
11 学習曲線
12 TFLOPS Swallow Project における TFLOPS Megatron-LM GPT-3 (175B) 51.4
% (=160TFLOPS)
補足資料
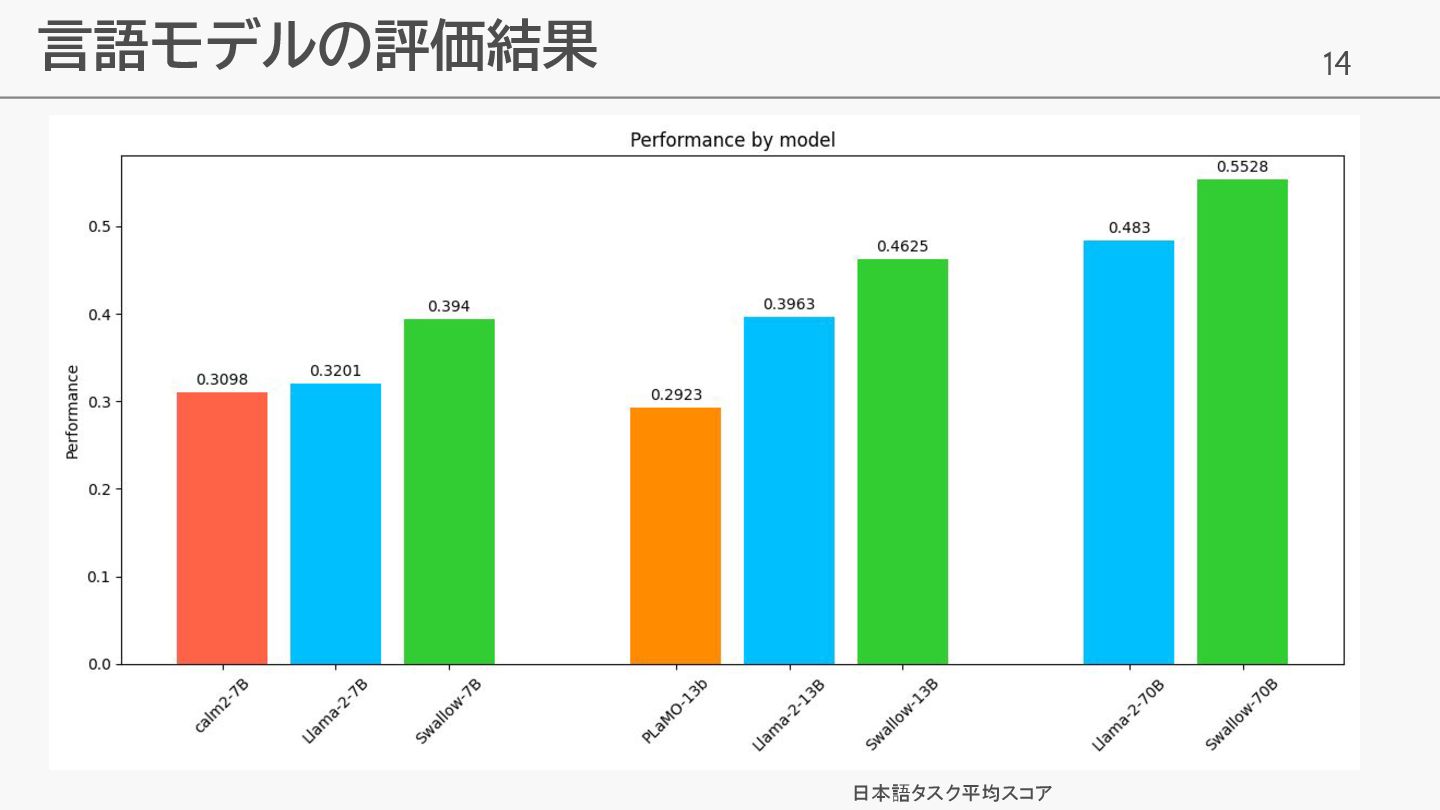
14 言語モデルの評価結果 日本語タスク平均スコア
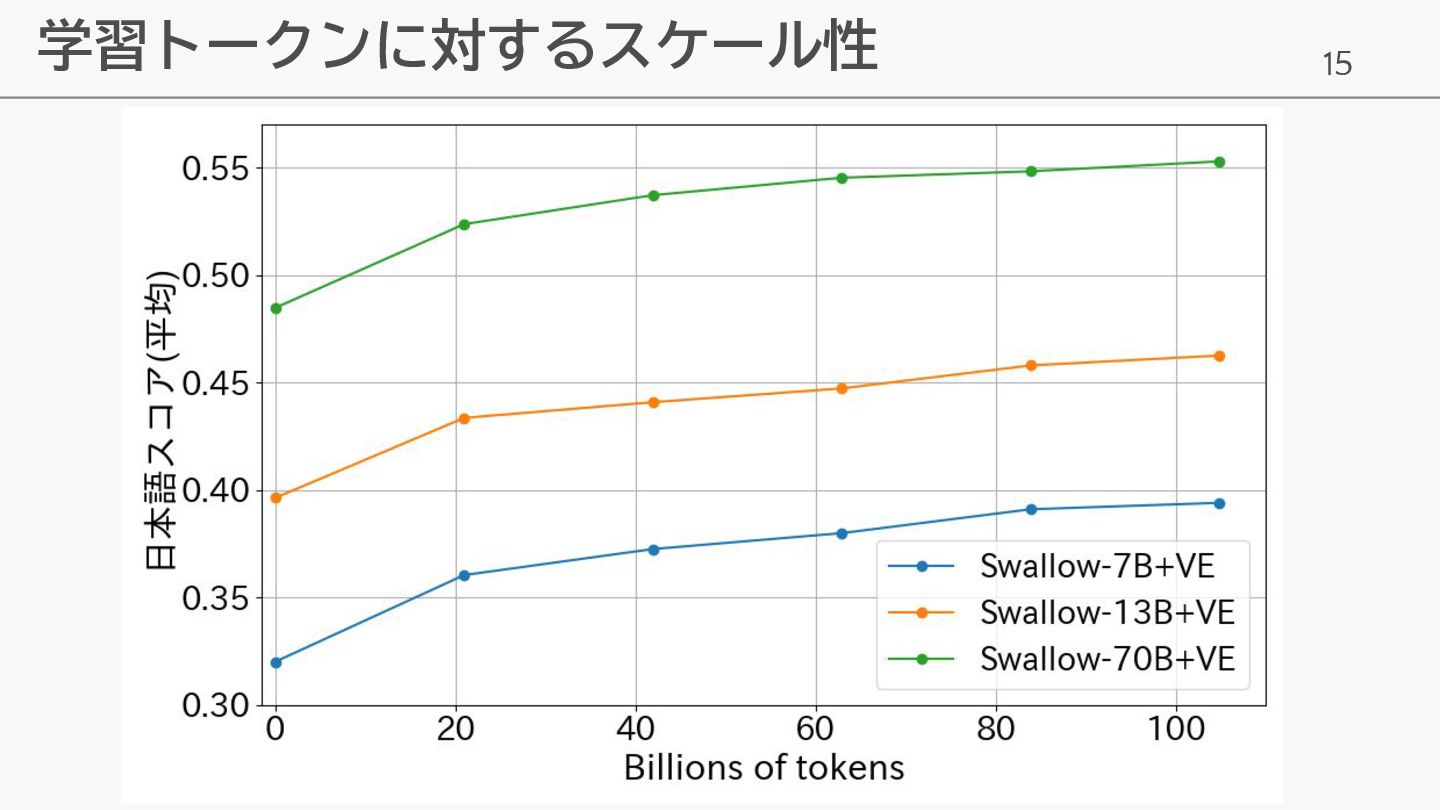
15 学習トークンに対するスケール性
16 学習ライブラリ 1. 3D Parallelism をサポート 2. Llamaアーキテクチャに対応 3. HF
→ Megatron 変換コードあり 詳細 ↓
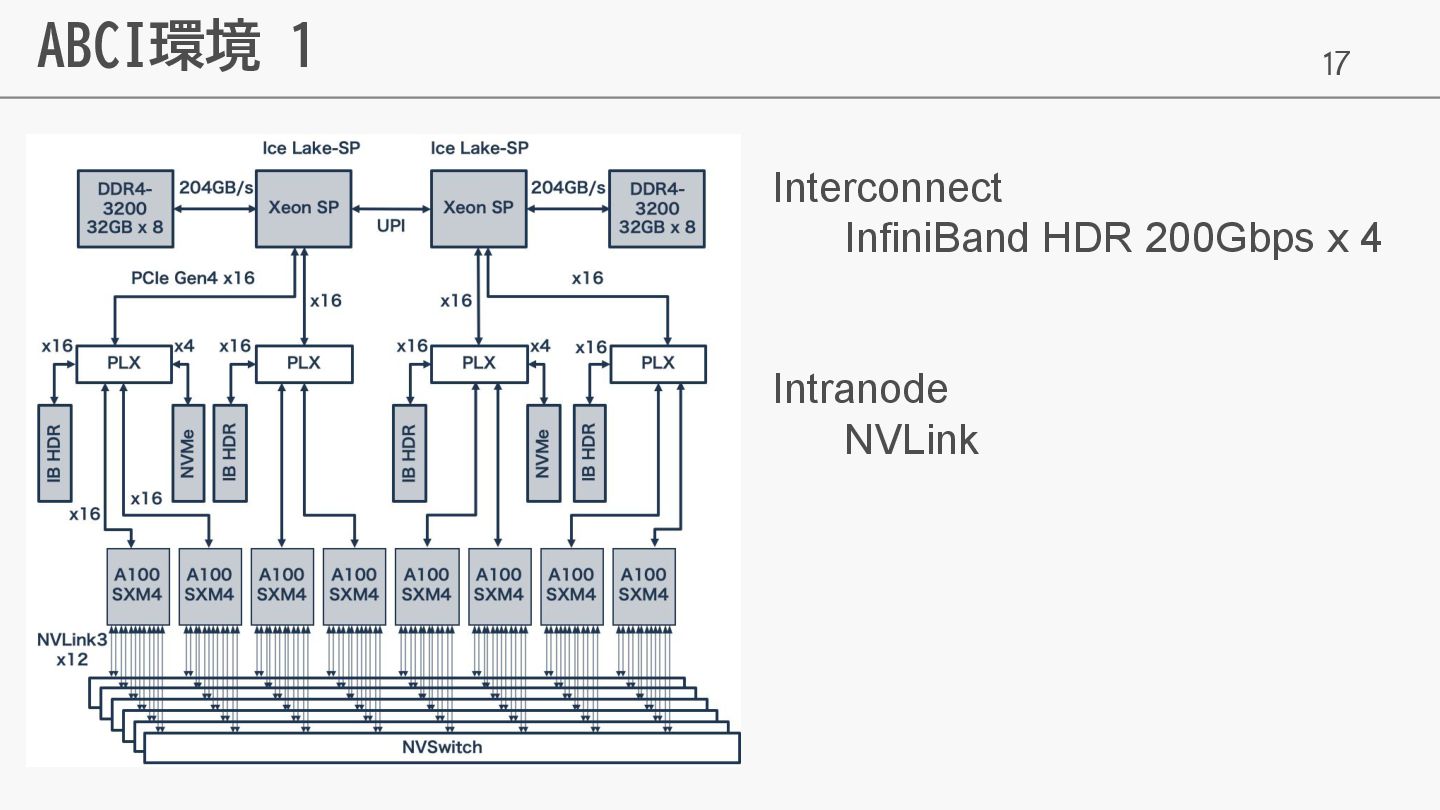
17 ABCI環境 1 Interconnect InfiniBand HDR 200Gbps x 4 Intranode
NVLink
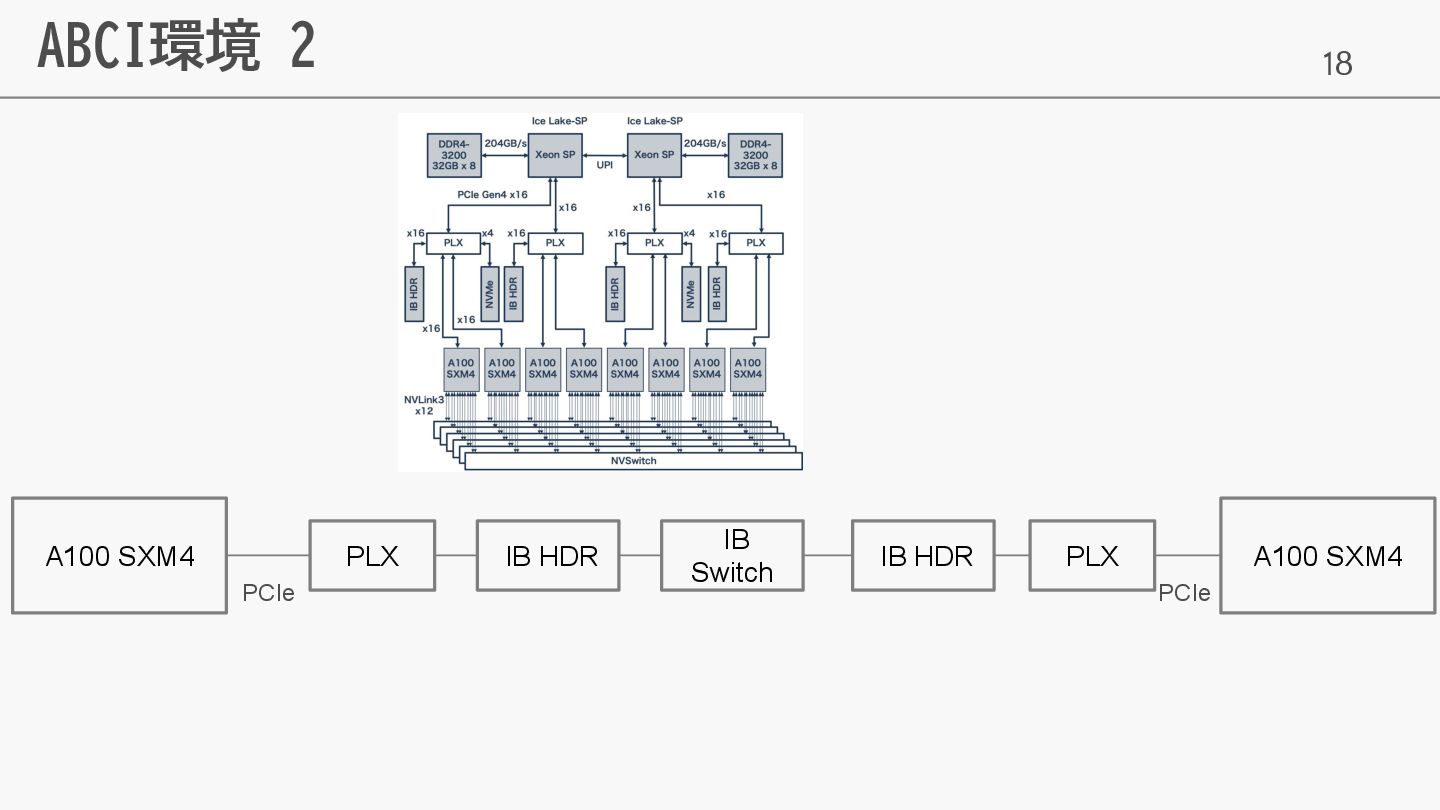
18 ABCI環境 2 A100 SXM4 PLX PCIe IB HDR PLX
A100 SXM4 IB HDR IB Switch PCIe
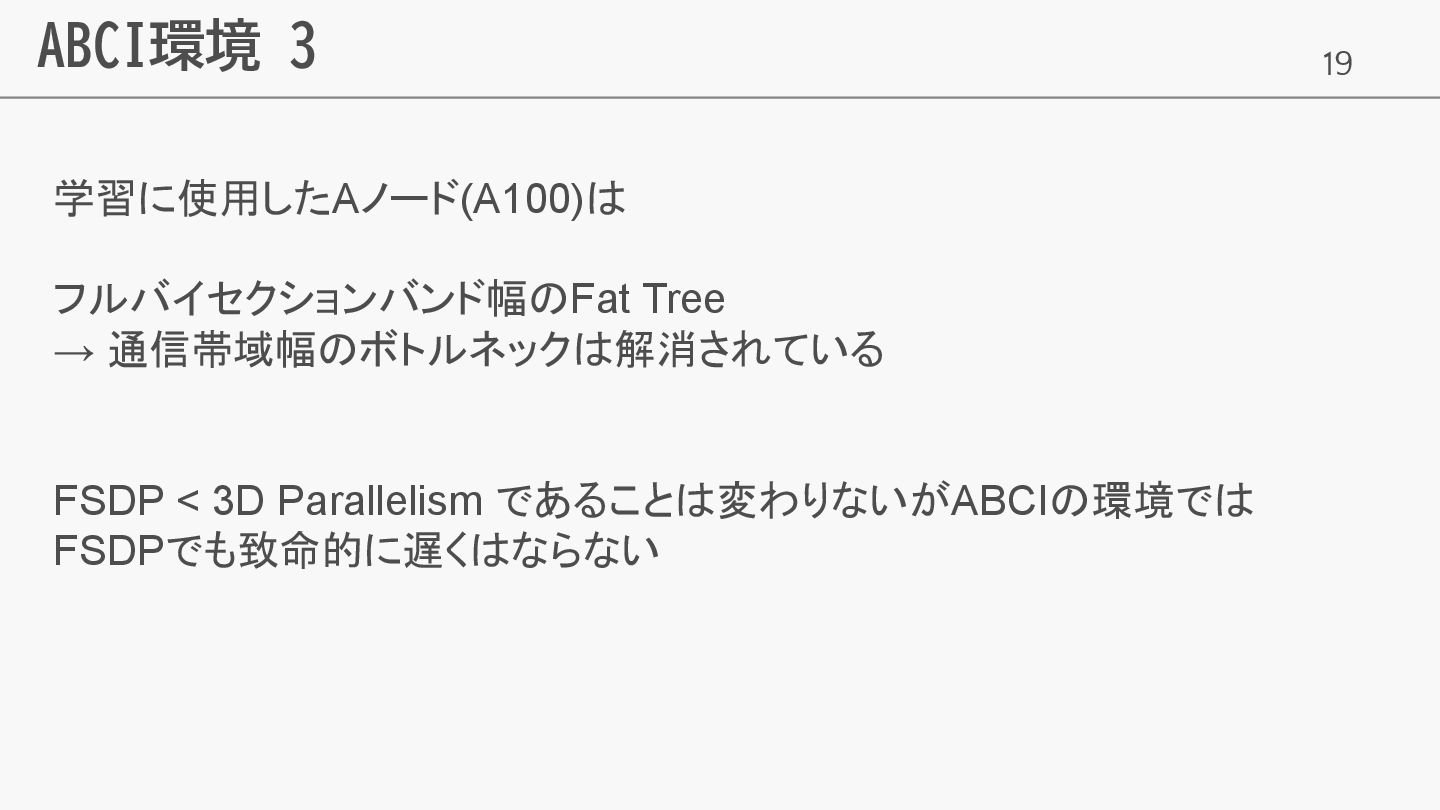
19 ABCI環境 3 学習に使用したAノード(A100)は フルバイセクションバンド幅のFat Tree → 通信帯域幅のボトルネックは解消されている FSDP <
3D Parallelism であることは変わりないがABCIの環境では FSDPでも致命的に遅くはならない


 fujiikazuki2000
 hisaokatsumi
 institutdelelevage
 satai
 anikisencyo
 tosseto
 takaomurakami
 pman0214
 corochann
 beale
 pomcho555
 stktu
 marcduiker
 tammielis
 katiecoart
 sarafernandez
 inesmontani
 trallard
 eileencodes
 takai
 nikkihalliwell
 hatefulcrawdad
 tamaranovitovic