Share
Embed
Digging into Sample Assignment Methods for Object Detection
How are training samples of object detection defined for the given feature map and ground-truth boxes? We have surveyed and compared the sample (target) assignment methods of state-of-the-art object detectors.
(presented at the DeNA / Mobility Technologies tech seminar on Oct. 1st, 2020.)
Hiroto Honda
November 30, 2020
Transcript
40 slides
-
Hiroto Honda - Mobility Technologies Co., Ltd. (Japan) - homepage:
https://hirotomusiker.github.io/ - blogs: Digging Into Detectron 2 - kaggle master: 6th place at Open Images Challenge ‘19 - Interests: Object Detection, Human Pose Estimation, Image Restoration About Me -
How to define training samples of object detection for the
given feature map and ground-truth boxes Today I talk about.. -
Accuracy and Inference Time Comparison among Object Detectors because It’s
Hard to See the Difference between Sampling Methods in a Fair Way Today I don’t talk about... -
Object Detection Input: Image Output: Bounding Boxes (xywh + class
id + confidence) from: [H1] -
Example of 2-stage Detector [H1][3] : Faster R-CNN [1] +
Feature Pyramid Network [2] How Object Detection Works -
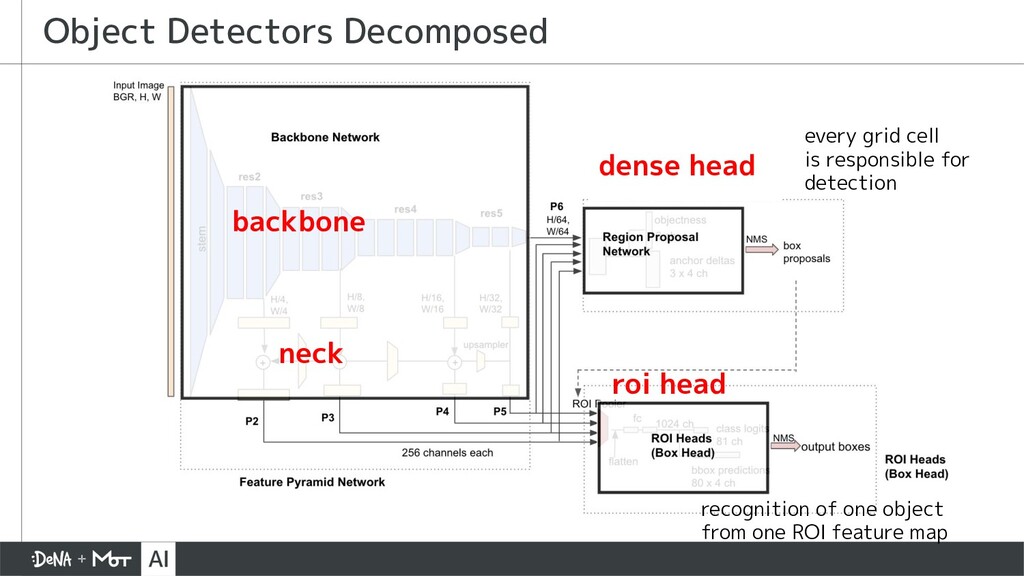
Object Detectors Decomposed backbone dense head roi head neck every
grid cell is responsible for detection recognition of one object from one ROI feature map -
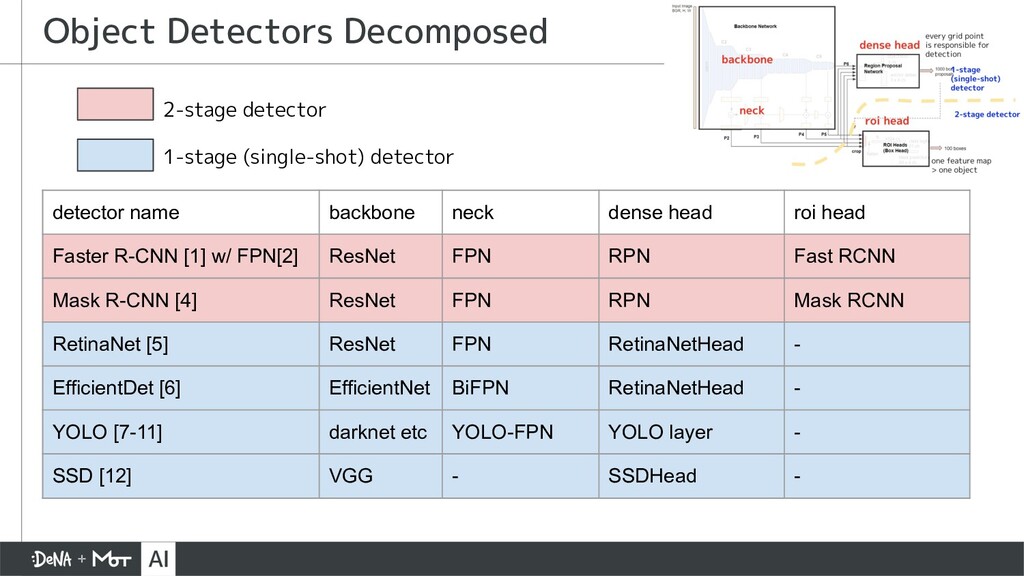
Object Detectors Decomposed backbone dense head roi head neck every
grid cell is responsible for detection 2-stage detector 1-stage (single-shot) detector recognition of one object from one ROI feature map -
Object Detectors Decomposed detector name backbone neck dense head roi
head Faster R-CNN [1] w/ FPN[2] ResNet FPN RPN Fast RCNN Mask R-CNN [4] ResNet FPN RPN Mask RCNN RetinaNet [5] ResNet FPN RetinaNetHead - EfficientDet [6] EfficientNet BiFPN RetinaNetHead - YOLO [7-11] darknet etc YOLO-FPN YOLO layer - SSD [12] VGG - SSDHead - 2-stage detector 1-stage (single-shot) detector -
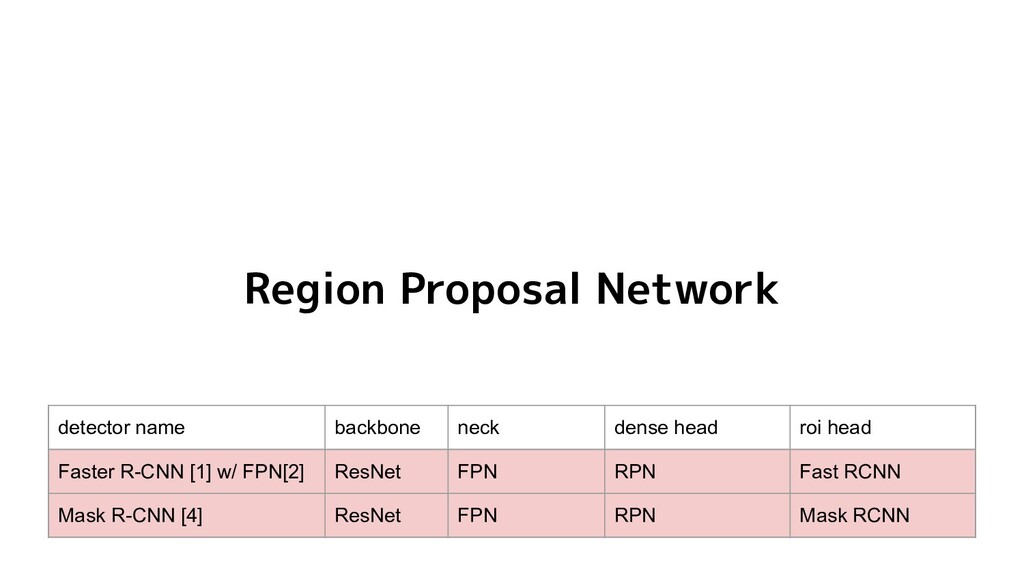
Region Proposal Network detector name backbone neck dense head roi
head Faster R-CNN [1] w/ FPN[2] ResNet FPN RPN Fast RCNN Mask R-CNN [4] ResNet FPN RPN Mask RCNN -
visualization of an objectness channel (corresponding to one of three
anchors) Multi-Scale Detection Results (objectness) stride = 4 stride = 8 stride = 64 stride = 32 stride = 16 from: [H1] -
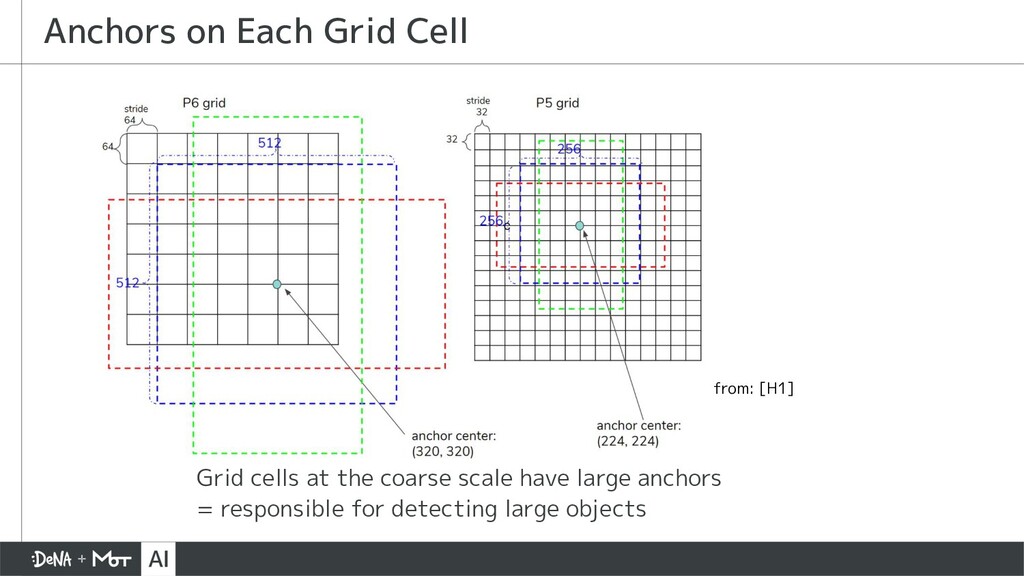
Anchors three anchors per scale aspect ratio : (1,1), (1,
2), (2, 1) from: [H1] -
Grid cells at the coarse scale have large anchors =
responsible for detecting large objects Anchors on Each Grid Cell from: [H1] -
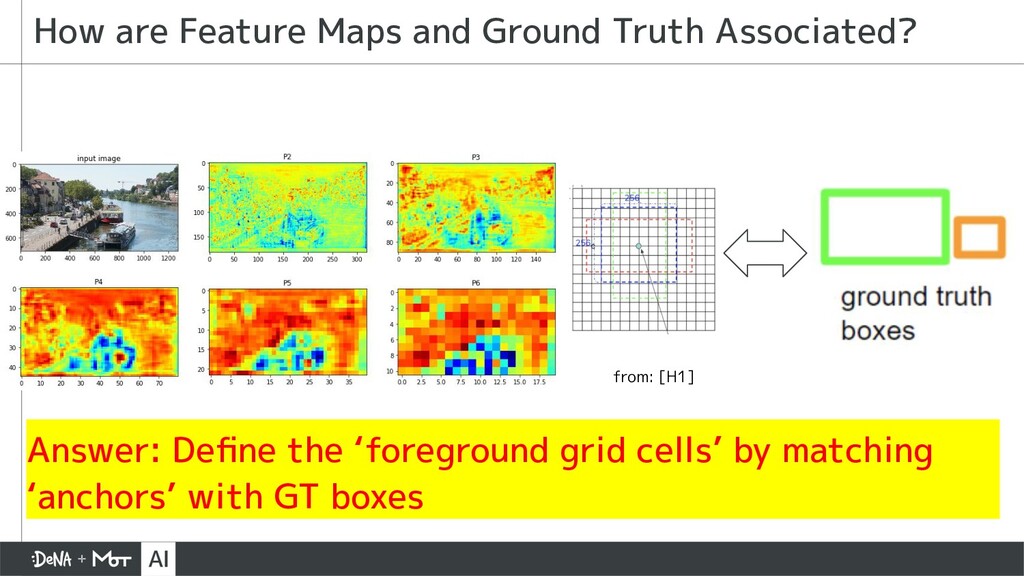
How are Feature Maps and Ground Truth Associated? Answer: Define
the ‘foreground grid cells’ by matching ‘anchors’ with GT boxes from: [H1] -
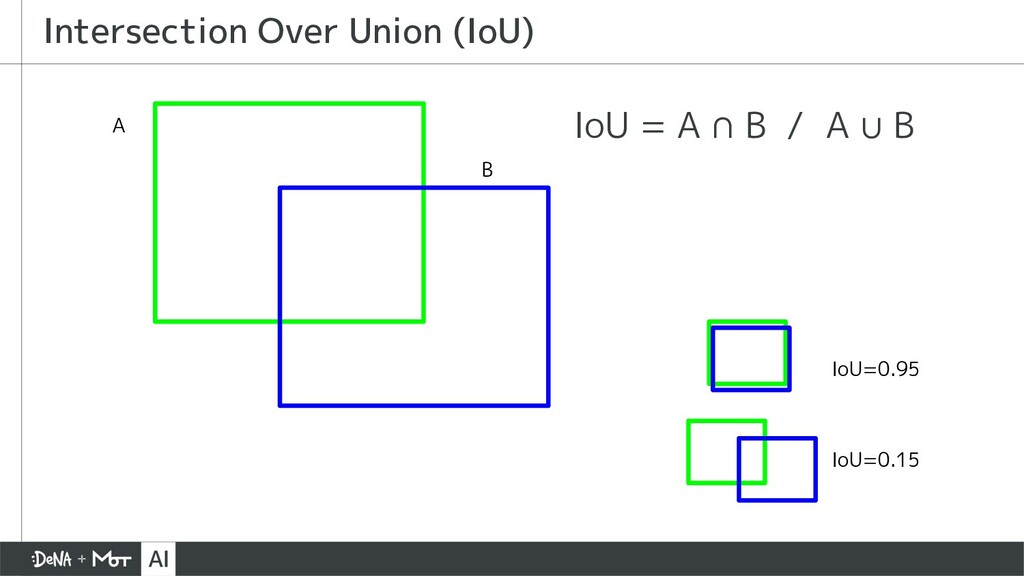
IoU = A ∩ B / A ∪ B Intersection
Over Union (IoU) A B IoU=0.15 IoU=0.95 -
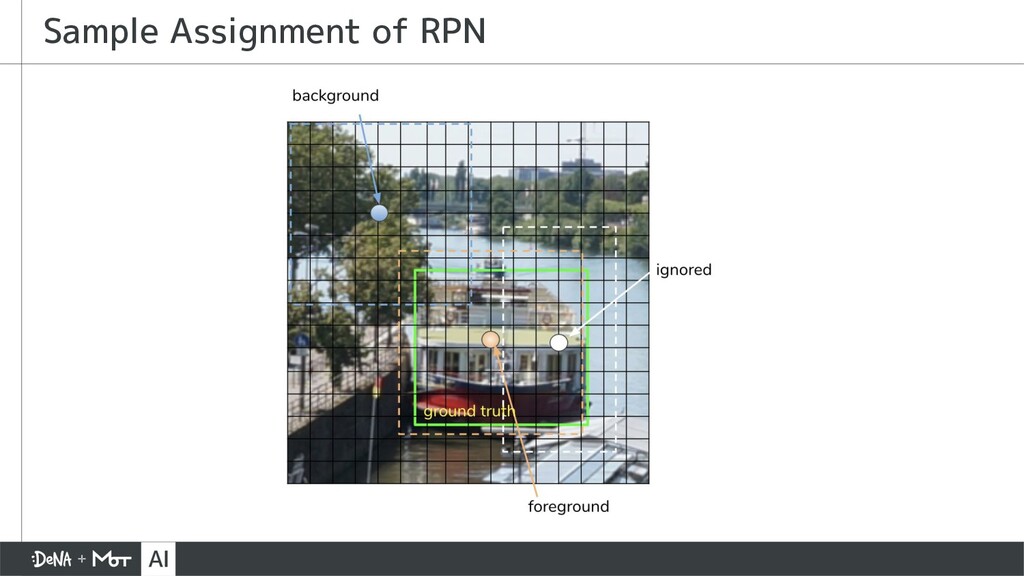
IoU Matrix for Anchor-GT Matching 0 0 0.61 0.28 0
0 0 0 0 0 0 0 0 0 0 0.98 0 0 GT box 0 GT box 1 matched with GT box 1, foreground background ignored foreground (IoU ≧ T1) -> objectness target=1, regression target background (IoU < T2) : objectness target=0, no regression loss ignored (T2 ≦ IoU < T1) from: [H1] T1 and T2: predefined threshold values IoU value anchors position 0 position 1 position 2 -
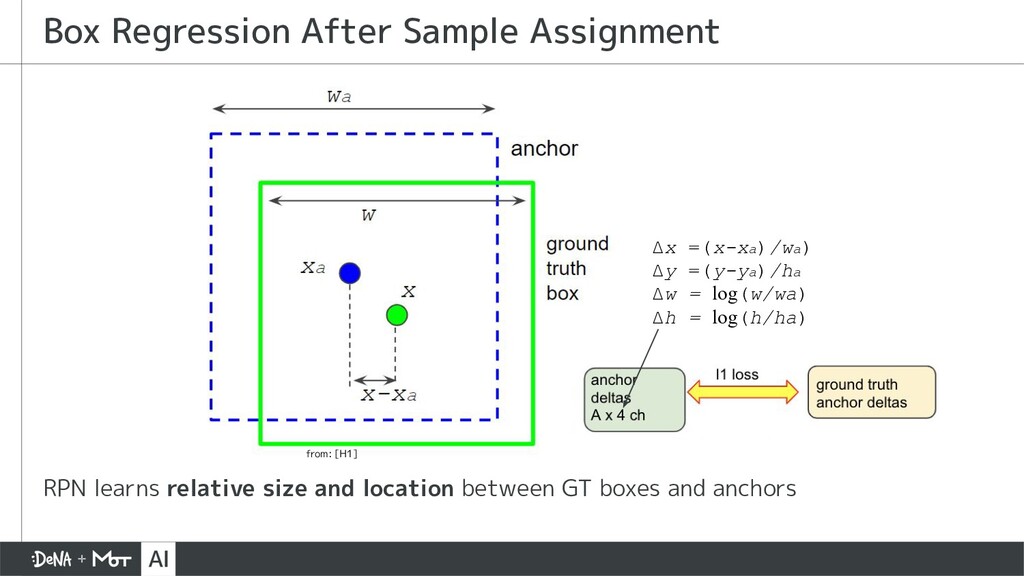
RPN learns relative size and location between GT boxes and
anchors Box Regression After Sample Assignment from: [H1] Δx =(x-xa)/wa) Δy =(y-ya)/ha Δw = log(w/wa) Δh = log(h/ha) -
RetinaNet / EfficientDet detector name backbone neck dense head roi
head RetinaNet [5] ResNet FPN RetinaNetHead - EfficientDet [6] EfficientNet BiFPN RetinaNetHead - -
RetinaNet stem C2 C3 C4 C5 Input Image BGR, H,
W P6, P7 P5 P4 P3 P2 + + + + Backbone RetinaNetHead cls_subnet -> cls_score bbox_subnet -> bbox_pred -
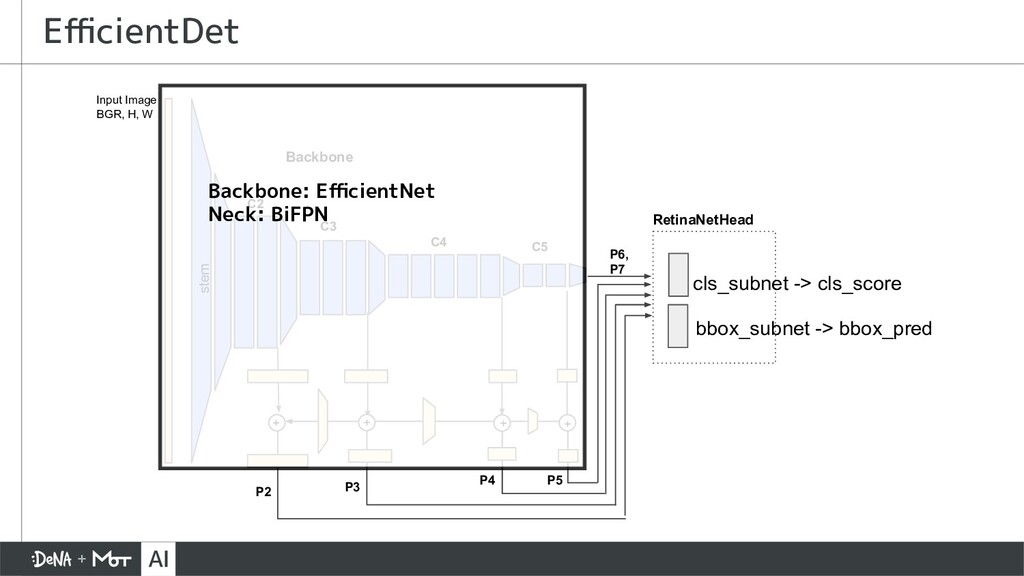
EfficientDet stem C2 C3 C4 C5 Input Image BGR, H,
W P6, P7 P5 P4 P3 P2 + + + + Backbone RetinaNetHead cls_subnet -> cls_score bbox_subnet -> bbox_pred Backbone: EfficientNet Neck: BiFPN -
same as RPN - number of anchors and IoU thresholds
are different Sample Assignment of RetinaNet and EfficientDet foreground (IoU ≧ T1) : class target = one-hot, regression target background (IoU < T2): class target = zeros, no regression loss ignored (T2 ≦ IoU < T1) [only RetinaNet] T1 and T2: predefined threshold values architecture num. anchors at grid cell T1 T2 Faster R-CNN 3 0.7 0.3 RetinaNet 9 0.5 0.4 EfficientDet 3 0.5 0.5 0 0 0.41 0.28 0 0 0 0 0 0 0 0 0 0 0 0.68 0 0 GT box 0 GT box 1 matched with GT box 1, foreground background ignored IoU value anchors position 0 position 1 position 2 [3] -
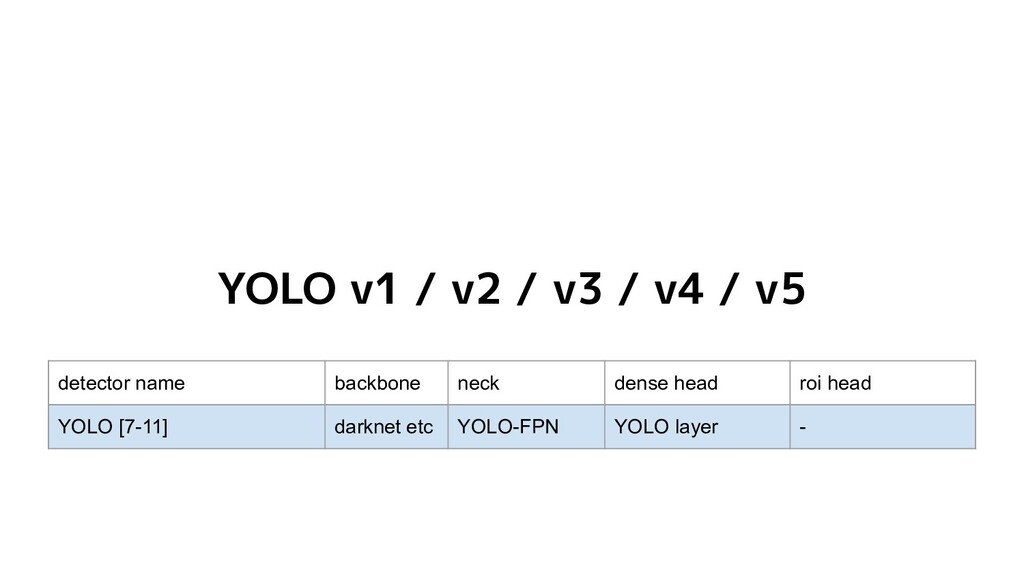
YOLO v1 / v2 / v3 / v4 / v5
detector name backbone neck dense head roi head YOLO [7-11] darknet etc YOLO-FPN YOLO layer - -
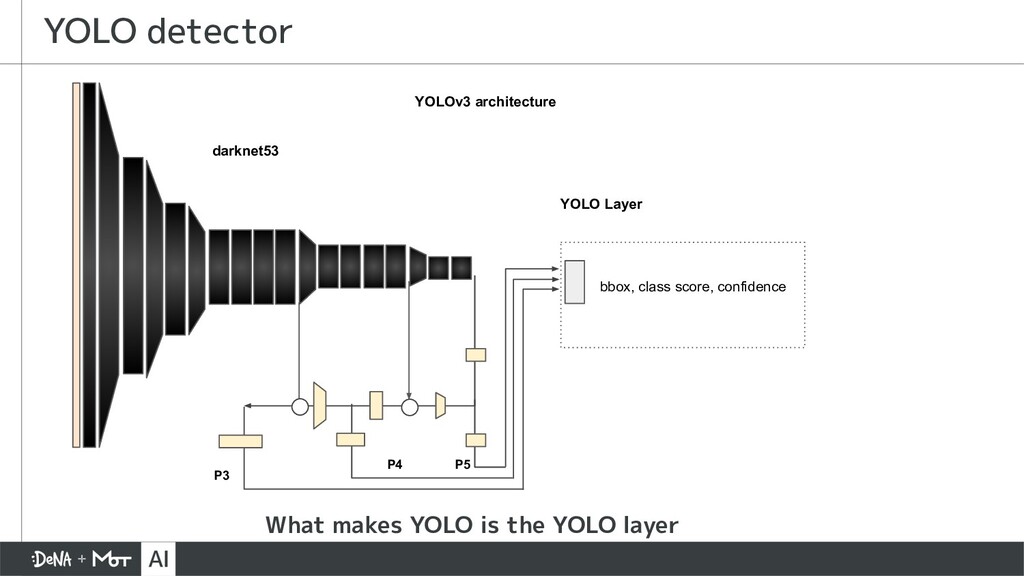
What makes YOLO is the YOLO layer YOLO detector P5
P4 P3 YOLO Layer bbox, class score, confidence darknet53 YOLOv3 architecture -
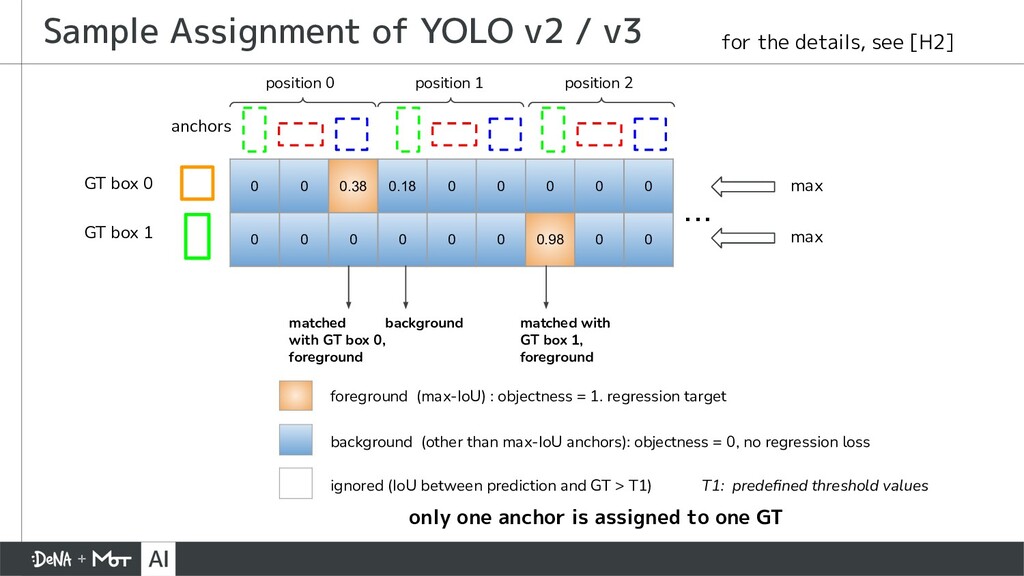
Sample Assignment of YOLO v2 / v3 0 0 0.38
0.18 0 0 0 0 0 0 0 0 0 0 0 0.98 0 0 GT box 0 GT box 1 ・・・ matched with GT box 1, foreground background matched with GT box 0, foreground ignored (IoU between prediction and GT > T1) only one anchor is assigned to one GT max max foreground (max-IoU) : objectness = 1. regression target background (other than max-IoU anchors): objectness = 0, no regression loss for the details, see [H2] T1: predefined threshold values position 0 position 1 position 2 anchors -
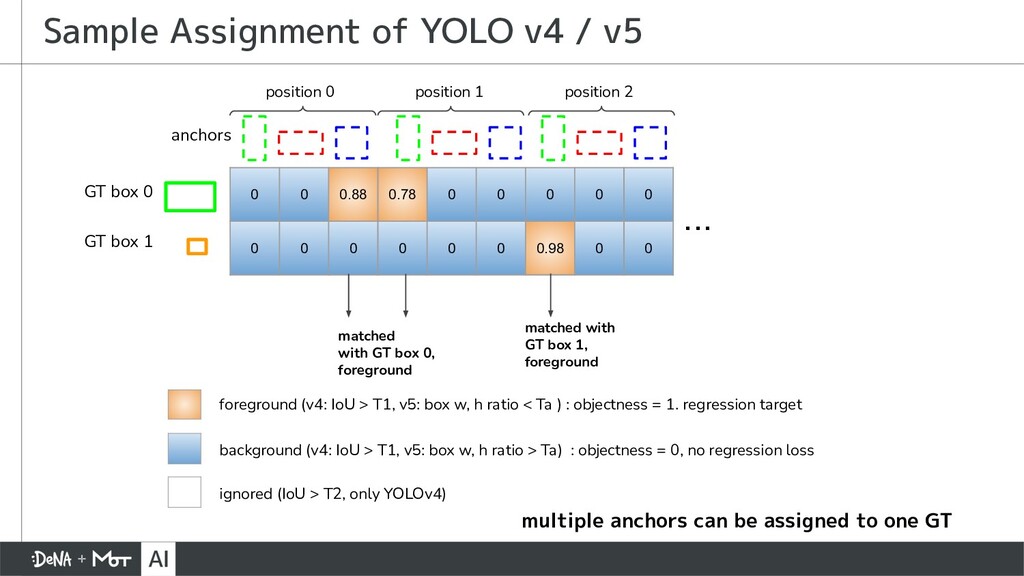
Sample Assignment of YOLO v4 / v5 0 0 0.88
0.78 0 0 0 0 0 0 0 0 0 0 0 0.98 0 0 foreground (v4: IoU > T1, v5: box w, h ratio < Ta ) : objectness = 1. regression target background (v4: IoU > T1, v5: box w, h ratio > Ta) : objectness = 0, no regression loss ignored (IoU > T2, only YOLOv4) GT box 0 GT box 1 ・・・ matched with GT box 1, foreground matched with GT box 0, foreground multiple anchors can be assigned to one GT anchors position 0 position 1 position 2 -
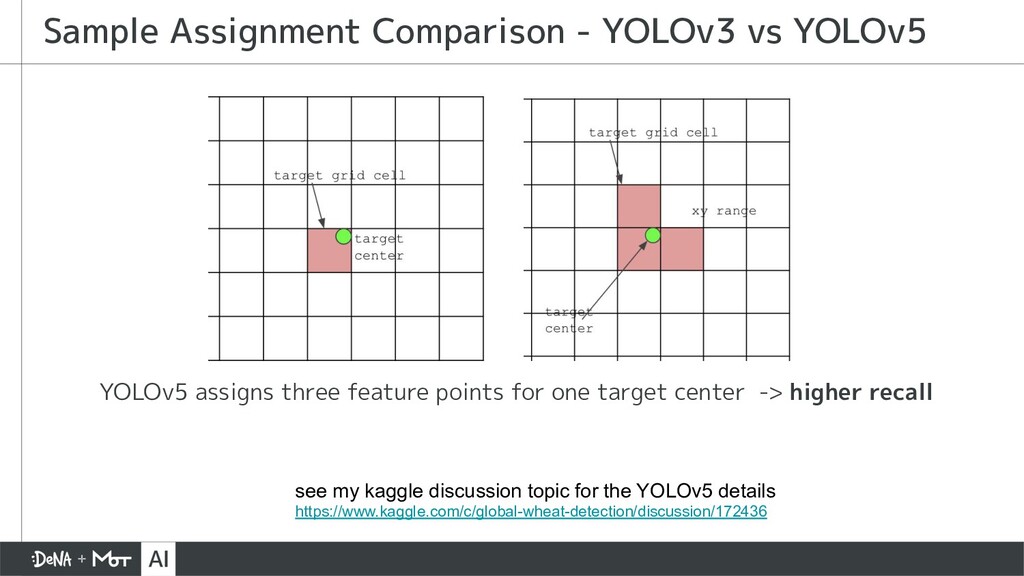
YOLOv5 assigns three feature points for one target center ->
higher recall Sample Assignment Comparison - YOLOv3 vs YOLOv5 see my kaggle discussion topic for the YOLOv5 details https://www.kaggle.com/c/global-wheat-detection/discussion/172436 -
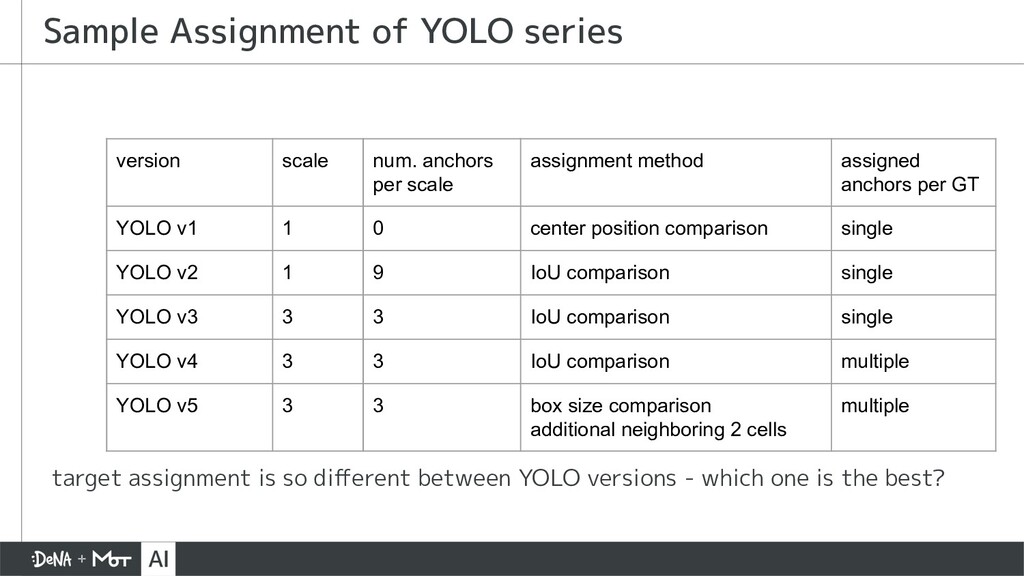
target assignment is so different between YOLO versions - which
one is the best? Sample Assignment of YOLO series version scale num. anchors per scale assignment method assigned anchors per GT YOLO v1 1 0 center position comparison single YOLO v2 1 9 IoU comparison single YOLO v3 3 3 IoU comparison single YOLO v4 3 3 IoU comparison multiple YOLO v5 3 3 box size comparison additional neighboring 2 cells multiple -
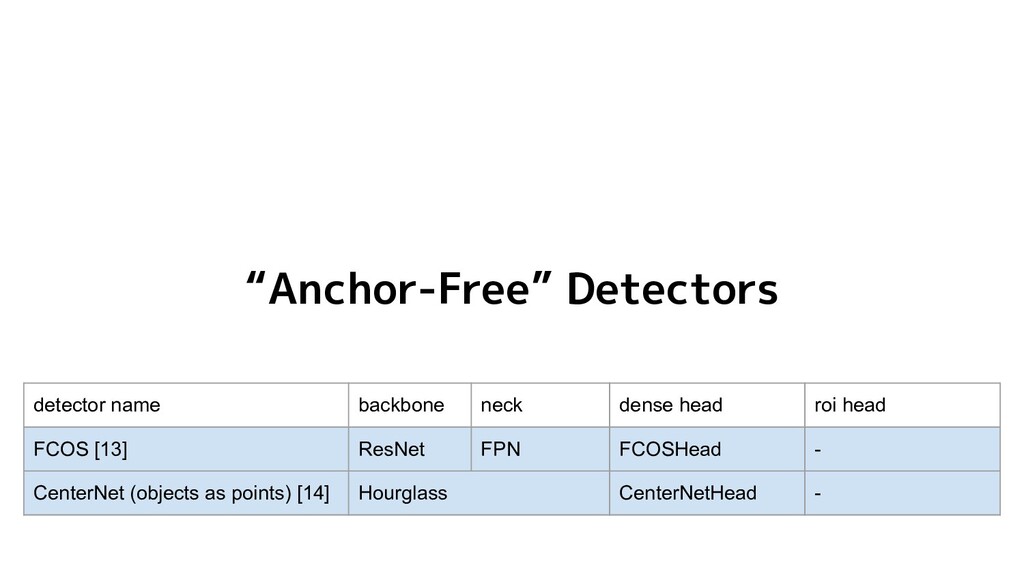
“Anchor-Free” Detectors detector name backbone neck dense head roi head
FCOS [13] ResNet FPN FCOSHead - CenterNet (objects as points) [14] Hourglass CenterNetHead - -
- Assign all the grid cells that fall into the
GT box - only at the appropriate scale - ‘Center-ness’ score is used additionally to suppress low-quality predictions far from the GT center FCOS -
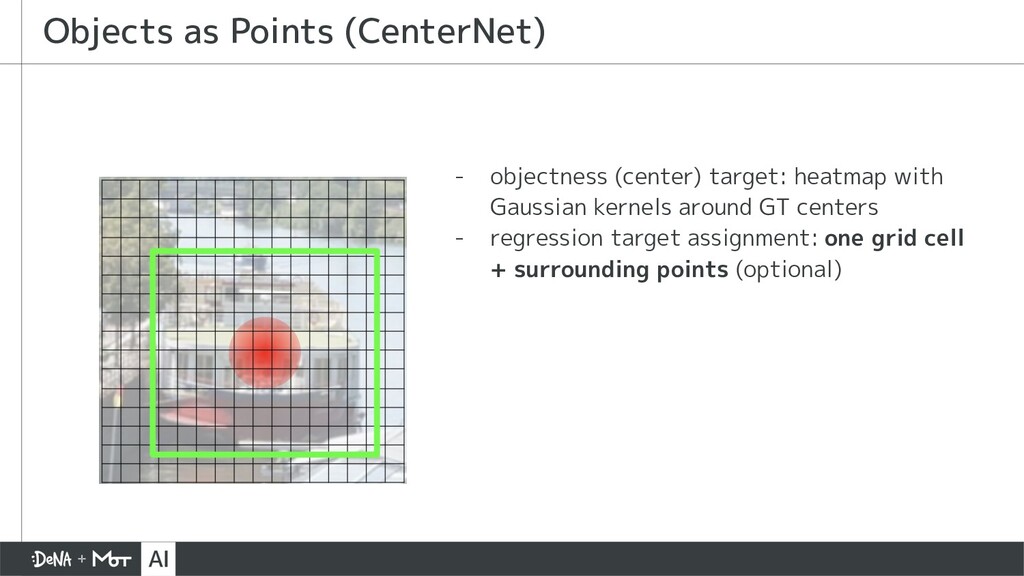
- objectness (center) target: heatmap with Gaussian kernels around GT
centers - regression target assignment: one grid cell + surrounding points (optional) Objects as Points (CenterNet) -
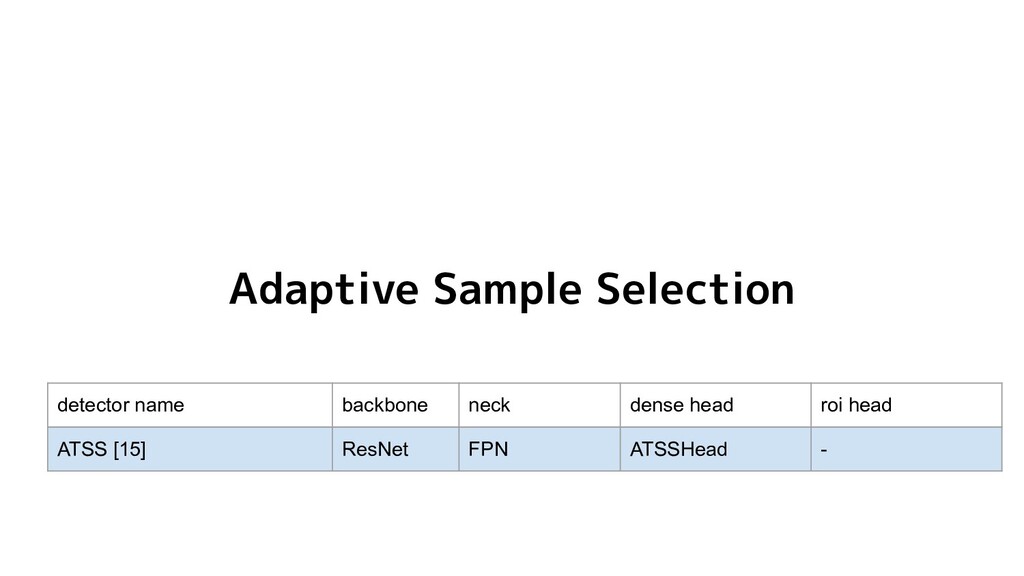
Adaptive Sample Selection detector name backbone neck dense head roi
head ATSS [15] ResNet FPN ATSSHead - -
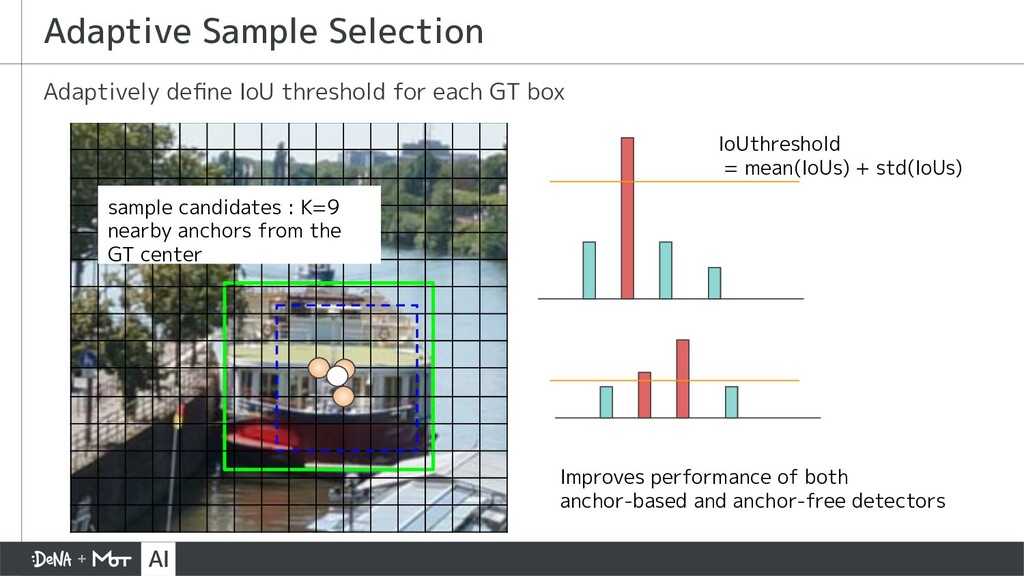
Adaptive Sample Selection Adaptively define IoU threshold for each GT
box IoUthreshold = mean(IoUs) + std(IoUs) sample candidates : K=9 nearby anchors from the GT center Improves performance of both anchor-based and anchor-free detectors -
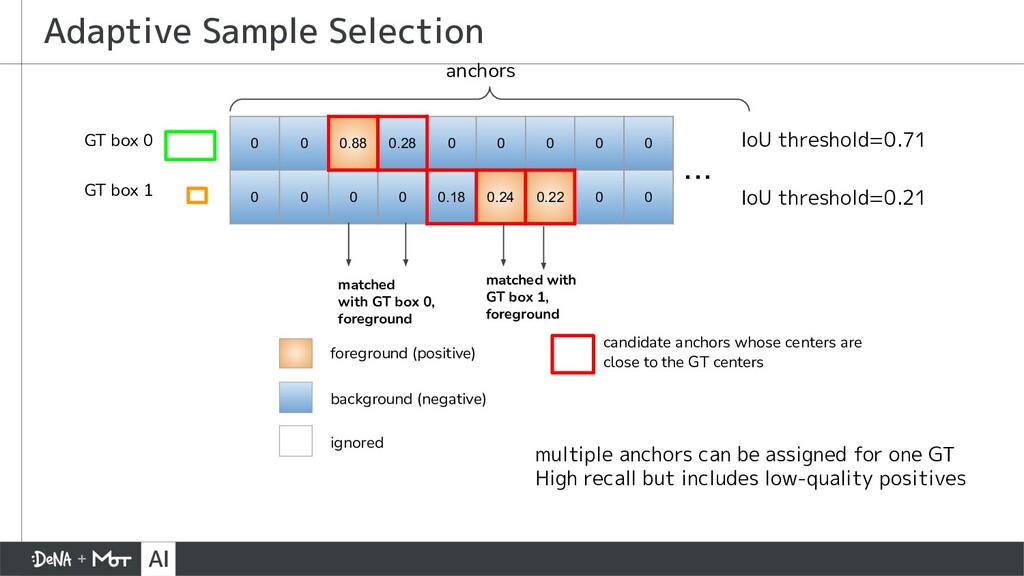
Adaptive Sample Selection 0 0 0.88 0.28 0 0 0
0 0 0 0 0 0 0.18 0.24 0.22 0 0 foreground (positive) background (negative) ignored GT box 0 GT box 1 ・・・ anchors matched with GT box 1, foreground matched with GT box 0, foreground multiple anchors can be assigned for one GT High recall but includes low-quality positives IoU threshold=0.71 IoU threshold=0.21 candidate anchors whose centers are close to the GT centers -
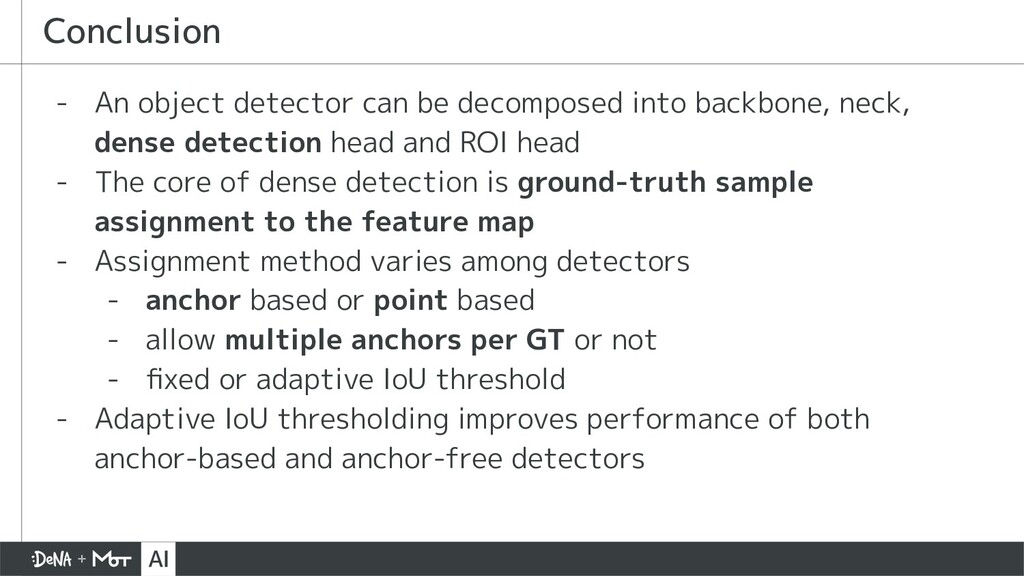
- An object detector can be decomposed into backbone, neck,
dense detection head and ROI head - The core of dense detection is ground-truth sample assignment to the feature map - Assignment method varies among detectors - anchor based or point based - allow multiple anchors per GT or not - fixed or adaptive IoU threshold - Adaptive IoU thresholding improves performance of both anchor-based and anchor-free detectors Conclusion -
[1] Shaoqing Ren, Kaiming He, Ross Girshick, and Jian Sun.
Faster R-CNN: Towards real-time object detection with region proposal networks. In NIPS, 2015. [2] T.-Y. Lin, P. Dollar, R. Girshick, K. He, B. Hariharan, and S. Belongie. Feature pyramid networks for object detection. In CVPR, 2017. [3] Yuxin Wu, Alexander Kirillov, Francisco Massa, Wan-Yen Lo and Ross Girshick, Detectron2. https://github.com/facebookresearch/detectron2, 2019. [4] Kaiming He, Georgia Gkioxari, Piotr Dollar, and Ross Girshick. Mask R-CNN. In ICCV, 2017. [5] T.-Y. Lin, P. Goyal, R. Girshick, K. He, and P. Dollar. Focal loss for dense object detection. In ICCV, 2017. [6] Mingxing Tan, Ruoming Pang, and Quoc V Le. EfficientDet: Scalable and efficient object detection. In CVPR , 2020. [7] Joseph Redmon, Santosh Divvala, Ross Girshick, and Ali Farhadi. You only look once: Unified, real-time object detection. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), pages 779– 788, 2016. [8] Joseph Redmon and Ali Farhadi. YOLO9000: better, faster, stronger. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR), pages 7263– 7271, 2017. [9] Joseph Redmon and Ali Farhadi. YOLOv3: An incremental improvement. arXiv preprint arXiv:1804.02767, 2018. [10] Alexey Bochkovskiy, Chien-Yao Wang, and Hong-Yuan Mark Liao. Yolov4: Optimal speed and accuracy of object detection. arXiv preprint arXiv:2004.10934, 2020. [11] YOLOv5, https://github.com/ultralytics/yolov5 , as of version 3.0 [12] Wei Liu, Dragomir Anguelov, Dumitru Erhan, Christian Szegedy, Scott Reed, Cheng-Yang Fu, and Alexander C 12 Berg. SSD: Single shot multibox detector. In ECCV, 2016. [13] Zhi Tian, Chunhua Shen, Hao Chen, and Tong He. FCOS: Fully convolutional one-stage object detection. In ICCV, 2019. [14] Xingyi Zhou, Dequan Wang, and Philipp Krahenbuhl. Objects as points. arXiv preprint arXiv:1904.07850, 2019. [15] Shifeng Zhang, Cheng Chi, Yongqiang Yao, Zhen Lei, and Stan Z Li. Bridging the gap between anchor-based and anchor-free detection via adaptive training sample selection. In CVPR, 2020. References -
Hiroto Honda’s medium blogs [H1] Digging Into Detectron 2 [part
1] : Introduction - Basic Network Architecture and Repo Structure [part 2] : Feature Pyramid Network [part 3] : Data Loader and Ground Truth Instances [part 4] : Region Proposal Network [part 5]: ROI (Box) Head [H2] Reproducing Training Performance of YOLOv3 in PyTorch [Part 0]: Introduction [Part 1]: Network Architecture and channel elements of YOLO layers [Part 2]: How to assign targets to multi-scale anchors References