Share
Embed
【論文紹介】Parallel Refinements for Lexically Constrained Text Generation with BART
社内の論文読み会にて発表した論文です。
元論文はこちらです。
https://aclanthology.org/2021.emnlp-main.681/
Soichiro Murakami
January 05, 2022
Transcript
21 slides
-
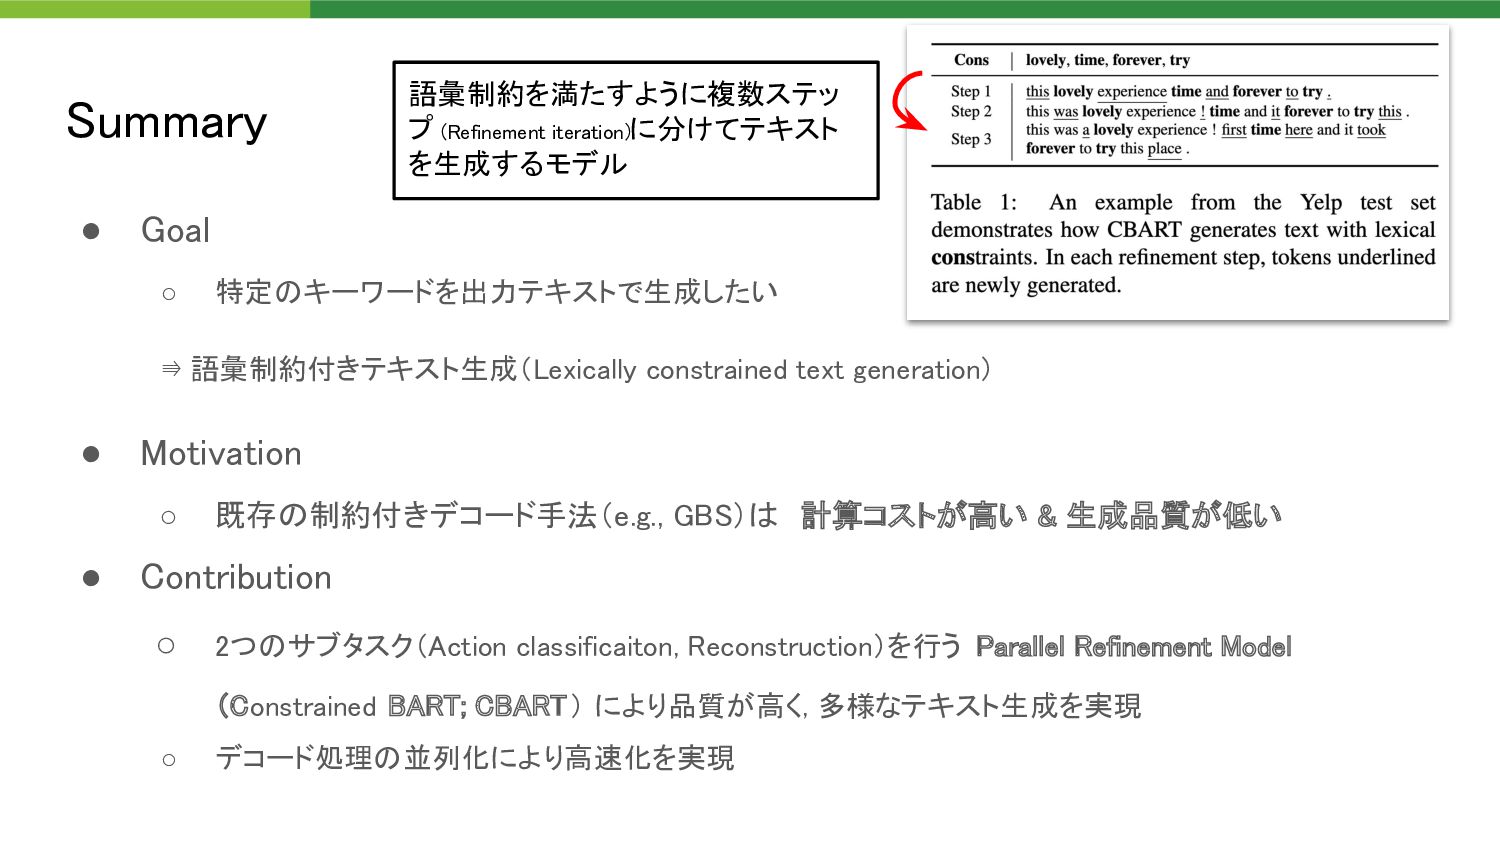
Summary • Goal ◦ 特定のキーワードを出力テキストで生成したい ⇛ 語彙制約付きテキスト生成(Lexically constrained text
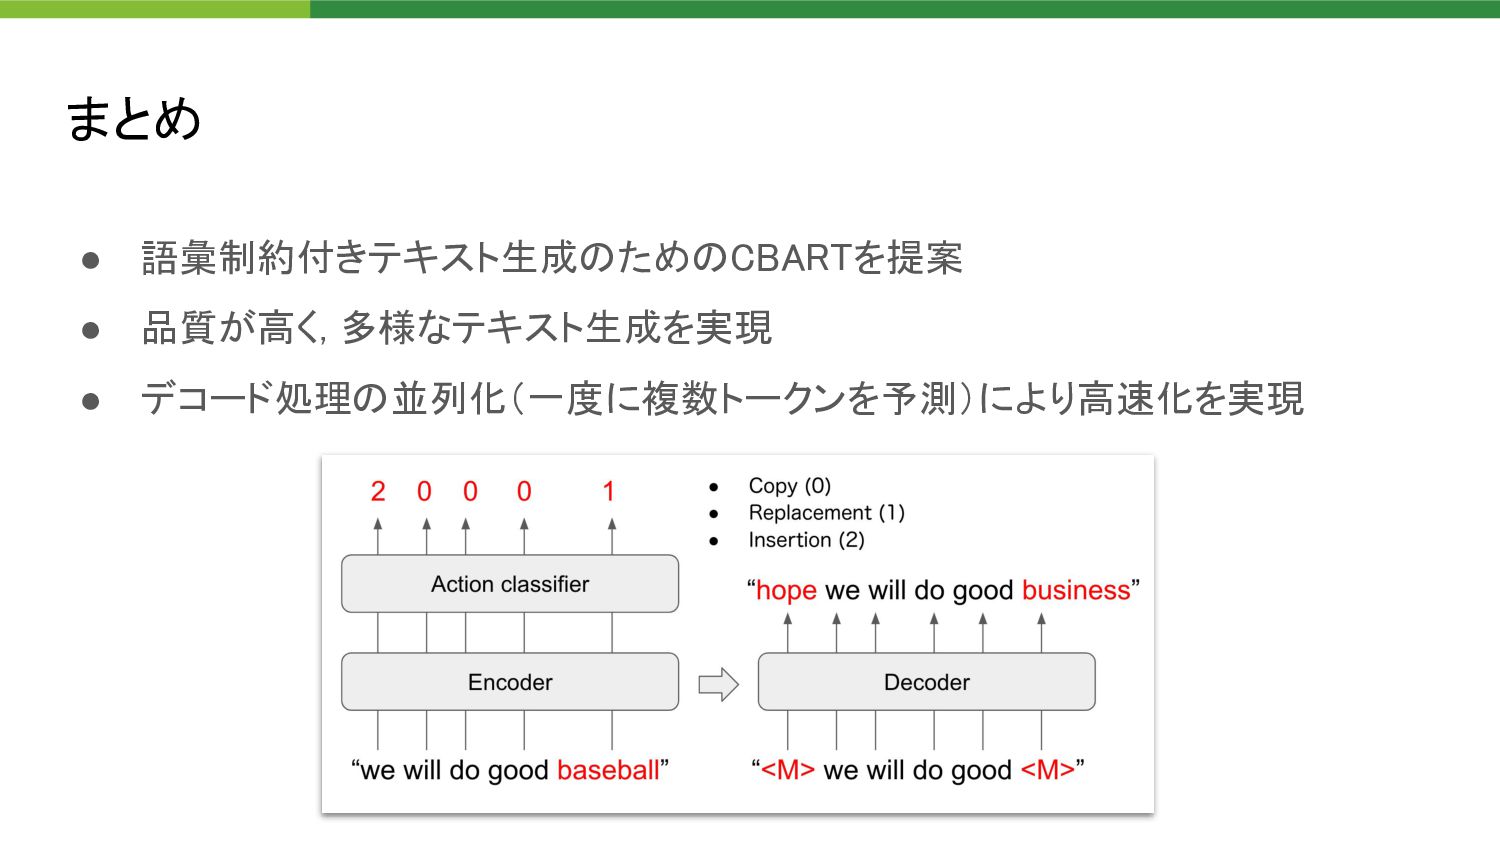
generation) • Motivation ◦ 既存の制約付きデコード手法(e.g., GBS)は 計算コストが高い & 生成品質が低い • Contribution ◦ 2つのサブタスク(Action classificaiton, Reconstruction)を行う Parallel Refinement Model (Constrained BART; CBART) により品質が高く, 多様なテキスト生成を実現 ◦ デコード処理の並列化により高速化を実現 語彙制約を満たすように複数ステッ プ (Refinement iteration) に分けてテキスト を生成するモデル -
Background: BART [Lewis+2019] • BART: Denoising Sequence-to-Sequence Pre-training for
Natural Language Generation, Translation, and Comprehension [Lewis+2019] 論文より引用 Denoising Autoencoder. Pretrained Seq-to-Seq Model -
Background: Non-Autoregressive Decoding BART [Lewis+2019] Autoregressive Decoding Levenshtein
Transformer [Gu+2019] Non-Autoregressive Decoding • デコード時に生成履歴を考慮できるの で流暢性が高い傾向 • デコード処理の並列化が難しい • デコード時に生成履歴を考慮できない ⇛ いくつかのステップを分けて生成する方法を提案 • デコード処理の並列化が容易 並列予測 1ステップ前の予測を基に、次を予測 ⇛ Refinement model とも呼ばれる -
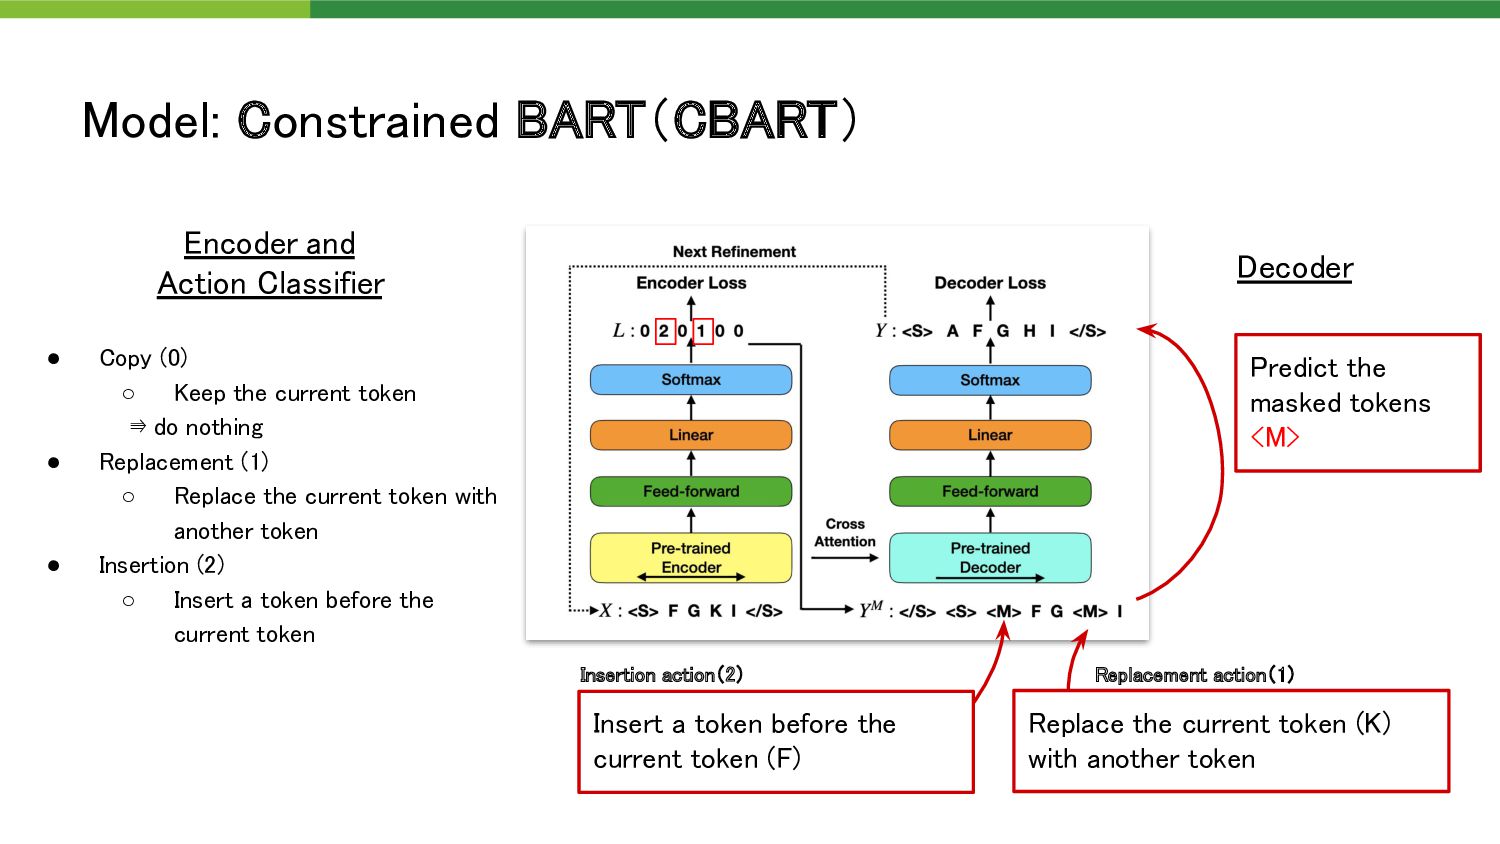
Model: Constrained BART(CBART) Encoder and Action Classifier Decoder Predict
the masked tokens <M> • Copy (0) ◦ Keep the current token ⇛ do nothing • Replacement (1) ◦ Replace the current token with another token • Insertion (2) ◦ Insert a token before the current token Insert a token before the current token (F) Replace the current token (K) with another token Insertion action(2) Replacement action(1) -
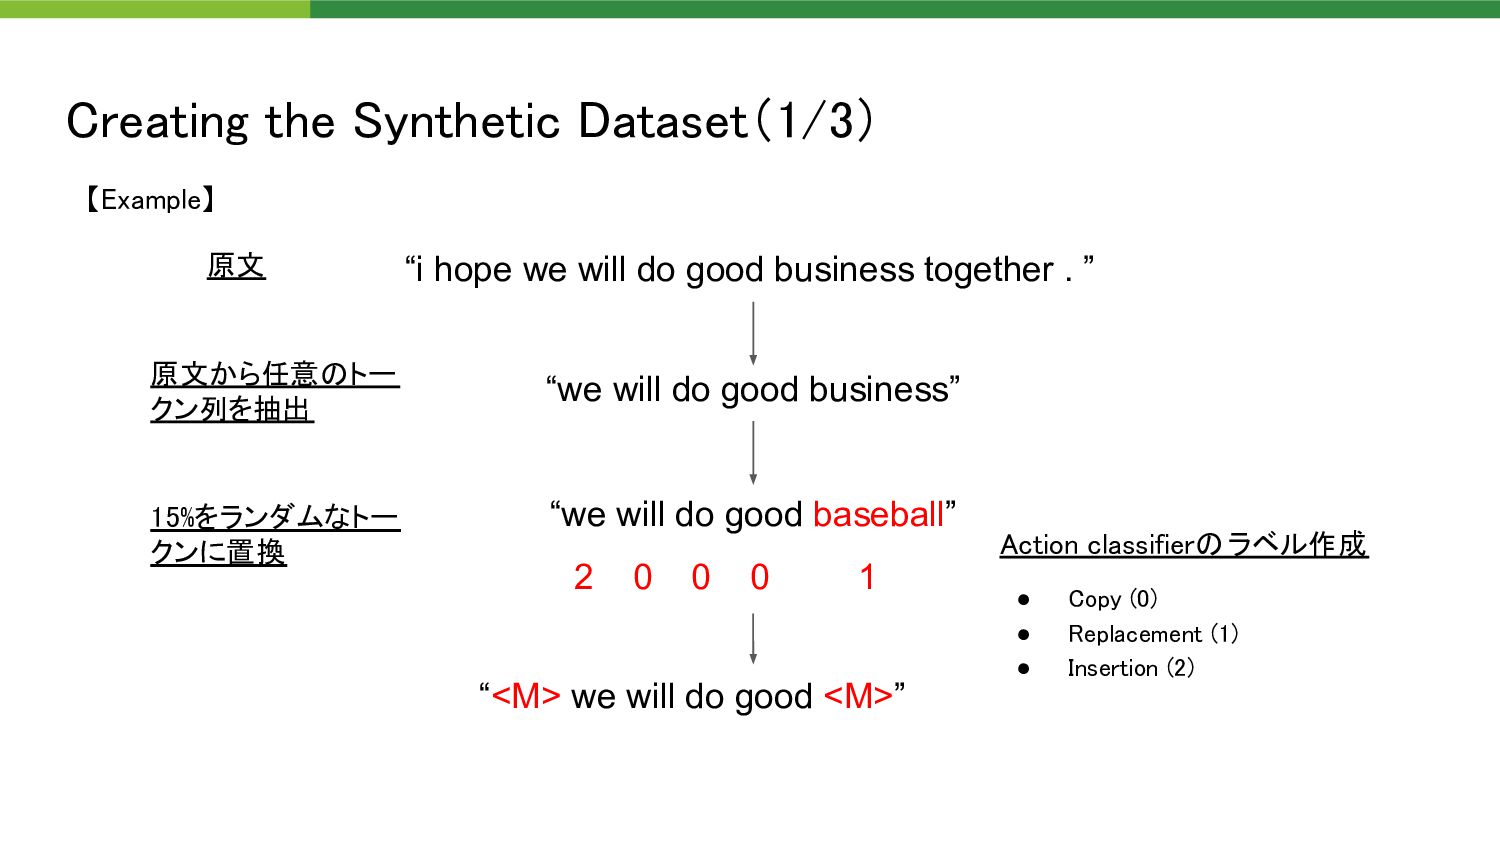
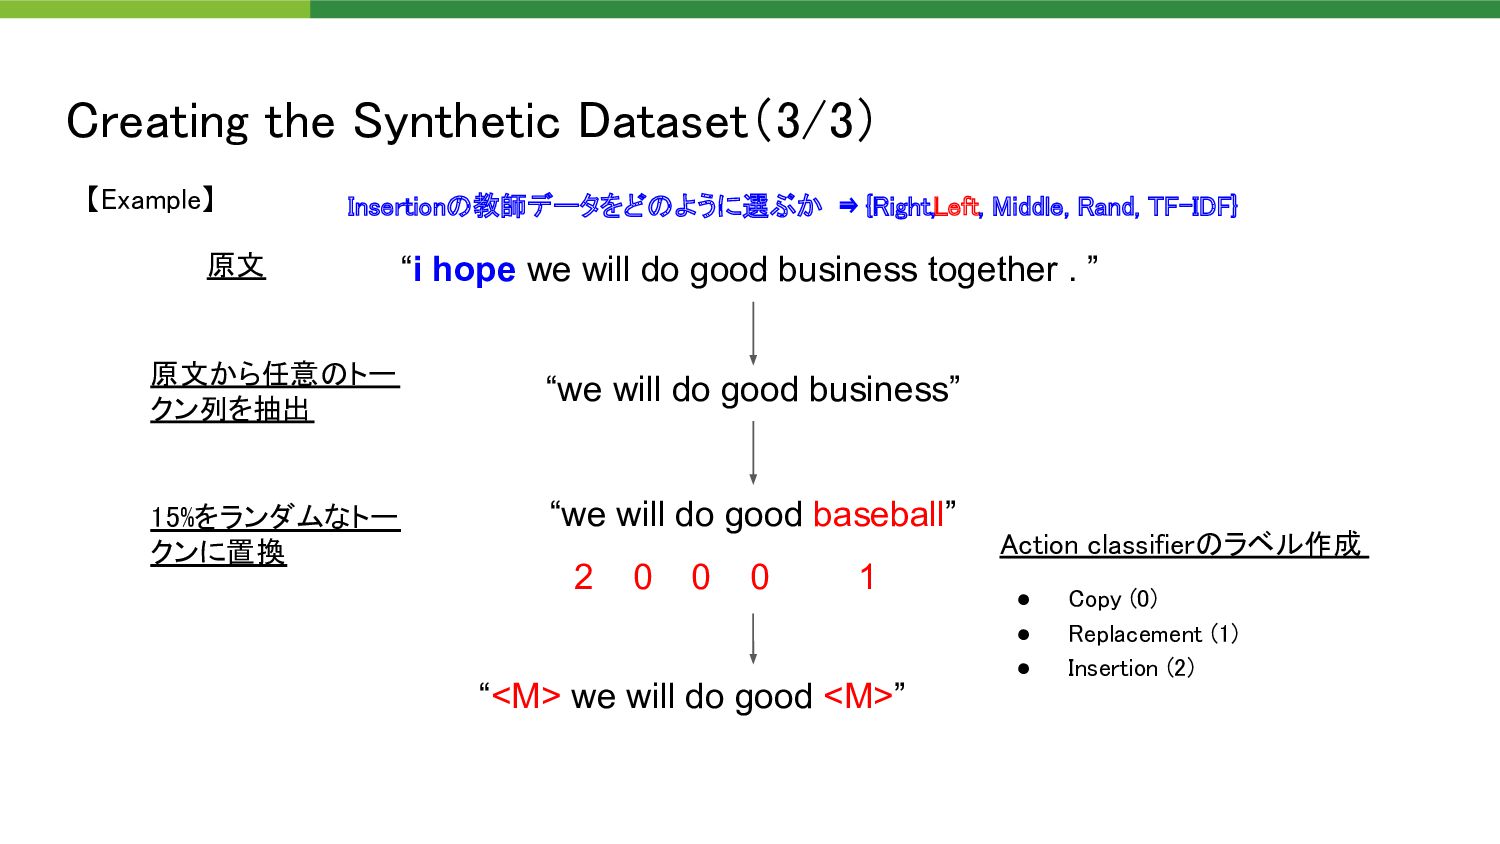
Creating the Synthetic Dataset(1/3) “i hope we will do good
business together . ” “we will do good business” 【Example】 “we will do good baseball” 原文 原文から任意のトー クン列を抽出 15%をランダムなトー クンに置換 “<M> we will do good <M>” 2 0 0 0 1 Action classifierのラベル作成 • Copy (0) • Replacement (1) • Insertion (2) -
Creating the Synthetic Dataset(2/3) “we will do good
baseball” Encoder Action classifier Decoder 2 0 0 0 1 “<M> we will do good <M>” “hope we will do good business” • Copy (0) • Replacement (1) • Insertion (2) -
Creating the Synthetic Dataset(3/3) “i hope we will
do good business together . ” “we will do good business” 【Example】 “we will do good baseball” 原文 原文から任意のトー クン列を抽出 15%をランダムなトー クンに置換 “<M> we will do good <M>” 2 0 0 0 1 Action classifierのラベル作成 • Copy (0) • Replacement (1) • Insertion (2) Insertionの教師データをどのように選ぶか ⇛ {Right, Left, Middle, Rand, TF-IDF} -
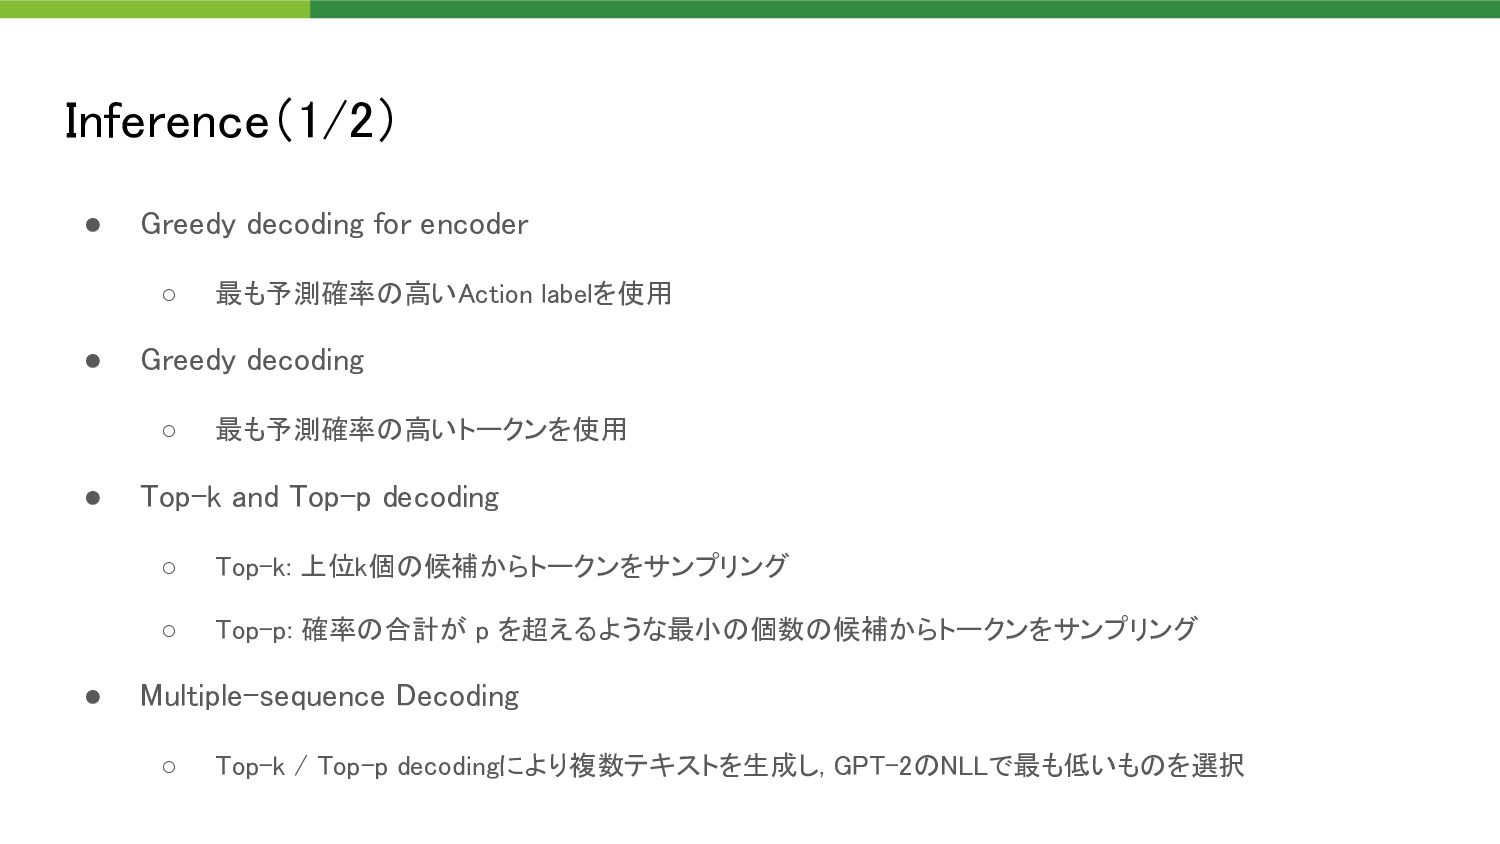
Inference(1/2) • Greedy decoding for encoder ◦ 最も予測確率の高いAction labelを使用
• Greedy decoding ◦ 最も予測確率の高いトークンを使用 • Top-k and Top-p decoding ◦ Top-k: 上位k個の候補からトークンをサンプリング ◦ Top-p: 確率の合計が p を超えるような最小の個数の候補からトークンをサンプリング • Multiple-sequence Decoding ◦ Top-k / Top-p decodingにより複数テキストを生成し, GPT-2のNLLで最も低いものを選択 -
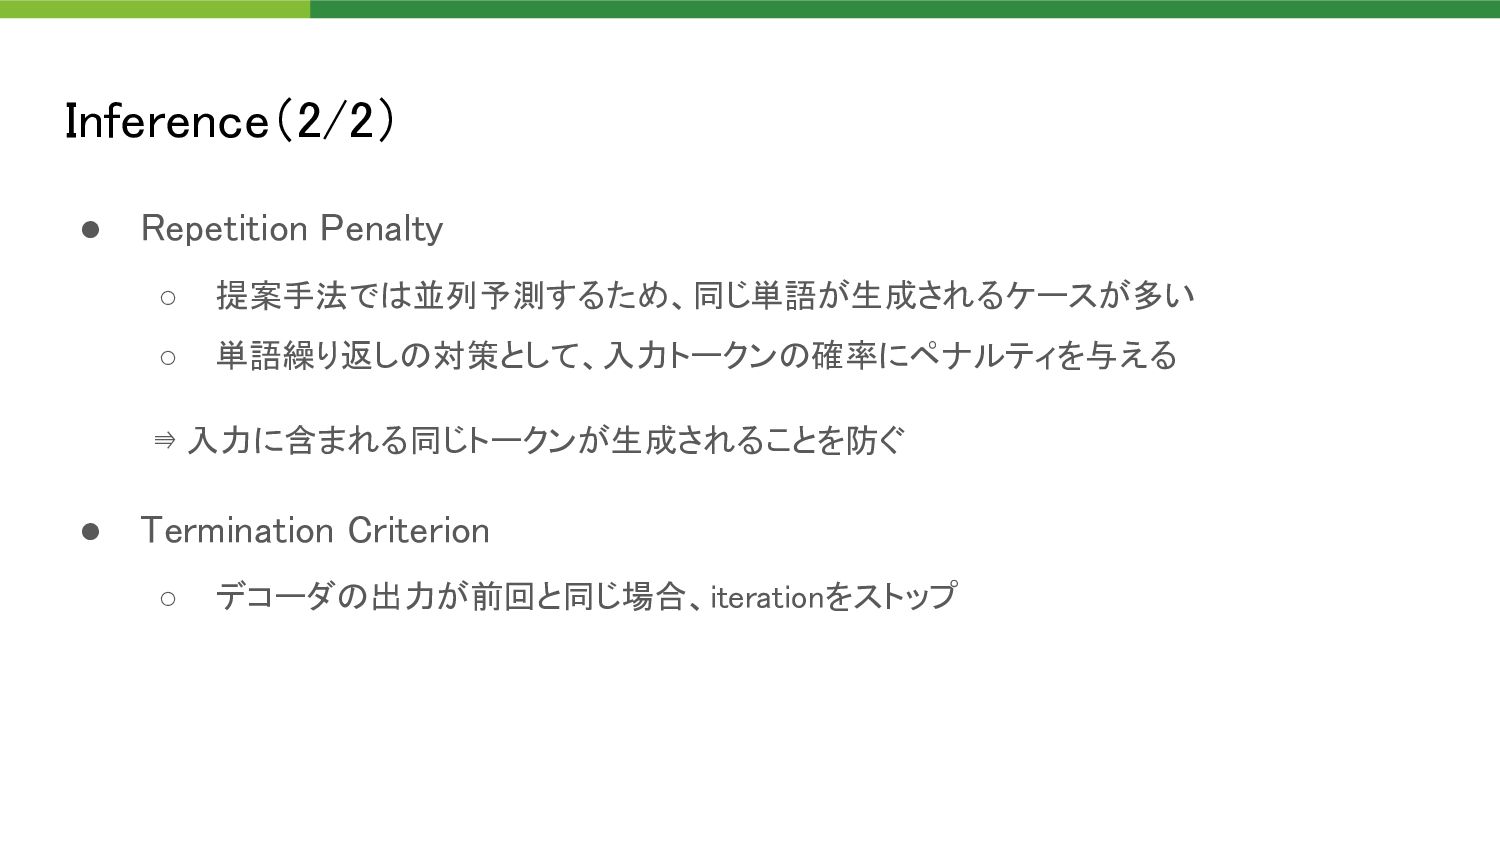
Inference(2/2) • Repetition Penalty ◦ 提案手法では並列予測するため、同じ単語が生成されるケースが多い ◦ 単語繰り返しの対策として、入力トークンの確率にペナルティを与える
⇛ 入力に含まれる同じトークンが生成されることを防ぐ • Termination Criterion ◦ デコーダの出力が前回と同じ場合、iterationをストップ -
Experiments • Model ◦ initialize CBART with the BART-large model
• Dataset ◦ One-Billion-Word ▪ news crawl data ◦ Yelp ▪ business reviews on Yelp • Preprocess ◦ 10 < length < 40 • Keywords ◦ extract 1-6 keywords from each sentence -
Baselines • Backward and forward Language Model (sep-B/F , asyn-B/F)
[Mou+2015][Liu+2019] ◦ 制約トークン数が1つに限られる • Grid Beam Search (GBS) [Hokamp+2017] ◦ 将来の制約トークンを考慮できないため、生成品質が劣る • CGMH [Miao+2019] ※MCMCに基づく手法 ◦ 1トークンずつ改善. 生成時のAction(挿入,削除,置換)と位置をランダム選択. • X-MCMC-C [He+2021] ※MCMCに基づく手法 ◦ 1トークンずつ改善. 分類器を導入. Contextsに応じて, 繰り返しトークンを改善. • POINTER / POINTER-2 [Zhang+2020] ◦ 複数トークンを同時に改善. しかし, 本モデルではActionと位置をBERTにより予測するが, BERTは 言語生成に向いていない Traditional baselines Recent models 合計で7つのモデルと比較 -
Main Comparison Experiment Results ※Yelpの結果は省略 Quality Diversity Latency Repetition
Refinementの繰り返し数 • Quality, Diversity, Latencyが改善 k: top-k, p: top-k, c: number of parallel sequence -
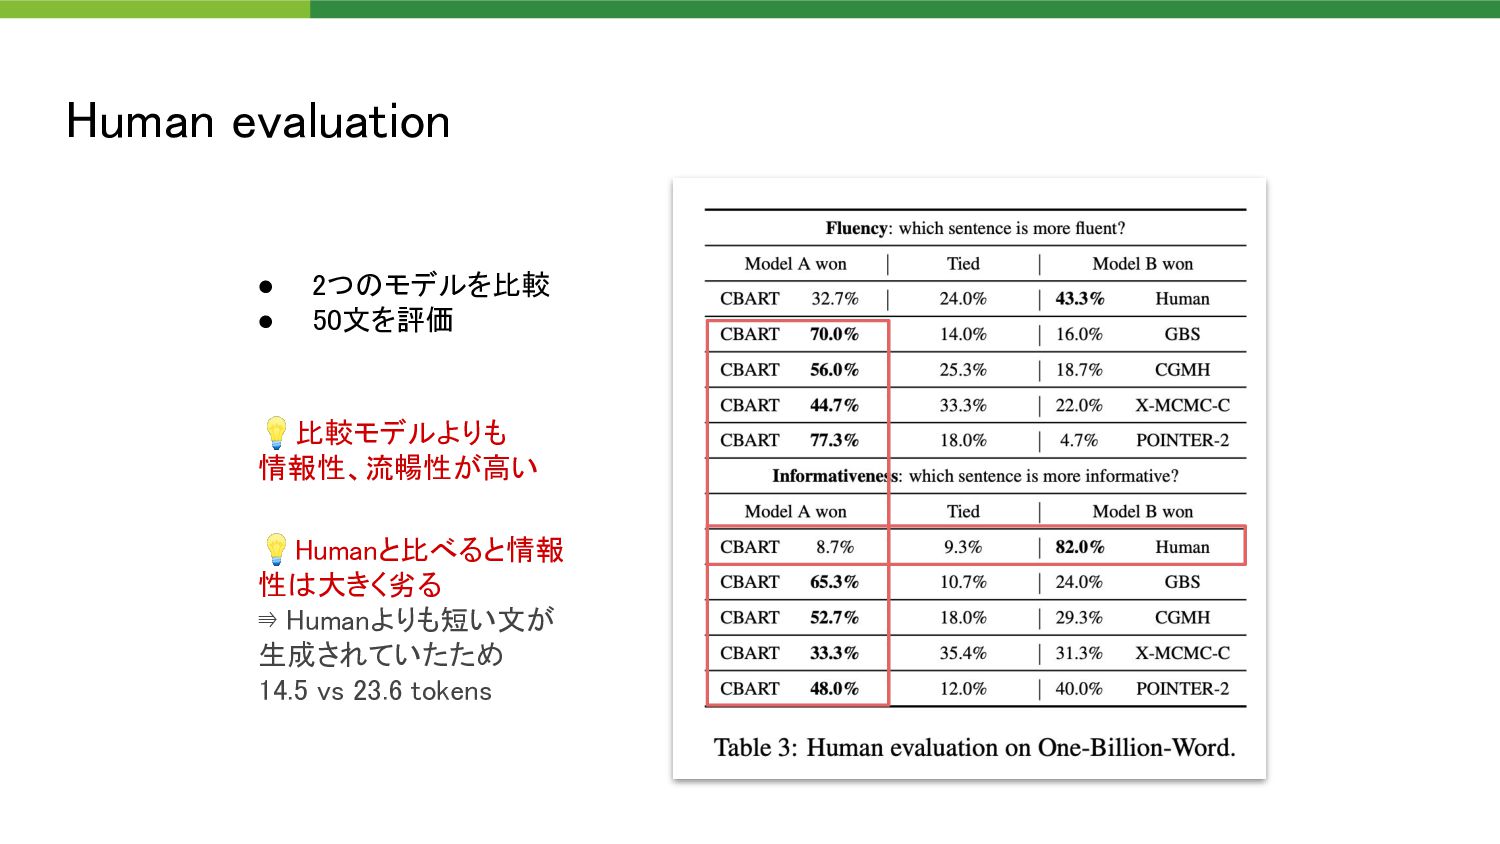
Human evaluation • 2つのモデルを比較 • 50文を評価 💡Humanと比べると情報 性は大きく劣る ⇛ Humanよりも短い文が
生成されていたため 14.5 vs 23.6 tokens 💡比較モデルよりも 情報性、流暢性が高い -
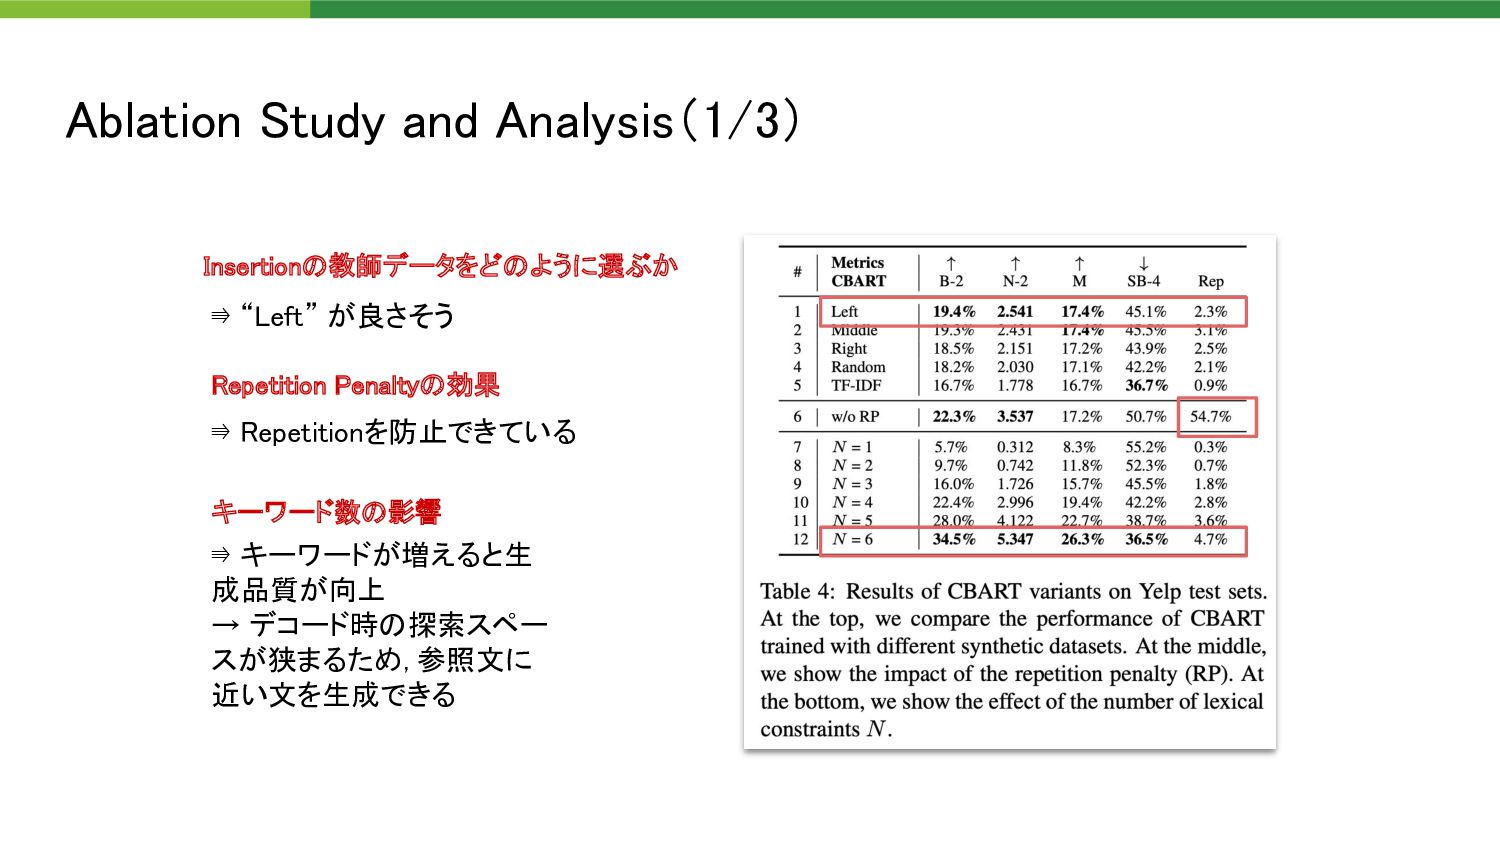
Ablation Study and Analysis(1/3) Insertionの教師データをどのように選ぶか Repetition Penaltyの効果 キーワード数の影響 ⇛
“Left” が良さそう ⇛ Repetitionを防止できている ⇛ キーワードが増えると生 成品質が向上 → デコード時の探索スペー スが狭まるため, 参照文に 近い文を生成できる -
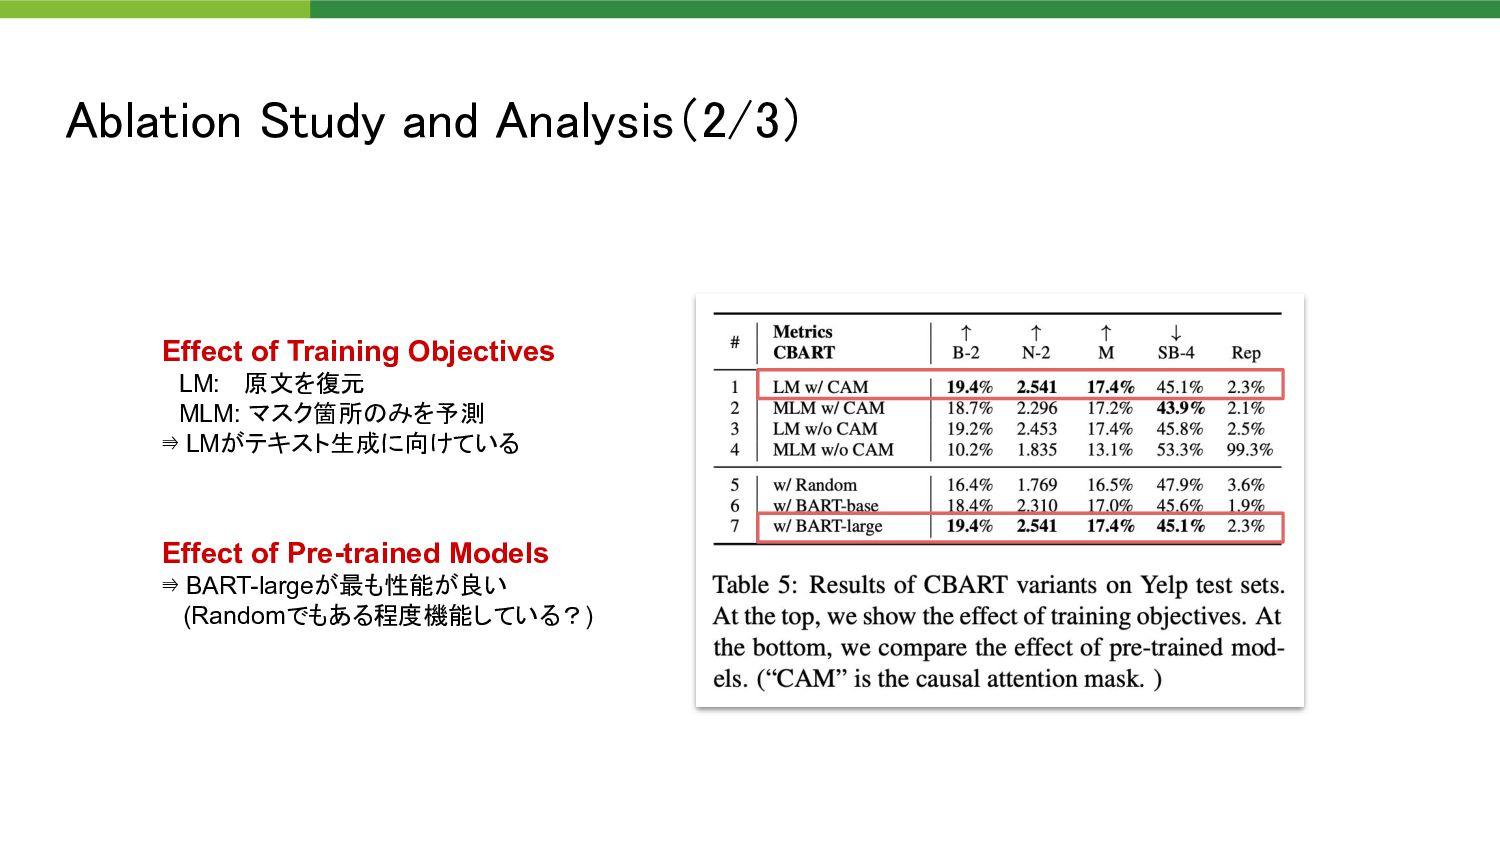
Ablation Study and Analysis(2/3) Effect of Training Objectives LM: 原文を復元
MLM: マスク箇所のみを予測 ⇛ LMがテキスト生成に向けている Effect of Pre-trained Models ⇛ BART-largeが最も性能が良い (Randomでもある程度機能している?) -
Related work • 制約トークン数が1つに限られる ◦ Backward and forward Language Model
(B/F-LM) [Mou+2015][Liu+2019] • 将来の制約トークンを考慮できないため、生成品質が劣る ◦ Grid Beam Search (GBS) [Hokamp+2017] • Contextsに応じて、繰り返しにトークンを改善で可能 ◦ MCMC-based Model [Berglund+2015][Su+2018][Devlin+2019] • 生成時のAction(挿入,削除,置換)と位置をランダムに選ぶため時間を要する ◦ CGMH [Miao+2019] • Actionと位置をBERTにより予測するが, BERTは言語生成に向いていない ◦ POINTER [Zhang+2020]