Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Cassandra for Data Analytics Backends
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
αλεx π
September 24, 2015
Research
470
7
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Cassandra for Data Analytics Backends
αλεx π
September 24, 2015
More Decks by αλεx π
See All by αλεx π
Scalable Time Series With Cassandra
ifesdjeen
1
440
Bayesian Inference is known to make machines biased
ifesdjeen
2
420
Stream Processing and Functional Programming
ifesdjeen
1
800
PolyConf 2015 - Rocking the Time Series boat with C, Haskell and ClojureScript
ifesdjeen
0
540
Clojure - A Sweetspot for Analytics
ifesdjeen
8
2.1k
Going Off Heap
ifesdjeen
3
1.9k
Always be learning
ifesdjeen
1
200
Learn Yourself Emacs For Great Good workshop slides
ifesdjeen
3
360
What Reading 5 Papers can yield for your Business
ifesdjeen
0
420
Other Decks in Research
See All in Research
湯村研究室の紹介2026 / yumulab2026
yumulab
0
210
Bilan travail en élevage : première restitution des enquêtes 2025-2026
institutdelelevage
PRO
0
280
Bilan travail en élevage : première restitution des enquêtes 2025-2026
institutdelelevage
PRO
0
170
Santé et fertilité des sols : ce que nous disent les pratiques dans les systèmes de polyculture-élevage
institutdelelevage
PRO
0
230
論文紹介:Doc-to-LoRA: Learning to Instantly Internalize Contexts
yukako_nakano
0
230
ros2-perf-multihost: Automated Coordination Framework for Objective Architecture Evaluation in Distributed Systems
takasehideki
0
170
全国町字単位空き家率推定データver1.0データ仕様
microbaseinc
0
330
最先端NLP勉強会2026 論文紹介:Reasoning with Sampling: Your Base Model is Smarter Than You Think (ICLR 2026 paper)
kogoro
4
960
ふとした出会いで生まれたSkillが、 社内利用1位になるまで
mikimhk
22
25k
山中市政が招いた組織崩壊:よこはま安心ボックスを例に
sishi
0
370
ICAITD 2026 Oral Presentation
rikkabotan7
0
140
論文紹介: Understanding Epistemic Language with a Language-augmented Bayesian Theory of Mind
hisaokatsumi
0
210
Featured
See All Featured
Reality Check: Gamification 10 Years Later
codingconduct
0
2.4k
Building a Scalable Design System with Sketch
lauravandoore
464
34k
The Art of Programming - Codeland 2020
erikaheidi
57
14k
Producing Creativity
orderedlist
PRO
348
41k
The Director’s Chair: Orchestrating AI for Truly Effective Learning
tmiket
1
350
WCS-LA-2024
lcolladotor
0
990
Between Models and Reality
mayunak
4
570
Java REST API Framework Comparison - PWX 2021
mraible
34
9.8k
How to train your dragon (web standard)
notwaldorf
96
6.9k
Optimising Largest Contentful Paint
csswizardry
37
4k
Bootstrapping a Software Product
garrettdimon
PRO
306
120k
10 Git Anti Patterns You Should be Aware of
lemiorhan
PRO
659
62k
Transcript
@ifesdjeen
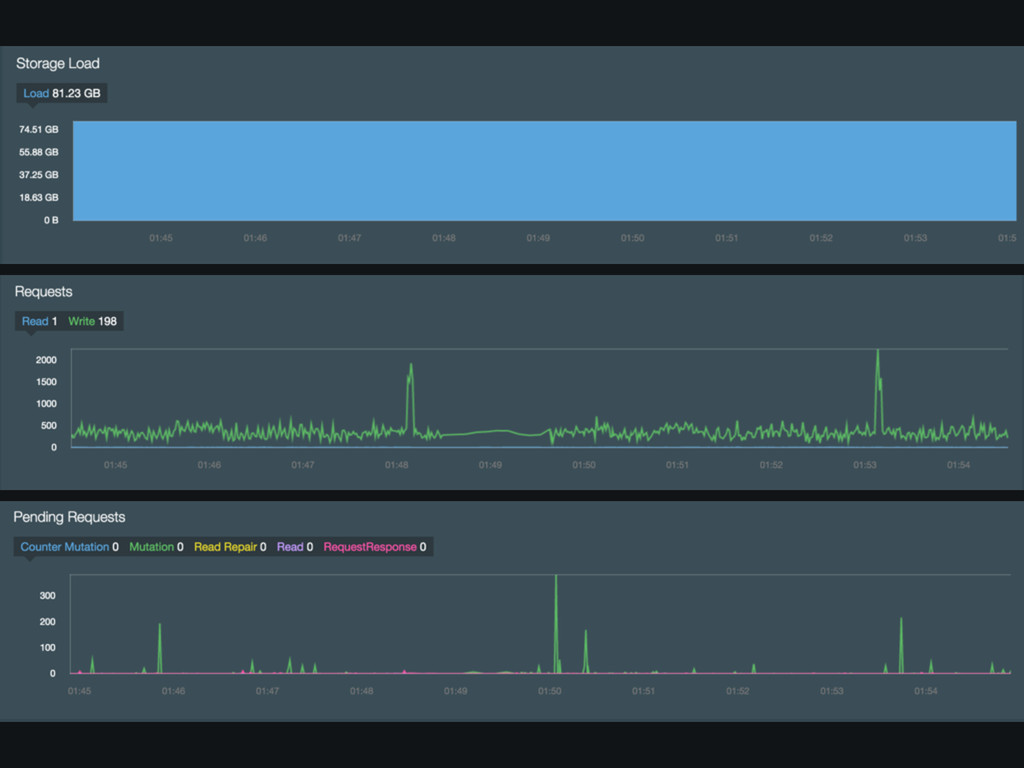
Cassandra Monitoring
None
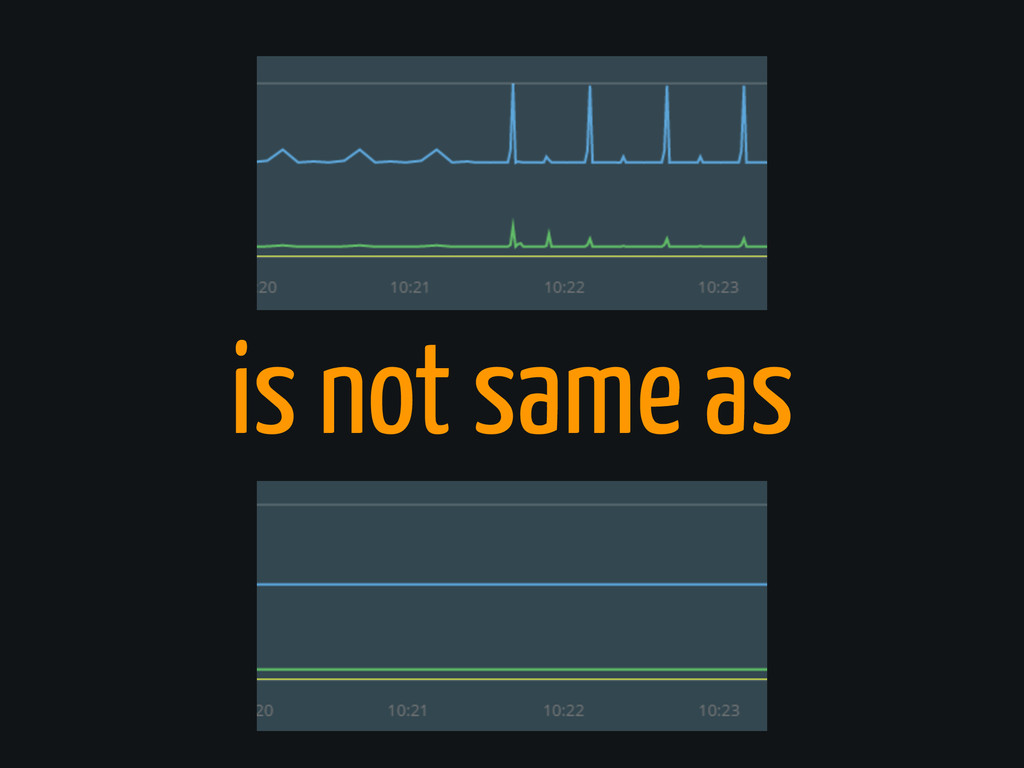
Precision
is not same as
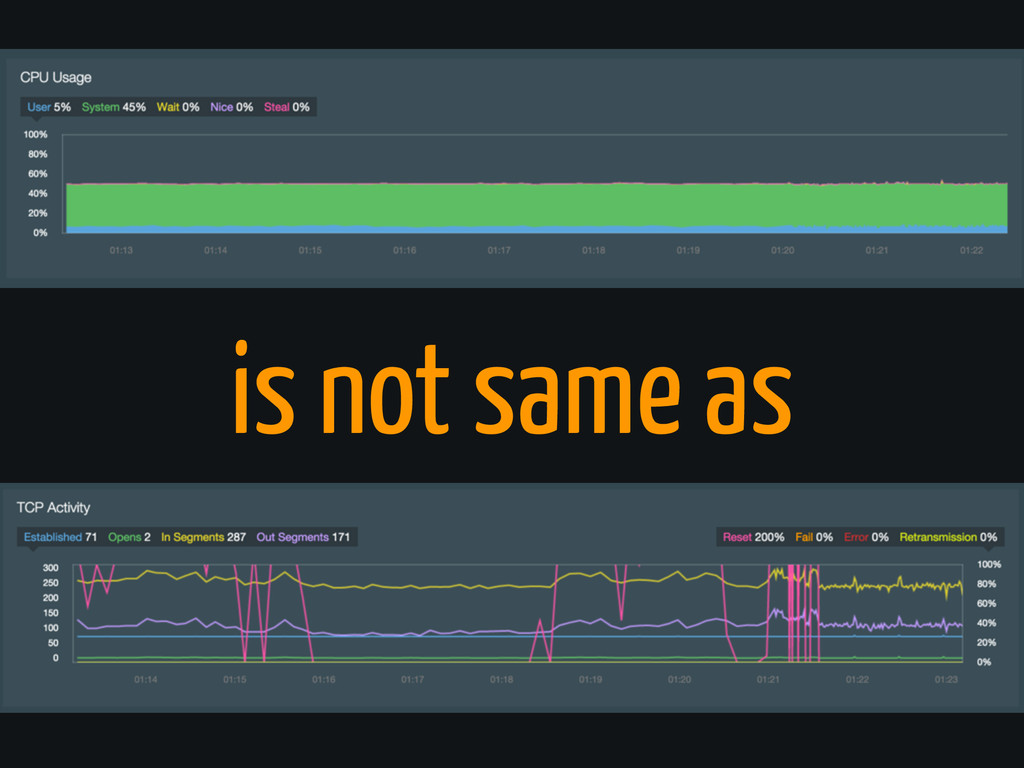
Semantics
is not same as
Anomaly detection
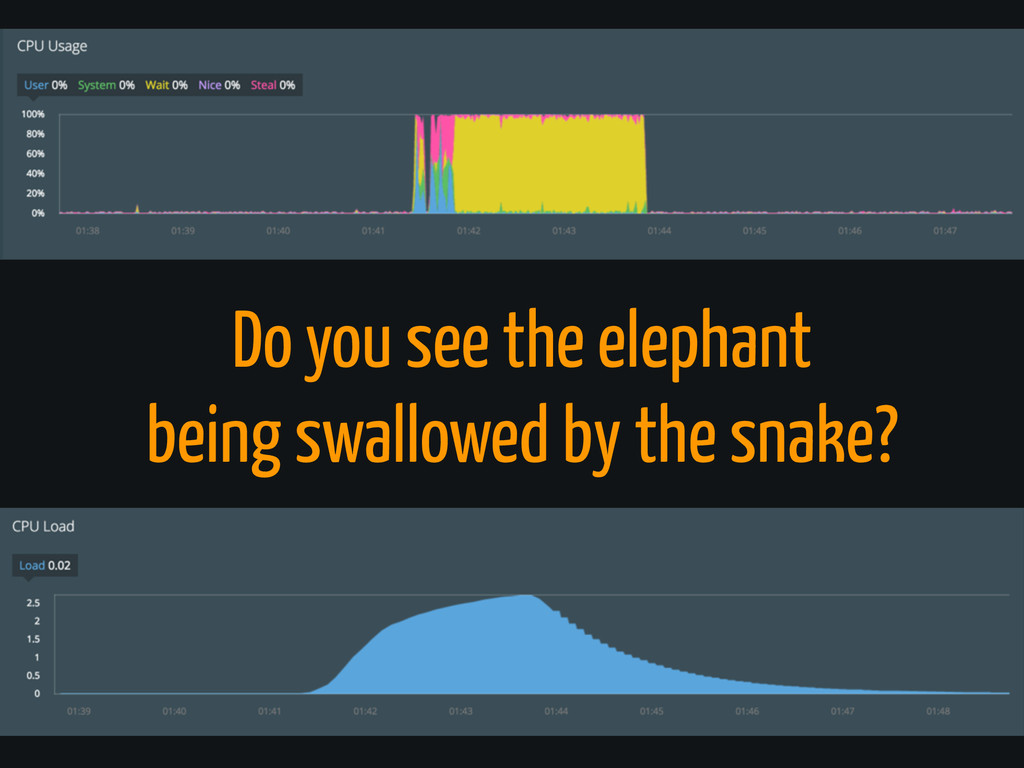
Do you see the elephant being swallowed by the snake?
Agenda
Ad-hoc queries
Aggregations Fast
Machine Learning
parallel queries Step 1
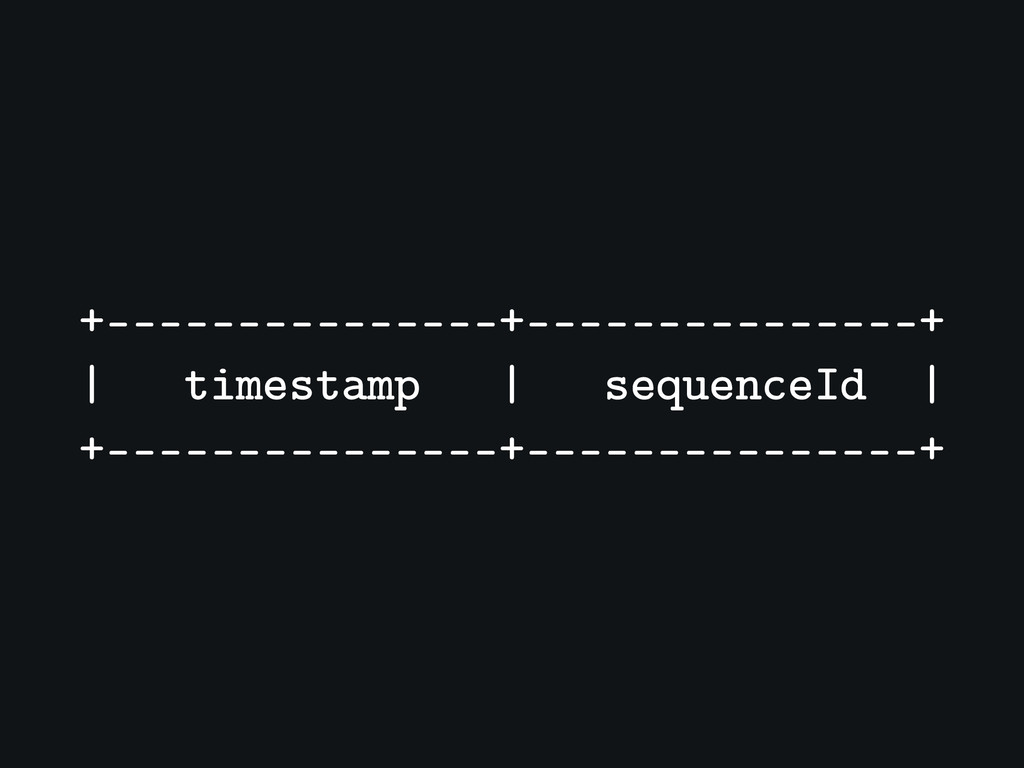
+---------------+---------------+ | timestamp | sequenceId | +---------------+---------------+
Used to avoid timestamp resolution collisions To ensure sub-resolution order
Snapshot the data on overflow or timeout Ensures idempotence Sequence ID
Fighting Dispersion
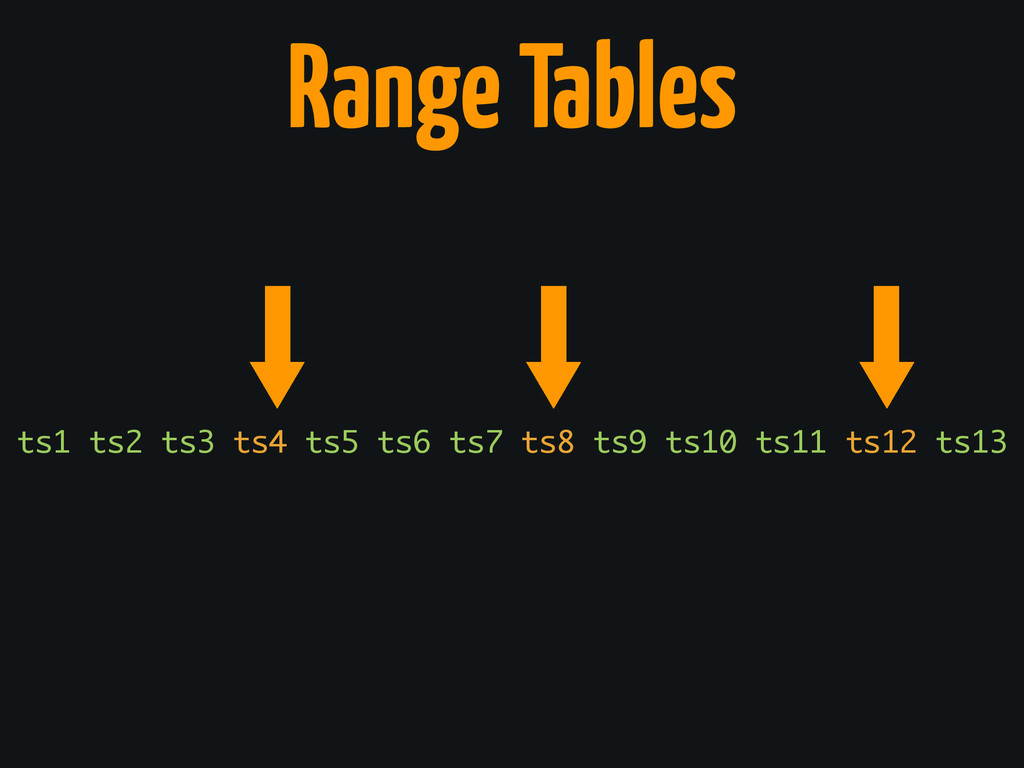
ts1 ts2 ts3 ts4 ts5 ts6 ts7 ts8 ts9 ts10
ts11 ts12 ts13 Range Tables
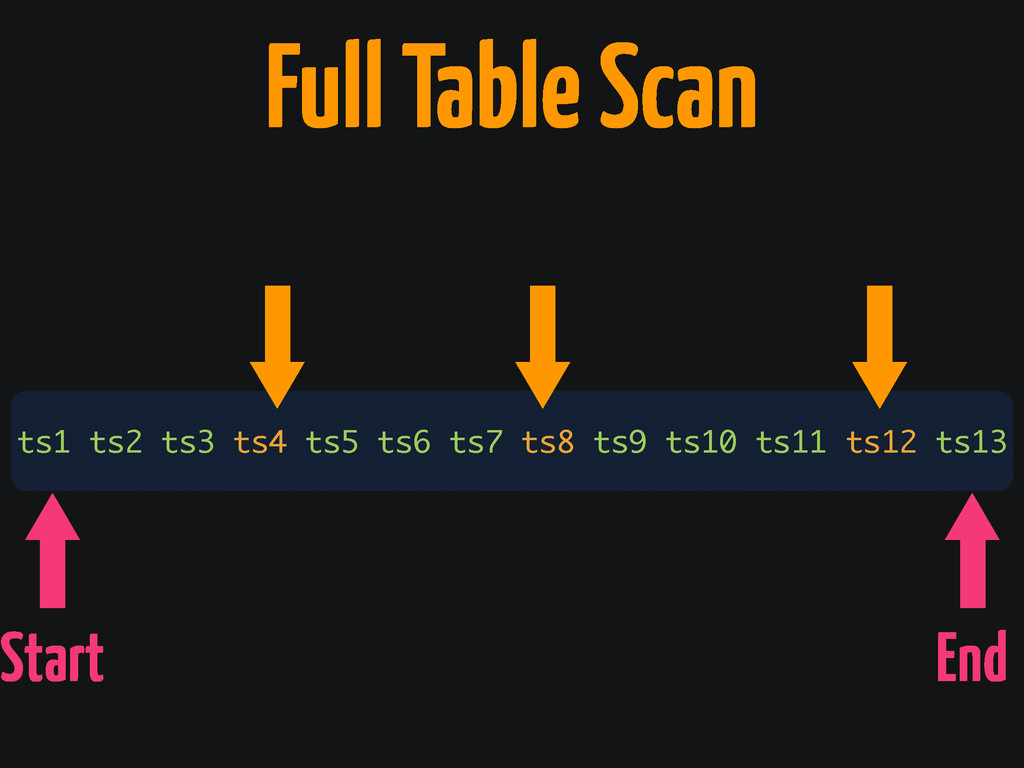
Full Table Scan ts1 ts2 ts3 ts4 ts5 ts6 ts7
ts8 ts9 ts10 ts11 ts12 ts13 Start End
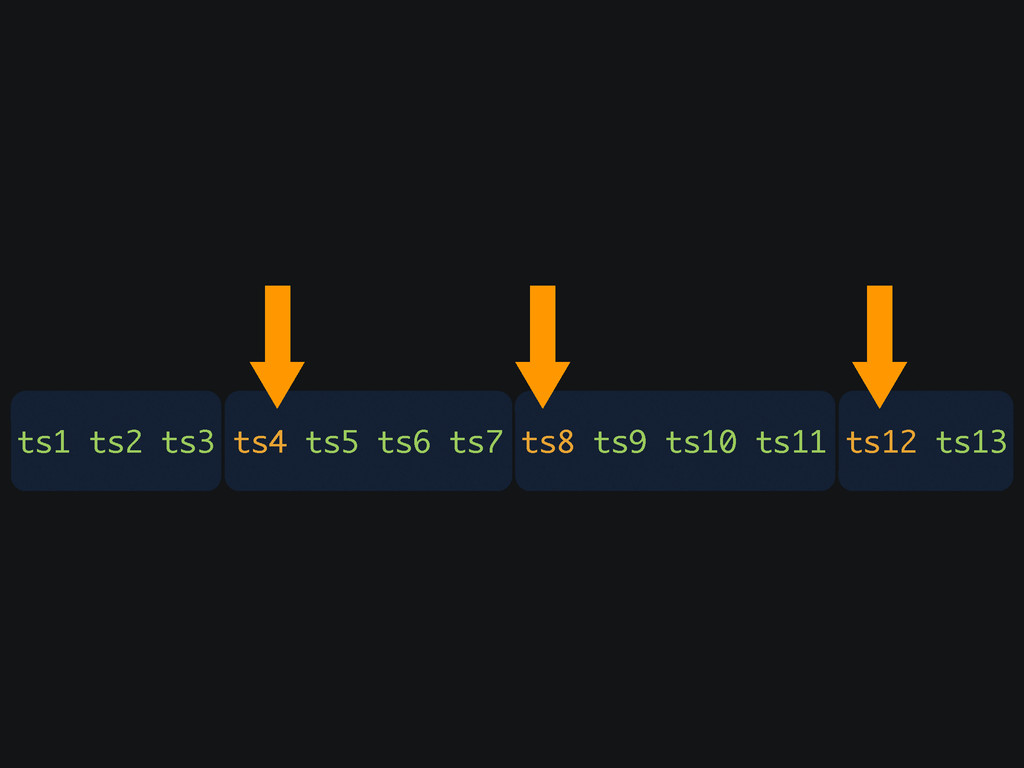
ts1 ts2 ts3 ts4 ts5 ts6 ts7 ts8 ts9 ts10
ts11 ts12 ts13
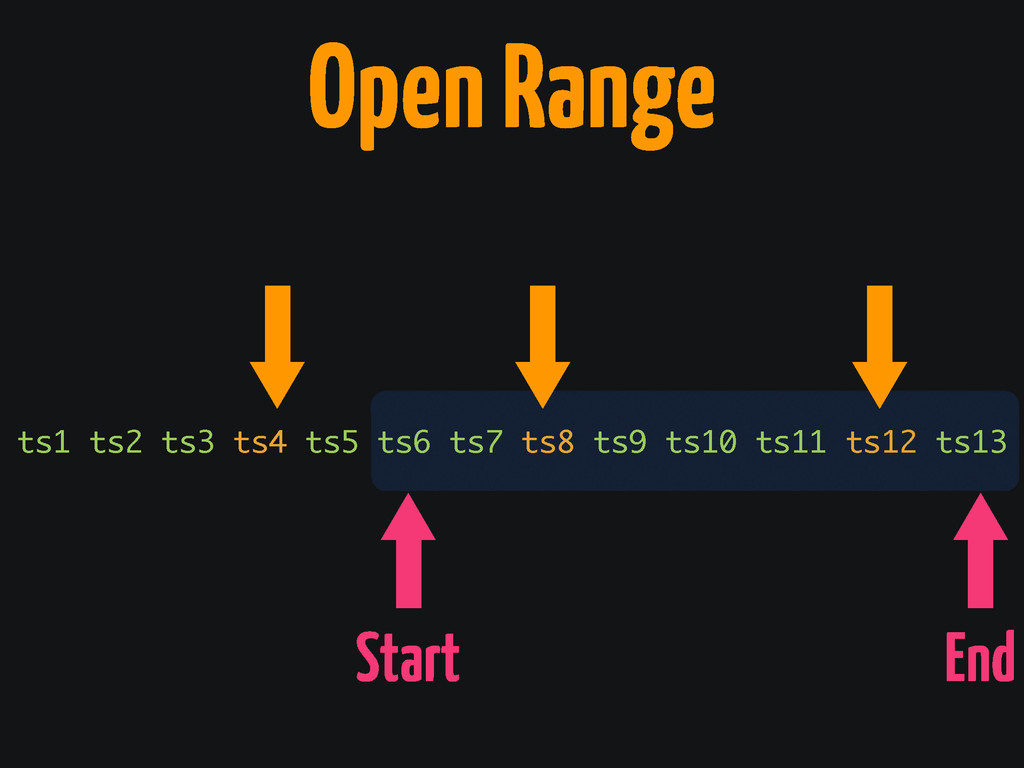
Open Range Start End ts1 ts2 ts3 ts4 ts5 ts6
ts7 ts8 ts9 ts10 ts11 ts12 ts13
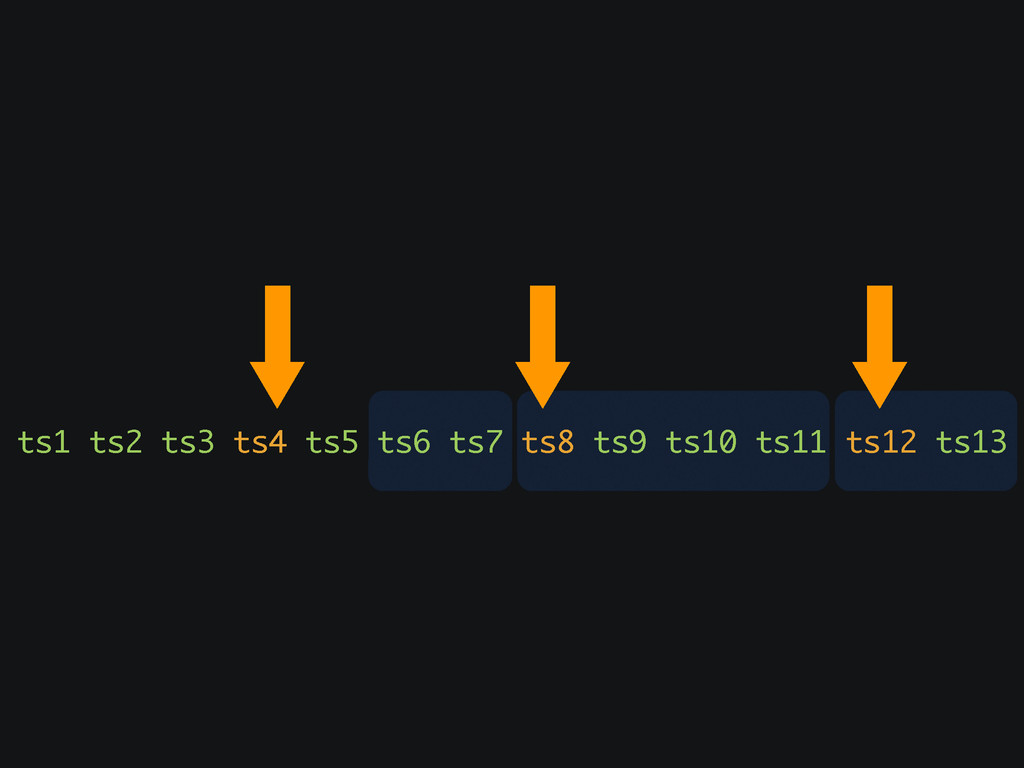
ts1 ts2 ts3 ts4 ts5 ts6 ts7 ts8 ts9 ts10
ts11 ts12 ts13
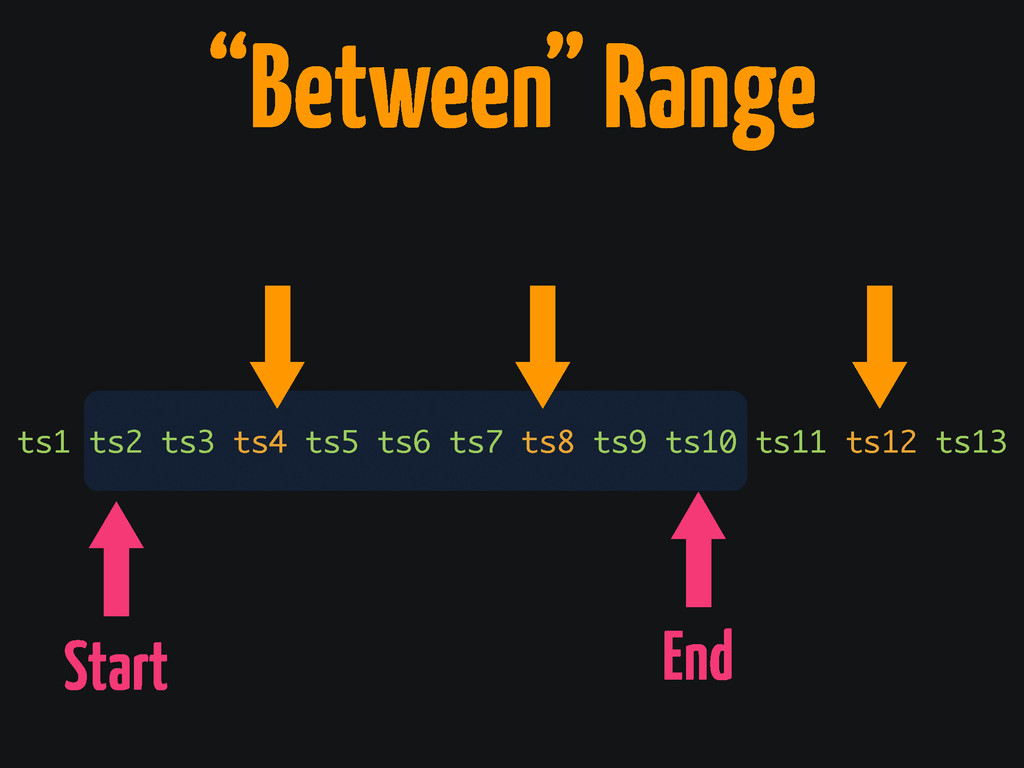
“Between” Range ts1 ts2 ts3 ts4 ts5 ts6 ts7 ts8
ts9 ts10 ts11 ts12 ts13 Start End
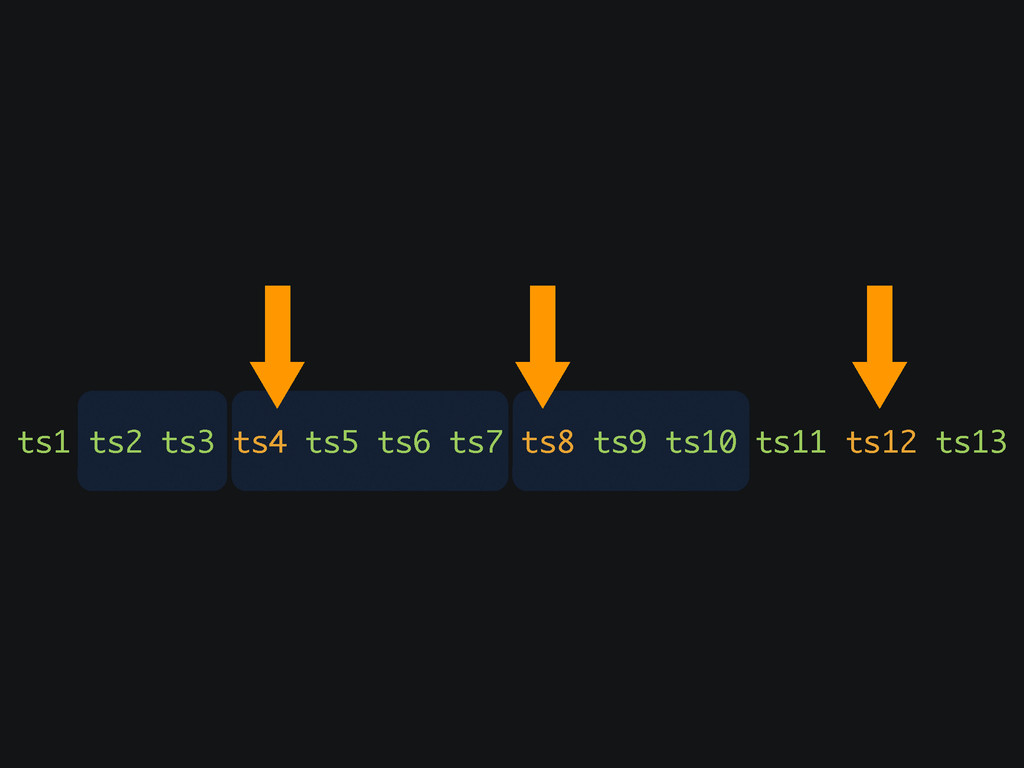
ts1 ts2 ts3 ts4 ts5 ts6 ts7 ts8 ts9 ts10
ts11 ts12 ts13
(rich query API) Step 2 add some algebra
None
Stream Fusion for rich ad-hoc queries
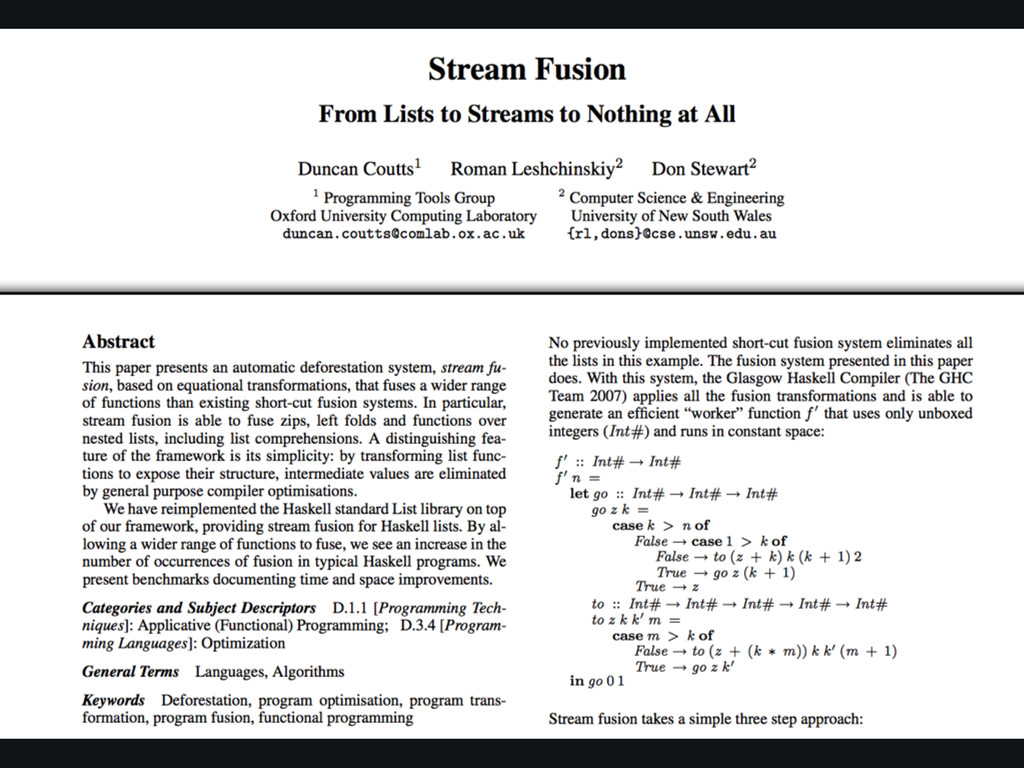
What is even Stream Fusion
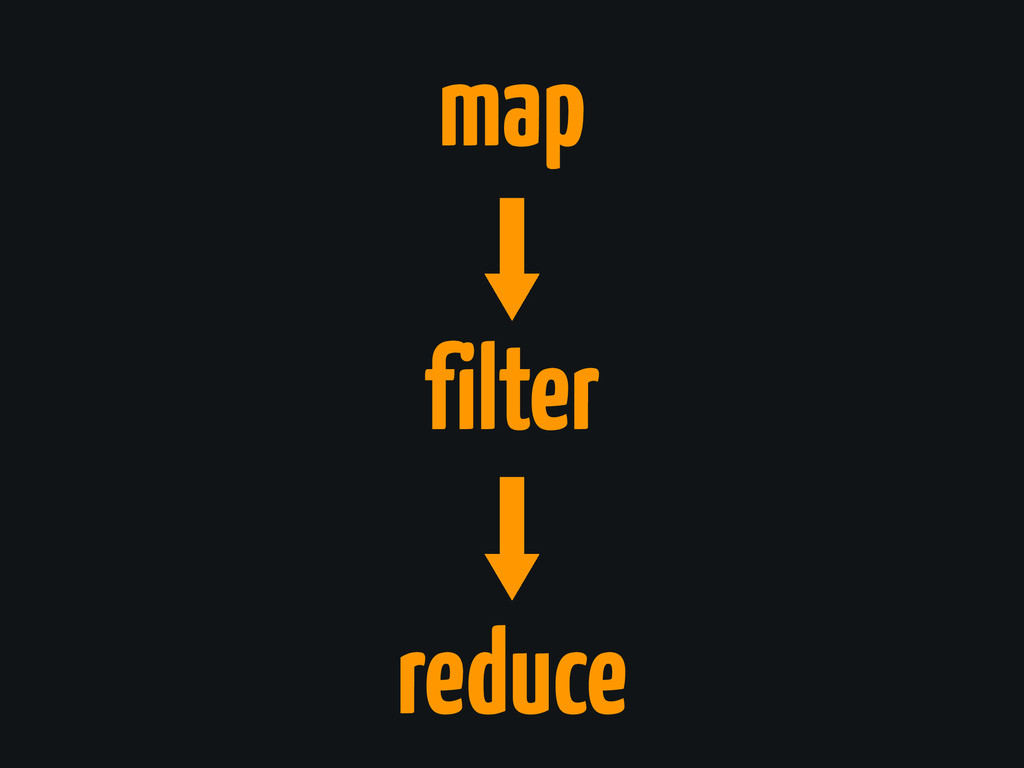
map filter reduce
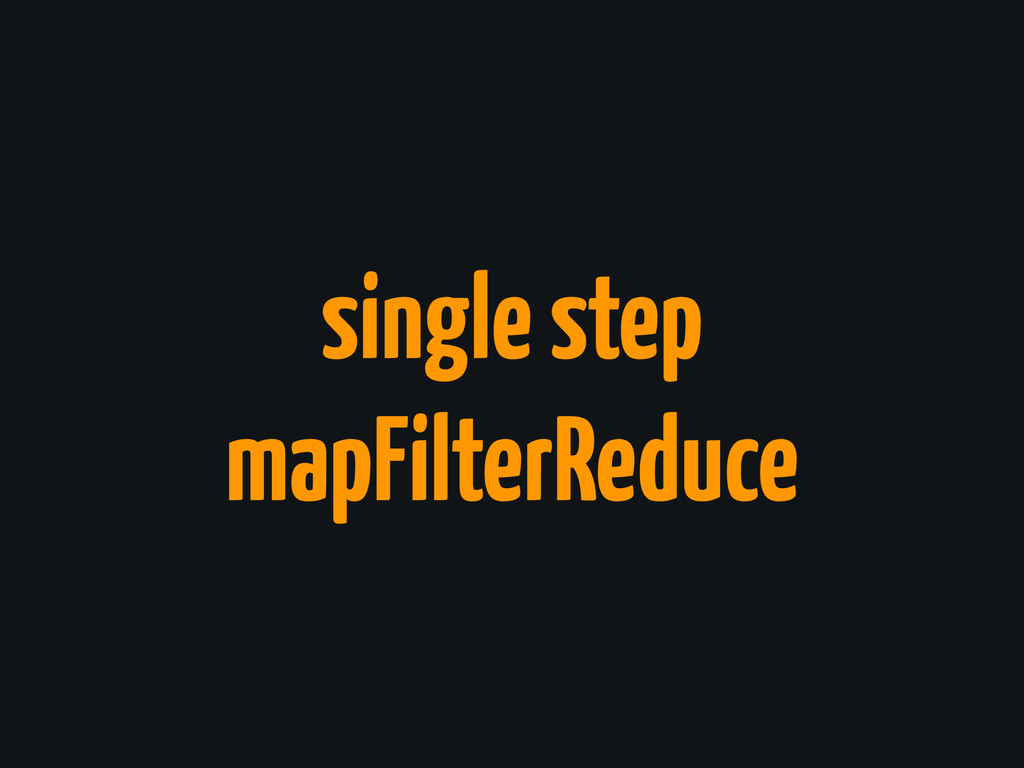
single step mapFilterReduce
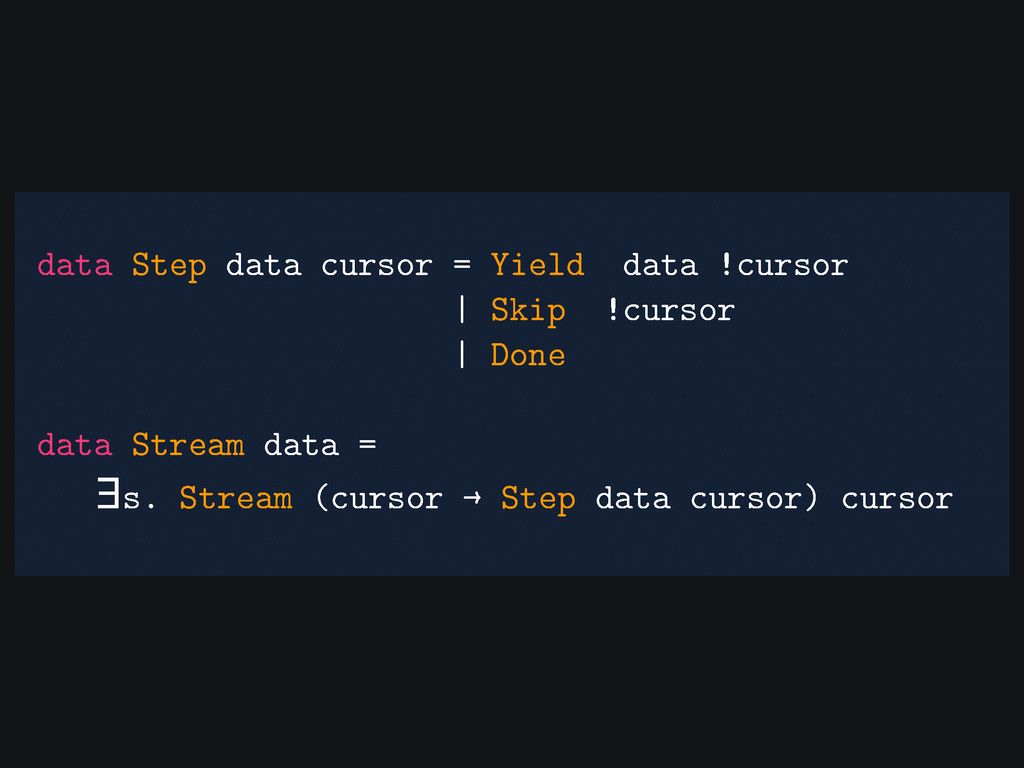
data Step data cursor = Yield data !cursor | Skip
!cursor | Done data Stream data = ∃s. Stream (cursor → Step data cursor) cursor
Stream Beginning: reading from the DB
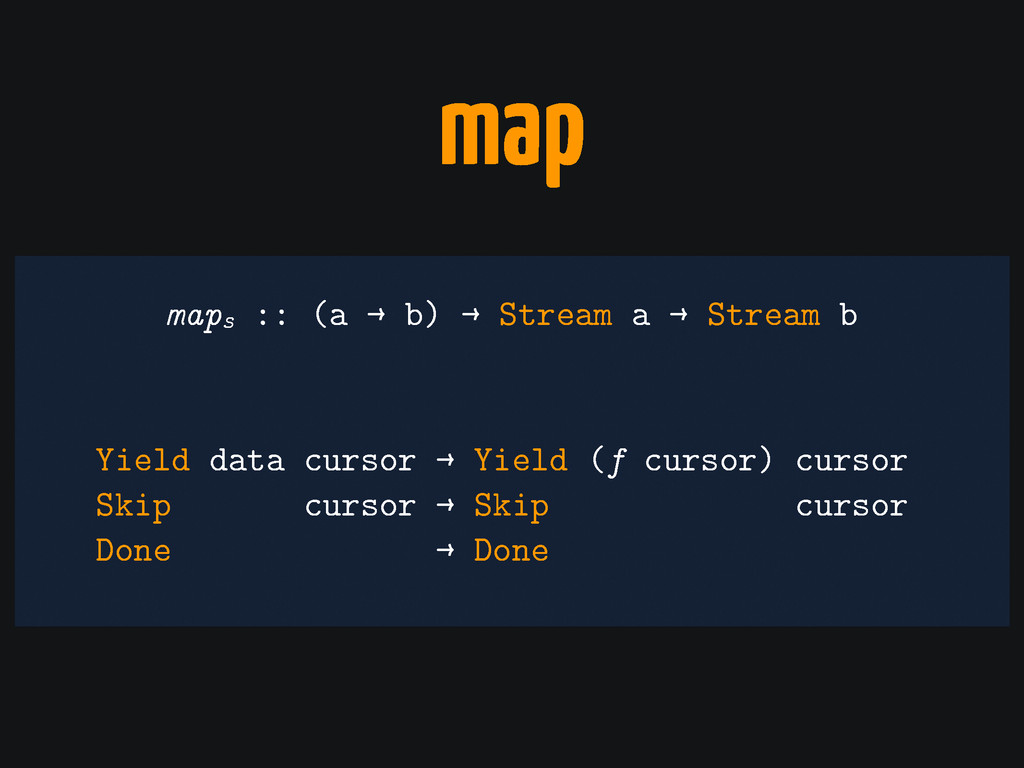
map Yield data cursor → Yield (f cursor) cursor Skip
cursor → Skip cursor Done → Done maps :: (a → b) → Stream a → Stream b
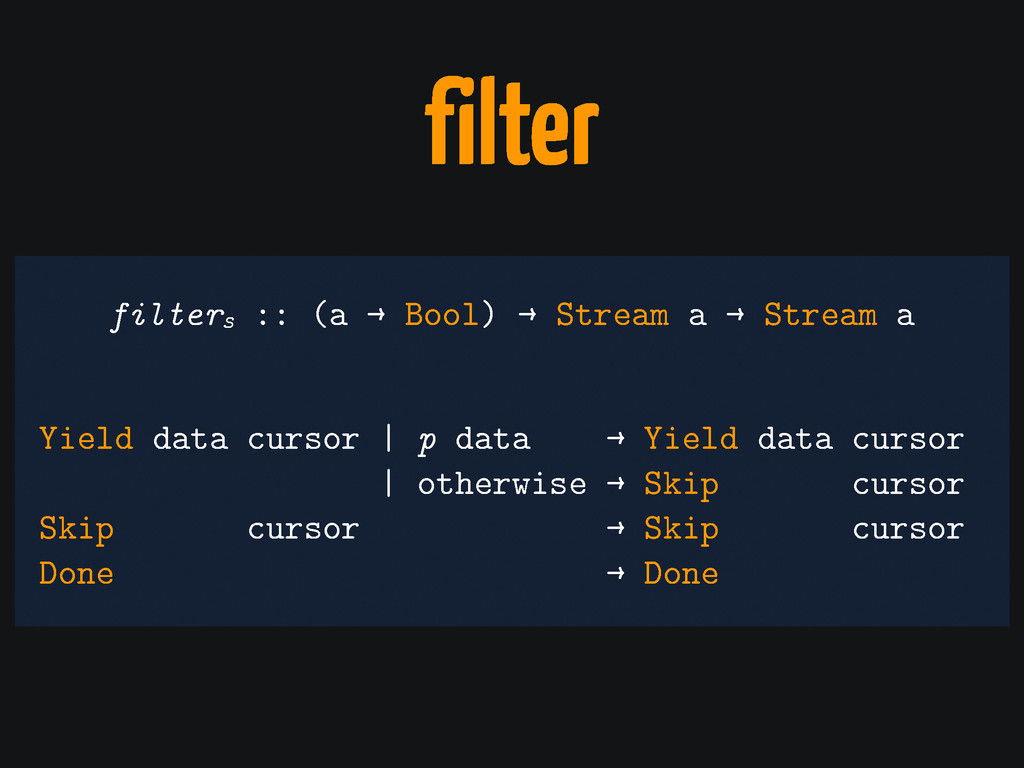
filter Yield data cursor | p data → Yield data
cursor | otherwise → Skip cursor Skip cursor → Skip cursor Done → Done filters :: (a → Bool) → Stream a → Stream a
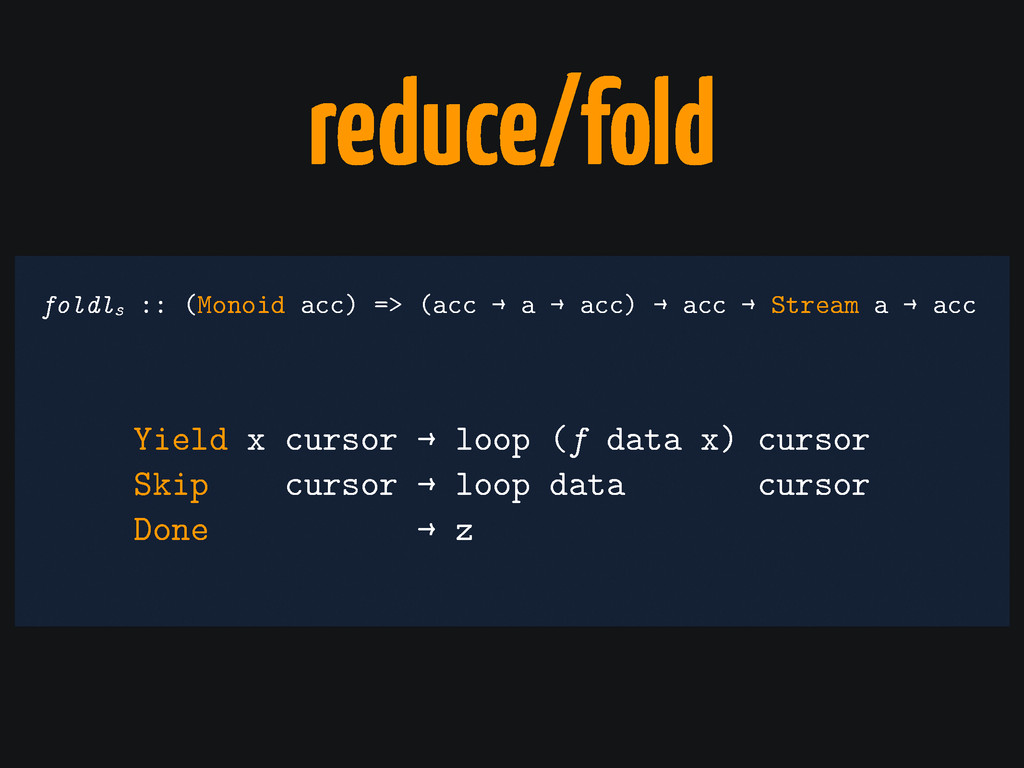
reduce/fold Yield x cursor → loop (f data x) cursor
Skip cursor → loop data cursor Done → z foldls :: (Monoid acc) => (acc → a → acc) → acc → Stream a → acc
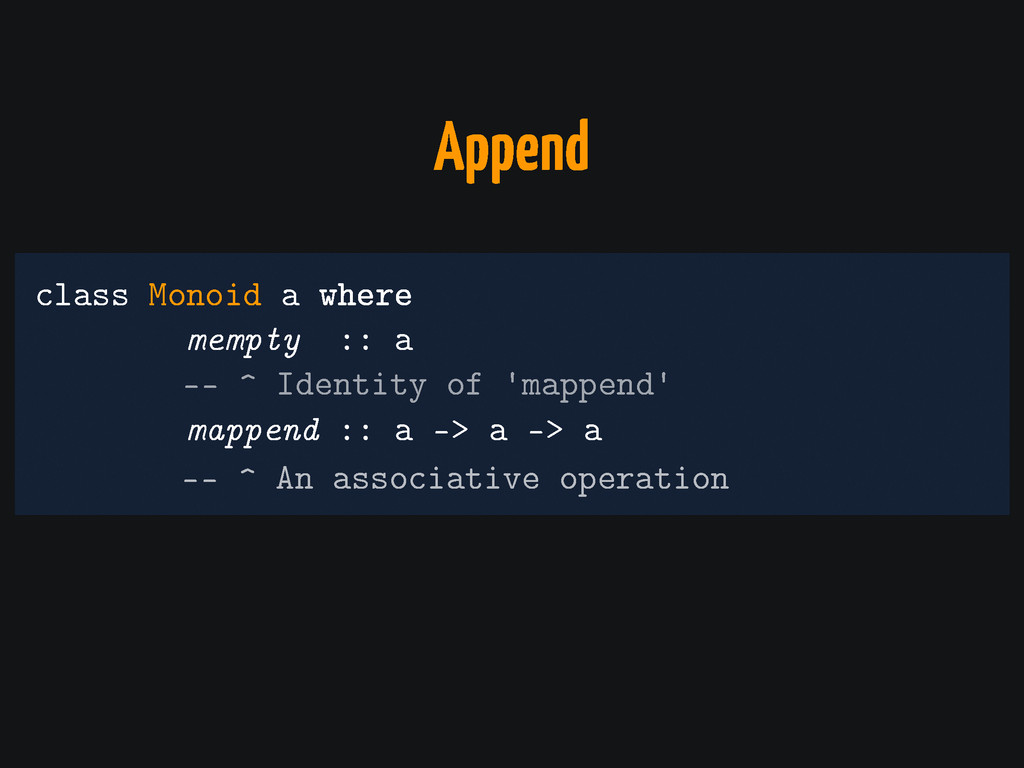
Append class Monoid a where mempty :: a mappend ::
a -> a -> a -- ^ Identity of 'mappend' -- ^ An associative operation
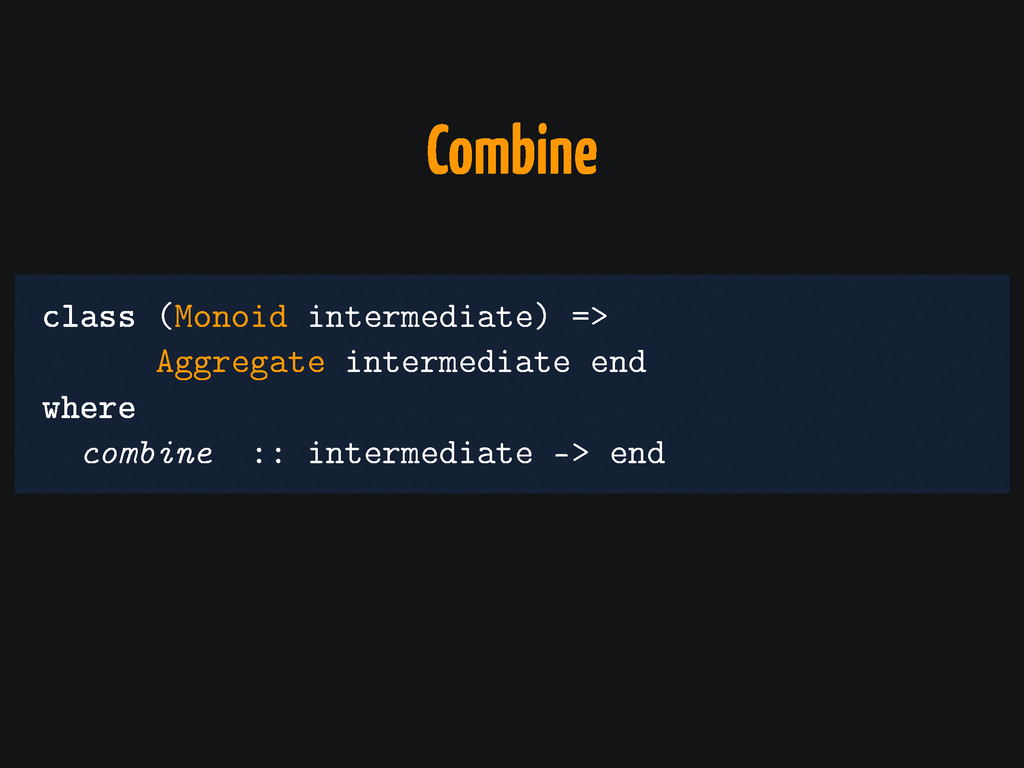
class (Monoid intermediate) => Aggregate intermediate end where combine ::
intermediate -> end Combine
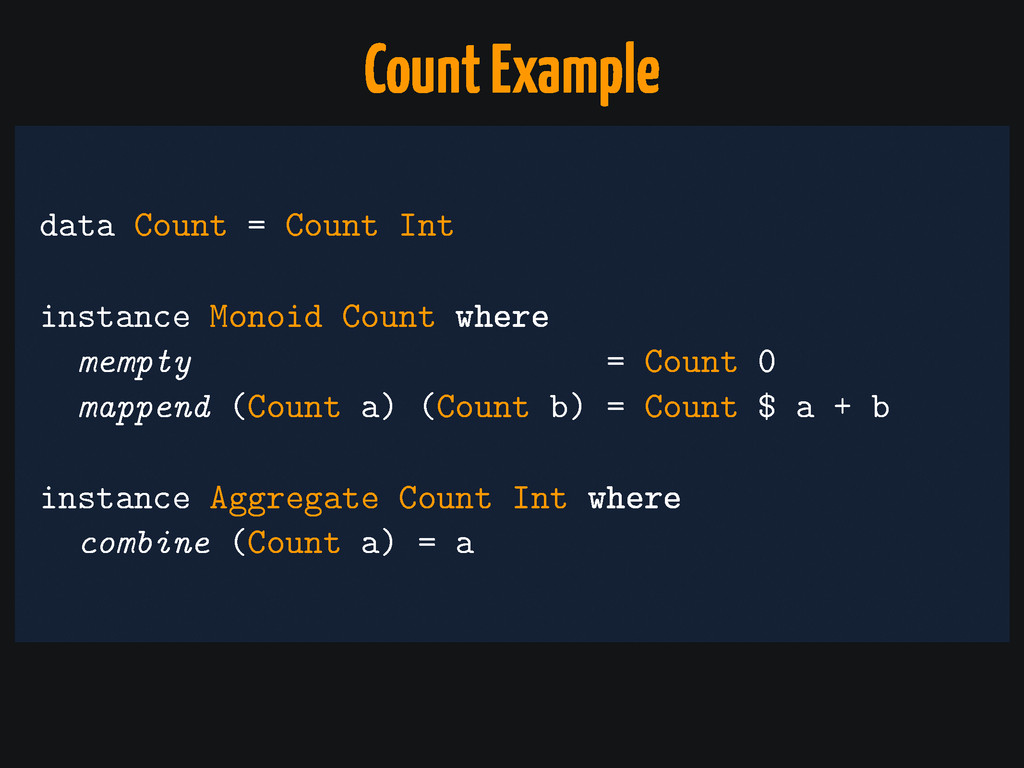
data Count = Count Int instance Monoid Count where mempty
= Count 0 mappend (Count a) (Count b) = Count $ a + b instance Aggregate Count Int where combine (Count a) = a Count Example
add some ML Step 3
Storing Models
Support Vector Machines
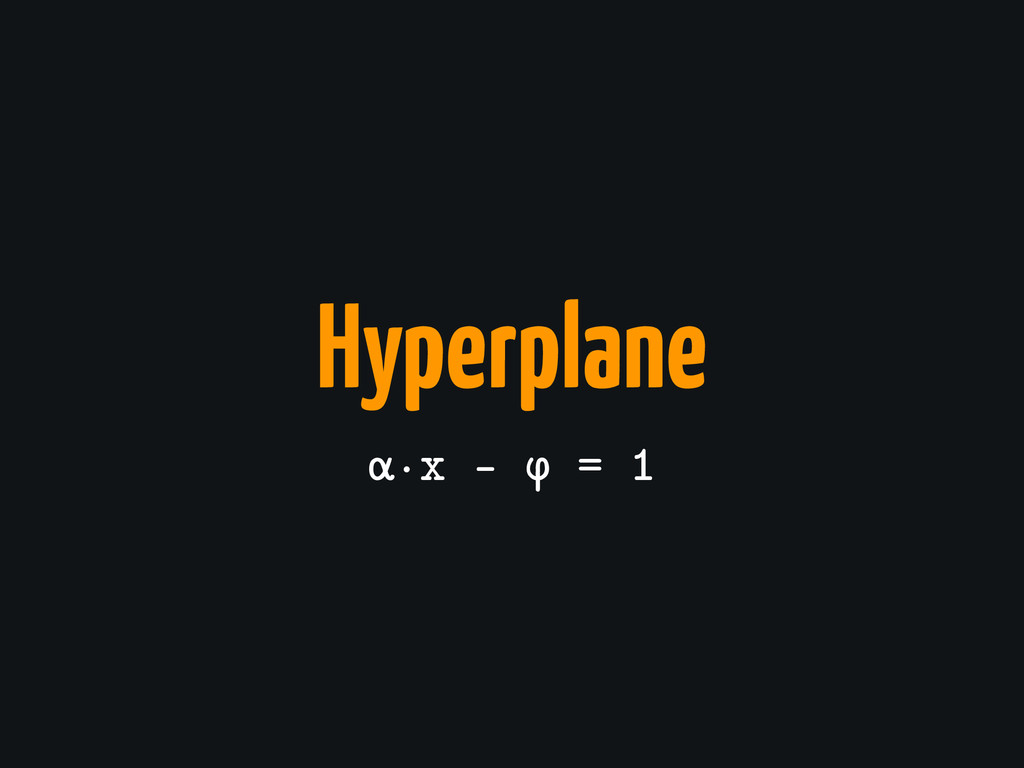
Hyperplane α·x - φ = 1
[ α1 α1 α1 ...αn ] ρ
Option 1: list<double>
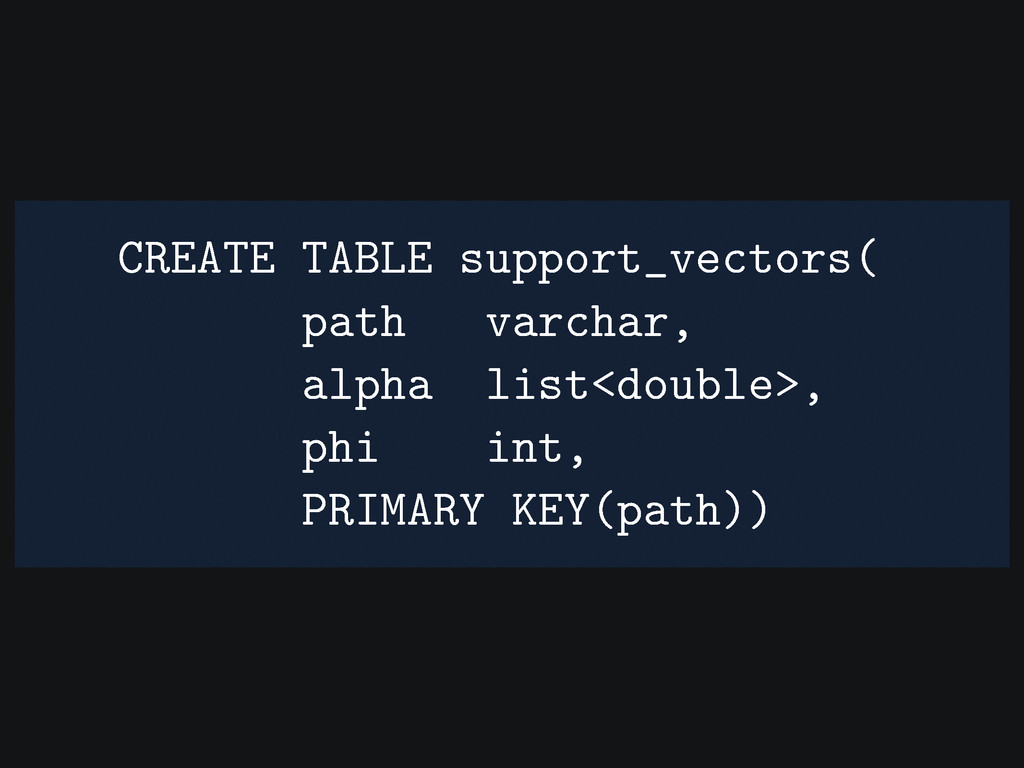
CREATE TABLE support_vectors( path varchar, alpha list<double>, phi int, PRIMARY
KEY(path))
Problems High deserialisation overhead Need to add PK specifiers for
multiple SVs
Alternative: blob & byte buffers
Vector Representation
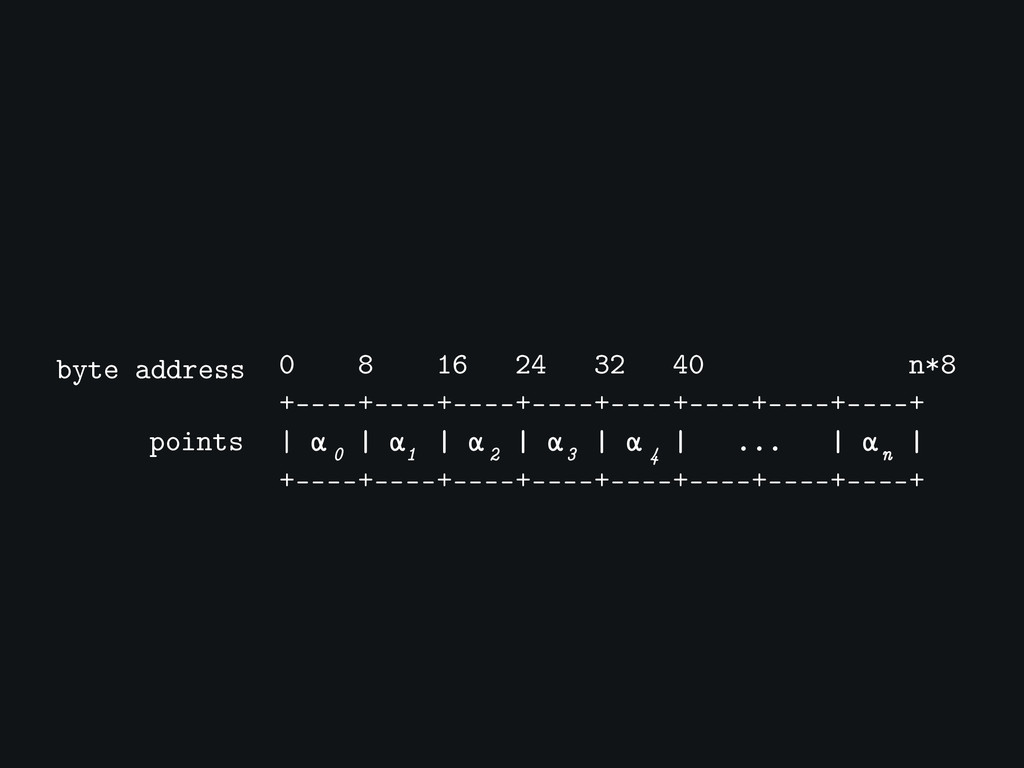
0 8 16 24 32 40 n*8 +----+----+----+----+----+----+----+----+ | α
| α | α | α | α | ... | α | +----+----+----+----+----+----+----+----+ byte address points 1 2 3 4 0 n
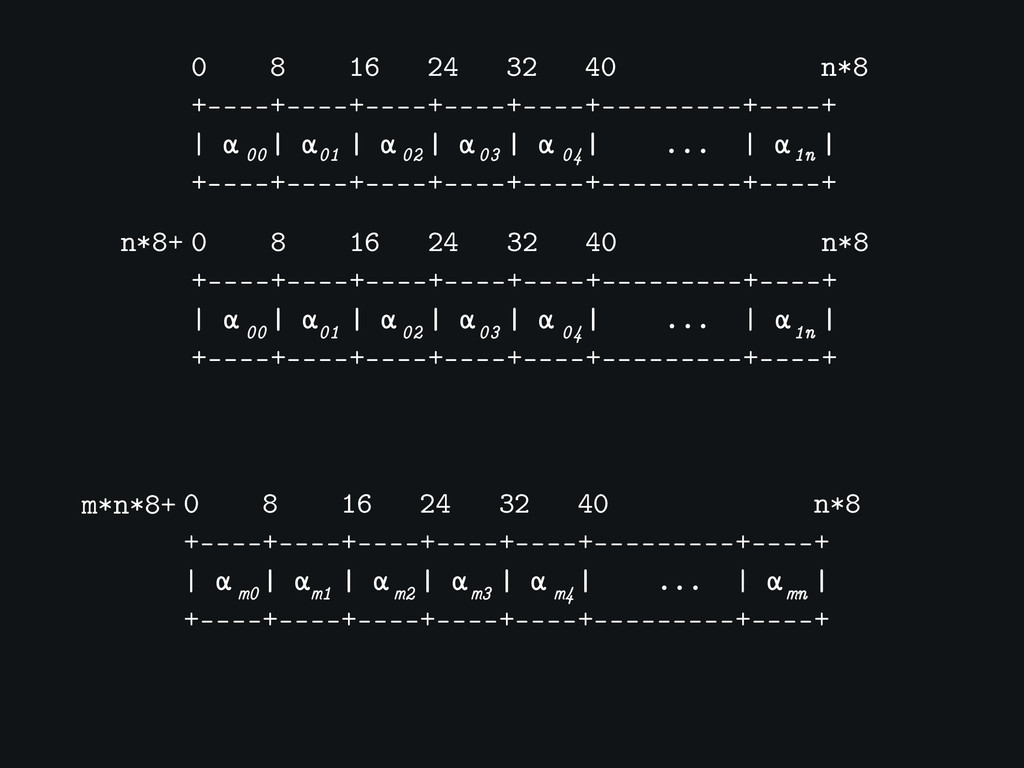
Matrix Representation
0 8 16 24 32 40 n*8 +----+----+----+----+----+---------+----+ | α
| α | α | α | α | ... | α | +----+----+----+----+----+---------+----+ 01 02 03 04 00 1n n*8+ 0 8 16 24 32 40 n*8 +----+----+----+----+----+---------+----+ | α | α | α | α | α | ... | α | +----+----+----+----+----+---------+----+ 01 02 03 04 00 1n m*n*8+ 0 8 16 24 32 40 n*8 +----+----+----+----+----+---------+----+ | α | α | α | α | α | ... | α | +----+----+----+----+----+---------+----+ m1 m2 m3 m4 m0 mn
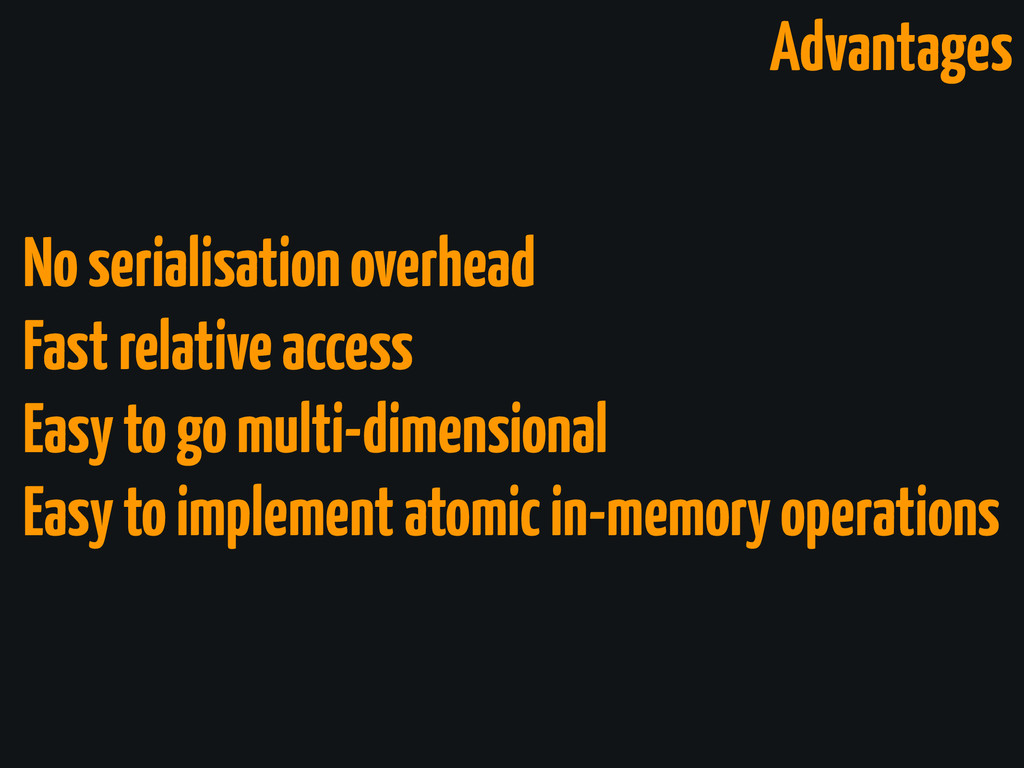
Advantages No serialisation overhead Fast relative access Easy to go
multi-dimensional Easy to implement atomic in-memory operations
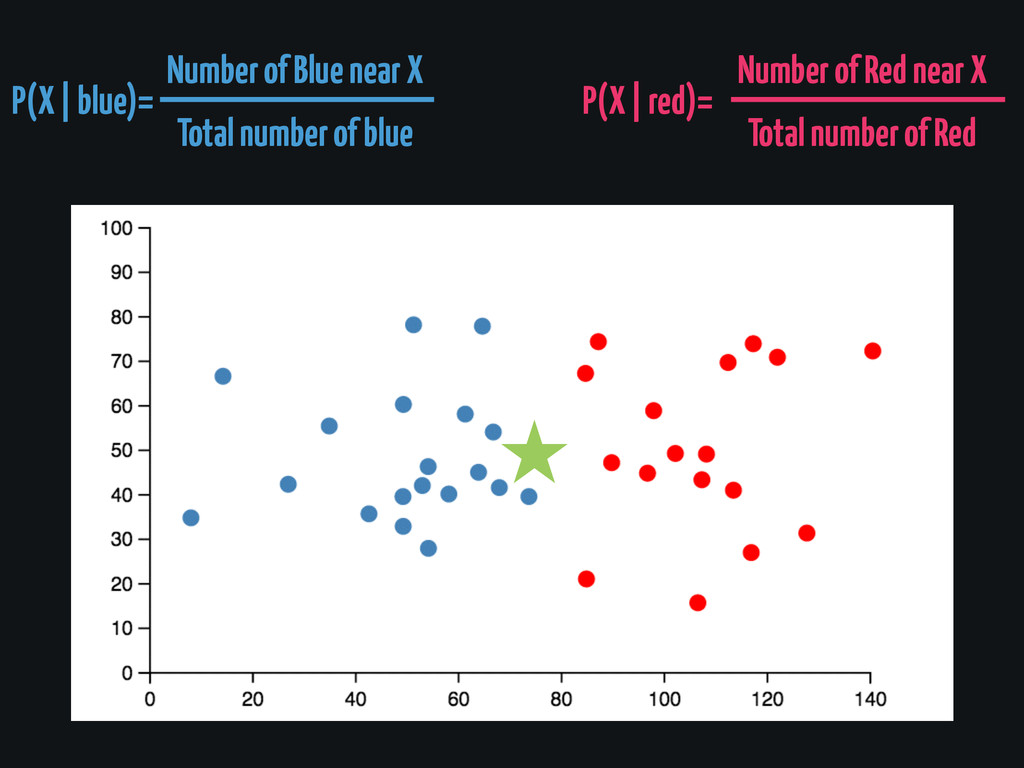
Bayesian Classifiers
P(X | blue)= Number of Blue near X Total number
of blue P(X | red)= Number of Red near X Total number of Red
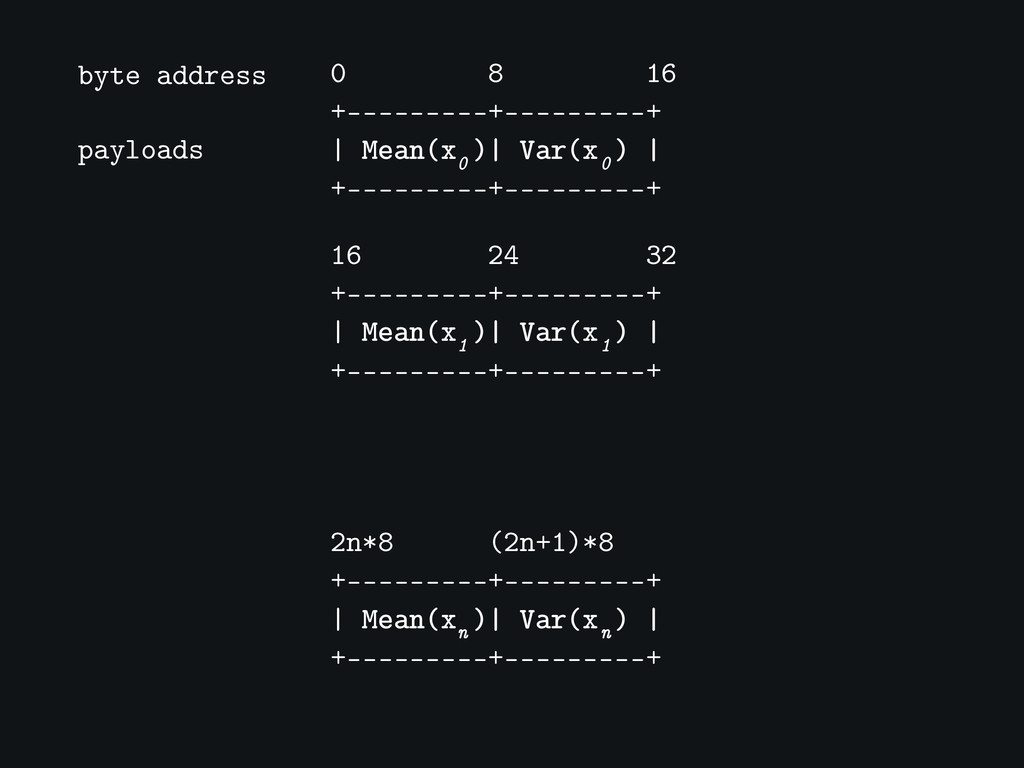
[[Mean(x1), Var(x1)] [Mean(x2), Var(x3)] ... [Mean(xn), Var(xn)]]
0 8 16 +---------+---------+ | Mean(x )| Var(x ) |
+---------+---------+ 0 0 16 24 32 +---------+---------+ | Mean(x )| Var(x ) | +---------+---------+ 1 1 2n*8 (2n+1)*8 +---------+---------+ | Mean(x )| Var(x ) | +---------+---------+ n n byte address payloads
make it rocket-fast Step 4
Approximate Data Structures
Bloom Filters are basically long arrays / vectors
BitSet
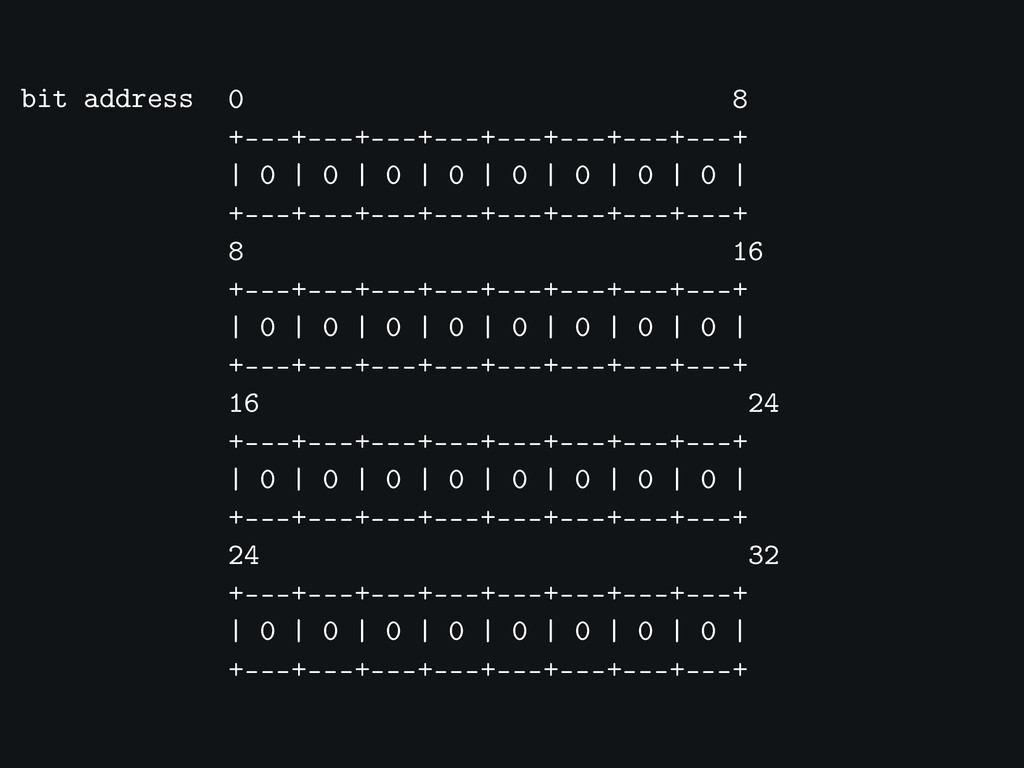
0 8 +---+---+---+---+---+---+---+---+ | 0 | 0 | 0 |
0 | 0 | 0 | 0 | 0 | +---+---+---+---+---+---+---+---+ 8 16 +---+---+---+---+---+---+---+---+ | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | +---+---+---+---+---+---+---+---+ 16 24 +---+---+---+---+---+---+---+---+ | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | +---+---+---+---+---+---+---+---+ 24 32 +---+---+---+---+---+---+---+---+ | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | +---+---+---+---+---+---+---+---+ bit address
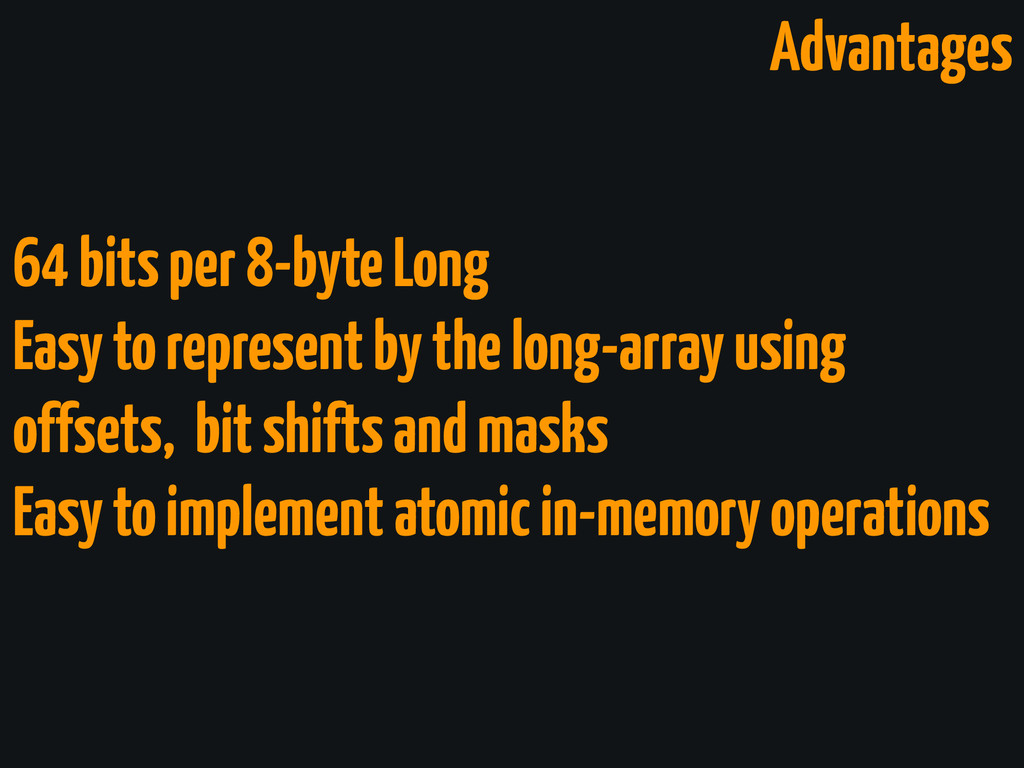
Advantages 64 bits per 8-byte Long Easy to represent by
the long-array using offsets, bit shifts and masks Easy to implement atomic in-memory operations
Count-min sketches are basically int matrices
Histograms are basically long vectors
Conclusions Ad-hoc queries Parallelism Lightweight DSs representation Optimisations and good
API fits
@ifesdjeen

 Your Podcast. Everywhere. Effortlessly.


 ifesdjeen
 yumulab
 institutdelelevage
 yukako_nakano
 takasehideki
 microbaseinc
 kogoro
 mikimhk
 sishi
 rikkabotan7
 hisaokatsumi
 codingconduct
 lauravandoore
 erikaheidi
 orderedlist
 tmiket
 lcolladotor
 mayunak
 mraible
 notwaldorf
 csswizardry
 garrettdimon
 lemiorhan