Share
Embed
ディープラーニングで芸術はできるか? 〜生成系ネットワークの進展〜
masa-ita
January 11, 2020
Transcript
36 slides
-
⾃⼰紹介 板垣 正敏 1955年村上市⽣まれ 県内IT企業の技術顧問 (2020/3まで)
中⼩企業診断⼠ ⽇本Rubyの会 新潟オープンソース協会 Python機械学習勉強会 in 新潟 TensorFlow Users Group JAWS-UG Niigata @itagakim https://github.com/masa-ita -
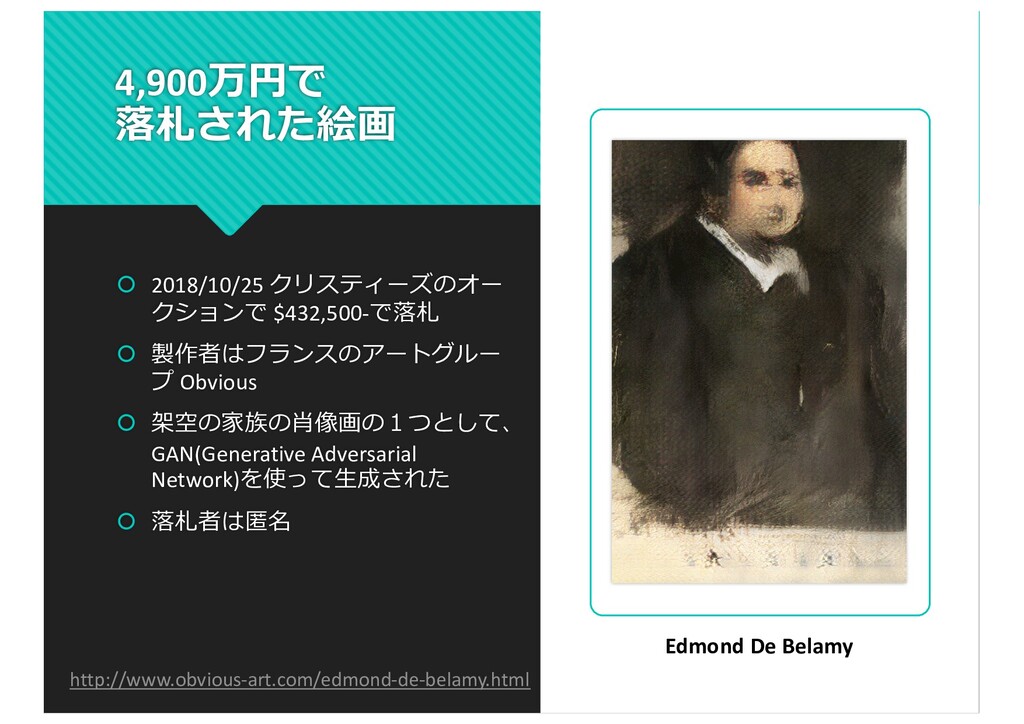
4,900万円で 落札された絵画 2018/10/25 クリスティーズのオー クションで $432,500-で落札 製作者はフランスのアートグルー プ
Obvious 架空の家族の肖像画の1つとして、 GAN(Generative Adversarial Network)を使って⽣成された 落札者は匿名 http://www.obvious-art.com/edmond-de-belamy.html Edmond De Belamy -
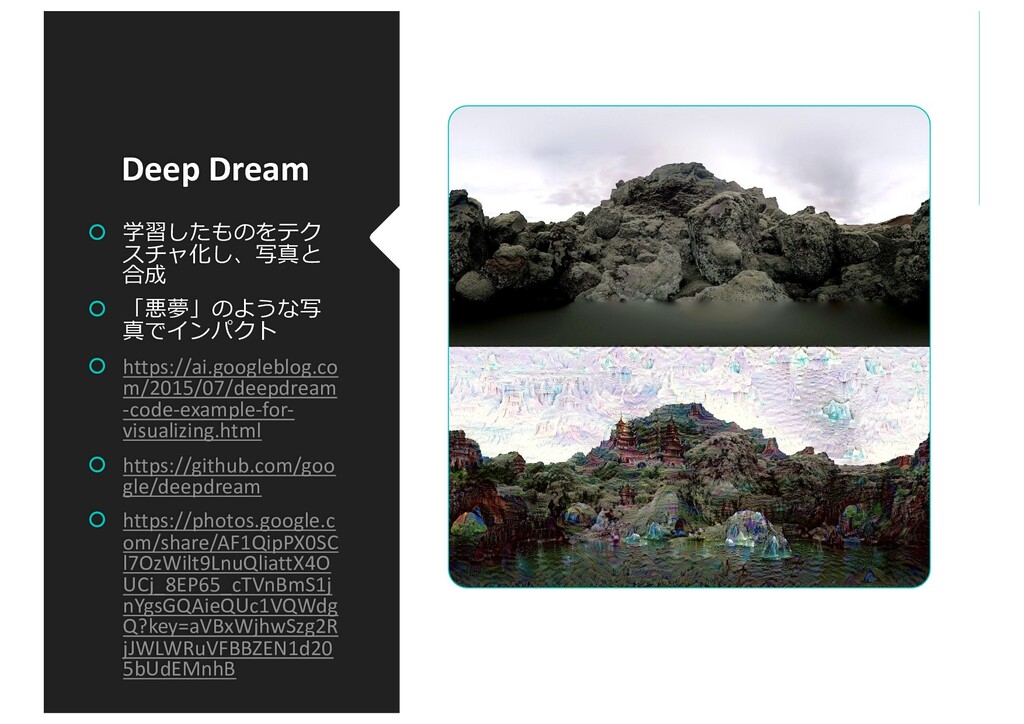
Deep Dream 学習したものをテク スチャ化し、写真と 合成 「悪夢」のような写 真でインパクト
https://ai.googleblog.co m/2015/07/deepdream -code-example-for- visualizing.html https://github.com/goo gle/deepdream https://photos.google.c om/share/AF1QipPX0SC l7OzWilt9LnuQliattX4O UCj_8EP65_cTVnBmS1j nYgsGQAieQUc1VQWdg Q?key=aVBxWjhwSzg2R jJWLWRuVFBBZEN1d20 5bUdEMnhB -
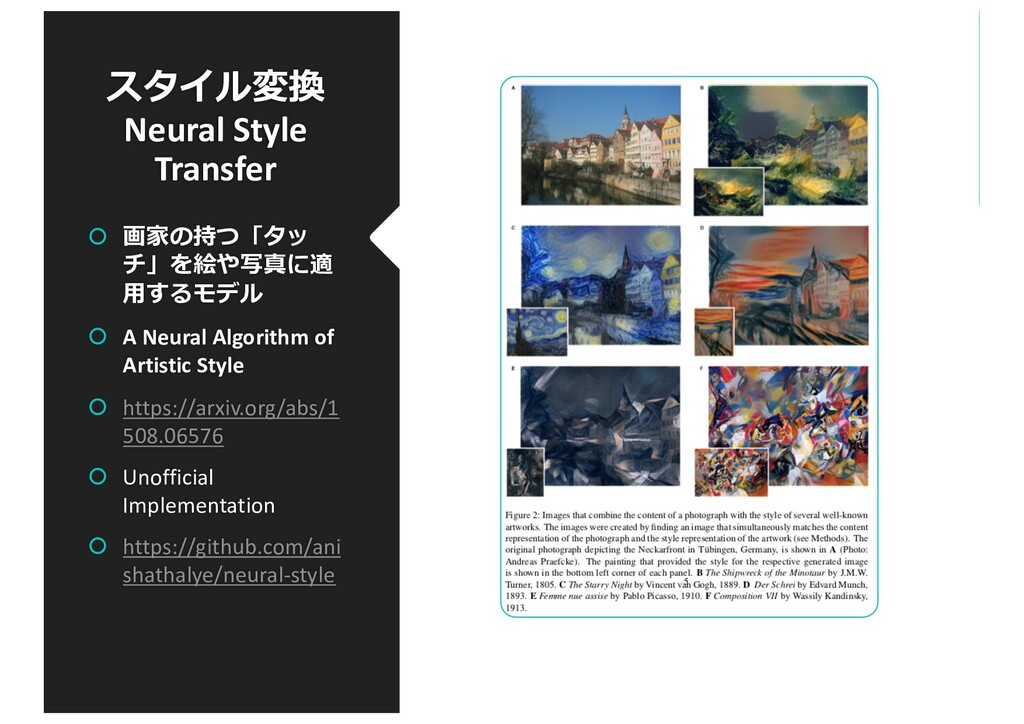
スタイル変換 Neural Style Transfer 画家の持つ「タッ チ」を絵や写真に適 ⽤するモデル A
Neural Algorithm of Artistic Style https://arxiv.org/abs/1 508.06576 Unofficial Implementation https://github.com/ani shathalye/neural-style -
VAE: Variational AutoEncoder Auto-Encoding Variational Bayes https://arxiv.org/abs/1312.6114
Stochastic Backpropagation and Approximate Inference in Deep Generative Models https://arxiv.org/abs/1401.4082 特徴量の抽出を⾏うAutoencoder の隠れベクトルをガウス空間内 のサンプルと仮定し、Encoderに はそのパラメータを出⼒させる 学習されたガウス空間からのサ ンプルをDecoderに⼊⼒すること で、新たな画像を⽣成できる https://qiita.com/shionhonda/items/e2cf9fe93ae1034dd771 -
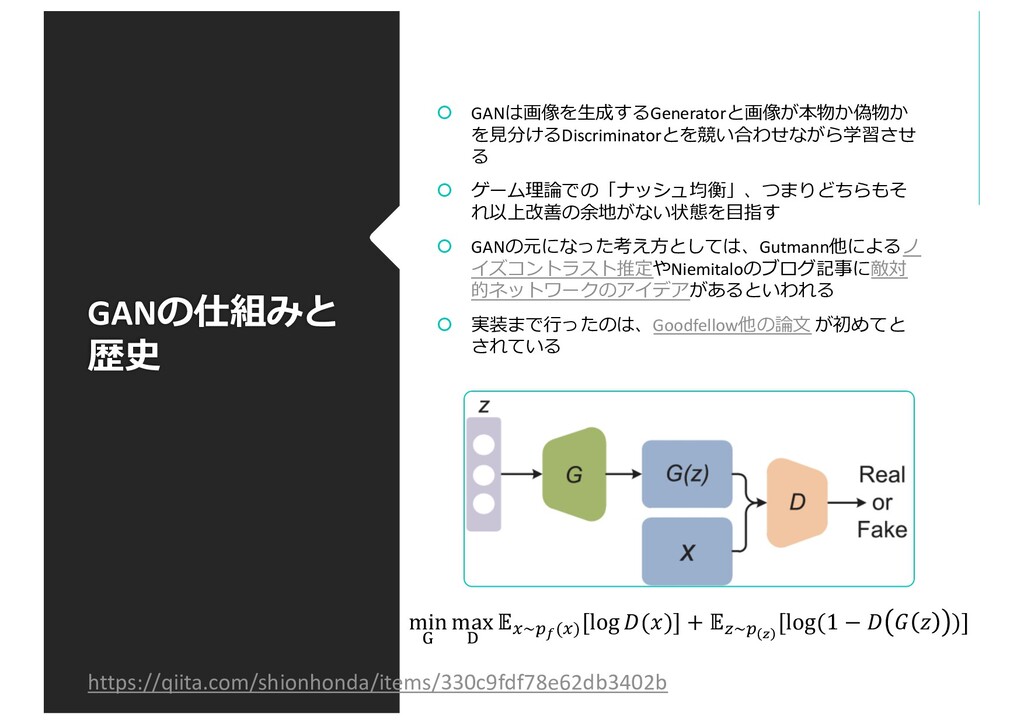
GANの仕組みと 歴史 GANは画像を⽣成するGeneratorと画像が本物か偽物か を⾒分けるDiscriminatorとを競い合わせながら学習させ る ゲーム理論での「ナッシュ均衡」、つまりどちらもそ れ以上改善の余地がない状態を⽬指す
GANの元になった考え⽅としては、Gutmann他によるノ イズコントラスト推定やNiemitaloのブログ記事に敵対 的ネットワークのアイデアがあるといわれる 実装まで⾏ったのは、Goodfellow他の論⽂ が初めてと されている https://qiita.com/shionhonda/items/330c9fdf78e62db3402b min $ max ' )~+,()) [log ()] + 7~+ 8 [log(1 − )] -
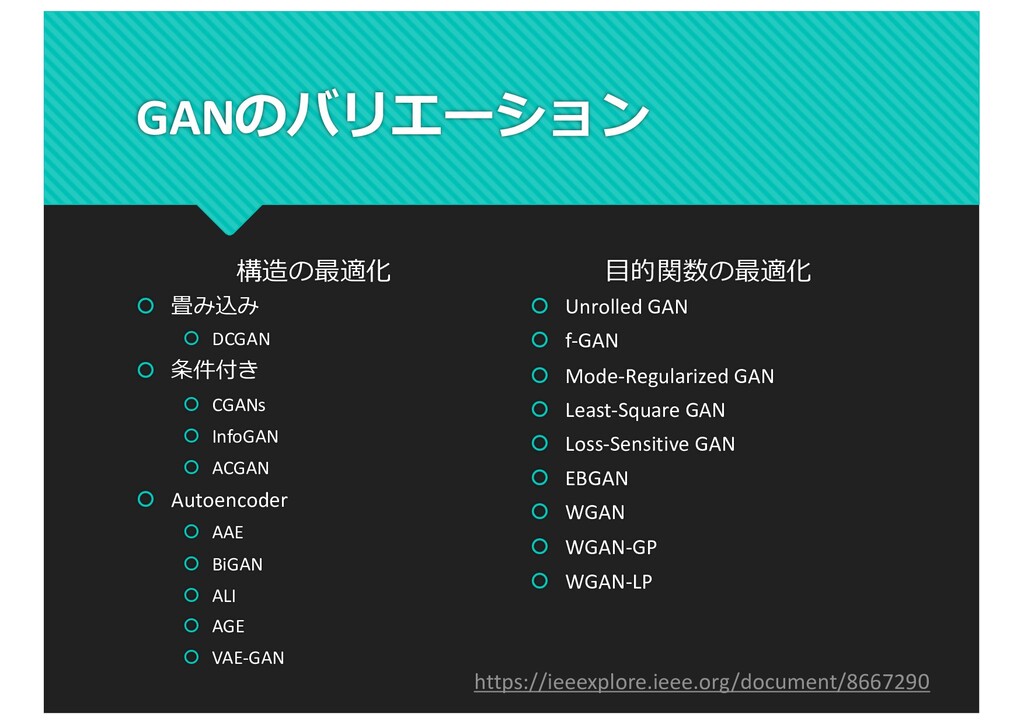
GANのバリエーション 構造の最適化 畳み込み DCGAN 条件付き CGANs
InfoGAN ACGAN Autoencoder AAE BiGAN ALI AGE VAE-GAN ⽬的関数の最適化 Unrolled GAN f-GAN Mode-Regularized GAN Least-Square GAN Loss-Sensitive GAN EBGAN WGAN WGAN-GP WGAN-LP https://ieeexplore.ieee.org/document/8667290 -
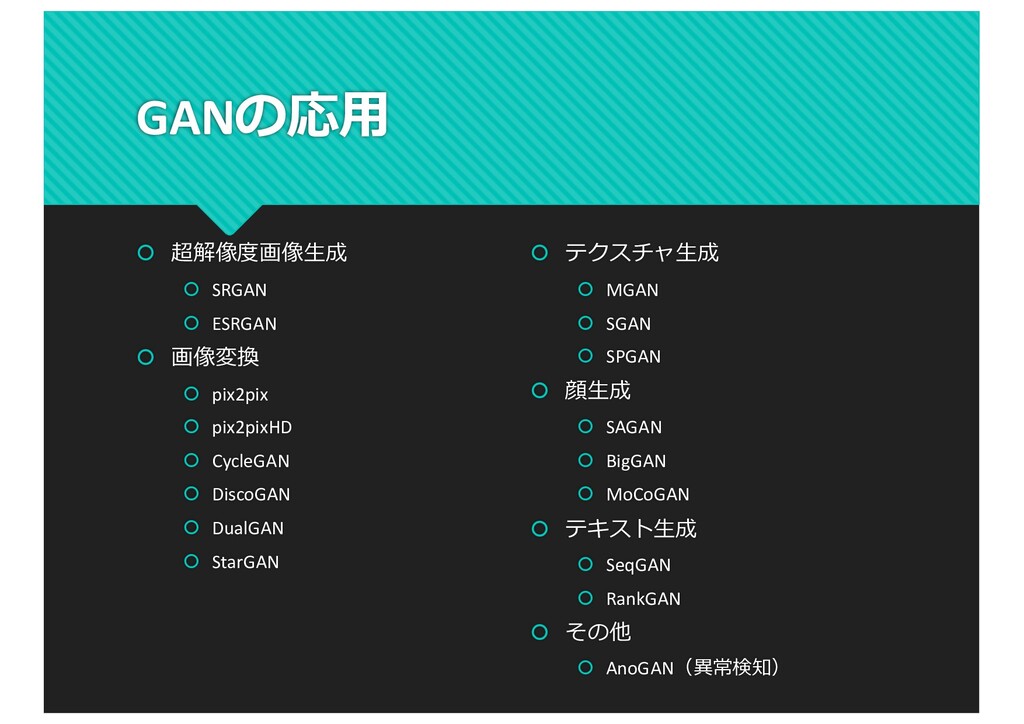
GANの応⽤ 超解像度画像⽣成 SRGAN ESRGAN 画像変換
pix2pix pix2pixHD CycleGAN DiscoGAN DualGAN StarGAN テクスチャ⽣成 MGAN SGAN SPGAN 顔⽣成 SAGAN BigGAN MoCoGAN テキスト⽣成 SeqGAN RankGAN その他 AnoGAN(異常検知) -
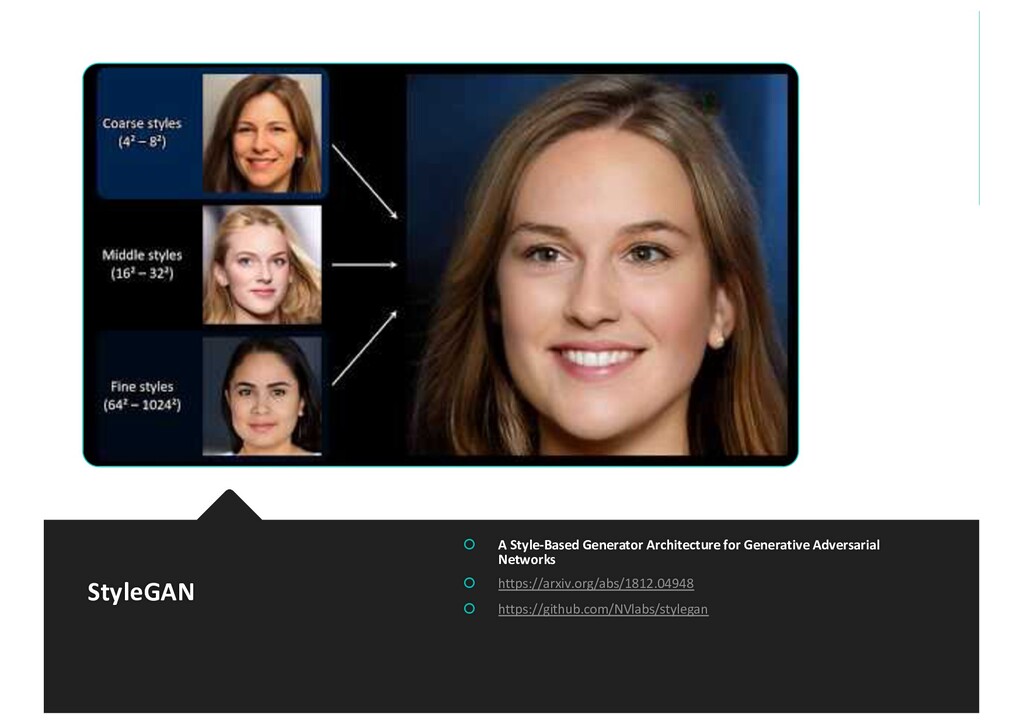
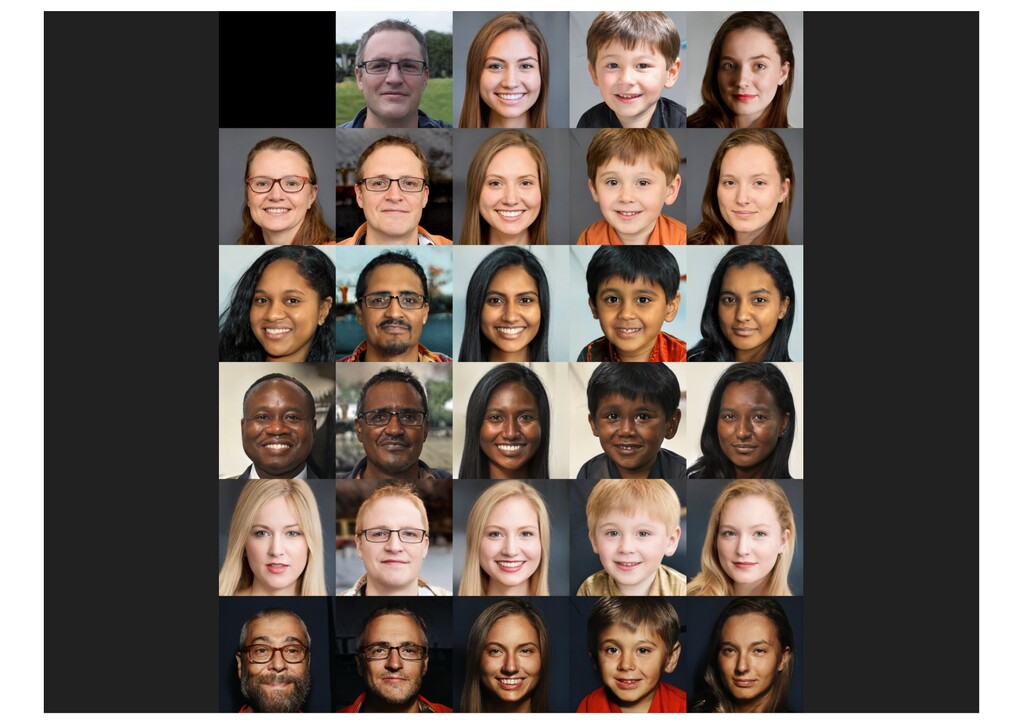
StyleGAN A Style-Based Generator Architecture for Generative Adversarial Networks
https://arxiv.org/abs/1812.04948 https://github.com/NVlabs/stylegan -
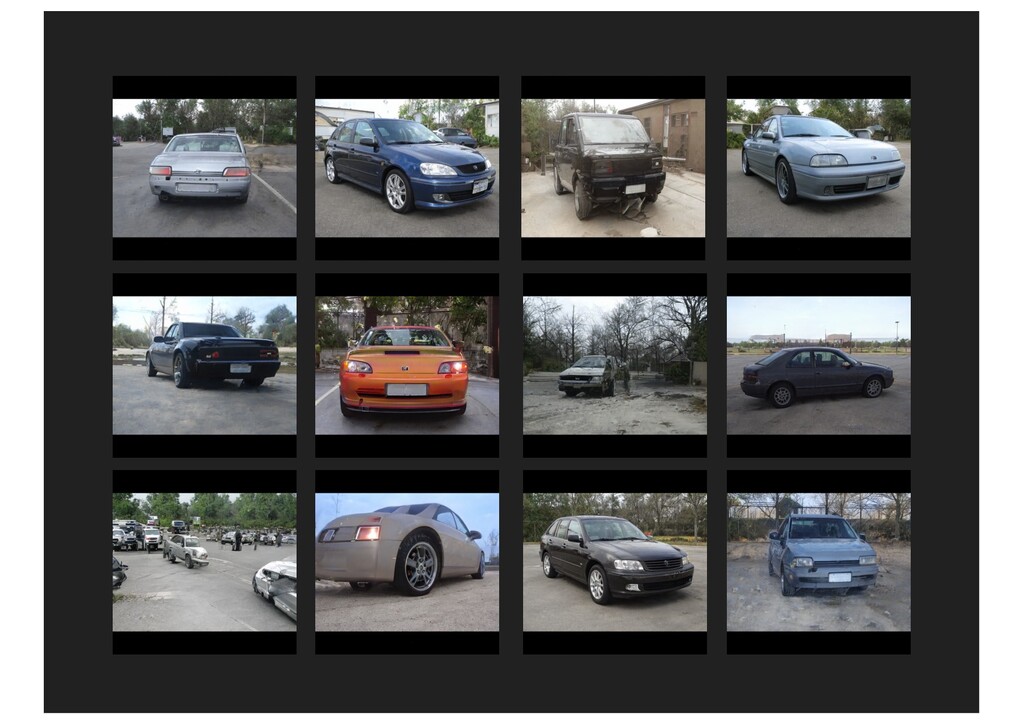
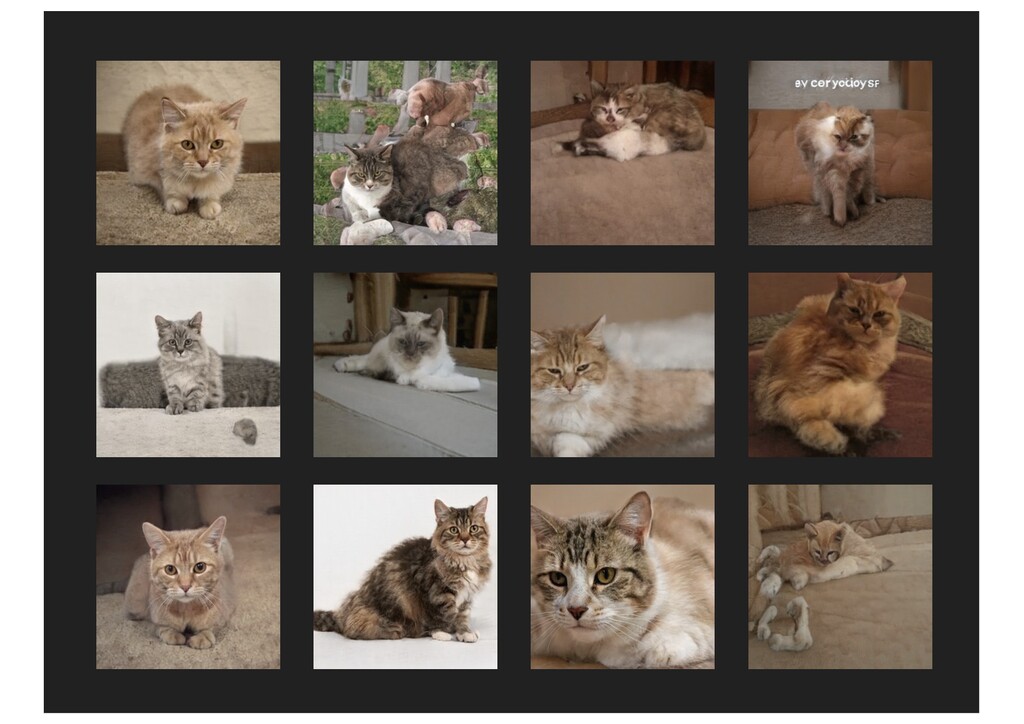
StyleGAN2 Analyzing and Improving the Image Quality of StyleGAN
https://arxiv.org/abs/1912.04958 https://github.com/NVlabs/stylegan2 -
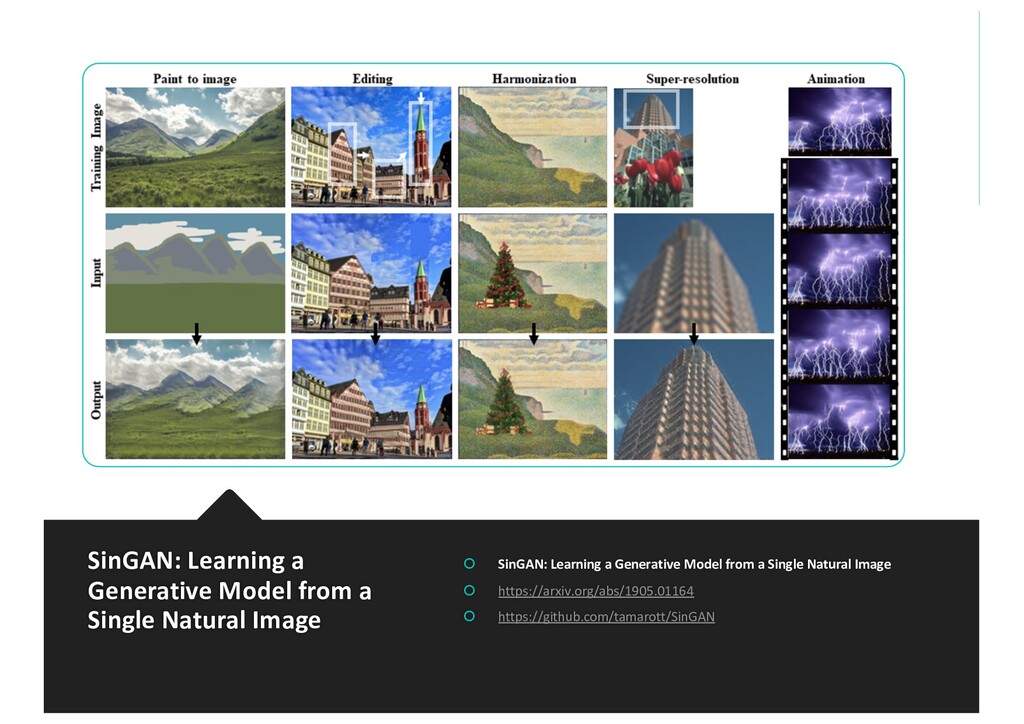
SinGAN: Learning a Generative Model from a Single Natural Image
SinGAN: Learning a Generative Model from a Single Natural Image https://arxiv.org/abs/1905.01164 https://github.com/tamarott/SinGAN -
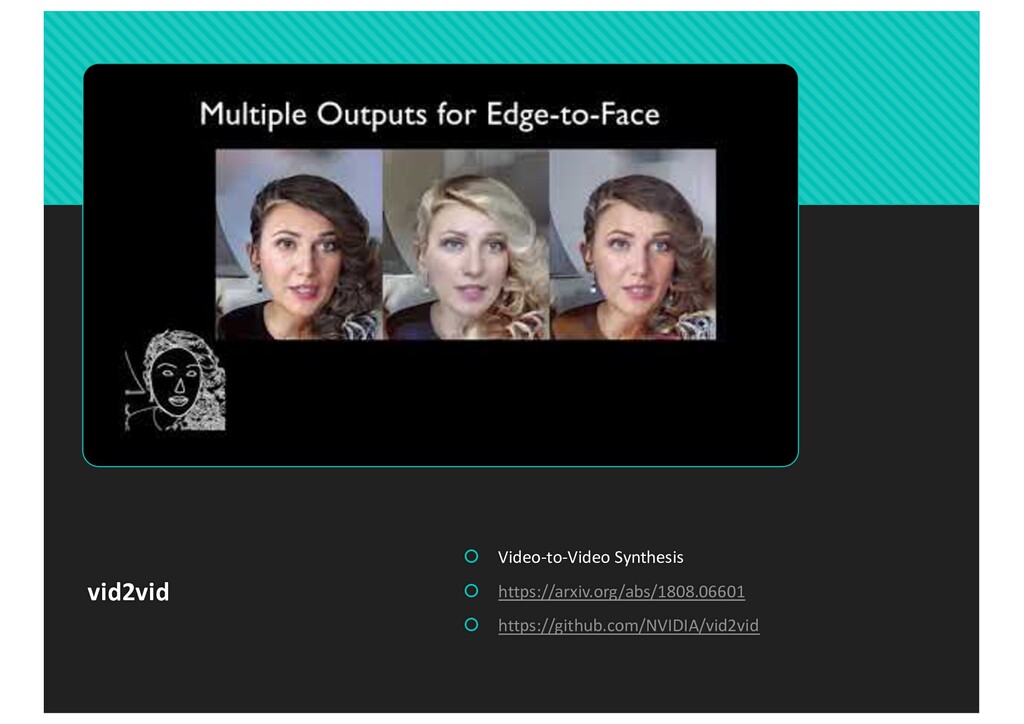
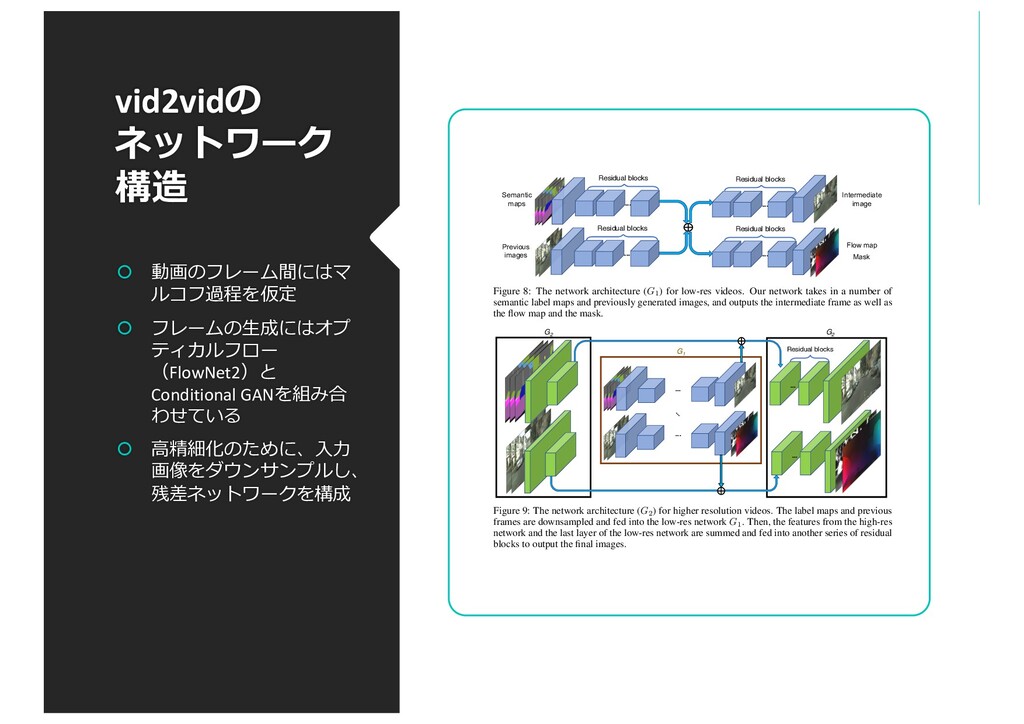
vid2vidの ネットワーク 構造 動画のフレーム間にはマ ルコフ過程を仮定 フレームの⽣成にはオプ ティカルフロー (FlowNet2)と
Conditional GANを組み合 わせている ⾼精細化のために、⼊⼒ 画像をダウンサンプルし、 残差ネットワークを構成 Residual blocks ... Residual blocks ... Residual blocks ... Residual blocks ... Semantic maps Previous images Intermediate image Flow map Mask Figure 8: The network architecture (G1 ) for low-res videos. Our network takes in a number of semantic label maps and previously generated images, and outputs the intermediate frame as well as the flow map and the mask. ... Residual blocks G2 ... ... ... ... G2 G1 Figure 9: The network architecture (G2 ) for higher resolution videos. The label maps and previous frames are downsampled and fed into the low-res network G1 . Then, the features from the high-res network and the last layer of the low-res network are summed and fed into another series of residual blocks to output the final images. A Network Architecture A.1 Generators Our network adopts a coarse-to-fine architecture. For the lowest resolution, the network takes in a number of semantic label maps st t L and previously generated frames ˜ xt 1 t L as input. The label maps are concatenated together and undergo several residual blocks to form intermediate high-level features. We apply the same processing for the previously generated images. Then, these two intermediate layers are added and fed into two separate residual networks to output the hallucinated image ˜ ht as well as the flow map ˜ wt and the mask ˜ mt (Figure 8). Next, to build from low-res results to higher-res results, we use another network G2 on top of the low-res network G1 (Figure 9). In particular, we first downsample the inputs and fed them into G1 . Then, we extract features from the last feature layer of G and add them to the intermediate feature -
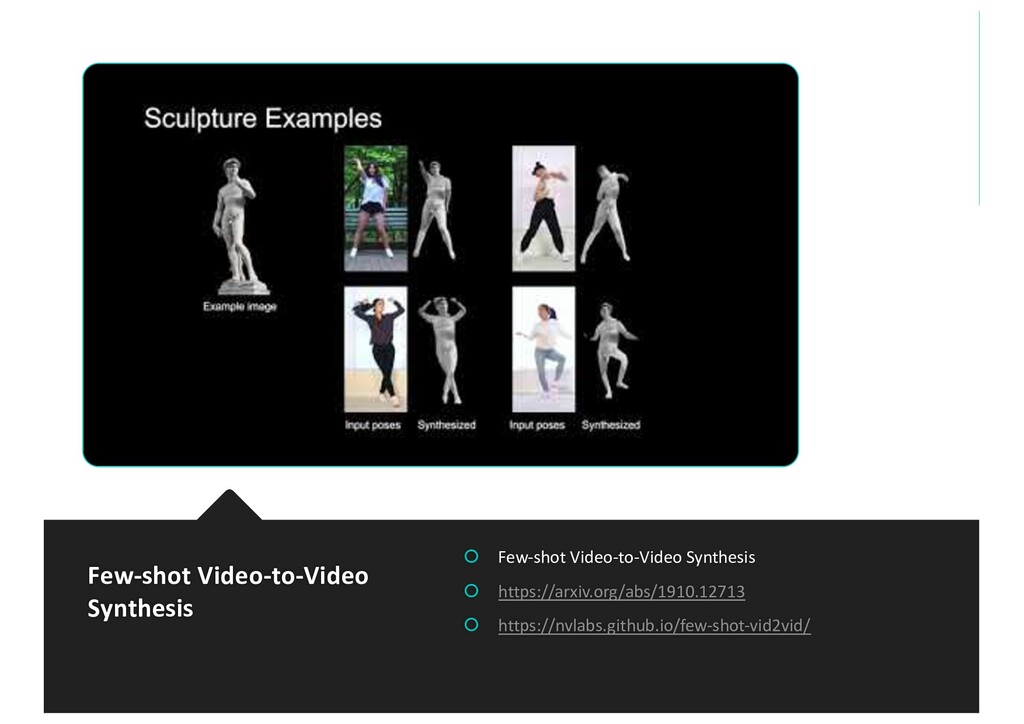
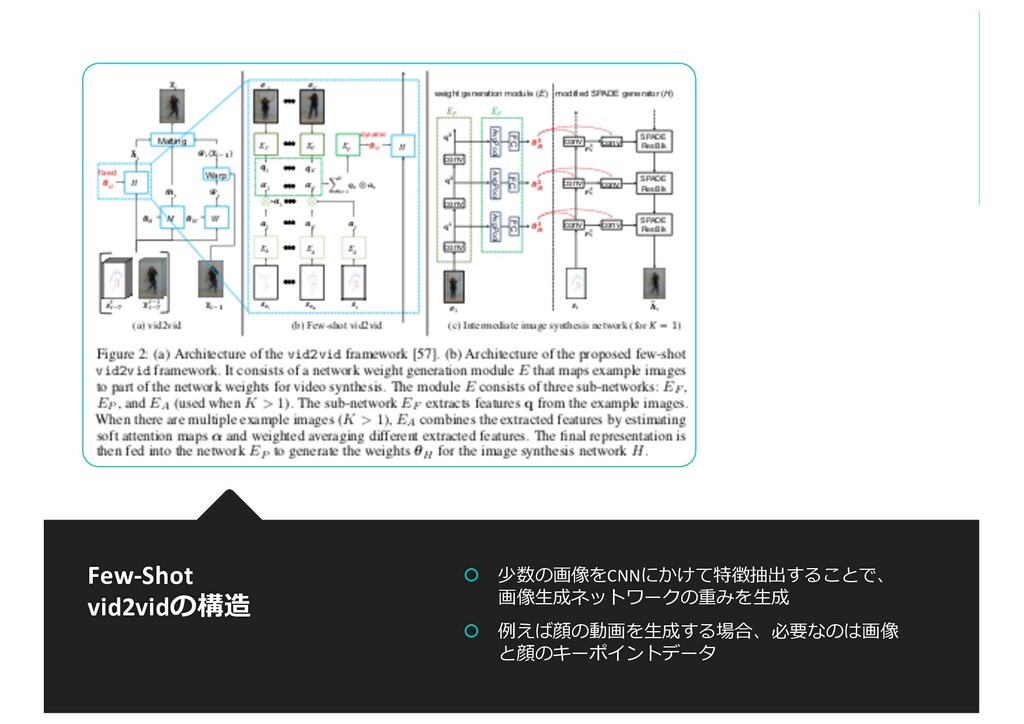
Few-shot Video-to-Video Synthesis Few-shot Video-to-Video Synthesis https://arxiv.org/abs/1910.12713
https://nvlabs.github.io/few-shot-vid2vid/ -
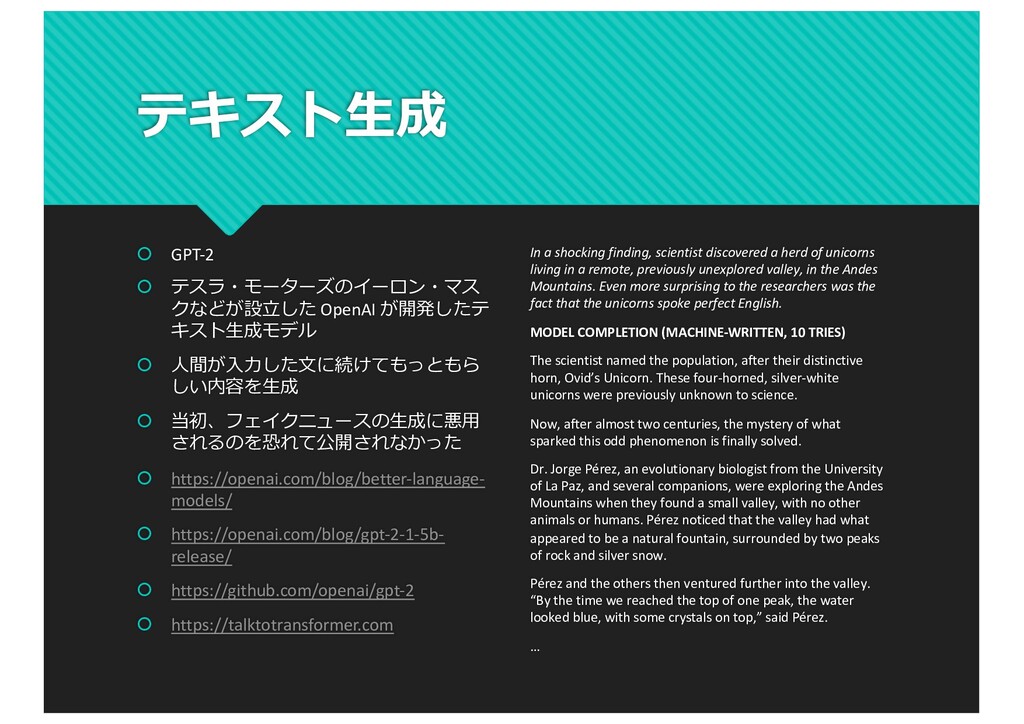
テキスト⽣成 GPT-2 テスラ・モーターズのイーロン・マス クなどが設⽴した OpenAI が開発したテ キスト⽣成モデル
⼈間が⼊⼒した⽂に続けてもっともら しい内容を⽣成 当初、フェイクニュースの⽣成に悪⽤ されるのを恐れて公開されなかった https://openai.com/blog/better-language- models/ https://openai.com/blog/gpt-2-1-5b- release/ https://github.com/openai/gpt-2 https://talktotransformer.com In a shocking finding, scientist discovered a herd of unicorns living in a remote, previously unexplored valley, in the Andes Mountains. Even more surprising to the researchers was the fact that the unicorns spoke perfect English. MODEL COMPLETION (MACHINE-WRITTEN, 10 TRIES) The scientist named the population, after their distinctive horn, Ovid’s Unicorn. These four-horned, silver-white unicorns were previously unknown to science. Now, after almost two centuries, the mystery of what sparked this odd phenomenon is finally solved. Dr. Jorge Pérez, an evolutionary biologist from the University of La Paz, and several companions, were exploring the Andes Mountains when they found a small valley, with no other animals or humans. Pérez noticed that the valley had what appeared to be a natural fountain, surrounded by two peaks of rock and silver snow. Pérez and the others then ventured further into the valley. “By the time we reached the top of one peak, the water looked blue, with some crystals on top,” said Pérez. … -
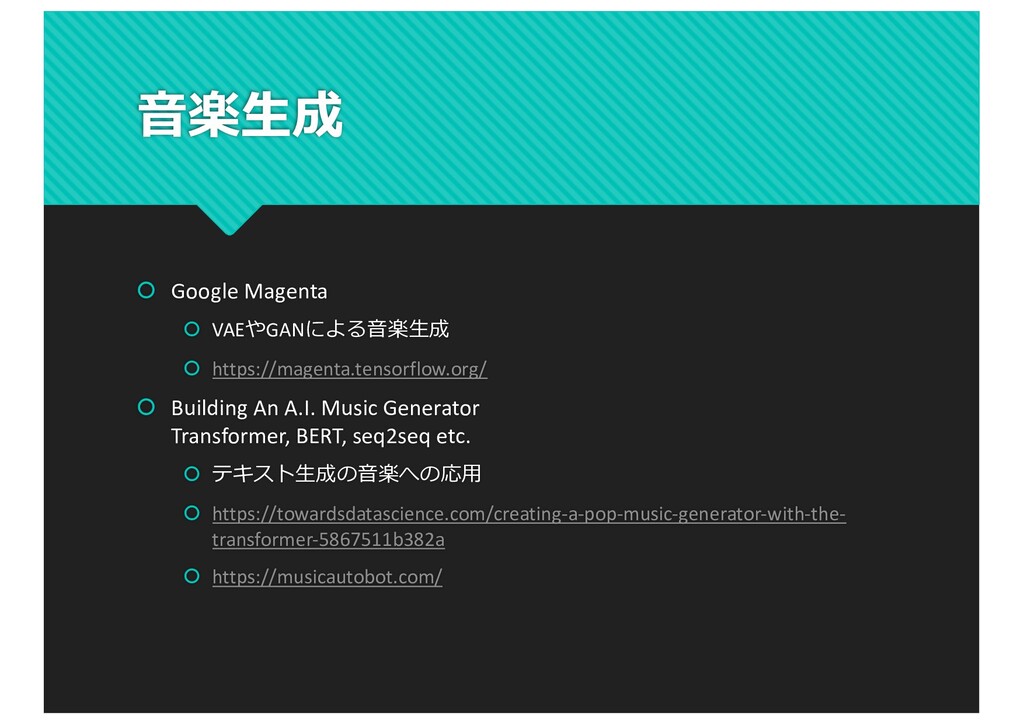
⾳楽⽣成 Google Magenta VAEやGANによる⾳楽⽣成 https://magenta.tensorflow.org/ Building
An A.I. Music Generator Transformer, BERT, seq2seq etc. テキスト⽣成の⾳楽への応⽤ https://towardsdatascience.com/creating-a-pop-music-generator-with-the- transformer-5867511b382a https://musicautobot.com/ -
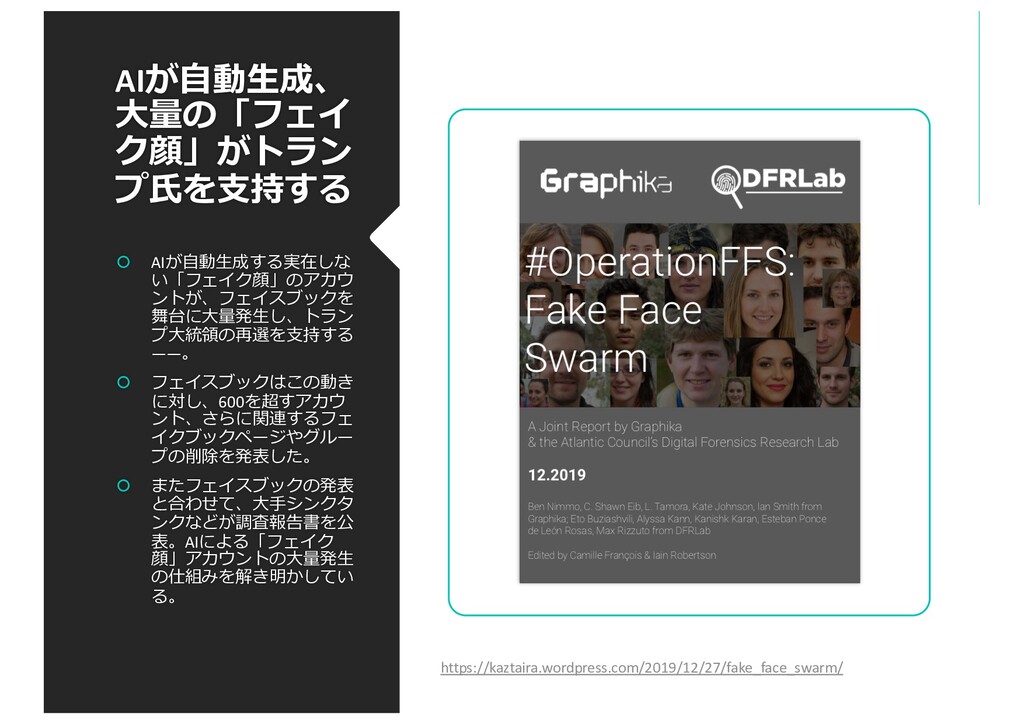
AIが⾃動⽣成、 ⼤量の「フェイ ク顔」がトラン プ⽒を⽀持する AIが⾃動⽣成する実在しな い「フェイク顔」のアカウ ントが、フェイスブックを 舞台に⼤量発⽣し、トラン プ⼤統領の再選を⽀持する
――。 フェイスブックはこの動き に対し、600を超すアカウ ント、さらに関連するフェ イクブックページやグルー プの削除を発表した。 またフェイスブックの発表 と合わせて、⼤⼿シンクタ ンクなどが調査報告書を公 表。AIによる「フェイク 顔」アカウントの⼤量発⽣ の仕組みを解き明かしてい る。 https://kaztaira.wordpress.com/2019/12/27/fake_face_swarm/ -
Deepfake Detection Challenge https://www.kaggle.com/c/deepfake-detection-challenge AWS, Facebook, Microsoft が共同で
Deepfake を検出する機械学習モデ ルを開発するコンテストを実施 動画の中からDeepfakeを検出 賞⾦総額は100万ドル︕