Share
Embed
Transcript
59 slides
-
REBASE 2025 ZJIT: Building a New JIT Compiler for Ruby
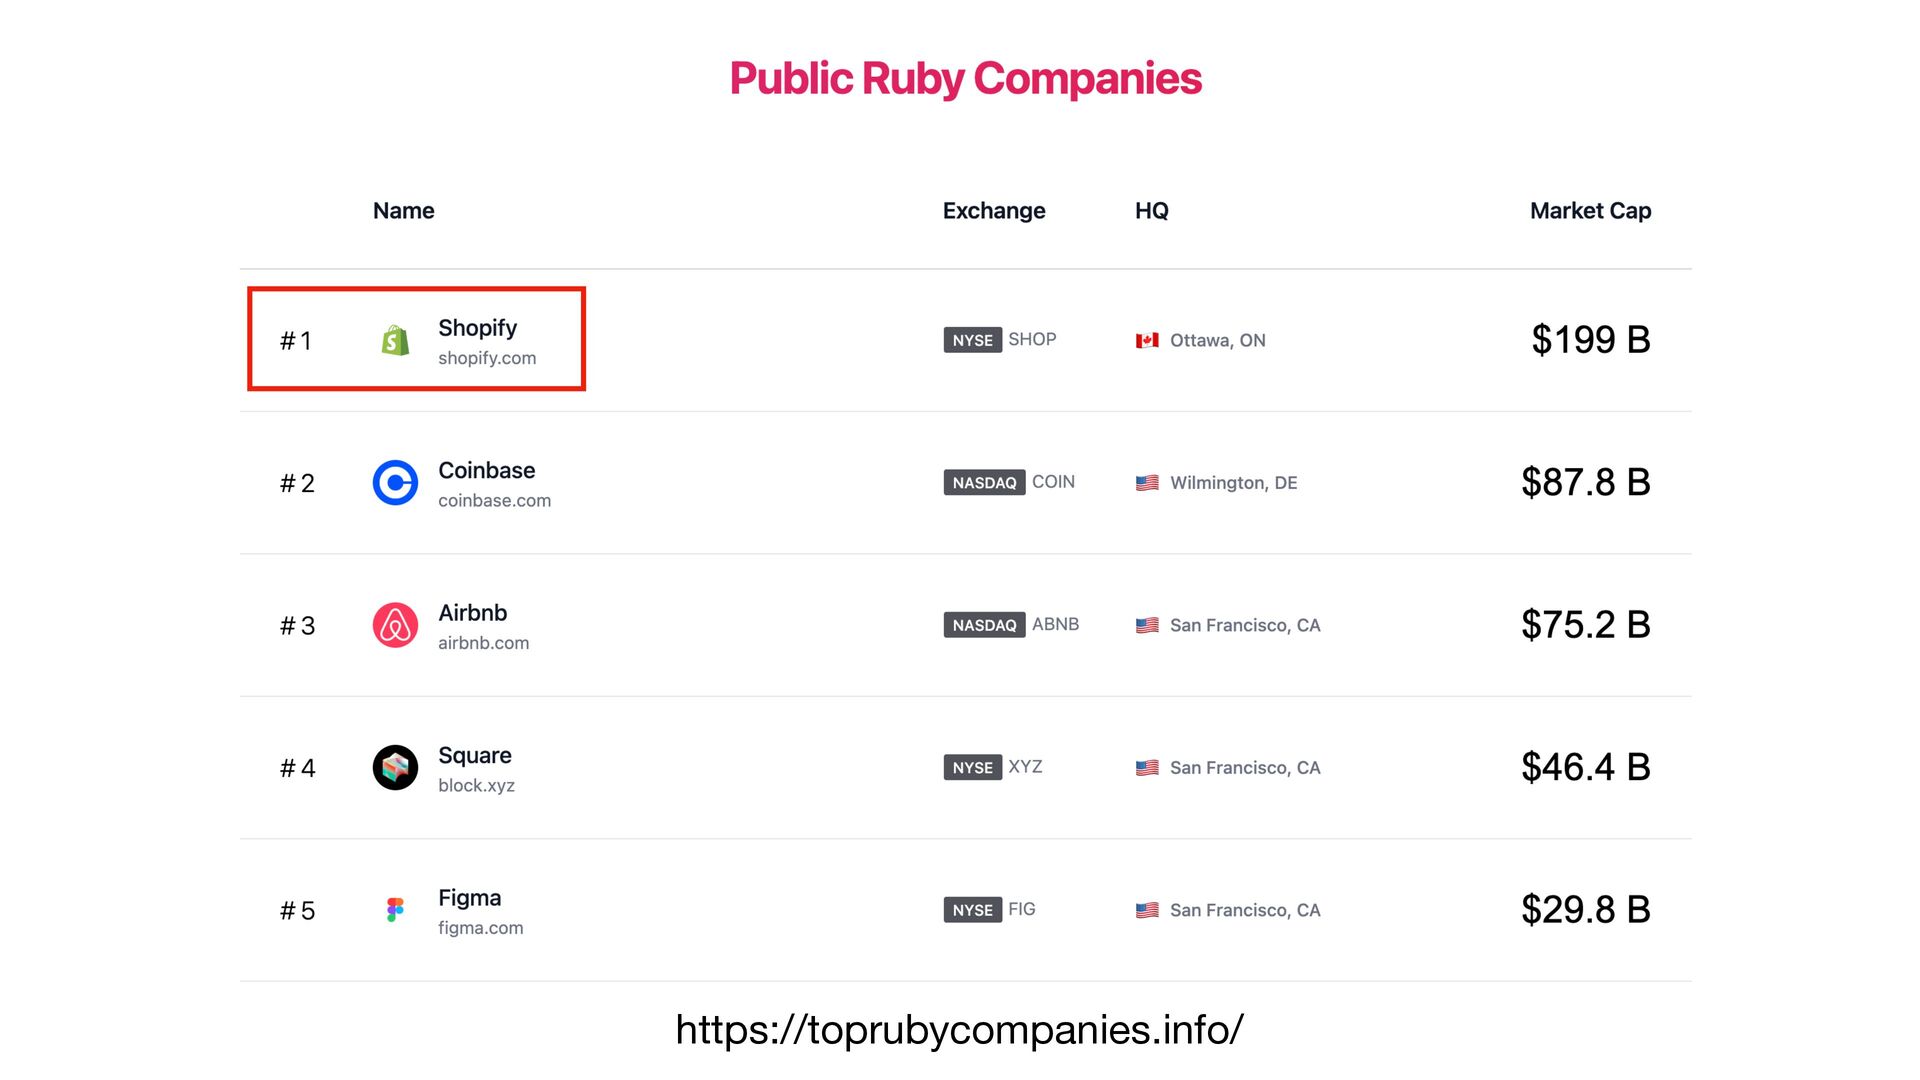
Takashi Kokubun Ruby Infrastructure team @ Shopify -
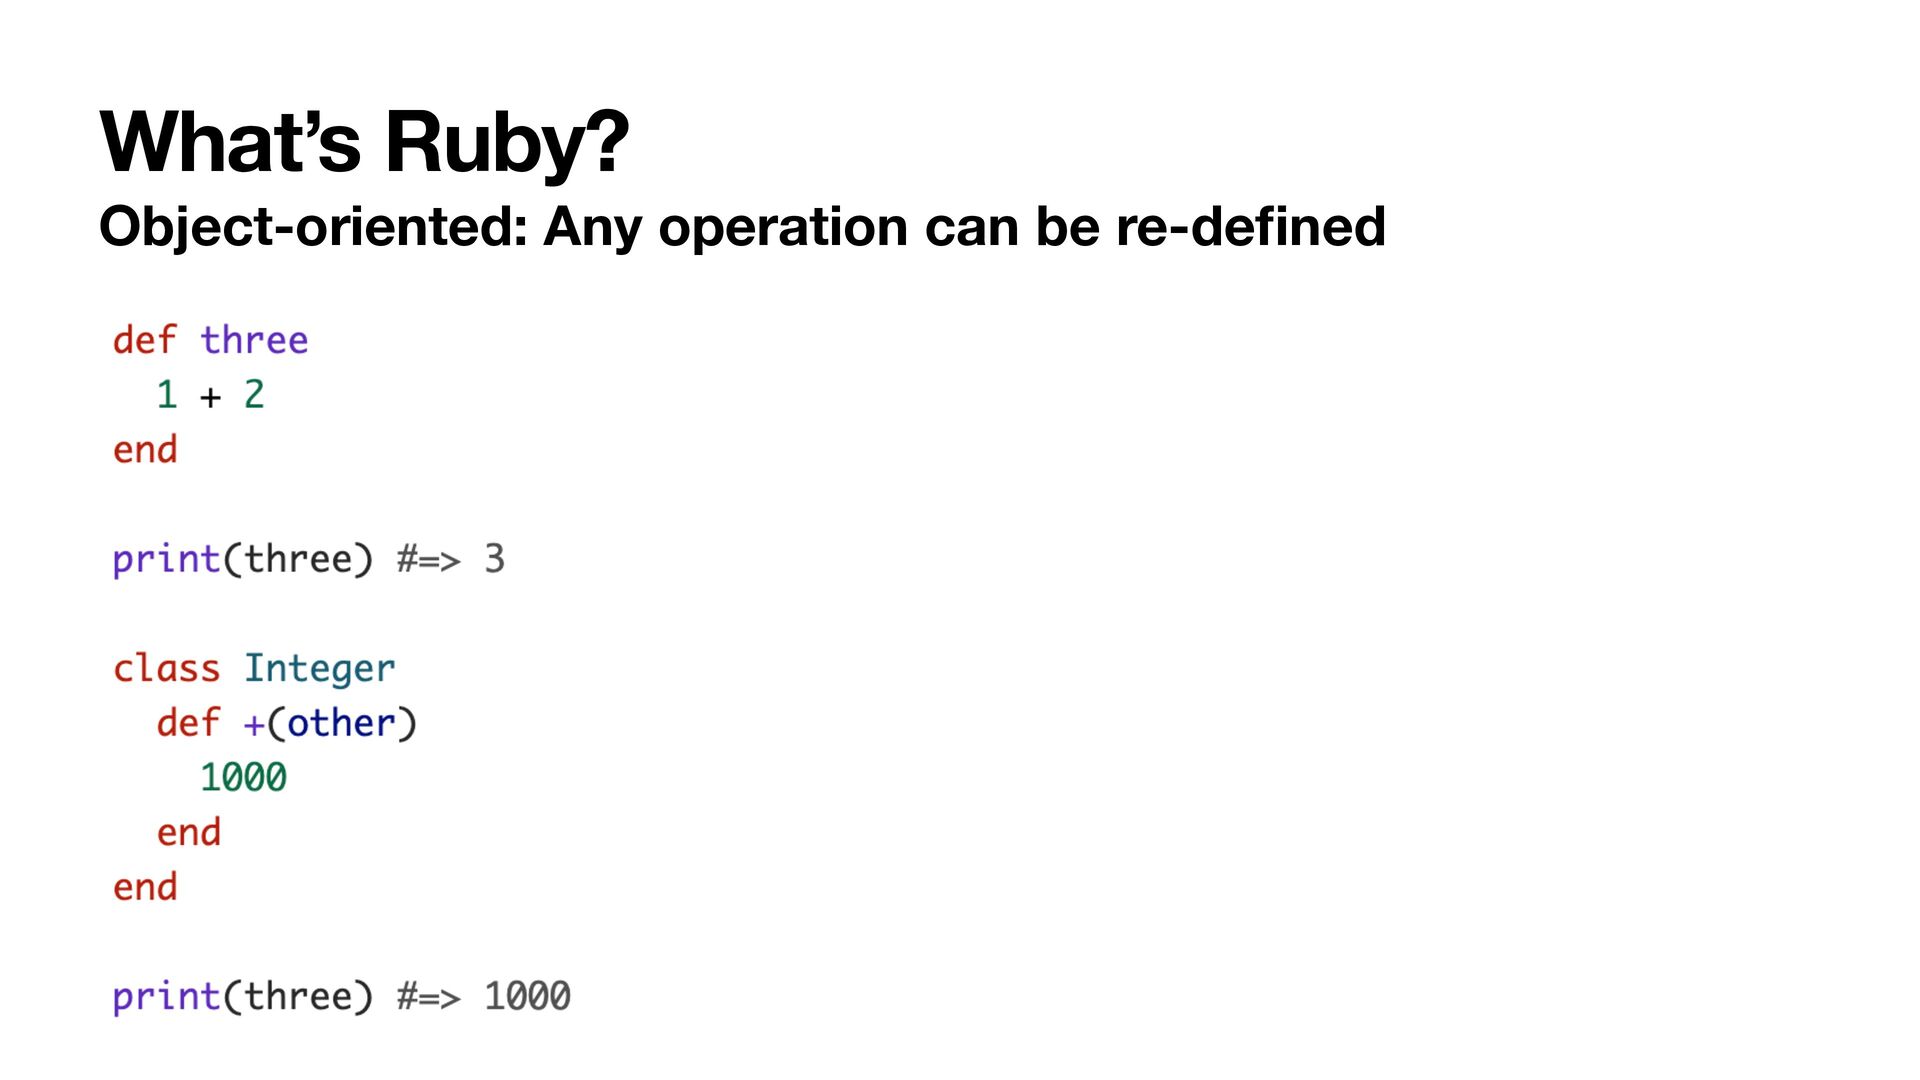
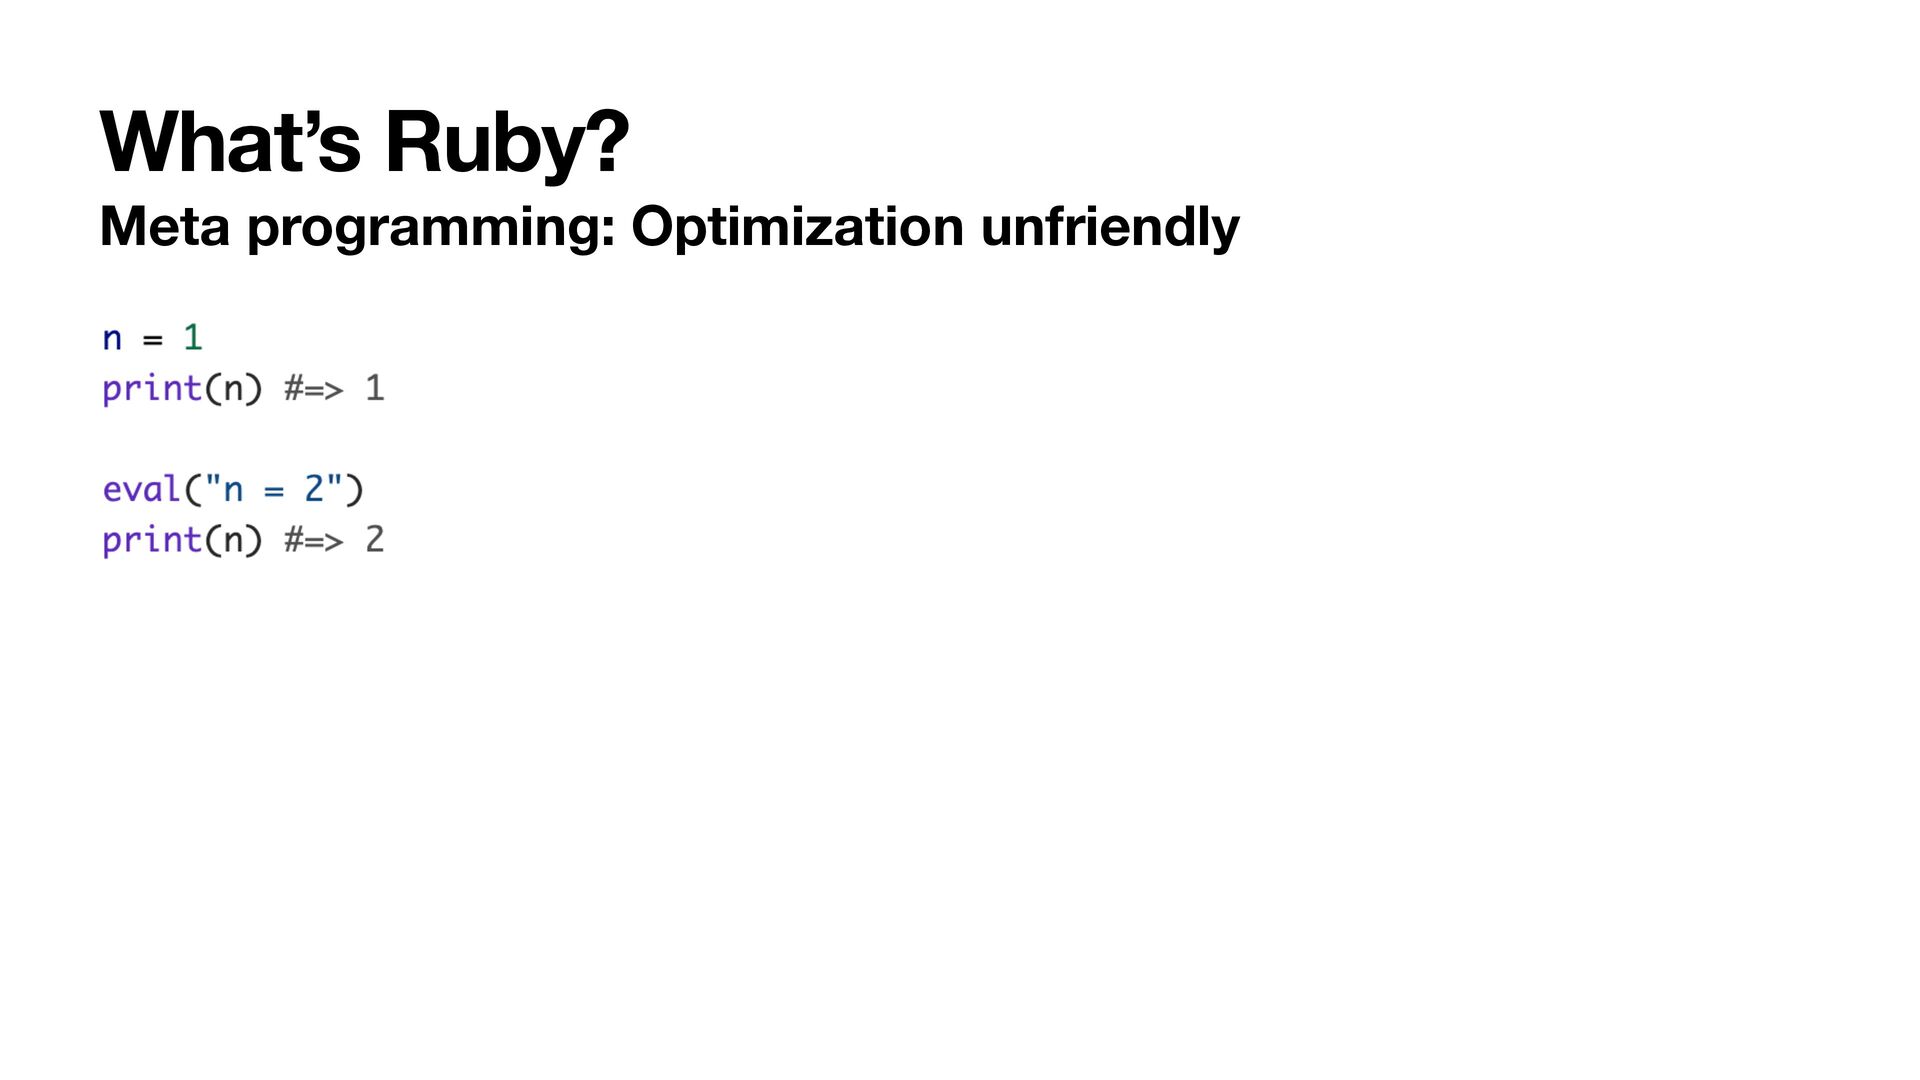
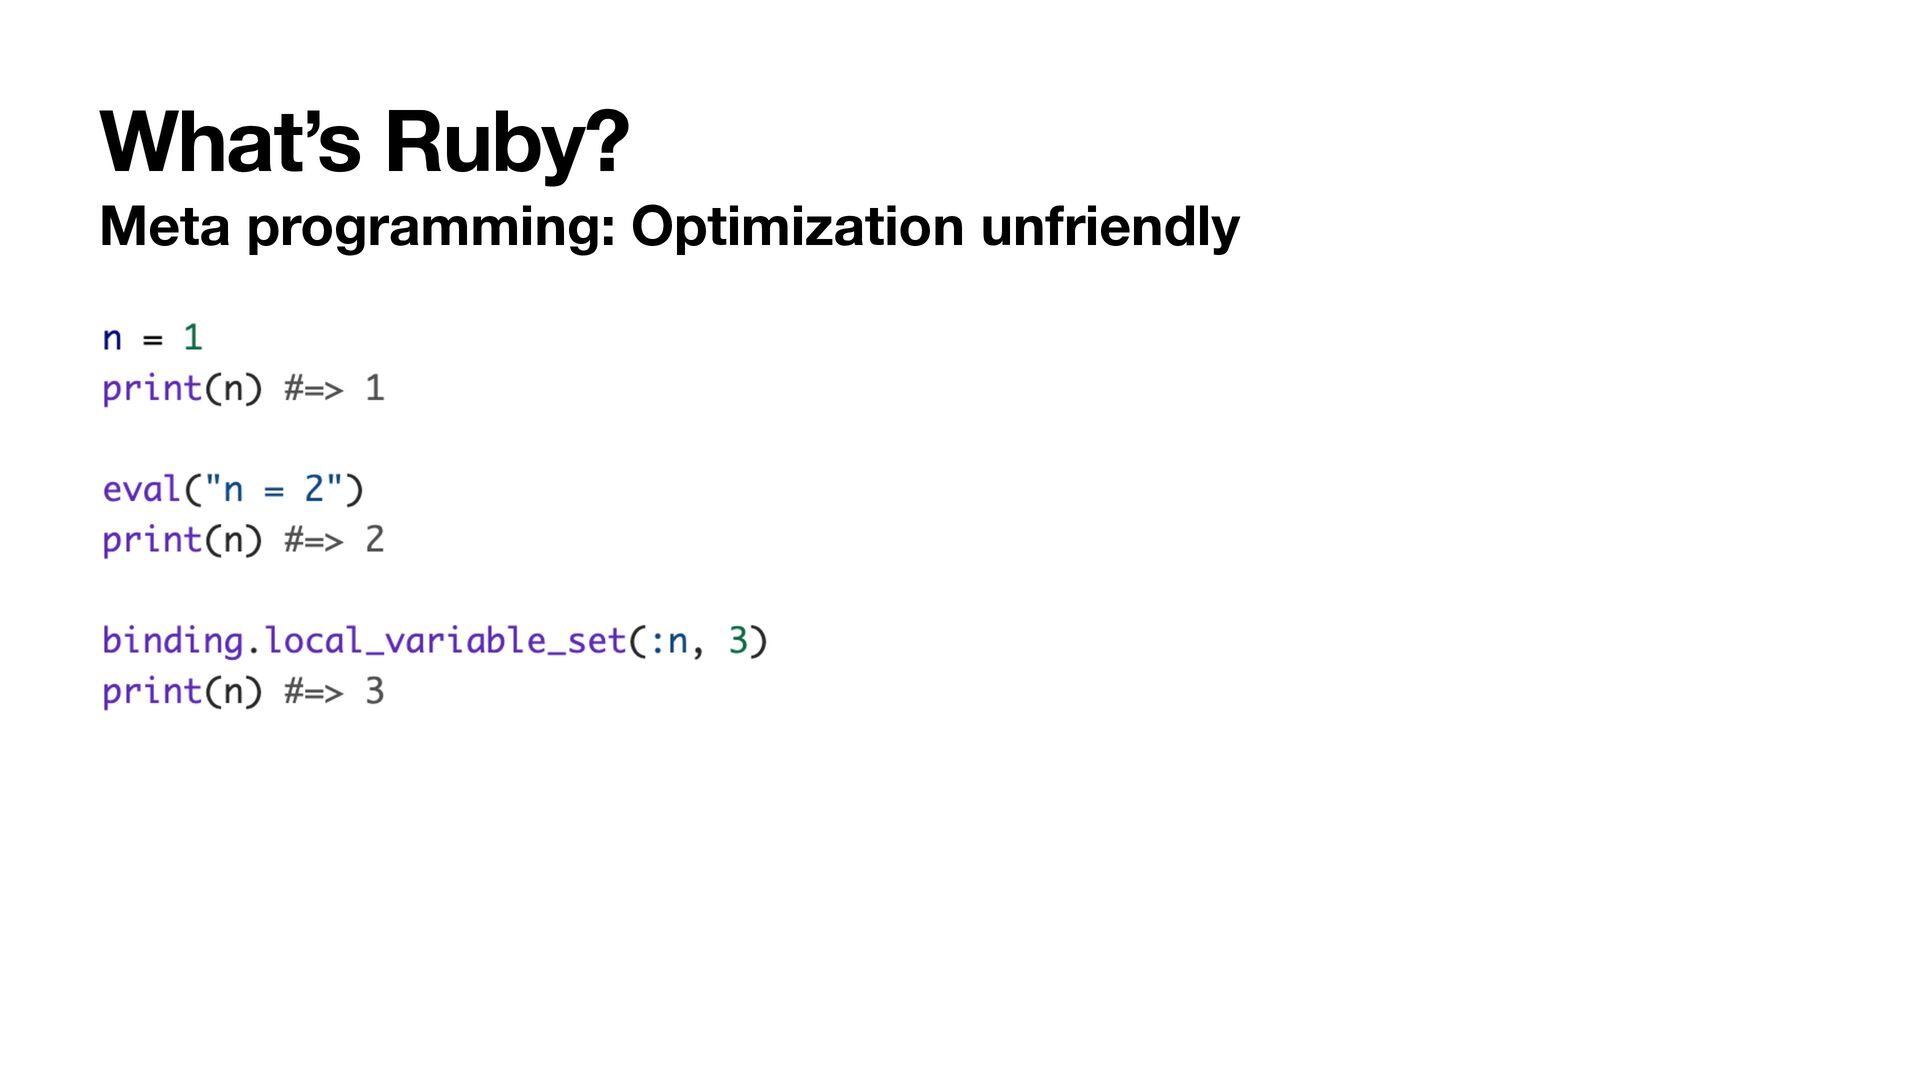
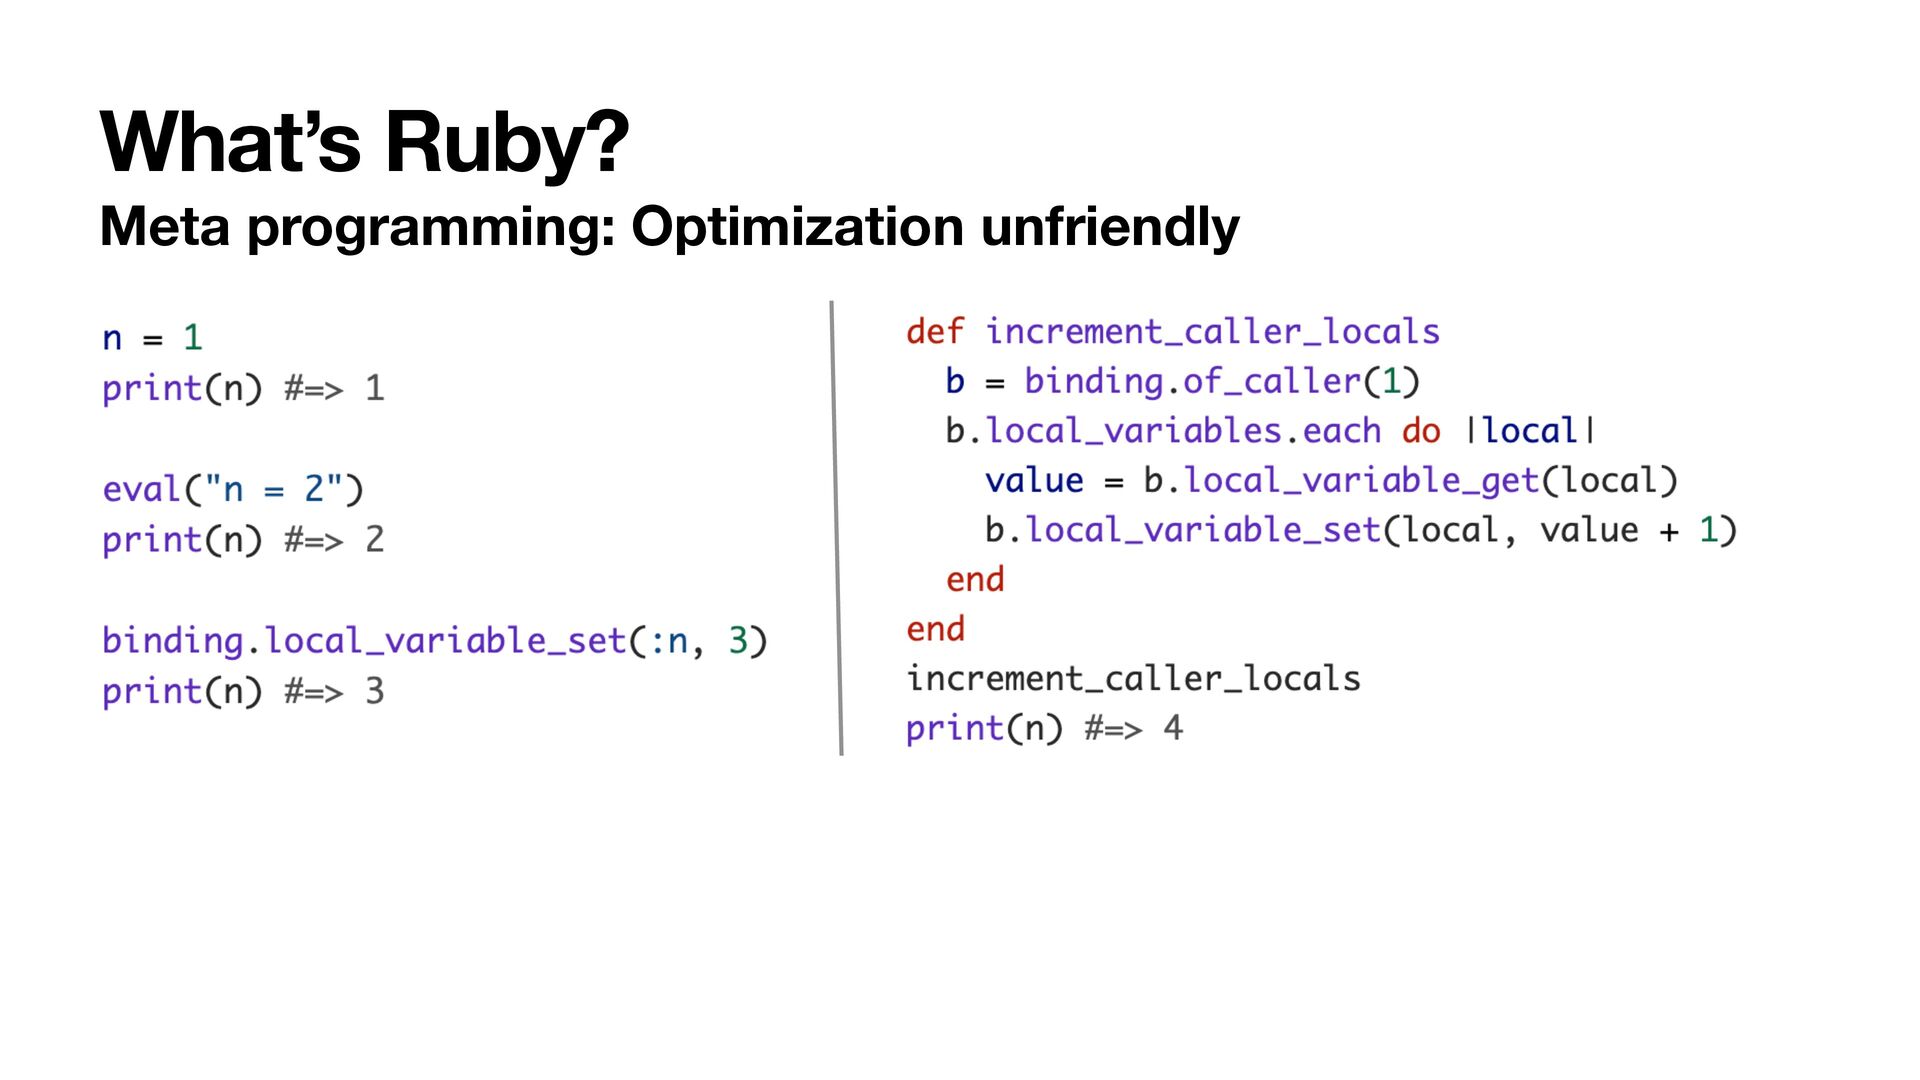
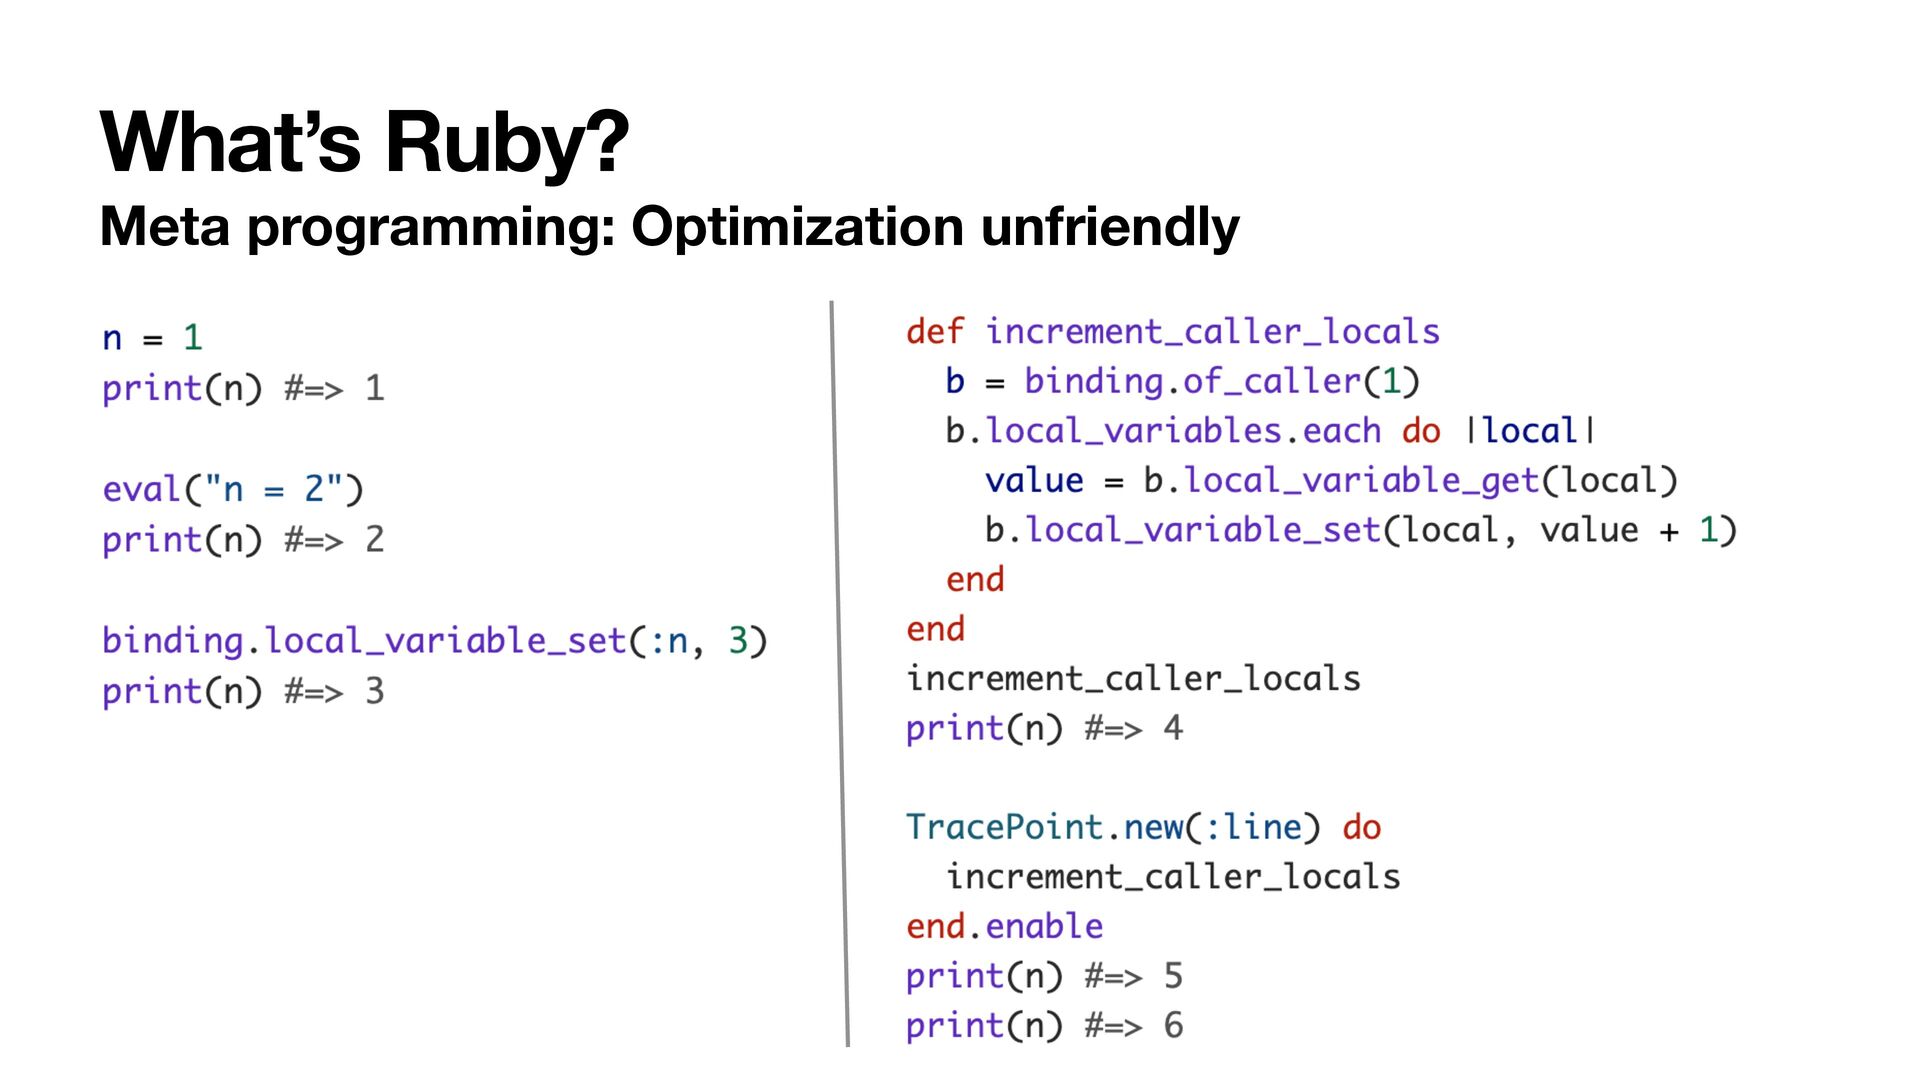
What’s Ruby? Language Characteristics • Object-oriented: Everything is an object
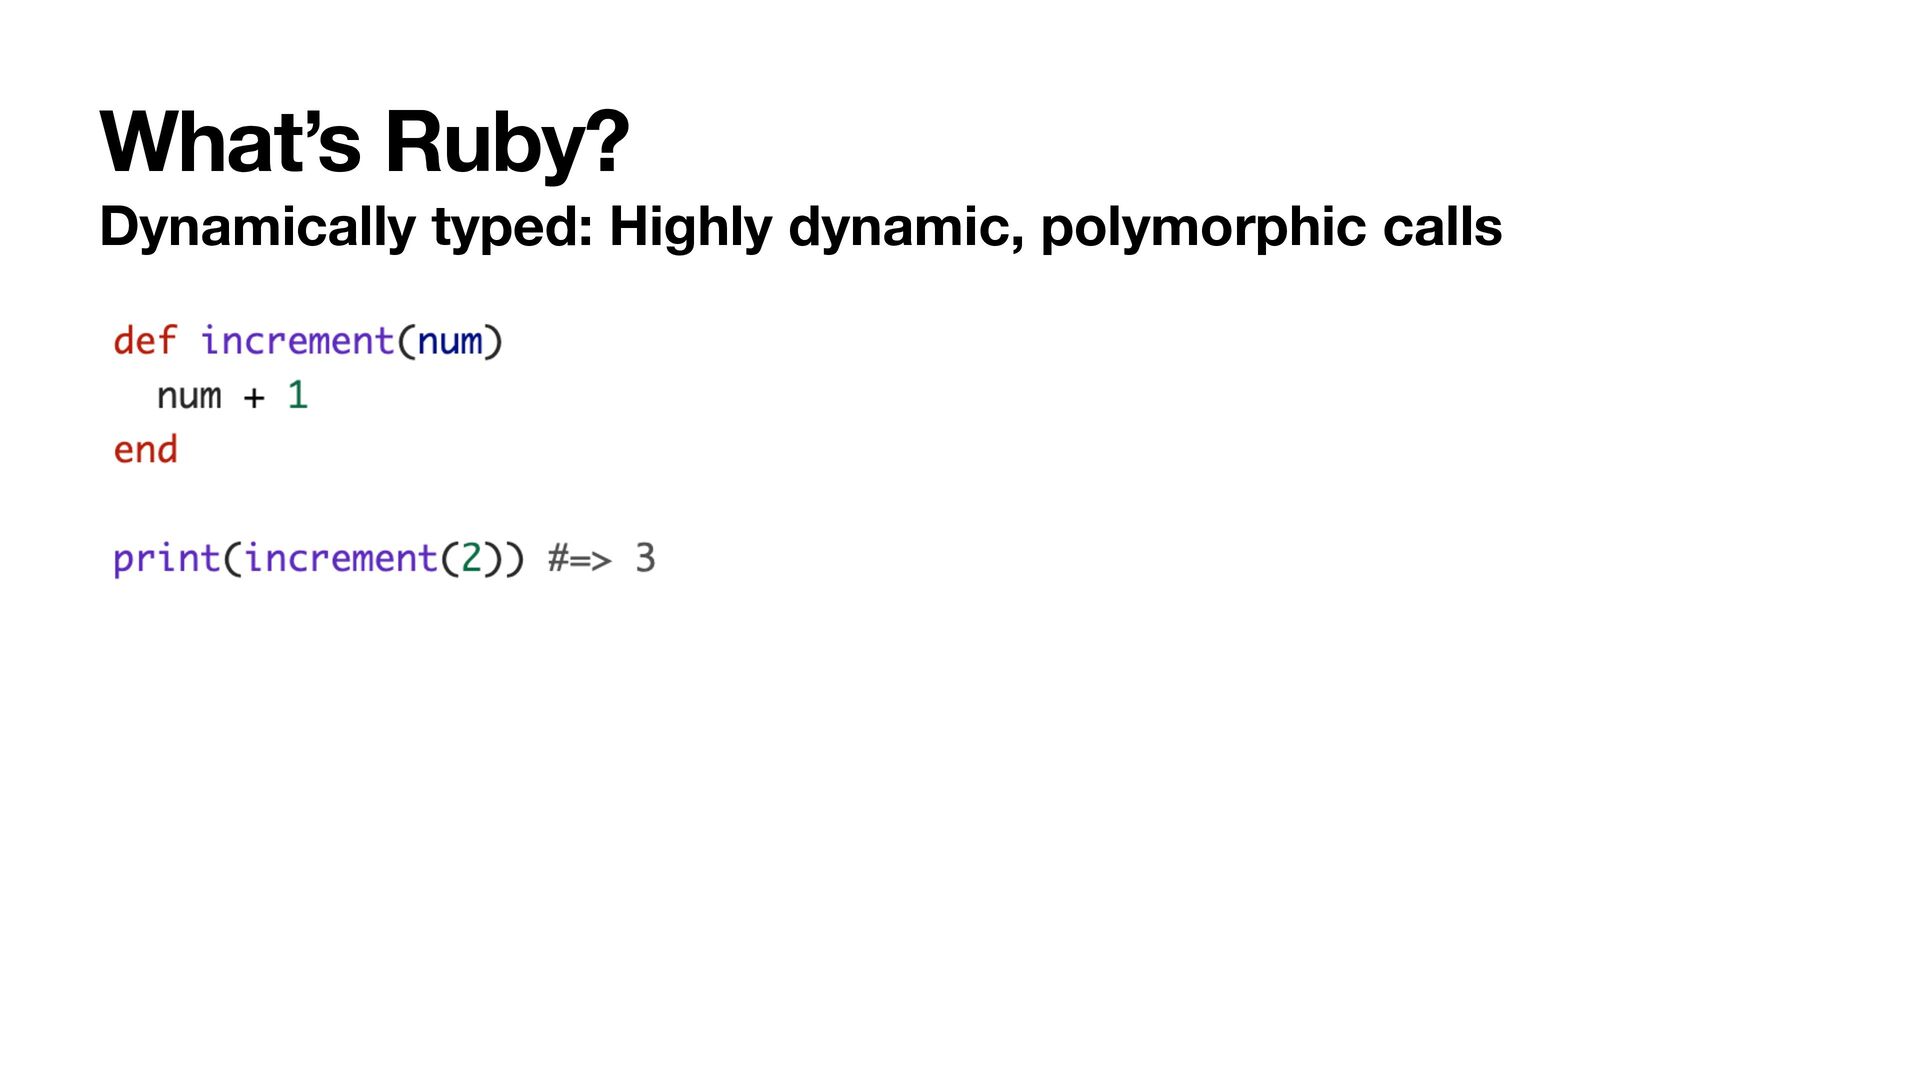
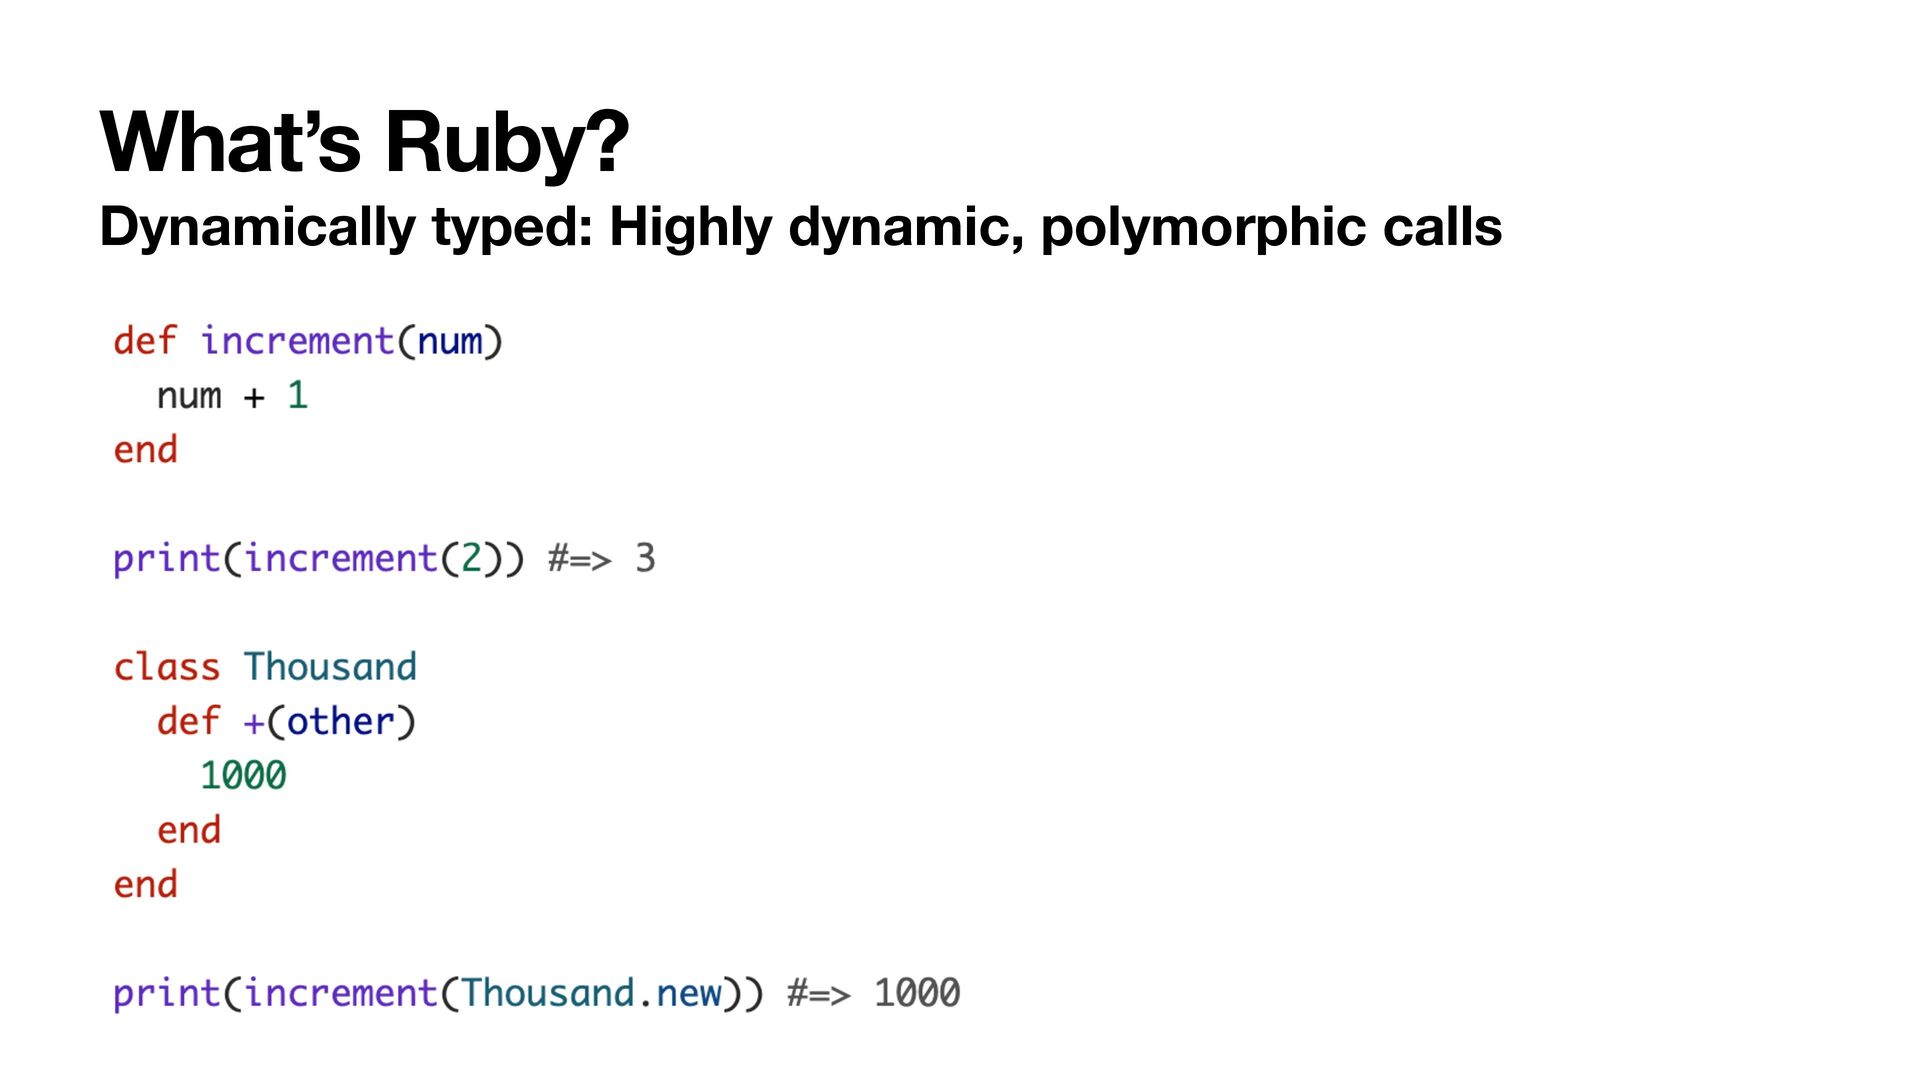
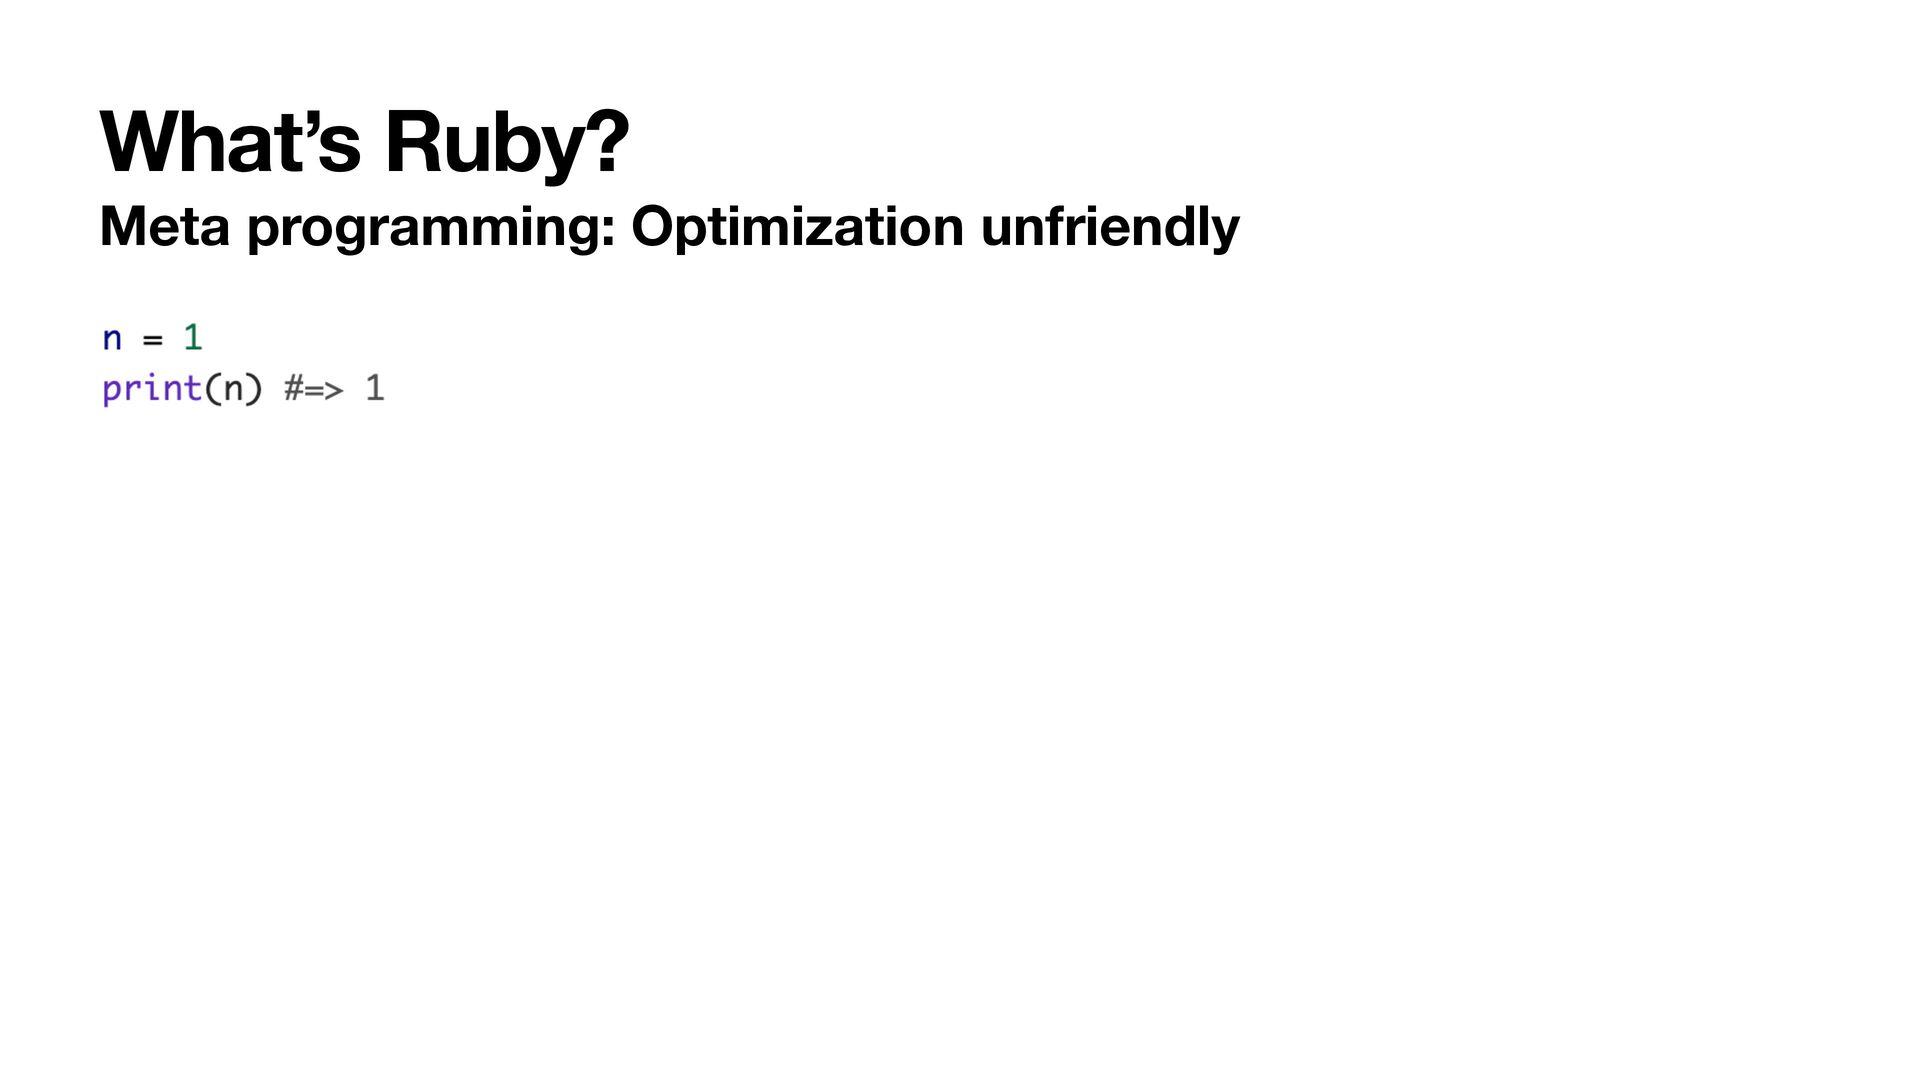
• Dynamically typed: Dynamic dispatch, polymorphic • Meta programming: Optimization unfriendly, e.g. eval -
What’s Ruby? Major Implementations • CRuby: Written in C, stack-based
interpreter, optional JIT • JRuby: Written in Java, Java bytecode, JVM • Tru ff l eRuby: Graal VM, AST interpreter, native or JVM -
What’s Ruby? Major Implementations • CRuby: Fast warmup, small memory
footprint • JRuby: No C extension support • Tru ff l eRuby: Slow warmup, high memory usage -
What’s Ruby? Major Implementations • CRuby: Fast warmup, small memory
footprint • JRuby: No C extension support • Tru ff l eRuby: Slow warmup, high memory usage -
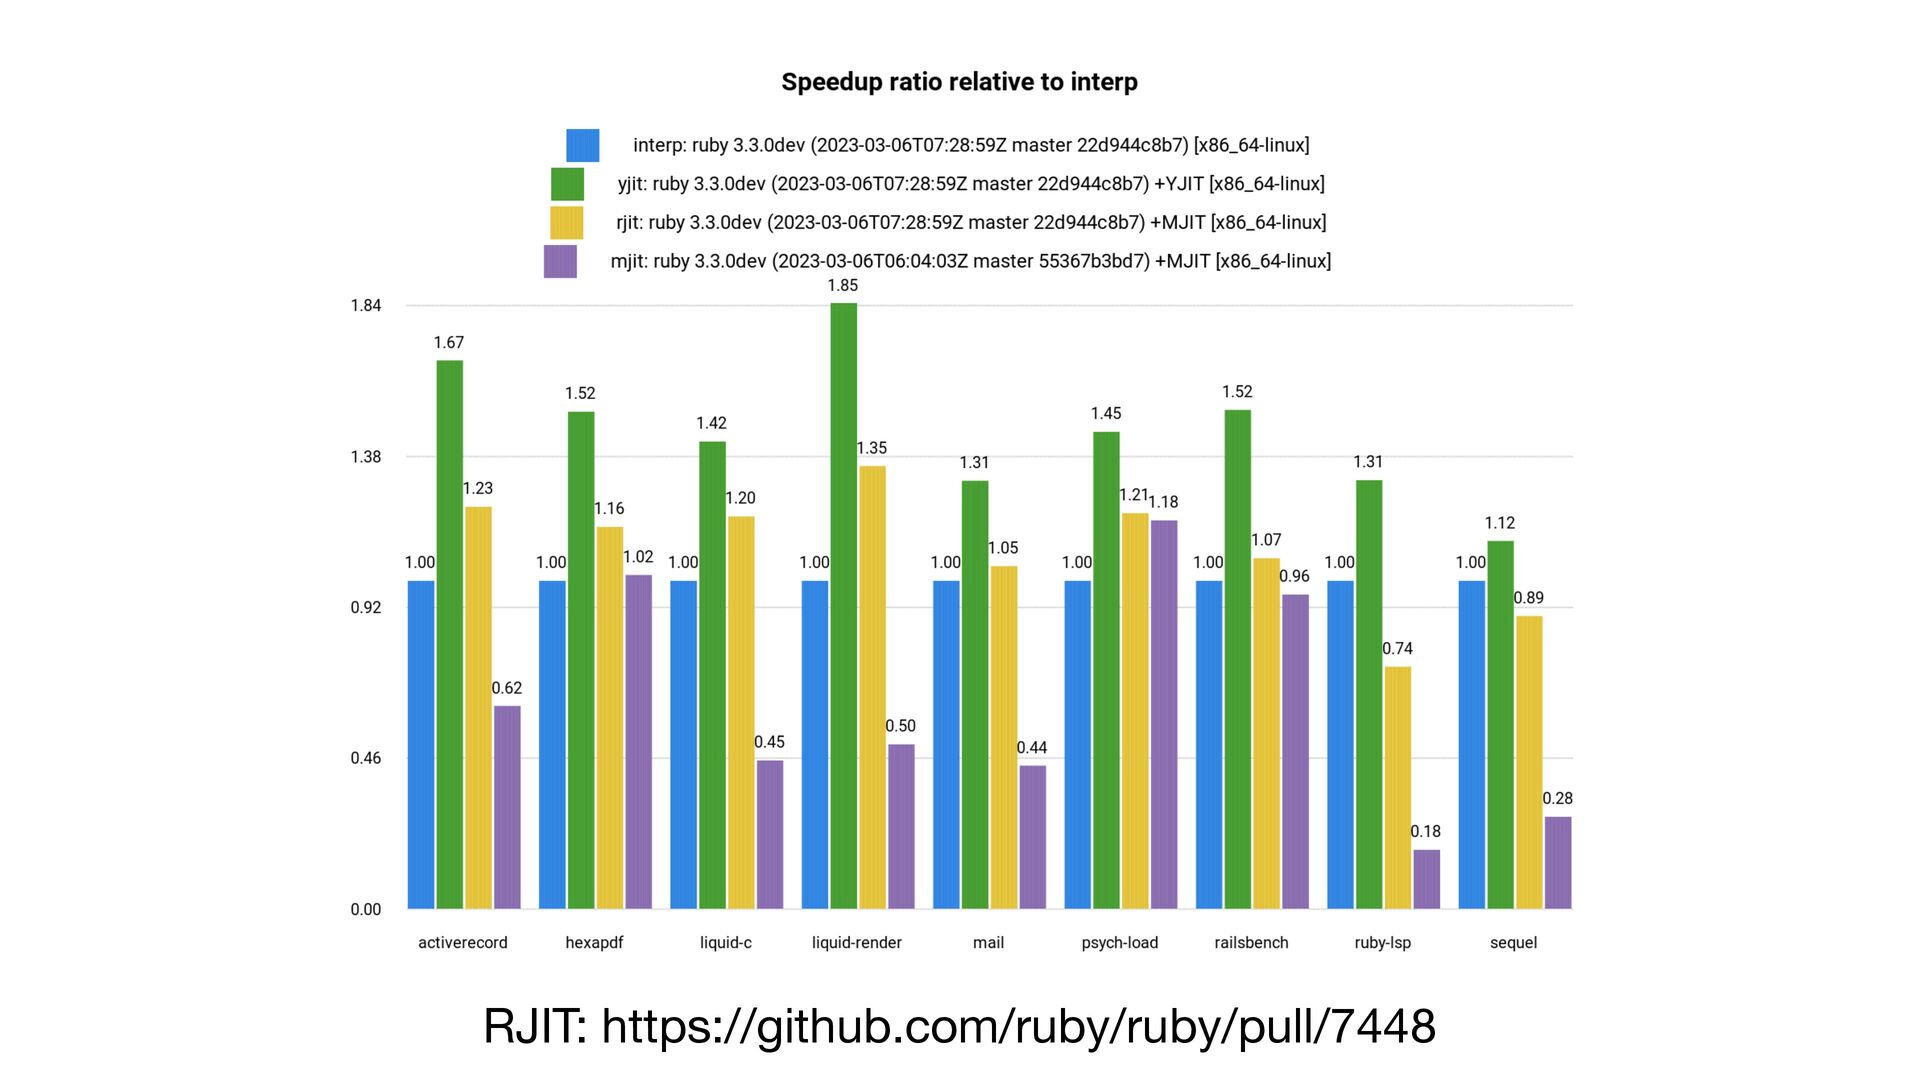
Ruby JITs Upstreamed to CRuby • MJIT: Ruby 2.6-3.2, uses
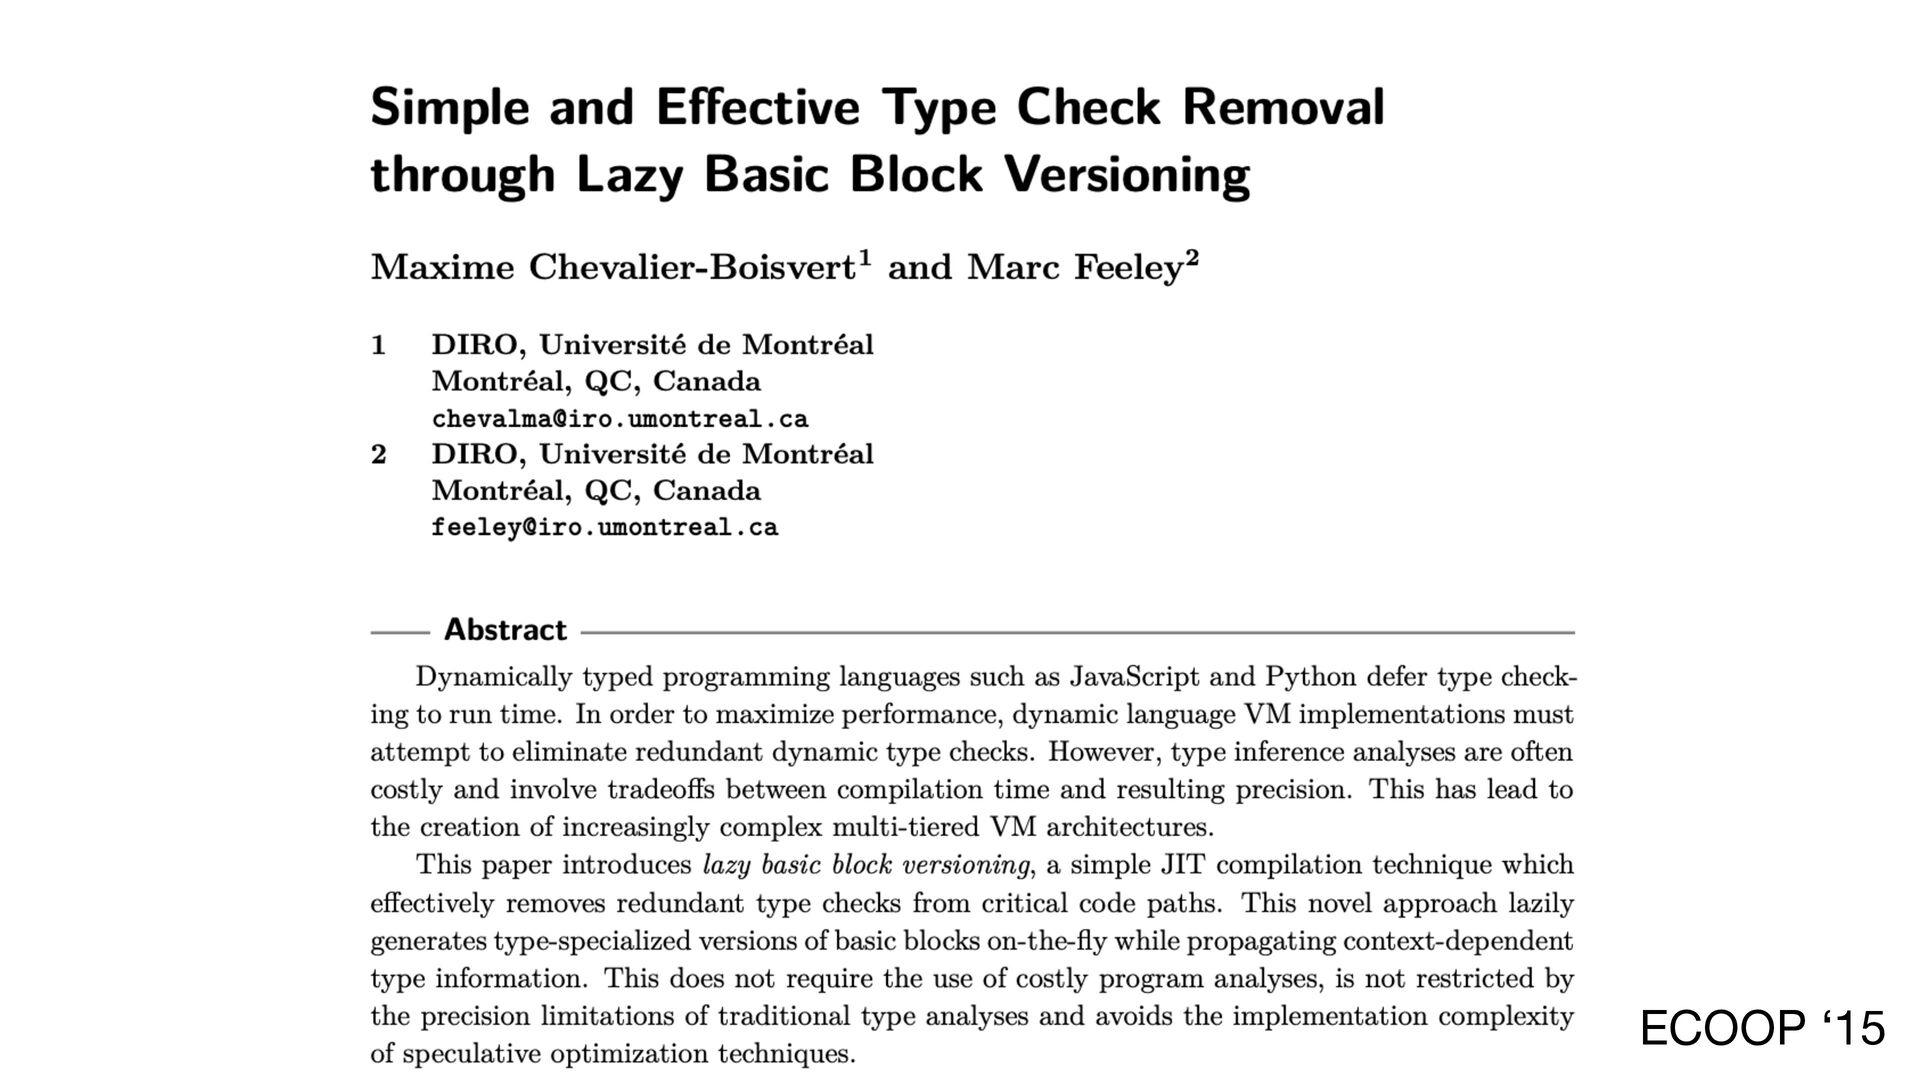
GCC/Clang/MSVC, written in C • YJIT: Ruby 3.1-now, Lazy Basic Block Versioning, Rust • RJIT: Ruby 3.3-3.4, Lazy Basic Block Versioning, Ruby • ZJIT: To be released in Ruby 3.5, SSA-based IR, Rust -
Ruby JITs Upstreamed to CRuby • MJIT: Ruby 2.6-3.2, uses
GCC/Clang/MSVC, written in C • YJIT: Ruby 3.1-now, Lazy Basic Block Versioning, Rust • RJIT: Ruby 3.3-3.4, Lazy Basic Block Versioning, Ruby • ZJIT: To be released in Ruby 3.5, SSA-based IR, Rust -
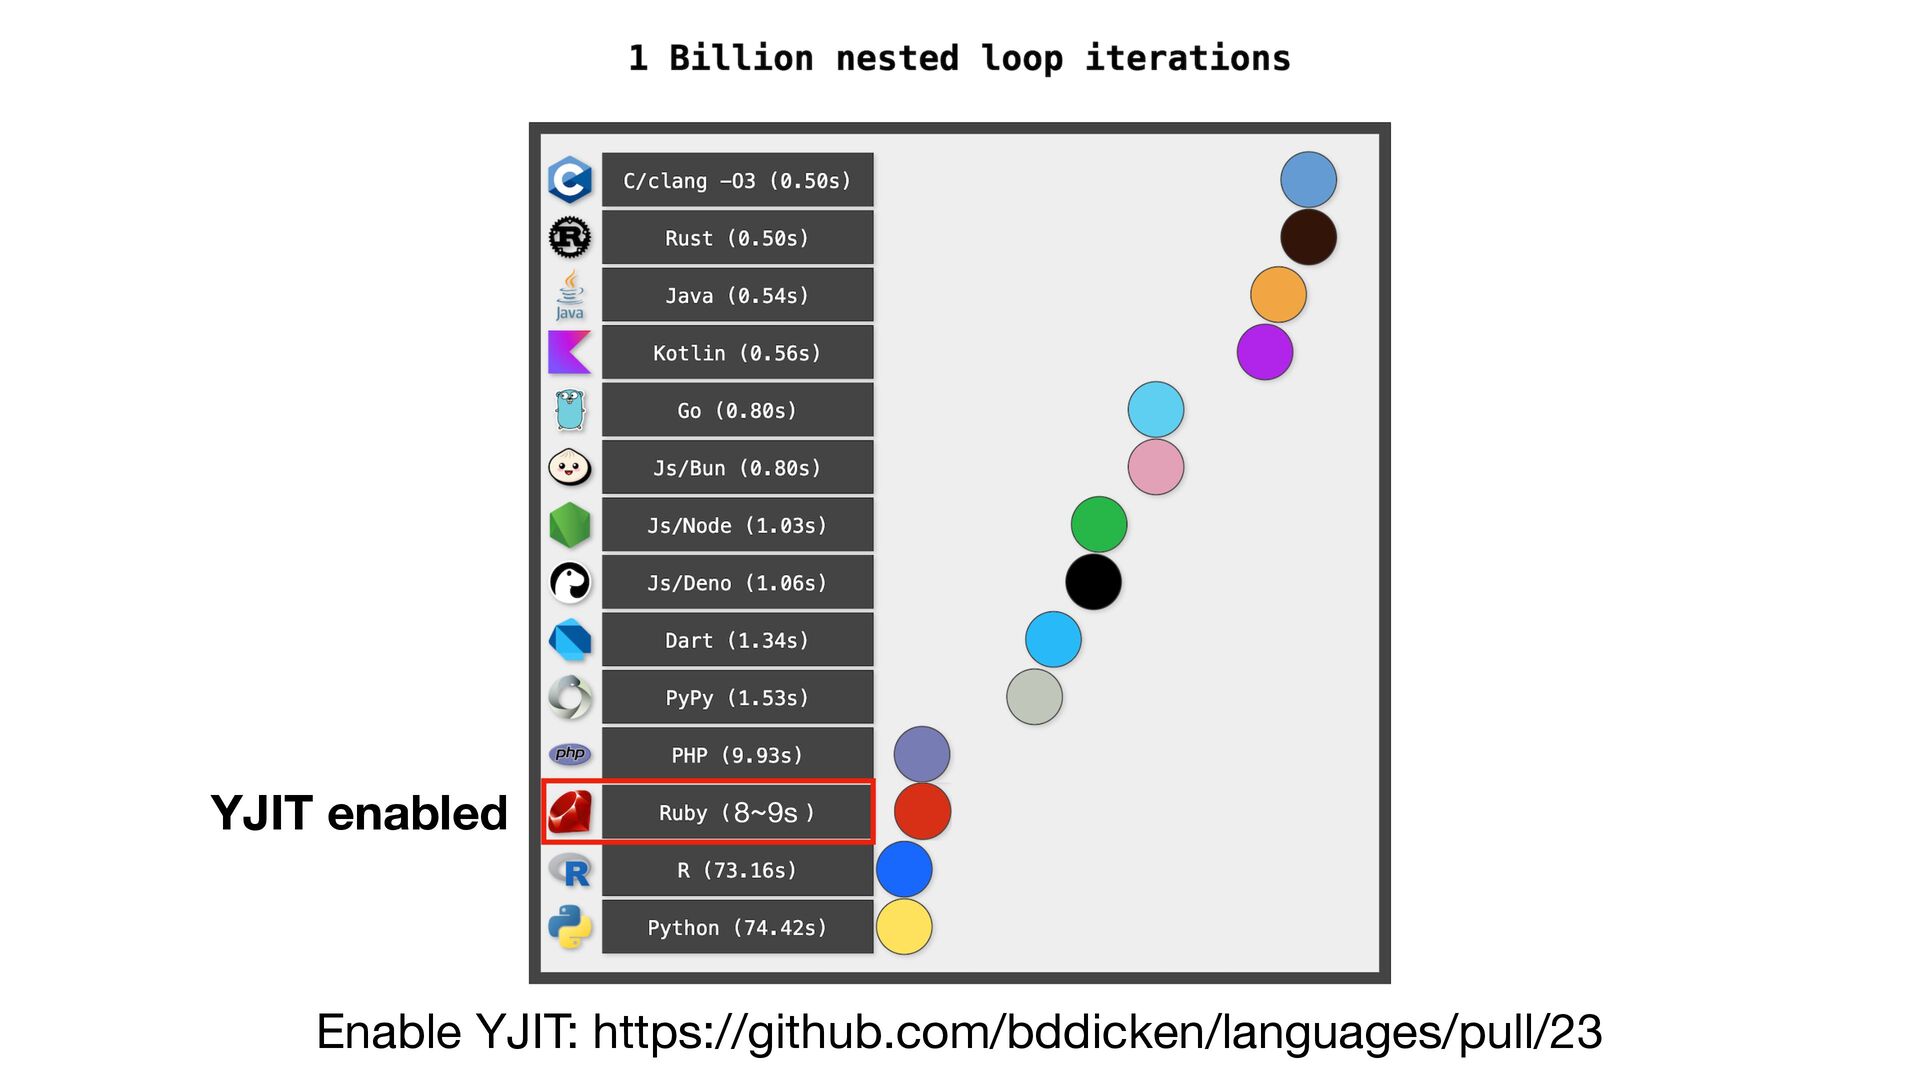
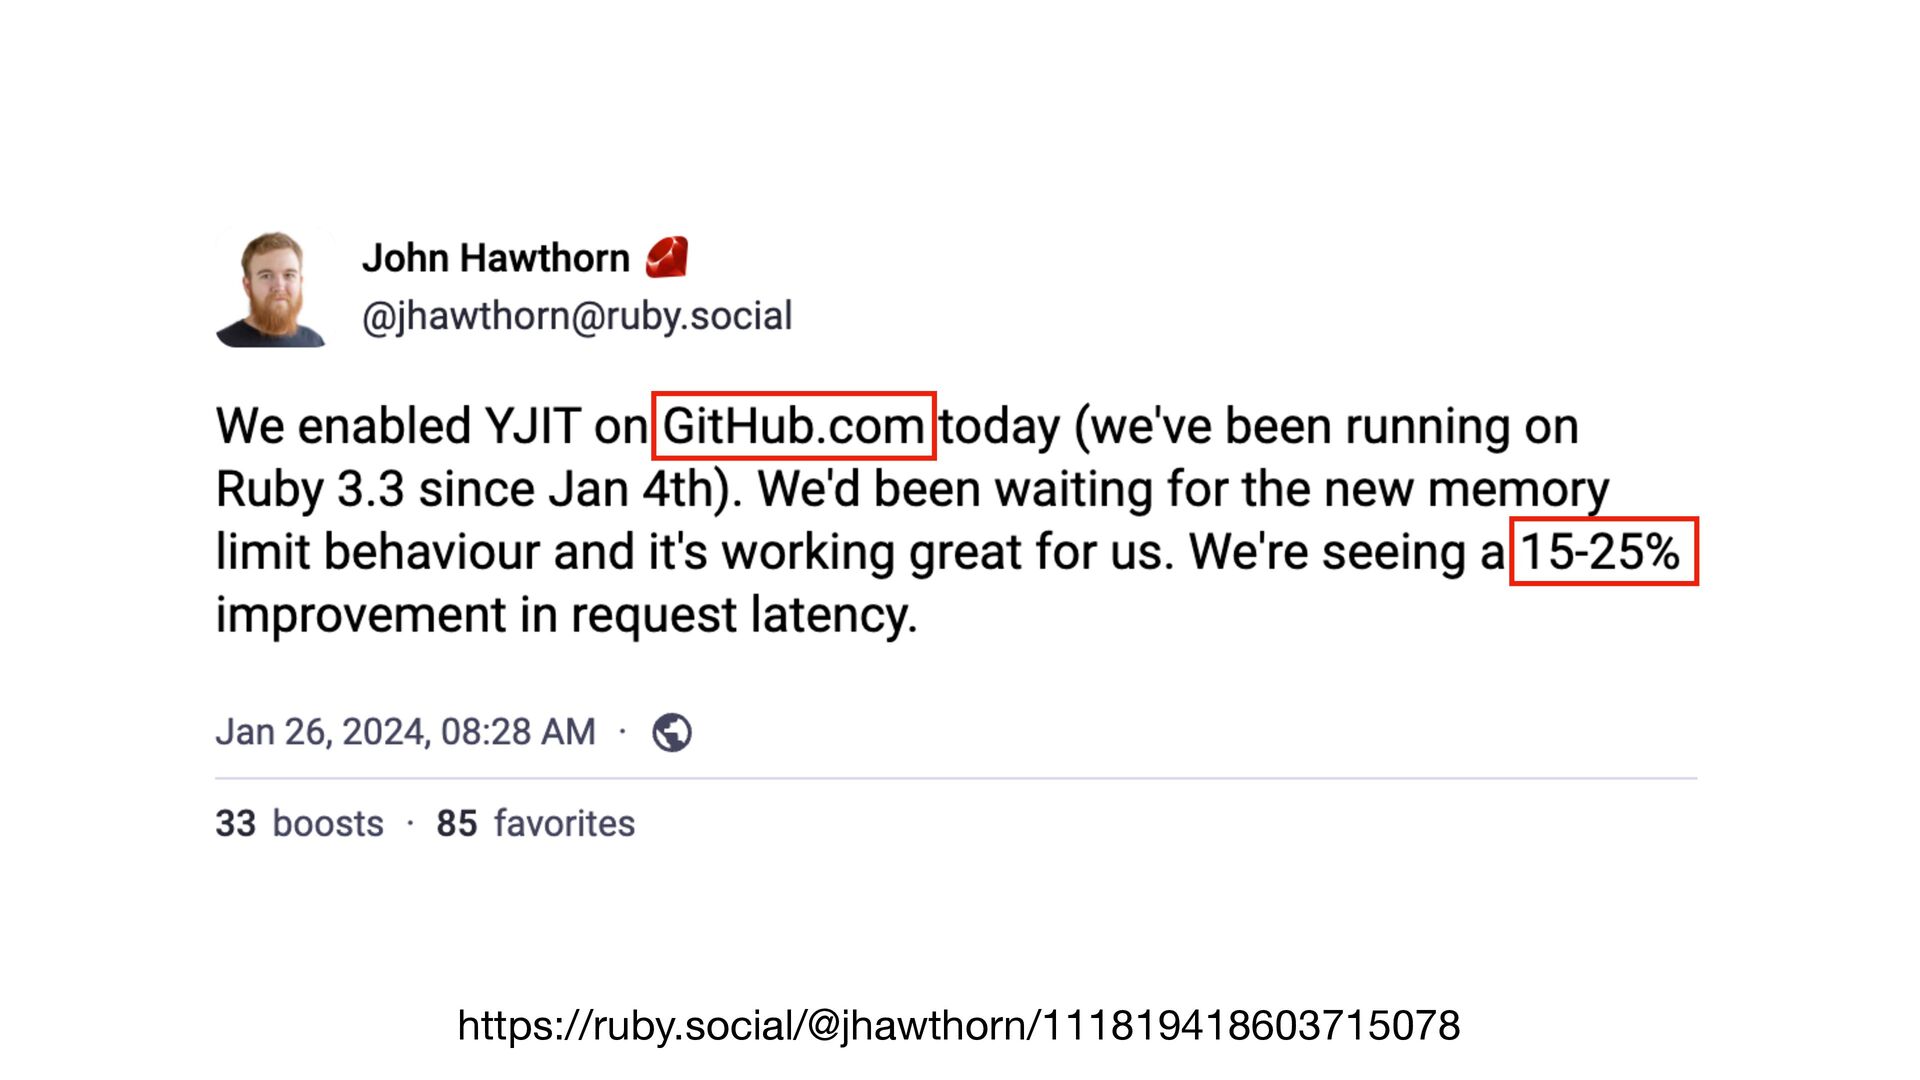
YJIT • Lazy Basic Block Versioning • Developed by Shopify
• Not enabled by default in Ruby, but it is in Rails • Bytecode → Low-level IR → Assembler (x86_64, arm64) Production-ready Ruby JIT -
ZJIT • Method JIT with SSA IR • Developed by
Shopify • Goal: Replace YJIT • Bytecode → High-level IR → Low-level IR → Assembler Next Generation Ruby JIT -
ZJIT • ZJIT development started in February • Passed the
CRuby test suite in September • Current status: Porting YJIT optimizations to ZJIT Disclaimer: Not ready for evaluation -
Why ZJIT? • Unblock cross-instruction optimizations • Less incremental, larger
compilation units • No memory overhead for adding optimizations Reasons why we changed the design -
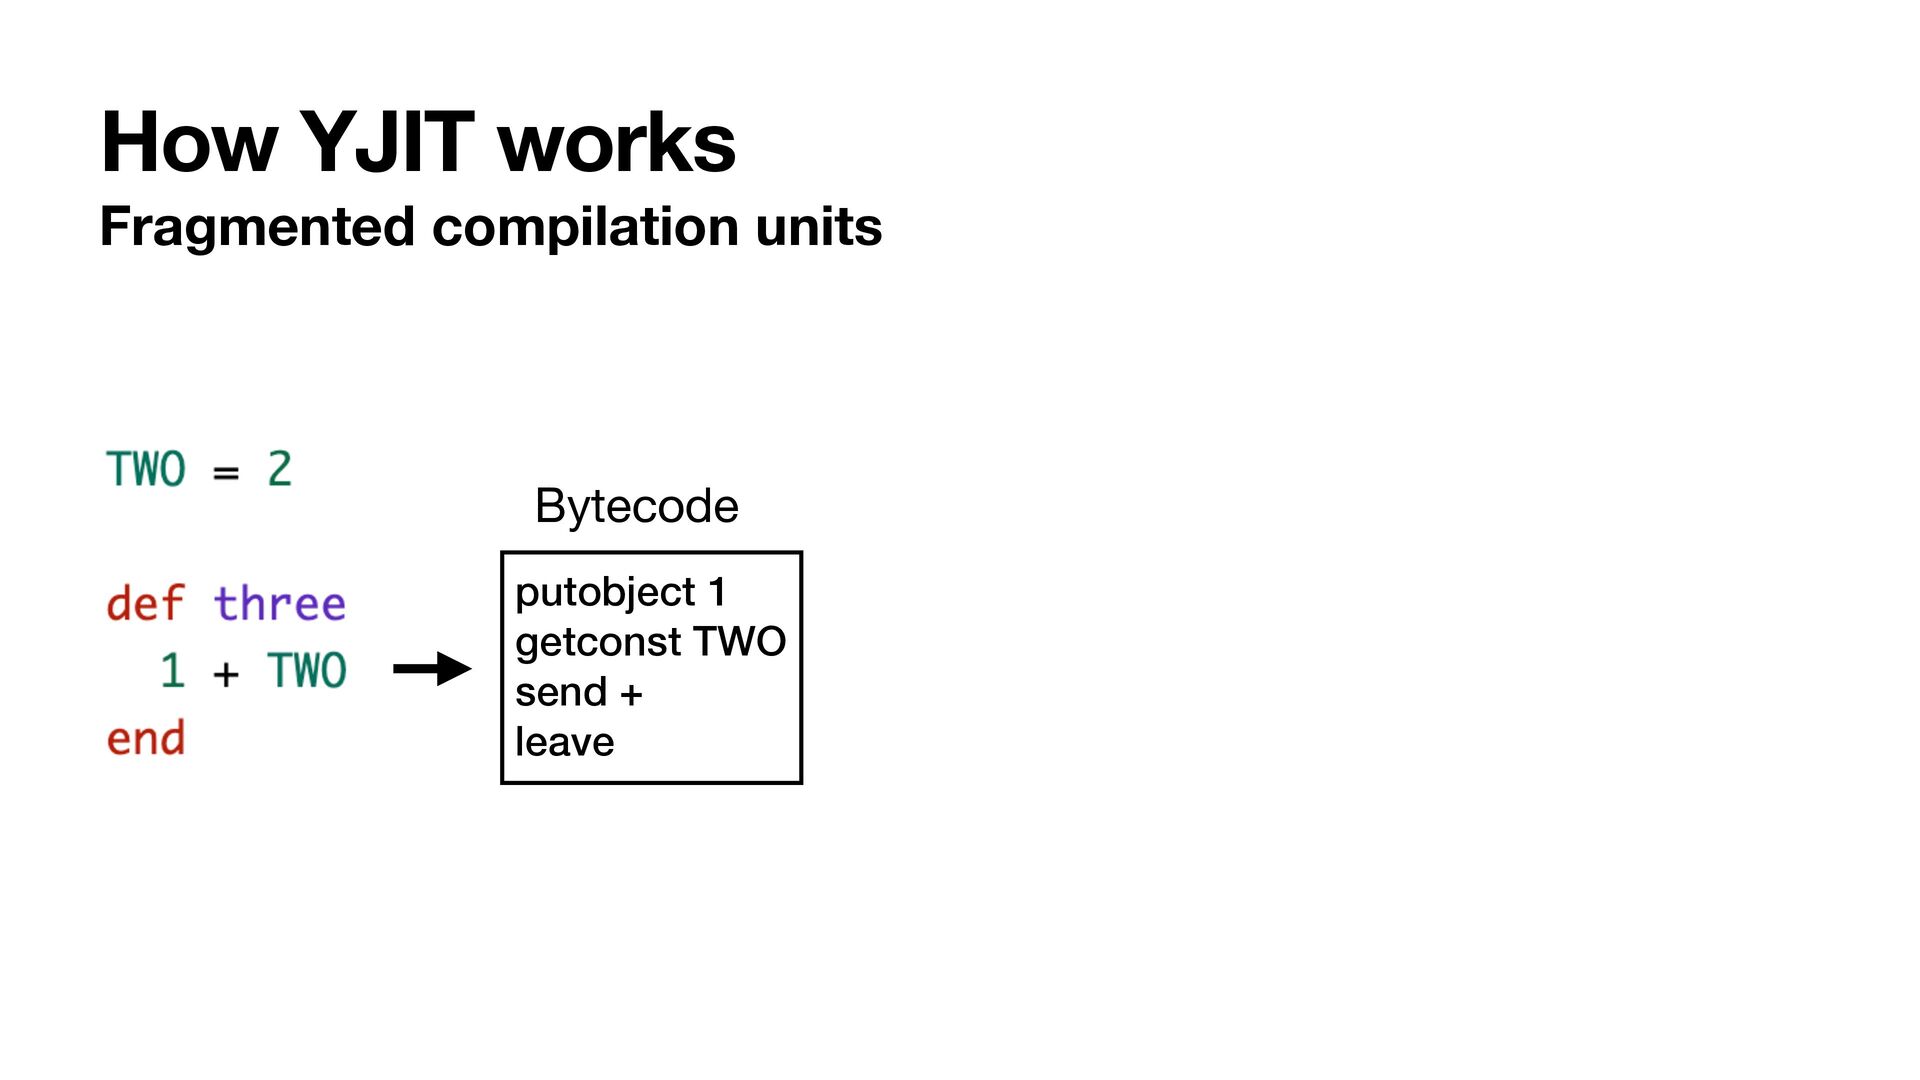
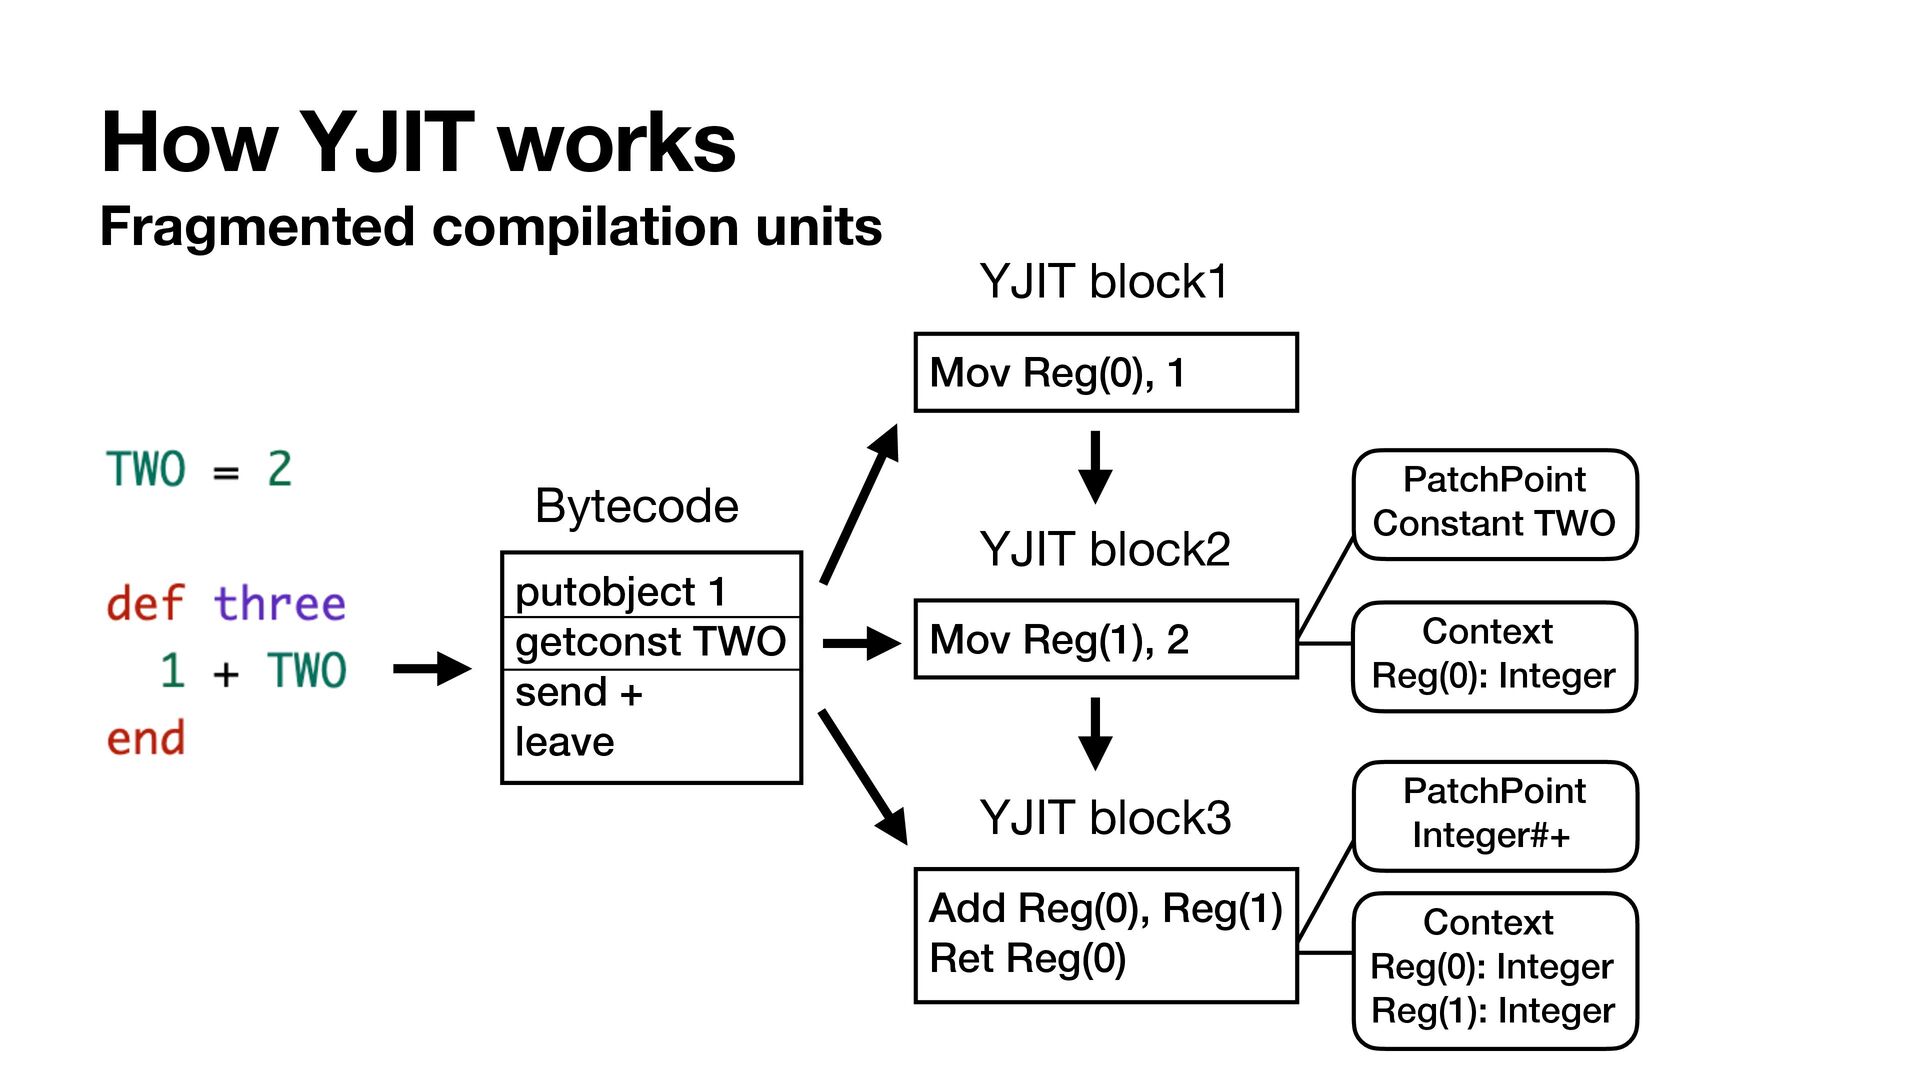
How YJIT works Fragmented compilation units putobject 1 getconst TWO
send + leave Bytecode -
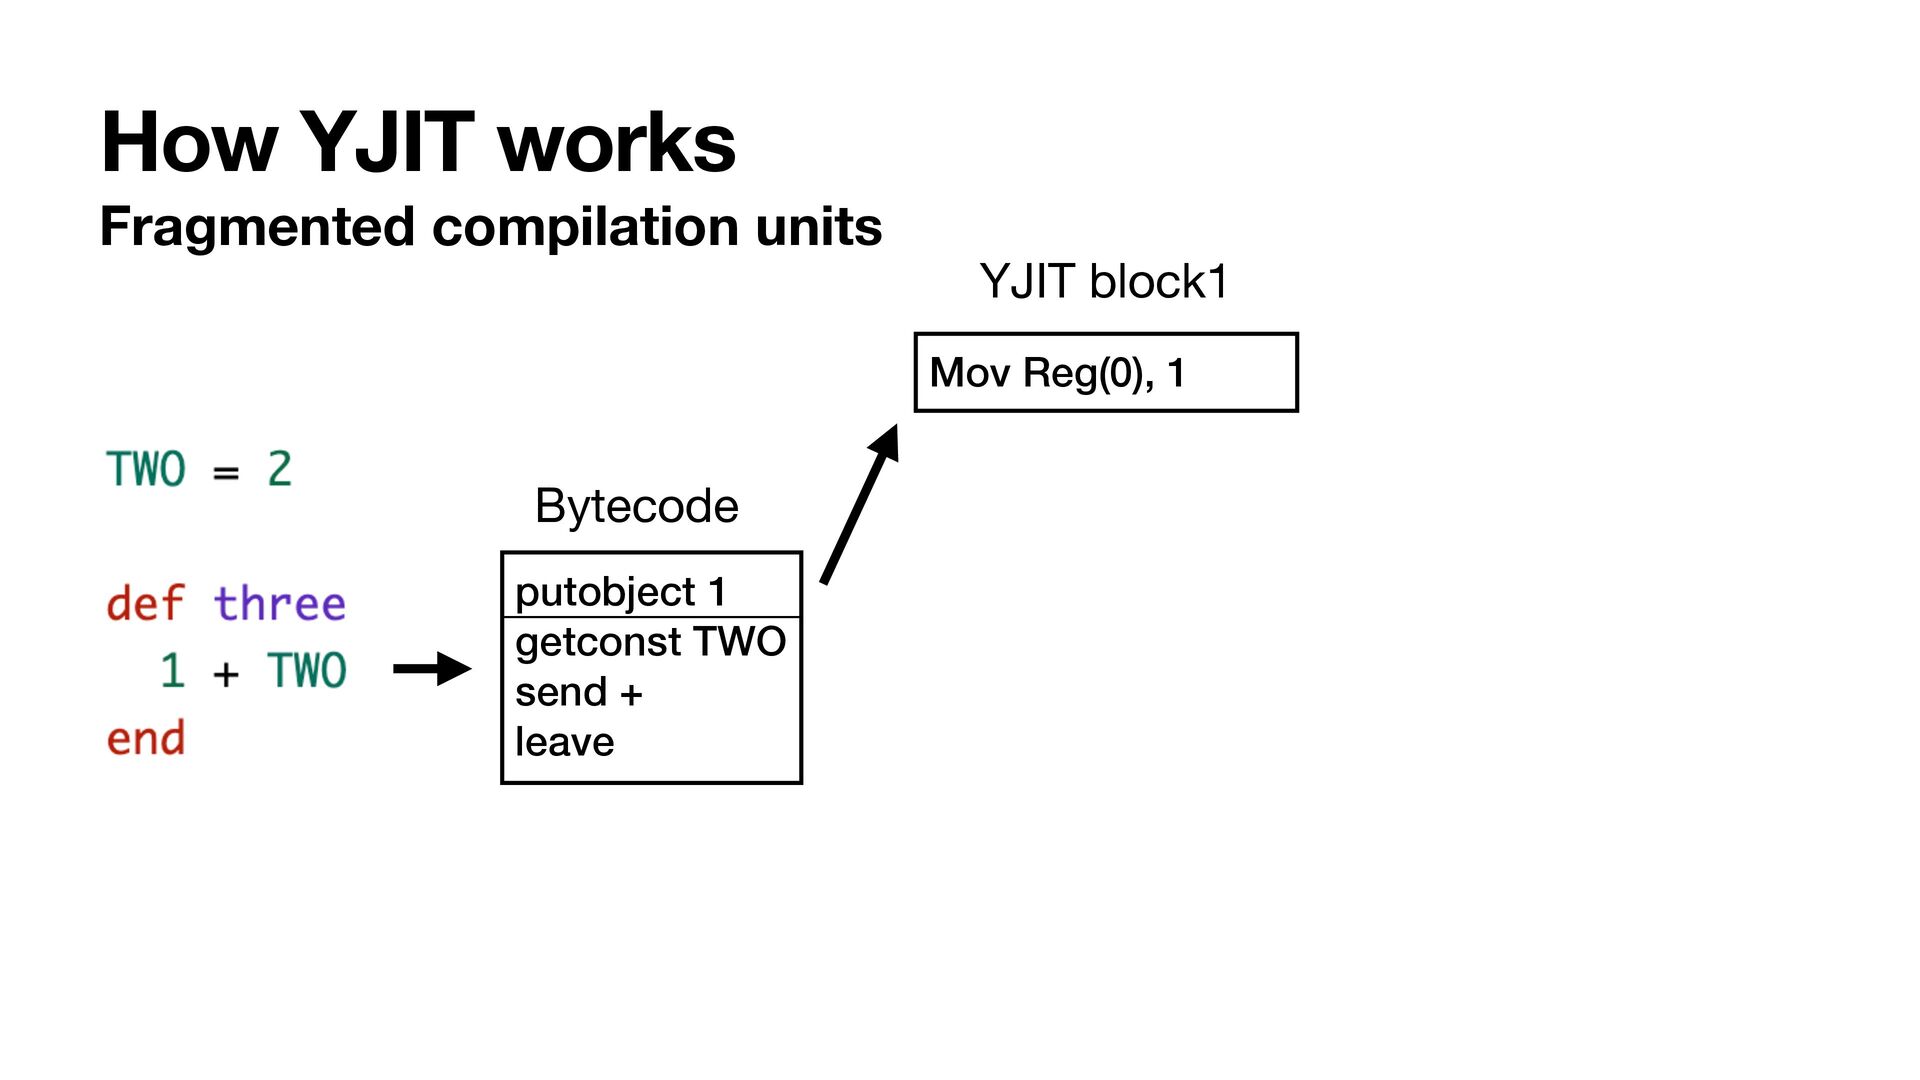
How YJIT works Fragmented compilation units putobject 1 getconst TWO
send + leave Bytecode YJIT block1 Mov Reg(0), 1 -
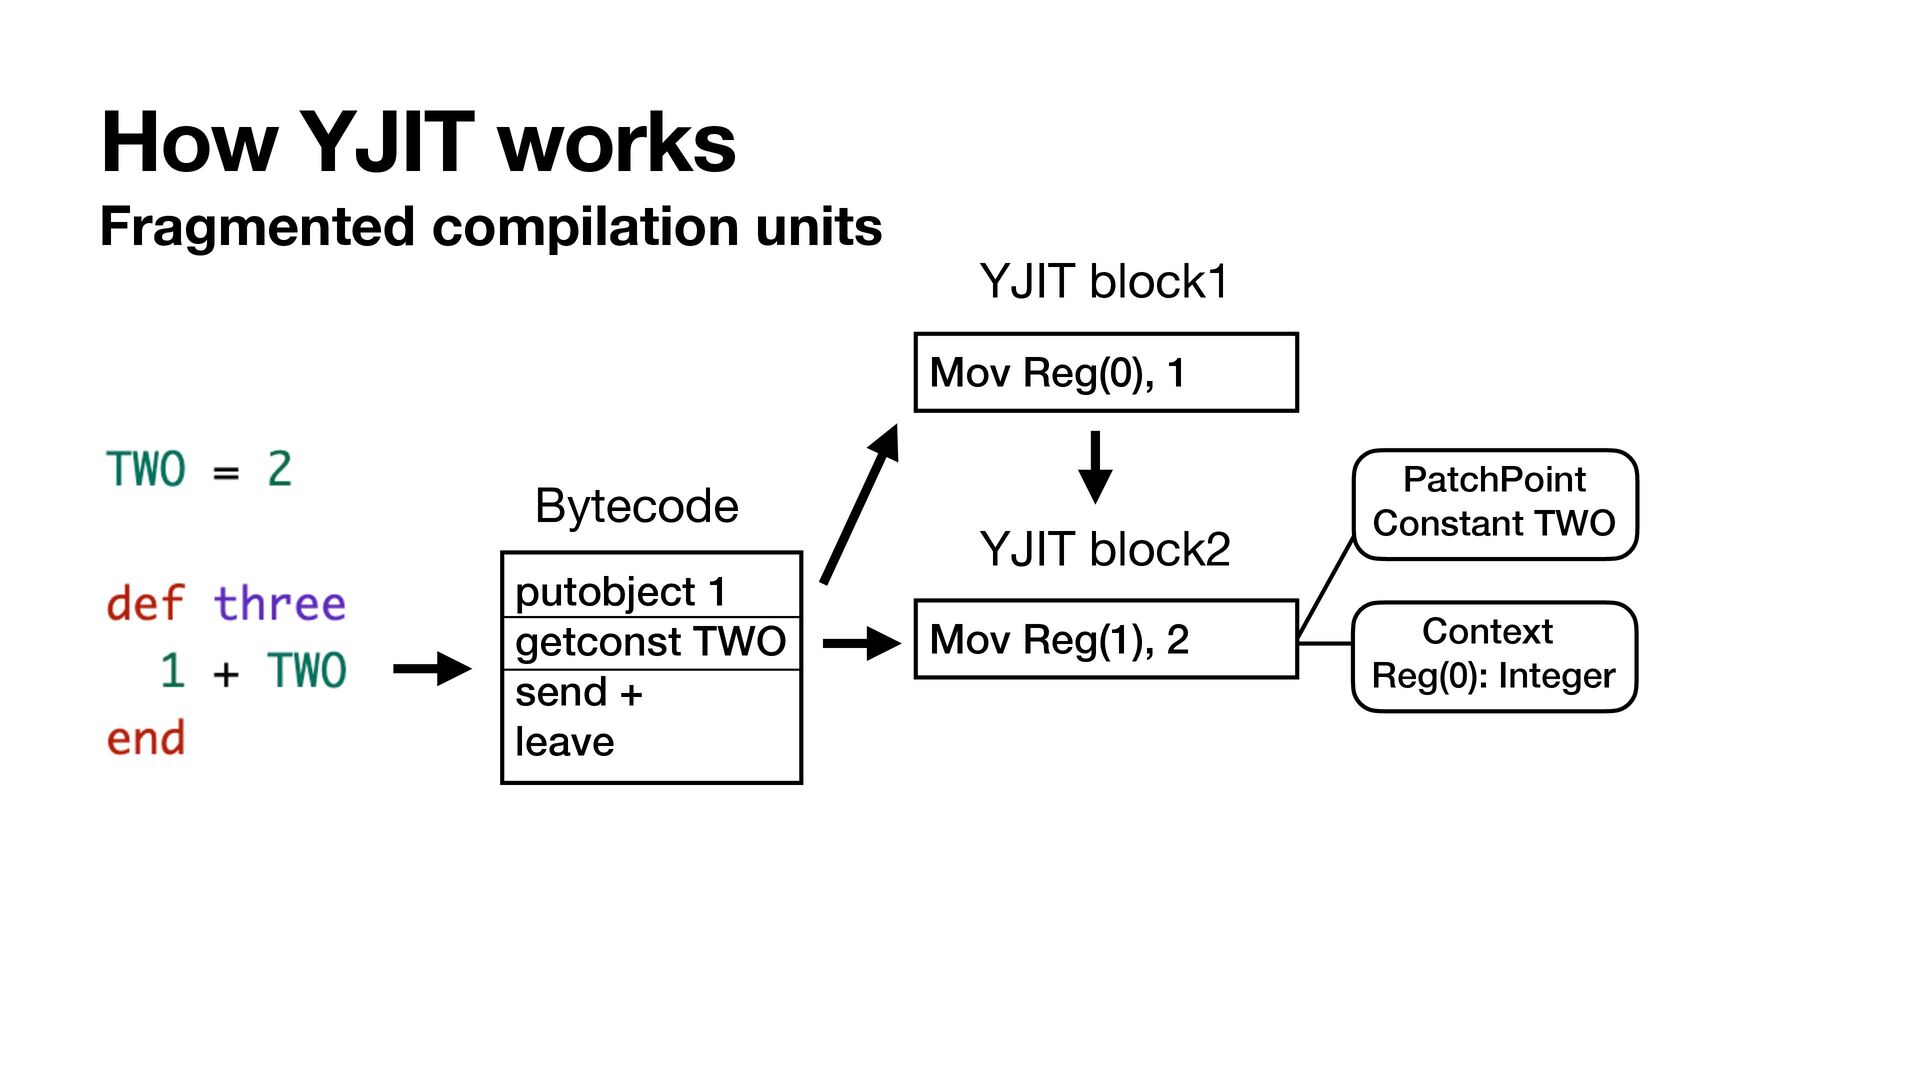
How YJIT works Fragmented compilation units putobject 1 getconst TWO
send + leave Bytecode YJIT block1 Mov Reg(0), 1 Context Reg(0): Integer YJIT block2 Mov Reg(1), 2 PatchPoint Constant TWO -
How YJIT works Fragmented compilation units putobject 1 getconst TWO
send + leave Bytecode YJIT block1 Mov Reg(0), 1 Context Reg(0): Integer YJIT block2 YJIT block3 Mov Reg(1), 2 PatchPoint Constant TWO Context Reg(0): Integer Reg(1): Integer PatchPoint Integer#+ Add Reg(0), Reg(1) Ret Reg(0) -
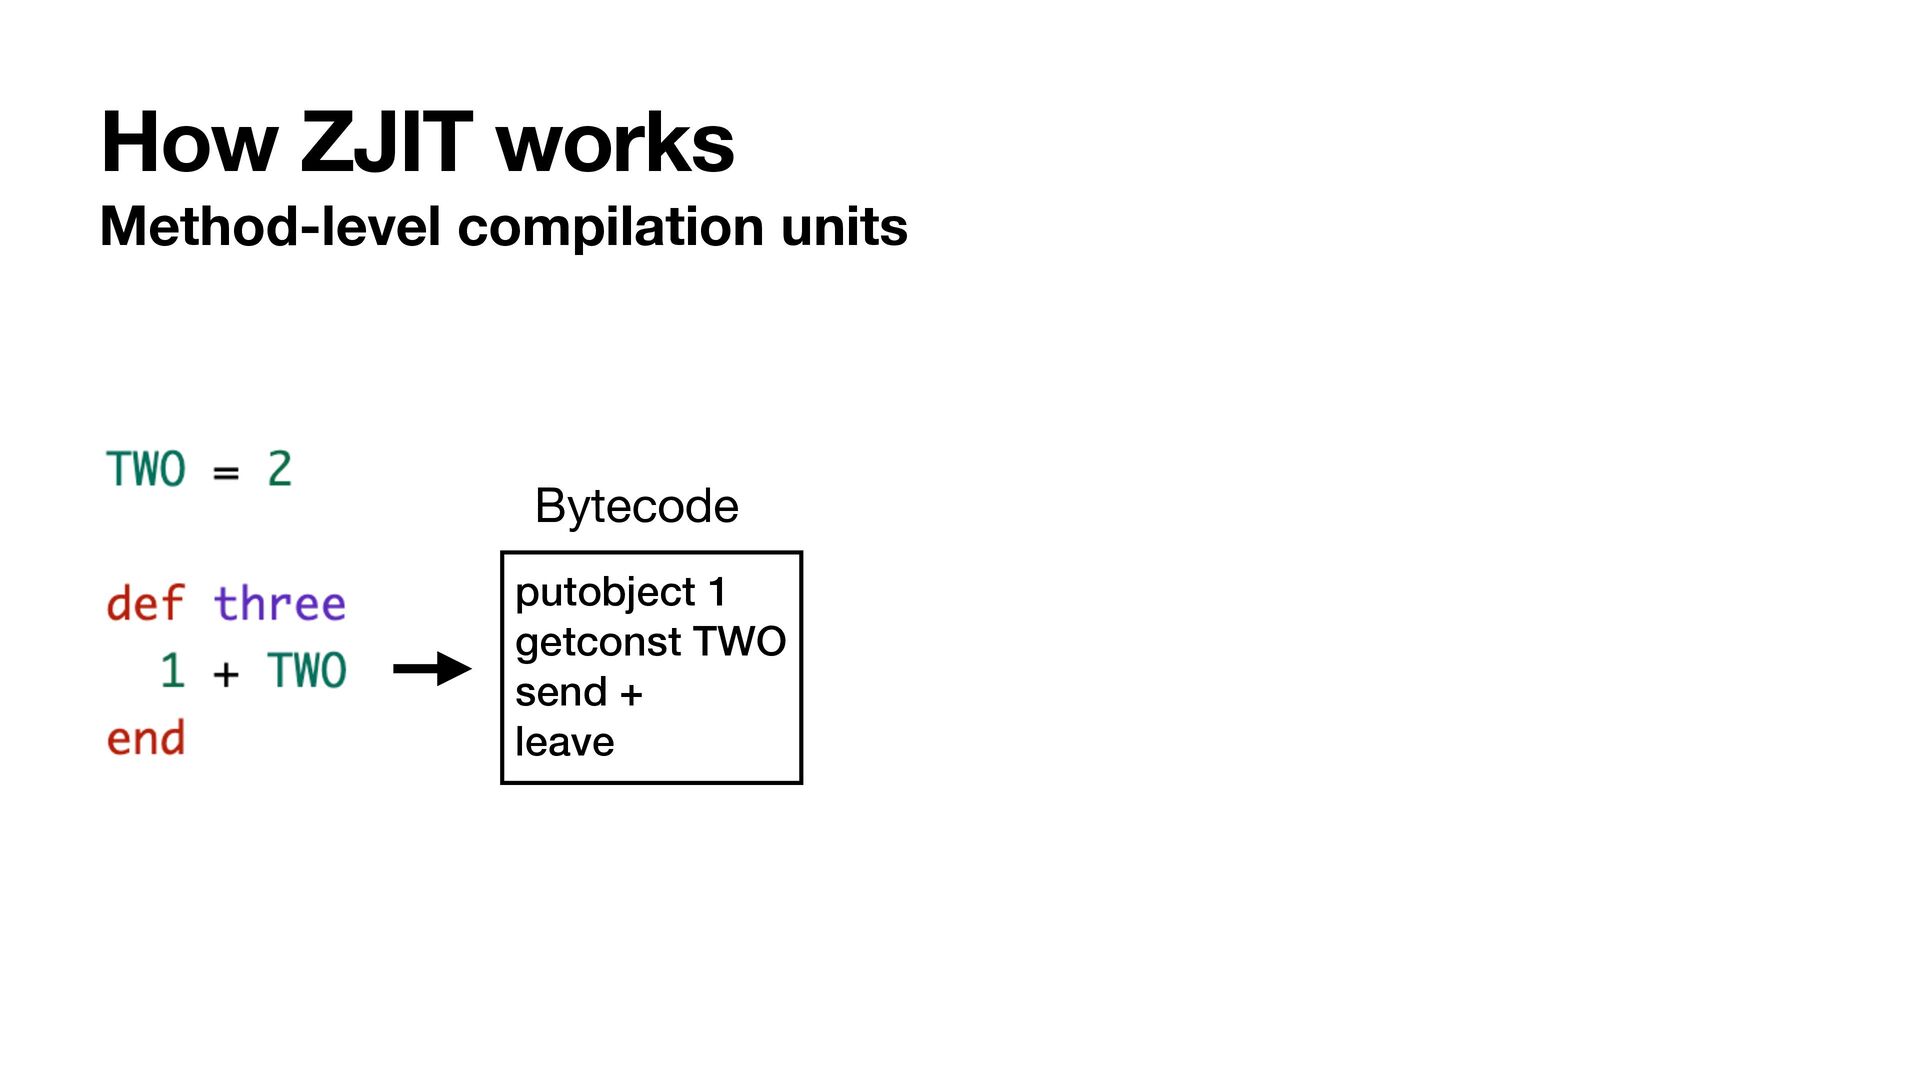
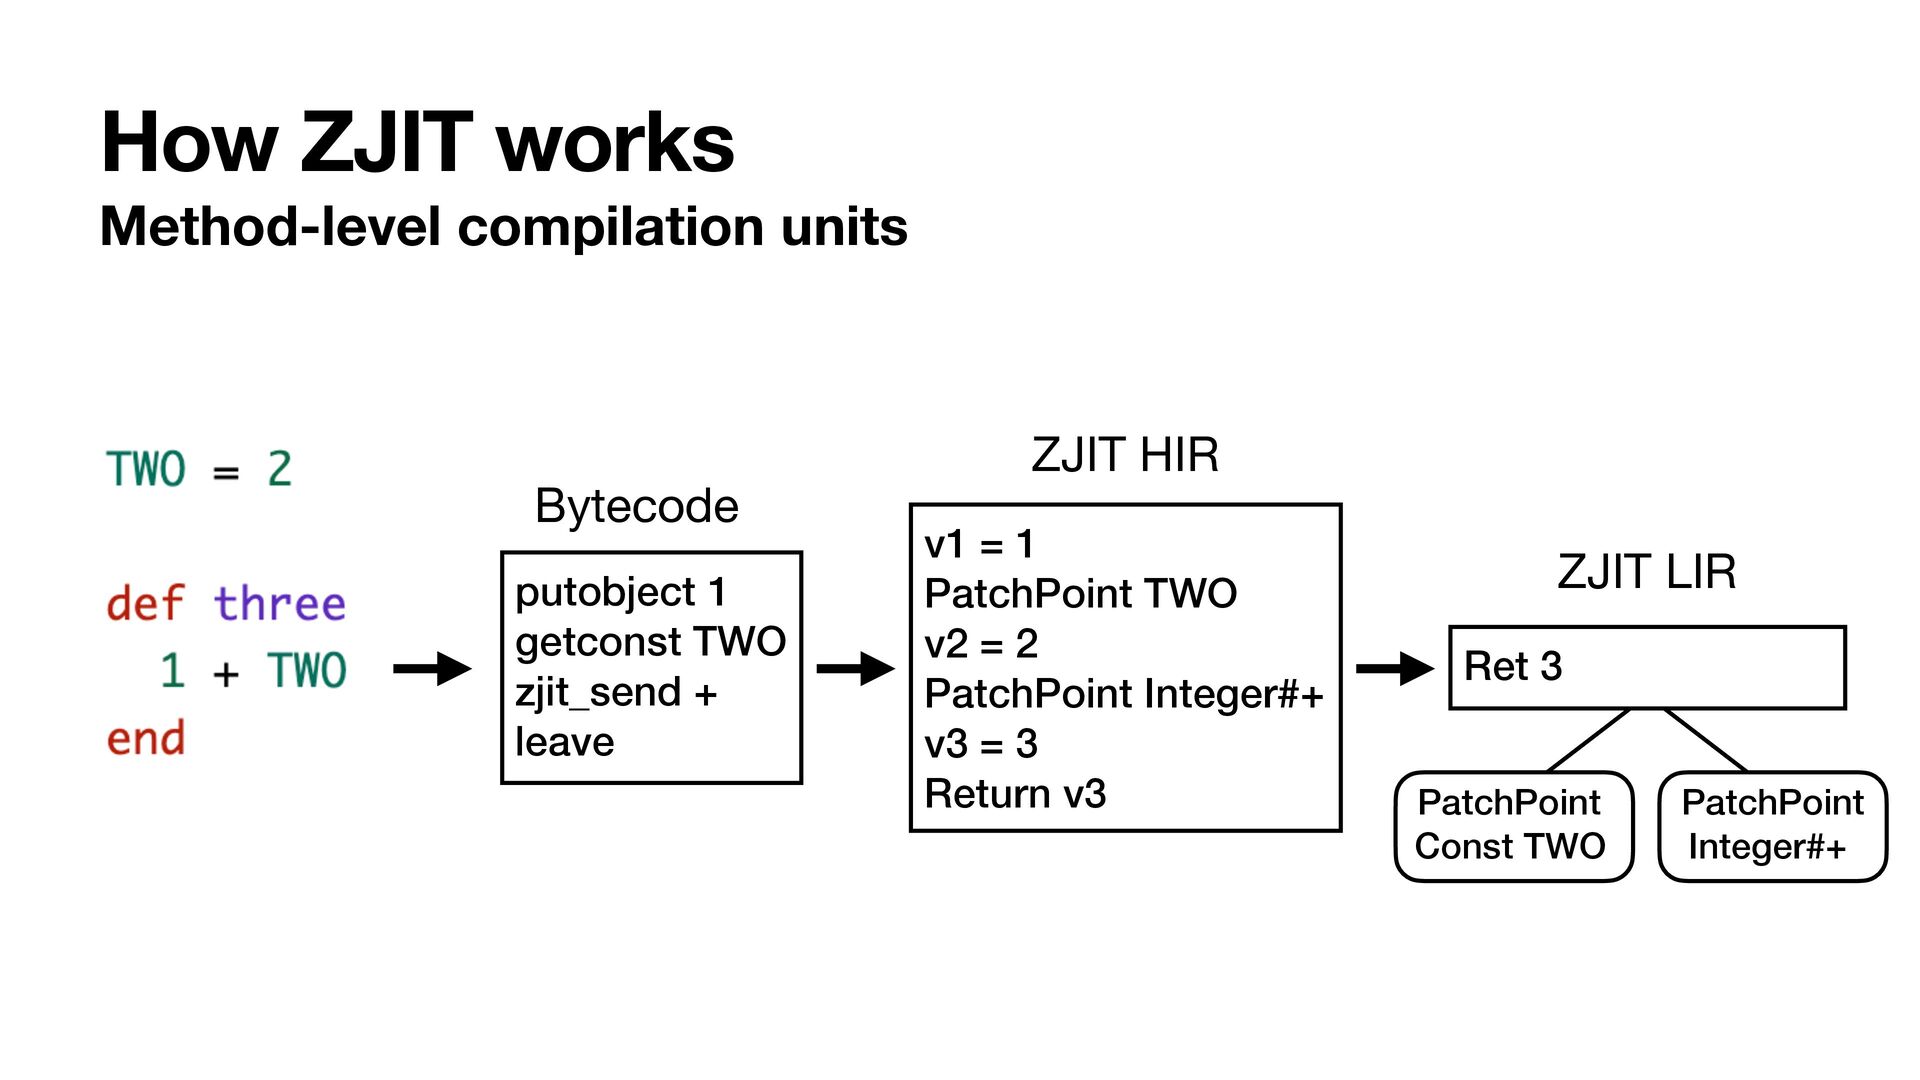
How ZJIT works Method-level compilation units putobject 1 getconst TWO
send + leave Bytecode -
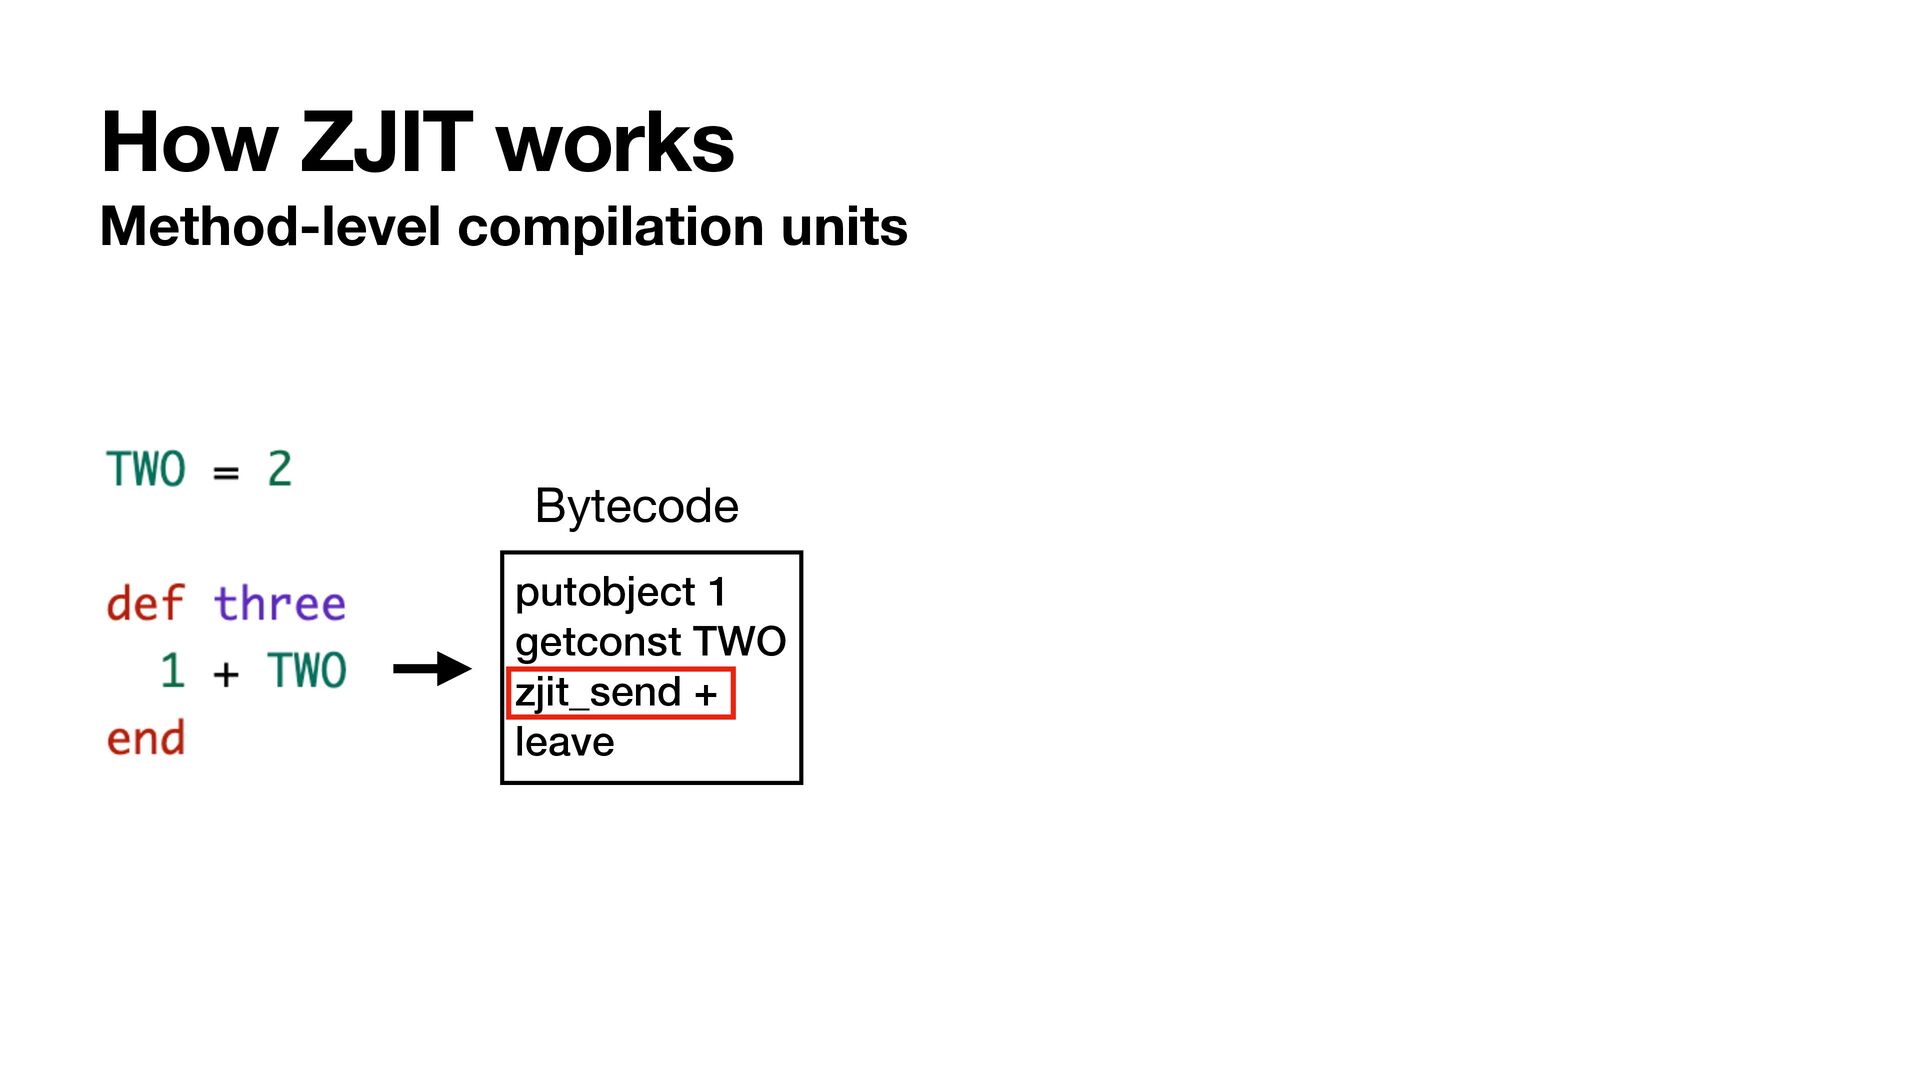
How ZJIT works Method-level compilation units putobject 1 getconst TWO
zjit_send + leave Bytecode -
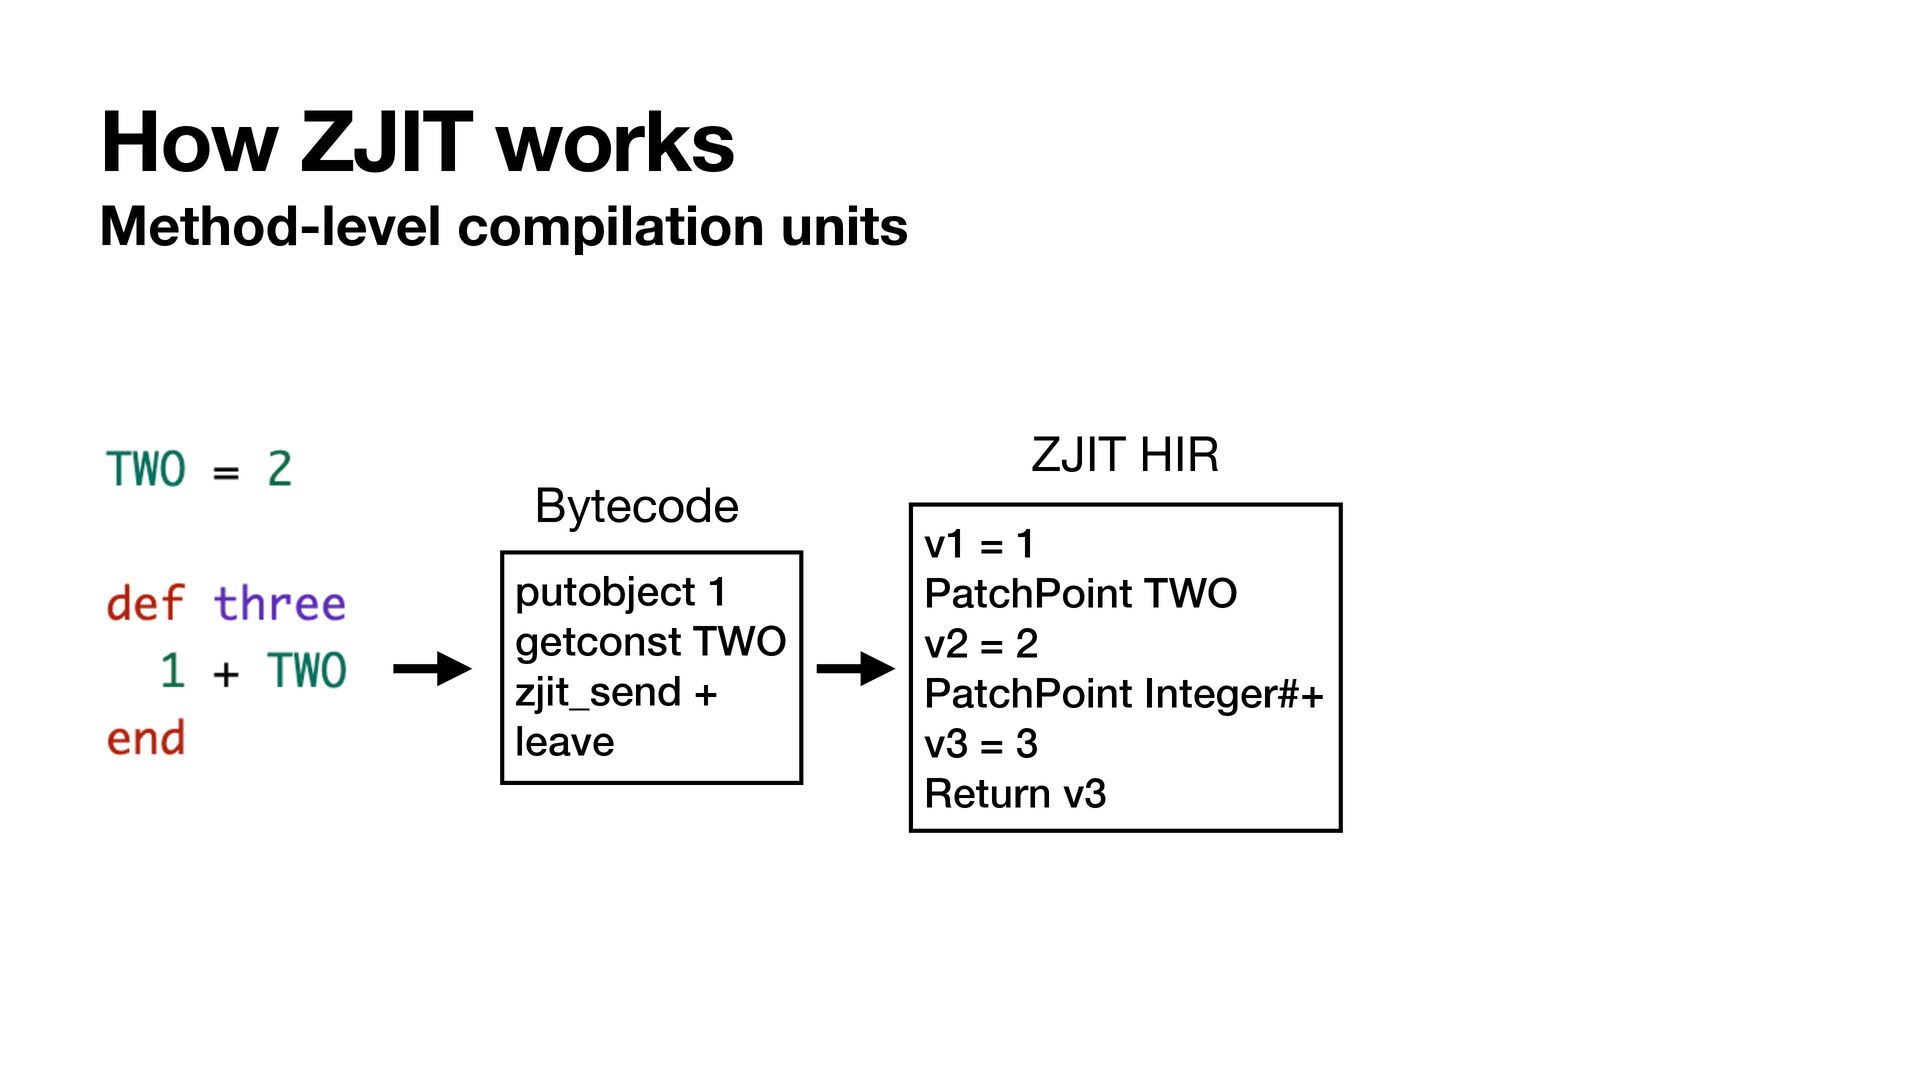
How ZJIT works Method-level compilation units putobject 1 getconst TWO
zjit_send + leave Bytecode ZJIT HIR v1 = 1 PatchPoint TWO v2 = 2 PatchPoint Integer#+ v3 = 3 Return v3 -
How ZJIT works Method-level compilation units putobject 1 getconst TWO
zjit_send + leave Bytecode ZJIT HIR v1 = 1 PatchPoint TWO v2 = 2 PatchPoint Integer#+ v3 = 3 Return v3 ZJIT LIR Ret 3 PatchPoint Const TWO PatchPoint Integer#+ -
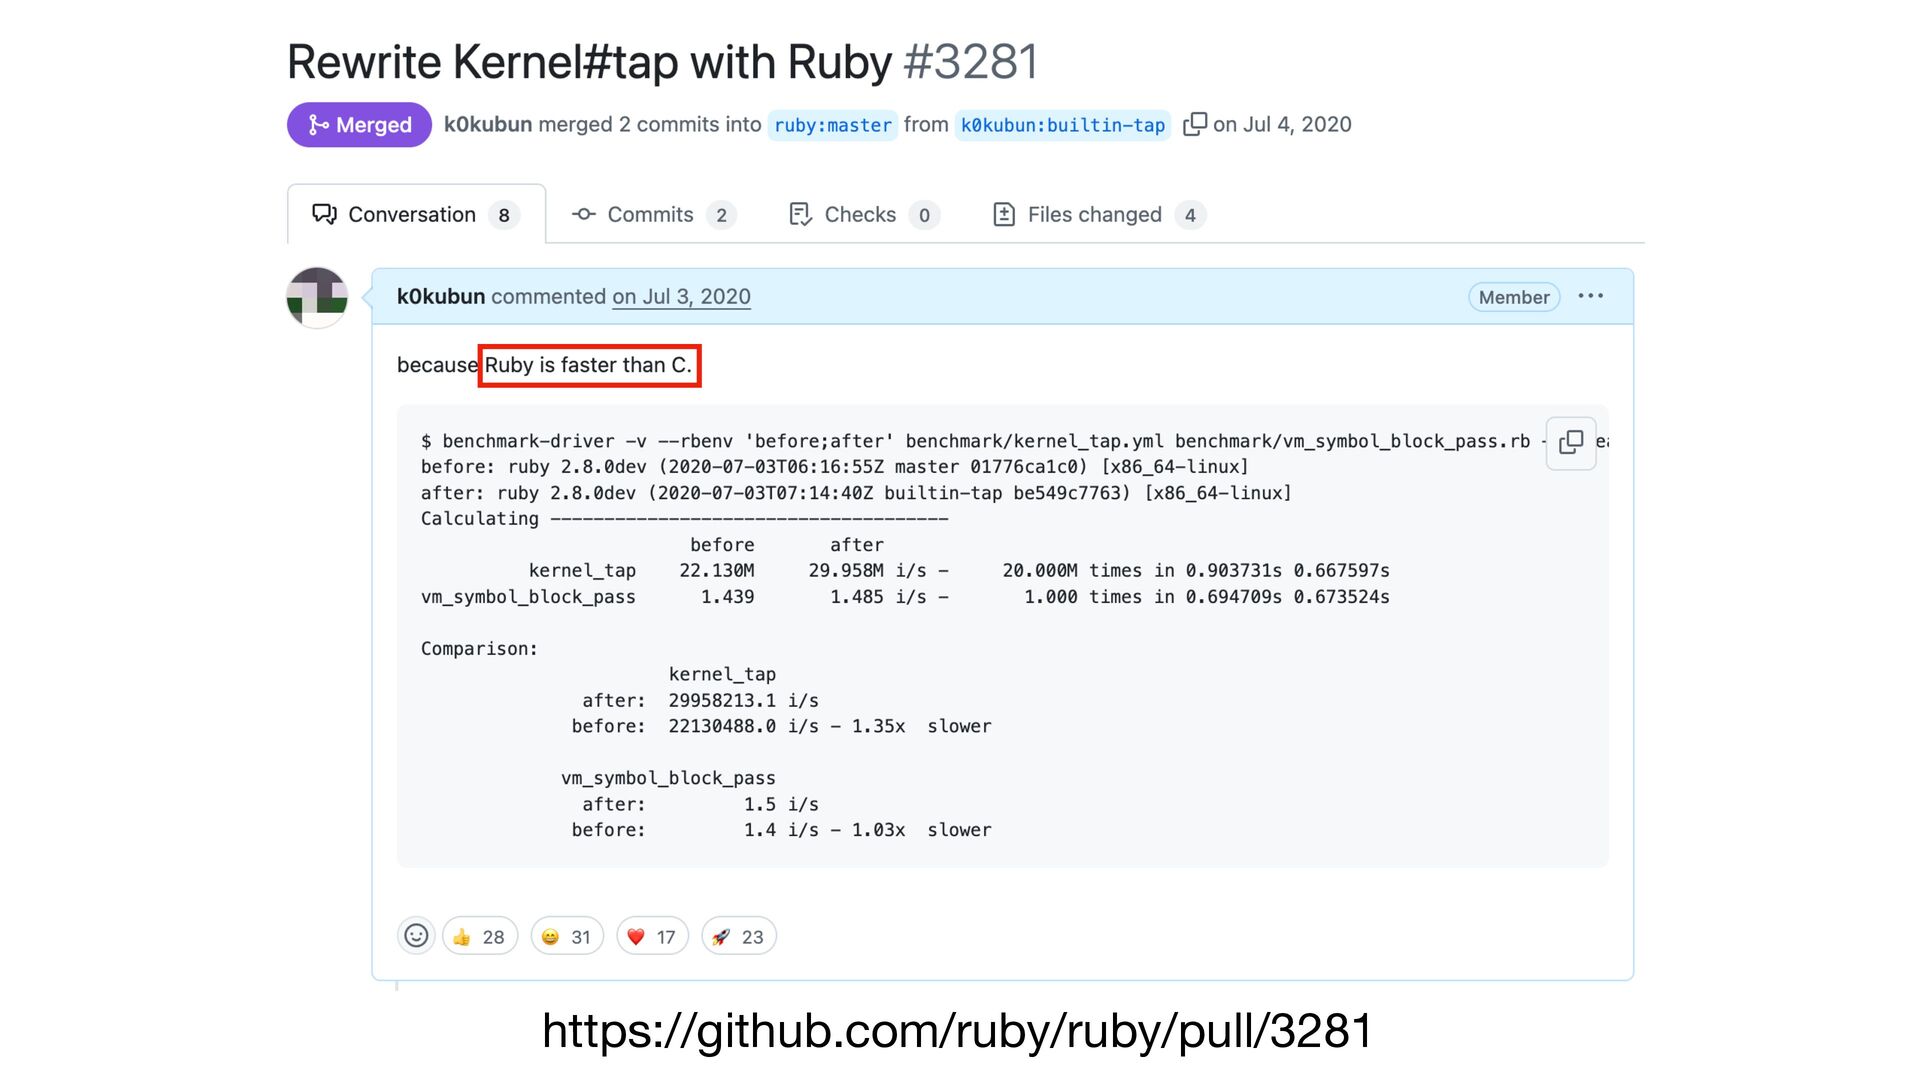
Challenges • C functions dominate execution time • Local variables
are too dynamic • Method calls are too slow What’s hard about optimizing Ruby? -
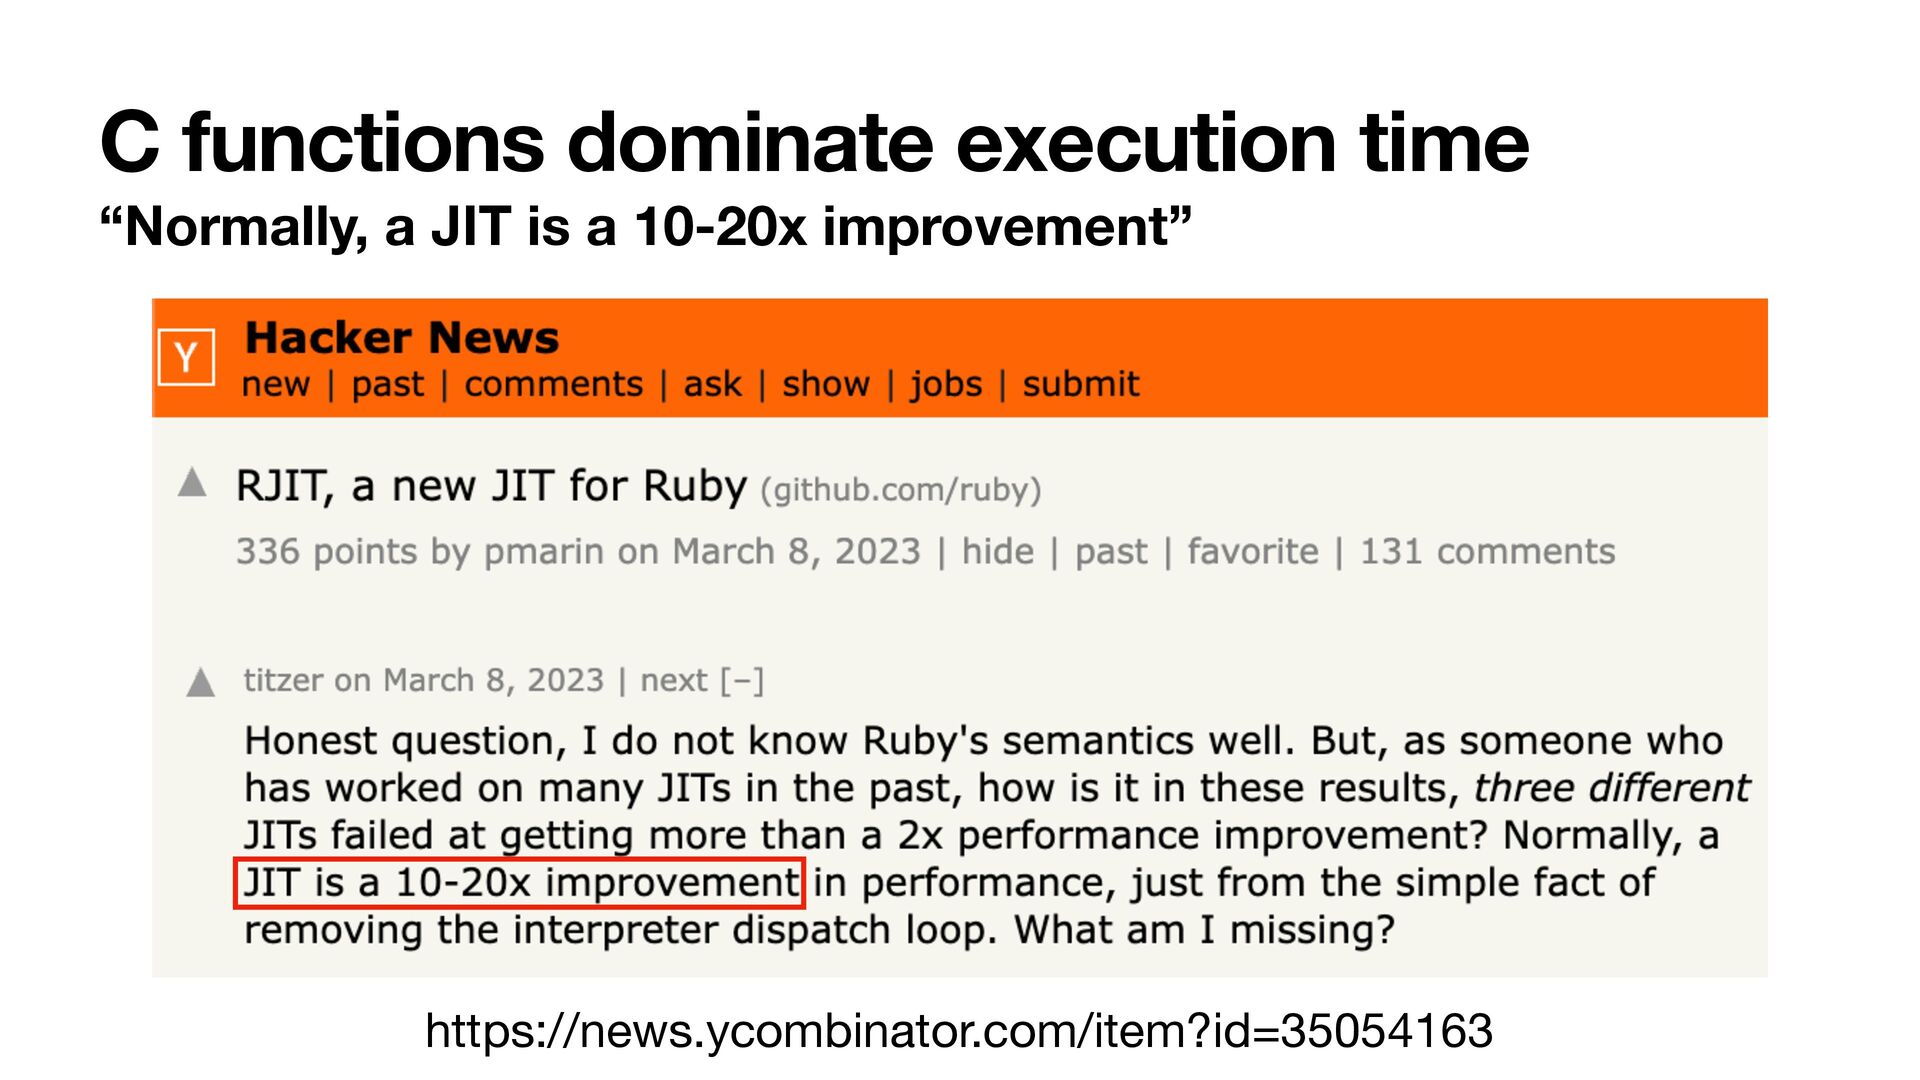
C functions dominate execution time “Normally, a JIT is a
10-20x improvement” https://news.ycombinator.com/item?id=35054163 -
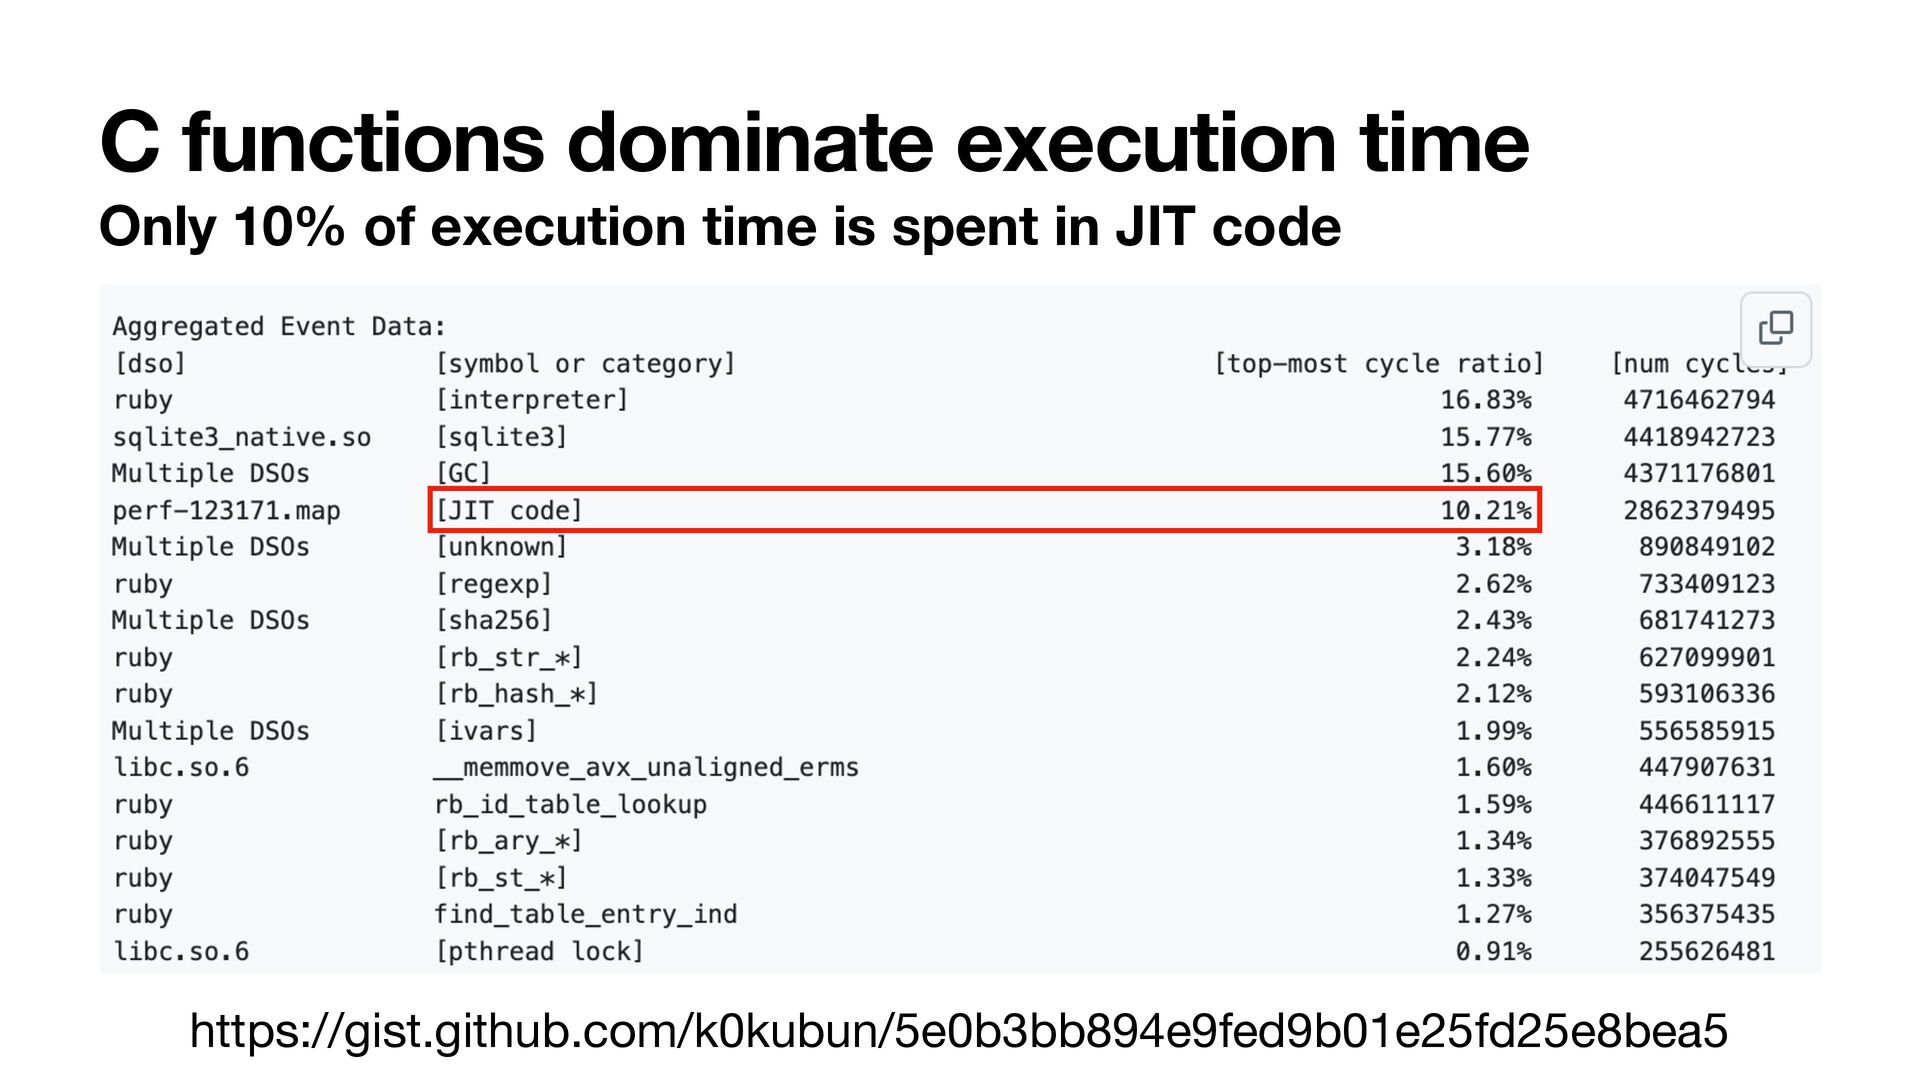
C functions dominate execution time Only 10% of execution time
is spent in JIT code https://gist.github.com/k0kubun/5e0b3bb894e9fed9b01e25fd25e8bea5 -
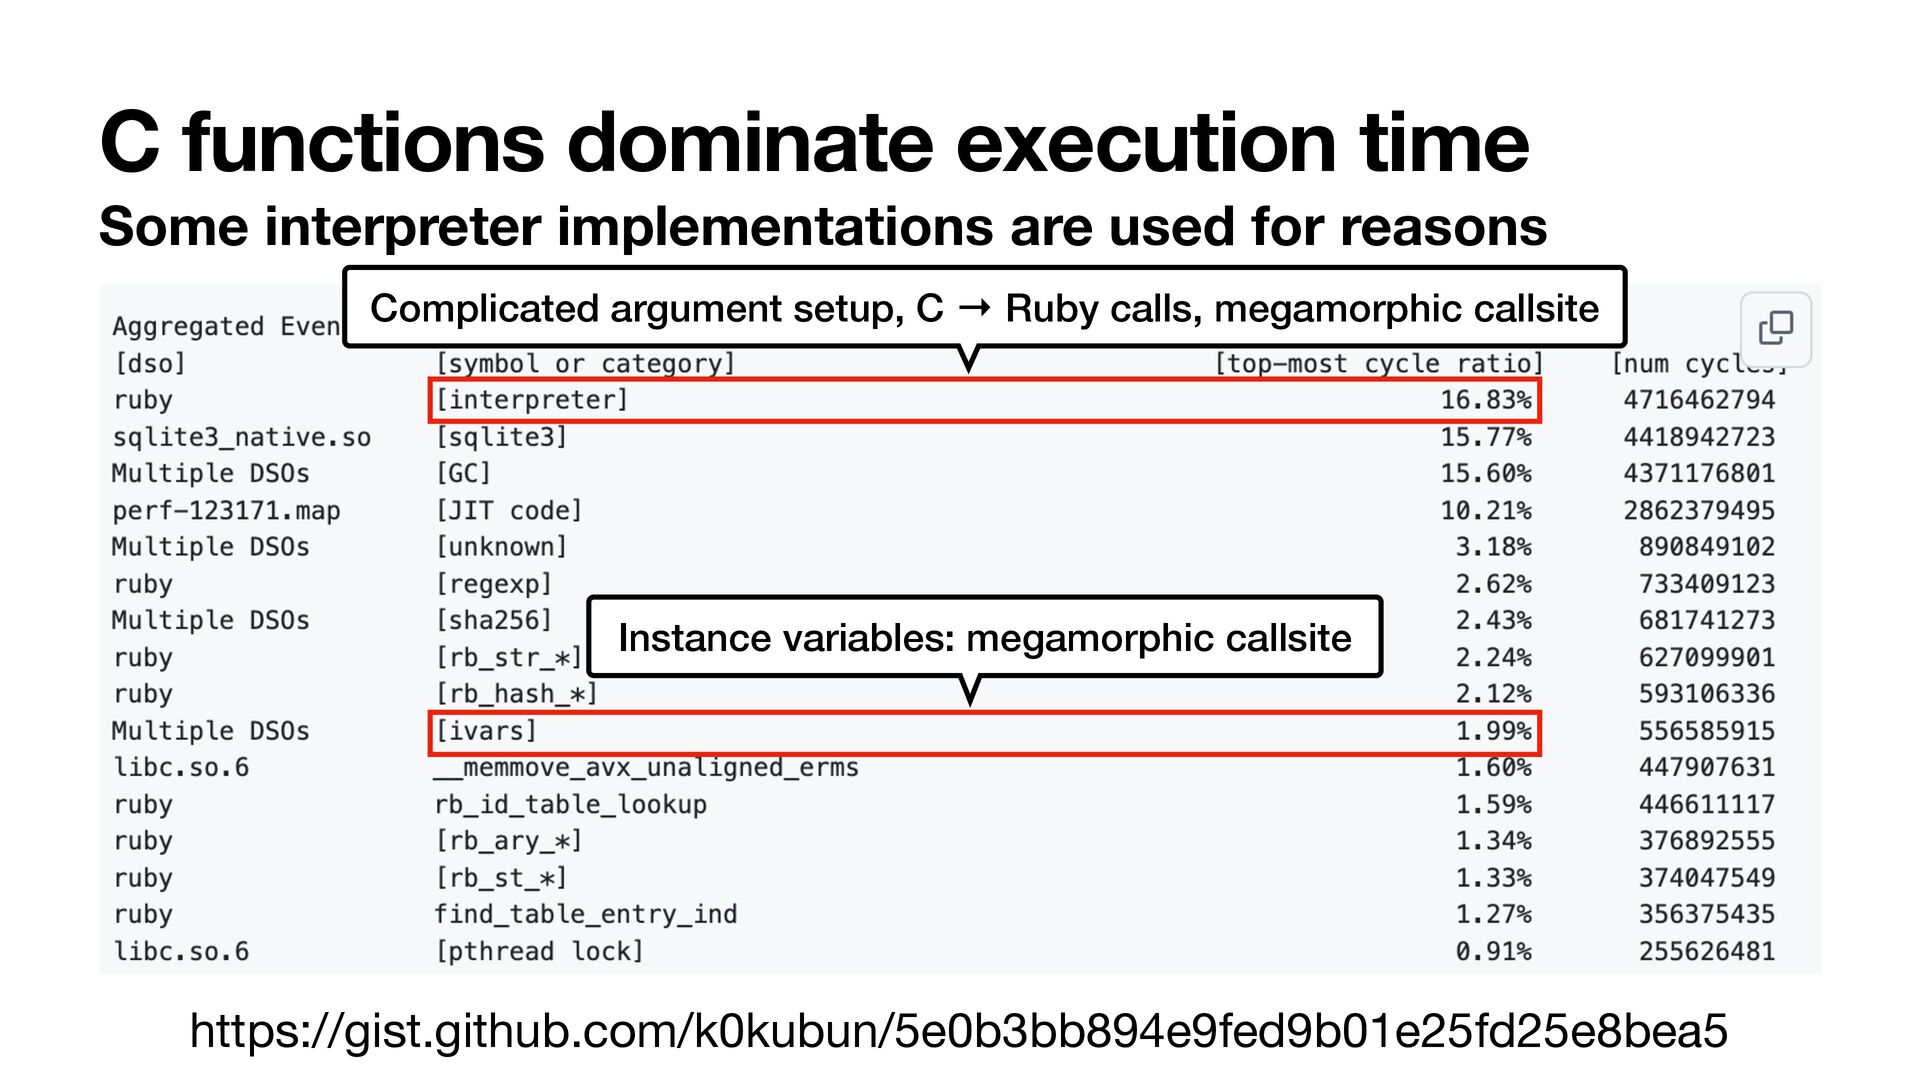
C functions dominate execution time Some interpreter implementations are used
for reasons https://gist.github.com/k0kubun/5e0b3bb894e9fed9b01e25fd25e8bea5 Complicated argument setup, C → Ruby calls, megamorphic callsite Instance variables: megamorphic callsite -
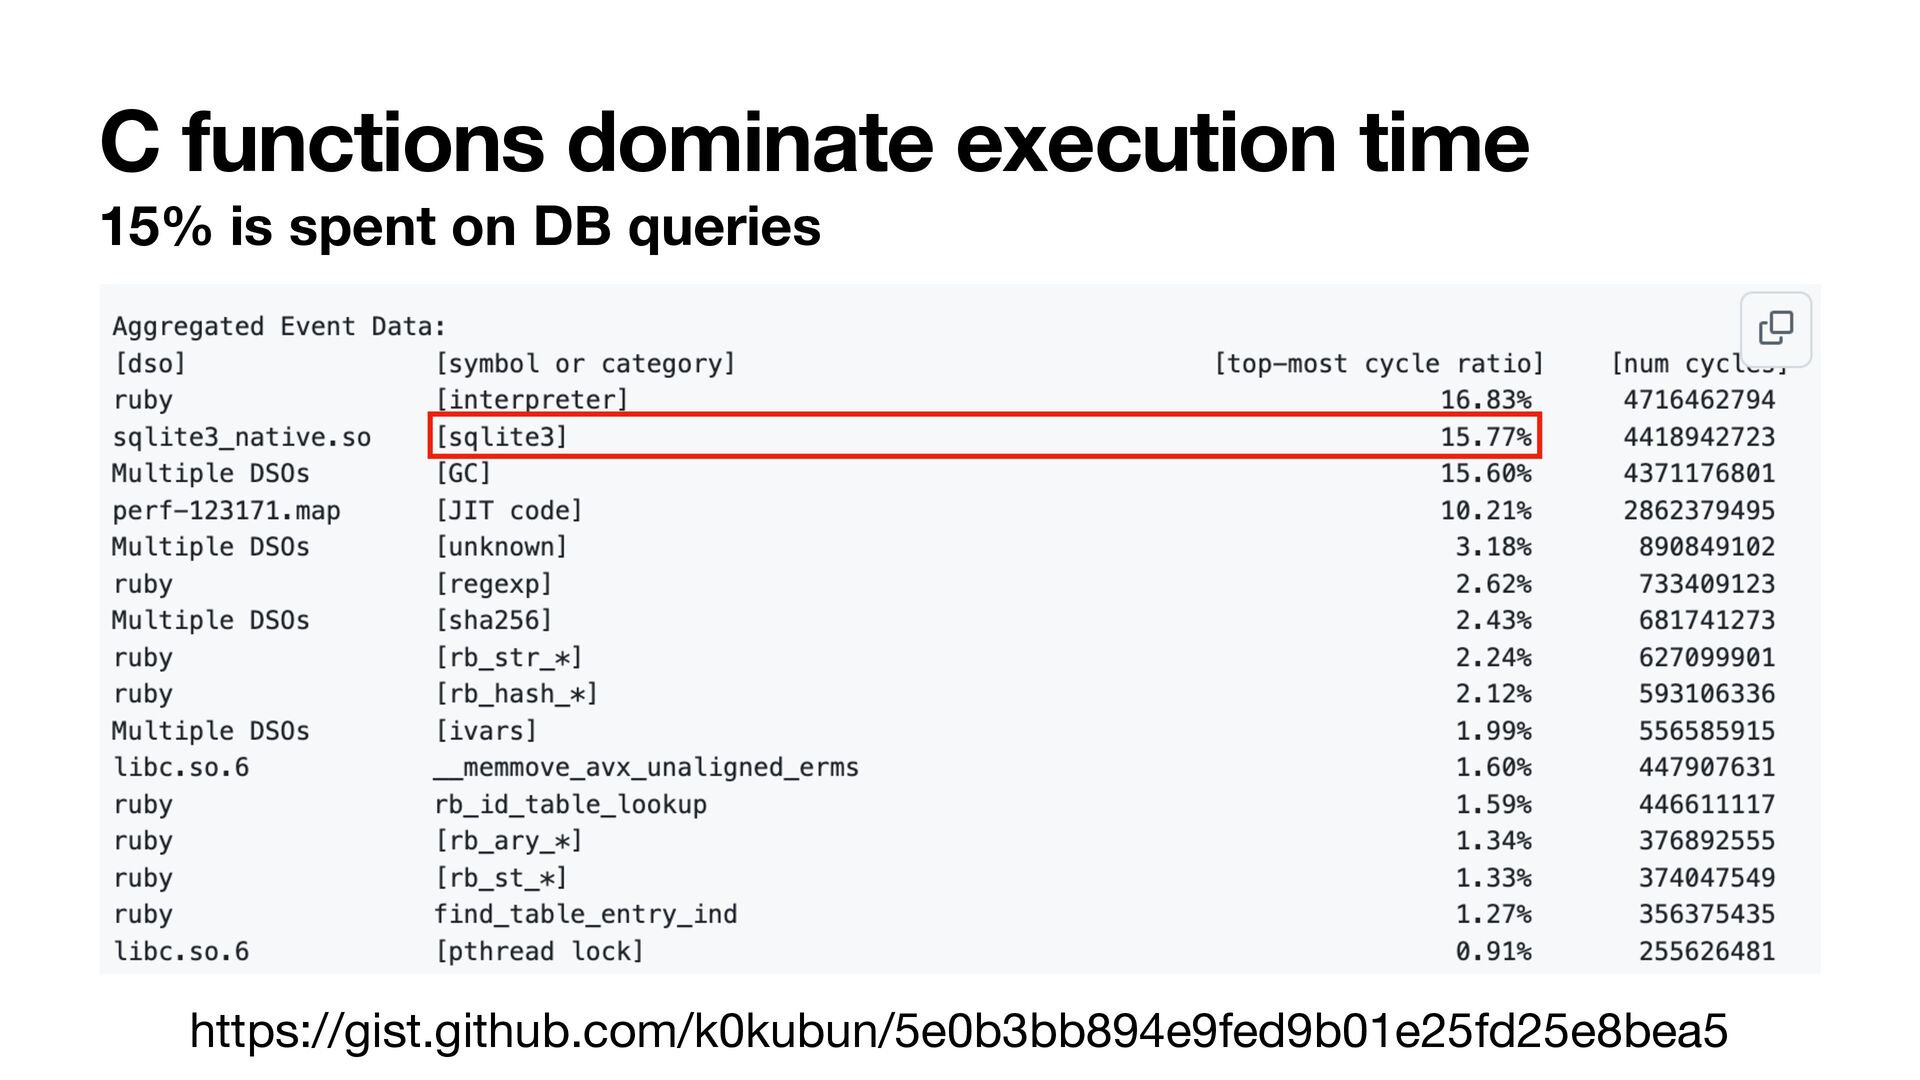
C functions dominate execution time 15% is spent on DB
queries https://gist.github.com/k0kubun/5e0b3bb894e9fed9b01e25fd25e8bea5 -
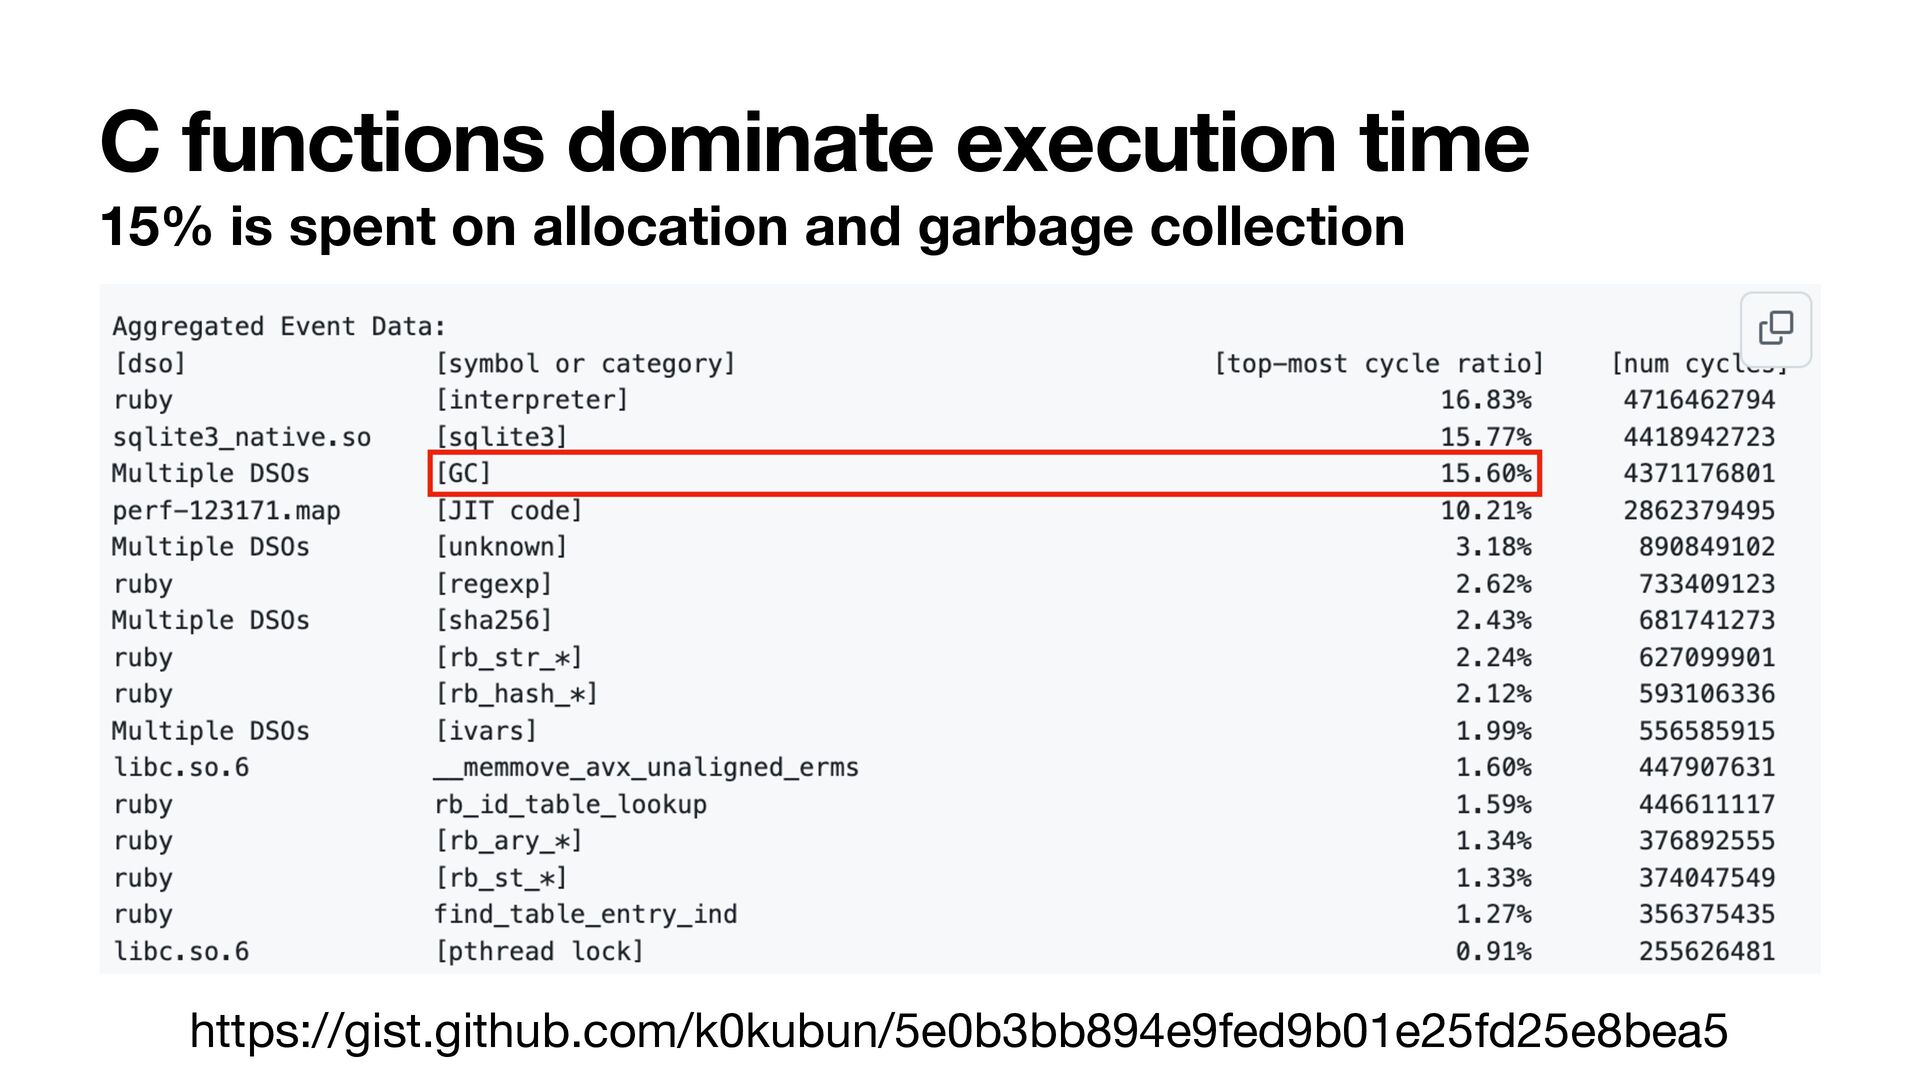
C functions dominate execution time 15% is spent on allocation
and garbage collection https://gist.github.com/k0kubun/5e0b3bb894e9fed9b01e25fd25e8bea5 -
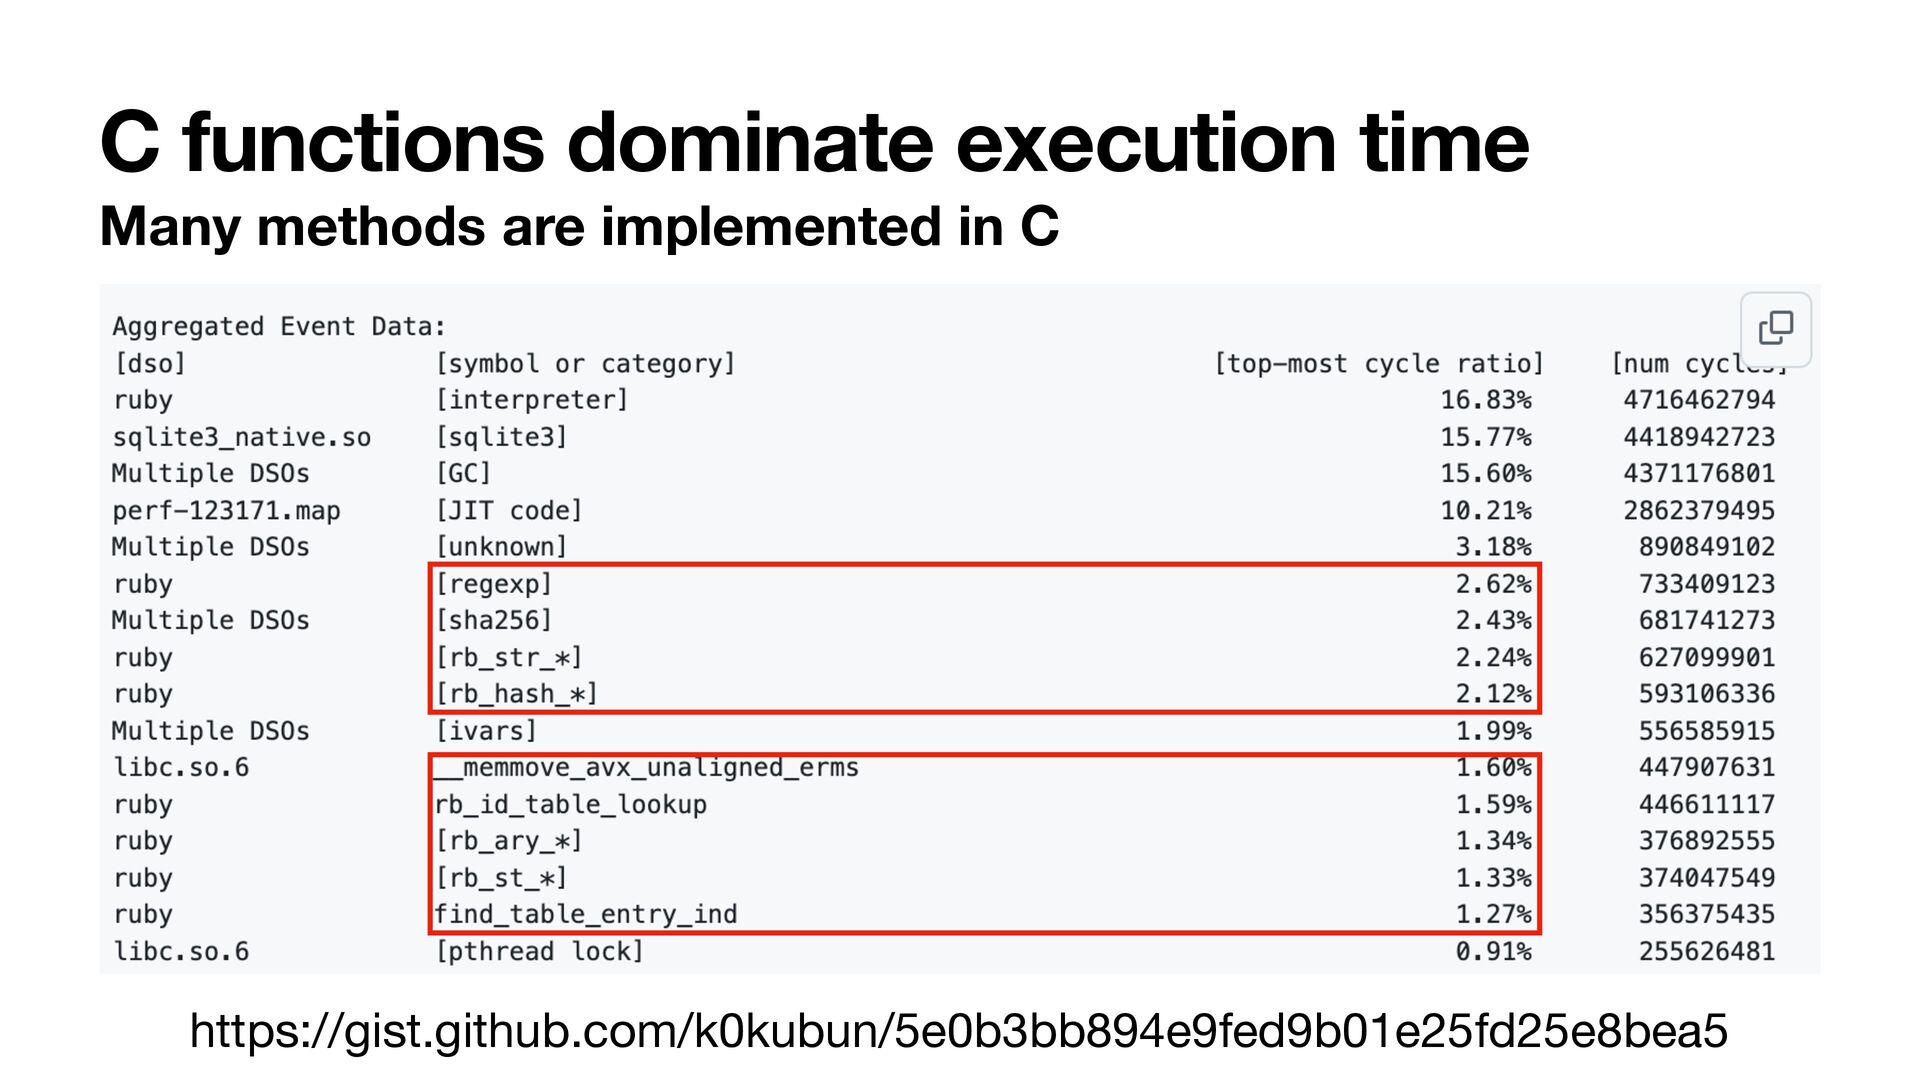
C functions dominate execution time Many methods are implemented in
C https://gist.github.com/k0kubun/5e0b3bb894e9fed9b01e25fd25e8bea5 -
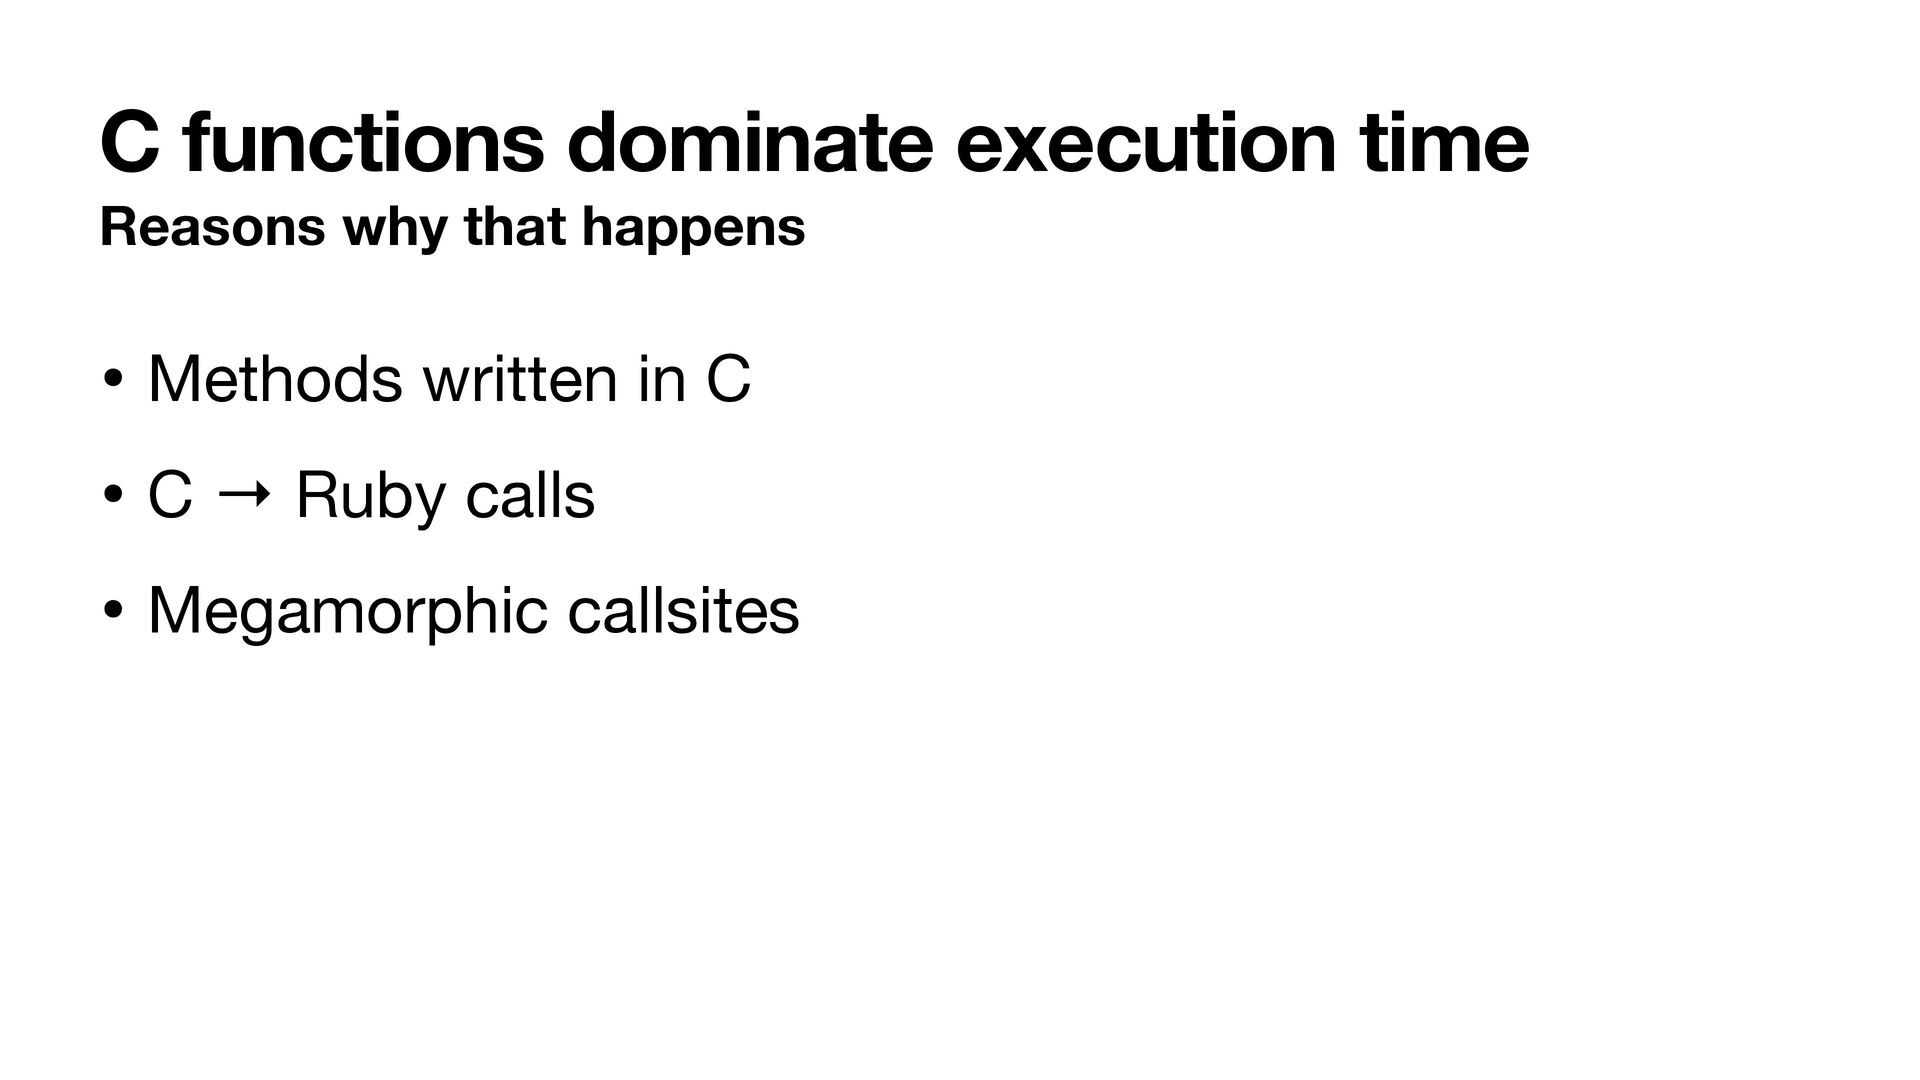
C functions dominate execution time • Methods written in C
• C → Ruby calls • Megamorphic callsites Reasons why that happens -
Local variables are too dynamic • YJIT does: • Spill
locals onto the VM stack • Spill every local on any C or method calls How YJIT deals with it -
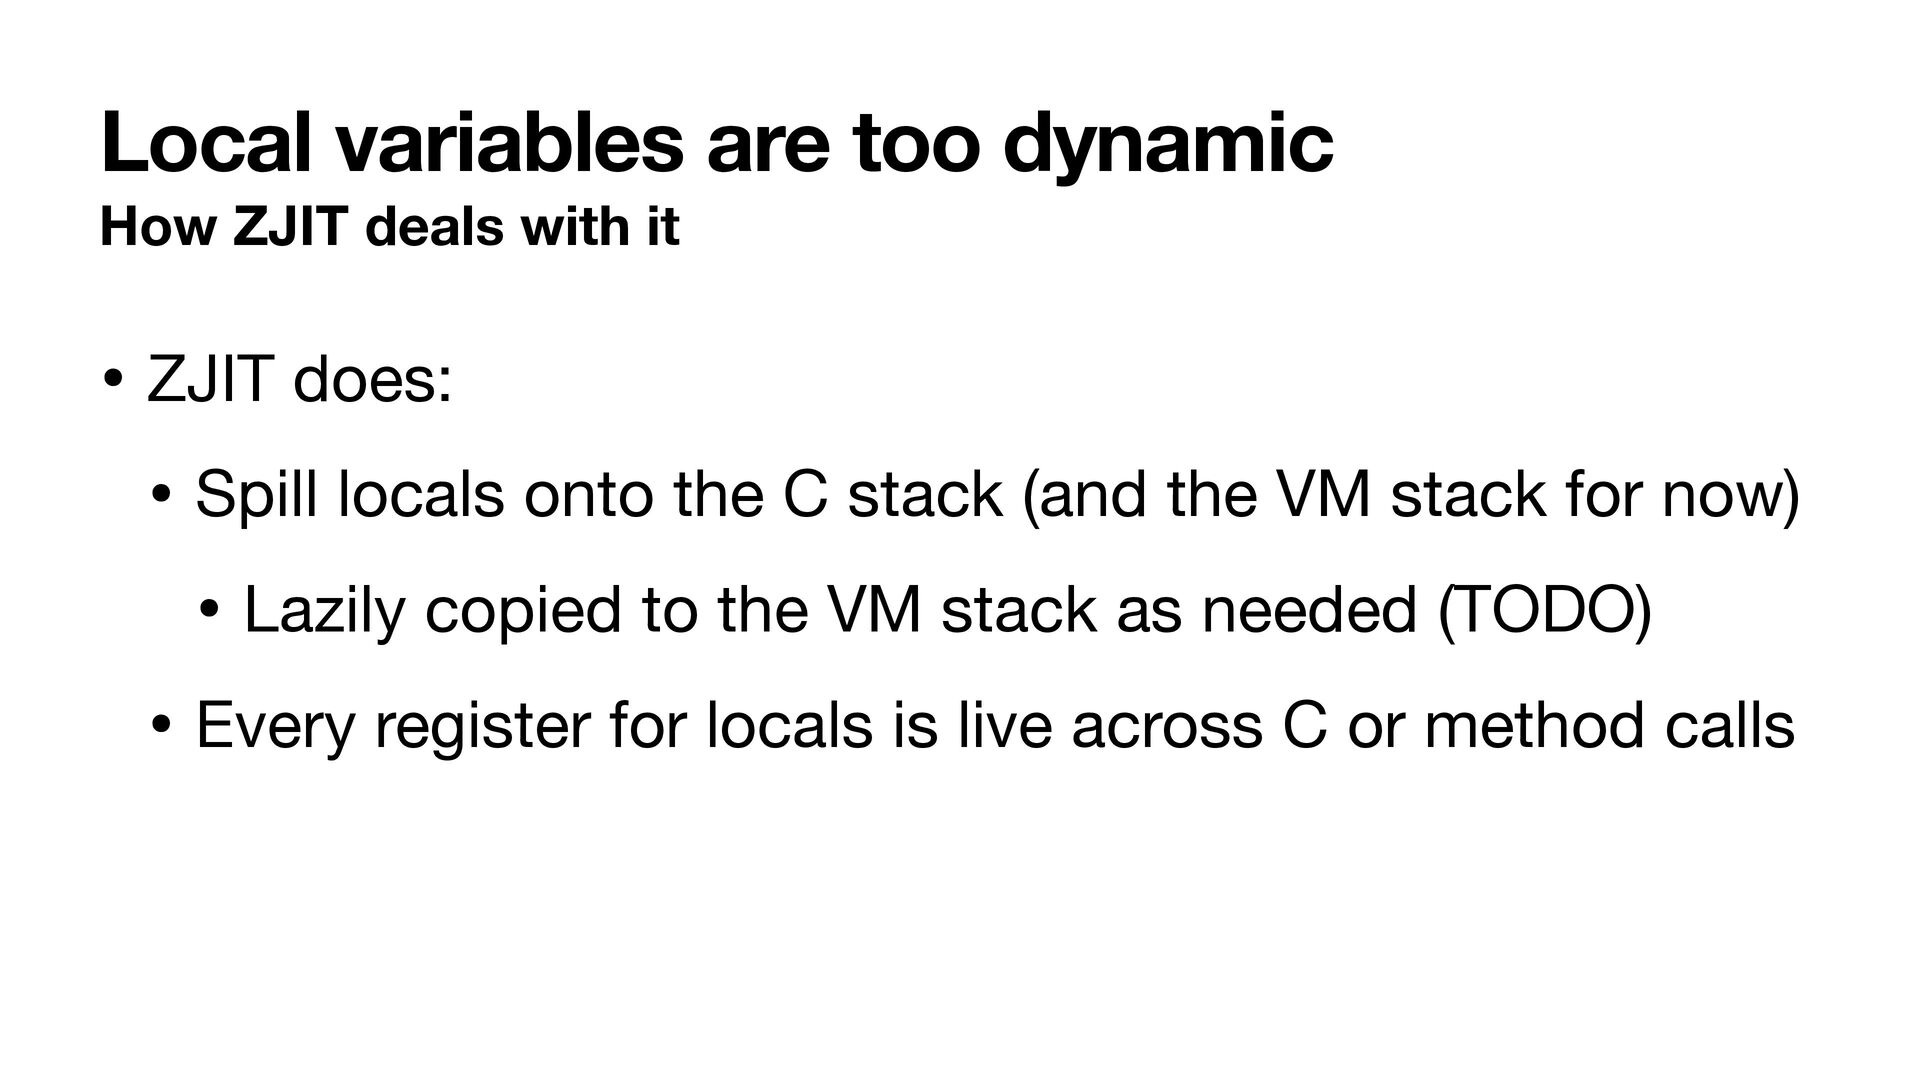
Local variables are too dynamic • ZJIT does: • Spill
locals onto the C stack (and the VM stack for now) • Lazily copied to the VM stack as needed (TODO) • Every register for locals is live across C or method calls How ZJIT deals with it -
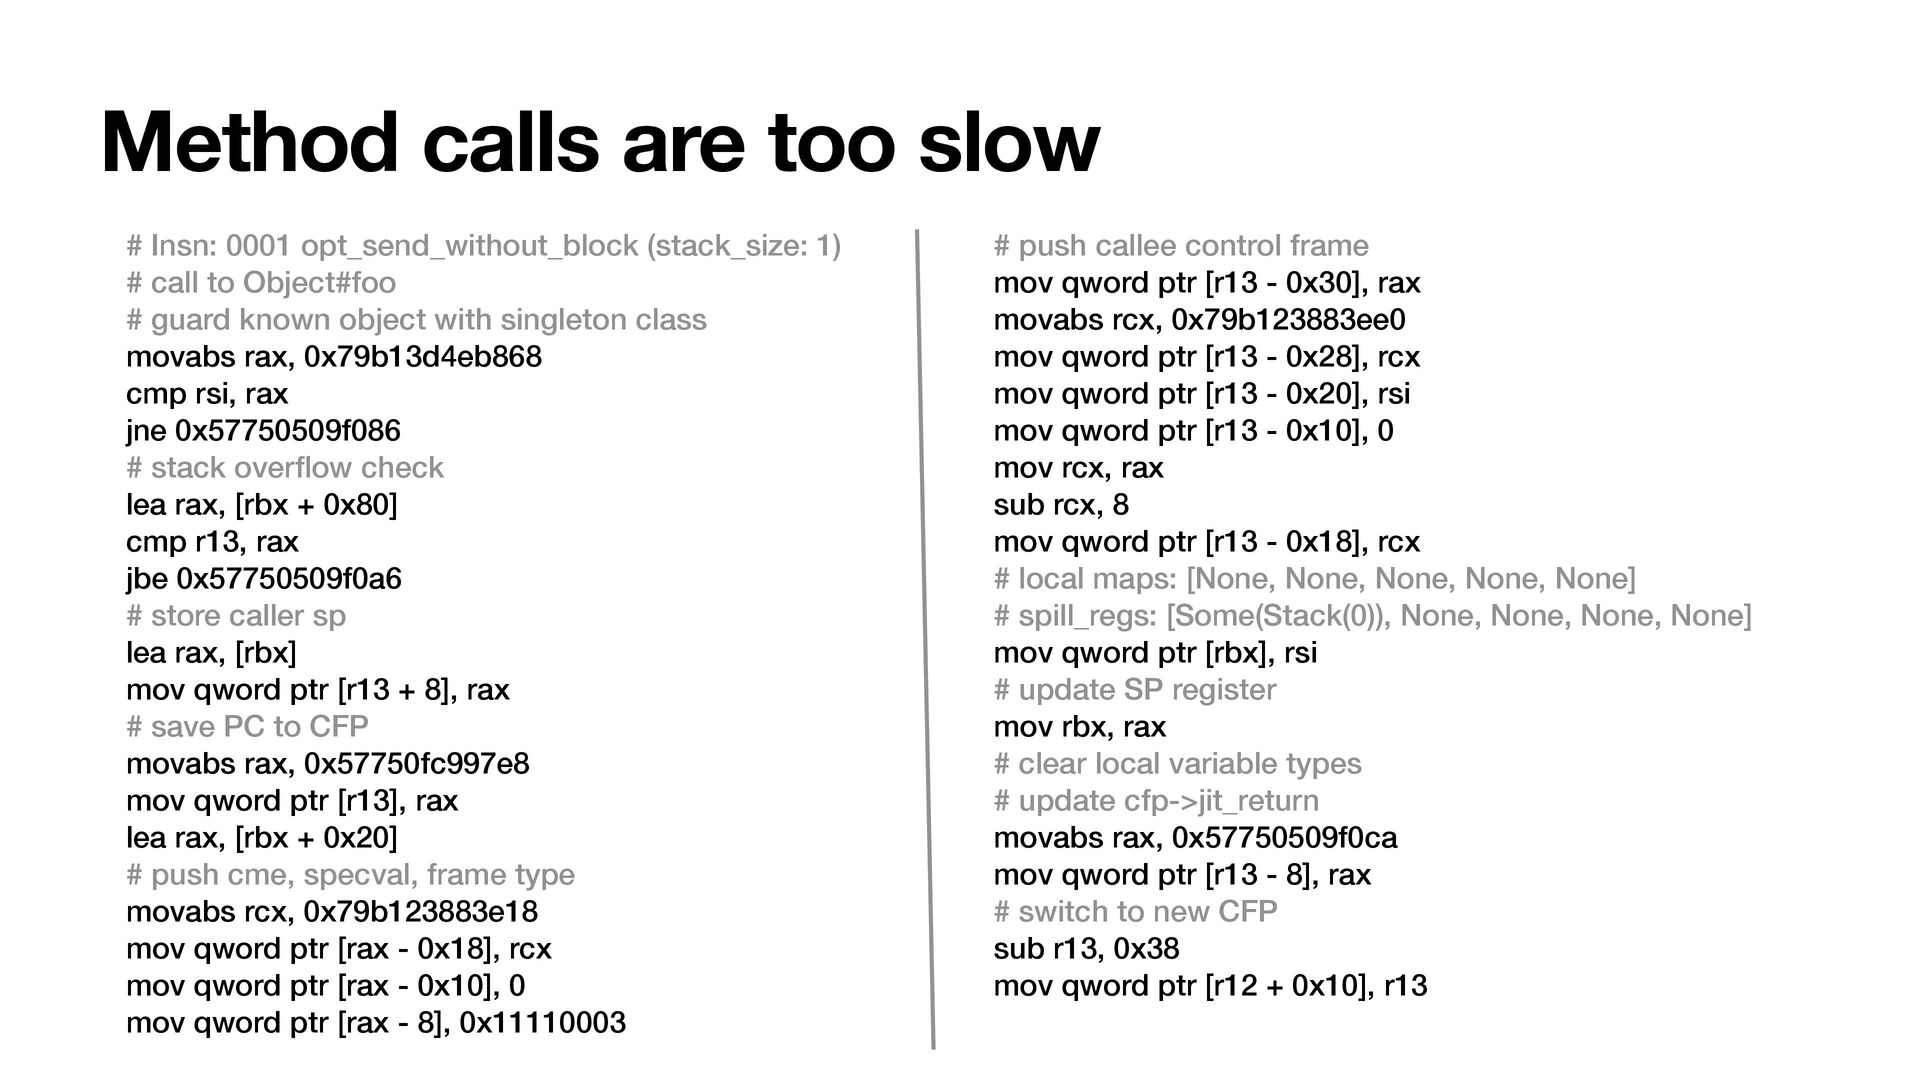
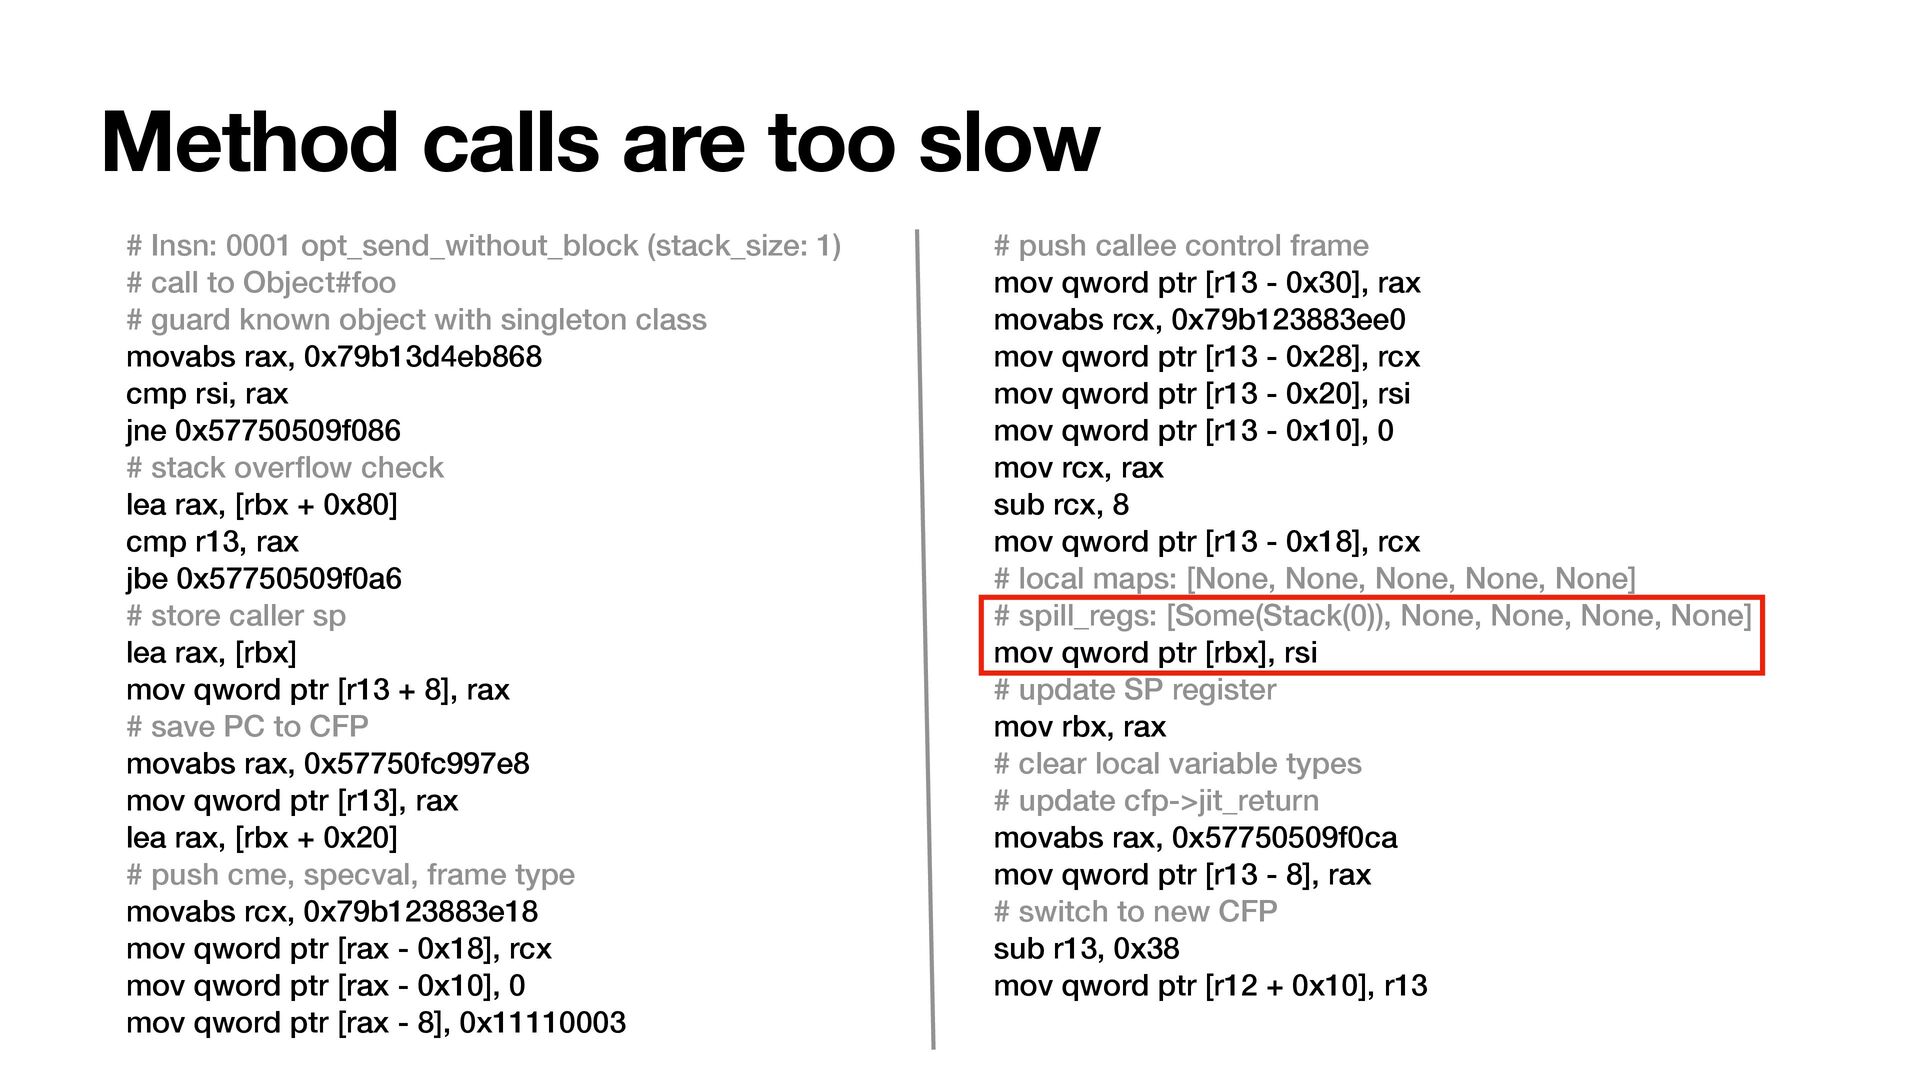
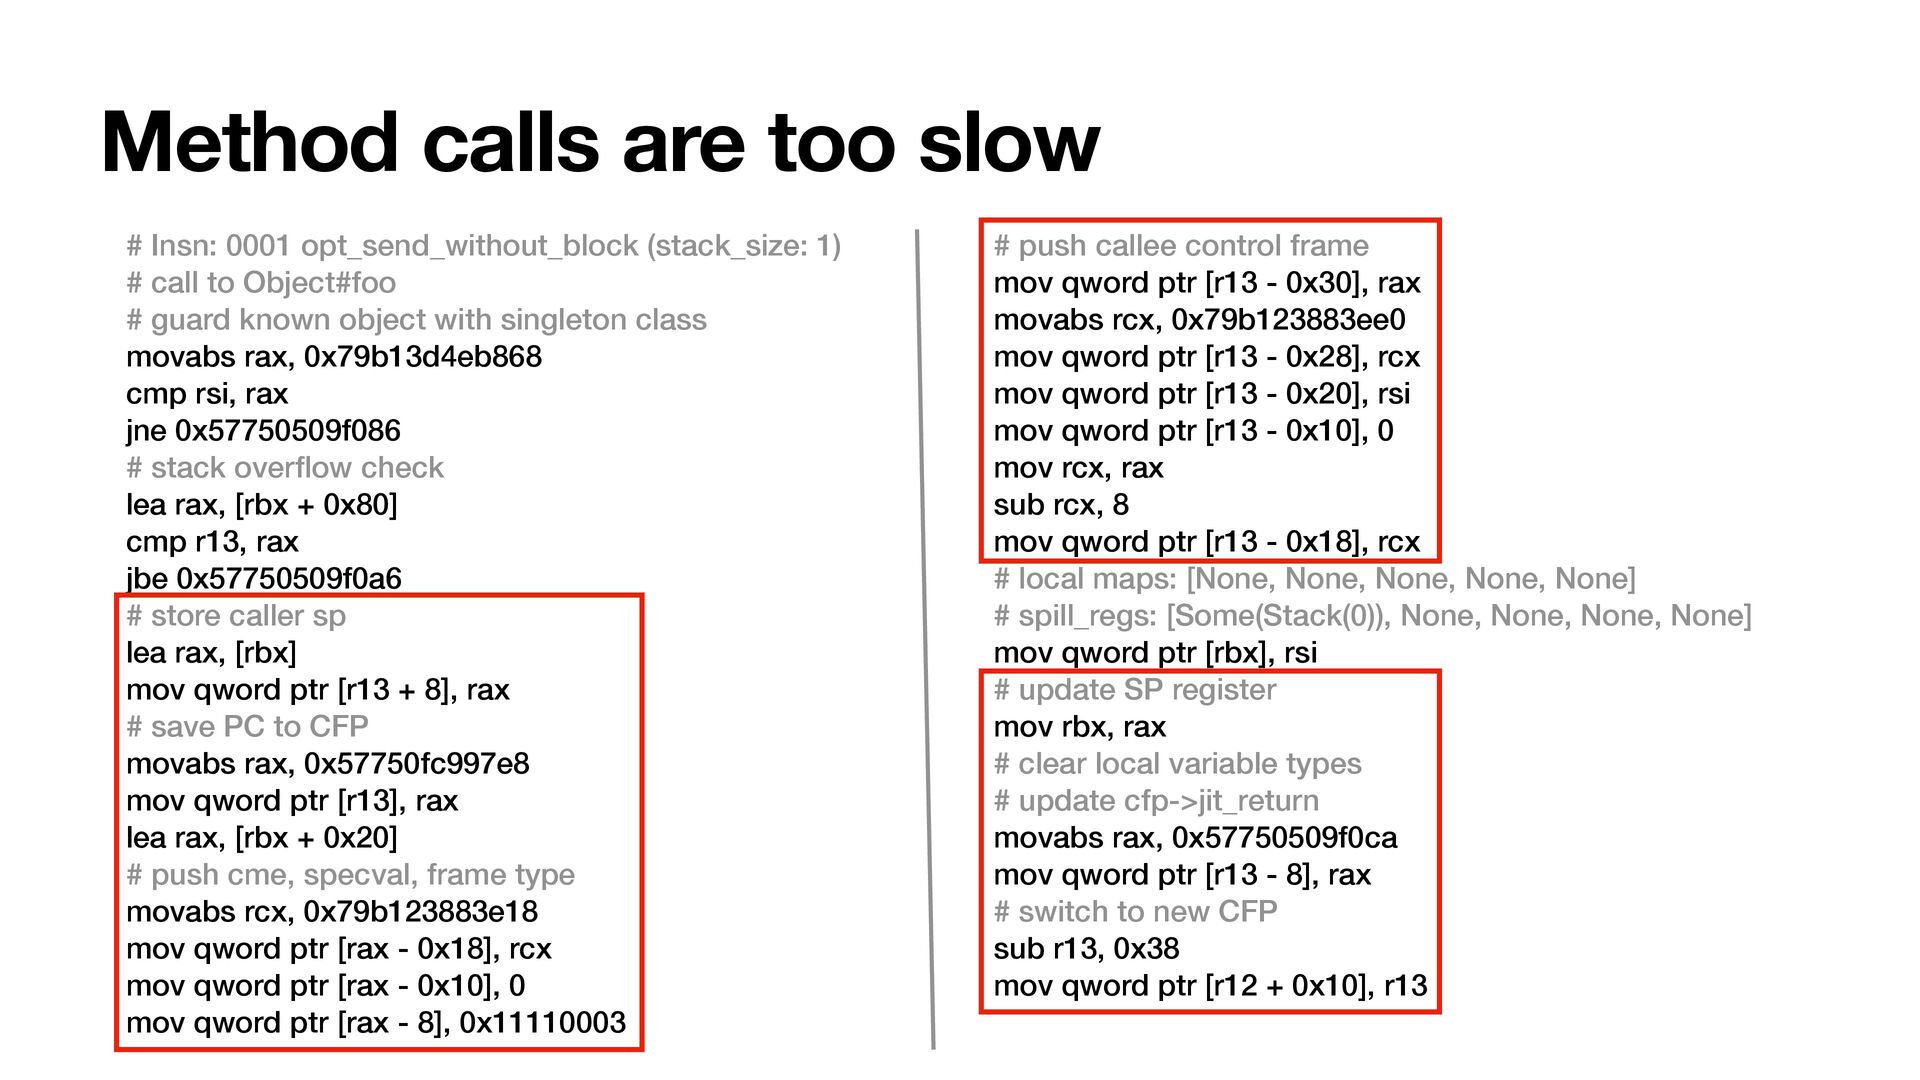
Method calls are too slow # Insn: 0001 opt_send_without_block (stack_size:
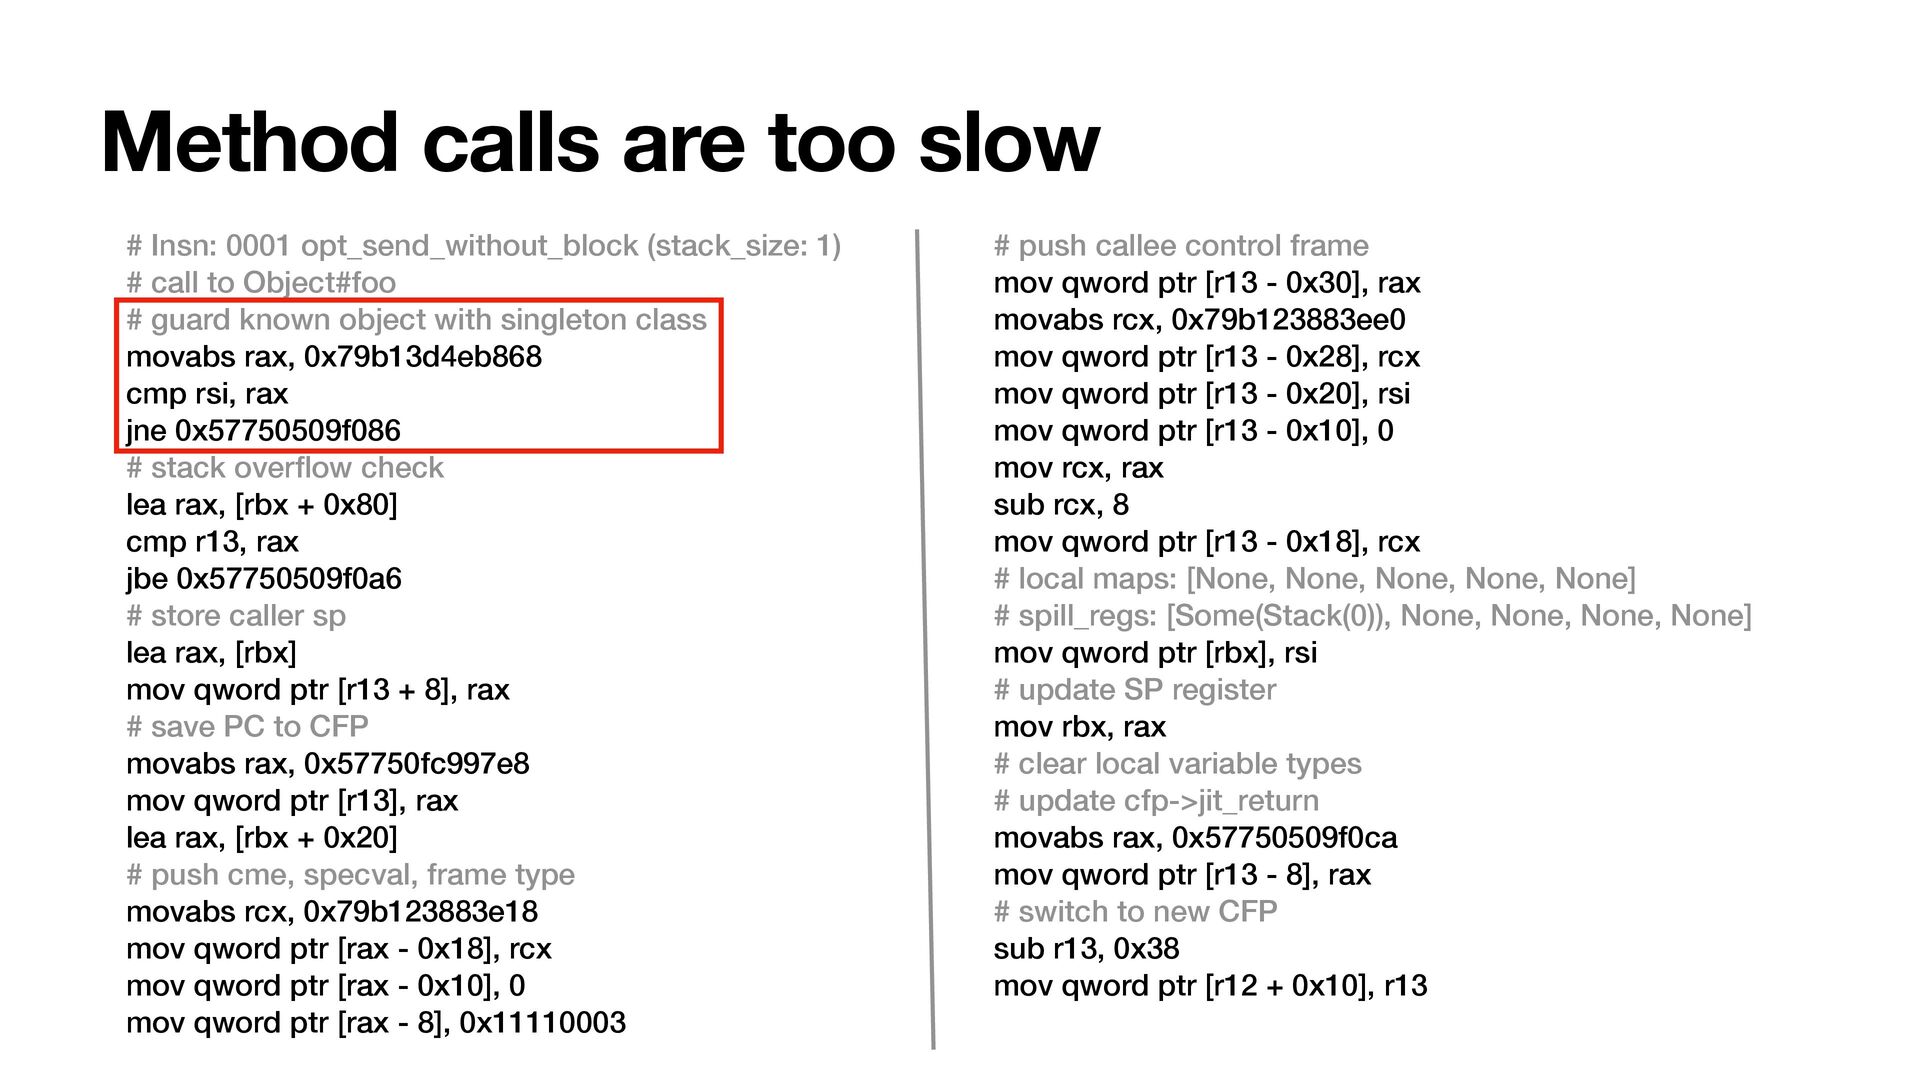
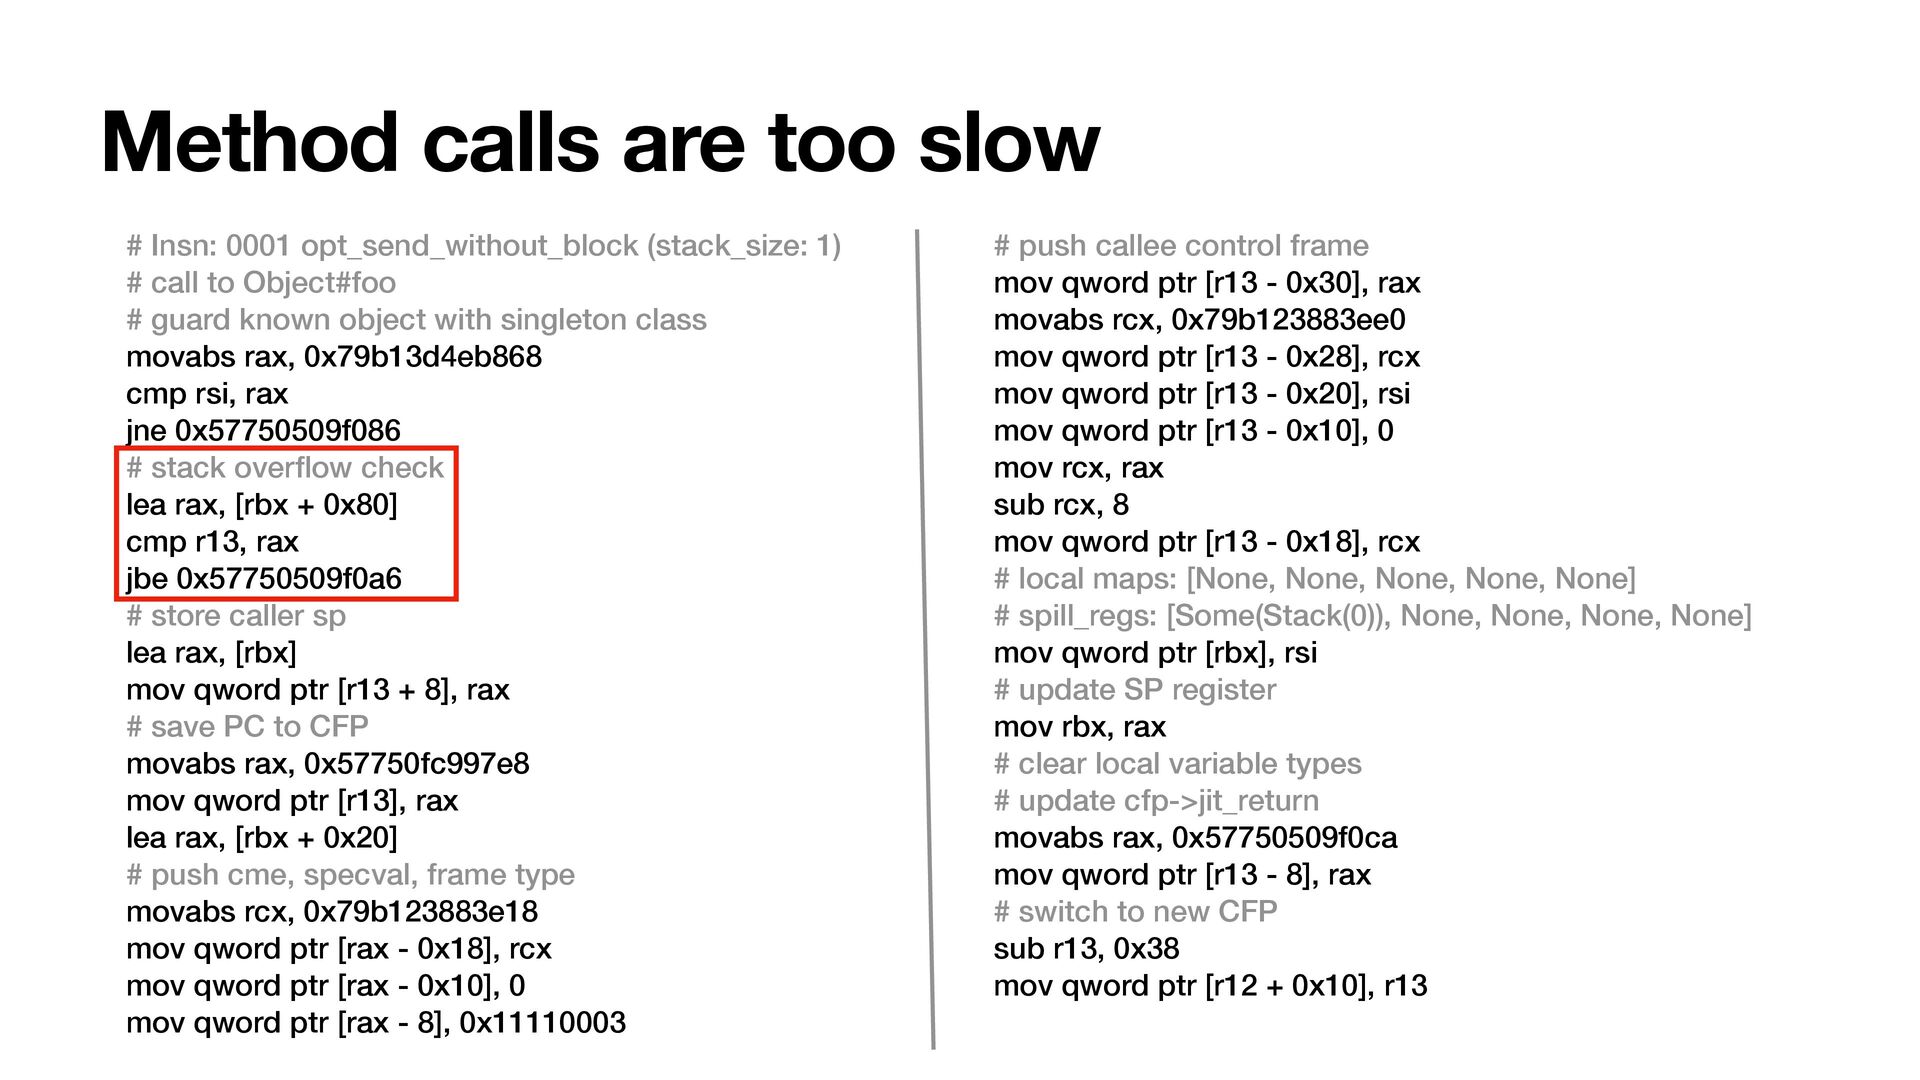
1) # call to Object#foo # guard known object with singleton class movabs rax, 0x79b13d4eb868 cmp rsi, rax jne 0x57750509f086 # stack over fl ow check lea rax, [rbx + 0x80] cmp r13, rax jbe 0x57750509f0a6 # store caller sp lea rax, [rbx] mov qword ptr [r13 + 8], rax # save PC to CFP movabs rax, 0x57750fc997e8 mov qword ptr [r13], rax lea rax, [rbx + 0x20] # push cme, specval, frame type movabs rcx, 0x79b123883e18 mov qword ptr [rax - 0x18], rcx mov qword ptr [rax - 0x10], 0 mov qword ptr [rax - 8], 0x11110003 # push callee control frame mov qword ptr [r13 - 0x30], rax movabs rcx, 0x79b123883ee0 mov qword ptr [r13 - 0x28], rcx mov qword ptr [r13 - 0x20], rsi mov qword ptr [r13 - 0x10], 0 mov rcx, rax sub rcx, 8 mov qword ptr [r13 - 0x18], rcx # local maps: [None, None, None, None, None] # spill_regs: [Some(Stack(0)), None, None, None, None] mov qword ptr [rbx], rsi # update SP register mov rbx, rax # clear local variable types # update cfp->jit_return movabs rax, 0x57750509f0ca mov qword ptr [r13 - 8], rax # switch to new CFP sub r13, 0x38 mov qword ptr [r12 + 0x10], r13 -
Method calls are too slow # Insn: 0001 opt_send_without_block (stack_size:
1) # call to Object#foo # guard known object with singleton class movabs rax, 0x79b13d4eb868 cmp rsi, rax jne 0x57750509f086 # stack over fl ow check lea rax, [rbx + 0x80] cmp r13, rax jbe 0x57750509f0a6 # store caller sp lea rax, [rbx] mov qword ptr [r13 + 8], rax # save PC to CFP movabs rax, 0x57750fc997e8 mov qword ptr [r13], rax lea rax, [rbx + 0x20] # push cme, specval, frame type movabs rcx, 0x79b123883e18 mov qword ptr [rax - 0x18], rcx mov qword ptr [rax - 0x10], 0 mov qword ptr [rax - 8], 0x11110003 # push callee control frame mov qword ptr [r13 - 0x30], rax movabs rcx, 0x79b123883ee0 mov qword ptr [r13 - 0x28], rcx mov qword ptr [r13 - 0x20], rsi mov qword ptr [r13 - 0x10], 0 mov rcx, rax sub rcx, 8 mov qword ptr [r13 - 0x18], rcx # local maps: [None, None, None, None, None] # spill_regs: [Some(Stack(0)), None, None, None, None] mov qword ptr [rbx], rsi # update SP register mov rbx, rax # clear local variable types # update cfp->jit_return movabs rax, 0x57750509f0ca mov qword ptr [r13 - 8], rax # switch to new CFP sub r13, 0x38 mov qword ptr [r12 + 0x10], r13 -
Method calls are too slow # Insn: 0001 opt_send_without_block (stack_size:
1) # call to Object#foo # guard known object with singleton class movabs rax, 0x79b13d4eb868 cmp rsi, rax jne 0x57750509f086 # stack over fl ow check lea rax, [rbx + 0x80] cmp r13, rax jbe 0x57750509f0a6 # store caller sp lea rax, [rbx] mov qword ptr [r13 + 8], rax # save PC to CFP movabs rax, 0x57750fc997e8 mov qword ptr [r13], rax lea rax, [rbx + 0x20] # push cme, specval, frame type movabs rcx, 0x79b123883e18 mov qword ptr [rax - 0x18], rcx mov qword ptr [rax - 0x10], 0 mov qword ptr [rax - 8], 0x11110003 # push callee control frame mov qword ptr [r13 - 0x30], rax movabs rcx, 0x79b123883ee0 mov qword ptr [r13 - 0x28], rcx mov qword ptr [r13 - 0x20], rsi mov qword ptr [r13 - 0x10], 0 mov rcx, rax sub rcx, 8 mov qword ptr [r13 - 0x18], rcx # local maps: [None, None, None, None, None] # spill_regs: [Some(Stack(0)), None, None, None, None] mov qword ptr [rbx], rsi # update SP register mov rbx, rax # clear local variable types # update cfp->jit_return movabs rax, 0x57750509f0ca mov qword ptr [r13 - 8], rax # switch to new CFP sub r13, 0x38 mov qword ptr [r12 + 0x10], r13 -
Method calls are too slow # Insn: 0001 opt_send_without_block (stack_size:
1) # call to Object#foo # guard known object with singleton class movabs rax, 0x79b13d4eb868 cmp rsi, rax jne 0x57750509f086 # stack over fl ow check lea rax, [rbx + 0x80] cmp r13, rax jbe 0x57750509f0a6 # store caller sp lea rax, [rbx] mov qword ptr [r13 + 8], rax # save PC to CFP movabs rax, 0x57750fc997e8 mov qword ptr [r13], rax lea rax, [rbx + 0x20] # push cme, specval, frame type movabs rcx, 0x79b123883e18 mov qword ptr [rax - 0x18], rcx mov qword ptr [rax - 0x10], 0 mov qword ptr [rax - 8], 0x11110003 # push callee control frame mov qword ptr [r13 - 0x30], rax movabs rcx, 0x79b123883ee0 mov qword ptr [r13 - 0x28], rcx mov qword ptr [r13 - 0x20], rsi mov qword ptr [r13 - 0x10], 0 mov rcx, rax sub rcx, 8 mov qword ptr [r13 - 0x18], rcx # local maps: [None, None, None, None, None] # spill_regs: [Some(Stack(0)), None, None, None, None] mov qword ptr [rbx], rsi # update SP register mov rbx, rax # clear local variable types # update cfp->jit_return movabs rax, 0x57750509f0ca mov qword ptr [r13 - 8], rax # switch to new CFP sub r13, 0x38 mov qword ptr [r12 + 0x10], r13 -
Method calls are too slow # Insn: 0001 opt_send_without_block (stack_size:
1) # call to Object#foo # guard known object with singleton class movabs rax, 0x79b13d4eb868 cmp rsi, rax jne 0x57750509f086 # stack over fl ow check lea rax, [rbx + 0x80] cmp r13, rax jbe 0x57750509f0a6 # store caller sp lea rax, [rbx] mov qword ptr [r13 + 8], rax # save PC to CFP movabs rax, 0x57750fc997e8 mov qword ptr [r13], rax lea rax, [rbx + 0x20] # push cme, specval, frame type movabs rcx, 0x79b123883e18 mov qword ptr [rax - 0x18], rcx mov qword ptr [rax - 0x10], 0 mov qword ptr [rax - 8], 0x11110003 # push callee control frame mov qword ptr [r13 - 0x30], rax movabs rcx, 0x79b123883ee0 mov qword ptr [r13 - 0x28], rcx mov qword ptr [r13 - 0x20], rsi mov qword ptr [r13 - 0x10], 0 mov rcx, rax sub rcx, 8 mov qword ptr [r13 - 0x18], rcx # local maps: [None, None, None, None, None] # spill_regs: [Some(Stack(0)), None, None, None, None] mov qword ptr [rbx], rsi # update SP register mov rbx, rax # clear local variable types # update cfp->jit_return movabs rax, 0x57750509f0ca mov qword ptr [r13 - 8], rax # switch to new CFP sub r13, 0x38 mov qword ptr [r12 + 0x10], r13 -
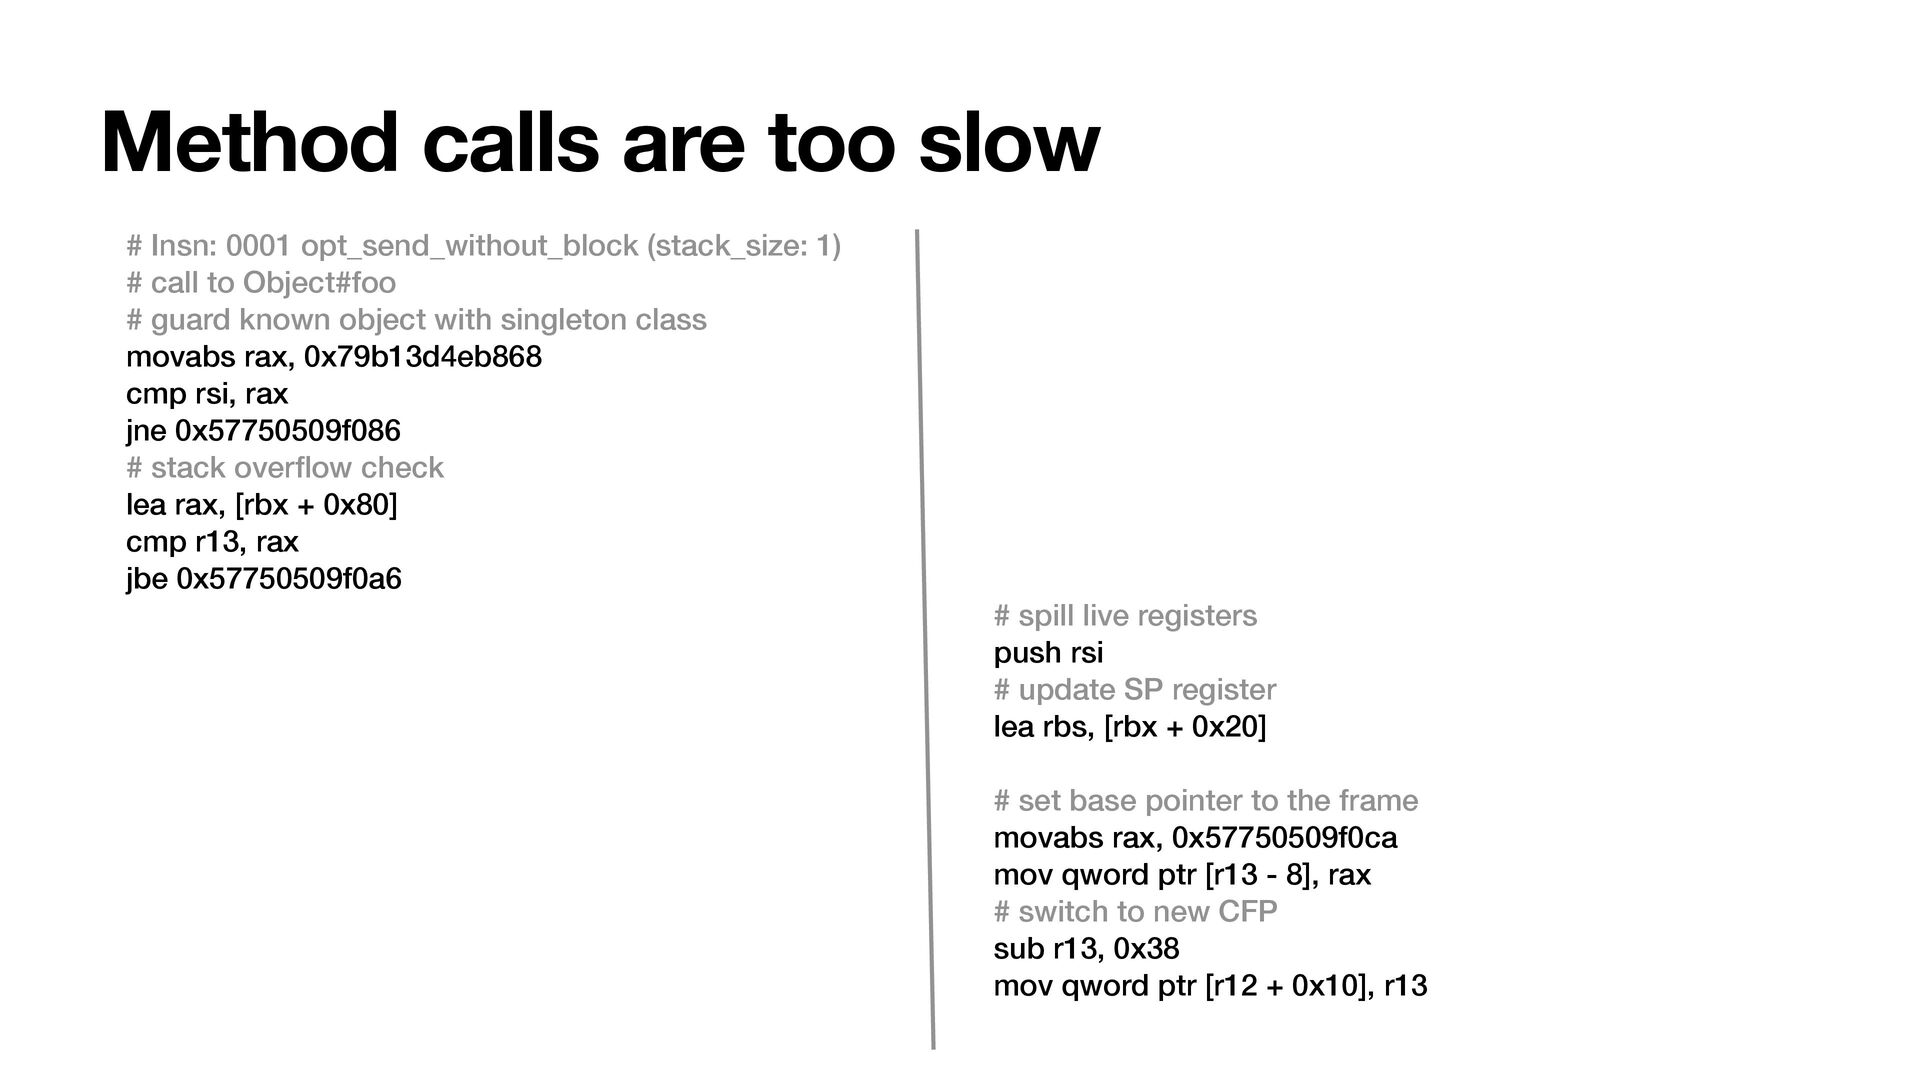
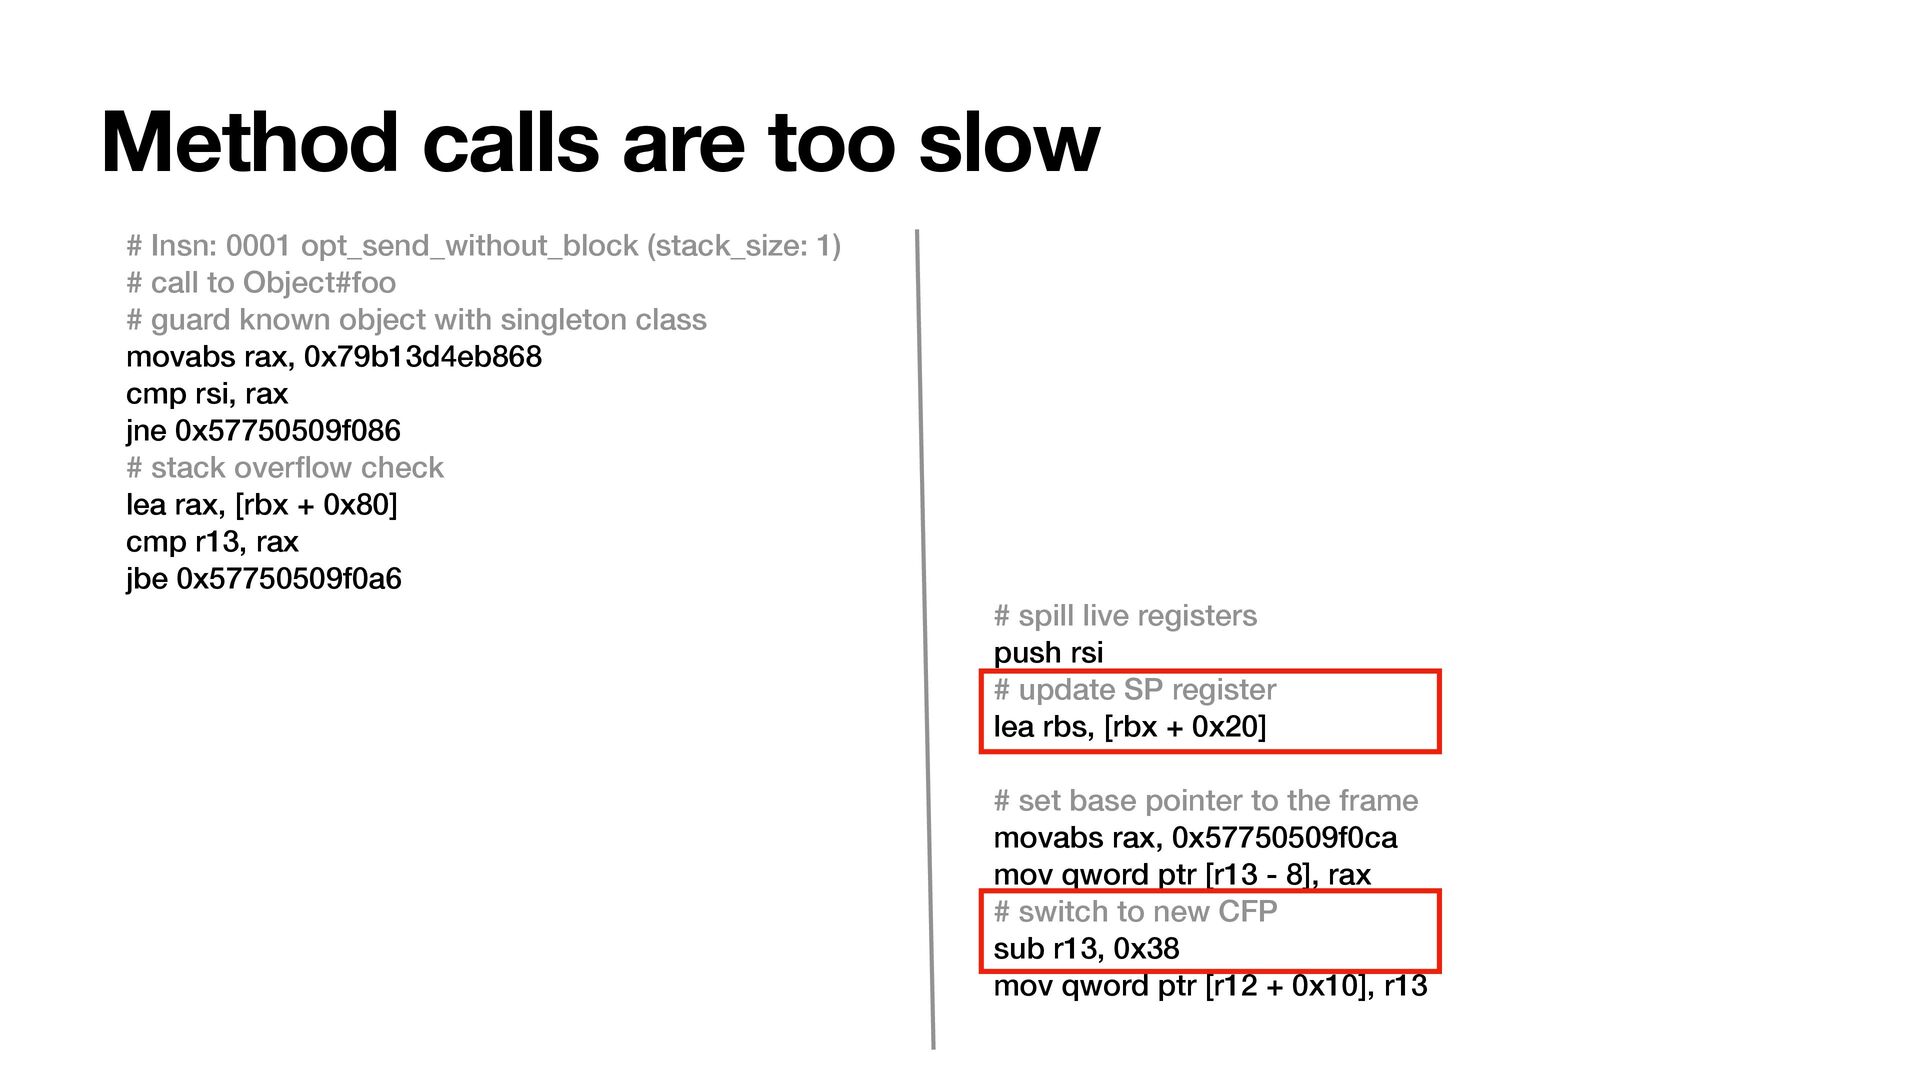
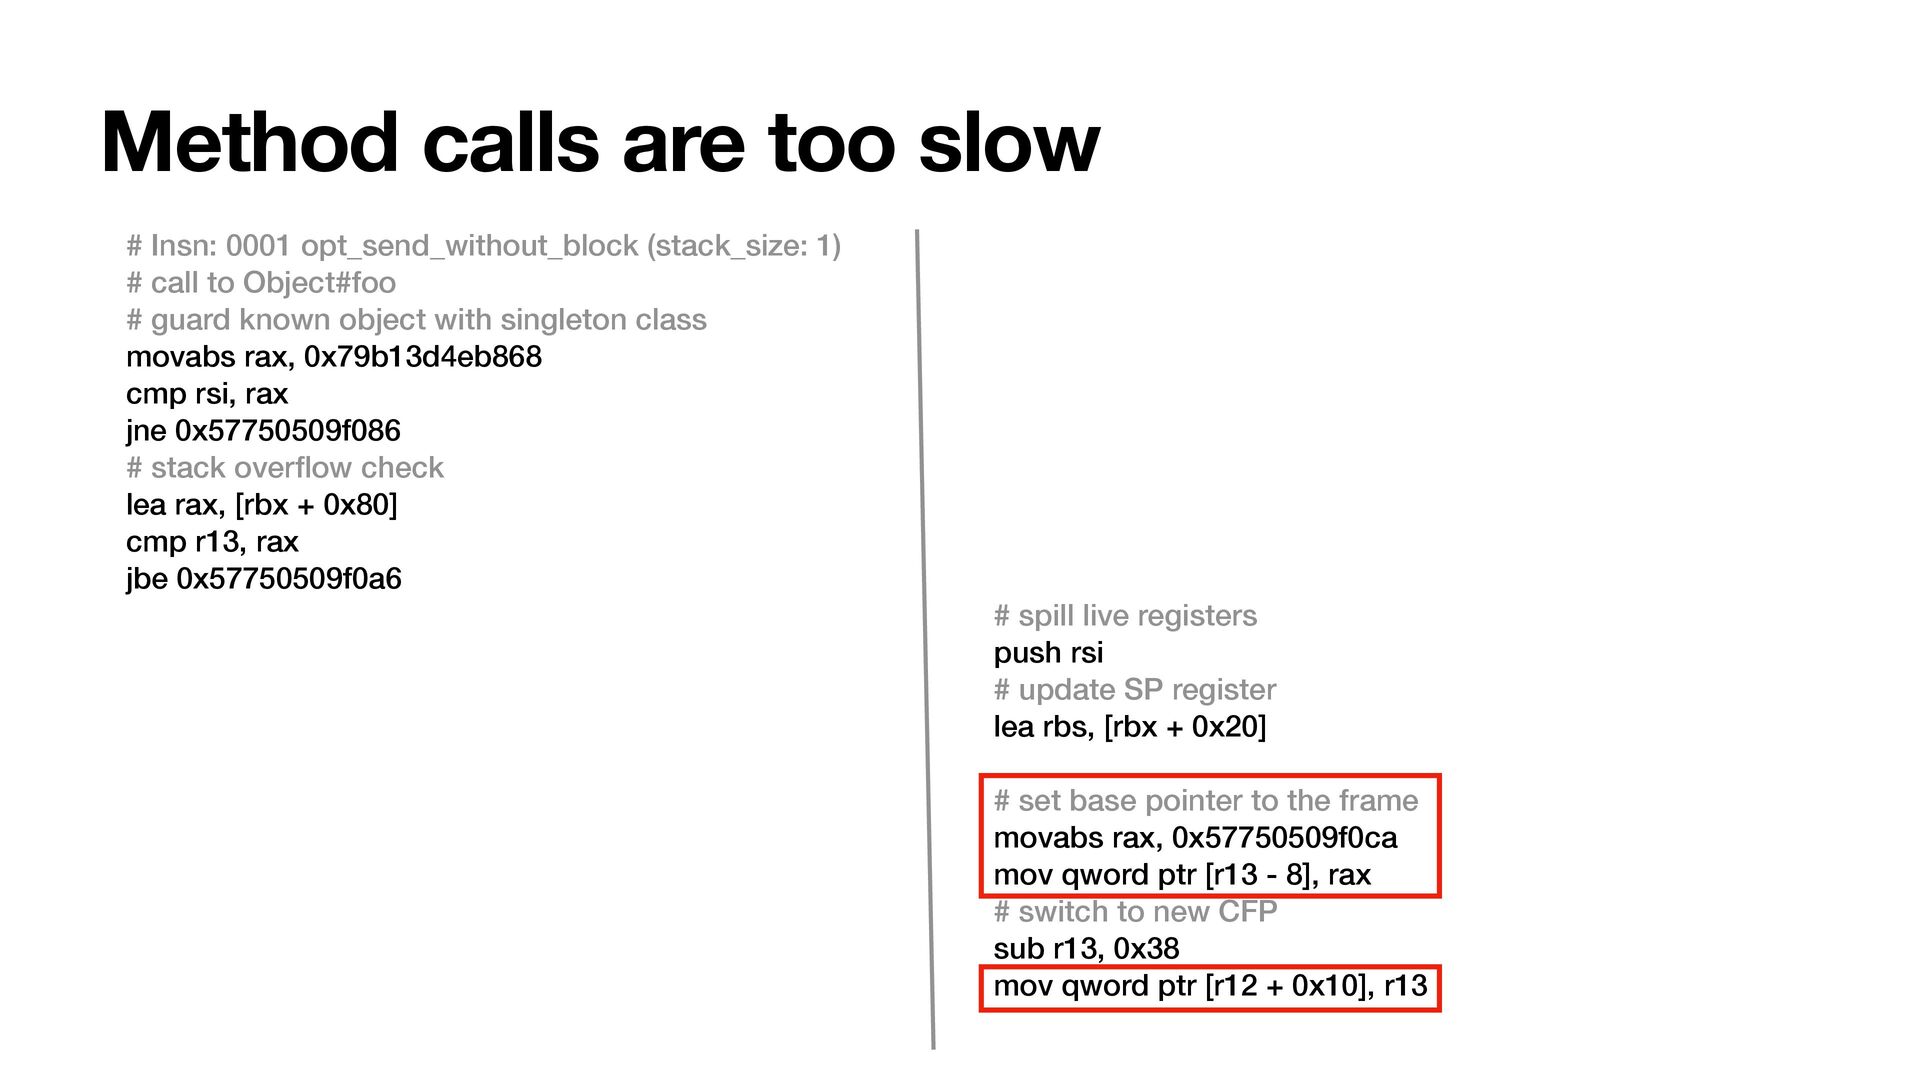
Method calls are too slow # Insn: 0001 opt_send_without_block (stack_size:
1) # call to Object#foo # guard known object with singleton class movabs rax, 0x79b13d4eb868 cmp rsi, rax jne 0x57750509f086 # stack over fl ow check lea rax, [rbx + 0x80] cmp r13, rax jbe 0x57750509f0a6 # spill live registers push rsi # update SP register lea rbs, [rbx + 0x20] # set base pointer to the frame movabs rax, 0x57750509f0ca mov qword ptr [r13 - 8], rax # switch to new CFP sub r13, 0x38 mov qword ptr [r12 + 0x10], r13 -
Method calls are too slow # Insn: 0001 opt_send_without_block (stack_size:
1) # call to Object#foo # guard known object with singleton class movabs rax, 0x79b13d4eb868 cmp rsi, rax jne 0x57750509f086 # stack over fl ow check lea rax, [rbx + 0x80] cmp r13, rax jbe 0x57750509f0a6 # spill live registers push rsi # update SP register lea rbs, [rbx + 0x20] # set base pointer to the frame movabs rax, 0x57750509f0ca mov qword ptr [r13 - 8], rax # switch to new CFP sub r13, 0x38 mov qword ptr [r12 + 0x10], r13 -
Method calls are too slow # Insn: 0001 opt_send_without_block (stack_size:
1) # call to Object#foo # guard known object with singleton class movabs rax, 0x79b13d4eb868 cmp rsi, rax jne 0x57750509f086 # stack over fl ow check lea rax, [rbx + 0x80] cmp r13, rax jbe 0x57750509f0a6 # spill live registers push rsi # update SP register lea rbs, [rbx + 0x20] # set base pointer to the frame movabs rax, 0x57750509f0ca mov qword ptr [r13 - 8], rax # switch to new CFP sub r13, 0x38 mov qword ptr [r12 + 0x10], r13 -
Conclusion • We’re building a new compiler ZJIT to unblock
cross- instruction optimizations • We discussed optimizations for: • C function calls • Local variables • Method calls