Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Hadoop Operations
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Marc Cluet
June 09, 2013
Technology
130
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Hadoop Operations
Marc Cluet
June 09, 2013
More Decks by Marc Cluet
See All by Marc Cluet
FOSDEM'14 - Autoscaling Best Practices
lynxman
1
130
A metadata ocean in Chef and Puppet
lynxman
0
70
Rackspace Hack Night - Vagrant & Packer
lynxman
0
170
Innovation in the Cloud - Rackspace Zurich Event
lynxman
0
110
Introduction to DevOps - Rackspace Tech Night
lynxman
1
90
Introduction To Hadoop
lynxman
1
130
SSH That Wonderful Thing
lynxman
1
110
Networking & DNS 101
lynxman
0
110
Juju and Puppet - Rapid Harmonious Deployment
lynxman
0
120
Other Decks in Technology
See All in Technology
Goodbye ShellScript, Hello File-based App
shunsock
0
670
アプリログインとWeb認証基盤をつなぐ ASWebAuthenticationSession 作法
shimastripe
1
390
2026_devsumi_ozono.pdf
o3
3
560
【技術的負債conf】事業成長に伴う技術的負債の説明責任とAIによるモニタリング、認知的負債について
i35_267
3
2k
AI 時代のスタートアップエコシステ厶から考究する技術的負債との向き合い方
m3m0r7
PRO
3
2.6k
Why Agent Cost Needs Observability
nttcom
0
130
2026-09-08 そのJavaモダナイゼーション、AIに丸投げで大丈夫?IBM Bobで変わる品質と効率
yutanonaka
1
130
What the customer really needed
kawaguti
PRO
3
220
技術的負債から考える、AI時代のエンジニアリング投資 — ビズリーチの技術的負債と向き合った経験から、変更し続けられるソフトウェアを考える/ technical-debt-con2026
visional_engineering_and_design
4
3.6k
すぐできる衛星通信対応 あとは山奥に行くだけ
tatetate55
0
140
AI時代の「技術的負債」の変質ー概念の終焉と再解釈、エージェントと共に向かう先
nwiizo
1
3.2k
開発投資の期待値を上げるプロダクトロードマップづくり ~プロダクトエンジニアが越境して事業を伸ばす~
kekekenta
1
240
Featured
See All Featured
30 Presentation Tips
portentint
PRO
1
400
Primal Persuasion: How to Engage the Brain for Learning That Lasts
tmiket
0
470
Agile that works and the tools we love
rasmusluckow
331
22k
The Art of Programming - Codeland 2020
erikaheidi
57
14k
Bioeconomy Workshop: Dr. Julius Ecuru, Opportunities for a Bioeconomy in West Africa
akademiya2063
PRO
1
360
Paper Plane (Part 1)
katiecoart
PRO
2
11k
More Than Pixels: Becoming A User Experience Designer
marktimemedia
3
530
Why Your Marketing Sucks and What You Can Do About It - Sophie Logan
marketingsoph
0
410
Self-Hosted WebAssembly Runtime for Runtime-Neutral Checkpoint/Restore in Edge–Cloud Continuum
chikuwait
0
820
Done Done
chrislema
186
17k
How to Create Impact in a Changing Tech Landscape [PerfNow 2023]
tammyeverts
56
3.5k
Navigating the moral maze — ethical principles for Al-driven product design
skipperchong
2
560
Transcript
Marc Cluet – Lynx Consultants How Hadoop Works
What we’ll cover? ¡ Understand Hadoop in detail ¡
See how Hadoop works operationally ¡ Be able to start asking the right questions from your data Lynx Consultants © 2013
Hadoop Distributions ¡ Cloudera CDH ¡ Hortonworks ¡
MapR Lynx Consultants © 2013
Hadoop Components ¡ HDFS ¡ Hbase ¡ MapRed
¡ YARN Lynx Consultants © 2013
Hadoop Components ¡ HDFS § Hadoop Distributed File System
§ Everything sits on top of it § Has 3 copies by default of every block ¡ Hbase ¡ MapRed ¡ YARN Lynx Consultants © 2013
Hadoop Components ¡ HDFS ¡ Hbase § Hadoop
Schemaless Database § Key value Store § Sits on top of HDFS ¡ MapRed ¡ YARN Lynx Consultants © 2013
Hadoop Components ¡ HDFS ¡ Hbase ¡ MapRed
§ Hadoop Map/Reduce § Non-‐pluggable, archaic § Requires HDFS for temp storage ¡ YARN Lynx Consultants © 2013
Hadoop Components ¡ HDFS ¡ Hbase ¡ MapRed
¡ YARN § Hadoop Map/Reduce version 2.0 § Pluggable, you can add your own § Fast and not so much memory hungry Lynx Consultants © 2013
Hadoop Component Breakdown ¡ All these components divide themselves in
§ client/server § master/slave scenarios ¡ We will now check each individual component breakdown Lynx Consultants © 2013
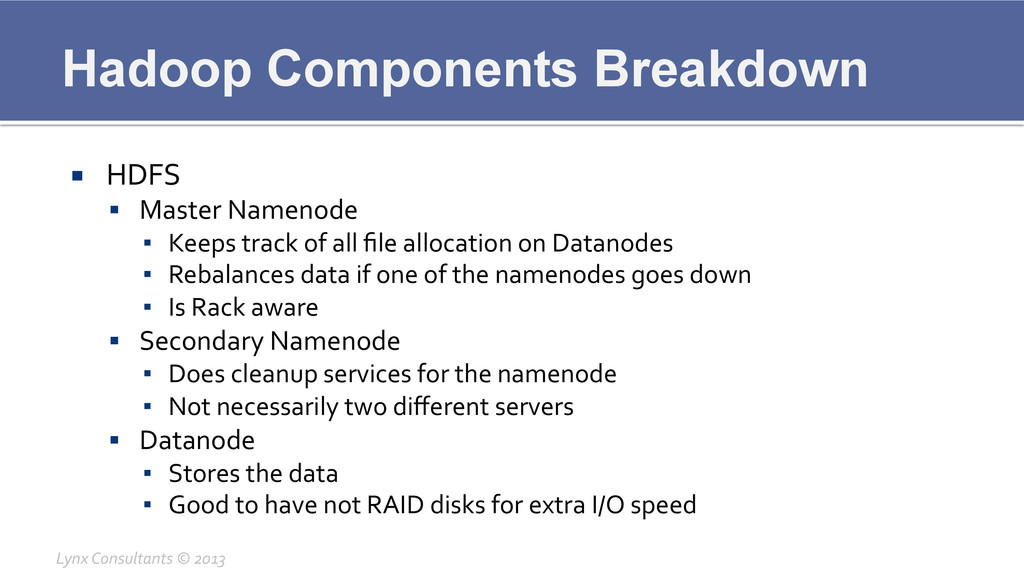
Hadoop Components Breakdown ¡ HDFS § Master Namenode
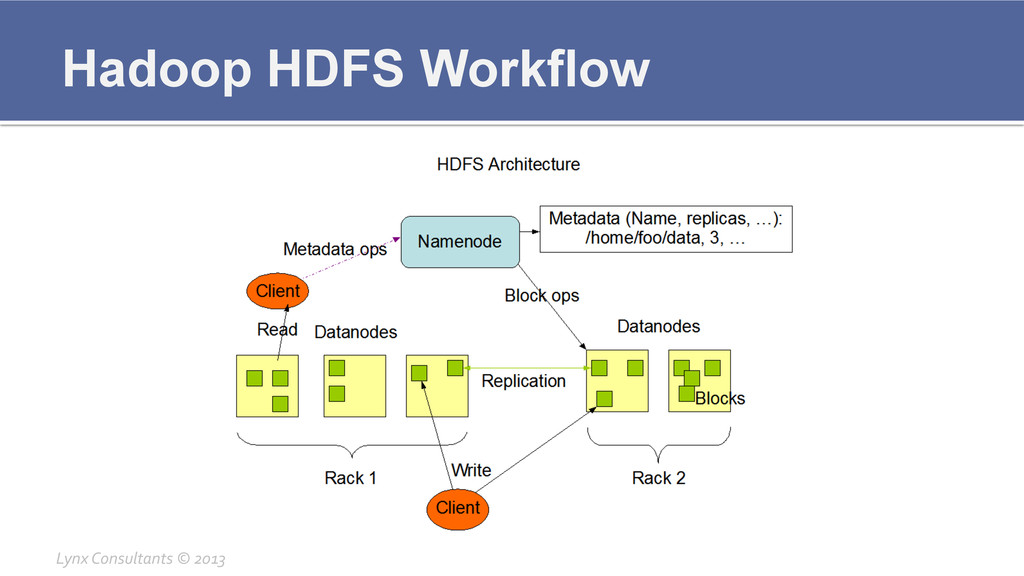
▪ Keeps track of all file allocation on Datanodes ▪ Rebalances data if one of the namenodes goes down ▪ Is Rack aware § Secondary Namenode ▪ Does cleanup services for the namenode ▪ Not necessarily two different servers § Datanode ▪ Stores the data ▪ Good to have not RAID disks for extra I/O speed Lynx Consultants © 2013
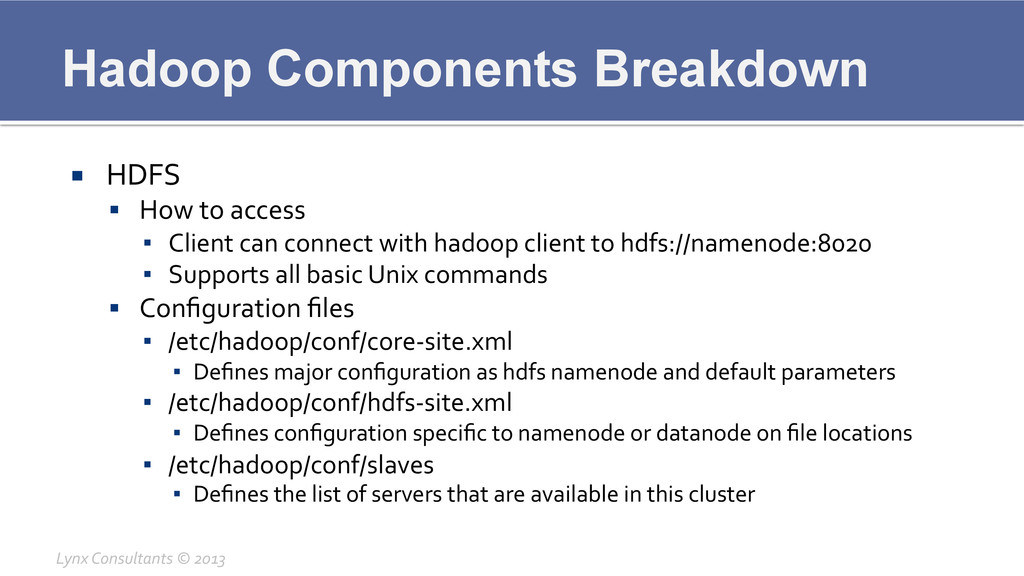
Hadoop Components Breakdown ¡ HDFS § How to access
▪ Client can connect with hadoop client to hdfs://namenode:8020 ▪ Supports all basic Unix commands § Configuration files ▪ /etc/hadoop/conf/core-‐site.xml ▪ Defines major configuration as hdfs namenode and default parameters ▪ /etc/hadoop/conf/hdfs-‐site.xml ▪ Defines configuration specific to namenode or datanode on file locations ▪ /etc/hadoop/conf/slaves ▪ Defines the list of servers that are available in this cluster Lynx Consultants © 2013
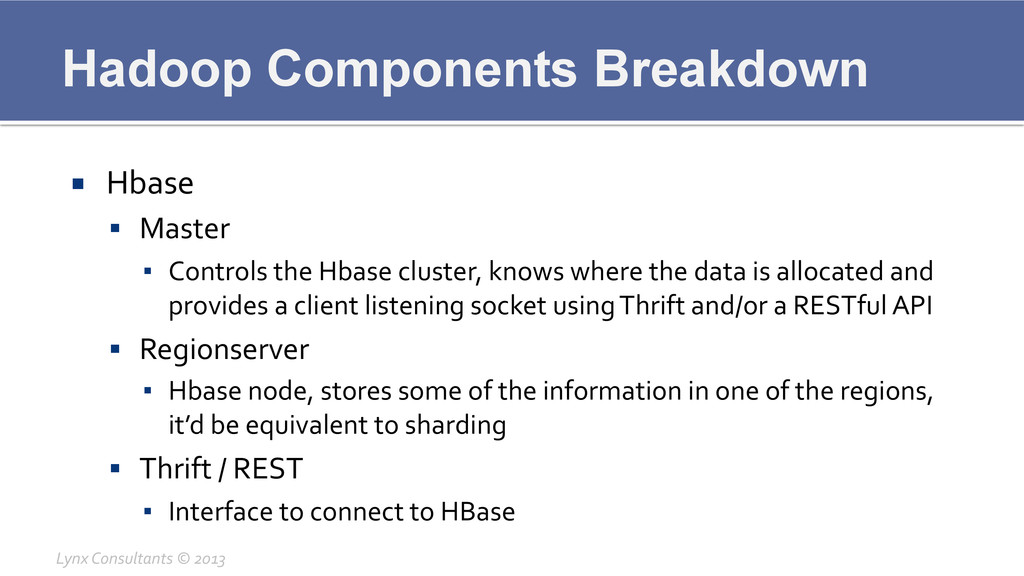
Hadoop Components Breakdown ¡ Hbase § Master ▪
Controls the Hbase cluster, knows where the data is allocated and provides a client listening socket using Thrift and/or a RESTful API § Regionserver ▪ Hbase node, stores some of the information in one of the regions, it’d be equivalent to sharding § Thrift / REST ▪ Interface to connect to HBase Lynx Consultants © 2013
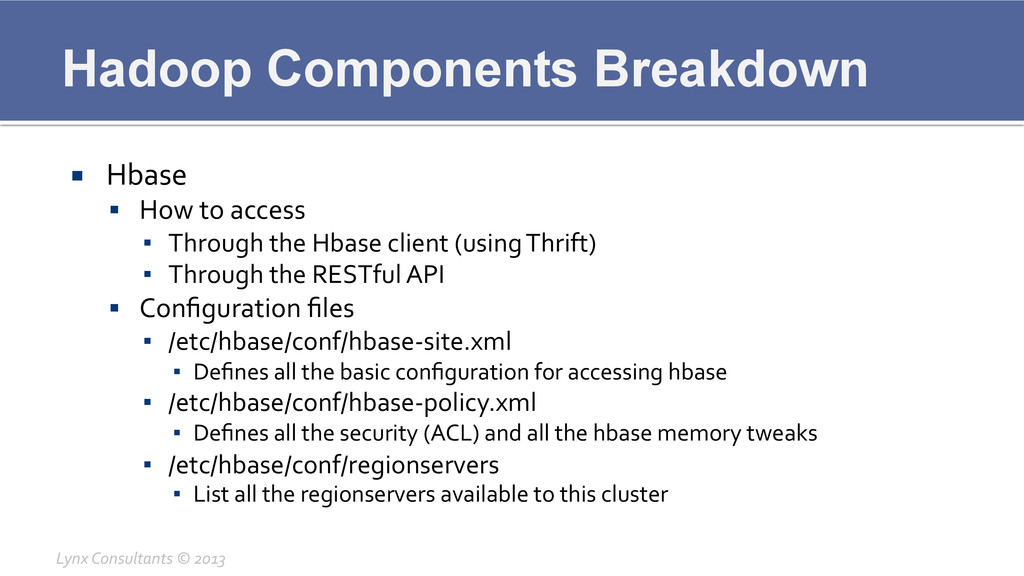
Hadoop Components Breakdown ¡ Hbase § How to access
▪ Through the Hbase client (using Thrift) ▪ Through the RESTful API § Configuration files ▪ /etc/hbase/conf/hbase-‐site.xml ▪ Defines all the basic configuration for accessing hbase ▪ /etc/hbase/conf/hbase-‐policy.xml ▪ Defines all the security (ACL) and all the hbase memory tweaks ▪ /etc/hbase/conf/regionservers ▪ List all the regionservers available to this cluster Lynx Consultants © 2013
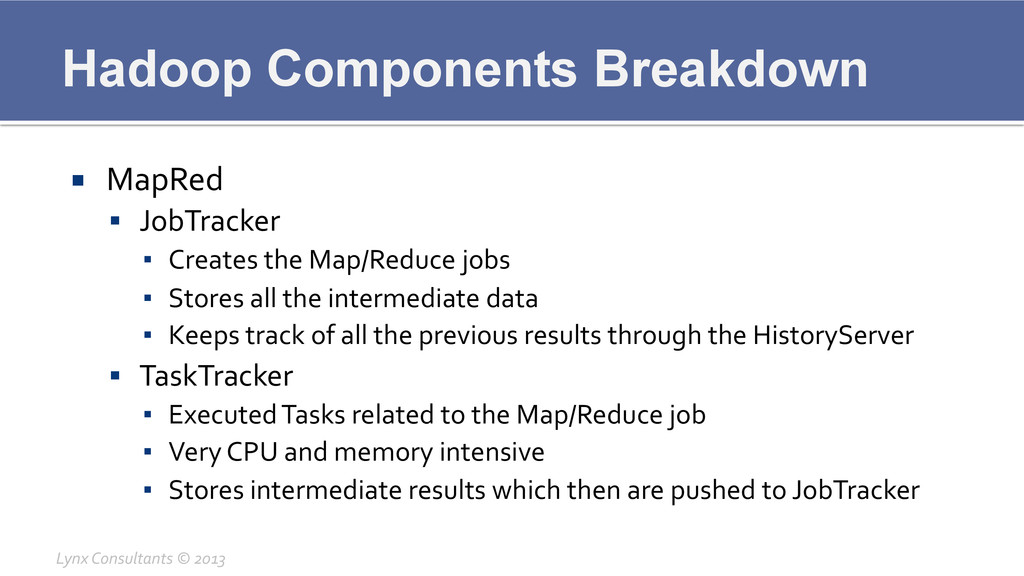
Hadoop Components Breakdown ¡ MapRed § JobTracker ▪
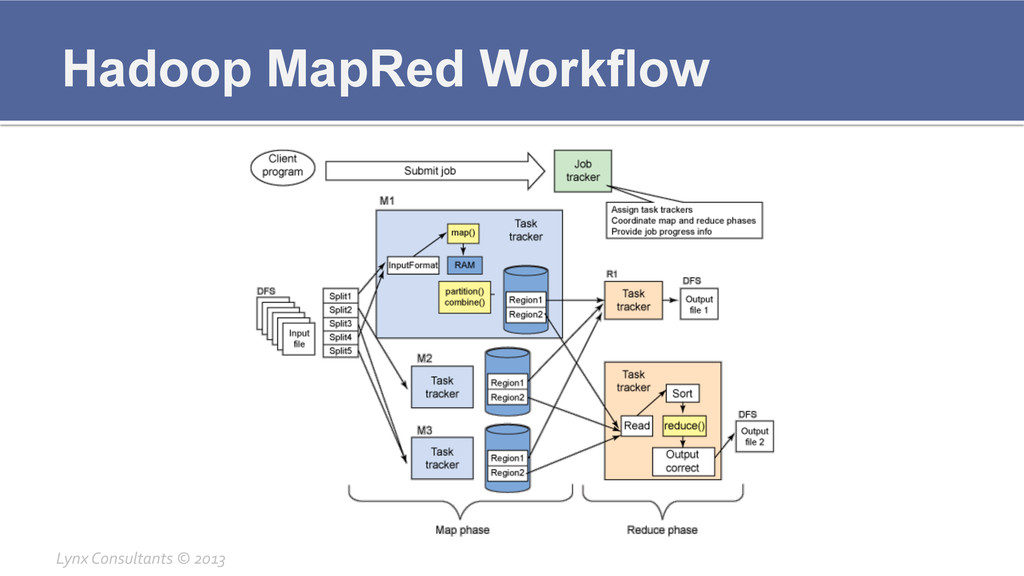
Creates the Map/Reduce jobs ▪ Stores all the intermediate data ▪ Keeps track of all the previous results through the HistoryServer § TaskTracker ▪ Executed Tasks related to the Map/Reduce job ▪ Very CPU and memory intensive ▪ Stores intermediate results which then are pushed to JobTracker Lynx Consultants © 2013
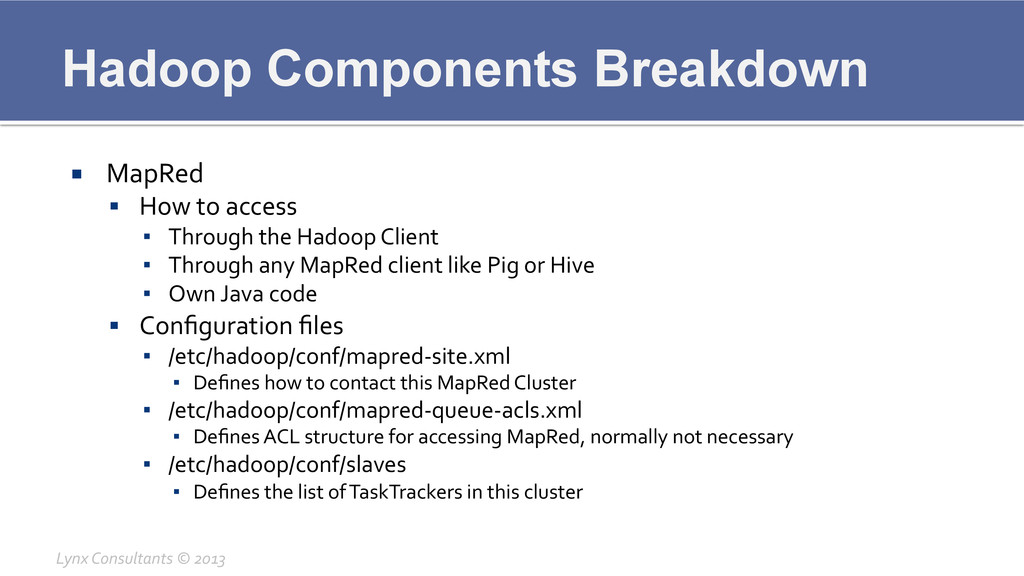
Hadoop Components Breakdown ¡ MapRed § How to access
▪ Through the Hadoop Client ▪ Through any MapRed client like Pig or Hive ▪ Own Java code § Configuration files ▪ /etc/hadoop/conf/mapred-‐site.xml ▪ Defines how to contact this MapRed Cluster ▪ /etc/hadoop/conf/mapred-‐queue-‐acls.xml ▪ Defines ACL structure for accessing MapRed, normally not necessary ▪ /etc/hadoop/conf/slaves ▪ Defines the list of TaskTrackers in this cluster Lynx Consultants © 2013
Hadoop Components Breakdown ¡ YARN § Same structure as
MapRed (lives on top of it) § Configuration files ▪ /etc/hadoop/conf/yarn-‐site.xml ▪ All required configuration for YARN Lynx Consultants © 2013
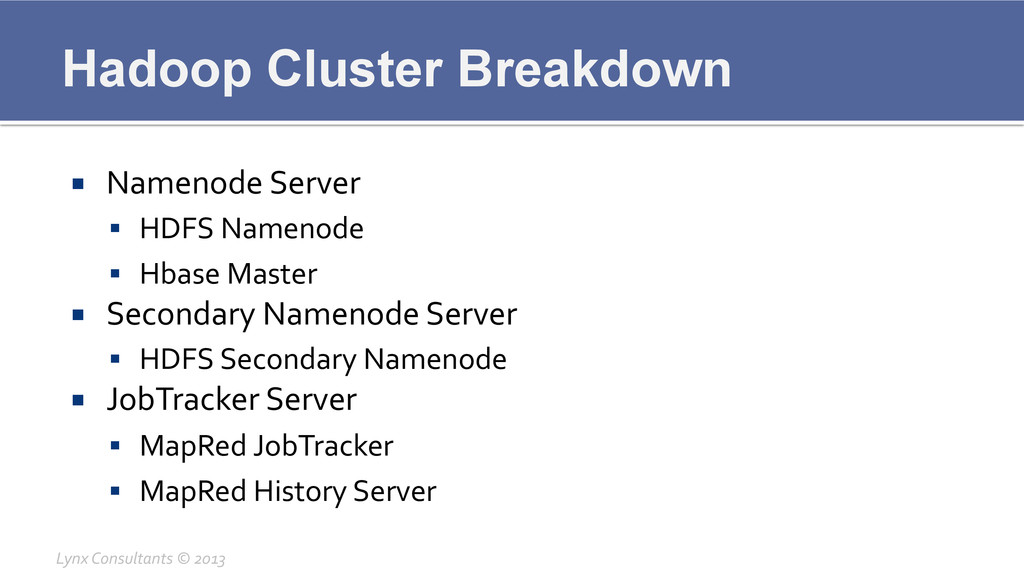
Hadoop Cluster Breakdown ¡ Namenode Server § HDFS Namenode
§ Hbase Master ¡ Secondary Namenode Server § HDFS Secondary Namenode ¡ JobTracker Server § MapRed JobTracker § MapRed History Server Lynx Consultants © 2013
Hadoop Cluster Breakdown ¡ Datanode Server § HDFS Datanode
§ Hbase RegionServer § MapRed TaskTracker Lynx Consultants © 2013
Hadoop Hardware Requirements ¡ Namenode Server § Redundant power
supplies § RAID1 Drives § Enough memory (16Gb) ¡ Secondary Namenode Server § Almost none Lynx Consultants © 2013
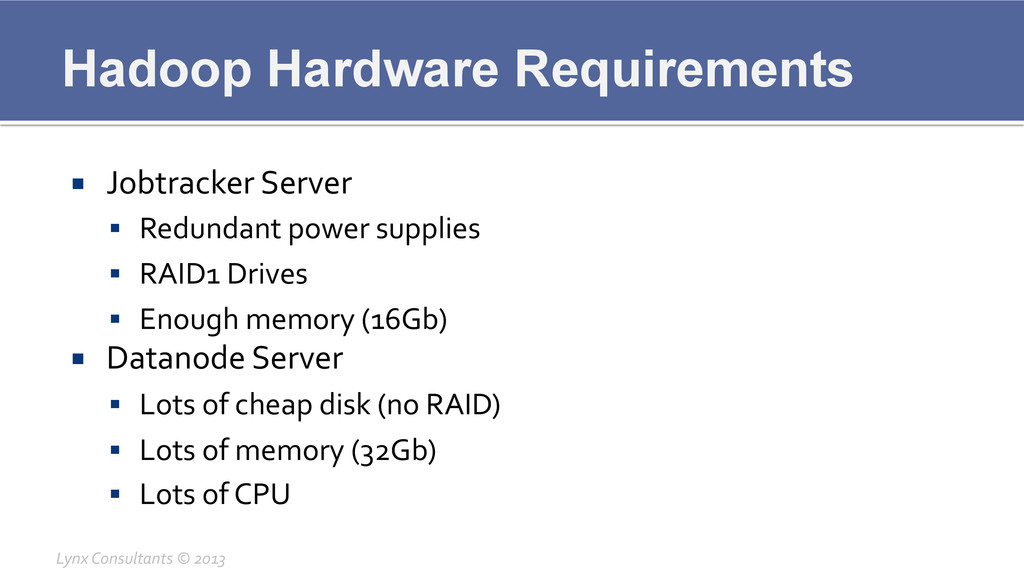
Hadoop Hardware Requirements ¡ Jobtracker Server § Redundant power
supplies § RAID1 Drives § Enough memory (16Gb) ¡ Datanode Server § Lots of cheap disk (no RAID) § Lots of memory (32Gb) § Lots of CPU Lynx Consultants © 2013
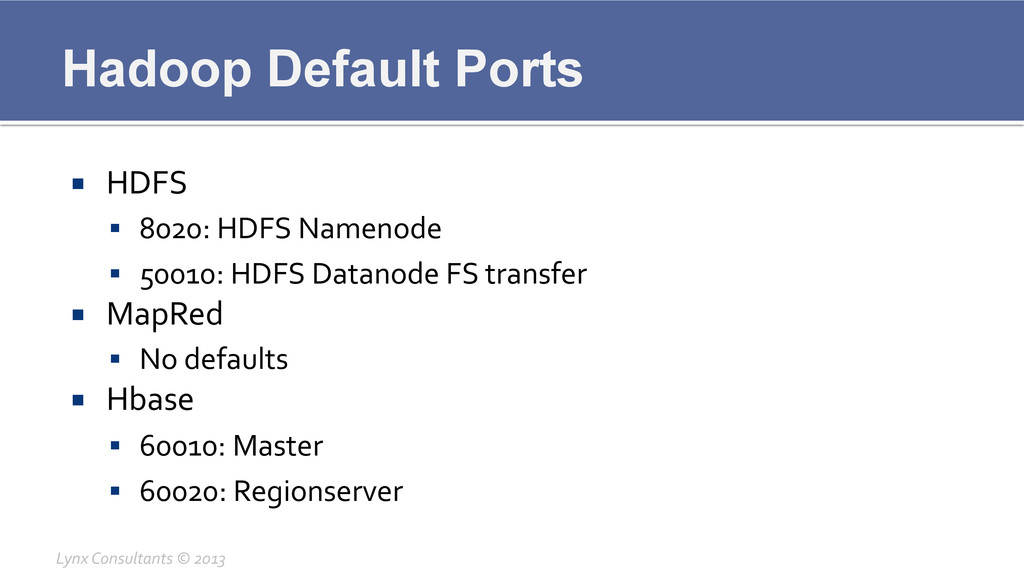
Hadoop Default Ports ¡ HDFS § 8020: HDFS Namenode
§ 50010: HDFS Datanode FS transfer ¡ MapRed § No defaults ¡ Hbase § 60010: Master § 60020: Regionserver Lynx Consultants © 2013
Hadoop HDFS Workflow Lynx Consultants © 2013
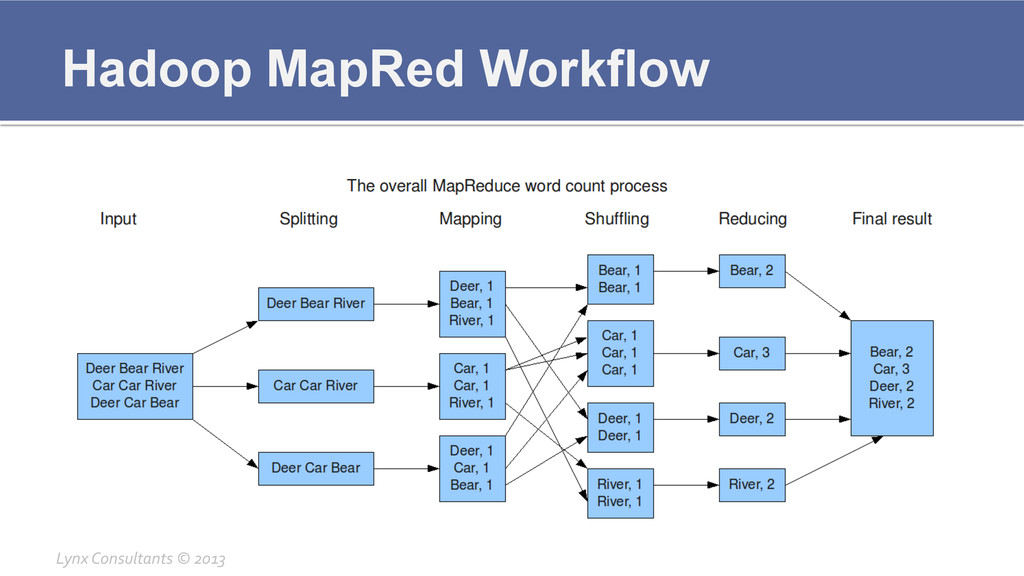
Hadoop MapRed Workflow Lynx Consultants © 2013
Hadoop MapRed Workflow Lynx Consultants © 2013
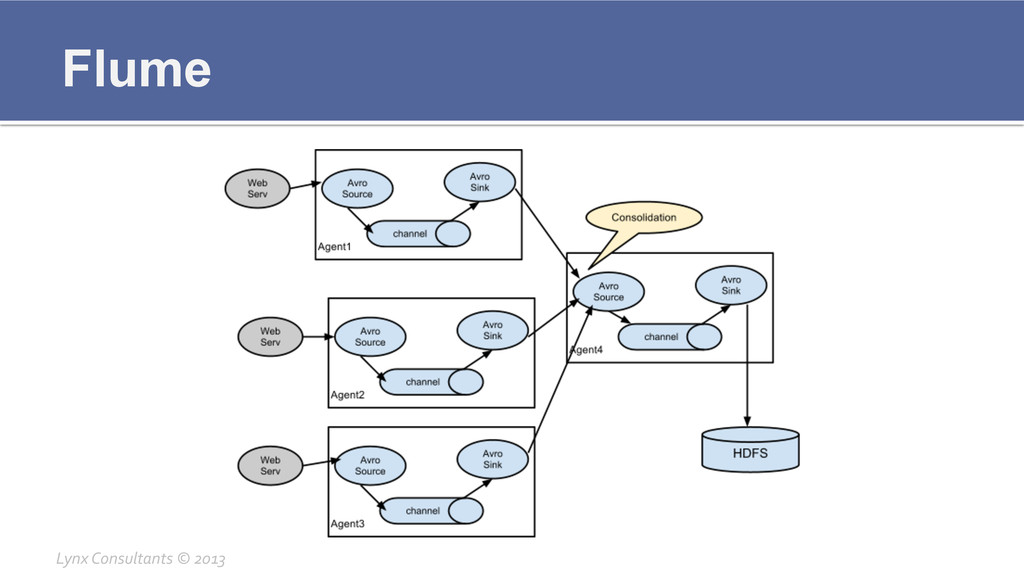
Flume ¡ Transports streams of data from point A to
point B ¡ Source § Where the data is read from ¡ Channel § How the data is buffered ¡ Sink § Where the data is written Lynx Consultants © 2013
Flume ¡ Flume is fault tolerant ¡ Sources are
pointer kept § With some exceptions, but most sources are in a known state ¡ Channels can be fault tolerant § Channel written to disk can recover from where it left ¡ Sinks can be redundant § More than one sink for the same data § Data is serialised and deduplicated using AVRO Lynx Consultants © 2013
Flume Lynx Consultants © 2013
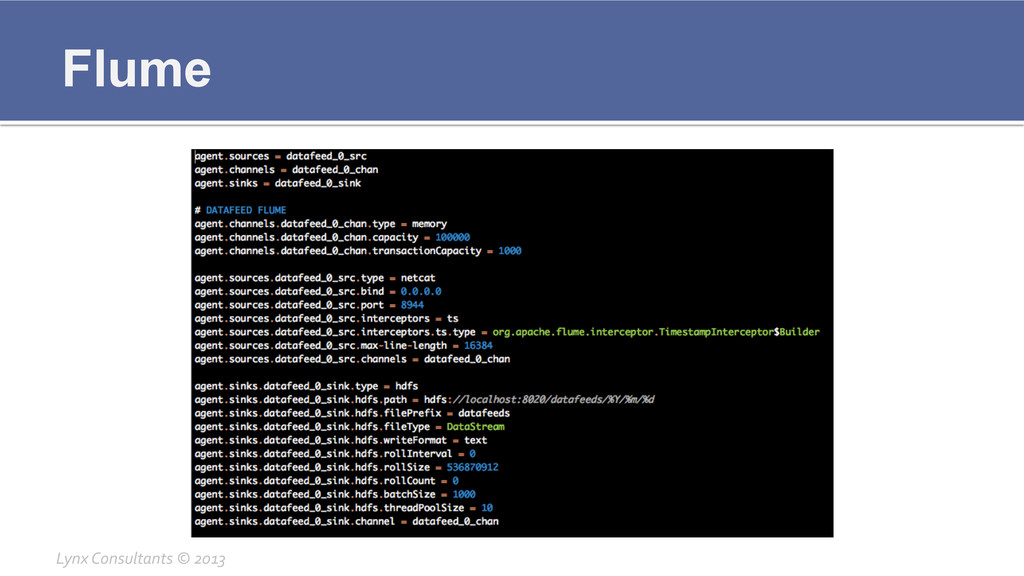
Flume ¡ Configuration files § /etc/flume-‐ng/conf/flume.conf ▪ Defines
the agent configuration with source, channel, sink Lynx Consultants © 2013
Flume Lynx Consultants © 2013
Hadoop Recommended Reads Lynx Consultants © 2013
Hadoop References ¡ Hadoop § http://hadoop.apache.org/docs/stable/cluster_setup.html § http://rc.cloudera.com/cdh/4/hadoop/hadoop-‐yarn/hadoop-‐yarn-‐site/
ClusterSetup.html § http://pig.apache.org/docs/r0.7.0/setup.html § http://wiki.apache.org/hadoop/NameNodeFailover ¡ Hbase § http://hbase.apache.org/book/book.html ¡ Flume § http://archive.cloudera.com/cdh4/cdh/4/flume-‐ng/ FlumeUserGuide.html Lynx Consultants © 2013
Questions? Lynx Consultants © 2013


 lynxman
 shunsock
 shimastripe
 o3
 i35_267
 m3m0r7
 nttcom
 yutanonaka
 kawaguti
 visional_engineering_and_design
 tatetate55
 nwiizo
 kekekenta
 portentint
 tmiket
 rasmusluckow
 erikaheidi
 akademiya2063
 katiecoart
 marktimemedia
 marketingsoph
 chikuwait
 chrislema
 tammyeverts
 skipperchong