Share
Embed
Netty Internals - Optimizations everywhere
Talk given at Line Dev Meetup 2018 in Tokyo and Netty Meetup @ Google in March 2018
Norman Maurer
February 27, 2018
Transcript
28 slides
-
ABOUT ME NORMAN MAURER ▸ Netty Project Lead ▸ Java
Champion ▸ Cassandra MVP ▸ Apache Software Foundation ▸ Working on large-scale Network Services / Frameworks -
WHAT IS NETTY THE ASYNCHRONOUS NETWORK FRAMEWORK FOR THE JVM
▸ General purpose network framework ▸ Low-level ▸ Tries to hide many optimisations from the end- user so they not need to care about all of it ▸ “easy to use” Optimize all the things -
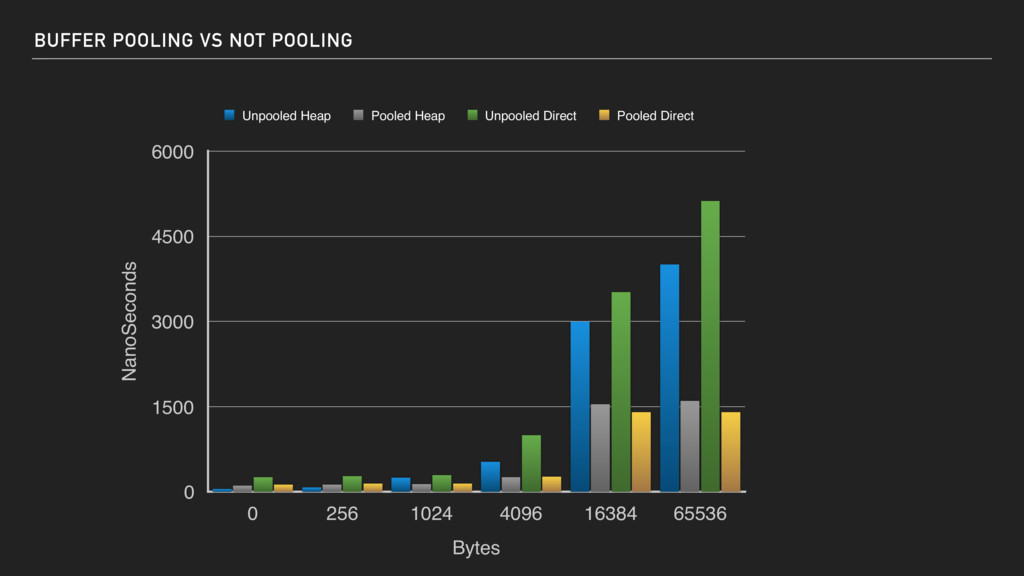
BUFFER POOLING VS NOT POOLING NanoSeconds 0 1500 3000 4500
6000 Bytes 0 256 1024 4096 16384 65536 Unpooled Heap Pooled Heap Unpooled Direct Pooled Direct -
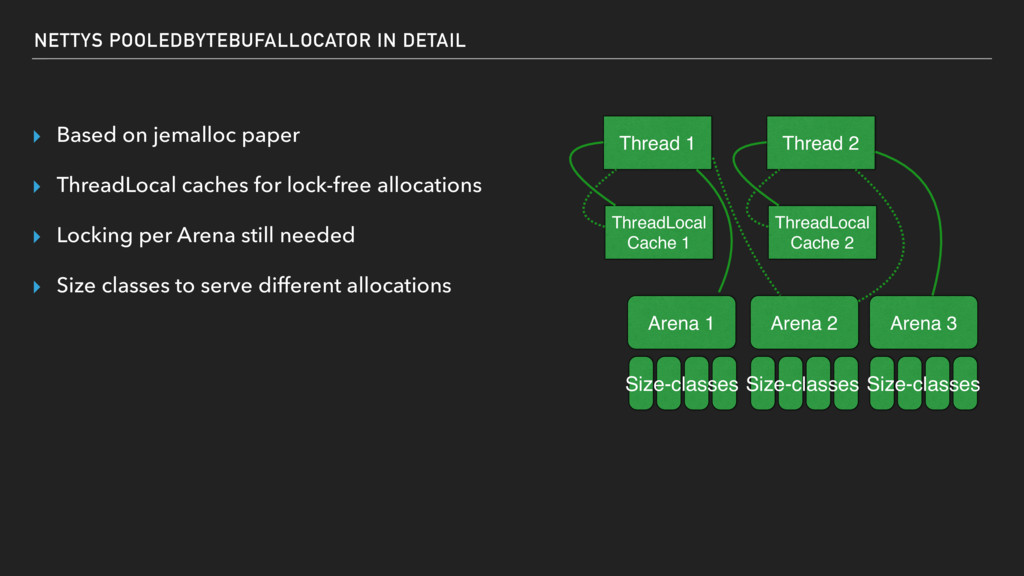
NETTYS POOLEDBYTEBUFALLOCATOR IN DETAIL ▸ Based on jemalloc paper ▸
ThreadLocal caches for lock-free allocations ▸ Locking per Arena still needed ▸ Size classes to serve different allocations ThreadLocal Cache 2 Arena 1 Arena 2 Arena 3 Size-classes Size-classes Size-classes Thread 2 ThreadLocal Cache 1 Thread 1 -
WHY IS BUFFER POOLING SO IMPORTANT ? ▸ Allocating and
deallocating of direct buffers is expensive ▸ Memory fragmentation ▸ applications often have a “constant” allocation pattern -
ALLOCATIONS OF BYTEBUFFER ▸ Generally allocations of ByteBuffer is expensive
because the storage will be zero’ed out ▸ This is true for direct but also heap buffers (and in general for byte[] allocations). -
SPEED UP DIRECT MEMORY ALLOCATIONS! SUN.MISC.UNSAFE TO THE RESCUE ▸
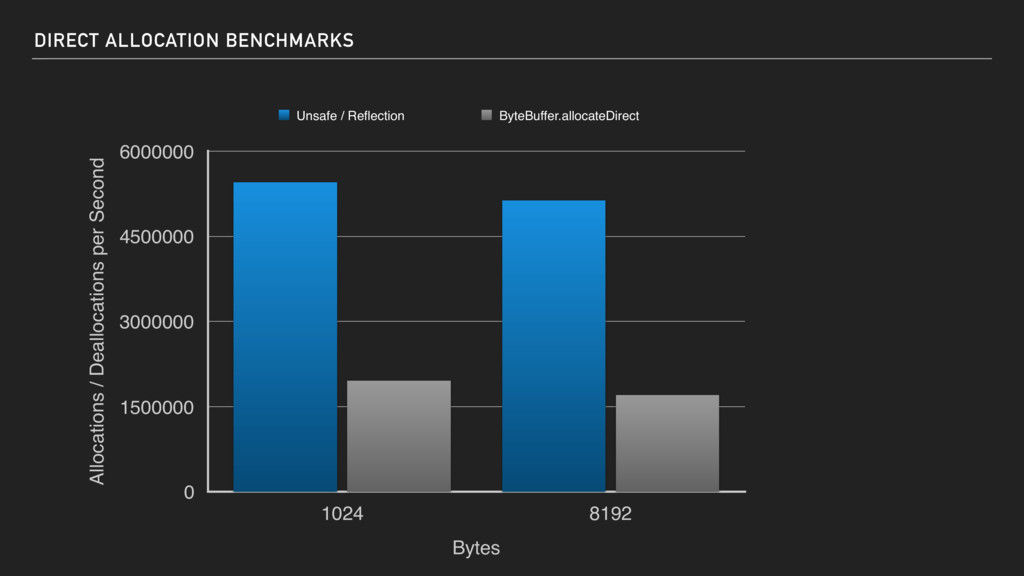
Use JNI to allocate the direct ByteBuffer ▸ Unfortunately too slow as calling JNI is “expensive” ▸ Use Unsafe to allocate direct memory and use reflect to create ByteBuffer from the memory ▸ Works very well but needs to use Unsafe and reflection (which breaks on Java9+) ▸ Need explicit to release direct memory as GC will not take care! -
DIRECT ALLOCATION BENCHMARKS Allocations / Deallocations per Second 0 1500000
3000000 4500000 6000000 Bytes 1024 8192 Unsafe / Reflection ByteBuffer.allocateDirect -
SPEED UP HEAP MEMORY ALLOCATIONS! JDK.INTERNAL.MISC.UNSAFE TO THE RESCUE ▸
Use jdk.internal.misc.Unsafe to allocate byte[] and use ByteBuffer.wrap(…) to create ByteBuffer that is heap based. ▸ Only works on Java9+ and needs to be “allowed” with JVM startup argument ( —add- opens java/base/jdk.internal.misc=ALL-UNNAMED) -
BYTE[] ALLOCATION BENCHMARK Nanoseconds per Allocation 0 3000 6000 9000
12000 Bytes 100 1000 10000 100000 new byte[...] Unsafe.allocateUninitializedArray(...) -
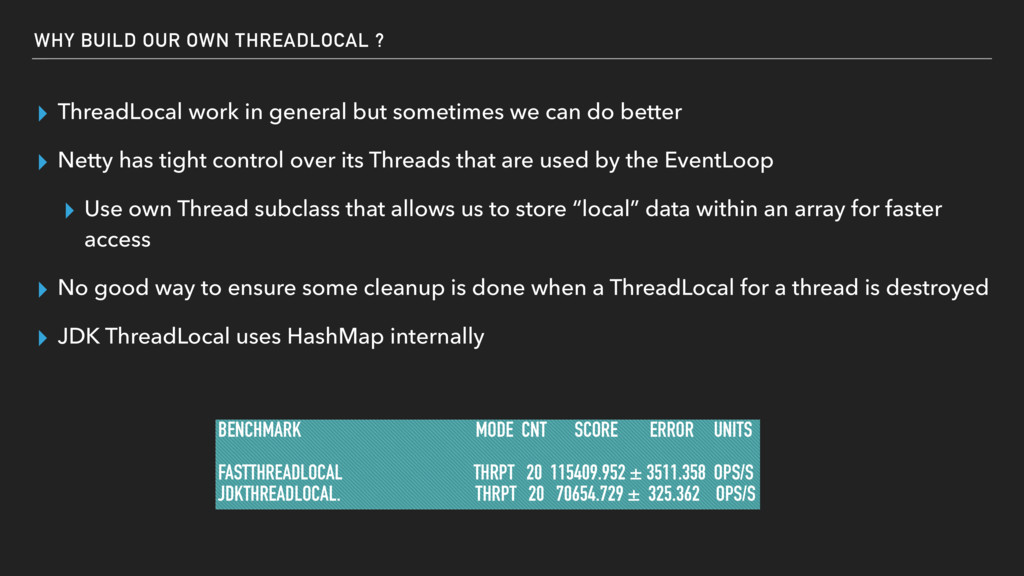
WHY BUILD OUR OWN THREADLOCAL ? ▸ ThreadLocal work in
general but sometimes we can do better ▸ Netty has tight control over its Threads that are used by the EventLoop ▸ Use own Thread subclass that allows us to store “local” data within an array for faster access ▸ No good way to ensure some cleanup is done when a ThreadLocal for a thread is destroyed ▸ JDK ThreadLocal uses HashMap internally BENCHMARK MODE CNT SCORE ERROR UNITS FASTTHREADLOCAL THRPT 20 115409.952 ± 3511.358 OPS/S JDKTHREADLOCAL. THRPT 20 70654.729 ± 325.362 OPS/S -
HOW TO USE FASTTHREADLOCAL ? ▸ Ensure you use the
DefaultThreadFactory provided by Netty or use FastThreadLocalThread ▸ Replace ThreadLocal with FastThreadLocal ▸ Win! ▸ Gotchas ? There are always some :( ▸ Using FastThreadLocal from a “NON” FastThreadLocalThread gives a ca 20% perf drop Doh! Why are there always gotchas!?!? -
SSL IN JAVA IS SLOW :( ▸ SSL implementation shipped
with Java is slow :( ▸ Its becoming better and better tho ▸ Most people will tell you that you should never terminate SSL in Java :/ Why we can’t have nice things ?!? -
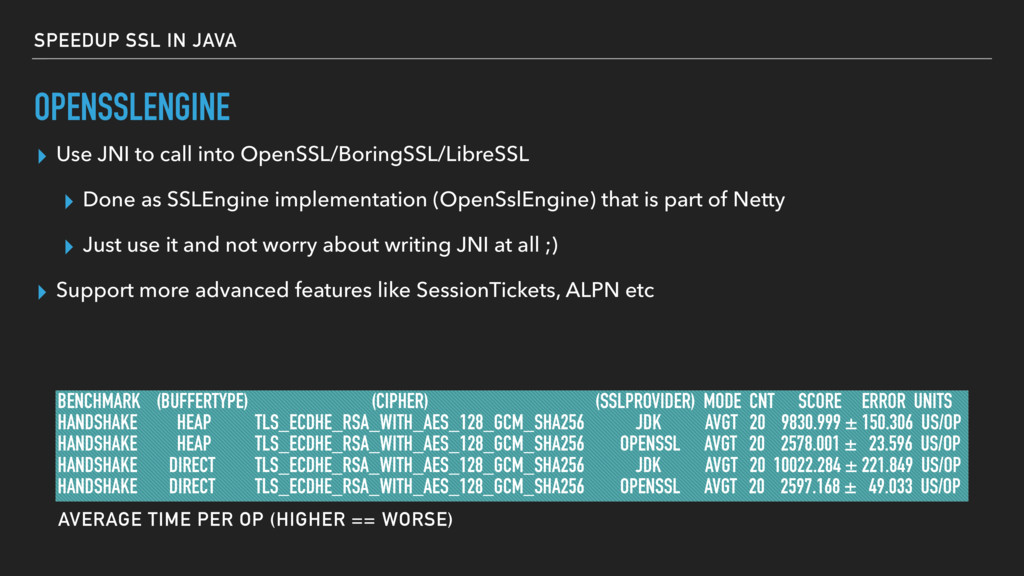
SPEEDUP SSL IN JAVA ▸ Use JNI to call into
OpenSSL/BoringSSL/LibreSSL ▸ Done as SSLEngine implementation (OpenSslEngine) that is part of Netty ▸ Just use it and not worry about writing JNI at all ;) ▸ Support more advanced features like SessionTickets, ALPN etc BENCHMARK (BUFFERTYPE) (CIPHER) (SSLPROVIDER) MODE CNT SCORE ERROR UNITS HANDSHAKE HEAP TLS_ECDHE_RSA_WITH_AES_128_GCM_SHA256 JDK AVGT 20 9830.999 ± 150.306 US/OP HANDSHAKE HEAP TLS_ECDHE_RSA_WITH_AES_128_GCM_SHA256 OPENSSL AVGT 20 2578.001 ± 23.596 US/OP HANDSHAKE DIRECT TLS_ECDHE_RSA_WITH_AES_128_GCM_SHA256 JDK AVGT 20 10022.284 ± 221.849 US/OP HANDSHAKE DIRECT TLS_ECDHE_RSA_WITH_AES_128_GCM_SHA256 OPENSSL AVGT 20 2597.168 ± 49.033 US/OP OPENSSLENGINE AVERAGE TIME PER OP (HIGHER == WORSE) -
NATIVE SSL ▸ You can use the SSLEngine implementation provided
by Netty even without Netty ▸ ….but you really should just use Netty ;) ▸ Alternative: Use Conscrypt as SSL provider. -
ALLOCATIONS / GC ▸ Allocations are not for free but
even worse is collecting the object ▸ The worst == finalize() ▸ Possible solutions: ▸ ThreadLocal (FastThreadLocal) ▸ Object-Pooling (Recycler) ▸ Just don’t allocate ?!? -
ALLOCATIONS / GC RECYCLER ▸ a “low-overhead” object pool ▸
Thread-safe ▸ Optimized for offer and poll from within the same Thread ▸ Because its the most likely thing to happen within Netty ▸ Used in multiple places in Netty: ▸ ByteBuf instances ▸ Tasks that are scheduled from outside the EventLoop -
MEMORY OVERHEAD ▸ Unfortunately Java is very memory heavy :(
▸ Object header overhead ▸ Everything (beside primitive types) will be stored as reference ▸ Possible workarounds: ▸ Extend objects when possible (for internal classes) ▸ Use alternatives that operate on primitives