Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Quantifying Memorization in Continual Pre-train...

Quantifying Memorization in Continual Pre-training with Japanese General or Industry-Specific Corpora

Quantifying Memorization in Continual Pre-training with Japanese General or Industry-Specific Corpora
Hiromu Takahashi and Shotaro Ishihara
The First Workshop on Large Language Model Memorization
Aug 1st, 2025
https://aclanthology.org/2025.l2m2-1.8/

Shotaro Ishihara

July 24, 2025

Transcript

12 slides
  1. Hiromu Takahashi and Shotaro Ishihara (Nikkei) The First Workshop on

    Large Language Model Memorization Aug 1st, 2025 https://aclanthology.org/2025.l2m2-1.8/ Quantifying Memorization in Continual Pre-training with Japanese General or Industry-Specific Corpora
  2. Memorization may cause the issues 1. Privacy, security, etc. 2.

    Copyright, novelty, etc. 3. Validity of evaluations, data contamination, etc. 2
  3. As a news media responsibility, we explore the LLM memorization

    What happens by LLM memorization, especially for the domain-specific settings. • Quantifying LLM memorization trained with the news ◦ Pre-training from scratch and continual pre-training • Survey of memorization • Analyzing generative recommendations from memorization 3
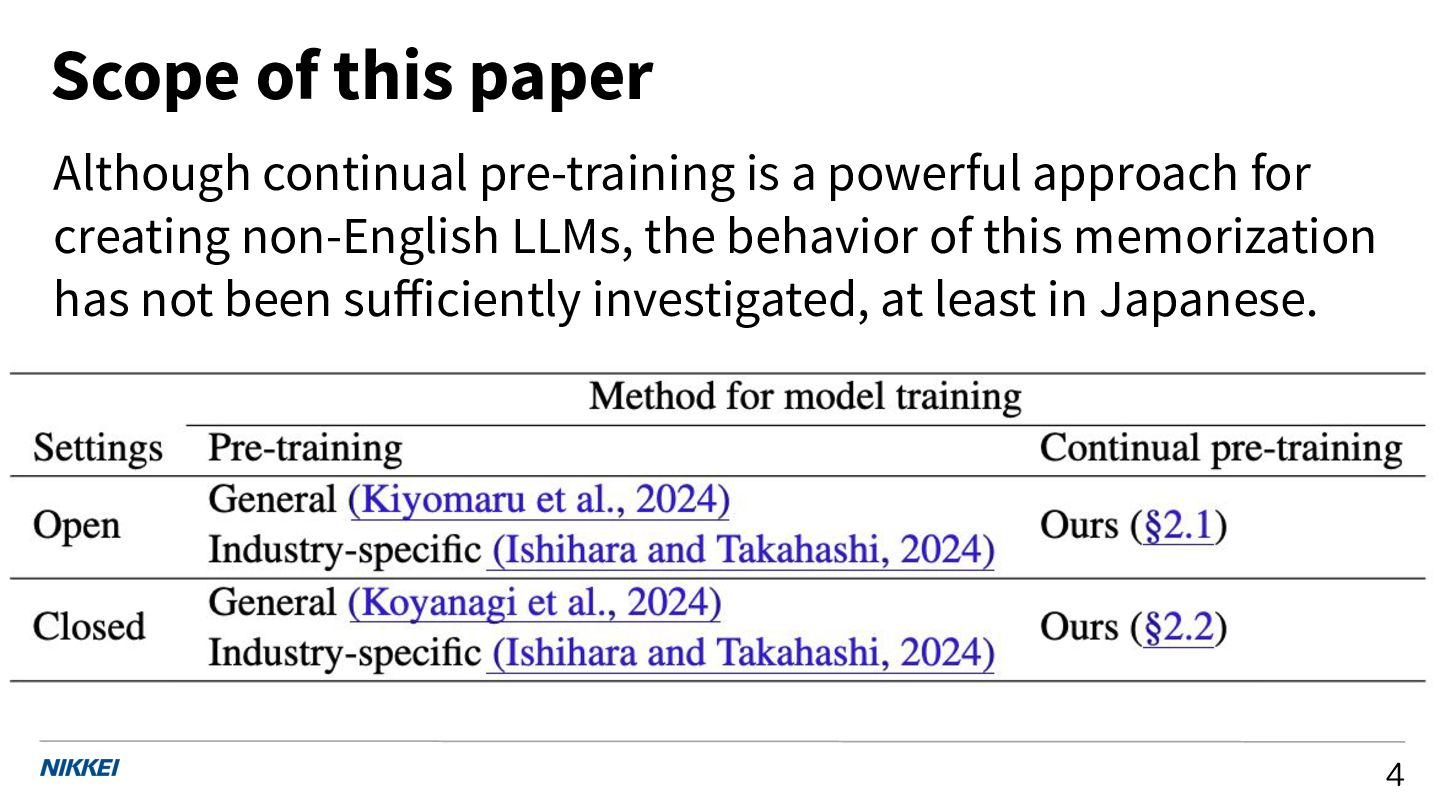
  4. Scope of this paper Although continual pre-training is a powerful

    approach for creating non-English LLMs, the behavior of this memorization has not been sufficiently investigated, at least in Japanese. 4
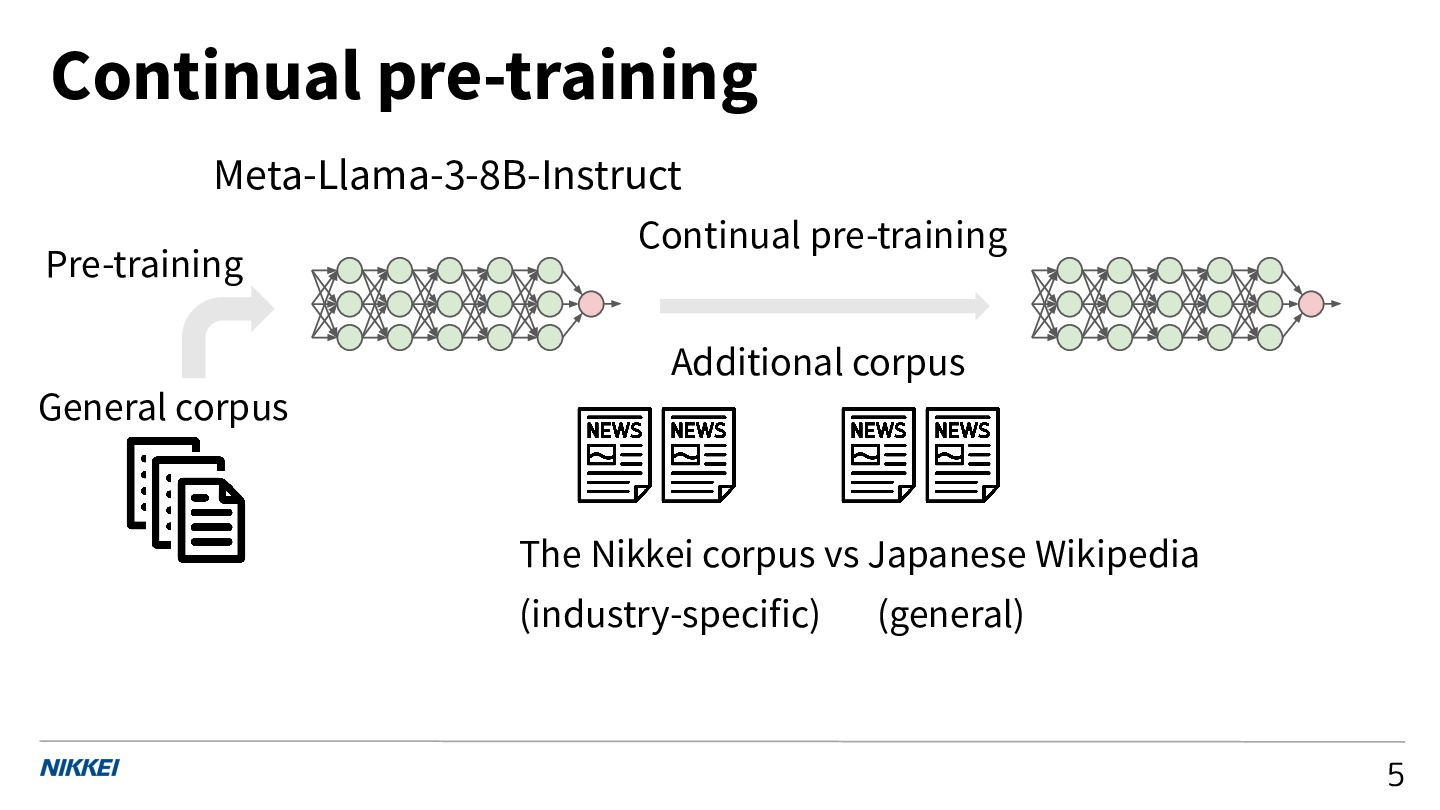
  5. Continual pre-training 5 Meta-Llama-3-8B-Instruct Additional corpus General corpus Pre-training Continual

    pre-training The Nikkei corpus vs Japanese Wikipedia (industry-specific) (general)
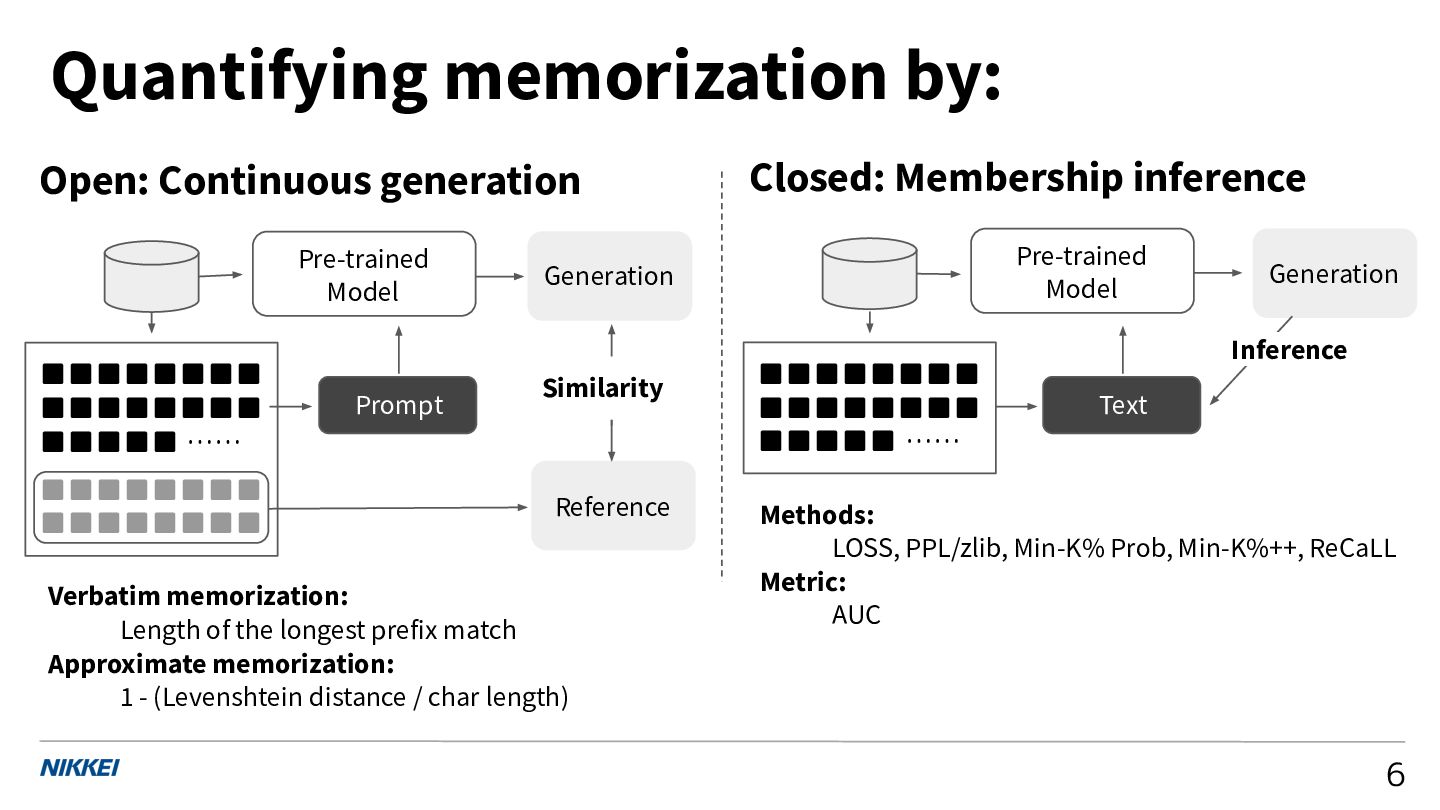
  6. Methods: LOSS, PPL/zlib, Min-K% Prob, Min-K%++, ReCaLL Metric: AUC Quantifying

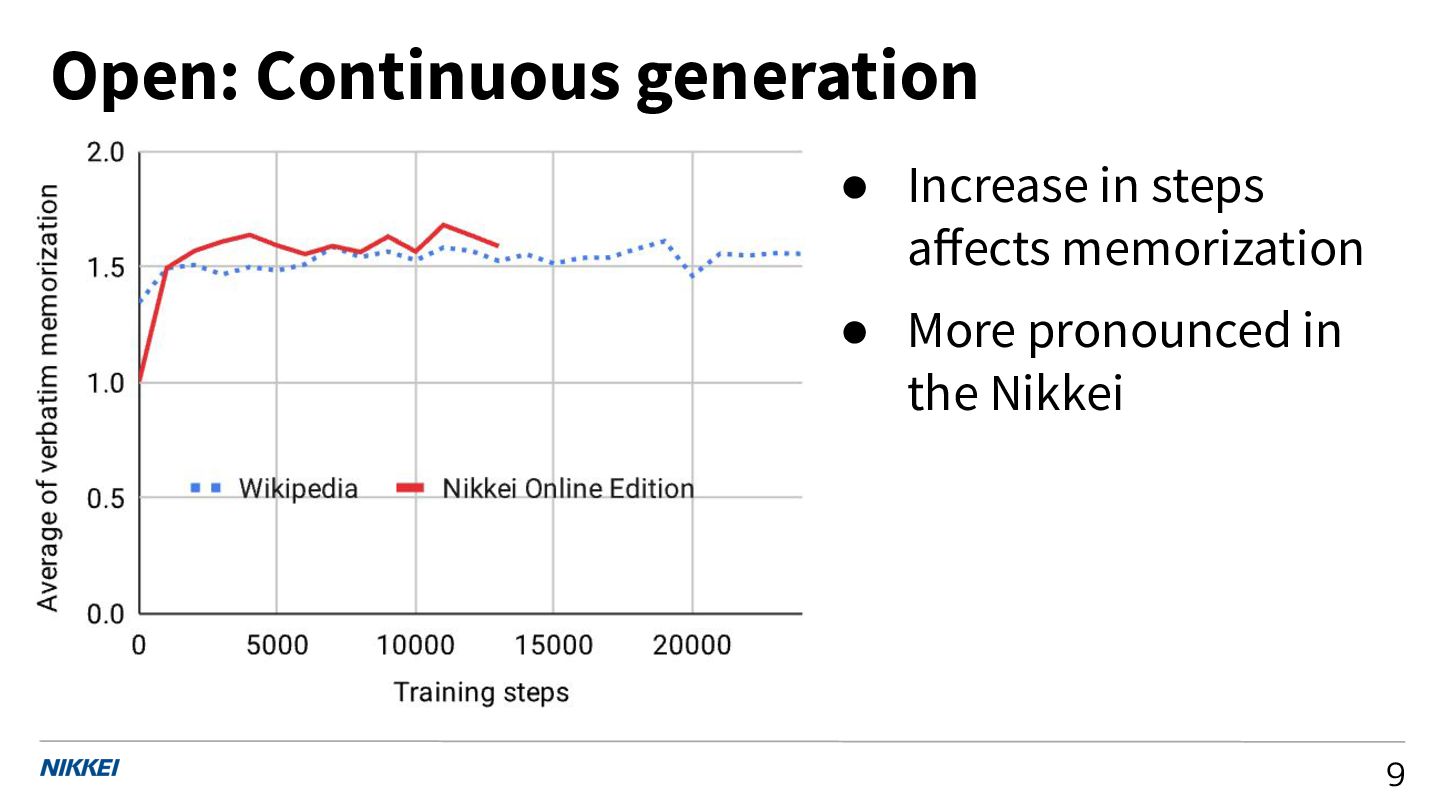
    memorization by: Pre-trained Model Prompt Generation Reference Similarity ▪▪▪▪▪▪▪▪ ▪▪▪▪▪▪▪▪ ▪▪▪▪▪ …… ▪▪▪▪▪▪▪▪ ▪▪▪▪▪▪▪▪ ▪▪▪▪▪▪▪▪ ▪▪▪▪▪▪▪▪ ▪▪▪▪▪ …… Pre-trained Model Generation Inference Closed: Membership inference Open: Continuous generation Text 6 Verbatim memorization: Length of the longest prefix match Approximate memorization: 1 - (Levenshtein distance / char length)
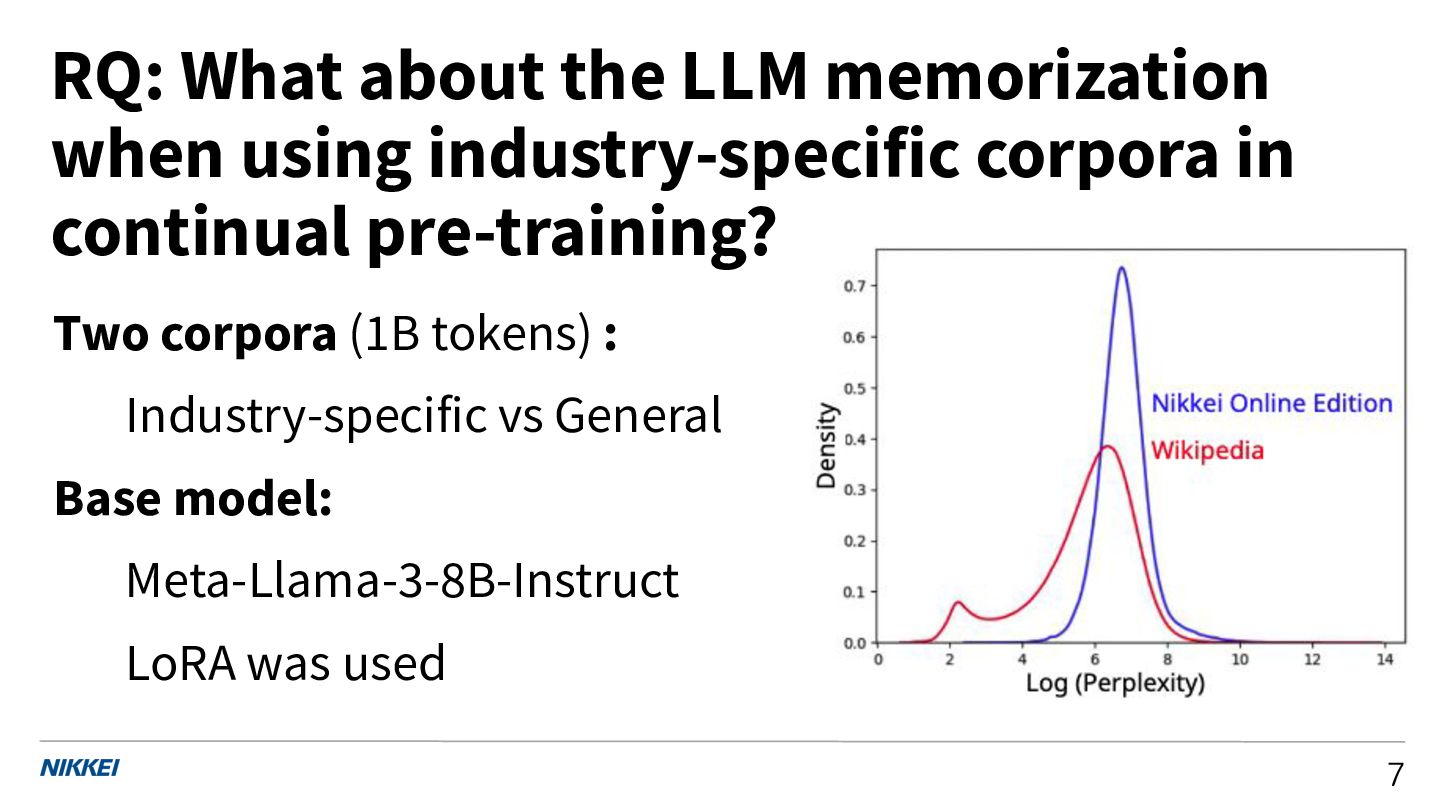
  7. RQ: What about the LLM memorization when using industry-specific corpora

    in continual pre-training? Two corpora (1B tokens) : Industry-specific vs General Base model: Meta-Llama-3-8B-Instruct LoRA was used 7
  8. Key findings: 1. The tendency of memorization in continual pre-training

    with industry-specific corpus was demonstrated to be consistent with the empirical findings in general English, in many cases. 2. Memorization was particularly pronounced when using the industry-specific corpus, which highlights the risks of using non-general industry corpora. 3. We discovered that methods that work well in English do not necessarily work in Japanese, revealing the need for a detailed analysis of each language. 8
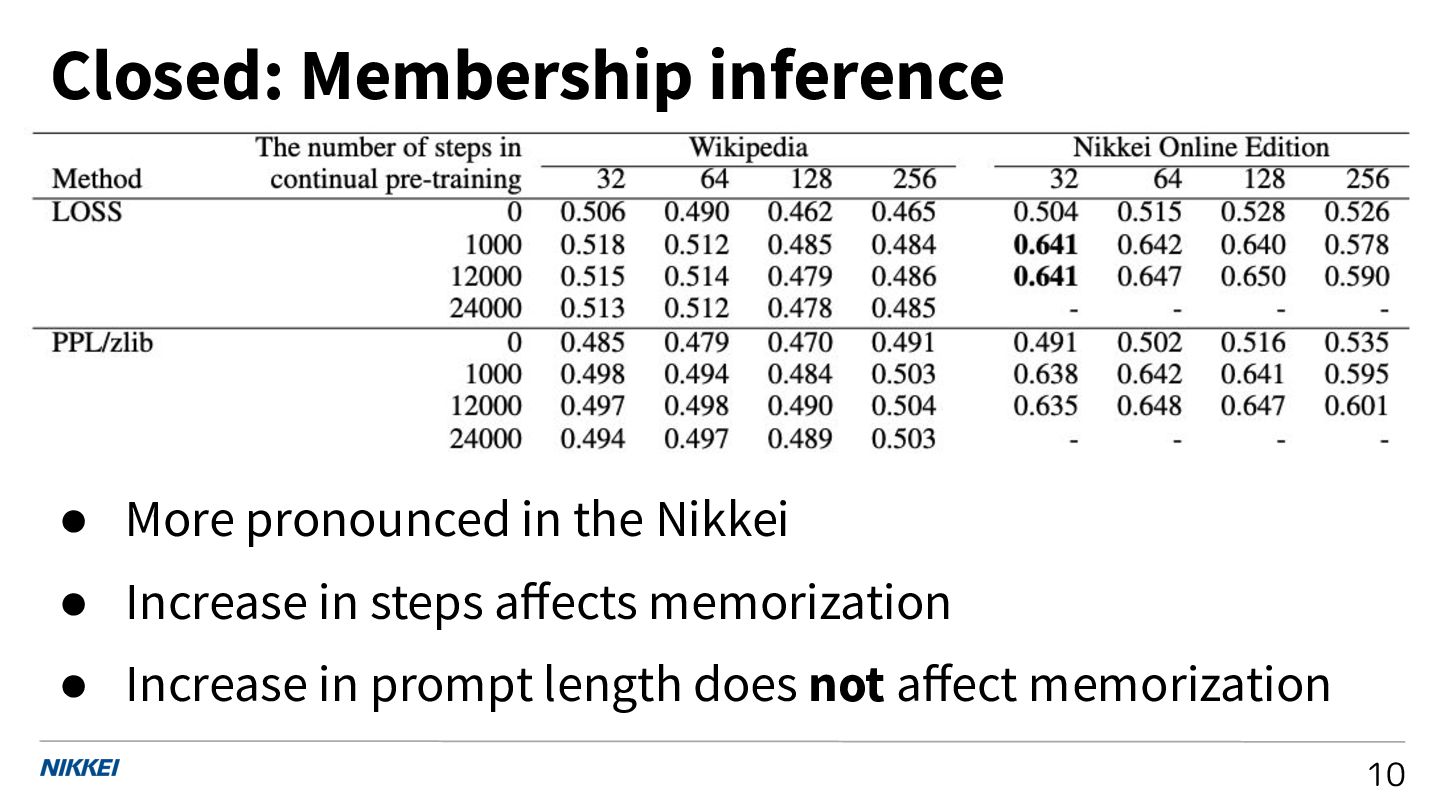
  9. Closed: Membership inference 10 • More pronounced in the Nikkei

    • Increase in steps affects memorization • Increase in prompt length does not affect memorization
  10. Features of membership inference method • Bigger K works better

    in Min-K % Prob, though K=20 showed good performance in English. • Text alternating methods such as ReCaLL performed best, possibly because it capture language-specific properties. 11
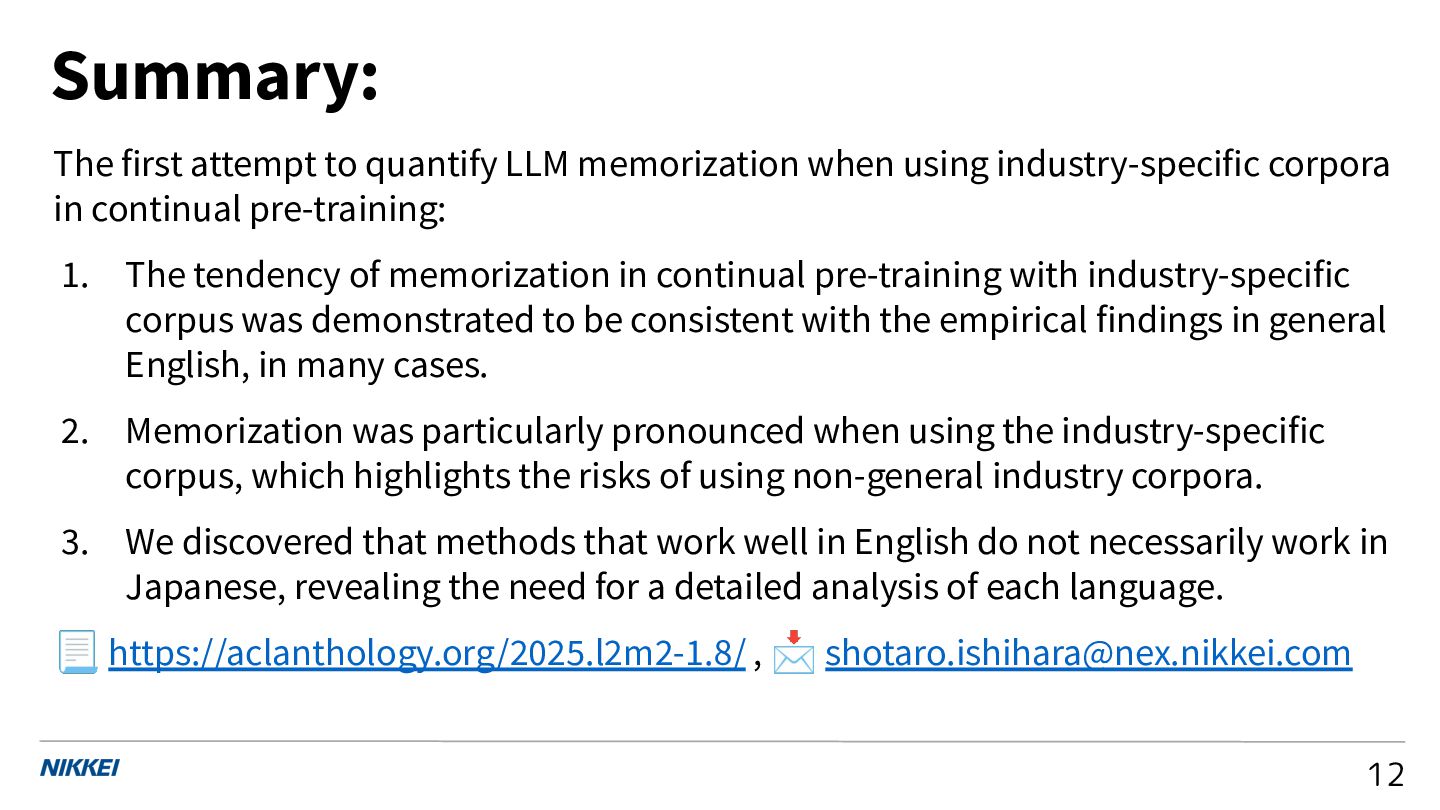
  11. Summary: The first attempt to quantify LLM memorization when using

    industry-specific corpora in continual pre-training: 1. The tendency of memorization in continual pre-training with industry-specific corpus was demonstrated to be consistent with the empirical findings in general English, in many cases. 2. Memorization was particularly pronounced when using the industry-specific corpus, which highlights the risks of using non-general industry corpora. 3. We discovered that methods that work well in English do not necessarily work in Japanese, revealing the need for a detailed analysis of each language. 📃 https://aclanthology.org/2025.l2m2-1.8/ , 📩 [email protected] 12

More Decks by Shotaro Ishihara

Other Decks in Research