Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
論文紹介:∞-former: Infinite Memory Transformer
Search
yuri
September 20, 2022
Research
450
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
論文紹介:∞-former: Infinite Memory Transformer
第14回最先端NLP勉強会(2022年9月26日、27日)@お茶大 発表用資料
yuri
September 20, 2022
More Decks by yuri
See All by yuri
データ指向モデリング「テキストマイニングの基礎」
yuri00
0
46
論文紹介:What In-Context Learning “Learns” In-Context: Disentangling Task Recognition and Task Learning
yuri00
0
660
論文紹介:Learning Dependency-Based Compositional Semantics
yuri00
0
170
論文紹介:What Context Features Can Transformer Language Models Use?
yuri00
0
490
Other Decks in Research
See All in Research
論文読み会 SNLP2026 Tau2-Bench: Evaluating Conversational Agents in a Dual-Control Environment
s_mizuki_nlp
0
320
Local Development Companies Network - National Conference 2026
ldcn
0
140
最先端NLP勉強会2026 論文紹介:Reasoning with Sampling: Your Base Model is Smarter Than You Think (ICLR 2026 paper)
kogoro
4
870
Easy to Guess, Hard to Verify: Lessons from AIMO 3 for Olympiad-Level AI Mathematics
corochann
0
140
Kaggle|AI Agent Security — しくじり先生、俺みたいになるな
pomcho555
1
130
全国町字単位空き家率推定データver1.0データ仕様
microbaseinc
0
300
Bilan travail en élevage : première restitution des enquêtes 2025-2026
institutdelelevage
PRO
0
130
生成AIなんでも展示会vol6 LT登壇資料 NexteraBERT
rikkabotan7
0
210
GeoAgent勉強会 論文紹介と強い推論モデルが与えるインパクト
satai
5
440
幾何学的深層学習入門 ~3次元構造と対称性を学習するニューラルネットワーク~
taniai
2
820
IA for theory
gpeyre
1
540
[最先端NLP勉強会2026] Checklists Are Better Than Reward Models For Aligning Language Models
nzw0301
1
340
Featured
See All Featured
Learning to Love Humans: Emotional Interface Design
aarron
275
41k
Game over? The fight for quality and originality in the time of robots
wayneb77
1
310
Facilitating Awesome Meetings
lara
57
7.2k
Prompt Engineering for Job Search
mfonobong
0
550
コードの90%をAIが書く世界で何が待っているのか / What awaits us in a world where 90% of the code is written by AI
rkaga
63
47k
Dominate Local Search Results - an insider guide to GBP, reviews, and Local SEO
greggifford
PRO
0
380
How To Speak Unicorn (iThemes Webinar)
marktimemedia
1
610
Ten Tips & Tricks for a 🌱 transition
stuffmc
1
270
Building Adaptive Systems
keathley
44
3.3k
The AI Revolution Will Not Be Monopolized: How open-source beats economies of scale, even for LLMs
inesmontani
PRO
3
3.8k
SEOcharity - Dark patterns in SEO and UX: How to avoid them and build a more ethical web
sarafernandez
0
310
<Decoding/> the Language of Devs - We Love SEO 2024
nikkihalliwell
1
370
Transcript
∞-former: Infinite Memory Transformer Pedro Henrique Martins, Zita Marinho, André
F. T. Martins ACL 2022 お茶大 村山友理
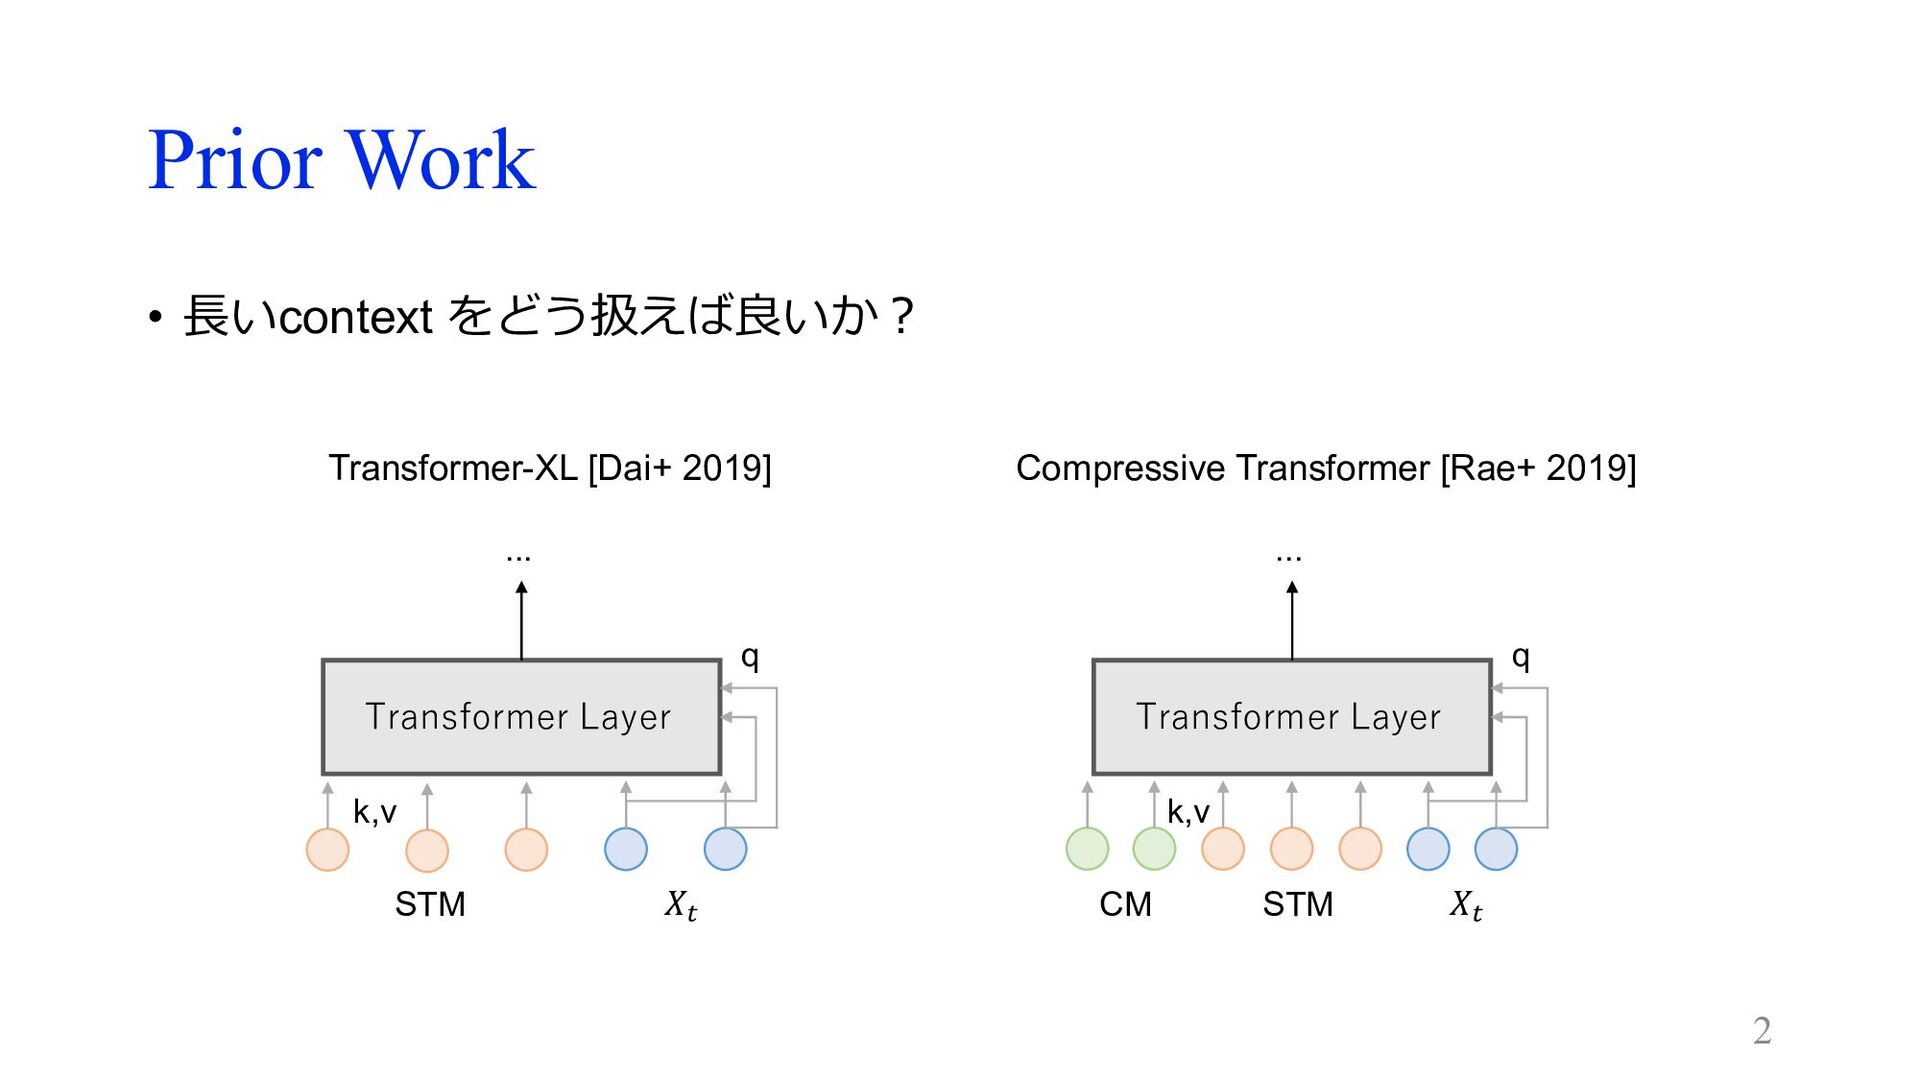
Prior Work • ⻑いcontext をどう扱えば良いか︖ 2 Transformer Layer 𝑋! STM
q k,v ... Transformer Layer 𝑋! STM CM q k,v ... Compressive Transformer [Rae+ 2019] Transformer-XL [Dai+ 2019]
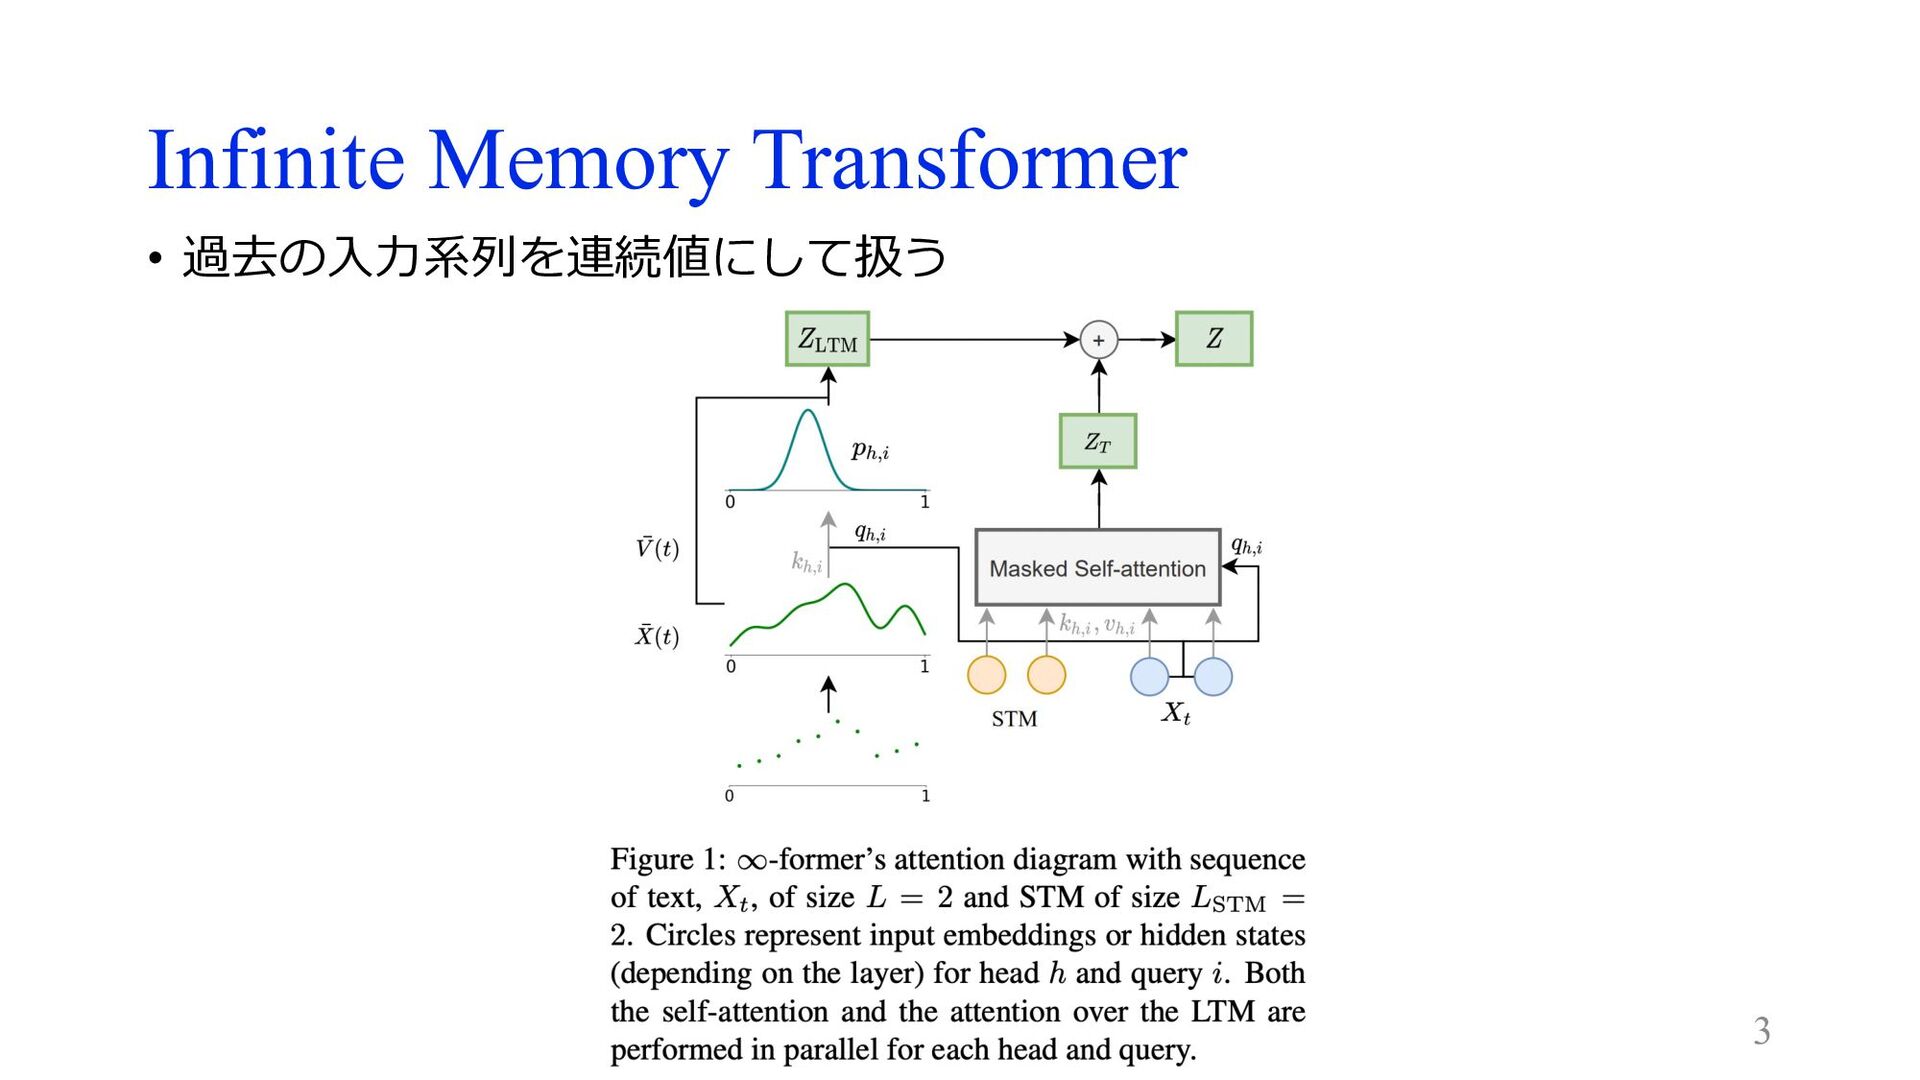
Infinite Memory Transformer • 過去の⼊⼒系列を連続値にして扱う 3
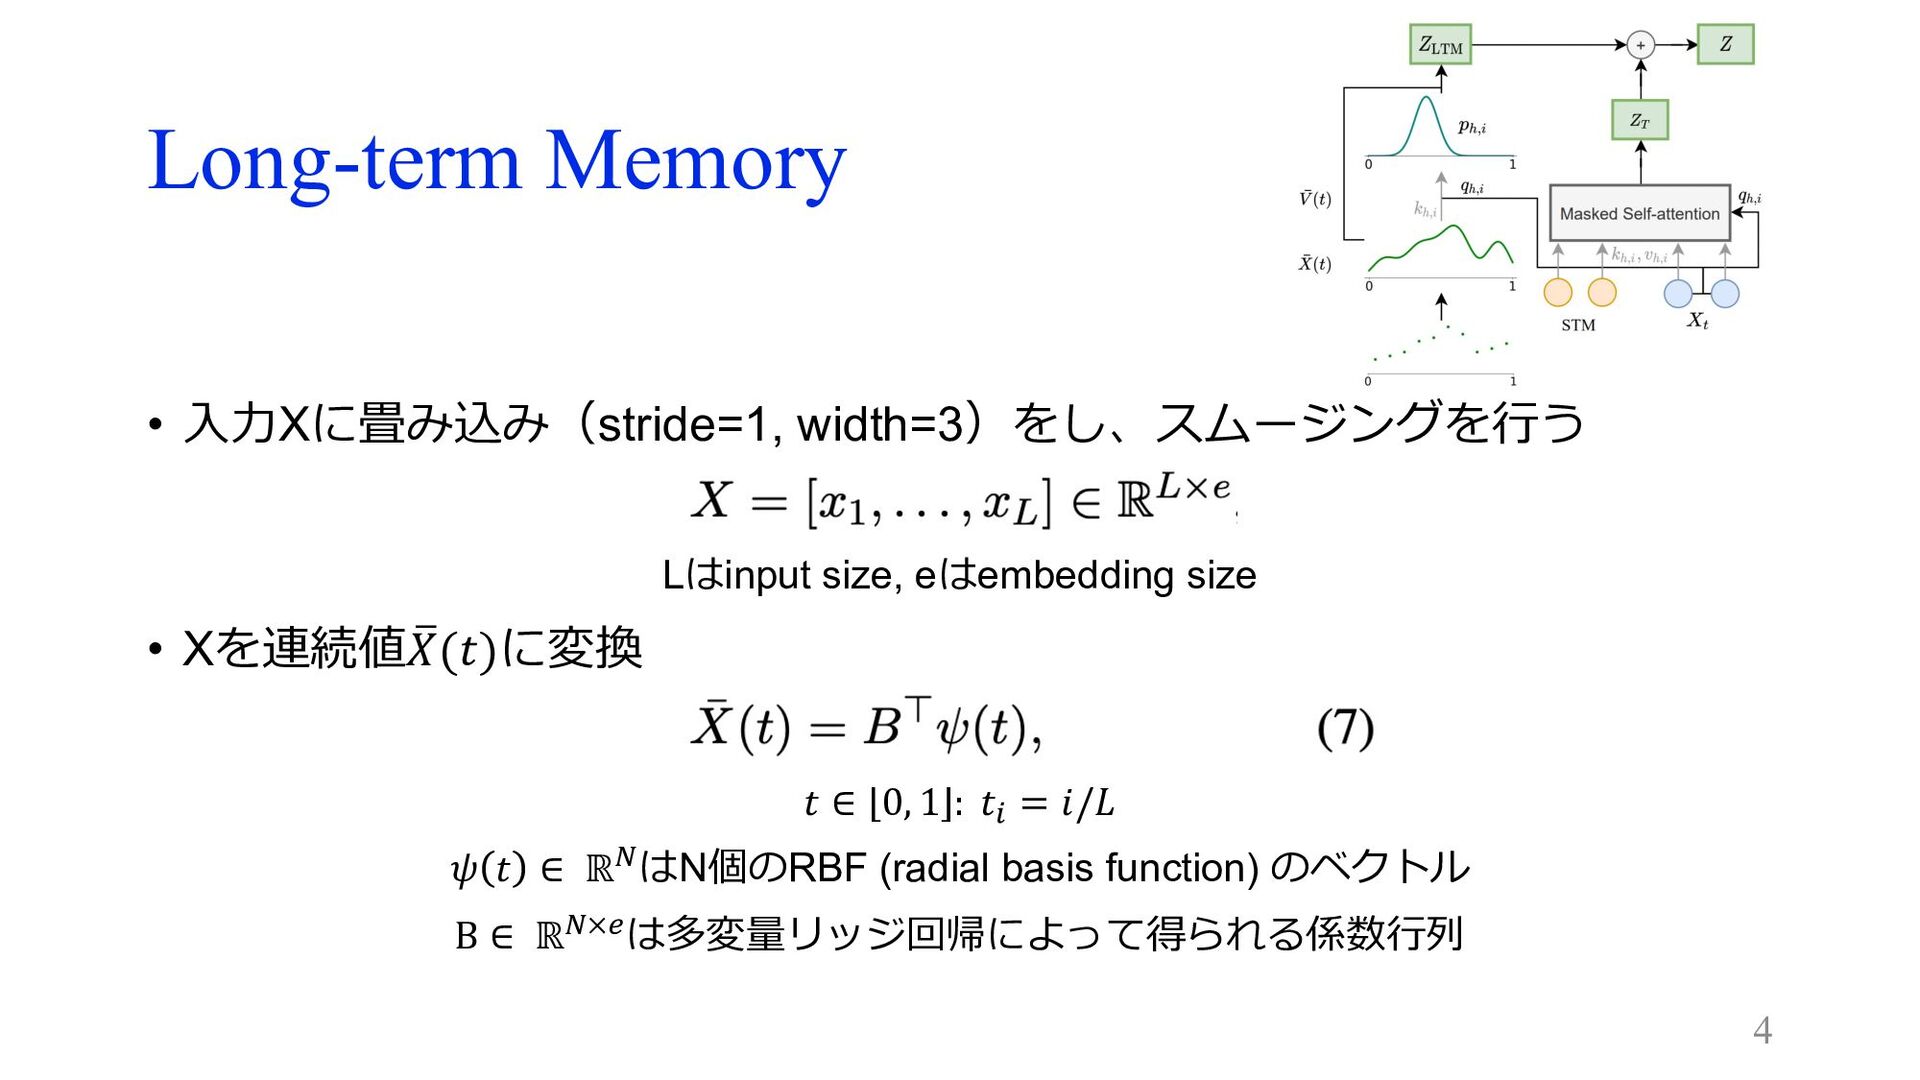
Long-term Memory • ⼊⼒Xに畳み込み(stride=1, width=3)をし、スムージングを⾏う Lはinput size, eはembedding size •
Xを連続値 ! 𝑋(𝑡)に変換 𝑡 ∈ 0, 1 : 𝑡! = 𝑖/𝐿 𝜓 𝑡 ∈ ℝ"はN個のRBF (radial basis function) のベクトル B ∈ ℝ"×$は多変量リッジ回帰によって得られる係数⾏列 4
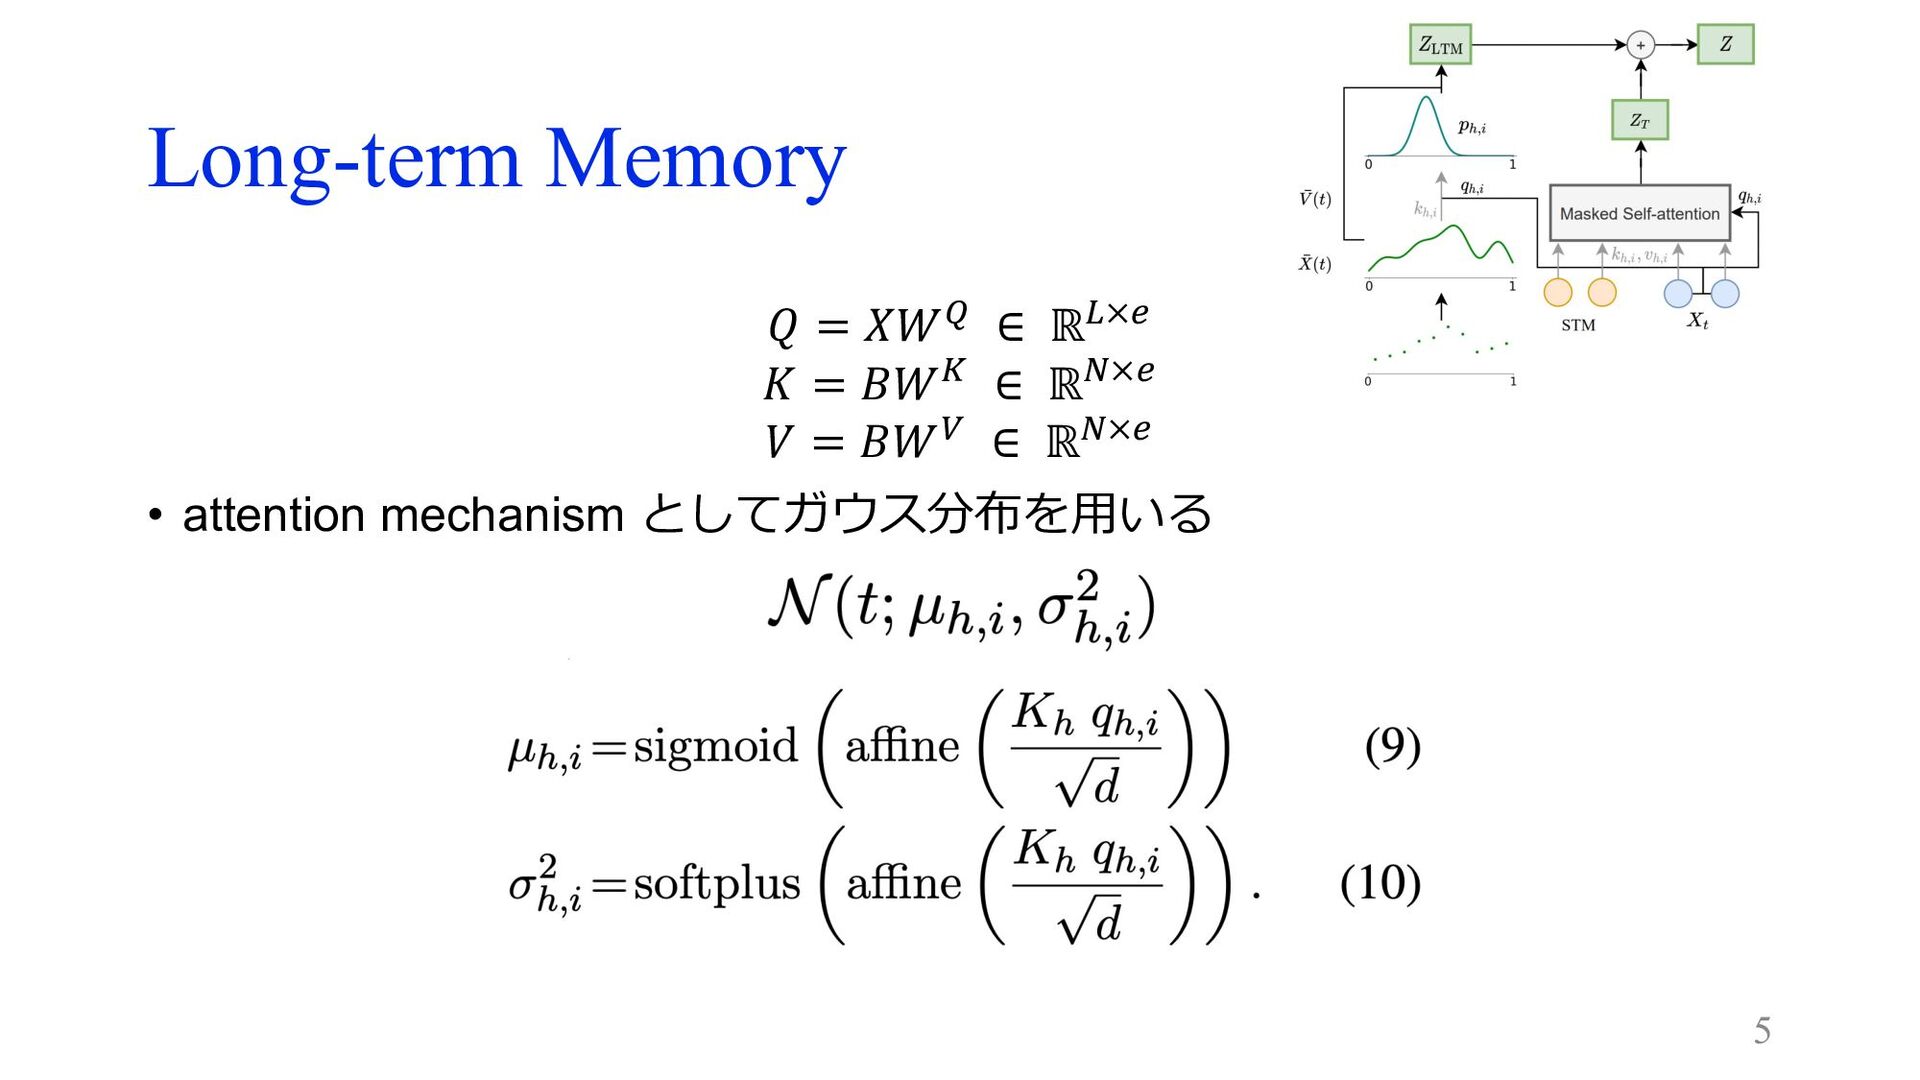
Long-term Memory 𝑄 = 𝑋𝑊" ∈ ℝ#×% 𝐾 = 𝐵𝑊&
∈ ℝ'×% 𝑉 = 𝐵𝑊( ∈ ℝ'×% • attention mechanism としてガウス分布を⽤いる 5
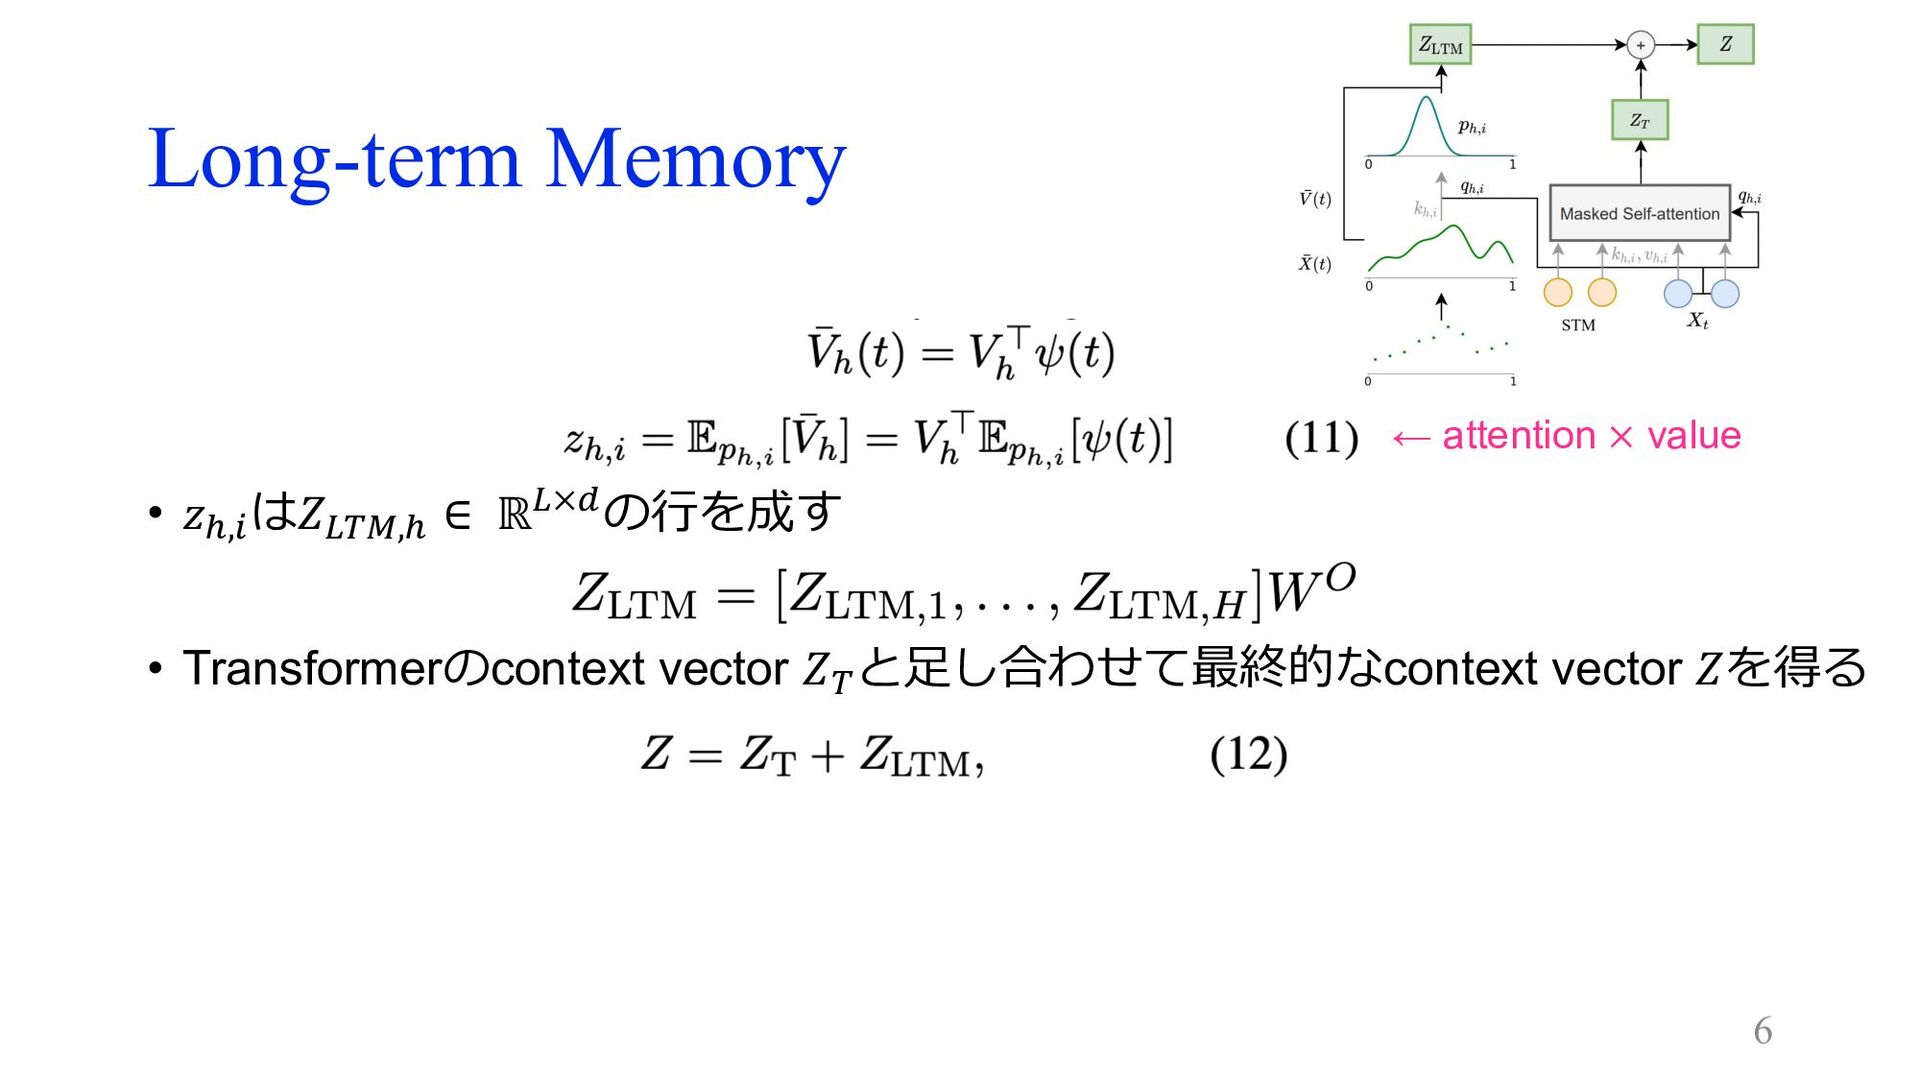
Long-term Memory • 𝑧),+ は𝑍#,-,) ∈ ℝ#×.の⾏を成す • Transformerのcontext vector
𝑍, と⾜し合わせて最終的なcontext vector 𝑍を得る 6 ← attention × value
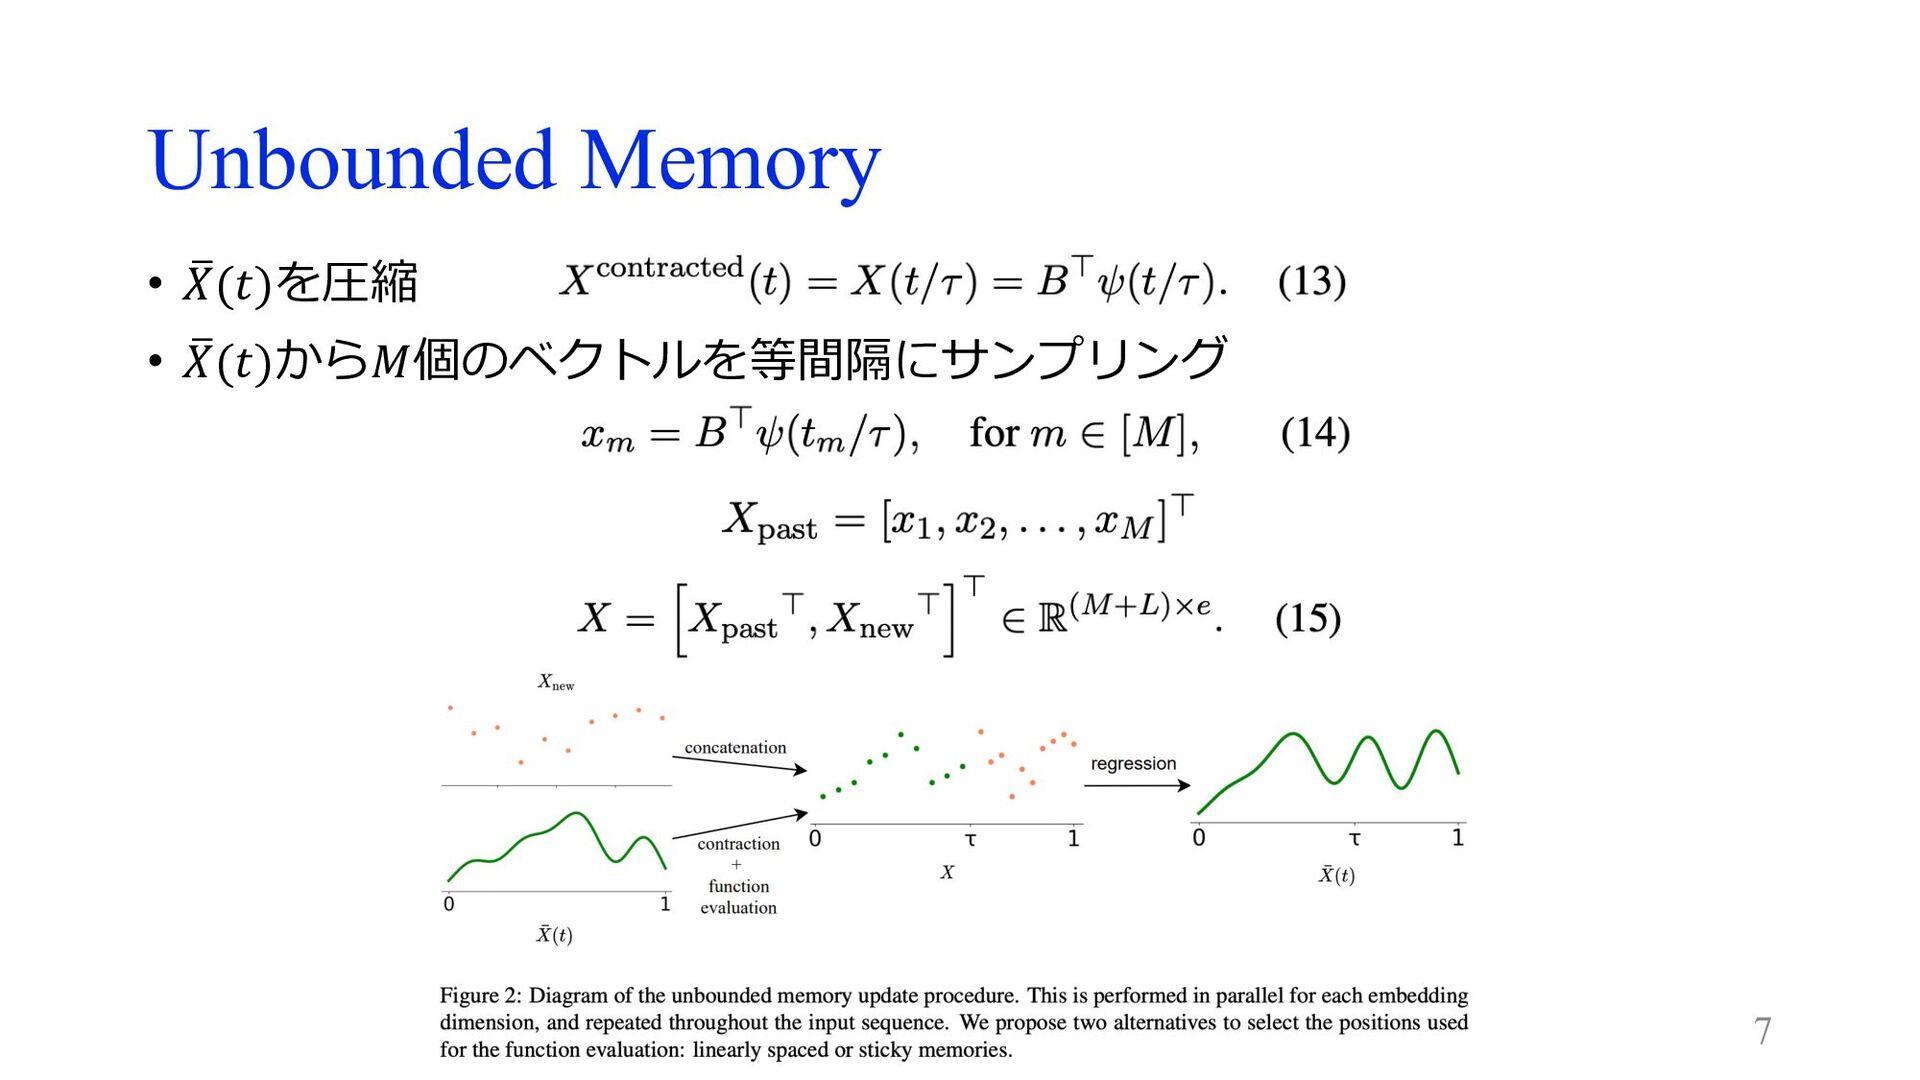
Unbounded Memory 7 • ! 𝑋(𝑡)を圧縮 • ! 𝑋(𝑡)から𝑀個のベクトルを等間隔にサンプリング
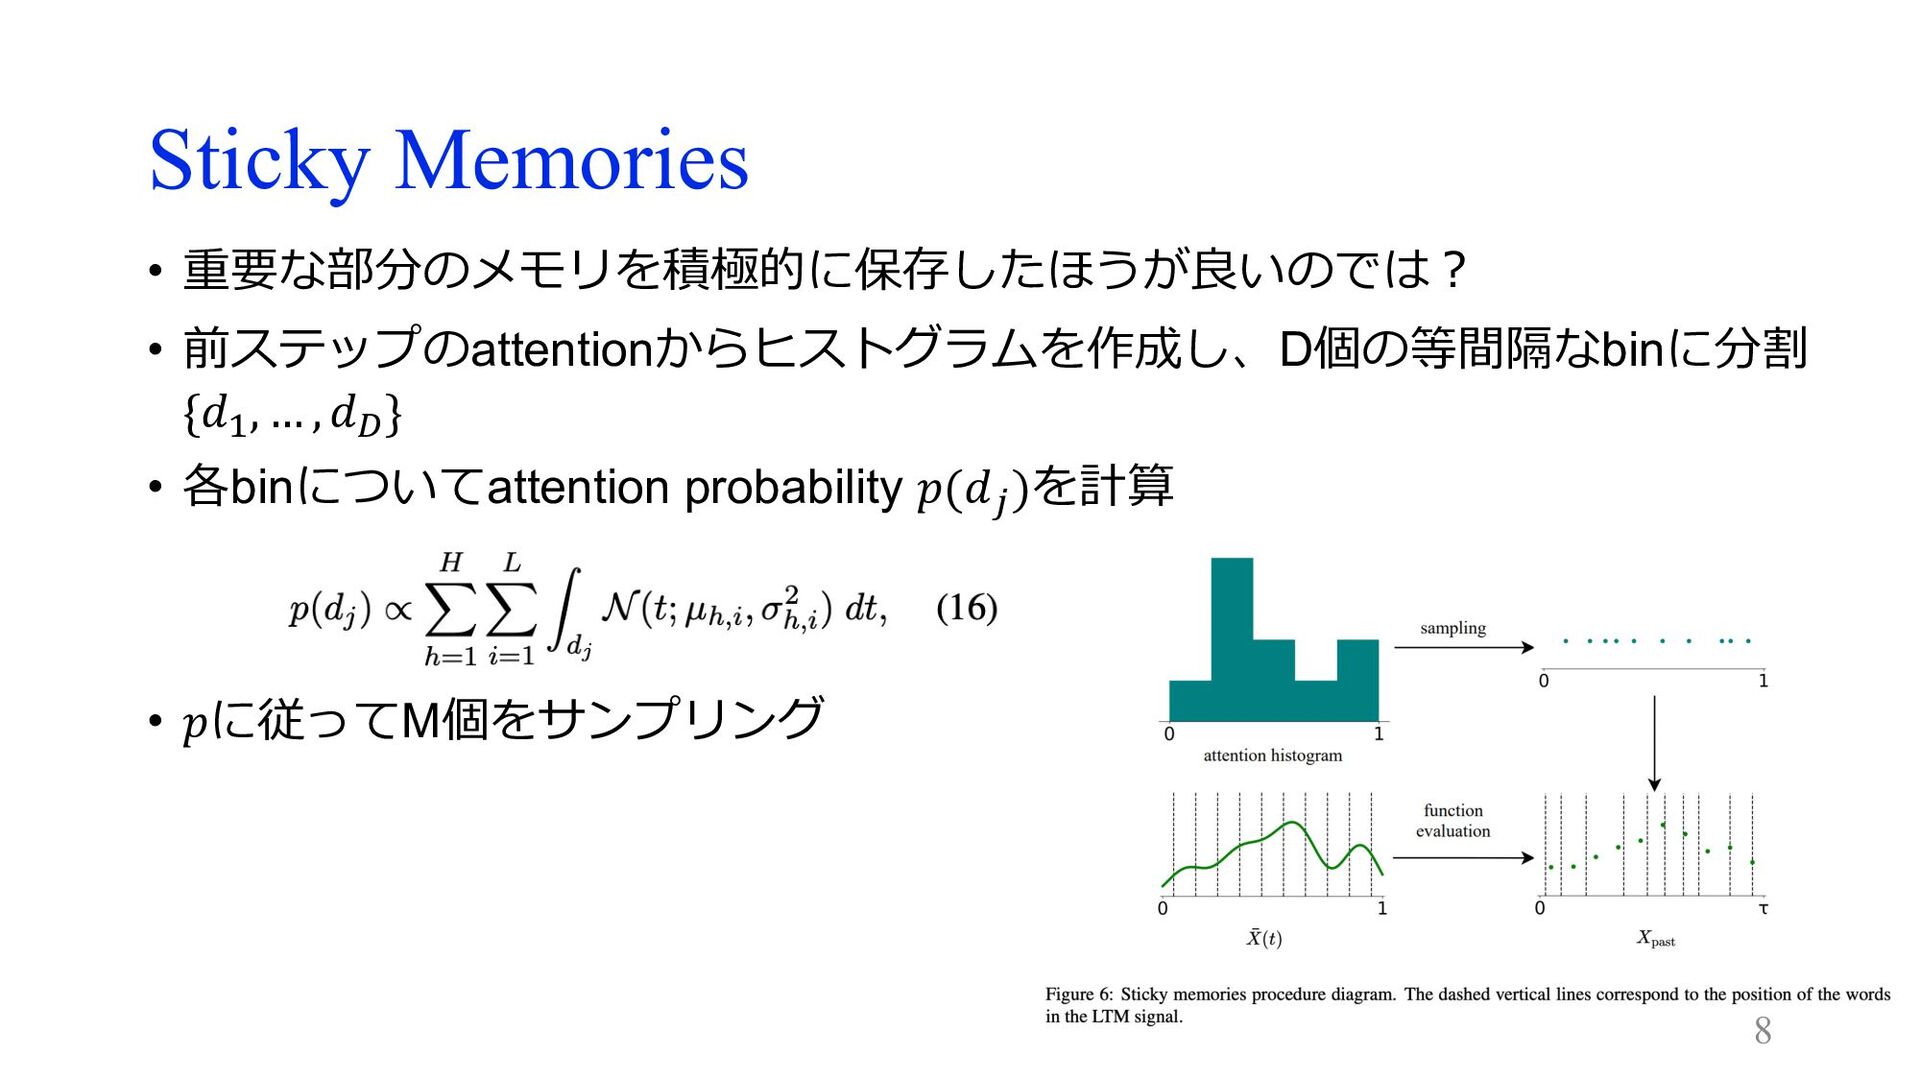
Sticky Memories • 重要な部分のメモリを積極的に保存したほうが良いのでは︖ • 前ステップのattentionからヒストグラムを作成し、D個の等間隔なbinに分割 {𝑑/, … , 𝑑0}
• 各binについてattention probability 𝑝(𝑑1 )を計算 • 𝑝に従ってM個をサンプリング 8
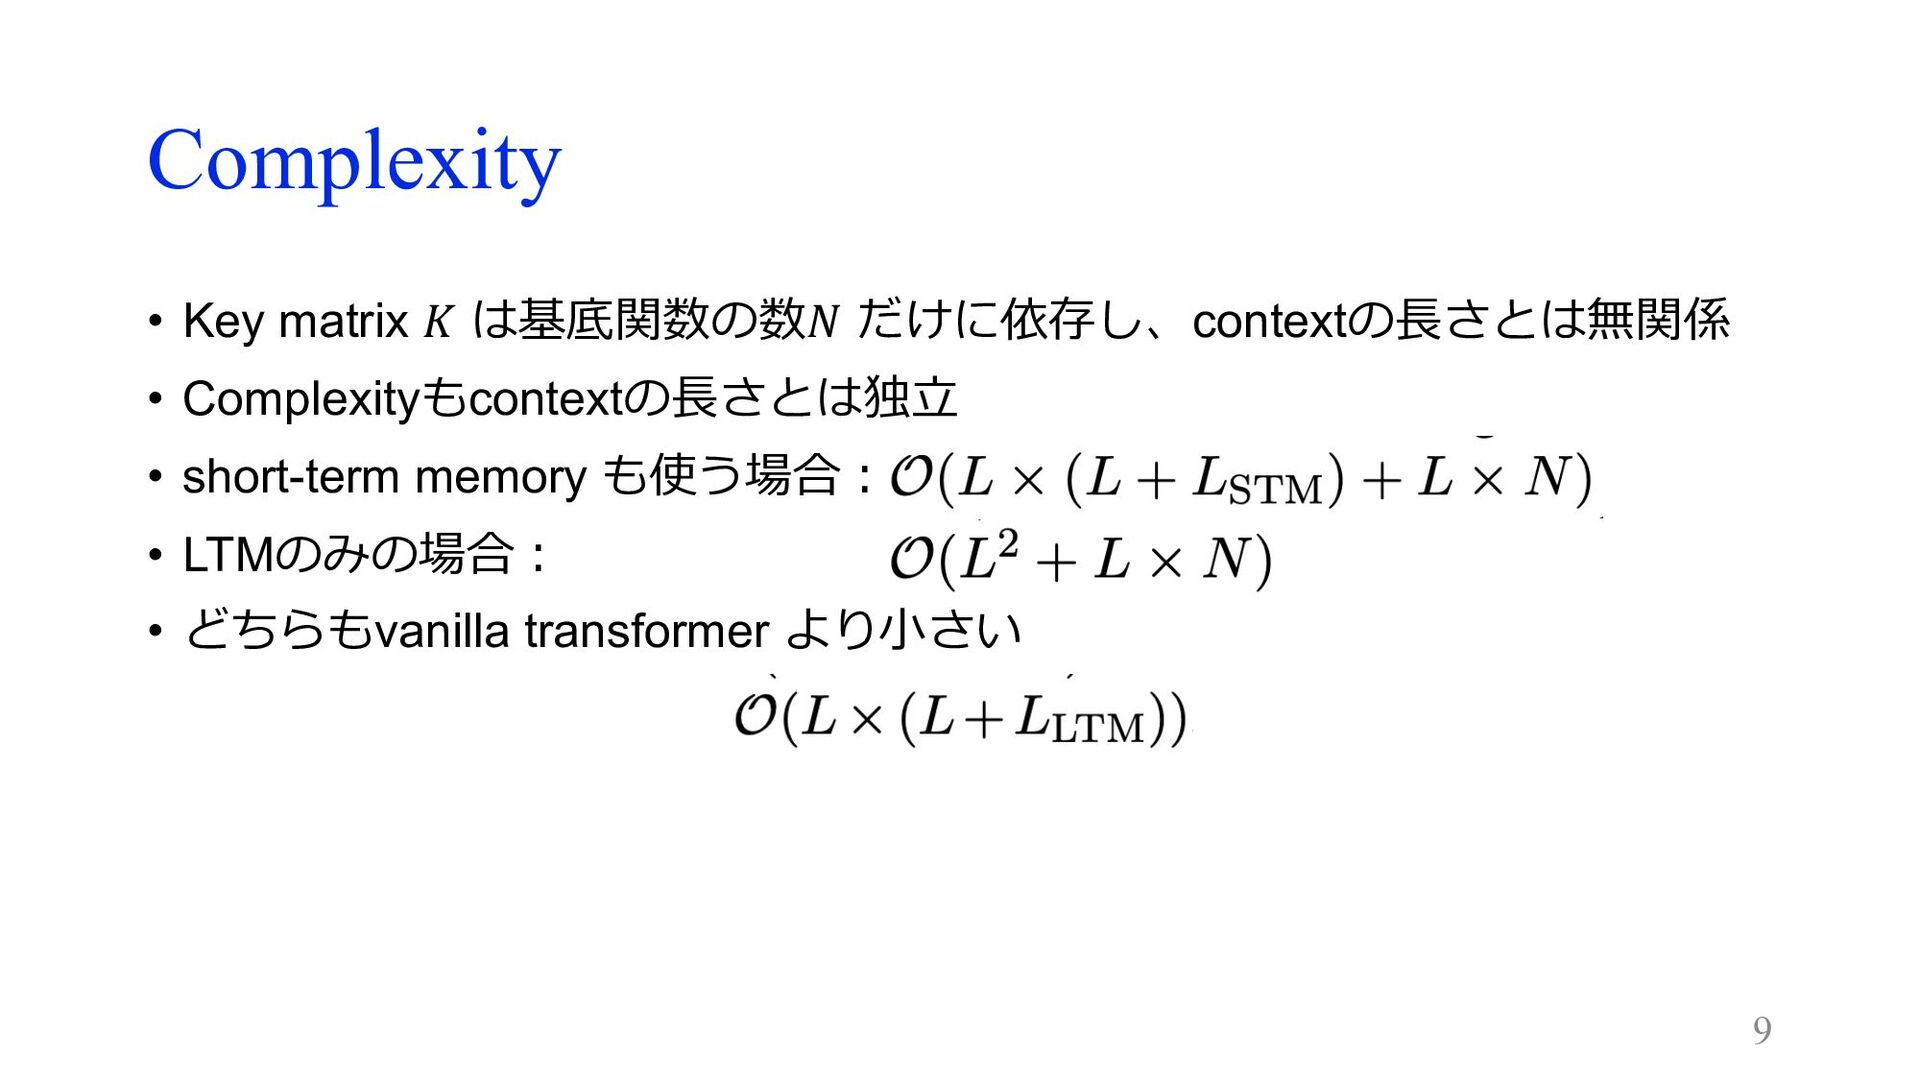
Complexity • Key matrix 𝐾 は基底関数の数𝑁 だけに依存し、contextの⻑さとは無関係 • Complexityもcontextの⻑さとは独⽴ •
short-term memory も使う場合︓ • LTMのみの場合︓ • どちらもvanilla transformer より⼩さい 9
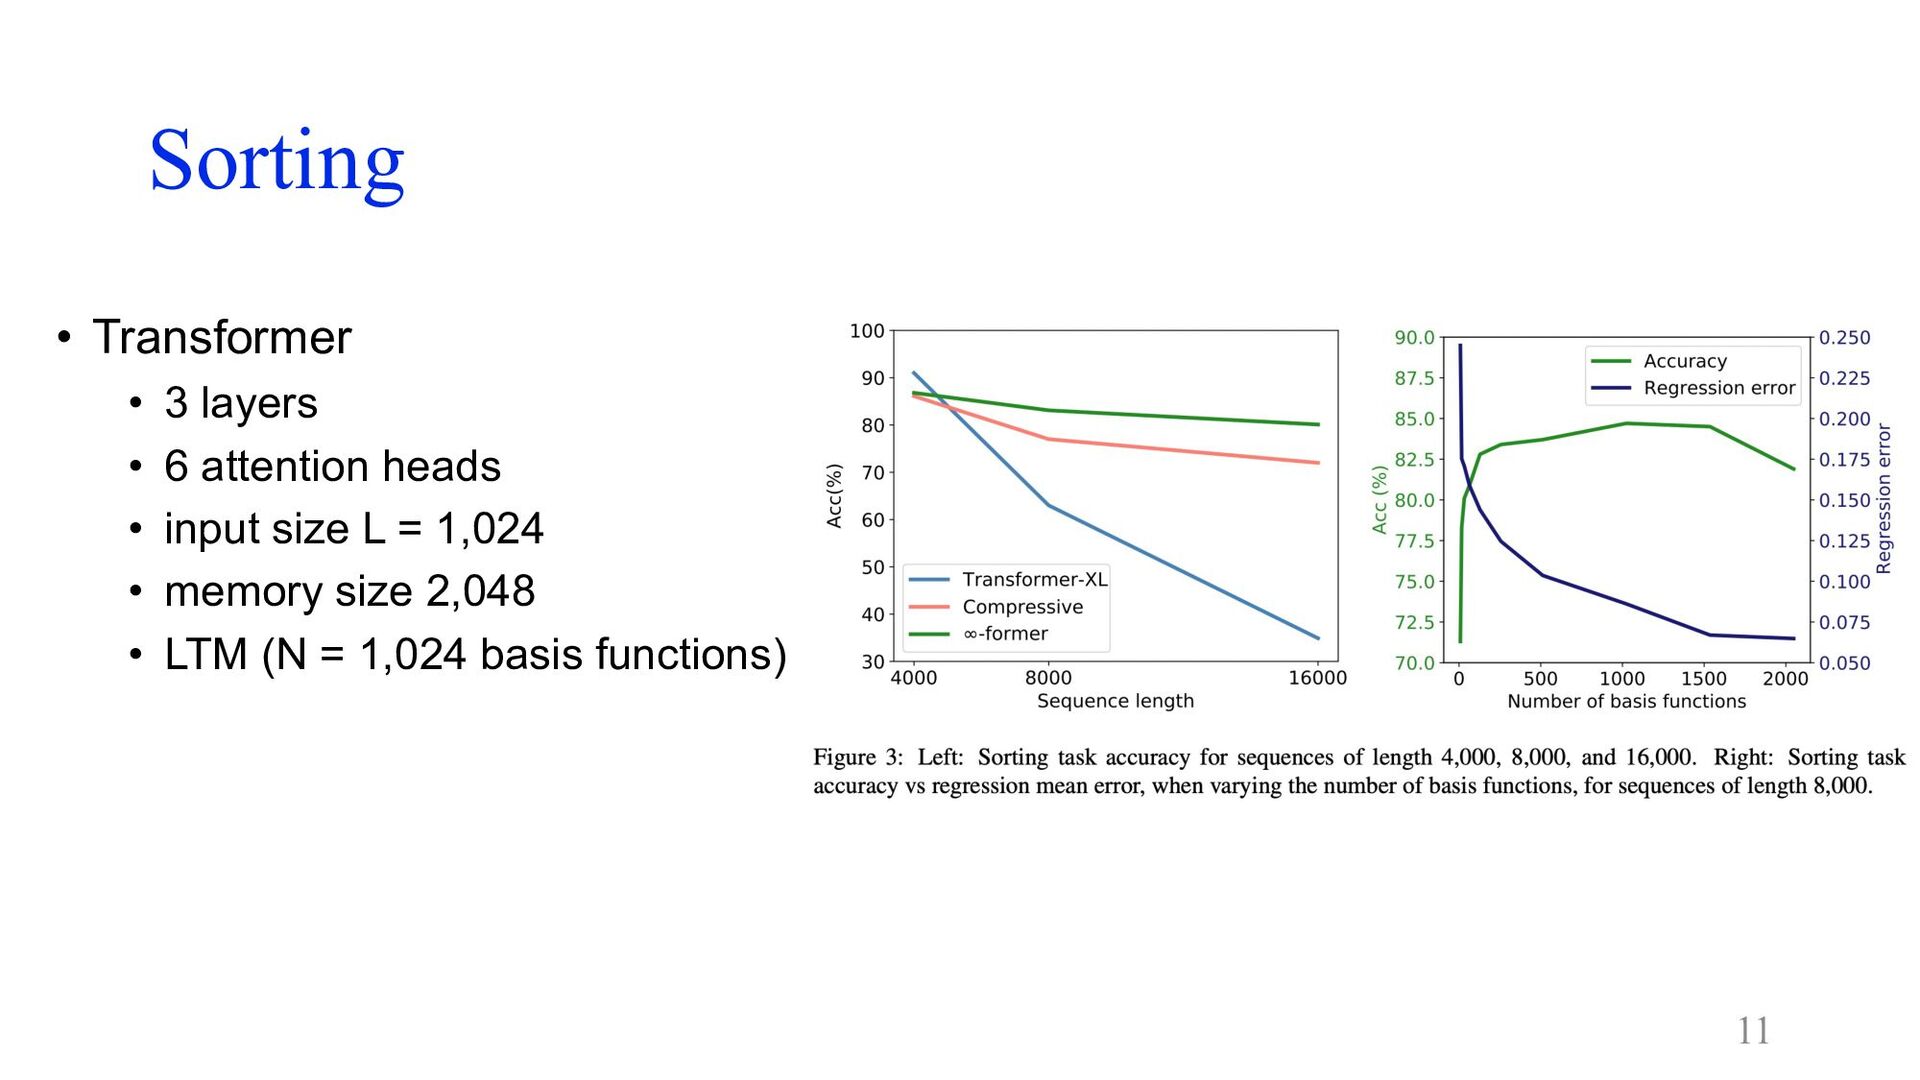
Sorting • 系列のトークンを頻度順に並べる • モデルが直近のトークンだけでなく⻑期記憶も⾒ているか調べるために、 トークンの確率分布を変化させていく • 系列が⻑くなるほど𝛼 ∈ [0,1]は0から1に徐々に増加
• vocabulary size 20 • 4,000, 8,000, 16,000トークンで実験 10
Sorting • Transformer • 3 layers • 6 attention heads
• input size L = 1,024 • memory size 2,048 • LTM (N = 1,024 basis functions) 11
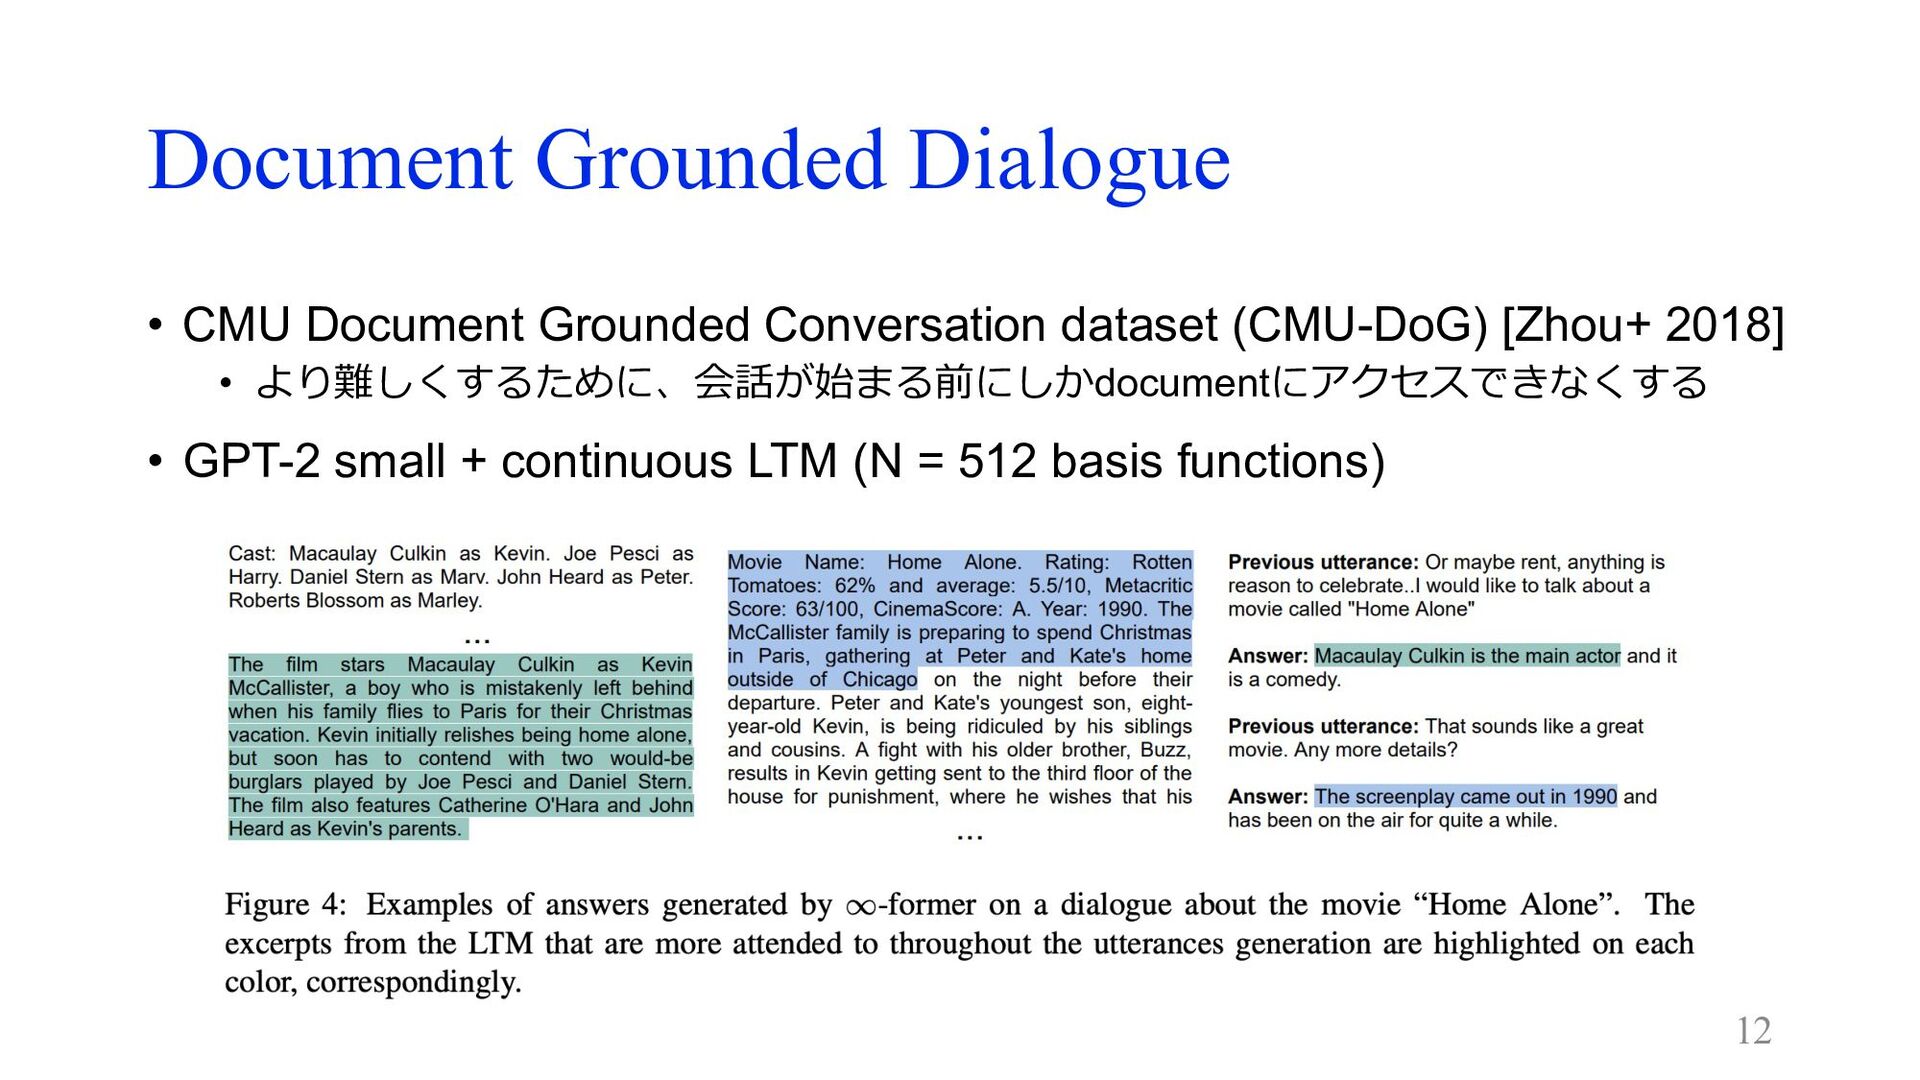
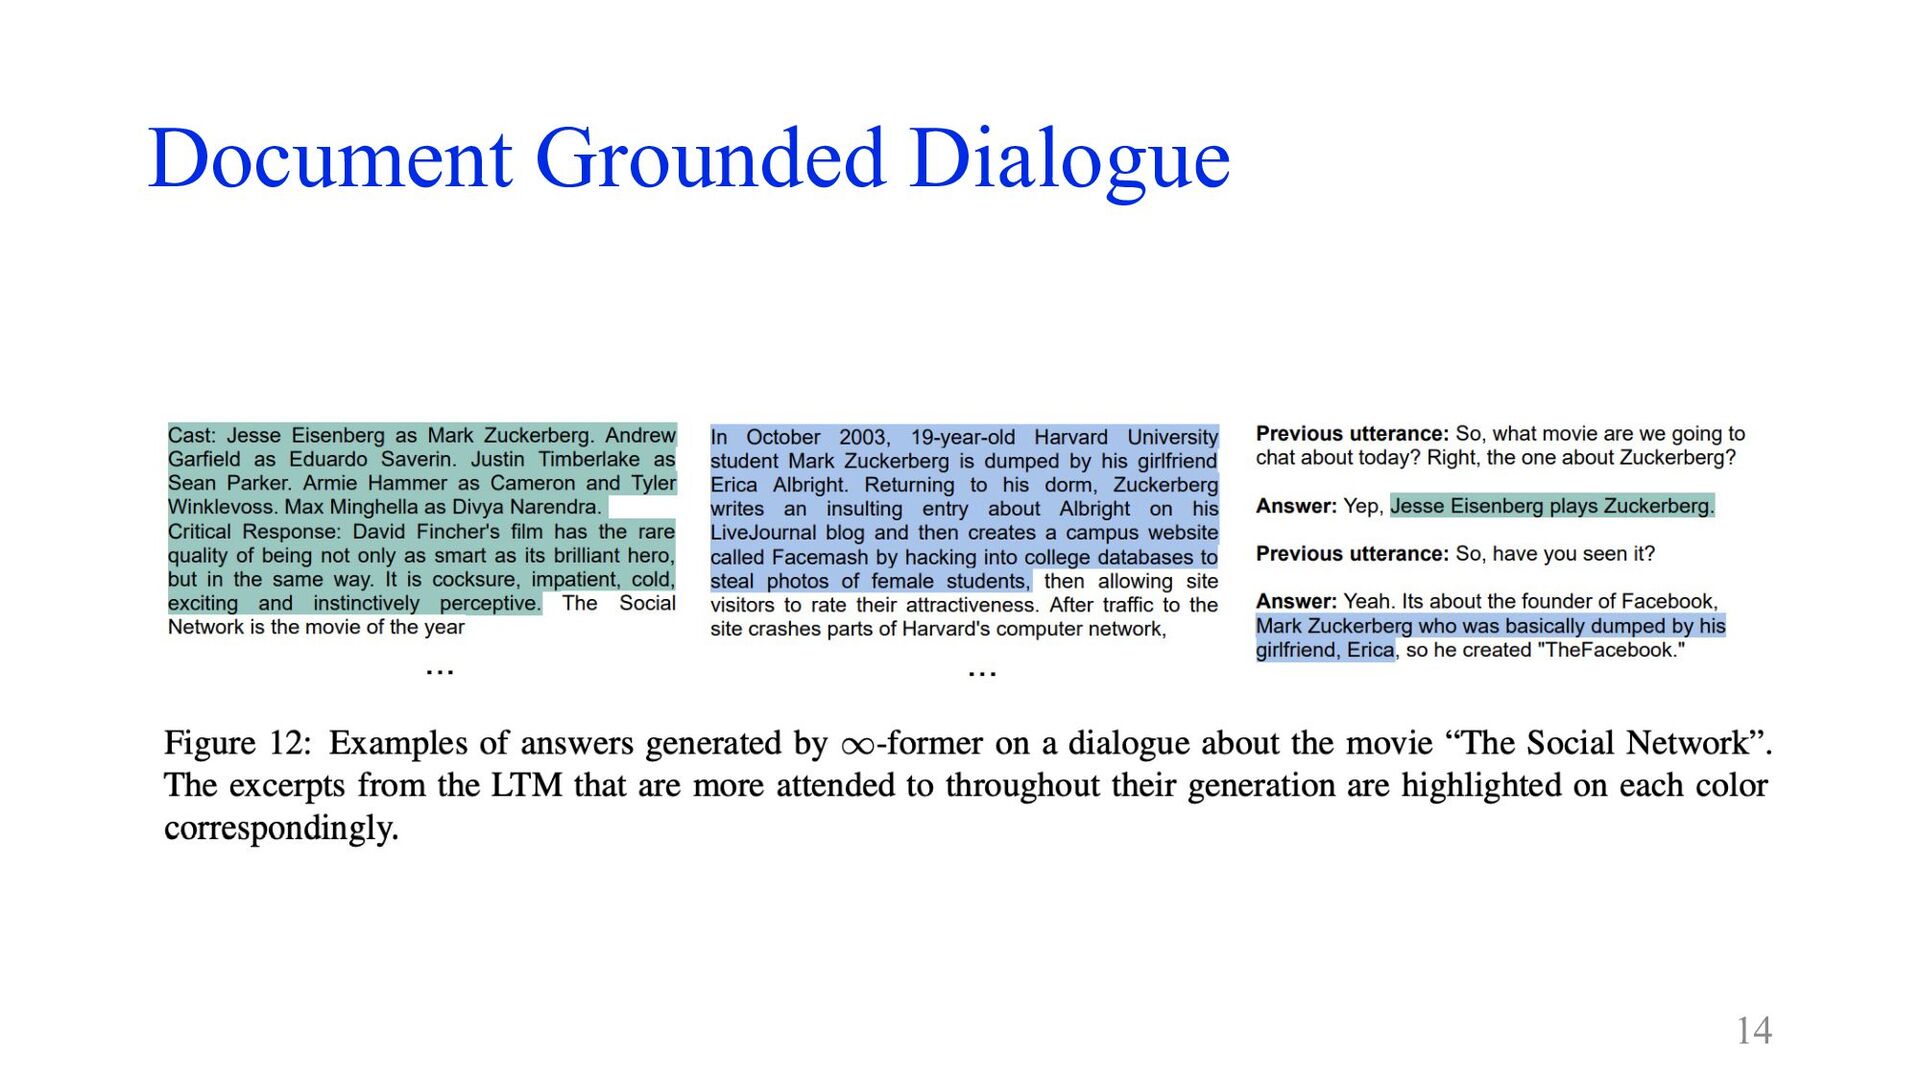
Document Grounded Dialogue • CMU Document Grounded Conversation dataset (CMU-DoG)
[Zhou+ 2018] • より難しくするために、会話が始まる前にしかdocumentにアクセスできなくする • GPT-2 small + continuous LTM (N = 512 basis functions) 12
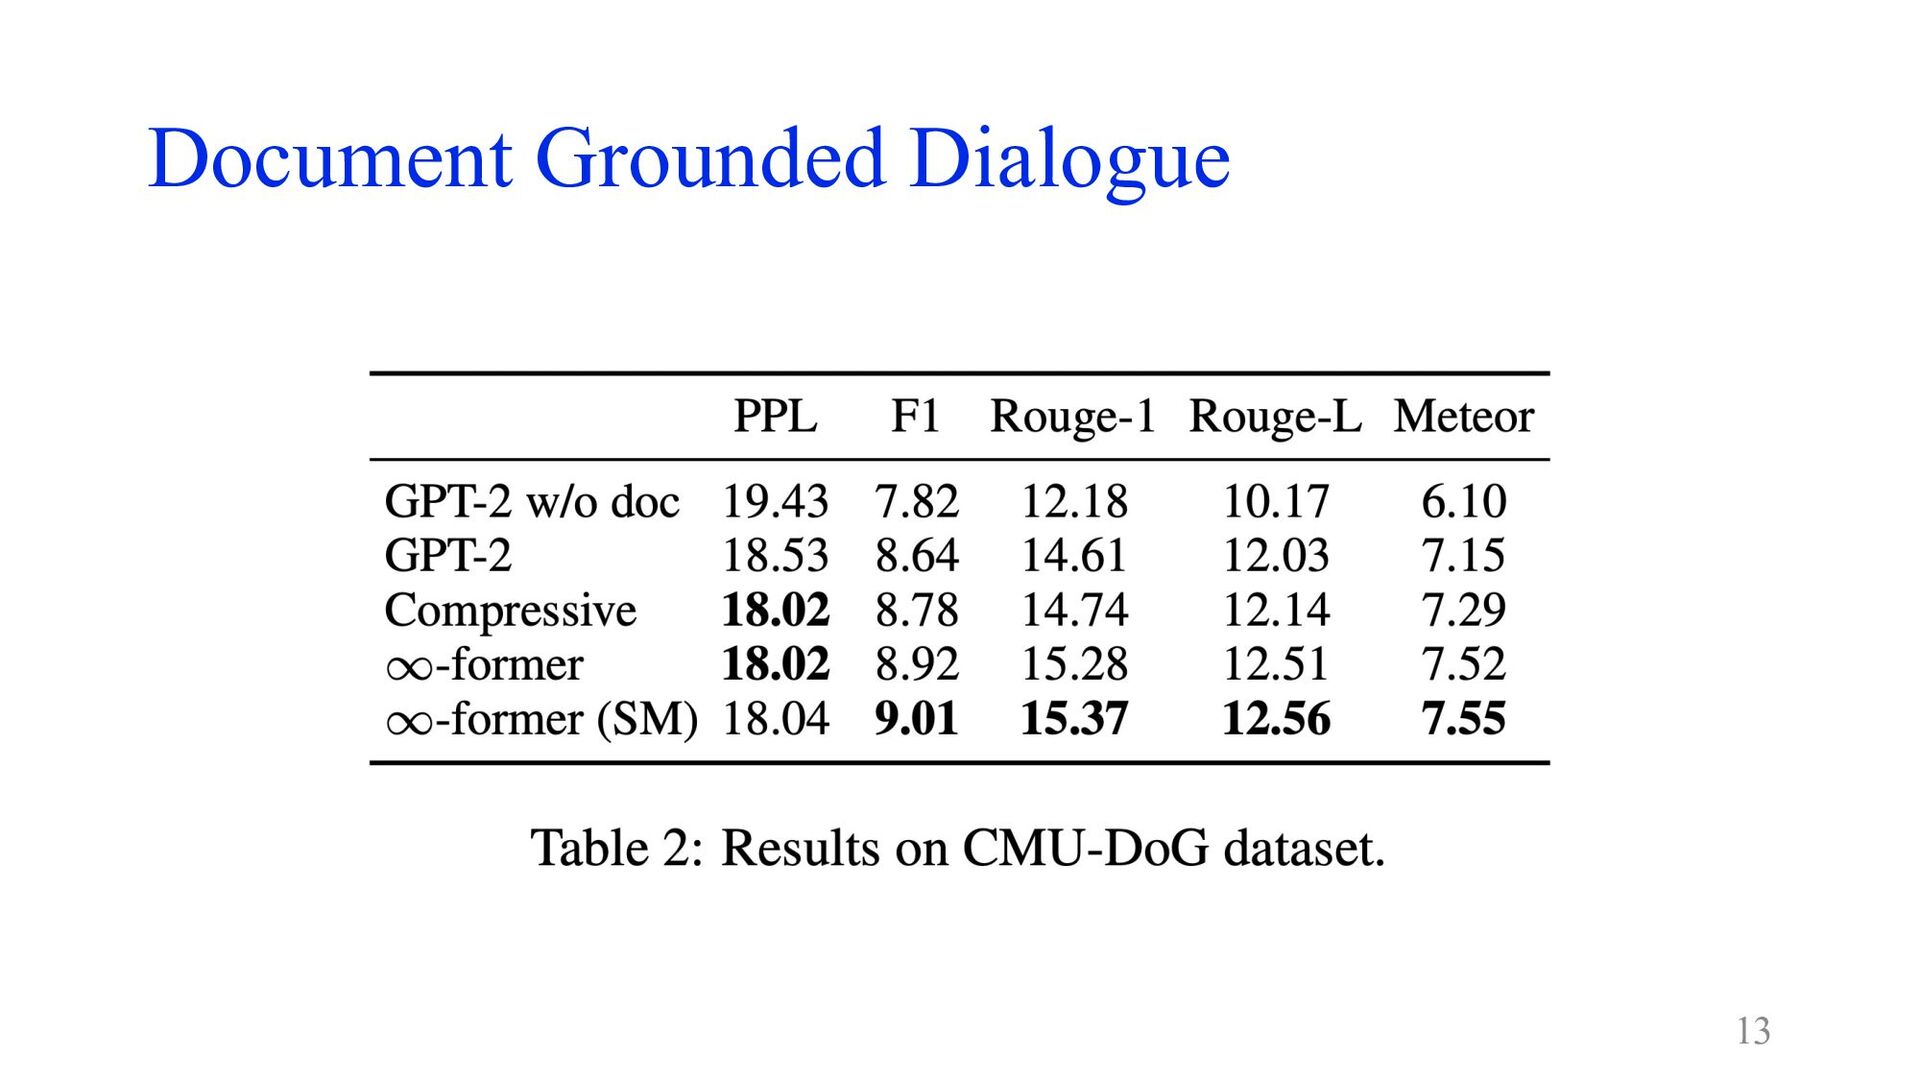
Document Grounded Dialogue 13
Document Grounded Dialogue 14
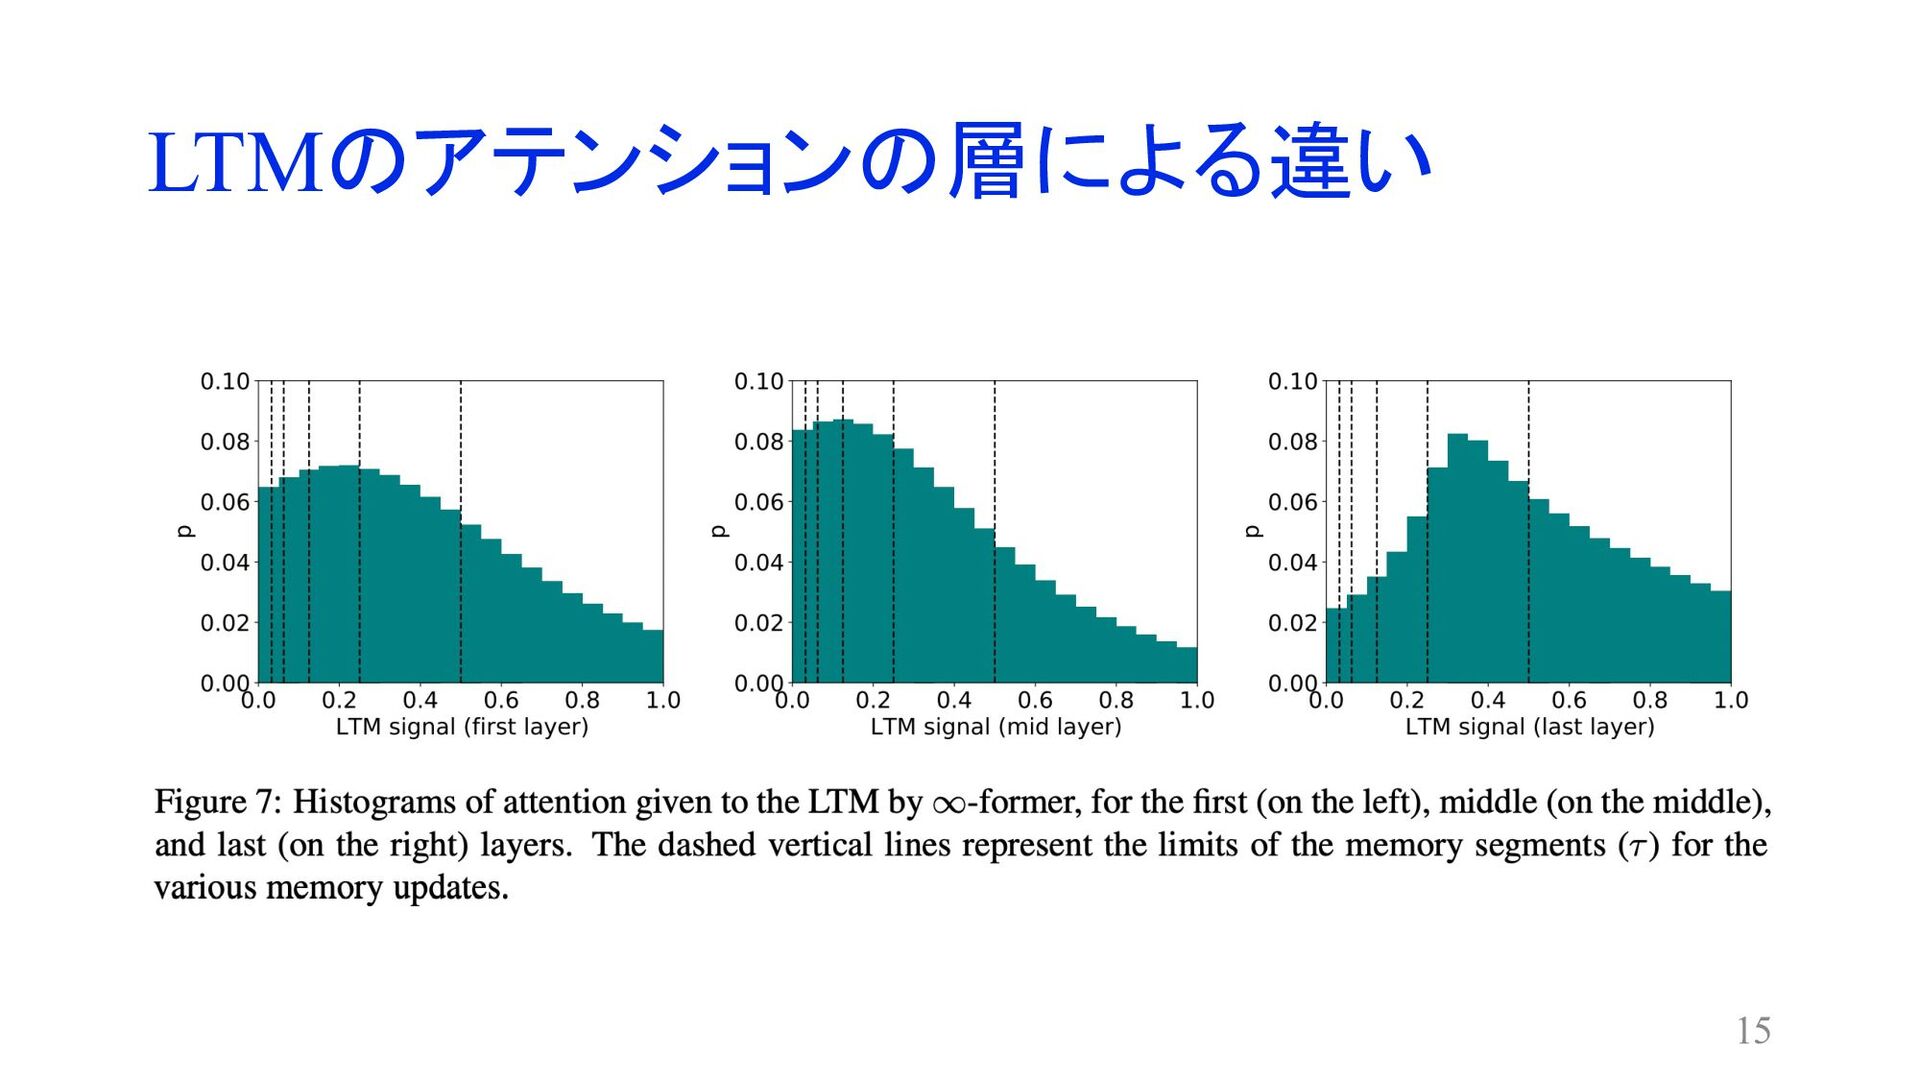
LTMのアテンションの層による違い 15
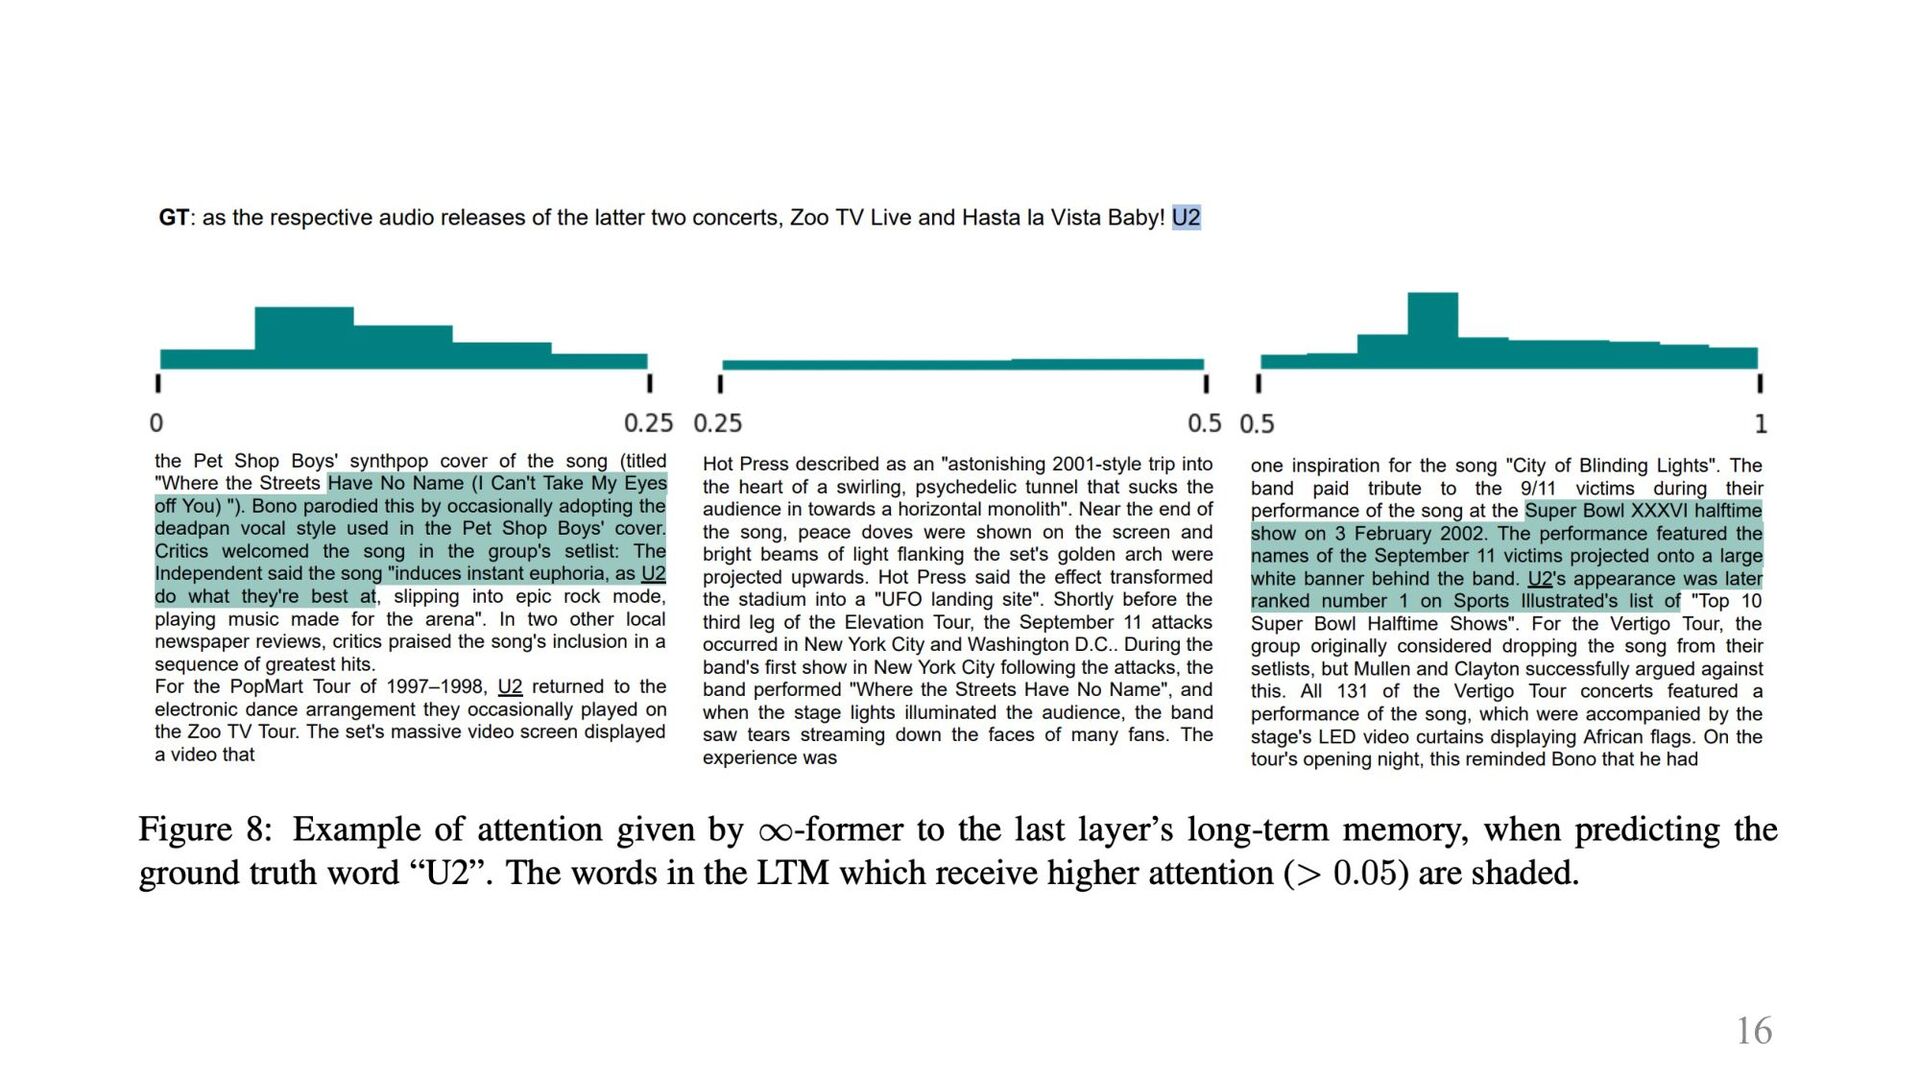
16
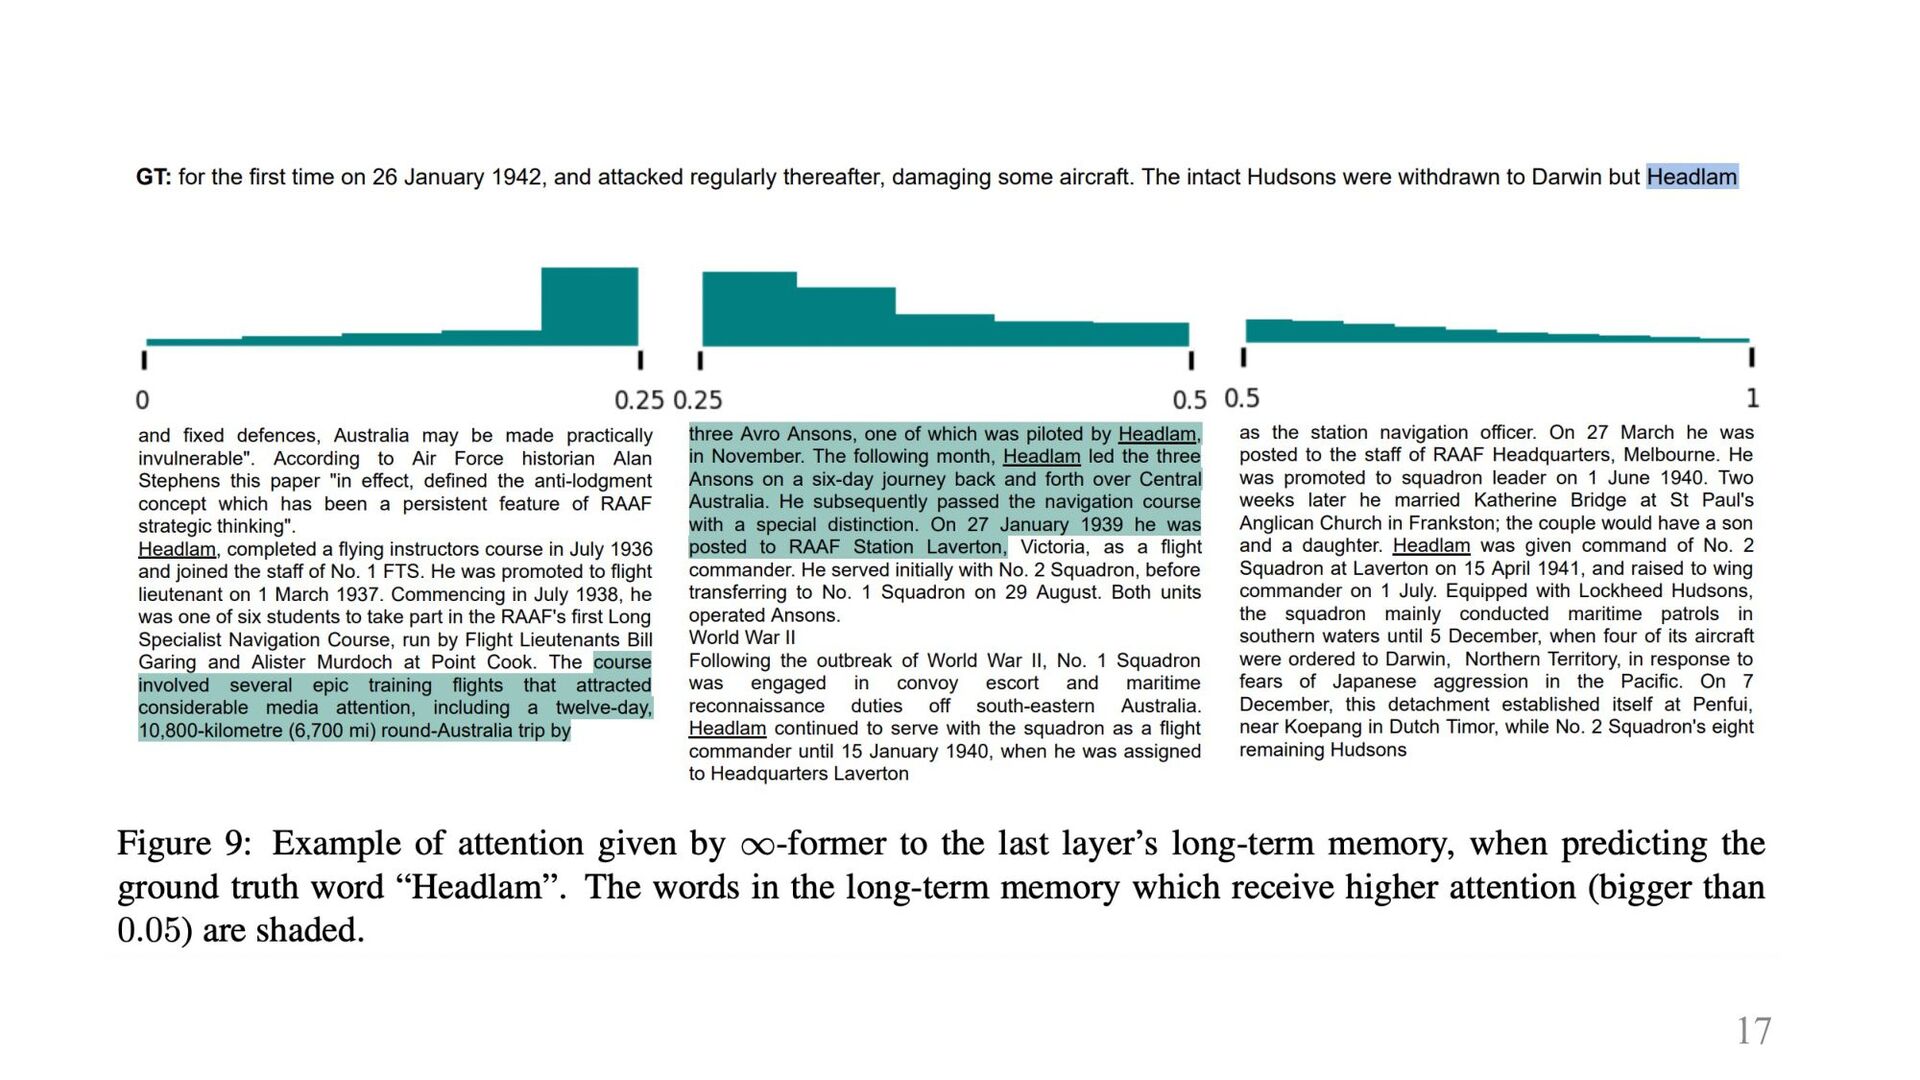
17
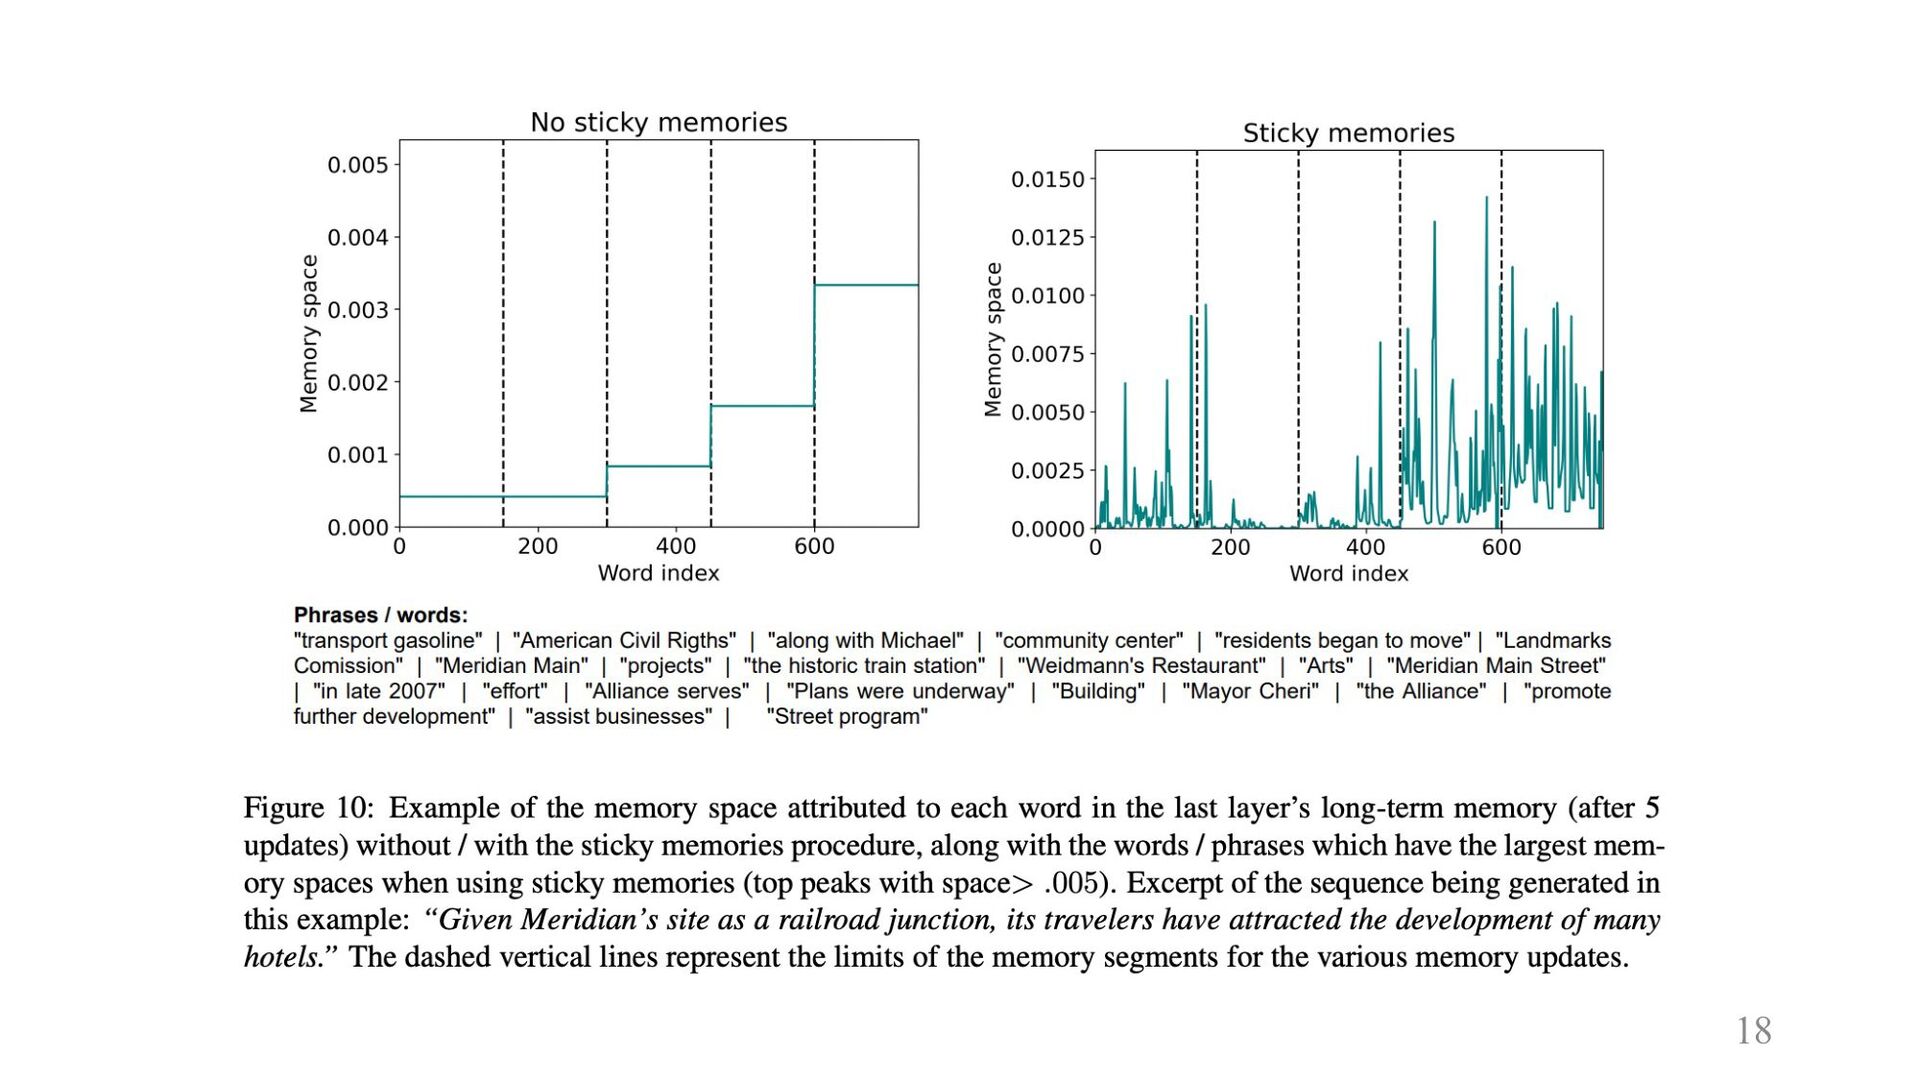
18
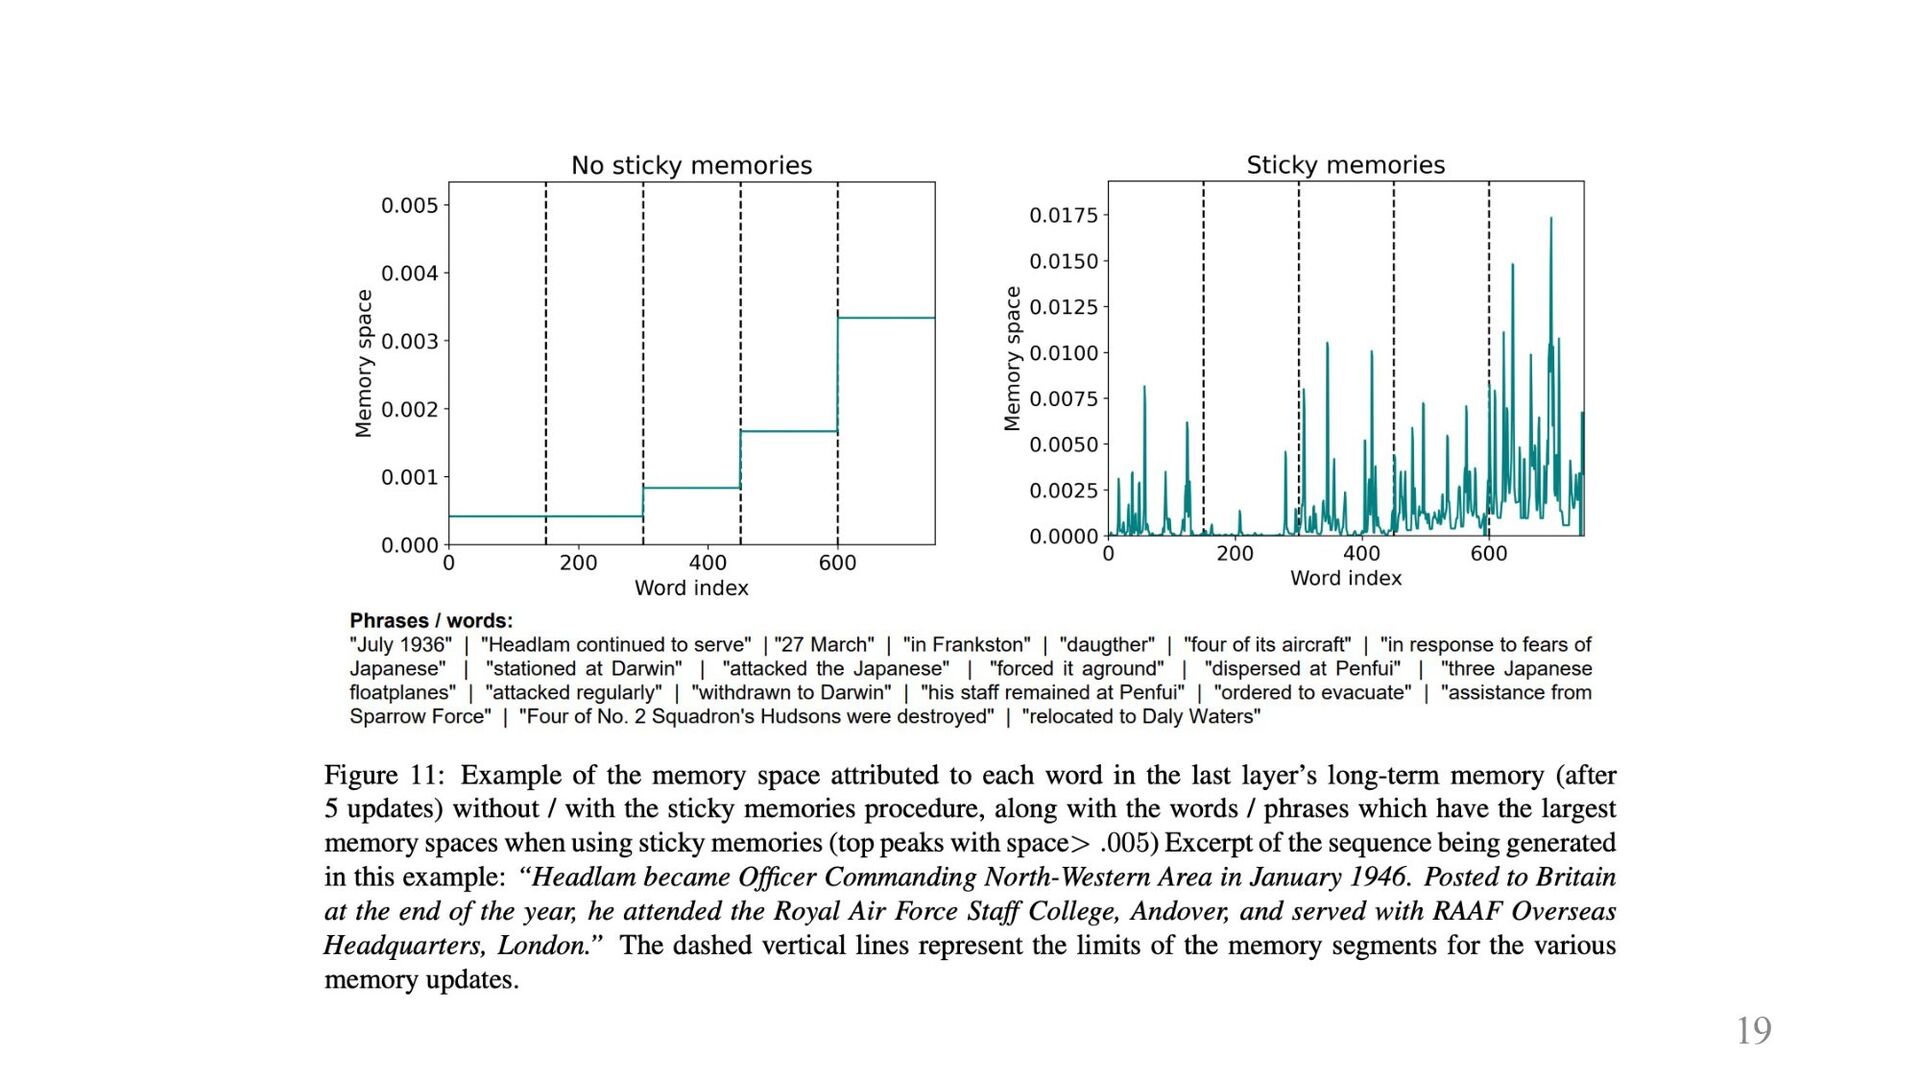
19
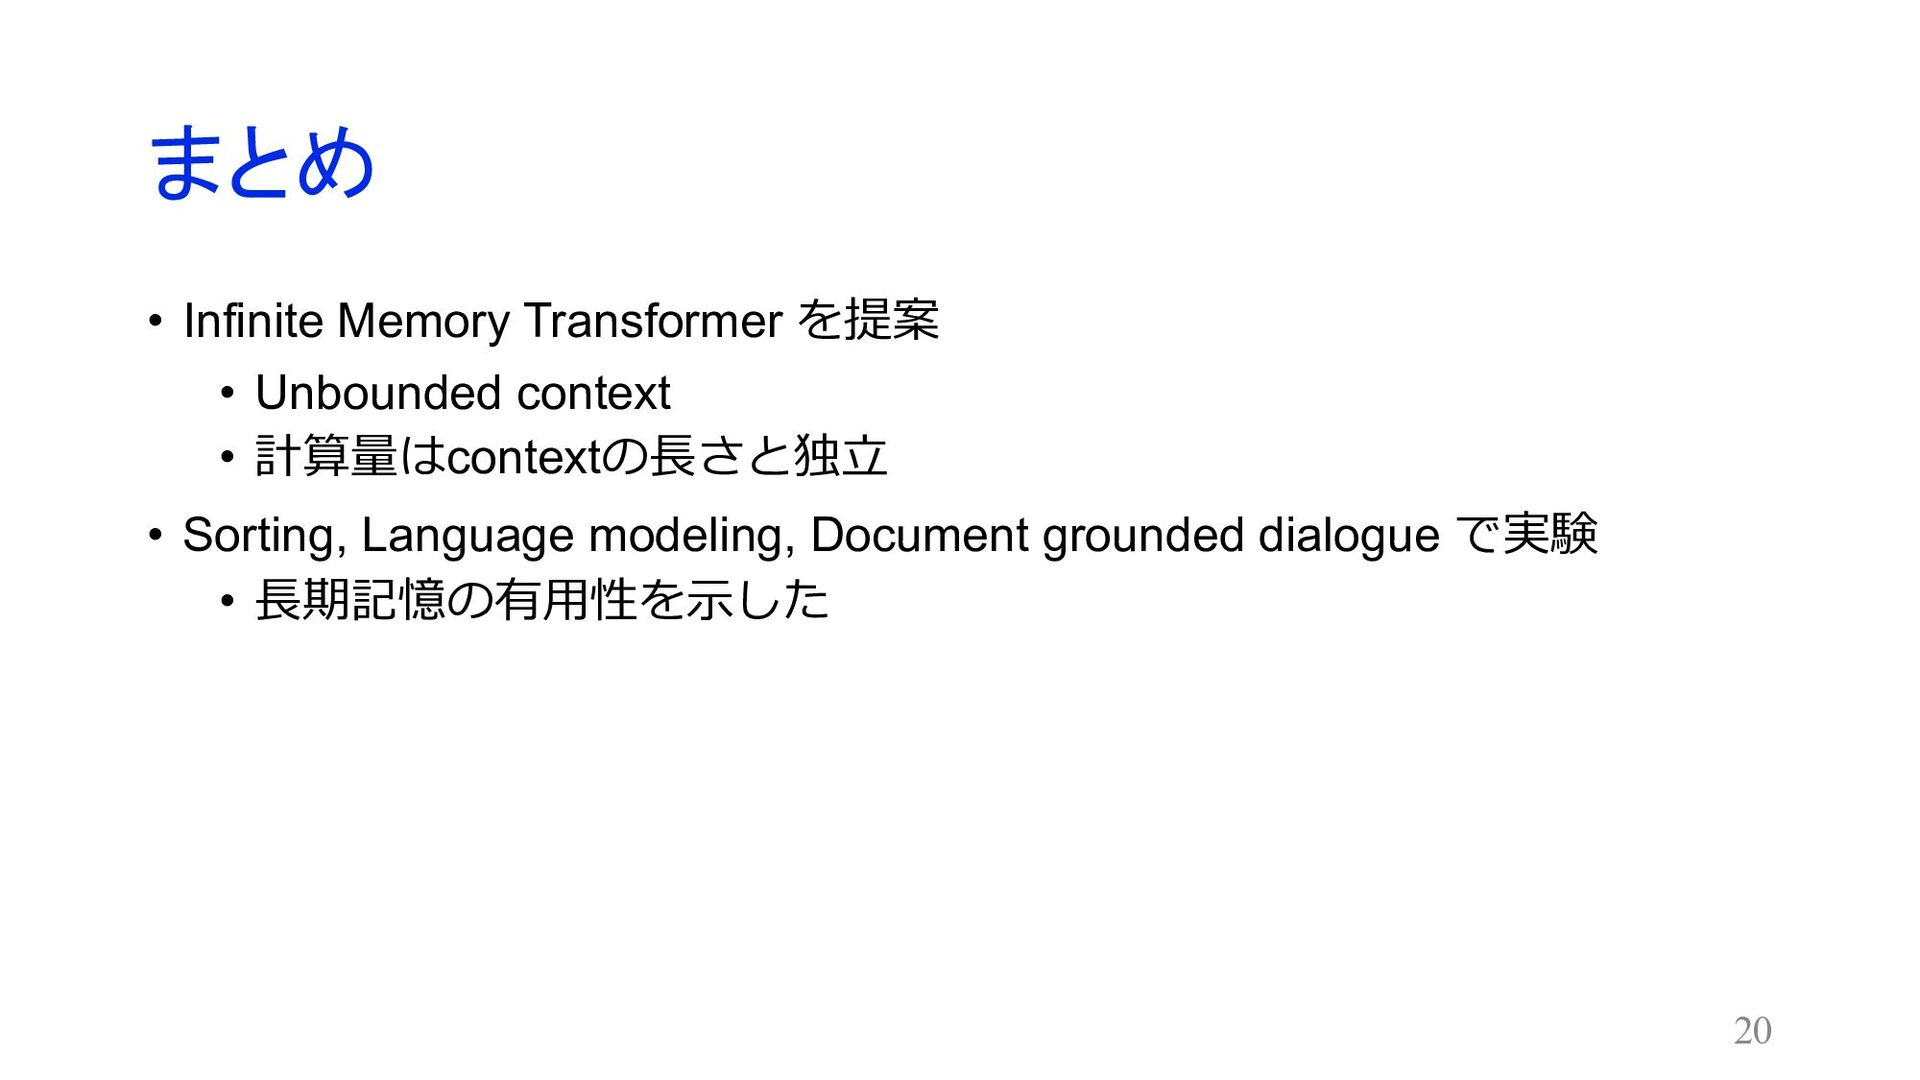
まとめ • Infinite Memory Transformer を提案 • Unbounded context •
計算量はcontextの⻑さと独⽴ • Sorting, Language modeling, Document grounded dialogue で実験 • ⻑期記憶の有⽤性を⽰した 20


 yuri00
 s_mizuki_nlp
 ldcn
 kogoro
 corochann
 pomcho555
 microbaseinc
 institutdelelevage
 rikkabotan7
 satai
 taniai
 gpeyre
 nzw0301
 aarron
 wayneb77
 lara
 mfonobong
 rkaga
 greggifford
 marktimemedia
 stuffmc
 keathley
 inesmontani
 sarafernandez
 nikkihalliwell