Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Direct Preference Optimization
Search
Henry Cui
February 24, 2024
Science
490
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Direct Preference Optimization
Henry Cui
February 24, 2024
More Decks by Henry Cui
See All by Henry Cui
プロダクション言語モデルの情報を盗む攻撃 / Stealing Part of a Production Language Model
zchenry
1
260
Diffusion Model with Perceptual Loss
zchenry
0
540
レンズの下のLLM / LLM under the Lens
zchenry
0
250
Go with the Prompt Flow
zchenry
0
260
Mojo Dojo
zchenry
0
290
ことのはの力で画像の異常検知 / Anomaly Detection by Language
zchenry
0
770
驚愕の事実!LangChainが抱える問題 / Problems of LangChain
zchenry
0
350
MLOps初心者がMLflowを触る / MLflow Brief Introduction
zchenry
0
230
{{guidance}}のガイダンス / Guidance of guidance
zchenry
0
220
Other Decks in Science
See All in Science
コーヒー豆様核 (Coffee-bean nuclei) における形態学的サブタイピングと精選・焙煎特性の同定
jagupath
PRO
0
230
データベース06: SQL (3/3) 副問い合わせ
trycycle
PRO
1
1.2k
機械学習 - DBSCAN
trycycle
PRO
0
2.3k
(CVPR2026) Back to Basics: Let Denoising Generative Models Denoise
shumpei777
0
430
Path integral polarons for real semiconductors
jarvist
0
120
Van Dare naar Durf
voginip
0
320
機械学習 - ニューラルネットワーク入門
trycycle
PRO
0
1.4k
データベース09: 実体関連モデル上の一貫性制約
trycycle
PRO
0
1.9k
機械学習 - SVM
trycycle
PRO
2
1.3k
機械学習 - K近傍法 & 機械学習のお作法
trycycle
PRO
1
1.7k
TypeScript で WebAssembly を用いた 型安全なプラグイン設計
nagano
2
670
Cognitive Debt - What AI will do to us
martinlippert
1
120
Featured
See All Featured
XXLCSS - How to scale CSS and keep your sanity
sugarenia
250
1.3M
Navigating the Design Leadership Dip - Product Design Week Design Leaders+ Conference 2024
apolaine
2
490
The SEO identity crisis: Don't let AI make you average
varn
0
610
How to Grow Your eCommerce with AI & Automation
katarinadahlin
PRO
2
330
Site-Speed That Sticks
csswizardry
13
1.6k
Claude Code のすすめ
schroneko
67
230k
Building the Perfect Custom Keyboard
takai
2
920
The Myth of the Modular Monolith - Day 2 Keynote - Rails World 2024
eileencodes
28
3.7k
The B2B funnel & how to create a winning content strategy
katarinadahlin
PRO
1
580
Impact Scores and Hybrid Strategies: The future of link building
tamaranovitovic
0
470
Navigating Weather and Climate Data
rabernat
0
560
Typedesign – Prime Four
hannesfritz
42
3.2k
Transcript
Direct Preference Optimization 機械学習の社会実装勉強会第32回 Henry 2024/2/24
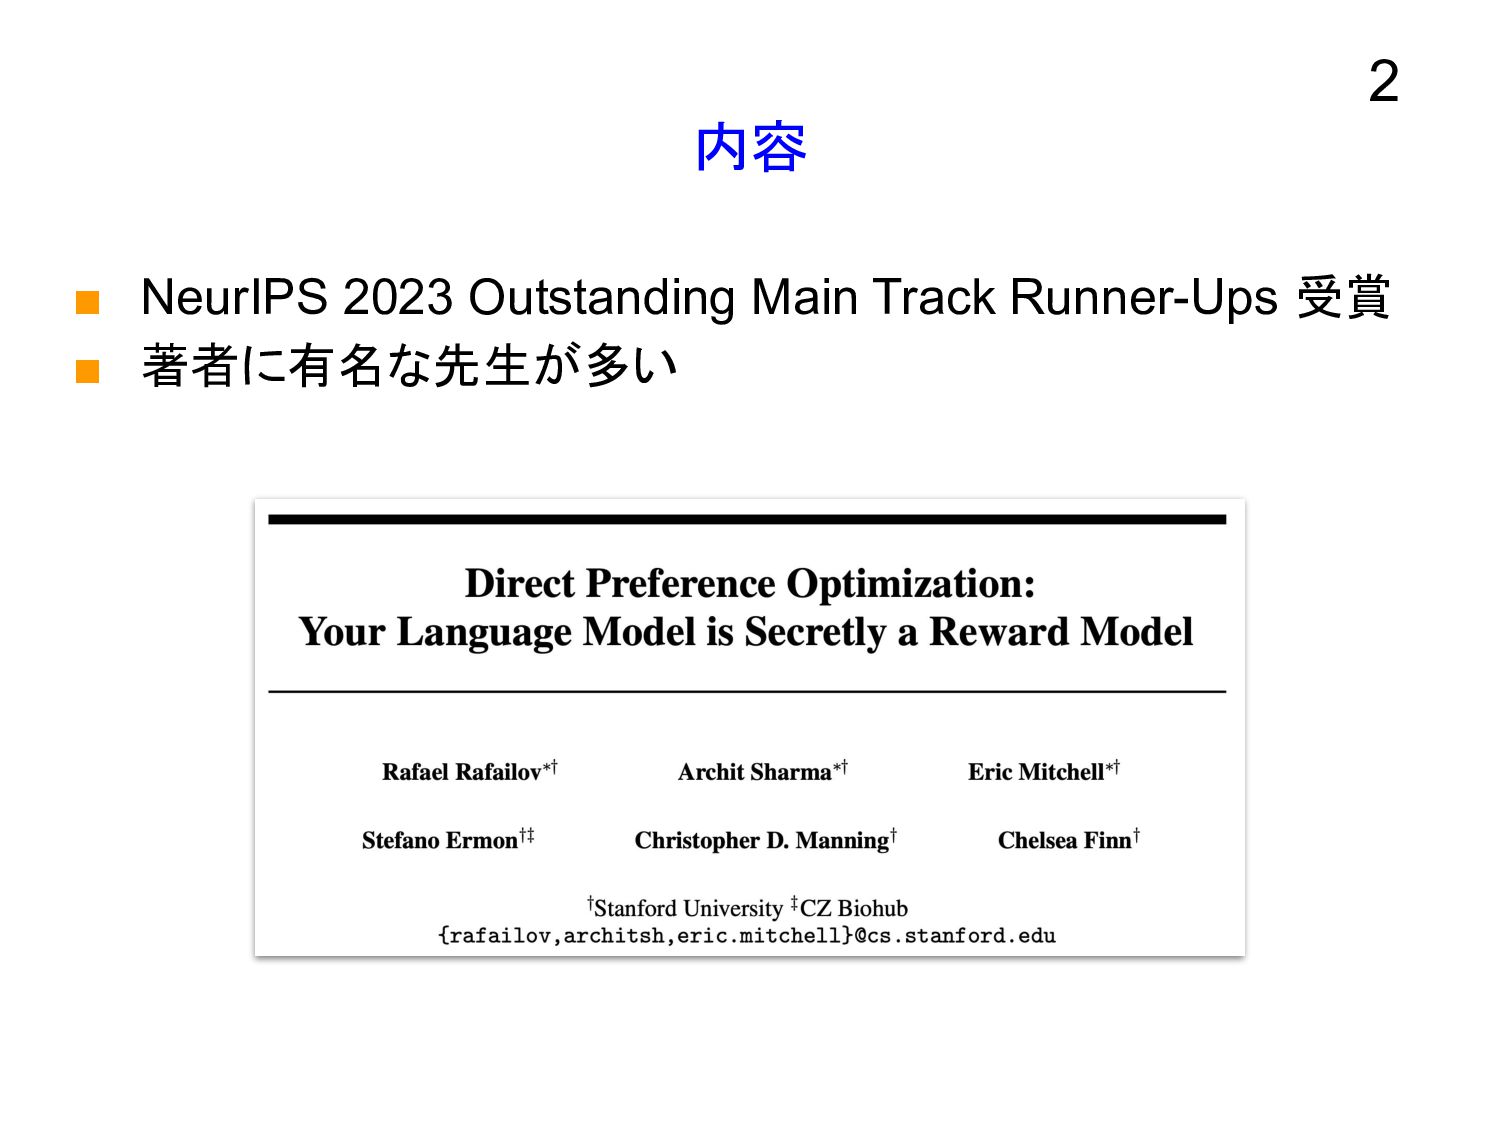
内容 ▪ NeurIPS 2023 Outstanding Main Track Runner-Ups 受賞 ▪
著者に有名な先生が多い 2
モチベーション ▪ 大量テキストで学習した言語モデルを望ましい挙動に微調整 する必要(Alignment) • 大量コードの平均能力でなく、少量存在の優れたコードに • 一般大衆のもつ誤認識でなく、それを修正すべき ▪ Alignmentを達成するために、現状2段階の複雑な強化学習
手法を使うので、それと理論上等価なシンプルな手法を提案 3
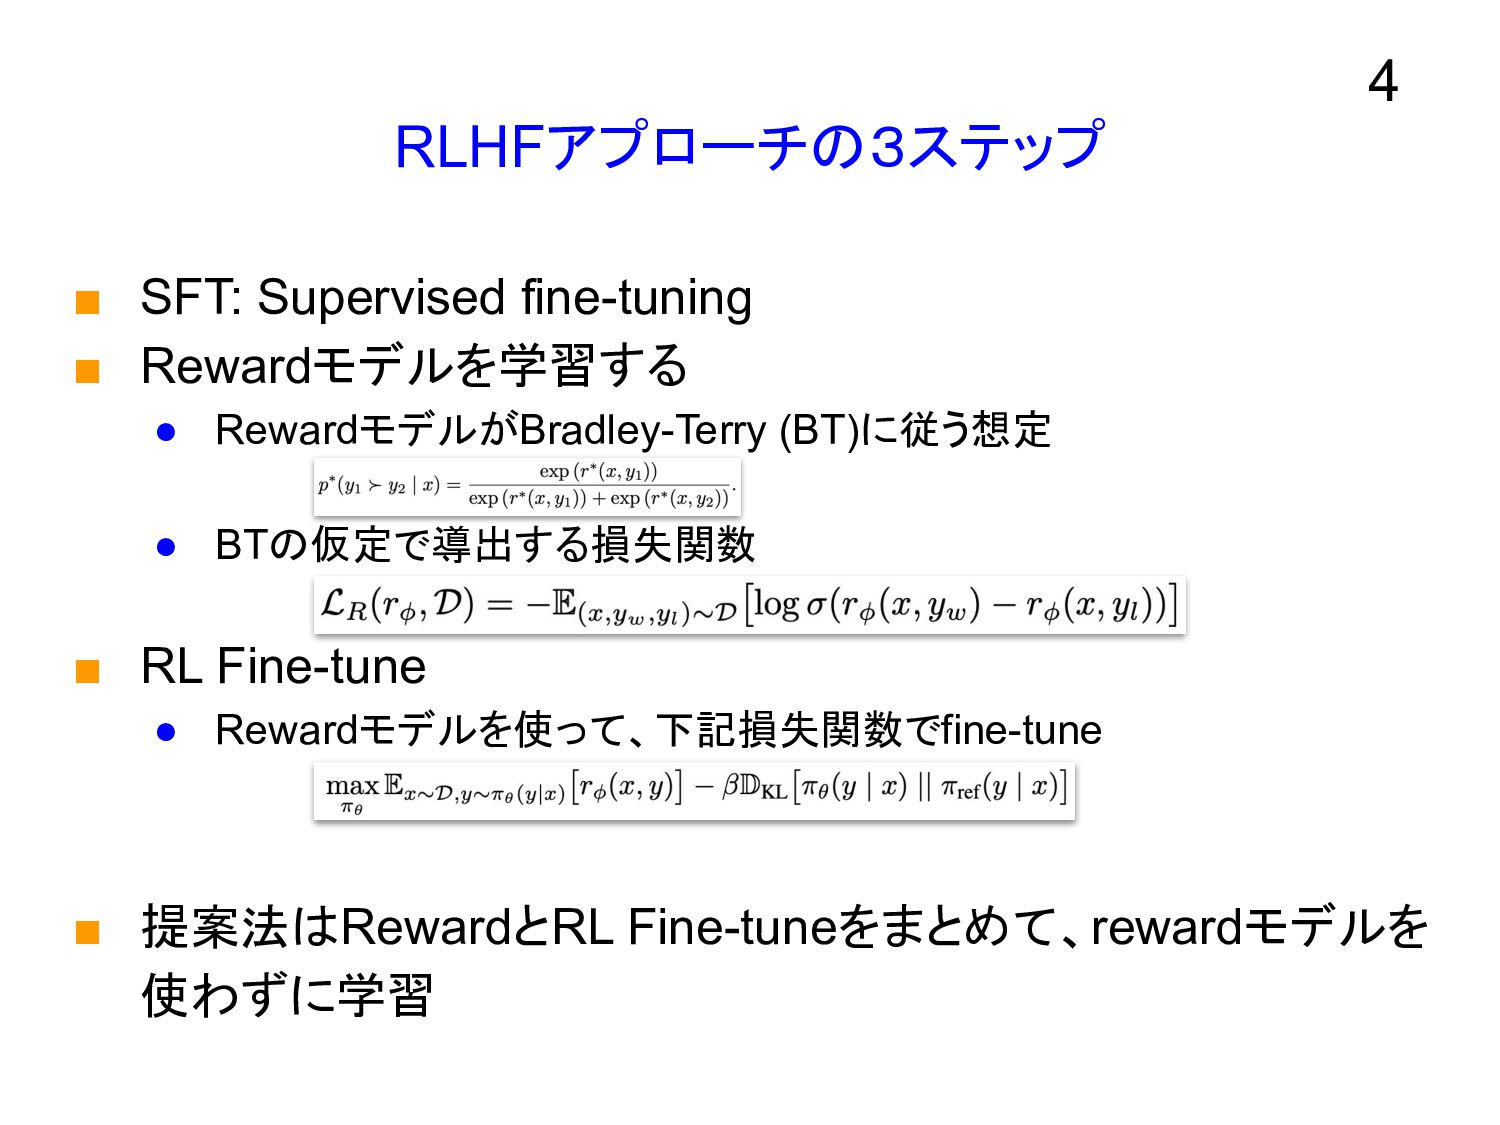
RLHFアプローチの3ステップ ▪ SFT: Supervised fine-tuning ▪ Rewardモデルを学習する • RewardモデルがBradley-Terry (BT)に従う想定
• BTの仮定で導出する損失関数 ▪ RL Fine-tune • Rewardモデルを使って、下記損失関数でfine-tune ▪ 提案法はRewardとRL Fine-tuneをまとめて、rewardモデルを 使わずに学習 4
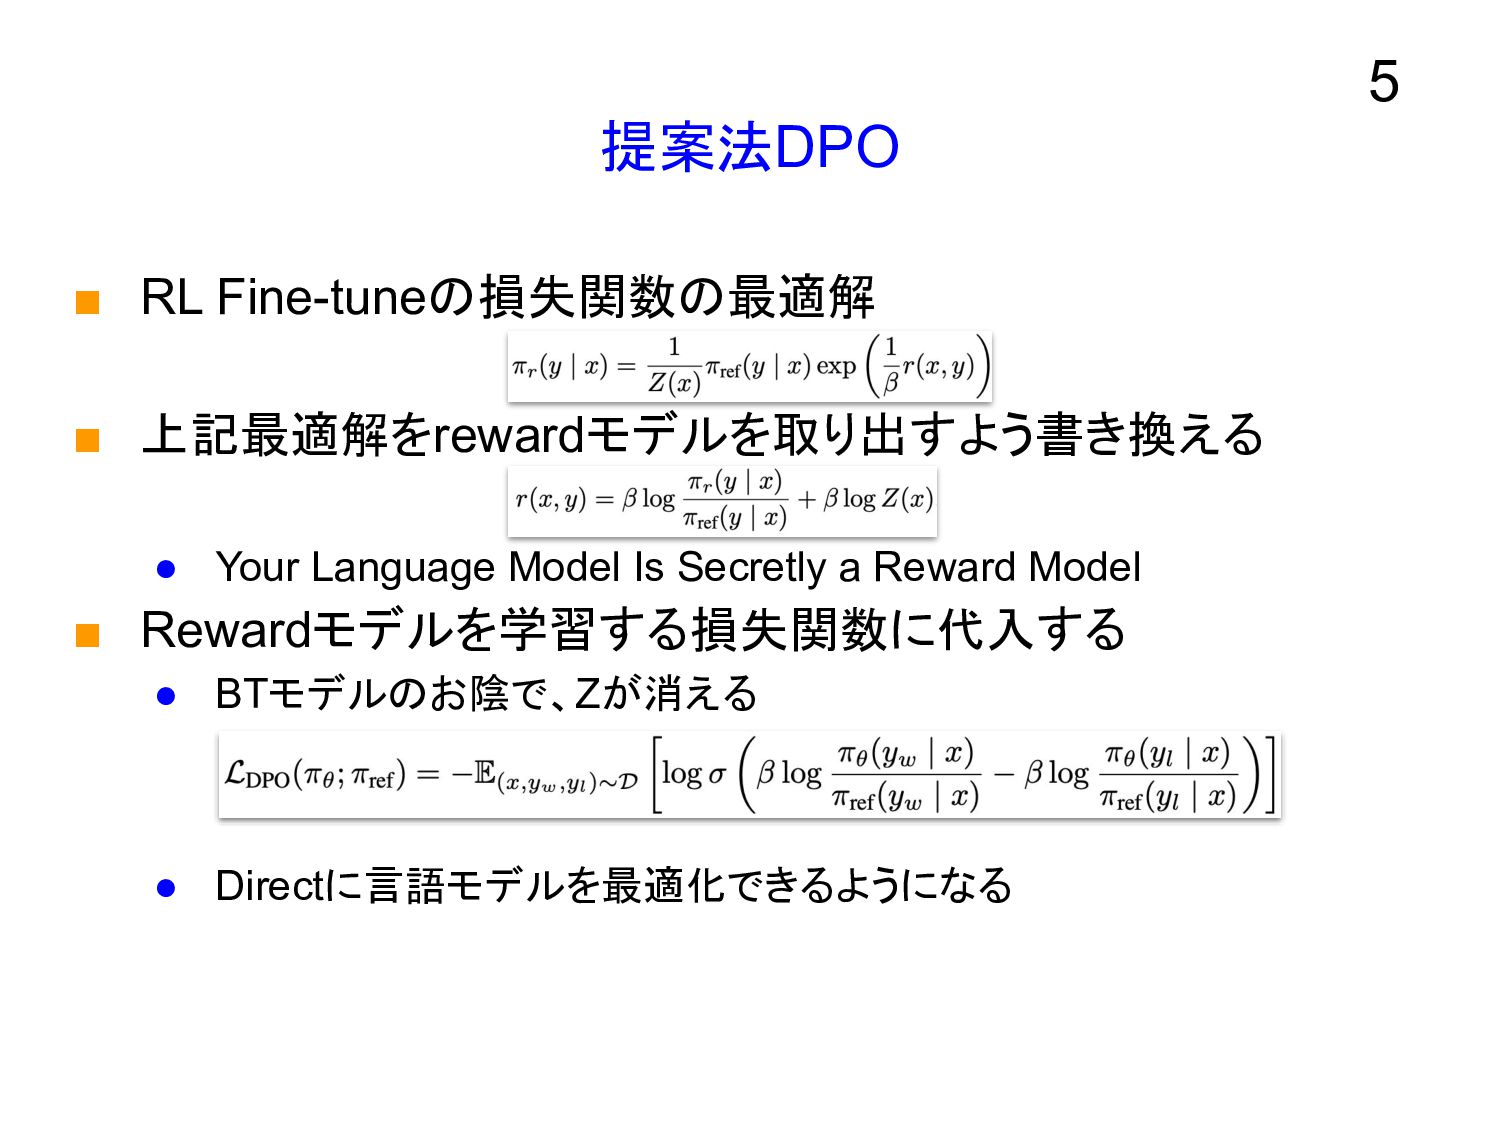
提案法DPO ▪ RL Fine-tuneの損失関数の最適解 ▪ 上記最適解をrewardモデルを取り出すよう書き換える • Your Language Model
Is Secretly a Reward Model ▪ Rewardモデルを学習する損失関数に代入する • BTモデルのお陰で、Zが消える • Directに言語モデルを最適化できるようになる 5
実験 ▪ 3つのタスクで評価 • controlled sentiment generation • summarization •
single-turn dialogue ▪ 複数スケールのデータセットでRHLFと同等またはそれ以上の 性能を確認 ▪ 多数のオープンソース言語モデルに実装 6


 zchenry
 jagupath
 trycycle
 shumpei777
 jarvist
 voginip
 nagano
 martinlippert
 sugarenia
 apolaine
 varn
 katarinadahlin
 csswizardry
 schroneko
 takai
 eileencodes
 tamaranovitovic
 rabernat
 hannesfritz