Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
[Journal Club]Interfacing Foundation Models’ Em...
Search
Semantic Machine Intelligence Lab., Keio Univ.
PRO
January 12, 2024
Technology
250
1
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
[Journal Club]Interfacing Foundation Models’ Embeddings
Semantic Machine Intelligence Lab., Keio Univ.
PRO
January 12, 2024
More Decks by Semantic Machine Intelligence Lab., Keio Univ.
See All by Semantic Machine Intelligence Lab., Keio Univ.
[RSJ26] Building a VLA Model Based on Self-Distilled Classification
keio_smilab
PRO
0
200
[RSJ26] AnoleVLA: Lightweight Vision-Language-Action Model with Deep State Space Models for Mobile Manipulation
keio_smilab
PRO
0
160
[RSJ26] NarrativeFlow: Flow-Based Vision-Language-Action Model Using Robot Velocity Fields
keio_smilab
PRO
0
230
[RSJ26] Flow as Flow: Modeling Robot Velocity Fields as Probability Velocity Fields
keio_smilab
PRO
1
230
[RSJ26] Hierarchy-Aware Multimodal Retrieval-Augmented Generation for Embodied Question Answering
keio_smilab
PRO
1
190
[MIRU26] Open-Vocabulary Intention-Guided Object Detection in Diverse Scenes
keio_smilab
PRO
0
230
[Journal club] Evo-1: Lightweight Vision-Language-Action Model with Preserved Semantic Alignment
keio_smilab
PRO
0
55
[MIRU26] To What Extent Does MLLM-as-a-Judge Exhibit Cross-Model Preference Bias?
keio_smilab
PRO
0
310
[Journal club] FlashVID: Efficient Video Large Language Models via Training-free Tree-based Spatiotemporal Token Merging
keio_smilab
PRO
0
49
Other Decks in Technology
See All in Technology
ビジネスを止めない技術的負債の返済のための戦略とその手法 - 技術的負債と向き合う / Complexity and Simplicity
soudai
PRO
2
390
BedrockとLambdaで作る リアルタイム進行型推理ゲーム
kawametho
0
150
Swap and Memory Reclaim - Squeezing Out More RAM
ennael
PRO
1
1.5k
覗いてみよう 関数型ビジュアル言語×2Dグラフィックスの世界
yohyamasaki
0
160
AI感のないAWS構成図をAIエージェントに描かせたい!
sagochiko
2
490
Apache Iceberg が拓く AI 時代のオープンレイクハウス
tomtanaka
0
210
IR Today: Theory, Practice, and Agents
dtunkelang
0
320
KanaAI
shreyas1009
0
140
FinTech 1-2 : Overview of FinTech
ks91
PRO
0
120
[2026-09-30]ロックンロールは鳴り止まないっ - 信頼性かまってちゃん - 「データ駆動を投げ捨ててまで。」追いかける信頼性改善に向けた取り組みの話
tosite
0
180
形式手法を使って仕様をコーディングしよう
mikanichinose
0
160
Oracle Cloud Infrastructure(OCI):Onboarding Session(はじめてのOCI/Oracle Supportご利⽤ガイド)
oracle4engineer
PRO
3
21k
Featured
See All Featured
Connecting the Dots Between Site Speed, User Experience & Your Business [WebExpo 2025]
tammyeverts
11
1k
Navigating Team Friction
lara
192
16k
Large-scale JavaScript Application Architecture
addyosmani
515
110k
Paper Plane (Part 1)
katiecoart
PRO
2
11k
Building AI with AI
inesmontani
PRO
1
1.3k
Performance Is Good for Brains [We Love Speed 2024]
tammyeverts
12
1.9k
Ethics towards AI in product and experience design
skipperchong
2
410
The Web Performance Landscape in 2024 [PerfNow 2024]
tammyeverts
12
1.3k
How to build a perfect <img>
jonoalderson
1
6.1k
Groundhog Day: Seeking Process in Gaming for Health
codingconduct
0
380
Jamie Indigo - Trashchat’s Guide to Black Boxes: Technical SEO Tactics for LLMs
techseoconnect
PRO
0
690
Efficient Content Optimization with Google Search Console & Apps Script
katarinadahlin
PRO
1
900
Transcript
Xueyan Zou1, Linjie Li2, Jianfeng Wang2, Jianwei Yang2, Mingyu Ding3,
Zhengyuan Yang2, Feng Li4, Hao Zhang4, Shilong Liu5, Arul Aravinthan1, Yong Lee1, Lijuan Wang2, 1UW-Madison, 2Microsoft, 3UC Berkeley, 4HKUST, 5Tsinghua University Interfacing Foundation Models’ Embeddings Zou, Xueyan, et al. "Interfacing Foundation Models' Embeddings." arXiv preprint arXiv:2312.07532, 2023. 慶應義塾大学 飯岡雄偉
概要:視覚言語間の相互入力/出力を可能に ▪ X-Decoder [Zou+, CVPR23],SEEM [Zou+, NeurIPS23]の後続モデル ▪ 背景 ◦
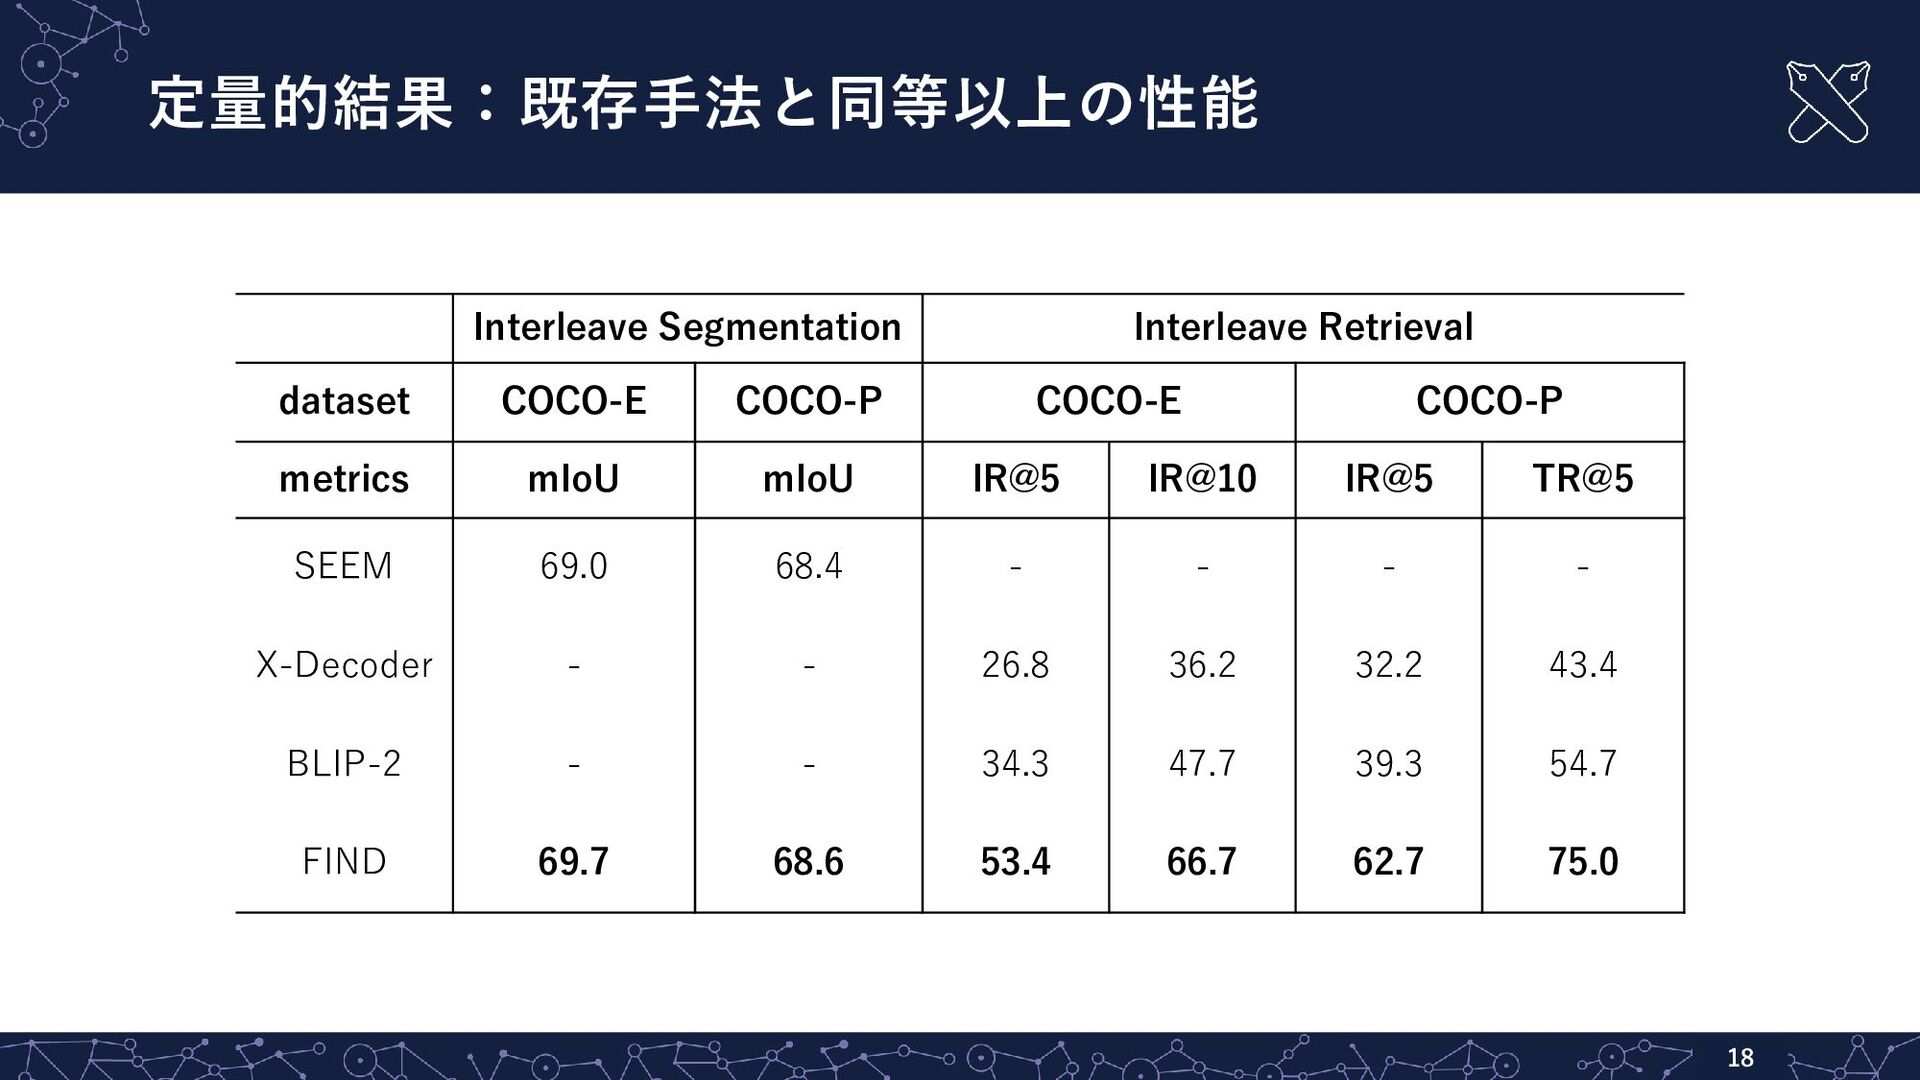
基盤モデルの訓練はコストが大きい & モダリティやタスクの制限がある ▪ 提案手法:FIND ◦ Configを書き換えるだけで様々なモダリティやタスクを統一的に扱うモデル ➢ 柔軟性があり,多様な基盤モデルへ応用可能 ▪ 結論 ◦ 新たなベンチマークFIND-Bench,SegmentationおよびImage Retrievalにおい て、既存手法と同等以上の性能 2
背景:大規模基盤モデルの制限 ▪ 出力のモダリティが単一なものが多く,制限がある 3 BLIP-2 [Li+, ICML23] VQA → Text
DALL·E 3 [Betker+, 2023] Image generation → Image
関連研究:基盤モデルをマルチモーダルに拡張 ▪ Prompt engineering:SoM [Yang+, 2023] ◦ ☺入出力のマルチモーダル化 ◦ 基盤モデルが扱うタスクそのものを拡張できて
いない 4 ▪ Adaptive tuning ◦ VisionLLM [Wang+, 2023] ◦ ☺出力形式の拡張 ◦ 基盤モデルそのものの拡張
関連研究:X-Decoder, SEEMにおける基盤モデル ▪ X-Decoder [Zou+, CVPR23] ◦ マルチモーダル/タスクの基盤モデル ◦ 統一されたdecoderで複数タスクを扱う
◦ 入力は画像と言語のみ 5 ▪ SEEM [Zou+, NeurIPS23] ◦ 言語での接地にとどまらず,画像内物体 を指定して入力できる ➢ 入力の柔軟性を向上 ◦ Segmentationタスクのみを扱う
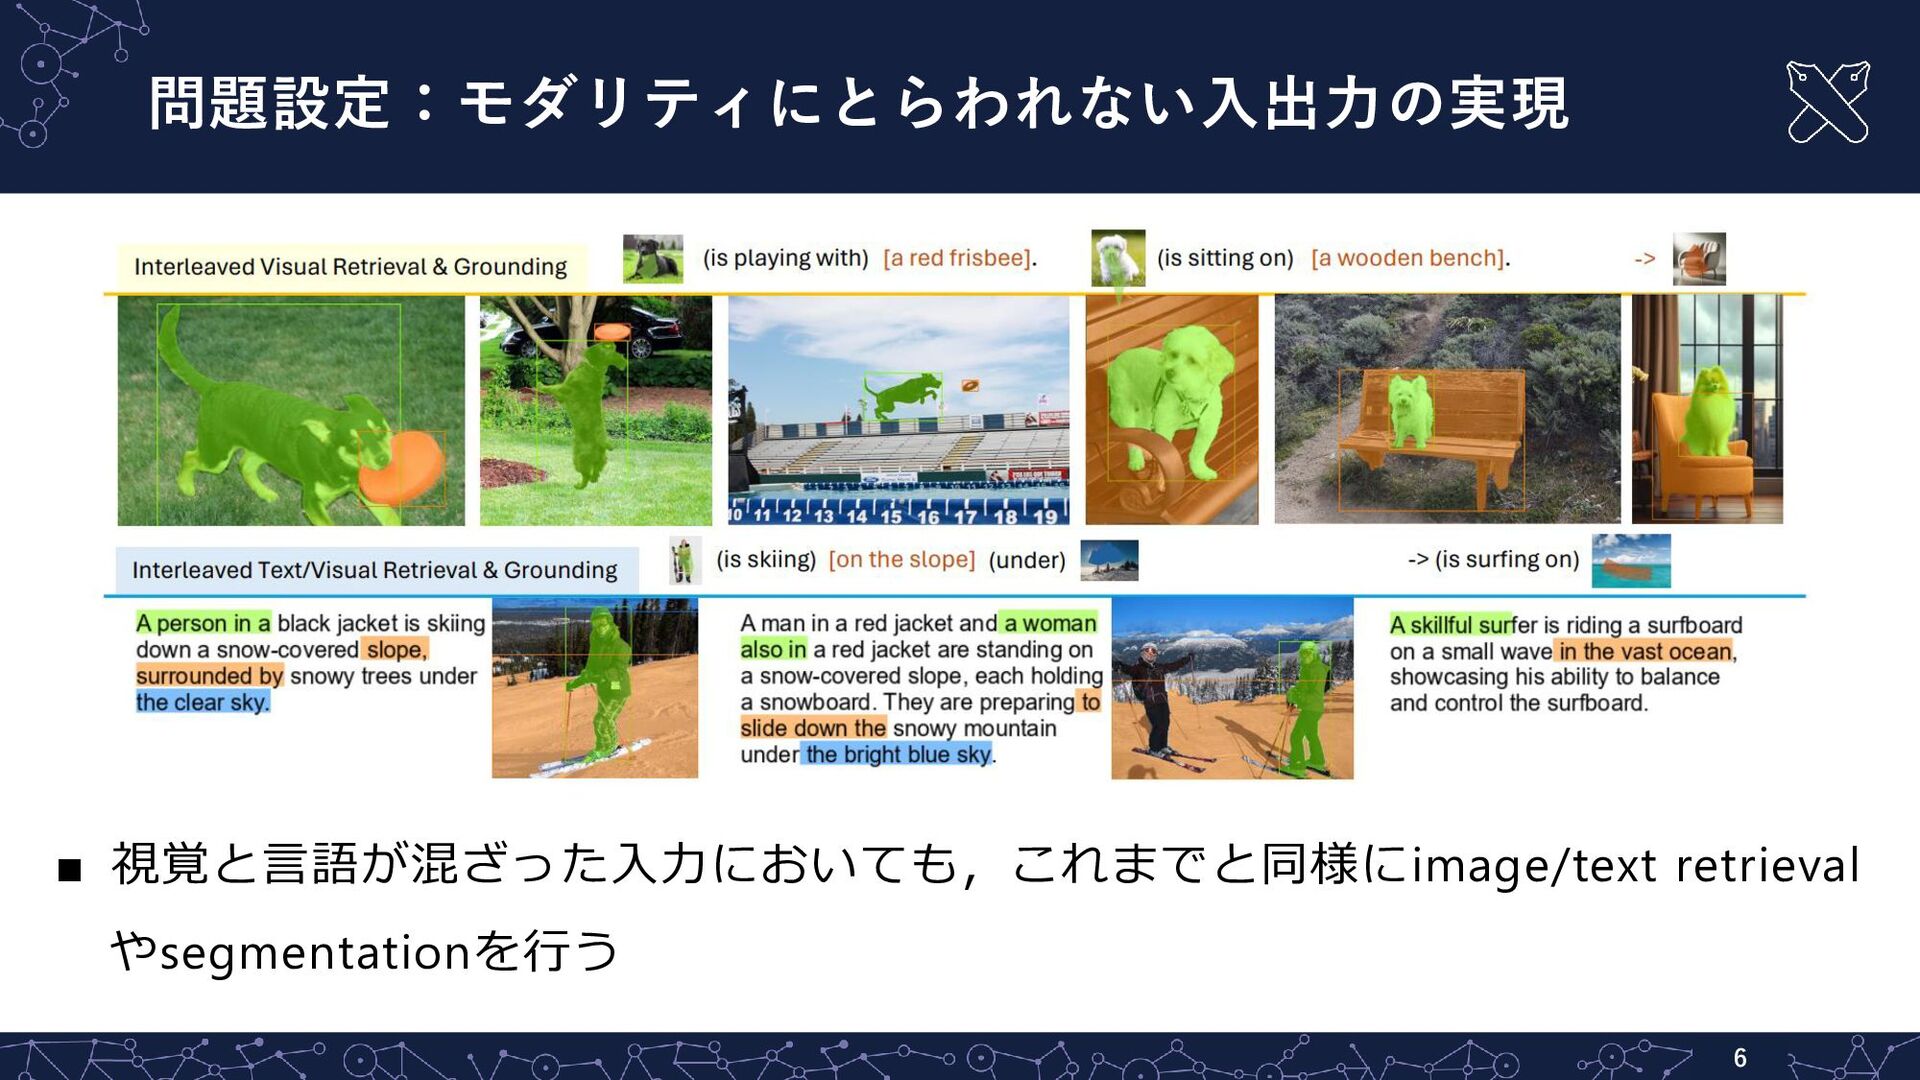
問題設定:モダリティにとらわれない入出力の実現 6 ▪ 視覚と言語が混ざった入力においても,これまでと同様にimage/text retrieval やsegmentationを行う
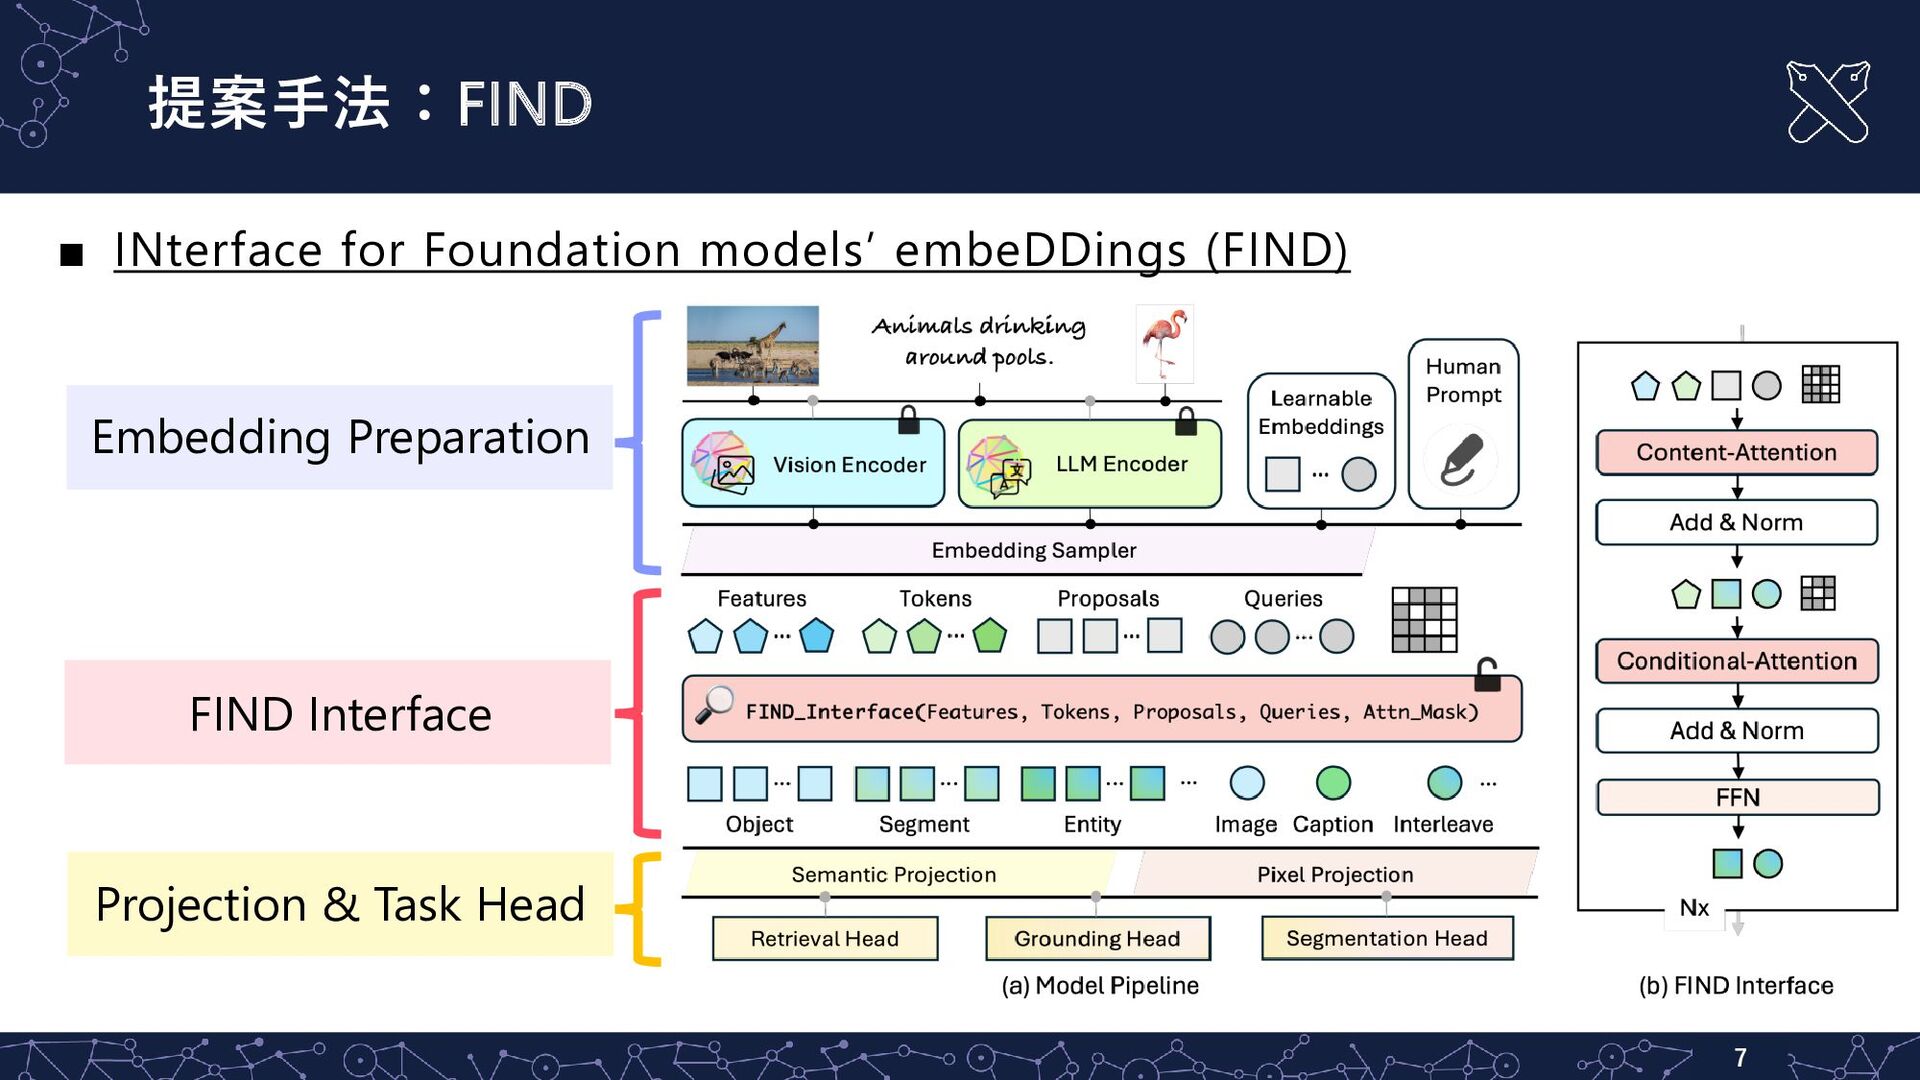
提案手法:FIND ▪ INterface for Foundation models’ embeDDings (FIND) 7 Embedding
Preparation FIND Interface Projection & Task Head
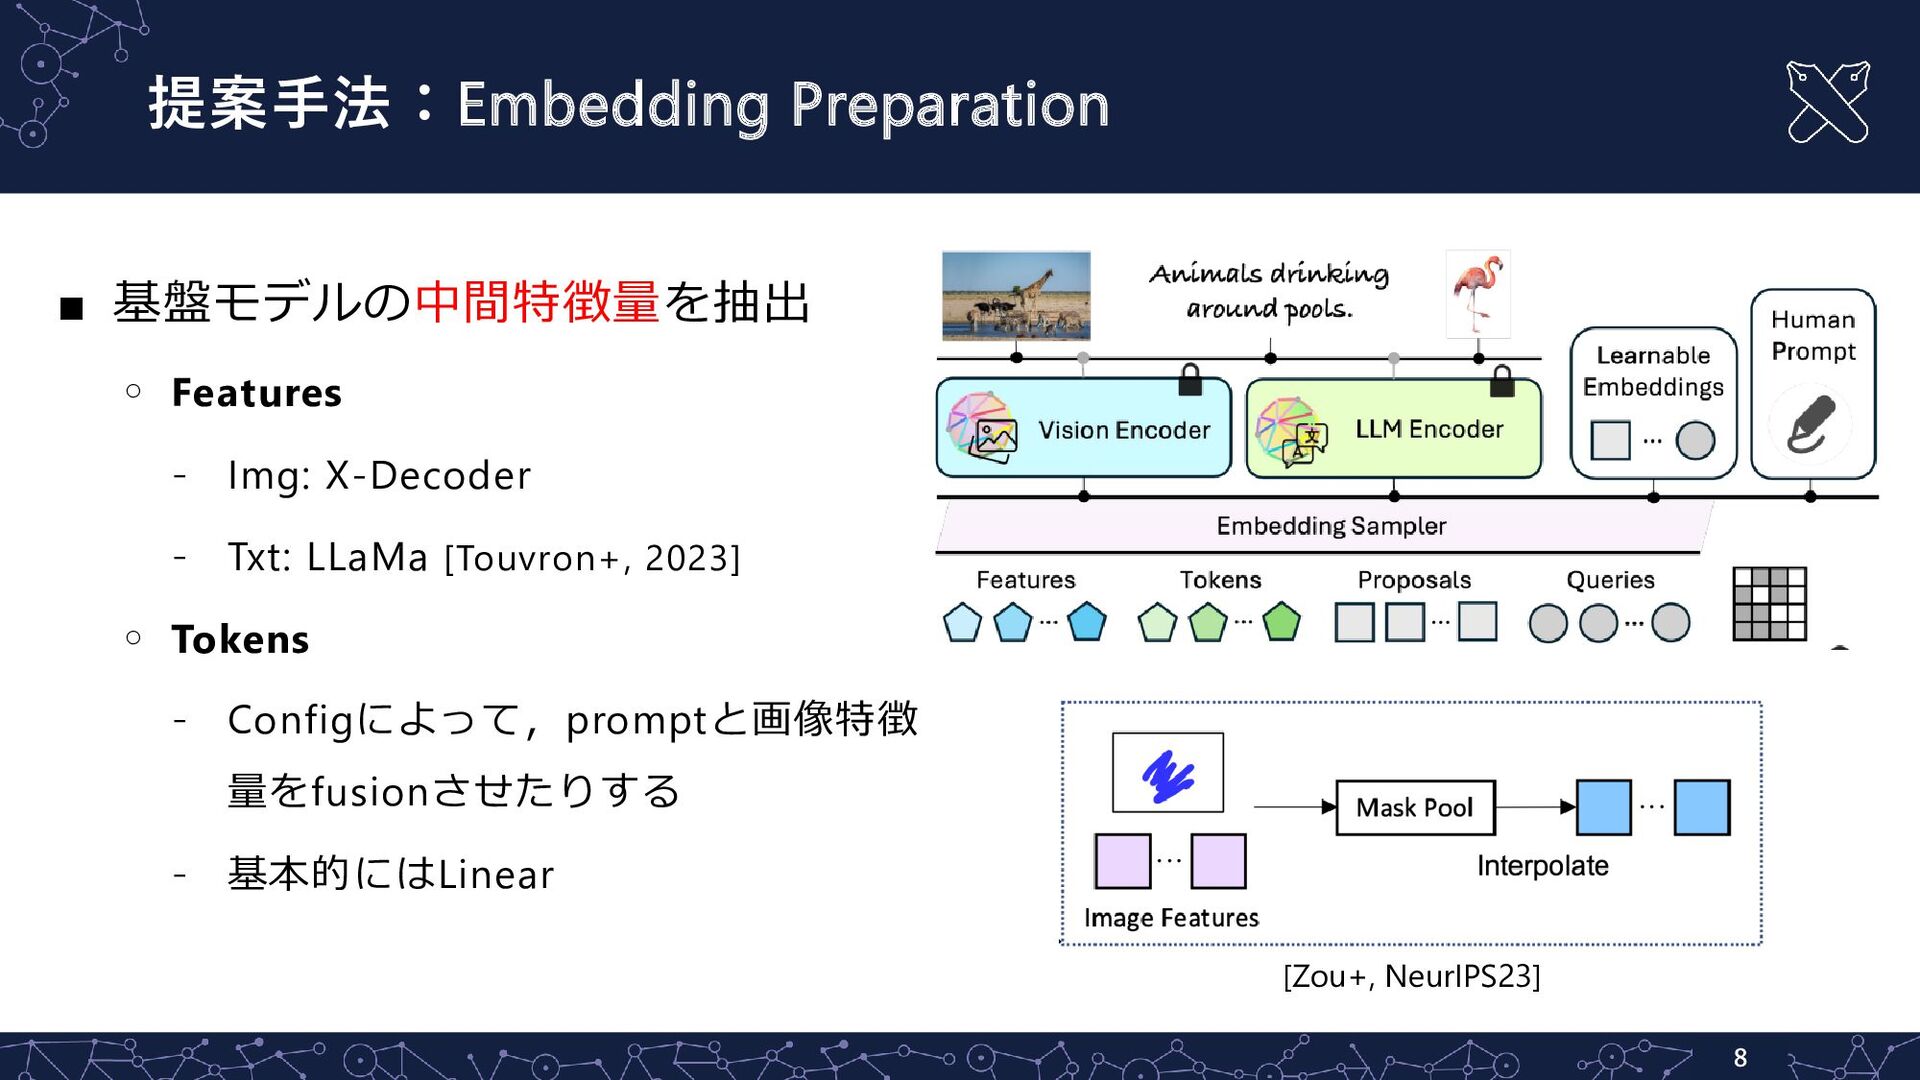
提案手法:Embedding Preparation ▪ 基盤モデルの中間特徴量を抽出 ◦ Features - Img: X-Decoder -
Txt: LLaMa [Touvron+, 2023] ◦ Tokens - Configによって,promptと画像特徴 量をfusionさせたりする - 基本的にはLinear 8 [Zou+, NeurIPS23]
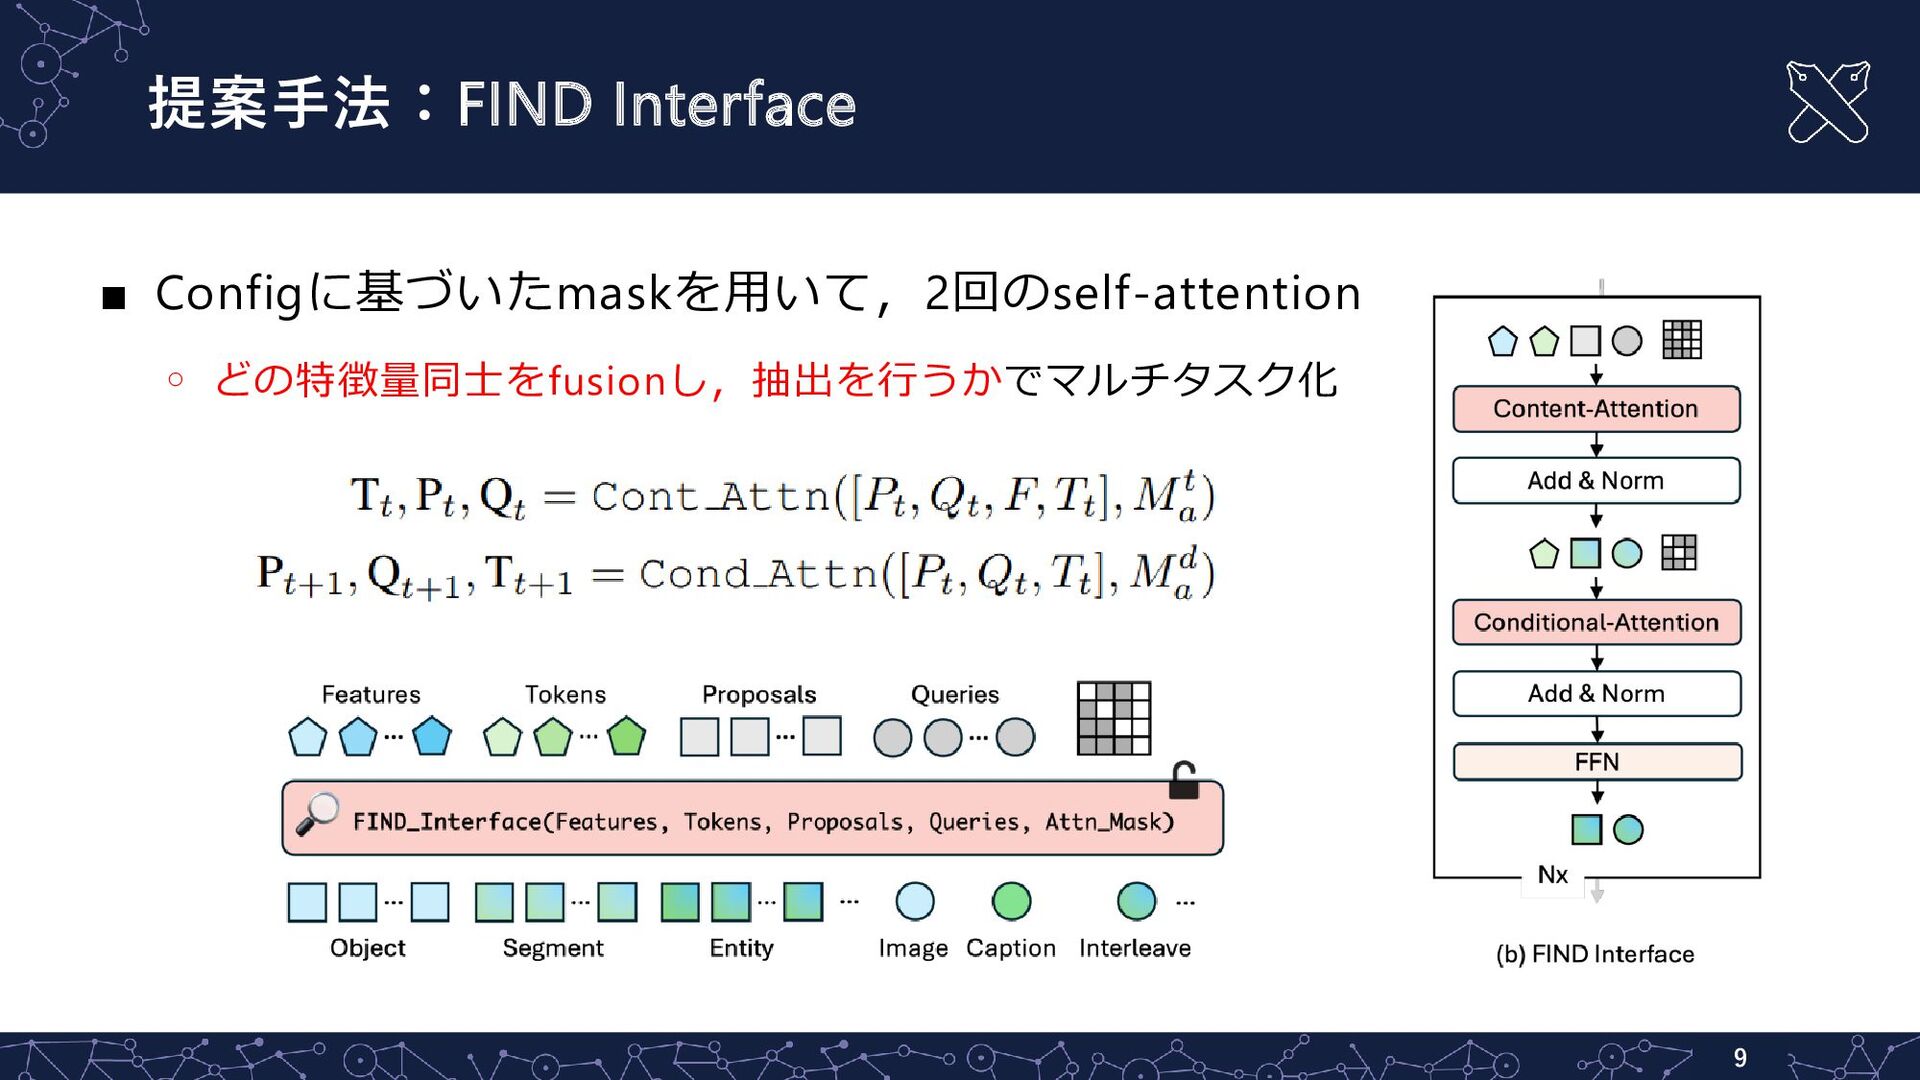
提案手法:FIND Interface ▪ Configに基づいたmaskを用いて,2回のself-attention ◦ どの特徴量同士をfusionし,抽出を行うかでマルチタスク化 9
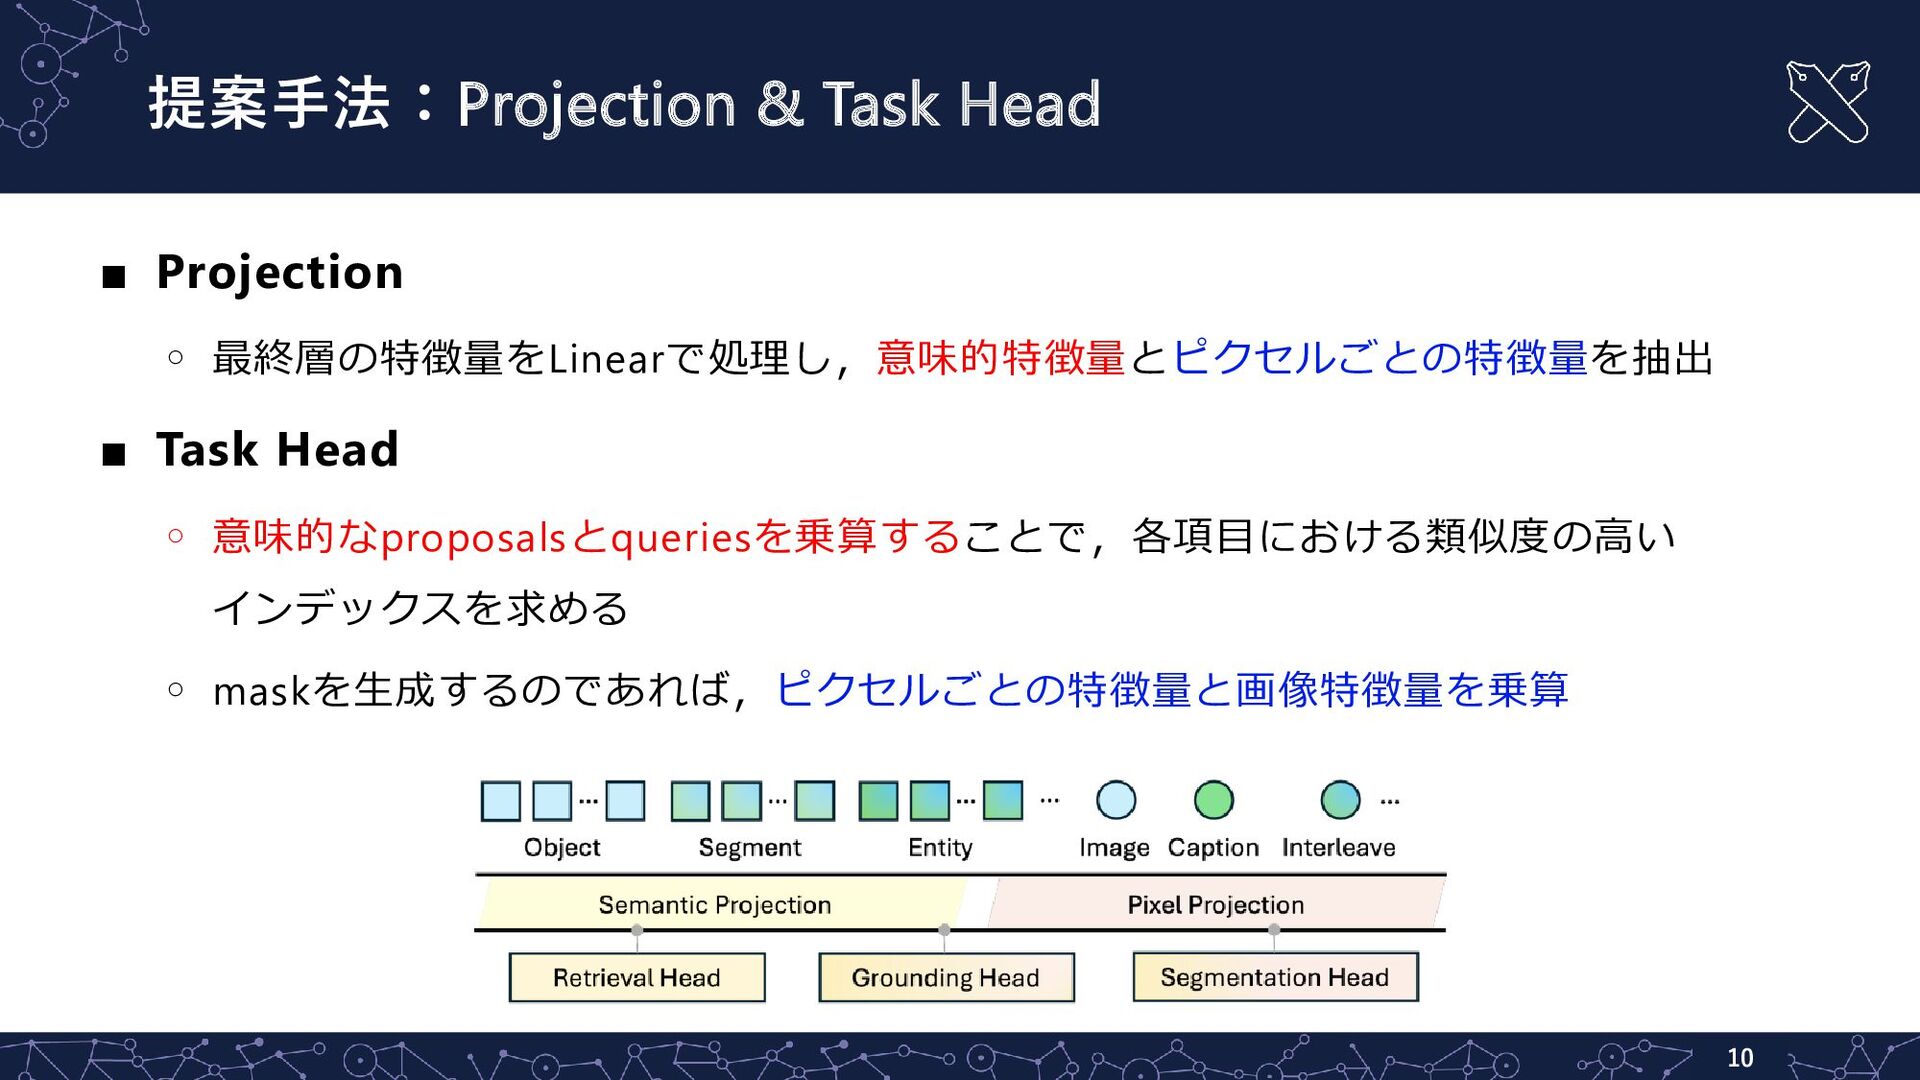
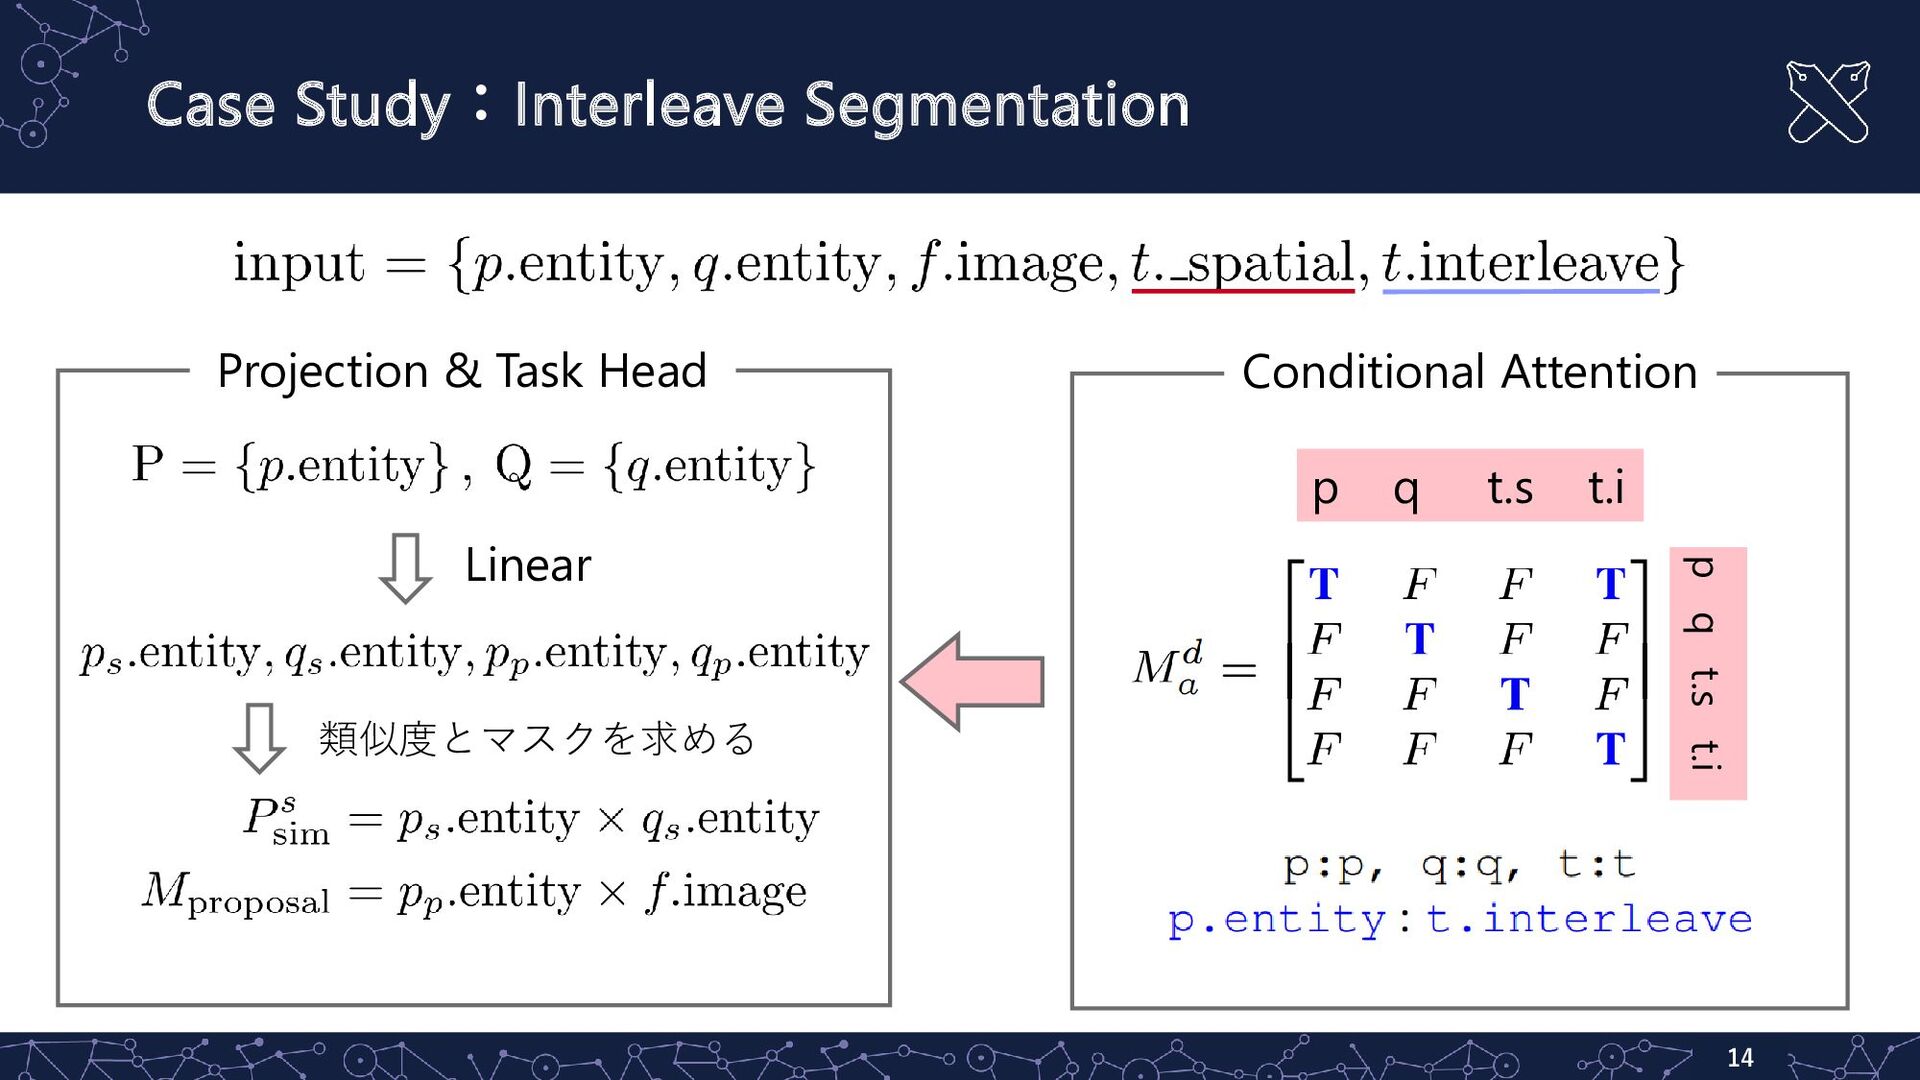
提案手法:Projection & Task Head ▪ Projection ◦ 最終層の特徴量をLinearで処理し,意味的特徴量とピクセルごとの特徴量を抽出 ▪ Task
Head ◦ 意味的なproposalsとqueriesを乗算することで,各項目における類似度の高い インデックスを求める ◦ maskを生成するのであれば,ピクセルごとの特徴量と画像特徴量を乗算 10
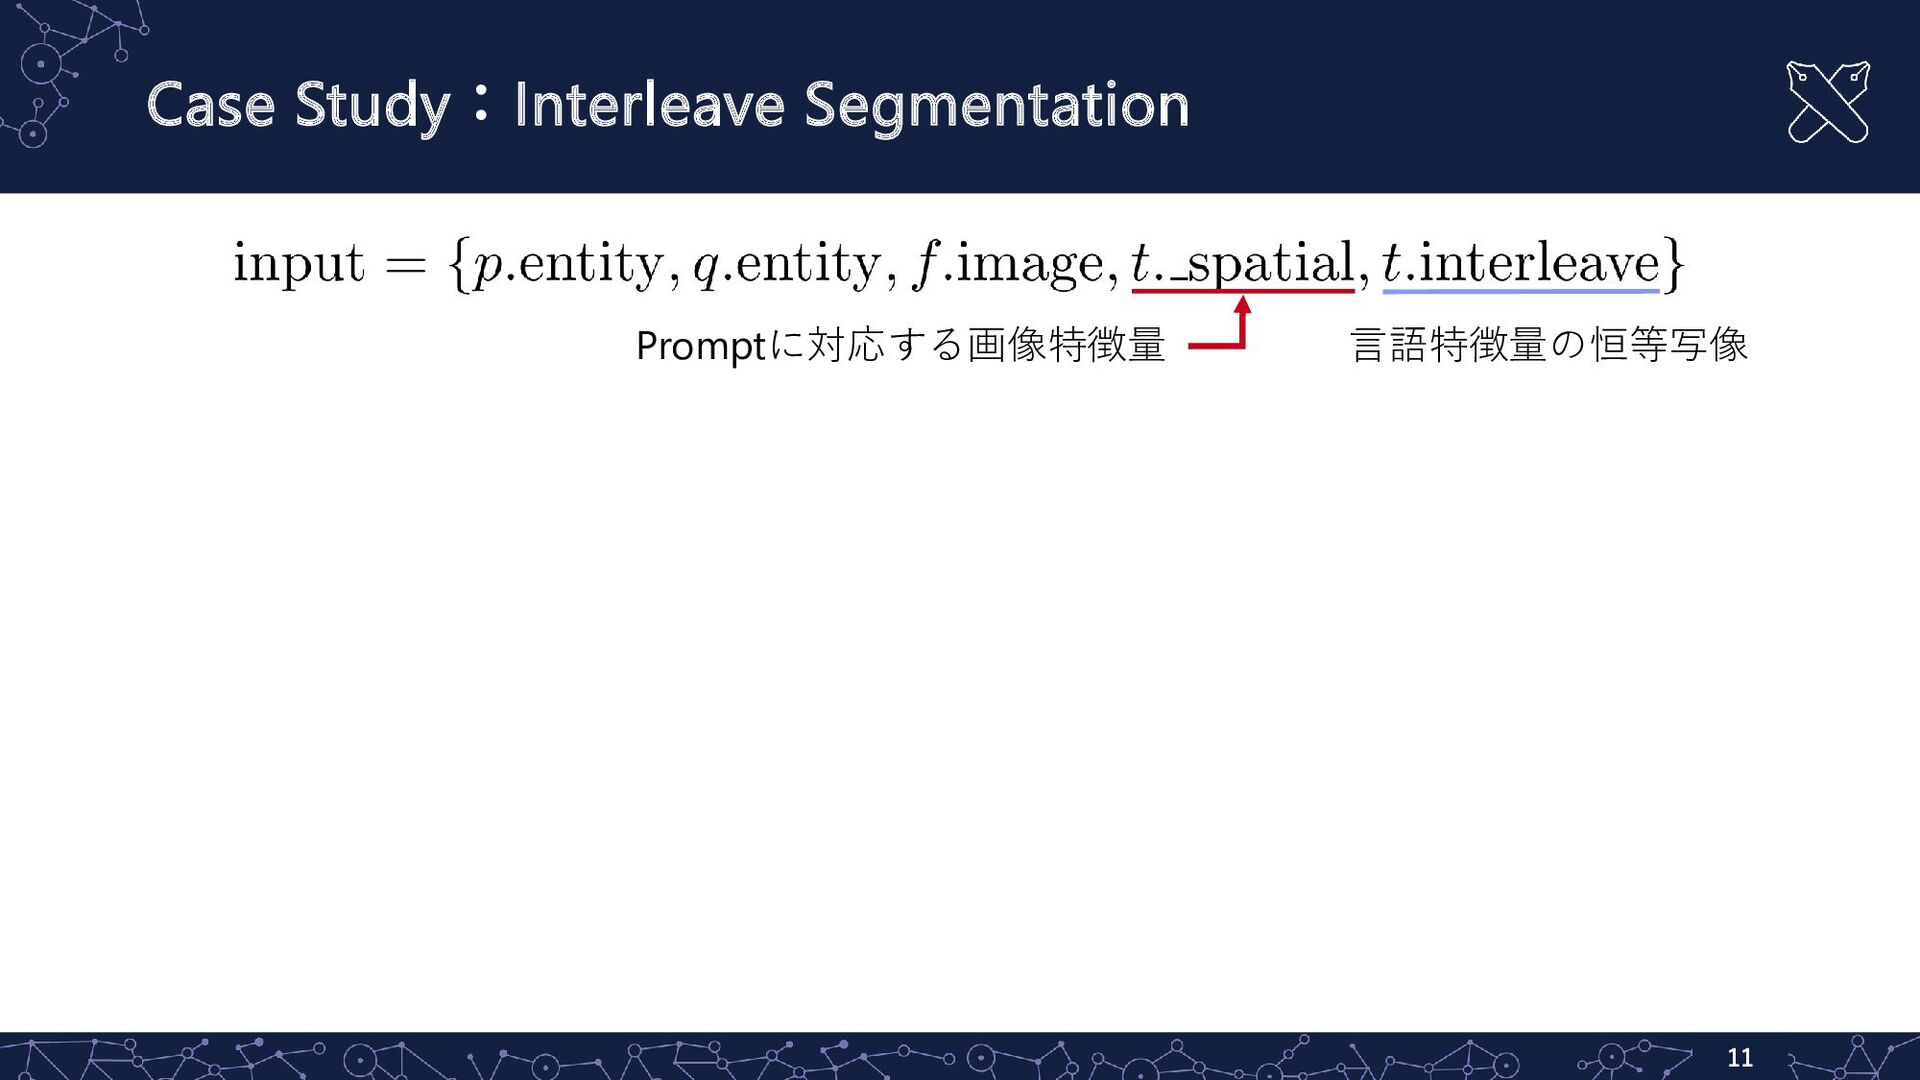
Case Study:Interleave Segmentation 11 Promptに対応する画像特徴量 言語特徴量の恒等写像
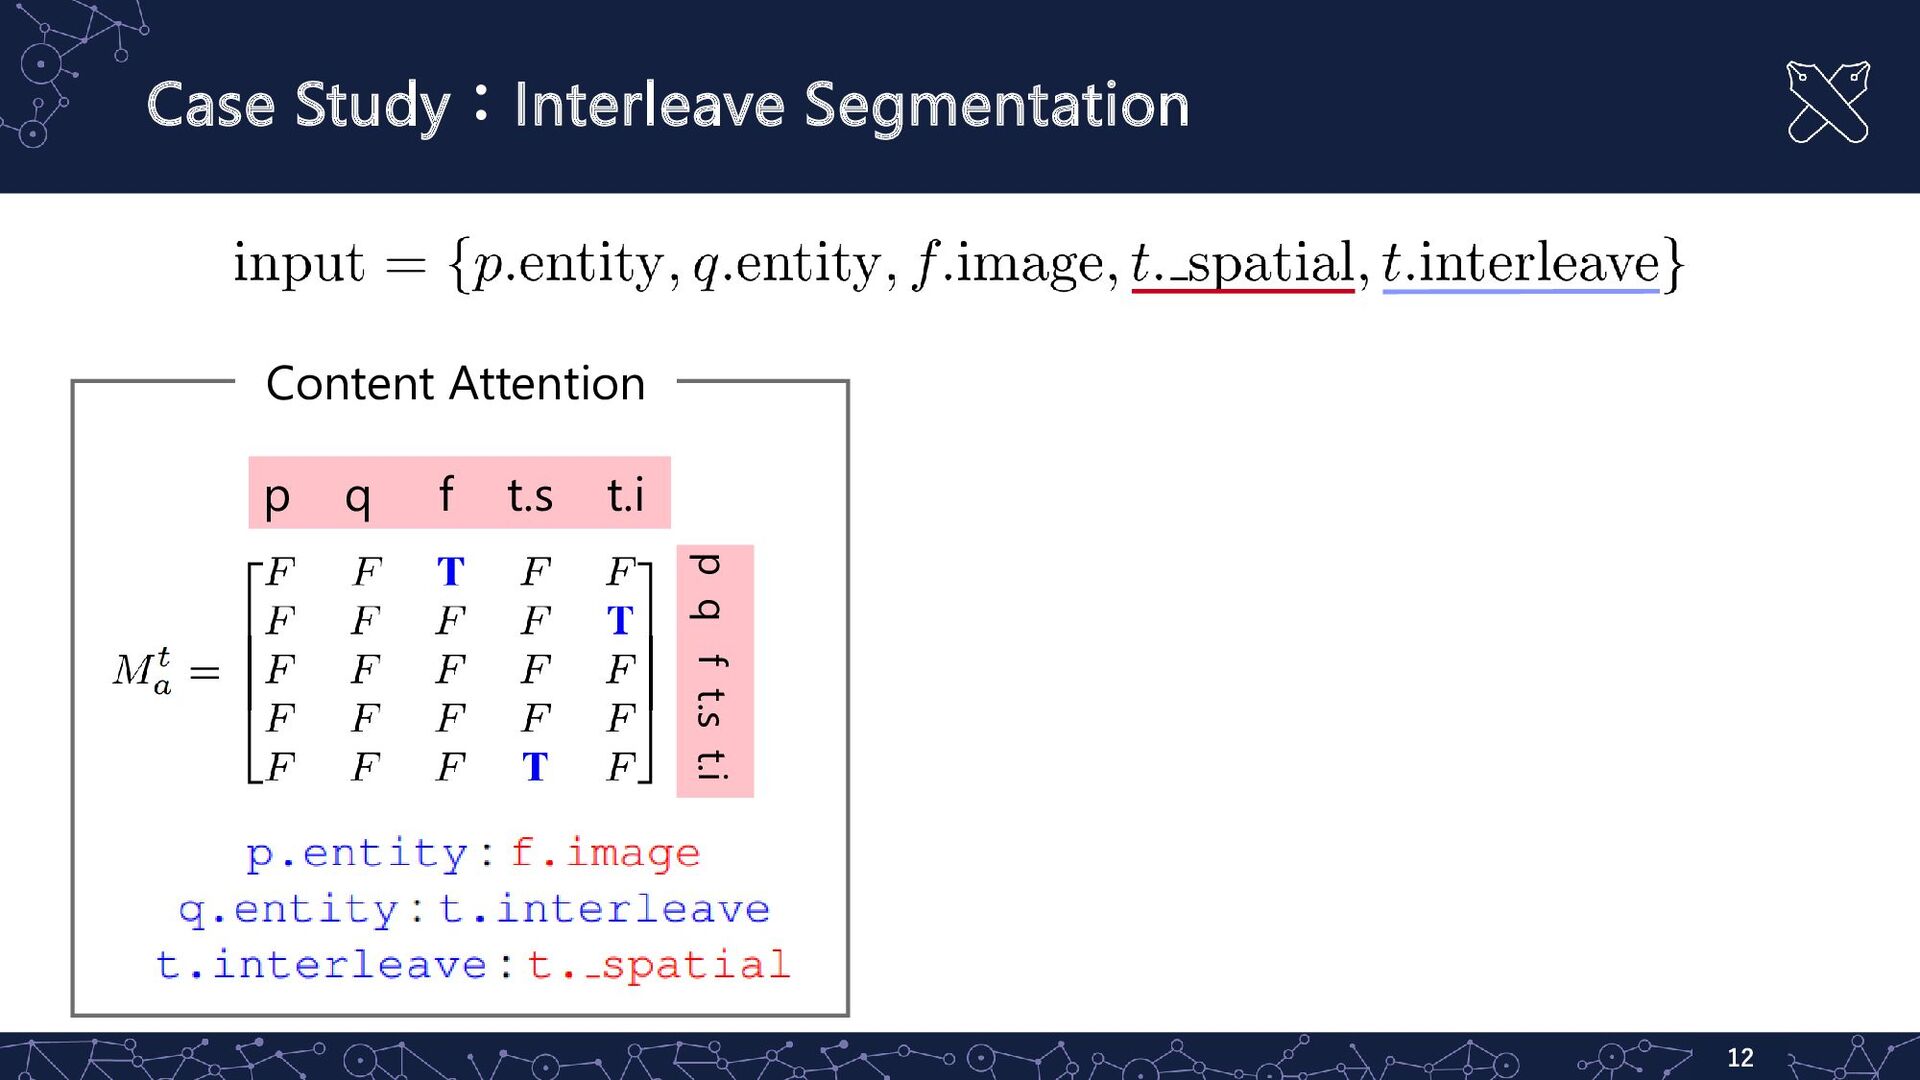
Case Study:Interleave Segmentation 12 p q f t.s t.i p
q f t.s t.i Content Attention
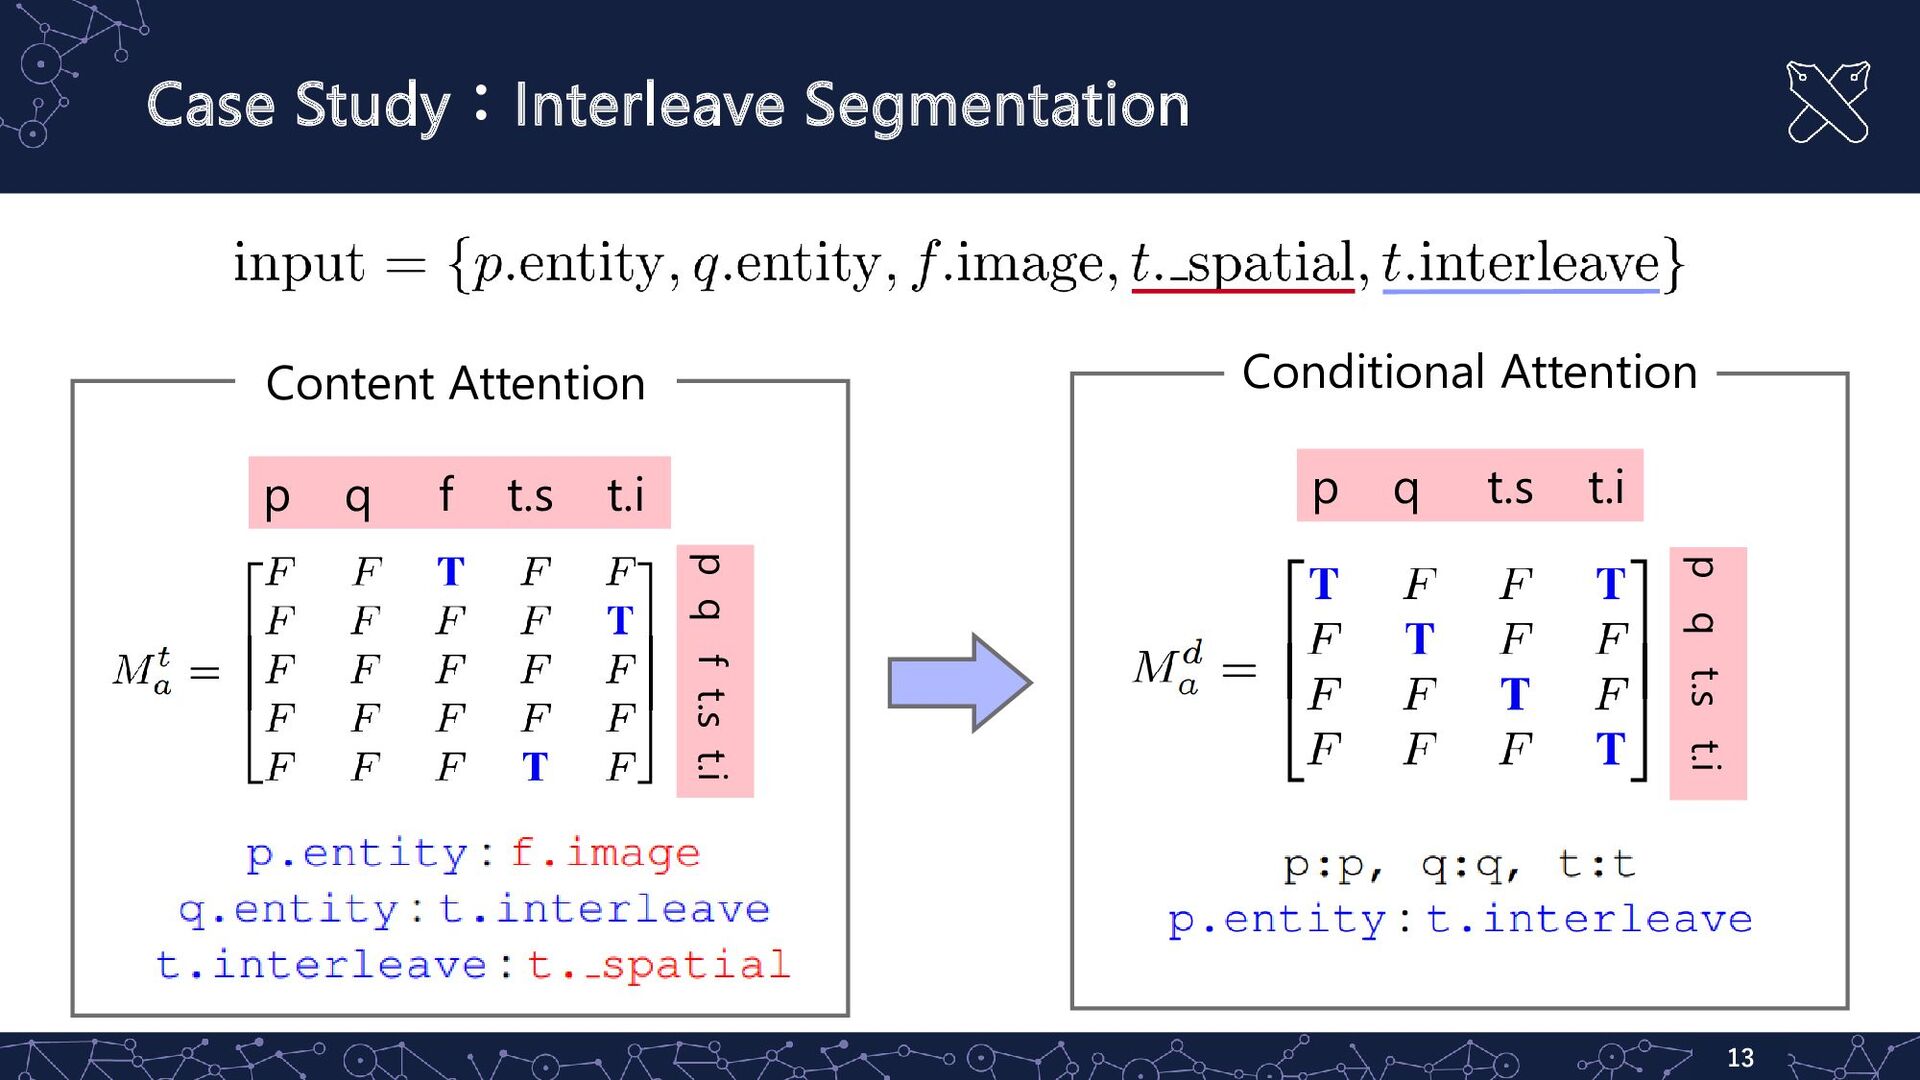
Case Study:Interleave Segmentation 13 p q f t.s t.i p
q f t.s t.i Content Attention p q t.s t.i p q t.s t.i Conditional Attention
Case Study:Interleave Segmentation 14 p q t.s t.i p q
t.s t.i Linear 類似度とマスクを求める Projection & Task Head Conditional Attention
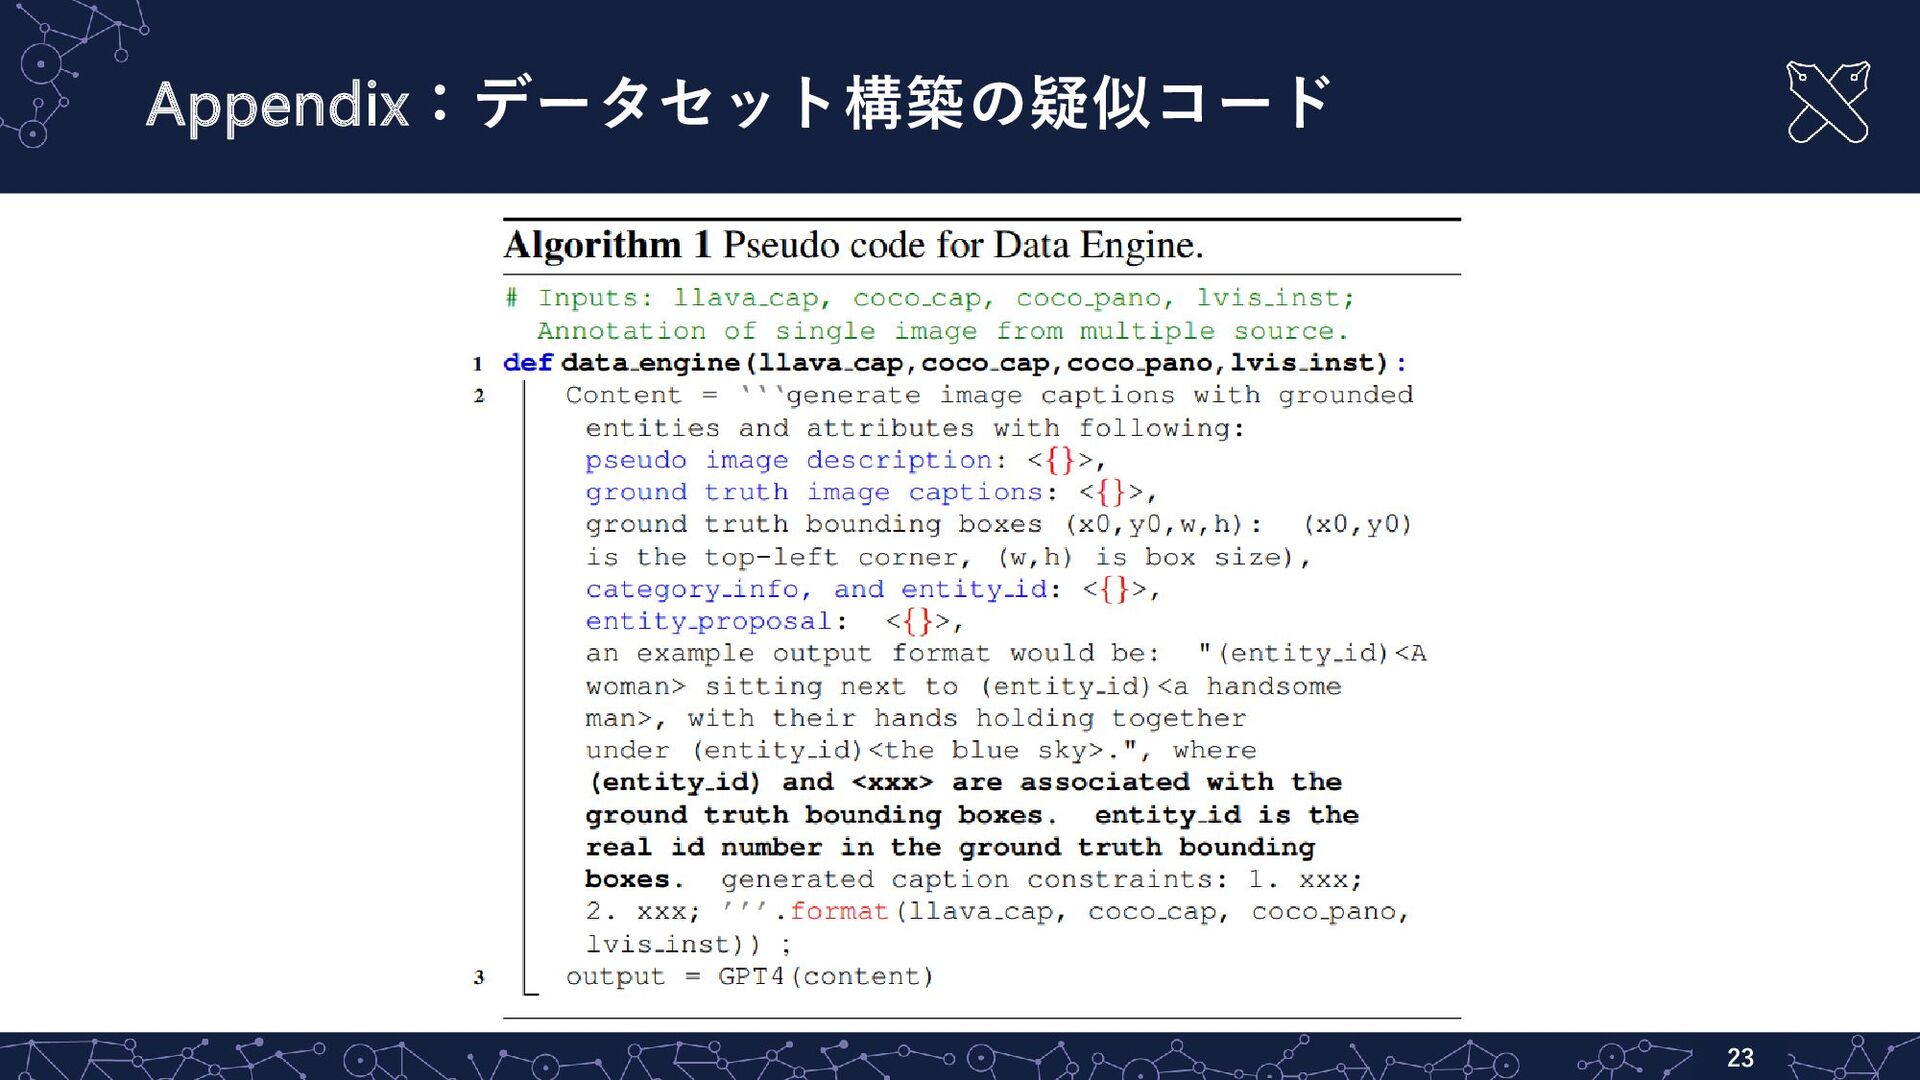
実験設定:新たなベンチマークFIND-Bench ▪ データセット ◦ COCO系統のデータセットをGPT-4やLLaVa [Liu+, NeurIPS23]によるcaptionで拡張 15
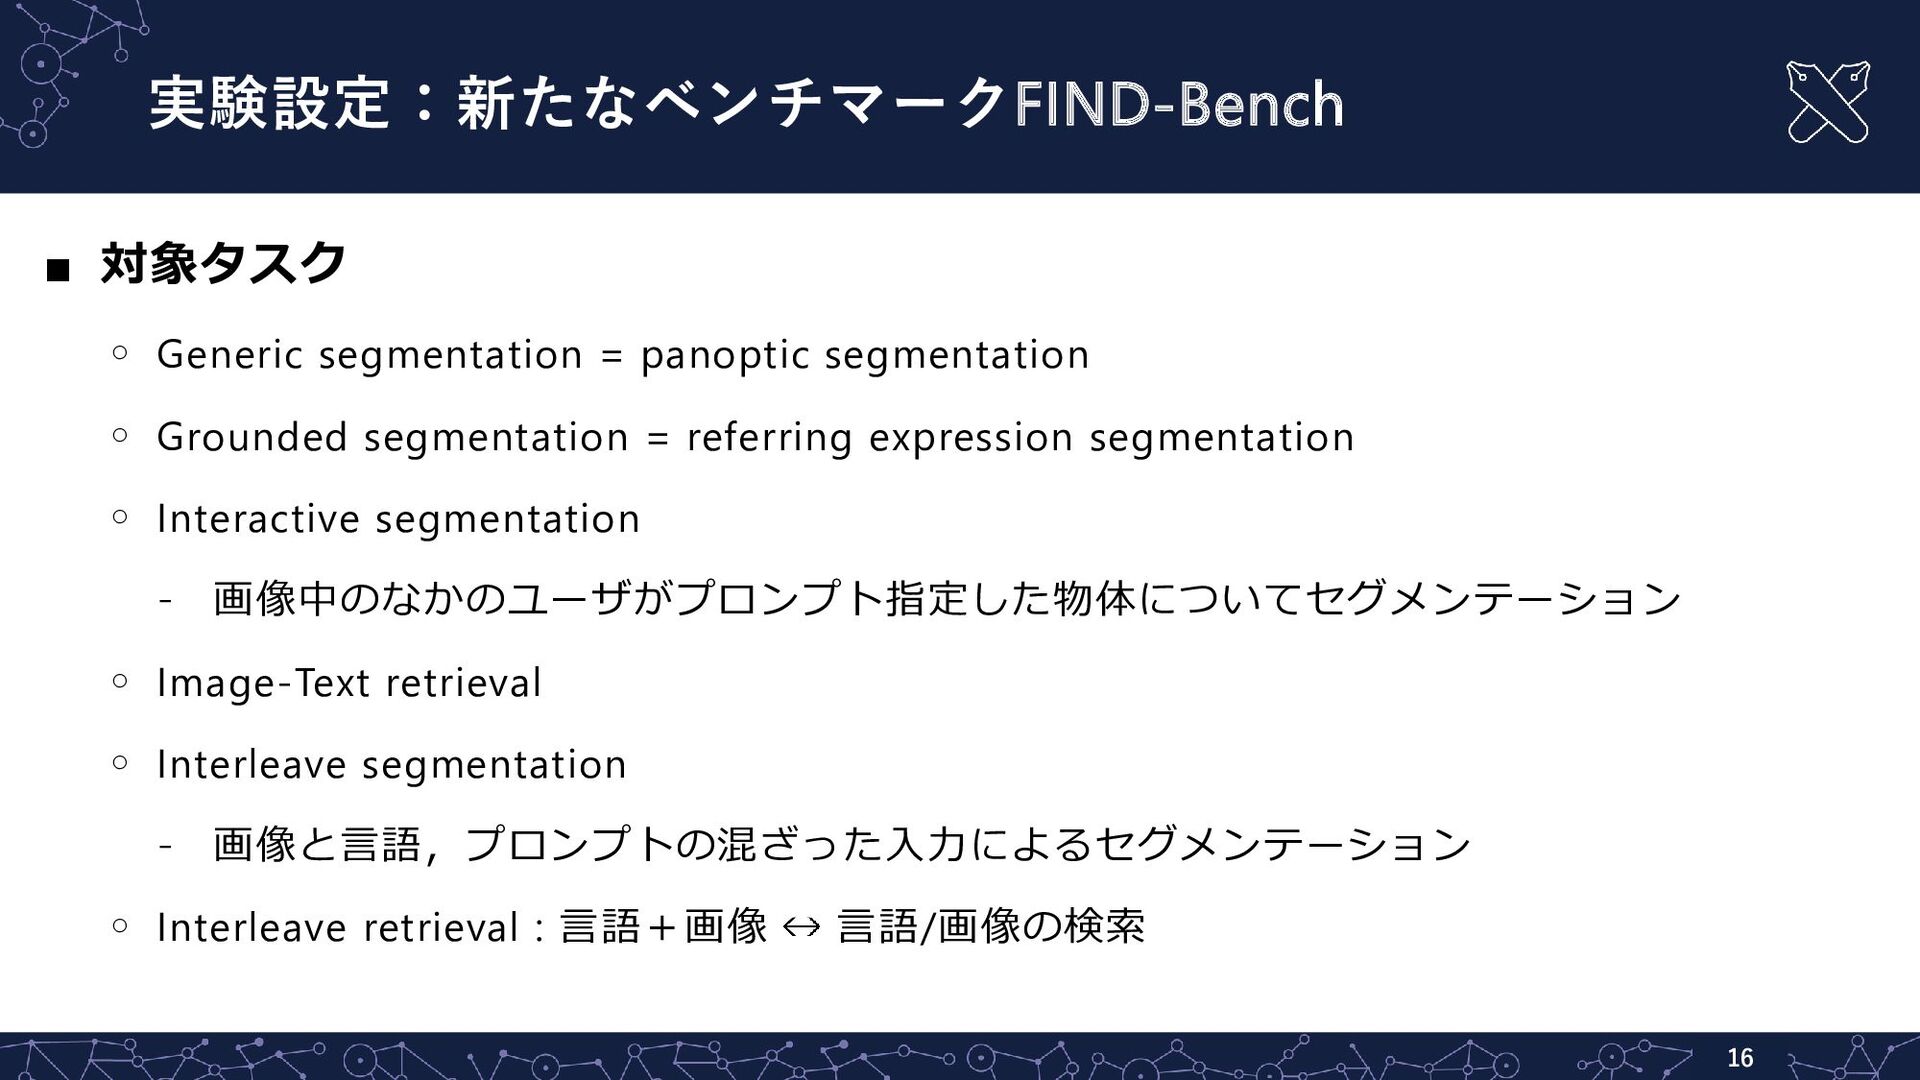
実験設定:新たなベンチマークFIND-Bench ▪ 対象タスク ◦ Generic segmentation = panoptic segmentation ◦
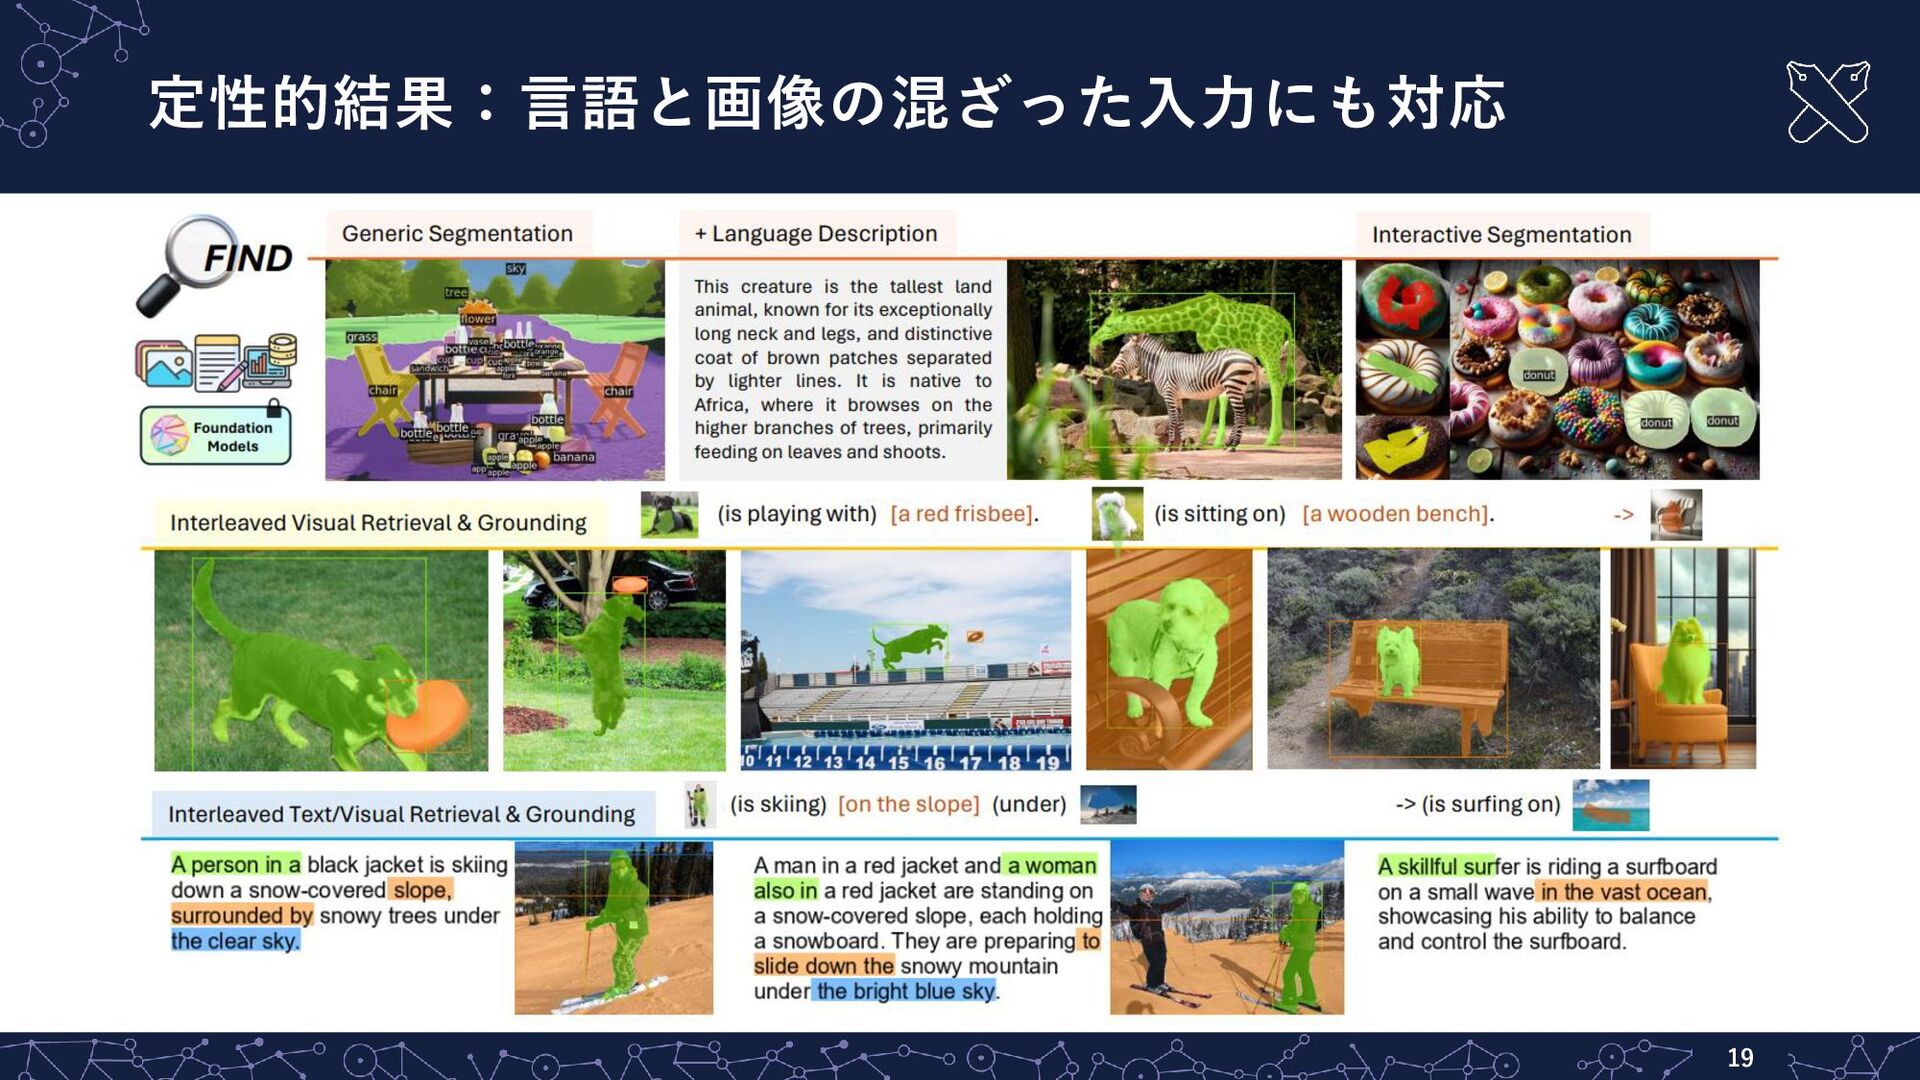
Grounded segmentation = referring expression segmentation ◦ Interactive segmentation - 画像中のなかのユーザがプロンプト指定した物体についてセグメンテーション ◦ Image-Text retrieval ◦ Interleave segmentation - 画像と言語,プロンプトの混ざった入力によるセグメンテーション ◦ Interleave retrieval : 言語+画像 言語/画像の検索 16
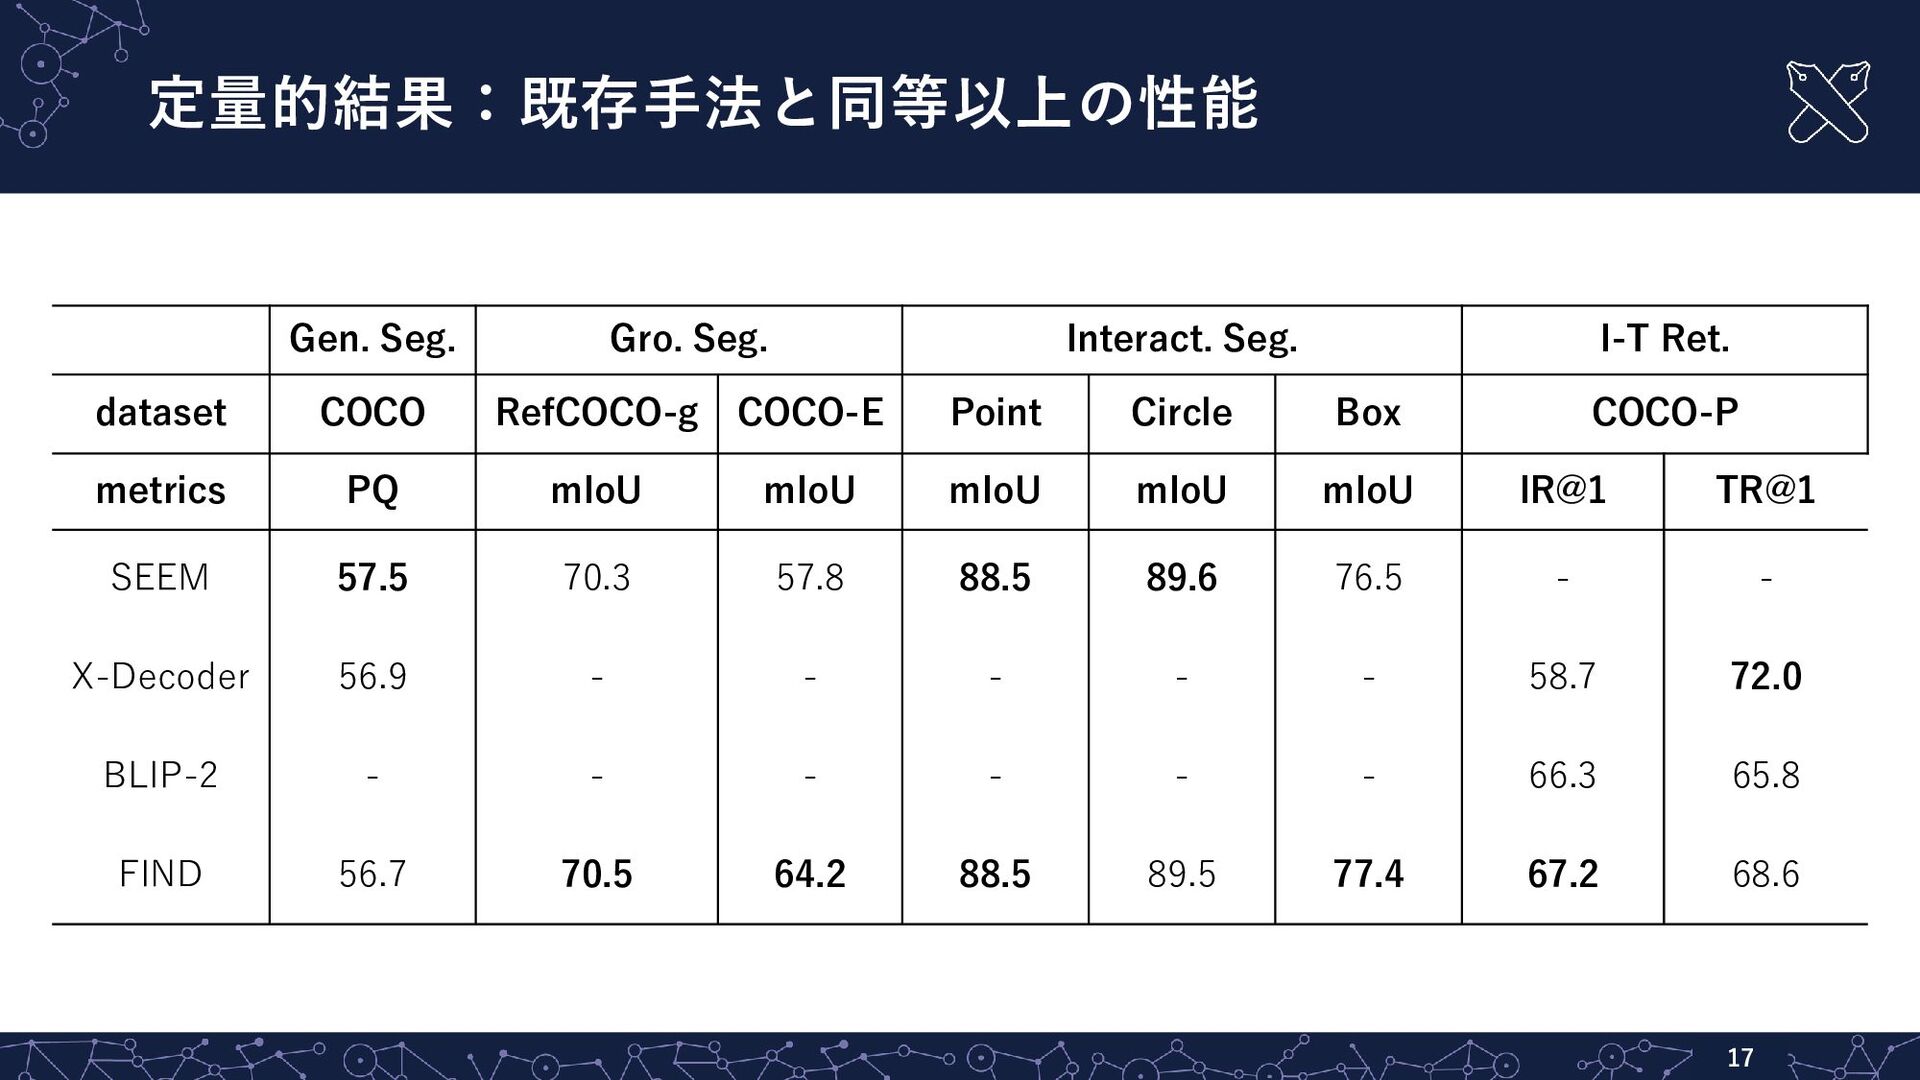
定量的結果:既存手法と同等以上の性能 17 Gen. Seg. Gro. Seg. Interact. Seg. I-T Ret.
dataset COCO RefCOCO-g COCO-E Point Circle Box COCO-P metrics PQ mIoU mIoU mIoU mIoU mIoU IR@1 TR@1 SEEM 57.5 70.3 57.8 88.5 89.6 76.5 - - X-Decoder 56.9 - - - - - 58.7 72.0 BLIP-2 - - - - - - 66.3 65.8 FIND 56.7 70.5 64.2 88.5 89.5 77.4 67.2 68.6
定量的結果:既存手法と同等以上の性能 18 Interleave Segmentation Interleave Retrieval dataset COCO-E COCO-P COCO-E
COCO-P metrics mIoU mIoU IR@5 IR@10 IR@5 TR@5 SEEM 69.0 68.4 - - - - X-Decoder - - 26.8 36.2 32.2 43.4 BLIP-2 - - 34.3 47.7 39.3 54.7 FIND 69.7 68.6 53.4 66.7 62.7 75.0
定性的結果:言語と画像の混ざった入力にも対応 ▪ aa 19
実際にやってみた ▪ Talk2Car [Deruyttere+, EMNLP19] 20
まとめ:FIND ▪ X-Decoder [Zou+, CVPR23],SEEM [Zou+, NeurIPS23]の後続モデル ▪ 背景 ◦
基盤モデルの訓練はコストが大きい & モダリティやタスクの制限がある ▪ 提案手法:FIND ◦ Configを書き換えるだけで様々なモダリティやタスクを統一的に扱うモデル ➢ 柔軟性があり,多様な基盤モデルへ応用可能 ▪ 結論 ◦ 新たなベンチマークFIND-Bench,SegmentationおよびImage Retrievalにおいて、既存 手法と同等以上の性能 21
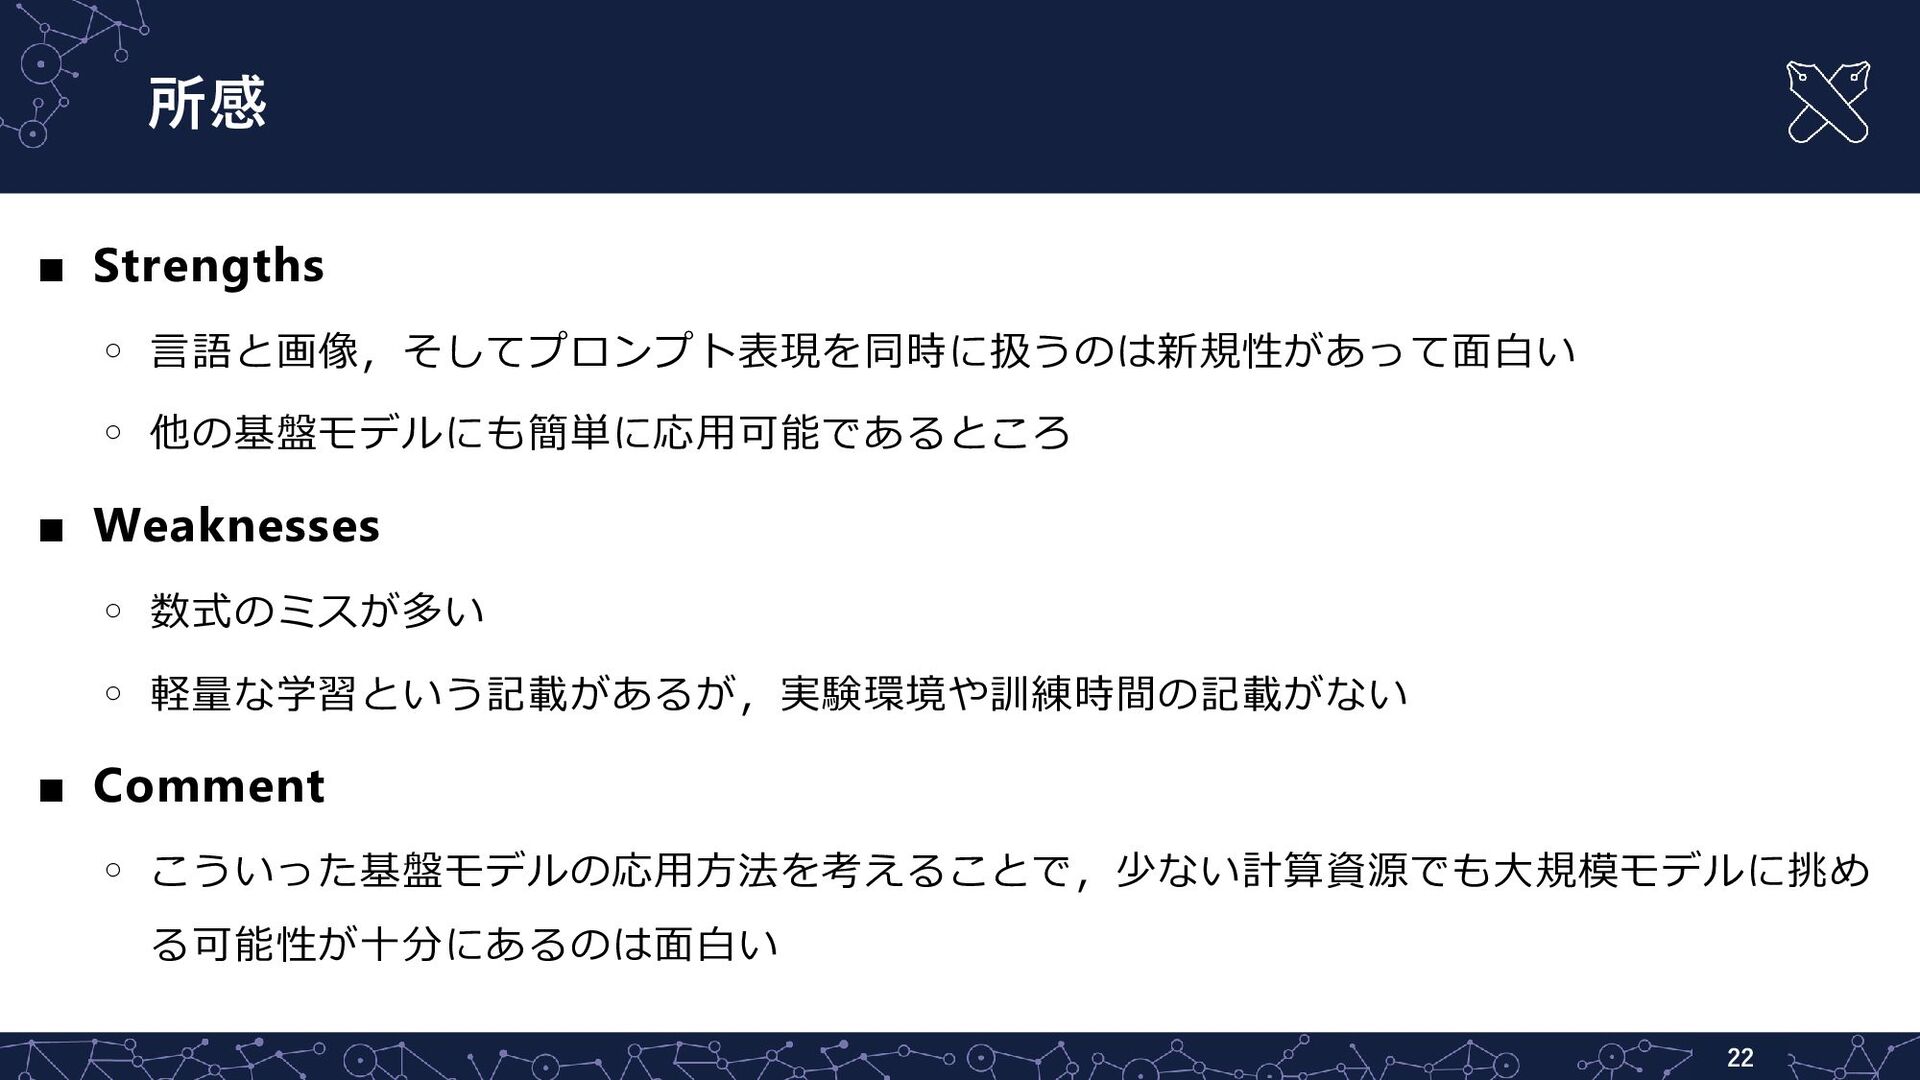
所感 ▪ Strengths ◦ 言語と画像,そしてプロンプト表現を同時に扱うのは新規性があって面白い ◦ 他の基盤モデルにも簡単に応用可能であるところ ▪ Weaknesses ◦
数式のミスが多い ◦ 軽量な学習という記載があるが,実験環境や訓練時間の記載がない ▪ Comment ◦ こういった基盤モデルの応用方法を考えることで,少ない計算資源でも大規模モデルに挑め る可能性が十分にあるのは面白い 22
Appendix:データセット構築の疑似コード 23


 keio_smilab
 soudai
 kawametho
 ennael
 yohyamasaki
 sagochiko
 tomtanaka
 dtunkelang
 shreyas1009
 ks91
 tosite
 mikanichinose
 oracle4engineer
 tammyeverts
 lara
 addyosmani
 katiecoart
 inesmontani
 skipperchong
 jonoalderson
 codingconduct
 techseoconnect
 katarinadahlin