Share
Embed
Nextflow tutorial - ACGT'14
Nextflow is a DSL for data-driven pipelines, this tutorial introduces on main concepts on show some praticale examples
Paolo Di Tommaso
May 29, 2014
Transcript
57 slides
-
WHAT IS NEXTFLOW A fluent DSL modelled around the UNIX
pipe concept that simplifies writing parallel pipelines in a portable manner -
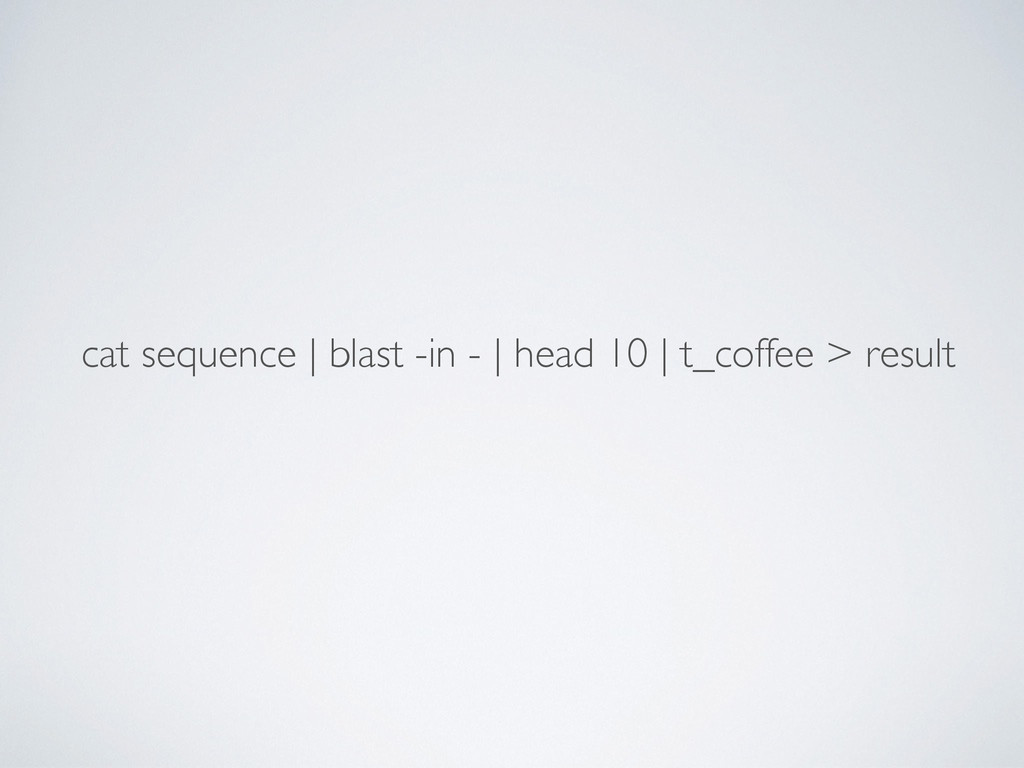
cat sequence | blast -in - | head 10 |
t_coffee > result -
THE RATIONALE • Fast prototyping • Smoothly integration with Linux
world • High-level parallelisation model -
NEXTFLOW • Portable across different execution platforms (clusters and cloud)
i.e. enable reproducibility • Error handling and crash recovery • Simplify debugging making possible to reproduce errors -
VFS Groovy Runtime Executors Tasks dispatcher Dataflow parallelisation & synchronisation
Script interpreter Java VM 7+ -
DATAFLOW • Declarative computational model for concurrent processes execution •
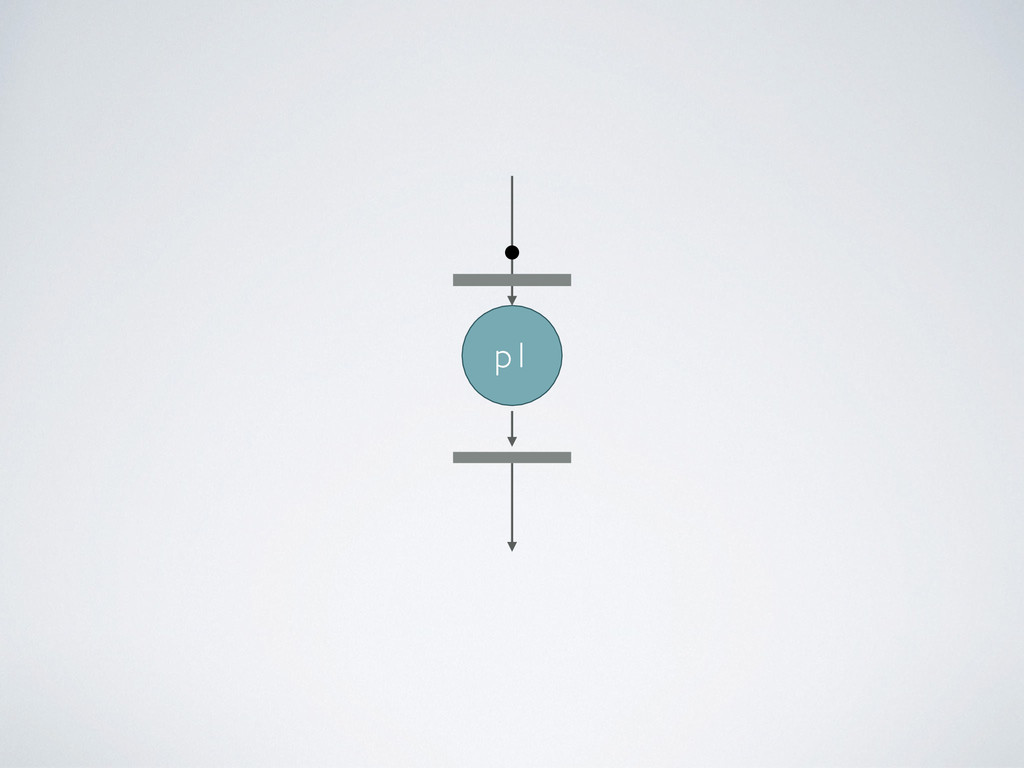
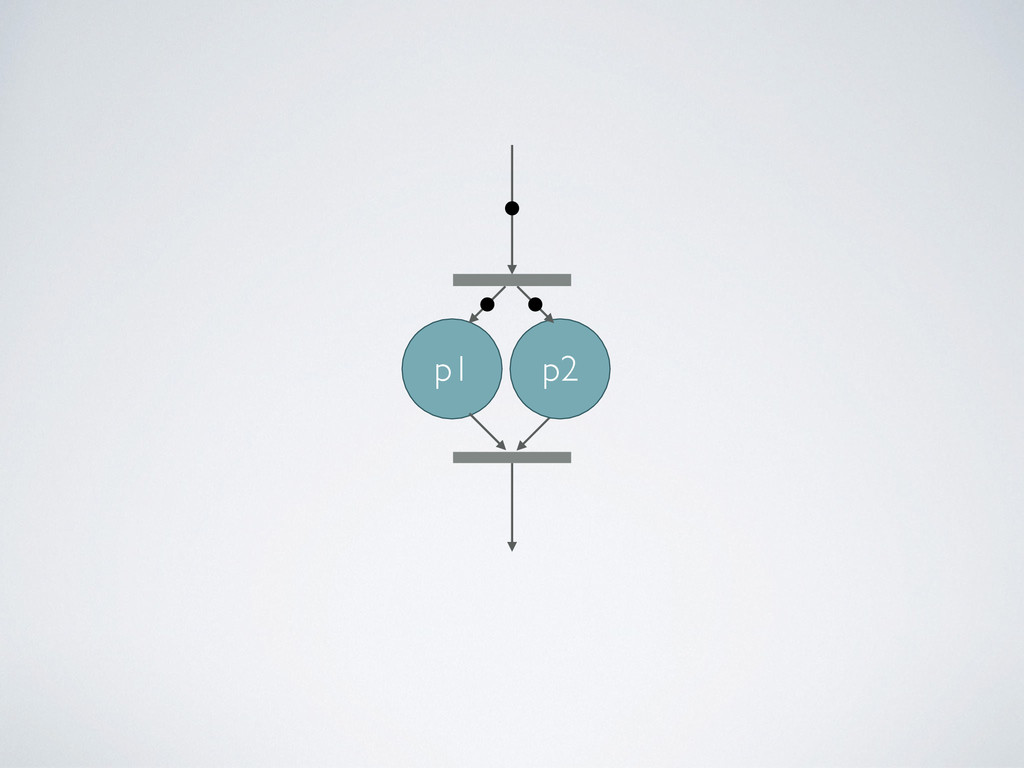
Processes wait for data, when an input set is ready the process is executed • They communicate by using dataflow variable i.e. async FIFO queues called channels • The synchronization is managed automatically -
– Henri E. Bal , Jennifer G. Steiner , Andrew
S. Tanenbaum. Programming languages for distributed computing systems (1989) “Dataflow variables are spectacularly expressive in concurrent programming when compared to explicit synchronisation” -
MAIN PRIMITIVES • Processes: run any piece of script •
Channels: unidirectional async queues that allows the processes to comunicate • Operators: transform channels content -
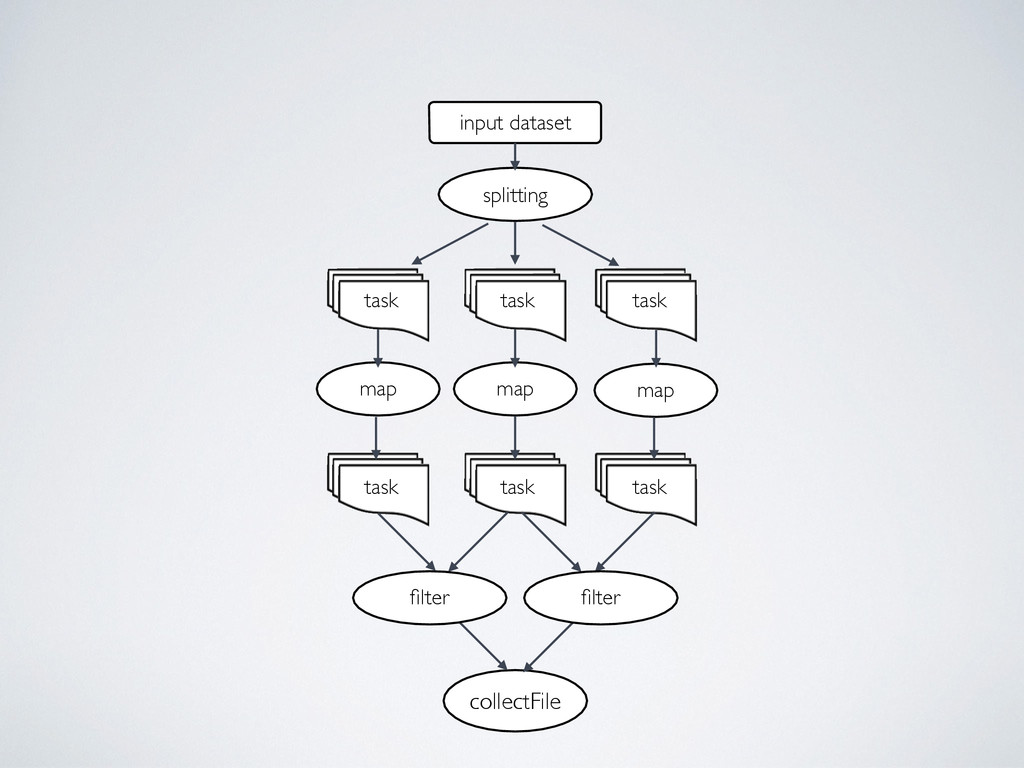
input dataset splitting collectFile map map map filter filter task
task task task task task -
GET STARTED Prerequisites: Java 7 or 8 Install by using
the following command wget -‐qO-‐ get.nextflow.io | bash nextflow -
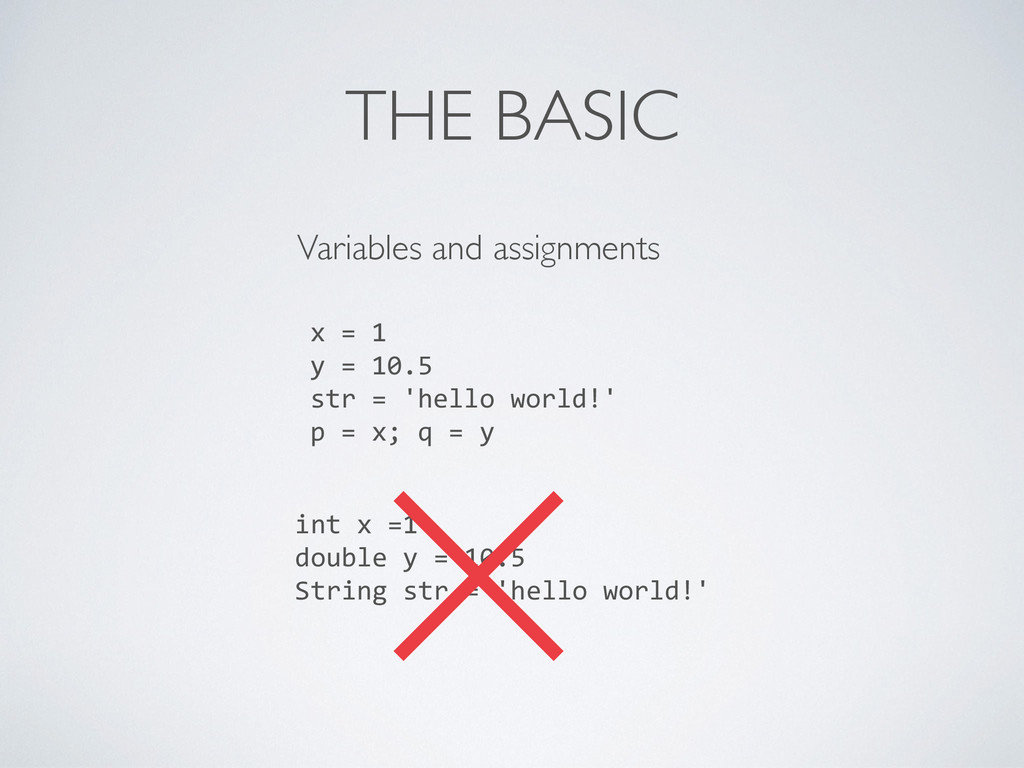
THE BASIC Variables and assignments x = 1 y
= 10.5 str = 'hello world!' p = x; q = y int x =1 double y = 10.5 String str = 'hello world!' -
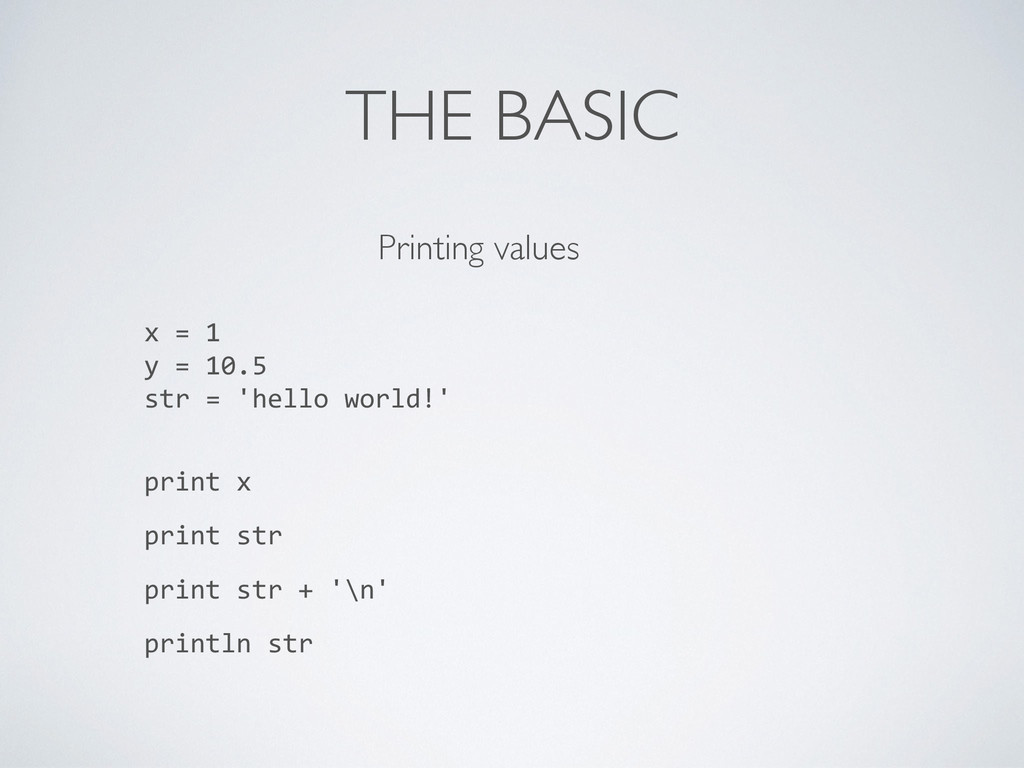
THE BASIC Printing values x = 1 y =
10.5 str = 'hello world!' print x print str print str + '\n' println str -
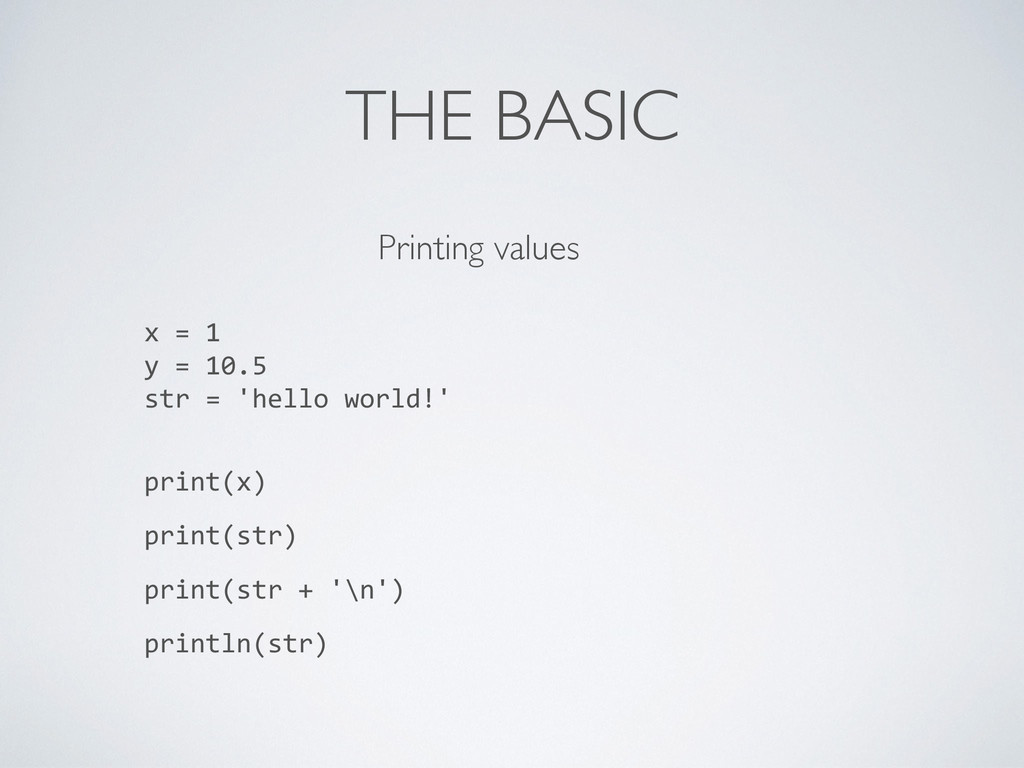
THE BASIC Printing values x = 1 y =
10.5 str = 'hello world!' print(x) print(str) print(str + '\n') println(str) -
MORE ON STRINGS str = 'bioinformatics' print str[0]
! print "$str is cool!" print "Current path: $PWD" str = ''' multi line string ''' ! str = """ User: $USER Home: $HOME """ -
LISTS simpleList = [1,2,5] strList = ['a','z'] emptyList
= [] ! simpleList.add(anyValue) simpleList << anyValue ! print simpleList[0] print simpleList[1] print simpleList[0..3] ! print simpleList.size() -
MAPS map = [:] ! map = [ k1:
10, k2: 20, k3: 'str' ] ! print map.k1 print map['k1'] print map.get('k1') ! map.k1 = 'Hello' map['k1'] = 'Hello' map.put('k1', 'Hello') ! print map.size() -
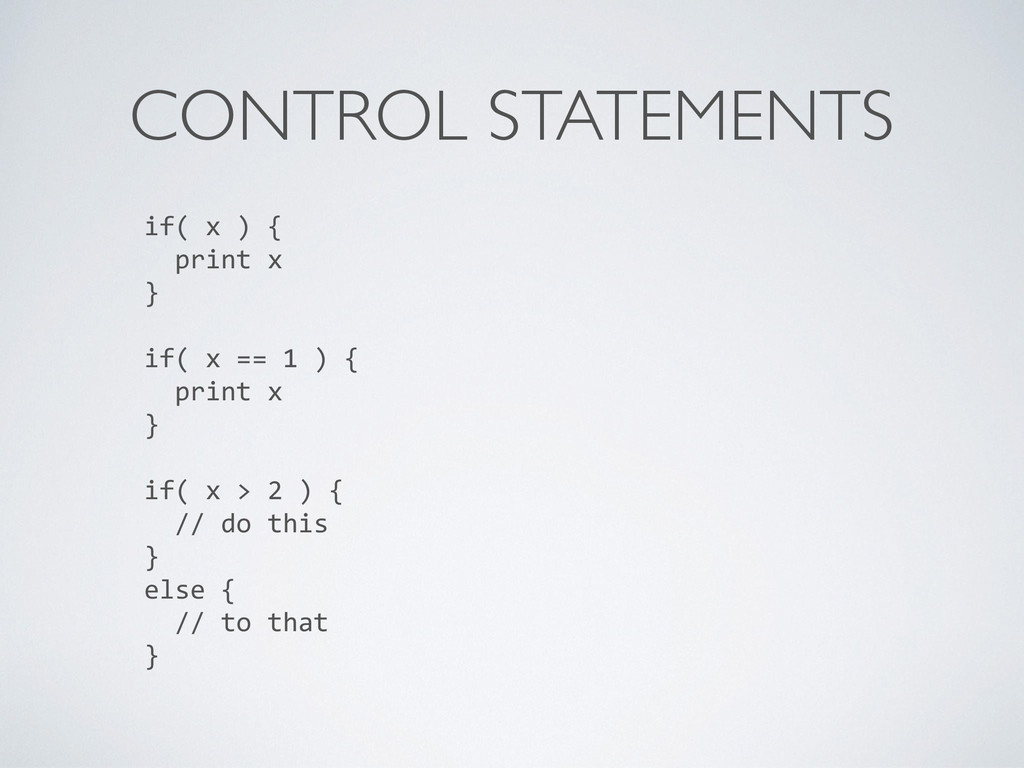
CONTROL STATEMENTS if( x ) { print x
} if( x == 1 ) { print x } ! if( x > 2 ) { // do this } else { // to that } -
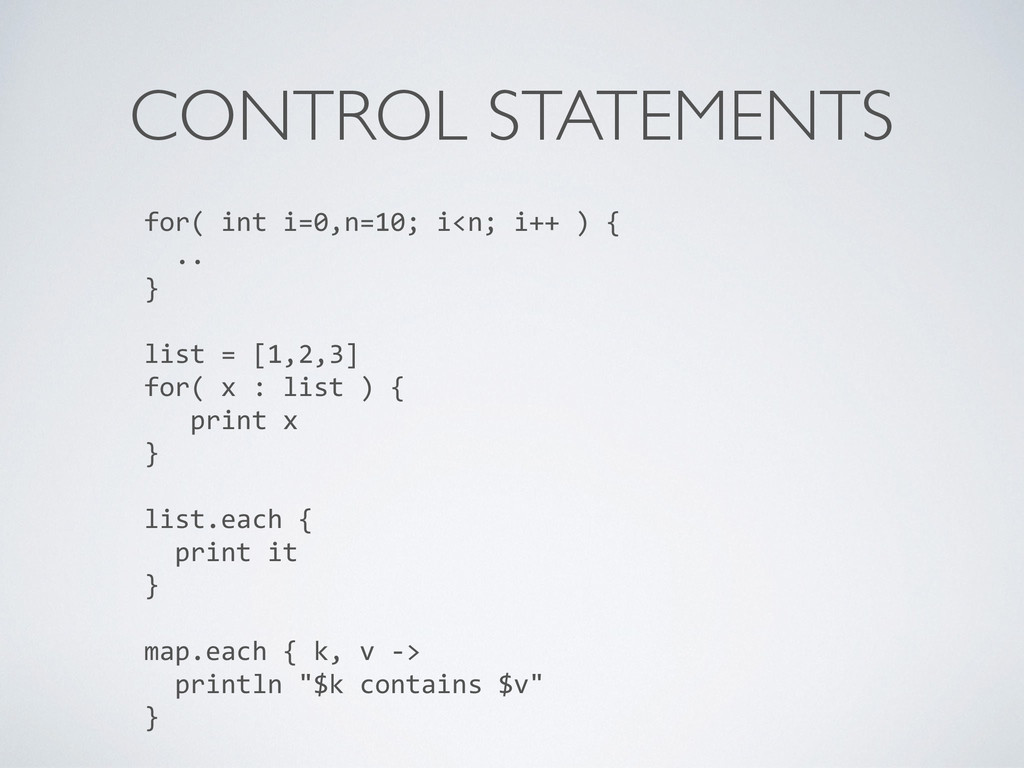
CONTROL STATEMENTS for( int i=0,n=10; i<n; i++ ) {
.. } ! list = [1,2,3] for( x : list ) { print x } ! list.each { print it } ! map.each { k, v -‐> println "$k contains $v" } -
FUNCTIONS def foo() { print 'Hello' }
! foo() ! def bar( x, y ) { x+y } ! print bar(1,2) -
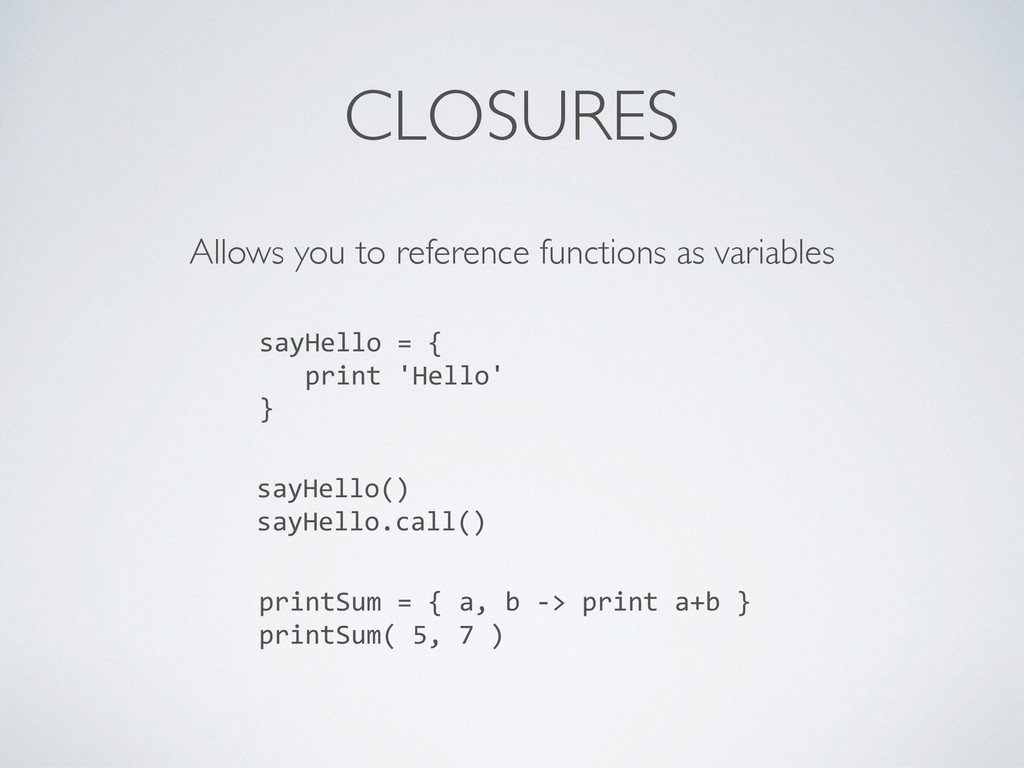
CLOSURES Allows you to reference functions as variables sayHello =
{ print 'Hello' } sayHello() sayHello.call() printSum = { a, b -‐> print a+b } printSum( 5, 7 ) -
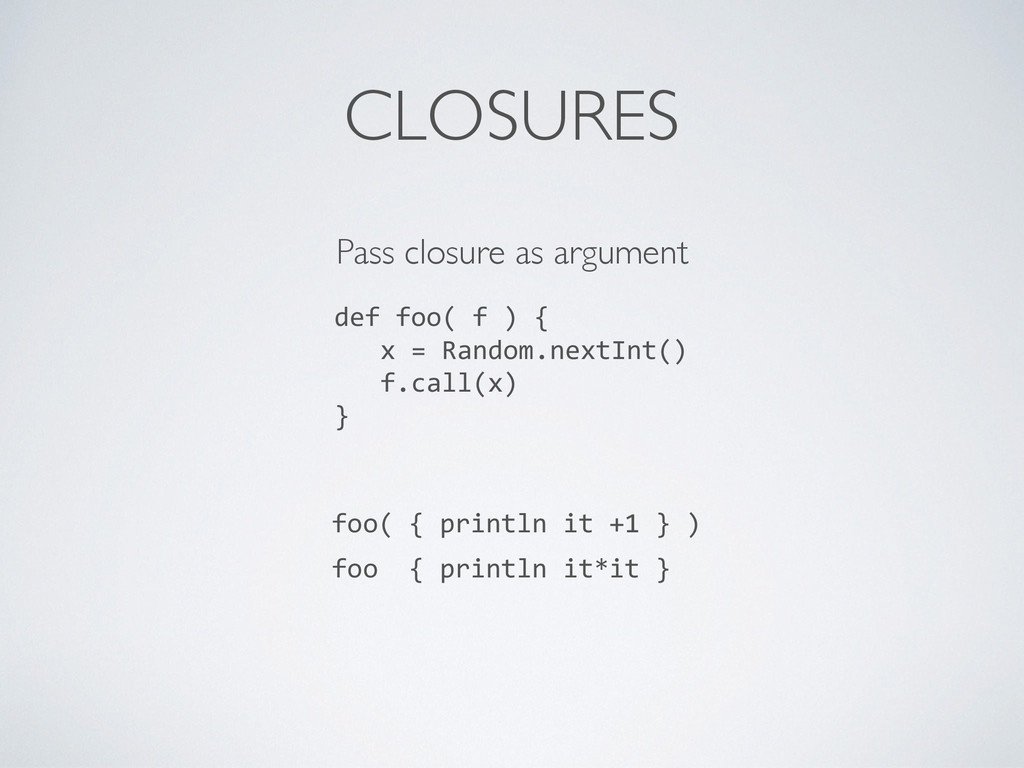
CLOSURES Pass closure as argument def foo( f ) {
x = Random.nextInt() f.call(x) } foo( { println it +1 } ) foo { println it*it } -
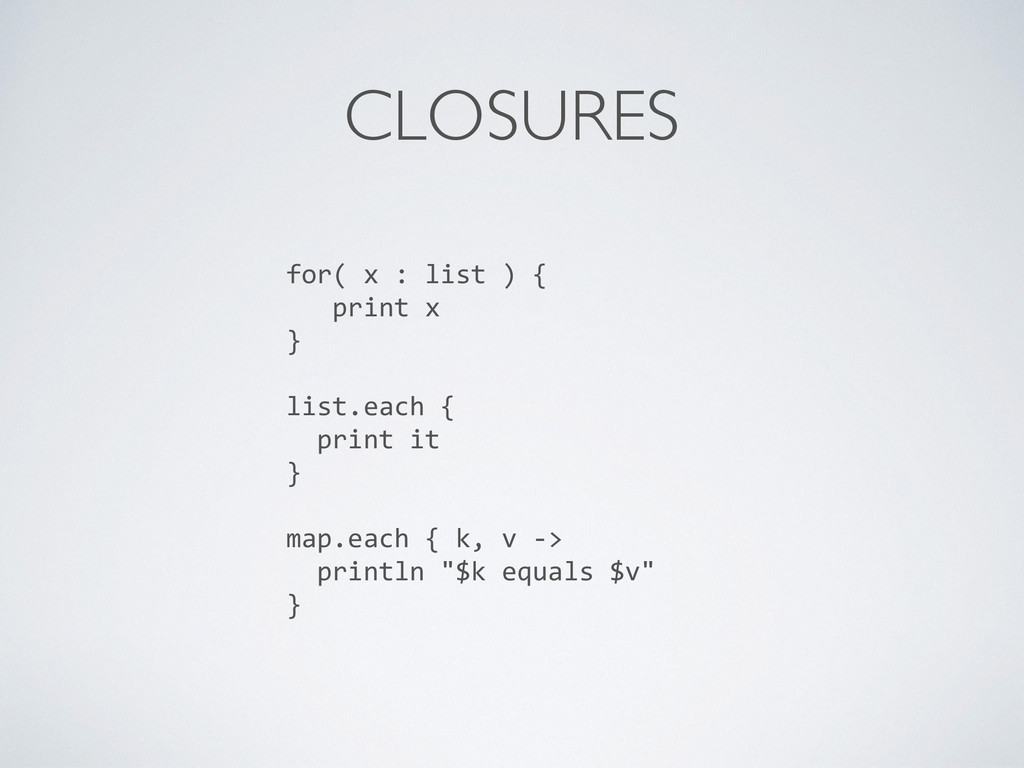
CLOSURES for( x : list ) {
print x } ! list.each { print it } ! map.each { k, v -‐> println "$k equals $v" } -
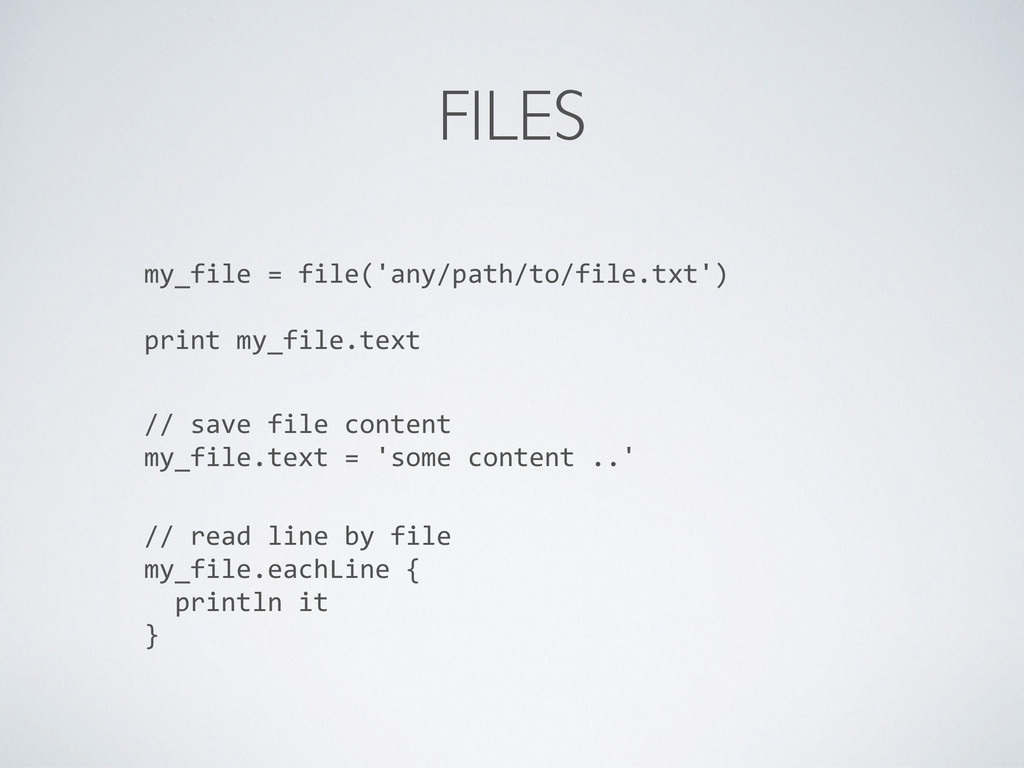
FILES my_file = file('any/path/to/file.txt') ! print my_file.text //
save file content my_file.text = 'some content ..' // read line by file my_file.eachLine { println it } -
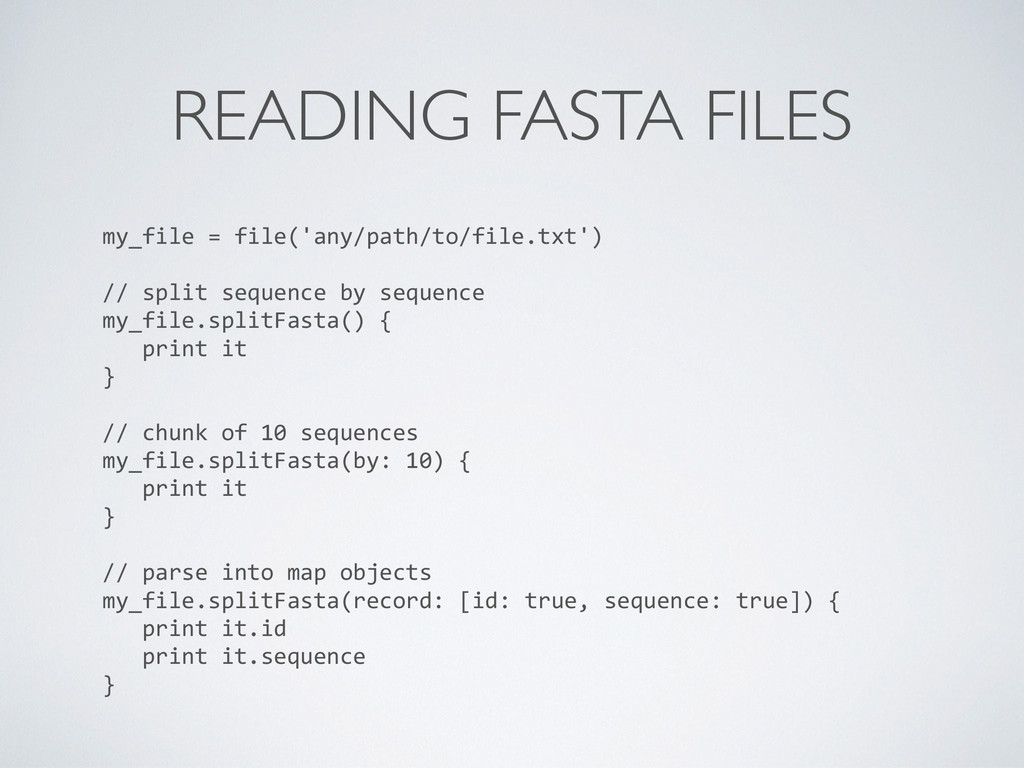
READING FASTA FILES my_file = file('any/path/to/file.txt') ! // split
sequence by sequence my_file.splitFasta() { print it } ! // chunk of 10 sequences my_file.splitFasta(by: 10) { print it } ! // parse into map objects my_file.splitFasta(record: [id: true, sequence: true]) { print it.id print it.sequence } -
EXAMPLE 1 • Print the content of a file •
Read FASTA file and print sequences • Read a FASTA file and print only the IDs -
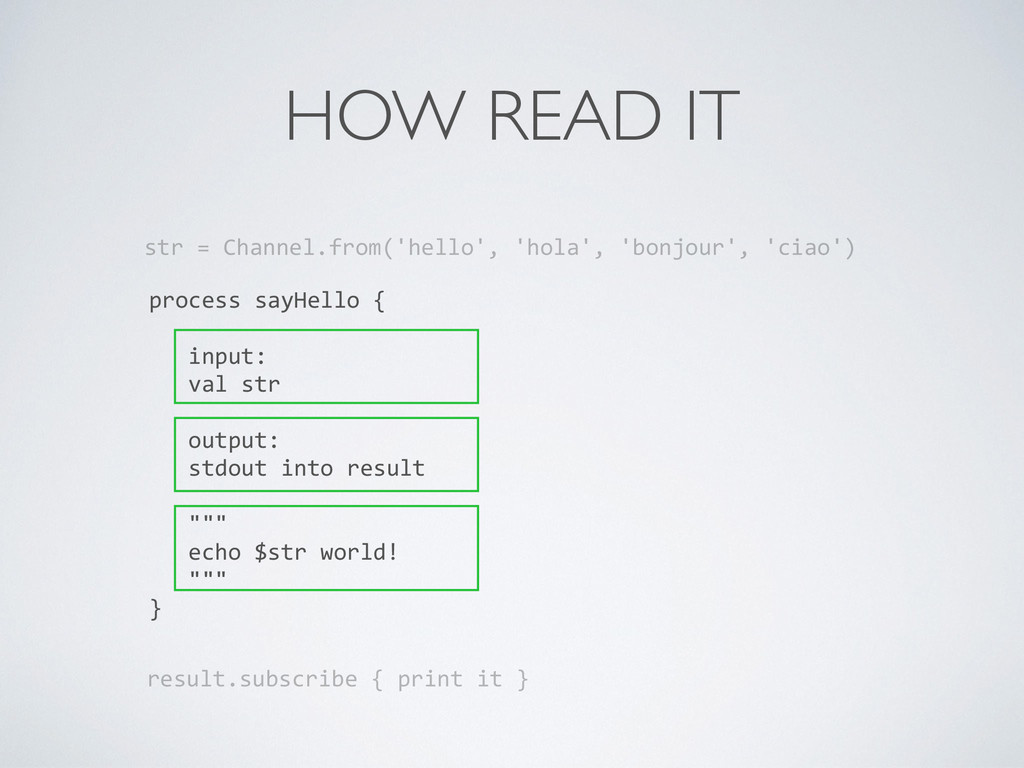
HOW READ IT process sayHello { !
input: val str ! output: stdout into result ! """ echo $str world! """ } ! str = Channel.from('hello', 'hola', 'bonjour', 'ciao') result.subscribe { print it } -
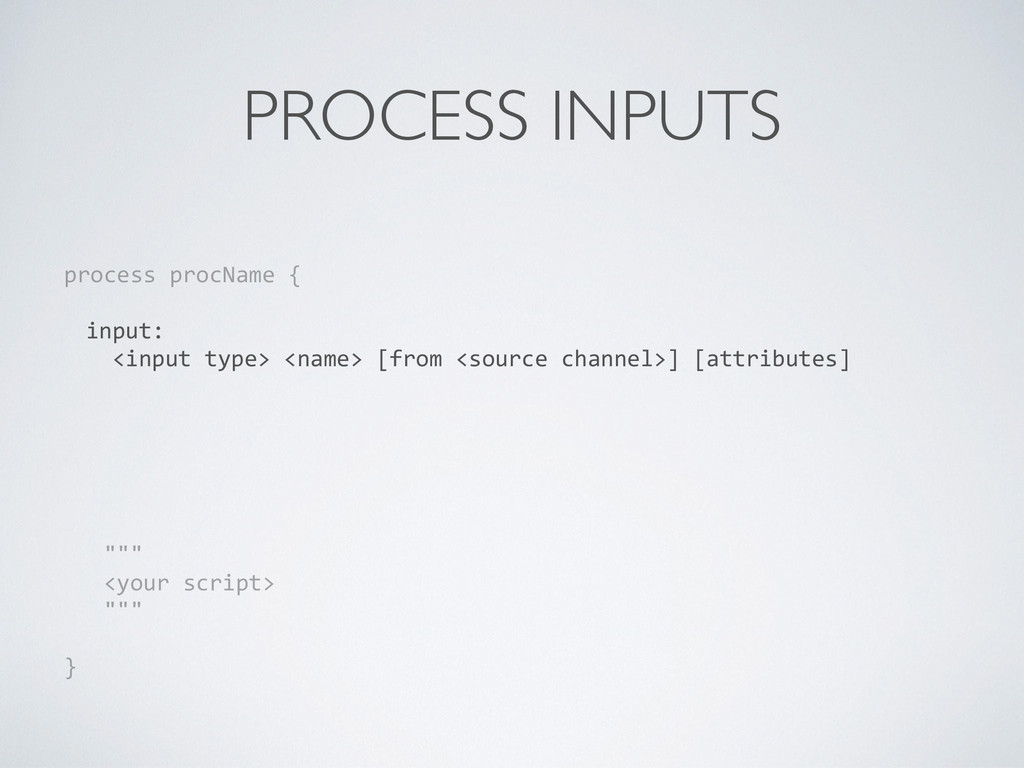
PROCESS INPUTS input: <input type> <name> [from <source
channel>] [attributes] process procName { ! ! ! ! ! ! ! ! ! """ <your script> """ ! } -
PROCESS INPUTS input: val x from ch_1
file y from ch_2 file 'data.fa' from ch_3 stdin from from ch_4 set (x, 'file.txt') from ch_5 process procName { ! ! ! ! ! ! ! ! ! """ <your script> """ ! } -
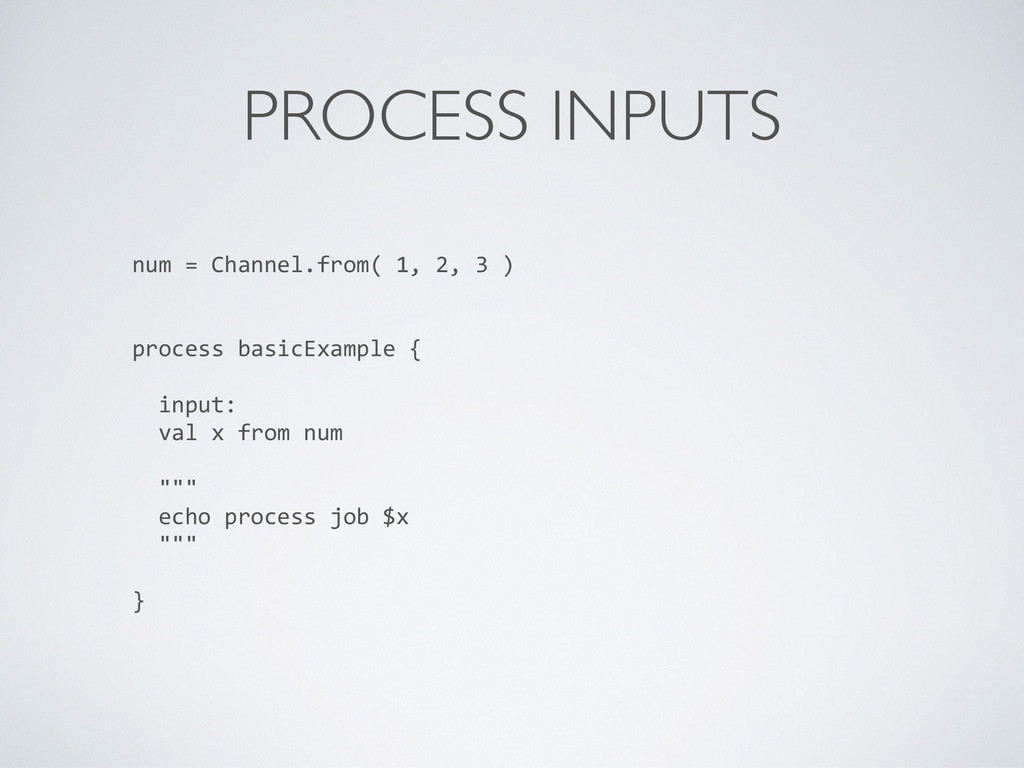
PROCESS INPUTS num = Channel.from( 1, 2, 3 )
! ! process basicExample { input: val x from num ! """ echo process job $x """ ! } -
PROCESS INPUTS proteins = Channel.fromPath( '/some/path/data.fa' ) ! !
! process blastThemAll { ! input: file 'query.fa' from proteins ! "blastp -‐query query.fa -‐db nr" ! } ! -
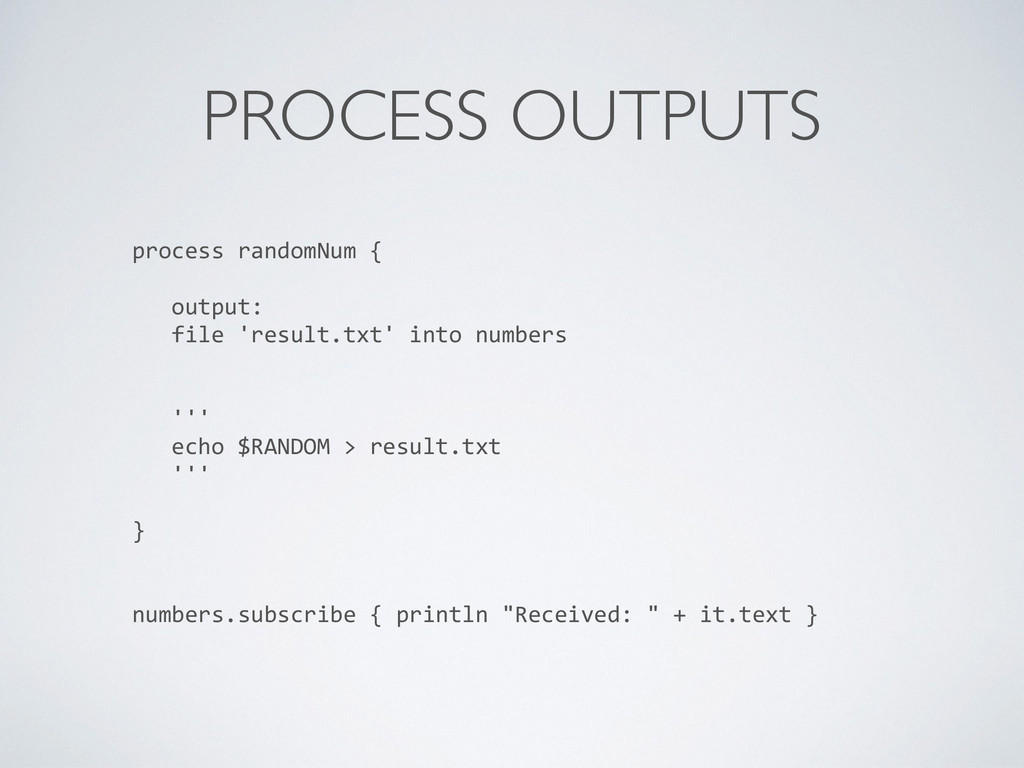
PROCESS OUTPUTS process randomNum { ! output:
file 'result.txt' into numbers ! ! ''' echo $RANDOM > result.txt ''' ! } ! ! numbers.subscribe { println "Received: " + it.text } -
EXAMPLE 2 • Execute a process running a BLAST job
given an input file • Execute a BLAST job emitting the produced output -
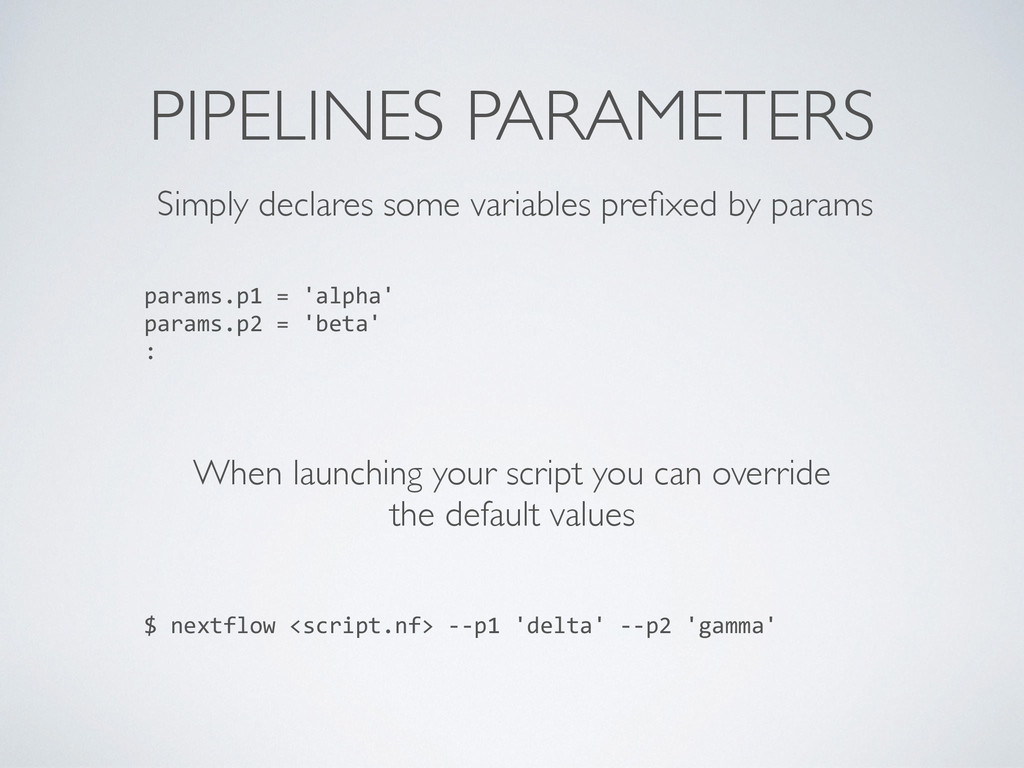
PIPELINES PARAMETERS params.p1 = 'alpha' params.p2 = 'beta'
: Simply declares some variables prefixed by params When launching your script you can override the default values $ nextflow <script.nf> -‐-‐p1 'delta' -‐-‐p2 'gamma' -
SPLITTING CONTENT You can split text object or files using
the splitting methods: • splitText - line by line • splitCsv - comma separated values format • splitFasta - by FASTA sequences • splitFastq - by FASTQ sequences -
SPLITTING CONTENT params.query = "$HOME/sample.fa" params.chunkSize = 5
! fasta = file(params.query) seq = Channel.from(fasta).splitFasta(by: params.chunkSize) ! process blast { input: file 'seq.fa' from seq ! output: file 'out' into blast_result ! """ blastp -‐db $DB -‐query seq.fa -‐outfmt 6 > out """ } -
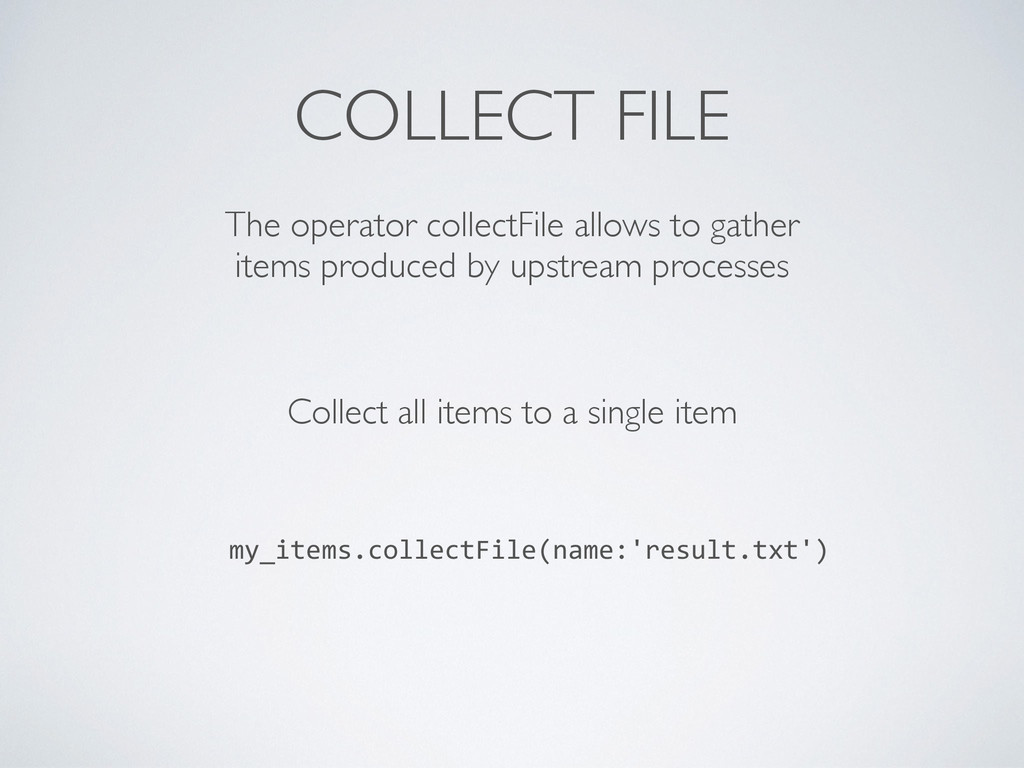
COLLECT FILE The operator collectFile allows to gather items produced
by upstream processes my_items.collectFile(name:'result.txt') Collect all items to a single item -
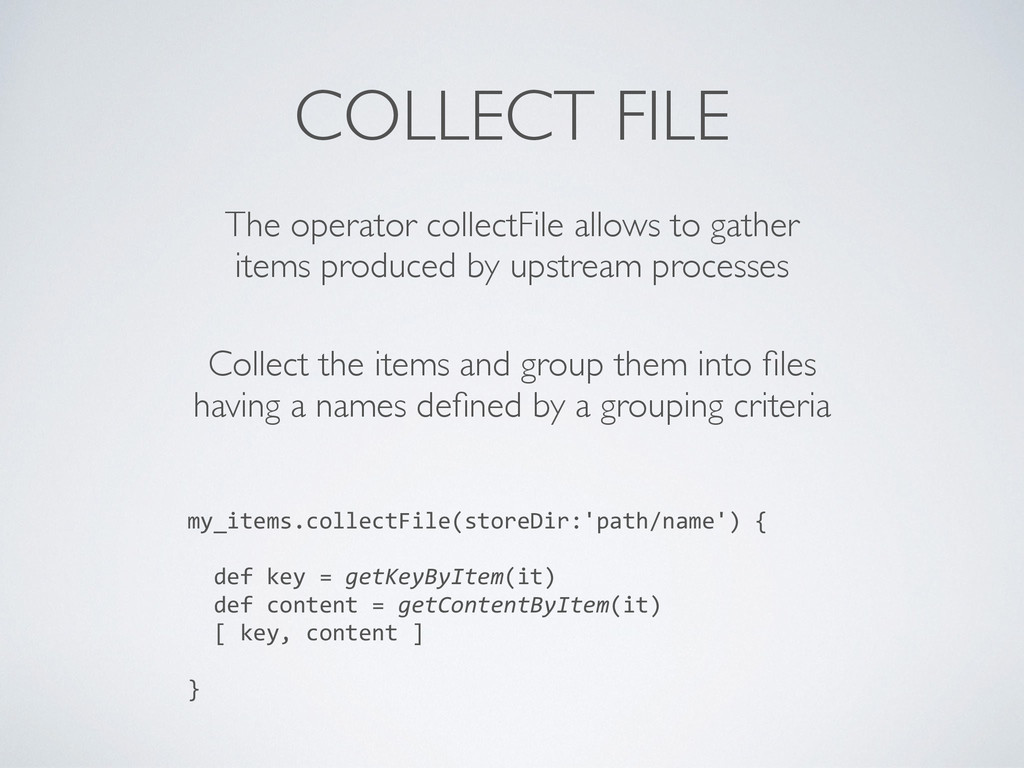
COLLECT FILE The operator collectFile allows to gather items produced
by upstream processes my_items.collectFile(storeDir:'path/name') { ! def key = getKeyByItem(it) def content = getContentByItem(it) [ key, content ] ! } Collect the items and group them into files having a names defined by a grouping criteria -
EXAMPLE 3 Split a FASTA file, execute a BLAST query
for each chunk and gather the results -
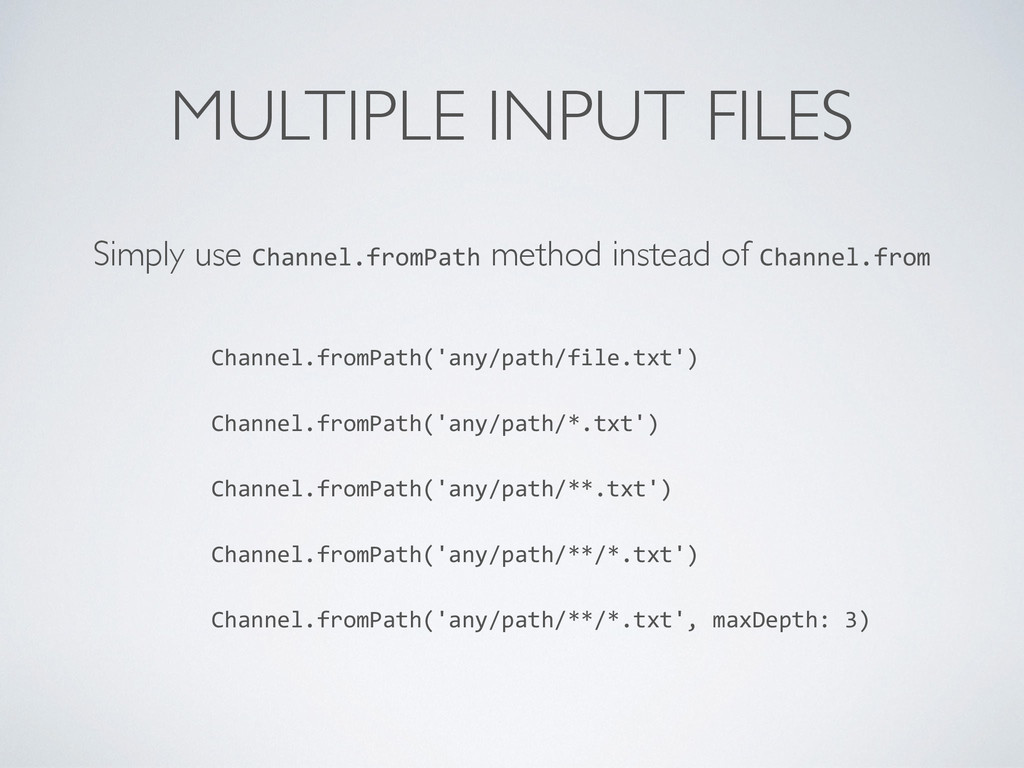
MULTIPLE INPUT FILES Simply use Channel.fromPath method instead of Channel.from
Channel.fromPath('any/path/file.txt') Channel.fromPath('any/path/*.txt') Channel.fromPath('any/path/**.txt') Channel.fromPath('any/path/**/*.txt') Channel.fromPath('any/path/**/*.txt', maxDepth: 3) -
EXAMPLE 4 Split many FASTA files and execute BLAST query
for each of them -
CONFIG FILE Allows you to save into a file commons
options and environment settings. By default it uses nextflow.config in current path params.p1 = 'alpha' params.p2 = 'beta' ! env.VAR_1 = 'some_value' env.CACHE_4_TCOFFEE = '/some/path/cache' env.LOCKDIR_4_TCOFFEE = '/some/path/lock' ! process.executor = 'sge' -
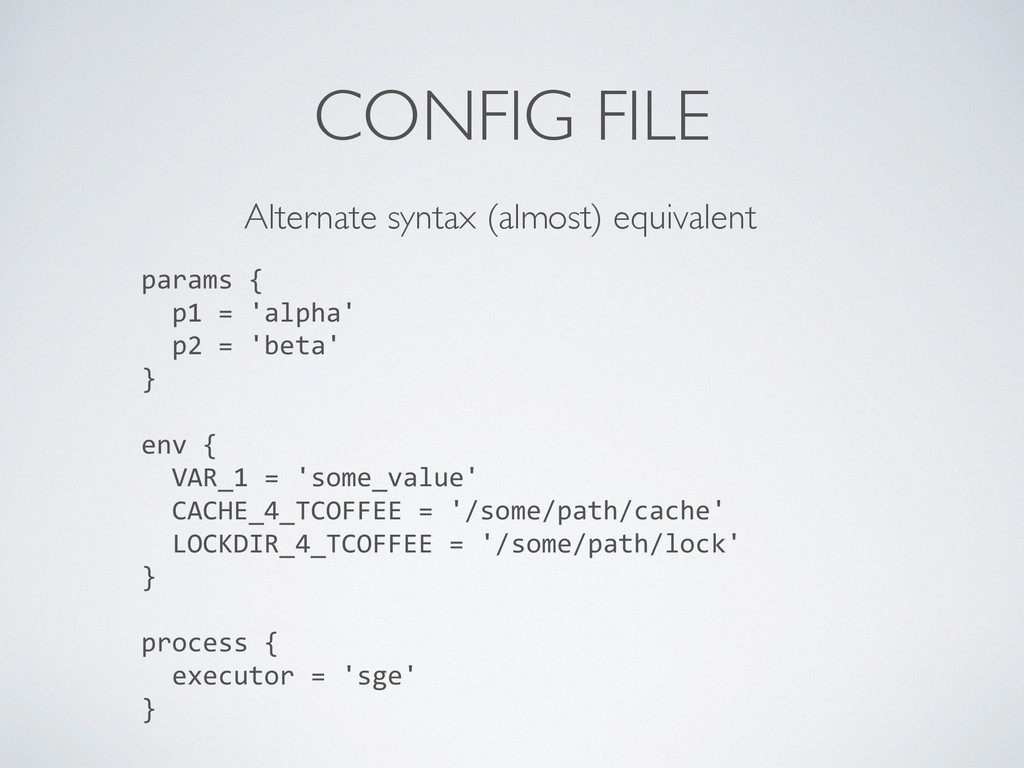
CONFIG FILE params { p1 = 'alpha'
p2 = 'beta' } ! env { VAR_1 = 'some_value' CACHE_4_TCOFFEE = '/some/path/cache' LOCKDIR_4_TCOFFEE = '/some/path/lock' } ! process { executor = 'sge' } Alternate syntax (almost) equivalent -
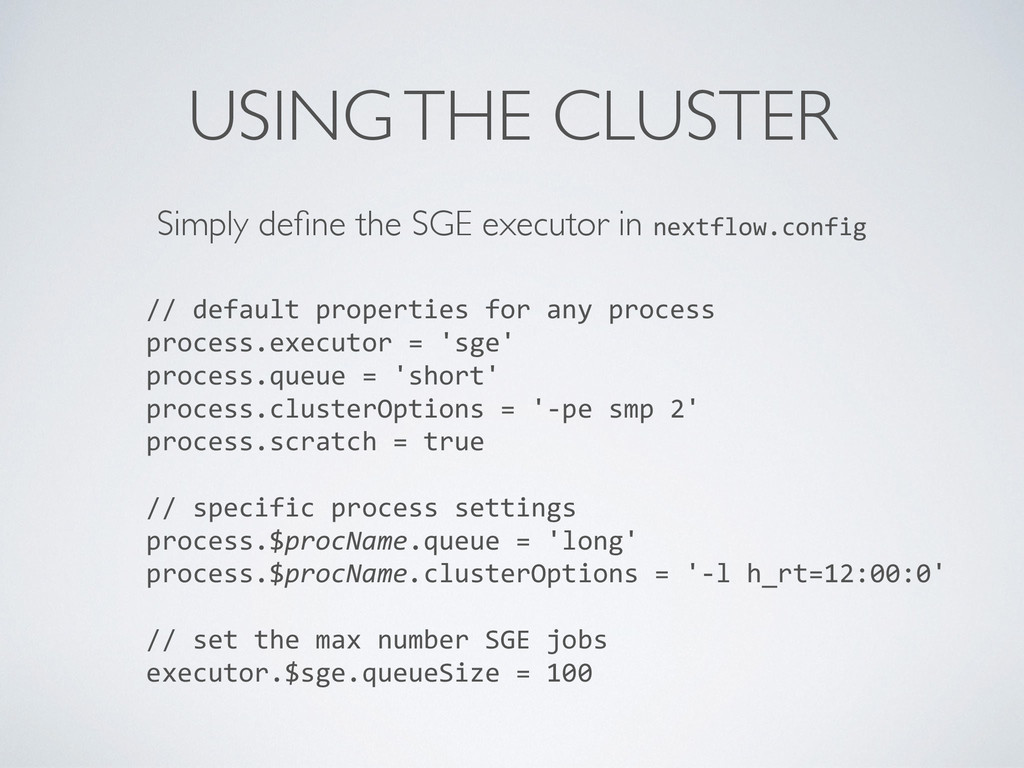
USING THE CLUSTER // default properties for any process
process.executor = 'sge' process.queue = 'short' process.clusterOptions = '-‐pe smp 2' process.scratch = true ! // specific process settings process.$procName.queue = 'long' process.$procName.clusterOptions = '-‐l h_rt=12:00:0' ! // set the max number SGE jobs executor.$sge.queueSize = 100 Simply define the SGE executor in nextflow.config -
MORE ON OPERATORS Operators are commonly used to transforms channels
content Channel .from( 1, 2, 3, 4, 5 ) .map { it * it } 1 4 9 16 25 // it prints -
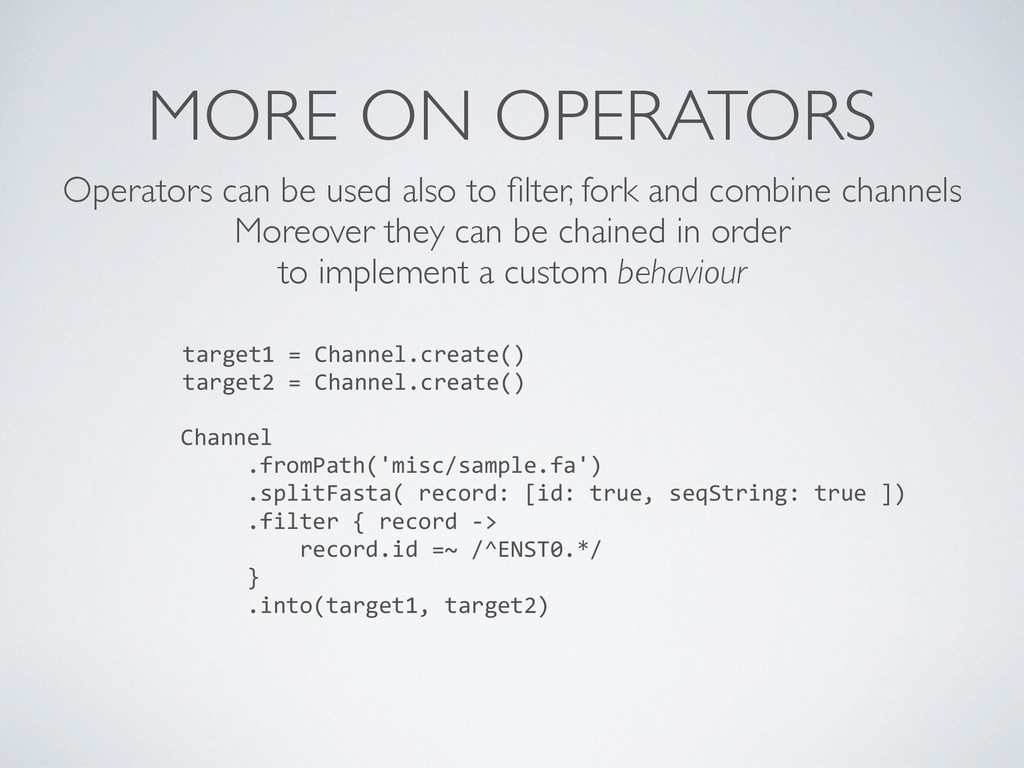
MORE ON OPERATORS target1 = Channel.create() target2 = Channel.create()
Operators can be used also to filter, fork and combine channels Moreover they can be chained in order to implement a custom behaviour Channel .fromPath('misc/sample.fa') .splitFasta( record: [id: true, seqString: true ]) .filter { record -‐> record.id =~ /^ENST0.*/ } .into(target1, target2) -
EXAMPLE 5 A toy RNAseq pipeline that: • Index a
reference genome • Maps a collection of read-pairs • Assemble a transcript for each read pair This example will run using a Docker container -
DOCKER • Enable to run processes in a isolated environment
• You can package and distribute a self-contained executable environment • Up today it runs only on Linux (partially OSX), Docker plans to support Windows as well.