Share
Embed
Transcript
58 slides
-
Spark and Shark: High-speed In-memory Analytics over Hadoop Data May
14, 2013 @ Oracle Reynold Xin, AMPLab, UC Berkeley -
The Big Data Problem Data is growing faster than computation
speeds Accelerating data sources » Web, mobile, scientific, … Cheap storage Stalling clock rates -
Result Processing has to scale out over large clusters Users
are adopting a new class of systems » Hadoop MapReduce now used at banks, retailers, … » $1B market by 2016 -
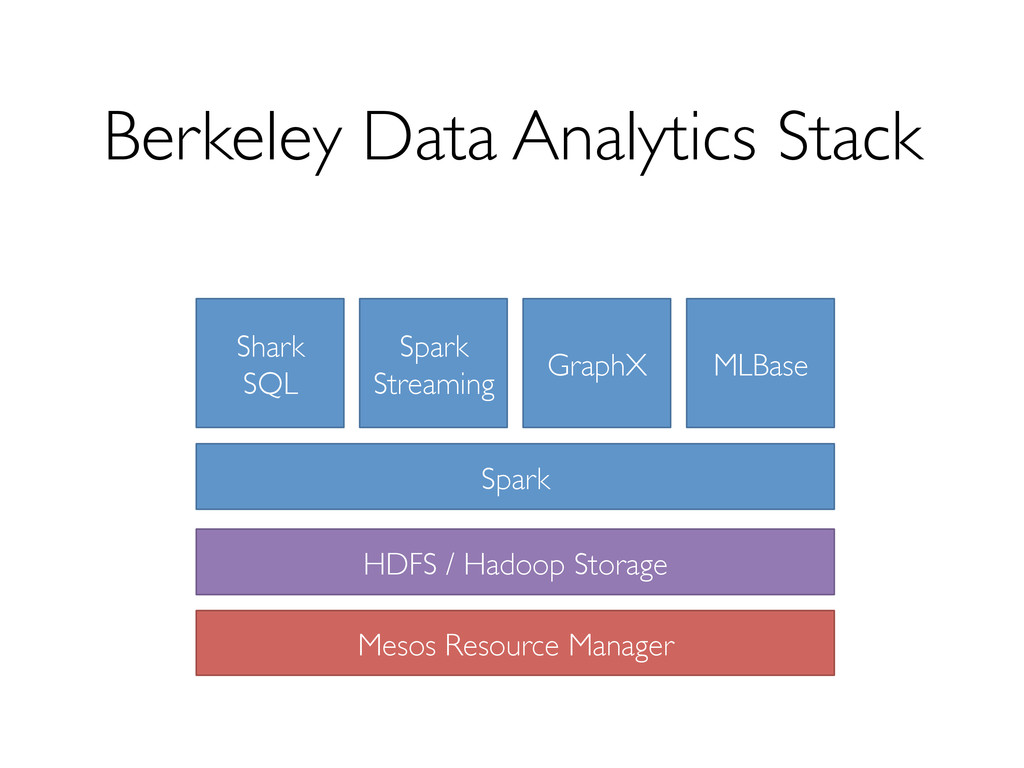
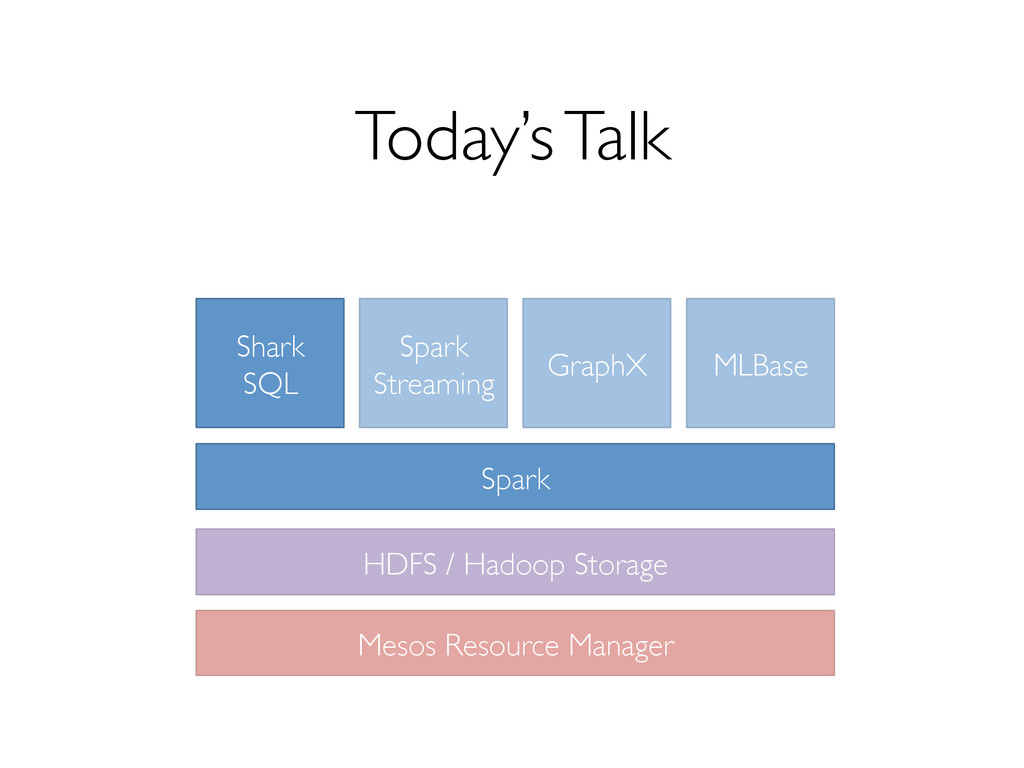
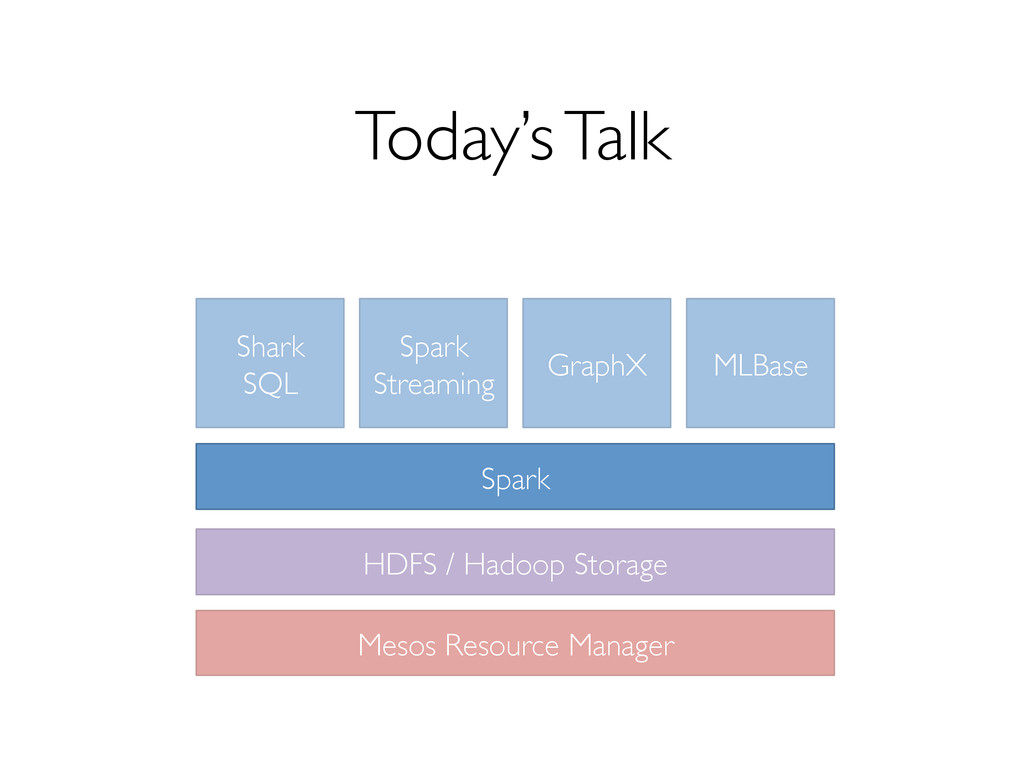
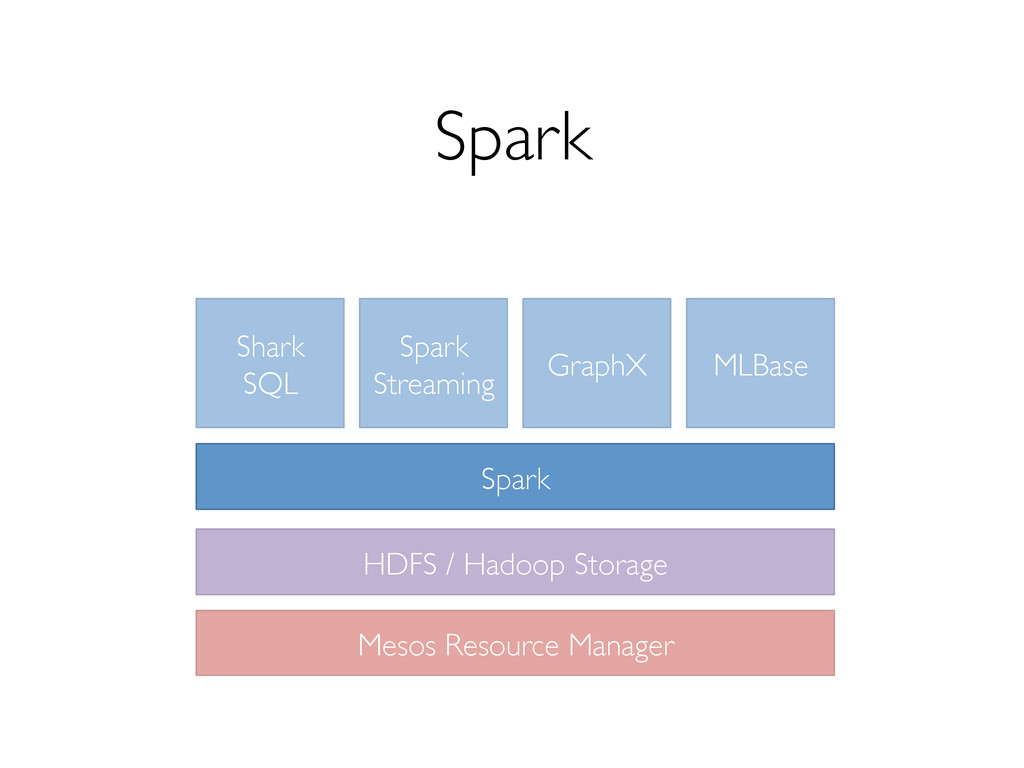
Berkeley Data Analytics Stack Spark Shark SQL HDFS / Hadoop
Storage Mesos Resource Manager Spark Streaming GraphX MLBase -
Today’s Talk Spark Shark SQL HDFS / Hadoop Storage Mesos
Resource Manager Spark Streaming GraphX MLBase -
Spark Separate, fast, MapReduce-like engine » In-memory storage for fast iterative
computations » General execution graphs » Up to 100X faster than Hadoop MapReduce Compatible with Hadoop storage APIs » Read/write to any Hadoop-supported systems, including HDFS, Hbase, SequenceFiles, etc -
Shark An analytics engine built on top of Spark » Support
both SQL and complex analytics » Up to 100X faster than Apache Hive Compatible with Hive data, metastore, queries » HiveQL » UDF / UDAF » SerDes » Scripts -
Community 3000 people attended online training 800 meetup members 14
companies contributing spark-‐project.org -
Today’s Talk Spark Shark SQL HDFS / Hadoop Storage Mesos
Resource Manager Spark Streaming GraphX MLBase -
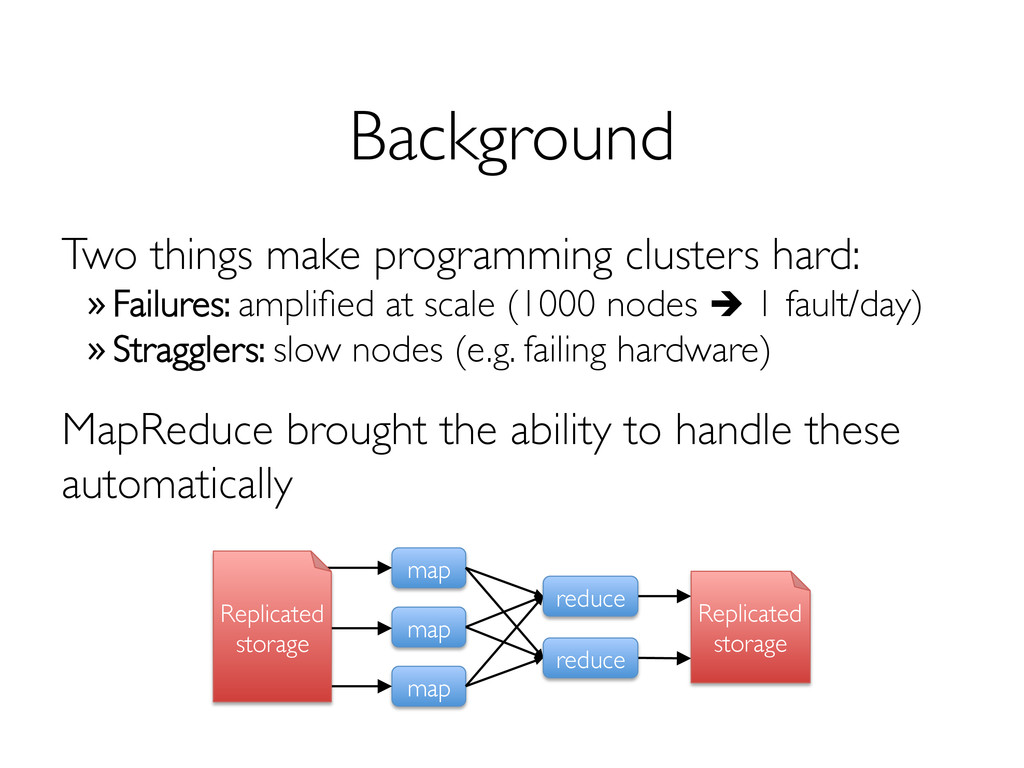
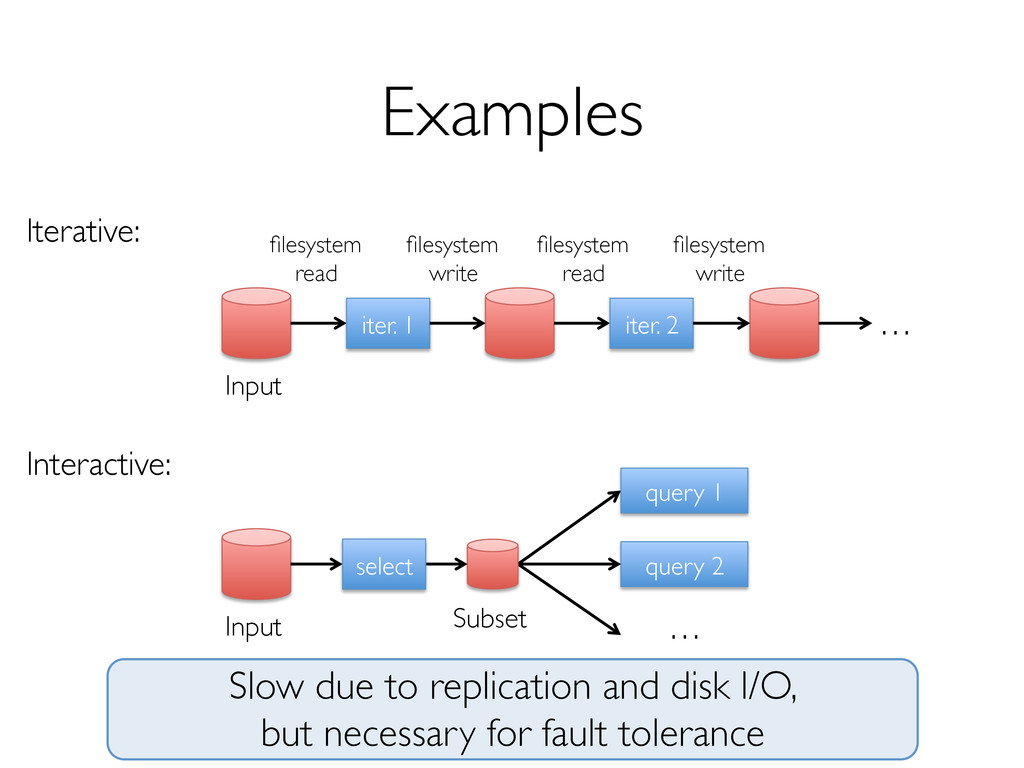
Background Two things make programming clusters hard: » Failures: amplified at
scale (1000 nodes è 1 fault/day) » Stragglers: slow nodes (e.g. failing hardware) MapReduce brought the ability to handle these automatically map map map reduce reduce Replicated -
Spark Motivation MapReduce simplified batch analytics, but users quickly needed
more: » More complex, multi-pass applications -
One Reaction Specialized models for some of these apps » Google
Pregel for graph processing » Iterative MapReduce » Storm for streaming Problem: » Don’t cover all use cases » How to compose in a single application? -
Observation Complex, streaming and interactive apps all need one thing
that MapReduce lacks: Efficient primitives for data sharing -
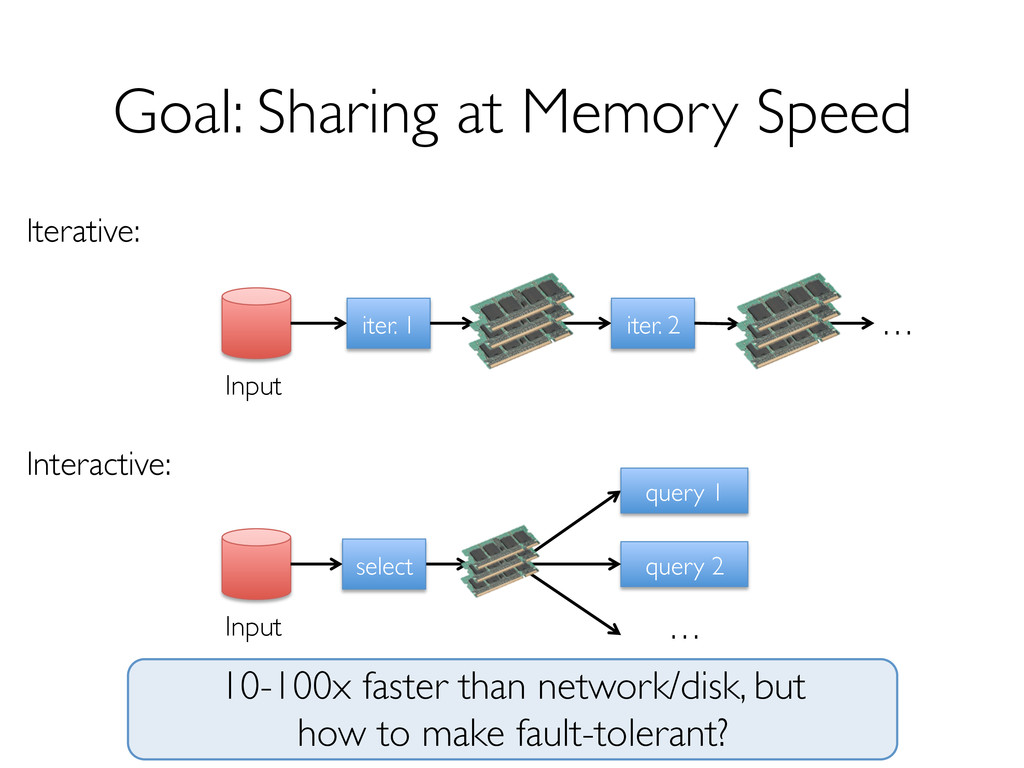
Goal: Sharing at Memory Speed iter. 1 iter. 2 …
Input Iterative: Interactive: Input query 1 query 2 select … 10-100x faster than network/disk, but -
Existing Storage Systems Based on a general “shared memory” model
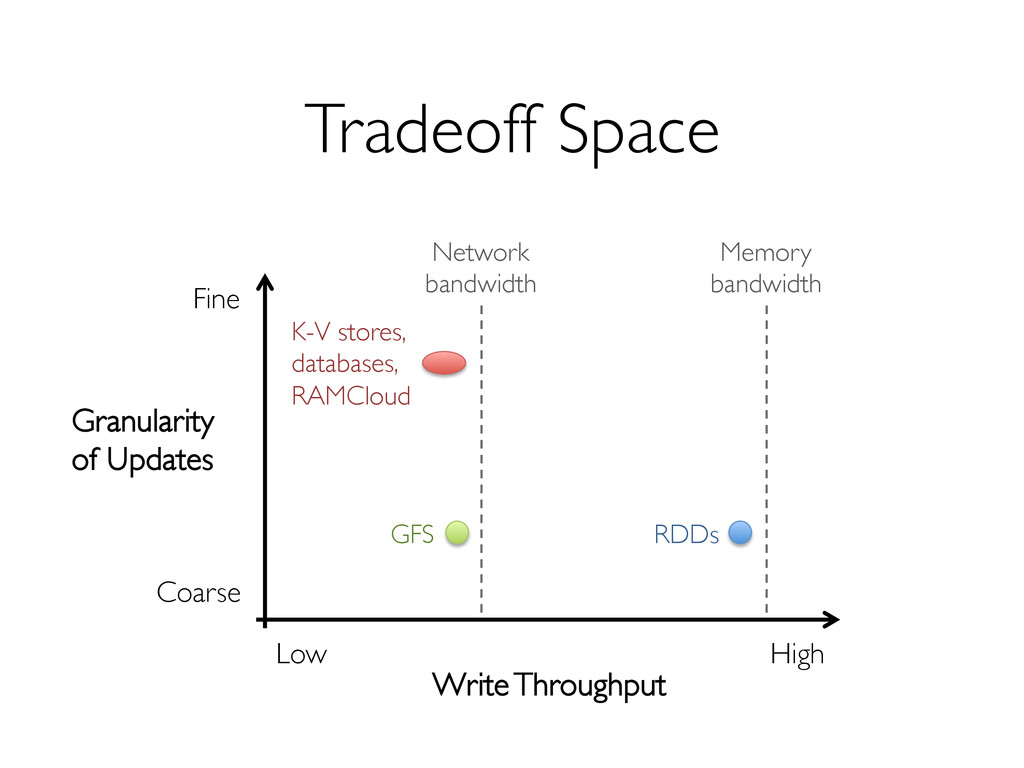
» Fine-grained updates to mutable state » E.g. databases, key-value stores, RAMCloud Requires replicating data across the network for fault tolerance » 10-100× slower than memory write! -
Restricted form of shared memory » Immutable, partitioned sets of records
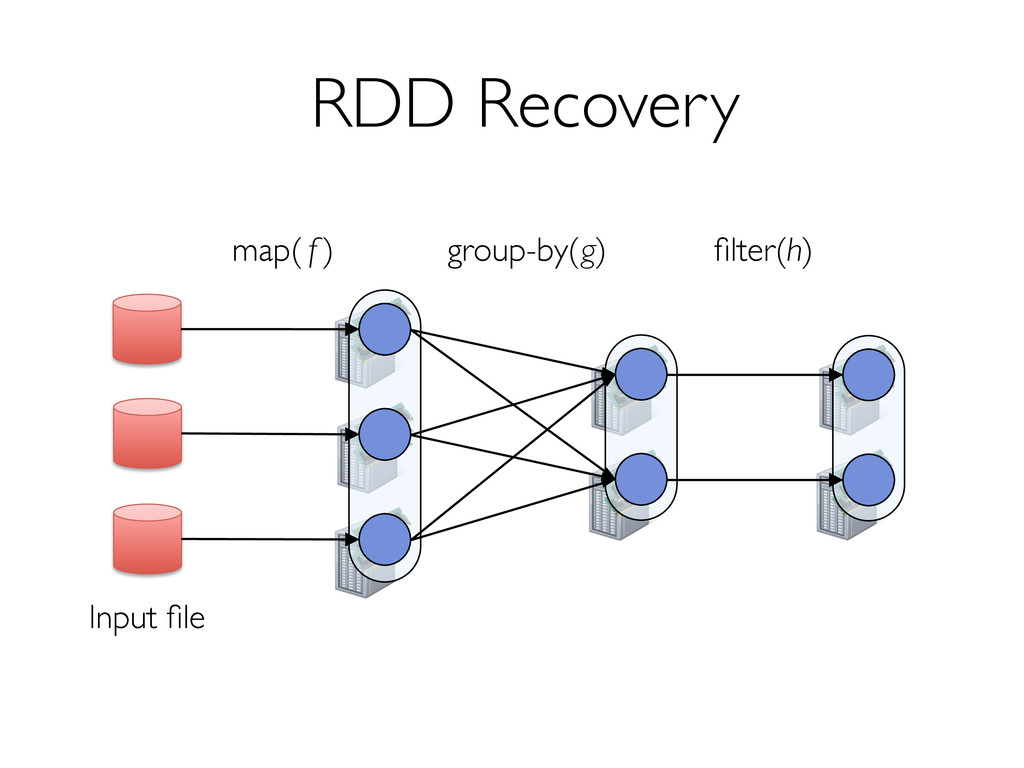
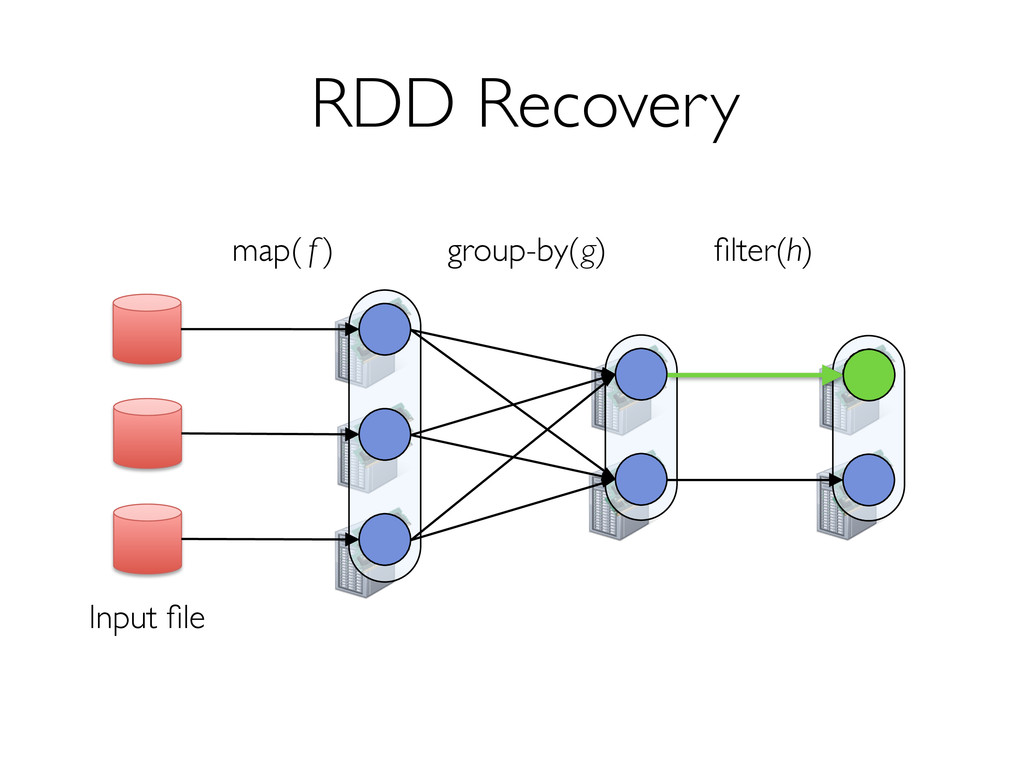
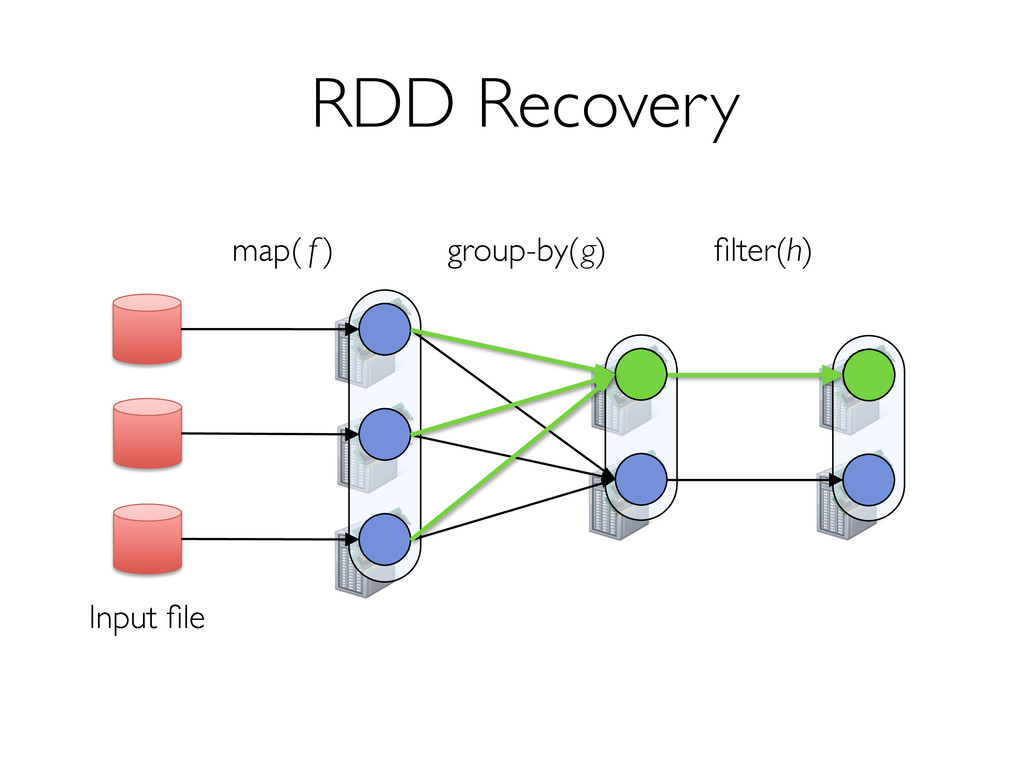
» Can only be built through coarse-grained, deterministic operations (map, filter, join, …) Enables fault recovery using lineage » Log one operation to apply to many elements » Recompute any lost partitions on failure Solution: Resilient Distributed Datasets (RDDs) [NSDI 2012] -
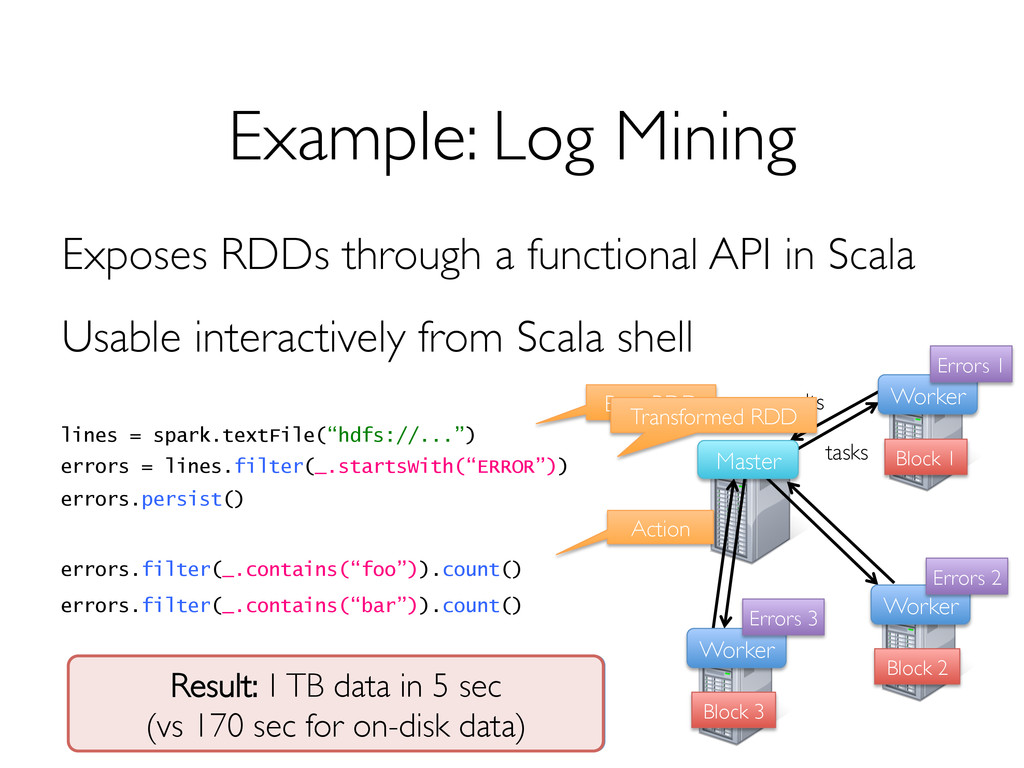
Example: Log Mining Exposes RDDs through a functional API in
Scala Usable interactively from Scala shell lines = spark.textFile(“hdfs://...”) errors = lines.filter(_.startsWith(“ERROR”)) errors.persist() Block 1 Block 2 Block 3 Worker errors.filter(_.contains(“foo”)).count() errors.filter(_.contains(“bar”)).count() tasks results Errors 2 Base RDD Transformed RDD Action Result: full-text search of Wikipedia in <1 sec (vs 20 sec for on-disk data) Result: 1 TB data in 5 sec -
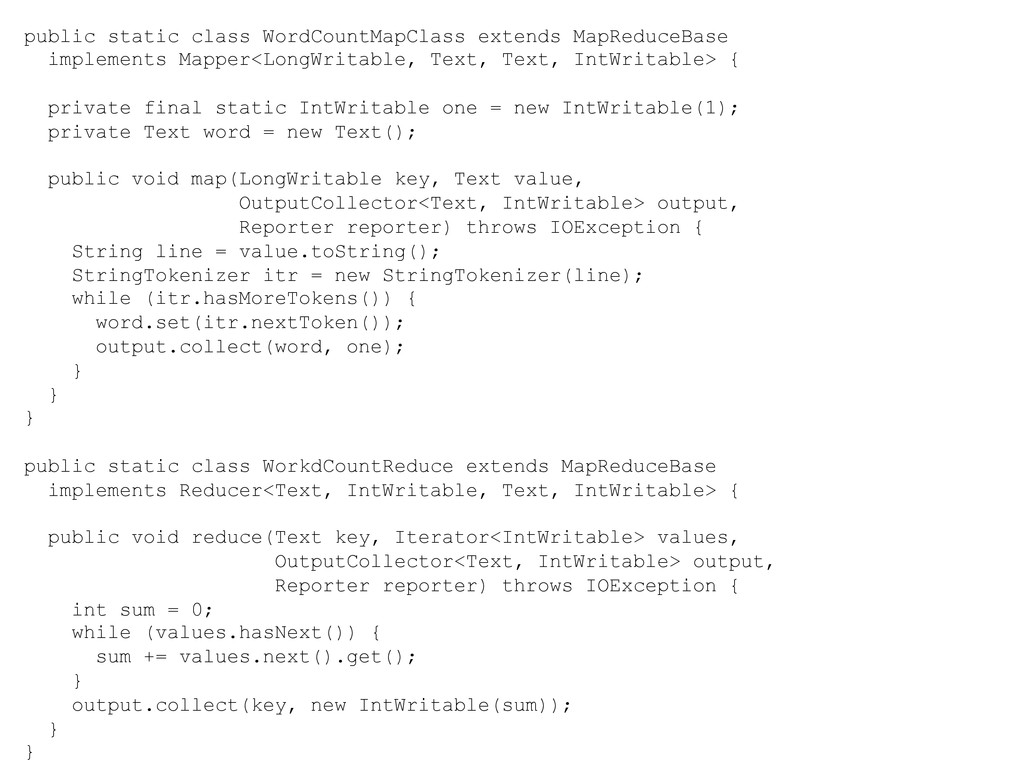
public static class WordCountMapClass extends MapReduceBase implements Mapper<LongWritable, Text, Text,
IntWritable> { private final static IntWritable one = new IntWritable(1); private Text word = new Text(); public void map(LongWritable key, Text value, OutputCollector<Text, IntWritable> output, Reporter reporter) throws IOException { String line = value.toString(); StringTokenizer itr = new StringTokenizer(line); while (itr.hasMoreTokens()) { word.set(itr.nextToken()); output.collect(word, one); } } } public static class WorkdCountReduce extends MapReduceBase implements Reducer<Text, IntWritable, Text, IntWritable> { public void reduce(Text key, Iterator<IntWritable> values, OutputCollector<Text, IntWritable> output, Reporter reporter) throws IOException { int sum = 0; while (values.hasNext()) { sum += values.next().get(); } output.collect(key, new IntWritable(sum)); } } -
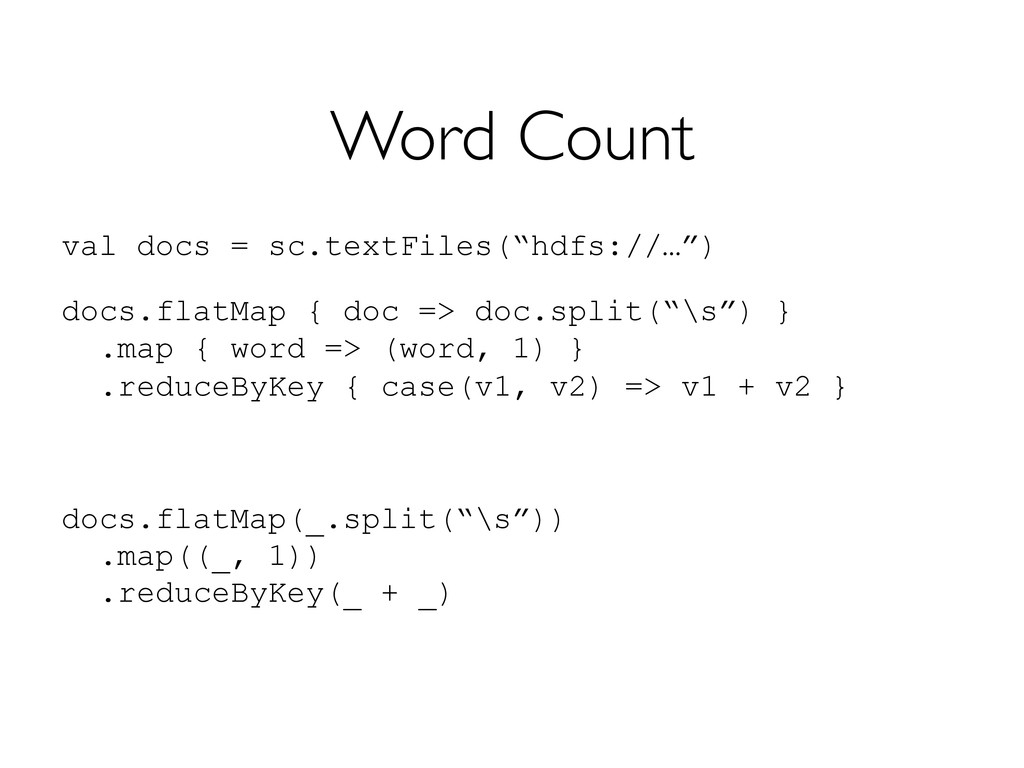
Word Count val docs = sc.textFiles(“hdfs://…”) docs.flatMap { doc =>
doc.split(“\s”) } .map { word => (word, 1) } .reduceByKey { case(v1, v2) => v1 + v2 } docs.flatMap(_.split(“\s”)) .map((_, 1)) .reduceByKey(_ + _) -
Generality of RDDs Despite their restrictions, RDDs can express surprisingly
many parallel algorithms » These naturally apply the same operation to many items Unify many current programming models » Data flow models: MapReduce, Dryad, SQL, … » Specialized models for iterative apps: Pregel, iterative MapReduce, GraphLab, … Support new apps that these models don’t -
Memory bandwidth Network bandwidth Tradeoff Space Granularity of Updates Write
Throughput Fine Coarse Low High K-V stores, databases, RAMCloud GFS RDDs -
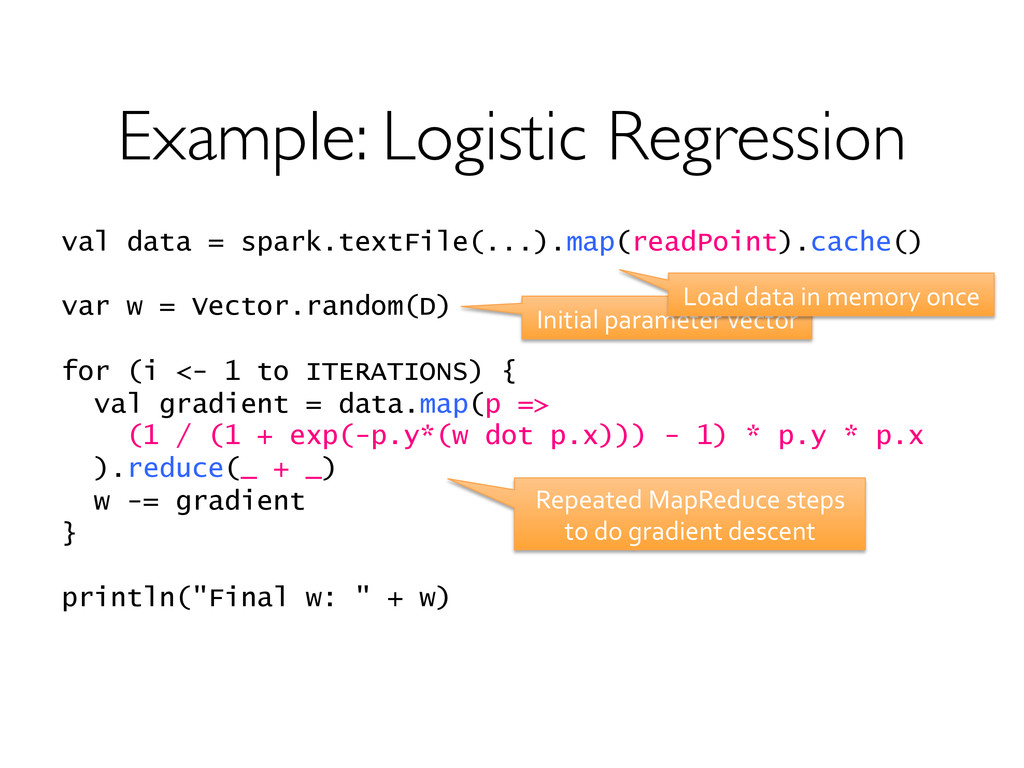
Example: Logistic Regression val data = spark.textFile(...).map(readPoint).cache() var w =
Vector.random(D) for (i <- 1 to ITERATIONS) { val gradient = data.map(p => (1 / (1 + exp(-p.y*(w dot p.x))) - 1) * p.y * p.x ).reduce(_ + _) w -= gradient } println("Final w: " + w) Initial parameter vector Repeated MapReduce steps to do gradient descent Load data in memory once -
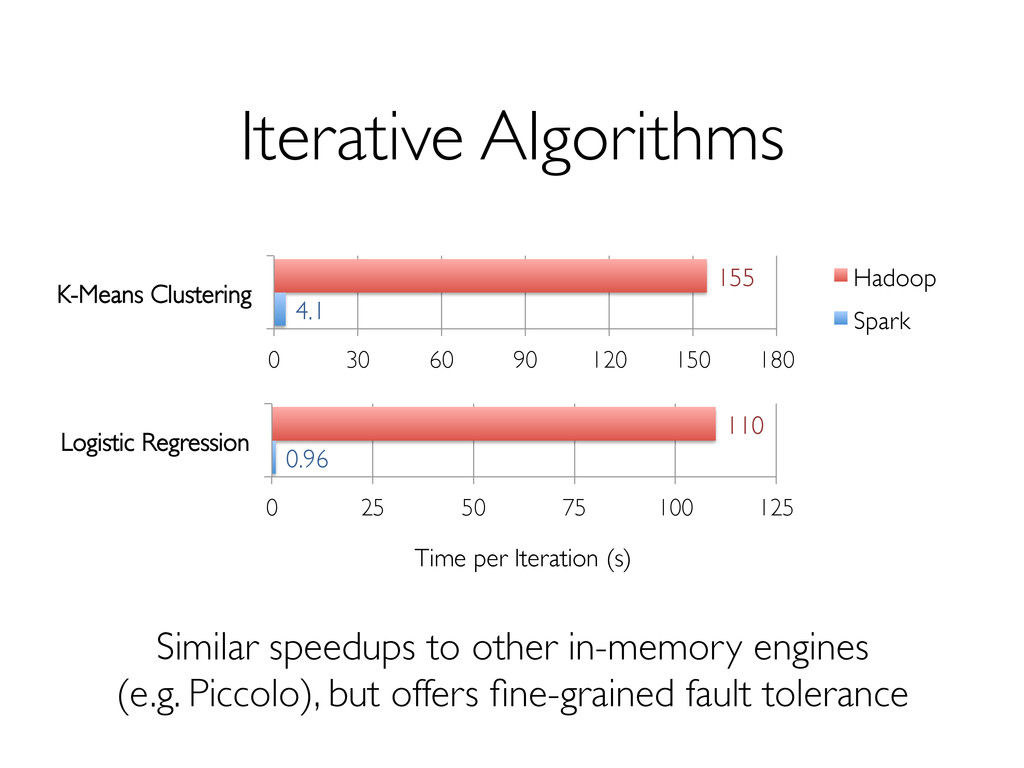
Iterative Algorithms 0.96 110 0 25 50 75 100 125
Logistic Regression 4.1 155 0 30 60 90 120 150 180 K-Means Clustering Hadoop Spark Time per Iteration (s) Similar speedups to other in-memory engines -
Spark Spark Shark SQL HDFS / Hadoop Storage Mesos Resource
Manager Spark Streaming GraphX MLBase -
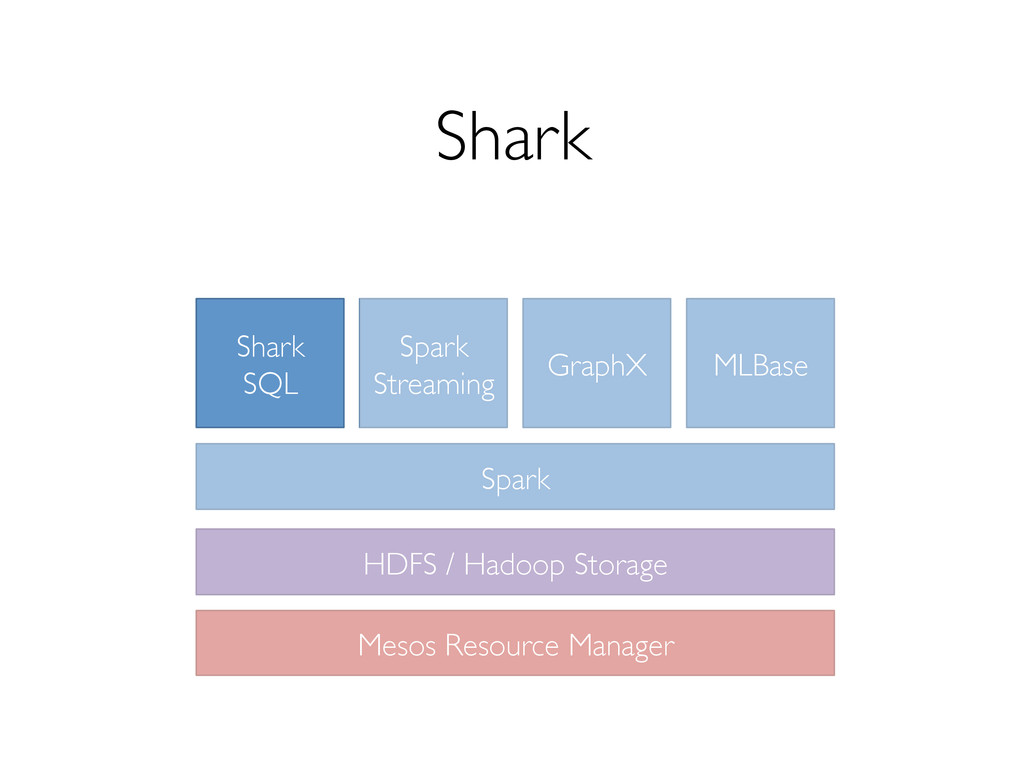
Shark Spark Shark SQL HDFS / Hadoop Storage Mesos Resource
Manager Spark Streaming GraphX MLBase -
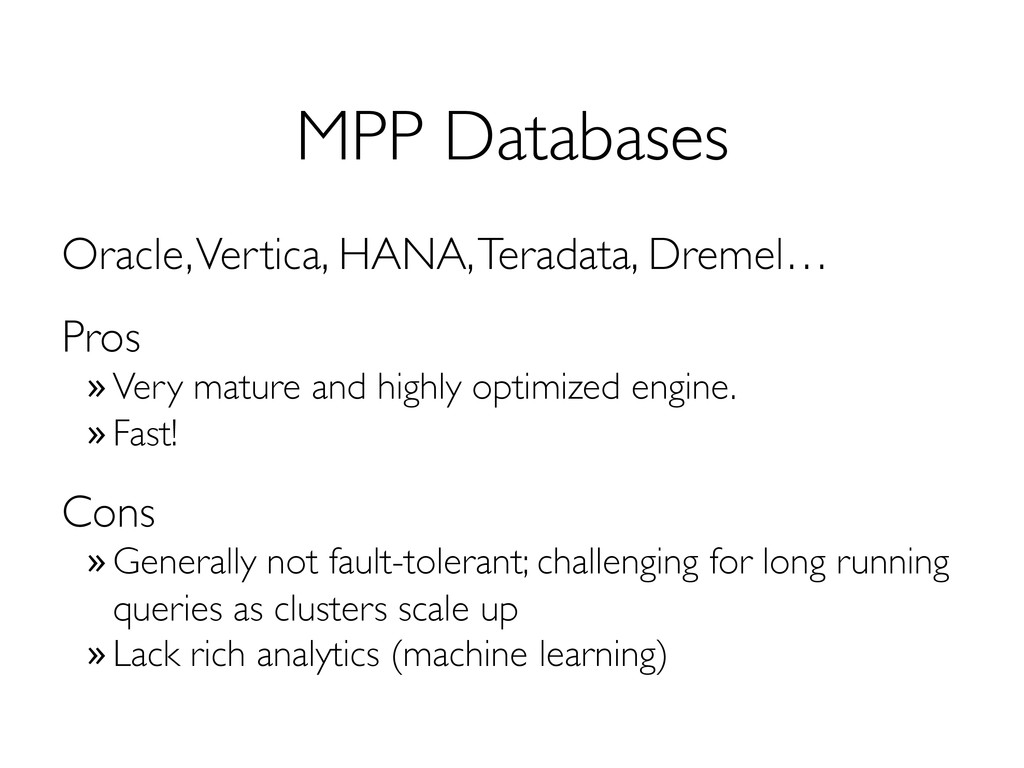
MPP Databases Oracle, Vertica, HANA, Teradata, Dremel… Pros » Very mature
and highly optimized engine. » Fast! Cons » Generally not fault-tolerant; challenging for long running queries as clusters scale up » Lack rich analytics (machine learning) -
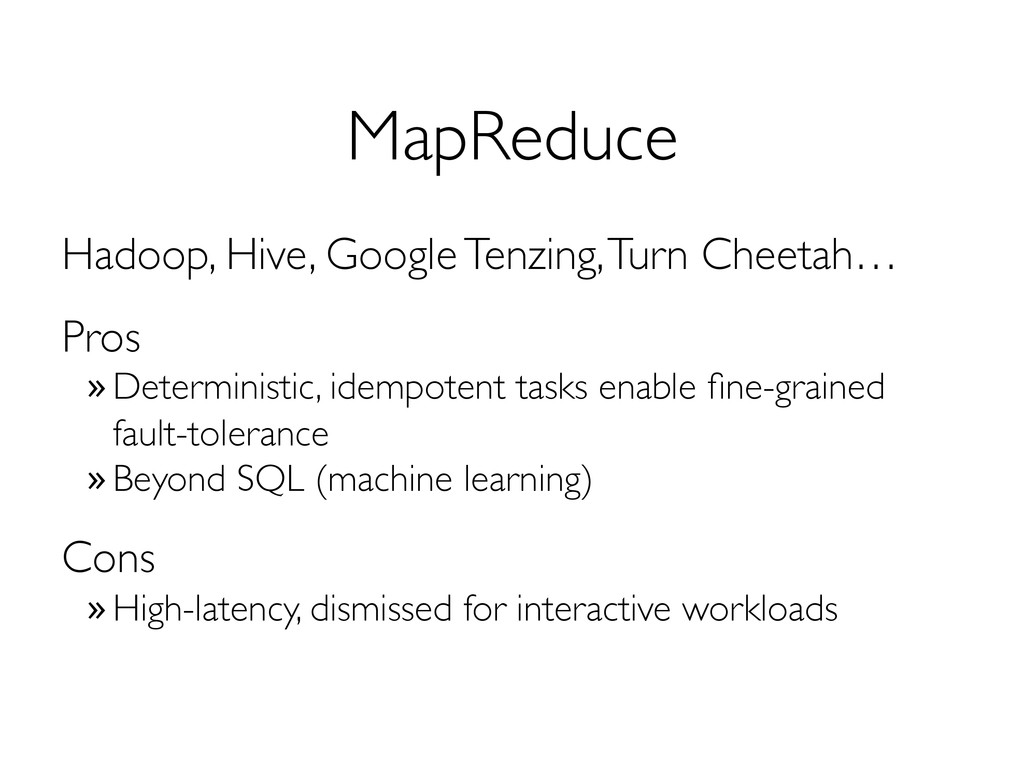
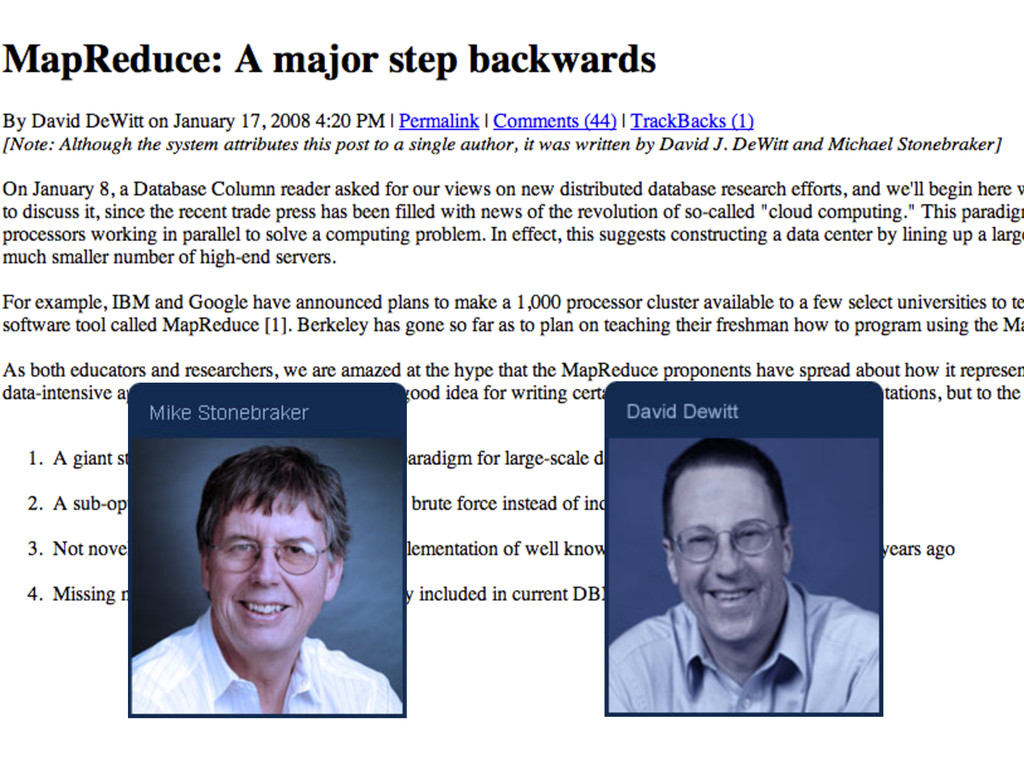
MapReduce Hadoop, Hive, Google Tenzing, Turn Cheetah… Pros » Deterministic, idempotent
tasks enable fine-grained fault-tolerance » Beyond SQL (machine learning) Cons » High-latency, dismissed for interactive workloads -
Shark A data analytics system that » builds on Spark, » scales
out and tolerate worker failures, » supports low-latency, interactive queries through in- memory computation, » supports both SQL and complex analytics, » is compatible with Hive (storage, serdes, UDFs, types, metadata). -
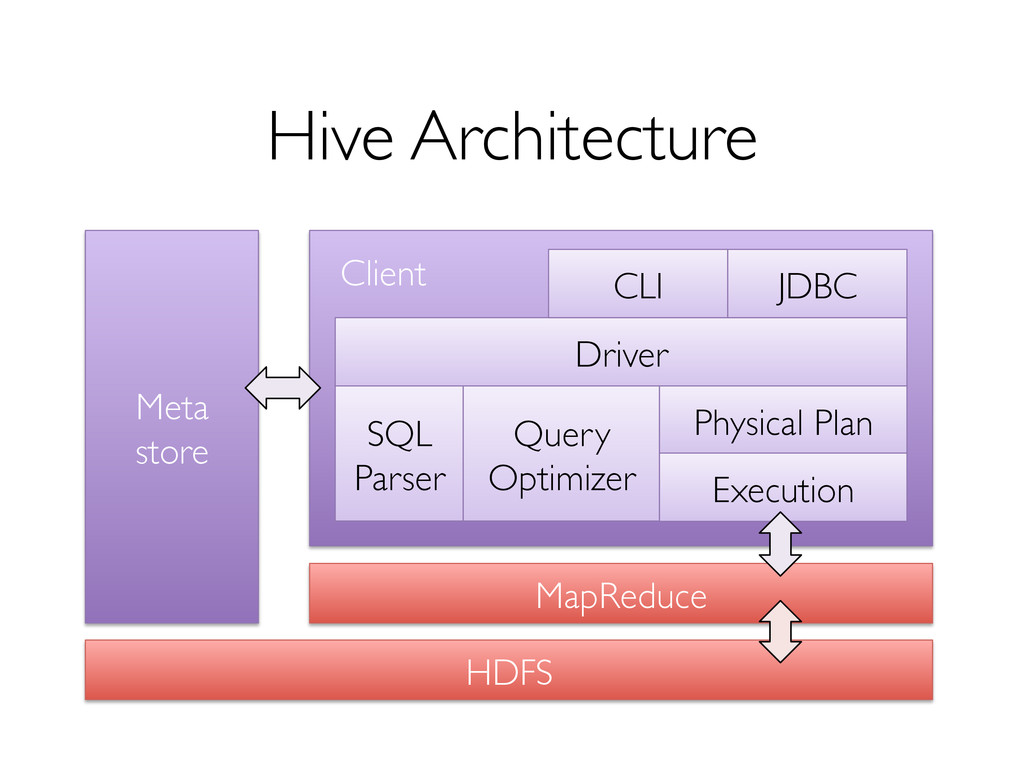
Hive Architecture Meta store HDFS Client Driver SQL Parser Query
Optimizer Physical Plan Execution CLI JDBC MapReduce -
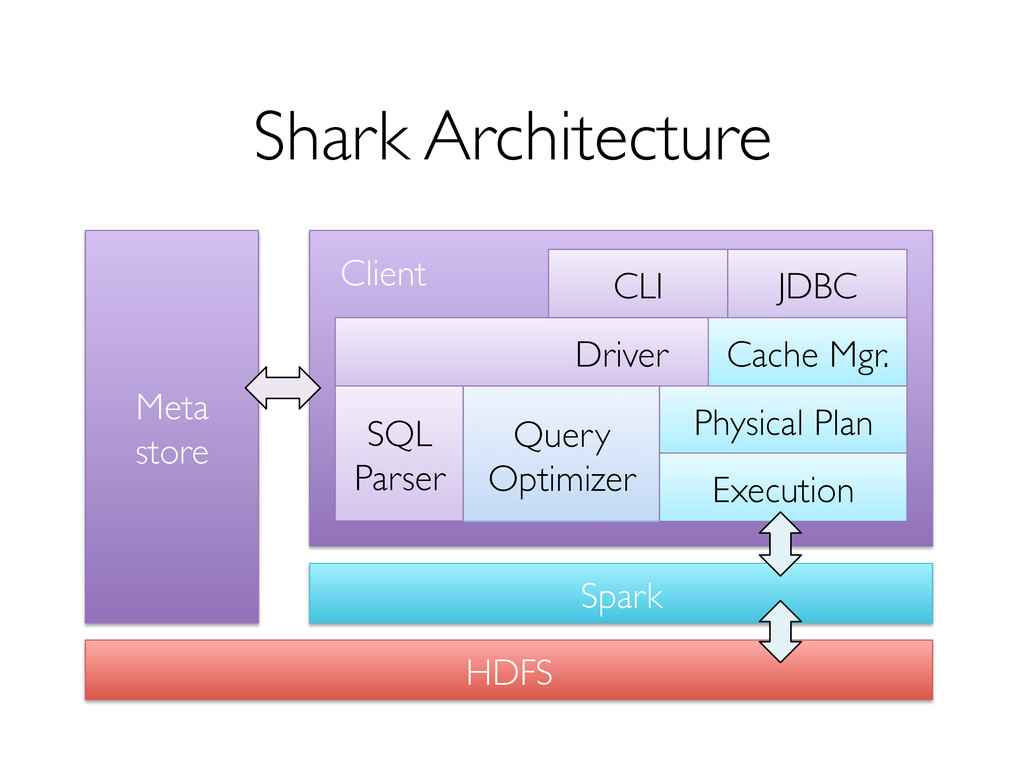
Shark Architecture Meta store HDFS Client Driver SQL Parser Physical
Plan Execution CLI JDBC Spark Cache Mgr. Query Optimizer -
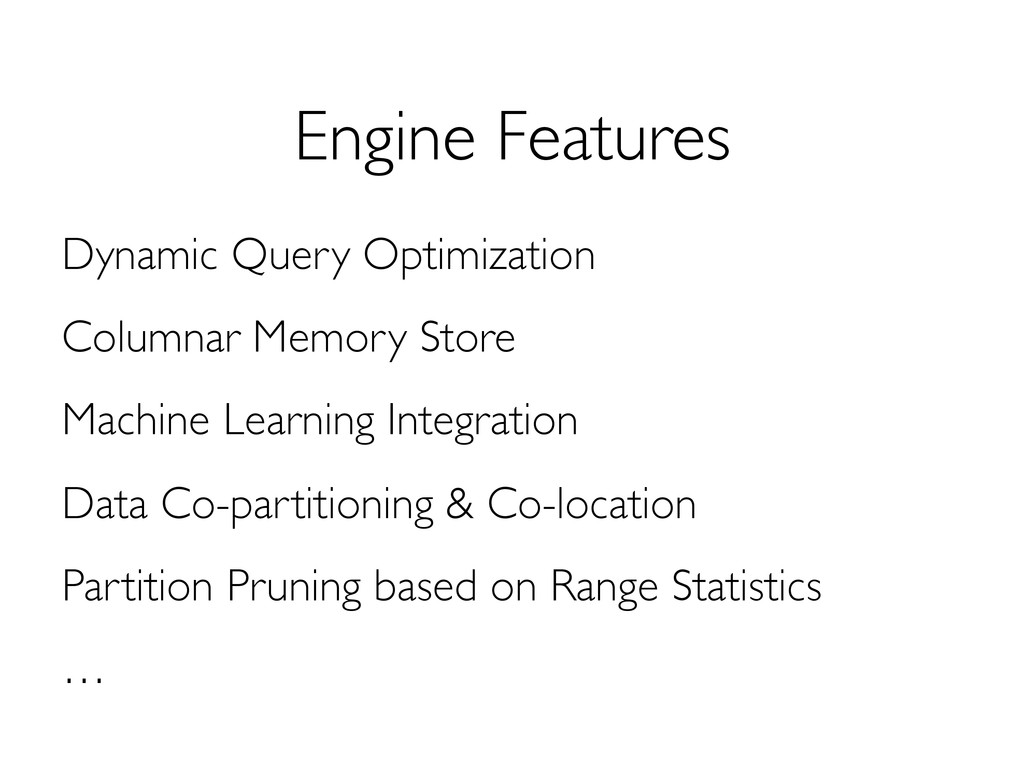
Engine Features Dynamic Query Optimization Columnar Memory Store Machine Learning
Integration Data Co-partitioning & Co-location Partition Pruning based on Range Statistics … -
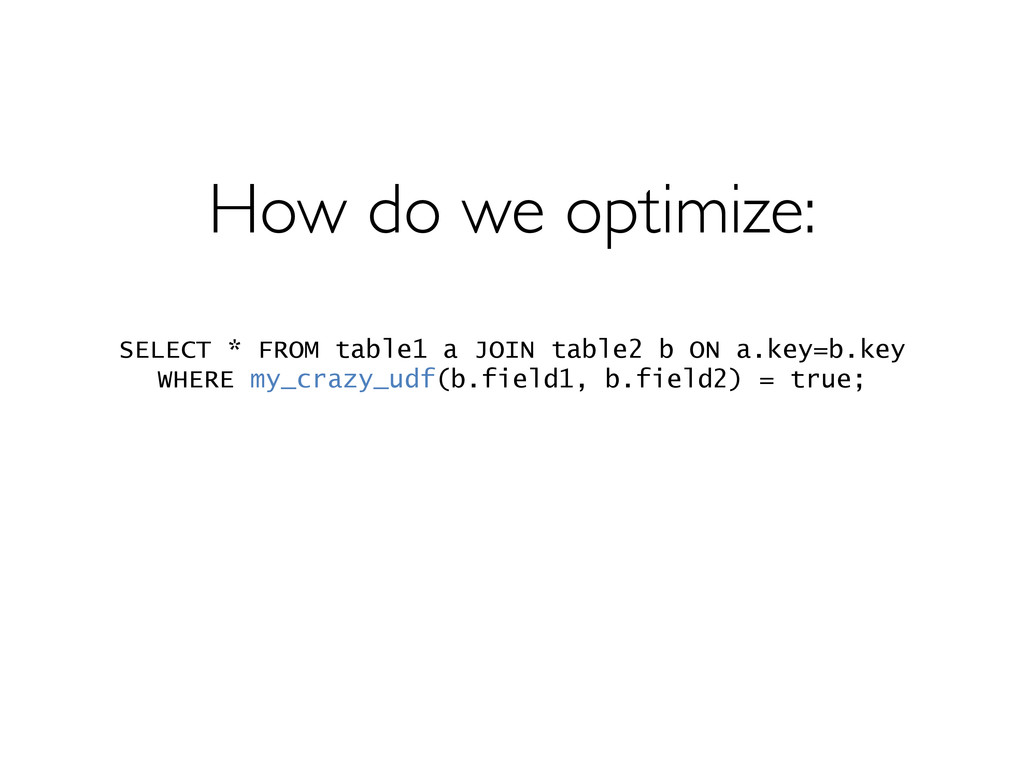
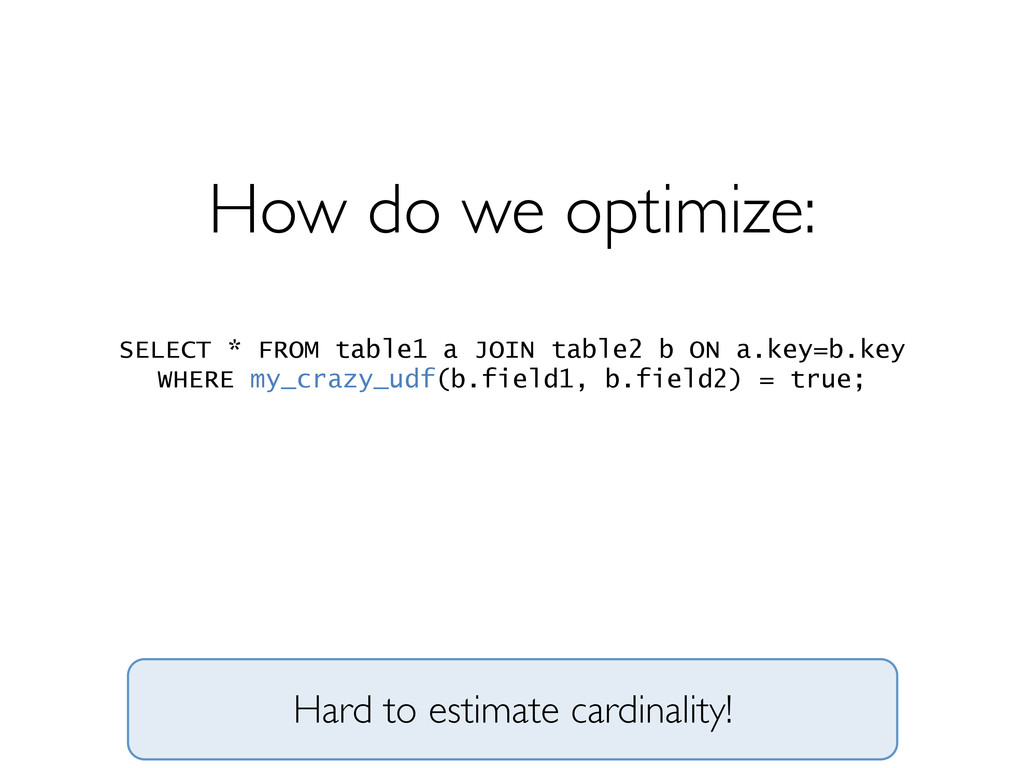
Partial DAG Execution (PDE) Lack of statistics for fresh data
and the prevalent use of UDFs necessitate dynamic approaches to query optimization. PDE allows dynamic alternation of query plans based on statistics collected at run-time. -
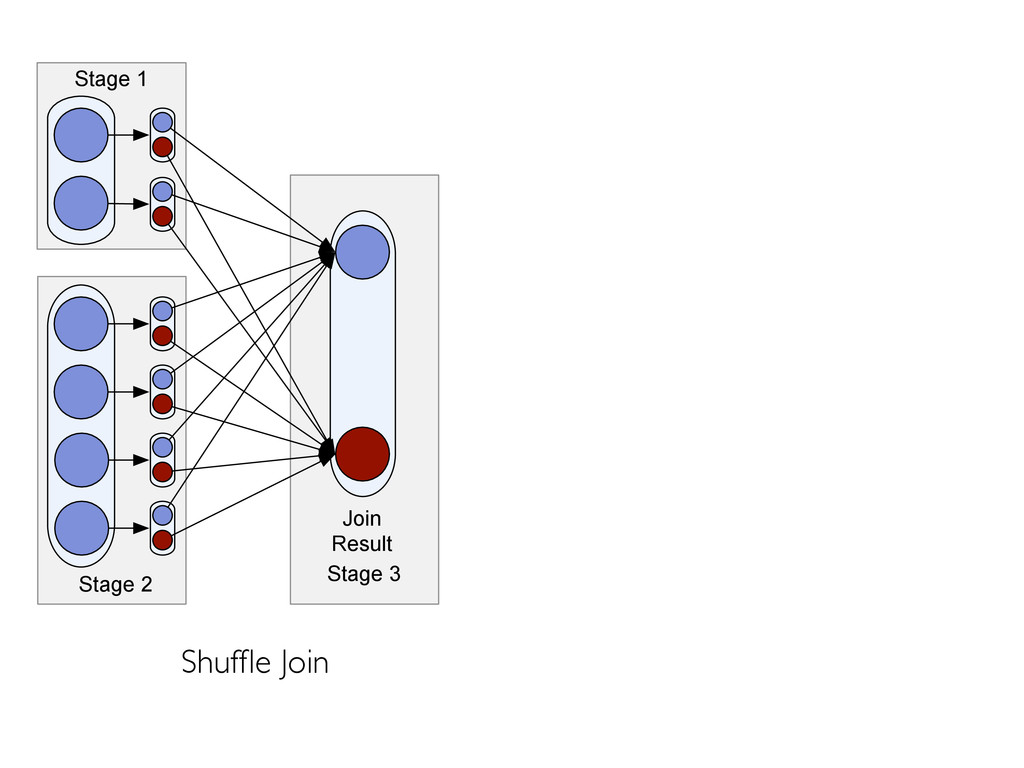
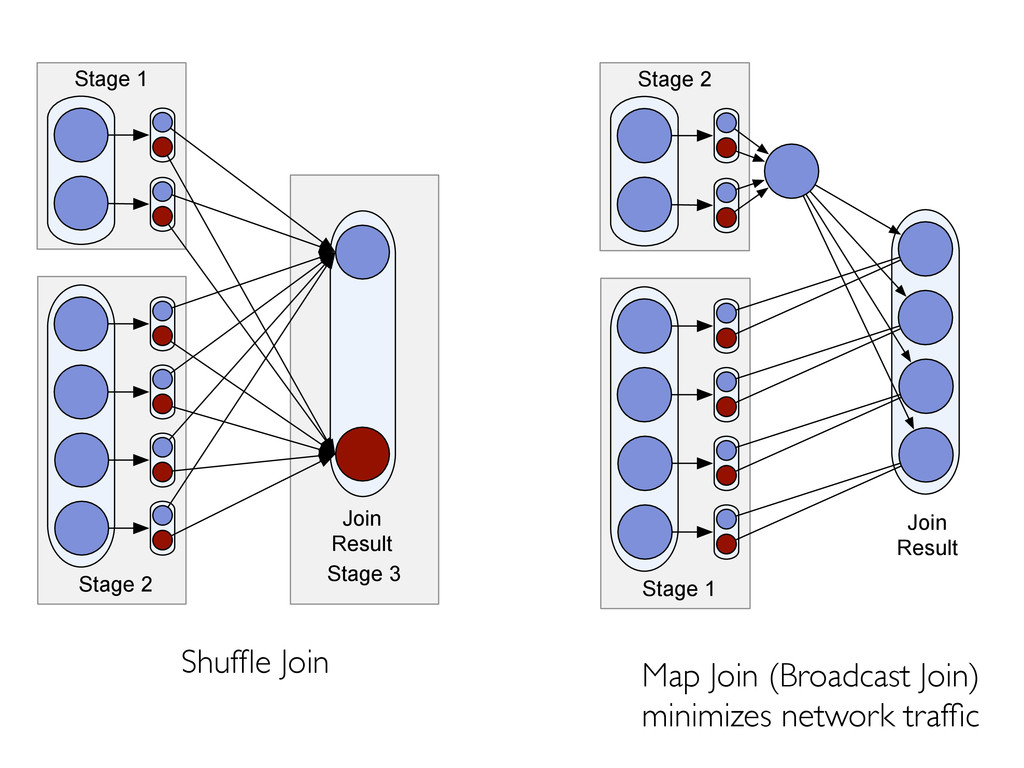
Shuffle Join Stage 3 Stage 2 Stage 1 Join Result
Stage 1 Stage 2 Join Result Map Join (Broadcast Join) minimizes network traffic -
PDE Statistics 1. Gather customizable statistics at per-partition granularities while
materializing map output. » partition sizes, record counts (skew detection) » “heavy hitters” » approximate histograms 2. Alter query plan based on such statistics » map join vs shuffle join » symmetric vs non-symmetric hash join » skew handling -
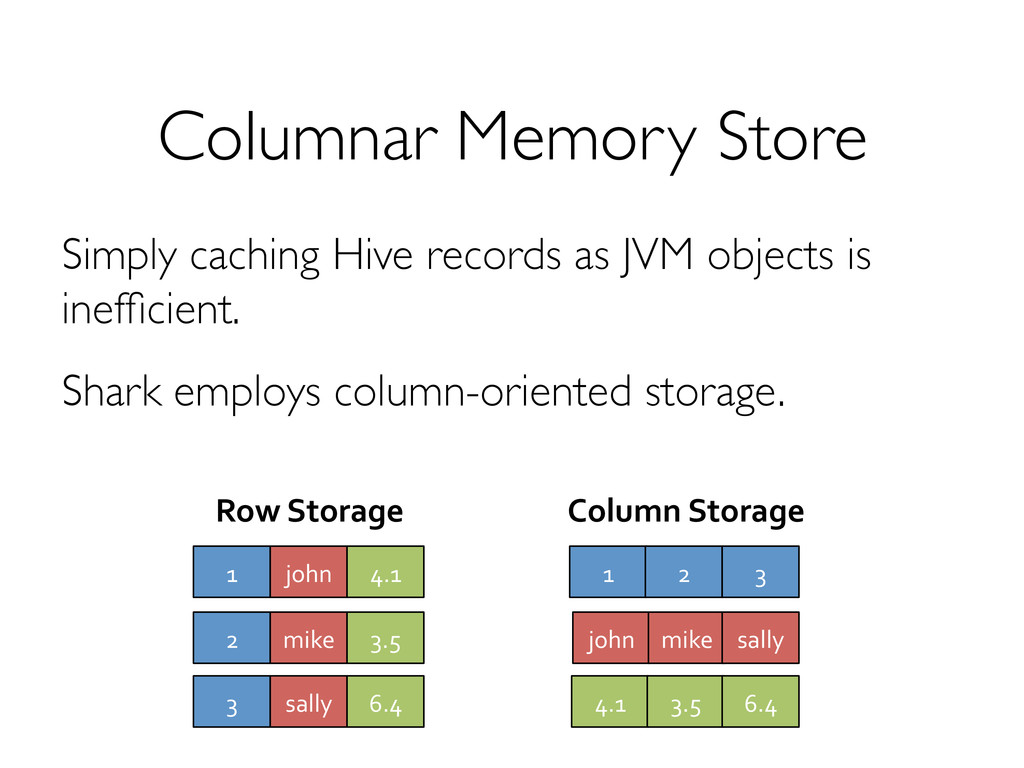
Columnar Memory Store Simply caching Hive records as JVM objects
is inefficient. Shark employs column-oriented storage. 1 Column Storage 2 3 john mike sally 4.1 3.5 6.4 Row Storage 1 john 4.1 2 mike 3.5 3 sally 6.4 -
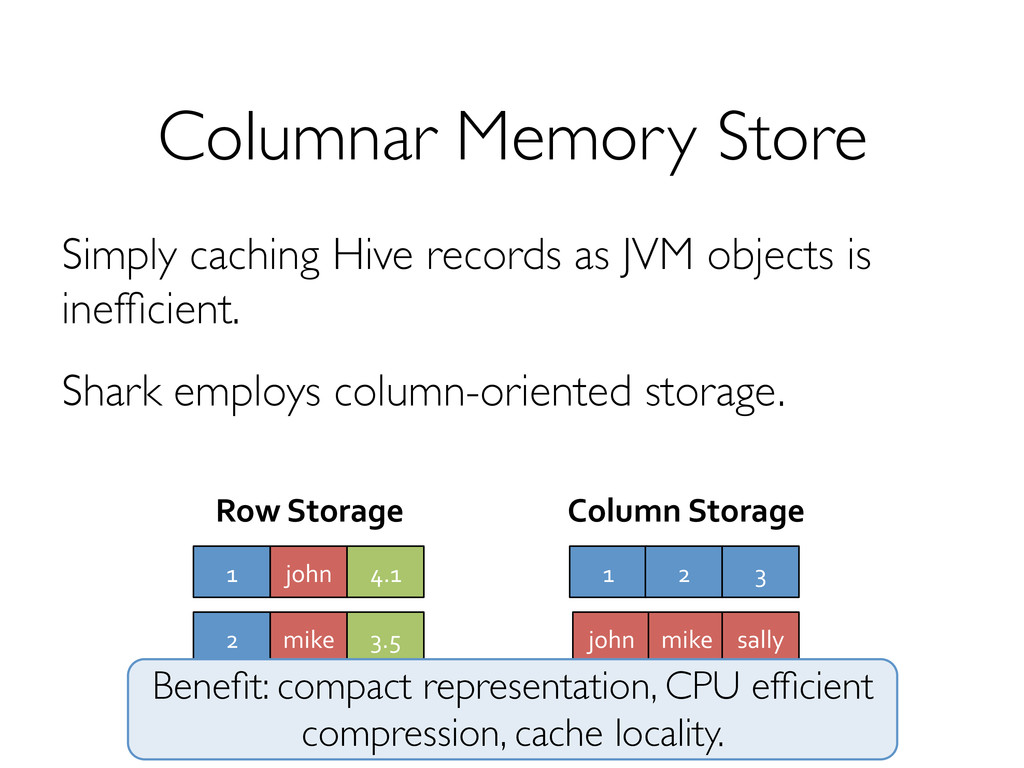
Columnar Memory Store Simply caching Hive records as JVM objects
is inefficient. Shark employs column-oriented storage. 1 Column Storage 2 3 john mike sally 4.1 3.5 6.4 Row Storage 1 john 4.1 2 mike 3.5 3 sally 6.4 Benefit: compact representation, CPU efficient compression, cache locality. -
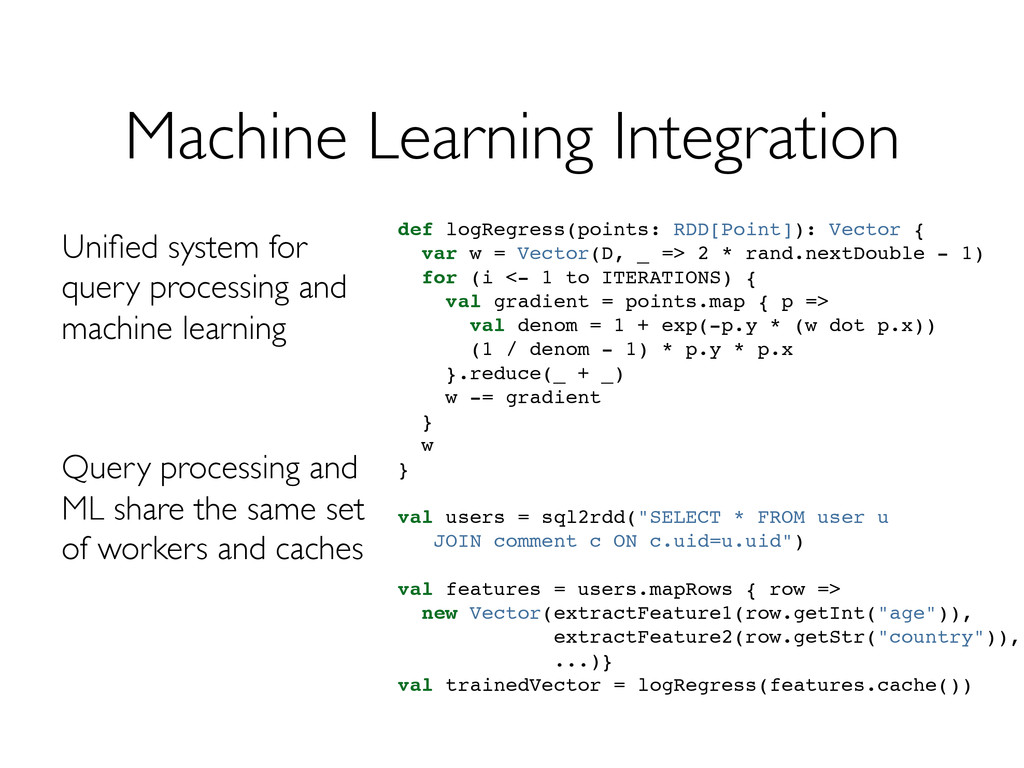
Machine Learning Integration Unified system for query processing and machine
learning Query processing and ML share the same set of workers and caches def logRegress(points: RDD[Point]): Vector { var w = Vector(D, _ => 2 * rand.nextDouble - 1) for (i <- 1 to ITERATIONS) { val gradient = points.map { p => val denom = 1 + exp(-p.y * (w dot p.x)) (1 / denom - 1) * p.y * p.x }.reduce(_ + _) w -= gradient } w } val users = sql2rdd("SELECT * FROM user u JOIN comment c ON c.uid=u.uid") val features = users.mapRows { row => new Vector(extractFeature1(row.getInt("age")), extractFeature2(row.getStr("country")), ...)} val trainedVector = logRegress(features.cache()) -
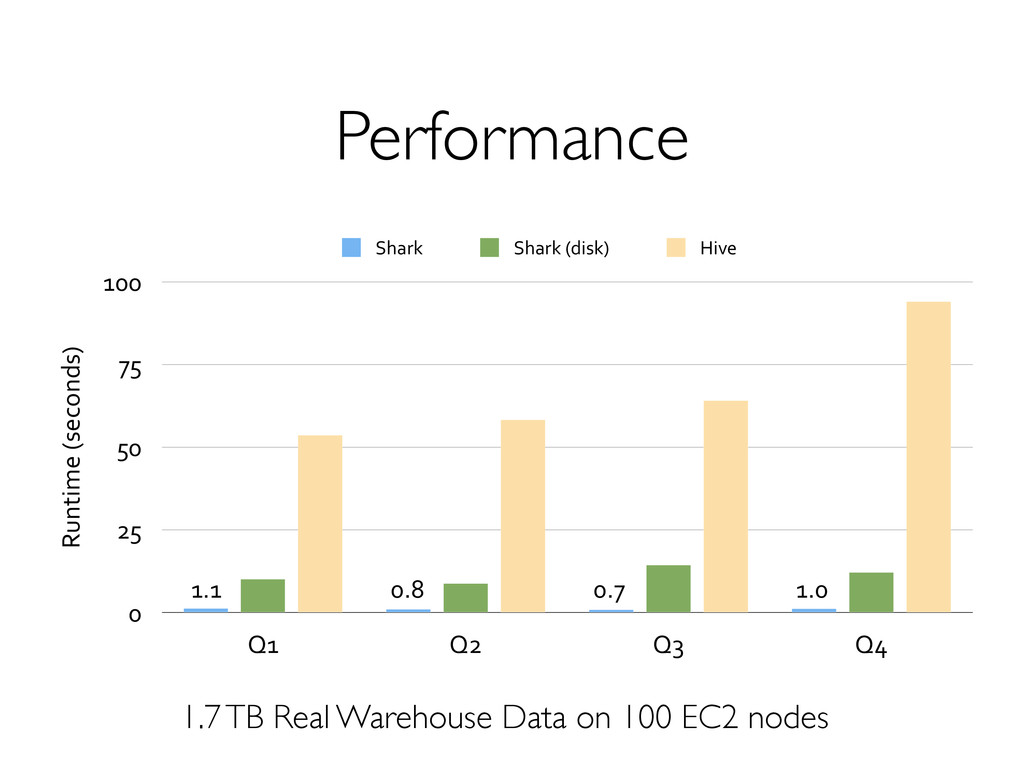
Performance 0 25 50 75 100 Q1 Q2 Q3 Q4
Runtime0(seconds) Shark Shark0(disk) Hive 1.1 0.8 0.7 1.0 1.7 TB Real Warehouse Data on 100 EC2 nodes -
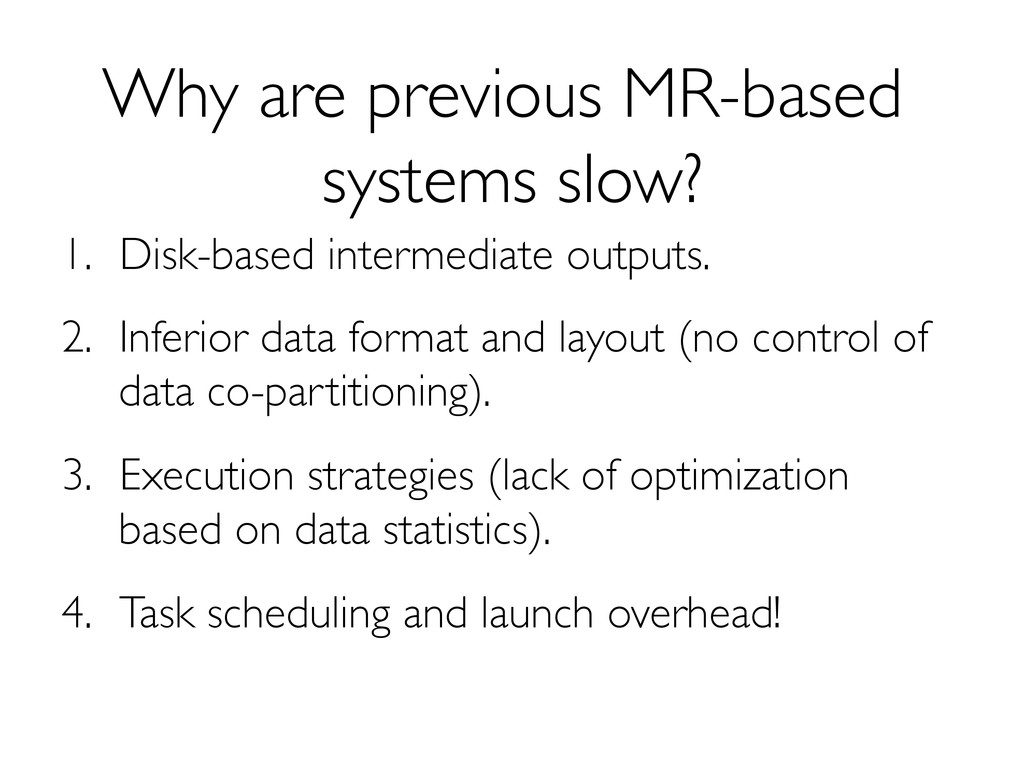
Why are previous MR-based systems slow? 1. Disk-based intermediate outputs.
2. Inferior data format and layout (no control of data co-partitioning). 3. Execution strategies (lack of optimization based on data statistics). 4. Task scheduling and launch overhead! -
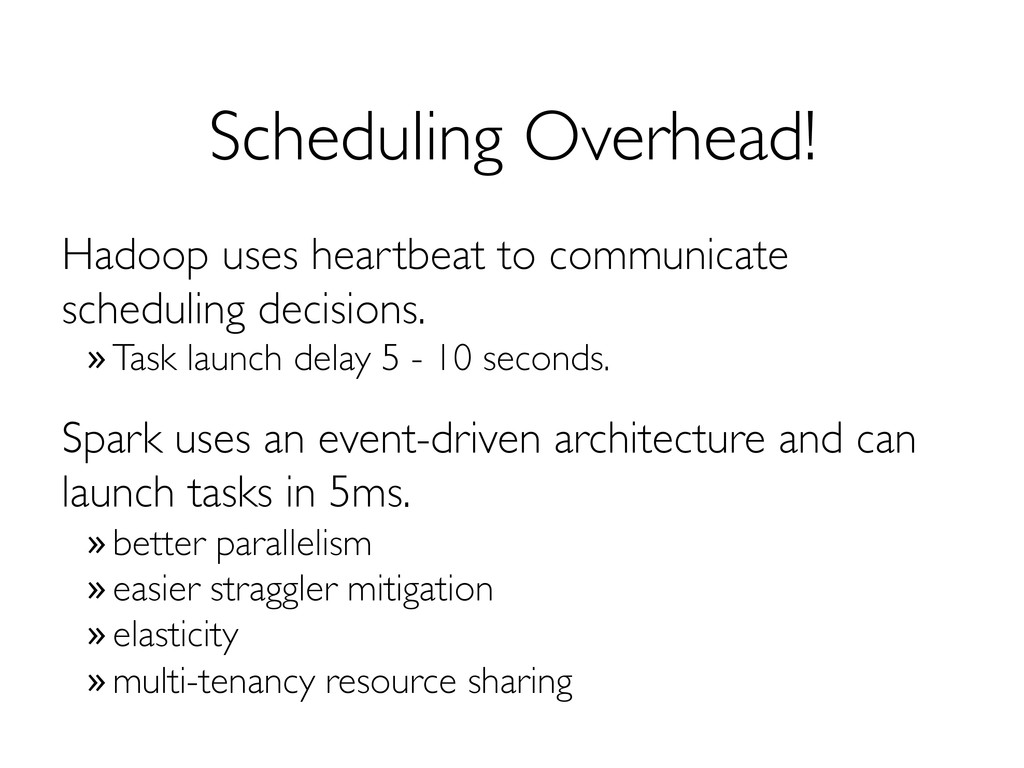
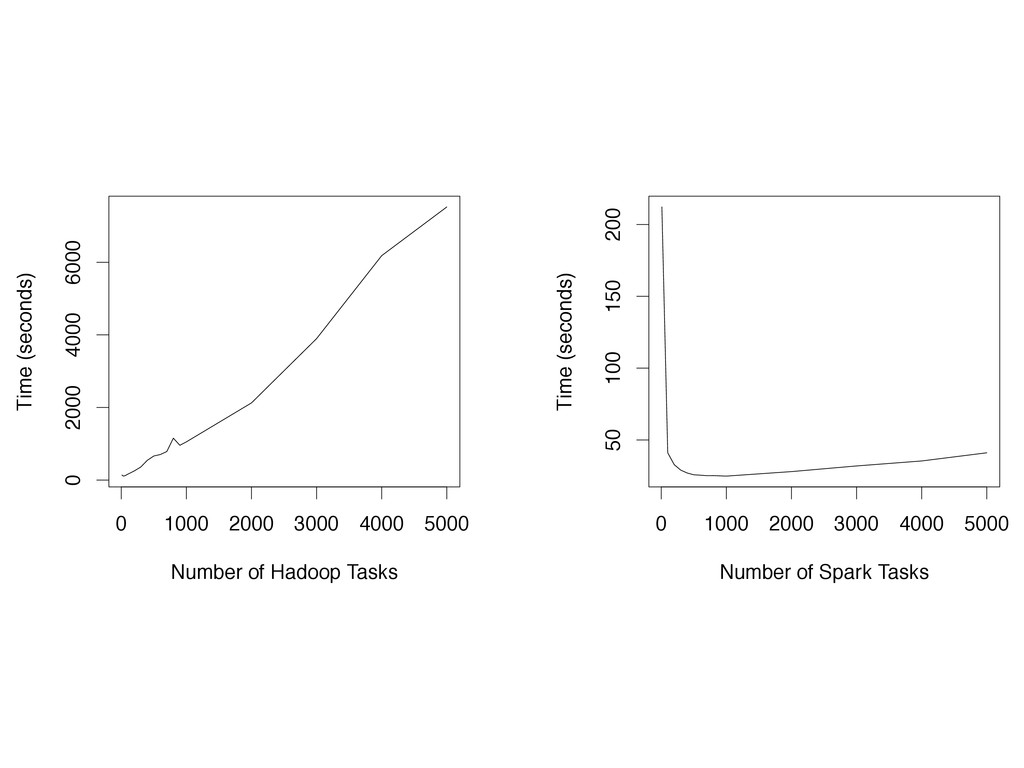
Scheduling Overhead! Hadoop uses heartbeat to communicate scheduling decisions. » Task
launch delay 5 - 10 seconds. Spark uses an event-driven architecture and can launch tasks in 5ms. » better parallelism » easier straggler mitigation » elasticity » multi-tenancy resource sharing -
0 1000 2000 3000 4000 5000 0 2000 4000 6000
Number of Hadoop Tasks Time (seconds) 0 1000 2000 3000 4000 5000 50 100 150 200 Number of Spark Tasks Time (seconds) -
More Information Download and docs: www.spark-project.org » Easy to run locally,
on EC2, or on Mesos/YARN Email: [email protected] Twitter: @rxin -
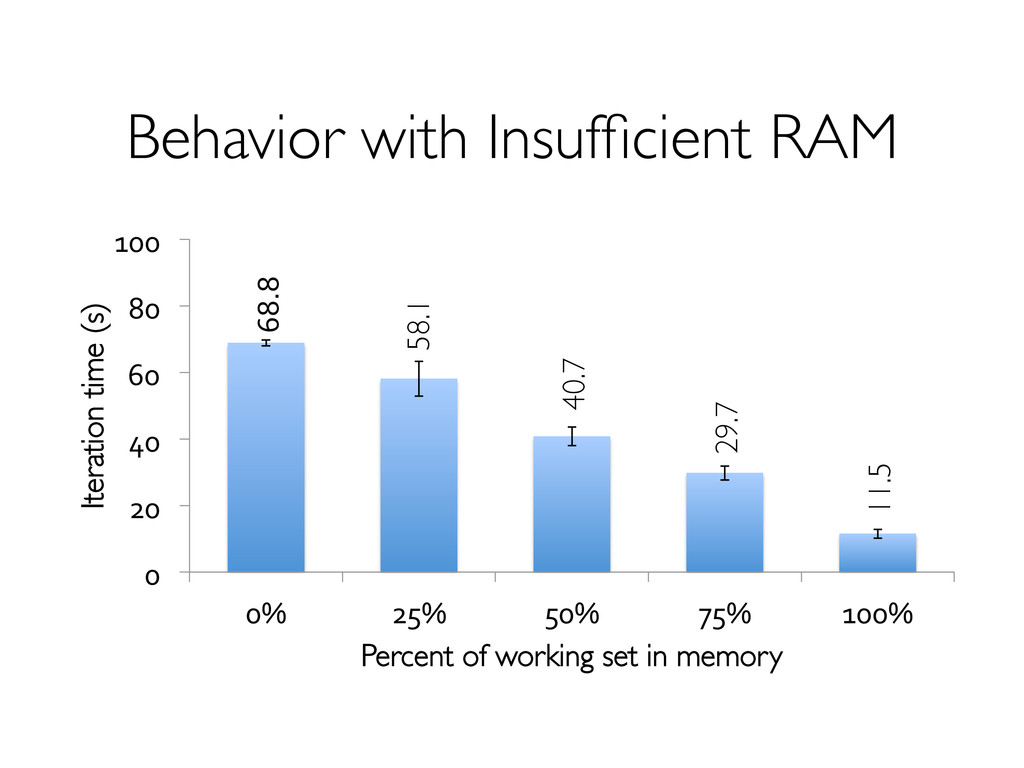
Behavior with Insufficient RAM 68.8 58.1 40.7 29.7 11.5
0 20 40 60 80 100 0% 25% 50% 75% 100% Iteration time (s) Percent of working set in memory -
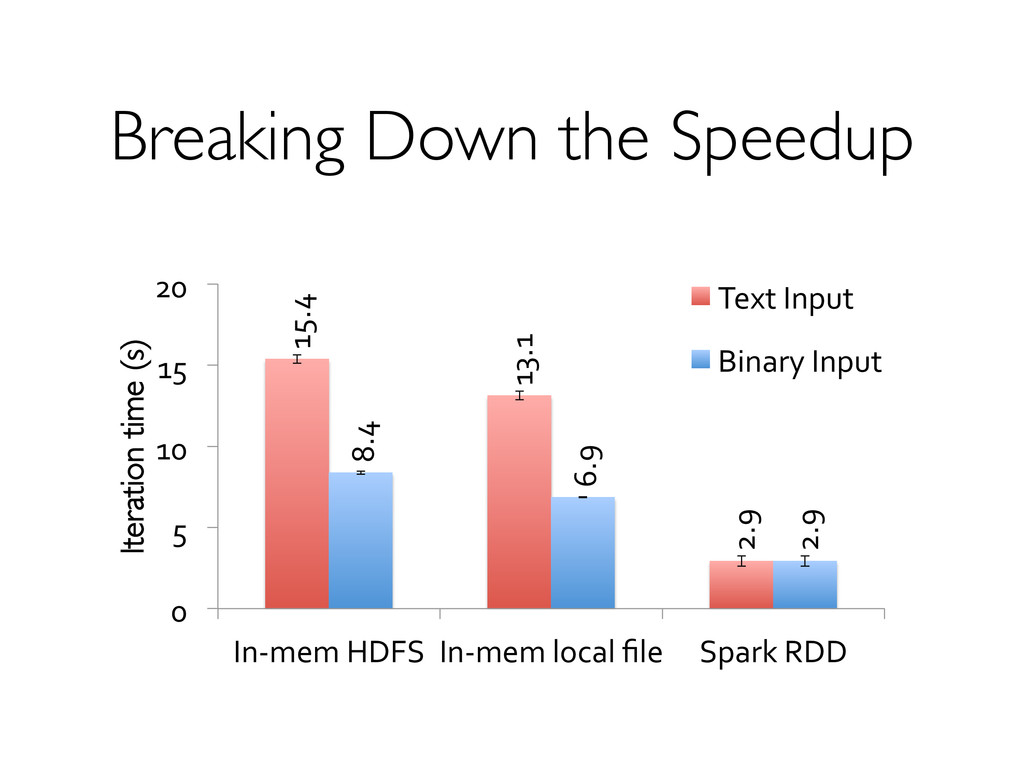
Breaking Down the Speedup 15.4 13.1 2.9
8.4 6.9 2.9 0 5 10 15 20 In-‐mem HDFS In-‐mem local file Spark RDD Iteration time (s) Text Input Binary Input -
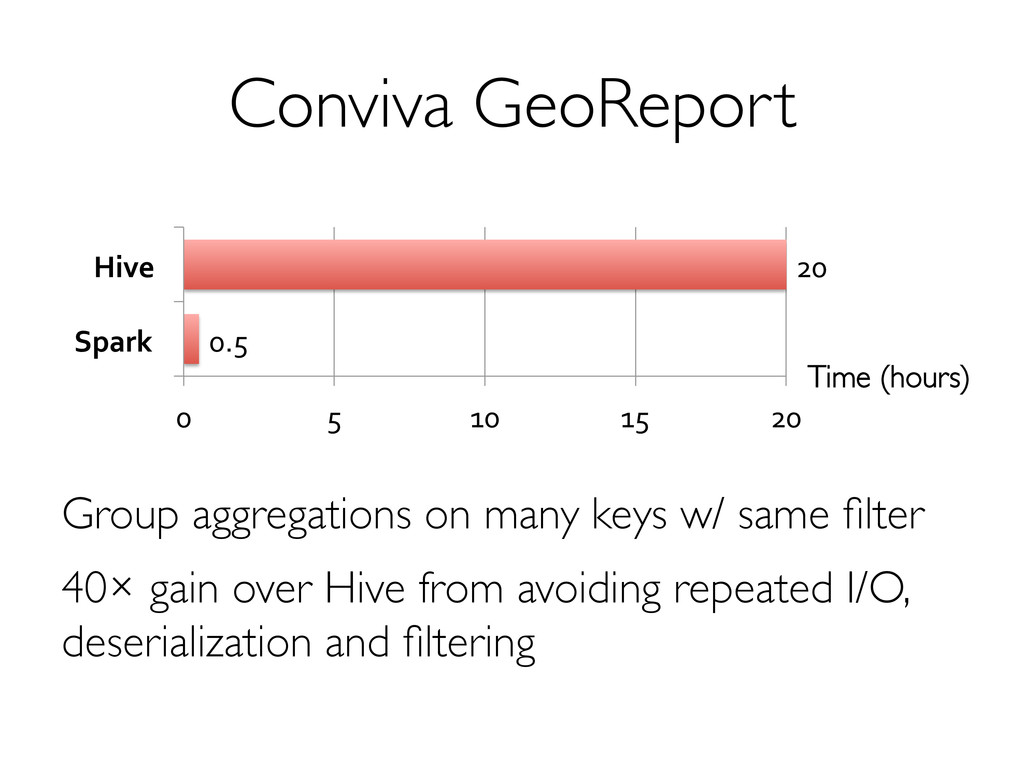
Conviva GeoReport Group aggregations on many keys w/ same filter
40× gain over Hive from avoiding repeated I/O, deserialization and filtering 0.5 20 0 5 10 15 20 Spark Hive Time (hours) -
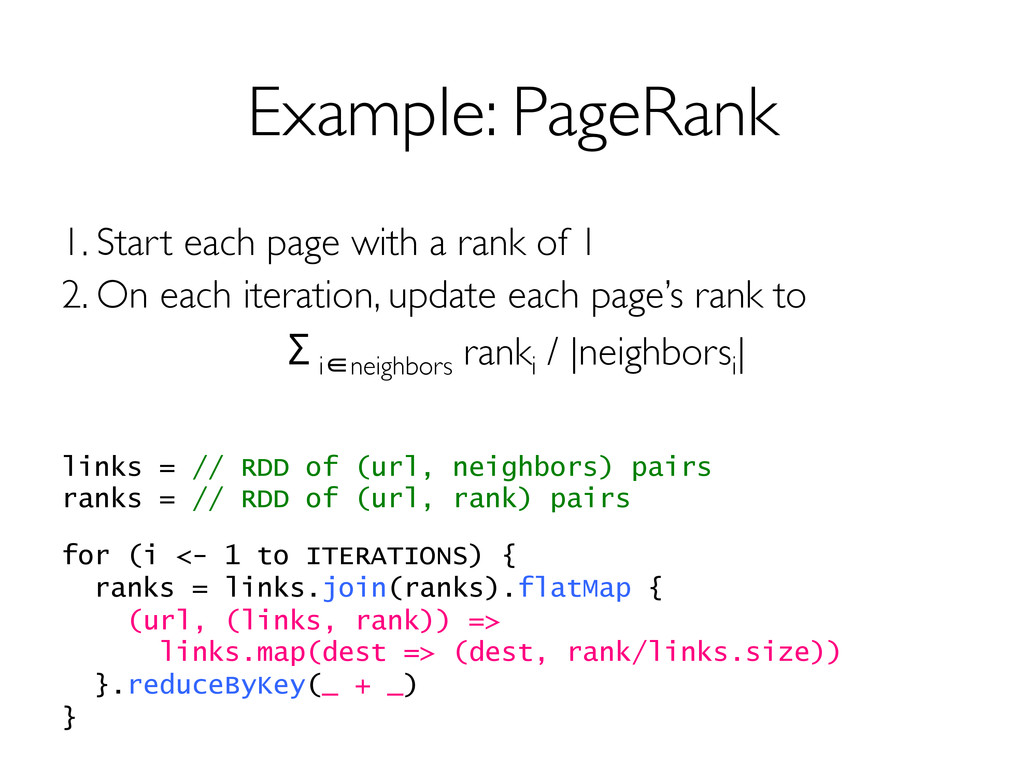
Example: PageRank 1. Start each page with a rank of
1 2. On each iteration, update each page’s rank to Σi∈neighbors ranki / |neighborsi | links = // RDD of (url, neighbors) pairs ranks = // RDD of (url, rank) pairs for (i <- 1 to ITERATIONS) { ranks = links.join(ranks).flatMap { (url, (links, rank)) => links.map(dest => (dest, rank/links.size)) }.reduceByKey(_ + _) }