Share
Embed
The Spark Ecosystem: Fast and Expressive Big Data Analytics in Scala @ Scala Days 2013
Reynold Xin
June 11, 2013
Transcript
40 slides
-
Matei Zaharia and Reynold Xin University of California,
Berkeley www.spark-‐project.org The Ecosystem Fast and Expressive Big Data Analytics in Scala UC BERKELEY -
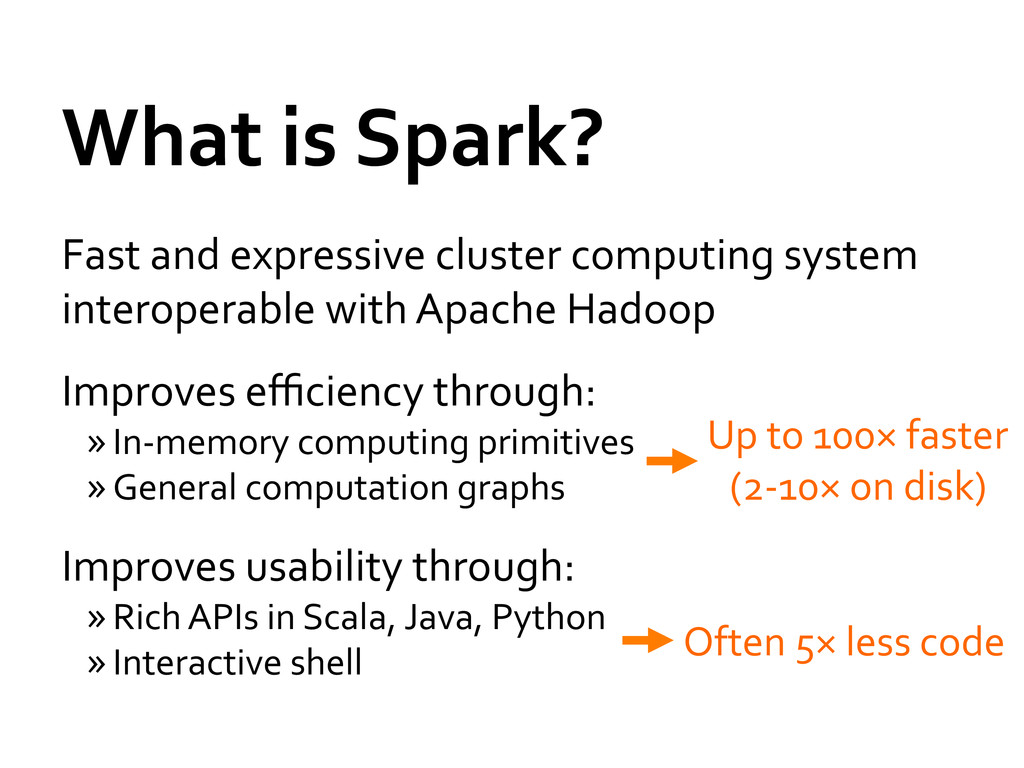
What is Spark? Fast and expressive cluster computing system
interoperable with Apache Hadoop Improves efficiency through: » In-‐memory computing primitives » General computation graphs Improves usability through: » Rich APIs in Scala, Java, Python » Interactive shell Up to 100× faster (2-‐10× on disk) Often 5× less code -
Project History Spark started in 2009, open sourced 2010
In use at Intel, Yahoo!, Adobe, Quantifind, Conviva, Ooyala, Bizo and others 17 companies now contributing code -
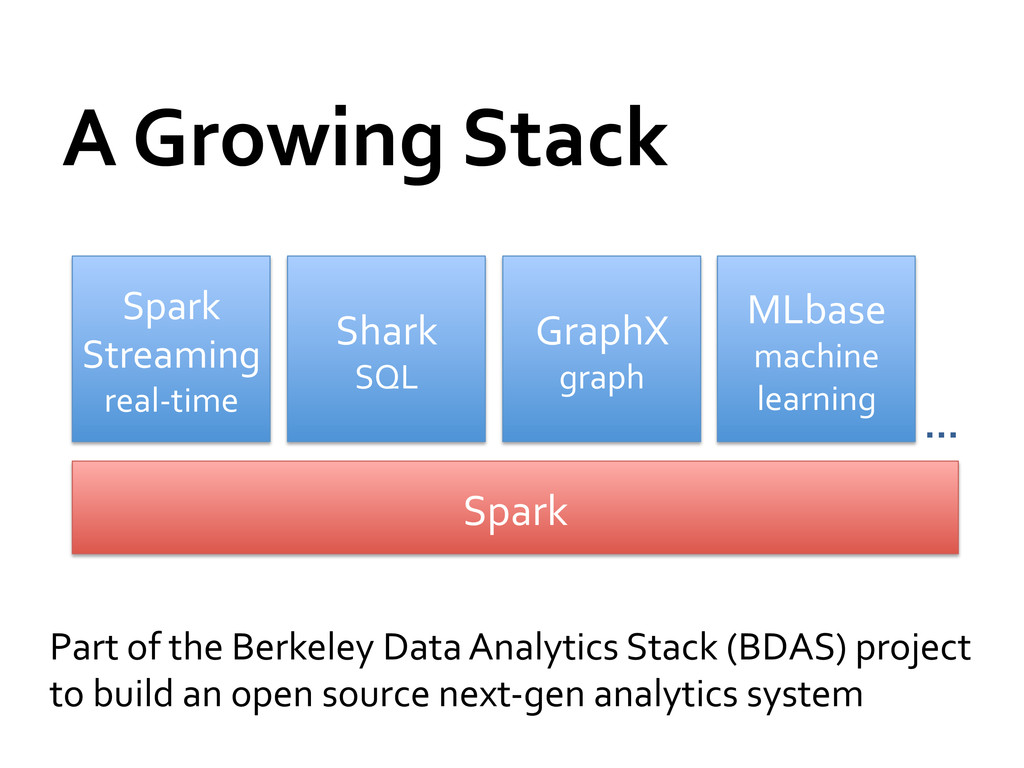
A Growing Stack Part of the Berkeley Data Analytics
Stack (BDAS) project to build an open source next-‐gen analytics system Spark Shark SQL Spark Streaming real-‐time GraphX graph MLbase machine learning … -
This Talk Spark introduction & use cases GraphX:
graph computation Shark: SQL over Spark See tomorrow for a talk on Streaming! -
Why a New Programming Model? MapReduce greatly simplified big
data analysis But as soon as it got popular, users wanted more: » More complex, multi-‐pass analytics (e.g. ML, graph) » More interactive ad-‐hoc queries » More real-‐time stream processing All 3 need faster data sharing across parallel jobs -
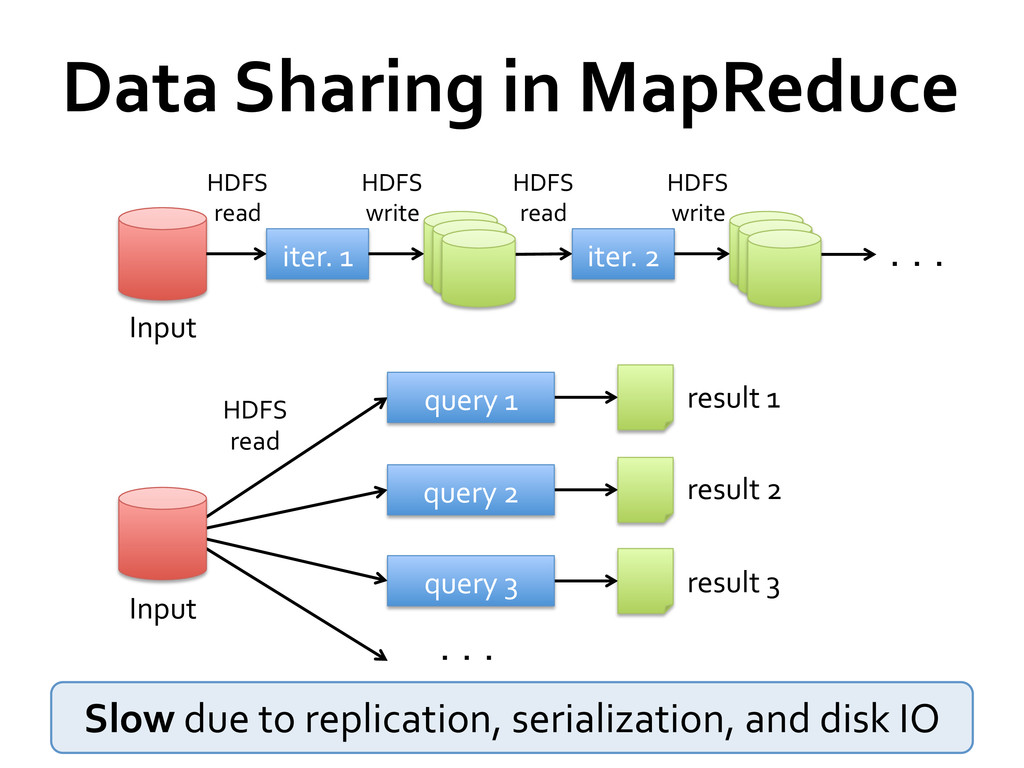
Data Sharing in MapReduce iter. 1 iter. 2
. . . Input HDFS read HDFS write HDFS read HDFS write Input query 1 query 2 query 3 result 1 result 2 result 3 . . . HDFS read Slow due to replication, serialization, and disk IO -
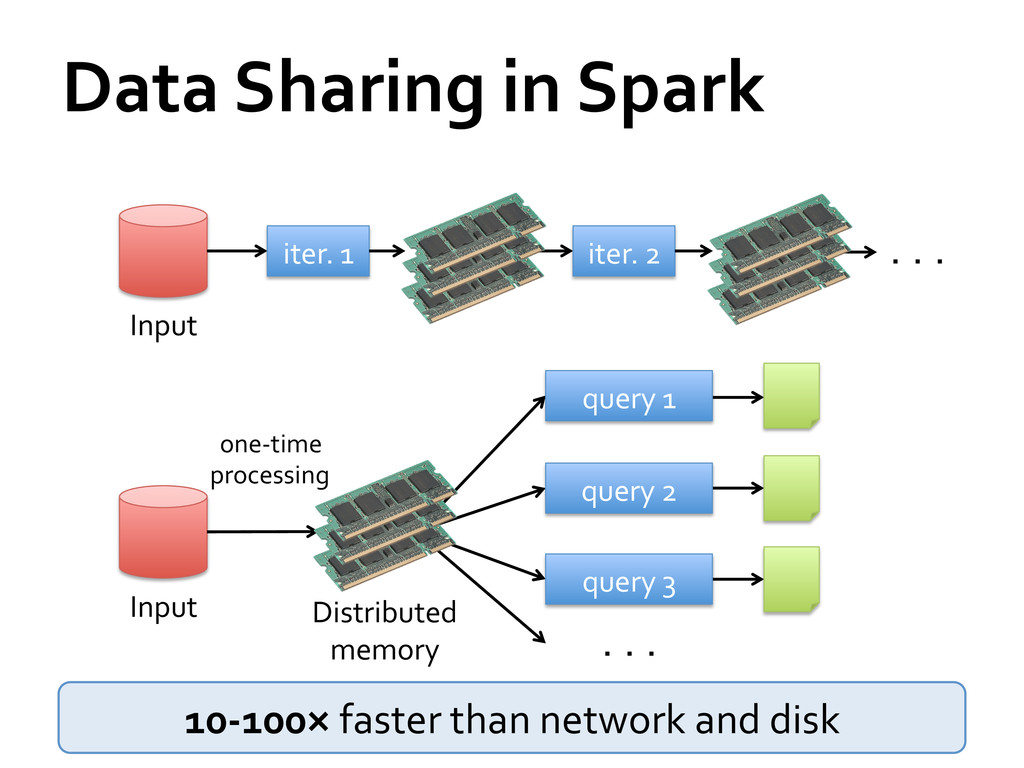
iter. 1 iter. 2 . .
. Input Data Sharing in Spark Distributed memory Input query 1 query 2 query 3 . . . one-‐time processing 10-‐100× faster than network and disk -
Spark Programming Model Key idea: resilient distributed datasets (RDDs)
» Distributed collections of objects that can be cached in memory across cluster » Manipulated through parallel operators » Automatically recomputed on failure Programming interface » Functional APIs in Scala, Java, Python » Interactive use from Scala shell -
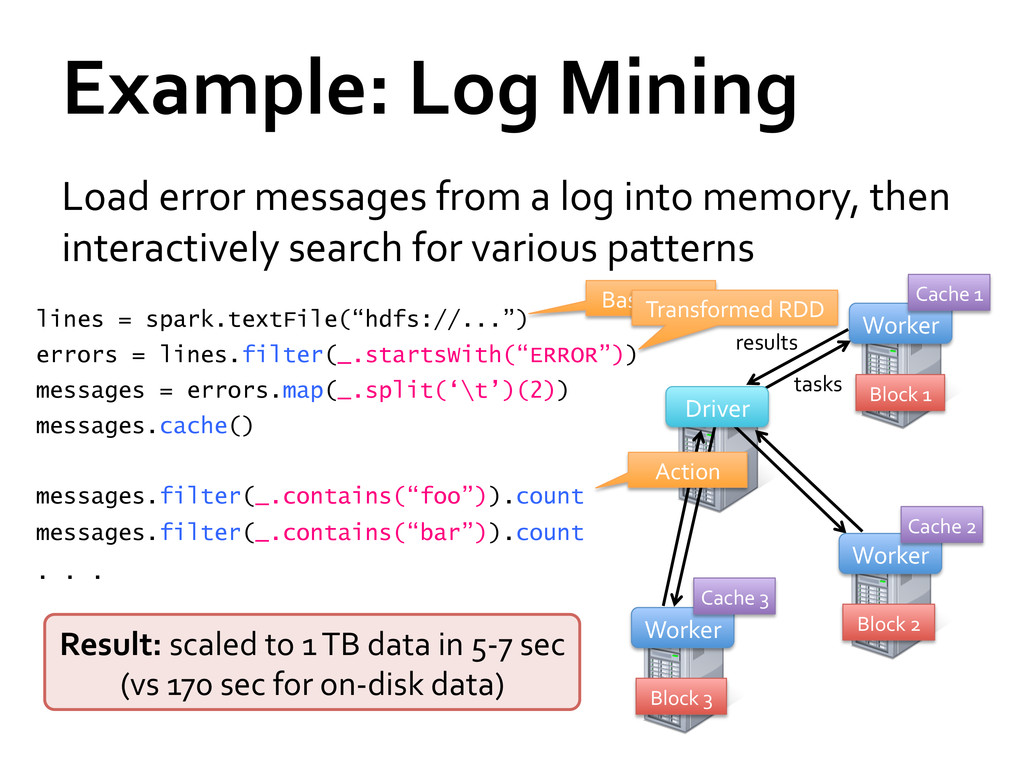
Example: Log Mining Load error messages from a log
into memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(_.startsWith(“ERROR”)) messages = errors.map(_.split(‘\t’)(2)) messages.cache() Block 1 Block 2 Block 3 Worker Worker Worker Driver messages.filter(_.contains(“foo”)).count messages.filter(_.contains(“bar”)).count . . . tasks results Cache 1 Cache 2 Cache 3 Base RDD Transformed RDD Action Result: full-‐text search of Wikipedia in <1 sec (vs 20 sec for on-‐disk data) Result: scaled to 1 TB data in 5-‐7 sec (vs 170 sec for on-‐disk data) -
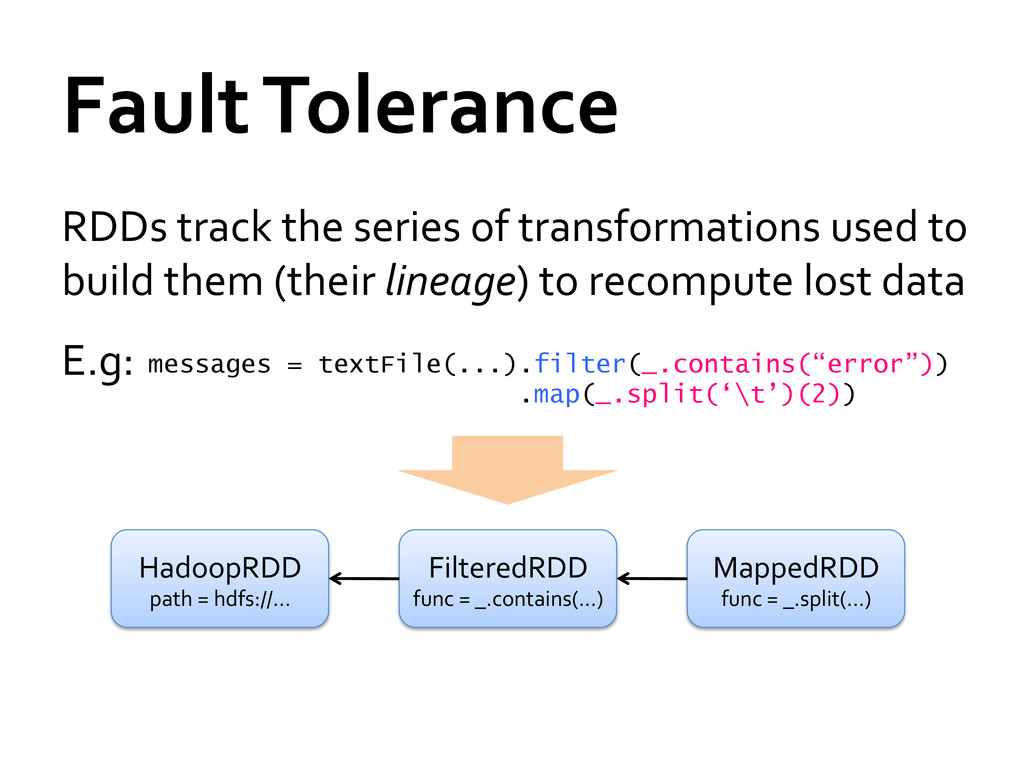
Fault Tolerance RDDs track the series of transformations used
to build them (their lineage) to recompute lost data E.g: messages = textFile(...).filter(_.contains(“error”)) .map(_.split(‘\t’)(2)) HadoopRDD path = hdfs://… FilteredRDD func = _.contains(...) MappedRDD func = _.split(…) -
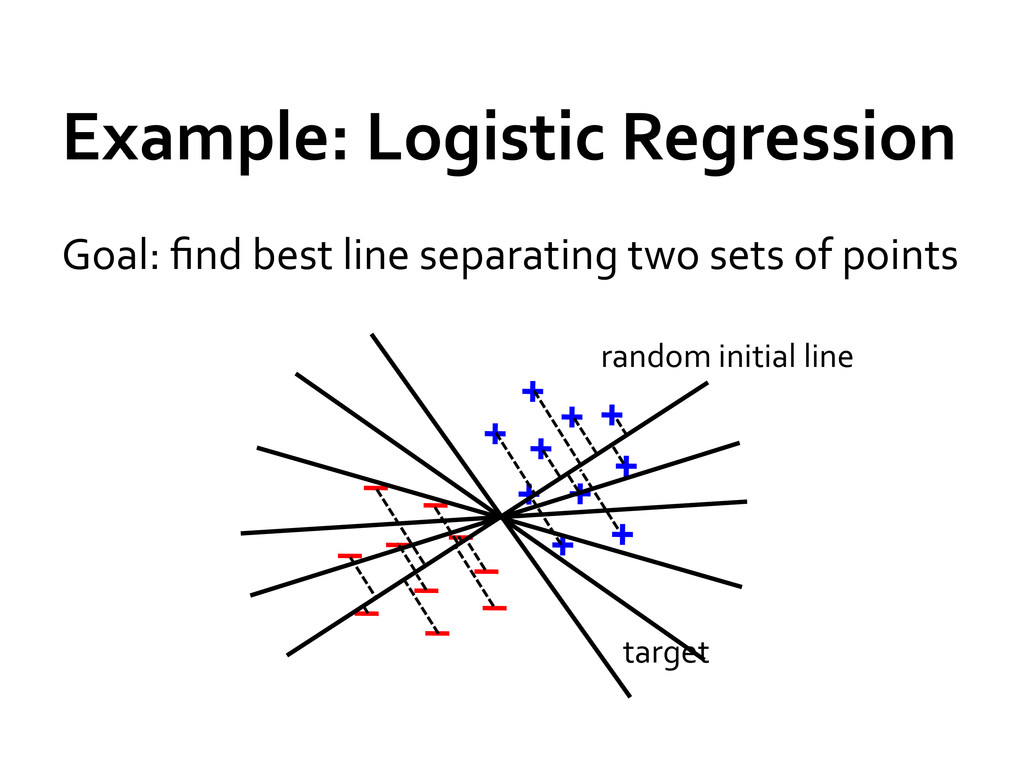
Example: Logistic Regression Goal: find best line separating two
sets of points + – + + + + + + + + – – – – – – – – + target – random initial line -
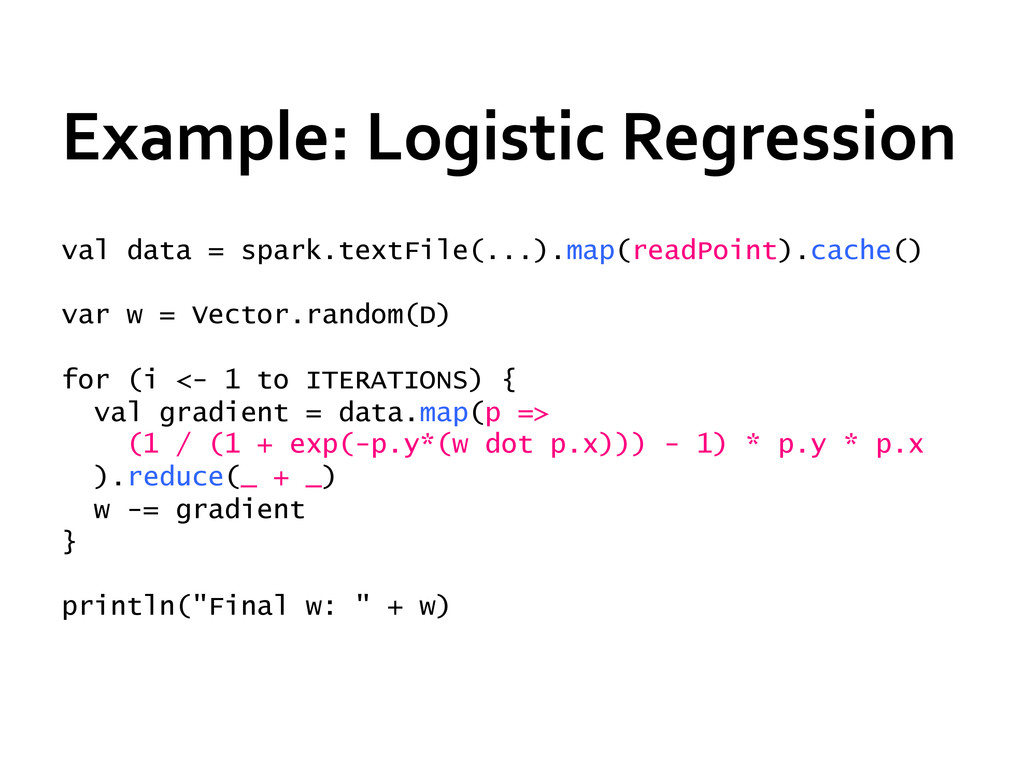
Example: Logistic Regression val data = spark.textFile(...).map(readPoint).cache() var w
= Vector.random(D) for (i <- 1 to ITERATIONS) { val gradient = data.map(p => (1 / (1 + exp(-p.y*(w dot p.x))) - 1) * p.y * p.x ).reduce(_ + _) w -= gradient } println("Final w: " + w) -
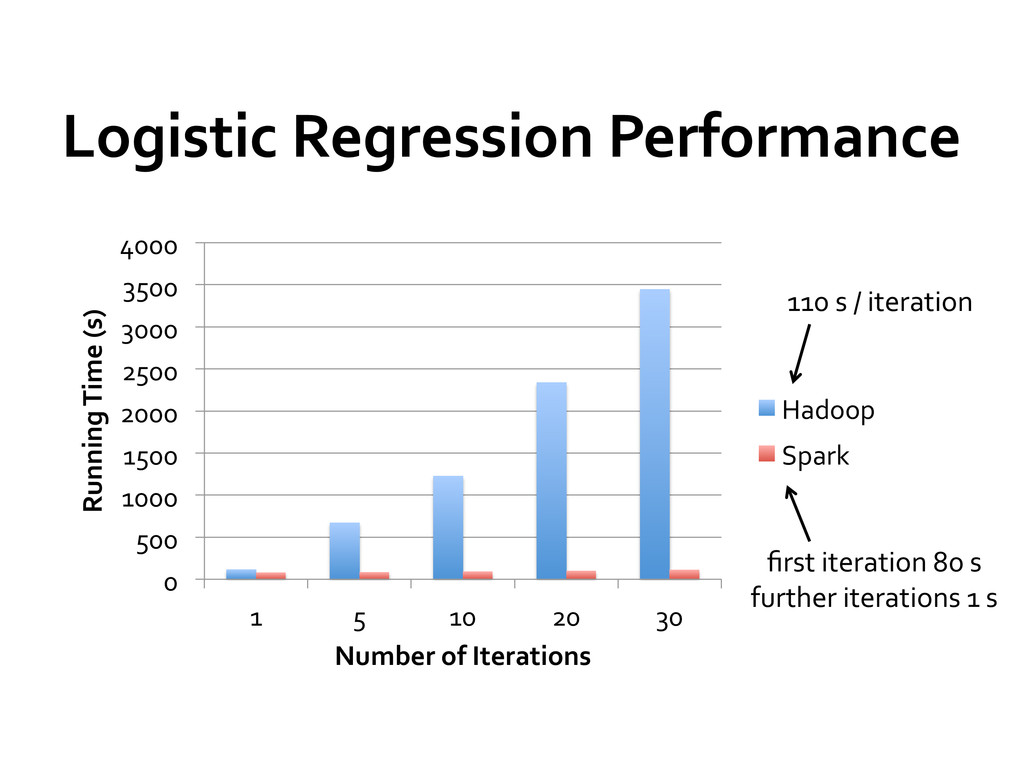
Logistic Regression Performance 0 500 1000
1500 2000 2500 3000 3500 4000 1 5 10 20 30 Running Time (s) Number of Iterations Hadoop Spark 110 s / iteration first iteration 80 s further iterations 1 s -
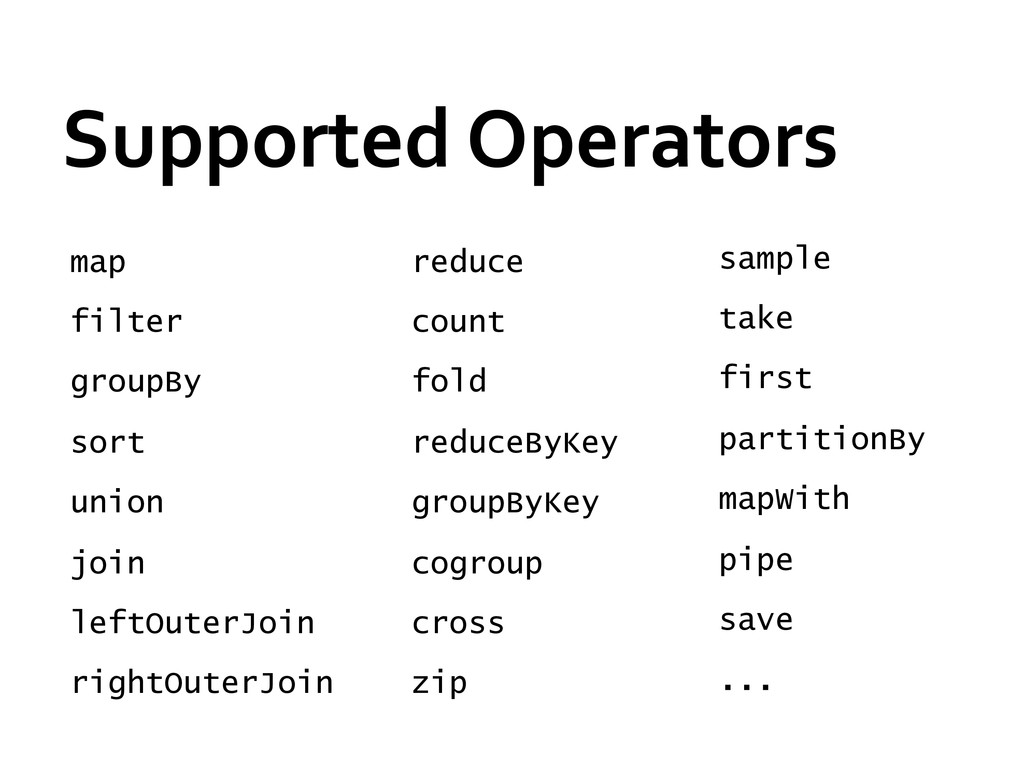
Supported Operators map filter groupBy sort union join leftOuterJoin
rightOuterJoin reduce count fold reduceByKey groupByKey cogroup cross zip sample take first partitionBy mapWith pipe save ... -
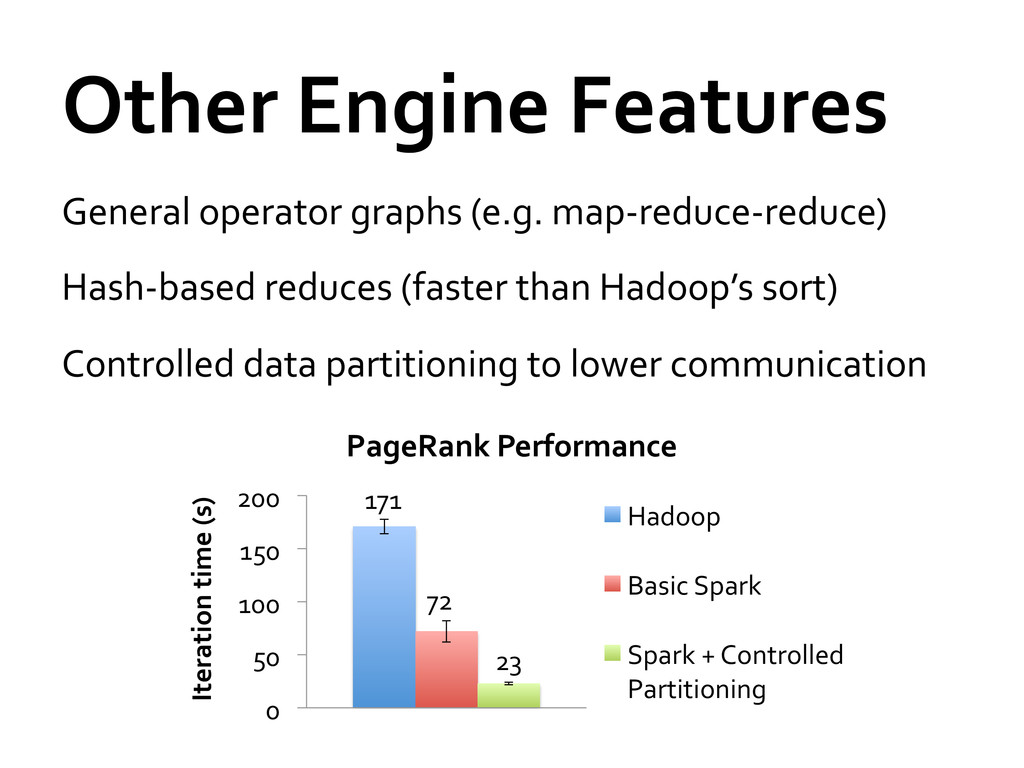
Other Engine Features General operator graphs (e.g. map-‐reduce-‐reduce)
Hash-‐based reduces (faster than Hadoop’s sort) Controlled data partitioning to lower communication 171 72 23 0 50 100 150 200 Iteration time (s) PageRank Performance Hadoop Basic Spark Spark + Controlled Partitioning -
700+ meetup members 30+ external contributors 17 companies
contributing Spark Community -
This Talk Spark introduction & use cases GraphX:
graph computation Shark: SQL over Spark -
Graphs are Essential to Data Mining Identify influential people
and information Find communities Target ads and products Model complex data dependencies -
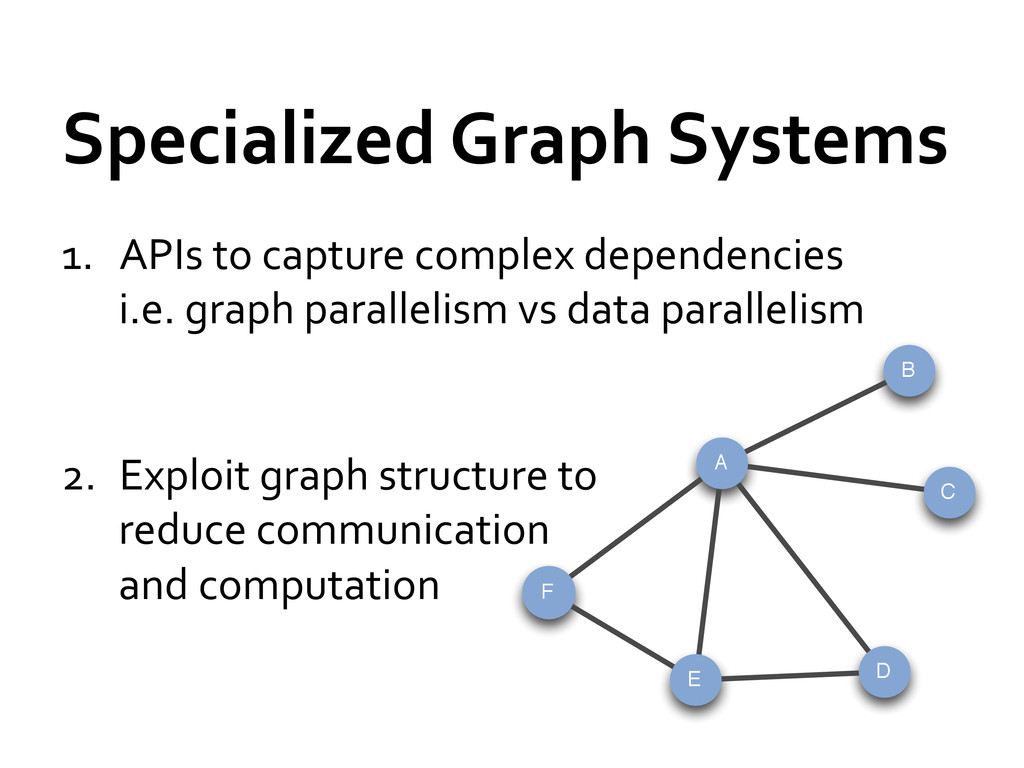
B C D E F A Specialized Graph Systems
1. APIs to capture complex dependencies i.e. graph parallelism vs data parallelism 2. Exploit graph structure to reduce communication and computation -
Simplicity Integration with Spark: no disparate system » ETL
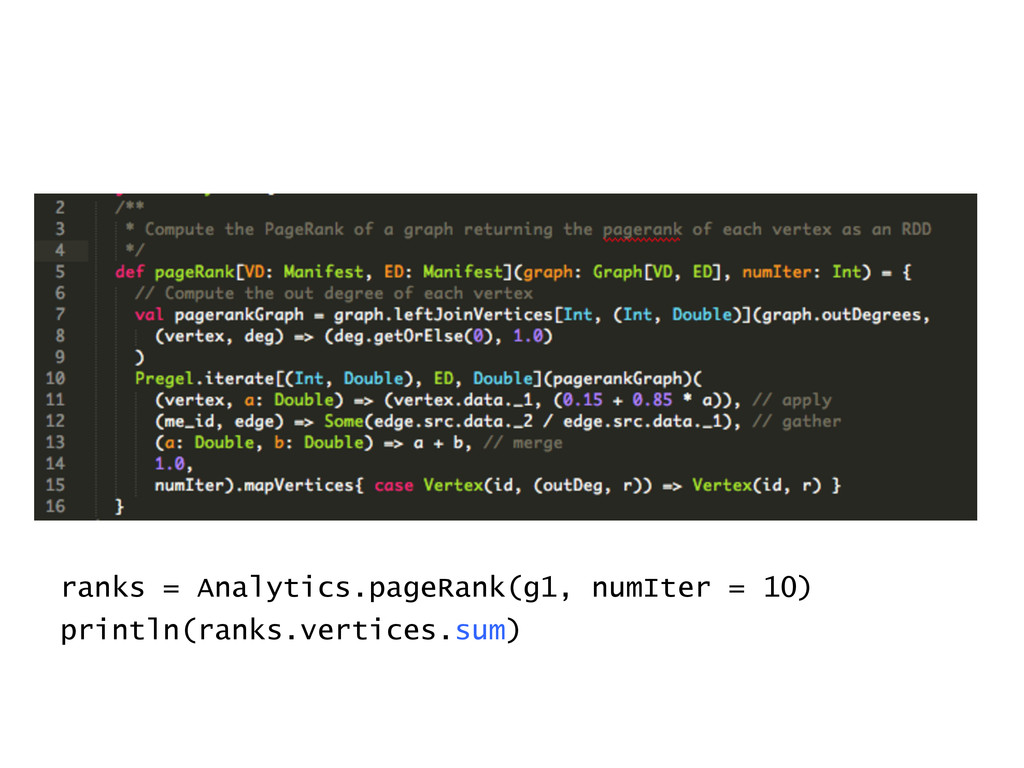
(Extract, transform, load) » Consumption of graph output » Fault-‐tolerance » Use the Scala REPL for interactive graph mining Programmability: leveraging Scala/Spark API » Implemented GraphLab / Pregel APIs in 20 loc » PageRank in 5 loc -
Resilient Distributed Graphs An extension of Spark RDDs
» Immutable, partitioned set of vertices and edges » Constructed using RDD[Edge] and RDD[Vertex] Additional set of primitives (3 functions) for graph computations » Able to express most graph algorithms (PageRank, Shortest Path, Connected Components, ALS, …) » Implemented GraphLab / Pregel in 20 lines of code -
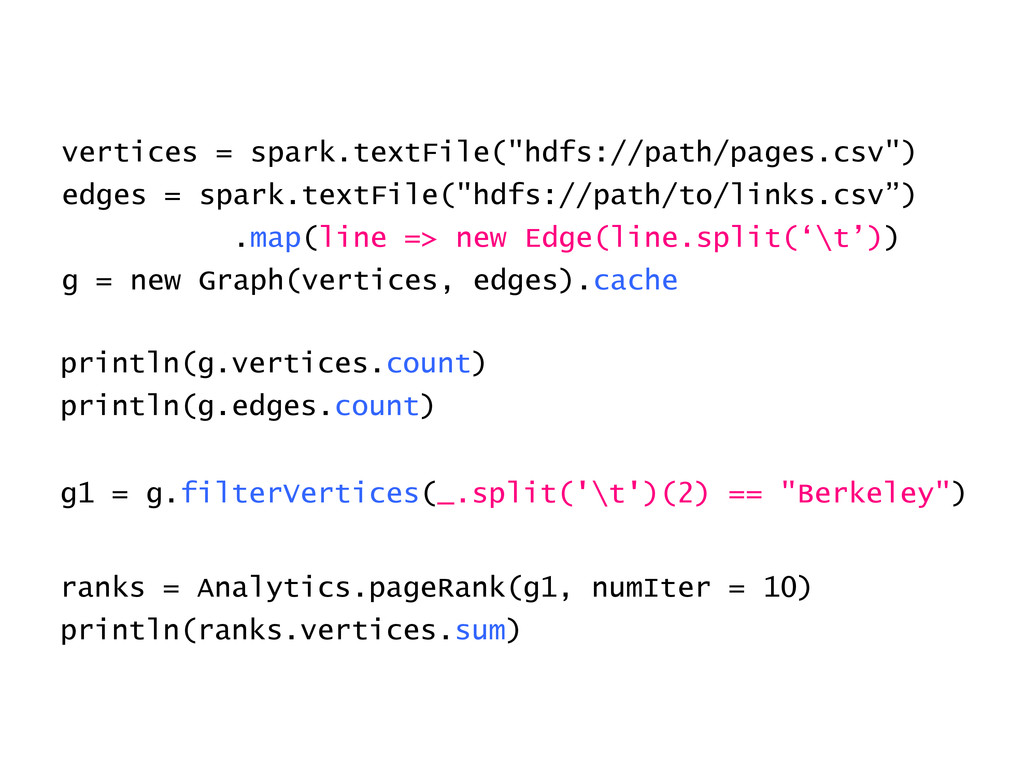
vertices = spark.textFile("hdfs://path/pages.csv") edges = spark.textFile("hdfs://path/to/links.csv”) .map(line => new Edge(line.split(‘\t’))
g = new Graph(vertices, edges).cache println(g.vertices.count) println(g.edges.count) g1 = g.filterVertices(_.split('\t')(2) == "Berkeley") ranks = Analytics.pageRank(g1, numIter = 10) println(ranks.vertices.sum) -
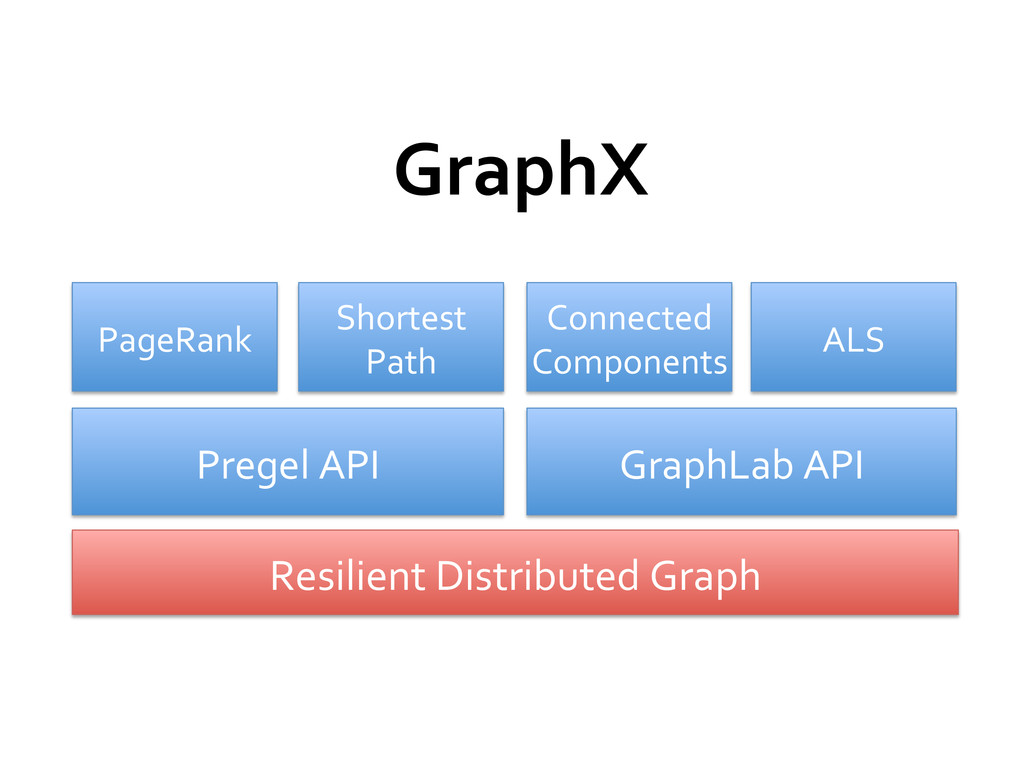
Resilient Distributed Graph Pregel API PageRank GraphLab
API Shortest Path Connected Components ALS GraphX -
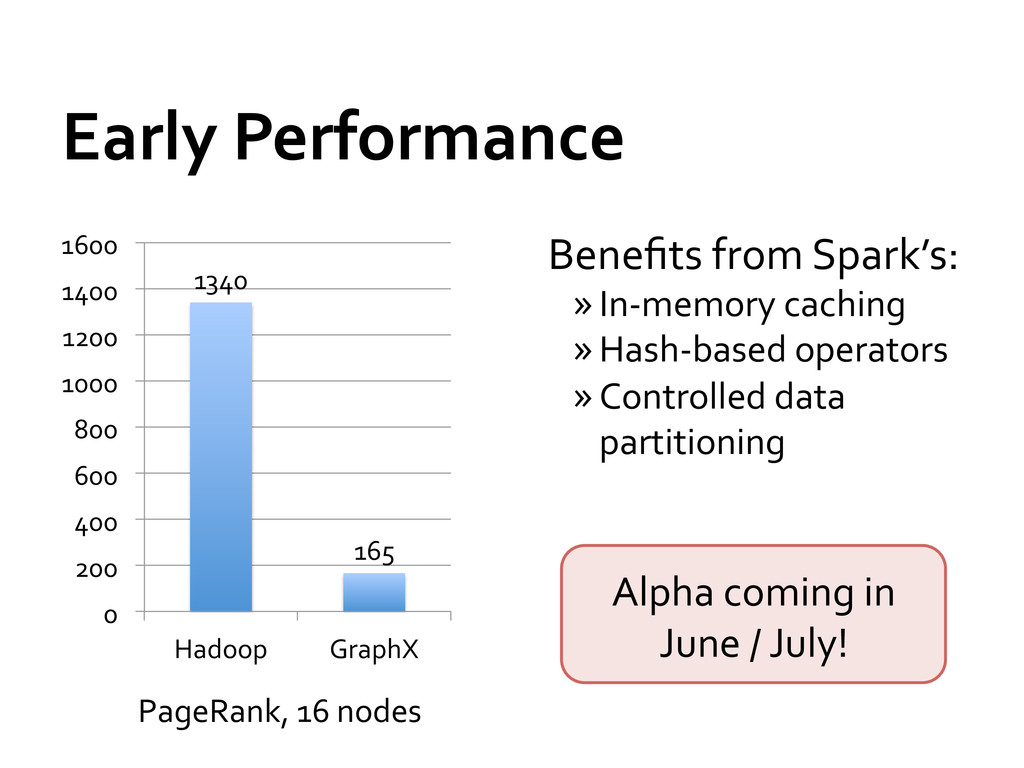
Early Performance Benefits from Spark’s: » In-‐memory caching
» Hash-‐based operators » Controlled data partitioning 1340 165 0 200 400 600 800 1000 1200 1400 1600 Hadoop GraphX PageRank, 16 nodes Alpha coming in June / July! -
This Talk Spark introduction & use cases GraphX:
graph computation Shark: SQL over Spark -
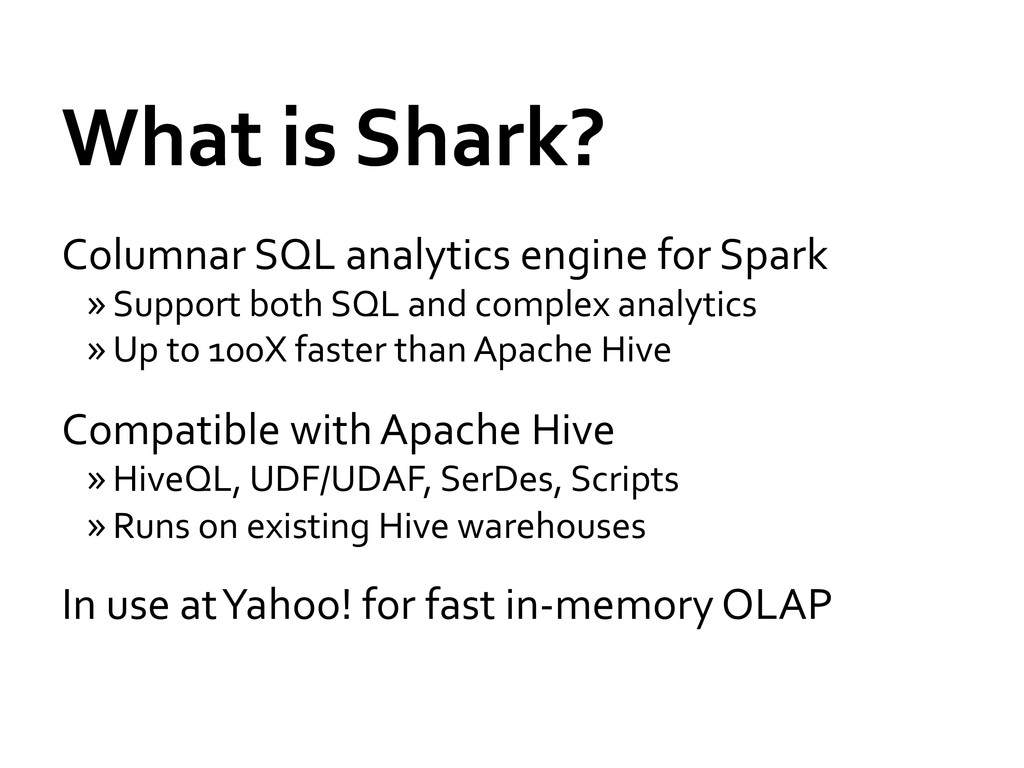
What is Shark? Columnar SQL analytics engine for Spark
» Support both SQL and complex analytics » Up to 100X faster than Apache Hive Compatible with Apache Hive » HiveQL, UDF/UDAF, SerDes, Scripts » Runs on existing Hive warehouses In use at Yahoo! for fast in-‐memory OLAP -
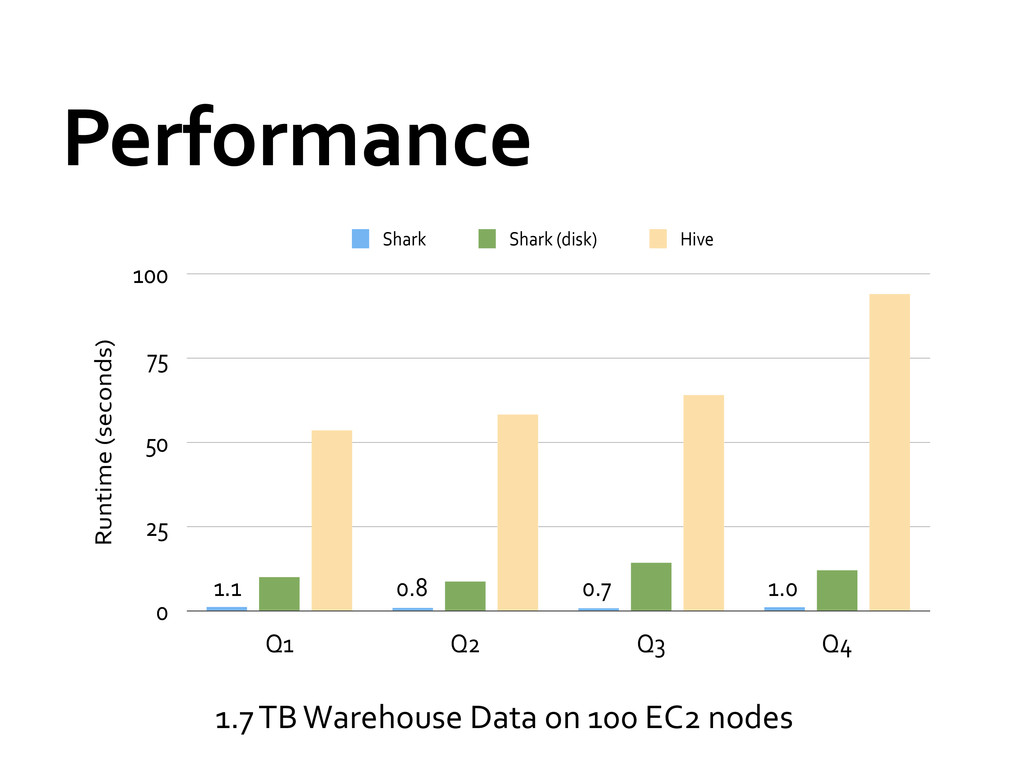
Performance 0 25 50 75 100 Q1 Q2 Q3
Q4 Runtime0(seconds) Shark Shark0(disk) Hive 1.1 0.8 0.7 1.0 1.7 TB Warehouse Data on 100 EC2 nodes -
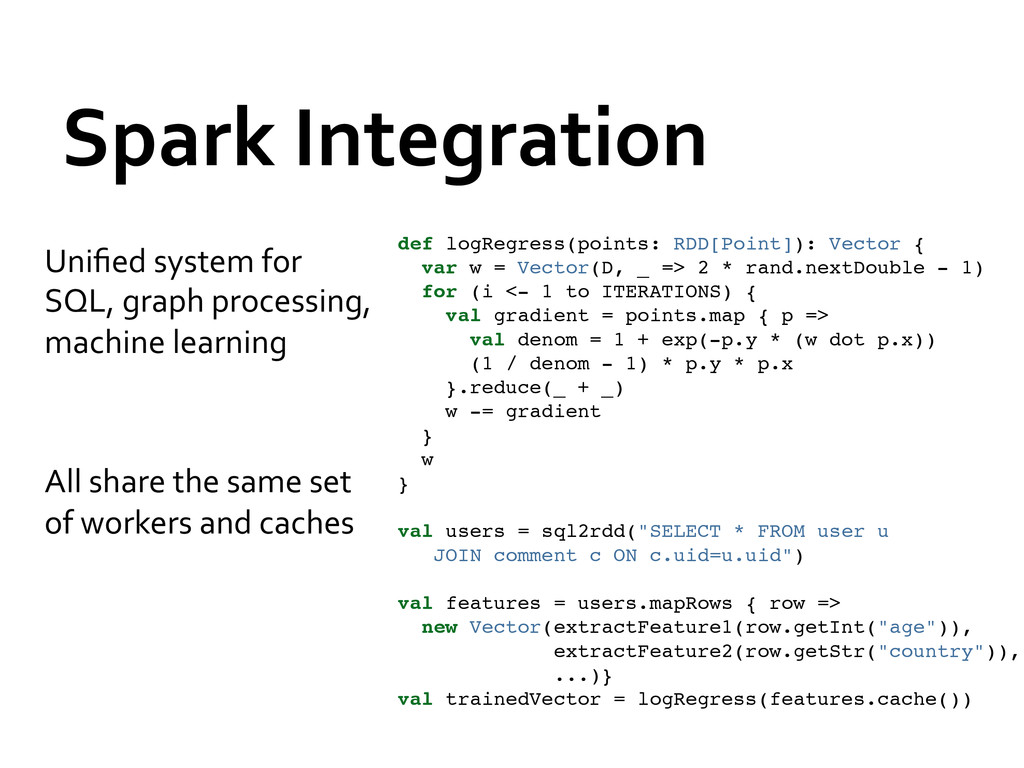
Spark Integration Unified system for SQL, graph processing,
machine learning All share the same set of workers and caches def logRegress(points: RDD[Point]): Vector { var w = Vector(D, _ => 2 * rand.nextDouble - 1) for (i <- 1 to ITERATIONS) { val gradient = points.map { p => val denom = 1 + exp(-p.y * (w dot p.x)) (1 / denom - 1) * p.y * p.x }.reduce(_ + _) w -= gradient } w } val users = sql2rdd("SELECT * FROM user u JOIN comment c ON c.uid=u.uid") val features = users.mapRows { row => new Vector(extractFeature1(row.getInt("age")), extractFeature2(row.getStr("country")), ...)} val trainedVector = logRegress(features.cache()) -
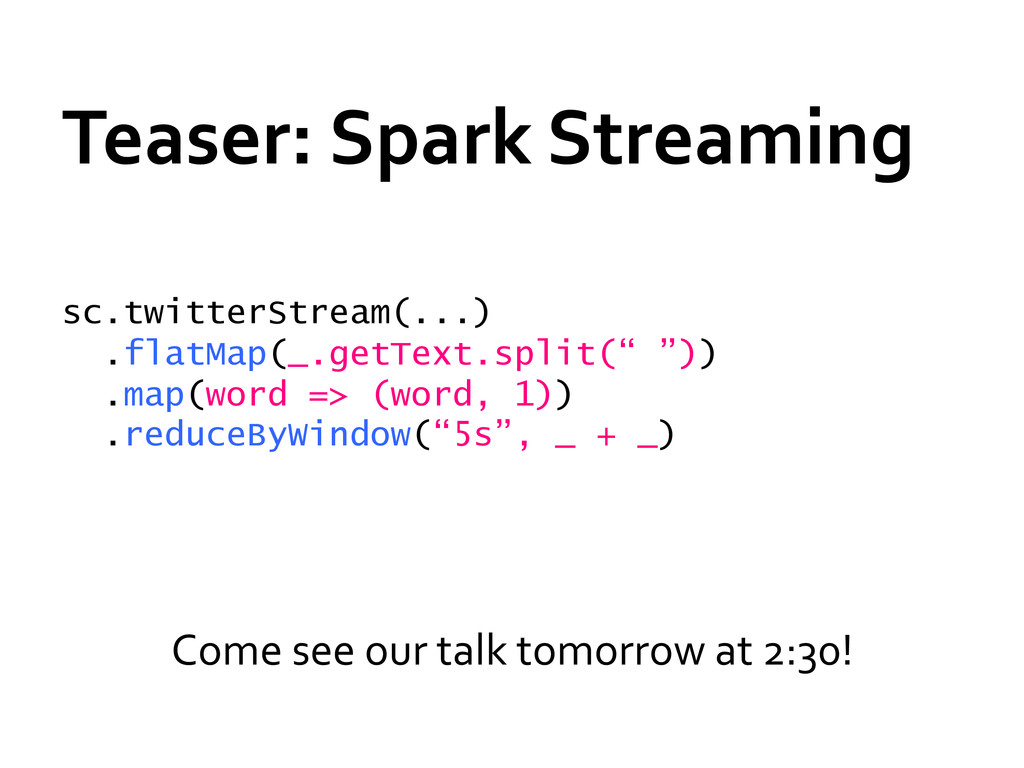
Teaser: Spark Streaming sc.twitterStream(...) .flatMap(_.getText.split(“ ”)) .map(word => (word,
1)) .reduceByWindow(“5s”, _ + _) Come see our talk tomorrow at 2:30! -
Getting Started Visit www.spark-‐project.org for » Video tutorials
» Online exercises (EC2) » Docs and API guides Easy to run in local mode, standalone clusters, Apache Mesos, YARN or EC2 Training camp at Berkeley in August -
Conclusion Big data analytics is evolving to include:
» More complex analytics (e.g. machine learning) » More interactive ad-‐hoc queries » More real-‐time stream processing Spark is a fast, unified platform for these apps Look for our training camp at Berkeley this August! spark-‐project.org -
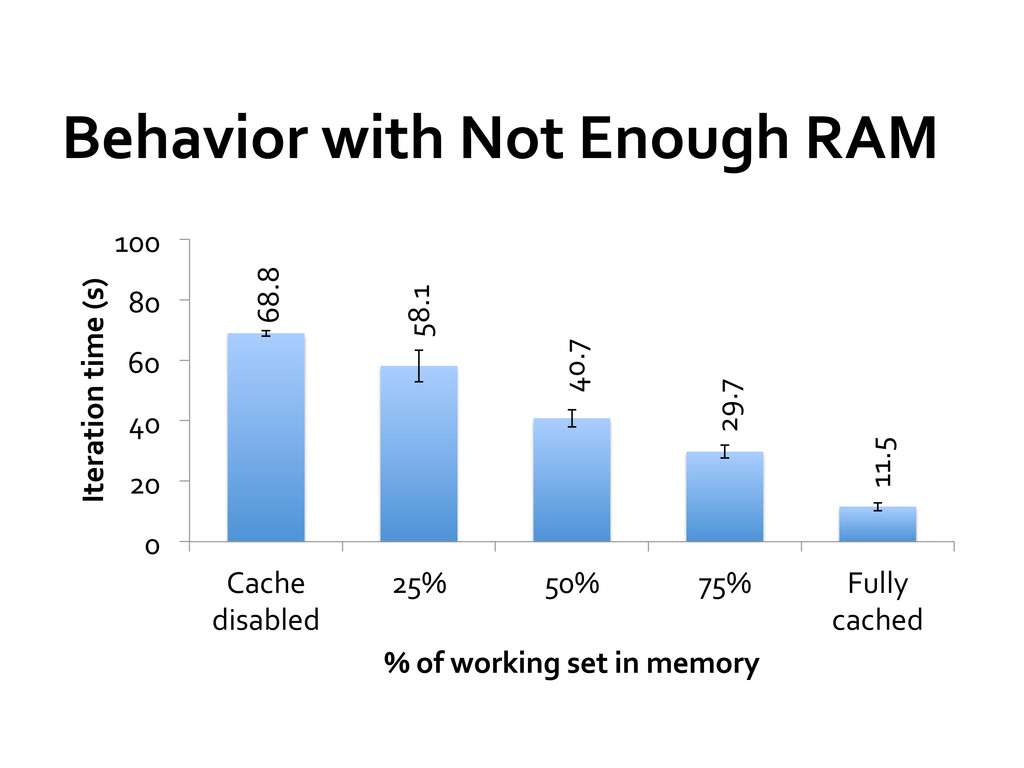
Behavior with Not Enough RAM 68.8 58.1
40.7 29.7 11.5 0 20 40 60 80 100 Cache disabled 25% 50% 75% Fully cached Iteration time (s) % of working set in memory -
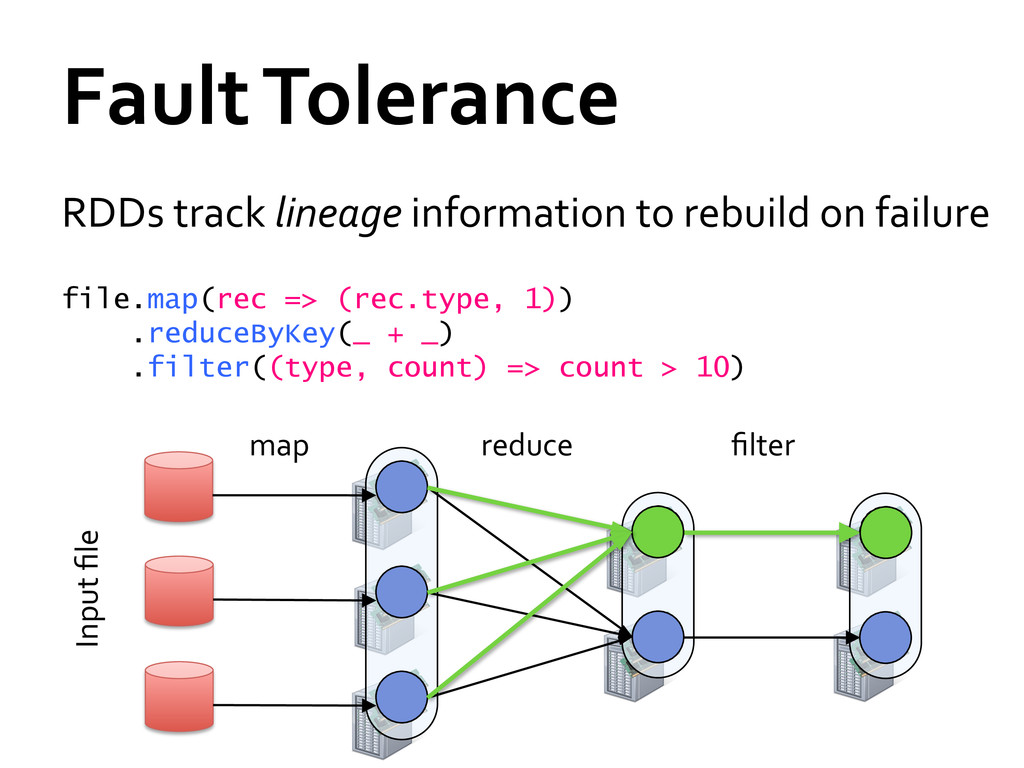
Fault Tolerance file.map(rec => (rec.type, 1)) .reduceByKey(_ + _)
.filter((type, count) => count > 10) filter reduce map Input file RDDs track lineage information to rebuild on failure -
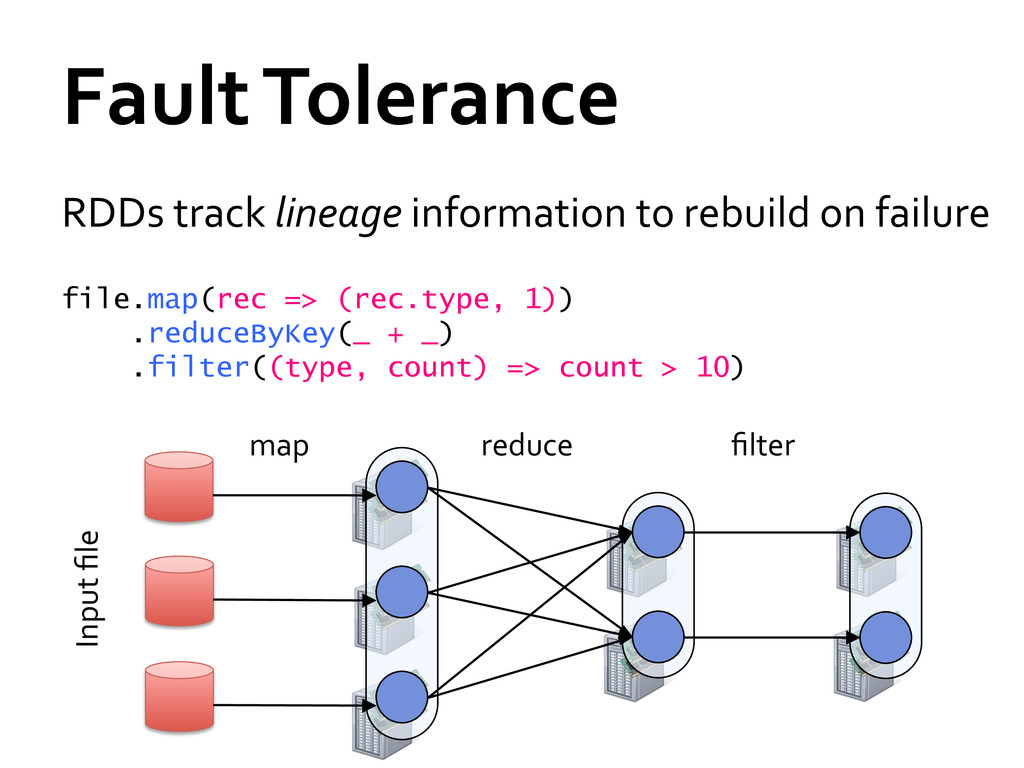
filter reduce map Input file Fault
Tolerance file.map(rec => (rec.type, 1)) .reduceByKey(_ + _) .filter((type, count) => count > 10) RDDs track lineage information to rebuild on failure