Share
Embed
Apache Spark: Easier and Faster Big Data
@ The Hive Big Data Think Tank meetup event
http://www.meetup.com/SF-Bay-Areas-Big-Data-Think-Tank/events/171098212/

Reynold Xin
April 09, 2014
Transcript
75 slides
-
Apache Spark: Easier and Faster Big Data Apr 9, 2014
@ The Hive Meetup! ! Patrick Wendell, Reynold Xin! -
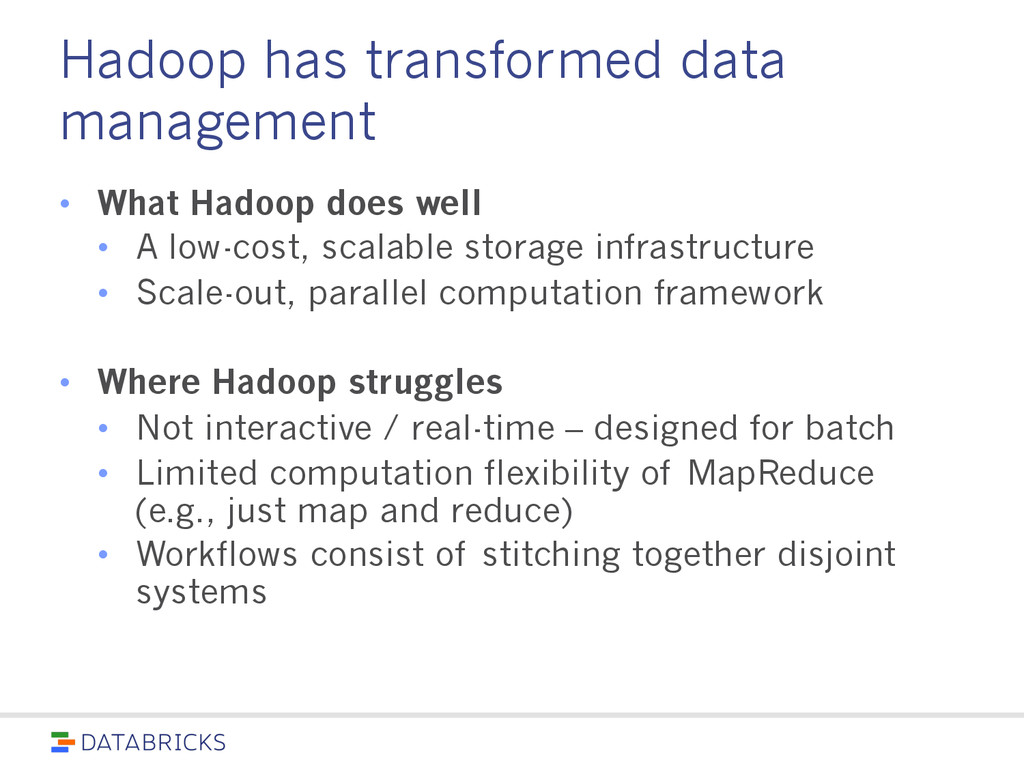
Hadoop has transformed data management • What Hadoop does well
• A low-cost, scalable storage infrastructure • Scale-out, parallel computation framework • Where Hadoop struggles • Not interactive / real-time – designed for batch • Limited computation flexibility of MapReduce (e.g., just map and reduce) • Workflows consist of stitching together disjoint systems -
Apace Spark A cluster compute engine that can handle a
wide range of workloads: ETL, SQL-like queries, machine learning, streaming etc. -
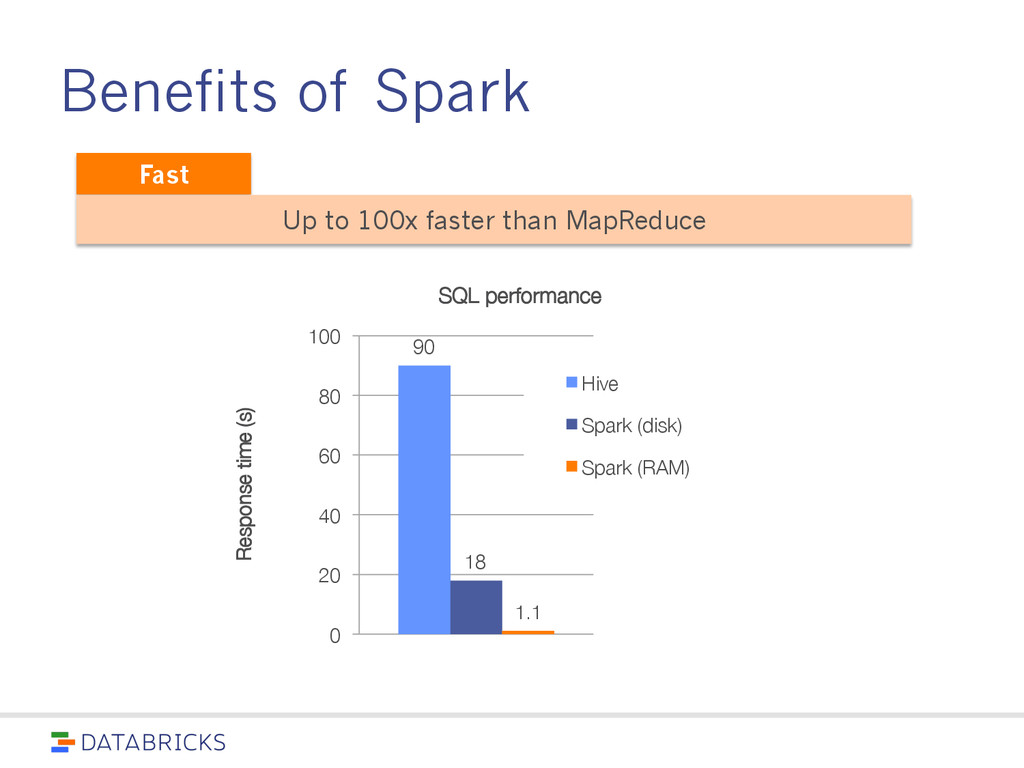
Fast Benefits of Spark 90 18 1.1 0 20 40
60 80 100 Hive Spark (disk) Spark (RAM) SQL performance Response time (s) Up to 100x faster than MapReduce -
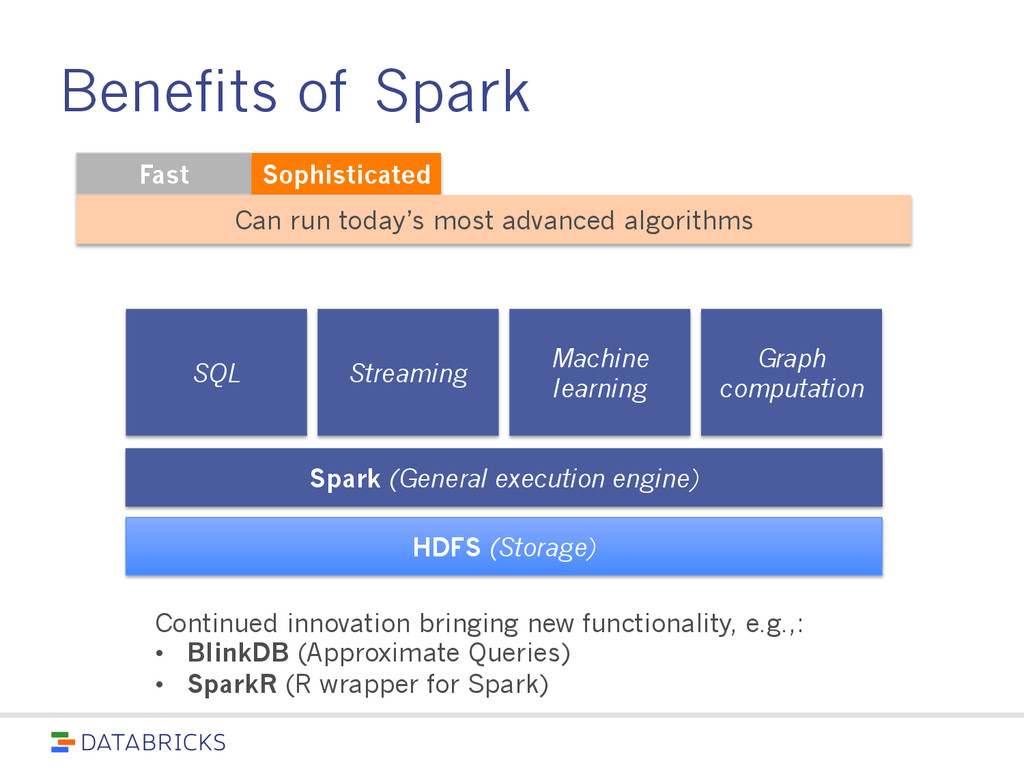
Fast Benefits of Spark Sophisticated HDFS (Storage) SQL Streaming Machine
learning Spark (General execution engine) Graph computation Continued innovation bringing new functionality, e.g.,: • BlinkDB (Approximate Queries) • SparkR (R wrapper for Spark) Can run today’s most advanced algorithms -
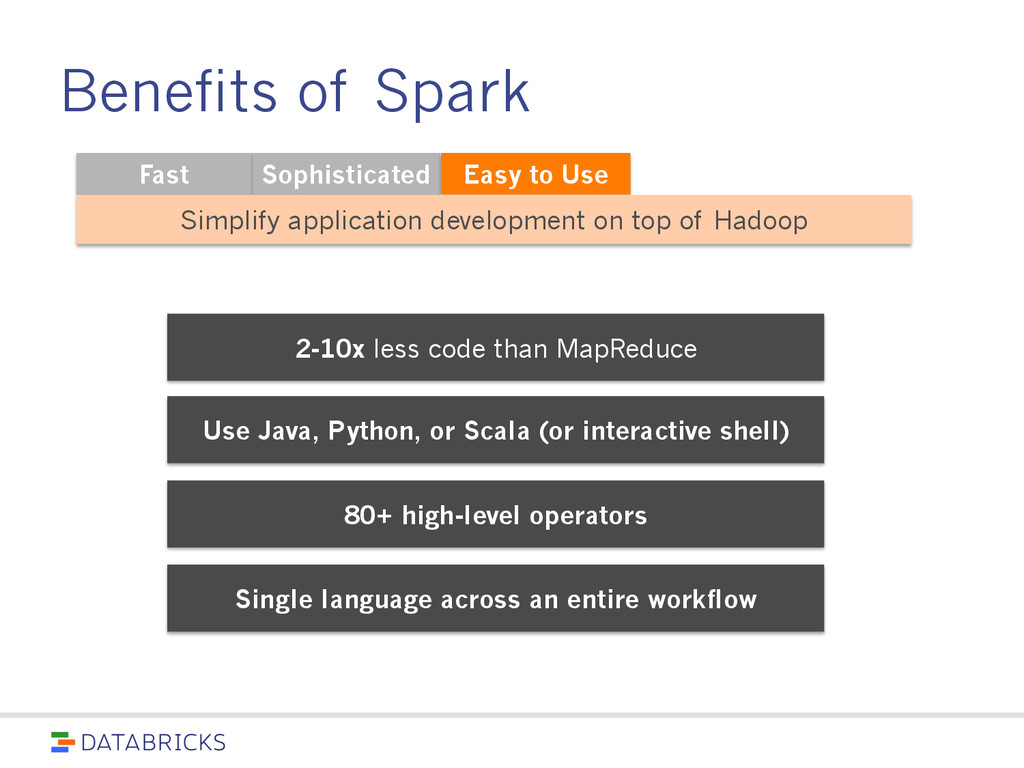
Sophisticated Fast Benefits of Spark Easy to Use 2-10x less
code than MapReduce Use Java, Python, or Scala (or interactive shell) 80+ high-level operators Single language across an entire workflow Simplify application development on top of Hadoop -
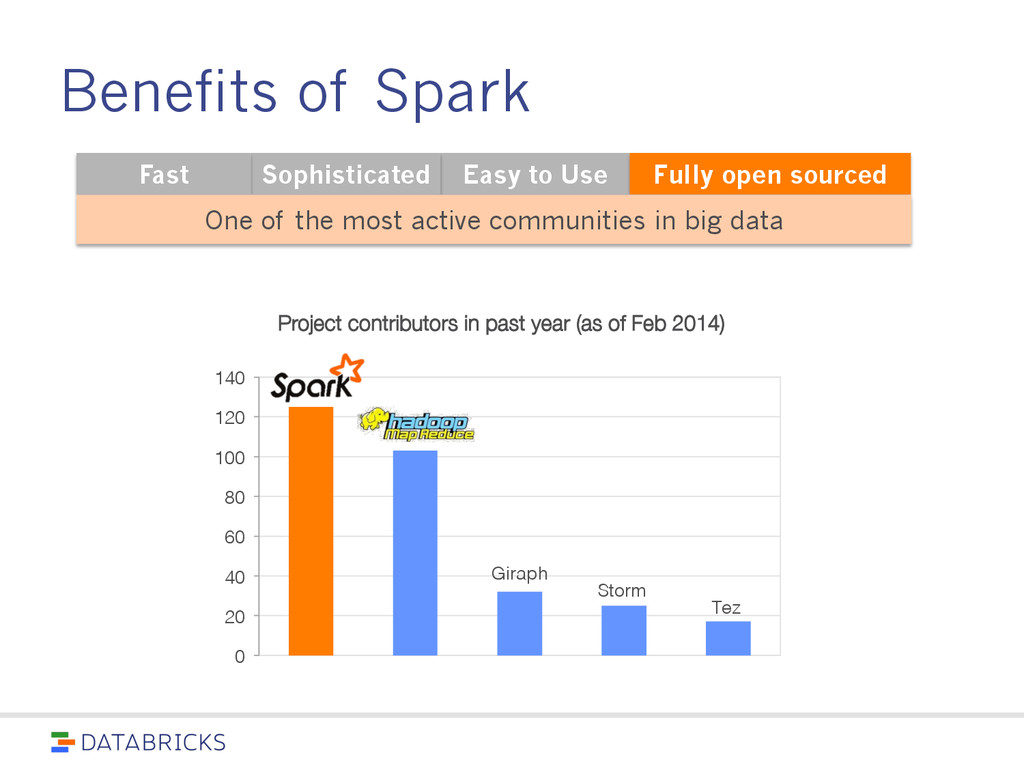
Easy to Use Sophisticated Fast Benefits of Spark Fully open
sourced One of the most active communities in big data Giraph! Storm! Tez! 0! 20! 40! 60! 80! 100! 120! 140! Project contributors in past year (as of Feb 2014) -
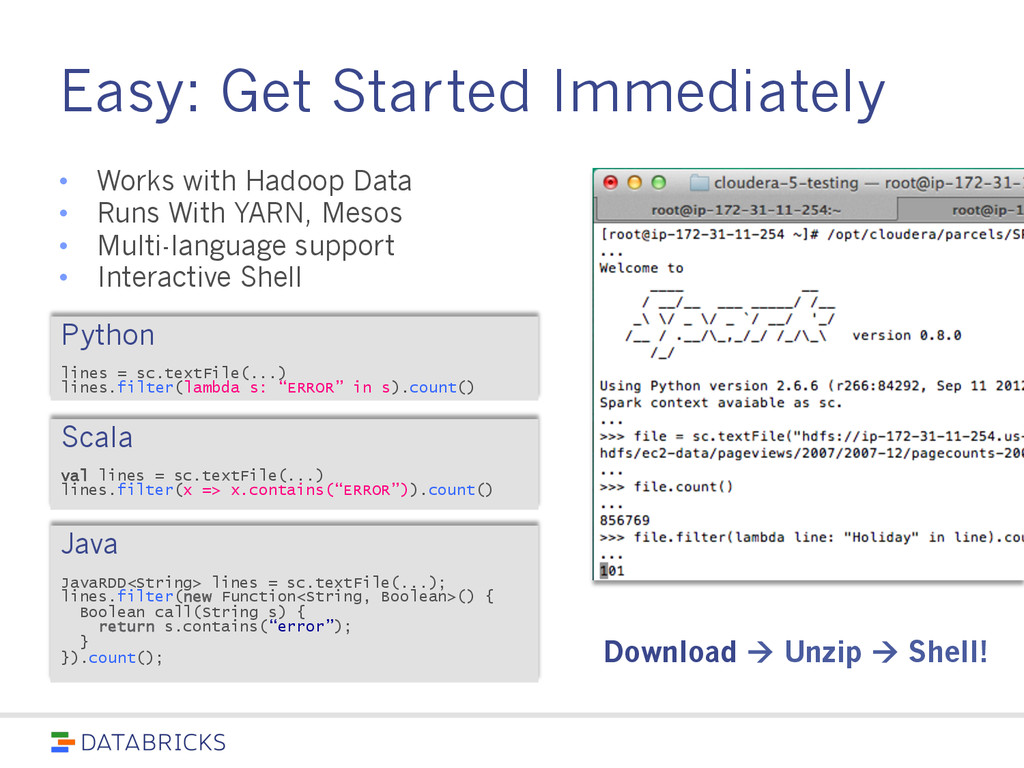
Easy: Get Started Immediately • Works with Hadoop Data •
Runs With YARN, Mesos • Multi-language support • Interactive Shell Python lines = sc.textFile(...) lines.filter(lambda s: “ERROR” in s).count() Scala val lines = sc.textFile(...) lines.filter(x => x.contains(“ERROR”)).count() Java JavaRDD<String> lines = sc.textFile(...); lines.filter(new Function<String, Boolean>() { Boolean call(String s) { return s.contains(“error”); } }).count(); Download ! Unzip ! Shell! -
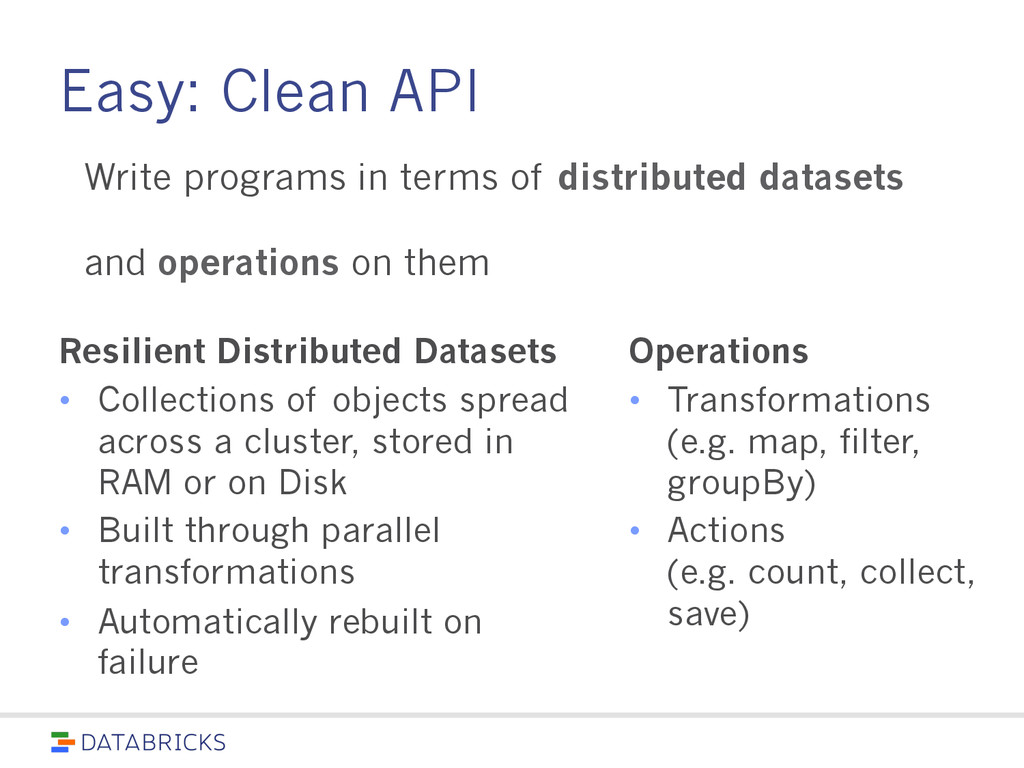
Easy: Clean API Resilient Distributed Datasets • Collections of objects
spread across a cluster, stored in RAM or on Disk • Built through parallel transformations • Automatically rebuilt on failure Operations • Transformations (e.g. map, filter, groupBy) • Actions (e.g. count, collect, save) Write programs in terms of distributed datasets and operations on them -
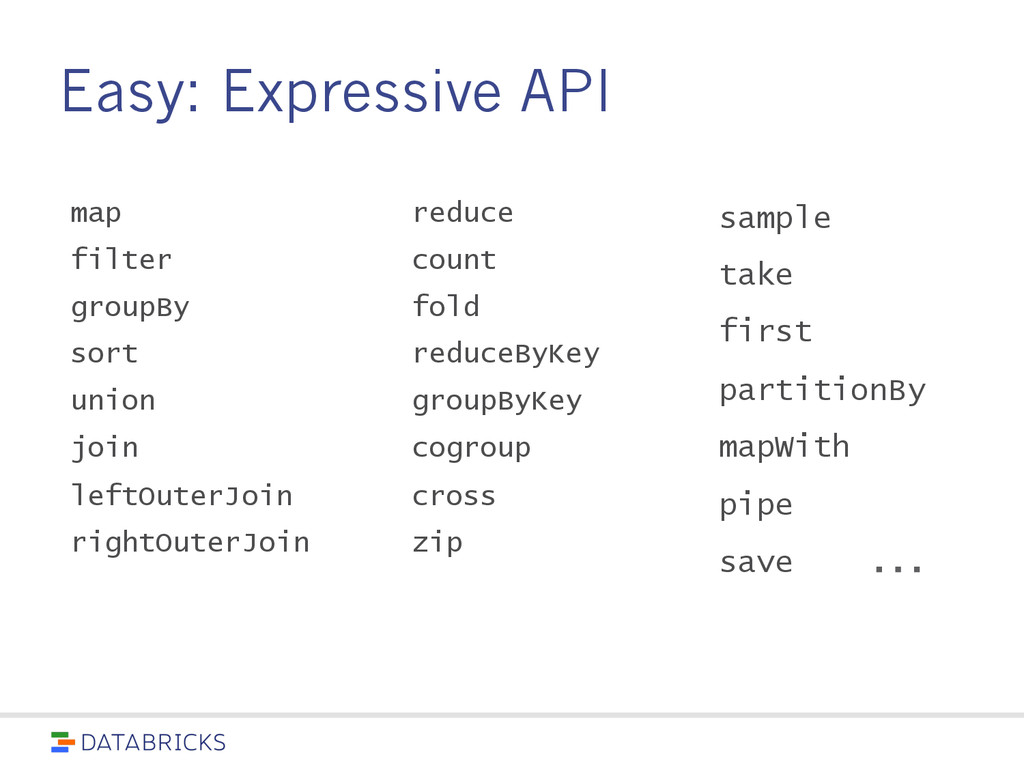
Easy: Expressive API map filter groupBy sort union join leftOuterJoin
rightOuterJoin reduce count fold reduceByKey groupByKey cogroup cross zip sample take first partitionBy mapWith pipe save ... -
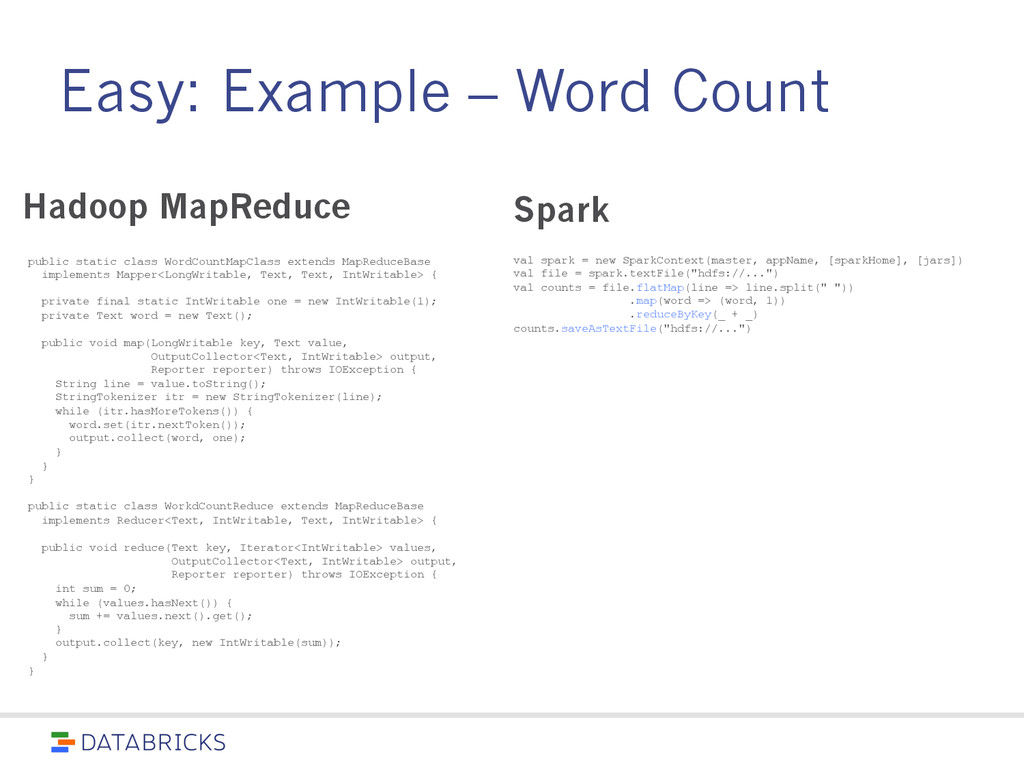
Easy: Example – Word Count Spark public static class WordCountMapClass
extends MapReduceBase implements Mapper<LongWritable, Text, Text, IntWritable> { private final static IntWritable one = new IntWritable(1); private Text word = new Text(); public void map(LongWritable key, Text value, OutputCollector<Text, IntWritable> output, Reporter reporter) throws IOException { String line = value.toString(); StringTokenizer itr = new StringTokenizer(line); while (itr.hasMoreTokens()) { word.set(itr.nextToken()); output.collect(word, one); } } } public static class WorkdCountReduce extends MapReduceBase implements Reducer<Text, IntWritable, Text, IntWritable> { public void reduce(Text key, Iterator<IntWritable> values, OutputCollector<Text, IntWritable> output, Reporter reporter) throws IOException { int sum = 0; while (values.hasNext()) { sum += values.next().get(); } output.collect(key, new IntWritable(sum)); } } Hadoop MapReduce val spark = new SparkContext(master, appName, [sparkHome], [jars]) val file = spark.textFile("hdfs://...") val counts = file.flatMap(line => line.split(" ")) .map(word => (word, 1)) .reduceByKey(_ + _) counts.saveAsTextFile("hdfs://...") -
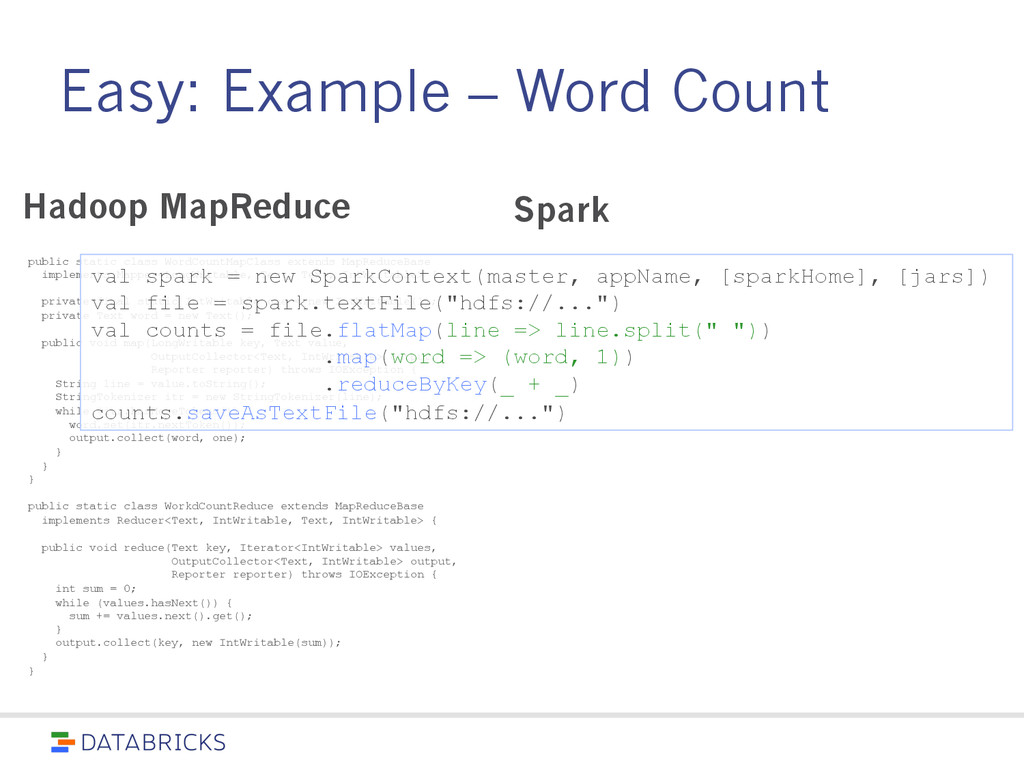
Easy: Example – Word Count Spark public static class WordCountMapClass
extends MapReduceBase implements Mapper<LongWritable, Text, Text, IntWritable> { private final static IntWritable one = new IntWritable(1); private Text word = new Text(); public void map(LongWritable key, Text value, OutputCollector<Text, IntWritable> output, Reporter reporter) throws IOException { String line = value.toString(); StringTokenizer itr = new StringTokenizer(line); while (itr.hasMoreTokens()) { word.set(itr.nextToken()); output.collect(word, one); } } } public static class WorkdCountReduce extends MapReduceBase implements Reducer<Text, IntWritable, Text, IntWritable> { public void reduce(Text key, Iterator<IntWritable> values, OutputCollector<Text, IntWritable> output, Reporter reporter) throws IOException { int sum = 0; while (values.hasNext()) { sum += values.next().get(); } output.collect(key, new IntWritable(sum)); } } Hadoop MapReduce val spark = new SparkContext(master, appName, [sparkHome], [jars]) val file = spark.textFile("hdfs://...") val counts = file.flatMap(line => line.split(" ")) .map(word => (word, 1)) .reduceByKey(_ + _) counts.saveAsTextFile("hdfs://...") -
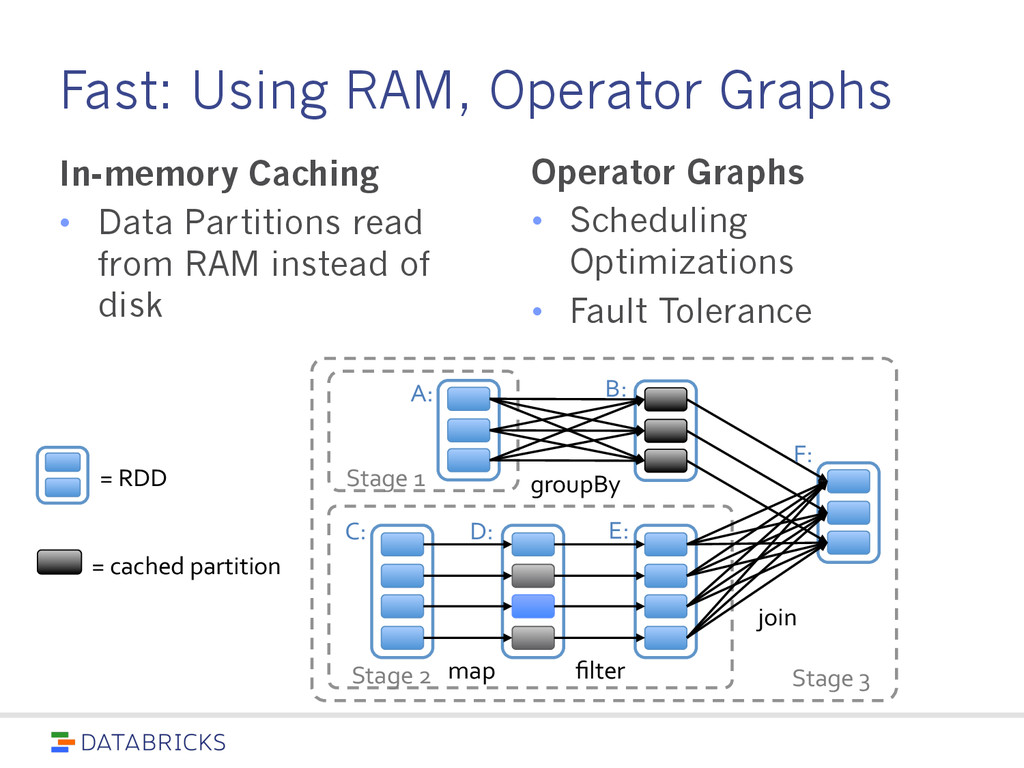
Fast: Using RAM, Operator Graphs In-memory Caching • Data Partitions
read from RAM instead of disk Operator Graphs • Scheduling Optimizations • Fault Tolerance ="cached"partition" ="RDD" join" filter" groupBy" Stage"3" Stage"1" Stage"2" A:" B:" C:" D:" E:" F:" map" -
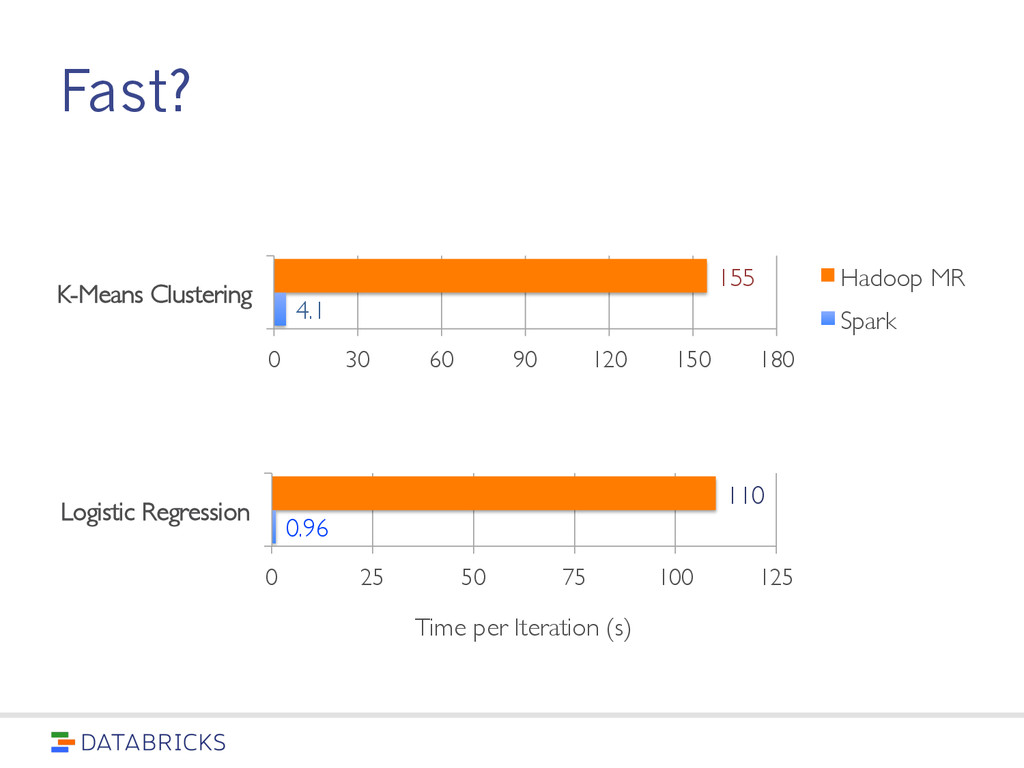
Fast? 0.96! 110! 0! 25! 50! 75! 100! 125! Logistic
Regression! 4.1! 155! 0! 30! 60! 90! 120! 150! 180! K-Means Clustering! Hadoop MR! Spark! Time per Iteration (s)! -
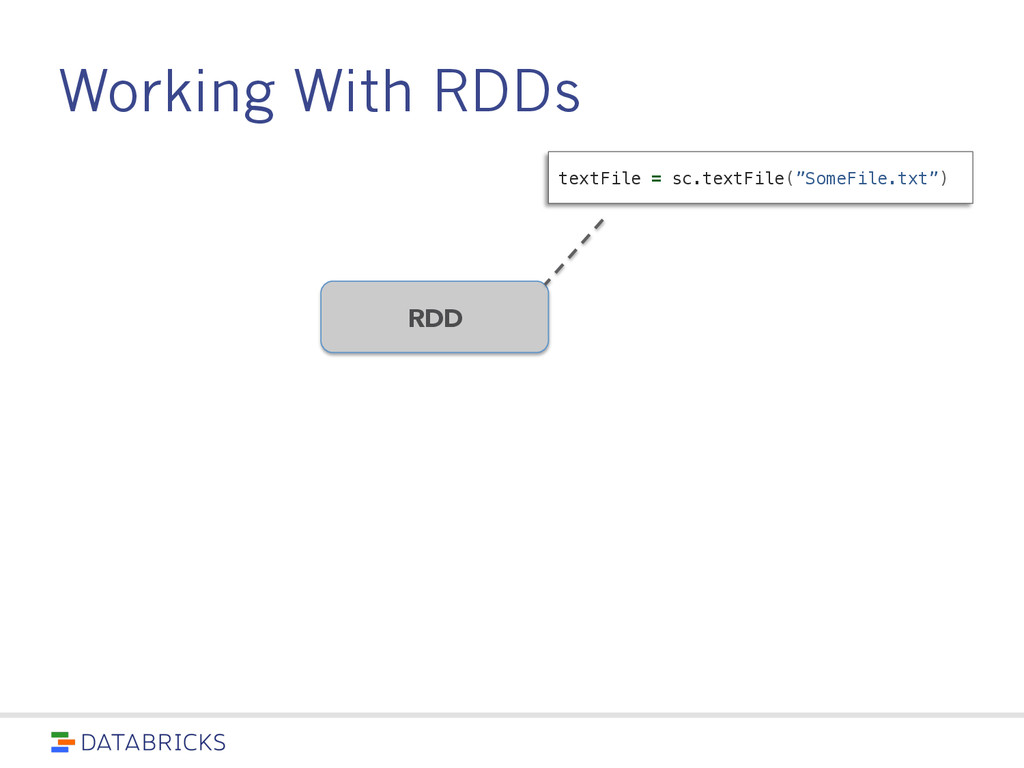
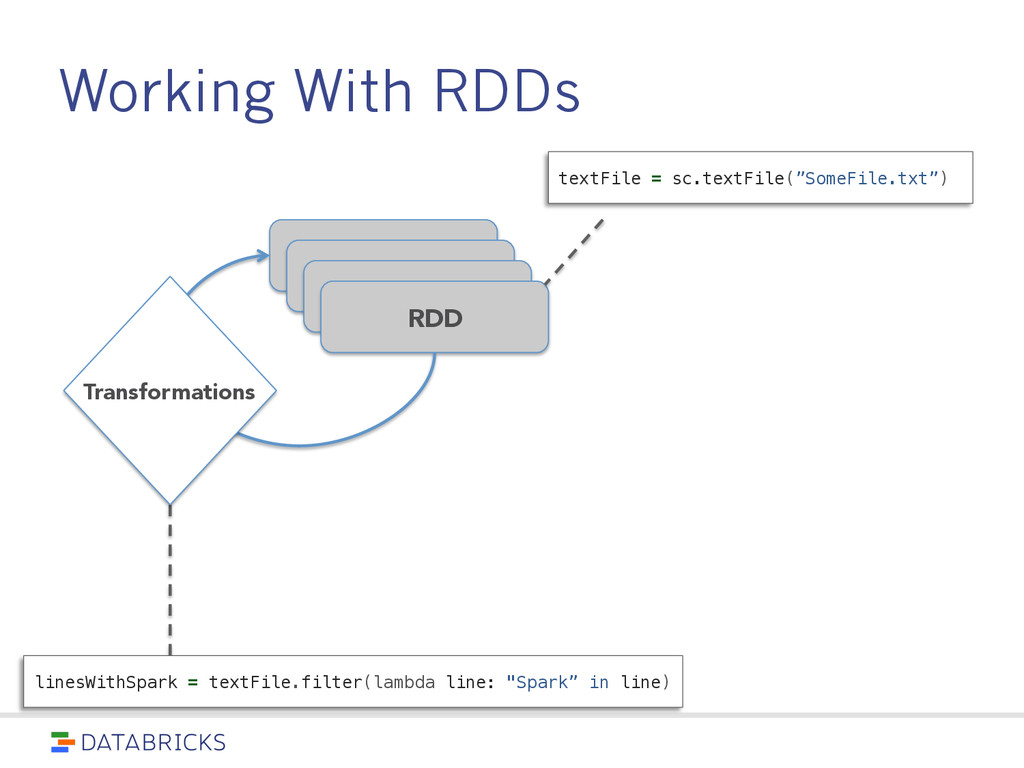
Working With RDDs RDD RDD RDD RDD Transformations linesWithSpark =
textFile.filter(lambda line: "Spark” in line)! textFile = sc.textFile(”SomeFile.txt”)! -
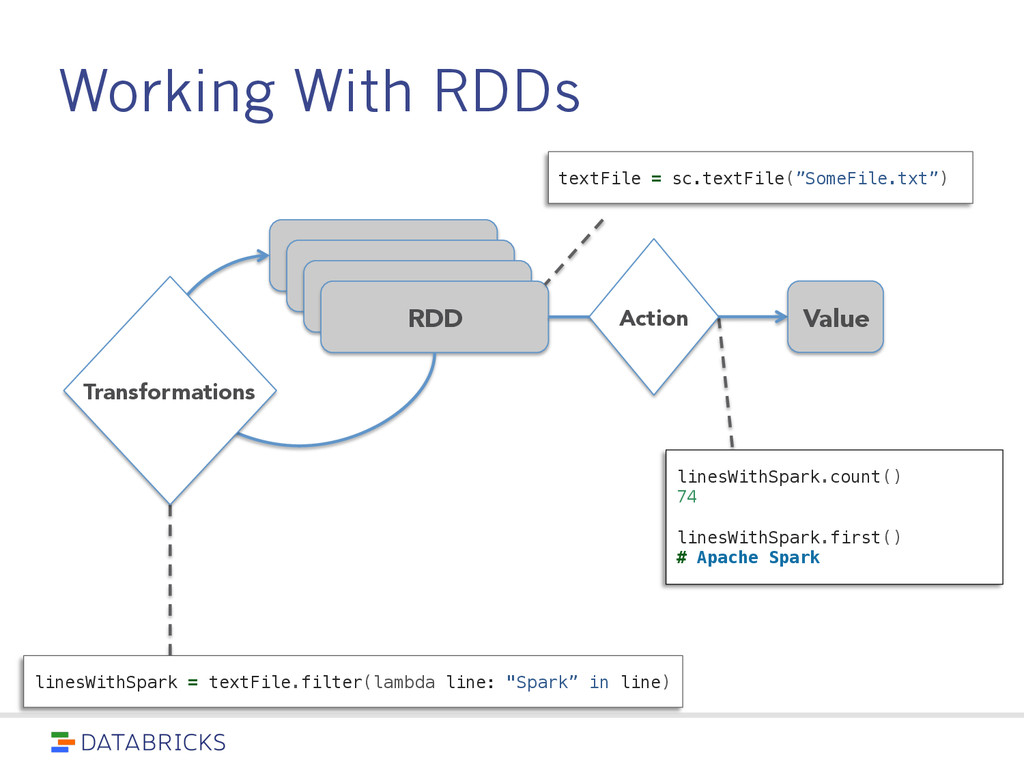
Working With RDDs RDD RDD RDD RDD Transformations Action Value
linesWithSpark = textFile.filter(lambda line: "Spark” in line)! linesWithSpark.count()! 74! ! linesWithSpark.first()! # Apache Spark! textFile = sc.textFile(”SomeFile.txt”)! -
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns -
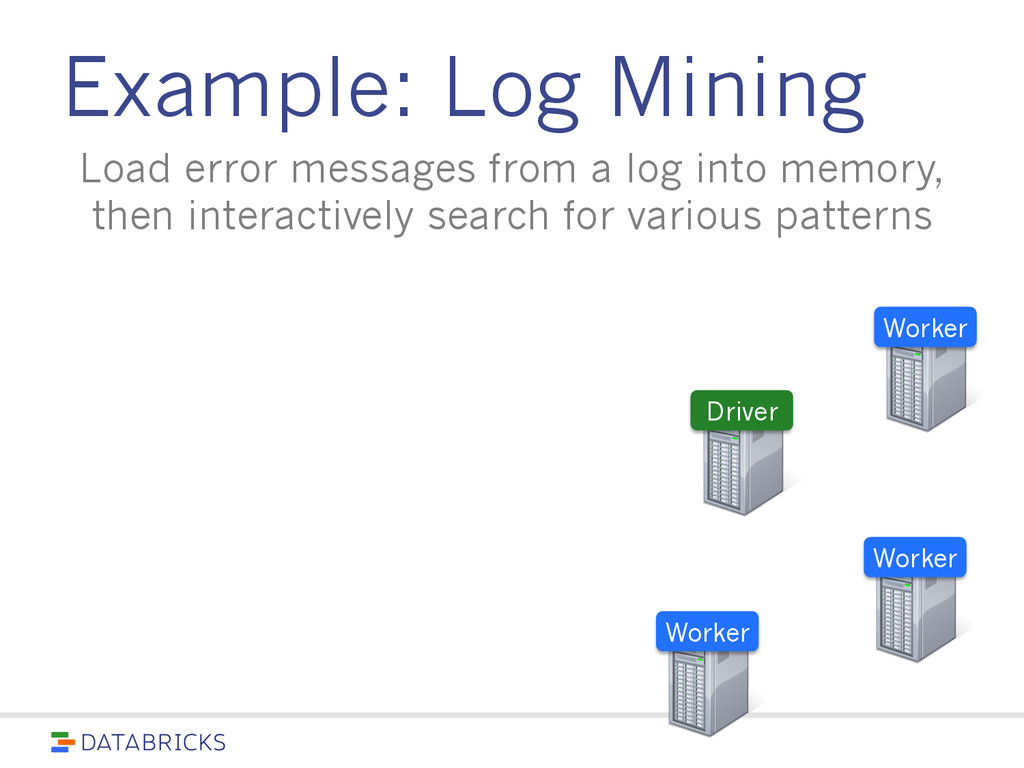
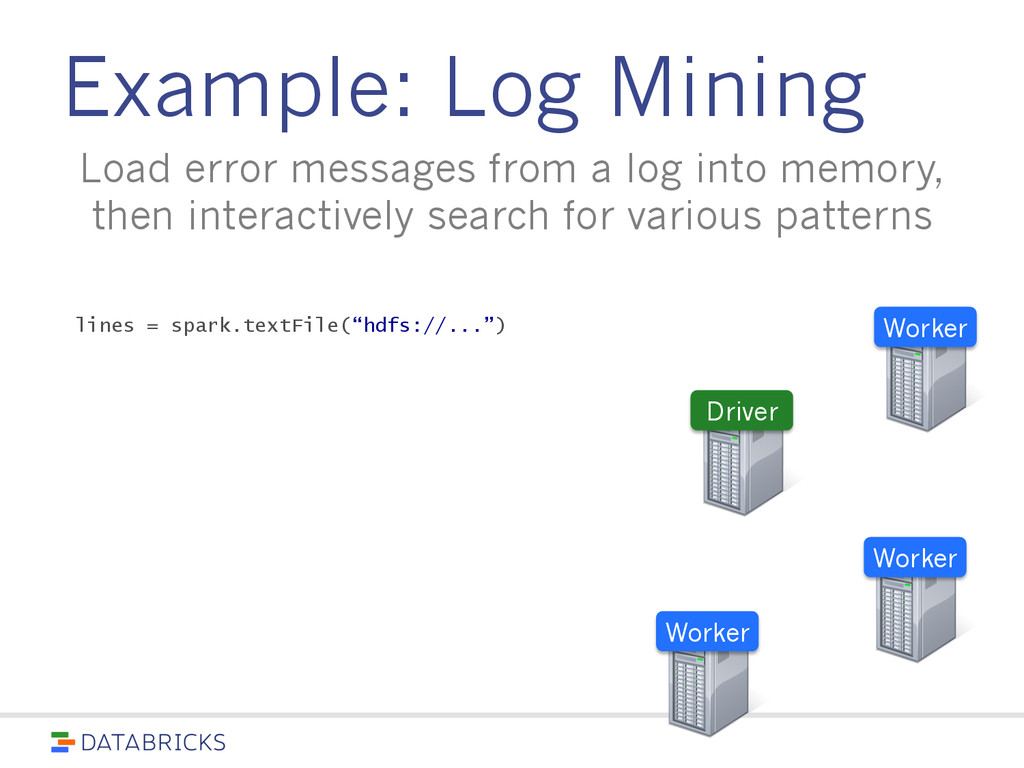
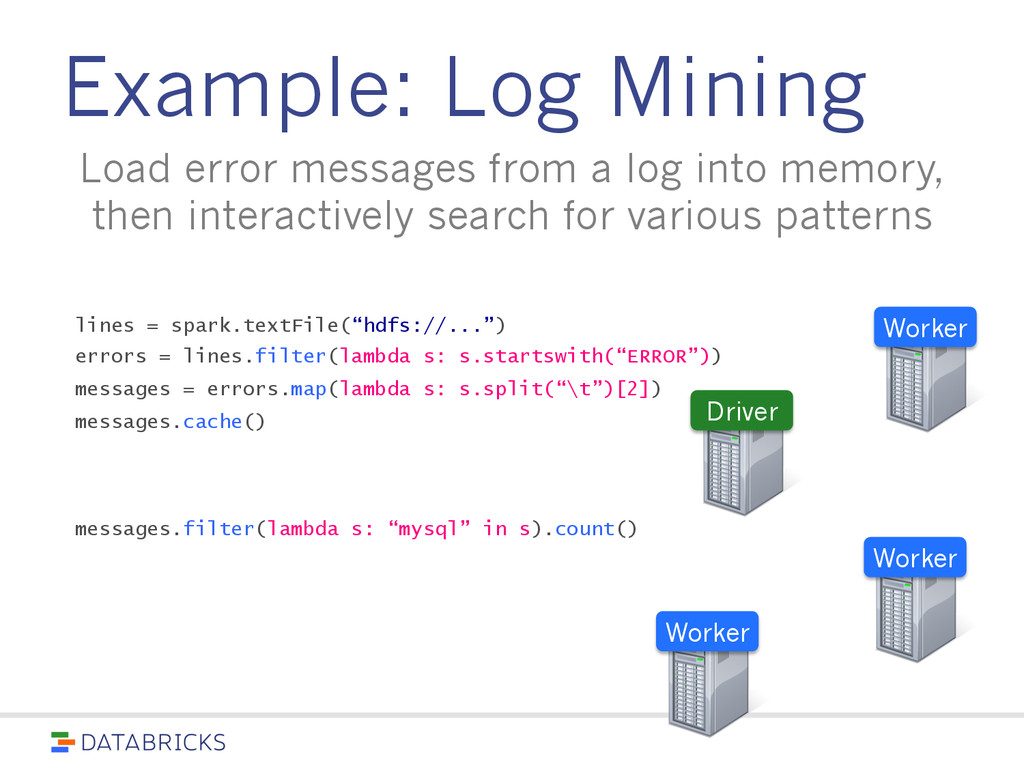
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns Worker Worker Worker Driver -
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns Worker Worker Worker Driver lines = spark.textFile(“hdfs://...”) -
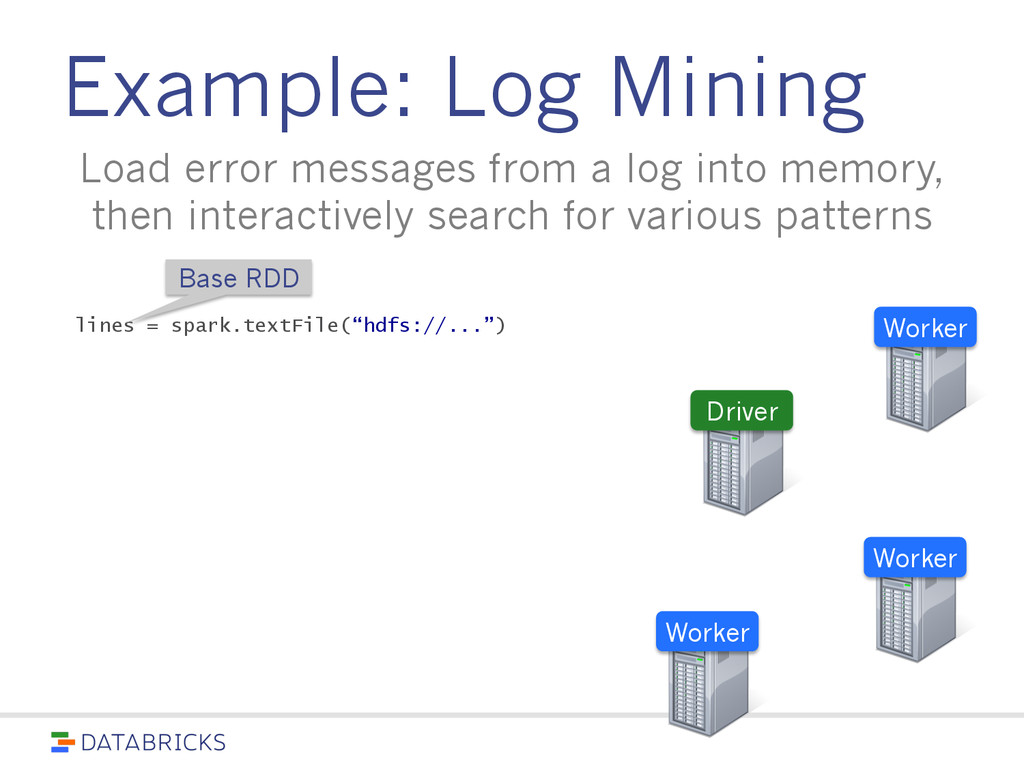
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns Worker Worker Worker Driver lines = spark.textFile(“hdfs://...”) Base RDD -
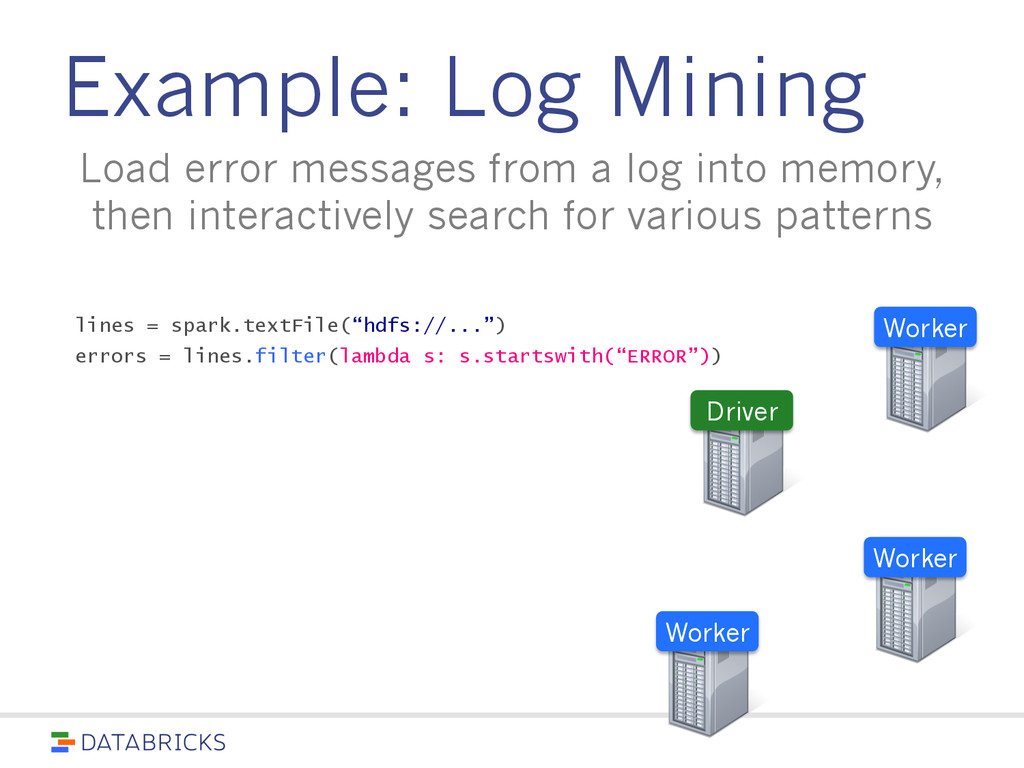
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) Worker Worker Worker Driver -
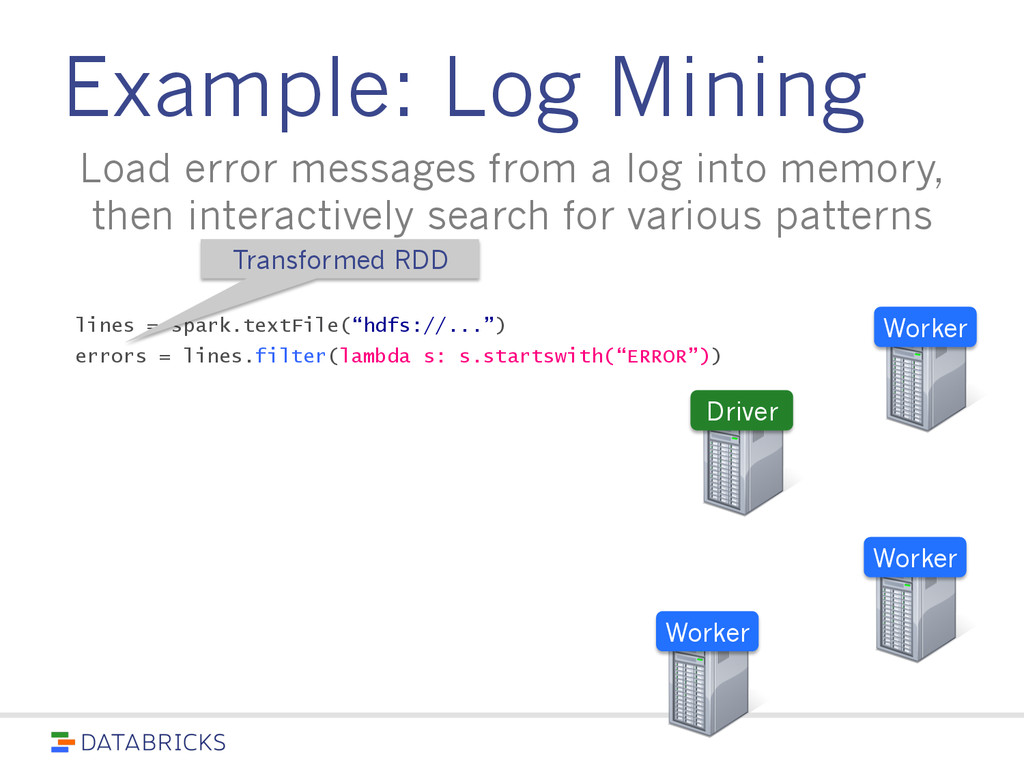
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) Worker Worker Worker Driver Transformed RDD -
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) messages = errors.map(lambda s: s.split(“\t”)[2]) messages.cache() Worker Worker Worker Driver messages.filter(lambda s: “mysql” in s).count() -
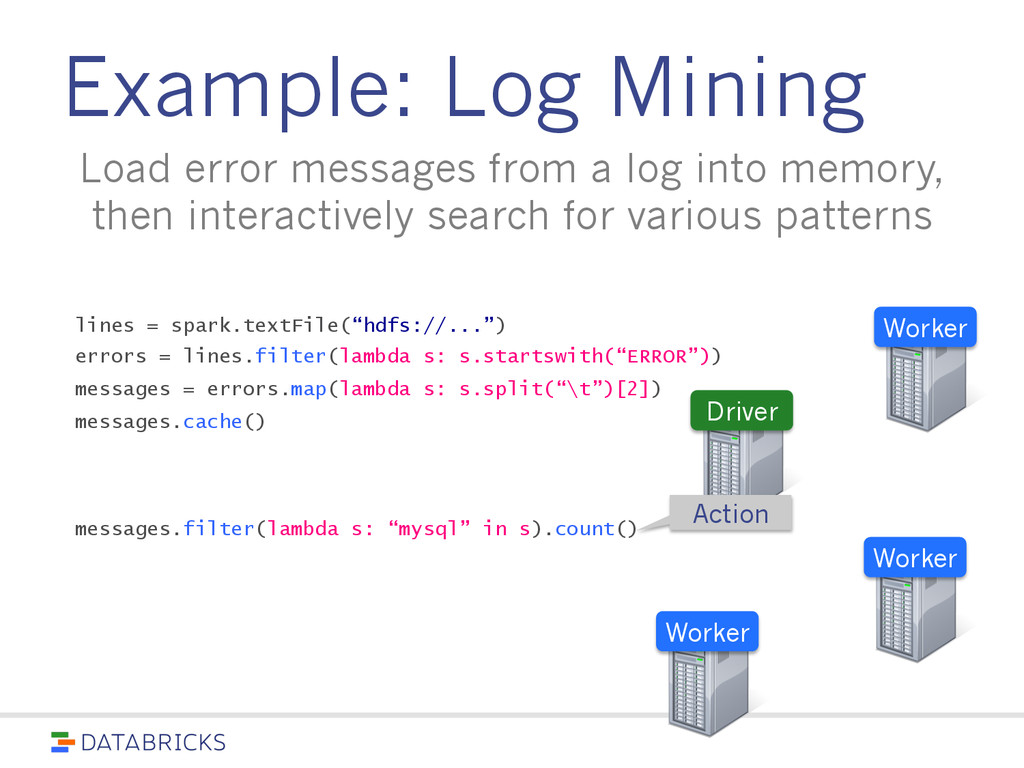
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) messages = errors.map(lambda s: s.split(“\t”)[2]) messages.cache() Worker Worker Worker Driver messages.filter(lambda s: “mysql” in s).count() Action -
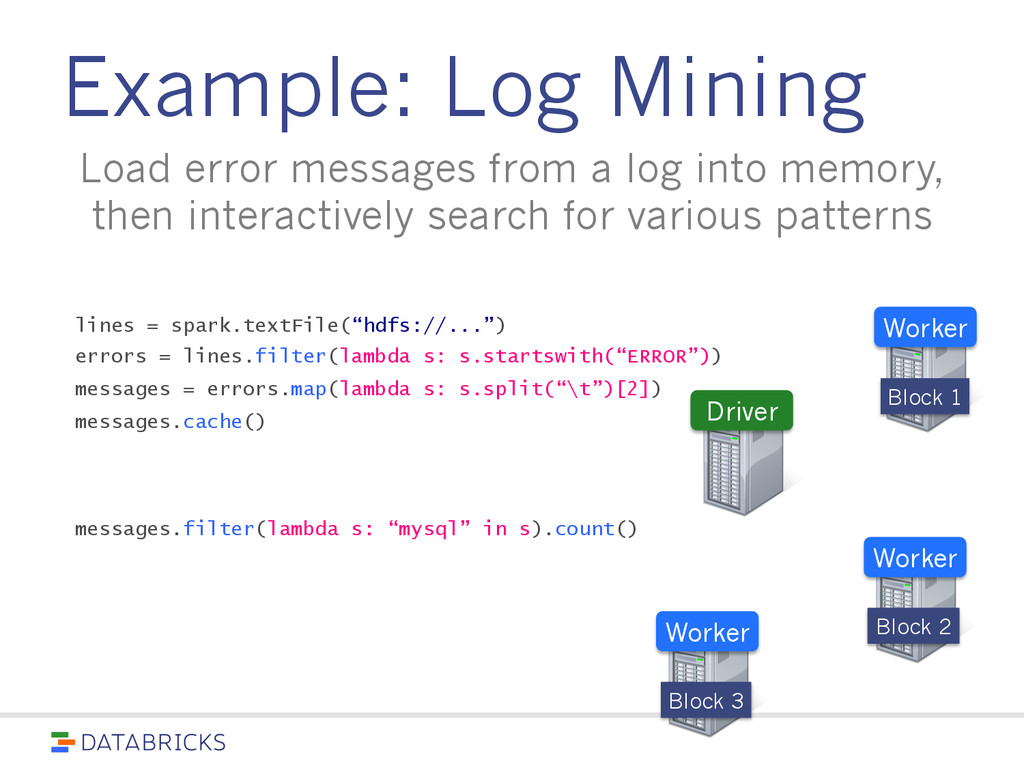
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) messages = errors.map(lambda s: s.split(“\t”)[2]) messages.cache() Worker Worker Worker Driver messages.filter(lambda s: “mysql” in s).count() Block 1 Block 2 Block 3 -
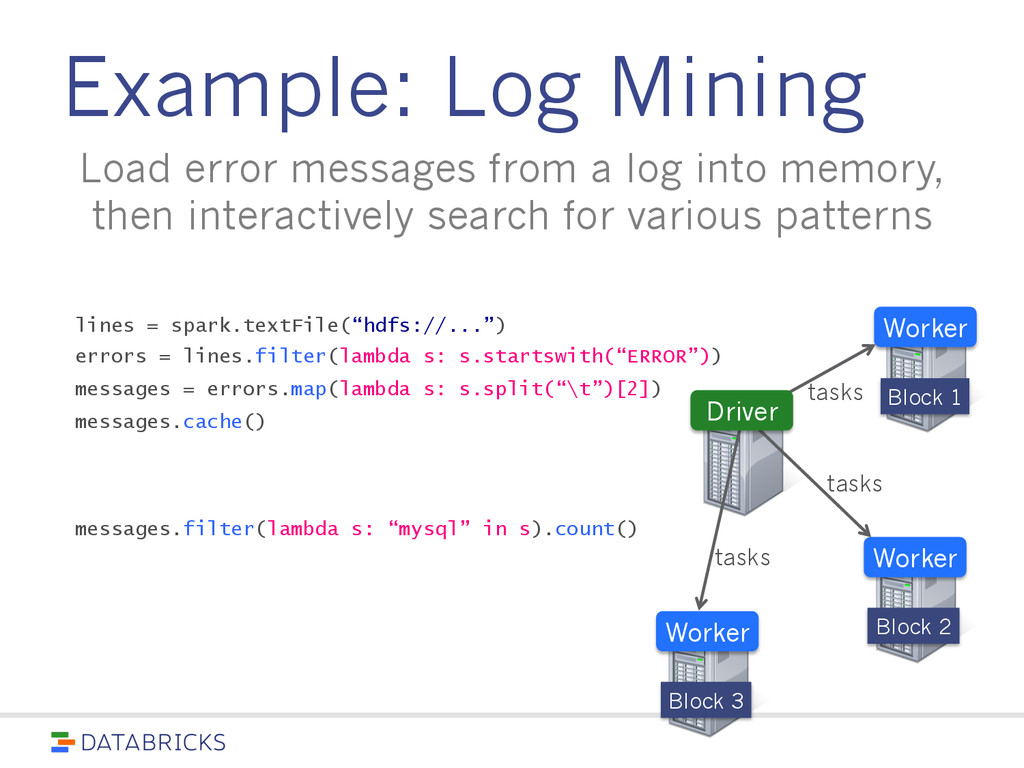
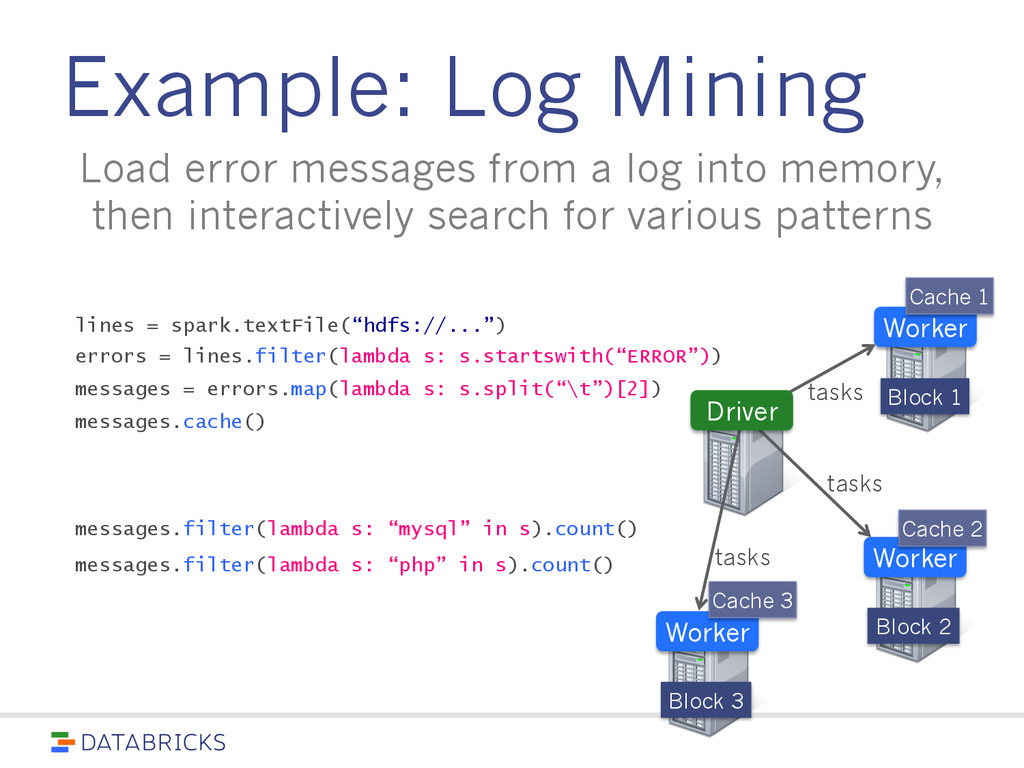
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) messages = errors.map(lambda s: s.split(“\t”)[2]) messages.cache() Worker Worker Worker messages.filter(lambda s: “mysql” in s).count() Block 1 Block 2 Block 3 Driver tasks tasks tasks -
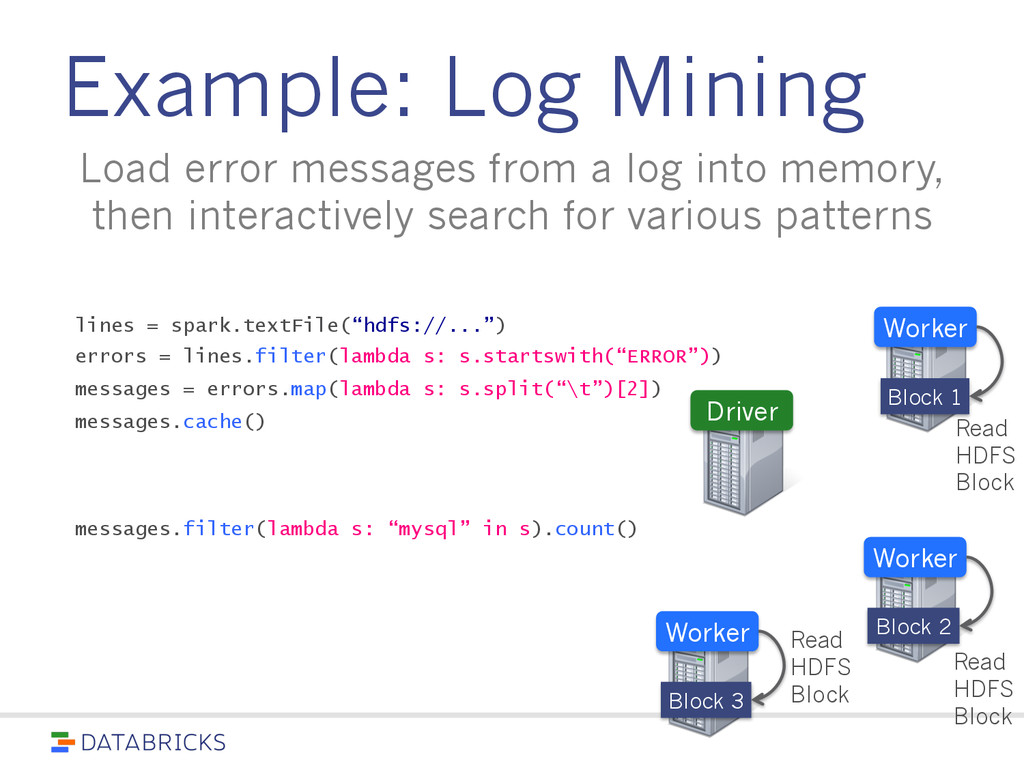
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) messages = errors.map(lambda s: s.split(“\t”)[2]) messages.cache() Worker Worker Worker messages.filter(lambda s: “mysql” in s).count() Block 1 Block 2 Block 3 Driver Read HDFS Block Read HDFS Block Read HDFS Block -
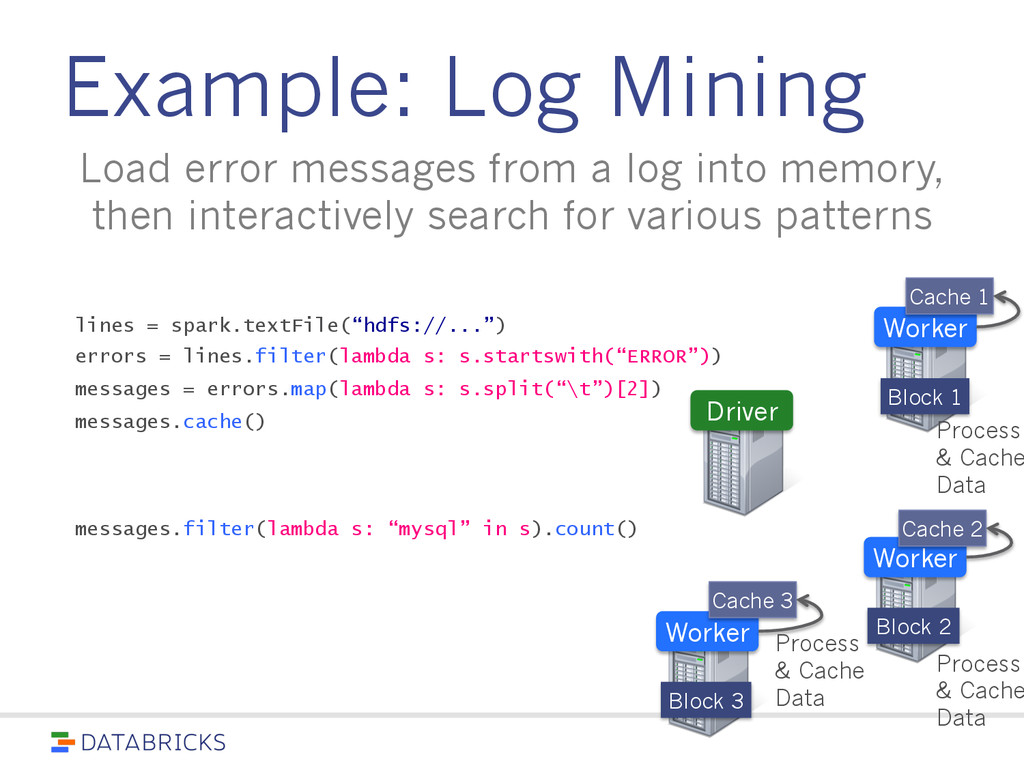
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) messages = errors.map(lambda s: s.split(“\t”)[2]) messages.cache() Worker Worker Worker messages.filter(lambda s: “mysql” in s).count() Block 1 Block 2 Block 3 Driver Cache 1 Cache 2 Cache 3 Process & Cache Data Process & Cache Data Process & Cache Data -
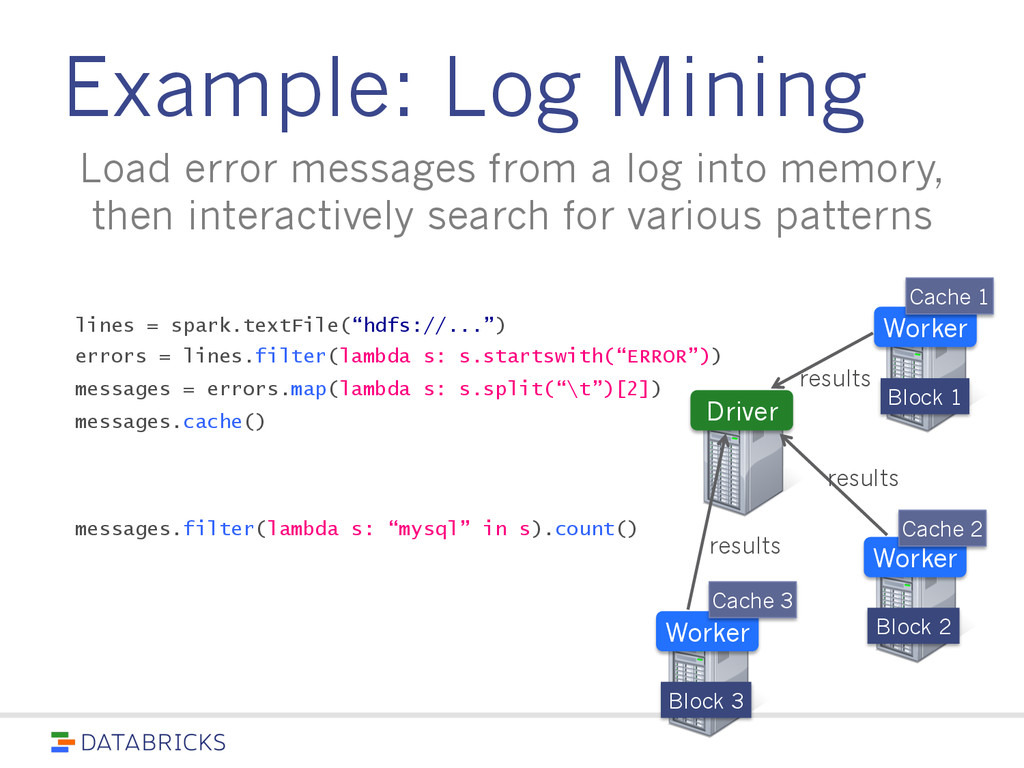
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) messages = errors.map(lambda s: s.split(“\t”)[2]) messages.cache() Worker Worker Worker messages.filter(lambda s: “mysql” in s).count() Block 1 Block 2 Block 3 Driver Cache 1 Cache 2 Cache 3 results results results -
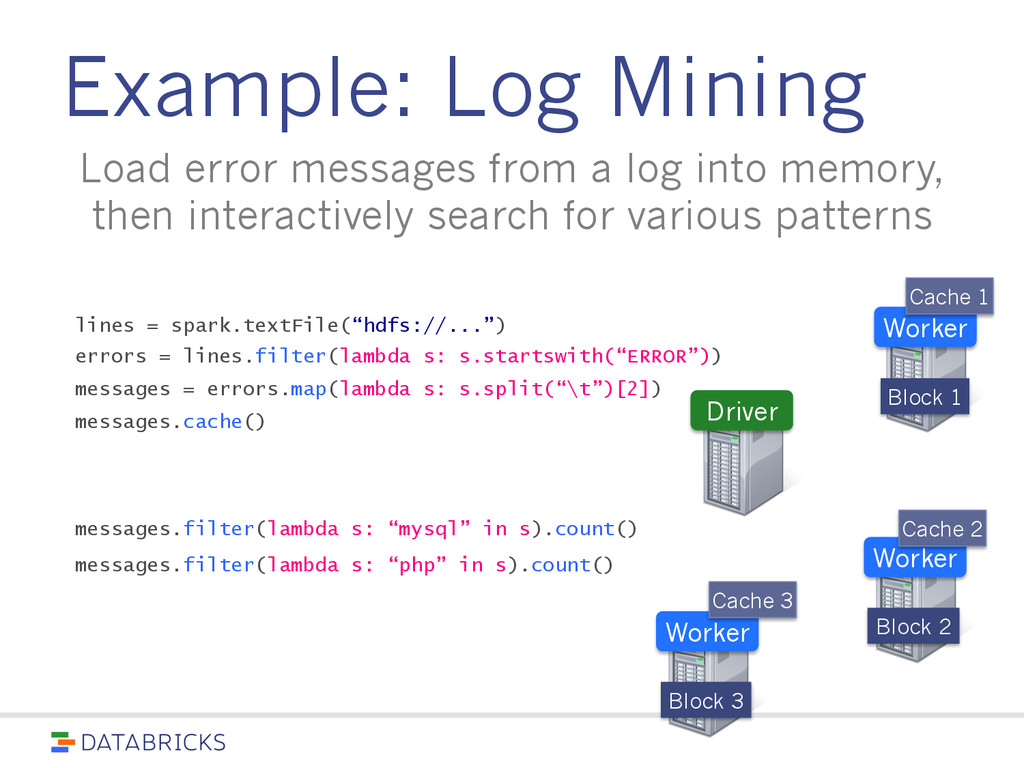
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) messages = errors.map(lambda s: s.split(“\t”)[2]) messages.cache() Worker Worker Worker messages.filter(lambda s: “mysql” in s).count() Block 1 Block 2 Block 3 Driver Cache 1 Cache 2 Cache 3 messages.filter(lambda s: “php” in s).count() -
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) messages = errors.map(lambda s: s.split(“\t”)[2]) messages.cache() Worker Worker Worker messages.filter(lambda s: “mysql” in s).count() Block 1 Block 2 Block 3 Cache 1 Cache 2 Cache 3 messages.filter(lambda s: “php” in s).count() tasks tasks tasks Driver -
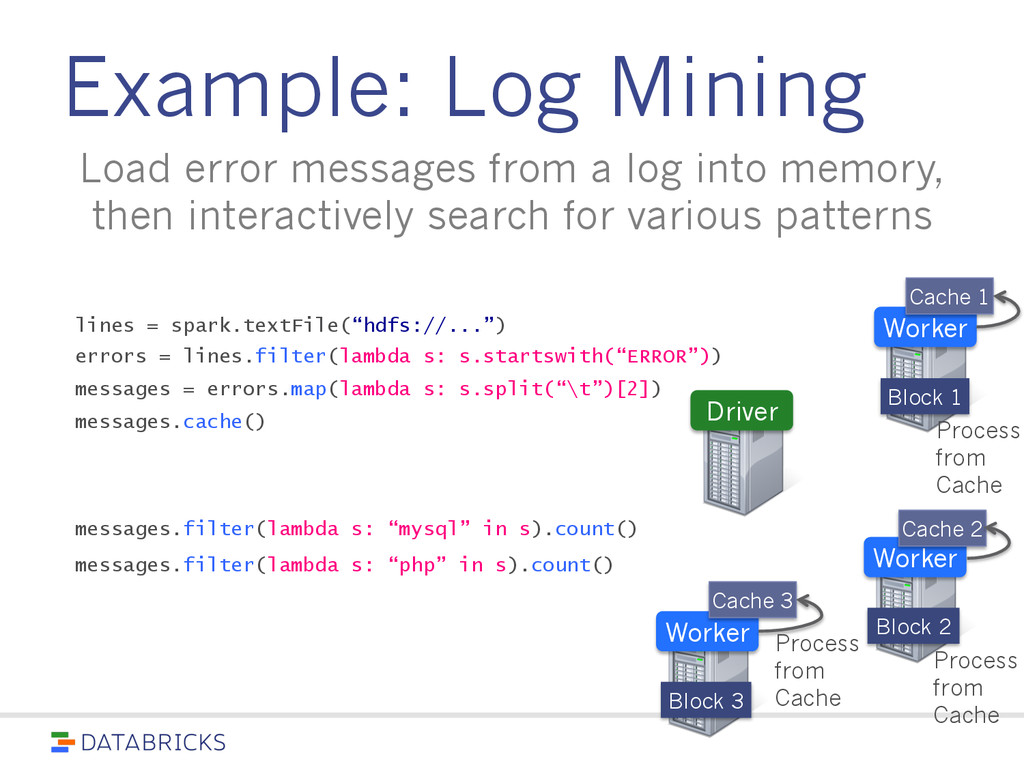
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) messages = errors.map(lambda s: s.split(“\t”)[2]) messages.cache() Worker Worker Worker messages.filter(lambda s: “mysql” in s).count() Block 1 Block 2 Block 3 Cache 1 Cache 2 Cache 3 messages.filter(lambda s: “php” in s).count() Driver Process from Cache Process from Cache Process from Cache -
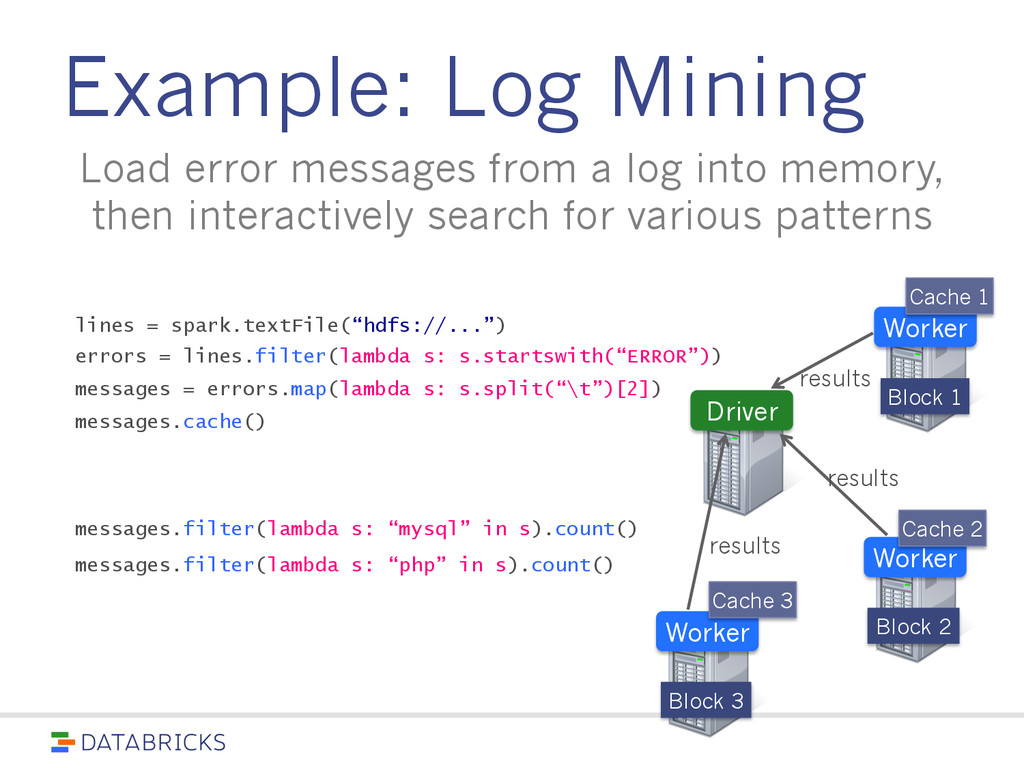
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) messages = errors.map(lambda s: s.split(“\t”)[2]) messages.cache() Worker Worker Worker messages.filter(lambda s: “mysql” in s).count() Block 1 Block 2 Block 3 Cache 1 Cache 2 Cache 3 messages.filter(lambda s: “php” in s).count() Driver results results results -
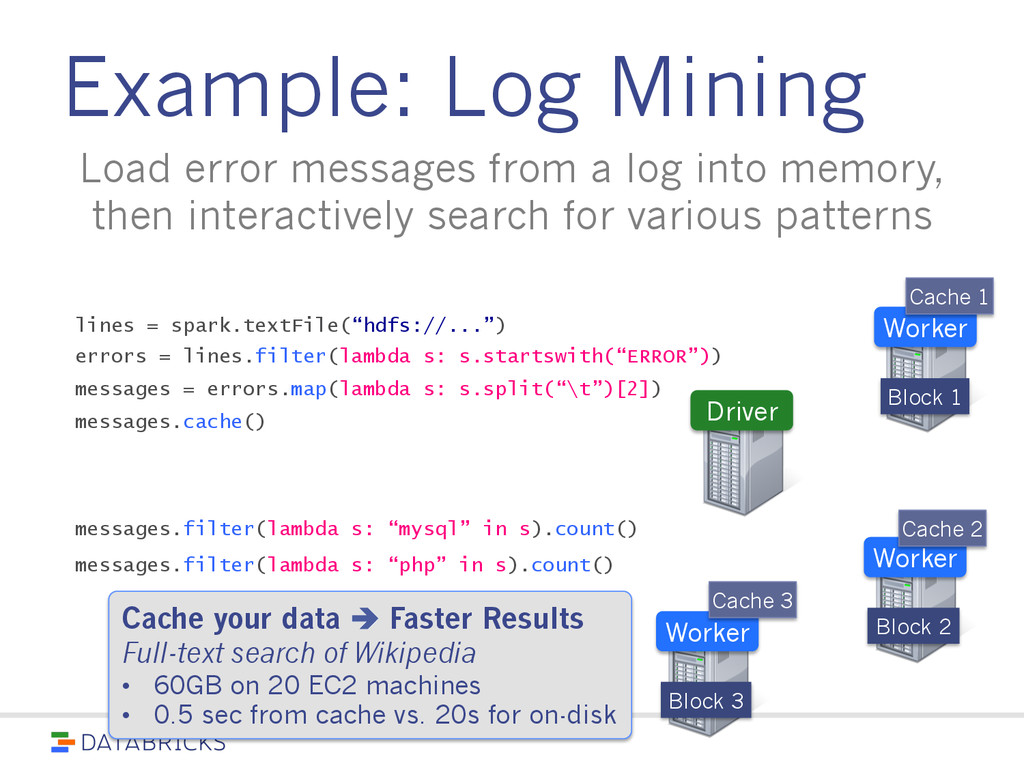
Example: Log Mining Load error messages from a log into
memory, then interactively search for various patterns lines = spark.textFile(“hdfs://...”) errors = lines.filter(lambda s: s.startswith(“ERROR”)) messages = errors.map(lambda s: s.split(“\t”)[2]) messages.cache() Worker Worker Worker messages.filter(lambda s: “mysql” in s).count() Block 1 Block 2 Block 3 Cache 1 Cache 2 Cache 3 messages.filter(lambda s: “php” in s).count() Driver Cache your data " Faster Results Full-text search of Wikipedia • 60GB on 20 EC2 machines • 0.5 sec from cache vs. 20s for on-disk -
Spark in 4 Bullet Points High performance: get insights faster
High developer productivity: make your life easier Sophistication: runs most advanced algorithms Active Open Source Community -
Patrick Wendell Databricks Spark.incubator.apache.org Beyond
Spark Core: Spark Ecosystem and Roadmap -
About me Committer and PMC member of Apache Spark
“Former” PhD student at Berkeley Left Berkeley to help found Databricks Now managing open source work at Databricks Focus is on networking and operating systems -
Show of hands Are you: 1. Data analyst:
i.e. work with analytics tools day-‐to-‐day. 2. Sales/marketing/business role and interested in analytics. 3. Other -
Dirty Secret In modern analytics environments… Most programmer
time is spent fighting with confusing, broken, or limited API’s. Most machine time is spent moving data in between systems. Huge room for improvement -
Project Philosophy Make life easy and productive for data
scientists Well documented, expressive API’s Powerful domain-‐specific libraries Easy integration with storage systems … and caching to avoid data movement Regular maintenance releases -
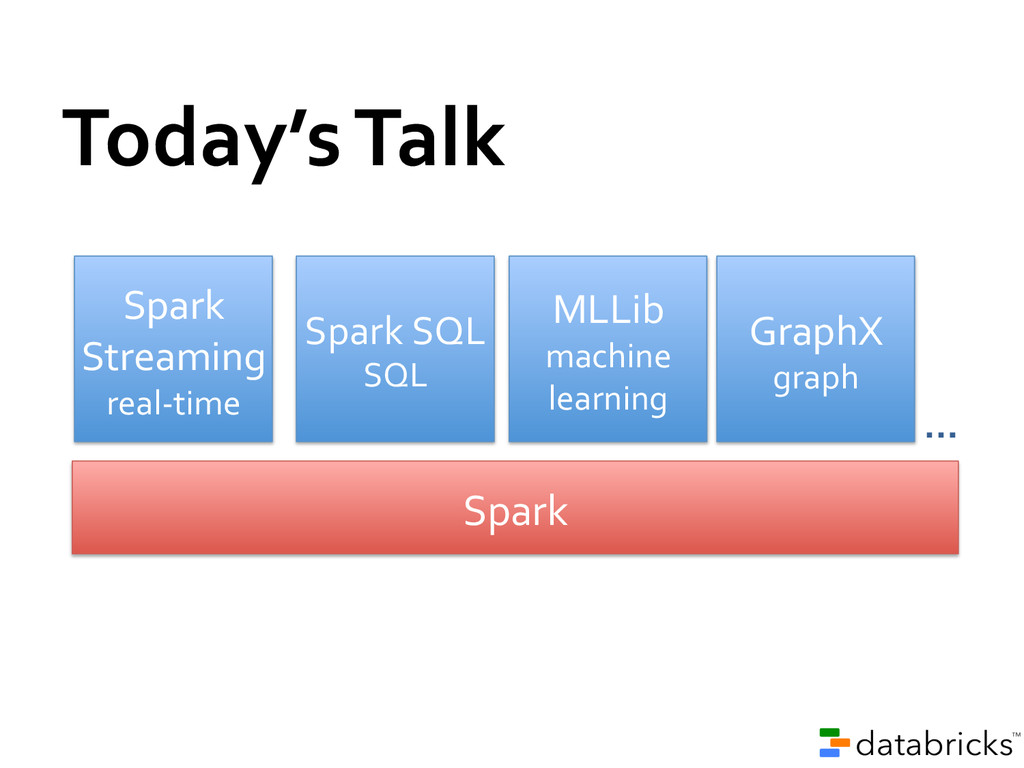
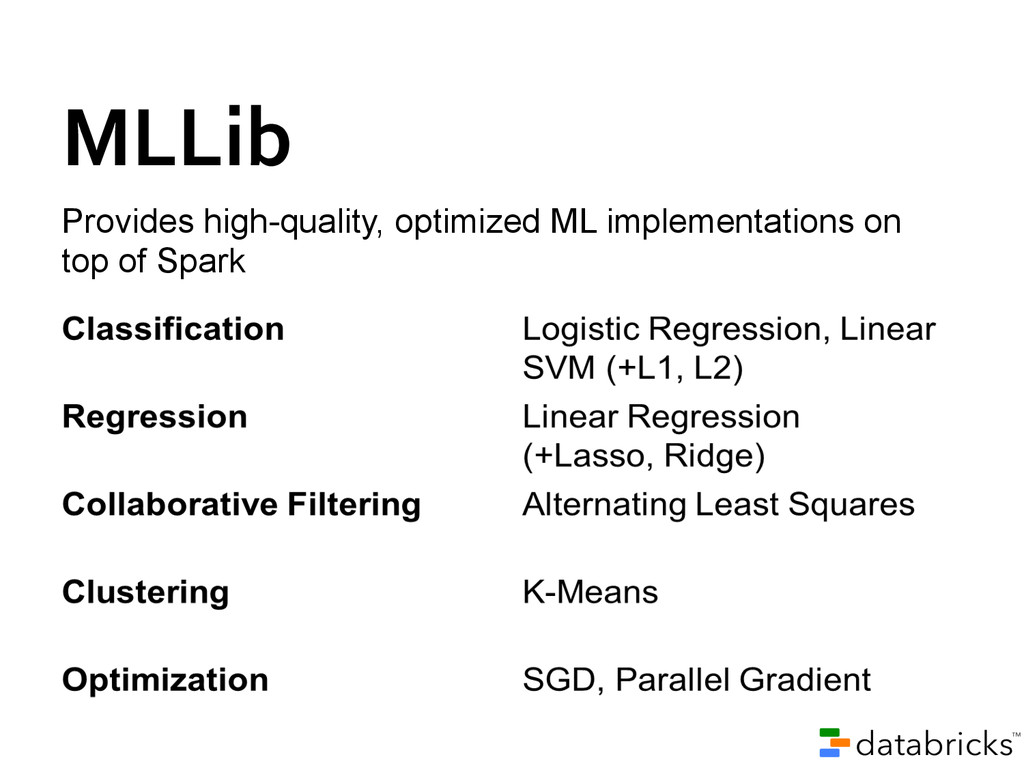
Today’s Talk Spark Spark Streaming real-‐time
Spark SQL SQL GraphX graph MLLib machine learning … -
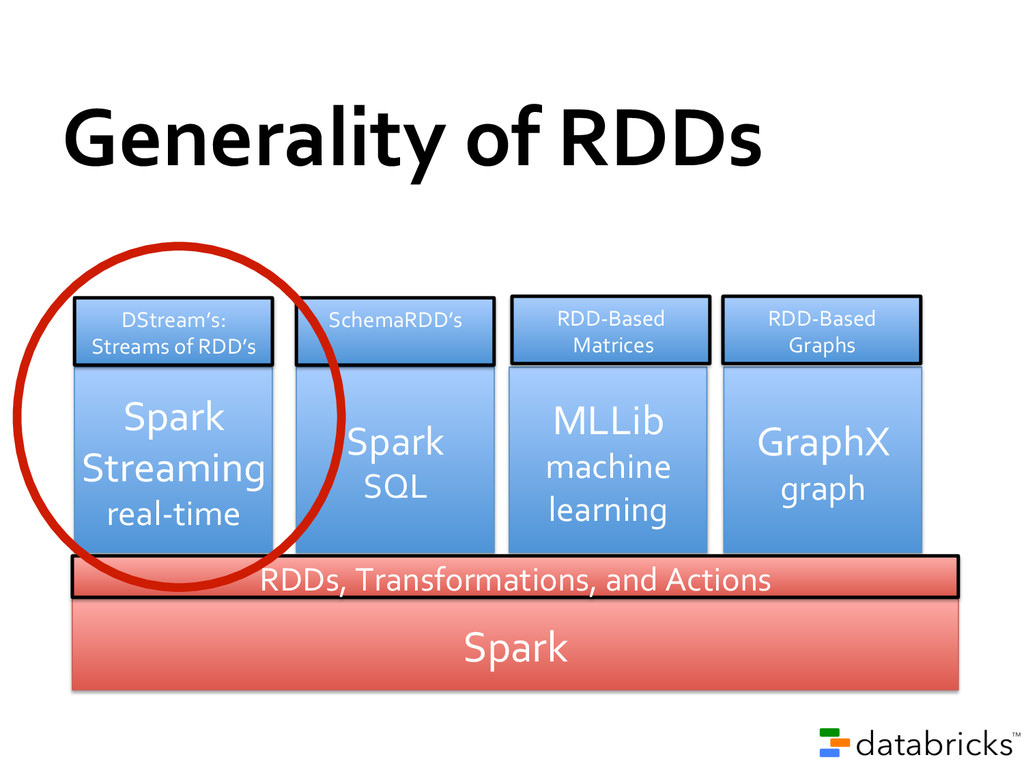
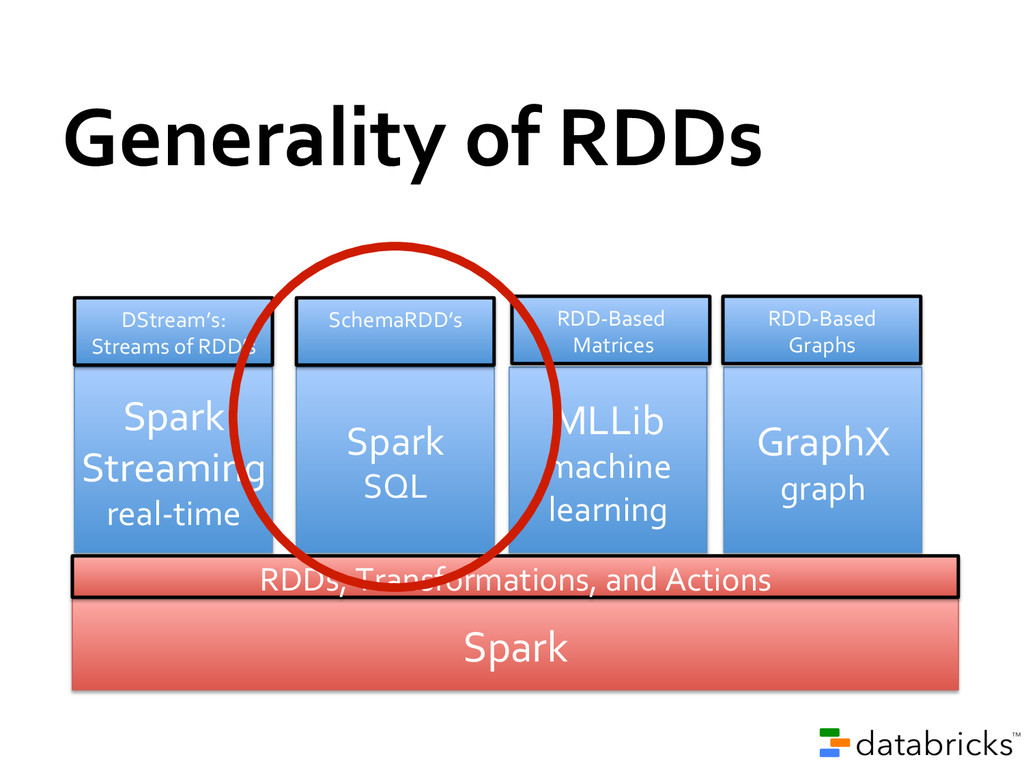
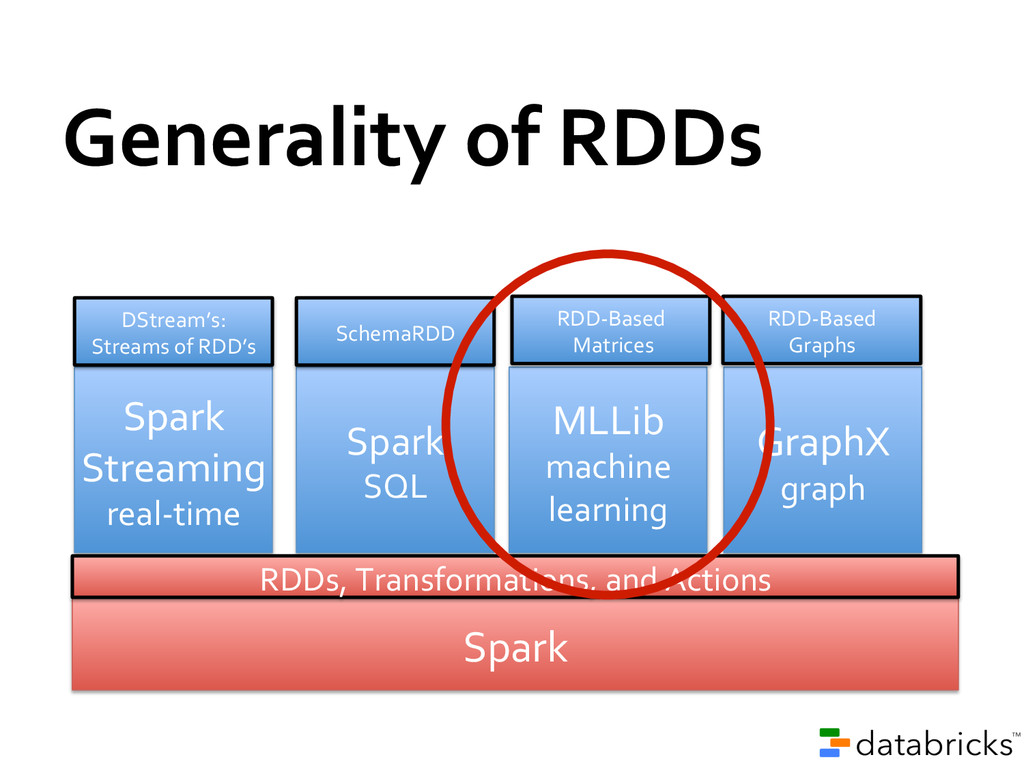
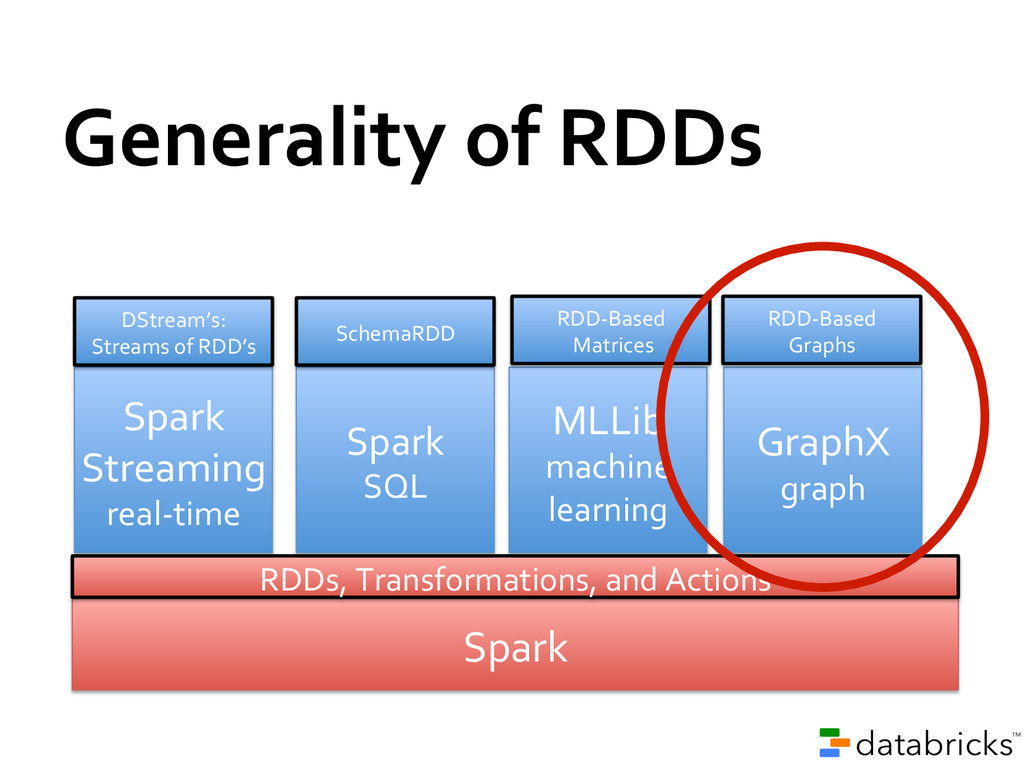
Generality of RDDs Spark RDDs, Transformations, and Actions
Spark Streaming real-‐time Spark SQL GraphX graph MLLib machine learning DStream’s: Streams of RDD’s SchemaRDD’s RDD-‐Based Matrices RDD-‐Based Graphs -
Many important apps must process large data streams at
second-‐scale latencies » Site statistics, intrusion detection, online ML To build and scale these apps users want: » Integration: with offline analytical stack » Fault-‐tolerance: both for crashes and stragglers » Efficiency: low cost beyond base processing Spark Streaming: Motivation -
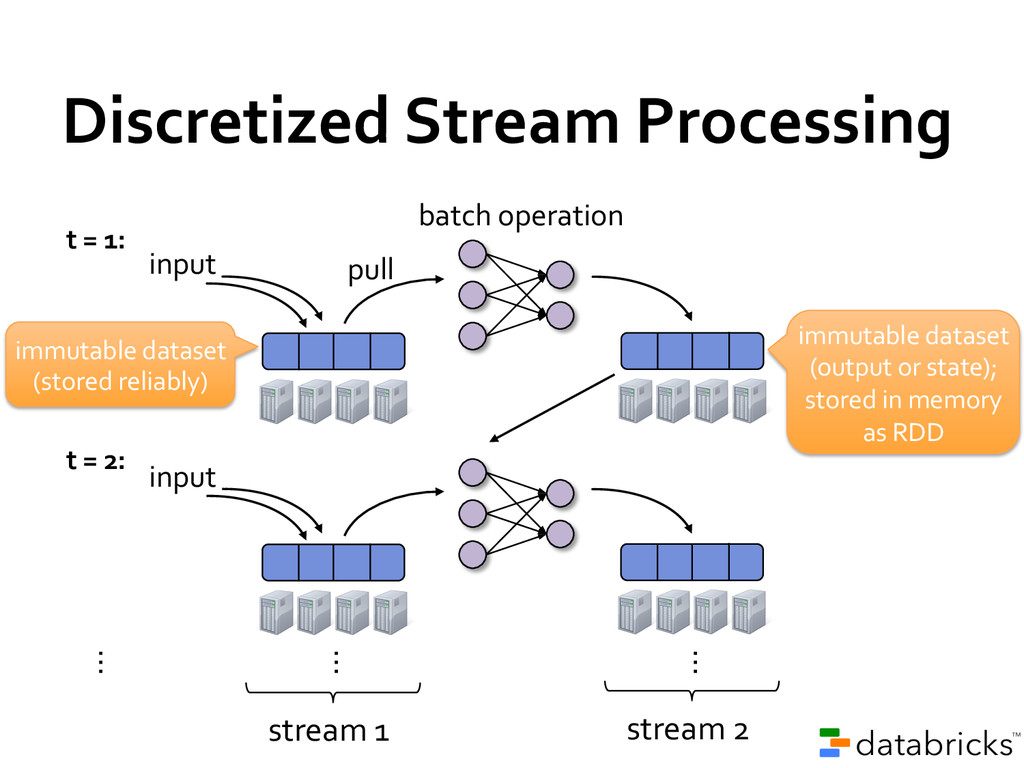
Discretized Stream Processing t = 1: t =
2: stream 1 stream 2 batch operation pull input … … input immutable dataset (stored reliably) immutable dataset (output or state); stored in memory as RDD … -
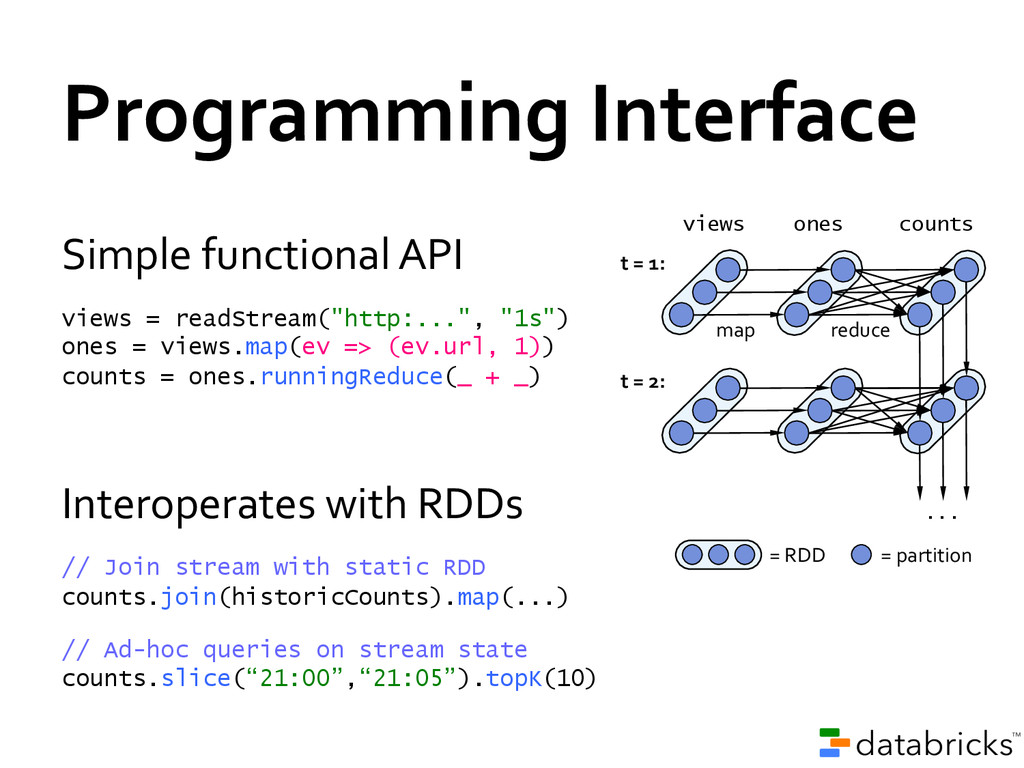
Programming Interface Simple functional API views =
readStream("http:...", "1s") ones = views.map(ev => (ev.url, 1)) counts = ones.runningReduce(_ + _) Interoperates with RDDs ! // Join stream with static RDD counts.join(historicCounts).map(...) ! // Ad-hoc queries on stream state counts.slice(“21:00”,“21:05”).topK(10) t = 1: t = 2: views ones counts map reduce . . . = RDD = partition -
Inherited “for free” from Spark RDD data model and
API Data partitioning and shuffles Task scheduling Monitoring/instrumentation Scheduling and resource allocation -
Generality of RDDs Spark RDDs, Transformations, and Actions
Spark Streaming real-‐time Spark SQL GraphX graph MLLib machine learning DStream’s: Streams of RDD’s SchemaRDD’s RDD-‐Based Matrices RDD-‐Based Graphs -
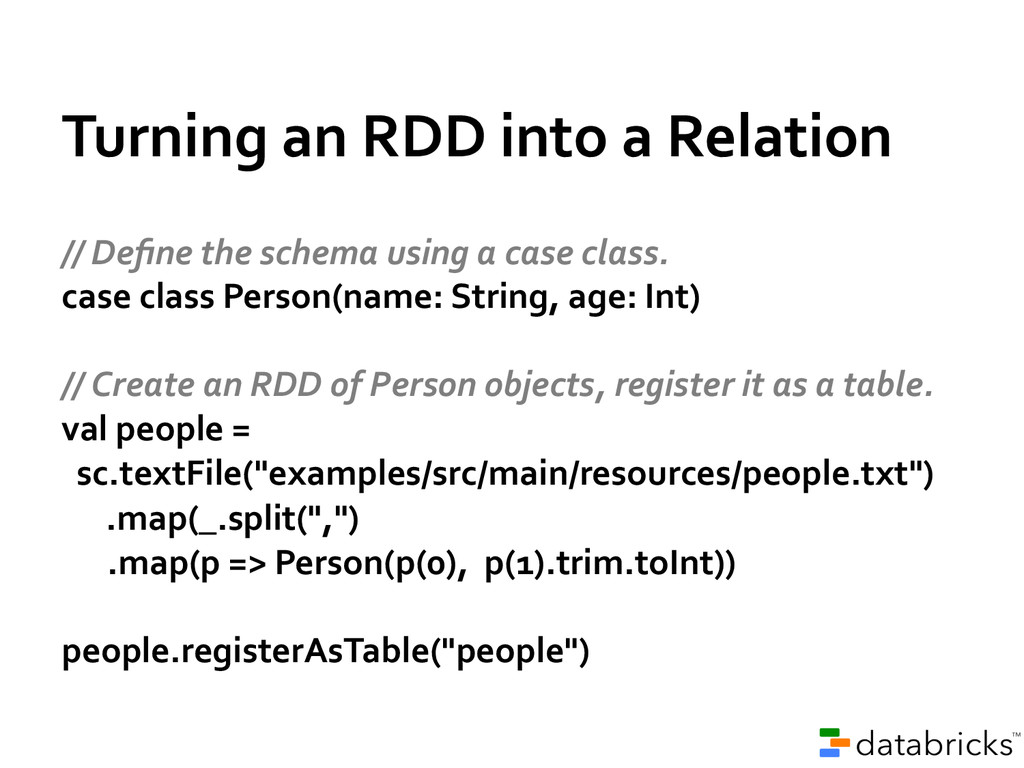
Turning an RDD into a Relation // Define the
schema using a case class. case class Person(name: String, age: Int) // Create an RDD of Person objects, register it as a table. val people = sc.textFile("examples/src/main/resources/people.txt") .map(_.split(",") .map(p => Person(p(0), p(1).trim.toInt)) people.registerAsTable("people") -
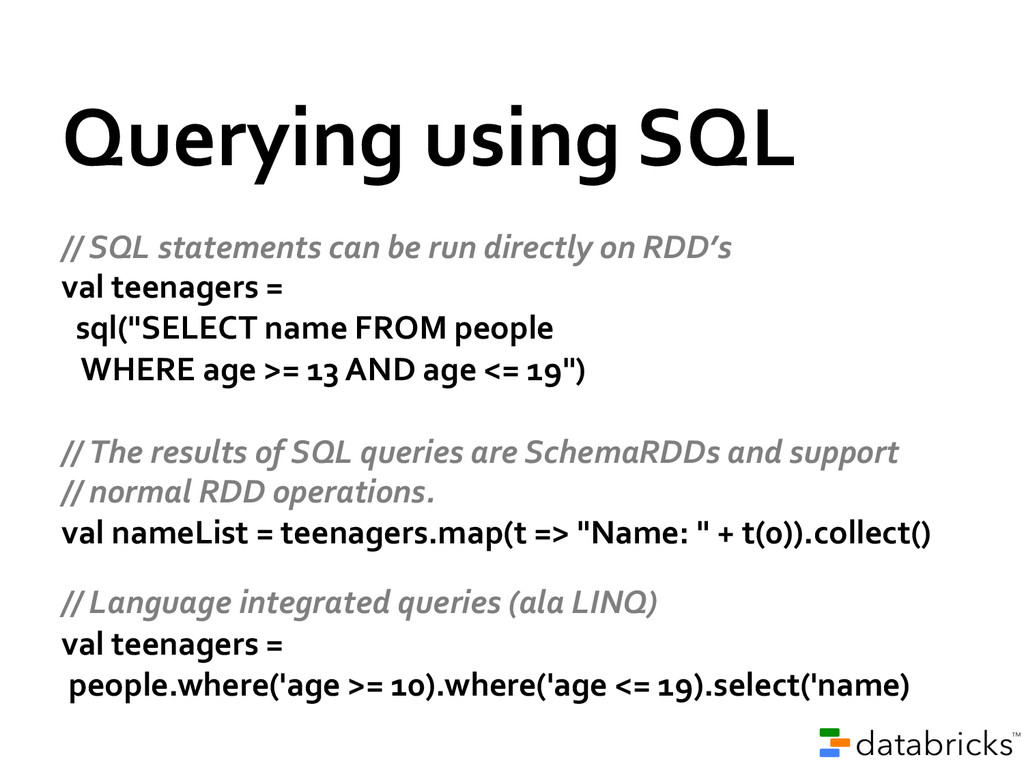
Querying using SQL // SQL statements can be run
directly on RDD’s val teenagers = sql("SELECT name FROM people WHERE age >= 13 AND age <= 19") // The results of SQL queries are SchemaRDDs and support // normal RDD operations. val nameList = teenagers.map(t => "Name: " + t(0)).collect() // Language integrated queries (ala LINQ) val teenagers = people.where('age >= 10).where('age <= 19).select('name) -
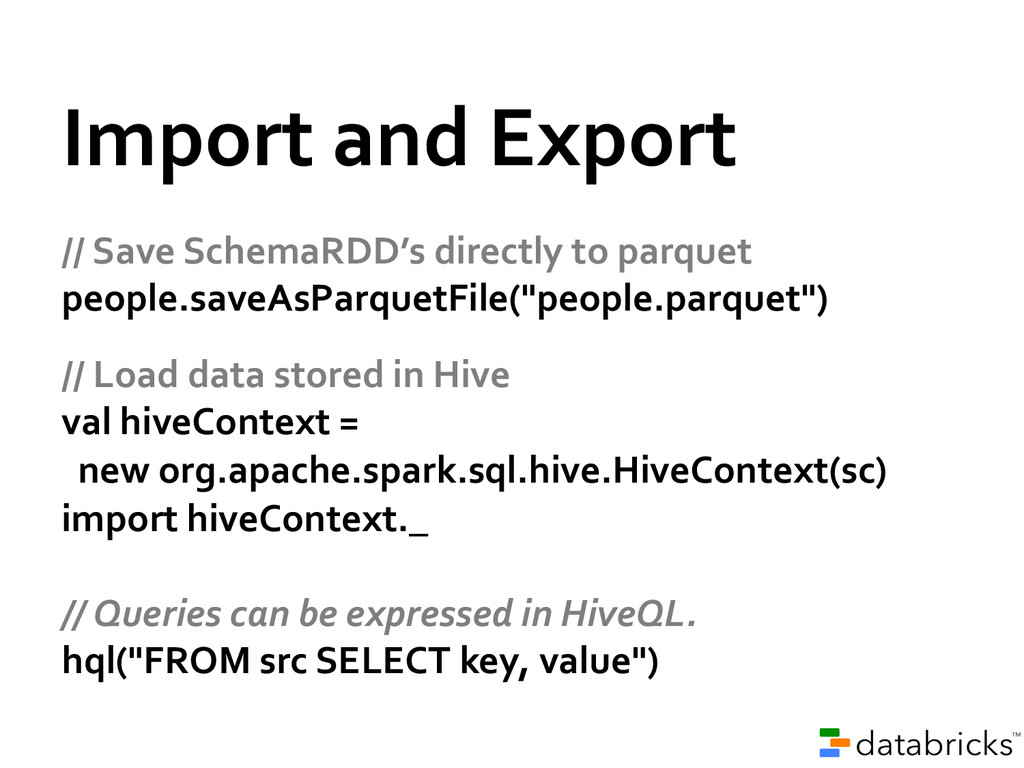
Import and Export // Save SchemaRDD’s directly to parquet
people.saveAsParquetFile("people.parquet") // Load data stored in Hive val hiveContext = new org.apache.spark.sql.hive.HiveContext(sc) import hiveContext._ // Queries can be expressed in HiveQL. hql("FROM src SELECT key, value") -
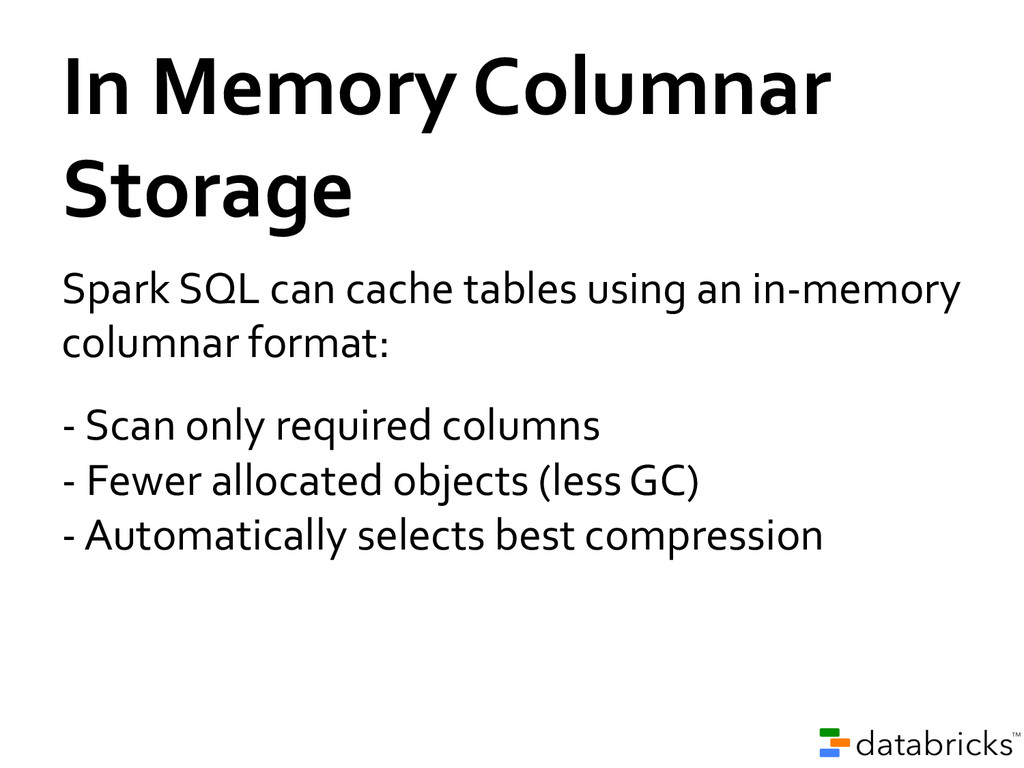
In Memory Columnar Storage Spark SQL can cache
tables using an in-‐memory columnar format: -‐ Scan only required columns -‐ Fewer allocated objects (less GC) -‐ Automatically selects best compression -
Generality of RDDs Spark RDDs, Transformations, and Actions
Spark Streaming real-‐time Spark SQL GraphX graph MLLib machine learning DStream’s: Streams of RDD’s SchemaRDD RDD-‐Based Matrices RDD-‐Based Graphs -
Generality of RDDs Spark RDDs, Transformations, and Actions
Spark Streaming real-‐time Spark SQL GraphX graph MLLib machine learning DStream’s: Streams of RDD’s SchemaRDD RDD-‐Based Matrices RDD-‐Based Graphs -
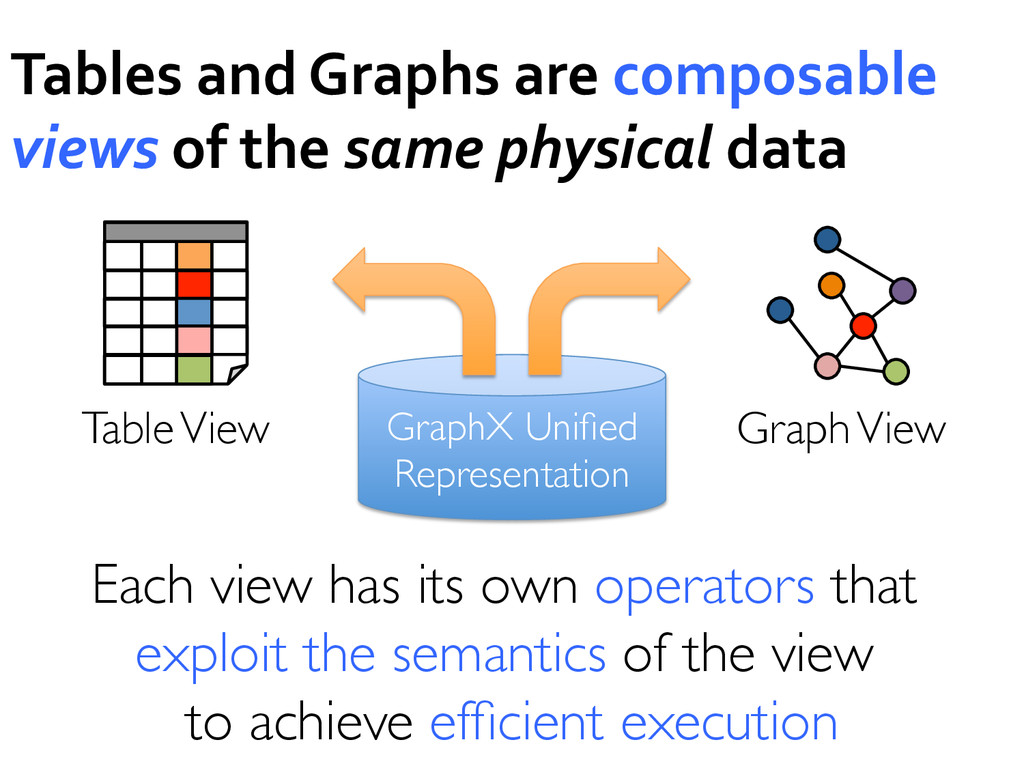
Tables and Graphs are composable views of the
same physical data GraphX Unified Representation Graph View Table View Each view has its own operators that -
GraphX Example val edgesRdd: RDD[Edge] = sc
.textFile(“edges.txt”) .map(line => extractEdge(line)) val vertexRDD: RDD[Vertex] = sc .textFile(“vertices.txt”) .map(line => extractVertex(line)) val graph = new Graph(edgeRdd, vertexRdd) Val result = graph.pageRank() -
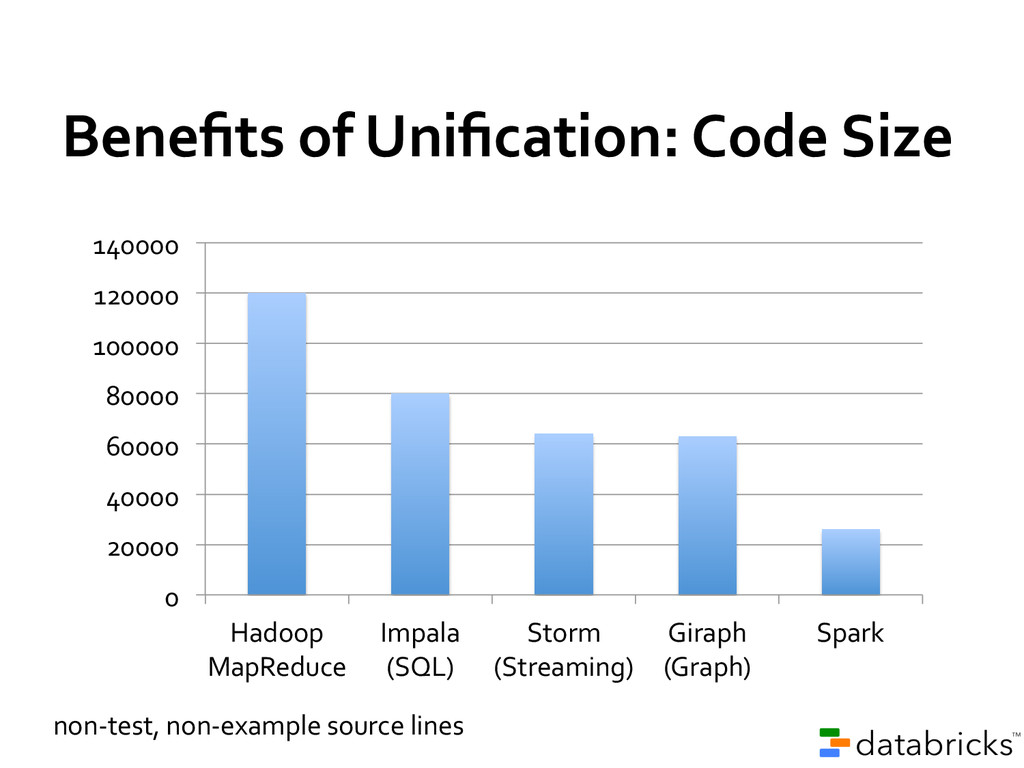
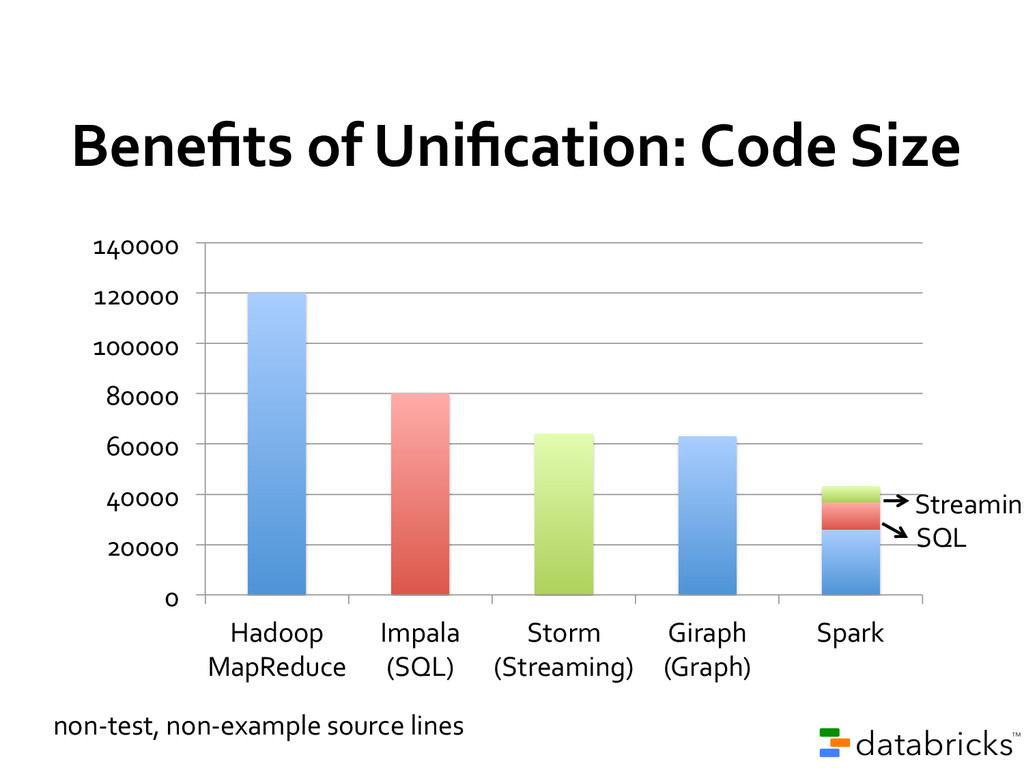
Benefits of Unification: Code Size 0 20000
40000 60000 80000 100000 120000 140000 Hadoop MapReduce Impala (SQL) Storm (Streaming) Giraph (Graph) Spark non-‐test, non-‐example source lines -
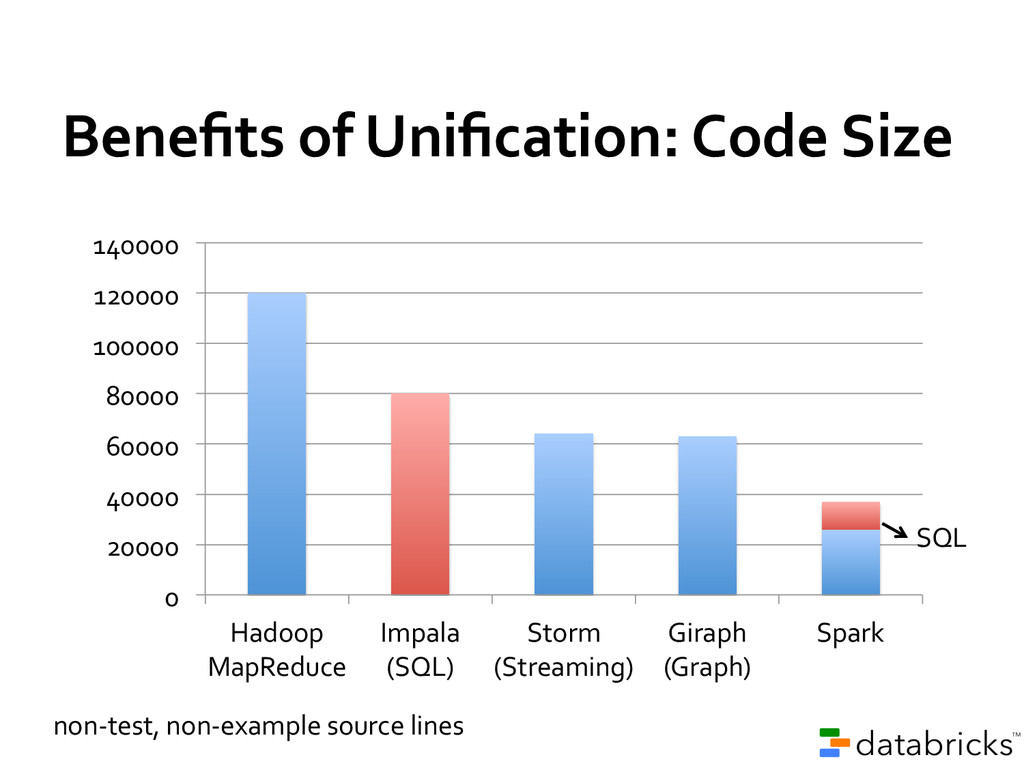
Benefits of Unification: Code Size 0 20000
40000 60000 80000 100000 120000 140000 Hadoop MapReduce Impala (SQL) Storm (Streaming) Giraph (Graph) Spark non-‐test, non-‐example source lines SQL -
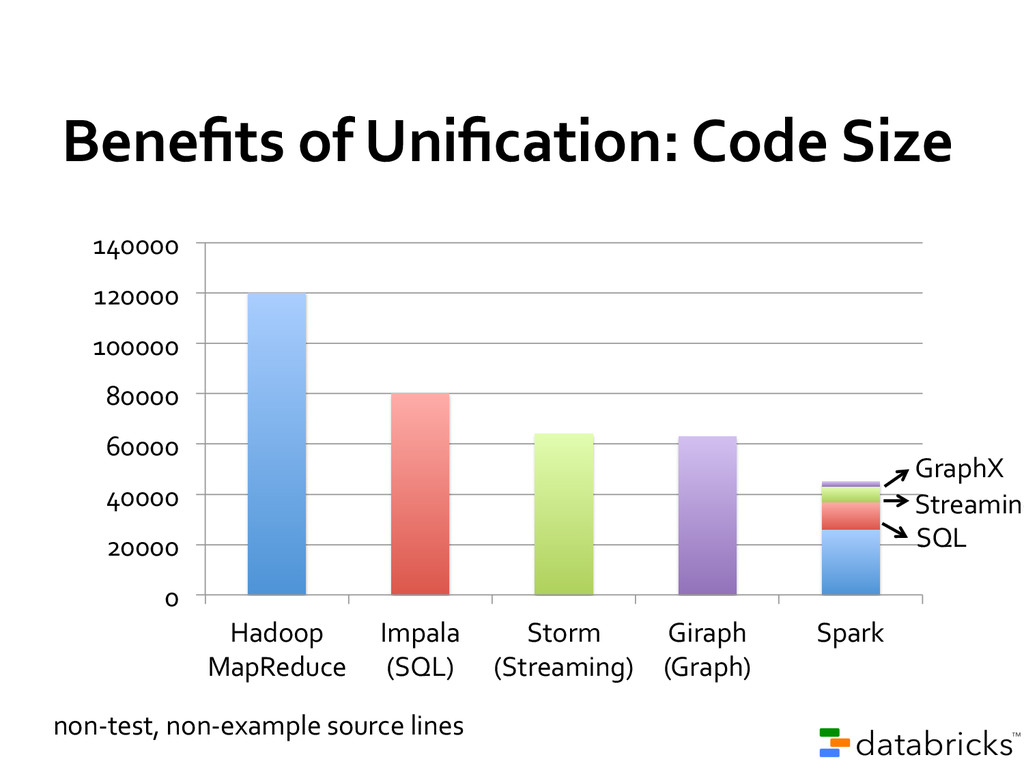
0 20000 40000 60000 80000
100000 120000 140000 Hadoop MapReduce Impala (SQL) Storm (Streaming) Giraph (Graph) Spark non-‐test, non-‐example source lines SQL Streaming Benefits of Unification: Code Size -
0 20000 40000 60000 80000
100000 120000 140000 Hadoop MapReduce Impala (SQL) Storm (Streaming) Giraph (Graph) Spark non-‐test, non-‐example source lines SQL GraphX Streaming Benefits of Unification: Code Size -
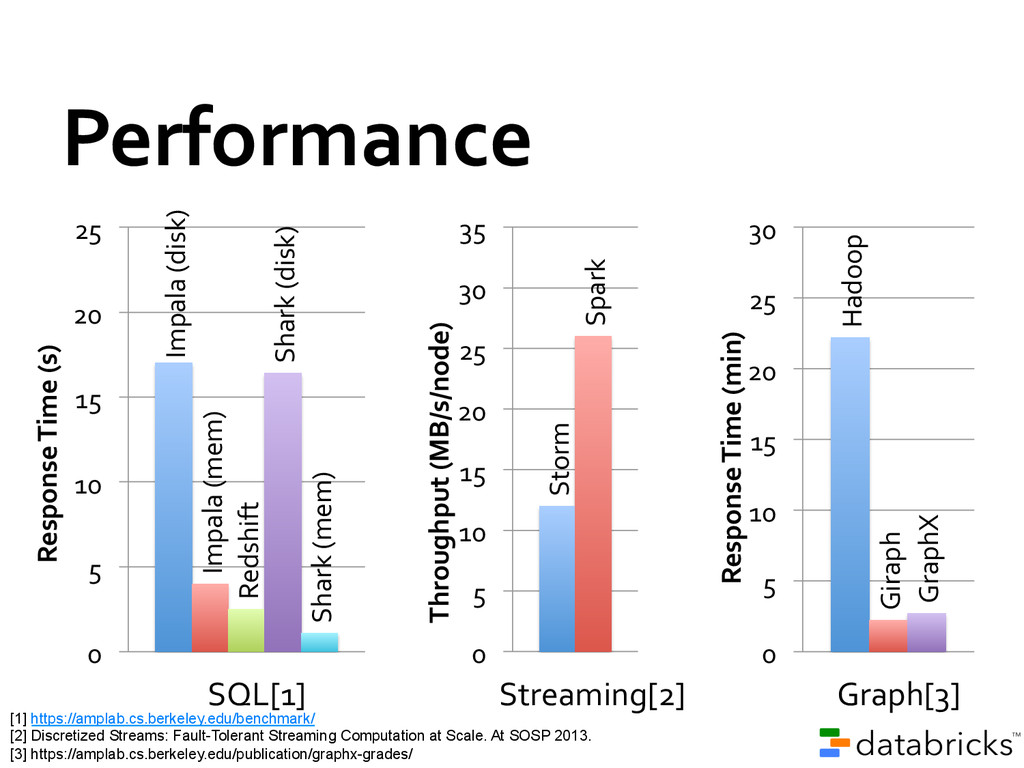
Performance Impala (disk) Impala (mem) Redshift
Shark (disk) Shark (mem) 0 5 10 15 20 25 Response Time (s) SQL[1] Storm Spark 0 5 10 15 20 25 30 35 Throughput (MB/s/node) Streaming[2] Hadoop Giraph GraphX 0 5 10 15 20 25 30 Response Time (min) Graph[3] [1] https://amplab.cs.berkeley.edu/benchmark/ [2] Discretized Streams: Fault-Tolerant Streaming Computation at Scale. At SOSP 2013. [3] https://amplab.cs.berkeley.edu/publication/graphx-grades/ -
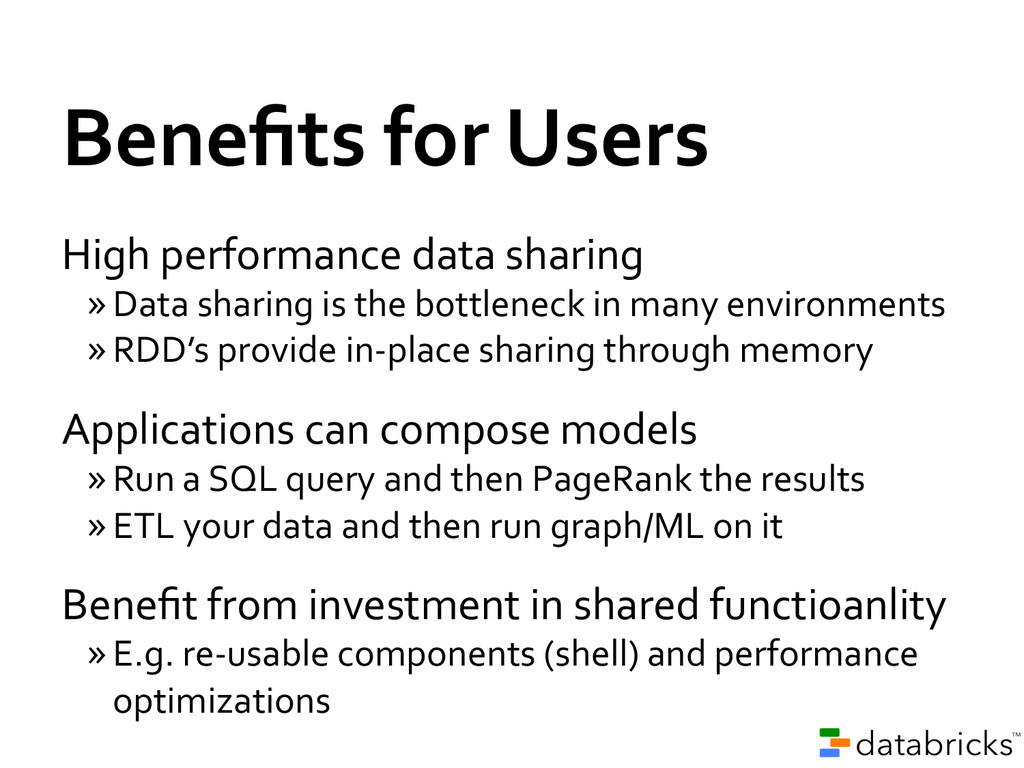
Benefits for Users High performance data sharing » Data
sharing is the bottleneck in many environments » RDD’s provide in-‐place sharing through memory Applications can compose models » Run a SQL query and then PageRank the results » ETL your data and then run graph/ML on it Benefit from investment in shared functioanlity » E.g. re-‐usable components (shell) and performance optimizations -
New Spark Releases Spark 0.9.1 Released today!
Maintenance release with stability fixes. Spark 1.0 Enters feature freeze this week QA period during April à final release likely end-‐of-‐April -
Spark 1.0: Major Features -‐ SparkSQL initial release
(w/ Java and Python API’s) -‐ Support for Java 8 lambda syntax -‐ Sparse vector support and new algorithms in MLLib -‐ History server for Spark’s UI -‐ API stability -‐ Improved YARN support -
Getting Started Visit spark.apache.org for videos, tutorials, and
hands-‐on exercises Easy to run in local mode, private clusters, EC2 Spark Summit on June 30th (spark-‐summit.org) Online training camp: ampcamp.berkeley.edu -
Conclusion Big data analytics is evolving to include:
» More complex analytics (e.g. machine learning) » More interactive ad-‐hoc queries » More real-‐time stream processing Spark is a platform that unifies these models, enabling sophisticated apps More info: spark-‐project.org -
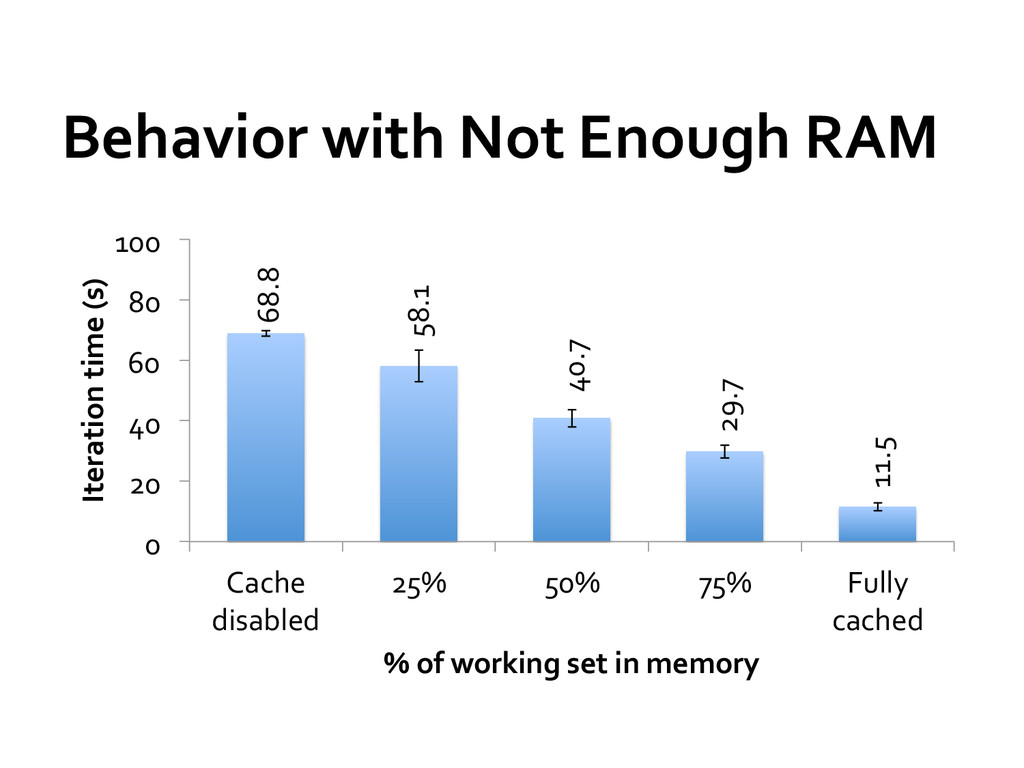
Behavior with Not Enough RAM 68.8 58.1
40.7 29.7 11.5 0 20 40 60 80 100 Cache disabled 25% 50% 75% Fully cached Iteration time (s) % of working set in memory
 rxin
 ykimi
 mikanichinose
 yama3133
 ama_ch
 jacopen
 takuyay0ne
 silmin_
 maguroalternative
 staka121
 sue445
 fj_yoshimura_kosuke
 110y
 khoart
 cargoodrich
 bkeepers
 davidcarrasco
 livdayseo
 garrettdimon
 panda_program
 nikkihalliwell
 csswizardry
 addyosmani
 aleyda
 helenjbeal