Upgrade to Pro — share decks privately, control downloads, hide ads and more …

Shark SIGMOD research deck

Sponsored · Your Podcast. Everywhere. Effortlessly. Share. Educate. Inspire. Entertain. You do you. We'll handle the rest. →

Shark SIGMOD research deck

The talk I gave at SIGMOD 2013. The audience is a large group of database researchers so the talk focuses on the research aspect of Shark.

Reynold Xin

June 25, 2013

Transcript

36 slides
  1. Shark: SQL and Rich Analytics at Scale! Reynold Xin, Josh

    Rosen, Matei Zaharia, Michael Franklin, Scott Shenker, Ion Stoica! ! AMPLab, UC Berkeley! ! June 25 @ SIGMOD 2013!
  2. Challenges ! Data size growing! » Processing has to scale out

    over large" clusters! » Faults and stragglers complicate DB design! ! Complexity of analysis increasing! » Massive ETL (web crawling)! » Machine learning, graph processing! » Leads to long running jobs!
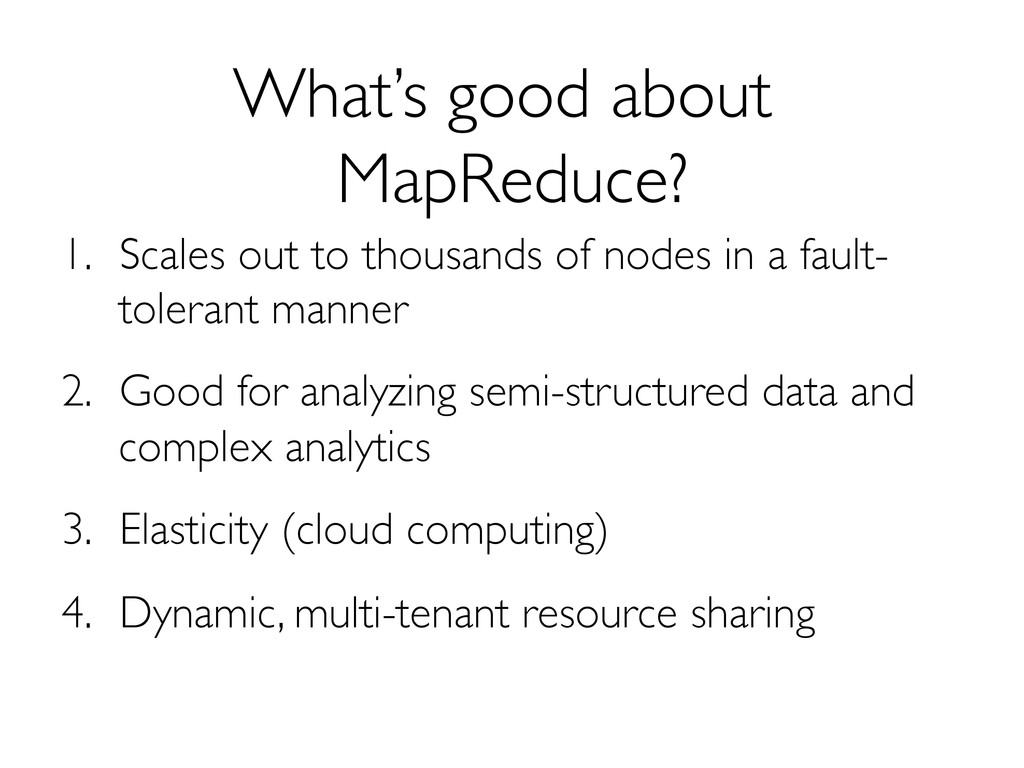
  3. What’s good about MapReduce? ! 1.  Scales out to thousands

    of nodes in a fault- tolerant manner! 2.  Good for analyzing semi-structured data and complex analytics! 3.  Elasticity (cloud computing)! 4.  Dynamic, multi-tenant resource sharing!
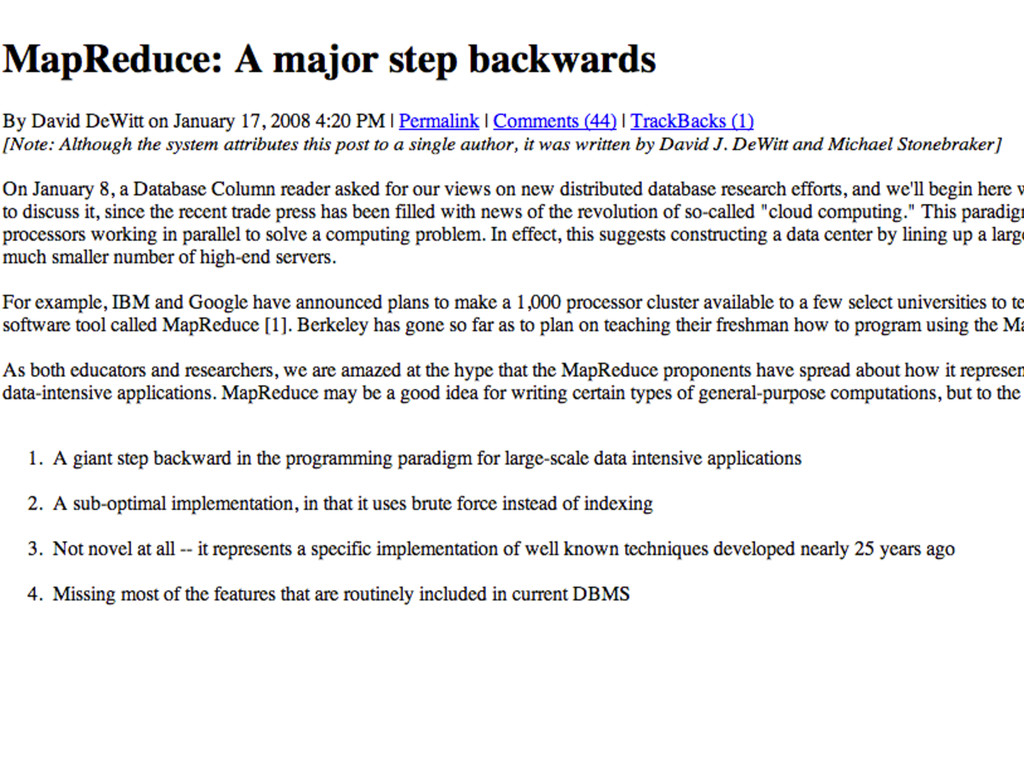
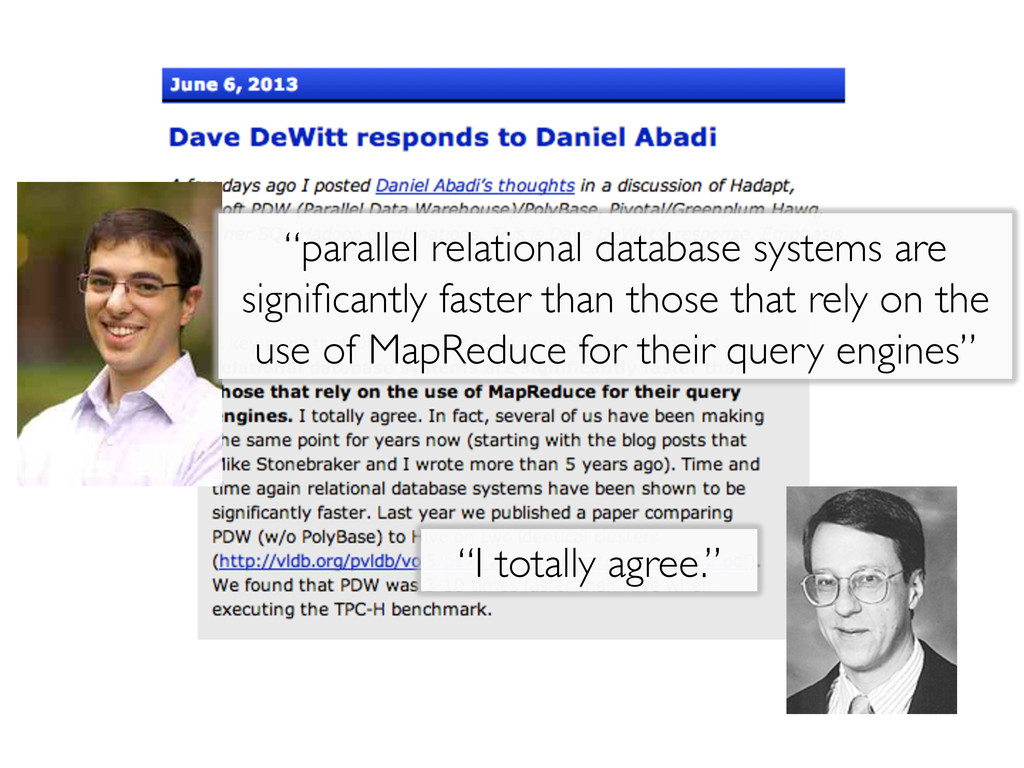
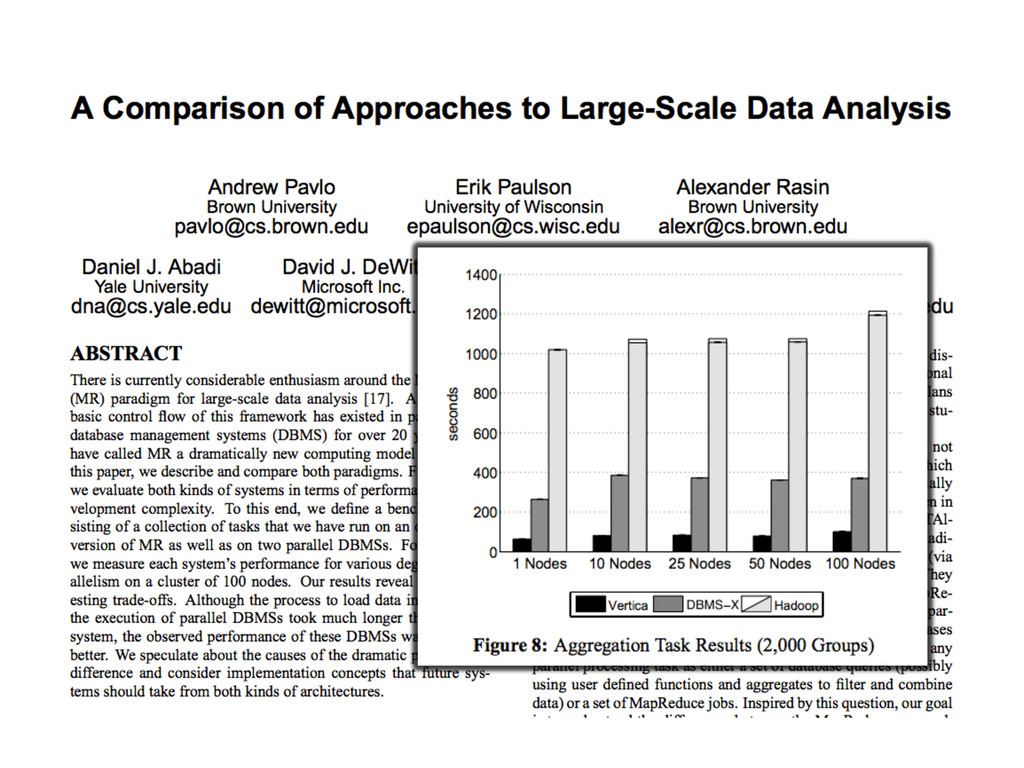
  4. “parallel relational database systems are significantly faster than those that

    rely on the use of MapReduce for their query engines”! “I totally agree.”!
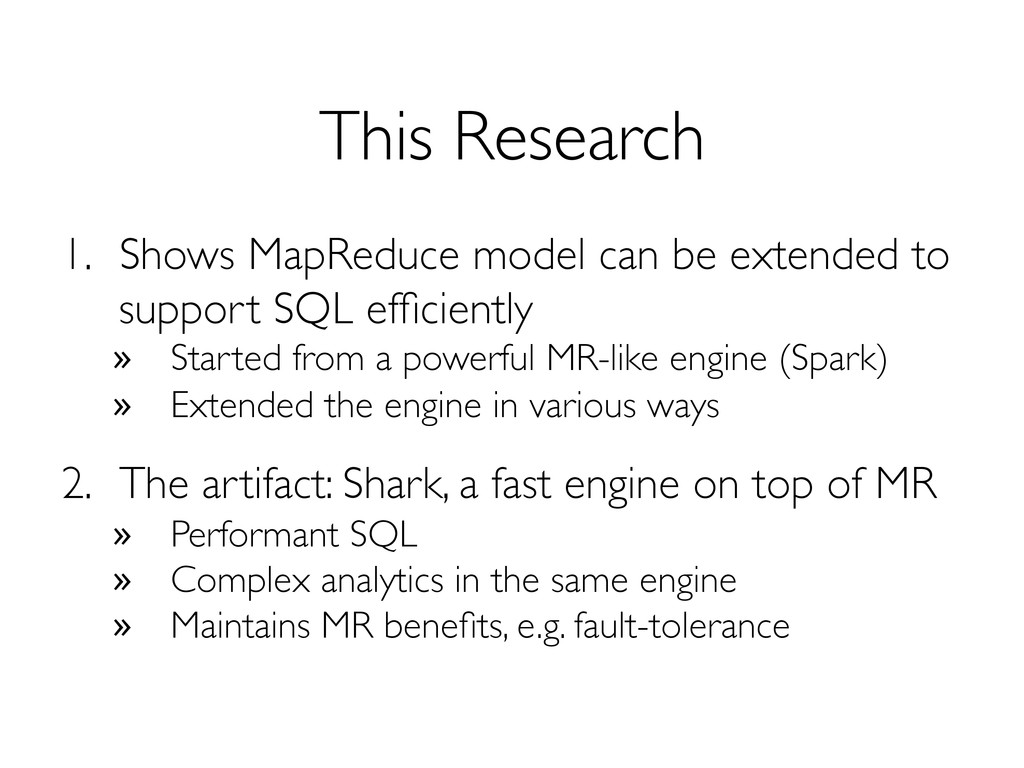
  5. This Research ! 1.  Shows MapReduce model can be extended

    to support SQL efficiently! »  Started from a powerful MR-like engine (Spark)! »  Extended the engine in various ways! 2.  The artifact: Shark, a fast engine on top of MR! »  Performant SQL! »  Complex analytics in the same engine! »  Maintains MR benefits, e.g. fault-tolerance!
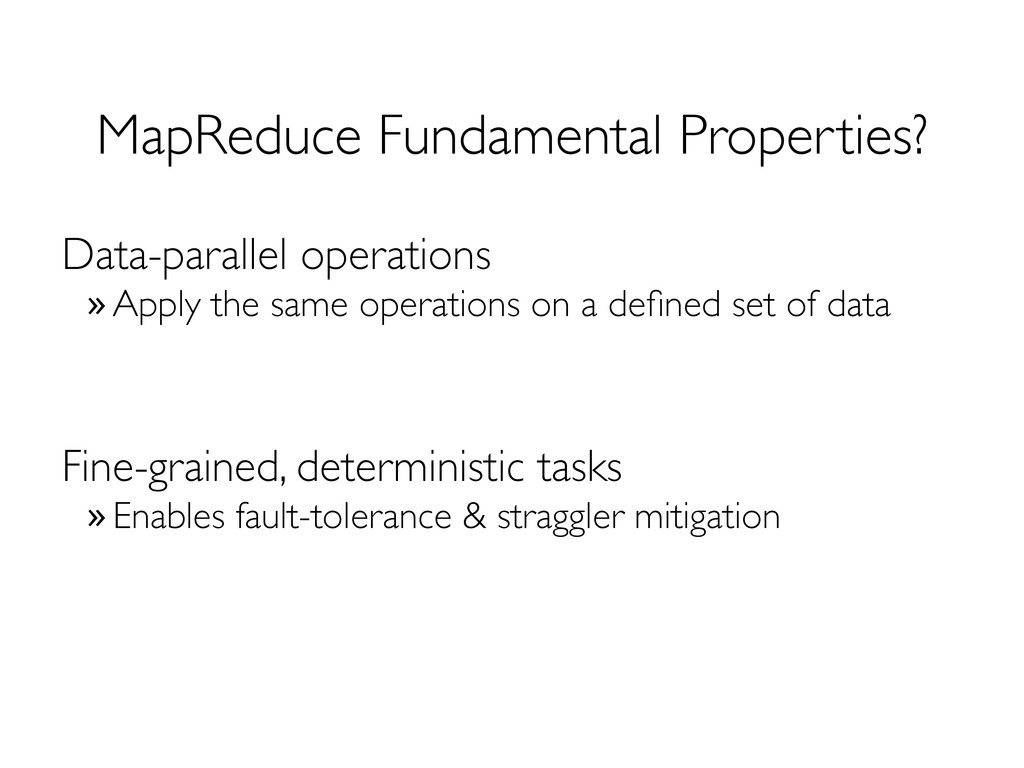
  6. MapReduce Fundamental Properties? ! Data-parallel operations! » Apply the same operations

    on a defined set of data! ! Fine-grained, deterministic tasks! » Enables fault-tolerance & straggler mitigation!
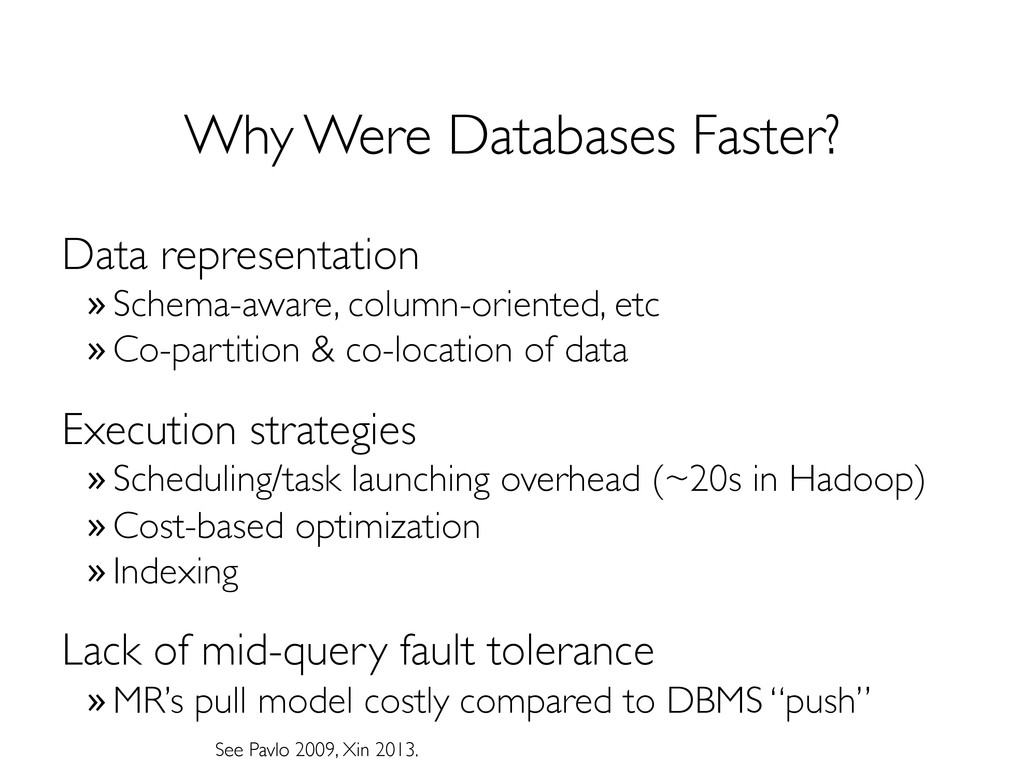
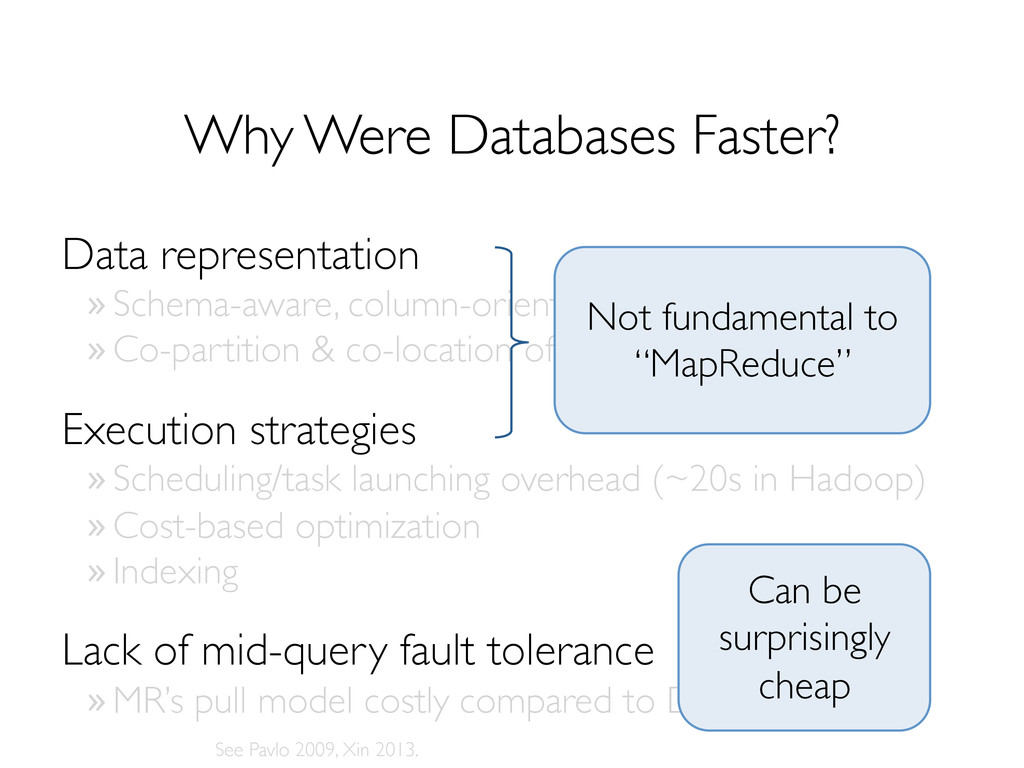
  7. Why Were Databases Faster? ! Data representation! » Schema-aware, column-oriented, etc!

    » Co-partition & co-location of data! Execution strategies! » Scheduling/task launching overhead (~20s in Hadoop)! » Cost-based optimization! » Indexing! Lack of mid-query fault tolerance! » MR’s pull model costly compared to DBMS “push”! See Pavlo 2009, Xin 2013.!
  8. Why Were Databases Faster? ! Data representation! » Schema-aware, column-oriented, etc!

    » Co-partition & co-location of data! Execution strategies! » Scheduling/task launching overhead (~20s in Hadoop)! » Cost-based optimization! » Indexing! Lack of mid-query fault tolerance! » MR’s pull model costly compared to DBMS “push”! See Pavlo 2009, Xin 2013.! Not fundamental to “MapReduce”! Can be surprisingly cheap!
  9. Introducing Shark ! MapReduce-based architecture! » Uses Spark as the underlying

    execution engine! » Scales out and tolerate worker failures! Performant! » Low-latency, interactive queries! » (Optionally) in-memory query processing! Expressive and flexible! » Supports both SQL and complex analytics! » Hive compatible (storage, UDFs, types, metadata, etc)!
  10. Spark Engine ! Fast MapReduce-like engine! » In-memory storage for fast

    iterative computations! » General execution graphs! » Designed for low latency (~100ms jobs)! Compatible with Hadoop storage APIs! » Read/write to any Hadoop-supported systems, including HDFS, Hbase, SequenceFiles, etc! Growing open source platform! » 17 companies contributing code!
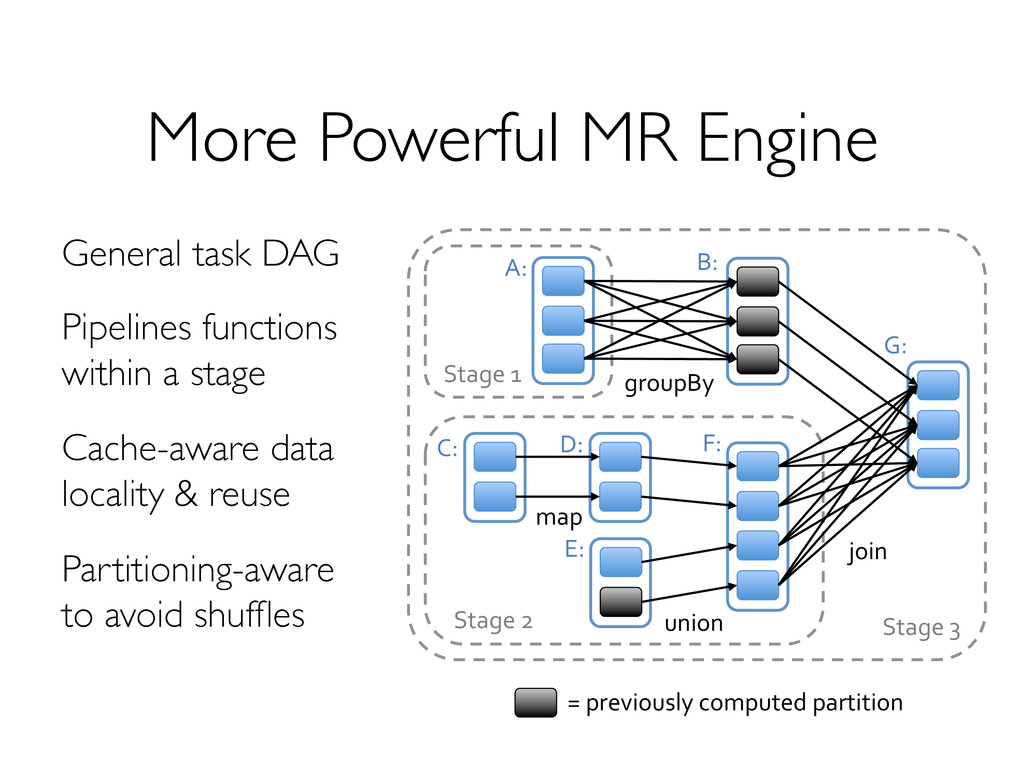
  11. More Powerful MR Engine ! General task DAG! Pipelines functions"

    within a stage! Cache-aware data" locality & reuse! Partitioning-aware" to avoid shuffles! join% union% groupBy% map% Stage%3% Stage%1% Stage%2% A:% B:% C:% D:% E:% F:% G:% =%previously%computed%partition%
  12. ! Client! CLI! JDBC! Hive Architecture ! Meta store! Hadoop

    Storage (HDFS, S3, …)! Driver! SQL Parser! Query Optimizer! Physical Plan! Execution! MapReduce!
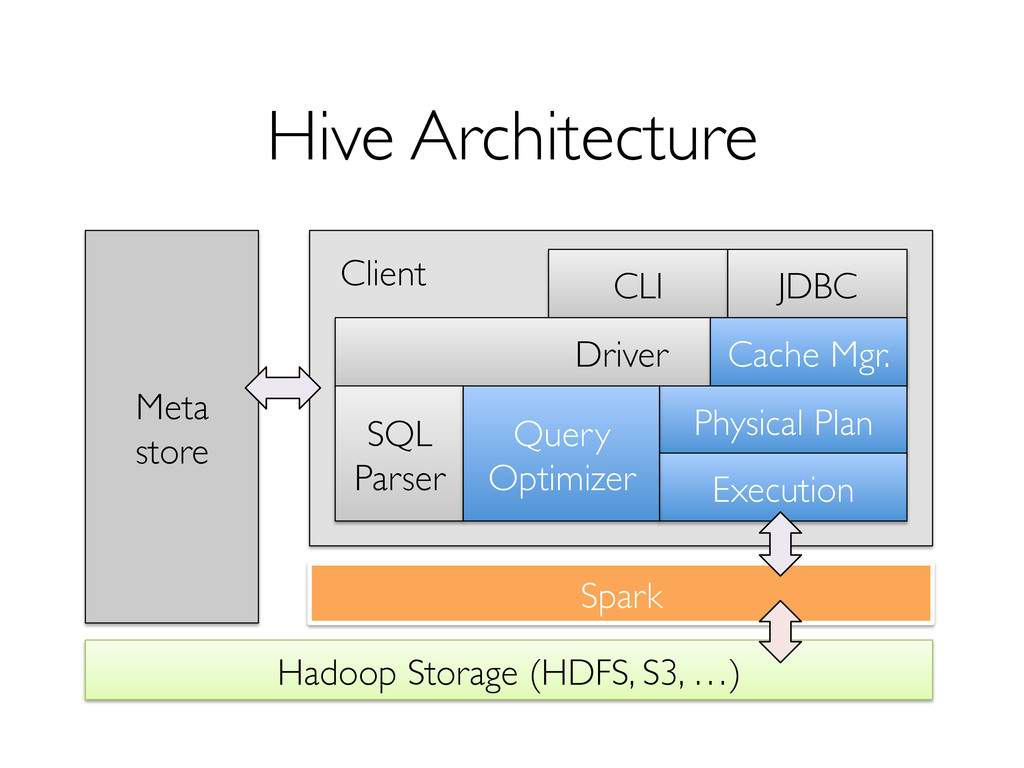
  13. ! Client! CLI! JDBC! Hive Architecture ! Meta store! Hadoop

    Storage (HDFS, S3, …)! Driver! SQL Parser! Spark! Cache Mgr.! Physical Plan! Execution! Query Optimizer!
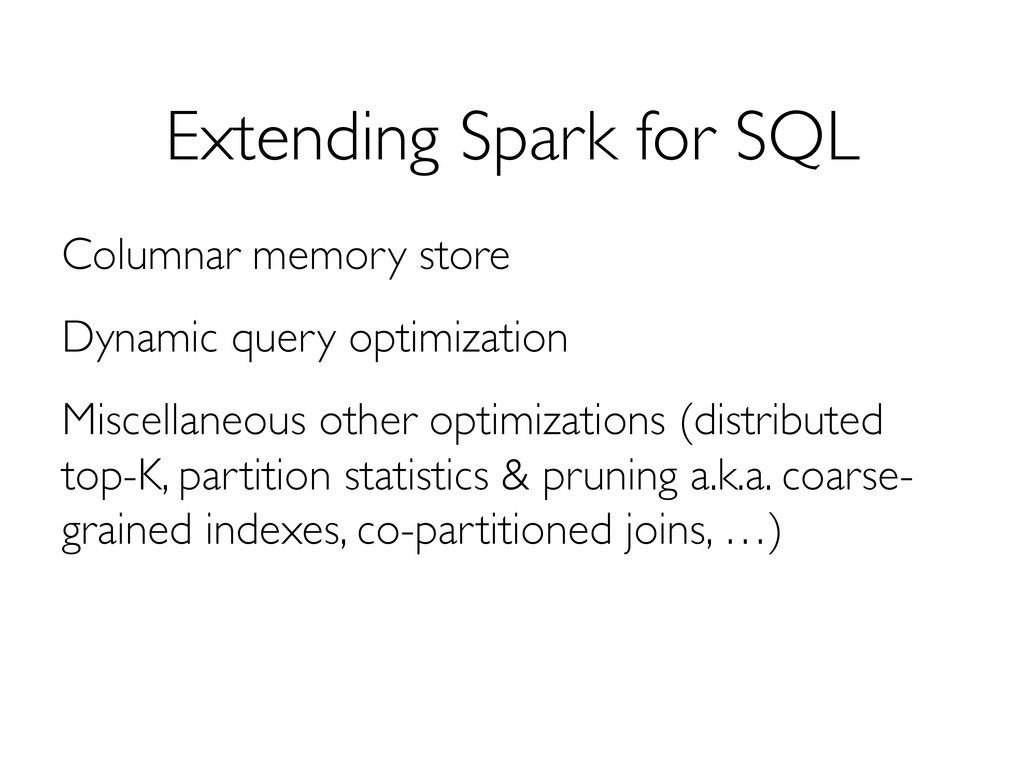
  14. Extending Spark for SQL ! Columnar memory store! Dynamic query

    optimization! Miscellaneous other optimizations (distributed top-K, partition statistics & pruning a.k.a. coarse- grained indexes, co-partitioned joins, …)!
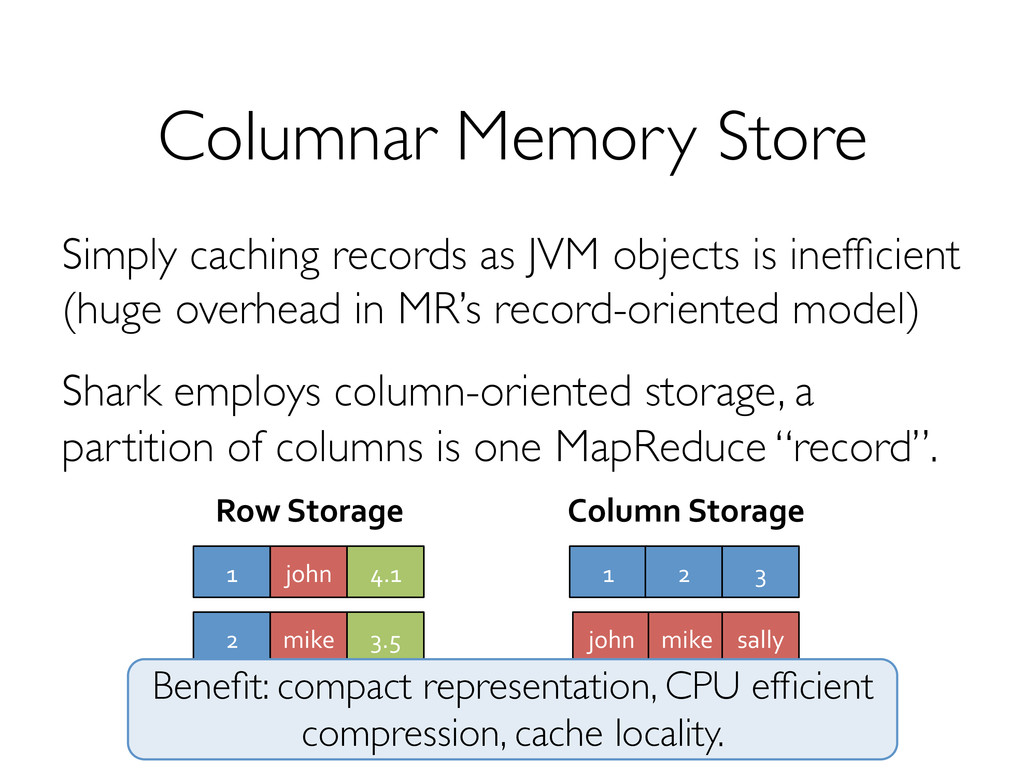
  15. Columnar Memory Store ! Simply caching records as JVM objects

    is inefficient (huge overhead in MR’s record-oriented model)! Shark employs column-oriented storage, a partition of columns is one MapReduce “record”.! 1% Column'Storage' 2% 3% john% mike% sally% 4.1% 3.5% 6.4% Row'Storage' 1% john% 4.1% 2% mike% 3.5% 3% sally% 6.4% Benefit: compact representation, CPU efficient compression, cache locality.!
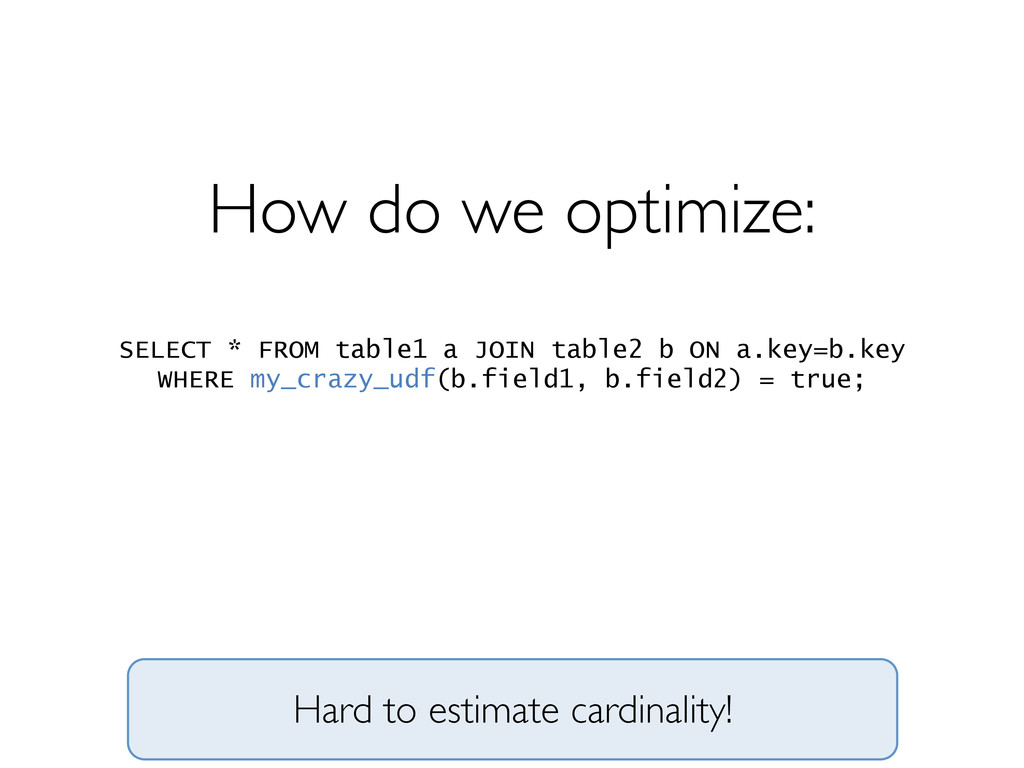
  16. How do we optimize:" " SELECT * FROM table1 a

    JOIN table2 b ON a.key=b.key WHERE my_crazy_udf(b.field1, b.field2) = true; Hard to estimate cardinality!!
  17. Partial DAG Execution (PDE) ! Lack of statistics for fresh

    data and the prevalent use of UDFs necessitate dynamic approaches to query optimization.! ! PDE allows dynamic alternation of query plans based on statistics collected at run-time.!
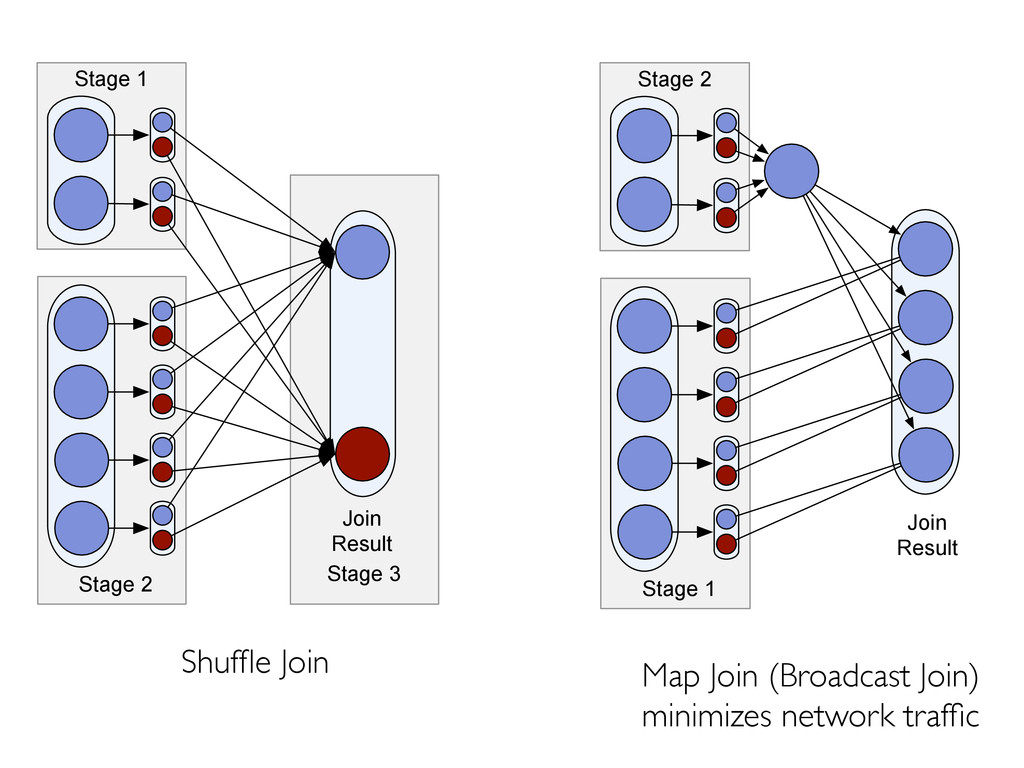
  18. Shuffle Join! Stage 3 Stage 2 Stage 1 Join Result

    Stage 1 Stage 2 Join Result Map Join (Broadcast Join)! minimizes network traffic!
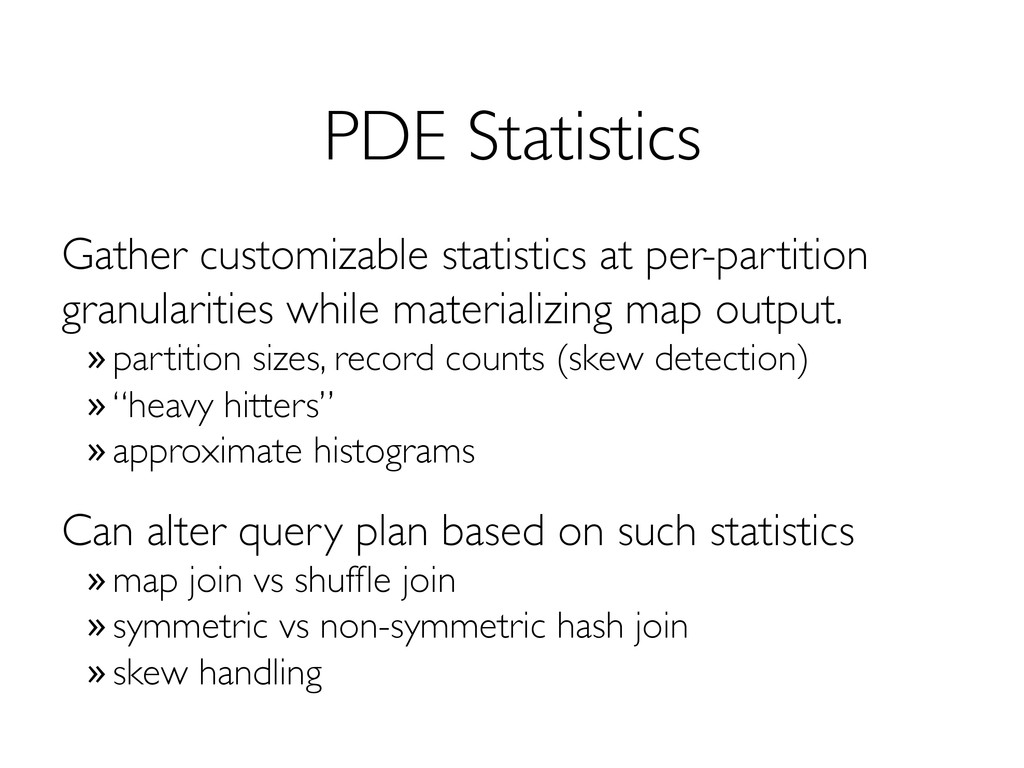
  19. PDE Statistics ! Gather customizable statistics at per-partition granularities while

    materializing map output.! » partition sizes, record counts (skew detection)! » “heavy hitters”! » approximate histograms! Can alter query plan based on such statistics! » map join vs shuffle join! » symmetric vs non-symmetric hash join! » skew handling!
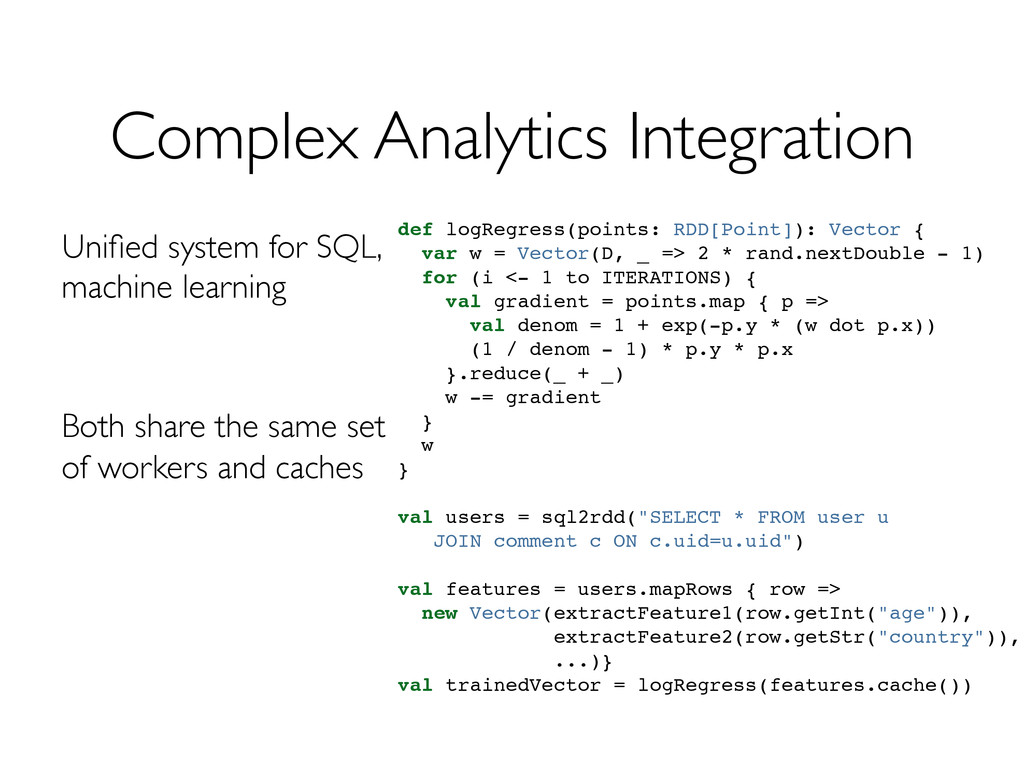
  20. Complex Analytics Integration ! Unified system for SQL, machine learning!

    ! Both share the same set of workers and caches! def logRegress(points: RDD[Point]): Vector { var w = Vector(D, _ => 2 * rand.nextDouble - 1) for (i <- 1 to ITERATIONS) { val gradient = points.map { p => val denom = 1 + exp(-p.y * (w dot p.x)) (1 / denom - 1) * p.y * p.x }.reduce(_ + _) w -= gradient } w } val users = sql2rdd("SELECT * FROM user u JOIN comment c ON c.uid=u.uid") val features = users.mapRows { row => new Vector(extractFeature1(row.getInt("age")), extractFeature2(row.getStr("country")), ...)} val trainedVector = logRegress(features.cache())
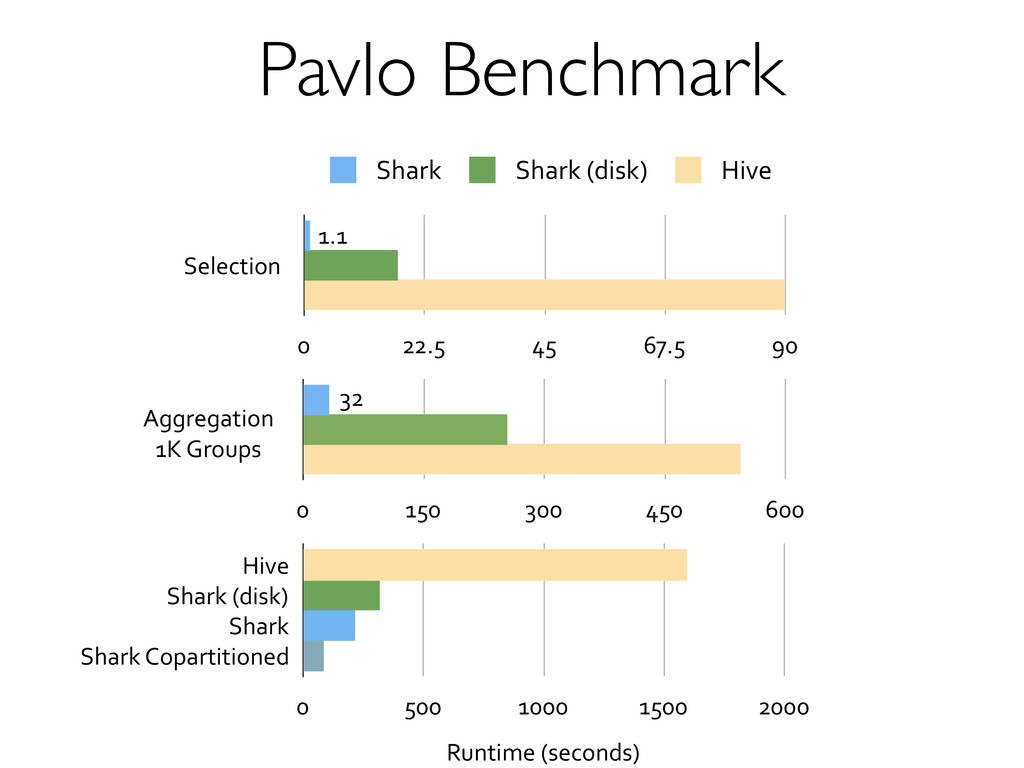
  21. Pavlo Benchmark ! Selection 0 22.5 45 67.5 90 Shark

    Shark5(disk) Hive 1.1 0 150 300 450 600 Aggregation 1K5Groups 32 Hive Shark5(disk) Shark Shark5Copartitioned 0 500 1000 1500 2000 Runtime5(seconds)
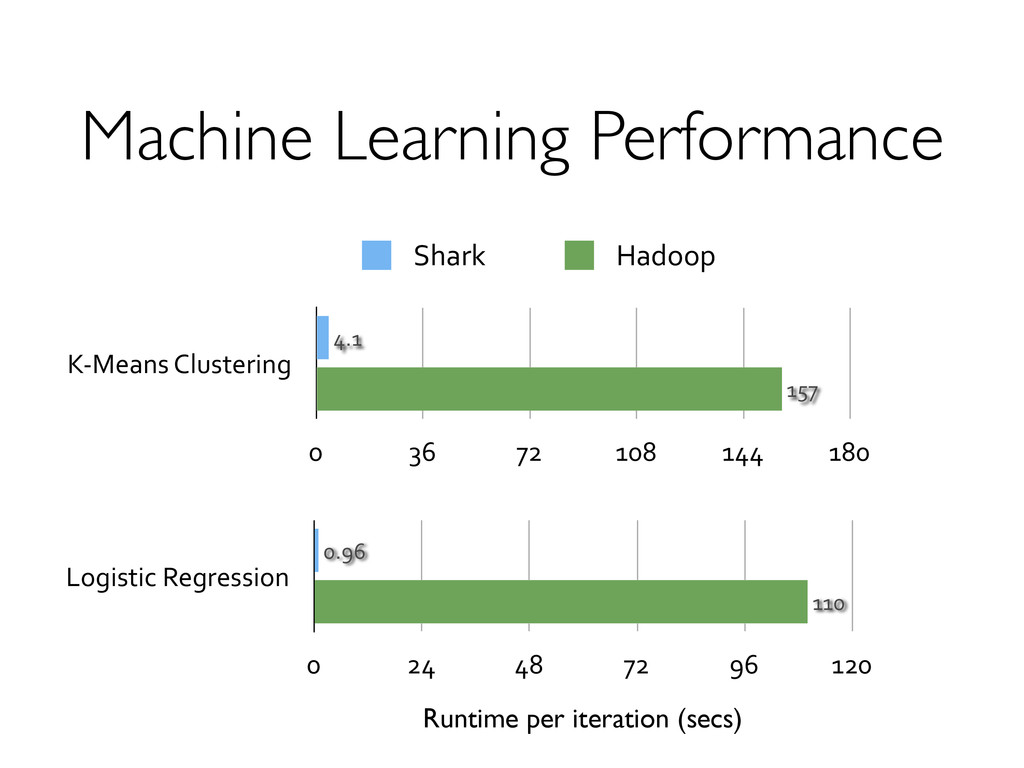
  22. Machine Learning Performance ! K"Means(Clustering 0 36 72 108 144

    180 157 4.1 Logistic(Regression 0 24 48 72 96 120 110 0.96 Shark Hadoop Runtime per iteration (secs)
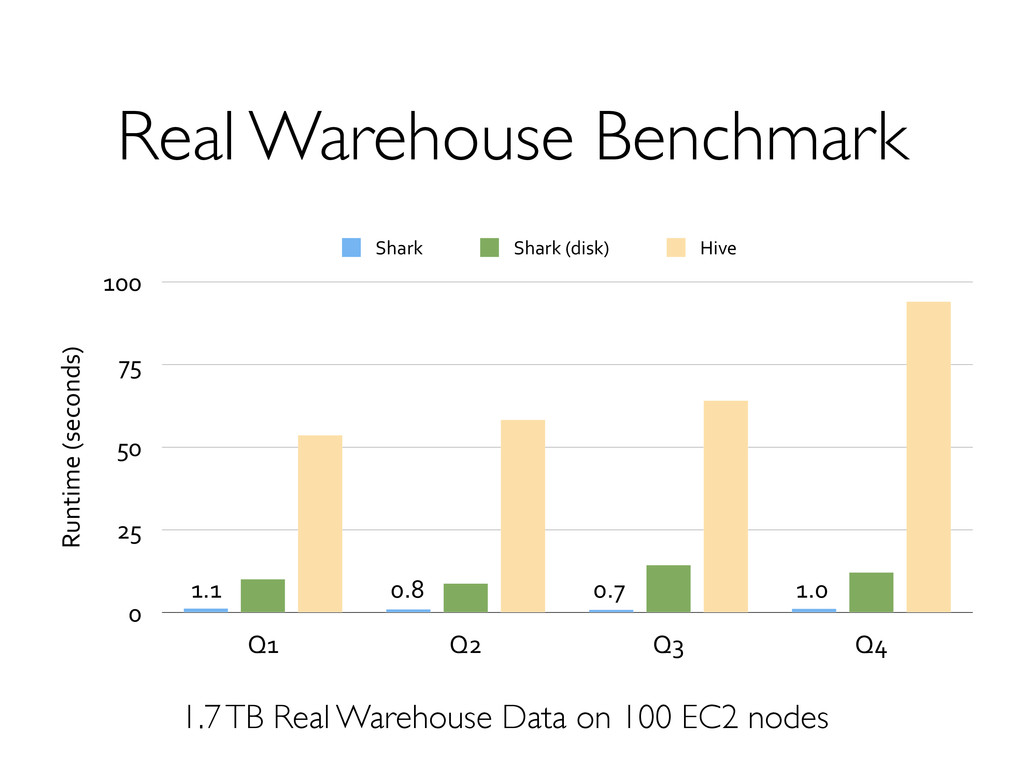
  23. Real Warehouse Benchmark ! 0 25 50 75 100 Q1

    Q2 Q3 Q4 Runtime0(seconds) Shark Shark0(disk) Hive 1.1 0.8 0.7 1.0 1.7 TB Real Warehouse Data on 100 EC2 nodes!
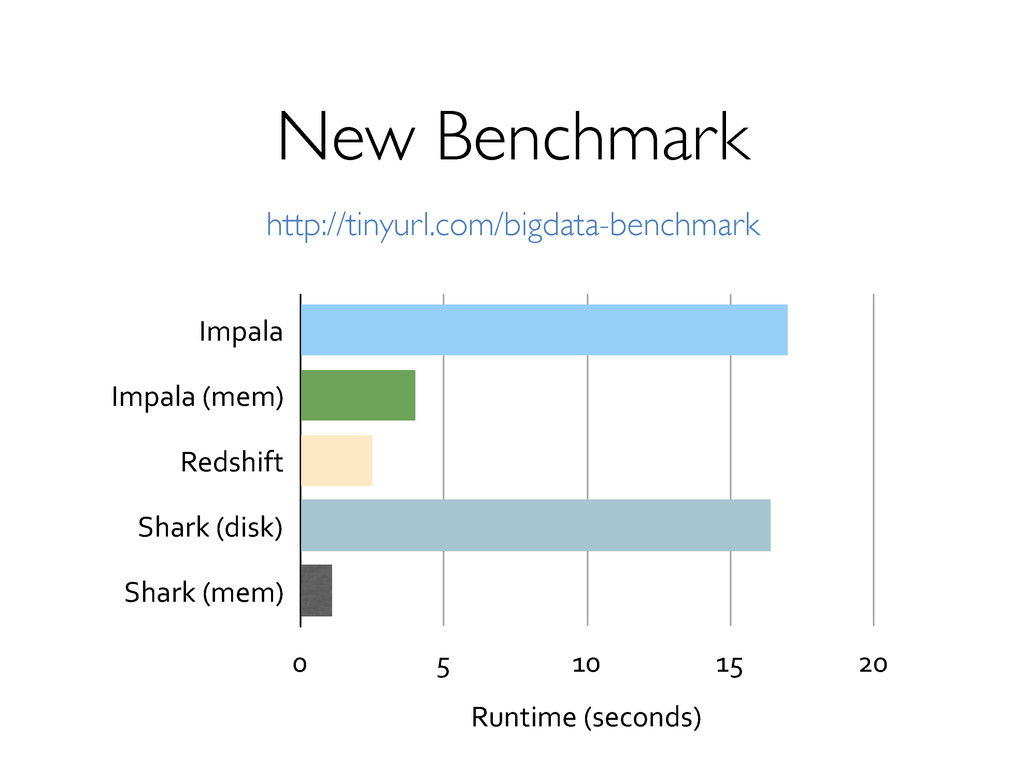
  24. New Benchmark ! Impala Impala&(mem) Redshift Shark&(disk) Shark&(mem) 0 5

    10 15 20 Runtime&(seconds) http://tinyurl.com/bigdata-benchmark!
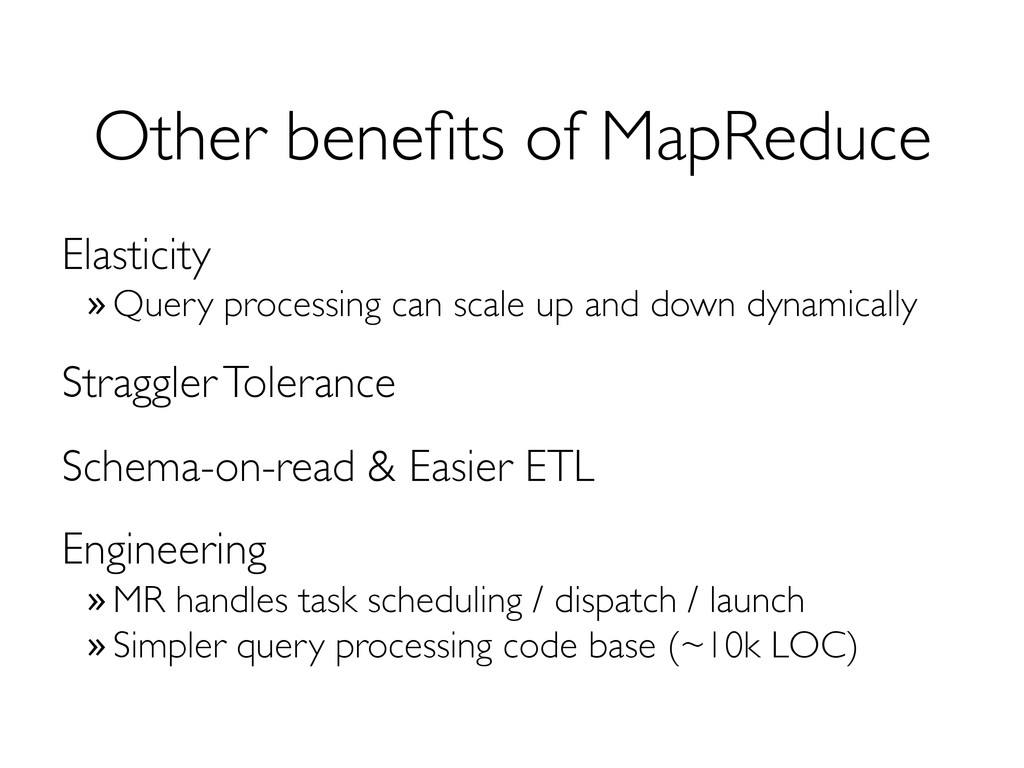
  25. Other benefits of MapReduce ! Elasticity! » Query processing can scale

    up and down dynamically! Straggler Tolerance! Schema-on-read & Easier ETL! Engineering! » MR handles task scheduling / dispatch / launch! » Simpler query processing code base (~10k LOC)!
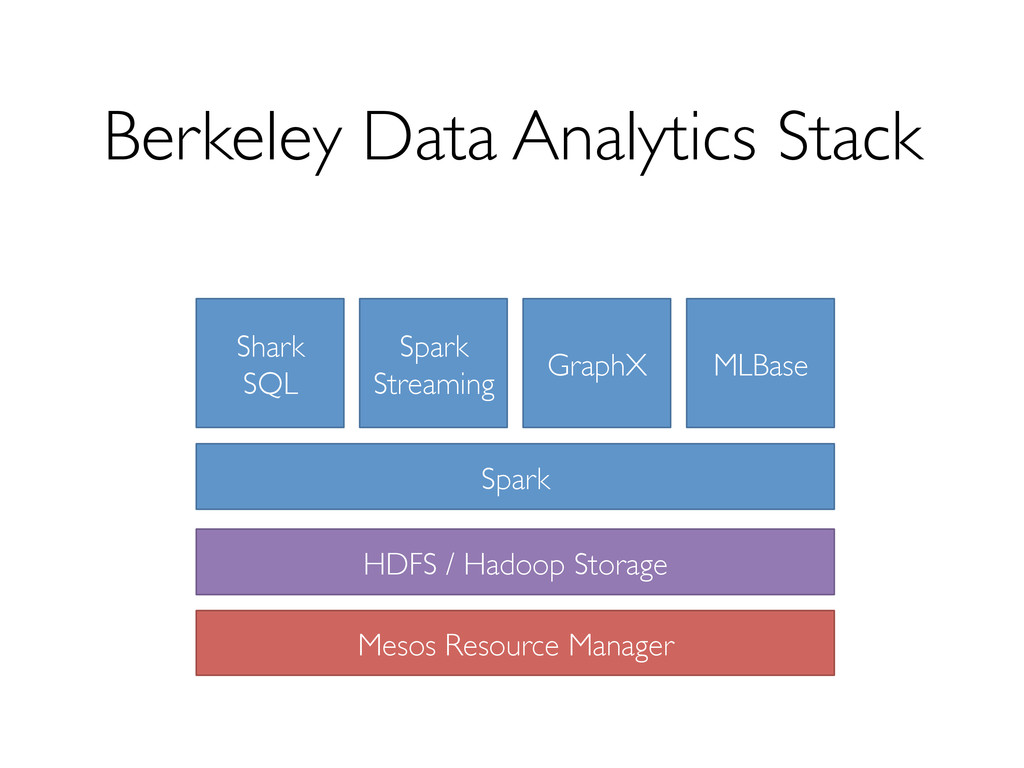
  26. Berkeley Data Analytics Stack ! Spark! Shark! SQL! HDFS /

    Hadoop Storage! Mesos Resource Manager! Spark Streaming! GraphX! MLBase!
  27. Conclusion ! Leveraging a modern MapReduce engine and techniques from

    databases, Shark supports both SQL and complex analytics efficiently, while maintaining fault-tolerance.! Growing open source community! » Users observe similar speedups in real use cases! » http://shark.cs.berkeley.edu! » http://www.spark-project.org! !

More Decks by Reynold Xin

Other Decks in Technology